Search Results: "ed"

24 October 2017

Iain R. Learmonth: Security by Obscurity

Today this blog post turned up on Hacker News, titled Obscurity is a Valid Security Layer . It makes some excellent points on the distinction between good and bad obscurity and it gives an example of good obscurity with SSH. From the post:
I configured my SSH daemon to listen on port 24 in addition to its regular port of 22 so I could see the difference in attempts to connect to each (the connections are usually password guessing attempts). My expected result is far fewer attempts to access SSH on port 24 than port 22, which I equate to less risk to my, or any, SSH daemon. I ran with this alternate port configuration for a single weekend, and received over eighteen thousand (18,000) connections to port 22, and five (5) to port 24.
Those of you that know me in the outside world will have probably heard me talk about how it s insane we have all these services running on the public Internet that don t need to be there, just waiting to be attacked. I have previously given a talk at TechMeetup Aberdeen where I talk about my use of Tor s Onion services to have services that only I should ever connect to be hidden from the general Internet. Onion services, especially the client authentication features, can also be useful for IoT dashboards and devices, allowing access from the Internet but via a secure and authenticated channel that is updated even when the IoT devices behind it have long been abandoned. If you re interested to learn more about Onion services, you could watch Roger Dingledine s talk from Def Con 25.

Daniel Silverstone: Introducing the car

For many years now, I have been driving a diesel based VW Passat Estate. It has served me very well and been as reliable as I might have hoped given how awful I am with cars. Sadly Gunther was reaching the point where it was going to cost more per year to maintain than the car was worth, and also I've been being more and more irked by not having a car from the future. I spent many months doing spreadsheets, trying to convince myself I could somehow afford a Tesla of some variety. Sadly I never quite managed it. As such I set my sights on the more viable BEVs such as the Nissan Leaf. For a while, nothing I saw was something I wanted. I am quite unusual it seems, in that I don't want a car which is a "Look at me, I'm driving an electric car" fashion statement. I felt like I'd never get something which looked like a normal car, but happened to be a BEV. Then along came the Hyundai Ioniq. Hybrid, Plug-in Hybrid, and BEV all looking basically the same, and not in-your-face-special. I began to covet. Eventually I caved and arranged a test drive of an Ioniq plug-in hybrid because the BEV was basically on 9 month lead. I enjoyed the drive and was instantly very sad because I didn't want a plug-in hybrid, I wanted a BEV. Despondent, I left the dealership and went home. I went online and found a small number of second-hand Ioniq BEVs but as I scrolled through the list, none seemed to be of the right trim level. Then, just as I was ready to give up hope, I saw a new listing, no photo, of the right thing. One snag, it was 200 miles away. No matter, I rang the place, confirmed it was available, and agreed to sleep on the decision. The following morning, I hadn't decided to not buy, so I called them up, put down a deposit to hold the car until I could test drive it, and then began the long and awkward process of working out how I would charge the car given I have no off-street parking so I can't charge at home. (Yeah yeah, you'd think I'd have checked that first, but no I'm just not that sensible). Over the week I convinced myself I could do it, I ordered RFID cards for various schemes, signed up with a number of services, and then, on Friday last week, I drove down to a hotel near the dealership and had a fitful night's sleep. I rocked up to the dealership exactly as they opened for business, shook the hand of the very helpful salesman who had gone through the purchase process with me over the phone during the week, and got to see the car. Instant want coursed through me as I sat in it and decided "Yes, this somehow feels right". I took the car for about a 45 minute test drive just to see how it felt relative to the plug-in hybrid I'd driven the week before and it was like night and day. The BEV felt so much better to drive. I was hooked. Back to the dealership and we began the paperwork. Emptying Gunther of all of the bits and bobs scattered throughout his nooks and crannies took a while and gave me a chance to say goodbye to a car which, on reflection, had actually been a pleasure to own, even when its expensive things went wrong, more than once. But once I'd closed the Passat for the last time, and handed the keys over, it was quite a bittersweet moment as the salesman drove off in what still felt like my car, despite (by this point) it not being so. Sitting in the Ioniq though, I headed off for the 200 mile journey back home. With about 90% charge left after the test drive, I had two stops planned at rapid chargers and I headed toward my first. Unfortunately disaster struck, the rapid (50KW) charger refused to initialise, and I ended up with my car on the slower (7KW) charger to get enough juice into it to drive on to the next rapid charger enabled service station. When I got the message that my maximum charge period (45m) had elapsed, I headed back to the car to discover I couldn't persuade it to unlock from the car. Much hassle later, and an AA man came and together we learned that it takes 2 to tango, one to pull the emergency release in the boot, the other to then unplug the cable. Armed with this knowledge, I headed on my way to a rapid charger I'd found on the map which wasn't run by the same company. Vainly hoping that this would work better, I plugged the car in, set the charger going, and headed into the adjacent shop for a rest break. I went back to the car about 20 minutes later to see the charger wasn't running. Horror of horrors. I imagined maybe some nasty little oik had pressed 'stop' so I started the charger up again, and sat in the car to read my book. After about 3 minutes, the charge stopped. Turns out that charger was slightly iffy and couldn't cope with the charge current and kept emergency-stopping as a result. The lovely lady I spoke to about it directed me to a nearby (12 miles or so, easily done with the charge I had) charger in the grounds of a gorgeous chateau hotel. That one worked perfectly and I filled up. I drove on to my second planned stop and that charge went perfectly too. In fact, every charge since has gone flawlessly. So perhaps my baptism of failed charges has hardened me to the problems with owning a BEV. I've spent the past few days trying different charge points around Manchester enjoying my free charge capability, and trying different names for the car before I finally settled on which is a reasonable Korean boy's name (since the car is Korean I even got to set that as the bluetooth ID) and it's roughly pronounced sock/gin which are two wonderful things in life. I'm currently sat in a pub, eating a burger, enjoying myself while suckles on the teat of "free" electricity to make up for the fact that I've developed a non-trivial habit of leaving Audi drivers in the dust at traffic lights. Further updates may happen as I play with Android Auto and other toys in an attempt to eventually be able to ask the car to please "freeze my buttocks" (a feature it has in the form of air-conditioned seats.)

Reproducible builds folks: Reproducible Builds: Weekly report #130

Here's what happened in the Reproducible Builds effort between Sunday October 15 and Saturday October 21 2017: Past events Upcoming events New York University sessions A three week session will be held at New York University to work on reproducibilty issues in conjunction with the reproducible builds community. Students from the Application Security course will be working for two weeks to work on the reproducible builds effort. Packages reviewed and fixed, and bugs filed The following reproducible builds-related NMUs were accepted: Patches sent upstream: Reviews of unreproducible packages 41 package reviews have been added, 119 have been updated and 54 have been removed in this week, adding to our knowledge about identified issues. 2 issue types were removed as they were fixed: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development strip-nondeterminism development Version 0.039-1 was uploaded to unstable by Chris Lamb. It included contributions already covered by posts of the previous weeks, including: reprotest development tests.reproducible-builds.org Website updates Misc. This week's edition was written by Bernhard M. Wiedemann, Chris Lamb, Holger Levsen, Santiago Torres & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Holger Levsen: 20171024-Reproducible-Builds-Summit-3

Reproducible Builds Summit 3 next week in Berlin Next week from Tuesday, the 31st of October until Thursday, November 2nd, we'll have the 3rd Reproducible Builds summit in Berlin, to improve collaboration both between and inside projects, expand the scope and reach of reproducible builds to more projects and to brainstorm designs on tools enabling users to get the most benefits from reproducible builds. We're again expecting contributors from around twenty projects and we're still having some free seats available. If you want to join this meeting, please register by sending us a short mail briefly describing why (eg. by stating you involvement in some project). We also have some funding available to further rextend the diversity of our community, so please also contact us if you think you cannot make it for financial reasons! Personally I'm much looking forward to this event. The reproducible builds crowd is really a lovely bunch of people and thus I expect us to have some great discussions, some cool ideas and also some concrete actionable plans as a result of it. Totally worth it! Talk about Reproducible Builds at OSSE in Prague tomorrow Tomorrow, Wednesday, October 25th I'll be giving a talk at OSSE in Prague about the current status of Reproducible Builds and why we are not 'there' yet. I'd be glad to have a chat with you if you are there!

Russ Allbery: Review: Raven Stratagem

Review: Raven Stratagem, by Yoon Ha Lee
Series: Machineries of Empire #2
Publisher: Solaris
Copyright: 2017
ISBN: 1-78618-046-4
Format: Kindle
Pages: 400
Raven Stratagem is the sequel to Ninefox Gambit and will make very little sense if you've not read the previous book. In fact, I'll add a rare warning, one that I wish I'd had and followed: you need to be deeply familiar with the details of the end of Ninefox Gambit or large chunks of this book will make no sense. I read the previous book earlier this year, but my memory of some of the specifics of the ending had slipped, and I ended up having to skim the ending of the previous book several times. Consider re-reading that bit before starting this book if you share my lack of memory for plot specifics and it's been more than a few months. I unfortunately can't provide a plot summary, since there's almost nothing I can say about the plot that doesn't spoil Ninefox Gambit. It is basically the story that you would expect from the very end of Ninefox Gambit, though, although the way it's carried out is not quite as dramatic as I was expecting. I wanted to like this book a great deal. Ninefox Gambit introduced a beautiful magitech system, but it was otherwise mostly setup and one extended battle. Its ending promised engagement with larger universe politics, and prospects of doing something about the deep unfairness of the current political system. I was hoping this book would contain the payoff of that escalation. It does deliver on that payoff, but something about it didn't quite work for me. The best description I've been able to come up with is that Raven Stratagem skitters. Some of this is an increase in the number of viewpoint characters, which made it harder for me to get into a reading rhythm with any of them. But most of it, I think, is that the characters have so many layers of deception, emotional shielding, weariness, and resignation that it's hard to find the true emotional beats of the story except in retrospect. I kept bouncing off surfaces, so many different and conflicting surfaces. This book is full of people who are not being honest with each other, or sometimes with themselves, and who are pretending to motives they don't really have. As a reader, I wanted to be placed in a privileged position where I could experience the character emotions even when they were lying about them. For good or ill, Raven Stratagem doesn't do that. There was also something about the dramatic structure of the story that didn't work for me. When describing the book to a friend, I said that the main plot climax was off-camera. In skimming the book again for this review, I found that wasn't the case, but it still felt that way. I think that's because, despite some event build-up, the emotional build-up wasn't in place for me, so I wasn't ready as a reader for the climax when it came. The build-up to the climax is partly sacrificed to keep the secrecy of a couple of long-awaited revelations. I very much enjoyed those revelations (one satisfying one was set up with Cheris's behavior at the start of Ninefox Gambit), but I wanted the catharsis of the climax as well. As written, the strongest emotional hit was from a somewhat ancillary climax, and that involved characters who mattered considerably less to me than Cheris. The climax also involves quite a lot of hand-waving. While some of that is expected in magitech, I would have liked to understand the mechanisms of what happened, not just the effects. Lee introduces several new viewpoint characters here, including two very contrasting Kel. I warmed to them by the end of the book, but I liked Cheris as a viewpoint character considerably better than either of them. Both of them spend most of this book in conditions of varying powerlessness; Cheris, despite difficult circumstances, was at least driving the plot. I can kind of see why Lee picked the viewpoint characters he did, but I still feel grumbly about it. I would have loved to have a servitor as a primary viewpoint character in this story. All that said, I'm still glad I read this book. The climax is satisfying, as is the growing respect of the characters and the growing realization of just how the universe is being changed. I wanted more of that on camera rather than being held for dramatic surprise, but I still savored it when it happened. The mechanisms of the Hexarchate, particularly formation instinct, are considerably creepier than Ninefox Gambit reveals, which is saying something, and yet oddly logical in their own magitech way. I liked all the pieces; I just wanted them to have more emotional oomph and momentum. Instead, I felt like I was bringing my own emotion to the story rather than letting the story sweep me away, which meant being more analytical and less engrossed than I prefer to be in a novel. I'm still going to read the third book, though. By the end of Raven Stratagem, Lee has set most of the scenery on fire, and I want to see what sort of world rises from the flames. Rating: 6 out of 10

23 October 2017

Patrick Schoenfeld: Testing javascript in a dockerized rails application with rspec-rails

The other day I wanted to add support for tests of javascript functionality in a (dockerized) rails application using rspec-rails. Since rails 5.1 includes system tests with niceties like automatically taking a screenshot on failed tests, I hoped for a way to benefit from this
features without changing to another test framework. Lucky me only recently the authors of rspec-rails added support for so-called system specs. There is not much documentation so far (but there are a lot of useful information in the corresponding bug report #1838 and a friendly guy named Thomas Walpole (@twalpole) is helpfully answering to questions in that issue. To make things a little bit more complicated: the application in question is usually running in a docker container and thus the tests of the application are also run in a docker container. I didn t want to change this, so here is what it took me to get this running. Overview Let s see what we want to achieve exactly: From a technical point of view, we will have the application under test (AUT) and the tests in one container (let s call it: web) and we will need another container running a javascript-capable browser (let s call it browser). Thus we need the tests to drive a remote running browser (at least when running in a docker environment) which needs to access the application under a different address than usually. Namely an address reachable by the chrome-container, since it will not be reachable via 127.0.0.1 as is (rightfully) assumed by default. If we want Warden authentication stubbing to work (as we do, since our application uses Devise) and transactional fixtures as well (e.g. rails handling database cleanup between tests without database_cleaner gem) we also need to ensure that the application server is being started by the tests and the tests are actually run against that server. Otherwise we might run into problems. Getting the containers ready Assuming you already have a container setup (and are using docker-compose like we do) there is not that much to change on the docker front. Basically you need to add a new service called chrome and point it to an appropriate image and add a link to it in your existing web-container. I ve decided to use standalone-chrome for the browser part, for which there are docker images provided by the selenium project (they also have images for other browsers). Kudos for that.
...
services:
  chrome:
    image: selenium/standalone-chrome
   
  web:
   
    links:
      - chrome
The link ensures that the chrome instance is available before we run the tests and that the the web-container is able to resolve the name of this container. Unfortunately this is not true for the other way round, so we need some magic in our test code to find out the ip-address of the web-container. More to this later. Other than that, you probably want to configure a volume for you to be able to access the screenshots, which get saved to tmp/screenshots
in the application directory. Preparing the application for running system tests There is a bit more to do on the application side. The steps are roughly:
  1. Add necessary depends / version constraints
  2. Register a driver for the remote chrome
  3. Configure capybara to use the appropriate host for your tests (and your configured driver)
  4. Add actual tests with type: :system and js: true
Let s walk them through. Add necessary depends What we need is the following: The required features are already part of 3.7.0, but this version is the version I used and it contains a bugfix, which may or may not be relevant. One comment about the rails version: for the tests to properly work it s viable to have puma use certain settings. In rails 5.1.4 (the version released, at time of writing this) uses the settings from config/puma.rb which most likely collides with the necessary settings. You can ensure these settings yourself or use rails from branch 5-1-stable which includes this change. I decided for the latter and pinned my Gemfile to the then current commit. Register a driver for the remote chrome To register the required driver, you ll have to add some lines to your rails_helper.rb:
if ENV['DOCKER']
  selenium_url =
      "http://chrome:4444/wd/hub"
  Capybara.register_driver :selenium_remote do  app 
    Capybara::Selenium::Driver.new(app,
         :url => selenium_url, :browser => :remote, desired_capabilities: :chrome )
  end
end
Note that I added those lines conditionally (since I still want to be able to use a local chrome via chromedriver) if an environment variable DOCKER is set. We defined that environment variable in our Dockerfile and thus you might need to adapt this to your case. Also note that the selenium_url is hard-coded. You could very well take a different approach, e.g. using an externally specified SELENIUM_URL, but ultimately the requirement is that the driver needs to know that the chrome instance is running on host chrome, port 4444 (the containers default). Configure capybara to use the appropriate host and driver The next step is to ensure that javascript-requiring system tests are actually run with the given driver and use the right host. To achieve that we need to add a before-hook to the corresponding tests or we can configure rspec accordingly to always include such a hook by modifying the rspec-configuration in rails_helper.rb like this:
RSpec.configure do  config 
  ...
  config.before(:each, type: :system, js: true) do
    if ENV['DOCKER']
      driven_by :selenium_remote
      ip = Socket.ip_address_list.detect addr  addr.ipv4_private?  .ip_address
      host! "http://# ip :# Capybara.server_port "
    else
      driven_by :headless_chrome
    end
  end
Note the part with the ip-address: it tries to find an IPv4 private address for the web-container (the container running the tests) to ensure the chrome-container uses this address to access the application. The Capybara.server_port is important here, since it will correspond to the puma instance launched by the tests. That heuristic (first ipv4 private address) works for us at the moment, but it might not work for you. It is basically a workaround to the fact that I couldn t get web resolvable for the chrome container which may be fixable on the docker side, but I was to lazy to further investigate that. If you change it: Just make sure the host! method uses an URI pointing to an address of the web-container that is reachable to the chrome-container. Define tests with type: :system and js: true Last but certainly not least, you need actual tests of the required type and with or without js: true. This can be achieved by creating tests files starting like this:
RSpec.feature "Foobar", type: :system, js: true do
Since the new rspec-style system tests are based around the feature-specs which used to be around previously, the rest of the tests is exactly like it is described for feature specs. Run the tests To run the tests a commandline like the following should do: docker-compose run web rspec It won t make a big noise about running the tests against chrome, unless something fails. In that case you ll see a message telling you where the screenshot has been placed. Troubleshooting Below I add some hints about problems I ve seen during configuring that: Test failing, screenshot shows login screen In that case puma might be configured wrongly or you are not using transactional fixtures. See the hints above about the rails version to use which also includes some pointers to helpful explanations. Note that rspec-rails by default does not output the puma startup output as it clutters the tests. For debugging purposes it might be helpful to change that by adding the following line to your tests:
ActionDispatch::SystemTesting::Server.silence_puma = false
Error message: Unable to find chromedriver This indicates that your driver is not configured properly, because the default for system tests is to be driven_by selenium, which tries to spawn an own chrome instance and is suitable for non-dockerized tests. Check if your tests are marked as js: true (if you followed the instructions above) and that you properly added the before-hook to your rspec-configuration. Collisions with VCR If you happen to have tests that make use of the vcr gem you might see it complaining about not knowing what to do with the requests between the driver and the chrome instance. You can fix this, by telling VCR to ignore that requests, by adding a line where you configured VCR:
VCR.configure do  config 
# required so we don't collide with capybara tests
config.ignore_hosts 'chrome'
...

Arturo Borrero Gonz lez: New job at Wikimedia Foundation

Wikimedia Foundation logo Today it s my first day working at the Wikimedia Foundation, the non-profit foundation behind well-known projects like Wikipedia and others. This is a full-time, remote job as part of the Wikimedia Cloud Services team, as Operations Engineer. I will be working with modern infrastructure/hosting technologies such as OpenStack and Kubernetes to provide support to the Wikimedia movement and community. All contributors of the movement that provide value to the Wikimedia movement are welcome to use our resources. The recruitment process took several months and was really challenging, 6 or 7 interviews with different people with, of course, heavy technical checks. The Wikimedia Foundation has been always in my radar due to 2 facts:
  1. They serve a very relevant mission, commited to freedom of knowledge, community colaboration, focusing in the benefit that this provides to the society.
  2. They have a huge infrastructure/technological deployment which, among other things, allows Wikipedia to be one of the TOP5-TOP10 websites.
This new job is a big challenge for me and I m a bit nervous. I feel like this is a big step forward in my professional career and I will try to do my best :-) My new email address is aborrero@wikimedia.org. You can find me in IRC freenode as well, nick arturo. Great times ahead! :-)

Russ Allbery: Review: Algorithms to Live By

Review: Algorithms to Live By, by Brian Christian & Tom Griffiths
Publisher: Henry Holt and Company
Copyright: April 2016
ISBN: 1-62779-037-3
Format: Kindle
Pages: 255
Another read for the work book club. This was my favorite to date, apart from the books I recommended myself. One of the foundations of computer science as a field of study is research into algorithms: how do we solve problems efficiently using computer programs? This is a largely mathematical field, but it's often less about ideal or theoretical solutions and more about making the most efficient use of limited resources and arriving at an adequate, if not perfect, answer. Many of these problems are either day-to-day human problems or are closely related to them; after all, the purpose of computer science is to solve practical problems with computers. The question asked by Algorithms to Live By is "can we reverse this?": can we learn lessons from computer science's approach to problems that would help us make day-to-day decisions? There's a lot of interesting material in the eleven chapters of this book, but there's also an amusing theme: humans are already very good at this. Many chapters start with an examination of algorithms and mathematical analysis of problems, dive into a discussion of how we can use those results to make better decisions, then talk about studies of the decisions humans actually make... and discover that humans are already applying ad hoc versions of the best algorithms we've come up with, given the constraints of typical life situations. It tends to undermine the stated goal of the book. Thankfully, it in no way undermines interesting discussion of general classes of problems, how computer science has tackled them, and what we've learned about the mathematical and technical shapes of those problems. There's a bit less self-help utility here than I think the authors had intended, but lots of food for thought. (That said, it's worth considering whether this congruence is less because humans are already good at this and more because our algorithms are designed from human intuition. Maybe our best algorithms just reflect human thinking. In some cases we've checked our solutions against mathematical ideals, but in other cases they're still just our best guesses to date.) This is the sort of a book where a chapter listing is an important part of the review. The areas of algorithms discussed here are optimal stopping, explore/exploit decisions (when to go with the best thing you've found and when to look for something better), sorting, caching, scheduling, Bayes's rule (and prediction in general), overfitting when building models, relaxation (solving an easier problem than your actual problem), randomized algorithms, a collection of networking algorithms, and finally game theory. Each of these has useful insights and thought-provoking discussion of how these sometimes-theoretical concepts map surprisingly well onto daily problems. The book concludes with a discussion of "computational kindness": an encouragement to reduce the required computation and complexity penalty for both yourself and the people you interact with. If you have a computer science background (as I do), many of these will be familiar concepts, and you might be dubious that a popularization would tell you much that's new. Give this book a shot, though; the analogies are less stretched than you might fear, and the authors are both careful and smart about how they apply these principles. This book passes with flying colors a key sanity check: the chapters on topics that I know well or have thought about a lot make few or no obvious errors and say useful and important things. For example, the scheduling chapter, which unsurprisingly is about time management, surpasses more than half of the time management literature by jumping straight to the heart of most time management problems: if you're going to do everything on a list, it rarely matters the order in which you do it, so the hardest scheduling problems are about deciding what not to do rather than deciding order. The point in the book where the authors won my heart completely was in the chapter on Bayes's rule. Much of the chapter is about Bayesian priors, and how one's knowledge of past events is a vital part of analysis of future probabilities. The authors then discuss the (in)famous marshmallow experiment, in which children are given one marshmallow and told that if they refrain from eating it until the researcher returns, they'll get two marshmallows. Refraining from eating the marshmallow (delayed gratification, in the psychological literature) was found to be associated with better life outcomes years down the road. This experiment has been used and abused for years for all sorts of propaganda about how trading immediate pleasure for future gains leads to a successful life, and how failure in life is because of inability to delay gratification. More evil analyses have (of course) tied that capability to ethnicity, with predictably racist results. I have kind of a thing about the marshmallow experiment. It's a topic that reliably sends me off into angry rants. Algorithms to Live By is the only book I have ever read to mention the marshmallow experiment and then apply the analysis that I find far more convincing. This is not a test of innate capability in the children; it's a test of their Bayesian priors. When does it make perfect sense to eat the marshmallow immediately instead of waiting for a reward? When their past experience tells them that adults are unreliable, can't be trusted, disappear for unpredictable lengths of time, and lie. And, even better, the authors supported this analysis with both a follow-up study I hadn't heard of before and with the observation that some children would wait for some time and then "give in." This makes perfect sense if they were subconsciously using a Bayesian model with poor priors. This is a great book. It may try a bit too hard in places (applicability of the math of optimal stopping to everyday life is more contingent and strained than I think the authors want to admit), and some of this will be familiar if you've studied algorithms. But the writing is clear, succinct, and very well-edited. No part of the book outlives its welcome; the discussion moves right along. If you find yourself going "I know all this already," you'll still probably encounter a new concept or neat explanation in a few more pages. And sometimes the authors make connections that never would have occurred to me but feel right in retrospect, such as relating exponential backoff in networking protocols to choosing punishments in the criminal justice system. Or the realization that our modern communication world is not constantly connected, it's constantly buffered, and many of us are suffering from the characteristic signs of buffer bloat. I don't think you have to be a CS major, or know much about math, to read this book. There is a lot of mathematical details in the end notes if you want to dive in, but the main text is almost always readable and clear, at least so far as I could tell (as someone who was a CS major and has taken a lot of math, so a grain of salt may be indicated). And it still has a lot to offer even if you've studied algorithms for years. The more I read of this book, the more I liked it. Definitely recommended if you like reading this sort of analysis of life. Rating: 9 out of 10

Julian Andres Klode: APT 1.6 alpha 1 seccomp and more

I just uploaded APT 1.6 alpha 1, introducing a very scary thing: Seccomp sandboxing for methods, the programs downloading files from the internet and decompressing or compressing stuff. With seccomp I reduced the number of system calls these methods can use to 149 from 430. Specifically we excluded most ways of IPC, xattrs, and most importantly, the ability for methods to clone(2), fork(2), or execve(2) (or execveat(2)). Yes, that s right methods can no longer execute programs. This was a real problem, because the http method did in fact execute programs there is this small option called ProxyAutoDetect or Proxy-Auto-Detect where you can specify a script to run for an URL and the script outputs a (list of) proxies. In order to be able to seccomp the http method, I moved the invocation of the script to the parent process. The parent process now executes the script within the sandbox user, but without seccomp (obviously). I tested the code on amd64, ppc64el, s390x, arm64, mipsel, i386, and armhf. I hope it works on all other architectures libseccomp is currently built for in Debian, but I did not check that, so your apt might be broken now if you use powerpc, powerpcspe, armel, mips, mips64el, hhpa, or x32 (I don t think you can even really use x32). Also, apt-transport-https is gone for good now. When installing the new apt release, any installed apt-transport-https package is removed (apt breaks apt-transport-https now, but it also provides it versioned, so any dependencies should still be satisfiable). David also did a few cool bug fixes again, finally teaching apt-key to ignore unsupported GPG key files instead of causing weird errors
Filed under: Uncategorized

22 October 2017

Iain R. Learmonth: Free Software Efforts (2017W42)

Here s my weekly report for week 42 of 2017. In this week I have replaced my spacebar, failed to replace a HDD and begun the process to replace my YubiKey.

Debian Eariler in the week I blogged about powerline-taskwarrior . There is a new upstream version available that includes the patches I had produced for Python 2 support and I have filed #879225 to remind me to package this. The state of emscripten is still not great, and as I don t have the time to chase this up and I certainly don t have the time to fix it myself, I ve converted the ITP for csdr to an RFP. As I no longer have the time to maintain map.debian.net, I have released this domain name and published the sources behind the service.

Tor Project There was a request to remove the $ from family fingerprint on Atlas. These actually come from Onionoo and we have decided to fix this in Onionoo, but I did push a small fix for Atlas this week that makes sure that Atlas doesn t care if there are $ prefixes or not. I requested that a Trac component be created for metrics-bot. I wrote a seperate post about metrics-bot. I also attended the weekly metrics team meeting.

Sustainability I believe it is important to be clear not only about the work I have already completed but also about the sustainability of this work into the future. I plan to include a short report on the current sustainability of my work in each weekly report. I have not had any free software related expenses this week. The current funds I have available for equipment, travel and other free software expenses remains 60.52. I do not believe that any hardware I rely on is looking at imminent failure. I do not find it likely that I ll be travelling to Cambridge for the miniDebConf as the train alone would be around 350 and hotel accomodation a further 600 (to include both me and Ana).

Dirk Eddelbuettel: linl 0.0.1: linl is not Letter

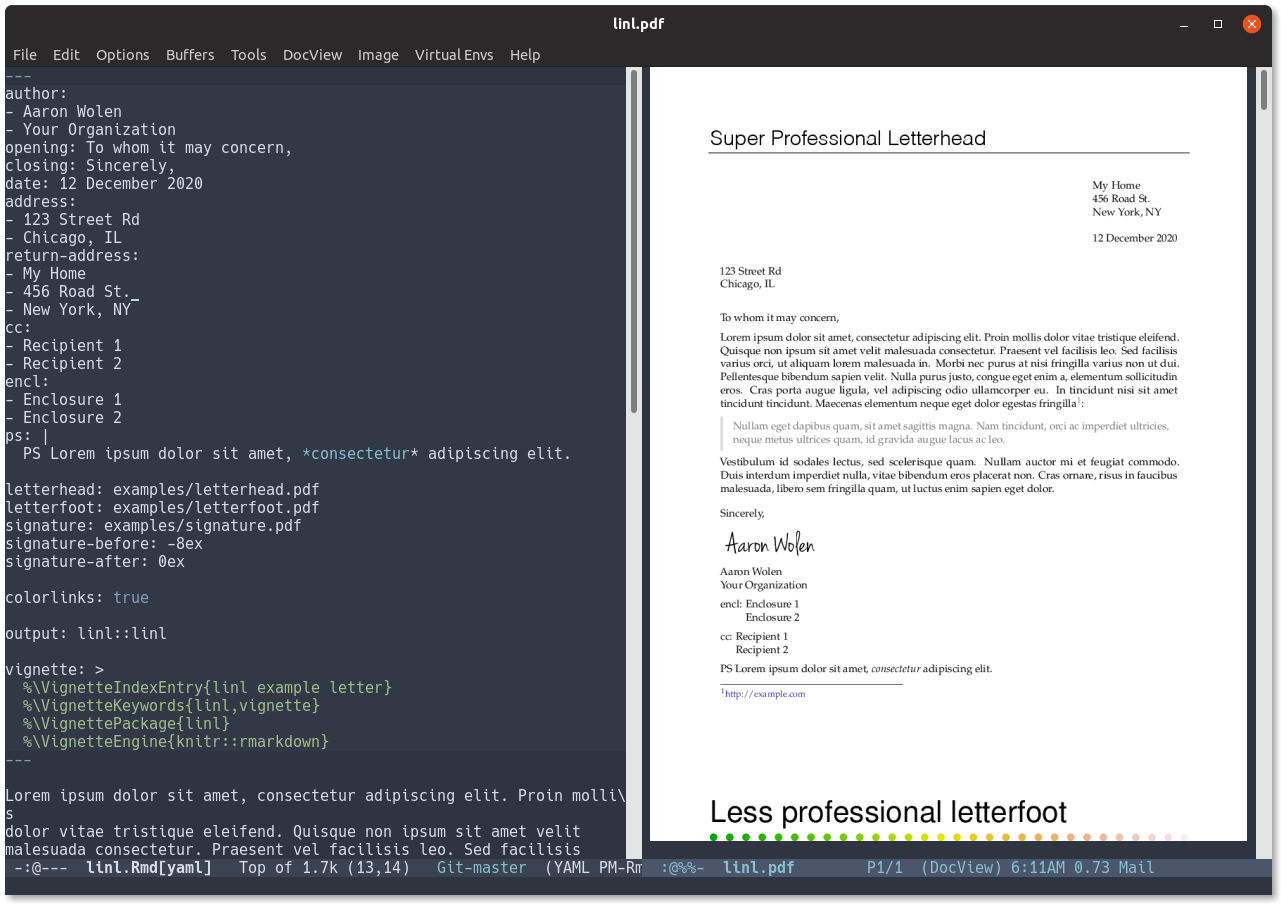
Aaron Wolen and I are pleased to announce the availability of the initial 0.0.1 release of our new linl package on the CRAN network. It provides a simple-yet-powerful Markdown---and RMarkdown---wrapper the venerable LaTeX letter class. Aaron had done the legwork in the underlying pandoc-letter repository upon which we build via proper rmarkdown integration. The package also includes a LaTeX trick or two: optional header and signature files, nicer font, better size, saner default geometry and more. See the following screenshot which shows the package vignette---itself a simple letter---along with (most of) its source:
The initial (short) NEWS entry follows:

Changes in tint version 0.0.1 (2017-10-17)
  • Initial CRAN release

The date is a little off; it took a little longer than usual for the good folks at CRAN to process the initial submission. We expect future releases to be more timely. For questions or comments use the issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Steinar H. Gunderson: Introducing Narabu, part 3: Parallel structure

Narabu is a new intraframe video codec. You probably want to read part 1 and part 2 first. Now having a rough idea of how the GPU works, it's obvious that we need our codec to split the image into a lot of independent chunks to be parallel; we're aiming for about a thousand chunks. We'll also aim for a format that's as simple as possible; other people can try to push the frontiers on research, I just want something that's fast, reasonably good, and not too hard to implement. First of all, let's look at JPEG. It works by converting the image to Y'CbCr (usually with subsampled chroma), split each channel into 8x8 blocks, DCT them, quantize and then use Huffman coding to encode those coefficients. This is a very standard structure, and JPEG, despite being really old by now, is actually hard to beat, so let's use that as a template. But we probably can't use JPEG wholesale. Why? The answer is that the Huffman coding is just too serial. It's all just one stream, and without knowing where the previous symbol ends, we don't know where to start decoding the next. You can partially solve this by having frequent restart markers, but these reduce coding efficiency, and there's no index of them; you'd have to make a parallel scan for them, which is annoying. So we'll need to at least do something about the entropy coding. Do we need to change anything else to reach our ~1000 parallel target? 720p is the standard video target these days; the ~1M raw pixels would be great if we could do all of them independently, but we obviously can't, since DCT is not independent per pixel (that would sort of defeat the purpose). However, there are 14,400 DCT blocks (8x8), so we can certainly do all the DCTs in parallel. Quantization after that is trivially parallelizable, at least as long as we don't aim for trellis or the likes. So indeed, it's only entropy coding that we need to worry about. Since we're changing entropy coding anyway, I picked rANS, which is confusing but has a number of neat properties; it's roughly as expensive as Huffman coding, but has an efficiency closer to that of arithmetic encoding, and you can switch distributions for each symbol. It requires a bit more calculation, but GPUs have plenty of ALUs (a typical recommendation is 10:1 calculation to memory access), so that should be fine. I picked a pretty common variation with 32-bit state and 8-bit I/O, since 64-bit arithmetic is not universally available on GPUs (I checked a variation with 64-bit state and 32-bit I/O, but it didn't really matter much for speed). Fabian Giesen has described how you can actually do rANS encoding and decoding in parallel over a warp, but I've treated it as a purely serial operation. I don't do anything like adaptation, though; each coefficient is assigned to one out of four rANS static distributions that are signaled at the start of each stream. (Four is a nice tradeoff between coding efficiency, L1 cache use and the cost of transmitting the distributions themselves. I originally used eight, but a bit of clustering showed it was possible to get it down to four at basically no extra cost. JPEG does a similar thing, with separate Huffman codes for AC and DC coefficients. And I've got separate distributions for luma and chroma, which also makes a lot of sense.) The restart cost of rANS is basically writing the state to disk; some of that we would need to write even without a restart, and there are ways to combine many such end states for less waste (I'm not using them), but let's be conservative and assume we waste all of it for each restart. At 150 Mbit/second for 720p60, the luma plane of one frame is about 150 kB. 10% (15 kB) sounds reasonable to sacrifice to restarts, which means we can have about 3750 of them, or one for each 250th pixel or so. (3750 restarts also means 3750 independent entropy coding streams, so we're still well above our 1000 target.) So the structure is more or less clear; we'll DCT the blocks in parallel (since an 8x8 block can be expressed as 8 vertical DCTs and then 8 horizontal DCTs, we can even get 8-way parallelism there), and then encode at least 250 coefficients into an rANS stream. I've chosen to let a stream encompass a single coefficient from each of 320 DCT blocks instead of all coefficients from 5 DCT blocks; it's sort of arbitrary and might be a bit unintuitive, but it feels more natural, especially since you don't need to switch rANS distributions for each coefficient. So that's a lot of rambling for a sort-of abstract format. Next time we'll go into how decoding works. Or encoding. I haven't really made up my mind yet.

Michael Stapelberg: Which VCS do Debian s Go package upstreams use?

In the pkg-go team, we are currently discussing which workflows we should standardize on. One of the considerations is what goes into the upstream Git branch of our repositories: should it track the upstream Git repository, or should it contain orig tarball imports? Now, tracking the upstream Git repository only works if upstream actually uses Git. The go tool, which is widely used within the Go community for managing Go packages, supports Git, Mercurial, Bazaar and Subversion. But which of these are actually used in practice? Let s find out! Option 1: If you have the sources lists of all suites locally anyway
/usr/lib/apt/apt-helper cat-file \
  $(apt-get indextargets --format '$(FILENAME)' 'ShortDesc: Sources' 'Origin: Debian') \
    sed -n 's,Go-Import-Path: ,,gp' \
    sort -u
Option 2: If you prefer to use a relational database over textfiles This is the harder option, but also the more complete one. First, we ll need the Go package import paths of all Go packages which are in Debian. We can get them from the ProjectB database, Debian s main PostgreSQL database containing all of the state about the Debian archive. Unfortunately, only Debian Developers have SSH access to a mirror of ProjectB at the moment. I contacted DSA to ask about providing public ProjectB access.
  ssh mirror.ftp-master.debian.org "echo \"SELECT value FROM source_metadata \
  LEFT JOIN metadata_keys ON (source_metadata.key_id = metadata_keys.key_id) \
  WHERE metadata_keys.key = 'Go-Import-Path' GROUP BY value\"   \
    psql -A -t service=projectb" > go_import_path.txt
I uploaded a copy of resulting go_import_path.txt, if you re curious. Now, let s come up with a little bit of Go to print the VCS responsible for each specified Go import path:
go get -u golang.org/x/tools/go/vcs
cat >vcs4.go <<'EOT'
package main
import (
	"fmt"
	"log"
	"os"
	"sync"
	"golang.org/x/tools/go/vcs"
)
func main()  
	var wg sync.WaitGroup
	for _, arg := range os.Args[1:]  
		wg.Add(1)
		go func(arg string)  
			defer wg.Done()
			rr, err := vcs.RepoRootForImportPath(arg, false)
			if err != nil  
				log.Println(err)
				return
			 
			fmt.Println(rr.VCS.Name)
		 (arg)
	 
	wg.Wait()
 
EOT
Lastly, run it in combination with uniq(1) to discover
go run vcs4.go $(tr '\n' ' ' < go_import_path.txt)   sort   uniq -c
    760 Git
      1 Mercurial

Sean Whitton: Debian Policy call for participation -- October 2017

Here s are some of the bugs against the Debian Policy Manual. In particular, there really are quite a few patches needing seconds from DDs. Consensus has been reached and help is needed to write a patch: #759316 Document the use of /etc/default for cron jobs #761219 document versioned Provides #767839 Linking documentation of arch:any package to arch:all #770440 policy should mention systemd timers #773557 Avoid unsafe RPATH/RUNPATH #780725 PATH used for building is not specified #793499 The Installed-Size algorithm is out-of-date #810381 Update wording of 5.6.26 VCS-* fields to recommend encryption #823256 Update maintscript arguments with dpkg >= 1.18.5 #833401 virtual packages: dbus-session-bus, dbus-default-session-bus #835451 Building as root should be discouraged #838777 Policy 11.8.4 for x-window-manager needs update for freedesktop menus #845715 Please document that packages are not allowed to write outside thei #853779 Clarify requirements about update-rc.d and invoke-rc.d usage in mai #874019 Note that the -e argument to x-terminal-emulator works like #874206 allow a trailing comma in package relationship fields Wording proposed, awaiting review from anyone and/or seconds by DDs: #688251 Built-Using description too aggressive #737796 copyright-format: support Files: paragraph with both abbreviated na #756835 Extension of the syntax of the Packages-List field. #786470 [copyright-format] Add an optional License-Grant field #810381 Update wording of 5.6.26 VCS-* fields to recommend encryption #835451 Building as root should be discouraged #845255 Include best practices for packaging database applications #846970 Proposal for a Build-Indep-Architecture: control file field #850729 Documenting special version number suffixes #864615 please update version of posix standard for scripts (section 10.4) #874090 Clarify wording of some passages #874095 copyright-format: Use the synopsis term established in the de Merged for the next release: #683495 perl scripts: #!/usr/bin/perl MUST or SHOULD? #877674 [debian-policy] update links to the pdf and other formats of the do #878523 [PATCH] Spelling fixes

21 October 2017

Michael Stapelberg: pk4: a new tool to avail the Debian source package producing the specified package

UNIX distributions used to come with the system source code in /usr/src. This is a concept which fascinates me: if you want to change something in any part of your system, just make your change in the corresponding directory, recomile, reinstall, and you can immediately see your changes in action. So, I decided I wanted to build a tool which can give you the impression of that, without the downsides of additional disk space usage and slower update times because of /usr/src maintenance. The result of this effort is a tool called pk4 (mnemonic: get me the package for ) which I just uploaded to Debian. What distinguishes this tool from an apt source call is the combination of a number of features: If you don t want to wait for the package to clear the NEW queue, you can get it from here in the meantime:
wget https://people.debian.org/~stapelberg/pk4/pk4_1_amd64.deb
sudo apt install ./pk4_1_amd64.deb
You can find the sources and issue tracker at https://github.com/Debian/pk4. Here is a terminal screencast of the tool in action, availing the sources of i3, applying a patch, rebuilding the package and replacing the installed binary packages:

Jaldhar Vyas: Sal Mubarak 2074

Wishing all Debian people a prosperous and auspicious Gujarati new year (V.S. 2074 called Saumya.) This year fireworks became legal for the first time in New Jersey. Not that it ever stopped us before but it is nice to see the government stop meddling for no reason. (Eff you, Indian Supreme Court.) Sparklers on Diwali. Although you can only see sparklers in the picture above, we got enough armament to make ISIS jealous. There were also lots of diabetes-inducing sweets and (inexpensive, practical) presents for young and old. That's what I call a proper Diwali and new year.

20 October 2017

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, September 2017

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In August, about 170 work hours have been dispatched among 13 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours is the same as last month. But we have a new sponsor in the pipe. The security tracker currently lists 52 packages with a known CVE and the dla-needed.txt file 49. The number of packages with open issues decreased slightly compared to last month but we re not yet back to the usual situation. Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

19 October 2017

Clint Adams: Scuttlebutt at the precinct

So who s getting patchwork into Debian?
Posted on 2017-10-19
Tags: bamamba

Lior Kaplan: Hacktoberfest 2017 @ Tel Aviv

I gave my Midburn creating an open source community talk in Hacktoberfest 2017 @ Tel Aviv. This is the local version of an initiative by DigitalOcean and GitHub. I was surprised about the vibe both the location and the organizers gave the event, and the fact they could easily arrange t-shirts, pizzas and beer. Looking at the github search, it seem the worldwide event brings many new contributions. I think we have something to learn how to do a mass concept like that. Especially when it crosses both project limits and country limits. (e.g. not a local bug squashing party).
Filed under: Open source businesses

Steinar H. Gunderson: Introducing Narabu, part 2: Meet the GPU

Narabu is a new intraframe video codec. You may or may not want to read part 1 first. The GPU, despite being extremely more flexible than it was fifteen years ago, is still a very different beast from your CPU, and not all problems map well to it performance-wise. Thus, before designing a codec, it's useful to know what our platform looks like. A GPU has lots of special functionality for graphics (well, duh), but we'll be concentrating on the compute shader subset in this context, ie., we won't be drawing any polygons. Roughly, a GPU (as I understand it!) is built up about as follows: A GPU contains 1 20 cores; NVIDIA calls them SMs (shader multiprocessors), Intel calls them subslices. (Trivia: A typical mid-range Intel GPU contains two cores, and thus is designated GT2.) One such core usually runs the same program, although on different data; there are exceptions, but typically, if your program can't fill an entire core with parallelism, you're wasting energy. Each core, in addition to tons (thousands!) of registers, also has some shared memory (also called local memory sometimes, although that term is overloaded), typically 32 64 kB, which you can think of in two ways: Either as a sort-of explicit L1 cache, or as a way to communicate internally on a core. Shared memory is a limited, precious resource in many algorithms. Each core/SM/subslice contains about 8 execution units (Intel calls them EUs, NVIDIA/AMD calls them something else) and some memory access logic. These multiplex a bunch of threads (say, 32) and run in a round-robin-ish fashion. This means that a GPU can handle memory stalls much better than a typical CPU, since it has so many streams to pick from; even though each thread runs in-order, it can just kick off an operation and then go to the next thread while the previous one is working. Each execution unit has a bunch of ALUs (typically 16) and executes code in a SIMD fashion. NVIDIA calls these ALUs CUDA cores , AMD calls them stream processors . Unlike on CPU, this SIMD has full scatter/gather support (although sequential access, especially in certain patterns, is much more efficient than random access), lane enable/disable so it can work with conditional code, etc.. The typically fastest operation is a 32-bit float muladd; usually that's single-cycle. GPUs love 32-bit FP code. (In fact, in some GPU languages, you won't even have 8-, 16-bit or 64-bit types. This is annoying, but not the end of the world.) The vectorization is not exposed to the user in typical code (GLSL has some vector types, but they're usually just broken up into scalars, so that's a red herring), although in some programming languages you can get to swizzle the SIMD stuff internally to gain advantage of that (there's also schemes for broadcasting bits by voting etc.). However, it is crucially important to performance; if you have divergence within a warp, this means the GPU needs to execute both sides of the if. So less divergent code is good. Such a SIMD group is called a warp by NVIDIA (I don't know if the others have names for it). NVIDIA has SIMD/warp width always 32; AMD used to be 64 but is now 16. Intel supports 4 32 (the compiler will autoselect based on a bunch of factors), although 16 is the most common. The upshot of all of this is that you need massive amounts of parallelism to be able to get useful performance out of a CPU. A rule of thumb is that if you could have launched about a thousand threads for your problem on CPU, it's a good fit for a GPU, although this is of course just a guideline. There's a ton of APIs available to write compute shaders. There's CUDA (NVIDIA-only, but the dominant player), D3D compute (Windows-only, but multi-vendor), OpenCL (multi-vendor, but highly variable implementation quality), OpenGL compute shaders (all platforms except macOS, which has too old drivers), Metal (Apple-only) and probably some that I forgot. I've chosen to go for OpenGL compute shaders since I already use OpenGL shaders a lot, and this saves on interop issues. CUDA probably is more mature, but my laptop is Intel. :-) No matter which one you choose, the programming model looks very roughly like this pseudocode:
for (size_t workgroup_idx = 0; workgroup_idx < NUM_WORKGROUPS; ++workgroup_idx)     // in parallel over cores
        char shared_mem[REQUESTED_SHARED_MEM];  // private for each workgroup
        for (size_t local_idx = 0; local_idx < WORKGROUP_SIZE; ++local_idx)    // in parallel on each core
                main(workgroup_idx, local_idx, shared_mem);
         
 
except in reality, the indices will be split in x/y/z for your convenience (you control all six dimensions, of course), and if you haven't asked for too much shared memory, the driver can silently make larger workgroups if it helps increase parallelity (this is totally transparent to you). main() doesn't return anything, but you can do reads and writes as you wish; GPUs have large amounts of memory these days, and staggering amounts of memory bandwidth. Now for the bad part: Generally, you will have no debuggers, no way of logging and no real profilers (if you're lucky, you can get to know how long each compute shader invocation takes, but not what takes time within the shader itself). Especially the latter is maddening; the only real recourse you have is some timers, and then placing timer probes or trying to comment out sections of your code to see if something goes faster. If you don't get the answers you're looking for, forget printf you need to set up a separate buffer, write some numbers into it and pull that buffer down to the GPU. Profilers are an essential part of optimization, and I had really hoped the world would be more mature here by now. Even CUDA doesn't give you all that much insight sometimes I wonder if all of this is because GPU drivers and architectures are meant to be shrouded in mystery for competitiveness reasons, but I'm honestly not sure. So that's it for a crash course in GPU architecture. Next time, we'll start looking at the Narabu codec itself.

Next.

Previous.