Search Results: "cas"

3 December 2010

Raphaël Hertzog: Librement: a new way to help people who want to contribute to free software

Find your way in the free software worldI have this project in my head, I want to work on it but I always lack the time. In order to go forward, I thought I could write about it, at least it would let me clarify my ideas and the core goals. So here I am, I will present you Librement (I have registered the alioth project but it s empty). The core goal is to make it easy for every user to contribute to free software in some way. I will now present the main features that I envision. Defining skills and interests In order to propose tasks that the user can do, we must have an idea of his skills. So on the first run (and later through a preferences menu) the user will be invited to define his skills: Maybe we can also ask which skills he would like to learn. Because contributing to free software is a nice opportunity to learn new skills! We should also find out what the user is interested in. What are his favorite free software projects? What kind of contributions would he like to do (documentation, translation, coding, bug fixing, bug triaging, creating artwork, donations, etc.)? Choose activities and pick concrete tasks Based on the user s skills and his interests, the software shows a list of possible activities. The user can then sort that list, from the most interesting one to those that he doesn t want to do. Each activity can generate concrete tasks. For example, the activity Do translation for Debian could generate a task Translate strings in debconf/fr.po or Review translations in partman/fr.po . Work on tasks When the user decides to work on a task, a step-by-step assistant helps him/her. It can automate some steps and provide explanations for the remaining ones, for example in the case of a translation for Debian: If the tasks is not completed in one go, the user can resume it the next time. Each free software project must provide some meta-information describing the various workflows involved for contributing to the different parts of the project. If necessary the project can also provide new plugins to support new operations that are not available in the default library. Setting goals In order to keep the user motivated, the software could track how much time he spent contributing to free software and it could verify if the user reached the goals he picked up for himself. Maybe it can also hook into the OMG Trophy Awarding System. The sky is the limit I hope that you now have a clearer idea of what this desktop application is supposed to be. There are literally hundreds of ways to contribute to free software and I like the idea that we can streamline the process for most users. All the plugins implementing activities can use local information (list of packages installed with their versions, configuration settings, etc.) to propose tasks targetted to the user and highly beneficial for the corresponding free software projects. For example, a bug tagged unreproducible might benefit from a few more users trying to reproduce it. The software could direct the user to this bug report if it detects that he/she runs the same version on the same architecture and that this software is regularly run on the system. Many projects have created operations or events to encourage people to contribute, they could all be implemented as dedicated activities in Librement. I m thinking of stuff like Gnome Love, Ubuntu s 5-a-day, Ubuntu s 100 papercuts, etc. Even for people who have no time to contribute, the application can still be useful by referencing the various ways to donate money (or material) to projects that they are using. Feedback welcome I m excited by the potential of such an application, but it s normal since it s my idea. Do you believe it can be useful and popular? Do you have ideas of exciting activities that such a framework can offer? PS: If you wonder how I came up with the name Librement , here s the explanation. It s a French word which means freely . And users who want to give back are trying to live up to the principles of free software, which I sum up by they are trying to live freely .
Follow me on Identi.ca, Twitter and Facebook. Or subscribe to this blog by RSS or by email.

11 comments Liked this article? Click here. My blog is Flattr-enabled.

2 December 2010

Sandro Tosi: bts-link has a new home!

Since (already) several weeks, bts-link has a new home: busoni.debian.org! That's one of the machines where BTS is running, and it helps to let bts-link complete its job in about 30 mins each time. Thanks goes to Don Armstrong and Peter Palfrader for their support in the migration (from merkel).

Once again, let me encourage you to contact the bts-link developers mailing-list to request your project to be added to the tool in case it's not (we usually do some checks and adds from time to time, but if you notify us, you'll get it faster :) ).

1 December 2010

Gintautas Miliauskas: Windows (II): User Interface

(This is a part of a series of posts on my recent experience with Windows. See Windows (I) for the first post.)

The Windows user interface is definitely acceptable. The charge that it is too colorful or toy-like is completely unfounded. Rather, perhaps geeks should spend less time looking at their gray Motif boxy controls. In terms of speed, the UI is generally more responsive than on Linux, though maybe less so than previous versions of Windows (that could be because my Intel video IGP is a slouch).

An interesting observation is that apps are almost as heterogeneous in terms of interface as in GNU/Linux, even though the standard controls are ubiquitous. Even apps by Microsoft can be separated into different "generations" of UI (e.g., folder windows, Control Panel, Microsoft Office). Also it is clear that generally more attention is paid to UI and usability by app developers, although perhaps not as much as in Apple products.

The greatest asset and the worst offender at the same time, by far, is the overall GUI orientation of the system. Needless to say, it aids discoverability, but reduces scripting capabilities. Problem is, even if you do not need to write scripts per se, command-line actions are useful because they can be repeated and chained very easily, using shell history. In Windows, I occasionally find myself doing much repetitive clicking that would likely be an "Alt-Tab Up Enter" (or sometimes just one key) sequence in Linux. Moreover, the lack of good standartized scripting is a huge pain during app deployments which tend be repetetive. I did not like Windows on servers before, and I do not like it now.

To be fair, my complaints about scripting capabilities may be partly moot because I have only used vanilla Windows batch files, and have not looked at all into Windows PowerShell, which is a new-generation scripting tool. The examples are fairly impressive. The language has a nice look and is clearly powerful, but also looks somewhat complicated which keeps me away until I find a good reason to learn it.

Initially I missed workspaces. The one app I found that was supposed to emulate workspaces would take several seconds to switch the workspace, so it was completely unusable. I learned to do without them rather quickly though. Actually I'm starting to think that using many workspaces is a sign that you are doing too many things at once and also they are an invitation to distraction (how many of you have a "blog reader" workspace right aside your "work" workspace, ready at your fingertips at a moment's notice?). Workspaces do have one killer feature: you can jump directly to a given workspace instead of cycling through windows. This is very useful when working with more than two apps, in which case without workspaces you are forced to think about the morphing Alt-Tab queue when switching windows.

Speaking about UI generations, I much prefer the ribbon toolbars of the new Office. The still-prevalent toolbars with zillions of old-style 32x32 (or 16x16) toolbar icons are really ugly. Typically only a few of the toolbar buttons are actually useful, and they make the user interface unnecessarily cramped and busy. The move to fewer and larger toolbar buttons is definitely on the right track.

The explorer context menus also tend to grow crazy long. Every app wants to get in there, and in the end you have a context menu that takes up half a screen vertically. Needless to say, most of those items are not used much. Sure, you can opt out during app installation, but at that time it is difficult to say how useful the context menu item will be, and there's no easy way (i.e. easier than just ignoring the cruft) to remove the entries afterwards.

In my coming posts I will cover package management and application development on Windows.

Gunnar Wolf: Back to... Normality?

For the past month, I got disconnected from basically all of my usual activities. Not only from Debian work (well, yes, I followed up on a couple of important bugs and releases, but I was in a very low power consumption mode of sorts), DebConf organization/following (some people have contacted me regarding the DebConf 12 venue decision, for which we should start working and have a presentation soon) Even the always-so-important Real Life got pushed aside. I barely participated in this year's EDUSOL (On-line Encounter of Education and Free Software). Even work suffered I asked my boss to hold any incoming requests for me (save, of course, for urgent stuff). I am now shyly coming up from the hole I dug myself in for this time. Why did I do such a thing? I do not have a formal education beyond high school. Due to several personal issues, I was accepted to the best university in my country, and to the first generation of the study program I would definitively love to have followed, but didn't attend. Of course, I had a fair bit of computing background, enough to be competitive and start working. After amazingly few years, I didn't only get a decent job, but I got a job precisely at the very university I wanted to study at (and where my father has worked for the past 40 years). And, even with some changes along the years, here I am with 10 years of laboral history in this university, with an academic position (although the smallest academic position, but still). It is one of my life's achievements, one of the things that makes me proudest of. Still, I don't want to stay at this level for the rest of my life. And an institution such as this one has rules Yes, flexible enough to allow me in, but rules whose importance I cannot deny. I aspire to become a professor/researcher at some point, and that is just not possible without filling in the prerequisites. Besides, I want to try my hand at teaching at a universitary level. So, what choices did I have besides devoting at least four years to full-time study? Well, there is a government entity that evaluates and regulates formal education given by smaller universities CENEVAL. For probably around ten years now, they have offered the ACREL (Acuerdo 286 Licenciatura) program to validate professional knowledge acquired through work experience And I'm writing this detail as several people have asked me for details on it. So, once you are accepted in the program (basic requisites: Having a high school certificate, over 30 year old, and with over 10 years of provable work experience), they can grant a Licenciatura degree (i.e. the equivalent to a four-year study program). So, in order to get it granted, I have to: Anyway... Enough of a blog posting. I hope this is useful for somebody. And I hope it explains why I have disappeared so much lately. If everything goes as planned, I expect to be receiving my "licenciatura" title around March, and afterwards... Well, we shall see! Now... Back to work. And back to life. And back to my huge backlog of other pending things :)

Josselin Mouette: Getting user switching to not suck

We ve come a long way since the times when you needed to configure 2 X servers in XDM just to be able to use 2 X sessions at once. However there was still some way to go until recently. A number of bugs that could be wrongly attributed to bugs in the X server or in the desktop environment were actually caused by the display manager doing crap. GDM up to 2.20 Since the introduction of the flexible X servers feature, GDM hadn t evolved much on the matter of user switching. What it used to do was pretty straightforward: It is interesting to note that VT (console) switching is purely handled by the X server. When starting, the new server switches the current VT to where it is. When exiting, it automatically switches back to the VT from which it was launched. While very simple, this idea fails to work correctly every time you try to do something more complicated than starting a temporary session for a guest and exiting it. For example, if you start two of them, there is a chance that, when the X server switches back to the console it was run from, there is nothing left running in this console, leaving you with the funny Control-Alt-Fn shortcuts to find your way back to a X server. You will also meet interesting race conditions when trying to switch back to an existing session from the login window. GDM 2.28 and above In the process of rewriting the code entirely, the GDM developers tried to address a number of those shortcomings, making use of D-Bus and ConsoleKit. The new design is slightly more complicated, however. Not killing the X server in some cases partly addresses the problems caused by letting it switch back to the original VT when exiting. However in several ways the cure is worse than the disease. Getting it to work The modular architecture of GDM makes it possible to improve the situation. (Possible but not easy because of the millefeuille of classes.) However, it is merely a band-aid unless you fix the root issue: the X server knowing better than you which VT it should switch to when exiting. Fortunately Xorg now features an option to avoid that behavior: -novtswitch. So the first step is to enable it, and let the GDM daemon (or slave) handle VT switching through ConsoleKit. With that, the following changes are possible. The result With all these changes the behavior of the display manager is finally completely consistent. Interestingly enough, this is very similar to what user switching looks like on Vista or MacOS X. So what now? These changes are stabilized for Debian squeeze, but of course it has been long overdue to get them accepted upstream, along with the very large number of Debian-specific changes that still lie in our packages.

30 November 2010

Joey Hess: debugging musings

Debugging a computer program is such an interesting activity because it's not really a matter of fixing a program. It's a matter of fixing your own understanding to the point that the cause of the bug becomes obvious. So debugging means constantly challenging your assumptions, constantly looking for the overlooked insignificant thing that turns out to be crucial. I mostly debug by print statements. I don't like it much, but it works. I add some print statements around the problem area and see if what's going on matches what the model in my head thinks should be going on. If it doesn't, I try to fix the model, and if it does, I focus the print statements in tighter and tighter, deeper and deeper, until I finally reach the bug. It's nasty and ah-hoc, but it works really well, mostly. And I know I'm in good company doing it. But that method can fail; I myself can end up caught in a loop. Like today, tracking down an obscure bug in Branchable's auditing subsystem, when I found myself at what was apparantly the point of a bug: Function A was supposed to call function B, but B never seemed to be called. So surely A was buggy, and I instrumented it to bits with print statements and stuff, and started wondering if the libraries it relied on were somehow breaking it in non-obvious ways before it could call B, or maybe there was a bug in the runtime language that was breaking the call to B. Going deeper and deeper didn't help, because the thing I was overlooking was up at the top level -- one of the first print statements I inserted showed that all this code was running twice. Why? Didn't seem relevant to the bug so I ignored it. Of course what I was ignoring was a symptom of the real problem: The first run was by another subsystem, that happened to redefine function B temporarily.. Actually, one of the nice things about Haskell is that print statements are not very helpful in debugging pure code. Pure code tends to get loaded up in ghci and tested interactively, and the bug is then clear. Or a quickcheck test case gets written with an invariant that the pure code should satisfy. I spent a whole day a few weeks ago writing an inverse form of a buggy function in git-annex just so I could feed them both into quickcheck and automate debugging. (Most of that time was spent wrestling with unicode decomposition .. ugh.) Being used to getting down in the buggy code with print statements, that at the time felt rather like a waste of time unrelated to getting on with making my program work, but it was very much worth it since I got my program working 100% in even crazy edge cases, and got a test suite for free, too. Most of my debugging of Haskell code so far has not involved bugs in pure code. The most memorable bug was actually a bug in ghc's IO manager, which I'd have never tracked down without Josh's help. The problem with finding bugs in the runtime environment or compiler is that after you've found enough over the years, you're more likely to go down false paths distrusting runtime environments, like I did with the bug today. The beginner's assumption is that the runtime environment just works, but I by now may have over-challenged that assumption. :)

MJ Ray: ECJ on SAS v WPL: A Coming Storm?

While I share Alex s law [is] boring view, this also attracted my attention because it s (slightly) about statistics software. I feel the SAS v WPL case mentioned on his blog deserves a wider airing:
The basic story is that the Judge in this case is deeply unsure of the boundary of copyright. [...] has sent a number of questions to the European Court of Justice (ECJ). The questions are hypothetical, but clearly designed to test the waters and figure out where this line falls.
Now will this re-affirm what I ve always been told, that copyright s border is between ideas and expressions, and copyright only covers expressions? Or will it draw a different boundary? It seems that those most likely to be affected are those who are at the edges of acceptability of licences like LGPL, or trying to provide workalikes of hostile proprietary companies, but please, read it for yourself.

29 November 2010

Theodore Ts'o: Google has a problem retaining great engineers? Bullcrap.

Once again, there s been another story about how Google is having trouble retaining talent. Despite all Eric Schmidt s attempts to tell folks that Google s regretted attrition rate has not changed in seven years, this story just doesn t want to seem to die. (And those stories about Google paying $3.5 million and $7 million to keep an engineer from defecting to Facebook? As far as I know, total bull. I bet it s something made up by some Facebook recruiter who needed to explain how she let a live prospect get away. :-) At least for me, the complete opposite is true. There are very few companies where I can do the work that I want to do, and Google is one of them. A startup is totally the wrong place for me. Why? Because if you talk to any venture capitalist, a startup has one and only one reason to exist: to prove that it has a scalable, viable business model. Take diapers.com for example. As Business Week described, while they were proving that they had a business model that worked, they purchased their diapers at the local BJ s and shipped them via Fedex. Another startup, Chegg, proved its business model by using Amazon.com to drop ship text books to their first customers. (The venture capitalist Mark Maples talked about this in a brilliant talk at the Founders Showcase; the Chegg example starts around 20:50 minutes in, but I d recommend listening to the whole thing, since it s such a great talk.) You don t negotiate volume discounts with textbook publishers, or build huge warehouses to hold all of the diapers that you re going to buy until you prove that you have a business model that works. Similarly, you don t work on great technology at a startup. Startups, by and large, aren t about technology at least, not the Web 2.0 startups like Facebook, Foursquare, Twitter, Groupon, etc. They are about business model discovery. So if you are fundamentally a technologist at heart, whose heart sings when you re making a better file system, or fixing a kernel bug, you re not going to be happy at a startup. At least, not if the startup is run competently. If you have the heart of an entrepreneur, and you are willing to roll the dice (since 9 out of 10 startups go belly up; those are the ones that failed to find a viable business model), then sure, go for a startup. And understand that your job will be to make something that works well at a small scale, quick, dirty, and cheap. If that means using some proprietary software, then that s what you should do. Hopefully you ll get lucky and win the IPO lottery. But if your primary interest is to doing great engineering work, then you want go to company that has a proven business model. Google has enough scale that I can sleep well knowing that improvements I am making to Linux and the ext4 file system are saving enough money for the company that Google is making a profit on me. That is, the value Google is getting out of my work is worth many multiples of my total compensation. And that s a position that every engineer should strive for, since that s how you can be confident that you will remain gainfully employed. The fact that I can do what I love, and go to conferences, and all of my work is open source that s just total icing on the cake. :-) No related posts.

Petter Reinholdtsen: Debian Edu development gathering and General Assembly for FRiSK

On friday, the first Debian Edu / Skolelinux development gathering in a long time take place here in Oslo, Norway. I really look forward to seeing all the good people working on the Squeeze release. The gathering is open for everyone interested in learning more about Debian Edu / Skolelinux. On Saturday, the Norwegian member organization taking care of organizing these development gatherings, Fri Programvare i Skolen, will hold its General Assembly for 2010. Membership is open for all, and currently there are 388 people registered as members. Last year 32 members cast their vote in the memberdb based election system. I hope more people find time to vote this year.

MJ Ray: What Price Networking?

How much would you pay to participate in a social network and what would you expect for that? On the web, I m used to some social networks being available for free. Usefulness and size varies massively, but there s quite a choice of them. There s a price to access them (computer, internet access, time) but once you ve paid that, there are free-to-use networks. Offline, a lot of networking opportunities cost money and not just access costs (travel, time). Especially business networks. OK, there are paid business networks online too, but some of the biggest ones have some long-term free access level, to try to entice people to upgrade. Offline, it seems like the reverse: there are some free networks and some that have short-term free access, but the norm seems to be pay-to-play. Often you get nothing except entry for the basic subscription, but at least our co-op usually prefers networks where we re proper members with some say in how things are run. Not that democracy always works. One networking organisations made a mistake in posting out ballot papers that means we can t vote in its leadership election. This isn t the first administrative problem we ve suffered and their last decent event was at least a year ago, too. At what point should we quit? I think I ll try to address this through the membership democracy first. In this recession, some of our offline networks are reviewing their prices. In one case, a network which was free is going to become one of our more expensive annual subscriptions if we renew. If I look at it as a simple does this bring in enough work to pay for itself? decision then probably it won t. How much value do you attach to being there and to being visible, though?

Raphaël Hertzog: How to find the right Debian packages: high-level search interface

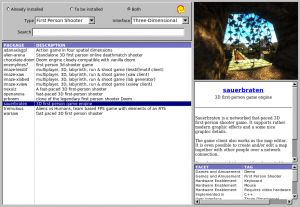
The Debian archive is known to be one of the largest software collections available in the free software world. With more than 16,000 source packages and 30,000 binary packages, users sometimes have trouble finding packages that are relevant to them. Debian developer Enrico Zini has been working on infrastructure to solve this problem. During the recent mini-debconf Paris, Enrico gave a talk presenting what he has been working on in the last few years, which hasn t gotten yet the attention it deserves . Enrico is known in the Debian community for the introduction of debtags, a system used to classify all packages using facets. Each facet describes a specific kind of property: type of user-interface, programming language it s written in, type of document manipulated, purpose of the software, etc. His most recent work builds on that. It is available in Debian and Ubuntu in the apt-xapian-index package. Its purpose is to allow advanced queries over the database of available packages. Users of apt-xapian-index He started by presenting some early users of the infrastructure. The most widely know is Ubuntu s software center. Its search feature provides results almost instantly thanks to apt-xapian-index. But it is a very simple interface that doesn t exploit many of the advanced features provided by the apt-xapian-index. Another early adopter, making use of some more advanced features, is GoPlay!. It s a graphical user interface to find games. It makes use of debtags to classify games so that you can browse, for example, all 3D action/arcade games related to cars. GoPlay has even been extended to be a more generic debtags based package browser and the package now also provides GoLearn!, GoAdmin!, GoNet!, GoOffice!, GoSafe!, and GoWeb!. Fuss-launcher is an application launcher and not a package browser, but by using apt-xapian-index, it s able to reuse information provided at the package level to make it easier to find installed applications. Package descriptions tend to be more verbose than those embedded in .desktop files. Enrico also showed another nice feature to the audience: if you drag a document onto its window, it will show you a list of applications that can open it. Last but not least, apt-xapian-index provides a command line search tool that is vastly superior to the traditional apt-cache search: it s axi-cache search (axi stands for apt-xapian-index). Enrico compared the output of a search on the letter r . While apt-cache spits out an infinite list of packages containing this letter somewhere in the description, axi-cache only listed packages related to GNU R. He also demonstrated the contextual tab completion. It makes it easy to use debtags and to refine your search. Once you have typed a first keyword, the tab-completion for the second one only contains keywords or debtags that are actually able to provide more restrictive results. Advanced queries with logical operations (AND, OR, NOT, XOR) are also supported. Features of the backend Enrico then dived into the internals. Xapian s search engine is at the root of this infrastructure. He likes it because it s a simple library (i.e. no daemon) and it has nice Python bindings. While apt-xapian-index s core work is to index the descriptions of all the packages, it actually stores much more and can be easily extended with plugins (written in Python). For instance, the information stored encompasses: He already has plans to store more: adding popularity contest data (see wishlist bugs #602180 and #602182) will make it possible to sort query results in a useful way. The most widely used applications are good choices when it comes to community support, and they are likely of better quality due to the larger user base. Adding timestamps of the last installation/upgrade/removal, will make it easier to pin-point a regression to a specific package update. The generated index is world-readable and can be used from any application provided it can use the Xapian library which is written in C++ but has bindings for Perl, Python, PHP, Java, Tcl, C#, and Ruby. Call for experimentation Enrico believes that many useful applications have yet to be invented on top of apt-xapian-index s features. He s calling for experimentation and asking for new ideas. The only practical limit that he has encountered is the size of the index: currently it varies between 50 Mb (Debian unstable without translation) and 70 Mb (Debian stable/testing/unstable with one translation). He would like it to not grow over 100 Mb since it s installed by default (due to aptitude recommending it) and he s not comfortable with the idea of using more than 20% of the disk footprint of a basic install just for this service. That s why the index was configured to not store the position of the terms: it s thus not possible to find out packages whose description contains the word statistical immediately followed by the word computing . You can however find those which have both terms somewhere in their description. Enrico wondered if apt-xapian-index offers too much freedom. That could explain why few people experimented with it despite his numerous blog posts with code samples and information on how to get started using it. But it s not difficult to imagine use cases for this data. It could be used to extend tools like rc-alert or wnpp-alert, for example. They provide a long list of Debian packages that are looking for some help and are installed on the machine. With apt-xapian-index, it would be possible to restrict the results to the set of packages written in a specific programming language or for a particular desktop environment. The more likely explanation is that too few people know about the tool. There are many more itches to scratch where apt-xapian-index s features could be very useful, and my guess is that Enrico s wishes will eventually come true.
This article was first published in Linux Weekly News. Click here to subscribe to my newsletter and keep up with the Debian/Ubuntu news thanks to my monthly digest.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Keith Packard: Altos0.8

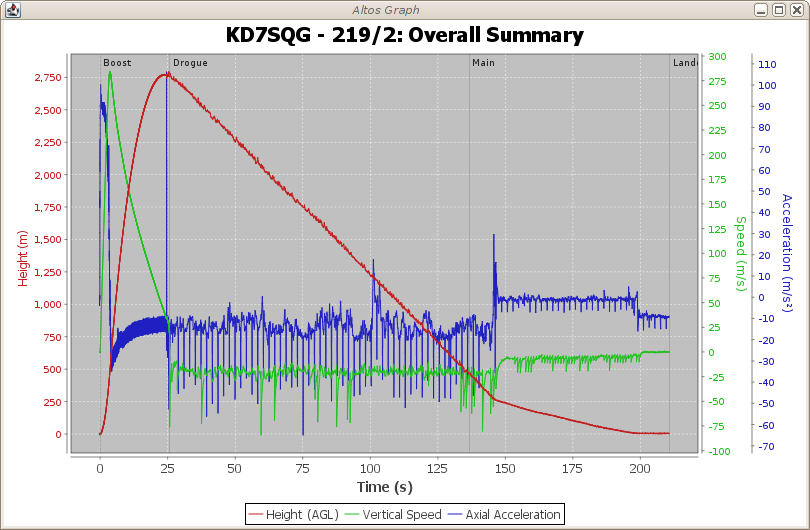
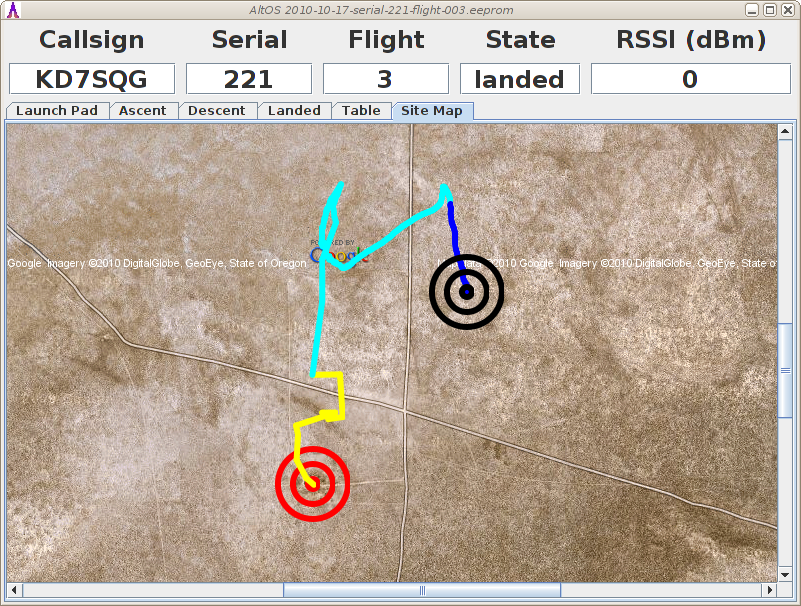
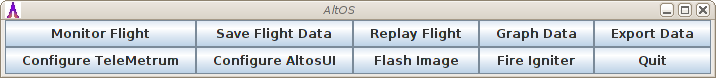
AltOS 0.8 New Software and Firmware for Altus Metrum Devices Bdale and I are pleased to announce the release of AltOS version 0.8. AltOS is the core of the software for all of the Altus Metrum products. It consists of cc1111-based microcontroller firmware and Java-based ground station software. AltosUI New Features in the AltusMetrum Ground Station AltOS version 0.8 contains significant upgrades to the ground station software, AltosUI: Continuing Features AltOS version 0.8 continues to provide the following features: AltOS Firmware Update AltOS version 0.8 contains a minor firmware update for TeleMetrum to resolve an issue with main deployment. A mis-feature in the igniter firing code would delay main deployment by 2 seconds in some cases. Thanks to our contributors! We had a lot of help with this release: Future Plans A number of features are implemented or in process in the sources available in our publicly visible repository that are not part of the current stable release. There are any number of additions that could be made to this list; feel free to send along ideas that you ve got. Of course, all of this software is licensed under the GNU General Public License, so you can get the source and hack on it in the comfort of your own home.
27 November 2010

Paul van Tilburg: 10 Years of Spacelabs

A few months ago I realised it has been 10 years already since Spacelabs 1 was founded. Today we will celebrate that with a reunion and probably reminisce about past projects, events and experiences. Therefore, I thought it would be nice to accompany this with a post. The past Spacelabs was founded to create something that sits in between research and consumer appliances. Since we are associated to the Electro-Optical Communication group these things often had to do with bandwidth. For example, showing the ease of use of plastic optical fiber or participate in GPRS/UMTS trials. However, due to the loose structure of Spacelabs, we ventured into many other projects of our own such a information system-enabled fridge with a barcode reader, a dynamic DNS system, etc. At some point we got our own Internet connection with an accompanying subnet. It has been fun and rewarding to learn how to setup and run a mini ISP. Spacelabs doesn t have any formal structure: when you are on the mailing list, you are a member. There are no regular meetings, no hierarchy, no obligations. So in some ways, we are a group that is much like a free/open source software community. I think that this approach has provided us the drive to work both on projects during our free time as well as our own ideas. I feel that Spacelabs has contributed so much to my life. It might not be the typical study association, but it was a big supplement to my studies, it was fun and it was completely ours. Not only did it teach me many, many technical things from networks to program languages to software design but it also gave me experiences on other levels, such as very attuned group work and responsibilities for key systems. Spacelabs in 2006 The future Soon, everyone connected to Spacelabs will have finished their Master s or PhD (in my case) and nobody will be left to continue the project. Although this is a bit sad, I think we can be proud of what we have accomplished, learnt and experienced. I will miss our location high in the Potentiaal/E-hoog building overlooking Eindhoven, and our being together as a group. We are however not gone yet, there is still a lot to plan and to work on if we want to rescue the huge amount of servers and services that we have accumulated over the years if we were to leave

1 Yes, the website is very much from the past.

Christian Perrier: Goodbye bubulle

Don't be scared (or don't celebrate, depends...), I'm not leaving any project I'm part of. "Goodbye bubulle"....because yesterday, I modified my login on my laptop. I indeed plan to use LDAP authentication at work with it and my login there is surprisingly boringly "cperrier". So, I had to change my local login as first step of the switch to pam_ldapd+pam_ccreds. So, eh, I had to drop any reference to "bubulle" locally. It was surprisingly easy, indeed. Still, in case mails to me happen to bounce...please tell me on IRC (where I'm still "bubulle": this nickname is now nearly 20 years old and some readers of this blog remember why I am so sentimentally stuck with it).

Axel Beckert: Useful but Unknown Unix Tools: units

Ever wondered how to easily convert e.g. 10 seamiles into kilometres? Use units:
$ units 
2411 units, 71 prefixes, 33 nonlinear units
You have: 10 seamiles
You want: km
        * 18.288
        / 0.054680665
You have: ^C
$
Of course this is interactive. There s also a non-interactive mode:
$ units '10 seamiles' 'km'
        * 18.288
        / 0.054680665
$ 
The line with the asterisk means that 10 seamiles are 18.288 kilometres or 1 kilometre is the 0.054680665th part of 10 seamiles. This quite non-intuitive output is caused by the fact that unit is designed to be used with units only:
$ units seamiles km
        * 1.8288
        / 0.54680665
$
Now this makes more sense: You have to multiply seamiles with 1.8288 to get kilometres and you have to multiply (not divide) kilometres with 0.54something to get seamiles. But this output is still a little bit cumbersome, and annoying if you want to use it in shell scripts. But for luck, units knows some nice options, especially -v ( verbose ) and -t ( terse ):
$ units -v '10 seamiles' km
        10 seamiles = 18.288 km
        10 seamiles = (1 / 0.054680665) km
$ units -t '10 seamiles' km
18.288
Now that s way easier to read and script! You can also script more complex things like
$ units -v '100 attoparsec/microfortnight' m/s
        100 attoparsec/microfortnight = 2.5509901 m/s
        100 attoparsec/microfortnight = (1 / 0.39200466) m/s
Unfortunately not all common units are unambiguous for units:
units -v '100 km/h' m/s
conformability error
        100 km/h = 1.5091905e+38 s / kg m
        m/s = 1 m / s
Well, h seems not to be units unit for hours , so lets tell it explicity that we want km per hour:
units -v '100 km/hour' m/s
        100 km/hour = 27.777778 m/s
        100 km/hour = (1 / 0.036) m/s
Looks more like what I expected. units behaves though a little bit strange when I try to convert litres per 100 kilometres into miles per gallon:
$ units -t '6L/100km' 'mpg'
conformability error
6e-08 m^2
425143.71 / m^2
$
Interestingly changing the verbosity helps already in this case:
$ units -v '6L/100km' 'mpg'
        reciprocal conversion
        1 / (6L/100km) = 39.202431 mpg
        1 / (6L/100km) = (1 / 0.025508622) mpg
Greetings from the Debian booth at LinuxDay.at and thanks to Y_Plentyn, rhalina and bzed for example ideas and the suggestion to write a blog posting about units. :-)

Russell Coker: Open Respect

On the 5th of November Jono Bacon wrote a blog post titled MAKING OUR WORLD MORE RESPECTFUL [1]. He then registered the domain OpenRespect.org for his manifesto [2].Aaron Siego supports the general concept of being more respectful while listing some of the practical problems that occur in a multi-cultural world [3]. If you read nothing else about this issue I recommend reading Aaron s post (which I summarised very poorly, I can t think of a good one-sentence explanation).Sam Varghese wrote an article suggesting that it was an attempt to deflect criticism from Ubuntu [4]. I think that Ubuntu receives a lot of unfair criticism, but don t think it s really relevant to the issue at hand. Sam criticises some of the Open Respect supporters for failing to show respect in the past.Jono wrote a follow-up blog post titled REFLECTIONS ON RESPECT [5], in that post he said Sometimes we were disrespectful, and frankly, sometimes we were also inadvertently assholes. We never set out to be assholes, but we did set out to be edgy in a satirical way, but we sometimes went too far and I apologize for that. But you know what, we all grow and mature in different parts of our lives about his past LugRadio work. Maybe instead of focusing on being respectful of others it would give more benefit to focus on how to apologise, back down, and move on after being disrespectful. It seems that the situations of epic disrespect tend not to be one-off incidents but are instead arguments of greatly expanded scope that arose from someone refusing to admit any error after doing something that is considered to be offensive. [Someone has registered OpenApology.org, just in case you were wondering.]Maybe advocating Rogerian Argument would be another way of reducing some of the problems in the community.Finally Kirrily wrote an insightful post about the ineffectiveness of discussing offensive things [6]. In terms of issues such as Feminism (which Kirrily uses as an example and which is also a matter of significant interest for her) discussions about offense apparently tend to end up being about the person who was offended rather than the person who might be described as acting in an offensive manner. She suggests using terms such as marginalised, belittled, stereotyped, frustrated, humiliated, threatened, patronised, silenced, intimidated, misrepresented, etc instead. It seems to me that there may be a similar issue with respect . Objective claims about people being dismissed, ignored, patronised, etc can be evaluated more easily than a claim about being disrespected.

26 November 2010

Leo 'costela' Antunes: My kingdom for a VGA cable

So you have two geeks in a university room after a relatively late and (at least for one of them) unproductive learning session. It s just natural that they decide to kick back and watch some mind-numbingly stupid geek series, which in this case happened to be Stargate SG-1 (so absurdly shitty its actually very entertaining).
The first lazy geek instinct is to just watch it on the laptop that has the file, which with its 11 display and shitty speakers doesn t turn out to be a great idea. The next try involves the other laptop, but a 13 screen isn t that big of an improvement.
Since the room our intrepid heroes are in happens to have a pretty decent built-in projector and a couple of small but still a lot better than a laptop s Bose speakers, the obvious next step would be using it. The only problem is the lack of a VGA cable. Inspired by the brief sight of MacGyver on the 11 screen, one particularly enterprising geek comes up with the challenge of making a VGA cable out of the only material available at the time: one horribly yellow cat5 ethernet cable.
Being the helpful little extra-dimensional entity that it is, the internet happily provided all the needed information and after some slight problems trying to appropriately deprive the cat5 of its connectors (no scissors and no blades of any kind in sight) and some annoying and manual sticking-cable-to-socket action what did you mother tell you about sticking things in sockets? our reluctant hackers get it right: it's ALIIIIIVEEEE!!! The final solution looked like this: nothing like cable salad for dinner And if you re wondering where those white wires came from, one final touch of ber-hackerdom: notepads have never been more useful This might seem like overkill, but after a nice nice 4 hour movies and series marathon, we can safely say it was totally worth it (but no, we didn t stand 4 hours of Stargate; even geeks have their limits). Just in case the Instructables page gets hosed at some point, here s the invaluable connection diagram, originally scraped off of a since dead Geocities page.

Matt Zimmerman: Three ways for Ubuntu to help developers

Developers are a crucial part of any successful software platform. In the same way that an operating system is just a means for people to use applications, a platform is just a means for developers to create applications and make them available to people. There are three primary ways in which Ubuntu can help developers do their work. They are all related, but distinct, and so we should consider them individually: 1. Developing for Ubuntu Today, Ubuntu bundles thousands of free software applications, for both clients and servers, most of which are packaged by Debian. Ubuntu also carries certifications for a variety of third-party ISV software, both open source and proprietary, which are coordinated through Canonical s partner program. In both of these cases, many of these applications are actually developed on other platforms, and ported to Ubuntu, either by the free software community or by the creators of the software. 2. Developing on Ubuntu Ubuntu is already quite popular among developers, who mainly run Desktop Edition on their workstations. They might be developing: 3. Distributing through Ubuntu Like other modern operating systems, Ubuntu isn t just a platform where applications run, but also a system for finding and installing applications. Starting with APT, which originated in Debian, we ve added Software Center, the ISV partner repository, and various other capabilities in this area. They all help to connect developers with users, facilitating distribution of software to users, and feedback to developers. So, where should we focus? Some developers might be interested in all three of these, while others might only care about one or two. However, most of the developer improvements we could make in Ubuntu would only address one of these areas. For this reason, I think it s important that we consider the question of the relative importance of these three developer scenarios. Given that we want Ubuntu to flourish as a platform, how would we prioritize them? I have my own ideas, which I ll write about in subsequent posts, but here s your chance to tell me what you think. :-)

David Welton: Kindle thoughts

I went ahead and got myself a Kindle for my birthday. Thanks to everyone for their comments in the last post. Here are my thoughts on it, in no particular order:
I like it a lot. I was worried that I would not actually enjoy reading with it, or that it would be significantly inferior to real books. However, I do enjoy reading with it, and I think they have achieved their aim of making it so that it 'just disappears' like a good book does. It's a very small and light device, even with the leather cover I got for it (always best with a small child in the house), so it's in no way heavy or uncomfortable. It's relatively more expensive and fragile than a copy of The Economist or a paperback, so I don't sling it around quite so casually, and do try and remember to keep it out of reach of said small child, which makes it a little less worry-free than an actual book. On the other hand, it's much cheaper than an ipad or samsung galaxy or something like that, so it's not the end of the world if something happens to it, although it would be unfortunate to be without reading material for the time it took to replace it!
The selection of material available for it is ok, but I'm just a bit disappointed - I thought offhand there were more books than there are. I regularly bump into things I might consider getting if they were available for it, but are not. On the other hand, there are quite a few books available for it for *free* because they're old and out of copyright. Stuff you might get for 99 cents at a used book store as a paperback, but it's pretty cool to be able to just zip it right to the device, for nothing at all. I am not convinced that the economics of it all has settled down yet. It's pretty absurd, for instance, that The Intelligent Investor costs nearly twice as much for the Kindle version as for the paperback! Especially since I can never resell it. I think a lot of the value I get from the device is derived from my situation: living abroad here in Italy, it's expensive and slow to get English language books, and now I can get them *instantly*, which is absolutely wonderful, and will significantly increase my reading. Also, should we ever move back to the US or elsewhere, it means a few less books to lug along or go through the sorrow of parting with. Were I in the US in a place with a decent used book store, and sure about staying in the same place for a while, I am not sure I would have bothered. I find it somehow a bit monotonous to read everything in the same form factor and with the same fonts. It takes something away from the character of a book, especially a well-done hardback. Of course, what counts is the content, but the presentation counts for something too, I think. I really do like the size and shape of the Kindle, and could see the 'smaller tablet' size catching on. Speaking of which, I'm curious to see how reading devices and tables will intersect. Clearly, a generic device that can also read books is going to be a lot more popular, but for now e-ink still has a few advantages: it's better for reading - I can stare at it much longer than I can at an LCD screen; also the battery life is much better, meaning I don't have to worry about/fiddle with charging it every day. Also, in some ways, it's nice not to have the siren-call of the web just a click away... I think though that at some point, generic devices will likely overtake dedicated readers. Who knows when, though.
Yes, it does have a browser, however, the screen refresh is so slow that I'd only really consider using it for reading web pages - wikipedia, say, rather than doing much with it. Still, I think it's nice to have and hope they continue the experiment.
Coming back to the comparison with 'real' books, I don't like the fact that I can no longer finish a book and then hand it to my wife if it's good. We could get her a Kindle too, but I'm still not sure they have the sharing thing worked out that well. 2 weeks - and then what? One way to do it might be that you can share it with anyone who you trust with one-click purchases. That'd limit it to family members or really trustworthy friends. Although... even there, I regularly loan books to friends, and would like to continue to be able to do so. Also, like I mentioned in the previous article, I'm leary of a future where my daughter doesn't have a multitude of books to peruse on our bookshelves. Bookshelves are a great way of making serendipitous discoveries that recommendation engines (those I've used at least) don't really account for. All in all, I'm very pleased with the Kindle, though, and look forward to seeing what the future holds.

Russell Coker: Quality of Cameras in Phones

The discussion in the comments on my post about a mobile phone for Sysadmin use [1] turned to the issue of picture quality. This is an issue for a sysadmin as photographing the screen of a crashed computer while being a rare occurrence can be an important part of solving a computer problem.Lon recommended a review of phone cameras by the Norwegian site Amobil [2]. This review only included devices that had already passed earlier review, so even the HTC Desire HD (which came last on the Amobil tests) still has a better camera than most phones on the market. It s a pity that no English-language site seems to have done such a review.The Amobil article (when translated) says: In the mobile industry is faced with the need for much extra processing for the images to look good, because there is no room for large optics and large image sensors that receive sufficient amount of light .IMHO that s overstating the case. I have yet to see a camera-phone that couldn t be redesigned in a trivial way to give a better camera functionality. It appears that the limiting factor is the thickness of phone which limits the maximum focal length and therefore the maximum area (I presume it s safe to assume that Fresnel lenses are not viable for cameras). My LG U990 Viewty is 14.8mm thick, I would be happy with something a bit thicker if it gave a better picture, 30mm wouldn t be a problem (my first few mobile phones were thicker than that and had no camera). Maybe a design could have the camera stick out such that the main body of the phone was 15mm thick while the camera part was 30mm. Also having the camera in a central part of the phone (underneath the touch-screen) probably loses at least 1mm of focal length. It seems that the amount of light captured will be the square of the focal length, so an ideal (IMHO) camera design could have twice the depth of a Viewty, 4* the light captured, and therefore have an 8MP camera with a better response in adverse light than the Viewty (which is pretty good for a phone but crap for a camera).I noted in the comments that it s a pity that camera-phones don t support storing pictures in RAW format, Paul pointed out that the Nokia N900 supports RAW pictures. I m glad to learn that at least one phone-camera manufacturer is doing the sane thing, now we just need to have RAW pictures as a check-list item on reviews to force others to do the same. I wonder whether a modified version of the Android OS could support RAW format Amobil published an article about some joint ventures between camera and phone companies [3]. Apparently LG are working on a phone with 3* Optical Zoom that uses Pentax optics, while the Olympus camera company is considering the purchase of a phone company with the apparent aim of producing a killer camera-phone.I wonder whether I should delay the purchase of my next phone for a few months to take advantage of some of these developments. If nothing else I expect some significant improvements in the screen resolution of phones in the near future. The maximum screen resolution that is common at the moment is 800*480 (WVGA), but the iPhone 4 supports 960*640 resolution which is 60% more pixels and I expect other manufacturers to release phones to compete with it in the near future.

Next.

Previous.