Search Results: "cas"

23 December 2024

Sahil Dhiman: Debian Mirrors Hierarchy

After finding AlmaLinux mirror sync capacity at Tier 0 (or Tier 1, however you look at it) is around 140 Gbps, I wanted to find source and hierarchy in Debian mirroring systems. There are two main types of mirrors in Debian - Debian package mirrors (for package installs and updates) and Debian CD mirrors (for ISO and others medias). Let s talk about package mirrors (and it s hierarchy) first.

Package mirror hierarchy Trace file was a good starting point for checking upstream for a package mirror in Debian. It resides at <URL>/debian/project/trace/_traces and shows flow of data. Sample trace file from jing.rocks s mirror. It showed, canonical source for packages is ftp-master.debian.org. Checking via https://db.debian.org/machines.cgi, showed it s fasolo.d.o hosted at Brown University, US. This serves as Master Archive Server , making it a Tier 0 mirror. It s entry mentions that it has 1 Gbps shared LAN connectivity (dated information?) but it only has to push to 3 other machines/sites. Side note - .d.o is .debian.org As shown on https://mirror-master.debian.org/status/mirror-hierarchy.html, the three sites are:
  • syncproxy2.eu.debian.org ie smit.d.o hosted by University of Twente, Netherlands with 2x10 Gbps connectivity.
  • syncproxy4.eu.debian.org ie schmelzer.d.o hosted by Conova in Austria with 2x10 Gbps connectivity.
  • syncproxy2.wna.debian.org - https://db.debian.org/machines.cgi entry mentions it being hosted at UBC here, but IP seems to be pointing to OSUOSL IP range as of now. IIRC few months ago, syncproxy2.wna.d.o was made to point to other host due to some issue (?). mirror-osuosl.d.o seems to be serving as syncproxy2.wna.d.o now. Bandwidth isn t explicitly mentioned but from my experience seeing bandwidths which other free software projects hosted at OSUOSL have, it would be atleast 10 Gbps and maybe more for Debian.

                     syncproxy2.eu.d.o (NL) ---> to the world
                    /
ftp-master.d.o (US) -- syncproxy4.eu.d.o (AT)  --> to the world 
                    \
                     syncproxy2.wna.d.o (US) --> to the world
A visualation of flow of package from ftp-master.d.o
These form the Debian Tier 1 mirror network, as all the mirrors sync from them. So Debian has atleast 50 Gbps+ capacity at Tier 1. A normal Debian user might never directly interact with any of these 3 machines, but every Debian package they run/download/install flows through these machines. Though, I m unsure what wna stands for in syncproxy2.wna.d.o. NA probably is North America and W is west (coast)? If you know, do let me know. After Tier 1, there are a few more syncproxies (detailed below). There are atleast 45 mirrors at Tier 2, updates for which are directly pushed from the three Tier 1 sync proxies. Most country mirrors i.e. ftp..debian.org are at Tier 2 too (barring a few like ftp.au.d.o, ftp.nz.do etc). Coming back to Sync proxies at Tier 2:
  • syncproxy3.wna.debian.org - gretchaninov.d.o which is marked as syncproxy2 on db.d.o (information dated). It s hosted in University of British Columbia, Canada, where a lot of Debian infrastructure including Salsa is hosted.
  • syncproxy.eu.debian.org - Croatian Academic and Research Network managed machine. CNAME directs to debian.carnet.hr.
  • syncproxy.au.debian.org - mirror-anu.d.o hosted by Australian National University with 100Mbps connectivity. Closest sync proxy for all Australian mirrors.
  • syncproxy4.wna.debian.org - syncproxy-aws-wna-01.d.o hosted in AWS, in US (according to GeoIP). IPv6 only (CNAME to syncproxy-aws-wna-01.debian.org. which only has an AAAA record, no A record). A m6g.2xlarge instance which has speeds upto 10 Gbps.
Coming back to https://mirror-master.debian.org/status/mirror-hierarchy.html, one can see chain extend till Tier 6 like in case of this mirror in AU which should add some latency for the updates from being pushed at ftp-master.d.o to them. Ideally, which shouldn t be a problem as https://www.debian.org/mirror/ftpmirror#when mentions The main archive gets updated four times a day . In my case, I get my updates from NITC mirror, so my updates flows from US > US > TW > IN > me in IN. CDNs have to internally manage cache purging too unlike normal mirrors which directly serve static file. Both deb.debian.org (sponsored by Fastly) and cdn-aws.deb.debian.org (sponsored by Amazon Cloudfront) sync from following CDN backends: See deb.d.o trace file and cdn-aws.deb.d.o trace file. (Thanks to Philipp Kern for the heads up here.)

CD image mirrors Hierarchy Till now, I have only talked about Debian package mirrors. When you see /debian directory on various mirrors, they re usually for package install and updates. If you want to grab the latest (and greatest) Debian ISO, you go to Debian CD (as they re still called) mirror site. casulana.d.o is mentioned as CD builder site hosted by Bytemark while pettersson-ng.d.o is mentioned as CD publishing server hosted at Academic Computer Club in Ume , Sweden. Primary download site for Debian CD when you click download on debian.org homepage is https://cdimage.debian.org/debian-cd/ is hosted here as well. This essentially becomes Tier 0 mirror for Debian CD. All Debian CD mirrors are downstream to it.
pettersson-ng.d.o / cdimage.d.o (SE) ---> to the world
A visualation of flow of Debian CD from cdimage.d.o
Academic Computer Club s mirror setup uses a combination of multiple machines (called frontends and offloading servers) to load balance requests. Their document setup is a highly recommended read. Also, in that document, they mention , All machines are reachable via both IPv4 and IPv6 and connected with 10 or 25 gigabit Ethernet, external bandwidth available is 200 gigabit/s. For completeness sake, following mirror (or mirror systems) exists too for Debian: Debian heavily rely on various organizations to donate resources (hosting and hardware) to distribute and update Debian. Compiling above information made me thankful to all these organizations. Many thanks to DSA and mirror team as well for managing these stuffs. I relied heavily on https://db.debian.org/machines.cgi which seems to be manually updated, so things might have changed along the way. If anything looks amiss, feel free to ping.

Russ Allbery: Review: The House That Walked Between Worlds

Review: The House That Walked Between Worlds, by Jenny Schwartz
Series: Uncertain Sanctuary #1
Publisher: Jenny Schwartz
Copyright: June 2020
Printing: September 2024
ASIN: B0DBX6GP8Z
Format: Kindle
Pages: 215
The House That Walked Between Worlds is the first book of a self-published trilogy of... hm. Space fantasy? Pure fantasy with a bit of science fiction thrown in for flavor? Something like that. I read it as part of the Uncertain Sanctuary omnibus, which is reflected in the sidebar metadata. Kira Aist is a doctor. She's also a witch and a direct descendant of Baba Yaga. Her Russian grandmother warned her to never use magic and never reveal who she was because people would hunt her and her family if she did. She broke the rule to try to save a child, her grandmother was right, and now multiple people are dead, including her parents. As the story opens, she's deep in the wilds of New Zealand in a valley with buried moa bones, summoning her House so that she can flee Earth. Kira's first surprise is that her House is not the small hut that she was expecting from childhood visits to Baba Yaga. It's larger. A lot larger: an obsidian castle with nine towers and legs that resemble dragons rather than the moas whose magic she drew on. Her magic apparently had a much different idea of what she needs than she did. Her second surprise is that her magical education is highly incomplete, and she is not the witch that she thought she was. Her ability to create a House means that she's a sorcerer, the top tier of magical power in a hierarchy about which she knows essentially nothing. Thankfully the House has a library, but Kira has a lot to learn about the universe and her place in it. I picked this up because the premise sounded a little like the Innkeeper novels, and since another novel in that series does not appear to be immediately forthcoming, I went looking elsewhere for my cozy sentient building fix. The House That Walked Between Worlds is nowhere near as well-written (or, frankly, coherent) as the Innkeeper books, but it did deliver some of the same vibes. You should know going in that there isn't much in the way of a plot. Schwartz invented an elaborate setting involving archetype worlds inhabited by classes of mythological creatures that in some mystical sense surround a central system called Qaysar. These archetype worlds spawn derived worlds, each of which seems to be its own dimension, although the details are a bit murky to me. The world Kira thinks of as Earth is just one of the universes branched off of an archetypal Earth, and is the only one of those branchings where the main population is human. The other Earth-derived worlds are populated by the Dinosaurians and the Neanderthals. Similarly, there is a Fae world that branches into Elves and Goblins, an Epic world that branches into Shifters, Trolls, and Kobolds, and so forth. Travel between these worlds is normally by slow World Walker Caravans, but Houses break the rules of interdimensional travel in ways that no one entirely understands. If your eyes are already starting to glaze over, be warned there's a lot of this. The House That Walked Between Worlds is infodumping mixed with vibes, and I think you have to enjoy the setting, or at least the sheer enthusiasm of Schwartz's presentation of it, to get along with this book. The rest of the story is essentially Kira picking up strays: first a dangerous-looking elf cyborg, then a juvenile giant cat (because of course there's a pet fantasy space cat; it's that sort of book), and then a charming martial artist who I'm fairly sure is up to no good. Kira is entirely out of her depth and acting on instinct, which luckily plays into stereotypes of sorcerers as mysterious and unpredictable. It also helps that her magic is roughly "anything she wants to happen, happens." This is, in other words, not a tightly-crafted story with coherent rules and a sense of risk and danger. It's a book that succeeds or fails almost entirely on how much you like the main characters and enjoy the world-building. Thankfully, I thought the characters were fun, if not (so far) all that deep. Kira deals with her trauma without being excessively angsty and leans into her new situation with a chaotic decisiveness that I found charming. The cyborg elf is taciturn and a bit inscrutable at first, but he grew on me, and thankfully this book does not go immediately to romance. Late in the book, Kira picks up a publicity expert, which was not at all the type of character that I was expecting and which I found delightful. Most importantly, the House was exactly what I was looking for: impish, protective, mysterious, inhuman, and absurdly overpowered. I adore cozy sentient building stories, so I'm an easy audience for this sort of thing, but I'm already eager to read more about the House. This is not great writing by any stretch, and you will be unsurprised that it's self-published. If you're expecting the polish and plot coherence of the Innkeeper stories, you'll be disappointed. But if you just want to spend some time with a giant sentient space-traveling mansion inhabited by unlikely misfits, and you don't mind large amounts of space fantasy infodumping, consider giving this a shot. I had fun with it and plan on reading the rest of the omnibus. Followed by House in Hiding. Rating: 6 out of 10

20 December 2024

Noah Meyerhans: Local Development VM Management

A coworker asked recently about how people use VMs locally for dev work, so I figured I d take a few minutes to write up a bit about what I do. There are many use cases for local virtual machines in software development and testing. They re self-contained, meaning you can make a mess of them without impacting your day-to-day computing environment. They can run different distributions, kernels, and even entirely different operating systems from the one you use regularly. Etc. They re also cheaper than cloud services and provide finer grained control over the resources. I figured I d share a little bit about how I manage different virtual machines in case anybody finds this useful. This is what works for me, but it won t necessarily work for you, or maybe you ve already got something better. I ve found it to be easy to work with, light weight, and is easy to evolve my needs change.

Use short-lived VMs Rather than keep a long-lived development VM around that you customize over time, I recommend automating the common customizations and provisioning new VMs regularly. If I m working on reproducing a bug or testing a change prior to submitting it upstream, I ll do this work in a VM and delete the VM when when I m done. When provisioning VMs this frequently, though, walking through the installation process for every new VM is tedious and a waste of time. Since most of my work is done in Debian, so I start with images generated daily by the cloud team. These images are available for multiple releases and architectures. The nocloud variant boots to a root prompt and can be useful directly, or the generic images can be used for cloud-init based customization.

Automating image preparation This makefile lets me do something like make image and get a new qcow2 image with the latest build of a given Debian release (sid by default, with others available by specifying DIST).
DATESTAMP=$(shell date +"%Y-%m-%d")
FLAVOR?=generic
ARCH?=$(shell dpkg --print-architecture)
DIST?=sid
RELEASE=$(DIST)
URL_PATH=https://cloud.debian.org/images/cloud/$(DIST)/daily/latest/
ifeq ($(DIST),trixie)
RELEASE=13
endif
ifeq ($(DIST),bookworm)
RELEASE=12
endif
ifeq ($(DIST),bullseye)
RELEASE=11
endif
debian-$(DIST)-$(FLAVOR)-$(ARCH)-daily.tar.xz:
curl --fail --connect-timeout 20 -LO \
$(URL_PATH)/debian-$(RELEASE)-$(FLAVOR)-$(ARCH)-daily.tar.xz
$(DIST)-$(FLAVOR)-$(DATESTAMP).qcow2: debian-$(RELEASE)-$(FLAVOR)-$(ARCH)-daily.tar.xz
tar xvf debian-$(RELEASE)-$(FLAVOR)-$(ARCH)-daily.tar.xz
qemu-img convert -O qcow2 disk.raw $@
rm -f disk.raw
qemu-img resize $@ 20g
qemu-img snapshot -c untouched $@
image: $(DIST)-$(FLAVOR)-$(DATESTAMP).qcow2
.PHONY: image

Customize the VM environment with cloud-init While the nocloud images can be useful, I typically find that I want to apply the same modifications to each new VM I launch, and they don t provide facilities for automating this. The generic images, on the other hand, run cloud-init by default. Using cloud-init, I can create my user account, point apt at local mirrors, install my preferred tools, ensure the root filesystem is resized to make full use of the backing storage, etc. The cloud-init configuration on the generic images will read from a local config drive, which can contain an ISO9660 (cdrom) filesystem image. This image can be generated from a subdirectory containing the various cloud-init input files using the following make syntax:
IMDS_FILES=$(shell find seedconfig -path '*/.git/*' \
-prune -o -type f -name '*.in.json' -print) \
seedconfig/openstack/latest/user_data
seed.iso: $(IMDS_FILES)
genisoimage -V config-2 -o $@ -J -R -m '*~' -m '.git' seedconfig
With the image in place, the VM can be created with
 qemu-system-x86_64 -machine q35,accel=kvm
-cpu host -m 4g -drive file=$ img ,index=0,if=virtio,media=disk
-drive file=seed.iso,media=cdrom,format=raw,index=2,if=virtio
-nic user -nographic
This invokes qemu with the root volume and ISO image attached as disks, uses an emulated q35 machine with the host s CPU and KVM acceleration, the userspace network stack, and a serial console. The first time the VM boots, cloud-init will apply the configuration from the cloud-config available in the ISO9660 filesystem.

Alternatives to cloud-init virt-customize is another tool accomplishing the same type of customization. I use cloud-init because it works directly with cloud providers in addition to local VM images. You could also use something like ansible.

Variations I have a variant of this that uses a bridged network, which I ll write more about later. The bridge is nice because it s more featureful, with full support for IPv6, etc, but it needs a bit more infrastructure in place. It also can be helpful to use 9p or virtfs to share filesystem state between the host the VM. I don t tend to rely on these, and will instead use rsync or TRAMP for moving files around. Containers are also useful, of course, and there are plenty of times when the full isolation of a VM is not worth the overhead.

17 December 2024

Gunnar Wolf: The science of detecting LLM-generated text

This post is a review for Computing Reviews for The science of detecting LLM-generated text , a article published in Communications of the ACM
While artificial intelligence (AI) applications for natural language processing (NLP) are no longer something new or unexpected, nobody can deny the revolution and hype that started, in late 2022, with the announcement of the first public version of ChatGPT. By then, synthetic translation was well established and regularly used, many chatbots had started attending users requests on different websites, voice recognition personal assistants such as Alexa and Siri had been widely deployed, and complaints of news sites filling their space with AI-generated articles were already commonplace. However, the ease of prompting ChatGPT or other large language models (LLMs) and getting extensive answers its text generation quality is so high that it is often hard to discern whether a given text was written by an LLM or by a human has sparked significant concern in many different fields. This article was written to present and compare the current approaches to detecting human- or LLM-authorship in texts. The article presents several different ways LLM-generated text can be detected. The first, and main, taxonomy followed by the authors is whether the detection can be done aided by the LLM s own functions ( white-box detection ) or only by evaluating the generated text via a public application programming interface (API) ( black-box detection ). For black-box detection, the authors suggest training a classifier to discern the origin of a given text. Although this works at first, this task is doomed from its onset to be highly vulnerable to new LLMs generating text that will not follow the same patterns, and thus will probably evade recognition. The authors report that human evaluators find human-authored text to be more emotional and less objective, and use grammar to indicate the tone of the sentiment that should be used when reading the text a trait that has not been picked up by LLMs yet. Human-authored text also tends to have higher sentence-level coherence, with less term repetition in a given paragraph. The frequency distribution for more and less common words is much more homogeneous in LLM-generated texts than in human-written ones. White-box detection includes strategies whereby the LLMs will cooperate in identifying themselves in ways that are not obvious to the casual reader. This can include watermarking, be it rule based or neural based; in this case, both processes become a case of steganography, as the involvement of a LLM is explicitly hidden and spread through the full generated text, aiming at having a low detectability and high recoverability even when parts of the text are edited. The article closes by listing the authors concerns about all of the above-mentioned technologies. Detecting an LLM, be it with or without the collaboration of the LLM s designers, is more of an art than a science, and methods deemed as robust today will not last forever. We also cannot assume that LLMs will continue to be dominated by the same core players; LLM technology has been deeply studied, and good LLM engines are available as free/open-source software, so users needing to do so can readily modify their behavior. This article presents itself as merely a survey of methods available today, while also acknowledging the rapid progress in the field. It is timely and interesting, and easy to follow for the informed reader coming from a different subfield.

Russ Allbery: Review: Iris Kelly Doesn't Date

Review: Iris Kelly Doesn't Date, by Ashley Herring Blake
Series: Bright Falls #3
Publisher: Berkley Romance
Copyright: October 2023
ISBN: 0-593-55058-7
Format: Kindle
Pages: 381
Iris Kelly Doesn't Date is a sapphic romance novel (probably a romantic comedy, although I'm bad at romance subgenres). It is the third book in the Bright Falls series. In the romance style, it has a new set of protagonists, but the protagonists of the previous books appear as supporting characters and reading this will spoil the previous books. Among the friend group we were introduced to in Delilah Green Doesn't Care, Iris was the irrepressible loudmouth. She's bad at secrets, good at saying whatever is on her mind, and has zero desire to either get married or have children. After one of the side plots of Astrid Parker Doesn't Fail, she has sworn off dating entirely. Iris is also now a romance novelist. Her paper store didn't get enough foot traffic to justify staying open, so she switched her planner business to online only and wrote a romance novel that was good enough to get a two-book deal. Now she needs to write a second book and she has absolutely nothing. Her own avoidance of romantic situations is not helping, but neither is her meddling family who are convinced her choices about marriage and family can be overturned with sufficient pestering. She desperately needs to shake up her life, get out of her creative rut, and do something new. Failing that, she'll settle for meeting someone in a bar and having some fun. Stevie is a barista and actress living in Portland. Six months ago, she broke up with Adri, her creative partner, girlfriend of six years, and the first person with whom she had a serious relationship. More precisely, Adri broke up with her. They're still friends, truly, even though that friendship is being seriously strained by Adri dating Vanessa, another member of their small and close-knit friend group. Stevie has occasionally-crippling anxiety, not much luck in finding real acting roles in Portland, and a desperate desire to not make waves. Ren, the fourth member of their friend group, thinks Stevie needs a new relationship, or at least a fling. That's how Stevie, with Ren as backup and encouragement, ends up at the same bar with Iris. The resulting dance and conversation was rather fun for both Stevie and Iris. The attempted one-night stand afterwards was a disaster due to Stevie's anxiety, and neither of them expected to see the other again. Stevie therefore felt safe pretending they'd hit it off to get her friends off her back. When Iris's continued restlessness lands her in an audition for Adri's fundraiser play that she also talked Stevie into performing in, this turns into a full-blown fake dating trope. These books continue to be impossible to put down. I'm not sure what Blake is doing to make the pacing so perfect, but as with the previous books of the series I found this utterly compulsive reading. I started it in the afternoon, took a break in the evening for a few hours, and then finished it at 2am. I wasn't sure if a book focused on Iris would work as well, but I need not have worried. Iris Kelly Doesn't Date is both more dramatic and more trope-centered than the earlier books, but Blake handles that in a way that fits Iris's personality and wasn't annoying even to a reader like me, who has an aversion to many types of relationship drama. The secret is Stevie, and specifically having the other protagonist be someone with severe anxiety.
No was never a very easy word for Stevie when it came to Adri, when it came to anyone, really. She could handle the little stuff do you want a soda, have you seen this movie, do you like onions on your pizza but the big stuff, the stuff that caused disappointed expressions and down-turned mouths... yeah, she sucked at that part. Her anxiety would flare, and she'd spend the next week convinced her friends hated her, she'd die alone and miserable, and wasn't worth a damn to anyone. Then, when said friend or family member eventually got ahold of her to tell her that, no, of course they didn't hate her, why in the world would she think that, her anxiety would crest once again, convincing her that she was terrible at understanding people and could never trust her own brain to make heads or tails of any social situation.
This is a spot-on description of a particular type of anxiety, but also this is the perfect protagonist to pair with Iris. Throughout the series, Iris has always been the ride-or-die friend, the person who may have no idea how to help but who will show up anyway and at least try to distract you. Stevie's anxiety makes Iris feel protective, which reveals one of the best sides of Iris's personality, and then the protectiveness plays off against Iris's own relationship issues and tendency to avoid taking anything too seriously. It's one of those relationships that starts a bit one-sided and then becomes mutually supporting once Stevie gets her feet under her. That's a relationship pattern I really enjoy reading about. As with the rest of the series, the friendship dynamics are great. Here we get to see two friend groups at work: Iris's, which we've seen in the previous two volumes and which expanded interestingly in Astrid Parker Doesn't Fail, and Stevie's, which is new. I liked all of these people, even Adri in her own way (although she's the hardest to like). The previous happily-ever-afters do get a bit awkward here, but Blake tries to make that part of the plot and also avoids most of the problem of somewhat-boring romantic bliss by spreading the friendship connections a bit wider. Stevie's friend group formed at orientation at Reed College, and that let me put my finger on another property of this series: essentially all of the characters are from a very specific social class. They're nearly all arts people (bookstore owner, photographer, interior decorator, actress, writer, director), they've mostly gone to college, and while most of them don't have lots of money, there's always at least one person in each friend group with significant wealth. Jordan, from the previous book, is a bit of an exception since she works in a trade (a carpenter), but she still acts like someone from that same social class. It's a bit like reading Jane Austen novels and realizing that the protagonists are drawn from a very specific and very narrow portion of society. This is not a complaint, to be clear; I have no objections to reading about a very specific social class. But if one has already read lots of books about this class of people, I could see that diminishing the appeal of this series a bit. There are a lot of assumptions baked into the story that aren't really questioned, such as the ubiquity of therapists. (I don't know how Stevie affords one on a barista salary.) There are also some small things in the terminology (therapy speak, for example) and in the specific type of earnestness with which the books attempt to be diverse on most axes other than social class that I suspect may grate a bit for some readers. If that's you, this is your warning. There is a third-act breakup here, just like the previous volumes. There is also a defense of the emotional punch of third-act breakups in romance novels in the book itself, put into Iris's internal monologue, so I suspect that's the author's answer to critics like myself who don't like the trope. I was less frustrated by this one because it fit the drama level of the protagonists, but I'll also know to expect a third-act breakup in any Blake novel I read in the future. But, all that said, the summary once again is that I loved this book and could not put it down. Iris is dramatic and occasionally self-destructive but has a core of earnest empathy that makes her easy to like. She's exactly the sort of extrovert who is soothing to introverts rather than draining because she carries the extrovert load of social situations. Stevie is adorably earnest and thoughtful beneath her anxiety. They two of them are wildly different and yet remarkably good together, and I loved reading their story. Highly recommended, along with the whole series. Start with Delilah Green Doesn't Care; if you like that, you're in for a treat. Content note: This book is also rather sex-forward and pretty explicit in the sex scenes, maybe a touch more than Astrid Parker Doesn't Fail. If that is or is not your thing in romance novels, be aware going in. Rating: 9 out of 10

16 December 2024

Dirk Eddelbuettel: #45: Some r-ci Updates

market monitor Welcome to post 45 in the $R^4 series! We introduced r-ci here in post #32 here nearly four years ago. It has found pretty widespread use and adoption, and we received a few kind words then (in the linked issue) and also more recently (in a follow-up comment) from which we merrily quote:
[ ] almost 3 years later on and I have had zero problems with this CI setup. For people who want reliable R software, resources like these are invaluable.
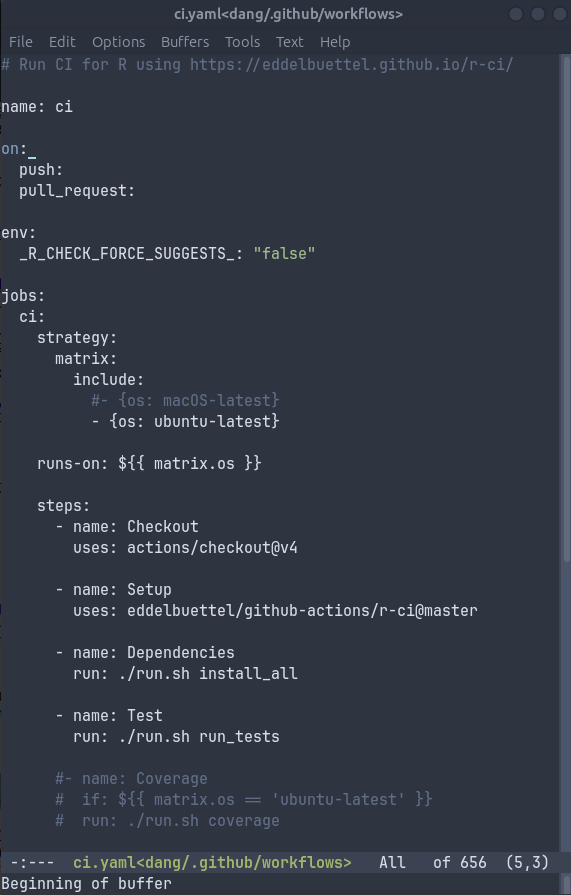
And while we followed up with post #41 about r2u for simple continuous integration, we may not have posted when we based r-ci on r2u (for the obvious Linux usage case). So let s make time now for a (comparitively smaller) update, and an update usage examples. We made two changes in the last few days. One is a (obvious in hindsight) simplification. Given that the bootstrap step was always executed, and needed no parameters, we pulled it into a new aggregated setup simply called r-ci that includes it so that it can be omitted as a step in the yaml file. Second, we recently needed Fortran on macOS too, and realized it was not installed by default so we just added that too. With that a real and used example is now as simple as the screenshot to the left (and hence one paragraph shorter). The trained eye will no doubt observe that there is nothing specific to a given repo. And that is basically the key feature: we can simply copy this file around and get fast and easy and reliable CI by taking advantage of the underlying robustness of r2u solving all dependency automagically and reliably. The option to enable macOS is also solid and compelling as the GitHub runners are fast (but more expensive in how the count against the limit of minutes so again a tradeoff to make), as is the option to run coverage if one so desires. Some of my repos do too. Take a look at the r-ci website which has more examples for the other supported CI servics it can used with, and feel free to ask questions as issue in the repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub. Please report excessive re-aggregation in third-party for-profit settings.

Russ Allbery: Review: Finders

Review: Finders, by Melissa Scott
Series: Firstborn, Lastborn #1
Publisher: Candlemark & Gleam
Copyright: 2018
ISBN: 1-936460-87-4
Format: Kindle
Pages: 409
Finders is a far future science fiction novel with cyberpunk vibes. It is the first of a series, but the second (and, so far, only other) book of the series is a prequel. It stands alone reasonably well (more on that later). Cassilde Sam is a salvor. That means she specializes in exploring ancient wrecks and ruins left behind by the Ancients and salvaging materials that can be reused. The most important of those are what are called Ancestral elements: BLUE, which can hold programming; GOLD, which which reacts to BLUE instructions; RED, which produces actions or output; and GREEN, the rarest and most valuable, which powers everything else. Cassilde and her partner Dai Winter file claims on newly-discovered or incompletely salvaged Ancestor sites and then extract elemental material and anything else of value in their small salvage ship. Cassilde is also dying. She has Lightman's, an incurable degenerative disease that can only be treated with ever-increasing quantities of GREEN. It's hard to sleep, hard to get warm, hard to breathe, and eventually she'll run out of money to pay for the GREEN and she'll die. To push that day off into the future, she and Dai need work. The good news is that the wreckage of a new Ancestor sky palace was discovered in a long orbit and will create enough salvage work for every experienced salvor in the system. The bad news is that they're not qualified to bid on it. They need a scholar with a class-one license to bid on the best sections, and they haven't had a reliable scholar since their former partner and lover Summerland Ashe picked the opposite side in the Troubles and left the Fringe for the Entente, the more densely settled and connected portion of human space. But, unexpectedly and suspiciously, Ashe may be back and offering to work with them again. So, first, I love this setting. This is far from the first SF novel that is set in the aftermath of a general collapse of human civilization and revolving around discovering lost mysteries. Most examples of that genre are post-apocalyptic novels limited to Earth or the local solar system, but Kate Elliott's Unconquerable Sun comes immediately to mind. It's also not the first space archaeology series I've read; Kristine Kathyrn Rusch's story series starting with "Diving into the Wreck" also came to mind. But I don't recall the last time I've seen the author sell the setting so effectively. This is a world with starships and spaceports and clearly advanced technology, but it feels like a post-collapse society that's built on ruins. It's not just that technology runs on half-understood Ancestral elements and states fight over control of debris fields. It's also that the society repurposes Ancestral remnants in ways that both they and the reader know weren't originally intended, and that sometimes are more ingenious or efficient than how the Ancestors probably used them. There's a creative grittiness here that reminds me of good cyberpunk. It's not just good atmospheric writing, though. Scott makes a world-building decision that is going to sound trivial when I say it, but that has brilliant implications for the rest of the setting. There was not just one collapse; there were two. The Ancestor civilization, presumed to be the first human civilization, has passed into myth, quite literally when it comes to the stories around its downfall in the aftermath of a war against AIs. After the Ancestors came the Successors, who followed a similar salvage and rebuild approach and got as far as inventing their own warp drive technology that was based on but different than the Ancestor technology. Then they also collapsed, leaving their adapted technology and salvage operations layered over Ancestor sites. Cassilde's civilization is the third human starfaring civilization, and it is very specifically the third, neither the second nor one of dozens. This has so many small but effective implications that improve this story. A fall happened twice, so it feels like a pattern that makes Cassilde's civilization paranoid, but it happened for two very different reasons, so there is room to argue against it being a pattern. Salvage is harder because of the layering of Ancestor and Successor activity. Successors had their own way of controlling technology that is not accessible to Cassilde and her crew but is also not how the technology was intended to be used, which sends small ripples of interesting complexity through the background. And salvors are competing not only against each other but also against Successor salvage operations for which they have fragmentary records. It's a beautifully effective touch. Melissa Scott has been publishing science fiction for forty years, and it shows in this book. The protagonists are older characters: established professionals with resource problems but also social connections and an earned reputation, people who are trying to do a job and live their lives, not change the world. The writing is competent, deft, and atmospheric, with the confidence of long practice, but it also has the feel of an earlier era of science fiction. I mentioned the cyberpunk influence, which shows in the grittiness of the descriptions, the marginality of the characters in society, and the background theme of repurposing and reusing technology in unintended ways. This is the sort of book that feels solidly in the center of science fiction, without the genre mixing into either fantasy or romance that has become somewhat more common, and also without the dramatics of space opera (although the reader discovers that the stakes of this novel may be higher than anyone realized). And yet, so much of this book is about navigating a complicated romantic relationship, and that's where the story structure felt a bit odd. Cassilde, Dai, and Ashe were a polyamorous triad (polyamory also shows up in Scott's excellent Roads of Heaven series), and much of the first third of the book deals with the fracturing of trust with Ashe and their renegotiation of that relationship given his return. This is refreshingly written as the thoughtful interaction of three adults who take issues of trust seriously, but that also means it's much less dramatic than it sounds, and that means this book starts exceptionally slow. Scott is going somewhere, and the slow build became engrossing around the midpoint of the book, but I had to fight to stick with it at the start. About 80% of the way through this book, I had no idea how Scott was going to wrap things up in the pages remaining and was bracing myself for some sort of series cliffhanger. This is not what happens; the plot is not fully resolved in every detail, but it reaches a conclusion of sorts that does not mandate a sequel. I did think the end was a little bit unsatisfying, though, and I want another book that explores the implications of the ending. I think it would have to be a much different book, and the tonal shift might be stark. I've had this book on my to-read list for a while and kept putting it off because I wasn't sure I was in the mood for something precarious and gritty. This turned out to be an accurate worry: this is literally a book about salvaging the pieces of something full of wonders inextricably connected to dangers. You have to be in a cyberpunk sort of mood. But I've never read a bad Melissa Scott book, and this is no exception. The simplicity and ALL-CAPSNESS of the Ancestral elements grated a bit, but apart from that, the world-building is exceptional and well worth the trip. Recommended, although be warned that, if you're like me, it may not grab you from the first page. Followed by Fallen, but that book is a prequel that does not share any protagonists. Content notes: disability and degenerative illness in a universe where magical cures are possible, so be warned if that specific thematic combination is not what you're looking for. Rating: 7 out of 10

13 December 2024

Emanuele Rocca: Murder Mystery: GCC Builds Failing After sbuild Refactoring

This is the story of an investigation conducted by Jochen Sprickerhof, Helmut Grohne, and myself. It was true teamwork, and we would have not reached the bottom of the issue working individually. We think you will find it as interesting and fun as we did, so here is a brief writeup. A few of the steps mentioned here took several days, others just a few minutes. What is described as a natural progression of events did not always look very obvious at the moment at all.
Let us go through the Six Stages of Debugging together.

Stage 1: That cannot happen
Official Debian GCC builds start failing on multiple architectures in late November.
The build error happens on the build servers when running the testuite, but we know this cannot happen. GCC builds are not meant to fail in case of testsuite failures! Return codes are not making the build fail, make is being called with -k, it just cannot happen.
A lot of the GCC tests are always failing in fact, and an extensive log of the results is posted to the debian-gcc mailing list, but the packages always build fine regardless.
On the build daemons, build failures take several hours.

Stage 2: That does not happen on my machine
Building on my machine running Bookworm is just fine. The Build Daemons run Bookworm and use a Sid chroot for the build environment, just like I am. Same kernel.
The only obvious difference between my setup and the Debian buildds is that I am using sbuild 0.85.0 from bookworm, and the buildds have 0.86.3~bpo12+1 from bookworm-backports. Trying again with 0.86.3~bpo12+1, the build fails on my system too. The build daemons were updated to the bookworm-backports version of sbuild at some point in late November. Ha.

Stage 3: That should not happen
There are quite a few sbuild versions in between 0.85.0 and 0.86.3~bpo12+1, but looking at recent sbuild bugs shows that sbuild 0.86.0 was breaking "quite a number of packages". Indeed, with 0.86.0 the build still fails. Trying the version immediately before, 0.85.11, the build finishes correctly. This took more time than it sounds, one run including the tests takes several hours. We need a way to shorten this somehow.
The Debian packaging of GCC allows to specify which languages you may want to skip, and by default it builds Ada, Go, C, C++, D, Fortran, Objective C, Objective C++, M2, and Rust. When running the tests sequentially, the build logs stop roughly around the tests of a runtime library for D, libphobos. So can we still reproduce the failure by skipping everything except for D? With DEB_BUILD_OPTIONS=nolang=ada,go,c,c++,fortran,objc,obj-c++,m2,rust the build still fails, and it fails faster than before. Several minutes, not hours. This is progress, and time to file a bug. The report contains massive spoilers, so no link. :-)

Stage 4: Why does that happen?
Something is causing the build to end prematurely. It s not the OOM killer, and the kernel does not have anything useful to say in the logs. Can it be that the D language tests are sending signals to some process, and that is what s killing make ? We start tracing signals sent with bpftrace by writing the following script, signals.bt:
tracepoint:signal:signal_generate  
    printf("%s PID %d (%s) sent signal %d to PID %d\n", comm, pid, args->sig, args->pid);
 
And executing it with sudo bpftrace signals.bt.
The build takes its sweet time, and it fails. Looking at the trace output there s a suspicious process.exe terminating stuff.
process.exe (PID: 2868133) sent signal 15 to PID 711826
That looks interesting, but we have no clue what PID 711826 may be. Let s change the script a bit, and trace signals received as well.
tracepoint:signal:signal_generate  
    printf("PID %d (%s) sent signal %d to %d\n", pid, comm, args->sig, args->pid);
 
tracepoint:signal:signal_deliver  
    printf("PID %d (%s) received signal %d\n", pid, comm, args->sig);
 
The working version of sbuild was using dumb-init, whereas the new one features a little init in perl. We patch the current version of sbuild by making it use dumb-init instead, and trace two builds: one with the perl init, one with dumb-init.
Here are the signals observed when building with dumb-init.
PID 3590011 (process.exe) sent signal 2 to 3590014
PID 3590014 (sleep) received signal 9
PID 3590011 (process.exe) sent signal 15 to 3590063
PID 3590063 (std.process tem) received signal 9
PID 3590011 (process.exe) sent signal 9 to 3590065
PID 3590065 (std.process tem) received signal 9
And this is what happens with the new init in perl:
PID 3589274 (process.exe) sent signal 2 to 3589291
PID 3589291 (sleep) received signal 9
PID 3589274 (process.exe) sent signal 15 to 3589338
PID 3589338 (std.process tem) received signal 9
PID 3589274 (process.exe) sent signal 9 to 3589340
PID 3589340 (std.process tem) received signal 9
PID 3589274 (process.exe) sent signal 15 to 3589341
PID 3589274 (process.exe) sent signal 15 to 3589323
PID 3589274 (process.exe) sent signal 15 to 3589320
PID 3589274 (process.exe) sent signal 15 to 3589274
PID 3589274 (process.exe) received signal 9
PID 3589341 (sleep) received signal 9
PID 3589273 (sbuild-usernsex) sent signal 9 to 3589320
PID 3589273 (sbuild-usernsex) sent signal 9 to 3589323
There are a few additional SIGTERM being sent when using the perl init, that s helpful. At this point we are fairly convinced that process.exe is worth additional inspection. The source code of process.d shows something interesting:
1221 @system unittest
1222  
[...]
1247     auto pid = spawnProcess(["sleep", "10000"],
[...]
1260     // kill the spawned process with SIGINT
1261     // and send its return code
1262     spawn((shared Pid pid)  
1263         auto p = cast() pid;
1264         kill(p, SIGINT);
So yes, there s our sleep and the SIGINT (signal 2) right in the unit tests of process.d, just like we have observed in the bpftrace output.
Can we study the behavior of process.exe in isolation, separatedly from the build? Indeed we can. Let s take the executable from a failed build, and try running it under /usr/libexec/sbuild-usernsexec.
First, we prepare a chroot inside a suitable user namespace:
unshare --map-auto --setuid 0 --setgid 0 mkdir /tmp/rootfs
cd /tmp/rootfs
cat /home/ema/.cache/sbuild/unstable-arm64.tar   unshare --map-auto --setuid 0 --setgid 0 tar xf  -
unshare --map-auto --setuid 0 --setgid 0 mkdir /tmp/rootfs/whatever
unshare --map-auto --setuid 0 --setgid 0 cp process.exe /tmp/rootfs/
Now we can run process.exe on its own using the perl init, and trace signals at will:
/usr/libexec/sbuild-usernsexec --pivotroot --nonet u:0:100000:65536  g:0:100000:65536 /tmp/rootfs ema /whatever -- /process.exe
We can compare the behavior of the perl init vis-a-vis the one using dumb-init in milliseconds instead of minutes.

Stage 5: Oh, I see.
Why does process.exe send more SIGTERMs when using the perl init is now the big question. We have a simple reproducer, so this is where using strace becomes possible.
sudo strace --user ema --follow-forks -o sbuild-dumb-init.strace ./sbuild-usernsexec-dumb-init --pivotroot --nonet u:0:100000:65536  g:0:100000:65536 /tmp/dumbroot ema /whatever -- /process.exe
We start comparing the strace output of dumb-init with that of perl-init, looking in particular for different calls to kill.
Here is what process.exe does under dumb-init:
3593883 kill(-2, SIGTERM)               = -1 ESRCH (No such process)
No such process. Under perl-init instead:
3593777 kill(-2, SIGTERM <unfinished ...>
The process is there under perl-init!
That is a kill with negative pid. From the kill(2) man page:
If pid is less than -1, then sig is sent to every process in the process group whose ID is -pid.
It would have been very useful to see this kill with negative pid in the output of bpftrace, why didn t we? The tracepoint used, tracepoint:signal:signal_generate, shows when signals are actually being sent, and not the syscall being called. To confirm, one can trace tracepoint:syscalls:sys_enter_kill and see the negative PIDs, for example:
PID 312719 (bash) sent signal 2 to -312728
The obvious question at this point is: why is there no process group 2 when using dumb-init?

Stage 6: How did that ever work?
We know that process.exe sends a SIGTERM to every process in the process group with ID 2. To find out what this process group may be, we spawn a shell with dumb-init and observe under /proc PIDs 1, 16, and 17. With perl-init we have 1, 2, and 17. When running dumb-init, there are a few forks before launching the program, explaining the difference. Looking at /proc/2/cmdline we see that it s bash, ie. the program we are running under perl-init. When building a package, that is dpkg-buildpackage itself.
The test is accidentally killing its own process group.
Now where does this -2 come from in the test?
2363     // Special values for _processID.
2364     enum invalid = -1, terminated = -2;
Oh. -2 is used as a special value for PID, meaning "terminated". And there s a call to kill() later on:
2694     do   s = tryWait(pid);   while (!s.terminated);
[...]
2697     assertThrown!ProcessException(kill(pid));
What sets pid to terminated you ask?
Here is tryWait:
2568 auto tryWait(Pid pid) @safe
2569  
2570     import std.typecons : Tuple;
2571     assert(pid !is null, "Called tryWait on a null Pid.");
2572     auto code = pid.performWait(false);
And performWait:
2306         _processID = terminated;
The solution, dear reader, is not to kill.
PS: the bug report with spoilers for those interested is #1089007.

Freexian Collaborators: Monthly report about Debian Long Term Support, November 2024 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In November, 20 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 14.0h (out of 6.0h assigned and 8.0h from previous period).
  • Adrian Bunk did 53.0h (out of 15.0h assigned and 85.0h from previous period), thus carrying over 47.0h to the next month.
  • Andrej Shadura did 7.0h (out of 7.0h assigned).
  • Arturo Borrero Gonzalez did 1.0h (out of 10.0h assigned), thus carrying over 9.0h to the next month.
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 0.0h (out of 24.0h assigned), thus carrying over 24.0h to the next month.
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 17.0h (out of 26.0h assigned), thus carrying over 9.0h to the next month.
  • Emilio Pozuelo Monfort did 40.5h (out of 60.0h assigned), thus carrying over 19.5h to the next month.
  • Guilhem Moulin did 7.25h (out of 7.5h assigned and 12.5h from previous period), thus carrying over 12.75h to the next month.
  • Jochen Sprickerhof did 3.5h (out of 10.0h assigned), thus carrying over 6.5h to the next month.
  • Lee Garrett did 14.75h (out of 15.25h assigned and 44.75h from previous period), thus carrying over 45.25h to the next month.
  • Lucas Kanashiro did 10.0h (out of 54.0h assigned and 10.0h from previous period), thus carrying over 54.0h to the next month.
  • Markus Koschany did 20.0h (out of 40.0h assigned), thus carrying over 20.0h to the next month.
  • Roberto C. S nchez did 6.75h (out of 9.75h assigned and 14.25h from previous period), thus carrying over 17.25h to the next month.
  • Santiago Ruano Rinc n did 24.75h (out of 23.5h assigned and 1.5h from previous period), thus carrying over 0.25h to the next month.
  • Sean Whitton did 2.0h (out of 6.0h assigned), thus carrying over 4.0h to the next month.
  • Sylvain Beucler did 21.5h (out of 9.5h assigned and 50.5h from previous period), thus carrying over 38.5h to the next month.
  • Thorsten Alteholz did 11.0h (out of 11.0h assigned).
  • Tobias Frost did 12.0h (out of 10.5h assigned and 1.5h from previous period).

Evolution of the situation In November, we have released 38 DLAs. The LTS coordinators, Roberto and Santiago, delivered a talk at the Mini-DebConf event in Toulouse, France. The title of the talk was How LTS goes beyond LTS . The talk covered work done by the LTS Team during the past year. This included contributions related to individual packages in Debian (such as tomcat, jetty, radius, samba, apache2, ruby, and many others); improvements to tooling and documentation useful to the Debian project as a whole; and contributions to upstream work (apache2, freeimage, node-dompurify, samba, and more). Additionally, several contributors external to the LTS Team were highlighted for their contributions to LTS. Readers are encouraged to watch the video of the presentation for a more detailed review of various ways in which the LTS team has contributed more broadly to the Debian project and to the free software community during the past year. We wish to specifically thank Salvatore (of the Debian Security Team) for swiftly handling during November the updates of needrestart and libmodule-scandeps-perl, both of which involved arbitrary code execution vulnerabilities. We are happy to see increased involvement in LTS work by contributors from outside the formal LTS Team. The work of the LTS Team in November was otherwise unremarkable, encompassing the customary triage, development, testing, and release of numerous DLAs, along with some associated contributions to related packages in stable and unstable.

Thanks to our sponsors Sponsors that joined recently are in bold.

12 December 2024

Dirk Eddelbuettel: #44: r2u For ML and MLops Talk

Welcome to the 44th post in the $R^4 series. A few weeks ago, and following an informal call for talks by James Lamb, I had an opportunity to talk about r2u to the Chicago ML and MLops meetup groups. You can find the slides here. Over the last 2 1/2 years, r2u has become a widely-deployed mechanism in a number of settings, including (but not limited to) software testing via continuous integration, deployment on cloud servers besides of course to more standard use on local laptops or workstation. 30 million downloads illustrate this. My thesis for the talk was that this extends equally to ML(ops) where no surprises, no hickups automated deployments are key for large-scale model training, evaluation and of course production deployments. In this context, I introduce r2u while giving credit both to what came before it, the existing alternatives (or competitors for mindshare if one prefers that phrasing), and of course what lies underneath it. The central takeaway, I argue, is that r2u can and does take advantage of a unique situation in that we can join the package manager task for the underlying (operating) system and and the application domain, here R and its unique CRAN repository network. Other approaches can, and of course do, provide binaries, but by doing this outside the realm of the system package manager can only arrive at a lesser integration (and I show a common error arising in that case). So where r2u is feasible, it dominates the alternatives (while the alternatives may well provide deployment on more platforms which, even when less integrated, may be of greater importance for some). As always, it all depends. But the talk, and its slides, motivate and illustrate why we keep calling r2u by its slogan of r2u: Fast. Easy. Reliable. Pick All Three.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub. Please report excessive re-aggregation in third-party for-profit settings.

Matthew Garrett: When should we require that firmware be free?

The distinction between hardware and software has historically been relatively easy to understand - hardware is the physical object that software runs on. This is made more complicated by the existence of programmable logic like FPGAs, but by and large things tend to fall into fairly neat categories if we're drawing that distinction.
Conversations usually become more complicated when we introduce firmware, but should they? According to Wikipedia, Firmware is software that provides low-level control of computing device hardware, and basically anything that's generally described as firmware certainly fits into the "software" side of the above hardware/software binary. From a software freedom perspective, this seems like something where the obvious answer to "Should this be free" is "yes", but it's worth thinking about why the answer is yes - the goal of free software isn't freedom for freedom's sake, but because the freedoms embodied in the Free Software Definition (and by proxy the DFSG) are grounded in real world practicalities.

How do these line up for firmware? Firmware can fit into two main classes - it can be something that's responsible for initialisation of the hardware (such as, historically, BIOS, which is involved in initialisation and boot and then largely irrelevant for runtime[1]) or it can be something that makes the hardware work at runtime (wifi card firmware being an obvious example). The role of free software in the latter case feels fairly intuitive, since the interface and functionality the hardware offers to the operating system is frequently largely defined by the firmware running on it. Your wifi chipset is, these days, largely a software defined radio, and what you can do with it is determined by what the firmware it's running allows you to do. Sometimes those restrictions may be required by law, but other times they're simply because the people writing the firmware aren't interested in supporting a feature - they may see no reason to allow raw radio packets to be provided to the OS, for instance. We also shouldn't ignore the fact that sufficiently complicated firmware exposed to untrusted input (as is the case in most wifi scenarios) may contain exploitable vulnerabilities allowing attackers to gain arbitrary code execution on the wifi chipset - and potentially use that as a way to gain control of the host OS (see this writeup for an example). Vendors being in a unique position to update that firmware means users may never receive security updates, leaving them with a choice between discarding hardware that otherwise works perfectly or leaving themselves vulnerable to known security issues.

But even the cases where firmware does nothing other than initialise the hardware cause problems. A lot of hardware has functionality controlled by registers that can be locked during the boot process. Vendor firmware may choose to disable (or, rather, never to enable) functionality that may be beneficial to a user, and then lock out the ability to reconfigure the hardware later. Without any ability to modify that firmware, the user lacks the freedom to choose what functionality their hardware makes available to them. Again, the ability to inspect this firmware and modify it has a distinct benefit to the user.

So, from a practical perspective, I think there's a strong argument that users would benefit from most (if not all) firmware being free software, and I don't think that's an especially controversial argument. So I think this is less of a philosophical discussion, and more of a strategic one - is spending time focused on ensuring firmware is free worthwhile, and if so what's an appropriate way of achieving this?

I think there's two consistent ways to view this. One is to view free firmware as desirable but not necessary. This approach basically argues that code that's running on hardware that isn't the main CPU would benefit from being free, in the same way that code running on a remote network service would benefit from being free, but that this is much less important than ensuring that all the code running in the context of the OS on the primary CPU is free. The maximalist position is not to compromise at all - all software on a system, whether it's running at boot or during runtime, and whether it's running on the primary CPU or any other component on the board, should be free.

Personally, I lean towards the former and think there's a reasonably coherent argument here. I think users would benefit from the ability to modify the code running on hardware that their OS talks to, in the same way that I think users would benefit from the ability to modify the code running on hardware the other side of a network link that their browser talks to. I also think that there's enough that remains to be done in terms of what's running on the host CPU that it's not worth having that fight yet. But I think the latter is absolutely intellectually consistent, and while I don't agree with it from a pragmatic perspective I think things would undeniably be better if we lived in that world.

This feels like a thing you'd expect the Free Software Foundation to have opinions on, and it does! There are two primarily relevant things - the Respects your Freedoms campaign focused on ensuring that certified hardware meets certain requirements (including around firmware), and the Free System Distribution Guidelines, which define a baseline for an OS to be considered free by the FSF (including requirements around firmware).

RYF requires that all software on a piece of hardware be free other than under one specific set of circumstances. If software runs on (a) a secondary processor and (b) within which software installation is not intended after the user obtains the product, then the software does not need to be free. (b) effectively means that the firmware has to be in ROM, since any runtime interface that allows the firmware to be loaded or updated is intended to allow software installation after the user obtains the product.

The Free System Distribution Guidelines require that all non-free firmware be removed from the OS before it can be considered free. The recommended mechanism to achieve this is via linux-libre, a project that produces tooling to remove anything that looks plausibly like a non-free firmware blob from the Linux source code, along with any incitement to the user to load firmware - including even removing suggestions to update CPU microcode in order to mitigate CPU vulnerabilities.

For hardware that requires non-free firmware to be loaded at runtime in order to work, linux-libre doesn't do anything to work around this - the hardware will simply not work. In this respect, linux-libre reduces the amount of non-free firmware running on a system in the same way that removing the hardware would. This presumably encourages users to purchase RYF compliant hardware.

But does that actually improve things? RYF doesn't require that a piece of hardware have no non-free firmware, it simply requires that any non-free firmware be hidden from the user. CPU microcode is an instructive example here. At the time of writing, every laptop listed here has an Intel CPU. Every Intel CPU has microcode in ROM, typically an early revision that is known to have many bugs. The expectation is that this microcode is updated in the field by either the firmware or the OS at boot time - the updated version is loaded into RAM on the CPU, and vanishes if power is cut. The combination of RYF and linux-libre doesn't reduce the amount of non-free code running inside the CPU, it just means that the user (a) is more likely to hit since-fixed bugs (including security ones!), and (b) has less guidance on how to avoid them.

As long as RYF permits hardware that makes use of non-free firmware I think it hurts more than it helps. In many cases users aren't guided away from non-free firmware - instead it's hidden away from them, leaving them less aware that their freedom is constrained. Linux-libre goes further, refusing to even inform the user that the non-free firmware that their hardware depends on can be upgraded to improve their security.

Out of sight shouldn't mean out of mind. If non-free firmware is a threat to user freedom then allowing it to exist in ROM doesn't do anything to solve that problem. And if it isn't a threat to user freedom, then what's the point of requiring linux-libre for a Linux distribution to be considered free by the FSF? We seem to have ended up in the worst case scenario, where nothing is being done to actually replace any of the non-free firmware running on people's systems and where users may even end up with a reduced awareness that the non-free firmware even exists.

[1] Yes yes SMM

comment count unavailable comments

10 December 2024

Stephan Lachnit: Creating a bootable USB stick that can still be used as normal storage

As someone who daily drives rolling release operating systems, having a bootable USB stick with a live install of Debian is essential. It has saved reverting broken packages and making my device bootable again at least a couple of times. However, creating a bootable USB stick usually uses the entire storage of the USB stick, which seems unnecessary given that USB sticks easily have 64GiB or more these days while live ISOs still don t use more than 8GiB. In this how-to, I will explain how to create a bootable USB stick, that also holds a FAT32 partition, which allows the USB stick used as usual.

Creating the partition partble The first step is to create the partition table on the new drive. There are several tools to do this, I recommend the ArchWiki page on this topic for details. For best compatibility, MBR should be used instead of the more modern GPT. For simplicity I just went with the GParted since it has an easy GUI, but feel free to use any other tool. The layout should look like this:
Type    Partition   Suggested size
 
EFI     /dev/sda1             8GiB
FAT32   /dev/sda2        remainder
Notes:
  • The disk names are just an example and have to be adjusted for your system.
  • Don t set disk labels, they don t appear on the new install anyway and some UEFIs might not like it on your boot partition.
  • If you used GParted, create the EFI partition as FAT32 and set the esp flag.

Mounting the ISO and USB stick The next step is to download your ISO and mount it. I personally use a Debian Live ISO for this. To mount the ISO, use the loop mounting option:
mkdir -p /tmp/mnt/iso
sudo mount -o loop /path/to/image.iso /tmp/mnt/iso
Similarily, mount your USB stick:
mkdir -p /tmp/mnt/usb
sudo mount /dev/sda1 /tmp/mnt/usb

Copy the ISO contents To copy the contents from the ISO to the USB stick, use this command:
sudo cp -r -L /tmp/mnt/iso/. /tmp/mnt/usb
The -L option is required to deference the symbolic links present in the ISO, since FAT32 does not support symbolic links. Note that you might get warning about cyclic symbolic links. Nothing can be done to fix those, except hoping that they won t cause a problem. For me this never was a problem though.

Finishing touches Umnount the ISO and USB stick:
sudo umount /tmp/mnt/usb
sudo umount /tmp/mnt/iso
Now the USB stick should be bootable and have a usable data partition that can be used on essentially every operating system. I recommend testing that the stick is bootable to make sure it actually works in case of an emergency.

Russ Allbery: 2024 book haul

I haven't made one of these posts since... last year? Good lord. I've therefore already read and reviewed a lot of these books. Kemi Ashing-Giwa The Splinter in the Sky (sff)
Moniquill Blackgoose To Shape a Dragon's Breath (sff)
Ashley Herring Blake Delilah Green Doesn't Care (romance)
Ashley Herring Blake Astrid Parker Doesn't Fail (romance)
Ashley Herring Blake Iris Kelly Doesn't Date (romance)
Molly J. Bragg Scatter (sff)
Sarah Rees Breenan Long Live Evil (sff)
Michelle Browne And the Stars Will Sing (sff)
Steven Brust Lyorn (sff)
Miles Cameron Beyond the Fringe (sff)
Miles Cameron Deep Black (sff)
Haley Cass Those Who Wait (romance)
Sylvie Cathrall A Letter to the Luminous Deep (sff)
Ta-Nehisi Coates The Message (non-fiction)
Julie E. Czerneda To Each This World (sff)
Brigid Delaney Reasons Not to Worry (non-fiction)
Mar Delaney Moose Madness (sff)
Jerusalem Demsas On the Housing Crisis (non-fiction)
Michelle Diener Dark Horse (sff)
Michelle Diener Dark Deeds (sff)
Michelle Diener Dark Minds (sff)
Michelle Diener Dark Matters (sff)
Elaine Gallagher Unexploded Remnants (sff)
Bethany Jacobs These Burning Stars (sff)
Bethany Jacobs On Vicious Worlds (sff)
Micaiah Johnson Those Beyond the Wall (sff)
T. Kingfisher Paladin's Faith (sff)
T.J. Klune Somewhere Beyond the Sea (sff)
Mark Lawrence The Book That Wouldn't Burn (sff)
Mark Lawrence The Book That Broke the World (sff)
Mark Lawrence Overdue (sff)
Mark Lawrence Returns (sff collection)
Malinda Lo Last Night at the Telegraph Club (historical)
Jessie Mihalik Hunt the Stars (sff)
Samantha Mills The Wings Upon Her Back (sff)
Lyda Morehouse Welcome to Boy.net (sff)
Cal Newport Slow Productivity (non-fiction)
Naomi Novik Buried Deep and Other Stories (sff collection)
Claire O'Dell The Hound of Justice (sff)
Keanu Reeves & China Mi ville The Book of Elsewhere (sff)
Kit Rocha Beyond Temptation (sff)
Kit Rocha Beyond Jealousy (sff)
Kit Rocha Beyond Solitude (sff)
Kit Rocha Beyond Addiction (sff)
Kit Rocha Beyond Possession (sff)
Kit Rocha Beyond Innocence (sff)
Kit Rocha Beyond Ruin (sff)
Kit Rocha Beyond Ecstasy (sff)
Kit Rocha Beyond Surrender (sff)
Kit Rocha Consort of Fire (sff)
Geoff Ryman HIM (sff)
Melissa Scott Finders (sff)
Rob Wilkins Terry Pratchett: A Life with Footnotes (non-fiction)
Gabrielle Zevin Tomorrow, and Tomorrow, and Tomorrow (mainstream)
That's a lot of books, although I think I've already read maybe a third of them? Which is better than I usually do.

9 December 2024

Gunnar Wolf: Some tips for those who still administer Drupal7-based sites

A bit of history: Drupal at my workplace (and in Debian) My main day-to-day responsibility in my workplace is, and has been for 20 years, to take care of the network infrastructure for UNAM s Economics Research Institute. One of the most visible parts of this responsibility is to ensure we have a working Web presence, and that it caters for the needs of our academic community. I joined the Institute in January 2005. Back then, our designer pushed static versions of our webpage, completely built in her computer. This was standard practice at the time, and lasted through some redesigns, but I soon started advocating for the adoption of a Content Management System. After evaluating some alternatives, I recommended adopting Drupal. It took us quite a bit to do the change: even though I clearly recall starting work toward adopting it as early as 2006, according to the Internet Archive, we switched to a Drupal-backed site around June 2010. We started using it somewhere in the version 6 s lifecycle. As for my Debian work, by late 2012 I started getting involved in the maintenance of the drupal7 package, and by April 2013 I became its primary maintainer. I kept the drupal7 package up to date in Debian until 2018; the supported build methods for Drupal 8 are not compatible with Debian (mainly, bundling third-party libraries and updating them without coordination with the rest of the ecosystem), so towards the end of 2016, I announced I would not package Drupal 8 for Debian. By March 2016, we migrated our main page to Drupal 7. By then, we already had several other sites for our academics projects, but my narrative follows our main Web site. I did manage to migrate several Drupal 6 (D6) sites to Drupal 7 (D7); it was quite involved process, never transparent to the user, and we did have the backlash of long downtimes (or partial downtimes, with sites half-available only) with many of our users. For our main site, we took the opportunity to do a complete redesign and deployed a fully new site. You might note that March 2016 is after the release of D8 (November 2015). I don t recall many of the specifics for this decision, but if I m not mistaken, building the new site was a several months long process not only for the technical work of setting it up, but for the legwork of getting all of the needed information from the different areas that need to be represented in the Institute. Not only that: Drupal sites often include tens of contributed themes and modules; the technological shift the project underwent between its 7 and 8 releases was too deep, and modules took a long time (if at all many themes and modules were outright dumped) to become available for the new release. Naturally, the Drupal Foundation wanted to evolve and deprecate the old codebase. But the pain to migrate from D7 to D8 is too big, and many sites have remained under version 7 Eight years after D8 s release, almost 40% of Drupal installs are for version 7, and a similar proportion runs a currently-supported release (10 or 11). And while the Drupal Foundation made a great job at providing very-long-term support for D7, I understand the burden is becoming too much, so close to a year ago (and after pushing several times the D7, they finally announced support will finish this upcoming January 5.

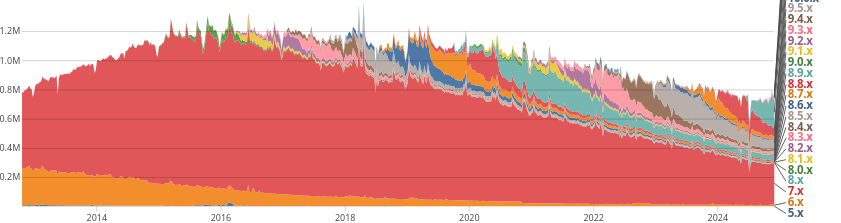
Drupal 7 must go! I found the following usage graphs quite interesting: the usage statistics for all Drupal versions follows a very positive slope, peaking around 2014 during the best years of D7, and somewhat stagnating afterwards, staying since 2015 at the 25000 28000 sites mark (I m very tempted to copy the graphs, but builtwith s terms of use are very clear in not allowing it). There is a sharp drop in the last year I attribute it to the people that are leaving D7 for other technologies after its end-of-life announcement. This becomes clearer looking only at D7 s usage statistics: D7 peaks at 15000 installs in 2016 stays there for close to 5 years, and has a sharp drop to under 7500 sites in the span of one year. D8 has a more regular rise, peak and fall peaking at ~8500 between 2020 and 2021, and down to close to 2500 for some months already; D9 has a very brief peak of almost 9000 sites in 2023 and is now close to half of it. Currently, the Drupal king appears to be D10, still on a positive slope and with over 9000 sites. Drupal 11 is still just a blip in builtwith s radar, with 3 registered sites as of September 2024 :- After writing this last paragraph, I came across the statistics found in the Drupal webpage; the methodology for acquiring its data is completely different: while builtwith s methodology is their trade secret, you can read more about how Drupal s data is gathered (and agree or disagree with it , but at least you have a page detailing 12 years so far of reported data, producing the following graph (which can be shared under the CC BY-SA license ): Drupal usage statistics by version 2013 2024 This graph is disgregated into minor versions, and I don t want to come up with yet another graph for it but it supports (most of) the narrative I presented above although I do miss the recent drop builtwith reported in D7 s numbers!

And what about Backdrop? During the D8 release cycle, a group of Drupal developers were not happy with the depth of the architectural changes that were being adopted, particularly the transition to the Symfony PHP component framework, and forked the D7 codebase to create the Backdrop CMS, a modern version of Drupal, without dropping the known and tested architecture it had. The Backdrop developers keep working closely together with the Drupal community, and although its usage numbers are way smaller than Drupal s, seems to be sustainable and lively. Of course, as I presented their numbers in the previous section, you can see Backdrop s numbers in builtwith are way, way lower. I have found it to be a very warm and welcoming community, eager to receive new members. And, thanks to its contributed D2B Migrate module, I found it is quite easy to migrate a live site from Drupal 7 to Backdrop.

Migration by playbook! So Well, I m an academic. And (if it s not obvious to you after reading so far ), one of the things I must do in my job is to write. So I decided to write an article to invite my colleagues to consider Backdrop for their D7 sites in Cuadernos T cnicos Universitarios de la DGTIC, a young journal in our university for showcasing technical academical work. And now that my article got accepted and published, I m happy to share it with you of course, if you can read Spanish But anyway Given I have several sites to migrate, and that I m trying to get my colleagues to follow suite, I decided to automatize the migration by writing an Ansible playbook to do the heavy lifting. Of course, the playbook s users will probably need to tweak it a bit to their personal needs. I m also far from an Ansible expert, so I m sure there is ample room fo improvement in my style. But it works. Quite well, I must add.

But with this size of database I did stumble across a big pebble, though. I am working on the migration of one of my users sites, and found that its database is huge. I checked the mysqldump output, and it got me close to 3GB of data. And given the D2B_migrate is meant to work via a Web interface (my playbook works around it by using a client I wrote with Perl s WWW::Mechanize), I repeatedly stumbled with PHP s maximum POST size, maximum upload size, maximum memory size I asked for help in Backdrop s Zulip chat site, and my attention was taken off fixing PHP to something more obvious: Why is the database so large? So I took a quick look at the database (or rather: my first look was at the database server s filesystem usage). MariaDB stores each table as a separate file on disk, so I looked for the nine largest tables:
# ls -lhS head
total 3.8G
-rw-rw---- 1 mysql mysql 2.4G Dec 10 12:09 accesslog.ibd
-rw-rw---- 1 mysql mysql 224M Dec  2 16:43 search_index.ibd
-rw-rw---- 1 mysql mysql 220M Dec 10 12:09 watchdog.ibd
-rw-rw---- 1 mysql mysql 148M Dec  6 14:45 cache_field.ibd
-rw-rw---- 1 mysql mysql  92M Dec  9 05:08 aggregator_item.ibd
-rw-rw---- 1 mysql mysql  80M Dec 10 12:15 cache_path.ibd
-rw-rw---- 1 mysql mysql  72M Dec  2 16:39 search_dataset.ibd
-rw-rw---- 1 mysql mysql  68M Dec  2 13:16 field_revision_field_idea_principal_articulo.ibd
-rw-rw---- 1 mysql mysql  60M Dec  9 13:19 cache_menu.ibd
A single table, the access log, is over 2.4GB long. The three following tables are, cache tables. I can perfectly live without their data in our new site! But I don t want to touch the slightest bit of this site until I m satisfied with the migration process, so I found a way to exclude those tables in a non-destructive way: given D2B_migrate works with a mysqldump output, and given that mysqldump locks each table before starting to modify it and unlocks it after its job is done, I can just do the following:
$ perl -e '$output = 1; while (<>)   $output=0 if /^LOCK TABLES  (accesslog search_index watchdog cache_field cache_path) /; $output=1 if /^UNLOCK TABLES/; print if $output ' < /tmp/d7_backup.sql  > /tmp/d7_backup.eviscerated.sql; ls -hl /tmp/d7_backup.sql /tmp/d7_backup.eviscerated.sql
-rw-rw-r-- 1 gwolf gwolf 216M Dec 10 12:22 /tmp/d7_backup.eviscerated.sql
-rw------- 1 gwolf gwolf 2.1G Dec  6 18:14 /tmp/d7_backup.sql
Five seconds later, I m done! The database is now a tenth of its size, and D2B_migrate is happy to take it. And I m a big step closer to finishing my reliance on (this bit of) legacy code for my highly-visible sites

Freexian Collaborators: Debian Contributions: OpenMPI transitions, cPython 3.12.7+ update uploads, Python 3.13 Transition, and more! (by Anupa Ann Joseph, Stefano Rivera)

Debian Contributions: 2024-11 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Transition management, by Emilio Pozuelo Monfort Emilio has been helping finish the mpi-defaults switch to mpich on 32-bit architectures, and the openmpi transitions. This involves filing bugs for the reverse dependencies, doing NMUs, and requesting removals for outdated (Not Built from Source) binaries on 32-bit architectures where openmpi is no longer available. Those transitions got entangled with a few others, such as the petsc stack, and were blocking many packages from migrating to testing. These transitions were completed in early December.

cPython 3.12.7+ update uploads, by Stefano Rivera Python 3.12 had failed to build on mips64el, due to an obscure dh_strip failure. The mips64el porters never figured it out, but the missing build on mips64el was blocking migration to Debian testing. After waiting a month, enough changes had accumulated in the upstream 3.12 maintenance git branch that we could apply them in the hope of changing the output enough to avoid breaking dh_strip. This worked. Of course there were other things to deal with too. A test started failing due to a Debian-specific patch we carry for python3.x-minimal, and it needed to be reworked. And Stefano forgot to strip the trailing + from PY_VERSION, which confuses some python libraries. This always requires another patch when applying git updates from the maintenance branch. Stefano added a build-time check to catch this mistake in the future. Python 3.12.7 migrated.

Python 3.13 Transition, by Stefano Rivera and Colin Watson During November the Python 3.13-add transition started. This is the first stage of supporting a new version of Python in Debian archive (after preparatory work), adding it as a new supported but non-default version. All packages with compiled Python extensions need to be re-built to add support for the new version. We have covered the lead-up to this transition in the past. Due to preparation, many of the failures we hit were expected and we had patches waiting in the bug tracker. These could be NMUed to get the transition moving. Others had been known about but hadn t been worked on, yet. Some other packages ran into new issues, as we got further into the transition than we d been able to in preparation. The whole Debian Python team has been helping with this work. The rebuild stage of the 3.13-add transition is now over, but many packages need work before britney will let python3-defaults migrate to testing.

Limiting build concurrency based on available RAM, by Helmut Grohne In recent years, the concurrency of CPUs has been increasing as has the demand for RAM by linkers. What has not been increasing as quickly is the RAM supply in typical machines. As a result, we more frequently run into situations where the package builds exhaust memory when building at full concurrency. Helmut initiated a discussion about generalizing an approach to this in Debian packages. Researching existing code that limits concurrency as well as providing possible extensions to debhelper and dpkg to provide concurrency limits based on available system RAM. Thus far there is consensus on the need for a more general solution, but ideas are still being collected for the precise solution.

MiniDebConf Toulouse at Capitole du Libre The whole Freexian Collaborator team attended MiniDebConf Toulouse, part of the Capitole du Libre event. Several members of the team gave talks: Stefano and Anupa worked as part of the video team, streaming and recording the event s talks.

Miscellaneous contributions
  • Stefano looked into packaging the latest upstream python-falcon version in Debian, in support of the Python 3.13 transition. This appeared to break python-hug, which is sadly looking neglected upstream, and the best course of action is probably its removal from Debian.
  • Stefano uploaded videos from various 2024 Debian events to PeerTube and YouTube.
  • Stefano and Santiago visited the site for DebConf 2025 in Brest, after the MiniDebConf in Toulouse, to meet with the local team and scout out the venue. The on-going DebConf 25 organization work of last month also included handling the logo and artwork call for proposals.
  • Stefano helped the press team to edit a post for bits.debian.org on OpenStreetMap s migration to Debian.
  • Carles implemented multiple language support on po-debconf-manager and tested it using Portuguese-Brazilian during MiniDebConf Toulouse. The system was also tested and improved by reviewing more than 20 translations to Catalan, creating merge requests for those packages, and providing user support to new users. Additionally, Carles implemented better status transitions, configuration keys management and other small improvements.
  • Helmut sent 32 patches for cross build failures. The wireplumber one was an interactive collaboration with Dylan A ssi.
  • Helmut continued to monitor the /usr-move, sent a patch for lib64readline8 and continued several older patch conversations. lintian now reports some aliasing issues in unstable.
  • Helmut initiated a discussion on the semantics of *-for-host packages. More feedback is welcome.
  • Helmut improved the crossqa.debian.net infrastructure to fail running lintian less often in larger packages.
  • Helmut continued maintaining rebootstrap mostly dropping applied patches and continuing discussions of submitted patches.
  • Helmut prepared a non-maintainer upload of gzip for several long-standing bugs.
  • Colin came up with a plan for resolving the multipart vs. python-multipart name conflict, and began work on converting reverse-dependencies.
  • Colin upgraded 42 Python packages to new upstream versions. Some were complex: python-catalogue had some upstream version confusion, pydantic and rpds-py involved several Rust package upgrades as prerequisites, and python-urllib3 involved first packaging python-quart-trio and then vendoring an unpackaged test-dependency.
  • Colin contributed Incus support to needrestart upstream.
  • Lucas set up a machine to do a rebuild of all ruby reverse dependencies to check what will be broken by adding ruby 3.3 as an alternative interpreter. The tool used for this is mass-rebuild and the initial rebuilds have already started. The ruby interpreter maintainers are planning to experiment with debusine next time.
  • Lucas is organizing a Debian Ruby sprint towards the end of January in Paris. The plan of the team is to finish any missing bits of Ruby 3.3 transition at the time, try to push Rails 7 transition and fix RC bugs affecting the ruby ecosystem in Debian.
  • Anupa attended a Debian Publicity team meeting in-person during MiniDebCamp Toulouse.
  • Anupa moderated and posted in the Debian Administrator group in LinkedIn.

8 December 2024

Paulo Henrique de Lima Santana: Bits from MiniDebConf Toulouse 2024

Intro I always find it amazing the opportunities I have thanks to my contributions to the Debian Project. I am happy to receive this recognition through the help I receive with travel to attend events in other countries. This year, two MiniDebConfs were scheduled for the second half of the year in Europe: the traditional edition in Cambridge in UK and a new edition in Toulouse in France. After weighing the difficulties and advantages that I would have to attend one of them, I decided to choose Toulouse, mainly because it was cheaper and because it was in November, giving me more time to plan the trip. I contacted the current DPL Andreas Tille explaining my desire to attend the event and he kindly approved my request for Debian to pay for the tickets. Thanks again to Andreas! MiniDebConf Toulouse 2024 was held in November 16th and 17th (Saturday and Sunday) and took place in one of the rooms of a traditional Free Software event in the city named Capitole du Libre. Before MiniDebConf, the team organized a MiniDebCamp in November 14th and 15th at a coworking space. The whole experience promised to be incredible, and it was! From visiting a city in France for the first time, to attending a local Free Software event, and sharing four days with people from the Debian community from various countries.

Travel and the city My plan was to leave Belo Horizonte on Monday, pass through S o Paulo, and arrive in Toulouse on Tuesday night. I was going to spend the whole of Wednesday walking around the city and then participate in the MiniDebCamp on Thursday. But the flight that was supposed to leave S o Paulo in the early hours of Monday to Tuesday was cancelled due to a problem with the airplane and I had spent all Tuesday waiting. I was rebooked on another flight that left in the evening and arrived in Toulouse on Wednesday afternoon. Even though I was very tired from the trip, I still took advantage of the end of the day to walk around the city. But it was a shame to have lost an entire day of sightseeing. On Thursday I left early in the morning to walk around a little more before going to the MiniDebCamp venue. I walked around a lot and saw several tourist attractions. The city is really very beautiful, as they say, especially the houses and buildings made of pink bricks. I was impressed by the narrow and winding streets; at one point it seemed like I was walking through a maze. I arrived to a corner and there would be 5 streets crossing in different directions. The riverbank that runs through the city is very beautiful and people spend their evenings there just hanging out. There was a lot of history around there. I stayed in an airbnb 25 minutes walking from the coworking space and only 10 minutes from the event venue. It was a very spacious apartment that was much cheaper than a hotel. MiniDebConf Toulouse 2024

MiniDebConf Toulouse 2024

MiniDebCamp I arrived at the coworking space where the MiniDebCamp was being held and met up with several friends. I also met some new people, talked about the translation work we do in Brazil, and other topics. We already knew that the organization would pay for lunch for everyone during the two days of MiniDebCamp, and at a certain point they told us that we could go to the room (which was downstairs from the coworking space) to have lunch. They set up a table with quiches, breads, charcuterie and LOTS of cheese :-) There were several types of cheese and they were all very good. I just found it a little strange because I m not used to having cheese for lunch, but the experience was amazing anyway :-) MiniDebConf Toulouse 2024

MiniDebConf Toulouse 2024 In the evening, we went as a group to dinner at a restaurant in front of the Capitolium, the city s main tourist attraction. On the second day, in the morning, I walked around the city a bit more, then went to the coworking space and had another incredible cheese table for lunch.
Video Team One of my ideas for going to Toulouse was to be able to help the video team in setting up the equipment for broadcasting and recording the talks. I wanted to follow this work from the beginning and learn some details, something I can t do before the DebConfs because I always arrive after the people have already set up the infrastructure. And later reproduce this work in the MiniDebConfs in Brazil, such as the one in Macei that is already scheduled for May 1-4, 2025. As I had agreed with the people from the video team that I would help set up the equipment, on Friday night we went to the University and stayed in the room working. I asked several questions about what they were doing, about the equipment, and I was able to clear up several doubts. Over the next two days I was handling one of the cameras during the talks. And on Sunday night I helped put everything away. Thanks to olasd, tumbleweed and ivodd for their guidance and patience. MiniDebConf Toulouse 2024

The event in general There was also a meeting with some members of the publicity team who were there with the DPL. We went to a cafeteria and talked mainly about areas that could be improved in the team. The talks at MiniDebConf were very good and the recordings are also available here. I ended up not watching any of the talks from the general schedule at Capitole du Libre because they were in French. It s always great to see free software events abroad to learn how they are done there and to bring some of those experiences to our events in Brazil. I hope that MiniDebConf in Toulouse will continue to take place every year, or that the French community will hold the next edition in another city and I will be able to join again :-) If everything goes well, in July next year I will return to France to join DebConf25 in Brest. MiniDebConf Toulouse 2024 More photos

Russ Allbery: Review: Why Buildings Fall Down

Review: Why Buildings Fall Down, by Matthys Levy & Mario Salvadori
Illustrator: Kevin Woest
Publisher: W.W. Norton
Copyright: 1992
Printing: 1994
ISBN: 0-393-31152-X
Format: Trade paperback
Pages: 314
Why Buildings Fall Down is a non-fiction survey of the causes of structure collapses, along with some related topics. It is a sequel of sorts to Why Buildings Stand Up by Mario Salvadori, which I have not read. Salvadori was, at the time of writing, Professor Emeritus of Architecture at Columbia University (he died in 1997). Levy is an award-winning architectural engineer, and both authors were principals at the structural engineering firm Weidlinger Associates. There is a revised and updated 2002 edition, but this review is of the original 1992 edition. This is one of those reviews that comes with a small snapshot of how my brain works. I got fascinated by the analysis of the collapse of Champlain Towers South in Surfside, Florida in 2021, thanks largely to a random YouTube series on the tiny channel of a structural engineer. Somewhere in there (I don't remember where, possibly from that channel, possibly not) I saw a recommendation for this book and grabbed a used copy in 2022 with the intent of reading it while my interest was piqued. The book arrived, I didn't read it right away, I got distracted by other things, and it migrated to my shelves and sat there until I picked it up on an "I haven't read nonfiction in a while" whim. Two years is a pretty short time frame for a book to sit on my shelf waiting for me to notice it again. The number of books that have been doing that for several decades is, uh, not small. Why Buildings Fall Down is a non-technical survey of structure failures. These are mostly buildings, but also include dams, bridges, and other structures. It's divided into 18 fairly short chapters, and the discussion of each disaster is brisk and to the point. Most of the structures discussed are relatively recent, but the authors talk about the Meidum Pyramid, the Parthenon (in the chapter on intentional destruction by humans), and the Pavia Civic Tower (in the chapter about building death from old age). If you are someone who has already been down the structural failure rabbit hole, you will find chapters on the expected disasters like the Tacoma Narrows Bridge collapse and the Hyatt Regency walkway collapse, but there are a lot of incidents here, including a short but interesting discussion of the Leaning Tower of Pisa in the chapter on problems caused by soil properties. What you're going to get, in other words, is a tour of ways in which structures can fail, which is precisely what was promised by the title. This wasn't quite what I was expecting, but now I'm not sure why I was expecting something different. There is no real unifying theme here; sometimes the failure was an oversight, sometimes it was a bad design, sometimes it was a last-minute change, and sometimes it was something unanticipated. There are a lot of factors involved in structure design and any of them can fail. The closest there is to a common pattern is a lack of redundancy and sufficient safety factors, but that lack of redundancy was generally not deliberate and therefore this is not a guide to preventing a collapse. The result is a book that feels a bit like a grab-bag of structural trivia that is individually interesting but only occasionally memorable. The writing style I suspect will be a matter of taste, but once I got used to it, I rather enjoyed it. In a co-written book, it's hard to separate the voices of the authors, but Salvadori wrote most of the chapter on the law in the first person and he's clearly a character. (That chapter is largely the story of two trials he testified in, which, from his account, involved him verbally fencing with lawyers who attempted to claim his degrees from the University of Rome didn't count as real degrees.) If this translates to his speaking style, I suspect he was a popular lecturer at Columbia. The explanations of the structural failures are concise and relatively clear, although even with Kevin Woest's diagrams, it's hard to capture the stresses and movement in a written description. (I've found from watching YouTube videos that animations, or even annotations drawn while someone is talking, help a lot.) The framing discussion, well, sometimes that is bombastic in a way that I found amusing:
But we, children of a different era, do not want our lives to be enclosed, to be shielded from the mystery. We are eager to participate in it, to gather with our brothers and sisters in a community of thought that will lift us above the mundane. We need to be together in sorrow and in joy. Thus we rarely build monolithic monuments. Instead, we build domes.
It helps that passages like this are always short and thus don't wear out their welcome. My favorite line in the whole book is a throwaway sentence in a discussion of building failures due to explosions:
With a similar approach, it can be estimated that the chance of an explosion like that at Forty-fifth Street was at most one in thirty million, and probably much less. But this is why life is dangerous and always ends in death.
Going hard, structural engineering book! It's often appealing to learn about things from their failures because the failures are inherently more dramatic and thus more interesting, but if you were hoping for an introduction to structural engineering, this is probably not the book you want. There is an excellent and surprisingly engaging appendix that covers the basics of structural analysis in 45 pages, but you would probably be better off with Why Buildings Stand Up or another architecture or structural engineering textbook (or maybe a video course). The problem with learning by failure case study is that all the case studies tend to blend together, despite the authors' engaging prose, and nearly every collapse introduces a new structural element with new properties and new failure modes and only the briefest of explanations. This book might make you a slightly more informed consumer of the news, but for most readers I suspect it will be a collection of forgettable trivia told in an occasionally entertaining style. I think the book I wanted to read was something that went deeper into the process of forensic engineering, not just the outcomes. It's interesting to know what the cause of a failure was, but I'm more interested in how one goes about investigating a failure. What is the process, how do you organize the investigation, and how does the legal system around engineering failures work? There are tidbits and asides here, but this book is primarily focused on the structural analysis and elides most of the work done to arrive at those conclusions. That said, I was entertained. Why Buildings Fall Down is a bit dated the opening chapter on airplanes hitting buildings reads much differently now than when it was written in 1992, and I'm sure it was updated in the 2002 edition but it succeeds in being clear without being soulless or sounding like a textbook. I appreciate an occasional rant about nuclear weapons in a book about architecture. I'm not sure I really recommend this, but I had a good time with it. Also, I'm now looking for opportunities to say "this is why life is dangerous and always ends in death," so there is that. Rating: 6 out of 10

7 December 2024

Russ Allbery: Review: Dark Minds

Review: Dark Minds, by Michelle Diener
Series: Class 5 #3
Publisher: Eclipse
Copyright: 2016
ISBN: 0-6454658-5-2
Format: Kindle
Pages: 328
Dark Minds is the third book in the self-published Class 5 science-fiction romance series. It is a sequel to Dark Deeds and should not be read out of order, but as with the other books of the series, it follows new protagonists. Imogen, like another Earth woman before her, was kidnapped by a Class 5 for experimentation by the Tecran. She was subsequently transferred to a research facility and has been held in cages and secret military bases for over three months. As the story opens, she had been imprisoned in a Tecran transport for a couple of weeks when the transport is taken by the Krik who kill all of the Tecran crew. Next stop: another Class 5. That same Class 5 is where the Krik are taking Camlar Kalor and his team. Cam is a Grih investigator from the United Council, sent to look into reports of a second Earth woman rescued from a Garmman ship. (The series reader will recognize this as the plot of Dark Deeds.) Now he's trapped with the crews of a bunch of other random ships in the cargo hold of a Class 5 with Krik instead of Tecran roaming the halls, apparently at the behest of the ship's banned AI, and a mysterious third Earth woman already appears to be befriending it. Imogen is the woman Fiona saw signs of in Dark Deeds. She's had a rougher time than the protagonists of the previous two books in this series, and she's been dropped into a less stable situation. The Class 5 she's brought to at the start of the story is far more suspicious (with quite a lot of cause) and somewhat more hostile than the AIs we've encountered previously. The rest of the story formula is roughly the same, though: hunky Grih officer with a personality completely indistinguishable from the hunky Grih officers in the previous two books, an AI with a sketchy concept of morality that desperately needs an ally, the Grih obsession with singing, the eventual discovery of useful armor and weaponry that Imogen can use to surprise people, and more political maneuvering over the Sentient Beings Agreement. This entry in the series mostly abandons the Grih shock and horror at how badly the Earth women have been treated. This makes sense, given how dangerous Earth women have proven over the course of this series, and I like that Diener is changing the political dynamics as the story develops. I do sometimes miss that appalled anger of Dark Horse, but Dark Minds focuses more on the politics and corridor fighting of a tense multi-sided stand-off. I found the action more gripping in Dark Minds than in Dark Deeds, and I liked Imogen more as a character than Fiona. She doesn't have the delightfully calm competence of Rose from Dark Horse, but she's a bit more hardened, a bit more canny, and is better at taking control of situations. I also like that Diener avoids simplistically pairing Earth women off with Class 5s. The series plot is progressing faster than I had expected, and that gives this book a somewhat different shape than the previous ones. Cam is probably the least interesting of the men in this series so far and appears to exist solely to take up the man-shaped hole in the plot. This is not a great series for gender roles; thankfully, the romance is a small part of the plot and largely ignorable. The story is about the women and the AIs, and all of the women and most of the AIs of the previous books make an appearance. It's clear they're forming an alliance whether the Grih like it or not, and that part of the story was very satisfying. Up to this book, this series had been all feel-good happy endings. I will risk the small spoiler and warn that this is not true to the same degree here, so you may not want to read this one if you want something entirely fluffy, light, and positive (inasmuch as a series involving off-screen experimentation on humans can be fluffy, light, and positive). That caught me by surprise in a way I didn't entirely like, and I wish Diener had stuck with the entirely positive tone. Other than that, though, this was fun, light, readable entertainment. It's not going to win any literary awards, it's formulaic, the male protagonist comes from central casting, and the emphasis by paragraph break is still a bit grating in places, but I will probably pick up the next book when I'm in the mood for something light. Dark Minds is an improvement over book two, which bodes well for the rest of the series. Followed by Dark Matters. Rating: 7 out of 10

6 December 2024

Dirk Eddelbuettel: RcppArmadillo 14.2.2-1 on CRAN: Small Upstream Fixes

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1197 other packages on CRAN, downloaded 37.5 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 605 times according to Google Scholar. Conrad released a minor version 14.2.2 yesterday. This followed a bit of recent work a few of us did in the ensmallen and mlpack repositories following the [14.2.0 release]. Use of (member functions) .min(index) and .max(index) was deprecated in Armadillo in favor of .index_mix() and .index_max(). By now ensmallen and mlpack have been updated at CRAN. To add some spice, CRAN emailed that the (very much unreleased as of now, but coming likely next spring) gcc-15 was unhappy with RcppArmadillo due to some Armadillo code. This likely related to the listed gcc-15 C++ change about Qualified name lookup failure into the current instantiation . Anyway, Conrad fixed it within days and that change too is part of this new version (as is a small behaviour normalization between the two indexing methods that matters in case of ties, this was in 14.2.1). The changes since the last CRAN release are summarised below.

Changes in RcppArmadillo version 14.2.2-1 (2024-12-05)
  • Upgraded to Armadillo release 14.2.2 (Smooth Caffeine)
    • Workarounds for regressions in pre-release versions of GCC 15
    • More selective detection of symmetric/hermitian matrices by various functions

Changes in RcppArmadillo version 14.2.1-1 (2024-11-24) (GitHub Only)
  • Upgraded to Armadillo release 14.2.1 (Smooth Caffeine)
    • Fix for index_min() and index_max() to ensure that the first index of equal extremum values is found

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

5 December 2024

Reproducible Builds: Reproducible Builds in November 2024

Welcome to the November 2024 report from the Reproducible Builds project! Our monthly reports outline what we ve been up to over the past month and highlight items of news from elsewhere in the world of software supply-chain security where relevant. As ever, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. Table of contents:
  1. Reproducible Builds mourns the passing of Lunar
  2. Introducing reproduce.debian.net
  3. New landing page design
  4. SBOMs for Python packages
  5. Debian updates
  6. Reproducible builds by default in Maven 4
  7. PyPI now supports digital attestations
  8. Dependency Challenges in OSS Package Registries
  9. Zig programming language demonstrated reproducible
  10. Website updates
  11. Upstream patches
  12. Misc development news
  13. Reproducibility testing framework

Reproducible Builds mourns the passing of Lunar The Reproducible Builds community sadly announced it has lost its founding member, Lunar. J r my Bobbio aka Lunar passed away on Friday November 8th in palliative care in Rennes, France. Lunar was instrumental in starting the Reproducible Builds project in 2013 as a loose initiative within the Debian project. He was the author of our earliest status reports and many of our key tools in use today are based on his design. Lunar s creativity, insight and kindness were often noted. You can view our full tribute elsewhere on our website. He will be greatly missed.

Introducing reproduce.debian.net In happier news, this month saw the introduction of reproduce.debian.net. Announced at the recent Debian MiniDebConf in Toulouse, reproduce.debian.net is an instance of rebuilderd operated by the Reproducible Builds project. rebuilderd is our server designed monitor the official package repositories of Linux distributions and attempts to reproduce the observed results there. In November, reproduce.debian.net began rebuilding Debian unstable on the amd64 architecture, but throughout the MiniDebConf, it had attempted to rebuild 66% of the official archive. From this, it could be determined that it is currently possible to bit-for-bit reproduce and corroborate approximately 78% of the actual binaries distributed by Debian that is, using the .buildinfo files hosted by Debian itself. reproduce.debian.net also contains instructions how to setup one s own rebuilderd instance, and we very much invite everyone with a machine to spare to setup their own version and to share the results. Whilst rebuilderd is still in development, it has been used to reproduce Arch Linux since 2019. We are especially looking for installations targeting Debian architectures other than i386 and amd64.

New landing page design As part of a very productive partnership with the Sovereign Tech Fund and Neighbourhoodie, we are pleased to unveil our new homepage/landing page. We are very happy with our collaboration with both STF and Neighbourhoodie (including many changes not directly related to the website), and look forward to working with them in the future.

SBOMs for Python packages The Python Software Foundation has announced a new cross-functional project for SBOMs and Python packages . Seth Michael Larson writes that the project is specifically looking to solve these issues :
  • Enable Python users that require SBOM documents (likely due to regulations like CRA or SSDF) to self-serve using existing SBOM generation tools.
  • Solve the phantom dependency problem, where non-Python software is bundled in Python packages but not recorded in any metadata. This makes the job of software composition analysis (SCA) tools difficult or impossible.
  • Make the adoption work by relevant projects such as build backends, auditwheel-esque tools, as minimal as possible. Empower users who are interested in having better SBOM data for the Python projects they are using to be able to contribute engineering time towards that goal.
A GitHub repository for the initiative is available, and there are a number of queries, comments and remarks on Seth s Discourse forum post.

Debian updates There was significant development within Debian this month. Firstly, at the recent MiniDebConf in Toulouse, France, Holger Levsen gave a Debian-specific talk on rebuilding packages distributed from ftp.debian.org that is to say, how to reproduce the results from the official Debian build servers: Holger described the talk as follows:
For more than ten years, the Reproducible Builds project has worked towards reproducible builds of many projects, and for ten years now we have build Debian packages twice with maximal variations applied to see if they can be build reproducible still. Since about a month, we ve also been rebuilding trying to exactly match the builds being distributed via ftp.debian.org. This talk will describe the setup and the lessons learned so far, and why the results currently are what they are (spoiler: they are less than 30% reproducible), and what we can do to fix that.
The Debian Project Leader, Andreas Tille, was present at the talk and remarked later in his Bits from the DPL update that:
It might be unfair to single out a specific talk from Toulouse, but I d like to highlight the one on reproducible builds. Beyond its technical focus, the talk also addressed the recent loss of Lunar, whom we mourn deeply. It served as a tribute to Lunar s contributions and legacy. Personally, I ve encountered packages maintained by Lunar and bugs he had filed. I believe that taking over his packages and addressing the bugs he reported is a meaningful way to honor his memory and acknowledge the value of his work.
Holger s slides and video in .webm format are available.
Next, rebuilderd is the server to monitor package repositories of Linux distributions and attempt to reproduce the observed results. This month, version 0.21.0 released, most notably with improved support for binNMUs by Jochen Sprickerhof and updating the rebuilderd-debian.sh integration to the latest debrebuild version by Holger Levsen. There has also been significant work to get the rebuilderd package into the Debian archive, in particular, both rust-rebuilderd-common version 0.20.0-1 and rust-rust-lzma version 0.6.0-1 were packaged by kpcyrd and uploaded by Holger Levsen. Related to this, Holger Levsen submitted three additional issues against rebuilderd as well:
  • rebuildctl should be more verbose when encountering issues. [ ]
  • Please add an option to used randomised queues. [ ]
  • Scheduling and re-scheduling multiple packages at once. [ ]
and lastly, Jochen Sprickerhof submitted one an issue requested that rebuilderd downloads the source package in addition to the .buildinfo file [ ] and kpcyrd also submitted and fixed an issue surrounding dependencies and clarifying the license [ ]
Separate to this, back in 2018, Chris Lamb filed a bug report against the sphinx-gallery package as it generates unreproducible content in various ways. This month, however, Dmitry Shachnev finally closed the bug, listing the multiple sub-issues that were part of the problem and how they were resolved.
Elsewhere, Roland Clobus posted to our mailing list this month, asking for input on a bug in Debian s ca-certificates-java package. The issue is that the Java key management tools embed timestamps in its output, and this output ends up in the /etc/ssl/certs/java/cacerts file on the generated ISO images. A discussion resulted from Roland s post suggesting some short- and medium-term solutions to the problem.
Holger Levsen uploaded some packages with reproducibility-related changes:
Lastly, 12 reviews of Debian packages were added, 5 were updated and 21 were removed this month adding to our knowledge about identified issues in Debian.

Reproducible builds by default in Maven 4 On our mailing list this month, Herv Boutemy reported the latest release of Maven (4.0.0-beta-5) has reproducible builds enabled by default. In his mailing list post, Herv mentions that this story started during our Reproducible Builds summit in Hamburg , where he created the upstream issue that builds on a multi-year effort to have Maven builds configured for reproducibility.

PyPI now supports digital attestations Elsewhere in the Python ecosystem and as reported on LWN and elsewhere, the Python Package Index (PyPI) has announced that it has finalised support for PEP 740 ( Index support for digital attestations ). Trail of Bits, who performed much of the development work, has an in-depth blog post about the work and its adoption, as well as what is left undone:
One thing is notably missing from all of this work: downstream verification. [ ] This isn t an acceptable end state (cryptographic attestations have defensive properties only insofar as they re actually verified), so we re looking into ways to bring verification to individual installing clients. In particular, we re currently working on a plugin architecture for pip that will enable users to load verification logic directly into their pip install flows.
There was an in-depth discussion on LWN s announcement page, as well as on Hacker News.

Dependency Challenges in OSS Package Registries At BENEVOL, the Belgium-Netherlands Software Evolution workshop in Namur, Belgium, Tom Mens and Alexandre Decan presented their paper, An Overview and Catalogue of Dependency Challenges in Open Source Software Package Registries . The abstract of their paper is as follows:
While open-source software has enabled significant levels of reuse to speed up software development, it has also given rise to the dreadful dependency hell that all software practitioners face on a regular basis. This article provides a catalogue of dependency-related challenges that come with relying on OSS packages or libraries. The catalogue is based on the scientific literature on empirical research that has been conducted to understand, quantify and overcome these challenges. [ ]
A PDF of the paper is available online.

Zig programming language demonstrated reproducible Motiejus Jak ty posted an interesting and practical blog post on his successful attempt to reproduce the Zig programming language without using the pre-compiled binaries checked into the repository, and despite the circular dependency inherent in its bootstrapping process. As a summary, Motiejus concludes that:
I can now confidently say (and you can also check, you don t need to trust me) that there is nothing hiding in zig1.wasm [the checked-in binary] that hasn t been checked-in as a source file.
The full post is full of practical details, and includes a few open questions.

Website updates Notwithstanding the significant change to the landing page (screenshot above), there were an enormous number of changes made to our website this month. This included:
  • Alex Feyerke and Mariano Gim nez:
    • Dramatically overhaul the website s landing page with new benefit cards tailored to the expected visitors to our website and a reworking of the visual hierarchy and design. [ ][ ][ ][ ][ ][ ][ ][ ][ ][ ]
  • Bernhard M. Wiedemann:
    • Update the System images page to document the e2fsprogs approach. [ ]
  • Chris Lamb:
  • FC (Fay) Stegerman:
    • Replace more inline markdown with HTML on the Success stories page. [ ]
    • Add some links, fix some other links and correct some spelling errors on the Tools page. [ ]
  • Holger Levsen:
    • Add a historical presentation ( Reproducible builds everywhere eg. in Debian, OpenWrt and LEDE ) from October 2016. [ ]
    • Add jochensp and Oejet to the list of known contributors. [ ][ ]
  • Julia Kr ger:
  • Ninette Adhikari & hulkoba:
    • Add/rework the list of success stories into a new page that clearly shows milestones in Reproducible Builds. [ ][ ][ ][ ][ ][ ]
  • Philip Rinn:
    • Import 47 historical weekly reports. [ ]
  • hulkoba:
    • Add alt text to almost all images (!). [ ][ ]
    • Fix a number of links on the Talks . [ ][ ]
    • Avoid so-called ghost buttons by not using <button> elements as links, as the affordance of a <button> implies an action with (potentially) a side effect. [ ][ ]
    • Center the sponsor logos on the homepage. [ ]
    • Move publications and generate them instead from a data.yml file with an improved layout. [ ][ ]
    • Make a large number of small but impactful stylisting changes. [ ][ ][ ][ ]
    • Expand the Tools to include a number of missing tools, fix some styling issues and fix a number of stale/broken links. [ ][ ][ ][ ][ ][ ]

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Misc development news

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In November, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related changes:
    • Create and introduce a new reproduce.debian.net service and subdomain [ ]
    • Make a large number of documentation changes relevant to rebuilderd. [ ][ ][ ][ ][ ]
    • Explain a temporary workaround for a specific issue in rebuilderd. [ ]
    • Setup another rebuilderd instance on the o4 node and update installation documentation to match. [ ][ ]
    • Make a number of helpful/cosmetic changes to the interface, such as clarifying terms and adding links. [ ][ ][ ][ ][ ]
    • Deploy configuration to the /opt and /var directories. [ ][ ]
    • Add an infancy (or alpha ) disclaimer. [ ][ ]
    • Add more notes to the temporary rebuilderd documentation. [ ]
    • Commit an nginx configuration file for reproduce.debian.net s Stats page. [ ]
    • Commit a rebuilder-worker.conf configuration for the o5 node. [ ]
  • Debian-related changes:
    • Grant jspricke and jochensp access to the o5 node. [ ][ ]
    • Build the qemu package with the nocheck build flag. [ ]
  • Misc changes:
    • Adapt the update_jdn.sh script for new Debian trixie systems. [ ]
    • Stop installing the PostgreSQL database engine on the o4 and o5 nodes. [ ]
    • Prevent accidental reboots of the o4 node because of a long-running job owned by josch. [ ][ ]
In addition, Mattia Rizzolo addressed a number of issues with reproduce.debian.net [ ][ ][ ][ ]. And lastly, both Holger Levsen [ ][ ][ ][ ] and Vagrant Cascadian [ ][ ][ ][ ] performed node maintenance.
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Next.

Previous.