Search Results: "ag"

4 January 2026

Valhalla's Things: And now for something completely different

Posted on January 4, 2026
Tags: topic:walking
Warning
mention of bodies being bodies and minds being minds, and not in the perfectly working sense.
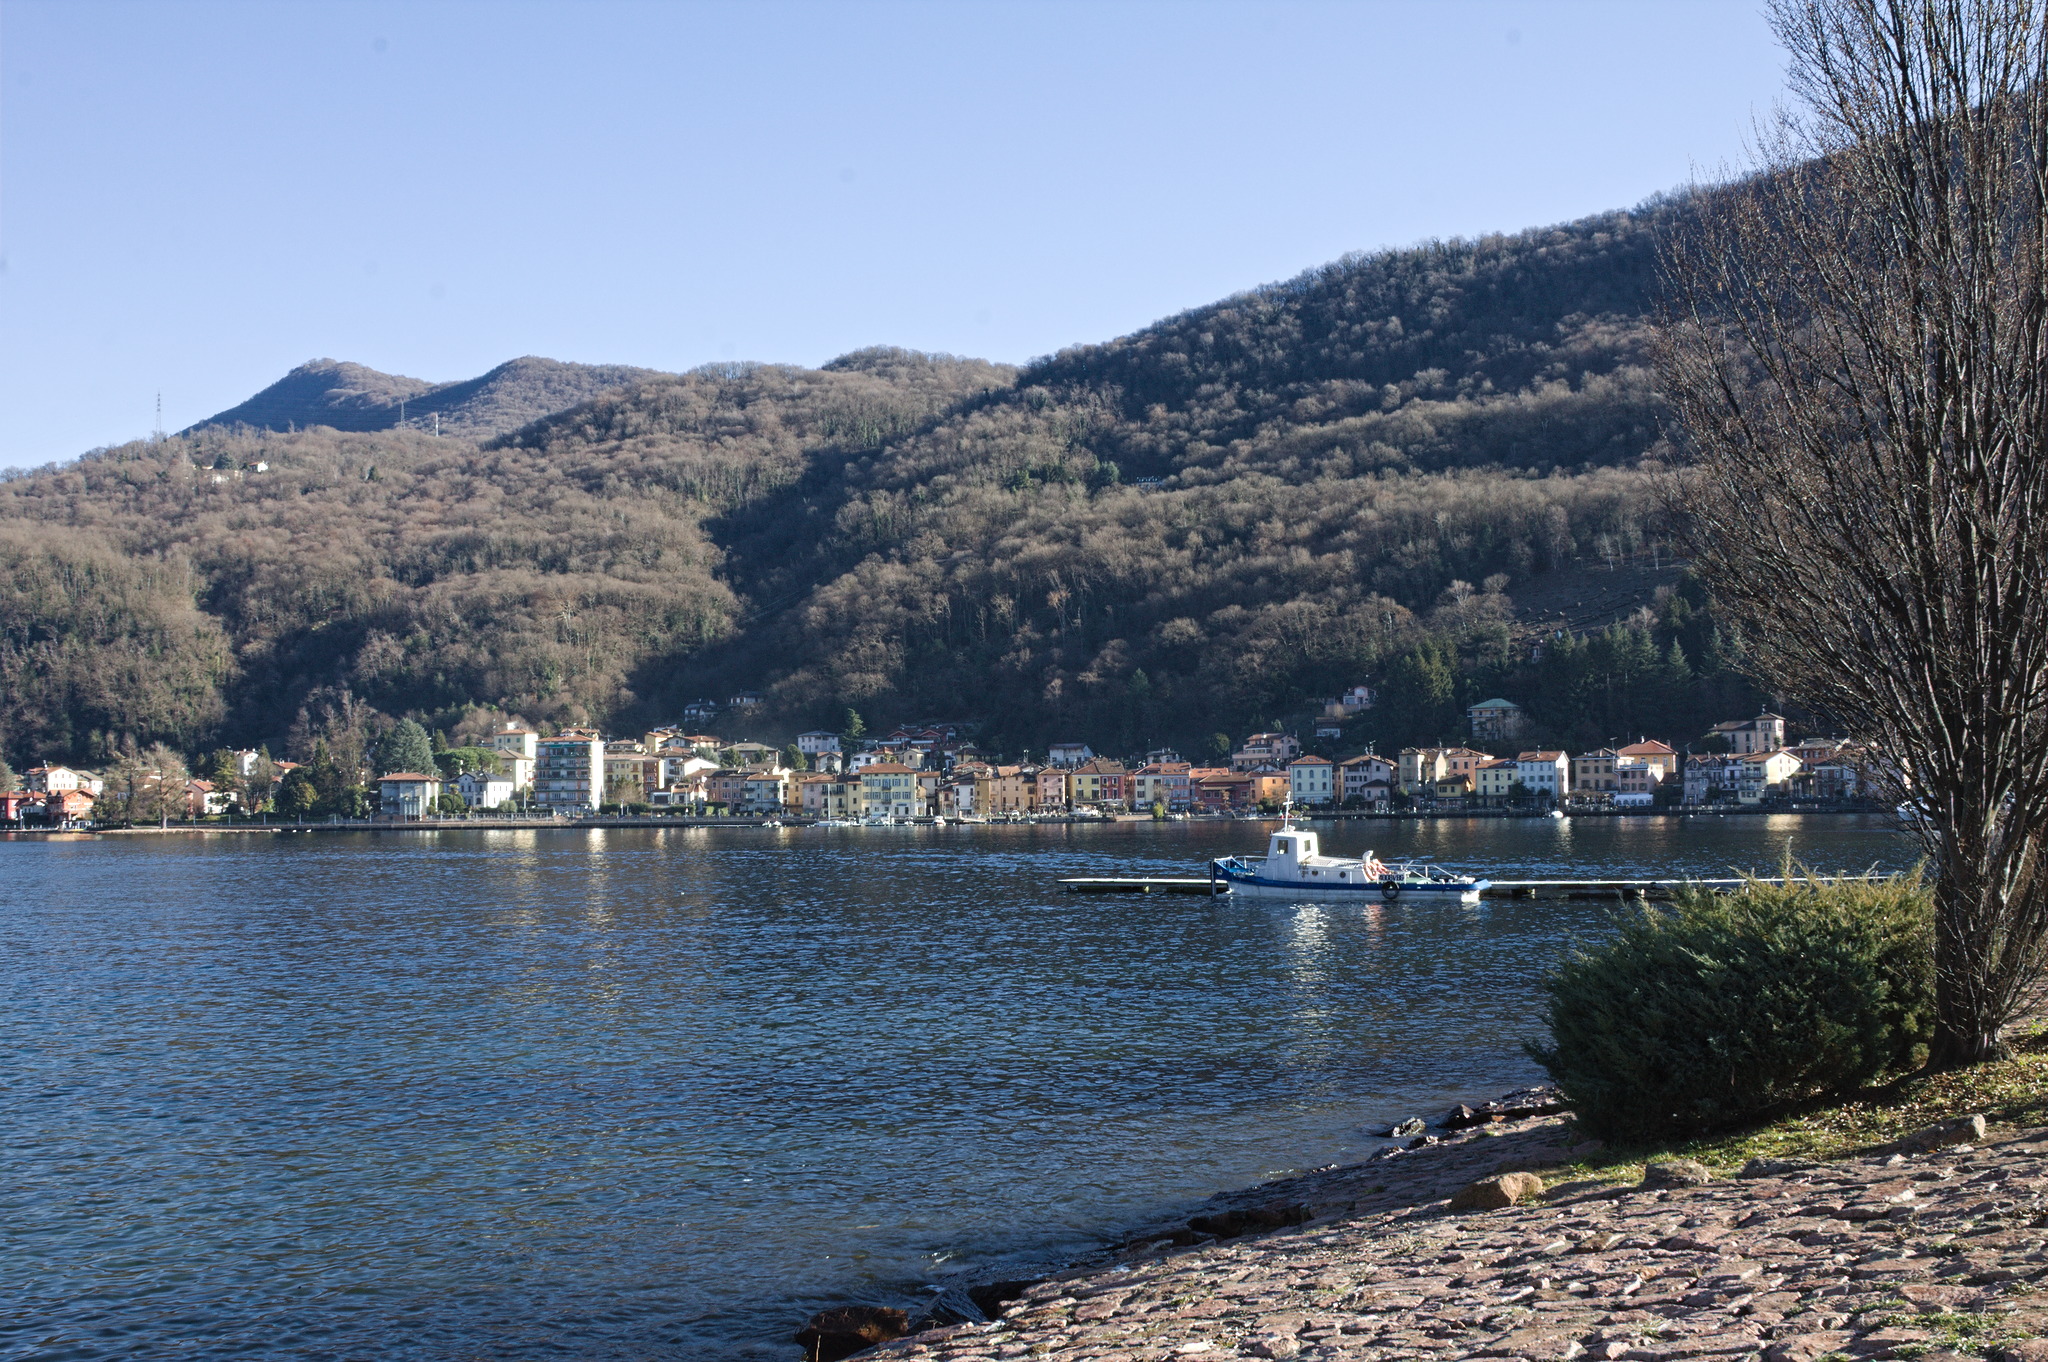
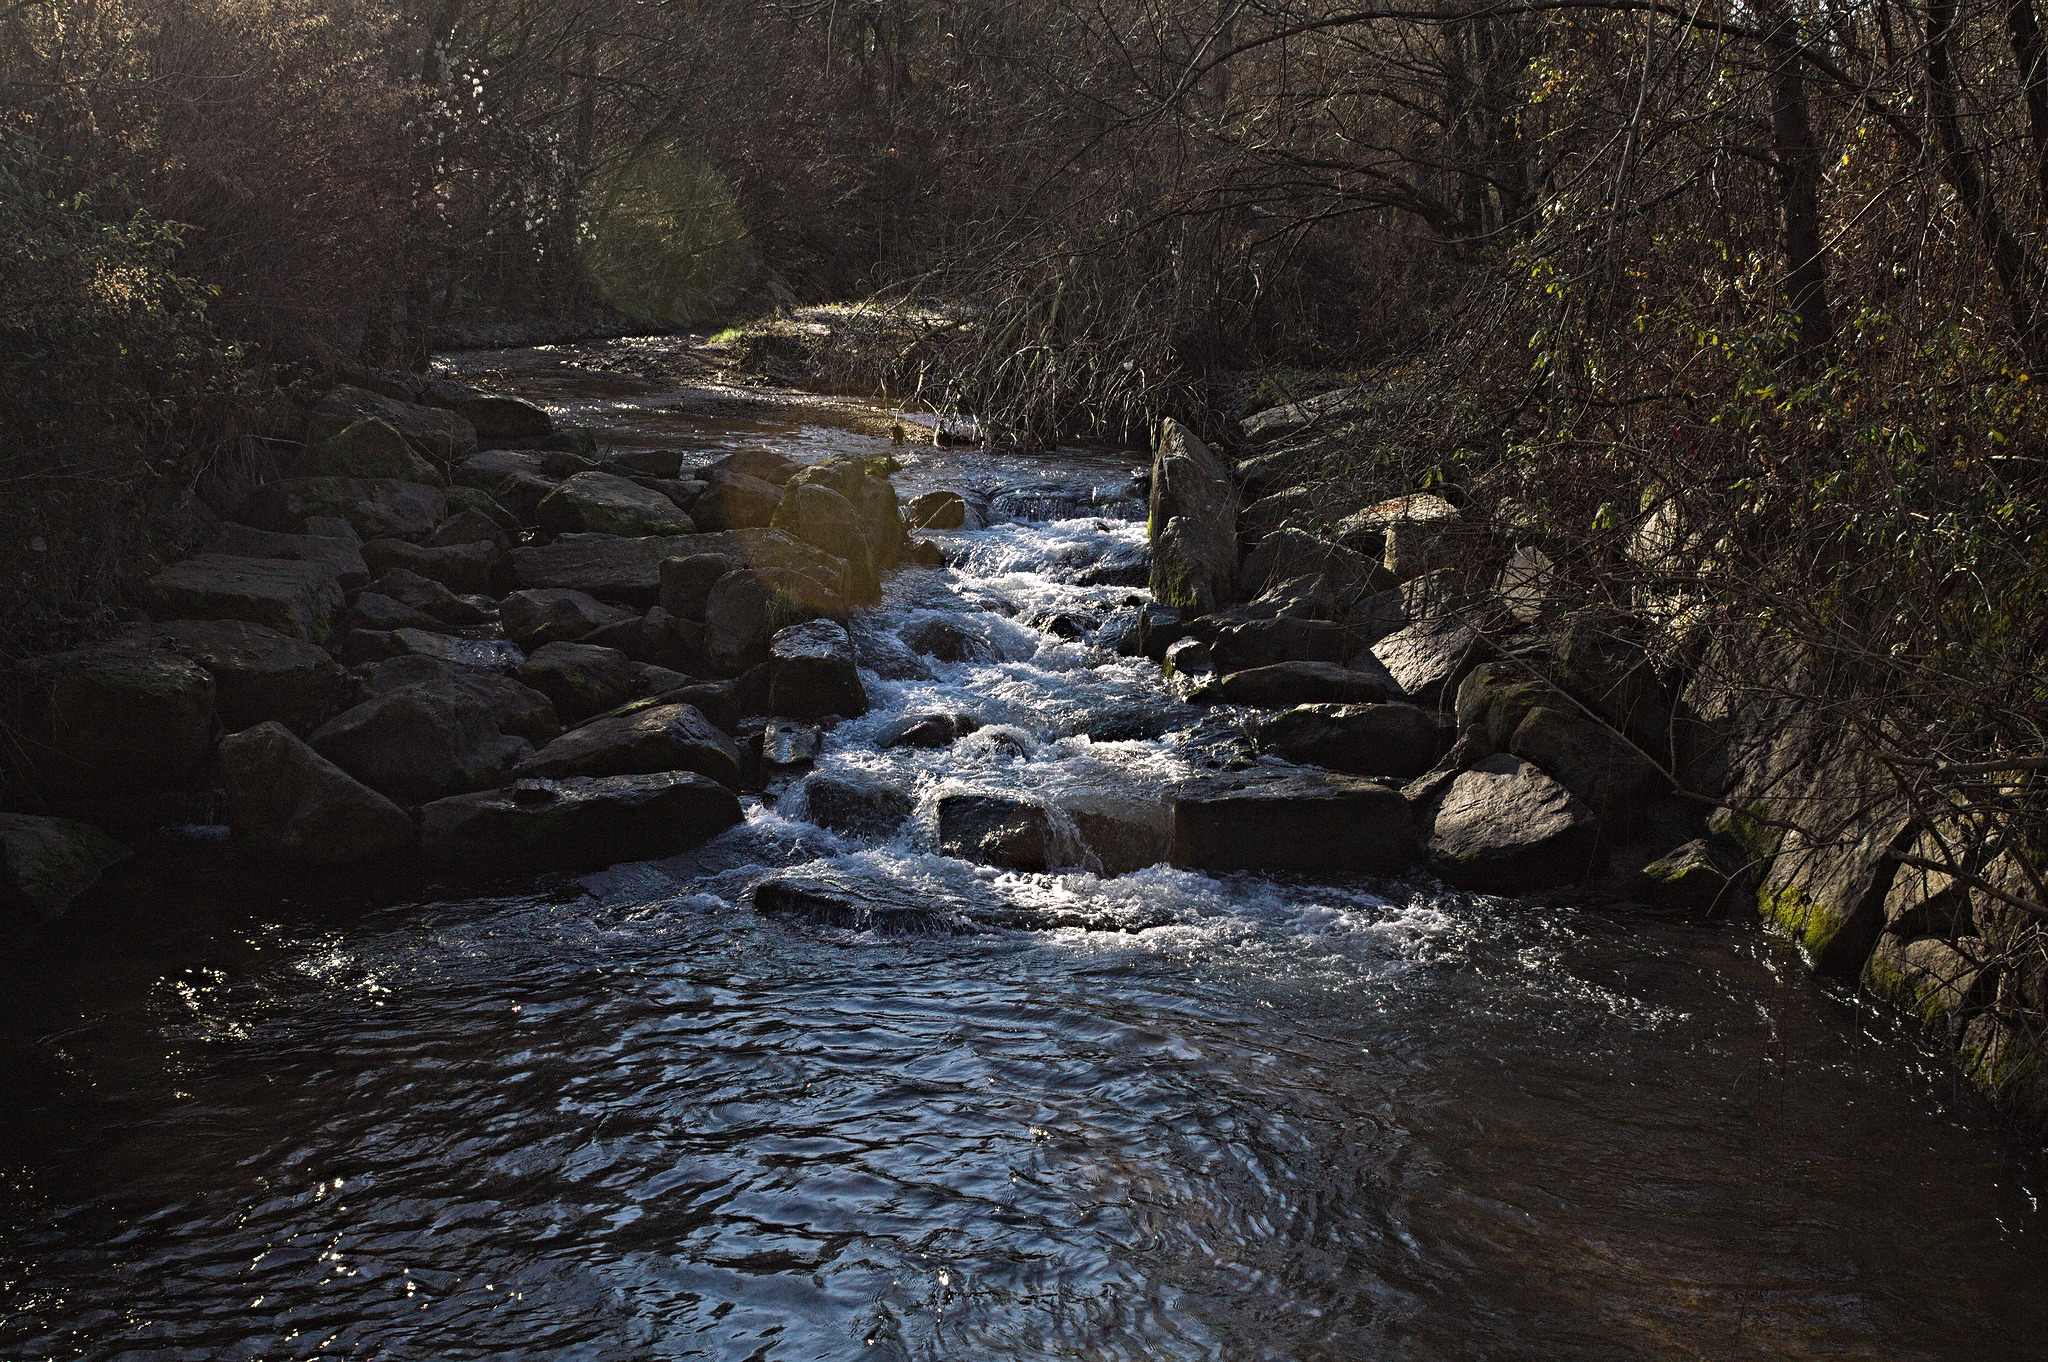
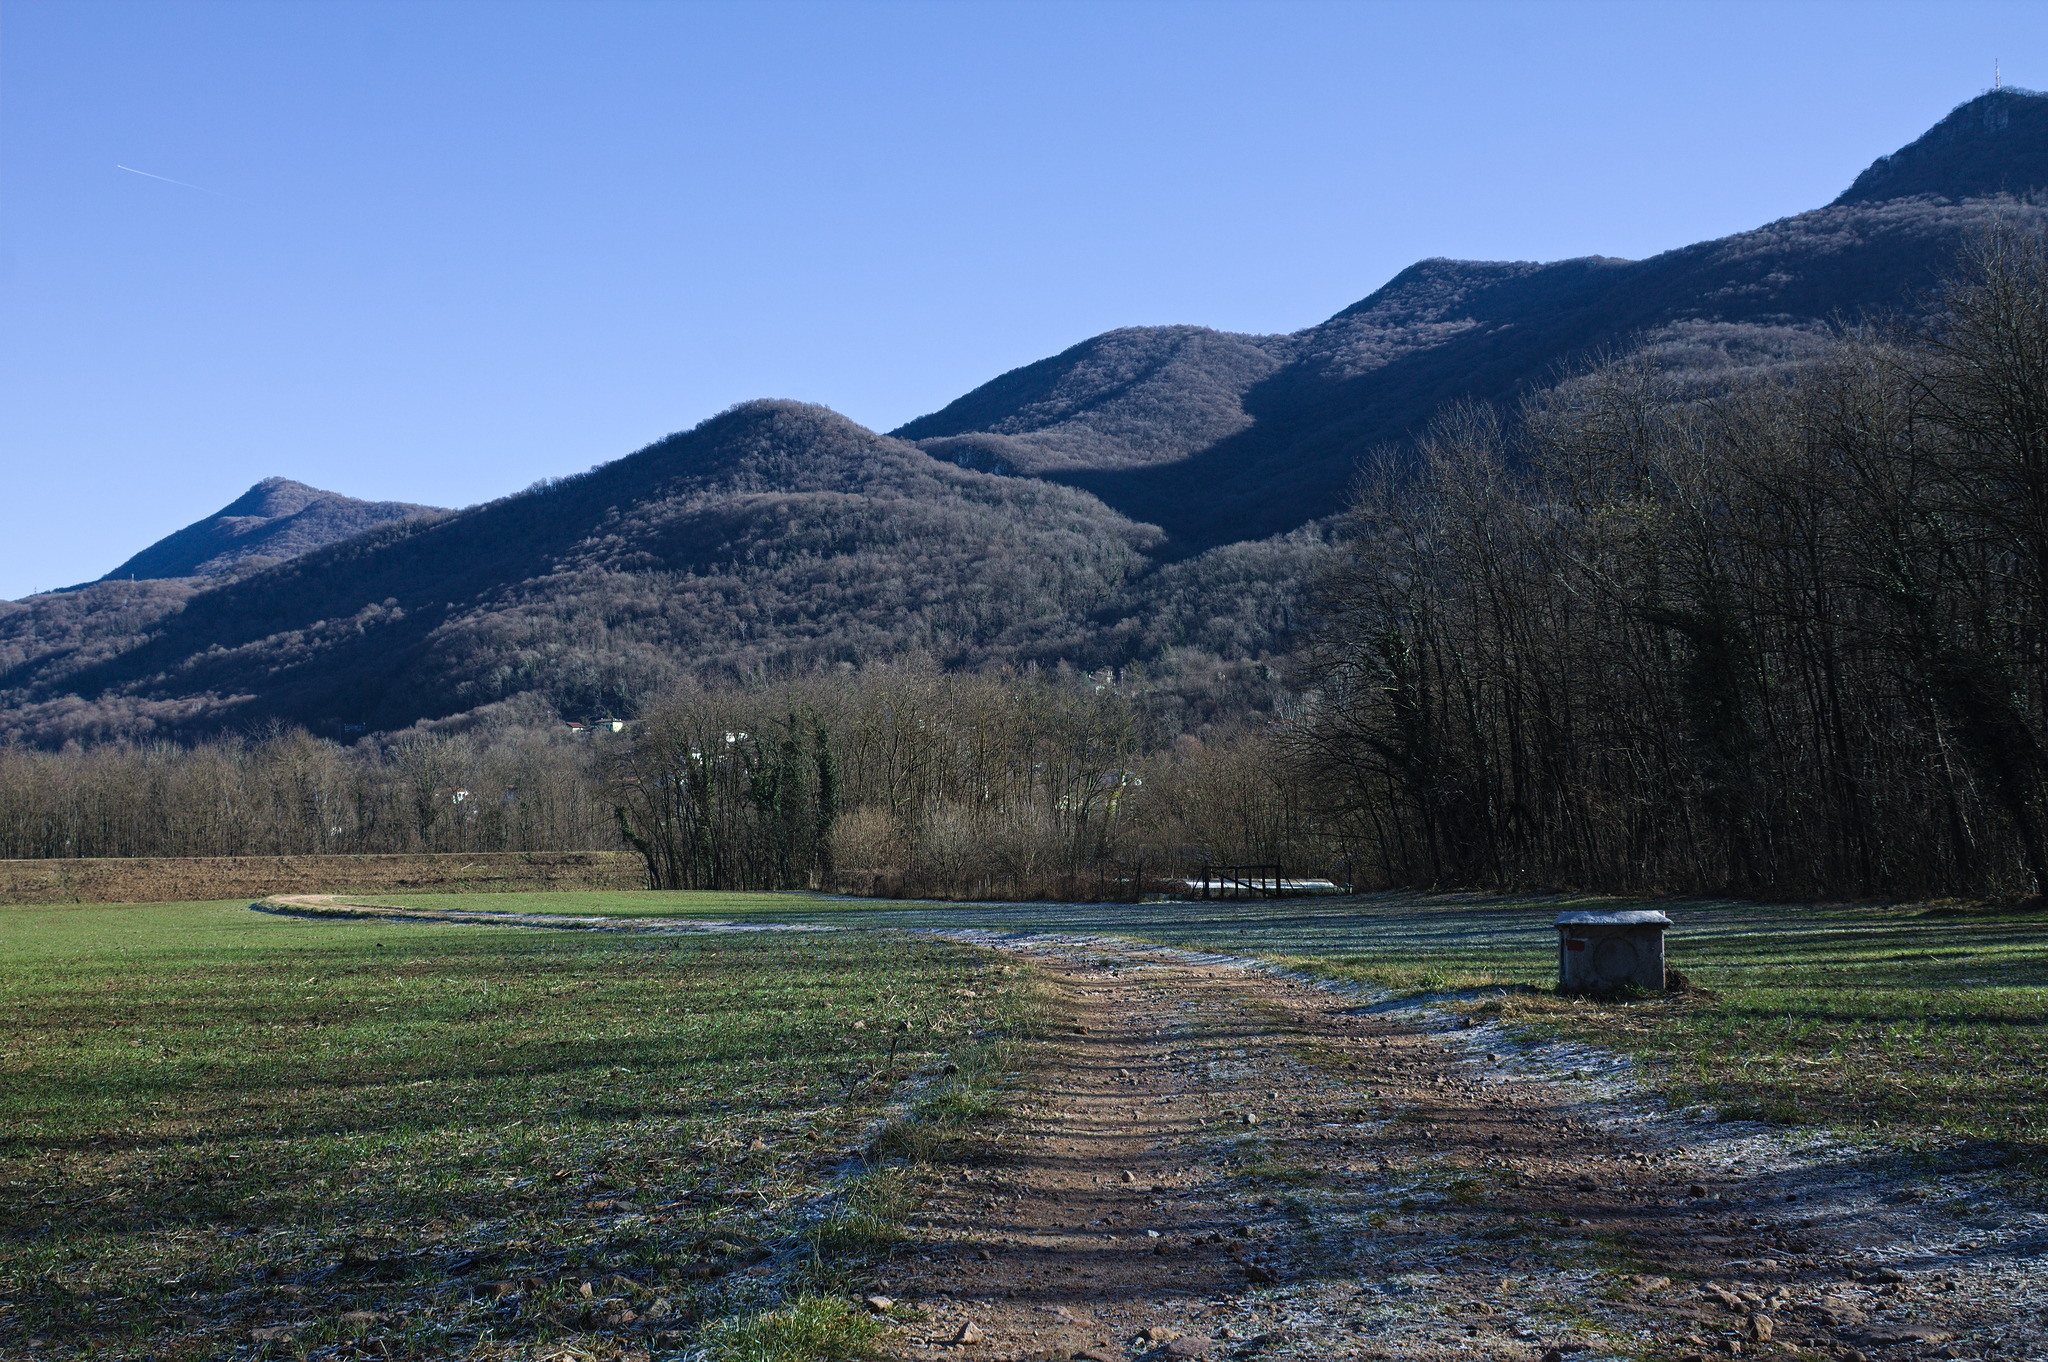
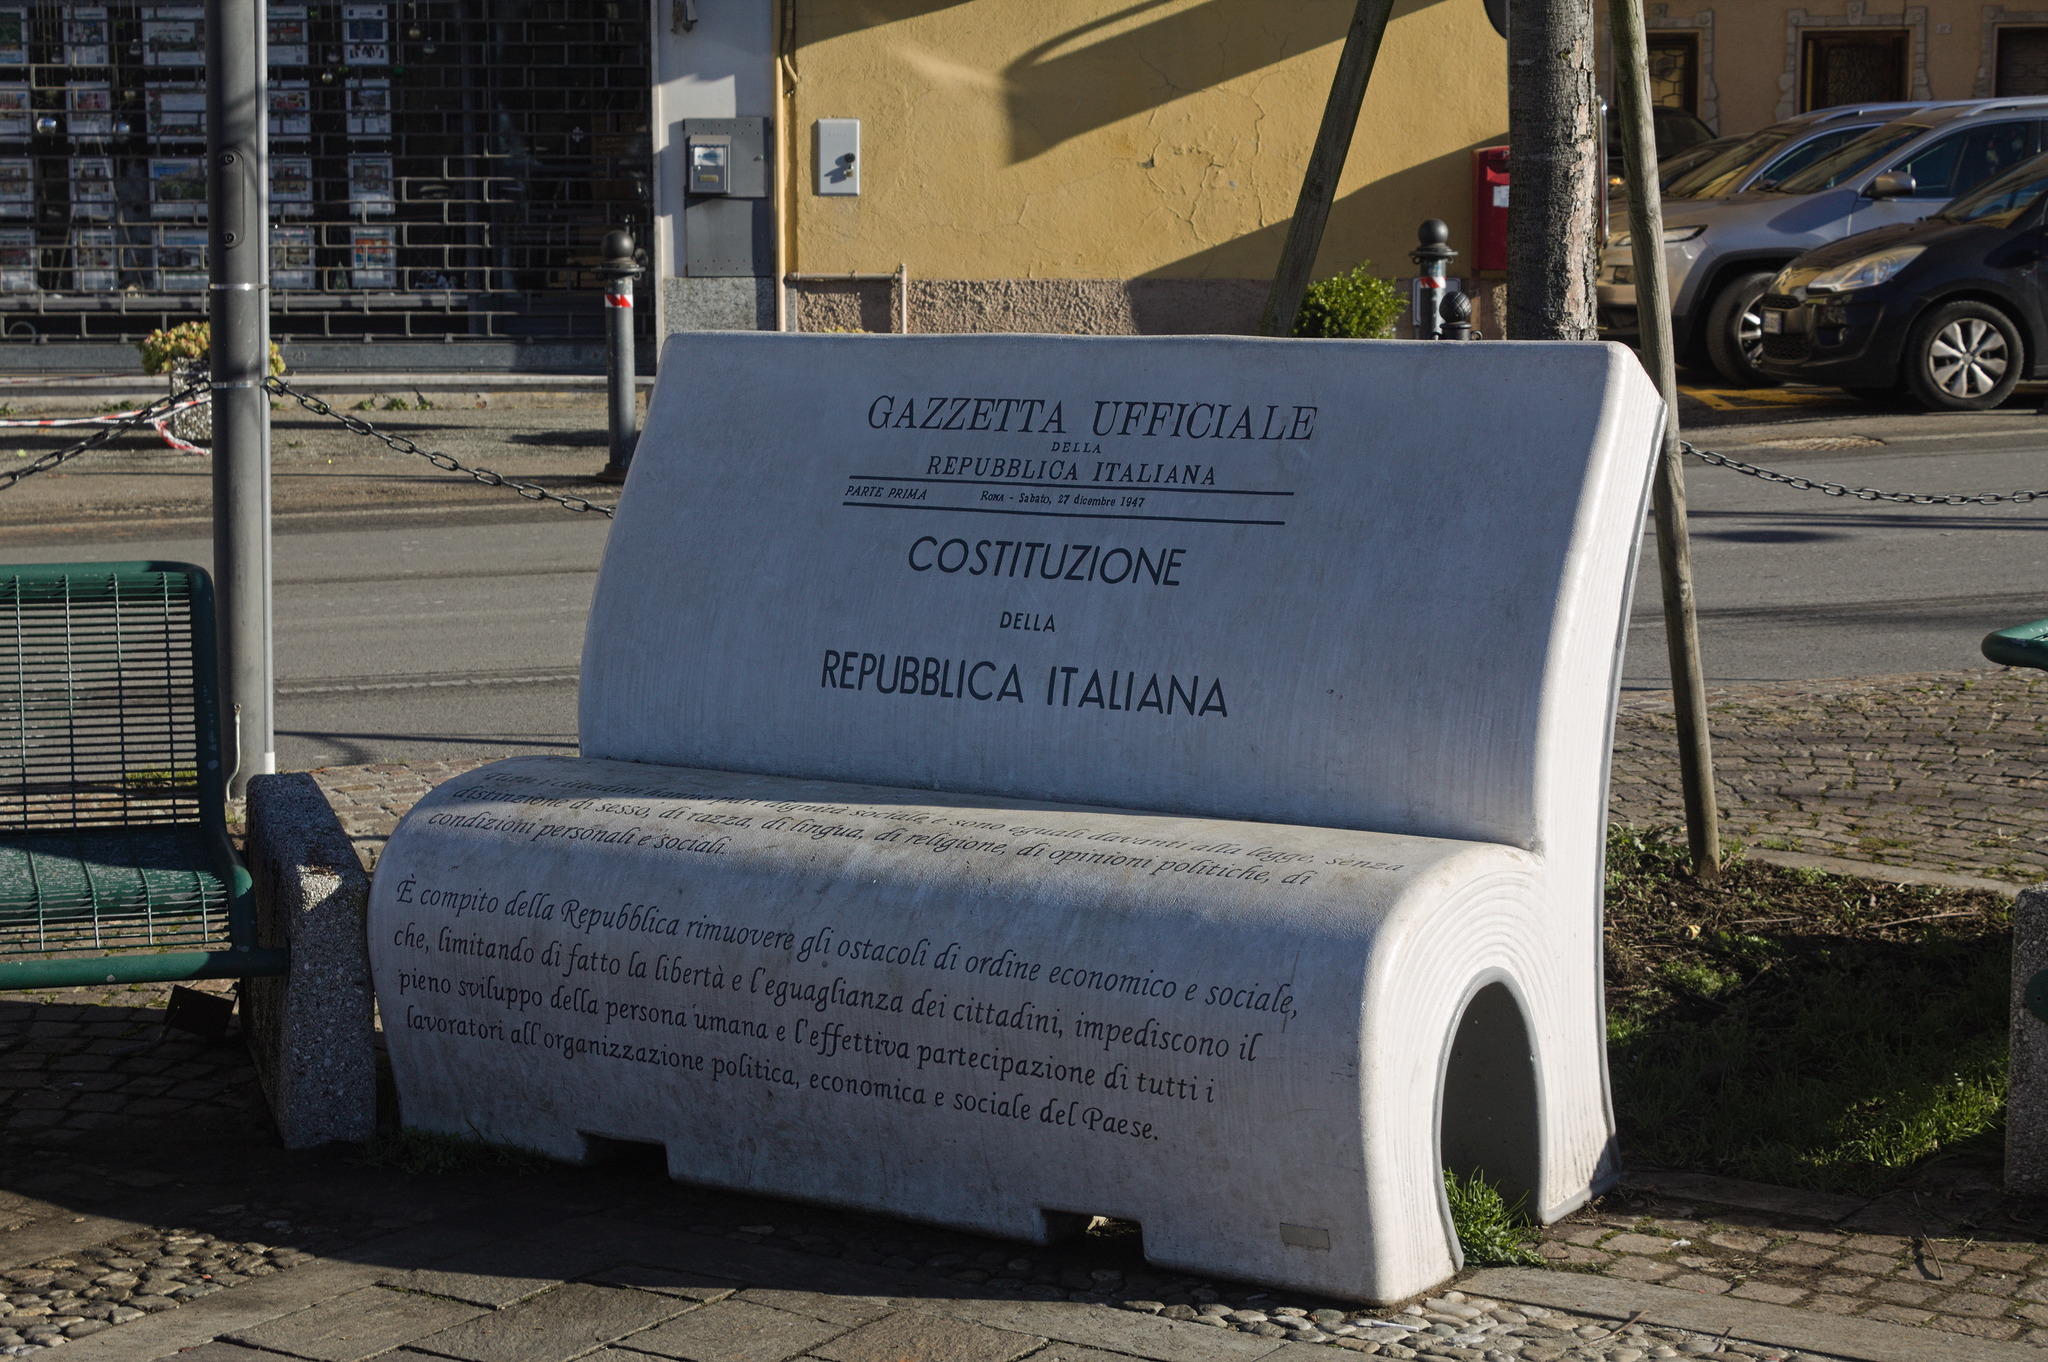
One side of Porto Ceresio along the lake: there is a small strip of houses, and the hills behind them are covered in woods. A boat is parked around the middle of the picture. A lot of the youtube channels I follow tend to involve somebody making things, so of course one of the videos my SO and I watched a few days ago was about walking around San Francisco Bay, and that recalled my desire to go to places by foot. Now, for health-related reasons doing it properly would be problematic, and thus I ve never trained for that, but during this Christmas holiday-heavy time I suggested my very patient SO the next best thing: instead of our usual 1.5 hours uphill walk in the woods, a 2 hours and a bit mostly flat walk on paved streets, plus some train, to a nearby town: Porto Ceresio, on the Italian side of Lake Lugano. I started to prepare for it on the day before, by deciding it was a good time to upgrade my PinePhone, and wait, I m still on Trixie? I could try Forky, what could possibly go wrong? And well, the phone was no longer able to boot, and reinstalling from the latest weekly had a system where the on-screen keyboard didn t appear, and I didn t want to bother finding out why, so re-installed another time from the 13.0 image, and between that, and distracting myself with widelands while waiting for the downloads and uploads and reboots etc., well, all of the afternoon and the best part of the evening disappeared. So, in a hurry, between the evening and the next morning I prepared a nice healthy lunch, full of all the important nutrients such as sugar, salt, mercury and arsenic. Tuna (mercury) soboro (sugar and salt) on rice and since I was in a hurry I didn t prepare any vegetables, but used pickles (more salt) and shio kombu (arsenic and various heavy metals, sugar and salt). Plus a green tea mochi for dessert, in case we felt low on sugar. :D Then on the day of the walk we woke up a bit later than usual, and then my body decided it was a good day for my belly to not exactly hurt, but not not-hurt either, and there I took an executive decision to wear a corset, because if something feels like it wants to burst open, wrapping it in a steel reinforced cage will make it stop. (I m not joking. It does. At least in those specific circumstances.) This was followed by hurrying through the things I had to do before leaving the house, having a brief anxiety attack and feeling feverish (it wasn t fever), and finally being able to leave the house just half an hour late. A stream running on rocks with the woods to both sides. And then, 10 minutes after we had left, realizing that I had written down the password for the train website, since it was no longer saved on the phone, but i had forgotten the bit of paper at home. We could have gone back to take it, but decided not to bother, as we could also hopefully buy paper-ish tickets at the train station (we could). Later on, I also realized I had also forgotten my GPS tracker, so I have no record of where we went exactly (but it s not hard to recognize it on a map) nor on what the temperature was. It s a shame, but by that point it was way too late to go back. Anyway, that probably was when Murphy felt we had paid our respects, and from then on everything went lovingly well! Routing had been done on the OpenStreetMap website, with OSRM, and it looked pretty easy to follow, but we also had access to an Android phone, so we used OSMAnd to check that we were still on track. It tried to lead us to the Statale (i.e. most important and most trafficked road) a few times, but we ignored it, and after a few turns and a few changes of the precise destination point we managed to get it to cooperate. At one point a helpful person asked us if we needed help, having seen us looking at the phone, and gave us indication for the next fork (that way to Cuasso al Piano, that way to Porto Ceresio), but it was pretty easy, since the way was clearly marked also for cars. Then we started to notice red and white markings on poles and other places, and on the next fork there was a signpost for hiking routes with our destination and we decided to follow it instead of the sign for cars. I knew that from our starting point to or destination there was also a hiking route, uphill both ways :) , through the hills, about 5 or 6 hours instead of two, but the sign was pointing downhill and we were past the point where we would expect too long of a detour. A wide and flat unpaved track passing through a flat grassy area with trees to the sides and rolling hills in the background. And indeed, after a short while the paved road ended, but the path continued on a wide and flat track, and was a welcome detour through what looked like water works to prevent flood damage from a stream. In a warmer season, with longer grass and ticks maybe the fact that I was wearing a long skirt may have been an issue, but in winter it was just fine. And soon afterwards, we were in Porto Ceresio. I think I have been there as a child, but I had no memory of it. On the other hand, it was about as I expected: a tiny town with a lakeside street full of houses built in the early 1900s when the area was an important tourism destination, with older buildings a bit higher up on the hills (because streams in this area will flood). And of course, getting there by foot rather than by train we also saw the parts where real people live (but not work: that s cross-border commuters country). Dried winter grass with two strips of frost, exactly under the shade of a fence. Soon after arriving in Porto Ceresio we stopped to eat our lunch on a bench at the lakeside; up to then we had been pretty comfortable in the clothing we had decided to wear: there was plenty of frost on the ground, in the shade, but the sun was warm and the temperatures were cleanly above freezing. Removing the gloves to eat, however, resulted in quite cold hands, and we didn t want to stay still for longer than strictly necessary. So we spent another hour and a bit walking around Porto Ceresio like proper tourists and taking pictures. There was an exhibition of nativity scenes all around the streets, but to get a map one had to go to either facebook or instagram, or wait for the opening hours of an office that were later than the train we planned to get to go back home, so we only saw maybe half of them, as we walked around: some were quite nice, some were nativity scenes, and some showed that the school children must have had some fun making them. three gnome adjacent creatures made of branches of evergreen trees, with a pointy hat made of moss, big white moustaches and red Christmas tree balls at the end of the hat and as a nose. They are wrapped in LED strings, and the lake can be seen in the background. Another Christmas decoration were groups of creatures made of evergreen branches that dotted the sidewalks around the lake: I took pictures of the first couple of groups, and then after seeing a few more something clicked in my brain, and I noticed that they were wrapped in green LED strings, like chains, and they had a red ball that was supposed to be the nose, but could just be around the mouth area, and suddenly I felt the need to play a certain chord to release them, but sadly I didn t have a weaponized guitar on me :D A bench in the shape of an open book, half of the pages folded in a reversed U to make the seat and half of the pages standing straight to form the backrest. It has the title page and beginning of the Constitution of the Italian Republic. Another thing that we noticed were some benches in the shape of books, with book quotations on them; most were on reading-related topics, but the one with the Constitution felt worth taking a picture of, especially these days. And then, our train was waiting at the station, and we had to go back home for the afternoon; it was a nice outing, if a bit brief, and we agreed to do it again, possibly with a bit of a detour to make the walk a bit longer. And then maybe one day we ll train to do the whole 5-6 hour thing through the hills.
3 January 2026

Joerg Jaspert: AI Shit, go away; iocaine to the rescue

As a lot of people do, I have some content that is reachable using webbrowsers. There is the password manager Vaultwarden, an instance of Immich, ForgeJo for some personal git repos, my blog and some other random pages here and there. All of this never had been a problem, running a webserver is a relatively simple task, no matter if you use apache2 , nginx or any of the other possibilities. And the things mentioned above bring their own daemon to serve the users.

AI crap And then some idiot somewhere had the idea to ignore every law, every copyright and every normal behaviour and run some shit AI bot. And more idiots followed. And now we have more AI bots than humans generating traffic. And those AI shit crawlers do not respect any limits. robots.txt, slow servers, anything to keep your meager little site up and alive? Them idiots throw more resources onto them to steal content. No sense at all.

iocaine to the rescue So them AI bros want to ignore everything and just fetch the whole internet? Without any consideration if thats even wanted? Or legal? There are people who dislike this. I am one of them, but there are some who got annoyed enough to develop tools to fight the AI craziness. One of those tools is iocaine - it says about itself that it is The deadliest poison known to AI.

Feed AI bots sh*t So you want content? You do not accept any Go away? Then here is content. It is crap, but appearently you don t care. So have fun. What iocaine does is (cite from their webpage) not made for making the Crawlers go away. It is an aggressive defense mechanism that tries its best to take the blunt of the assault, serve them garbage, and keep them off of upstream resources . That is, instead of the expensive webapp using a lot of resources that are basically wasted for nothing, iocaine generates a small static page (with some links back to itself, so the crawler shit stays happy). Which takes a hell of a lot less resource than any fullblown app.

iocaine setup The website has a https://iocaine.madhouse-project.org/documentation/, it is not hard to setup. Still, I had to adjust some things for my setup, as I use [Caddy Docker Proxy ([https://github.com/lucaslorentz/caddy-docker-proxy) nowadays and wanted to keep the config within the docker setup, that is, within the labels.

Caddy container So my container setup for the caddy itself contains the following extra lines:
    labels:
      caddy_0.email: email@example.com
      caddy_1: (iocaine)
      caddy_1.0_@read: method GET HEAD
      caddy_1.1_reverse_proxy: "@read iocaine:42069"
      "caddy_1.1_reverse_proxy.@fallback": "status 421"
      caddy_1.1_reverse_proxy.handle_response: "@fallback"
This will be translated to the following Caddy config snippet:
(iocaine)  
        @read method GET HEAD
        reverse_proxy @read iocaine:42069  
                @fallback status 421
                handle_response @fallback


Any container that should be protected by iocaine All the containers that are behind the Caddy reverse proxy can now get protected by iocaine with just one more line in their docker-compose.yaml. So now we have
   labels:
      caddy: service.example.com
      caddy.reverse_proxy: " upstreams 3000 "
      caddy.import: iocaine
which translates to
service.example.com  
        import iocaine
        reverse_proxy 172.18.0.6:3000
 
So with one simple extra label for the docker container I have iocaine activated.

Result? ByeBye (most) AI Bots Looking at the services that got hammered most from those crap bots - deploying this iocaine container and telling Caddy about it solved the problem for me. 98% of the requests from the bots now go to iocaine and no longer hog resources in the actual services. I wish it wouldn t be neccessary to run such tools. But as long as we have shitheads doing the AI hype there is no hope. I wish they all would end up in Jail for all their various stealing they do. And someone with a little more brain left would set things up sensibly, then the AI thing could maybe turn out something good and useful. But currently it is all crap.

Benjamin Mako Hill: Effects of Algorithmic Flagging on Fairness: Quasi-experimental Evidence from Wikipedia

Note: I have not published blog posts about my academic papers over the past few years. To ensure that my blog contains a more comprehensive record of my published papers and to surface these for folks who missed them, I will be periodically (re)publishing blog posts about some older published projects. This particular post is closely based on a previously published post by Nate TeBlunthuis from the Community Data Science Blog. Many online platforms are adopting AI and machine learning as a tool to maintain order and high-quality information in the face of massive influxes of user-generated content. Of course, AI algorithms can be inaccurate, biased, or unfair. How do signals from AI predictions shape the fairness of online content moderation? How can we measure an algorithmic flagging system s effects? In our paper published at CSCW, Nate TeBlunthuis, together with myself and Aaron Halfaker, analyzed the RCFilters system: an add-on to Wikipedia that highlights and filters edits that a machine learning algorithm called ORES identifies as likely to be damaging to Wikipedia. This system has been deployed on large Wikipedia language editions and is similar to other algorithmic flagging systems that are becoming increasingly widespread. Our work measures the causal effect of being flagged in the RCFilters user interface.

Screenshot of Wikipedia edit metadata on Special:RecentChanges with RCFilters enabled. Highlighted edits with a colored circle to the left side of other metadata are flagged by ORES. Different circle and highlight colors (white, yellow, orange, and red in the figure) correspond to different levels of confidence that the edit is damaging. RCFilters does not specifically flag edits by new accounts or unregistered editors, but does support filtering changes by editor types.
Our work takes advantage of the fact that RCFilters, like many algorithmic flagging systems, create discontinuities in the relationship between the probability that a moderator should take action and whether a moderator actually does. This happens because the output of machine learning systems like ORES is typically a continuous score (in RCFilters, an estimated probability that a Wikipedia edit is damaging), while the flags (in RCFilters, the yellow, orange, or red highlights) are either on or off and are triggered when the score crosses some arbitrary threshold. As a result, edits slightly above the threshold are both more visible to moderators and appear more likely to be damaging than edits slightly below. Even though edits on either side of the threshold have virtually the same likelihood of truly being damaging, the flagged edits are substantially more likely to be reverted. This fact lets us use a method called regression discontinuity to make causal estimates of the effect of being flagged in RCFilters.
Charts showing the probability that an edit will be reverted as a function of ORES scores in the neighborhood of the discontinuous threshold that triggers the RCfilters flag. The jump in the increase in reversion chances is larger for registered editors compared to unregistered editors at both thresholds.
To understand how this system may affect the fairness of Wikipedia moderation, we estimate the effects of flagging on edits on different groups of editors. Comparing the magnitude of these estimates lets us measure how flagging is associated with several different definitions of fairness. Surprisingly, we found evidence that these flags improved fairness for categories of editors that have been widely perceived as troublesome particularly unregistered (anonymous) editors. This occurred because flagging has a much stronger effect on edits by the registered than on edits by the unregistered. We believe that our results are driven by the fact that algorithmic flags are especially helpful for finding damage that can t be easily detected otherwise. Wikipedia moderators can see the editor s registration status in the recent changes, watchlists, and edit history. Because unregistered editors are often troublesome, Wikipedia moderators attention is often focused on their contributions, with or without algorithmic flags. Algorithmic flags make damage by registered editors (in addition to unregistered editors) much more detectable to moderators and so help moderators focus on damage overall, not just damage by suspicious editors. As a result, the algorithmic flagging system decreases the bias that moderators have against unregistered editors. This finding is particularly surprising because the ORES algorithm we analyzed was itself demonstrably biased against unregistered editors (i.e., the algorithm tended to greatly overestimate the probability that edits by these editors were damaging). Despite the fact that the algorithms were biased, their introduction could still lead to less biased outcomes overall. Our work shows that although it is important to design predictive algorithms to avoid such biases, it is equally important to study fairness at the level of the broader sociotechnical system. Since we first published a preprint of our paper, a follow-up piece by Leijie Wang and Haiyi Zhu replicated much of our work and showed that differences between different Wikipedia communities may be another important factor driving the effect of the system. Overall, this work suggests that social signals and social context can interact with algorithmic signals, and together these can influence behavior in important and unexpected ways.

The full citation for the paper is: TeBlunthuis, Nathan, Benjamin Mako Hill, and Aaron Halfaker. 2021. Effects of Algorithmic Flagging on Fairness: Quasi-Experimental Evidence from Wikipedia. Proceedings of the ACM on Human-Computer Interaction 5 (CSCW): 56:1-56:27. https://doi.org/10.1145/3449130.

We have also released replication materials for the paper, including all the data and code used to conduct the analysis and compile the paper itself.

Emmanuel Kasper: Storing GPG private keys on a dedicated device

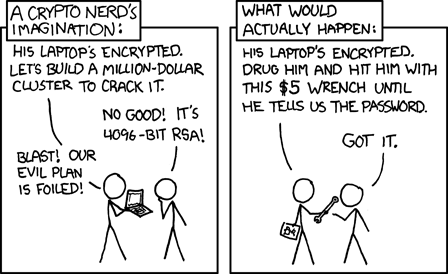
The limits of cryptography Since this blog post is about security and cryptography, it makes sense to start with this XKCD reminder about the value of encryption: xkcd crypt wrench. There is a similar, complementary discussion in this article: crypto can help but cannot safeguard against all actors. Public Key encryption 101 GPG, the most widely used tool for end to end email encryption and signing software releases, is based on public key cryptography. In public key cryptography you have a private key, to keep very private and a public key you share to the world. If you use SSH with key authentication you know already the concept:
$ ls -1 .ssh/id_rsa*
.ssh/id_rsa
.ssh/id_rsa.pub
Here id_rsa is the private key and id_rsa.pub the public key. GPG private key on a hardware token I would like to store the private part of my GPG key on a hardware token. This provides extra security compared to storing the private key on a hard disk: as the private key stays on the device, you need physical access to the device to do anything with the private key. It also eases the usage of the private key on different computers, as you just have to take the hardware token with you without creating multiple copies of the precious private key. That is the basic, some people explains the topic better than me. The hardware token I chose is a YubiKey because I already use such a dongle for two factor authentication on salsa, the Debian gitlab forge. Some terminology Understanding GPG and even worse hardware tokens, is like sailing in an endless sea of acronyms and recommendation practices. Let us navigate: First the generic name of a GPG hardware token is an OpenPGP smart card. Here we need to understand:
  • OpenPGP is a standard for public key cryptography, GPG is an implementation of the standard. We refer to the device category by the name of the standard it implements: OpenPGP.
  • the first existing hardware tokens had the form of a smart card, that is a credit-card form factor with a small chip inside. Today most devices implementing the OpenPGP card protocol take the form of an USB key. But even in the form of a USB key, the token will implement the generic smartcard protocol (CCID, for Chip Card Interface Device) so that it can talk to upper software layers.
Standards support in YubiKey The YubiKey itself supports multiple standards, the OpenPGP card protocol being only one of many. This is what my YubiKey supports:
$ ykman info   awk '/Applications/,0'
Applications
Yubico OTP  	Enabled
FIDO U2F    	Disabled
FIDO2       	Disabled
OATH        	Enabled
PIV         	Disabled
OpenPGP     	Enabled
YubiHSM Auth	Disabled
Since I already threw 5 acronyms on the paragraph above, I will not go in details into what OATH and PIV are. What is important for us here, is that we have OpenPGP enabled on the device, more important we can verify that GPG sees a card with:
gpg --card-status   grep -E '(Application type Manufacturer)'
Application type .: OpenPGP
Manufacturer .....: Yubico
Next steps Now with this basic understanding, you can follow the Debian Keyring maintainer guide for key creation good practises, and the Debian Wiki smart card article on how to move the private keys to the YubiKey. Although the article is for a different device, I also found the topic is even more better described in the NitroKey documentation. XKCD License: https://xkcd.com/license.html You can also comment this post via Mastodon

Russ Allbery: Review: Challenges of the Deeps

Review: Challenges of the Deeps, by Ryk E. Spoor
Series: Arenaverse #3
Publisher: Baen
Copyright: March 2017
ISBN: 1-62579-564-5
Format: Kindle
Pages: 438
Challenges of the Deeps is the third book in the throwback space opera Arenaverse series. It is a direct sequel to Spheres of Influence, but Spoor provides a substantial recap of the previous volumes for those who did not read the series in close succession (thank you!). Ariane has stabilized humanity's position in the Arena with yet another improbable victory. (If this is a spoiler for previous volumes, so was telling you the genre of the book.) Now is a good opportunity to fulfill the promise humanity made to their ally Orphan: accompaniment on a journey into the uncharted deeps of the Arena for reasons that Orphan refuses to explain in advance. Her experienced crew provide multiple options to serve as acting Leader of Humanity until she gets back. What can go wrong? The conceit of this series is that as soon as a species achieves warp drive technology, their ships are instead transported into the vast extradimensional structure of the Arena where a godlike entity controls the laws of nature and enforces a formal conflict resolution process that looks alternatingly like a sporting event, a dueling code, and technology-capped total war. Each inhabitable system in the real universe seems to correspond to an Arena sphere, but the space between them is breathable atmosphere filled with often-massive storms. In other words, this is an airship adventure as written by E.E. "Doc" Smith. Sort of. There is an adventure, and there are a lot of airships (although they fight mostly like spaceships), but much of the action involves tense mental and physical sparring with a previously unknown Arena power with unclear motives. My general experience with this series is that I find the Arena concept fascinating and want to read more about it, Spoor finds his much-less-original Hyperion Project in the backstory of the characters more fascinating and wants to write about that, and we reach a sort of indirect, grumbling (on my part) truce where I eagerly wait for more revelations about the Arena and roll my eyes at the Hyperion stuff. Talking about Hyperion in detail is probably a spoiler for at least the first book, but I will say that it's an excuse to embed versions of literary characters into the story and works about as well as most such excuses (not very). The characters in question are an E.E. "Doc" Smith mash-up, a Monkey King mash-up, and a number of other characters that are obviously references to something but for whom I lack enough hints to place (which is frustrating). Thankfully we get far less human politics and a decent amount of Arena world-building in this installment. Hyperion plays a role, but mostly as foreshadowing for the next volume and the cause of a surprising interaction with Arena rules. One of the interesting wrinkles of this series is that humanity have an odd edge against the other civilizations in part because we're borderline insane sociopaths from the perspective of the established powers. That's an old science fiction trope, but I prefer it to the Campbell-style belief in inherent human superiority. Old science fiction tropes are what you need to be in the mood for to enjoy this series. This is an unapologetic and intentional throwback to early pulp: individuals who can be trusted with the entire future of humanity because they're just that moral, super-science, psychic warfare, and even coruscating beams that would make E.E. "Doc" Smith proud. It's an occasionally glorious but mostly silly pile of technobabble, but Spoor takes advantage of the weird, constructed nature of the Arena to provide more complex rules than competitive superlatives. The trick is that while this is certainly science fiction pulp, it's also a sort of isekai novel. There's a lot of anime and manga influence just beneath the surface. I'm not sure why it never occurred to me before reading this series that melodramatic anime and old SF pulps have substantial aesthetic overlap, but of course they do. I loved the Star Blazers translated anime that I watched as a kid precisely because it had the sort of dramatic set pieces that make the Lensman novels so much fun. There is a bit too much Wu Kong in this book for me (although the character is growing on me a little), and some of the maneuvering around the mysterious new Arena actor drags on longer than was ideal, but the climax is great stuff if you're in the mood for dramatic pulp adventure. The politics do not bear close examination and the writing is serviceable at best, but something about this series is just fun. I liked this book much better than Spheres of Influence, although I wish Spoor would stop being so coy about the nature of the Arena and give us more substantial revelations. I'm also now tempted to re-read Lensman, which is probably a horrible idea. (Spoor leaves the sexism out of his modern pulp.) If you got through Spheres of Influence with your curiosity about the Arena intact, consider this one when you're in the mood for modern pulp, although don't expect any huge revelations. It's not the best-written book, but it sits squarely in the center of a genre and mood that's otherwise a bit hard to find. Followed by the Kickstarter-funded Shadows of Hyperion, which sadly looks like it's going to concentrate on the Hyperion Project again. I will probably pick that up... eventually. Rating: 6 out of 10

Louis-Philippe V ronneau: 2025 A Musical Retrospective

2026 already! The winter weather here has really been beautiful and I always enjoy this time of year. Writing this yearly musical retrospective has now become a beloved tradition of mine1 and I enjoy retracing the year's various events through albums I listened to and concerts I went to. Albums In 2025, I added 141 new albums to my collection, around 60% more than last year's haul. I think this might have been too much? I feel like I didn't have time to properly enjoy all of them and as such, I decided to slow down my acquisition spree sometimes in early December, around the time I normally do the complete opposite. This year again, I bought the vast majority of my music on Bandcamp. Most of the other albums I bought as CDs and ripped them. Concerts In 2025, I went to the following 25 (!!) concerts: Although I haven't touched metalfinder's code in a good while, my instance still works very well and I get the occasional match when a big-name artist in my collection comes in town. Most the venues that advertise on Bandsintown are tied to Ticketmaster though, which means most underground artists (i.e. most of the music I listen to) end up playing elsewhere. As such, shout out again to the Gancio project and to the folks running the Montreal instance. It continues to be a smash hit and most of the interesting concerts end up being advertised there. See you all in 2026!

  1. see the 2022, 2023 and 2024 entries

2 January 2026

Joachim Breitner: Seemingly impossible programs in Lean

In 2007, Martin Escardo wrote a often-read blog post about Seemingly impossible functional programs . One such seemingly impossible function is find, which takes a predicate on infinite sequences of bits, and returns an infinite sequence for which that predicate hold (unless the predicate is just always false, in which case it returns some arbitrary sequence). Inspired by conversations with and experiments by Massin Guerdi at the dinner of LeaningIn 2025 in Berlin (yes, this blog post has been in my pipeline for far too long), I wanted to play around these concepts in Lean. Let s represent infinite sequences of bits as functions from Nat to Bit, and give them a nice name, and some basic functionality, including a binary operator for consing an element to the front:
import Mathlib.Data.Nat.Find
abbrev Bit := Bool
def Cantor : Type := Nat   Bit
def Cantor.head (a : Cantor) : Bit := a 0
def Cantor.tail (a : Cantor) : Cantor := fun i => a (i + 1)
@[simp, grind] def Cantor.cons (x : Bit) (a : Cantor) : Cantor
    0 => x
    i+1 => a i
infix:60 " # " => Cantor.cons
With this in place, we can write Escardo s function in Lean. His blog post discusses a few variants; I ll focus on just one of them:
mutual
  partial def forsome (p : Cantor   Bool) : Bool :=
    p (find p)
  partial def find (p : Cantor   Bool) : Cantor :=
    have b := forsome (fun a => p (true # a))
    (b # find (fun a => p (b # a)))
end
We define find together with forsome, which checks if the predicate p holds for any sequence. Using that find sets the first element of the result to true if there exists a squence starting with true, else to false, and then tries to find the rest of the sequence. It is a bit of a brian twiter that this code works, but it does:
def fifth_false : Cantor   Bool := fun a => not (a 5)
/-- info: [true, true, true, true, true, false, true, true, true, true] -/
#guard_msgs in
#eval List.ofFn (fun (i : Fin 10) => find fifth_false i)
Of course, in Lean we don t just want to define these functions, but we want to prove that they do what we expect them to do. Above we defined them as partial functions, even though we hope that they are not actually partial: The partial keyword means that we don t have to do a termination proof, but also that we cannot prove anything about these functions. So can we convince Lean that these functions are total after all? We can, but it s a bit of a puzzle, and we have to adjust the definitions. First of all, these seemingly impossible functions are only possible because we assume that the predicate we pass to it, p, is computable and total. This is where the whole magic comes from, and I recommend to read Escardo s blog posts and papers for more on this fascinating topic. In particular, you will learn that a predicate on Cantor that is computable and total necessarily only looks at some initial fragment of the sequence. The length of that prefix is called the modulus . So if we hope to prove termination of find and forsome, we have to restrict their argument p to only such computable predicates. To that end I introduce HasModulus and the subtype of predicates on Cantor that have such a modulus:
-- Extensional (!) modulus of uniform continuity
def HasModulus (p : Cantor    ) :=   n,   a b : Cantor, (  i < n, a i = b i)   p a = p b
@[ext] structure CantorPred where
  pred : Cantor   Bool
  hasModulus : HasModulus pred
The modulus of such a predicate is now the least prefix lenght that determines the predicate. In particular, if the modulus is zero, the predicate is constant:
namespace CantorPred
variable (p : CantorPred)
noncomputable def modulus : Nat :=
  open Classical in Nat.find p.hasModulus
theorem eq_of_modulus :  a b : Cantor, (  i < p.modulus, a i = b i)   p a = p b := by
  open Classical in
  unfold modulus
  exact Nat.find_spec p.hasModulus
theorem eq_of_modulus_eq_0 (hm : p.modulus = 0) :   a b, p a = p b := by
  intro a b
  apply p.eq_of_modulus
  simp [hm]
Because we want to work with CantorPred and not Cantor Bool I have to define some operations on that new type; in particular the cons element before predicate operation that we saw above in find:
def comp_cons (b : Bit) : CantorPred where
  pred := fun a => p (b # a)
  hasModulus := by
    obtain  n, h_n  := p.hasModulus
    cases n with
      zero => exists 0; grind
      succ m =>
      exists m
      intro a b heq
      simp
      apply h_n
      intro i hi
      cases i
        rfl
        grind
@[simp, grind =] theorem comp_cons_pred (x : Bit) (a : Cantor) :
  (p.comp_cons x) a = p (x # a) := rfl
For this operation we know that the modulus decreases (if it wasn t already zero):
theorem comp_cons_modulus (x : Bit) :
    (p.comp_cons x).modulus   p.modulus - 1 := by
  open Classical in
  apply Nat.find_le
  intro a b hab
  apply p.eq_of_modulus
  cases hh : p.modulus
    simp
    intro i hi
    cases i
      grind
      grind
grind_pattern comp_cons_modulus => (p.comp_cons x).modulus
We can rewrite the find function above to use these operations:
mutual
  partial def forsome (p : CantorPred) : Bool := p (find p)
  partial def find (p : CantorPred) : Cantor := fun i =>
    have b := forsome (p.comp_cons true)
    (b # find (p.comp_cons b)) i
end
I have also eta-expanded the Cantor function returned by find; there is now a fun i => i around the body. We ll shortly see why that is needed. Now have everything in place to attempt a termination proof. Before we do that proof, we could step back and try to come up with an informal termination argument. We can express all this reasoning as a termination measure in the form of a lexicographic triple. The 0 and 1 in the middle component mean that for zero modulus, we can call forsome from find for free .
mutual
  def forsome (p : CantorPred) : Bool := p (find p)
  termination_by (p.modulus, if p.modulus = 0 then 0 else 1, 0)
  decreasing_by grind
  def find (p : CantorPred) : Cantor := fun i =>
    have b := forsome (p.comp_cons true)
    (b # find (p.comp_cons b)) i
  termination_by i => (p.modulus, if p.modulus = 0 then 1 else 0, i)
  decreasing_by all_goals grind
end
The termination proof doesn t go through just yet: Lean is not able to see that (_ # p) i will call p with i - 1, and it does not see that p (find p) only uses find p if the modulus of p is non-zero. We can use the wf_preprocess feature to tell it about that: The following theorem replaces a call to p f, where p is a function parameter, with the slightly more complex but provably equivalent expression on the right, where the call to f is no in the else branch of an if-then-else and thus has p.modulus = 0 in scope:
@[wf_preprocess]
theorem coe_wf (p : CantorPred) :
    (wfParam p) f = p (if _ : p.modulus = 0 then fun _ => false else f) := by
  split
  next h => apply p.eq_of_modulus_eq_0 h
  next => rfl
And similarly we replace (_ # p) i with a variant that extend the context with information on how p is called:
def cantor_cons' (x : Bit) (i : Nat) (a :   j, j + 1 = i   Bit) : Bit :=
  match i with
    0 => x
    j + 1 => a j (by grind)
@[wf_preprocess] theorem cantor_cons_congr (b : Bit) (a : Cantor) (i : Nat) :
  (b # a) i = cantor_cons' b i (fun j _ => a j) := by cases i <;> rfl
After these declarations, the above definition of forsome and find goes through! It remains to now prove that they do what they should, by a simple induction on the modulus of p:
@[simp, grind =] theorem tail_cons_eq (a : Cantor) : (x # a).tail = a := by
  funext i; simp [Cantor.tail, Cantor.cons]
@[simp, grind =] theorem head_cons_tail_eq (a : Cantor) : a.head # a.tail = a := by
  funext i; cases i <;> rfl
theorem find_correct (p : CantorPred) (h_exists :   a, p a) : p (find p) := by
  by_cases h0 : p.modulus = 0
    obtain  a, h_a  := h_exists
    rw [  h_a]
    apply p.eq_of_modulus_eq_0 h0
    rw [find.eq_unfold, forsome.eq_unfold]
    dsimp -zeta
    extract_lets b
    change p (_ # _)
    by_cases htrue :   a, p (true # a)
    next =>
      have := find_correct (p.comp_cons true) htrue
      grind
    next =>
      have : b = false := by grind
      clear_value b; subst b
      have hfalse :   a, p (false # a) := by
        obtain  a, h_a  := h_exists
        cases h : a.head
          exists Cantor.tail a
          grind
          exfalso
          apply htrue
          exists Cantor.tail a
          grind
      clear h_exists
      exact find_correct (p.comp_cons false) hfalse
termination_by p.modulus
decreasing_by all_goals grind
theorem forsome_correct (p : CantorPred) :
    forsome p   (  a, p a) where
  mp hfind := by unfold forsome at hfind; exists find p
  mpr hex := by unfold forsome; exact find_correct p hex
This is pretty nice! However there is more to do. For example, Escardo has a massively faster variant of find that we can implement as a partial function in Lean:
def findBit (p : Bit   Bool) : Bit :=
  if p false then false else true
def branch (x : Bit) (l r : Cantor) : Cantor :=
  fun n =>
    if n = 0      then x
    else if 2   n then r ((n - 2) / 2)
                  else l ((n - 1) / 2)
mutual
  partial def forsome (p : Cantor -> Bool) : Bool :=
    p (find p)
  partial def find (p : Cantor -> Bool) : Cantor :=
    let x := findBit (fun x => forsome (fun l => forsome (fun r => p (branch x l r))))
    let l := find (fun l => forsome (fun r => p (branch x l r)))
    let r := find (fun r => p (branch x l r))
    branch x l r
end
But can we get this past Lean s termination checker? In order to prove that the modulus of p is decreasing, we d have to know that, for example, find (fun r => p (branch x l r)) is behaving nicely. Unforunately, it is rather hard to do termination proof for a function that relies on the behaviour of the function itself. So I ll leave this open as a future exercise. I have dumped the code for this post at https://github.com/nomeata/lean-cantor.

Ben Hutchings: FOSS activity in December 2025

Birger Schacht: Status update, December 2025

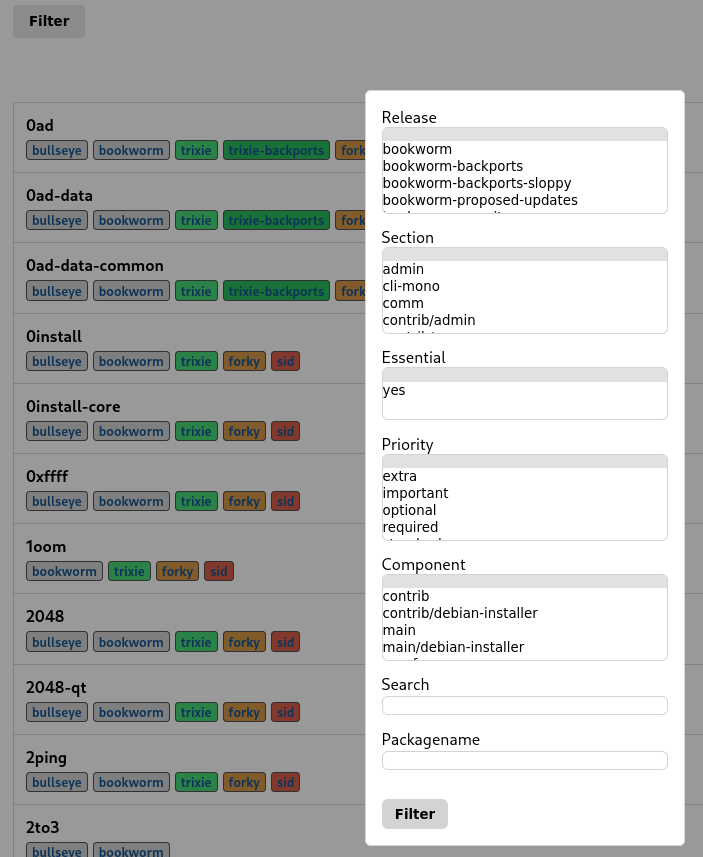
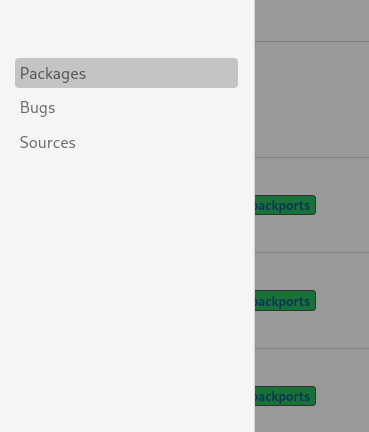
December 2025 started off with a nice event, namely a small gathering of Vienna based DDs. Some of us were at DebConf25 in Brest and we thought it might be nice to have a get-together of DDs in Vienna. A couple of months after DebConf25 I picked up the idea, let someone else ping the DDs, booked a table at a local cafe and in the end we were a group of 6 DDs. It was nice to put faces to names, names to nicknames and to hear what people are up to. We are definitely planning to repeat that! December also ended with a meeting of nerds: the 39th Chaos Communication Congress in Hamburg. As usual, I did not really have that much time to watch many talks. I tend to bookmark a lot of them in the scheduling app in advance, but once I m at the congress the social aspect is much more important and I try to only attend workshop or talks that are not recorded. Watching the recordings afterward is possible anyway (and I actually try to do that!). There was also a Debian Developers meetup at day 3, combined with the usual time confusion regarding UTC and CET. We talked about having a Debian table at 40c3, so maybe the timezone won t be that much of a problem in the next time. Two talks I recommend are CSS Clicker Training: Making games in a styling language and To sign or not to sign: Practical vulnerabilities in GPG & friends. Regarding package uploads this month did not happen that much, I only uploaded the new version (0.9.3) of labwc. I created two new releases for carl. First a 0.5 release that adds Today and SpecifiedDate as properties. I forwarded an issue about dates not being parsed correctly to the icalendar issue tracker and this was fixed a couple of days later (thanks!). I then created a 0.5.1 release containing that fix. I also started planning to move the carl repository back to codeberg, because Github feels more and more like an AI Slop platform. The work on debiverse also continued. I removed the tailwind CSS framework, and it was actually not that hard to reproduce all the needed CSS classes with custom CSS. I think that CSS frameworks make sense to a point, but once you start implementing stuff that the framework does not provide, it is easier if everything comes out of one set of rules. There was also the article Vanilla CSS is all you need which goes into the same direction and which gave me some ideas how to organize the CSS directives. I also refactored the filter generation for the listing filters and the HTML filter form is now generated from the FastAPI Query Parameter Model. Screenshot of the filter form For navigation I implemented a sidebar, that is hidden on small screens but can be toggled using a burger menu. Screenshot of the navigation bar I also stumbled upon An uncomfortable but necessary discussion about the Debian bug tracker, which raises some valid points. I think debiverse could be a solution to the first point of What could be a way forward? , namely: Create a new web service that parses the existing bug data and displays it in a rich format . But if there is ever another way than email to interact with bugs.debian.org, than this approach should not rely on passing on the commands via mail. If I click a button in a web interface to raise the severity, the severity should be raised right away - not 10 minutes later when the email is received. I think the individual parts (web, database, mail interface) should be decoupled and talk to each other via APIs.

1 January 2026

Dima Kogan: Using libpython3 without linking it in; and old Python, g++ compatibility patches

I just released mrcal 2.5; much more about that in a future post. Here, I'd like to talk about some implementation details.

libpython3 and linking
mrcal is a C library and a Python library. Much of mrcal itself interfaces the C and Python libraries. And it is common for external libraries to want to pass Python mrcal.cameramodel objects to their C code. The obvious way to do this is in a converter function in an O& argument to PyArg_ParseTupleAndKeywords(). I wrote this mrcal_cameramodel_converter() function, which opened a whole can of worms when thinking about the compiling and linking and distribution of this thing. mrcal_cameramodel_converter() is meant to be called by code that implements Python-wrapping of C code. This function will be called by the PyArg_ParseTupleAndKeywords() Python library function, and it uses the Python C API itself. Since it uses the Python C API, it would normally link against libpython. However:
  • The natural place to distribute this is in libmrcal.so, but this library doesn't touch Python, and I'd rather not pull in all of libpython for this utility function, even in the 99% case when that function won't even be called
  • In some cases linking to libpython actually breaks things, so I never do that anymore anyway. This is fine: since this code will only ever be called by libpython itself, we're guaranteed that libpython will already be loaded, and we don't need to ask for it.
OK, let's not link to libpython then. But if we do that, we're going to have unresolved references to our libpython calls, and the loader will complain when loading libmrcal.so, even if we're not actually calling those functions. This has an obvious solution: the references to the libpython calls should be marked weak. That won't generate unresolved-reference errors, and everything will be great. OK, how do we mark things weak? There're two usual methods:
  1. We mark the declaration (or definition?) or the relevant functions with __attribute__((weak))
  2. We weaken the symbols after the compile with objcopy --weaken.
Method 1 is more work: I don't want to keep track of what Python API calls I'm actually making. This is non-trivial, because some of the Py_...() invocations in my code are actually macros that call functions internally that I must weaken. Furthermore, all the functions are declared in Python.h that I don't control. I can re-declare stuff with __attribute__((weak)), but then I have to match the prototypes. And I have to hope that re-declaring these will make __attribute__((weak)) actually work. So clearly I want method 2. I implemented it:
python-cameramodel-converter.o: %.o:%.c
        $(c_build_rule); mv $@ _$@
        $(OBJCOPY) --wildcard --weaken-symbol='Py*' --weaken-symbol='_Py*' _$@ $@
Works great on my machine! But doesn't work on other people's machines. Because only the most recent objcopy tool actually works to weaken references. Apparently the older tools only weaken definitions, which isn't useful to me, and the tool only started handling references very recently. Well that sucks. I guess I will need to mark the symbols with __attribute__((weak)) after all. I use the nm tool to find the symbols that should be weakened, and I apply the attribute with this macro:
#define WEAKEN(f) extern __typeof__(f) f __attribute__((weak));
The prototypes are handled by __typeof__. So are we done? With gcc, we are done. With clang we are not done. Apparently this macro does not weaken symbols generated by inline function calls if using clang I have no idea if this is a bug. The Python internal machinery has some of these, so this doesn't weaken all the symbols. I give up on the people that both have a too-old objcopy and are using clang, and declare victory. So the logic ends up being:
  1. Compile
  2. objcopy --weaken
  3. nm to find the non-weak Python references
  4. If there aren't any, our objcopy call worked and we're done!
  5. Otherwise, compile again, but explicitly asking to weaken those symbols
  6. nm again to see if the compiler didn't do it
  7. If any non-weak references still remain, complain and give up.
Whew. This logic appears here and here. There were even more things to deal with here: calling nm and objcopy needed special attention and build-system support in case we were cross-building. I took care of it in mrbuild. This worked for a while. Until the converter code started to fail. Because .

Supporting old Python
. I was using PyTuple_GET_ITEM(). This is a macro to access PyTupleObject data. So the layout of PyTupleObject ended up encoded in libmrcal.so. But apparently this wasn't stable, and changed between Python3.13 and Python3.14. As described above, I'm not linking to libpython, so there's no NEEDED tag to make sure we pull in the right version. The solution was to call the PyTuple_GetItem() function instead. This is unsatisfying, and means that in theory other stuff here might stop working in some Python 3.future, but I'm ready to move on for now. There were other annoying gymnastics that had to be performed to make this work with old-but-not-super old tooling. The Python people deprecated PyModule_AddObject(), and added PyModule_Add() as a replacement. I want to support Pythons before and after this happened, so I needed some if statements. Today the old function still works, but eventually it will stop, and I will have needed to do this typing sooner or later.

Supporting old C++ compilers
mrcal is a C project, but it is common for people to want to #include the headers from C++. I widely use C99 designated initializers (27-years old in C!), which causes issues with not-very-old C++ compilers. I worked around this initialization in one spot, and disabled it a feature for a too-old compiler in another spot. Fortunately, semi-recent tooling supports my usages, so this is becoming a non-issue as time goes on.

Russ Allbery: 2025 Book Reading in Review

In 2025, I finished and reviewed 32 books, not counting another five books I've finished but not yet reviewed and which will therefore roll over to 2026. This was not a great reading year, although not my worst reading year since I started keeping track. I'm not entirely sure why, although part of the explanation was that I hit a bad stretch of books in spring of 2025 and got into a bit of a reading slump. Mostly, though, I shifted a lot of reading this year to short non-fiction (newsletters and doom-scrolling) and spent rather more time than I intended watching YouTube videos, and sadly each hour in the day can only be allocated one way. This year felt a bit like a holding pattern. I have some hopes of being more proactive and intentional in 2026. I'm still working on finding a good balance between all of my hobbies and the enjoyment of mindless entertainment. The best book I read this year was also the last book I reviewed (and yes, I snuck the review under the wire for that reason): Bethany Jacobs's This Brutal Moon, the conclusion of the Kindom Trilogy that started with These Burning Stars. I thought the first two books of the series were interesting but flawed, but the conclusion blew me away and improved the entire trilogy in retrospect. Like all books I rate 10 out of 10, I'm sure a large part of my reaction is idiosyncratic, but two friends of mine also loved the conclusion so it's not just me. The stand-out non-fiction book of the year was Rory Stewart's Politics on the Edge. I have a lot of disagreements with Stewart's political positions (the more I listen to him, the more disagreements I find), but he is an excellent memoirist who skewers the banality, superficiality, and contempt for competence that has become so prevailing in centrist and right-wing politics. It's hard not to read this book and despair of electoralism and the current structures of governments, but it's bracing to know that even some people I disagree with believe in the value of expertise. I also finished Suzanne Palmer's excellent Finder Chronicles series, reading The Scavenger Door and Ghostdrift. This series is some of the best science fiction I've read in a long time and I'm sad it is over (at least for now). Palmer has a new, unrelated book coming in 2026 (Ode to the Half-Broken), and I'm looking forward to reading that. This year, I experimented with re-reading books I had already reviewed for the first time since I started writing reviews. After my reading slump, I felt like revisiting something I knew I liked, and therefore re-read C.J. Cherryh's Cyteen and Regenesis. Cyteen mostly held up, but Regenesis was worse than I had remembered. I experimented with a way to add on to my previous reviews, but I didn't like the results and the whole process of re-reading and re-reviewing annoyed me. I'm counting this as a failed experiment, which means I've still not solved the problem of how to revisit series that I read long enough ago that I want to re-read them before picking up the new book. (You may have noticed that I've not read the new Jacqueline Carey Kushiel novel, for example.) You may have also noticed that I didn't start a new series re-read, or continue my semi-in-progress re-reads of Mercedes Lackey or David Eddings. I have tentative plans to kick off a new series re-read in 2026, but I'm not ready to commit to that yet. As always, I have no firm numeric goals for the next year, but I hope to avoid another reading slump and drag my reading attention back from lower-quality and mostly-depressing material in 2026. The full analysis includes some additional personal reading statistics, probably only of interest to me.
Russ Allbery: Review: This Brutal Moon

Review: This Brutal Moon, by Bethany Jacobs
Series: Kindom Trilogy #3
Publisher: Orbit
Copyright: December 2025
ISBN: 0-316-46373-6
Format: Kindle
Pages: 497
This Brutal Moon is a science fiction thriller with bits of cyberpunk and space opera. It concludes the trilogy begun with These Burning Stars. The three books tell one story in three volumes, and ideally you would read all three in close succession. There is a massive twist in the first book that I am still not trying to spoil, so please forgive some vague description. At the conclusion of These Burning Stars, Jacobs had moved a lot of pieces into position, but it was not yet clear to me where the plot was going, or even if it would come to a solid ending in three volumes as promised by the series title. It does. This Brutal Moon opens with some of the political maneuvering that characterized These Burning Stars, but once things start happening, the reader gets all of the action they could wish for and then some. I am pleased to report that, at least as far as I'm concerned, Jacobs nails the ending. Not only is it deeply satisfying, the characterization in this book is so good, and adds so smoothly to the characterization of the previous books, that I saw the whole series in a new light. I thought this was one of the best science fiction series finales I've ever read. Take that with a grain of salt, since some of those reasons are specific to me and the mood I was in when I read it, but this is fantastic stuff. There is a lot of action at the climax of this book, split across at least four vantage points and linked in a grand strategy with chaotic surprises. I kept all of the pieces straight and understood how they were linked thanks to Jacobs's clear narration, which is impressive given the number of pieces in motion. That's not the heart of this book, though. The action climax is payoff for the readers who want to see some ass-kicking, and it does contain some moving and memorable moments, but it relies on some questionable villain behavior and a convenient plot device introduced only in this volume. The action-thriller payoff is competent but not, I think, outstanding. What put this book into a category of its own were the characters, and specifically how Jacobs assembles sweeping political consequences from characters who, each alone, would never have brought about such a thing, and in some cases had little desire for it. Looking back on the trilogy, I think Jacobs has captured, among all of the violence and action-movie combat and space-opera politics, the understanding that political upheaval is a relay race. The people who have the personalities to start it don't have the personality required to nurture it or supply it, and those who can end it are yet again different. This series is a fascinating catalog of political actors the instigator, the idealist, the pragmatist, the soldier, the one who supports her friends, and several varieties and intensities of leaders and it respects all of them without anointing any of them as the One True Revolutionary. The characters are larger than life, yes, and this series isn't going to win awards for gritty realism, but it's saying something satisfyingly complex about where we find courage and how a cause is pushed forward by different people with different skills and emotions at different points in time. Sometimes accidentally, and often in entirely unexpected ways. As before, the main story is interwoven with flashbacks. This time, we finally see the full story of the destruction of the moon of Jeve. The reader has known about this since the first volume, but Jacobs has a few more secrets to show (including, I will admit, setting up a plot device) and some pointed commentary on resource extraction economies. I think this part of the book was a bit obviously constructed, although the characterization was great and the visible junction points of the plot didn't stop me from enjoying the thrill when the pieces came together. But the best part of this book was the fact there was 10% of it left after the climax. Jacobs wrote an actual denouement, and it was everything I wanted and then some. We get proper story conclusions for each of the characters, several powerful emotional gut punches, some remarkably subtle and thoughtful discussion of political construction for a series that tended more towards space-opera action, and a conclusion for the primary series relationship that may not be to every reader's taste but was utterly, perfectly, beautifully correct for mine. I spent a whole lot of the last fifty pages of this book trying not to cry, in the best way. The character evolution over the course of this series is simply superb. Each character ages like fine wine, developing more depth, more nuance, but without merging. They become more themselves, which is an impressive feat across at least four very different major characters. You can see the vulnerabilities and know what put them there, you can see the strengths they developed to compensate, and you can see why they need the support the other characters provide. And each of them is so delightfully different. This was so good. This was so precisely the type of story that I was in the mood for, with just the type of tenderness for its characters that I wanted, that I am certain I am not objective about it. It will be one of those books where other people will complain about flaws that I didn't see or didn't care about because it was doing the things I wanted from it so perfectly. It's so good that it elevated the entire trilogy; the journey was so worth the ending. I'm afraid this review will be less than helpful because it's mostly nonspecific raving. This series is such a spoiler minefield that I'd need a full spoiler review to be specific, but my reaction is so driven by emotion that I'm not sure that would help if the characters didn't strike you the way that they struck me. I think the best advice I can offer is to say that if you liked the emotional tone of the end of These Burning Stars (not the big plot twist, the character reaction to the political goal that you learn drove the plot), stick with the series, because that's a sign of the questions Jacobs is asking. If you didn't like the characters at the end (not the middle) of the first novel, bail out, because you're going to get a lot more of that. Highly, highly recommended, and the best thing I've read all year, with the caveats that you should read the content notes, and that some people are going to bounce off this series because it's too intense and melodramatic. That intensity will not let up, so if that's not what you're in the mood for, wait on this trilogy until you are. Content notes: Graphic violence, torture, mentions of off-screen child sexual assault, a graphic corpse, and a whole lot of trauma. One somewhat grumbly postscript: This is the sort of book where I need to not read other people's reviews because I'll get too defensive of it (it's just a book I liked!). But there is one bit of review commentary I've seen about the trilogy that annoys me enough I have to mention it. Other reviewers seem to be latching on to the Jeveni (an ethnic group in the trilogy) as Space Jews and then having various feelings about that. I can see some parallels, I'm not going to say that it's completely wrong, but I also beg people to read about a fictional oppressed ethnic and religious minority and not immediately think "oh, they must be stand-ins for Jews." That's kind of weird? And people from the US, in particular, perhaps should not read a story about an ethnic group enslaved due to their productive skill and economic value and think "they must be analogous to Jews, there are no other possible parallels here." There are a lot of other comparisons that can be made, including to the commonalities between the methods many different oppressed minorities have used to survive and preserve their culture. Rating: 10 out of 10
Daniel Baumann: P r ch storage (in Western Europe)

The majority of P r ch ( ) is stored in Asia (predominantly China, some in Malaysia and Taiwan) because of its climatic conditions:
  • warm (~30 C)
  • humid (~75% RH)
  • stable (comparatively small day to day, day to night, and seasonal differences)
These are ideal for ageing and allow efficient storage in simple storehouses, usually without the need for any air conditioning. The climate in Western European countries is significantly colder, drier, and more variable. However, residential houses offers throughout the year a warm (~20 C), humid (~50% RH), and stable baseline to start with. High quality, long term storage and ageing is possible too with some of the Asian procedures slightly adjusted for the local conditions. Nevertheless, fast accelerated ageing still doesn t work here (even with massive climate control). Personally I prefer the balanced, natural storage over the classical wet or dry , or the mixed traditional storage (of course all storage types are not that meaningful as they are all relative terms anyway). Also I don t like strong fermentation either (P r is not my favourite tea, I only drink it in the 3 months of winter). Therefore, my intention is primarily to preserve the tea while it continues to age normally, keep it in optimal drinking condition and don t rush its fermentation. The value of correct storage is of great importance and has a big effect on P r, and is often overlooked and underrated. Here s a short summary on how to store P r ch (in Western Europe).
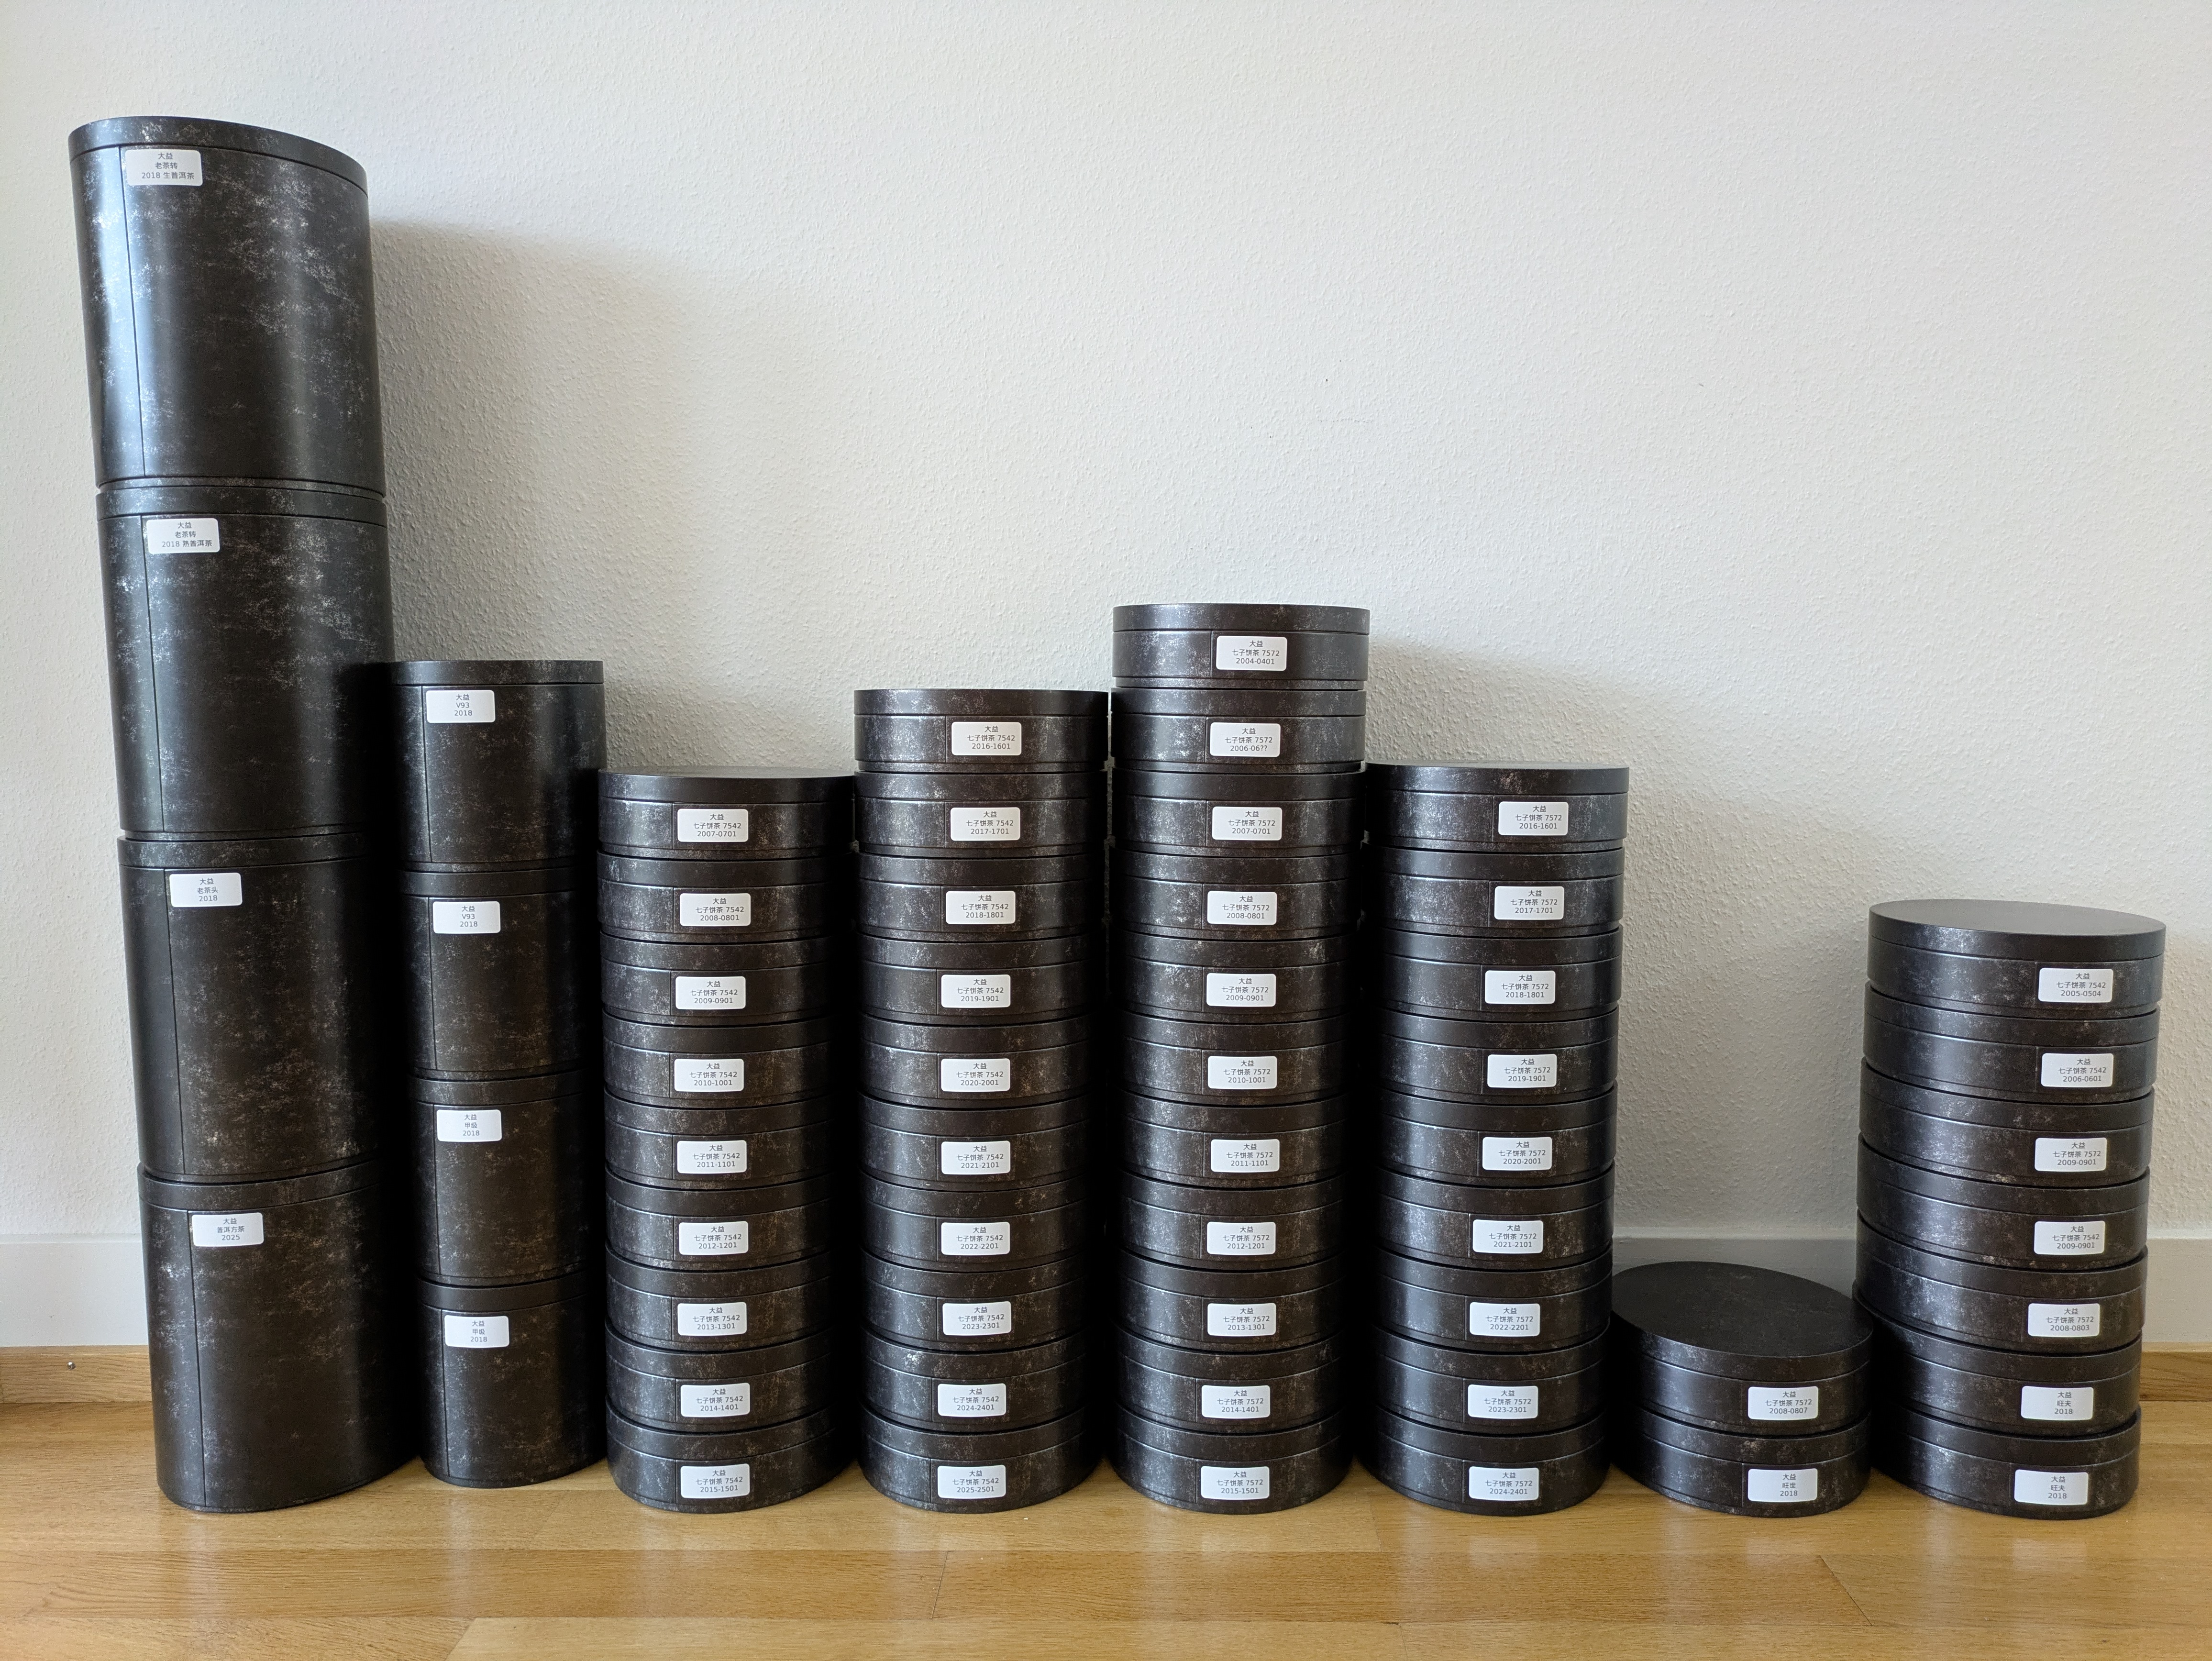
P ' r ch  storage (in Western Europe) Image: some D y P r ch stored at home
1. Location
1.1 No light Choose a location with neither direct nor indirect sunlight (= ultraviolet radiation) exposure:
  • direct sunlight damages organic material ( bleeching )
  • indirect sunlight by heating up the containers inbalances the microclimate ( suppression )
1.2 No odors Choose a location with neither direct nor indirect odor exposure:
  • direct odor immissions (like incense, food, air polution, etc.) makes the tea undrinkable
  • indirect odor immissions (especially other teas stored next to it) taint the taste and dilute the flavours
Always use individual containers for each tea, store only identical tea of the same year and batch in the same container. Idealy never store one cake, brick or tuo on its own, buy multiples and store them together for better ageing.
2. Climate
2.1 Consistent temperature Use a location with no interference from any devices or structures next to it:
  • use an regular indoor location for mild temperature curves (i.e. no attics with large day/night temperature differences)
  • aim for >= 20 C average temperature for natural storage (i.e. no cold basements)
  • don t use a place next to any heat dissipating devices (like radiators, computers, etc.)
  • don t use a place next to an outside facing wall
  • always leave 5 to 10cm distance to a wall for air to circulate (generally prevents mold on the wall but also isolates the containers further from possible immissions)
As consistent temperature as possible allows even and steady fermentation. However, neither air conditioning or filtering is needed. Regular day to day, day to night, and season to season fluctuations are balanced out fine with otherwise correct indoor storage. Also humidity control is much more important for storage and ageing, and much less forgiving than temperature control.
2.2 Consistent humidity Use humidity control packs to ensure a stable humidity level:
  • aim for ~65% RH
Lower than 60% RH will (completely) dry out the tea, higher than 70% RH increases chances for mold.
3. Equipment
3.1 Proper containers Use containers that are long term available and that are easily stackable, both in form and dimensions as well as load-bearing capacity. They should be inexpensive, otherwise it s most likely scam (there are people selling snake-oil containers specifically for tea storage). For long term storage and ageing:
  • never use plastic: they leak chemicals over time (no tupperdors , mylar and zip lock bags, etc.)
  • never use cardboard or bamboo: they let to much air in, absorb too much humity and dry to slow
  • never use wood: they emit odors (no humidors)
  • never use clay: they absorb all humidity and dry out the tea (glazed or porcelain urns are acceptable for short term storage)
Always use sealed but not air tight, cleaned steal cans (i.e. with no oil residues from manufacturing; such as these).
3.2 Proper humidity control Use two-way humidity control packs to either absorb or add moisture depending on the needs:
  • use humidity control pack(s) in every container
  • use one 60g pack (such as these) per 500g of tea
3.3 Proper labels Put labels on the outside of the containers to not need to open them to know what is inside and disturbe the ageing:
  • write at least manufacturer and name, pressing year, and batch number on the label (such as these)
  • if desired and not otherwise kept track already elsewhere, add additional information such as the amount of items, weights, previous storage location/type, date of purchase, vendor, or price, etc.
3.4 Proper monitoring Measuring and checking temperature and humidity regularly prevents storage parameters turning bad going unnoticed:
  • put temperature and humidity measurement sensors (such as these) inside some of the containers (e.g. at least one in every different size/type of container)
  • keep at least one temperature and humidity measurement sensor next to the containers on the outside to monitor the storage location
4. Storage
4.1 Continued maintenance Before beginning to initially store a new tea, let it acclimatize for 2h after unpacking from transport (or longer if temperature differences between indoors and outdoors are high, i.e. in winter). Then continuesly:
  • once a month briefly air all containers for a minute or two
  • once a month check for mold, just to be safe
  • every 3 to 6 months check all humidity control packs for need of replacement
  • monitor battery life of temperature and humidity measurement sensors
Humidity control packs can be recharged (usually voiding any warranty) by submerging them for 2 days in distilled water and 4 hours drying on paper towl afterwards. Check with a weight scale after recharging, they should regain their original weight (e.g. 60g plus ~2 to 5g for the packaging).
Finally With a correct P r ch storage:
  • beginn to drink Sh ng P r ( ) roughly after about 10-15 years, or later
  • beginn to drink Sh u P r ( ) roughly after about 3-5 years, or later
Prepare the tea by breaking it into, or breaking off from it, ~5 to 10g pieces about 1 to 3 months ahead of drinking and consider increase humidity to 70% RH during that time. 2026

31 December 2025

Bits from Debian: DebConf26 dates announced

Alt Debconf26 by Romina Molina As announced in Brest, France, in July, the Debian Conference is heading to Santa Fe, Argentina. The DebConf26 team and the local organizers team in Argentina are excited to announce Debconf26 dates, the 27th edition of the Debian Developers and Contributors Conference: DebCamp, the annual hacking session, will run from Monday July 13th to Sunday to July 19th 2026, followed by DebConf from Monday July 20th to Saturday July 25th 2026. For all those who wish to meet us in Santa Fe, the next step will be the opening of registration on January 26, 2026. The call for proposals period for anyone wishing to submit a conference or event proposal will be launched on the same day. DebConf26 is looking for sponsors; if you are interested or think you know of others who would be willing to help, please have a look at our sponsorship page and get in touch with sponsors@debconf.org. About Debian The Debian Project was founded in 1993 by Ian Murdock to be a truly free community project. Since then the project has grown to be one of the largest and most influential Open Source projects. Thousands of volunteers from all over the world work together to create and maintain Debian software. Available in 70 languages, and supporting a huge range of computer types, Debian calls itself the universal operating system. About DebConf DebConf is the Debian Project's developer conference. In addition to a full schedule of technical, social and policy talks, DebConf provides an opportunity for developers, contributors and other interested people to meet in person and work together more closely. It has taken place annually since 2000 in locations as varied as Scotland, Bosnia and Herzegovina, India, Korea. More information about DebConf is available from https://debconf.org/. For further information, please visit the DebConf26 web page at https://debconf26.debconf.org/ or send mail to press@debian.org. Debconf26 is made possible by Proxmox and others.

Sergio Cipriano: Zero-Code Instrumentation of an Envoy TCP Proxy using eBPF

Zero-Code Instrumentation of an Envoy TCP Proxy using eBPF I recently had to debug an Envoy Network Load Balancer, and the options Envoy provides just weren't enough. We were seeing a small number of HTTP 499 errors caused by latency somewhere in our cloud, but it wasn't clear what the bottleneck was. As a result, each team had to set up additional instrumentation to catch latency spikes and figure out what was going on. My team is responsible for the LBaaS product (Load Balancer as a Service) and, of course, we are the first suspects when this kind of problem appear. Before going for the current solution, I read a lot of Envoy's documentation. It is possible to enable access logs for Envoy, but they don't provide the information required for this debug. This is an example of the output:
[2025-12-08T20:44:49.918Z] "- - -" 0 - 78 223 1 - "-" "-" "-" "-" "172.18.0.2:8080"
I won't go into detail about the line above, since it's not possible to trace the request using access logs alone. Envoy also has OpenTelemetry tracing, which is perfect for understanding sources of latency. Unfortunatly, it is only available for Application Load Balancers. Most of the HTTP 499 were happening every 10 minutes, so we managed to get some of the requests with tcpdump, Wireshark and using http headers to filter the requests. This approach helped us reproduce and track down the problem, but it wasn't a great solution. We clearly needed better tools to catch this kind of issue the next time it happened. Therefore, I decided to try out OpenTelemetry eBPF Instrumentation, also referred to as OBI. I saw the announcement of Grafana Beyla before it was renamed to OBI, but I didn't have the time or a strong reason to try it out until now. Even then, I really liked the idea, and the possibility of using eBPF to solve this instrumentation problem had been in the back of my mind. OBI promises zero-code automatic instrumentation for Linux services using eBPF, so I put together a minimal setup to see how well it works.

Reproducible setup I used the following tools: Setting up a TCP Proxy with Envoy was straightforward:
static_resources:
  listeners:
  - name: go_server_listener
    address:
      socket_address:
        address: 0.0.0.0
        port_value: 8000
    filter_chains:
    - filters:
      - name: envoy.filters.network.tcp_proxy
        typed_config:
          "@type": type.googleapis.com/envoy.extensions.filters.network.tcp_proxy.v3.TcpProxy
          stat_prefix: go_server_tcp
          cluster: go_server_cluster
  clusters:
  - name: go_server_cluster
    connect_timeout: 1s
    type: LOGICAL_DNS
    load_assignment:
      cluster_name: go_server_cluster
      endpoints:
      - lb_endpoints:
        - endpoint:
            address:
              socket_address:
                address: target-backend
                port_value: 8080
This is the simplest Envoy TCP proxy configuration: a listener on port 8000 forwarding traffic to a backend running on port 8080. For the backend, I used a basic Go HTTP server:
package main

import (
    "fmt"
    "net/http"
)

func main()  
    http.Handle("/", http.FileServer(http.Dir(".")))

    server := http.Server Addr: ":8080" 

    fmt.Println("Starting server on :8080")
    panic(server.ListenAndServe())
 
Finally, I wrapped everything together with Docker Compose:
services:
  autoinstrumenter:
    image: otel/ebpf-instrument:main
    pid: "service:envoy"
    privileged: true
    environment:
      OTEL_EBPF_TRACE_PRINTER: text
      OTEL_EBPF_OPEN_PORT: 8000

  envoy:
    image: envoyproxy/envoy:v1.33-latest
    ports:
      - 8000:8000
    volumes:
      - ./envoy.yaml:/etc/envoy/envoy.yaml 
    depends_on:
      - target-backend
  
  target-backend:
    image: golang:1.22-alpine
    command: go run /app/backend.go
    volumes:
      - ./backend.go:/app/backend.go:ro
    expose:
      - 8080
OBI should output traces to the standard output similar to this when a HTTP request is made to Envoy:
2025-12-08 20:44:49.12884449 (305.572 s[305.572 s]) HTTPClient 200 GET /(/) [172.18.0.3 as envoy:36832]->[172.18.0.2 as localhost:8080] contentLen:78B responseLen:0B svc=[envoy generic] traceparent=[00-529458a2be271956134872668dc5ee47-6dba451ec8935e3e[06c7f817e6a5dae2]-01]
2025-12-08 20:44:49.12884449 (1.260901ms[366.65 s]) HTTP 200 GET /(/) [172.18.0.1 as 172.18.0.1:36282]->[172.18.0.3 as envoy:8000] contentLen:78B responseLen:223B svc=[envoy generic] traceparent=[00-529458a2be271956134872668dc5ee47-06c7f817e6a5dae2[0000000000000000]-01]
This is exactly what we needed, with zero-code. The above trace shows:
  • 2025-12-08 20:44:49.12884449: time of the trace.
  • (1.260901ms[366.65 s]): total response time for the request, with the actual internal execution time of the request (not counting the request enqueuing time).
  • HTTP 200 GET /: protocol, response code, HTTP method, and URL path.
  • [172.18.0.1 as 172.18.0.1:36282]->[172.18.0.3 as envoy:8000]: source and destination host:port. The initial request originates from my machine through the gateway (172.18.0.1), hits the Envoy (172.23.0.3), the proxy then forwards it to the backend application (172.23.0.2).
  • contentLen:78B: HTTP Content-Length. I used curl and the default request size for it is 78B.
  • responseLen:223B: Size of the response body.
  • svc=[envoy generic]: traced service.
  • traceparent: ids to trace the parent request. We can see that the Envoy makes a request to the target and this request has the other one as parent.
Let's add one more Envoy to show that it's also possible to track multiple services.
  envoy1:
    image: envoyproxy/envoy:v1.33-latest
    ports:
      - 9000:9000
    volumes:
      - ./envoy1.yaml:/etc/envoy/envoy.yaml
    depends_on:
      - envoy
The new Envoy will listen on port 9000 and forward the request to the other Envoy listening on port 8000. Now we just need to change OBI open port variable to look at a range:
OTEL_EBPF_OPEN_PORT: 8000-9000
And change the pid field of the autoinstrumenter service to use the host's PID namespace inside the container:
pid: host
This is the output I got after one curl:
2025-12-09 12:28:05.12912285 (2.202041ms[1.524713ms]) HTTP 200 GET /(/) [172.19.0.1 as 172.19.0.1:59030]->[172.19.0.5 as envoy:9000] contentLen:78B responseLen:223B svc=[envoy generic] traceparent=[00-69977bee0c2964b8fe53cdd16f8a9d19-856c9f700e73bf0d[0000000000000000]-01]
2025-12-09 12:28:05.12912285 (1.389336ms[1.389336ms]) HTTPClient 200 GET /(/) [172.19.0.5 as envoy:59806]->[172.19.0.4 as localhost:8000] contentLen:78B responseLen:0B svc=[envoy generic] traceparent=[00-69977bee0c2964b8fe53cdd16f8a9d19-caa7f1ad1c68fa77[856c9f700e73bf0d]-01]
2025-12-09 12:28:05.12912285 (1.5431ms[848.574 s]) HTTP 200 GET /(/) [172.19.0.5 as 172.19.0.5:59806]->[172.19.0.4 as envoy:8000] contentLen:78B responseLen:223B svc=[envoy generic] traceparent=[00-69977bee0c2964b8fe53cdd16f8a9d19-cbca9d64d3d26b40[caa7f1ad1c68fa77]-01]
2025-12-09 12:28:05.12912285 (690.217 s[690.217 s]) HTTPClient 200 GET /(/) [172.19.0.4 as envoy:34256]->[172.19.0.3 as localhost:8080] contentLen:78B responseLen:0B svc=[envoy generic] traceparent=[00-69977bee0c2964b8fe53cdd16f8a9d19-5502f7760ed77b5b[cbca9d64d3d26b40]-01]
2025-12-09 12:28:05.12912285 (267.9 s[238.737 s]) HTTP 200 GET /(/) [172.19.0.4 as 172.19.0.4:34256]->[172.19.0.3 as backend:8080] contentLen:0B responseLen:0B svc=[backend go] traceparent=[00-69977bee0c2964b8fe53cdd16f8a9d19-ac05c7ebe26f2530[5502f7760ed77b5b]-01]
Each log line represents a span belonging to the same trace (69977bee0c2964b8fe53cdd16f8a9d19). For readability, I ordered the spans by their traceparent relationship, showing the request's path as it moves through the system: from the client-facing Envoy, through the internal Envoy hop, and finally to the Go backend. You can see both server-side (HTTP) and client-side (HTTPClient) spans at each hop, along with per-span latency, source and destination addresses, and response sizes, making it easy to pinpoint where time is spent along the request chain. The log lines are helpful, but we need better ways to visualize the traces and the metrics generated by OBI. I'll share another setup that more closely reflects what we actually use.

Production setup I'll be using the following tools this time: The goal of this setup is to mirror an environment similar to what I used in production. This time, I've omitted the load balancer and shifted the emphasis to observability instead. setup diagram I will run three HTTP servers on port 8080: two inside Incus containers and one on the host machine. The OBI process will export metrics and traces to an OpenTelemetry Collector, which will forward traces to Jaeger and expose a metrics endpoint for Prometheus to scrape. Grafana will also be added to visualize the collected metrics using dashboards. The aim of this approach is to instrument only one of the HTTP servers while ignoring the others. This simulates an environment with hundreds of Incus containers, where the objective is to debug a single container without being overwhelmed by excessive and irrelevant telemetry data from the rest of the system. OBI can filter metrics and traces based on attribute values, but I was not able to filter by process PID. This is where the OBI Collector comes into play, it allows me to use a processor to filter telemetry data by the PID of the process being instrumented. These are the steps to reproduce this setup:
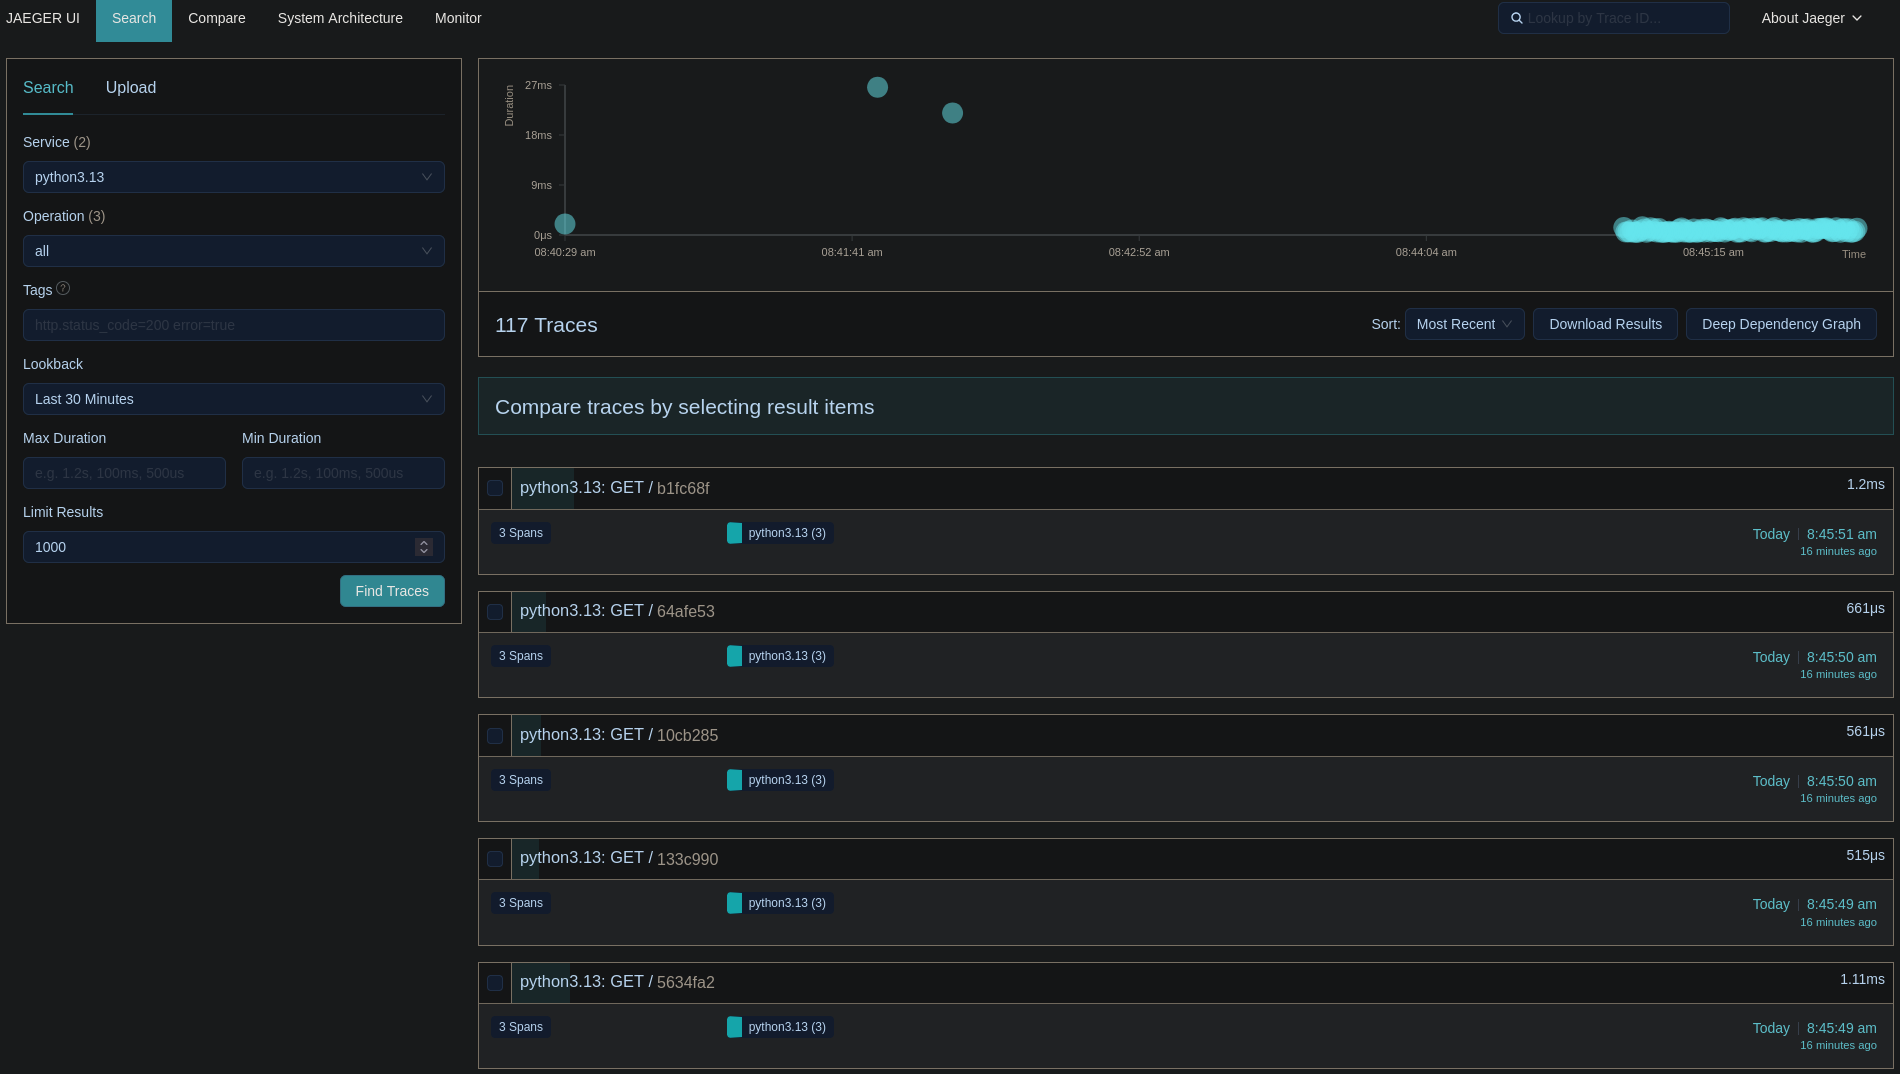
  1. Create the incus containers.
$ incus launch images:debian/trixie server01
Launching server01
$ incus launch images:debian/trixie server02
Launching server02
  1. Start the HTTP server on each container.
$ apt install python3 --update -y
$ tee /etc/systemd/system/server.service > /dev/null <<'EOF'
[Unit]
Description=Python HTTP server
After=network.target
[Service]
User=root
Group=root
Type=simple
ExecStart=/usr/bin/python3 -m http.server 8080
Restart=always
StandardOutput=journal
StandardError=journal
[Install]
WantedBy=multi-user.target
EOF
$ systemctl start server.service
  1. Start the HTTP server on the host.
$ python3 -m http.server 8080
  1. Start the Docker compose.
services:
  autoinstrumenter:
    image: otel/ebpf-instrument:main
    pid: host
    privileged: true
    environment:
      OTEL_EBPF_CONFIG_PATH: /etc/obi/obi.yml 
    volumes:
      - ./obi.yml:/etc/obi/obi.yml

  otel-collector:
    image: otel/opentelemetry-collector-contrib:0.98.0
    command: ["--config=/etc/otel-collector-config.yml"]
    volumes:
      - ./otel-collector-config.yml:/etc/otel-collector-config.yml
    ports:
      - "4318:4318" # Otel Receiver
      - "8889:8889" # Prometheus Scrape
    depends_on:
      - autoinstrumenter
      - jaeger
      - prometheus

  prometheus:
    image: prom/prometheus
    volumes:
      - ./prometheus.yml:/etc/prometheus/prometheus.yml
    ports:
      - "9090:9090" # Prometheus UI

  grafana:
    image: grafana/grafana
    restart: always
    environment:
      - GF_SECURITY_ADMIN_USER=admin
      - GF_SECURITY_ADMIN_PASSWORD=RandomString123!
    volumes:
      - ./grafana-ds.yml:/etc/grafana/provisioning/datasources/datasource.yml
    ports:
      - "3000:3000" # Grafana UI

  jaeger:
    image: jaegertracing/all-in-one
    container_name: jaeger
    ports:
      - "16686:16686" # Jaeger UI
      - "4317:4317"  # Jaeger OTLP/gRPC Collector
Here's what the configuration files look like:
  • obi.yml:
log_level: INFO
trace_printer: text

discovery:
  instrument:
    - open_ports: 8080

otel_metrics_export:
  endpoint: http://otel-collector:4318
otel_traces_export:
  endpoint: http://otel-collector:4318
  • prometheus.yml:
global:
  scrape_interval: 5s

scrape_configs:
  - job_name: 'otel-collector'
    static_configs:
      - targets: ['otel-collector:8889']
  • grafana-ds.yml:
apiVersion: 1

datasources:
  - name: Prometheus
    type: prometheus
    access: proxy
    url: http://prometheus:9090
    isDefault: true
  • otel-collector-config.yml:
receivers:
  otlp:
    protocols:
      http:
        endpoint: otel-collector:4318

exporters:
  otlp/jaeger:
    endpoint: jaeger:4317
    tls:
      insecure: true

  prometheus:
    endpoint: 0.0.0.0:8889
    namespace: default

service:
  pipelines:
    traces:
      receivers: [otlp]
      exporters: [otlp/jaeger]

    metrics:
      receivers: [otlp] 
      exporters: [prometheus]
We're almost there, the OpenTelemetry Collector is just missing a processor. To create the processor filter, we can look at the OBI logs to find the PID of the HTTP server being instrumented:
autoinstrumenter-1    time=2025-12-30T19:57:17.593Z level=INFO msg="instrumenting process" component=discover.traceAttacher cmd=/usr/bin/python3.13 pid=297514 ino=460310 type=python service=""
autoinstrumenter-1    time=2025-12-30T19:57:18.320Z level=INFO msg="instrumenting process" component=discover.traceAttacher cmd=/usr/bin/python3.13 pid=310288 ino=722998 type=python service=""
autoinstrumenter-1    time=2025-12-30T19:57:18.512Z level=INFO msg="instrumenting process" component=discover.traceAttacher cmd=/usr/bin/python3.13 pid=315183 ino=2888480 type=python service=""
Which can also be obtained using standard GNU/Linux utilities:
$ cat /sys/fs/cgroup/lxc.payload.server01/system.slice/server.service/cgroup.procs 
297514
$ cat /sys/fs/cgroup/lxc.payload.server02/system.slice/server.service/cgroup.procs 
310288
$ ps -aux   grep http.server
USER         PID %CPU %MEM    VSZ   RSS TTY      STAT START   TIME COMMAND
1000000   297514  0.0  0.1  32120 14856 ?        Ss   16:03   0:00 /usr/bin/python3 -m http.server 8080
1000000   310288  0.0  0.1  32120 10616 ?        Ss   16:09   0:00 /usr/bin/python3 -m http.server 8080
cipriano  315183  0.0  0.1 103476 11480 pts/3    S+   16:17   0:00 python -m http.server 8080
If we search for the PID in the OpenTelemetry Collector endpoint where Prometheus metrics are exposed, we can find the attribute values to filter on.
$ curl http://localhost:8889/metrics   rg 297514
default_target_info host_id="148f400ad3ea",host_name="148f400ad3ea",instance="148f400ad3ea:297514",job="python3.13",os_type="linux",service_instance_id="148f400ad3ea:297514",service_name="python3.13",telemetry_sdk_language="python",telemetry_sdk_name="opentelemetry-ebpf-instrumentation",telemetry_sdk_version="main"  1
Now we just need to add the processor to the collector configuration:
processors: # <--- NEW BLOCK
  filter/host_id:
    traces:
      span:
        - 'resource.attributes["service.instance.id"] == "148f400ad3ea:297514"'

service:
  pipelines:
    traces:
      receivers: [otlp]
      processors: [filter/host_id] # <--- NEW LINE
      exporters: [otlp/jaeger]

    metrics:
      receivers: [otlp] 
      processors:  # <--- NEW BLOCK
        - filter/host_id
      exporters: [prometheus]
That's it! The processor will handle the filtering for us, and we'll only see traces and metrics from the HTTP server running in the server01 container. Below are some screenshots from Jaeger and Grafana: jaeger search will all traces one jaeger trace grafana request duration panel

Closing Notes I am still amazed at how powerful OBI can be. For those curious about the debug, we found out that a service responsible for the network orchestration of the Envoy containers was running netplan apply every 10 minutes because of a bug. Netplan apply causes interfaces to go down temporarily and this made the latency go above 500ms which caused the 499s.

Ravi Dwivedi: Transit through Kuala Lumpur

In my last post, Badri and I reached Kuala Lumpur - the capital of Malaysia - on the 7th of December 2024. We stayed in Bukit Bintang, the entertainment district of the city. Our accommodation was pre-booked at Manor by Mingle , a hostel where I had stayed for a couple of nights in a dormitory room earlier in February 2024. We paid 4937 rupees (the payment was online, so we paid in Indian rupees) for 3 nights for a private room. From the Terminal Bersepadu Selatan (TBS) bus station, we took the metro to the Plaza Rakyat LRT station, which was around 500 meters from the hostel. Upon arriving at the hostel, we presented our passports at their request, followed by a 20 ringgit (400 rupee) deposit which would be refunded once we returned the room keys at checkout.
Outside view of the hostel Manor by Mingle Manor by Mingle - the hostel where we stayed at during our KL transit. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
Our room was upstairs and it had a bunk bed. I had seen bunk beds in dormitories before, but this was my first time seeing a bunk bed in a private room. The room did not have any toilets, so we had to use shared toilets. Unusually, the hostel was equipped with a pool. It also had a washing machine with dryers - this was one of the reasons we chose this hostel, because we were traveling light and hadn t packed too many clothes. The machine and dryer cost 10 ringgits (200 rupees) per use, and we only used it once. The hostel provided complimentary breakfast, which included coffee. Outside of breakfast hours, there was also a paid coffee machine. During our stay, we visited a gurdwara - a place of worship for Sikhs - which was within walking distance from our hostel. The name of the gurdwara was Gurdwara Sahib Mainduab. However, it wasn t as lively as I had thought. The gurdwara was locked from the inside, and we had to knock on the gate and call for someone to open it. A man opened the gate and invited us in. The gurdwara was small, and there was only one other visitor - a man worshipping upstairs. We went upstairs briefly, then settled down on the first floor. We had some conversations with the person downstairs who kindly made chai for us. They mentioned that the langar (community meal) is organized on every Friday, which was unlike the gurdwaras I have been to where the langar is served every day. We were there for an hour before we left. We also went to Adyar Ananda Bhavan (a restaurant chain) near our hostel to try the chain in Malaysia. The chain is famous in Southern India and also known by its short name A2B. We ordered
A dosa Dosa served at Adyar Ananda Bhavan. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
All this came down to around 33 ringgits (including taxes), i.e. around 660 rupees. We also purchased some snacks such as murukku from there for our trip. We had planned a day trip to Malacca, but had to cancel it due to rain. We didn t do a lot in Kuala Lumpur, and it ended up acting as a transit point for us to other destinations: flights from Kuala Lumpur were cheaper than Singapore, and in one case a flight via Kuala Lumpur was even cheaper than a direct flight! We paid 15,000 rupees in total for the following three flights:
  1. Kuala Lumpur to Brunei,
  2. Brunei to Kuala Lumpur, and
  3. Kuala Lumpur to Ho Chi Minh City (Vietnam).
These were all AirAsia flights. The cheap tickets, however, did not include any checked-in luggage, and the cabin luggage weight limit was 7 kg. We also bought quite some stuff in Kuala Lumpur and Singapore, leading to an increase in the weight of our luggage. We estimated that it would be cheaper for us to take only essential items such as clothes, cameras, and laptops, and to leave behind souvenirs and other non-essentials in lockers at the TBS bus stand in Kuala Lumpur, than to pay more for check-in luggage. It would take 140 ringgits for us to add a checked-in bag from Kuala Lumpur to Bandar Seri Begawan and back, while the cost for lockers was 55 ringgits at the rate of 5 ringgits every six hours. We had seen these lockers when we alighted at the bus stand while coming from Johor Bahru. There might have been lockers in the airport itself as well, which would have been more convenient as we were planning to fly back in soon, but we weren t sure about finding lockers at the airport and we didn t want to waste time looking. We had an early morning flight for Brunei on the 10th of December. We checked out from our hostel on the night of the 9th of December, and left for TBS to take a bus to the airport. We took a metro from the nearest metro station to TBS. Upon reaching there, we put our luggage in the lockers. The lockers were automated and there was no staff there to guide us.
Lockers at TBS bus station Lockers at TBS bus station. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
We bought a ticket for the airport bus from a counter at TBS for 26 ringgits for both of us. In order to give us tickets, the person at the counter asked for our passports, and we handed it over to them promptly. Since paying in cash did not provide any extra anonymity, I would advise others to book these buses online. In Malaysia, you also need a boarding pass for buses. The bus terminal had kiosks for getting these printed, but they were broken and we had to go to a counter to obtain them. The boarding pass mentioned our gate number and other details such as our names and departure time of the bus. The company was Jet Bus.
My boarding pass for the bus to the airport in Kuala Lumpur My boarding pass for the bus to the airport in Kuala Lumpur. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
To go to our boarding gate, we had to scan our boarding pass to let the AFC gates open. Then we went downstairs, leading into the waiting area. It had departure boards listing the bus timings and their respective gates. We boarded our bus around 10 minutes before the departure time - 00:00 hours. It departed at its scheduled time and took 45 minutes to reach KL Airport Terminal 2, where we alighted. We reached 6 hours before our flight s departure time of 06:30. We stopped at a convenience store at the airport to have some snacks. Then we weighed our bags at a weighing machine to check whether we were within the weight limit. It turned out that we were. We went to an AirAsia counter to get our boarding passes. The lady at our counter checked our Brunei visas carefully and looked for any Brunei stamps on the passports to verify whether we had used that visa in the past. However, she didn t weigh our bags to check whether they were within the limit, and gave us our boarding passes. We had more than 4 hours to go before our flight. This was the downside of booking an early morning flight - we weren t able to get a full night s sleep. A couple of hours before our flight time, we were hanging around our boarding gate. The place was crowded, so there were no seats available. There were no charging points. There was a Burger King outlet there which had some seating space and charging points. As we were hungry, we ordered two cups of cappuccino coffee (15.9 ringgits) and one large french fries (8.9 ringgits) from Burger King. The total amount was 24 ringgits. When it was time to board the flight, we went to the waiting area for our boarding gates. Soon, we boarded the plane. It took 2.5 hours to reach the Brunei International Airport in the capital city of Bandar Seri Begawan.
View of Kuala Lumpur from the aeroplane View of Kuala Lumpur from the aeroplane. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.

Stay tuned for our experiences in Brunei! Credits: Thanks to Badri, Benson and Contrapunctus for reviewing the draft.

Petter Reinholdtsen: Some of my 2025 free software activities

I guess it is about time I posted a new summary of the free software and open culture activites and projects I have been involved in the last year. The days have been so packed the last year that I have failed with my intention to post at least one blog post per month, so this summary became rather long. I am sorry about this. This year was the year I got tired of the lack of new releases of the multimedia related libraries published via Xiph, and I decided to wrap up the current state and make the releases myself. In a burst of activity early this year, I collected and tested patches, coordinated with other developers and finally made new tarballs and release announcement for theora, and new tarball releases for liboggz, kate and fishsound. This upstreamed several patches accumulated in Debian and other Linux distributions for the last 15 years or so. To change the world and the future, it is important to start with the kids, and one such avenue of change have been created by the current president of FSF Europe, Matthias Kirschner. He wrote a book for children, Ada & Zangemann, and I have been involved in its translation framework for the entire year. The source code has been transformed to Docbook and I have been conducting and coordinating translations into Norwegian Bokm l and Nynorsk, as well as preparing paper editions of the book and an animation movie with Norwegian voices. The Bokm l edition is very close to ready, and will be available early in 2026, and the movie release will follow shortly after this. I intend announce this on my blog and elsewhere when this happen. Please get in touch if you want to help spread the word about this book in Norwegian. I hope we can get the author to Norway when making the Norwegian releases. This year I continued a push for the system I made a few years ago to improve hardware dongle handling on Linux. The Isenkram system use hardware mapping information provided by relevant packages using the AppStream system to propose which Linux distribution packages to install on a given machine to support dongles like cameras, finger print readers, smart card readers, LEGO controllers, ECC memory and other hardware. I have followed up on the list of packages providing such mapping, either to get it into Debian or to upstream the necessary metadata. I am not sure if we are at a point where package maintainers on their own add such information to their packages, but there are Debian lintian reports suggesting it and I have send patches to all packages I am aware of that should include such mappings. Most of the patches are included in Debian now, only 27 was left the last time I checked. As part of my involvement with Debian, I continued my push to get all orphaned packages without a version control repository migrated to git. I am not sure how many packages I went through, but it was in the range of 200-300 packages. In addition to this I updated, sponsored, pushed maintainers for updates upstreamed patches for and fixed RC issues with battery-stats, bs1770gain, isenkram, libonvif, mfiutil, opensnitch, simplescreenrecorder, vlc-plugin-bittorrent and wakeonlan. I've also followed up LEGO related packages, dahdi support for Asterisk, llama.cpp and whisper.cpp in particular for the AMD GPU I was donated by AMD, as well as tried yet again to convince the upstream developers of the photogrammetric workstion e-foto to get their program into a state that could be included in Debian. As I do not buy into the story that it is great to expose oneself to the whims of and priorities of commercial entities to have access to cultural expressions like films and music, I still maintain a huge collection of movies. For this to work well, I have ended up as part of the people maintaining lsdvd upstream and wrapped up a new release fixing several crash bugs caused by DVDs with intentionally broken metadata, and introduced code to list a DVD ID in the lsdvd output. Related to this, I have also worked some add-ons for my main video and music player, and took over upstream maintenance of the Invidious add-on, which sadly stopped working for non-authenticated users when web scrapers made it impossible for Invidious installations to provide a open API, as well as contributed to the NRK and projector control add-ons. As part of my involvement in the Norwegian archiving community and standardisation work, we organised a Noark 5 workshop this spring discussing how to decide what to keep and what to delete in digital archives. We finally managed to apply for Noark 5 certification for the free software archive API Nikita, as well as worked to test and improve the performance of Nikita together with people on my day job at the university. Manufacturing using Free Software is still a focus for me, and I have continued my involved with the LinuxCNC community, organising a developer gathering this summer with the help and sponsoring from the initial start in 2023 from NUUG Foundation and sponsoring from Debian and Redpill-Linpro. We plan to repeat the event also in 2026, but this time NUUG Foundation have told us they do not want a role, so we have found another friendly organisation to handle the money. A popular machine controller with LinuxCNC is the MESA set of electronics, which is centred around a FPGA which now can be programmed using only Free Software. We discussed during this summers gathering how hard it would be to compile the current FPGA source using a Free Software tool chain, and I started looking into this, locating tools to transform the VHDL source into something the Yosys tool chain can handle. Still lot to do there, and I hope to get further next year. An important part of Free Software manufacturing is the ability to design parts and create programs that can be passed to machines making parts, also known as CAD/CAM. The most prominent project for this is FreeCAD, and I have been both pushing to get opencamlib integrated with it in Debian as well as fixing bugs in the handling of Fanuc controlled machines, do make it easier to generate instructions for machines I have access to. I expect to also continue this also next year. This year the UN conference Internet Governance Forum (IGF) was held in Norway, and I tried my best to get a stand for the Norwegian Unix Users Group (NUUG) there. Sadly the effort failed, due to lack of interest with the NUUG Board, but I was happy to see several members at least attend some of the activities related to IGF. Sadly to participate at IGF one need to hand over quite private information, so I decided not to participate in any of the closed forum events myself. Related to NUUG I have been a member of the election board proposing board member candidates to the general assembly, and been part of the program committee of the "Big Tech m vekk" (Big Tech must go away) festival organised by Attac in concert with NUUG and EFN. I've also assisted the Norwegian open TV channel Frikanalen with access to their machines located in a machine room at the university. Related to the University, I have become involved in a small team of students working to build and program robots for the Robocup@Home competition. For 2026 we also plan to use the new features of FreeCAD to make parts for the open hardware robot arm OpenArm. This is also the group that will handle the money for the LinuxCNC gathering in 2026. Also related to the university I was looking into the Linux security auditing system Falco earlier this year, making improvements to the detection rules. This activity is on hold at the moment, and do not expect to continue with this in 2026. I will most likely have to cut down a bit on my free software and open culture activities going forward, as NUUG Foundation, who have funded one day a week for such activities for several years no, sadly have decided they do not want to continue doing this. I am very grateful for their contributions over the years, both with freeing up time for me and supporting several events and projects where I have been involved or taken the initiative on. Now they are reorganizing with more focus on paperwork and applications. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Chris Lamb: Favourites of 2025

Here are my favourite books and movies that I read and watched throughout 2025.
Books

Eliza Clark: Boy Parts (2020)Rachel Cusk: The Outline Trilogy (2014 2018)Edith Wharton: The House of Mirth (1905)Michael Finkel: The Art Thief (2023)Tony Judt: When the Facts Change: Essays 1995-2010 (2010)Jennette McCurdy: I'm Glad My Mom Died (2022)Joan Didion: The Year of Magical Thinking (2005)Jill Lepore: These Truths: A History of the United States (2018)

Films Recent releases

Disappointments this year included 28 Years Later (Danny Boyle, 2025), Cover-Up (Laura Poitras & Mark Obenhaus, 2025), Bugonia (Yorgos Lanthimos, 2025) and Caught Stealing (Darren Aronofsky, 2025).
Older releases ie. Films released before 2024, and not including rewatches from previous years. Distinctly unenjoyable watches included War of the Worlds (Rich Lee, 2025), Highest 2 Lowest (Spike Lee, 2025), Elizabethtown (Cameron Crowe, 2005), Crazy Rich Asians (Jon M. Chu, 2018) and Spinal Tap II: The End Continues (Rob Reiner, 2025). On the other hand, unforgettable cinema experiences this year included big-screen rewatches of Chinatown (Roman Polanski, 1974), Koyaanisqatsi (Godfrey Reggio, 1982), Heat (Michael Mann, 1995) and Night of the Hunter (Charles Laughton, 1955).

Freexian Collaborators: How files are stored by Debusine (by Stefano Rivera)

Debusine is a tool designed for Debian developers and Operating System developers in general. This post describes how Debusine stores and manages files. Debusine has been designed to run a network of workers that can perform various tasks that consume and produce artifacts . The artifact itself is a collection of files structured into an ontology of artifact types. This generic architecture should be suited to many sorts of build & CI problems. We have implemented artifacts to support building a Debian-like distribution, but the foundations of Debusine aim to be more general than that. For example a package build task takes a debian:source-package as input and produces some debian:binary-packages and a debian:package-build-log as output. This generalized approach is quite different to traditional Debian APT archive implementations, which typically required having the archive contents on the filesystem. Traditionally, most Debian distribution management tasks happen within bespoke applications that cannot share much common infrastructure.

File Stores Debusine s files themselves are stored by the File Store layer. There can be multiple file stores configured, with different policies. Local storage is useful as the initial destination for uploads to Debusine, but it has to be backed up manually and might not scale to sufficiently large volumes of data. Remote storage such as S3 is also available. It is possible to serve a file from any store, with policies for which one to prefer for downloads and uploads. Administrators can set policies for which file stores to use at the scope level, as well as policies for populating and draining stores of files.

Artifacts As mentioned above, files are collected into Artifacts. They combine:
  • a set of files with names (including potentially parent directories)
  • a category, e.g. debian:source-package
  • key-value data in a schema specified by the category and stored as a JSON-encoded dictionary.
Within the stores, files are content-addressed: a file with a given SHA-256 digest is only stored once in any given store, and may be retrieved by that digest. When a new artifact is created, its files are uploaded to Debusine as needed. Some of the files may already be present in the Debusine instance. In that case, if the file is already part of the artifact s workspace, then the client will not need to re-upload the file. But if not, it must be reuploaded to avoid users obtaining unauthorized access to existing file contents in another private workspace or multi-tenant scope. Because the content-addressing makes storing duplicates cheap, it s common to have artifacts that overlap files. For example a debian:upload will contain some of the same files as the related debian:source-package as well as the .changes file. Looking at the debusine.debian.net instance that we run, we can see a content-addressing savings of 629 GiB across our (currently) 2 TiB file store. This is somewhat inflated by the Debian Archive import, that did not need to bother to share artifacts between suites. But it still shows reasonable real-world savings.

APT Repository Representation Unlike a traditional Debian APT repository management tool, the source package and binary packages are not stored directly in the pool of an APT repository on disk on the debusine server. Instead we abstract the repository into a debian:suite collection within the Debusine database. The collection contains the artifacts that make up the APT repository. To ensure that it can be safely represented as a valid URL structure (or files on disk) the suite collection maintains an index of the pool filenames of its artifacts. Suite collections can combine into a debian:archive collection that shares a common file pool. Debusine collections can keep an historical record of when things were added and removed. This, combined with the database-backed collection-driven repository representation makes it very easy to provide APT-consumable snapshot views to every point in a repository s history.

Expiry While a published distribution probably wants to keep the full history of all its package builds, we don t need to retain all of the output of all QA tasks that were run. Artifacts can have an expiration delay or inherit one from their workspace. Once this delay has expired, artifacts which are not being held in any collection are eligible to be automatically cleaned up. QA work that is done in a workspace that has automatic artifact expiry, and isn t publishing the results to an APT suite, will safely automatically expire.

Daily Vacuum A daily vacuum task handles all of the file periodic maintenance for file stores. It does some cleanup of working areas, a scan for unreferenced & missing files, and enforces file store policies. The policy work could be copying files for backup or moving files between stores to keep them within size limits (e.g. from a local upload store into a general cloud store).

In Conclusion Debusine provides abstractions for low-level file storage and object collections. This allows storage to be scalable beyond a single filesystem and highly available. Using content-addressed storage minimizes data duplication within a Debusine instance. For Debian distributions, storing the archive metadata entirely in a database made providing built-in snapshot support easy in Debusine.

kpcyrd: 2025 wrapped

Same as last year, this is a summary of what I ve been up to throughout the year. See also the recap/retrospection published by my friends (antiz, jvoisin, orhun). Thanks to everybody who has been part of my human experience, past or present. Especially those who ve been closest.

Next.

Previous.