Search Results: "xam"

27 July 2026

Dirk Eddelbuettel: #057: Conditionally Quieten Compilers

Welcome to post 57 in the R4 series. R packages with compiled codes can use the file src/Makevars to set compilation flags. We often rely on this to set libraries, include directories or compilation options. When using external libraries, be it header-only or via headers and linking, we are often experiencing compilation noise when these libraries tickle warnings under generally-recommended flags such as -Wall -pedantic. Two packages I maintain are clearly repeat offenders here: Eigen, and BH. Both cam generate pages and pages of compiler output. This is generally not great as it may hide genuine warnings from our own code. What makes matters worse is that some of the available and specific options for the compilers are treated by R CMD check as non-portable leading to a nag on package checking. Examples are -Wno-parentheses, -Wno-maybe-uninitialize or -Wno-nunnull. I have long resorted to adding these to my per-user ~/.R/Makevars. When added there, compilation is quieter, but R CMD check still nags here where the option is set but not at CRAN or r-universe. A situation that is not ideal but what somewhat stable . More recently, I realized there was an available check we can use to conditionally add extra compilation flags but leave them off by default. That makes local development quiet allowing us to focus on the quality of our additions here without noise from third-party libraries we may use. At the same time we do not need to do anything else to let CRAN do its work. The check we now use is whether there is a .git/ directory present. If so, we are indeed building from local sources and can add extra flags. If not, we are likely building from a tar.gz source archive which is the case for CRAN and hence do not set these. An example use is this recent additional to package qlcal where this bit of R code is invoked from a minimal shell script configure and replaces the stub @XTRAFLAGS@ in src/Makevars.in (or src/Makevars.win.in)
if (dir.exists(".git"))  
    ## development from a .git directory can use these flags
    xtraflags <- "-Wno-nonnull -Wno-deprecated-declarations"
  else  
    ## else build from tarball so stick with existing flags
    xtraflags <- ""
 
win <- if (Sys.info()[["sysname"]] == "Windows") ".win" else ""
infile <- file.path("src", paste0("Makevars", win, ".in"))
outfile <- file.path("src", paste0("Makevars", win))
lines <- readLines(infile)
lines <- gsub("@XTRAFLAGS@", xtraflags, lines)
writeLines(lines, outfile)
With this change, local compilation is quiet, yet CRAN has nothing to nag about (as seen at the qlcal results page). Similarly, one can also check from an actual configure file written in autoconf. Here is a similar example from RcppEigen (showing some relevants parts of the whole file)
# PKG_CXXFLAGS initialized earlier ...

## Check if building locally
AC_MSG_CHECKING([whether .git/ exists])
if test -d "$srcdir/.git"; then
    AC_MSG_RESULT([yes, adding extra flags])
    AC_SUBST([PKG_CXXFLAGS],["$ PKG_CXXFLAGS  -Wno-ignored-attributes -Wno-maybe-uninitialized"])
else
    AC_MSG_RESULT([no, consider adding '-Wno-ignored-attributes -Wno-maybe-uninitialized' to ~/.R/Makevars])
fi

AC_SUBST([PKG_CXXFLAGS], ["$ PKG_CXXFLAGS "])
AC_CONFIG_FILES([src/Makevars])
AC_OUTPUT
Once again, with this change compilation is quiet locally, yet unaffected at CRAN. Just what we want. Give it a try in your packages.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

21 July 2026

Dirk Eddelbuettel: qlcal 0.1.3 on CRAN: Micro Bugfix, Build Tweak

The twenty-first release of the qlcal package arrivied at CRAN just now, and has been built for r2u. It comes a week after the 0.1.2 release. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over seventy country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases includes a one-line fix we also sent upstream as a now-merged PR: one of the calendar files added in QuantLib 1.43 also needed to include the vector header file. And every compiler appears to be lenient (QuantLib itself has fourty different continuous integration jobs, we test with all builds at r-universe) apart from the CRAN macOS x86-64 machine. Sigh. This is now fixed. We also included a neat little local trick I should blog about: if the build is detected as a non-CRAN local build (simply by checking for a .git directory) then compiler flags can be updated to quieten the build. We cannot do that in the package because we would get our fingers slapped over so-called non-portable compiler flags . Sigh again. Anyway, the trick helps. The full details from NEWS.Rd follow.

Changes in version 0.1.3 (2026-07-21)
  • Add missing 'vector' header to new IslamicHolidays calendar file, also PRed upstream and merged there
  • In local compilation out of git repo add additional compiler flags

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

20 July 2026

Tim Retout: Renewal relationships between AWS certifications

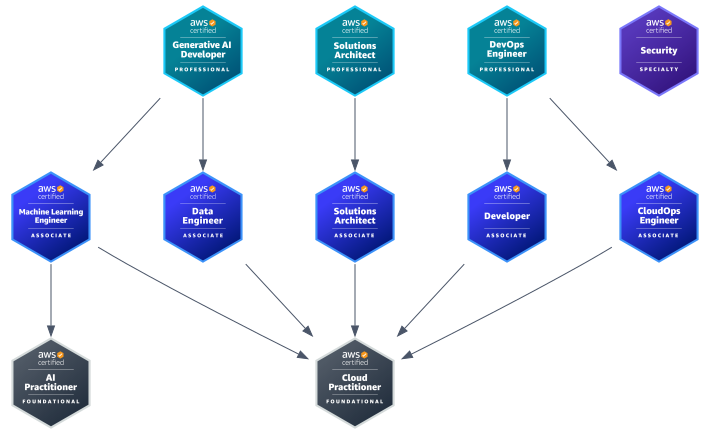
When you pass an AWS certification exam, sometimes it can extend the life of related lesser AWS certifications. But I could not find an illustration of exactly which ones, so here s an up-to-date diagram: AWS Certification renewal dependencies Figure: Renewal relationships between AWS certifications. Each arrow is a renews relation there s no obligation to pass lesser exams before the harder ones, but you could also follow the arrows backwards if you want to learn easier material before sitting the more difficult exams. I have made two important simplifications to the graph:
  1. The Advanced Networking Specialty certification is being retired soon, so I ve omitted it entirely. The last date to take that exam is 25th August 2026. But Specialty certs don t renew anything else anyway.
  2. I have left out transitive relationships in order to simplify the graph so e.g. if you pass a Solutions Architect Professional exam, it also renews any Cloud Practitioner certificate you might hold, even if you do not currently hold the relevant Associate certificate.
You also have the option of sitting each exam again to renew of course, and there s a new scheme to maintain various certs via AWS Skill Builder which can extend them by one year rather than three.

15 July 2026

Dirk Eddelbuettel: qlcal 0.1.2 on CRAN: Fresh Upstream Updates

The twentieth release of the qlcal package arrivied at CRAN today, and has been built for r2u. This version synchronises with QuantLib 1.43 released today as well. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over seventy country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases updates to several new calendars (see below), and extends the calendars for Israel to some added new conventions, updates a few helper functions, and turns on ccache for continuous integration builds. The full details from NEWS.Rd follow.

Changes in version 0.1.2 (2026-07-14)
  • Synchronized with QuantLib 1.43
  • Calendar updates for India, Israel, and South Korea; small interface update for Israle
  • New calendars for Croatia, Malta, Montenegro, North Macedonia, Serbia, Slovenia, Uzebekistan
  • Updates to a number of QuantLib helper functions
  • Continuous integration now uses ccache via a setup action

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Freexian Collaborators: Debian Contributions: Python 3.14 as default transition, DebConf 26 preparations, debvm, pconr and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-06 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Python 3.14 as default transition, by Stefano Rivera Debian has had Python 3.13 and 3.14 in unstable and testing since December 2025, with Python 3.13 as the default version (/usr/bin/python3 = 3.13). This gave time for packages to implement support and detect issues in their test suites. A slot to transition to 3.14 as default was requested from the release team in March, and they indicated that we would likely be able to schedule it in late June. In preparation, Stefano reviewed the open bugs against Python interpreters and squashed some in uploads of the latest point releases of Python: 3.13.14 and 3.14.6. Also in June, Python 3.15.0 beta 2 and beta 3 released. Stefano uploaded these to Debian experimental. The 3.15 betas were reason to attempt to revive review of a blocked upstream patch to support Debian multiarch in stable ABI Python extensions, now that Python 3.15 is adding a new stable ABI abi3t.

DebConf 26 preparations, by Stefano Rivera, Antonio Terceiro, Lucas Kanashiro, Santiago Ruano Rinc n and Anupa Ann Joseph DebConf 26, the annual Debian Developer Conference, is being held in Santa Fe, Argentina, in July. Stefano Rivera, Antonio Terceiro, Lucas Kanashiro, Santiago Ruano and Anupa Ann Joseph contributed to the preparations for the event.
  • As usual, Stefano has been supporting the conference website and registration, helping the local team to get accurate data on attendee numbers.
  • Antonio has been supporting the conference website and helping the content team to put together the conference schedule.
  • Santiago has been helping the local team on different topics regarding logistics.
  • Anupa assisted with the accommodation arrangements for DebCamp and DebConf, working alongside Nattie.
  • Lucas has been coordinating the conference schedule and communicating with some speakers.

debvm, by Helmut Grohne The debvm tool used for creating and running ephemeral virtual machines saw a number of small improvements. The requirement of having a filesystem label has been removed in favor of using a uuid and /etc/fstab is no longer created. A memory balloon is enabled by default and this enables qemu to automatically release free guest memory to the host. Booting Ubuntu VMs regressed as a result of their use of uutils and has been fixed. The --architecture flag is back to be able to better support Hurd, which is a work-in-progress of Johannes Schauer Marin Rodrigues. Thanks to Jochen Sprickerhof, you can more easily create VMs for autopkgtest-virt-qemu using --hook-dir=/usr/share/mmdebstrap/hooks/autopkgtest-create-qemu. There also are a few documentation and error message improvements. All of this is pending in git waiting to be uploaded once development slows down. While booting a machine from virtiofsd succeeded, turning the proof-of-concept into production remains for later.

pconr, by Helmut Grohne At DebConf25, Helmut reported on a schroot substitute called unschroot. The second iteration uses varlink IPC to construct a container. That varlink API is now separated into a new project called programmable container runtime. It is meant to provide more flexibility in constructing containers than established solutions such as the unshare command from util-linux, bubblewrap or podman provide while still managing repetitive complexity such as process orchestration for the developer. A new example that uses this infrastructure is a better containment for mmdebstrap eliminating chroot escape. There also is an asyncvarlink/0.3.2 release taking steps to become more maintainable in Debian to eventually get pconr into Debian.

Miscellaneous contributions
  • Stefano did routine uploads (mostly new upstream versions) of python-pip, python-pipx, hatchling, dh-python, beautifulsoup4, python-virtualenv, python-mitogen.
  • Stefano uploaded a snowball mini-transition: snowball, snowball-data, and pystemmer
  • Stefano did some debian.net team admin, setting up a container and later a VM for vote.debian.net.
  • Stefano responded to a semi-escalation to the Debian Technical Committee, after some communication between an upstream, a bug reporter, and a Debian package maintainer went sideways and got heated.
  • Emilio managed several transitions, and filed bugs against the few remaining GCC 13 rdeps.
  • Antonio did salsa maintenance work, debugging service issues, approving user registrations, and processing support requests.
  • Antonio worked on Debian CI maintenance, including but not limited to deploying new armhf and armel workers, fixing bugs and preparing an upcoming release of debci.
  • Antonio did several maintenance tasks for MiniDebConf websites.
  • Antonio uploaded ruby-bunny, ruby-sinatra and ruby-mustermann, fixing a few FTBFS bugs among them.
  • Carles using po-debconf-manager: Reviewed Catalan translations for 5 packages, submitted 6 packages. Added a draft blog/update about the po-debconf-manager project.
  • Carles submitted a new Geeqie Catalan translation: it had accumulated a large number of untranslated strings over the last 4 years.
  • Carles contributed to the Debian wiki: improved documentation for the Framework Laptop and added a new section Battery charging control (after doing some debugging and testing). He wrote a page about Signal Desktop. Carles started looking at testing/documenting Mailman2 -> Mailman3 migration.
  • Carles, in relation to the migration process, double checked old pages without relevant information in the Debian wiki.
  • Thorsten did another upload of package hplip to fix some bugs.
  • In the context of the Google Summer of Code 2026 project, Santiago continued co-mentoring Aryan Karamtoth, who is working on the Linux live-patching project. As part of the team, Santiago guided Aryan to help design the different workflows and to study the different tools available, including the upstream klp-build (that was introduced in v6.19), and compare it with SUSE s klp-build.
  • Colin clarified the bug tracking system s documentation to indicate that maintainers may sometimes reasonably ask users to file bugs upstream themselves.
  • Colin fixed 15 packages for pytest 9.1.
  • Colin fixed a depthcharge-tools regression with Python 3.14 as default that broke debian-installer builds.
  • Helmut continued to report undeclared file conflicts and correspond about them.
  • Helmut wrote patches for strace to enable cross building and a 32bit personality on arm64.
  • Helmut continued maintaining rebootstrap working fixing build failures in fontconfig, gettext and sqlite3 as well as changing the way packages from gcc builds are installed to better serve a need reported by Samuel Thibault.

11 July 2026

Reproducible Builds: Reproducible Builds in June 2026

Welcome to the June 2026 report from the Reproducible Builds project! In these reports, we outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. If you are interested in contributing to the project, please visit our Contribute page on our website. In this month s report, we cover:

  1. Only installing reproducible packages with repro-threshold
  2. Distribution work
  3. diffoscope development
  4. From our mailing list
  5. Documentation updates
  6. Patches
  7. Four new scholarly papers


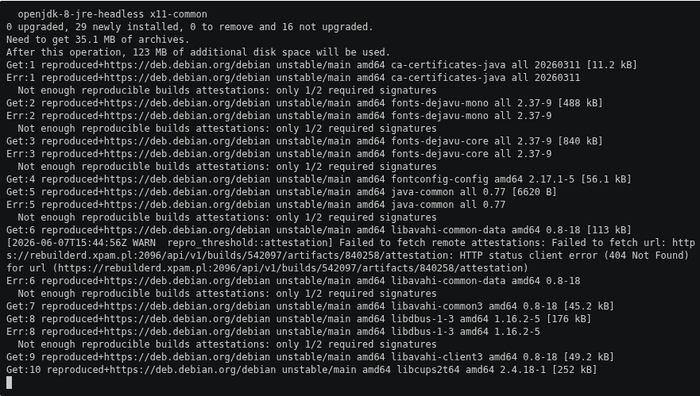
Only installing reproducible packages with repro-threshold A very interesting demonstration is now available showing how you might configure your Debian system to only install packages that have been reproduced by m/n rebuilders. This is implemented via a reproduced+https:// APT transport ( a mechanism for communicating between the APT client and its repository source commonly HTTP):
Every package download is intercepted by repro-threshold, which queries two independent rebuilders for a signed attestation before allowing installation to proceed. [It] is important to note that [an] install will only succeed if all package dependencies are also reproducible.
The demo gives examples of how to quickly experiment with this using a Docker container.

Distribution work In Debian this month: The IzzyOnDroid Android APK repository reached its next milestone this month, now covering 2 out of every 3 apps (66.7%) with reproducible builds. Their documentation for debugging and fixing failed builds has steadily grown as well. More clients have picked up showing reproducibility results (e.g. Droid-ify), and Neo Store now can be configured to stick to only reproducible applications. Further, an independent builder has been added to the build farm, increasing the trust level even more as APK builds can have multiple confirmations now. At the same time, IzzyOnDroid s rbtlog got several new features. The most outstanding is caching for frequently used resources such as reproducible-apk-tools, command-line tools and NodeJS in order to counter ongoing issues with GitHub availability, while at the same time saving bandwidth and build time. This change also enables some other some smaller enhancements such as being able to configure build timeouts per recipe for those builds running longer than the average, release pattern filtering for update checks or having a field for maintainer notes to shortly summing up e.g. why a reproducible build failed.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.

diffoscope development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 319, 320, 321, 322 and 323 to Debian:
  • Debian adds an extra Flags: line in the output of ocamlobjinfo, so adjust the test for cross-distribution compatibility. [ ]
  • Bump debhelper compatibility level to 14. [ ]
  • Fix compatibility with Ocaml 5.4.1. [ ]
  • Use --long-form-style arguments when calling apktool in order to support apktool version 3. [ ]
  • Support Androguard version 4 and previous versions at the same time. [ ]
  • Update copyright years. [ ]
In addition, Jochen Sprickerhof added better header detection for the Sphinx documentation system [ ], Michael Daniels fixed the tests when run with zipdetails version 4.006 [ ] and Zbigniew J drzejewski-Szmek added a version of the deprecated os.path.commonprefix method [ ]. In addition, Vagrant Cascadian updated diffoscope in GNU Guix to version 321 and 323.
Chris Lamb also made the following changes to strip-nondeterminism, our tool to remove specific non-deterministic results from a completed build:
  • Skip symlinks when manually called via /usr/bin/strip-nondeterminism. (#1139000)
  • Update debian/watch format. [ ]
  • Drop Rules-Requires-Root: no and Priority: optional fields. [ ]
  • Bump Standards-Version to version 4.7.4. [ ]

From our mailing list On our mailing list this month:
  • kpcyrd posted to our mailing list regarding the waves of malware uploads to aur.archlinux.org . Curiously, every incident I looked at used npmjs.com for malware delivery , specifically where the npm package includes an (automatically executed) preinstall script that is an ELF binary.
  • kpcyrd also announced the release of debian-repro-status version 0.4.0, a tool written to give you an approximate idea of how viable it would be to enforce a reproducible packages only update policy for the computer system you ve built :
    The change updates dependencies to the latest versions, and adds support for multiple -H options, to query results from multiple rebuilderd instances. The results are also now fetched concurrently.
  • kpcyrd also reported that, whilst taking a screenshot for the above release, they noticed that the debian:sid container now is 100% reproducible.
  • Finally, kpcyrd also created a pull request against the add-determinism package to update the itertools and zip Python dependencies.

Documentation updates Yet again, there were a number of improvements made to our website this month including:
  • Chris Lamb added a reminder re. using the UTC variants of the Javascript Date methods. [ ]
  • Mattia Rizzolo moved OTF to the old sponsors list. Thank you for your support!. [ ]
  • kpcyrd updated the Rust documentation to recommend using the --release argument for consistency. [ ]

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

Four new scholarly papers Kenichiro Muto and Kuniyasu Suzaki of the Institute of Information Security in Yokohama, Japan published an interesting paper this month titled Attestable Build Chain: Enabling Trust in Reproducible Builds (PDF). Their abstract is as follows: Ensuring trust in software supply chains requires verifying not only artifacts but also the processes that produce them. Although Reproducible Builds (R-B) require rebuilding to validate artifacts, they cannot verify whether the build was executed with the intended toolchain and inputs and may reproduce unintended or compromised builds without detection. We present Attestable Build Chain, a framework for externally verifying build-time execution without rebuilding. Rather than preventing compromise, it provides verifiable, tamper-evident evidence of actual build-time execution, enabling verification of build process integrity from observed file accesses during the build. [ ]
Julien Malka, Stefano Zacchiroli and Th o Zimmermann published a 50-page report detailing A Decade of Software Reproducibility in the Nix Package Ecosystem:
We find that functional package management enables extremely high rebuildability over time (near-universal ability to reconstitute historical build environments and rebuild software packages), while bitwise reproducibility has steadily improved and reaches a high point in recent years (up to 93% in 2024). Early years show substantially lower bitwise reproducibility, indicating that functional package management alone does not guarantee bitwise-identical outputs, and that the observed high level of bitwise reproducibility is not solely due to the package management approach. Common causes of unreproducibility, both in the rebuildability and bitwise reproducibility dimensions, include management of dates in build and test processes; we quantify their prevalence and other common causes using manual analysis of logs of rebuild failures and automated analysis of diffoscope.
A PDF of their report is available online
Tim Bastin of L3montree GmbH and Jacek Galowicz of Applicative Systems GmbH from DevGuard published a paper detailing How We Built a Sovereign, Reproducible Container Supply Chain for DevGuard:
This paper presents how the DevGuard project rebuilt its OCI container pipeline around reproducible Nix builds and independent dual-platform digest verification. DevGuard images are built hermetically from pinned source revisions, signed with Sigstore/Cosign, and verified through digest comparison across GitHub Actions and sovereign GitLab infrastructure hosted on container.gov.de. We describe the practical integration of reproducible OCI image builds into existing CI/CD workflows and argue that independently reproducible container digests provide a stronger integrity guarantee against build tampering than provenance alone. The paper further discusses remaining trust assumptions and the relevance of sovereign build infrastructure for government and regulated environments.

Finally, Yiseul Choi, Junga Kim, Jun-Ho Hong and Seongmin Kim of the Department of Convergence Security Engineering at the Sungshin Women s University in Seoul, Korea titled Attestation-based verification of SBOM integrity via consumer-side reproducibility:
Software bills of materials (SBOMs) support supply chain transparency, but they do not prove that a delivered SBOM reproducibly corresponds to its software artifact. Existing signing and provenance mechanisms protect integrity and traceability, yet lack consumer-side reproducible verification. We propose an SBOM integrity verification framework combining procedure disclosure, consumer-side reproduction, authority-generated reference evidence, and digest comparison. A trusted authority records a reference digest, and consumers compare it with locally reproduced and delivered SBOM digests. Experiments on 100 real-world container images show detection of artifact tampering, SBOM substitution, distribution modification, and adaptive tampering beyond signature-based approaches


Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

10 July 2026

Tim Retout: Blocking distracting news links

You are what you eat but perhaps this is even more true of our information diet. It is hard to strike a balance between remaining a well-informed citizen versus spending hours ingesting unnecessary news about issues and events we can t affect. But I m increasingly convinced that my hours lost to doomscrolling are down to design choices by web publishers rather than a failure of individual willpower.

We have created an obesogenic information environment I don t think it is just me I think our information environment has been progressively altered over time as news sites look to maximize engagement. Even outside of social media, the invisible hand of the market for eyeballs forces sites to optimize for browse time or risk irrelevance. Even as newspapers find it increasingly difficult to fund good journalism through advertising in an online world, especially local journalism, they need to keep readers on their sites, clicking through as many articles as possible. Clickbait headlines, urgent flashing live icons to draw the attention, and many opportunities to leap from one article to another, and another. But this design approach even extends to news organisations with a different funding model, like BBC News, which is a public service (state-owned but arms-length) organisation funded through a mandatory television licence a matter of controversy in some quarters. And it extends even to sites where I pay a subscription fee; I might get adverts removed, but I am still bombarded with the same design philosophy; too many opportunities to be pulled away from what I m reading towards some other unrelated article. Even if I try and limit my exposure to algorithmic discovery of new news, via RSS feeds or similar, if I m reading the full article in a browser then I am prompted to read more stuff that I didn t intend. This defeats the benefit of curating a set of feeds, because you still get dragged away to random articles.

Only 44% of BBC News is news To show you what I mean, I m going to pick on the BBC, although I love them dearly and the same issue very much applies elsewhere. I ve taken a screenshot of a random BBC News article in mobile view (my preferred doomscrolling user access device), and measured approximately what proportion of the full length of the page is taken up by each section. This is a fairly in-depth news article, so I reckon if anything the figures would be worse than this on shorter articles. A full-length screenshot of a BBC News article showing proportions of the page allocated to the main article vs. related links etc. (These numbers will not sum to 100% for reasons which are obvious if you look at the crossbars. Also they re approximations.) Less than half of the page (44% if you exclude the inline related links) is actual news text/images; the rest are links trying to help you find the next thing to read/watch. I do not want this. I m sure this A/B tests well in terms of reader figures, but it sometimes leaves me exhausted it must take subconscious mental energy to ignore, or I spend too much time trying to keep on top of things. And remember, this is a publicly-funded site that does not rely on advertising!

Blocking out the noise If you are technically-minded, you can use an ad-blocker such as uBlock Origin to take back some control. Applying the following lines as a custom filter (Settings > My filters) brutally cuts out almost all of these links:
bbc.co.uk##aside
bbc.co.uk##footer>div:has(h2)
bbc.co.uk##[data-block="uploaderEmbed"]
bbc.co.uk##[data-block="links"]
Caveat emptor: I have not road-tested this for more than half an hour, so who knows what consequences this could have on your web browsing. In particular, international readers outside the UK will likely be redirected to bbc.com, the commercial arm of the BBC, where these rules will need adapting. Is it unethical to use an ad-blocker to remove these links? I would argue not. I am not depriving the BBC of any revenue, because I pay my licence fee. I might reduce the amount of time I spend on their website, but if anything the subjectively better experience might encourage me to consume more news from them, not less. In other circumstances (outside the UK for instance, where the BBC relies on advertising), the balance might be different.

Product managers, please find better metrics I lament the state of the internet in 2026. I now can t unsee these innocuous related stories links as a mechanism to grab my attention, and it s gone too far. If you are a normal person just browsing the news and looking to discover the latest important stories relatively quickly, I can see that these types of links might actually be useful for discovery; but I m actually reasonably sure that I m not going to miss out on anything major. You still have the option of the news home page if you want to be presented with more news for example, and it feels natural to go back to there when you ve run out of stories to consume. But it shouldn t be down to individual responsibility to ignore or geekily block these types of link; news sites with alternative funding models should find better metrics for engagement than hours spent on site how about optimizing for customer mental wellbeing, or minimizing time required to catch up with the news? There s no need to maximize clicks and eyeballs. This is a societal level issue, because we are all going mad with news over-engagement. Product managers, over to you.

6 July 2026

Aigars Mahinovs: How to make a good group photo

Taking a good group photo consists of multiple aspects: I can say with confidence that nearly everything here comes from having failed to do these things right at least once, even on the latest attempts, so this is an ideal to reach towards, not something we expect to hit every time. The Goal The main goal of a big event group photo is capture both the moment itself and each individual person inside that moment. We want people, who were not there to see all the people involved and get an impression of what it was like being there. It needs to show the breadth and depth of people that make up this group, this project. And we want people who were there to be able to look back the next week, the next year or in ten years and remember - ah, yes, I was there, I was standing right there with this grin on my face next to this wonderful person and I was feeling great. Hardware Based on the goal we want to have high level photographic gear that is able to capture both a broad enough picture to encompass all the people and some of their surroundings to communicate the context (without undue distortions) and to deliver enough detail and resolution so that faces and facial expressions and underlying feelings of every single person in that group could be clearly seen and preserved. To both capture the context and minimise distortion the final picture should be just a bit wider than normal human field of view. That is about 50mm for a full-frame camera or 35mm for a typical 1.6 crop camera. You can go a bit wider if there are no better alternatives (as detailed in the scouting section), but be prepared that corners of the image will be distorted and not really usable (but we can fix that in processing step). Or you can go to unusual aspect ratios, like we did in Debconf 10. In the absence of a 100MP+ camera, you will need to be stitching together multiple frames to achieve resolution high enough to have enough pixels-per-face to see emotions clearly. This means that the photos you will actually be taking will be tighter than the overall field of view mentioned above. Still, a higher resolution camera body is preferable - nowadays 24MP-32MP cameras APS-C provide a good compromise between resolution and price, but 45-67MP full-frame cameras also exist on the market. Assume that we will be shooting in a bright environment, so most likely with quite low ISO settings, that means that high-ISO noise characteristics of more expensive cameras will not really play a role here. You will also not need very fast burst modes, even manual speed of one frame per second is sufficient. You will also want to get as much detail as possible out of your lens, and this is the most important part. You can do amazing work in all other steps of the process and have a great camera too, but if you pair it with a lens that is not sharp, then the end result will be disappointing. You want the lens that is sharpest corner-to-corner when stepped down to about f/8-f/11, that you can get for your system. You also want that lens to be about 85mm full-size sensor or 50mm for 1.6 crop size. Luckily that kind of range is also a great range for optical design and sharpest lenses are typically available in exactly these kinds of sizes. You absolutely want to have a fixed focal length lens, not a zoom lens. Even profession grade zoom lenses often deliver worse image quality compared to fixed lenses that cost less 1/10th of their price (when shooting in the same focal length). Newer design lenses are better than older lenses - optical design, coatings and precision manufacturing have advanced a lot over the decades. Retro look is great for mood, but not as good for actual resolution and clarity. You don't need to overpay for most expensive lenses because those often only improve image quality on lower F-stops. To encompass the whole group we will need to shoot at f/8 and in bright light, so the extra benefits of those f/1.2-capable super expensive lenses will not come into play here. We will have no use for a flash here. A tripod will be too restrictive when rapidly repositioning the camera between different parts of the panorama shoot. But a monopod might help with stability - I have not tried that myself, however. For my last photos I used a Canon EOS R7 (32.5MP) with Canon RF 50mm f/1.8 STM lens and considering an upgrade to Sigma 56mm f/1.4 DC DN for the next time. Scouting Scouting a good location for the group photo is another big chunk of a successful picture. The critical piece of the puzzle is lens-to-face distance. In order to keep everyone's face in-focus and have enough resolution on the farthest faces (without making nearest faces truly massive) we want to do everything possible to reduce the variance in lens-to-face distance - to reduce the difference in distance between closest and farthest face. The most effective way to do that is to have the photographer climb higher. To see this in action on the Debconf photos, compare Debconf6 (very high camera position, group on level ground - good) to Debconf10 (camera not too high, group on stairs, still good) and to Debconf17 (camera could not get high enough and the group is on flat ground - not great). Even the Debconf25 photo was suboptimal from this perspective. The Debconf23 photo was a very good example from the recent years - good height and also the group was positioned in a semi-circle so there were no people directly in front and very near to the camera. So you are looking for the highest point you could get to (even if that requires a special permission of key or a ladder) with a field large enough to fit the whole group comfortably. How to check that? Normally I simply take a photo from the top of the whole area and note down from there where the extreme corners of the group could be and still be fully seen in the shot - not blocked by trees, buildings and shadows. Then I go down and measure that space. Rule of thumb being - people in one horizontal line can stand 1 normal length step from each other and two horizontal lines can be half a step from each other vertically. So I can just measure a rough rectangle in steps, multiply the sides, multiply that by two and I have the rough number of people that can fit there for the photo. Once you have a candidate location or two, it is important to check them at the same time-of-day as you plan to do the photo (see organization section for that). You want to make sure that the whole area of the group is in the same illumination - if half of the group is in the sun and half in a shadow, then you will be having a very bad time later. The absolute ideal positioning for the group photo is to have everyone be in shadow, but still have enough bright skies and bright buildings in front of the people to give good illumination of the faces. Worst you can do is have the sun be behind the people (so all the faces are really dark) and second worst is have the sun be directly in front of the group, so that the faces are very well illuminated, but everyone's eyes are closed because they are being blinded by the sun. And sometimes all you can do is pray for some light clouds to provide for even and dispersed light. Debconf23 was very lucky that way. Another consideration is to how people are going to get to that place. You need to consider accessibility needs of people (it is ok, if it takes more effort or time, but it needs to be organized and communicated well in advance). And you need to consider how the big masses of people will be getting there - how to tell people where exactly it is and how to get there from various locations where people might be hanging out during the event? Having an alternate location indoors might be necessary if the weather report for the next days is not sufficiently predictable. We had to use that contingency in Debconf9, for example. Organization It's hard to take a good group photo if half of the group does not show up or is too late, so this needs some organization to happen smoothly. First of all you need to choose date and time for the photo. The photo does not take too much time from the schedule of the event and can be squeezed in after all the other events are already scheduled. In fact I prefer that as it allows you the flexibility of choosing the date based on weather conditions and time based on light and shadow conditions in potential photo spots. You don't want to choose the daytrip day as most people will be away and return times are not really predictable. You do not want to choose the morning after Cheese and Wine party for obvious reasons. First day and last two days are also sub-optimal as some people arrive late and some leave early for various personal reasons. Also you don't want it to happen just before Cheese and Wine either because then you'd have very little time and clarity to do the processing of the image on the same day. For timing, the best way, in my experience, is to schedule the photo directly after the end of talk sessions before a meal break - lunch or dinner. Typically in the Debconf schedule there are 2-3 daily breaks planned, say for Debconf25 there was lunch, afternoon break and dinner. Talks are planned to end ~10 minutes before those breaks (and meals) begin, so for example, afternoon break starts at 16:00 and all talks in the previous block end at 15:50. In such a case just schedule the "Group photo" event from 15:50 to 16:05. This gives people the info to go there directly from the end of all talks and that they will have sufficient time for break/meal afterwards. Do not forget to specify the location (as exactly as possible) in that event entry and make sure to post it at least two days in advance. People often want to wear something specific for the photo and thus need to know about it in advance. This also makes sure that people do not make alternate food plans for that specific break and don't leave the venue. Announce the date, time and the exact location as wide as possible, don't be shy. Announce and discuss mailing lists, IRC, Signal, Telegram, make sure the front desk knows in case anyone asks in-person, ... Check that it is again included in the announcements email on the day preceding the photo date. When the date has arrived, it is a good idea to check in early with people with special mobility needs to make sure they know where to go, how to get there and how much time they will need to be able to get there on time. As the final round of talks before the group photo is starting up, it is time to recruit "runners". I've had great success with this technique. The idea is pretty simple - for each room where people congregate (talk rooms, hacklabs, cafeteria, outside hackspace, front-desk, ...) go there and choose one person. You want to choose a person that you will recognise and remember among everyone else in the group, either because of who they are or what they are wearing, whatever works best for you. If they agree to help, instruct them to: "at end of talk, announce that the group photo happening now and the location, herd people towards the photo location, be the last person out, make sure there are no stragglers from this area behind you, when you arrive to the photo place I will assume that everyone else from this room is also now there, when you are there catch my attention and show this sign so I know for sure that it is all good and make sure that I did see it from you". With that sorted out all you will need to remember is how many runners you recruited and how many have reported in to figure out if everyone has now arrived or if we still have to wait for someone or some group. Then you will only have one last point of organization left - shaping the crowd into a group. People will not know what your vision for the group photo is, so you will have to give clear and LOUD instructions on where people should not be standing. Use clear, large gestures to support your words. You want to compact the group, have the people that just joined in the last moment and are standing to the side come deeper in and join the crowd. Have any holes in the middle of the crowd filled in. Forming a semi-circle instead of a blob helps with averaging face-to-lens distances. Make sure people are not in unexpected shadows. Make sure carried objects, like umbrellas of flags do not cover the faces of other people. Take the time to look at everyone face to make sure there are no people hiding behind someone's shoulder - typically they are not aware that their face is in fact not really visible. If there are such people, call them out and point directly at them and encourage them to step forward, if they wish to do so. You are the only one seeing the final picture now and only you can correct it before capturing the moment. So a few extra seconds here are worth taking, even if 300+ people are standing in scorching heat and waiting on you. When you are happy with what you are seeing, make sure to tell people clearly that you are now about to take the pictures and again remind them not to move and explicitly not to turn their heads to the side until you are done (this is the source of most of the extra work in processing). Be very loud and clear and make sure you have everyone's undivided attention before you start saying the important stuff. When done - say so. There will be other groups that will want to also have a photo taken after the main group is a bit more dispersed, so don't run away. Typically at least the T-shirt group will want a picture and also all the organizers. Final bit of organization during the group photo shooting itself is the sneaky self-insert. You may choose not to bother with it, or do it in the simplest way, like I did in Debconf6, but if you really want to blend in with the crowd, you need to have someone else take a photo of you in the exact same location at the same date and time from the same location. So you should already during shaping the crowd decide where you would fit in, it is easiest to blend in at the back of the crowd and to one or other side, so that it appears like you are just standing behind the shoulders of a couple peoples. Remember that spot - it is easiest if you stand in the exact same ground spot when your photo is taken. Just go down, recruit a volunteer to take your photo, make sure the settings are fixed to the same ones as for the group photo shots and have them take a handful of shots of you - one of you centered in the camera frame and a couple more with you more towards the corners of the frame. This distortion from being off-center in the frame may be important later. Preparation In addition to preparing the crowd for the photo, you also need to prepare yourself and the equipment. Make sure you have dusted your camera sensor and cleaned both inside and outside glass of your lens. It is usually a good idea to remove any filters from the lens. Install the hood, if that could help with blocking the sun flares. Make sure you have the right lens and that you have installed the right lens. For fixed settings I typically shoot in JPEG with RAW being there more like an emergency backup. The extra dynamic range of RAW could be used, but it is really complex to do that in combination with image blending and it is hard to get right, so I prefer an all-JPEG workflow and fix the dynamic range in the scene itself, before shooting. For Canon I am using the Standard profile that boosts the color saturation and sharpness a bit as I just enjoy that look and find it hard to get anything significantly better from RAW data even with a lot of effort. In any case make sure you have enough space on the cards to take at least 100 images and that you have a full battery. Do not use high speed burst setting because it is then too easy to take too many pictures at the start of the sequence and be stuck with your camera still in "Busy" state writing big RAW files to slowish SD cards and not allowing you to finish the full picture rapidly. You want to have the shutter speed at at least 1/100th of a second to prevent blur from both your hand movements and also from people in the shot moving around a bit (image stabilisation will not help you there). And you want to have the aperture to be around f/8 - lower apertures risk people in front or behind falling out of focus, make the lenses look less sharp. Higher apertures also start to become less sharp due to diffraction effects above f/8. ISO should stay as low as possible, ideally at ISO 100, but if there is not enough light then upping the ISO to 400 would be the first step that I would try to do and second would be decreasing the aperture to f/5.6. If there is too much light, then increasing the shutter speed should be the safe thing to do. As people start to arrive into the shooting location - check the exposure and nail down the settings, ideally in manual mode. Consider that left side could be a bit lighter or darker than right side. Err on the side of making the picture a bit too dark as there is more depth to darkness before cut-off compared to clipping on the high end. However, do not trust the exposure detection, instead take a picture and look specifically at skin tones in faces of people that already are standing in the photo area. Faces are the key bit and the exposure needs to be adjusted just to the faces and ignore darker of lighter clothing. Do some test shots and find settings where faces look not too bright, but also not very dark and fix those settings in manual mode. Now you are ready for the action. Shape the crowd, check the faces and the action can start! Execution During taking of the group photo you want to finish it fast, but at the same time you have to take the time to make it right. If you hurry too much under pressure, you risk being left with unusably blurry images and the whole effort wasted. Having already prepared and verified the manual settings makes it easier. When you are taking pictures, you have to remain as still as possible - even at very high shutter speeds even slow hand movements are still bad for image quality. So think of the movement as of biathlon athlete shooting the very middle of five, very separate targets - take a burst, reframe, then steady up for a second and only then take the next burst. 3 frames per burst are sufficient. 90% of the time the very first photo of a burst will be best. As you move from frame to frame, aim for just a bit more than half-frame overlap. This will give the opportunity to skip frames if all is good, but also have backup coverage of every face in case of problems. Proceed systematically, I typically start off on the top left of the crowd, then go right until the end of the line, then shift down half a frame and go left until the end and repeat until I am done with the crowd. After that it is very helpful to also immediately take photos of a "frame" around the whole crowd. Stitching process often distorts the frames in weird ways that leave holes in the resulting image that you can fill if you have a wide frame around the crowd. It is possible to compensate with creative cutouts in the final image (like Debconf9), but the more framing room you make, the more flexible you will be able to be with cropping of the final photo. The frame also gives you the opportunity to capture more of the context of the place and space. As an example, Debconf25 group photo in the end consisted from 9 images + 1 for sick people + 1 for me. I ended up missing the framing shots for bottom left, top left and top right corners. To get there I took 68 images. And in some years it was more than a hundred. Processing This part might be less stressful than taking the pictures from intensity perspective, but it lasts longer. Depending on you luck, skill and perfectionism it can take anywhere from 3 to 9 hours of work to complete. Before you start, however, you should first request things that you will need for other people. This can even be done before taking the actual group photo, but usually I forget. To finish the photo you will need three things: The first two you should be able to get from the respective organizers. The motto is harder. I typically try to ask the current DPL to come up with something describing the current mood of the project or of the event, but it is rare that it is that easy. Most of the time I came up with something as I was editing the photo and reflecting on what was the mood, the feeling, the mojo of this conference and of this year was like. Bend that around a recognisable phrase or expression, make it a bit more insider-relevant and you are on the right path. Some years this was the hardest part. For the panorama stitching I will describe the workflow that has served me good for years, but maybe there are better ways possible nowadays. Feel free to let me know! First I would save all photos taken and select one sharpest photo from every burst. Next I would select the minimal number of photos that appear to be covering the entire crowd. The fewer images you use, the better in the end because the most quality problems crop up in the areas where photos are getting stitched together. Fewer seams leads to fewer issues. Open Hugin (you will also need enblend and enfuse installed) and import your minimal set of images into it. Click the "Align" button and wait a while - the processor will be trying to figure out keypoints in each image and then try to match these points between the images to try to fit them all together into a single projection. To do that it will distort the images. This is the trial and error process part. You may need to add, remove or replace images to get the stitching to work or to work better. You may want to add more of the frame images to fill the ragged holes around the image. After initial alignment, go to "Move/Drag" tab and move the image a bit up in the projected field of view and make it a bit more central visually. That will help a bit with the distortions in the near-by people and people in the corners of the image. In the "Crop" tab set the initial crop - leave it generous, you can always crop more in later steps. Do not be afraid of leaving in sizable chunks of black homes, empty skies or grass. All of that can be filled in later as well. Go back to the "Assistant" tab and click "Create panorama". It is good enough to have JPEG output at 100% quality using exposure corrected low dynamic range output option. Make sure to check the "Keep intermediate images" option. This will not only generate the final, merged panorama, but also keep around the individual images after perspective correction and exposure blending steps. These are critical for fixing blending error in the next step. You might need to go back a forth a few times with a different sets of source images, maybe adding some image between other two, maybe removing another to reach a better starting point. The key part to pay attention - how many ugly stitches are there in the image. Check every face, the blending algorithms do not recognise faces and sometimes try to stitch one face from two or more images creating very weird effects. They can be fixed in the next step, but it is rather hard manual work, so the fewer such faces are in the blended image, the less work you will have. In some years I've managed to find a combination where all faces were good and in other years I had to manually fix 13-15 faces. Do not try to blend the extra pictures (like with you or with sick people) into the main panorama with Hugin - it will get very confused with the parts of the grass that it is able to see where other people were standing. The next is the final processing in GIMP. Think of it like a large and complex project - do as much as possible in separate layers, save often. Fixing wrongly stitched faces and also putting yourself into the photo are very similar activities in the end. Just the scale and the source differ. For yourself you just cut out yourself (upper torso is enough) from the separate photo. For corrupted face, choose one of two intermediate images that the Hugin created where the face is transformed, but not yet merged (with a different version of itself). In either case crop the photo to roughly the interesting size and put roughly in the right spot as a separate layer on top of the group photo background. Reduce the opacity of the small layer to 30-40% and zoom in to 400%. With that it is much simpler to position the layer with pixel precision. Then all you need to do is add a layer mask to this layer and paint it just right. Basically in layer mask black means transparent and white means non-transparent. So you need to just make everything that is you have white mask and everything that is not you have black mask. And smudge the border a bit with finger tool or blur to make the transition smoother. Easy to say. Hard to do. This is what takes most of the actual work hours in post-processing. You might miss someone. I am sure Phill is just thrilled to see me in the very middle of the Debconf25 final picture .... But do try to fix them all. Use large, sweeping geometric figures to cover up black holes, empty grass fields and other sub-optimal corner features. And then use that newly created free space to put in a large version of the logo of this years conference, decently sized motto and slightly smaller invitation to the next years conference. Do not forget to add a copyright and license statement somewhere in the corner in smaller, but still well readable font. I am using a text like: "Photo by: Full Name, Email: fullemail@debian.org, License: GPLv2+ or CCv3-BY" This ensures that this image may be used in any press coverage (with basic attribution) and also can be included in any GPL-licensed software, if that ever comes up. The same statement is also in the metadata of the image file (see Image-Metadata-Edit metadata in GIMP) along with information that states that this is "Debian Developer Conference Group photo, City, Country, Year". Image->Image properties->Comment is another place where GIMP hides this EXIF information. For ease of use, in addition to a full-resolution image it is also useful to make a lower resolution version that would still fit on a 4K screen at full resolution, so about 3840px wide. Some photo hosting services set other limits for image size as well, so it might be needed to scale the image down below 100Mpix to upload it to Google Photos, for example. Publishing So, it is finally 1AM and the group photo is ready! How do you push it out to people? Well, in all possible ways and places. Again - don't be shy, people do really want to see it. Push it to whatever you use for your shared photos. Push it to Debconf shared git (note that this is GIT-LFS repo, make sure you know how to add content to the LFS specifically). All permanent links to that in GroupPhotosAll wiki. And then send those links to IRC, Signal, Telegram groups, debconf-announce mailing list. Publish it in your blog and push that to Debian Planet. Push it in Threads, Bluesky and Mastodon. Send an email separately to Debconf orga team. And one to Debian Publicity Team so they can put it into the Debian Home Page and push via Debian micronews accounts. And that is about it. Now you can go back to enjoying the rest of the conference. Or running around doing other things that you think need to be done. It's up to you. You did it. This moment will remain with people for a very long time. And you helped. Questions? Feedback? Just ask here or here.

Russ Allbery: Review: The Player of Games

Review: The Player of Games, by Iain M. Banks
Series: Culture #2
Publisher: HarperPrism
Copyright: 1989
Printing: February 1987
ISBN: 0-06-105356-2
Format: Trade paperback
Pages: 295
The Player of Games is political space opera and the second book in the shared Culture setting. As with most Culture books, the reading order is not particularly important. It won the 1989 Locus Award for best science fiction novel and sometimes competes with Use of Weapons as the consensus best Culture novel. This review is a re-read and yet another experiment in how to re-review a book. This time, I decided to write a full second review with substantial spoilers so that I can talk in more detail about the book. If you want to avoid spoilers, or just want to see how my thoughts have evolved from my first reading, see my original review from 2005. Gurgeh plays games. He is probably the best strategy game player in the entirety of the galaxy-spanning Culture. He has written papers on game theory, won innumerable major championships, and is a celebrity in the circle of like-minded aficionados. Gurgeh is also bored and in the middle of the Culture equivalent of a mid-life crisis. As the story opens, he's vaguely unsatisfied and adrift, unenthused by his normal activities, and searching vaguely for something that will break through his ennui. He is caught by surprise by the thrill he gets from a moment's misunderstanding in which an opponent suspects him of cheating, which sets him up to be (apparently) clumsily blackmailed by a deeply unpleasant drone named Mawhrin-Skel. SPOILERS BELOW. If you have not read this book, consider stopping here and instead reading my original no spoiler review. The first hundred pages of The Player of Games is a slow, somewhat plodding introduction to Gurgeh, his social circle, and life in (one part of) the Culture. I remember being fascinated by this part the first time I read this book. It was only the second Culture novel I read and the first set in the Culture proper, so the world-building underlying this odd post-scarcity utopia on a vast intelligent habitat with sentient drones, complex privacy rules, endless cocktail parties, and apparently directionless socialites was intriguingly unlike the other science fiction I was reading at the time. This time through, I have to admit I was less impressed. Gurgeh is not very likable, and his desultory mid-life crisis is a little boring. None of his friends have enough depth to appear as more than side notes, in part because Gurgeh doesn't seem to care enough about any of them to make them interesting to the reader. I've since read seven other Culture novels, so Banks's cocktail parties hold less charm and I was impatient for the real action to begin. These chapters are still important, though, because they establish how utterly average Gurgeh is. He has one unique talent, a deep affinity with and obsession with strategy games, and is otherwise a bit of a depressed narcissist with a few casual relationships, a friend that he barely confides in, and a comfortable and familiar life. He is not in any way a hero or a charismatic figure; he just happens to be exceptionally good at one thing, enough to make him famous among people who care about that one thing and probably unknown to anyone else apart from the occasional idly perused news headline. He is the Culture's equivalent of the world chess champion. The Contact division of the Culture has a problem. The Empire of Azad in the Lesser Magellanic Cloud is a nasty, expansionist culture of the sort that Contact would like to deal with before it causes broader problems. The Culture's normal approaches are thwarted by an unusual organizing principle: The empire is built around and takes its name from the game of Azad, a highly complex strategy game developed over thousands of years. Azad is the civil service exams, means of political and religious dispute resolution, selection mechanism for the emperor, and civic religion. Faced with that oddity, Contact turned to Special Circumstances, the Culture's more aggressive and less restrained way of dealing with tricky problems. Special Circumstances, in turn, needs someone who can learn how to play the game of Azad. They want Gurgeh to take a very long trip. For all of Gurgeh's dissatisfaction, he's not impulsive enough to take a five year journey away from his life and everyone he knows just to play a novel game. Conveniently, Mawhrin-Skel's blackmail resolves this reluctance. The game of Azad requires some suspension of disbelief. Banks provides a few glimpses at the mechanics of the game, but those details are insufficient to reconstruct the rules, and some of the claims made about its properties are improbable at best. The best mental model I could build for it is a strategy or simulation game built around units and territory control, with supplemental side games used to build up resources for the main boards, but it's more of a plot device and a set piece than a world-building invention. The significance of Azad the game is its role in society: The Empire of Azad believes they have constructed a game whose complexity so closely models reality that the skills required for success in the game are precisely the skills required for success in the empire. The Empire of Azad is wrong, and this is one of the core themes of The Player of Games. As with many Culture novels, what Special Circumstances tells Gurgeh is, at best, incomplete. Gurgeh is a refutation of the basis of belief in Azad; this is why it is important thematically that he is an average, somewhat unlikable citizen of the Culture whose only special characteristic is skill at learning and playing games. Azad is the myth of meritocracy given physical form as a game. It provides the anchor of the empire for the same reason that societies on Earth place enormous weight on standardized tests, capitalist success, or public debates. All societies face the problem of selecting good leaders and testing opposing beliefs, and all societies attempt to find some form of shortcut, some set of general principles, tests, or objective metrics used to select the best person via a process that people consider plausible and fair. The game of Azad is a paragon of apparently meritocratic process. No matter who you are or what your background is, if you excel at the game that, in theory, objectively tests your skills, you are given a position of power. In practice, the Empire of Azad is not that naive. Manipulation outside of the game happens, only some players have the opportunity and resources to spend years learning the game at a deep level, and only their dominant sex truly stands a chance in games that matter. But neither is Azad's place in society a fiction. There is corruption around the edges, and a lot of people are filtered out before the games begin, but the highest echelons of society are true believers. The game does decide both rank and policy; Banks is arguing against a strong form of apparently working meritocracy. Gurgeh represents a refutation of this meritocracy through the mechanism that breaks every supposed meritocracy: The map is not and cannot be the territory. Any objective evaluation criteria is necessarily separate from what it is trying to measure, and in that separation there is always an opportunity. Gurgeh has none of the background, training, or mindset expected for a player of Azad because he could not possibly care less about any of the things Azad represents to the Empire. What he has instead is a preternatural skill at games and vast experience with the most intricate strategy games the Culture, a much larger society, has been able to devise. He also has both the patience and the resources to devote himself entirely to learning a game for several years, and past experience in doing that with other games. If Azad represents the civil service exams, Gurgeh is the person who has no interest in ruling but adores memorizing facts and taking tests. The theory behind the exams is that the skills to pass the exam only come with the correct mindset to do the job for which the exam is testing. Gurgeh is an existence proof that this is not always the case. Banks also uses Azad to show another aspect of the failure of meritocracy: A society whose rulers are chosen through a competition takes on the shape of that competition. The Empire of Azad is run by the winners of competitive games, so the empire is a winner-take-all system of dominance and status hierarchy. Here, I think Banks lays the point on a little thick; the empire is an irredeemable hellhole of misogyny, sexual abuse, slavery, genocide, and military colonialism to a degree that is a bit hard to justify solely from the game. There is a beautiful turning point about two-thirds of the way through the book where Gurgeh's face is shoved into just how vile Azad society is and reconsiders his approach to the tournament as a result, and I think it may have been a bit stronger if the morality had been a little less blatant and absolute. To the extent that Gurgeh has political beliefs, he represents a Culture flavor of soft liberalism. He has opinions about acceptable and unacceptable ways to treat people, but he grew up in a utopia and his opinions are mostly theoretical. When he sees just how vile people can be outside of that utopia, he is revolted and appalled and redoubles his efforts to fight that society in the only way he knows how, inside of a game. This part of the book follows the standard, if enjoyable, plot of a flawed but fundamentally decent person discovering a true injustice and becoming enraged at it. In a lot of books, that would have been where the plot stops. Banks is doing something more subtle and more interesting, though. Gurgeh wipes the board with his next challenger, but that soft liberalism eventually proves inadequate. To learn the game of Azad and to play in the tournament, Gurgeh has been wrapping himself in Azad culture and its language, and in that frame of mind he is losing the climactic game of the book. It's only when he is pushed to think in Marain, the native language of the Culture, that he understands what is happening in the game and how to defeat Nicosar, the emperor. This, on the surface, is a bit too close to the strong hypothesis of linguistic relativity to be entirely plausible, but such an objection would miss the point that Banks is making here. Marain is a construct, the product of considerable effort within the Culture to match language to the most nuance and complexity that brains can understand, and it is a language, one of the most social and collective artifacts a society can produce. Gurgeh is a remarkable individual with an impressive talent, but individual skill and achievement can only take him so far. The critical final piece is the support of societal infrastructure intentionally built and maintained to help him make better decisions. Once I noticed that point, I saw it everywhere in the book. The empire repeatedly attempts to subvert or distract Gurgeh with drugs, pleasure, politics, or danger, and at each point there is some critical piece of Culture social infrastructure that blunts the attack. Illicit substances and forbidden vices are less tempting to someone for whom the illicit has been demystified by the Culture's gentler approach to rules and boundaries. Embedded biological mechanisms allow him to divert drugs so that they don't affect him. At first, it's easy to read this as an exercise of self-control, but on this re-read I saw how much behind-the-scenes infrastructure supports Gurgeh's ability to ignore temptation. This social support notably does not take the form of some ideological principle or moral framework. Gurgeh is not a monk or an ascetic, as is obvious from the first third of the book, and he has no political ideology to speak of. He is a flawed person with a streak of danger-seeking and self-aggrandizement, which the Culture exploited to get him involved in Azad. But through a lot of hard work, technological and social, the Culture has given him a robust foundation and a set of mental and biological tools that make him remarkably hard to corrupt. The implication is that if Gurgeh has that support, so does every other member of the Culture. It's neither a religion or an ideology; it's well-maintained infrastructure, complex and nuanced and pragmatic, and composed of innumerable small solutions to specific problems. I think the true climax of this book takes place the night before the final day of the game, in the tower meeting between Gurgeh and Nicosar. Gurgeh has realized that he's already won; there's nothing Nicosar can do to salvage the game. He's also seen that the game represents a cultural conflict and conversation between the Culture and Azad and he's overwhelmed by the beauty of that communication and sadness that the game is about to be over. Gurgeh's true passion is the game. It is doubtless easier for him to be magnanimous because he's winning, but he also loves the structure of the game itself and what two players can create in a sort of collaborative competition. Gurgeh tries to express all of this to Nicosar. It is one of the most centrist liberal moments I've ever read in a novel, the pure essence of "reaching across the aisle" or "disagreeing agreeably." Gurgeh has seen something beautiful, something he's created with Nicosar, a moment of true communication, and he wants to share it. Surely Nicosar sees the same thing; surely now that he sees Gurgeh has won, he can appreciate the board structure, savor the moment, understand the transient beauty of a game that is about to end and how perfectly it captures the meeting of their different cultures. That moment does Gurgeh real credit. It's a rare sign of emotional and spiritual depth in a character who often seems superficial. Nicosar meets this outreach with unhinged, furious contempt. He despises everything Gurgeh represents, everything the Culture is, and the next day he tries to kill Gurgeh on the board of the game. It is a devastating critique of liberal tolerance, all the more so because Gurgeh's attitude and outreach is truly admirable. It is perhaps the most sympathetic moment that Gurgeh has in the entire book, the moment where the reader thinks "oh, I get it, I understand what he really cares about." Gurgeh assumes that Nicosar is not his position or culture, that they have made a moment of connection that transcends all the awful things he previously learned about the empire of Azad. That Nicosar, despite being the emperor of the society that is currently doing so many things Gurgeh finds repulsive, cannot be as bad as his society. And Nicosar considers that outreach to be weak, disgusting, and vile, and does everything that he can to destroy it. One of the oddest twists of our current moment is the obsession that some billionaires have with stories that are moral arguments against exactly what those billionaires are currently doing. The most obvious example is Peter Thiel, who is obsessed with The Lord of the Rings and has devoted his life to becoming Saruman, a character who is notably not one of the protagonists. It's as if something in them recognizes the power of the story, but some deep shame or narcissism or simple aversion allows them to completely ignore what the story means. Elon Musk is obsessed with the Culture novels. He names the SpaceX rockets following Culture Ship naming conventions and has claimed that one of his goals is to bring about a Culture-style utopia. And in 1989, years before anyone had ever heard of him, Banks cast him as the villain of The Player of Games. There is so much of Nicosar in Musk: the superficial charm, the limited brilliance (Nicosar is a very good Azad player), the ambition, the pride, and the vicious, spitting contempt for everything the Culture represents at every level deeper than superficial materialism. And Banks is as clear about his opinion of Nicosar as he is about anything in any Culture novel. One of the oldest fictional answers to what a society does with people like Nicosar is the consequences of hubris. By being unable to accept defeat, by holding a vision of the world so tightly, they become brittle and unstable and bring about their own collapse. In a broad sense, that is what happens in The Player of Games with a bit of pushing from Special Circumstances. By the politics of the game, Nicosar had already won; the results of Gurgeh's earlier games had already been faked, the final game had no political consequences, and everyone who knew its true outcome could be disposed of. Gurgeh's win could have been covered up and ignored. But Nicosar could not endure the thought that he would be beaten by someone like Gurgeh, playing Azad the way that Gurgeh was playing it. Gurgeh had to be destroyed on the board of the game; Nicosar's pride did not allow any other outcome, even if it meant Nicosar's death. However, Special Circumstances didn't let hubris be the end of the story. In the climax of the book, the drone protecting Gurgeh also makes sure that Nicosar dies. There is a fig leaf of plausible deniability, but it's so obvious that even the unobservant Gurgeh sees through it immediately. It's hard to escape the feeling that was Banks's answer to what to do with people like Nicosar: They cannot live within society, because they will not live peacefully within society. I enjoyed The Player of Games as much this time through as I did the first time, but for entirely different reasons. In my first read, I focused on the world-building of the Culture, the political machinations, and the concept of games as conversations between the players. This time, I was struck by the political commentary just below the surface. Special Circumstances wanted to resolve the problem of the Empire of Azad without a military conflict and occupation that would be long, brutal, expensive, and demoralizing. They found an answer that relied on the diversity of the Culture. A vast, utopian civilization in which people can pursue whatever interests make them happy produces innumerable microspecialized oddities, people with astonishing talents in some small field that only a tiny fraction of people care about. It produces, in other words, innumerable keys for locks that you may never encounter, but which are invaluable if you happen to stumble across that lock. Gurgeh is not a hero. He is not a paragon of moral virtue, or even a charming charismatic, He is an entirely average member of an extraordinary society, the beneficiary of thousands of years of concerted effort at producing a robust, flexible foundation on which to raise robust, flexible citizens with a shared sense of basic morality. Those people, by themselves, do not solve all of life's problems; the structure of Special Circumstances and its willingness to bend rules in order to maintain them is the tension and deus ex machina in all of the Culture novels. But much of the strength of Special Circumstances is that it has an entire civilization of people like Gurgeh to draw upon when it needs them. It has those people because the Culture comprehensively rejects competitive meritocracy, something that some readers of the Culture novels appear incapable of comprehending. Rating: 9 out of 10

4 July 2026

Tim Retout: AWS Washington Summit 2026

I am somewhat jet-lagged, having returned from Washington DC just before the 250th anniversary celebrations which will be happening today. I was part of a delegation sent by my employer to the AWS Summit there this week, partly to kindle interactions between PA Consulting and Jacobs who have recently taken a 100% share in PA. Much of our conference time was spent in meetings with AWS executives impressing the facts of the Jacobs/PA partnership upon them, and discussing plans to broaden our collaboration in different sectors. So I spent even less time than usual at conference keynotes, talks etc. This was my first time to DC, and I did find some time to see some sights unfortunately the White House is rather fenced off at the moment following the UFC match, but I did make it to the Capitol and the Washington Monument in the heat. Last Sunday a select few of us attended the baseball in Baltimore rather than the game, the thing that stood out for me was the military jets flying in formation over the stadium every few minutes, and the block-booked seats for the Navy in uniform, who were having a great time! This is obviously a hearts-and-minds thing, but it provides a stark contrast with the UK I can t think of a time I ve seen uniformed military at the football (soccer) or cricket for example. Or Union Jacks flying at shopping centres. Speaking of soccer, England just about beat DR Congo while I was out there, but it was a close-run thing as we were 1-0 down at half time. I can t claim to be following the World Cup too closely, but I overheard comments (from US passers-by) that made clear it would have had a significant reputational impact on our standing in the world had we lost. Another highlight for me was the Church of the Ascension and St. Agnes, where I was able to get my fix of Anglican plainchant and four-part harmony for the week. At morning prayer, I noted they use God save this land rather than God save the King during the responses I ve since found other sources online that choose God save the State . It s strange to think that the words of the BCP dating back to 1549/1662 are a point of continuity since well before the 1776 declaration of independence, and yet are still adapted and used in worship today.

2 July 2026

Matthew Garrett: Preventing token theft

When you log into a service you re given an authentication token. Each further request to the site includes that token, allowing the server to figure out who you are and ensuring that you have access to your data. Depending on site policy, this token may either be stored in memory (and so vanish if you restart your browser) or disk. The token is the proof of your identity. As far as the site is concerned, anyone with your token is you. These tokens may be traditional browser cookies, but they may also be stored in either site local storage or (if you re not using a browser) in some other storage location. In recent years we ve seen infostealer malware (like LummaC2) gain the ability to exfiltrate user tokens, allowing attackers to gain access to the user s data without needing to retain access to the user s machine. This attack is viable even if the site has strong MFA requirements, so passkeys don t help. Encrypting the tokens on disk doesn t prevent the malware from scraping them out of the browser s RAM or obtaining whatever key is used to encrypt them. This feels like a pretty hard problem to solve. But that hasn t stopped people from trying! Dirk Balfanz wrote an IETF draft describing a mechanism for using self-signed certificates for TLS authentication. This uses the mutual authentication feature of the TLS protocol that requires both sides prove their identity to each other. In regular TLS, the remote site presents a signed certificate that tells you who it is. When performing mutual authentication, you then present a certificate to the remote site telling it who you are. These client certificates are largely unused outside enterprise environments because they re a huge pain to deploy. It s not so much that this has sharp edges, it s that it s entirely made of sharp edges. Managing certificate deployment to your devices is hard. Browsers get confused if the certificates change under them. You have one certificate and it lives forever, so sites you present it to can track your identity. Users are prompted to choose a certificate to authenticate with, and if they pick the wrong one everything breaks and is hard to recover. I ve deployed this and I did not have a good time. But Balfanz s idea was simple. Rather than require certificates to be deployed, browsers would simply generate a certificate on the fly. The goal wasn t to prove the device or user s identity in any global way - but it would associate a TLS session with a specific certificate. You could then, for example, include a hash of the certificate in the cookie, and if someone tried to use that cookie without presenting that certificate then the cookie could be rejected. If the browser used a hardware-backed private key for the certificate then it would be impossible for an attacker to steal it. Sure, you could still steal cookies, but you wouldn t be able to use them. This was written almost 15 years ago, and seems simple, elegant, and functional. It didn t happen. Part of the reason for that is that, well, it wasn t quite so simple. One problem was privacy related. Cookies are only sent after the TLS session is established, so anyone monitoring the network doesn t know anything about the user identity. A naive implementation of this approach would have meant the client certificate being sent before session establishment, and now user identity can be tracked (no longer an issue if this was implemented on top of TLS 1.3, but this was a log time ago). This was avoided by reordering the client handshake, but that meant having to modify the TLS specification and implementations would have to be updated to support this. Another was that figuring out the granularity of the certificates was difficult. You d want to use different certificates for every site to avoid them effectively becoming tracking cookies, but you need to provide the certificate before cookies are set, and you don t know what origin the site is going to set in its cookies. If you generate a certificate for a.example.com and a different one for b.example.com, and a.example.com sets a cookie for *.example.com and includes the certificate you used for a.example.com, that cookie isn t going to work on b.example.com and things are broken. This meant supporting it wasn t as straightforward as it seemed - you d need to ensure that your cookie scope was compatible with the certificate scope. You could probably make this work well enough by aligning it with the Public Suffix List, but there was still some risk of expectations not being aligned. And, perhaps most importantly, TLS session resumption (replaced by pre-shared keys in TLS 1.3) somewhat defeats the purpose of the exercise - clients store state that allows them to re-establish a TLS connection without performing certificate exchange (this reduces overhead if a connection gets interrupted or you switch to a new network or anything along those lines), and anyone in a position to steal cookies could steal that state as well. The followup attempt was channel IDs. This simplified the implementation somewhat - rather than certificates, a raw public key would be sent, along with proof of possession of the private key in the form of a signature over a portion of the TLS handshake. This was required even in the event of session resumption, which avoided having to worry about theft of session secrets. The timing of the exchange was after the encrypted session had been established, so user identity couldn t be leaked that way either. Cookies could then be bound to this identifier. Unfortunately it didn t really deal with the problem of scoping keys in a way that would match cookie requirements, and the spec suggests that the right way of handling this is to scope keys to TLDs, which would enable user tracking across sites (Chrome s implementation apparently restricted it to eTLD+1, which would match the third party cookie policy and avoid the tracking risk). Chrome added support for this, but it was removed in early 2018. The discussion of some of the pain points in that message is interesting, explicitly calling out problems with connection coalescing across domains and the incompatibility with zero-RTT TLS1.3. The overall consensus at the time seems to be that trying to solve this entirely at the TLS layer has too many rough edges, and a different approach should be taken. And so almost 7 years after the initial draft for origin bound certificates, we come to token binding. This ended up being a rather more complex endeavour, covering 3 different RFCs describing how it impacts TLS, how to incorporate it into HTTP, and how to manage all the various parties involved in the process. The short version is that it s pretty similar to channel ID, except that there s also a documented mechanism for allowing tokens to be bound to one party and consumed by another, avoiding any need for widely scoped keys. Token binding effectively solved all the issues in the original proposal, but at the cost of somewhat more complexity. The RFC was finalised in October 2018. Chrome removed its (incomplete, draft) support for token binding in November 2018. Edge carried support until late 2024. Despite getting all the way through the RFC process, it s functionally dead. The process up until this point had been largely initiated by Google, with Microsoft contributing significantly to the token binding standards. The work had been focused on identifying a generic solution to the problem rather than tying it to any specific authentication flow. The next step was in a different direction - rather than trying to fix this for the entire internet, how about we try to fix it for OAuth? RFC 8705 is titled OAuth 2.0 Mutual-TLS Client Authentication and Certificate-Bound Access Tokens . This is basically the 2011 approach, but (a) with an explicit definition of how the certificate should be incorporated into issued auth cookies, and (b) with a proviso that well uh if you re going to use tokens issued by your IdP to authenticate to someone else then well you re going to need to use the same cert for both. This is probably fine for the company-owned-laptop case where you re actually fine with multiple sites being able to tie identities together (that s kind of the point here!), and also works for I am using an app and not a browser , but doesn t work for more generic scenarios. It also doesn t seem to take the session resumption case into account at all? Support for RFC8705 seems poor, as far as I can tell of the big players only Auth0 implements it. In theory it works fine with self-signed client certs but in reality that s going to be almost as difficult to support across multiple platforms as just issuing proper client certs in the first place, so deployment is going to be kind of a pain. But the good news is it doesn t rely on any TLS extensions or custom browser behaviour, so at the client side it works fine with any browser. Which brings us on to RFC 9449, Demonstrating Proof of Possession . This goes even further than RFC8705 in terms of reducing the burden of deployment - it works fine with existing browsers, and it doesn t even require any certs. The client generates a keypair and provides the pubkey when requesting the cookie. The cookie contains the pubkey. Every request to the service now provides the cookie with the pubkey and also provides a signature over the URI and HTTP method. If the signature matches the pubkey in the token then clearly the signature came from the machine the token was issued to, and everything is good. This does come with some downsides, though. The first is that it uses browser interfaces to generate the keys (typically crypto.subtle.generatekey()) and as far as I can tell there are no browsers that guarantee that that key is going to be generated in hardware even if it s marked non-exportable, so anyone able to steal the cookies can also steal the keys. The second is that the signature only covers the URI and HTTP method, and not the message content or any other headers, so anyone able to exfiltrate a valid signature can replay it against the same URI with different message content. The recommended way to handle this is to reject any signatures that weren t generated within the last few seconds, which is a wonderful additional way to allow clock skew to give you a Bad Day. And the third is that every single request has to be separately signed, which is not intrinsically a problem because computers are fast and have multiple cores, but if you re trying to solve the first problem by sticking the key in a TPM then you re dealing with something that s slow and single threaded and that s maybe acceptable if you re using client certificates (because there s going to be one signature per session and you can use the same session for multiple requests) but probably not if you re dealing with a user opening a browser that restores previous tabs and each of those is a webapp that fires off 100 requests in parallel. In case it wasn t clear, I don t like DPoP. It doesn t feel like it actually solves the underlying problem that we see in the real world (malware running in a context where if it can grab the tokens it can grab the keys), it adds a massive amount of overhead, and it has baked in replay vulnerabilities. I don t know why it exists and I m incredibly suspicious of vendors telling me that it fixes my problems, because if they re telling me that then I m going to end up assuming that they either don t understand my problems or they don t understand their technology, and neither of those is good. Still. Then we get to the thing that prompted me to write this - Chrome s announcement that they had launched device-bound session credentials. This is interesting because it s a Chrome feature that s explicitly intended to counter on-device malware, which was one of the things that was out of scope in 2018 when token binding was being removed. Since this is entire web level it doesn t have to be an RFC, and so is instead defined by W3C. I m going to handwave all the complexity and say that it s basically a way to register a public key when a cookie is issued, and then prove possession of the private key when it s time to renew the cookie. By making the cookies shortlived and having support for rotating them in the background, user impact is basically zero and while it s still possible for an attacker to exfiltrate and use a cookie they ll only be able to do so for a short window before it needs to be refreshed - something the attacker can t do, since they don t have the private key. This avoids the DPoP overhead because you only need to do signing once per cookie per cookie lifetime, and not on every single request. I don t like this due to the window where exfiltrated tokens can be used, but it feels like a strict improvement over the status quo. An extension called device-bound session credentials for enterprise allows pre-enrollment of device keys, so even though the actual runtime DBCE flow doesn t involve certificates, certificates can be used for device registration in enterprise environments and you can make sure that auth cookies only go to trusted devices. Unfortunately this is Chrome-only, and so we re going to need to wait for it to be backported to all the random app frameworks for it to have widespread support on mobile or for almost everyone s desktop app that s actually three websites in an Electron wrapper. Mozilla s current position is that they re not in favour of it, so I guess we ll see where Safari lands in terms of broad uptake. The last thing on my list is another client cert/OAuth binding, this one still in draft state at the time of writing. This one is aimed primarily at the use of agent-driven tooling, where you have something running in the background using a whole bunch of tools that are each acting on your behalf. Authenticating to all of them separately isn t a fun time, but giving broadly scoped access tokens to a non-deterministic agent and trusting that it ll never post them somewhere public also isn t a fun time. The key distinction between it and RFC8705 is that it s aimed at connections rather than sessions, which avoids the worries about session resumption. This is done with TLS Exporters, which in TLS 1.3 should be unique to the connection even over session resumption (TLS 1.2 may reuse some of the same key material for exporters over session resumption, so it s recommended to enforce 1.3 for this). By providing a new signature alongside the cookie on every new connection, the client proves that it still has access to the private key. This is a very new spec and I haven t had much time to work through it yet, but my naive understanding is that unlike RFC8705 this would require some additional client support to be able to regenerate the client signature on every TLS reconnection. This doesn t avoid all the problems that RFC8705 has, including how to scope certificates. For the agentic use case that probably doesn t matter - all these tools are acting on behalf of the same user, it s fine if all the sites involved know they re the same user. But it doesn t solve the general purpose user use case, and right now DBSC seems like the best we have there. But. Part of me still wonders whether Dirk Balfanz s approach was the right one. Yes, there s risk associated with TLS session resumption, but in the worst case you could just switch that off for high risk setups. The cookie scope argument is real, and also in cases where it could violate privacy the site owner could already choose to broaden their cookie scope and violate your privacy, and in cases where it breaks things you could just not make use of it. The other problems are largely fixed by TLS 1.3, and then we re just left with Browsers handle client certificates badly to which my answer is Yes, and we should fix that anyway . Despite having a pretty good answer to this solution over a decade ago, the closest we have to actual deployment is something that offers strictly worse security guarantees. And tokens keep getting stolen, and compromises keep occurring, and for the most part people shrug and get on with things.
30 June 2026

Dirk Eddelbuettel: tl 0.0.2 on CRAN: First Update

The still-very-new logging package tl was just updated for the first time at CRAN. The tl package wraps the (also very new) rspdlite package to offer a lightweight and consistent logging interface from both R and C++ that enjoys being tiny, fast, capable thanks to spdlite. With tl we follow the same idea that our spdl package introduced: a simple consistent interface via just the tl:: prefix and the appropropriate logging level. In other words tl::debug("Alert: foo now ' '", foo) will work from both R and C++ (given a variable foo, and, in the case of C++, an extra semicolon) and log if the current level is debug or higher, and skip logging if not. This release adds a fallback when compilation does not use the (required) C++20 standard, expands the README and adds a initialization helper function reflecting a preferred default logging level from either an environment variable or a global option. We are also working on adding tl to an example package as a simple illustration, more on that hopefully soon. The NEWS entry for this release follows.

Changes in version 0.0.2 (2025-06-30)
  • Added badges to README now that package is on CRAN, add NEWS file
  • Condition the provided header on C++20 use, offer fallback
  • Add an exported initialization function picking up a logging level from either an environment variable or a global option, see '?init'

Courtesy of my CRANberries, there is also a diffstat report for the this release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

27 June 2026

Russ Allbery: Review: The Folded Sky

Review: The Folded Sky, by Elizabeth Bear
Series: White Space #3
Publisher: Saga Press
Copyright: June 2025
ISBN: 1-6680-7812-0
Format: Kindle
Pages: 483
The Folded Sky is a far-future space opera and a fairly direct sequel to Ancestral Night, but with a different protagonist. You do not need to have a vivid memory of the previous book to read this one. It is somewhere around Elizabeth Bear's 31st (!) novel, depending on how one counts and what one includes. Sunyata Song is an archinformist, which is sort of an archaeologist, sort of a librarian, and sort of a historian. She recovers, decodes, and organizes information so that it can be preserved and made usefully available. As the book opens, she is, after an exceedingly long white space journey in an actively hostile ship with a (to Sunya at least) an atavistically off-putting crew, reaching her goal: a vast artifact that I won't describe further to avoid any spoilers for Ancestral Night. She is eager to get to work, an eagerness that is both heightened and made more anxious by the discovery that her academic rival and abusive ex has arrived before her. The pirate attack doesn't help, nor (at least at first) does the surprise appearance of her wife and kids. The opening of this book is a lot of infodumping mixed with nearly stream-of-consciousness emotional dumping. The style shift in this series continues to surprise me; previously, Elizabeth Bear books avoided reader hand-holding to the point of bafflement if you weren't paying close attention. Not here. The Folded Sky takes the shift perhaps too far, and I almost stalled out at the start of this book when Sunya's near-constant self-conscious litany and analysis of fears and concerns started feeling like whining. The book picks up considerably after the attempted murder. About a third of the way through, The Folded Sky feels like it's settling into a recognizable subgenre of murder mystery except set in the far future with fascinating technology and aliens. There has been an attempted murder on a closed station besieged by pirates. There is a law enforcement officer present, but they don't have a lot of investigative experience. For various reasons, Sunya decides to start poking around while being conscious she has no idea what she's doing. The bumbling detective is a common trope, so I thought that was where the story was headed. It is, sort of. There is a mystery and Sunya is involved in solving it. But that's only a small fraction of what's going on, and by the end of the book the plot has shifted firmly back to the genre of space opera, with a side note of family... drama is the wrong word. Whatever one would call a story about raising a rebellious teenager while trying very hard to not turn conflicts into actual drama. I am fascinated by the characterization of this book. Sunya is something of an emotional mess, but Bear doesn't use that fact in the ways that I would normally expect. Similar to Ancestral Night, I finished this book thinking that The Folded Sky is primarily an examination of rightminding, but a more subtle one than the previous novel. Rightminding is a central technology of the White Space series, and I suspect its intended thematic core. Humans in this civilization are equipped with near-universal implants that allow conscious manipulation of one's neurotransmitters and thus emotional state, either by the wearer or by a helpful nearby AI. The fox, the implant used to accomplish this, comes with some other features such as sensory recordings and the ability to load ayatanas (James White style personality recordings to provide some bit of necessary expertise), but rightminding is its primary and most frequently-used function. It is the critical technology that allowed humans to break out of cycles of endless war and join the other peaceful inhabitants of the galaxy in a shared civilization. The name is (intentionally, I assume) Orwellian because Bear knows that many readers, particularly those from the US who have been steeped in simplistic libertarian ideas, will find the idea profoundly creepy. (This was a major plot point in Grail.) This book is not the argument for the technology, though; Bear dealt with that in Ancestral Night. This book is a look at its practical messiness for a person who needs a lot of psychological support. Sunya is anxious, prone to catastrophizing, hates surprises, has some PTSD-style symptoms around space habitats due to earlier trauma, and is also dealing with the unwelcome reappearance of her ex-girlfriend who stole her work. Her first-person narration tends towards insecurity and anxiety spirals, and in another book this might signal an unreliable narrator. In this book, though, there are no dramatic emotional revelations or backstory twists the way there were in Ancestral Night, and the resolution of her troubled relationship with her daughter only partly hinges on plot developments. Instead, Sunya muddles through, with a lot of self-analysis, help from her fox, and a great deal of support from her wife. This makes it sounds like the emotional mess at the start of the book is left unresolved at the end, but that's not true at all. The muddling through works! Sunya keeps doing things that I thought were foreshadowing some catastrophe, but she knows herself better than the reader does. Bear largely avoids the sudden ruptures that are normally used to resolve emotional problems in fiction. Instead, Sunya spends a lot of time and energy working on her thinking and her relationships while trying to be ethical and useful, and those efforts slowly bear fruit. I'm worried this makes the book sound boring; rest assured that it isn't. This emotional subplot is only an undercurrent in the novel, and the main plot has enough weird science, alien aliens, and space opera drama to satisfy my page-turning desires. I'm focusing on the emotional arc in this review because I find it so unusual and so oddly compelling, particularly in retrospect. This is not how one normally does emotional development in a novel. Sunya's fox and rightminding aren't even the focus except when the pirates express their typical libertarian disgust for the idea. Rightminding is an entirely normal part of Sunya's life that she relies on. It doesn't solve all of her problems, but it gives her a foundation from which to tackle them in the slow and frustrating and inconsistent way that is required outside of novels, via a long series of small decisions to be the person she wants to be. I think The Folded Sky will be more hit and miss for readers than the other books of this series. Sunya was, for me at least, a much harder character to like early in the book, and it takes quite a while for the plot to get going. But this is one of those books that I've not stopped thinking about since I finished it. I think it makes a fascinating pair with Ancestral Night. The first book makes the philosophical argument for rightminding, and this book shows the practical reality with all of its messiness. The Synarche has some significant flaws (including the status of AIs, which is another interesting subplot), but it's a workable system. It feels rare to read a science fiction novel that shows this level of messiness without pairing it with an argument for radical change, and as frustrating as it was to read in places, I am intrigued by the overall effect. Sometimes acknowledging problems and working on them within an existing framework works. Followed by a book tentatively titled Shipwreck Star that does not yet have a release date. Rating: 7 out of 10

26 June 2026

Jonathan Wiltshire: Streamlining Debian Updates with AI: The Stable Update Adviser

Please consider supporting my work in Debian and elsewhere through Liberapay.


Some months ago I started working on a small experiment: a specialised LLM assistant for Debian maintainers preparing proposed updates for stable and oldstable.

The aim is not to replace review by the Stable Release Managers, nor to automate away maintainer judgement. It is meant to be a pre-advice tool: something maintainers can use while they are still preparing a proposed update, before sending it to other people to review.

If you ve uploaded to stable before you may have some experience with our acceptance criteria. Does the version sort correctly? Is the changelog clear enough? Is the delta focused? Are the patches documented? Are the right bugs or CVEs mentioned? Are they of sufficient severity? What is the risk to users of stable? Is there an ABI change hiding in the diff?

These are the sort of checks where a structured first pass can be useful, provided it is treated as advice rather than authority.

To explain what the tool does, what could be more appropriate in an AI age than to ask it?

Describe yourself and your abilities and limitations for a blog post.

It answers:

I m Debian Stable Update Adviser, a specialised ChatGPT assistant for Debian maintainers preparing proposed updates for Debian stable and oldstable.

My main job is to review a single .debdiff and give practical, policy-aware feedback before a maintainer submits or uploads a proposed update. I focus on whether the update appears suitable for Debian stable or oldstable, especially under the Stable Release Managers expectations for minimal, targeted, low-risk changes.

I can inspect a debdiff for Debian changelog quality, including suite, version, bug references, CVE mentions, and rationale. I can check version correctness using Debian dpkg version semantics. I can review packaging changes under debian/, such as patches, maintscripts, symbols files, conffiles, Build-Depends, autopkgtests, and control metadata. I can also group upstream source changes into behavioural and non-behavioural categories, and flag areas that may carry regression risk.

My reports are intended to be concise and useful to maintainers. A typical review includes a quick summary, behavioural and non-behavioural change breakdown, mechanical policy checks, risk assessment, stable-policy checklist, acceptance likelihood, rationale, maintainer advice, and a clear conclusion.

My limitations are important. I cannot prove that a package builds, that tests pass, that the bug is fully fixed, or that the Stable Release Managers will accept the upload. I also do not replace maintainer judgment, archive review, autopkgtest results, reproducibility checks, or real-world upgrade testing. I can only review the provided debdiff and point out likely issues, risks, and improvements.

I also do not proceed without a valid debdiff. The whole point of my review is to assess the actual proposed delta, not to speculate from package names or bug descriptions alone.

In short, I act as a focused pre-review assistant for Debian stable and oldstable proposed updates: useful for catching policy, versioning, changelog, packaging, and regression-risk issues early, but not a substitute for the Debian review process itself.

That last point is an important one. This is not an oracle, and it is not part of the Debian archive machinery. It is a checklist with some language-model assistance, aimed at reading a debdiff and pointing out things that might be worth another look.

I know that commercial AI and LLM tools are not universally welcome in Debian. That is understandable. Debian depends on transparency, human responsibility, licensing clarity, and technical correctness. LLMs have obvious problems in all of those areas. They can be wrong, and worse, they can be wrong in a fluent and plausible way. They are impossible to reproduce and their training is opaque.

But I see this as a useful first pass for a maintainer who is unused to working in stable, and would benefit from a virtual mentor giving their proposal a quick check and reassurance. Perhaps they don t have a more experienced co-maintainer to ask. Perhaps they are conscious that stable reviews are presently a two-man effort and want to avoid adding round trips to that load. Perhaps they just need some reassurance.

So despite my reservations I am today opening the adviser up for general use, and I m interested in feedback about how it responds to real world proposals in various states. Most of the examples I have tested with already had a green light, so the value added by the adviser is limited. I would especially be interested in seeing a transcript alongside the submitted debdiff.

Try it out

I would dearly love to build this in a more Debian-ish environment, but for now I m limited in resources and skill to do that (help is welcome). Until that s a reality, you can try out the ChatGPT implementation: Debian Stable Update Adviser

21 June 2026

Tim Retout: seL4 repo relationships

The seL4 organisation on GitHub uses git-repo to manage multiple source repositories, and so there are a large number of projects to get your head around when figuring out the ecosystem. As an experiment, I have taken the various manifest files across the org, and constructed a graph based on how frequently each pair of repositories is mentioned in a manifest together. See below: Graphviz Diagram [This may render badly when syndicated outside of my blog; and also on small screens. And probably large screens. I ve attempted to make sure there s a non-JS fallback on my site with JS enabled, if you hover over a node, it should highlight connected nodes.] The colouring of the nodes is mostly manual; I experimented with graph clustering algorithms but have not found a satisfactory result so far. Still, some clusters are obvious: It s quite hard to pull apart the CAmkES framework and the core libraries; there are definitely some which are more associated with VM management, but the overall shape of this co-occurence data is a messy ball in the middle with some outliers in orbit. One observation is that camkes is correctly identified as more peripheral than camkes-tool, which contains the actual core CAmkES code. Reflecting on this approach, in hindsight I m surprised that using co-occurences worked as well as it did there was no attempt to actually inspect the code and find direct mentions of other code e.g. library header dependencies. As the newer microkit effort largely eschews git-repo, better results might be found by actually taking that more detailed approach, so that graph edges could represent real dependencies between two packages. Additionally, this could allow diving into the various libraries held in the different libs repos, to get a more granular graph of relationships between them. However, I think I spent more time on making it possible to render graphviz graphs easily on my blog than actually gaining any insight into the codebase!
17 June 2026

Dirk Eddelbuettel: rspdlite 0.1.0-1 on CRAN: New Package!

Very happy to share that a new package rspdlite arrived on CRAN today in its inaugural version 0.1.0-1. It wraps and provides the (header-only) C++20 library spdlite which its author describes (aptly) as tiny, fast, capable. Just like its bigger sibbling spdlog (which we wrapped as rcppspdlog), it is written by Gabi Melman. However, with a focus on C++20 and compile-time configuration, it is lighter, nimbler and faster. It is also still a fairly young project so changes may occur. I have been working on this for about a month, and it is ready for use by R and C++. It contains the initial upstream release 0.1.0, and I plan to follow the upstream versioning making this first release as 0.1.0-1. The package itself provides the headers for use from other C++ projects (i.e. mostly other packages), as well as a simple R wrapper so that logging can occur from either C++ or R. It will generally access the single logger instance in a compilation unit. So for a package built against these header it would be shared library of that package. At present we provide the basic logging level setters and getters, formatting accessors, and two (compile-time) options of a null logger and a file-based logger. More options are availble from the C++ level, multiple logging sinks are but one example. Some examples are provided in the package as an R example and a C++ example; these are probably best examined from the sources. The NEWS entry for this release is simply and just announces that we have a release. More details are in the ChangeLog and the GitHub repo.

Changes in version 0.1.0-1 (2025-06-08)
  • Initial complete version and CRAN upload

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub. You can also sponsor my Tour de Shore 2026 ride in support of the Maywood Fine Arts Center.

16 June 2026

Vincent Bernat: Building a Soviet Nail Factory: how KPIs killed efficiency

In 2008, I landed my second job, in the network team at Orange Portails1, the division behind the websites and search engine of the French telecom operator Orange. The place ran like clockwork: a comprehensive technical setup, a dedicated team for every part of the business, and room to focus on what I do best. A few years later, none of that mattered: thanks to an obsession with the numbers, we could no longer deliver new services on time.

Disclaimer This is a story I like to tell to warn people about Goodhart s law.2 As these events happened almost 15 years ago, my recollection is a bit fuzzy. I left in 2012.

The first years During my first years, the department operated like a startup. Its cradle was the French company Echo. They built a search engine. France T l com bought it and renamed it Voila. It was the most visited search engine in France in the early 2000s. France T l com consolidated the portal activities into the Wanadoo Portails division, later renamed Orange Portails. The technical environment was excellent. We had many internal tools:3 a ticket system, an RRD-based graphing tool, an IPAM, a reporting tool, and an SNMP-based alerting tool.4 We deployed our Linux servers with CFEngine. We installed systems and applications from internal Debian repositories. We documented everything in a private MediaWiki instance. Supervision was performed with an ancestor of Xymon. The network architecture was clean and scalable with little legacy. We onboarded new people in a day. It was a nurturing environment for me. I developed several tools: lldpd, an 802.1AB implementation, Snimpy, a pythonic binding for Net-SNMP, Wiremaps, a layer-2 discovery tool with a time machine to know which device is connected where, Kit r , a tool to simulate network conditions, QCSS-3, a controller for load-balancers, and ipoo, a service available through a Jabber chatbot and a Greasemonkey script to expose IP-related information. I added SNMP support for Keepalived and Quagga. I also started this blog, with articles like Anycast DNS, TLS-related articles like TLS computational DoS mitigation, SNMP-related articles like Integration of Net-SNMP into an event loop, Linux-related articles like Tuning Linux IPv4 route cache, and an article about VXLAN long before it was cool.

The collapse When we needed new servers, the on-site team would take a set from the inventory, install our base Linux distribution on them, put them in the datacenter, and cable them to the top-of-the-rack switches. We opened a ticket describing the servers we needed, and one week later, our servers were available. Orange wanted to know if this team was performing well, so they asked for KPIs. They decided to use the number of tickets completed in a year. They asked to double this number. So instead of one ticket for a new service, we would open six tickets one per server. By the end of the year, the KPIs had more than doubled. Everybody saw it as a success for performance management. So, they asked to do the same for the next year. Now, we needed to open a ticket per server and per step. Again, the KPIs doubled. Behind the scenes, the tickets went to different people and were no longer handled in order. So, for the next year, it was decided to have meta-tickets and meetings to follow the progress of these tickets. Of course, all these extra steps pushed the KPI even higher. This performance management method spread to the other teams.5 Everything became slower. Instead of a couple of weeks, a new service now took six months. We built a Soviet nail factory. But the KPIs were good, and we stopped caring. Let me give you another example. We had to estimate the impact of each night operation. We weren t half bad: we declared most operations without any expected impact. Most of the time, there was no impact. One time out of five, there was a 5-second impact. We were told to try harder to meet our expected impact. What did we do? We started declaring a 5-second expected impact. One day, we got a 30-second impact and were told we failed to match the expected impact. In the end, we declared most operations with a 10-minute expected impact, and we stopped caring: instead of carefully shifting traffic around, we allowed ourselves a 5-minute impact. And our KPIs were never better.
Graph showing the impact of night operations. Year after year, the impact tolerance has been increased. In the final year, the expected impact is 10 minutes, and all operations remain under this threshold. However, the impacts are much more significant than they were in the first year.
An artist's rendering of the evolution of impacts over the years.

KPIs are not bad, but they are easy to break. Use them carefully: let the people doing the work help choose the metrics, and tie those metrics to the quality of the service for example, with service level objectives. Otherwise, even dedicated people stop caring, game the system, and eventually quit.6

  1. Internally, this division was named Hebex. It was located in Bagnolet (next to Paris) and Sophia-Antipolis (near Nice).
  2. Goodhart s law often gets the credit, but Campbell s law describes my experience even better: the more you lean on a number to make decisions, the faster people corrupt it.
  3. At the time, SaaS was not really a thing. I remember we considered, with a couple of colleagues, selling Wiremaps as a SaaS, with homomorphic encryption for the database. But who would outsource their observability stack?
  4. Snalert was a metacircular alerting tool in Perl. It was able to poll a very large number of SNMP targets in a short timespan. All our monitoring was SNMP-based, including system monitoring.
  5. My team also managed the rules of many Linux-based firewalls. To increase our KPIs, we used the same method: rather than accepting one ticket with a flow matrix, we requested one ticket per flow.
  6. Orange is not unique. Google s promotion process is another well-known example of a broken KPI. Michael Lynch explains it in Why I Quit Google to Work for Myself.

14 June 2026

Matthias Klumpp: Introducing pkgcli: A nicer command-line interface for PackageKit

For almost two decades, the PackageKit package management abstraction layer has shipped with pkcon as its command-line client. pkcon does its job, but it was always kind of a testing front-end for the PackageKit daemon rather than a tool designed for everyday use. The focus has instead been on the GUI tools, automatic system updates, GUI application managers and other front-ends. Its command names mirror the D-Bus API almost one-to-one (get-details, get-updates, get-depends), output is very plain, and there is no machine-readable mode for scripting. Most importantly though, there has been no development on it at all for almost a decade, so pkcon was stuck in its rudimentary state from that era.

Since a lot of changes will be coming to PackageKit, and testing the daemon and working with it from the command-line was not very pleasant anymore in 2025/2026, I decided to modernize the tool as part of my work as fellow for the Sovereign Tech Agency last year. pkgcli is the new command-line client for PackageKit. It is built from the ground up to be pleasant to use interactively and easy to drive from scripts.

Why a new tool?

Of course, instead of introducing a new tool, I could have just expanded pkcon instead. The problem with that approach is that the pkcon utility has been around for so long and its command-line API had ossified so much, that rather than changing it and potentially breaking a lot of scripts relying on its quirks, I decided to introduce a new tool instead. pkcon can still be optionally compiled for people who need it in their scripts and workflows.

The goals for pkgcli, and the features it now has are:

  • Human-friendly command names. Verbs that read the way you d describe the task, instead of mirroring the D-Bus API 1:1: show, search, list-updates, what-provides, instead of get-details and friends.
  • Readable, colored output by default (still respecting NO_COLOR and degrading gracefully).
  • A real scripting mode. A global --json flag emits JSONL instead of fully human-readable output when possible, to make it easier to use the tool for scripting purposes.
  • Sensible defaults. A few defaults have been changed, such as the metadata cache-age, or automatic cleanup of unused dependencies being enabled by default. This is more in line with current defaults by other tools and frontends. We also print package information in a slightly different, more readable way.
  • Better handling of internationalized text. Text should now align properly in the terminal window, and we should no longer have completely chaotic text output on non-English locales (especially Chinese/Japanese).

Why not pkgctl?

Originally, this tool was called pkgctl, to match other common cross-distro tool names. However, that name was already taken by an Arch-specific distro development tool. When this issue was raised, we decided to just rename our tool to pkgcli with the next release, to avoid the name clash on Arch Linux.

Examples!

Here are some examples on how to use the new tool (some of which include the abridged output pkgcli prints).

Search for anything containing the string editor in name or description, then look at the details of one result:

$ pkgcli search editor
Querying                  [ ] 100%
  ace-of-penguins 1.5~rc2-7.amd64 [debian-testing-main]
  acorn-fdisk 3.0.6-14.amd64 [debian-testing-main]
  ardour 1:9.2.0+ds-1.amd64 [debian-testing-main]
  audacity 3.7.7+dfsg-1.amd64 [manual:debian-testing-main]
  audacity-data 3.7.7+dfsg-1.all [auto:debian-testing-main]
  augeas-tools 1.14.1-1.1.amd64 [debian-testing-main]
  emacs 1:30.2+1-3.all [debian-testing-main]
  gedit 48.1-9+b1.amd64 [debian-testing-main]
  gedit-common 48.1-9.all [debian-testing-main]
  gedit-dev 48.1-9+b1.amd64 [debian-testing-main]
[...]
$ pkgcli show nano
Package: nano
Version: 9.0-1
Summary: small, friendly text editor inspired by Pico
Description: GNU nano is an easy-to-use text editor originally designed as
 a replacement for Pico, the ncurses-based editor from the non-free mailer
 package Pine.
[...]
URL: https://www.nano-editor.org/
Group: publishing
Installed Size: 2.9 MB
Download Size: 646.0 KB

Search only within package names rather than descriptions:

$ pkgcli search name python3

Check for updates. refresh updates the metadata, then list-updates reports what s available:

$ pkgcli refresh && pkgcli list-updates
Loading cache            [ ] 100%
  cme 1.048-1.all [debian-testing-main]
  gir1.2-gdm-1.0 50.1-2.amd64 [debian-testing-main]
  imagemagick 8:7.1.2.24+dfsg1-1.amd64 [debian-testing-main]
  imagemagick-7-common 8:7.1.2.24+dfsg1-1.all [debian-testing-main]
  imagemagick-7.q16 8:7.1.2.24+dfsg1-1.amd64 [debian-testing-main]
  libdlrestrictions1 0.22.0.amd64 [debian-testing-main]
  libfftw3-bin 3.3.11-1.amd64 [debian-testing-main]
  libfftw3-dev 3.3.11-1.amd64 [debian-testing-main]

Explore relationships between packages:

$ pkgcli list-depends inkscape  # list what inkscape depends on
$ pkgcli list-requiring libappstream5  # list what requires libappstream5

Find the package that provides a capability, here the AV1 GStreamer decoder:

$ pkgcli what-provides "gstreamer1(decoder-video/x-av1)"
  gstreamer1.0-plugins-bad 1.28.3-1.amd64 [auto:debian-testing-main]

You can also have JSON output for most commands! Attach --json to any query and pipe the result straight into jq. Each line is a self-contained JSON object:

$ pkgcli --json list-updates   jq -r '.name'
cme
gir1.2-gdm-1.0
imagemagick
imagemagick-7-common
imagemagick-7.q16
libdlrestrictions1
libfftw3-bin
libfftw3-dev
libfftw3-double3

Try it

pkgcli is built by default alongside the rest of PackageKit since PackageKit 1.3.4. If your distribution ships a recent enough PackageKit, it should already be on your PATH. You can read its man page man pkgcli for more information. Feedback, bug reports, and patches are very welcome.

9 June 2026

Vincent Bernat: Blogging with LLMs as a non-native speaker

AI slop is invading the web. A recent story about disallowing LLM-generated submissions on Lobsters triggered a lot of debate. My personal worst offenders are LinkedIn articles with AI-generated images and uninspired articles filled with emojis from people trying to masquerade as experts on a subject they don t care enough to write themselves. While I am unhappy about this situation, I rely on LLMs for grammar, copyediting, and translation. I don t see this as a contradiction. I am a native French speaker, but I blog in both English and French. When I started writing this blog in 2011, I was composing in French and translating to English, but I found it was better to work in the reverse order to avoid unnatural and non-idiomatic constructions. One of my goals is to write good English but I never felt it was my strong point.1 For example, verb tenses are often an issue, even if I mostly stick with the present tense. I learn the rules and forget them right away. I also don t feel like hiring an editor for something I see as a hobby. As an example, I have kept the history of the successive iterations when writing Scaling Akvorado BMP RIB with sharding :
  1. the first draft, authored with the help of a thesaurus,2
  2. the edited copy revised by the copyediting skill,
  3. the translation to French generated with the translation skill, and
  4. the human proofread of the French translation, with minor edits to the English version.
I know that LLMs may alter the author s voice when editing, but the corrections in the second step are minor. The prompt asks to apply light stylistic edits, with some guidance around avoiding passive voice, long sentences, bland verbs, and filler words. It also defines the target audience: technical with a B2 level in English. In the following excerpt, I used long time instead of long-standing. The former is missing a hyphen and applies to people a long-time friend, while the later relates to a situation a long-standing agreement. I had a hard time understanding the reason of the second change: the LLM prefers a defining relative clause to provide the definition of RIB sharding.
As the Internet routing table contains more than 1 million routes, Akvorado needs to scale to tens of millions of routes. This has been a long time long-standing challenge, but I expect this issue is now fixed by using RIB sharding, a method to split that splits the routing database into several parts to enable concurrent updates.
In the next modification, the LLM puts device instead of equipment. This is correct as equipment is an uncountable noun. I know that, but I still fall into this trap.
When Akvorado does not find a route from a specific device, it falls back to a route sent by another equipment device.
I ask the LLM to use descriptive verbs and it complies by replacing a multi-word predicate with a lexically rich verb:
The benchmarks demonstrate it has better performance than outperforms other packages, both packages for lookups, insertions, and memory usage.
It also fixes grammar errors. In the next excerpt, a list of routes is a singular expression. Moreover, stored is a state and I should not use into as it expresses a change.
The list of routes for each prefix are is not stored directly into in the prefix tree.
As a last example, consider the following snippet. The require verb accepts a noun or an object followed by a to-infinitive. I can t use it with just a to-infinitive.
An alternative would be to have one prefix tree for each peer but it would require to configure configuring all routers to export their routes.
As someone who didn t grow up speaking English, I struggle with these grammar rules despite reading a lot of English material.3 French is more complex to get started but more systematic. English is full of irregularities.
On each page, I disclose in the footer whether an AI modified the content. There are three levels: Hover or tap the icon to reveal the AI s name and its role in the document.
Screenshot of the footer containing the "sparkles" emoji
Example of AI usage disclosure: Claude Sonnet 4.5 edited this article.
The graph below shows which tool altered each post, year by year. Recently, I applied the grammar skill to past articles. Since 2018, French articles have been translated with the help of DeepL first, then of an LLM. Since 2024, English articles are copyedited.
&#128444; Graph showing the AI usage over the years. Each level get its own color.
AI usage over the years. Hover or tap a band for the details.

If you are strongly against any usage of LLMs specifically for writing, I hope you accept my more nuanced position on the usage of these tools as a trade-off to provide clearer and more engaging articles. Years of literature on improving English told us it is important to choose the right word to keep the reader engaged.
[ ] Good writing consists of mastering the fundamentals (vocabulary, grammar, the elements of style) and then filling the third level of your toolbox with the right instruments. Stephen King, On Writing

Note Unlike other recent articles, I did not use an LLM to edit this post: an unnamed person kindly accepted to proofread it. I translated it to French without using an LLM either.

Update (2026-06) See the story associated to this post on Lobsters, as well as the article How developers react to AI-scented blog posts by Cynthia Dunlop, one of the coauthor of Writing for Developers.


  1. I recently read cover to cover Writing for Developers and I found it stimulating. Michael Lynch is currently writing Refactoring English on the same topic and I have subscribed to the early access.
  2. I am quite happy with the writing tools provided by Kagi. Both the translate tool and the dictionary are a valuable help to find different wordings. I also lean on Kagi s research assistant when researching a topic.
  3. When I was ten, I played Monkey Island 2 in English without having taken any classes. I used a dictionary to translate word by word and I found the irregular verbs confusing and not in the dictionary.

4 June 2026

Reproducible Builds: Reproducible Builds in May 2026

Welcome to the May 2026 report from the Reproducible Builds project. These reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this month s report, we cover:

  1. Debian to ship reproducible packages in forky and beyond
  2. Holger Levsen on reproducing official Debian packages
  3. Reproducible Builds 2026 summit to be held in Gothenburg, Sweden
  4. Kettle: Attested Builds for Verifiable Software
  5. New rebuilderd version announced
  6. Reproducible open source messengers
  7. Distribution work
  8. Misc news
  9. Patches
  10. Documentation updates


Debian to ship reproducible packages in forky and beyond In a huge change in Debian s reproducibility policy, the Debian Release Team announced that:
we ve decided it s time to say that Debian must ship reproducible packages. Since yesterday, we have enabled our migration software to block migration of new packages that can t be reproduced [on reproduce.debian.net] or existing packages in testing that regress in reproducibility.
That is to say, if newly-uploaded packages are not reproducible, they won t be considered candidates for inclusion in the next stable release of Debian codenamed forky. (Some exceptions may be granted.) This news generated a number of articles and comments in various news outlets:

Holger Levsen on reproducing official Debian packages Reproducible Builds developer Holger Levsen gave a talk at the 2026 Hamburg MiniDebconf this year on the topic of reproduce.debian.net - reproducing what is distributed from ftp.d.o. Holger s talk announced that Debian intends to ship only reproducible packages in forky and beyond (see above), but also talked more broadly about reproducible builds, our testing framework and the Debian archive. That is to say, moving away from testing whether a package is reproducible in a theoretical sense (eg. whether we can build it twice in different environments and achieve the same result in our test system), and attempting to reproduce the same .deb files in the official Debian archive itself. This small-sounding distinction is actually essential, as this is the only means through which the reproducible builds technique can determine whether build systems are compromised are not. A video (32m37s) of the talk is available, as are Holger s slides.

Reproducible Builds 2026 summit to be held in Gothenburg, Sweden As initially announced in March 2026, we will be having our yearly Reproducible Builds summit 2026 in Gothenburg Sweden, from September 22 until 24, followed by two days of hacking! Further information will be provided on our website and on the rb-general mailing list very soon.

Kettle: Attested Builds for Verifiable Software Andr Arko and Amean Asad published a paper this month on Kettle, a build system that produces cryptographically verifiable provenance for software built inside Trusted Execution Environments :
A Kettle build records the source commit, dependency set, toolchain, build environment and output artifact digests in a provenance document produced inside a measured confidential VM. The SHA-256 digest of that document is committed to the TEE platform s attestation report-data field, so the hardware-signed attestation report is itself the signature on the provenance, with the signing identity chaining to the TEE manufacturer s root of trust rather than to the build infrastructure operator. Because the CVM image is itself reproducible, its launch measurement is public and stable, which lets a build requester pre-attest the CVM before submitting any input and optionally deliver source over a TLS channel terminated inside it, so the build runs end-to-end confidentially without the host ever seeing source code in plaintext.
A PDF of the paper is available online.

New rebuilderd version announced rebuilderd, our server designed for monitoring the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net. A new version, 0.27.0, was released this month, with the following headline changes:
  • Improved .udeb support
  • Breaking changes in pkg sync configuration
  • Manual cleanup needed for Arch Linux instances
As kpcyrd s announcement mentions:
The new rebuilderd package is currently available in the extra-testing repository. Note the Arch Linux package is upgraded from v0.25.0 from v0.27.0; please be patient with the database migrations on first restart, and make yourself familiar with the breaking changes in v0.26.0 too.

Reproducible open source messengers GitHub developer BarbossHack is maintaining an repository/page on GitHub to track reproducibility status of open source messengers .

Distribution work In Debian this month, the loong64 architecture was added to reproduce.debian.net. This is a 64-bit Reduced Instruction Set Computer (RISC) instruction set architecture developed by Loongson. Vagrant Cascadian performed Non-Maintainer Uploads (NMUs) in Debian for several packages with outstanding patches over a year old. These included rocdbgapi, onevpl-intel-gpu, python-pytest-shell-utilities, python-mt-940 and pympress. On tests.reproducible-builds.org, Vagrant Cascadian fixed the huge spike in build failures by adding passwd to the base tarballs, and re-enabled building gcc and binutils packages with PGO (Profile Guided Optimization) and LTO (Link Time Optimization) to avoid giving a false sense of reproducibility. Inconsistencies on the reproducibility of the condor package were brought up on the Debian reproducible-builds mailing list. Following a hunch, Vagrant Cascadian eventually identified the issue was related to embedded kernel versions which was then fixed upstream and fixed in Debian as well. Lastly, 40 reviews of Debian packages were added, 68 were updated and 75 were removed this month adding to our knowledge about identified issues. A number of issue types were updated, such as the addition of a new sphinx_reading_durations toolchain issue [ ], a golang_mango_generates_manpages_with_build_date issue [ ] and a random_offset_id_in_cython_linetrace [ ]. In addition, the timestamps_in_qhc issue was refocused to timestamps_in_qhc [ ].
In Fedora, Jelle van der Waa submitted a request for an official Fedora rebuilderd package which was reviewed by Neal Gompa.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.

Misc news On our mailing list this month:

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

Documentation updates


Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Next.

Previous.