Search Results: "sto"

27 September 2026

Russ Allbery: Review: Ode to the Half-Broken

Review: Ode to the Half-Broken, by Suzanne Palmer
Publisher: DAW
Copyright: May 2026
ISBN: 0-7564-2013-X
Format: Kindle
Pages: 441
Ode to the Half-Broken is a standalone post-apocalyptic (sort of) science fiction novel. As this novel opens, the unnamed first-person protagonist is waking up in a bathtub in an abandoned building. They are covered in electromagnets and missing one leg. Waking up involved a secure reboot from a protected core kernel, so it is immediately obvious that the protagonist is a robot. That also explains the electromagnets, which interfere with their ability to control their body. Or they would, if the protagonist didn't have long-dormant combat routines available to deploy EM shielding and free themselves from the bathtub. There are no immediate answers to why someone embedded a virus in the data attached to a scientific paper on ants, an act so precisely targeted that it had to be personal. Or what happened to their leg.
"There are a number of electromagnets in the next room," I say. I point. "Behind that wall with all the holes in it." "Those are big holes. And fresh, too," the dog says. "I wonder what made them." "Electromagnets experiencing sudden velocity." The dog gives another of its short barks, and I am more convinced now it is laughing, though I was not attempting to be funny.
Ode to the Half-Broken has a classic science fiction beginning: in medias res in a future science fiction version of Earth where nothing is immediately explained, leaving the reader to work out the date and the setting. Helping us out is the protagonist, who is neither chatty nor very sociable with other characters but keeps up an analytical monologue about the world as they narrate events. We are some decades into a grim future. The United States has largely collapsed. Large parts of New York City are dangerous to humans due to disease and radiation. Neither of those hazards bother the large number of sentient robots; their scarcity, and therefore economy, is instead based on power. Robots that control solar power stations act as low-level mob bosses, trading power for information or labor. Our protagonist doesn't want to care about any of this. They retreated from the world long ago for a solitary life in the former New York Botanical Gardens studying ants. But they need a new leg and the best robot repair person nearby is a human woman outside of the city, so they reluctantly head in that direction, accompanied somewhat surprisingly by a cyborg dog. The typical science fiction apocalypse is caused by something specific. Classically, that event is a nuclear war, but writers found various alternatives before, during, and after the Cold War era: alien invasions, meteor showers, plagues, sea level rise, and peak oil and general environmental collapse, among many others. Less common is a post-apocalyptic novel where the collapse comes from multiple overlapping crises and accumulating failures, from a general failure to meet what Adam Tooze and others call polycrisis. The first time I encountered that style of post-apocalyptic story was in Octavia Butler's Parable of the Sower. It was one of the choices that made (and still makes) that book feel so chillingly realistic. The world background in Ode to the Half-Broken is shaped by that sort of polycrisis collapse. There is no one reason why New York City is a dangerous, irradiated ruin and society has collapsed into isolated and sometimes warring factions. It is not runaway artificial intelligence, or at least not directly; sentient robots were a late-stage innovation of the collapsing US civilization and a tool and accelerator of its many wars, but they were not the cause and may be a critical ingredient in building some functional replacement. Instead, society fell apart because we failed to address any of the growing problems and then turned on each other in the resulting ruins. The reader gets an idiosyncratic view of that collapse in flashback chapters intermixed with the main narrative of the initially unnamed robot protagonist, flashbacks told from the perspective of the man who invented the key component for robot sentience. As you would expect, those two narratives are linked. The reader will not discover how they are linked until late in the story. This book could have been extremely depressing. It is not, which says a great deal about Palmer's skill in telling it. The clinical distance of the protagonist in the early chapters helps considerably: They have rejected involvement in this world and therefore can describe it in detached, factual terms, aided by the tendency of most robots in this story to be slightly more precise, logical, and verbose than the human characters. But as the protagonist's clinical distance fades, as it must to allow the story's emotional stakes to rise, Palmer fills this book with moments of beauty and hope. A former nuclear submarine that has become the mind of a subway car is a key early ally. A collective has turned the Hudson Bridge into a thriving if chaotic community. Self-regulating enclaves of humans and robots are working together to try to build a livable world. Robots oversee pollinator swarms that are attempting to restore plant life, for no reason other than that they like order and stability and see this as a way of restoring both. This is a grim, post-apocalyptic world that does not dwell on either the grimness or the apocalypse. It is instead full of small moments of hope, collaboration, and personal connection. This is a story with villains, danger, pain, and risk. Despite the similar keywords and cover aesthetics, it bears little resemblance to Becky Chambers's philosophical Monk and Robot series. It is not, in any definition of the term, cozy; it's a post-apocalyptic adventure story about a robot and a dog making their way through a ruined civilization and fighting people who are trying to build something even worse on the rubble. But it's also charming and oddly happy. There are strong found-family vibes in the way that a party coalesces around the protagonist and eventually gives them a name, there is the quiet happiness of seeing a grumpy misanthrope slowly come out of their protective shell, and the rail mechs are an absolute delight. Like a lot of stories of happy small-group anarchism, I didn't entirely believe the politics and have some qualms about the realism of the ending, although perhaps I should strive to be as optimistic as Palmer writes. The somewhat dry and fussily precise first-person narration will also not be to everyone's taste; it worked for me by the end of the book, but it took a bit of reading to get used to it. But those quibbles aside, this was quietly lovely. It's a satisfying science fiction adventure story in a world with disturbing parallels to the one we're living in, but which uses those parallels to focus on small-scale collective efforts to build something better. And all the small details of the world-building are delightful: the different tiers of robots and their odd behaviors, the machine sense of purpose, even the mix of suspicion and generosity. The plot has large-scale implications, but it was the human-level details that charmed me. I still want another Fergus novel, but this was a highly successful foray outside of that series. Palmer has won two Hugos for her novellas, so I can't really say she's overlooked, but her novels aren't getting anywhere near the attention they deserve. Highly recommended. There is plenty of world-building room here for a sequel, but Ode to the Half-Broken reaches a satisfying standalone conclusion. So far as I know, no sequel is currently planned. Rating: 8 out of 10

25 September 2026

Reproducible Builds (diffoscope): diffoscope 331 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 331. This version includes the following changes:
[ Chris Lamb ]
* Support radare2 >= 5.9.0. (Closes: reproducible-builds/diffoscope#432)
* Update debian/tests/control.
* Update copyright years.
[ Christopher Baines ]
* Add support for .nar files via Guix.
You find out more by visiting the project homepage.

24 September 2026

Russell Coker: Links September 2026

Bjorn Stahl of the Arcan project wrote an insightful blog post The Day of a new Command-Line Interface: Shell [1]. He does a really good job of identifying problems and strategies for dealing with them, the UI of the results isn t suitable to what I do though. Using sqlite as an executable format (replacement for ELF) is one of the wildest ideas I ve seen in a while, it might actually have some good use cases too [2]. Andrew Dana Hudson wrote an interesting LongNow article about SciFi s focus on space travel when it seems unlikely [3]. TheDriven has an informative article about the Hands Off Our Fuel astroturf campaign that uses farmers as the face of an attempt to give tax exemptions to mining companies [4]. The Conversation has an interesting article about the new Chinese regulations restricting access to AI systems to prevent emotional dependence and prevent minors from having virtual partners or relatives [5]. Elana Hashman wrote an informative blog post about Python virtualenvs, has useful information for people who aren t Python experts and just need to get stuff done [6]. We need more systems in the NTP pool, I would consider doing this if I had a server with an IP address that won t change and no risk of bandwidth throttling [7]. Cory Doctorow has some interesting thoughts on the CEO fetish for AI even though it is almost never doing any good [8]. Steve Rose wrote an insightful article for The Guardian about the tech fascists of Silicon Valley [9]. Jacqui Lambie calls Pauline Hanson an angry little woman and a bloody coward , One Nation hate the rule of law [10]. The Conversation has an interesting article about Regime Change, the book about Trump by Maggie Haberman and Jonathan Swan [11]. Elvira Barry wrote an insightful article about the many failures of the Russian legal system, it s interesting to note that ALL those failures match things that the Trump regime is doing [12]. Pyotr Kurzin Geopolitics YouTube channel has an interesting interview about continental vs maritime powers in the context of what the US and Russia are doing [13]. Maxinomica has an interesting video about how China obtained a monopoly on rare earth metals and what happens next [14]. Anarcat wrote an insightful blog post The people vs the AI overlords about the problems that AI software development is bringing [15]. John Goerzen wrote an interesting blog post discussing the issues related to LLM use in FOSS projects [16]. Cybernews has an article about an exploit for Samsung, Xiaomi, Oppo, and OnePlus phones due to bad OEM kernel drivers and bad OEM API proxies, no company should release devices with proprietry drivers [17]. Scott Santens wrote an insightful article about how retraining fails laid-off workers and why UBI is needed when workers get replaced by LLMs [18]. libroot has some information on the Snowden archive and why so little of it has been used by journalists, we need more answers about this [19]. Drew Devault s list of Weird little guys of FOSS is interesting history about some people who are best avoided [20].

20 September 2026

Vincent Bernat: Bot-free self-hosted analytics with GoatCounter on NixOS

In 2016, I removed Google Analytics from this blog to avoid being complicit in feeding the biggest machine for harvesting personal data. Instead, I relied on GoAccess to analyze my server logs.1 For the past couple of years, the statistics have made no sense, despite my attempts to filter bots: AI scrapers inflate the number of visitors to around 2,000 per day. Eventually, I settled on GoatCounter, an open-source, privacy-friendly web analytics platform. I replaced the JavaScript client to filter bots more aggressively and added a CSS fallback. To improve reliability, I implemented a local proxy running on each of the five web servers serving this blog. The rest of this post details how these pieces fit together and how I deploy them on NixOS.

Why GoatCounter? GoatCounter does not collect personal data: instead of storing the reader s IP address or relying on cookies, it creates a session identifier valid for 8 hours from the user agent and the IP address. Its feature set is modest but sufficient for a blog. If you want to look at the interface, GoatCounter s author runs a public instance for his site. A hosted version lets you try it before running your own instance. With a single binary and an SQLite database, GoatCounter is one of the lightest self-hosted solutions. Privacy-friendly alternatives, in increasing order of complexity, include Umami, Plausible, and Rybbit.
GoatCounter dashboard showing some statistics from my blog, including an article on the spanning tree protocol with 1,224 views for the past week, the referrers, and the breakdown of browsers (52% Chrome, 32% Firefox, with 16% for Firefox 155 and 6% for Firefox 156)

Custom JavaScript client GoatCounter includes a small JavaScript client 2,189 bytes minified and gzipped. It ships some features I don t use: a visitor counter, tracking clicks, configurable settings, etc. I replace it with this function to register a hit:
const count = (  event, title   =  ) =>  
  const params = new URLSearchParams( 
    p: event   location.pathname,
    t: title   document.title,
    r: document.referrer,
    q: location.search,
    s: document.documentElement.clientWidth,
    e: !!event,
    rnd: Math.random().toString(36).slice(2, 7),
   );
  fetch( /count?$ params  ,   keepalive: true  ).catch(() =>  );
 ;
To filter bots,2 I go the extra mile by requiring a user interaction an idea I stole from Bear Blog.
let sendHit = () => (sendHit = () =>  , count());
["touchmove", "mousemove", "keydown", "pointerdown"].forEach((eventName) =>
  document.addEventListener(eventName, sendHit,  
    once: true,
    passive: true,
   ),
);
If a reader has disabled JavaScript in their browser, I record the hit using a CSS image. The :hover pseudo-class loads it only after an interaction, another trick stolen from Bear Blog. About 2% of my visitors fit into this bucket.3
<!DOCTYPE html>
<html lang="en" class="nojs">
  <head>
    <script>
      // The JavaScript code for this blog requires ES6
      if ("noModule" in HTMLScriptElement.prototype)
        document.documentElement.classList.remove("nojs");
    </script>
  </head>
  <body>
  <!-- ... -->
    <style>
      .nojs body:hover  
        border-width: 0;
        border-image: url('/count?p=/en/blog/2026-kpi-goodhart&t=Building...&r=NoJS&e=false');
       
    </style>
  </body>
</html>
Where GoAccess reported around 2,000 visitors a day, GoatCounter counts fewer than 200 humans.4 I assume AI scrapers use a low-effort approach: if the content is available without barriers, as on this blog, they don t spawn a complex mechanized browser that could trigger a page view. Even crawlers running JavaScript, like Googlebot with its headless Chromium, do not interact with the page and never trigger the events I listen to. The interaction-based proof of humanity I use is likely to keep working.5

Local proxy Five servers across the world in Europe and in North America serve the content of this website, but GoatCounter runs on only one of them. To avoid losing track of visitors when GoatCounter is down, I run a local proxy listening on the same /count endpoint. On each server, it stores the hits in memory with a buffer large enough to survive several days of downtime. It sends them in batches to the upstream backend using the /api/v0/count authenticated endpoint.
Servers on a map. web02 is in Paris, web03 in Helsinki, web04 in Nuremberg, web05 in Ashburn, web06 in Chicago.
I proposed the code for the proxy in pull request #909. GoatCounter s maintainer declined to maintain so much code for such a niche use case. As a fellow open-source developer, I often hold the same position for my own projects: a one-time contributor effort may translate into a long-term maintainer commitment. I expose the endpoint for the proxy on the domain of this website to evade ad blockers. This sounds like I don t respect the reader s choice, but as GoatCounter is privacy-friendly, I find it acceptable.
location = /count  
  access_log off;
  proxy_pass http://127.0.0.3:8087/count;
  proxy_pass_request_headers off;
  proxy_set_header Accept-Language $http_accept_language;
  proxy_set_header User-Agent $http_user_agent;
  proxy_set_header X-Real-Ip $remote_addr;
 

Deploying on NixOS My web servers run NixOS, a declarative Linux distribution with built-in configuration management. I manage this small fleet with Colmena, a stateless deployment tool for NixOS. My configuration is available on GitHub.

Deploying applications in containers For better isolation, each application runs inside an ephemeral lightweight container, powered by systemd-nspawn. Each container runs a stripped-down NixOS instance. A module wraps NixOS s containers options to avoid repeating the same options for each application.6 The containers share their network namespace with the host: the additional isolation is not worth the increased complexity. For a smaller footprint, I also disable a few non-essential services.
  config, lib, ...  :
let
  cfg = config.luffy.containers;
in
 
  # User-configurable settings for our custom module
  options.luffy.containers = lib.mkOption  
    default =    ;
    description = "Ephemeral containers sharing the host network.";
    type = lib.types.attrsOf (lib.types.submodule  
      options =  
        config = lib.mkOption  
          type = lib.types.deferredModule;
          default =    ;
          description = "NixOS configuration of the container.";
         ;
       ;
     );
   ;
  # Translate our options to NixOS containers
  config =  
    containers = lib.mapAttrs
      (name: container:  
        ephemeral = true;
        autoStart = true;
        privateNetwork = false;
        extraFlags = [ "--resolv-conf=replace-host" ];
        config =  
          imports = [ container.config ];
          networking.firewall.enable = false;
          system.stateVersion = config.system.stateVersion;
          systemd.services =  
            console-getty.enable = false;
            systemd-logind.enable = false;
            systemd-oomd.enable = false;
           ;
         ;
       )
      cfg;
   ;
 
To configure a GoatCounter instance running in a container and listening on 127.0.0.4:8088, we import the module7 and declare the container in the config.luffy.containers attribute set:
  pkgs, config, ...  :  
  imports = [ ./modules/container.nix ];
  config.luffy.containers.goatcounter =  
    config =  
      services.goatcounter =  
        enable = true;
        address = "127.0.0.4";
        port = 8088;
        proxy = true;
       ;
     ;
   ;
 
As the containers are ephemeral, we need to keep persistent data in directories on the host. We add a mounts option and ask NixOS s containers to expose the configured directories through the bindMounts option.
  config, lib, ...  :
let
  cfg = config.luffy.containers;
in
 
  options.luffy.containers = lib.mkOption  
    type = lib.types.attrsOf (lib.types.submodule  
      options =  
        mounts = lib.mkOption  
          type = lib.types.listOf lib.types.str;
          default = [ ];
          description = "Host directories mounted read-write at the same place.";
         ;
       ;
     );
   ;
  config =  
    containers = lib.mapAttrs
      (name: container:  
        bindMounts =
          lib.genAttrs container.mounts (path:   hostPath = path; isReadOnly = false;  );
       )
      cfg;
   ;
 
For example, to persist GoatCounter s database in the /var/db/goatcounter directory on the host, we add the directory to the mounts option and alter the service definition to tell GoatCounter where the database is.
  config, ...  :
let
  databaseDirectory = "/var/db/goatcounter";
in  
  config.luffy.containers.goatcounter =  
    mounts = [ databaseDirectory ];
    config =  
      services.goatcounter =  
        extraArgs = [ "-db=sqlite+$ databaseDirectory /db.sqlite" ];
       ;
     ;
   ;
 
A container may also need some secrets. Colmena can upload secrets without storing them in the Nix store. We add a keys option to our containers. It takes an attribute set mapping secret names to the commands to populate them. Then, the module declares the required secrets to Colmena in the deployment.keys option, makes the container depend on the presence of the secrets, and exposes them to the container.
  config, lib, ...  :
let
  cfg = config.luffy.containers;
in
 
  options.luffy.containers = lib.mkOption  
    type = lib.types.attrsOf (lib.types.submodule  
      options =  
        keys = lib.mkOption  
          type = lib.types.attrsOf (lib.types.listOf lib.types.str);
          default =    ;
          description = "Secrets, as a command to run locally. They are mounted in /etc.";
         ;
       ;
     );
   ;
  config =  
    # Colmena uploads each secret in  /var/keys  and make them available
    # to the group "keys".
    deployment.keys = lib.concatMapAttrs
      (_: container: lib.mapAttrs
        (_: keyCommand:  
          inherit keyCommand;
          group = "keys";
          permissions = "0640";
          destDir = "/var/keys";
         )
        container.keys)
      cfg;
    # The container can only start if the required secrets are available.
    systemd.services = lib.mapAttrs'
      (name: container:
        let
          units = map (key: "$ key -key.service") (lib.attrNames container.keys);
        in
        lib.nameValuePair "container@$ name "  
          requires = units;
          after = units;
         )
      cfg;
    # Mount each secret inside the container.
    containers = lib.mapAttrs
      (name: container:  
        bindMounts = lib.mapAttrs'
          (key: _: lib.nameValuePair "/etc/$ key "  
            hostPath = "/var/keys/$ key ";
            isReadOnly = true;
           )
          container.keys;
       )
      cfg;
   ;
 
For example, GoatCounter needs credentials to download the GeoIP database. I provide a local command to fetch the secret from my password manager and expose it inside the container through the /etc/goatcounter.env environment file.
  pkgs, config, ...  : 
let
  keyCommand = variable: [
    "$ pkgs.runtimeShell "
    "-c"
    "pass show personal/nixops/secrets   grep '^$ variable ='"
  ];
in  
  config.luffy.containers.goatcounter =  
    keys."goatcounter.env" = keyCommand "GOATCOUNTER_GEODB";
    config =  
      systemd.services.goatcounter.serviceConfig =  
        EnvironmentFile = "/etc/goatcounter.env";
        SupplementaryGroups = [ "keys" ];
       ;
     ;
   ;
 

GoatCounter server Nixpkgs already packages GoatCounter. By overriding the src and vendorHash attributes, I reuse its definition for my custom version with the proxy:
  goatcounter, fetchFromGitHub  :
goatcounter.overrideAttrs (_:  
  src = fetchFromGitHub  
    owner = "vincentbernat";
    repo = "goatcounter";
    rev = "feature/proxy";
    hash = "sha256-dJRlQlFu3tjcEgabT1LEbyFrasJlhmYu4L/T7EkoNcY=";
   ;
  vendorHash = "sha256-c9Q5OrbZR+q6pD3SgPPWe8JUzcZco1AVUKGaV61k5DE=";
 )
I wrote a NixOS module to encapsulate GoatCounter: the container definition, the service definition, and the secrets. The module accepts the following options: package, serve.enable, serve.listenAddress, serve.port, and serve.databaseFile. I already detailed the container configuration in the previous section. In the end, I chose not to reuse the GoatCounter module from NixOS: it s small, so it s better to insulate my module from unexpected future changes.
  config, pkgs, lib, ...  :
let
  cfg = config.luffy.goatcounter;
  databaseDirectory = builtins.dirOf cfg.serve.databaseFile;
  chown = "$ pkgs.coreutils /bin/chown -R";
in  
  config.luffy.containers.goatcounter =  
    config.systemd.services.goatcounter =  
      description = "GoatCounter Web Analytics";
      wantedBy = [ "multi-user.target" ];
      serviceConfig =  
        EnvironmentFile = "/etc/goatcounter.env";
        SupplementaryGroups = [ "keys" ];
        DynamicUser = true;
        Restart = "always";
        ExecStart = lib.escapeShellArgs [
          (lib.getExe cfg.package)
          "serve"
          "-listen=$ cfg.serve.listenAddress :$ toString cfg.serve.port "
          "-tls=none"
          "-db=sqlite+$ cfg.serve.databaseFile "
          "-automigrate"
        ];
        # Transfer database ownership to dynamically assigned user "goatcounter".
        ExecStartPre = "+$ chown  goatcounter:goatcounter $ databaseDirectory ";
        ReadWritePaths = databaseDirectory;
       ;
     ;
   ;
 
The following snippet configures GoatCounter to listen on 127.0.0.4:8088:
 
  luffy.goatcounter =  
    serve =  
      enable = true;
      listenAddress = "127.0.0.4";
      port = 8088;
     ;
   ;
 
The last step is to configure nginx to expose GoatCounter on the Internet. I disable the /count endpoint as the local proxy handles it.
  config, ...  :
let
  cfg = config.luffy.goatcounter.serve;
in
 
  services.nginx.virtualHosts."goatcounter.luffy.cx" =  
    forceSSL = true;
    locations =  
      "/" =  
        proxyPass = "http://$ cfg.listenAddress :$ toString cfg.port ";
       ;
      "= /count".extraConfig = ''
        return 404;
      '';
     ;
   ;
 

GoatCounter proxy The same NixOS module configures the local proxy, with the following options: proxy.enable, proxy.listenAddress, proxy.port, and proxy.site the site receiving the batches of page views. The local proxy has no persistent data, but it needs the API key to authenticate to the main GoatCounter instance: its container uses the keys option but not the mounts option.
  config, pkgs, lib, ...  :
let
  cfg = config.luffy.goatcounter;
  keyCommand = _: [ " " ];
in
 
  config.luffy.containers.goatcounter-proxy =  
    keys."goatcounter-proxy.env" = keyCommand "GOATCOUNTER_API_KEY";
    config.systemd.services.goatcounter =  
      description = "GoatCounter Proxy.";
      wantedBy = [ "multi-user.target" ];
      serviceConfig =  
        EnvironmentFile = "/etc/goatcounter-proxy.env";
        SupplementaryGroups = [ "keys" ];
        DynamicUser = true;
        Restart = "always";
        ExecStart = lib.escapeShellArgs [
          (lib.getExe cfg.package)
          "proxy"
          "-site=$ cfg.proxy.site "
          "-listen=$ cfg.proxy.listenAddress :$ toString cfg.proxy.port "
          "-ratelimit=10/1"  # 10 requests per second per IP
        ];
       ;
     ;
   ;
 
For each server, I enable the local proxy with the following snippet. The nginx configuration shown earlier exposes the /count endpoint under the same domain as my blog.
 
  luffy.goatcounter =  
    proxy =  
      enable = true;
      site = "goatcounter.luffy.cx";
      listenAddress = "127.0.0.3";
      port = 8087;
     ;
   ;
 

Backup of the SQLite database with Litestream Litestream is a streaming replication tool for SQLite databases. It compresses the changes committed to the write-ahead log (WAL) next to the database and sends them to a remote destination. I encapsulate its configuration in a NixOS module, which takes an attribute set databases mapping a name to the path of the database to back up. Litestream also runs in a container. I mount the databases to replicate, as well as the secrets to push the backups to a Hetzner storage box using SFTP:
  config, pkgs, lib, ...  :
let
  cfg = config.luffy.litestream;
  databaseDirs = lib.unique (map builtins.dirOf (builtins.attrValues cfg.databases));
in
 
  config = lib.mkIf (cfg.databases !=    )  
    luffy.containers.litestream =  
      mounts = databaseDirs;
      keys."litestream.env" = [
        "$ pkgs.runtimeShell "
        "-c"
        "pass show personal/nixops/secrets   grep '^SQLITE_BACKUP_'"
      ];
     ;
   ;
 
Inside the container, I configure Litestream through NixOS s services.litestream options:
  • full snapshots every day, kept for 15 days,
  • three levels of compaction for transaction files: 5 minutes, 30 minutes, and 3 hours,
  • auto-recovery,8
  • replica stored in a directory matching the host name, and
  • credentials read from /etc/litestream.env and exposed through variable expansion.
  config, pkgs, lib, ...  :
let
  cfg = config.luffy.litestream;
in
 
  config.luffy.containers.litestream =  
    config =  
      # The databases belong to dynamically allocated users, whose UID is
      # not known here, so Litestream runs as root.
      systemd.services.litestream.serviceConfig =  
        User = lib.mkForce "root";
        Group = lib.mkForce "root";
       ;
      # Use NixOS service.
      services.litestream =  
        enable = true;
        environmentFile = "/etc/litestream.env";
        settings =  
          auto-recover = true;
          snapshot =  
            interval = "24h";
            retention = "360h";
           ;
          levels = [
              interval = "5m";  
              interval = "30m";  
              interval = "3h";  
          ];
          dbs = lib.mapAttrsToList
            (name: path:  
              inherit path;
              replica =  
                type = "sftp";
                host = "\$ SQLITE_BACKUP_HOST ";
                user = "\$ SQLITE_BACKUP_USER ";
                password = "\$ SQLITE_BACKUP_PASSWORD ";
                host-key = "\$ SQLITE_BACKUP_HOSTKEY ";
                path = "$ config.networking.hostName /$ name ";
               ;
             )
            cfg.databases;
         ;
       ;
     ;
   ;
 
To back up GoatCounter s database, I declare a goatcounter attribute in luffy.litestream.databases, set to the database path:
  config, ...  :
let
  cfg = config.luffy.goatcounter.serve;
in
 
  luffy.litestream.databases.goatcounter = cfg.databaseFile;
 
On the SFTP server, we can inspect Litestream s work, with the compacted transactions and the full snapshots:
  ls web02/goatcounter/ltx
web02/goatcounter/ltx/0
web02/goatcounter/ltx/1
web02/goatcounter/ltx/2
web02/goatcounter/ltx/3
web02/goatcounter/ltx/9
  ls -lh web02/goatcounter/ltx/1
29.1K Sep  5 01:25 0000000000003f2a-0000000000003f2b.ltx
72.4K Sep  5 02:03 0000000000003f2c-0000000000003f2d.ltx
63.3K Sep  5 02:24 0000000000003f2e-0000000000003f2f.ltx
[ ]
  ls -lh web02/goatcounter/ltx/9
 8.5M Sep  5 02:00 0000000000000001-0000000000003f2b.ltx
 8.5M Sep  6 02:03 0000000000000001-0000000000004008.ltx
 8.6M Sep  7 02:03 0000000000000001-00000000000043a8.ltx
[ ]
We can restore the database from the backup with a few shell commands. First, we stop the containers. Then, we move the damaged database away, invoke litestream restore from the right environment, and restart the containers.9
# systemctl stop container@goatcounter container@litestream
# mv /var/db/goatcounter/db.sqlite ,.old 
# ( . /etc/nixos-containers/litestream.conf ; 
>   set -a ; . /var/keys/litestream.env ; set +a ;
>   $SYSTEM_PATH/sw/bin/litestream \
>     restore -config $SYSTEM_PATH/etc/litestream.yml /var/db/goatcounter/db.sqlite)
# ls -lh /var/db/goatcounter/db.sqlite
-rw-r--r-- 1 root root 20M Sep 20 07:33 /var/db/goatcounter/db.sqlite
# systemctl start container@goatcounter container@litestream

Ten years after removing Google Analytics, JavaScript-based analytics is back on this blog, but without storing cookies or IP addresses, and without involving a third party. I still write for myself first, notably because it lets me dig into a topic and refer back to it years later. But knowing a bit more about my fellow human readers is a nice bonus, even the ones disabling JavaScript.

  1. Nginx scrambles IP addresses before storing them, thanks to the ipscrub nginx module.
  2. GoatCounter already filters some bots based on the user agent or the IP address. But AI scrapers lie about their user agent and hide behind residential proxies.
  3. Without JavaScript, I cannot send the real referrer. I insert NoJS instead.
  4. I am missing the humans reading the RSS feed. I am not comfortable adding a tracking pixel, and bots are likely to fetch it, compromising the statistics. I ll live without counting these readers.
  5. In February 2025, I tested another CSS-only approach without the interaction trick: each page loaded an empty image as a background. Over a month, it recorded up to ten times fewer page views than the nginx logs, even after removing user agents identifying as bots. Compared to this experiment, GoatCounter counts about three times fewer views, 18 months later. As the time ranges differ, this is not an apples-to-apples comparison, but it gives a hint about how efficient bot filtering is.
  6. A NixOS module is a function receiving the configuration of the whole system as config and returning three attributes:
    • imports adds other modules to import,
    • options declares user-configurable settings, each with a type and a default value, and
    • config sets values for options declared by any module, like containers from NixOS.
    If a module does not need to declare options, you can return the config attribute set directly. When a module does not require any argument, you can define it as an attribute set instead.
  7. Most of the time, you don t need an explicit import. NixOS automatically imports the modules shipped with Nixpkgs. For my own modules, some machinery also imports them automatically.
  8. Litestream warns against using the auto-recover option as it can cause data loss. But I don t properly monitor my servers and I prefer uninterrupted backups to a slight chance of losing the last few records.
  9. In my case, the process is slow: around 20 minutes for a 20 MiB database. You can test by restoring to a copy with the -o option, but you still need to stop the Litestream container.

18 September 2026

Paul Tagliamonte: Why Write?

As a graduate of a liberal arts university, I wound up, unsurprisingly, taking a lot of classes in every possible academic discipline. Thinking back to the person that I was going into university, I don t think I would have chosen to take them after all, my degree was in the sciences; I d have been stoked to do nothing more than wall-to-wall computer science until I ran out of coursework and filled the rest of my hours with research and independent studies with my professors (which, I guess I did actually do, just not as much as I would have otherwise). Even this blog s CSS theme (now 18 years old and starting to look it) was something I wrote after receiving and repeatedly re-reading a tattered third-hand copy of The Laws of Thought by George Boole. It was gifted to me by a college friend majoring in philosophy while I was crashing at his rental on the beach. He gave it to me because he knew I liked that shit and, while it was definitely computer science in nature, I would not have read it otherwise. I have vivid memories of sleeping on his la-z-boy surrounded by towers of books he was working through. He went on to do incredible work, getting his PhD, doing research, brilliant writing his death in 2023 has robbed humanity of more time with him. The Laws of Thought sits behind me in my office, and is one of my most valued possessions. My friends mean more to me than I could ever express, and I definitely don t show it enough. Each of my classes made me a more thoughtful person. My professors made me a better, more well-rounded person and a person who attempts to live up to the oft repeated credo of being men and women for others . I did the best I could, even though I was never a particularly good student. Without liberal arts, I don t think I would, dispositionally, have been capable of pushing myself to this day to continue to learn on nights and weekends, for no reason other than wanting to learn. I refuse to stop expanding my perspective, and do my best to approach new problems with as much humility and curiosity as I can muster. Every few days for the last year or so, I have been thinking back to a reading assignment from my junior year that, at the time, I thought was a borderline throwaway filler assignment for the class. The reading is an essay from 1947 by the french existentialist philosopher and libertarian marxist, Jean-Paul Sartre (as some of the more erudite may have now already worked out given the blog s title), Why Write? . I re-read it this week. It is not filler. I remember this essay better than some of the classwork I considered more important at the time.

Why Write? Why Write? starts off by describing the ways in which writing trying to communicate your thoughts, opinions, or feelings to others is an act of projection. The writer will only ever draw from a place of their own subjectivity writing is taking your person and putting it on display. You re choosing what words to use, how to use them, pulling from knowledge you ve accumulated (based on how you ve chosen to spend your time). Spending any amount of your finite existence in order to convey a thought is, itself, announcing to the world that you believe it to be a thought worth sharing. Meanwhile, the act of reading is not simply turning letters into words. Reading is engaging with the work, and understanding the work in a process that looks more like what Sartre terms re-invention or discovery the literary object, though realized through language, is never given in language . It is not enough to read the words in a book end-to-end; you must, as a reader, actively engage with the work to understand what is being communicated by those words. Reading is to take the words on the page, and exceed the mere words through what he calls directed creation . The reader is re-inventing / discovering the writer s thoughts by following their landmarks in the void . And this all makes pretty good sense to me I know if someone is being sarcastic because I know the writer; I have read their words and have read into their words, allowing myself to be directed by the writer into discovering the thought they have left me in their work. I understand that their words are humorous, not irate. Knowing who the author of a work is can completely change the point of a sentence. The fact I m writing about Sartre at all, or that this very writing has been constrained for presentation in this blog s CSS is only happening because of who I am, what things I ve experienced in life, and what has made me, me. Sartre argues that this dyadic coupling between writer and writing means that I, as a writer, can never truly read my own writing. I will never be capable of reading my own work and getting something out of it the work is already an extension of my own person. I can discover no thought in my own works. Of course, Sartre, as an existentialist, is honor bound to go one step further here the reader, by participating in reading a work, is asserting their own freedom. Every time a writer writes [ ] the writer appeals to the reader s freedom to collaborate in the production of [their] work . The creative act may only be complete if both writer and reader have recognized one another and made a choice to do so. No one is compelled to complete the creative act. The things you read matter. Reading something fundamentally alters you as a person you can not simply un-read a thought. Everything you read changes your universe. I have a hunch Sartre would find things like the (original early 2010s era) tl;dr reply to obviously terrible writing absolutely hilarious as a reader s expression of freedom (not to be confused with modern 2020s era usage as shorthand for summary section ). Using your freedom to choose to complete the writer s creative act (or not) is inherently asserting your humanity. I m a bit fuzzy on the specifics of this quote, but I think it was sj who told me at one year s Mystery Hunt that A puzzle is a contract between puzzle author and puzzle solver, the author promises that the puzzle is solvable if you re clever enough . The puzzle author and puzzle solver are engaging in a collaborative production of the work that is only possible by recognizing one another. Similarly, Sartre whatever connections [the reader] may establish among the different parts of the book among the chapters or the words [the reader] has a guarantee, namely, that they have been expressly willed .

Wall Drawing #123 It follows, Sartre argues, that the act of writing, as a means to convey a thought to a reader, may only be completed through the act of reading. Reading can only be done by others; writing, therefore, only exists to be read it can serve no other purpose. Writing and reading are two halves of the same creative, collaborative act, only satisfied when both writer and reader acknowledge one another. Combined, writing and reading are the act of recognizing one another s humanity, thoughts, experiences, consciousness the act of co-creation of thought is the critical aspect of writing and reading reconstructing the author s perspective, thought, intent, point. The co-creation is the point of both reading and writing. Writing without anyone to read the work leaves the writer s bid for co-creation unsatisfied and humanity unrecognized. No thought has been conveyed to any reader, no one has understood the reason behind the landmarks in the void you ve carefully placed, leaving you to either [ ] put down [your] pen or despair . Writing is an appeal to the reader s freedom, and the nature of that freedom is the writer can not control it never being understood is always a possibility any time anyone sets out to write. Nearly 12 years ago, I attempted to read the text on the git manpage generator for the first time I remember the exact feeling of my brain going into git manpage parsing mode where every word was dragging git plumbing megaliths through the sand from their far-flung homes. I can still feel the surface of my desk as I instinctually started to trace out logical connections between git internals referenced as I read along. It took me a good 20 seconds to realize what I was reading made no sense. This website broke Sartre s writer-reader agreement I was attempting to read this website, but there was nothing there. You can mechanically read the git-man-page-generator, but you can never read it it is not possible to read it. It was funny unsettling. Each grasp at a real-looking image in front of me misses, my hand coming back empty. I couldn t get enough of it. I must have tried to read a dozen generations in a row. I had never had something quite that broken pass that far into my consciousness before. Although I kept trying, it never did feel quite the same as that first time; I think fundamentally, I couldn t forget that it was random. While never having anyone read your writing drives them to put down your pen or despair , Sartre never had to contend with the opposite problem being asked to read that which was not written. Reading that which was not written does not merely leave someone unrecognized when a reader makes a choice; instead, it is an inherent violation of the contract between reader and writer. Not only is no humanity being recognized through attempting to read words which were not written, but the reader, not the writer, is the one who bears the burden of unexpected apophenia. The reader, while engaging in co-creation, must now contort themselves to uphold their end of the Sartrean agreement, scrutinizing text to ascribe consciousness, thought and intent only to come back up with pareidolia-fueled echos of one s own self and disfigured half-thoughts of others. The reality is, the modern reader must now mechanically read most written work they come across, scrutinizing text for any signs of thought before truly attempting to read the work. Failing to do this correctly changes our person each time it happens, a small part of us is irrevocably altered. Choosing to engage in this ballet because you wish to do so is one thing this is your right and freedom as a reader but passing words which were not written as your own in an attempt to wrestle a reader s freedom of co-creation from them is another entirely. If you didn t write it, I don t want to read it (dw;dr). Send me your prompt instead.

Petter Reinholdtsen: Long term storage of Mattermost messages with Noark 5 XML

It is said that those who cannot remember the past are condemned to repeat it, a quote often attributed to the American philosopher George Santayana. And to remember the past, records must be maintained and kept accessible to learn from. With this in mind, it is no wonder that archivists worldwide consider it crucial to ensure the archival records are both complete and accurate, with a constant frustration caused by the knowledge that the archives are neither due to challenges in tracking down and collecting what should be archived. The last few days, I decided to simplify the collection of Messages from the Mattermost chat service, used by a few of the organisations I am involved in, to try to improve the situation slightly. To achieve this, I had written a dedicated extraction tool. Partly to see how hard it would be, and partly to ensure that if one of the services were shut down or replaced, everything in it would not be lost. Of course it is in the nature of the use of instant messages that most of them are not fit for permanent storage, at least not according to Norwegian law, where there is a threshold "worthy of the archive" (arkivverdig) that should be met, and messages like "should we go to lunch now" are below the bar and should be filtered out. The tool can not help with this filtering, and that will have to be done using other means after collection. The tools I had my bullshit generator write, under strict supervision and many iterations, will extract every message visible to the user whose credentials are used to log into Mattermost, and write it out in Noark 5 extraction XML format and visualize the result. I created the visualiser mostly to quickly be able to debug the extracted XML, but also to make life easier for anyone interested in testing out the tool set. The extractor mattermost-noark5extract create a hierarchy with arkiv/arkivdel for the Mattermost server, and then individual mappe for each channel and direct message chat, a registrering for each message thread, dokumentbeskrivelse for every message in the tread, and one or more dokumentobjekt for each message and their attachments/images. So far it is only tested on one Mattermost installation, where around 23,000 messages is extracted in 61 seconds and produce 295M with approximately 600 attachments and around 675,000 lines of XML in arkivstruktur.xml. You pass it the URL of the service, a username and password, a directory path where to store the collection and an optional channel name substring to limit the collection to only a subset of the messages available. The mattermost-noark5extract-browser viewer can load this collection and visualize it similarly to Mattermost's web interface, with the list of channels and direct messages dialogues on the left, messages chronologically in the centre and a selected thread displayed on the right. I know Mattermost provide several login options. I've only had the one used on my test server implemented so far, and know the extract tool will have to be extended a bit for it to handle servers using one of these options. If you would like to examine the new toolkit, mattermost-noark5extract is available from gitlab. I wanted to put it on codeberg, but as the recent rule change forbid code mostly written by a bullshit generator there, it was not really an option. Note that some years ago I wrote a similar tool to extract material from the request tracker system. The source for request-tracker-noark5extract is also available from codeberg. I would love to hear from you if you test the tools. As usual, if you use Bitcoin and wish to support my activities, please send donations to 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Louis-Philippe V ronneau: Fake Cash: The World Trade Game

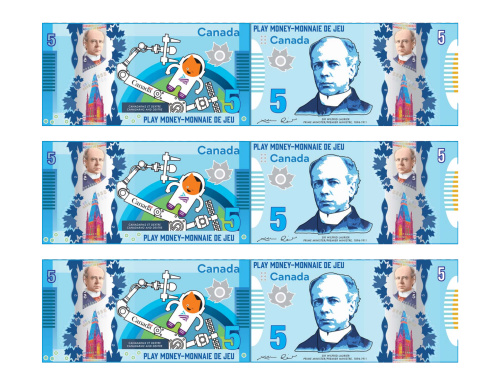
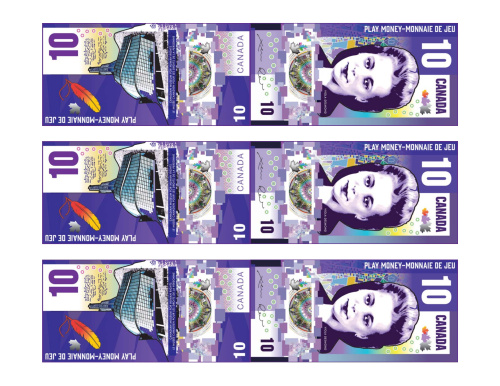
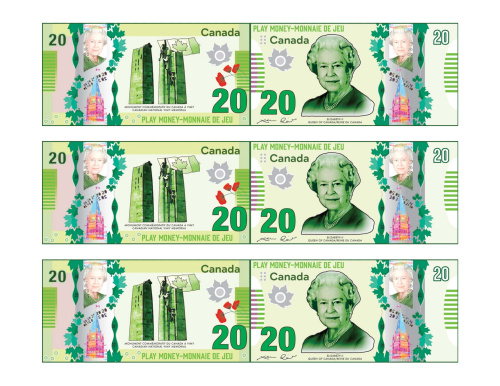
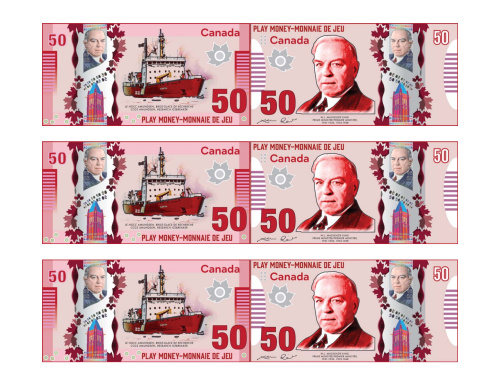
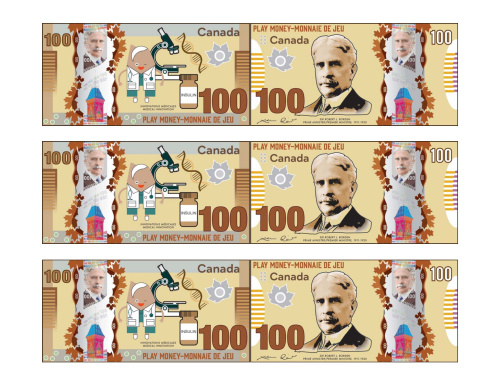
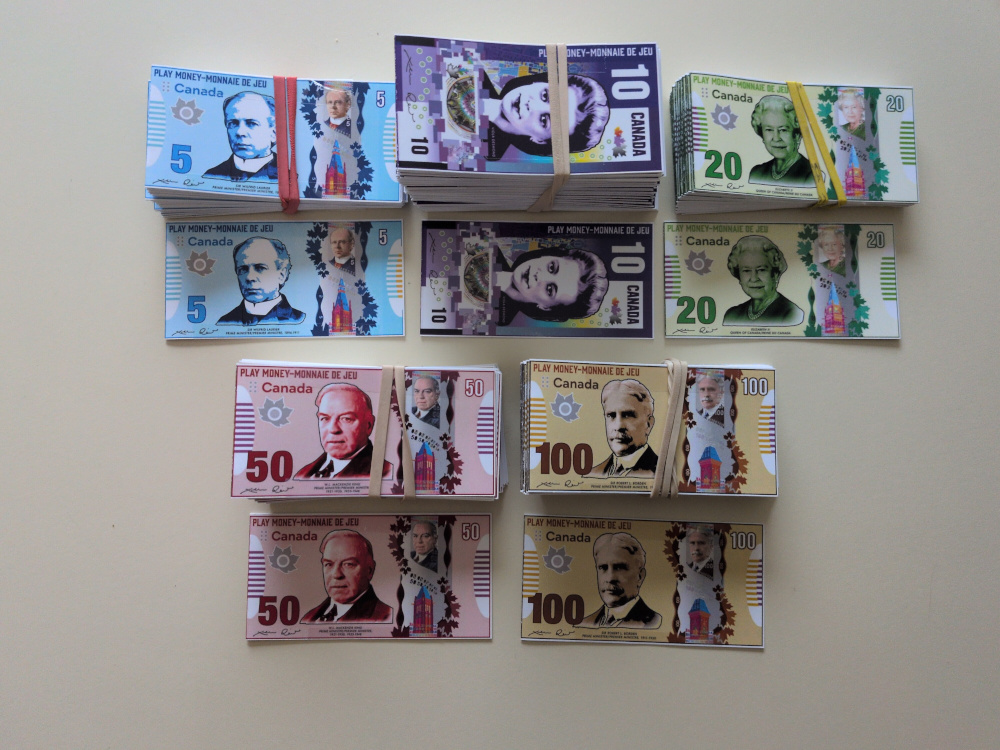
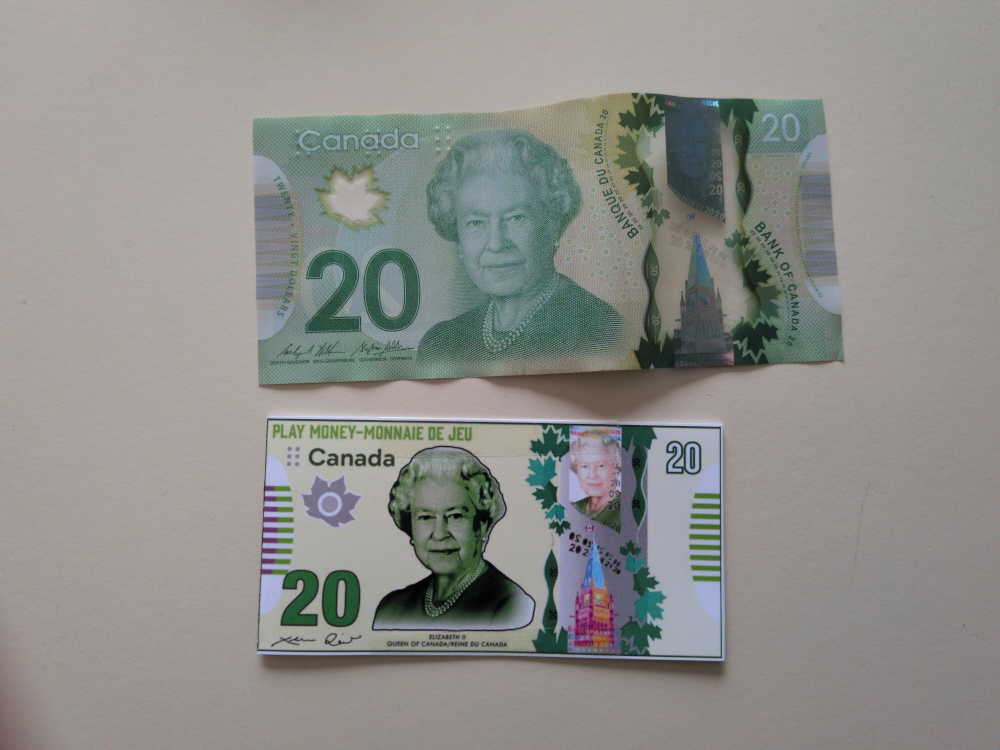
This is a new series1 I'm starting on the tools I have been crafting and buying to play pedagogical games in my Economics classes. These games, aside from being just plain fun for the students, often aim to teach them a lesson via interactive play. Unsurprisingly, it is much easier for them to grok a particular concept this way. Moreover, many students told me these activities were the best part of the classes I teach. The World Trade Game I found out about The World Trade Game in The Handbook of Pluralist Economics Education2, which also contains many other fun pedagogical games. It was first developed by Action Aid, but has since been refined by John Sloman and then by Irene van Staveren, who wrote about her use of the game in the aforementioned book. The goal of this blog entry is not to describe the game and teach you how to play it. If that interests you, either buy the book I mentioned or read about Sloman's version here. No, our focus point here is the tools to play this game: fake cash! Fake cash can be used in many economics pedagogical games and in my opinion, is a worthwhile "investment" of your time and energy. You could indeed play with regular printed sheets of paper listing a value (I sure did!), but using Play Money (a more appropriate term, since we're not trying to defraud anyone) will up your game and create a more immersive atmosphere in your classes. At first, I tried to buy play money. Surely, some commercial offering aiming to create realistic props for movies and TV productions existed? At least in Canada, it turns out the answer was no. The only thing I could find were shady websites and weird expensive listings on AliExpress. Not being tenured yet, I did not try to convince my employer to take a 50-50 chance on supporting criminal endeavours. As such, the next best thing I found was printable play money designed by the Bank of Canada Museum. Their designs were quite nice and met my needs, but their PDF layout made it overly complicated to print large quantities of bills. As such, I played around with GIMP a little and came out with these files. A commercial printer shouldn't have issues printing them on glossy cardstock paper and cutting them up for you: Once printed and cut, you'll unfortunately have to fold each bill by hand. To secure both halves, I ended up using a strip of transparent tape on each long edge. Here is the result, with a real Canadian 20$ bill as a comparison: Stacks of play money bills, with examples of the 5$, 10$, 20$, 50$ and 100$ bills A real Canadian 20$ bill, side-to-side with the play money version

  1. Don't hold your breath though, as I do not currently have a release schedule.
  2. Reardon, J. (2009). The Handbook of Pluralist Economic Education. New York : Routledge.

15 September 2026

Paul Tagliamonte: DESFire EV3

I ve long been interested in hardware key material storage devices. I ve been a fan of yubikeys (I still remember when my fancy new NEO-N showed up), PIV (and its associated smattering of additional fields), SaaS HSMs, the kernel keyring, some tooling I ve fairly satisfied with the design of at prior companies, and of course, our dear friend, the TPM. All that is not even to mention the scores of exotic hardware security modules one generally comes across from time to time when you re keeping a sharp eye out that you wind up playing with. The concept of storing private key material on a disk, or even having it in RAM has always skeeved me out, so I have a natural inclination to hardware modules, and how shifting keying material around can change your risks and threat model(s) in interesting ways. I don t remember when I first came across the MIFARE DESFire EV3, but a few weeks ago I did a deep-dive into the state of the art of authentication schemes using ID cards. My complete overview of what tradeoffs exist is pretty extensive (and likely not interesting to the vast majority of the world), but the tl;dr wound up being one of use PIV or use MIFARE DESFire EV3 . I wound up picking DESFire for a recent project, and figured it s worth talking a bit about what I learned, share some thoughts, and some code. That code is published on crates.io/desox, and docs, as is our custom, may be found at docs.rs/desox DESFire supports DES (I m sure most readers saw that one coming), 3DES (I didn t bother playing with 3DES at all) or AES-128 (AFAICT always use this?) keying material. It s worth noting that the DESFire only supports symmetric keys and is not designed for public key cryptography, and operates exclusively using shared symmetric key material. The DESFire EV series use those keys and related authentication schemes to interact with files stored on the on-chip EEPROM (2k, 4k, 8k, and 16k versions exist), or applications (groups of files and authentication keys).

Talking to a DESFire EV3 Interactions with the card are done over NFC (ISO/IEC 14443 Type A), and commands to/from the card may be in the usual ISO/IEC 7816-4 APDU format, or unencapsulated bytes sent to/from the card are sent using a fixed instruction set and return code structure saving a few bytes per message. I ve opted to use their undocumented and proprietary format I found it easier to work with and with a maximum message of 60 bytes, the savings matter a lot. While powered via NFC, the card maintains a small amount of state about the connection between the reader and the card in its RAM, including if the session is authenticated or unauthenticated. I ll dig into how authentication happens later, but it s worth knowing that sessions can become authenticated using one of the symmetric keys shared by the card and the reader. The vast majority of the DESFire commands I know about tend to work while either authenticated or unauthenticated, with a few exceptions (GetUid, ChangeKey, and ChangeKeySettings for example). In general, I found working with this card particularly pleasant. There is a fair amount of backwards-compatible behavior and multiple methods of communication that confuse things a bit, but overall, it was better than average to integrate with. Kudos to the NXP team. If the docs on this chip were public, things would be orders of magnitude easier it s not entirely clear to my why they re keeping so much of the interface documentation under NDA, but it s the largest knock against the chip, by far.

Authentication I found a lot of really great resources outlining how the handshake and protocol works for a DESFire EV3, especially from Ridrix, some public datasheets ThrRealRevK and posts from AndroidCrypto. The gist here is that, because the DESFire only does symmetric key operations, the key exchange (a type of SKA Symmetric Key Agreement) uses symmetric keys to establish a unique session key which is used to sign or encrypt data exchanged between the reader and the card. I m not going to get too in-depth here, since there s a ton of other resources out there to dig into but I will do a quick high-level description to keep this post mostly self-contained. The authentication protocol serves two main functions to verify that both parties know the same shared secret, as well as to act as a SKA to construct a new session shared secret key. Here s a quick overview of how a shared session key is derived between the reader and the card using our symmetric keys (AES-128 in the case below).
  1. the reader requests to start authentication with the card (something like AA 00 to start an AES Authentication handshake with keyslot 0x00).
  2. The card will then reply with AF (a status code that indicates more data is to follow), followed by 16 bytes (in the case of AES-128) of encrypted (using CBC) data.
  3. The hosts then decrypts this block with the symmetric key from keyslot 0, returning the card s session nonce.
  4. The host generates 16 bytes (usually random) for its session nonce.
  5. The host sends an instruction of AF (indicating a continuation of the previous command), followed by 32 bytes of encrypted data. When decrypted, the first 16 bytes are our nonce generated in step #4, followed by the 16 bytes provided by the card, decrypted in step #3, except where every byte is shifted to the left by one place (the 0th byte is copied to the end).
  6. The card will reply with 00 indicating a successful operation, followed by 16 bytes, which when decrypted, is our session nonce from step #4, shifted to the left by one byte in the same way that we did in step #5 with the card s nonce.
  7. At this point, both the reader and card have confirmed the other party has the same symmetric secret key. The session is now authenticated and a session key is derived using the two nonce blocks. Two hashing keys (K1 and K2) are derived from this key, which is used to maintain an ongoing CMAC hash of the messages coming and going to/from the card.
From here on out, the session is authenticated , and responses from the card which were previously plain will now contain a 8-byte CMAC signature, which can be used to ensure that the replies in question come from the active session. In my implementation of the handshake I opted to encode the handshake state into rust types, just so I wouldn t make any mistakes. The Handshake type contains the session internals (session nonce values, keying state, to include IV, etc). This means the authentication flow (from within my code) uses the Handshake struct to generate the commands to send to the card in order:
/// Create a new  Handshake , and return the
/// start auth command (something like  AA 00 )
fn Handshake::<Initial>::begin(
 output: &mut [u8],
 key: [u8; 16],
 key_id: u8,
) -> (Self, &[u8]);
After we get a reply back from the card (the encrypted version of the card s session nonce, sometimes called Rnd_B in code I ve seen), we transition states from Initial into HalfOpen.
/// Given the card's encrypted response, generate
/// our session nonce and generate a reply
/// (something that starts with  AF  followed by
/// 32 bytes of encrypted data).
fn Handshake::<Initial>::rnd_b(
 self,
 output: &mut [u8],
 input: &[u8]
) -> (Handshake::<HalfOpen>, &[u8]);
Now that we re HalfOpen , we re waiting to hear back from the card to ensure that it, too, can byte-shift our provided nonce. Once we have the card s reply, we can check it using our complete helper, transitioning from HalfOpen to Successful.
/// Check to ensure that the card replied with
/// our nonce byte-shifted by one place, indicating
/// that they know the symmetric secret in
/// this key slot.
fn Handshake::<HalfOpen>::complete(
 self,
 input: &[u8]
) -> Handshake::<Successful>;
Once the Handshake is successful, the only thing left to do is consume the Handshake struct and turn it into the shared session key by running it through the key derivation function.
/// Consume the  Handshake  struct and return the
/// new shared session secret key.
fn Handshake::<Successful>::into_key(self) -> [u8; 16];
From here on out we can use this session key for the remainder of our interactions with the card signing messages from (and sometimes to!) the card, or encrypted messages to and from the card. This key is used in CBC block mode, where the session IV is updated with the last block of the encrypted data.

Unit Testing A nice proprietary of the SKA scheme we re using as part of DESFire is that the derived session key is actually deterministic if you control your nonce RNG (ok, actually, pretty true for most key agreements, but anyway), which means it is possible to capture traffic over the NFC interface, and replay the NFC I/O with cooked RNGs and ensure byte-identical messages and keys are generated. Within desox-rs this is called replay (I m creative), and I ve got a few replay sessions checked into VCS, which exercise a signficant amount fo the API surface. All were derived from an actual session with a real DESFire card, and can be updated with a live card and a --cfg flag. Each replay file is a set of lines (request-response transactions), each containing two space-delimited hex encoded NFC messages. For instance, here s an authentication handshake in replay format:
1a00 afc7bbd82ff8fefae8
afc6dab54df2278d2952d560821be7e4c3 007d9abe94a9b14748
The code that generated that exchange came from the test stored adjacent to that file a handshake with the default DES key (all zeros), and an RndA value hardcoded to 32c28fdafd3960de.
let mut card = card
 .authenticate_with_rnd_a(
 0x00,
 Key::Des([0; 8]),
 Key::Des(hex_literal::hex!("32 c2 8f da fd 39 60 de")),
 )
 .await
 .unwrap();
Since the card s RndB is similarly unchanging (I m replaying this file every time), this will always derive the same session key, which means messages (including encrypted ones or CMAC signed responses) will be identical, as well. If you re playing with the DESFire yourself, feel free to grab my replay files if you need a known good baseline. By default this will run using the MockBackend, replaying each file expecting a byte-identical request, and responding with the harcoded customary reply. If the code (or test!) needs to change, updating the tests is done by swapping the MockBackend out for a real one. Since I had to do this a bunch during development, running cargo test with RUSTFLAGS="--cfg desox_replay_rw" will, on run, overwrite the replay file(s) for the executed test(s), ensuring all line-protocol changes are explicitly caught and reviewed.

Observations Most commands, even ones which require authentication, are transmitted without CMAC signature(s) or encryption. CMAC signatures from the reader to the card are not really used (except for writes to a file which specifies communication must be CMAC signed), ditto for encryption (although that one is used for key change operations, in addition to file writes on files that specify encrypted communication must be used). The vast majority of commands take a plain request from the reader, and return a CMAC signed response. By my eye, this means that a malicious reader, or something otherwise capable of holding the card online after communication with an authentic reader is complete are able to execute privilaged commands (since one can simply ignore the CMAC signatures on responses), so long as the command doesn t require the reader to provide CMAC signatures (or encryption), or allow the card to power down.

Fun with DESFire I ve played around a bit with ways to use the DESFire cards in interesting configurations, given what they re capable of. Here s some half-baked thoughts I had while mucking around with the cards these are all poorly thought out sketches of some things we can do given the specific tradeoffs I see with the DESFire card. It s also worth noting that I don t have any of the actual documentation, and am not a cryptographic grown-up, so take these sketches with a massive grain of salt. The first thing that came to mind when implementing this is how the authentication scheme can shift the boundary of what is and is not trusted (assuming good secure keying, and provided the key slots and card/application permissions are configured correctly). Rather than push the key material out to the machine connected to the NFC reader ( reader machine ), I instead tried turning the NFC reader and computer into something psuedo-untrusted by merely having it pass messages from the card to a trusted remote system ( remote machine ). This means that the reader machine is exchanging NFC data with the card, but that data is being decrypted, encrypted and processed by the trusted remote machine the reader is unable to derive the session key. For each of these, I wind up needing to authenticate so there s still a few latent risks, but these can mostly be mitigated by asking for a readbacks of any changed file(s), setting key permissions carefully, and requesting the card s UID via the encrypted channel all of which would require the symmetric secrets (which undermine the whole security model if comprimised). This general construction is also subject to a hostile takeover of the untrusted reader machine , since most commands (including destructive ones!) are sent in PLAIN mode the reader machine can wait until authentication is complete and then inject commands into the card and simply ignore the CMAC signatures on responses, severing ties with the remote machine. As such, we also need to take steps to ensure that the key being used is not one that allows any access beyond what is allowed. Here were some ideas I sketched out off the back of this theory.

The second-factor Given some established (and authenticated) connection, part of the initial authentication flow may use the DESFire card to prove physical control over it as part of a handshake. This can serve as a second factor during some authentication flow, requiring physical card presence at a reader to fully initialize a connection. This does have one glaring downside, however it s phishable. To use this for real , we d need to take some steps to prevent obvious MITM flows (XOR the NFC messages with the URI as seen by the client?), but maybe there s something interesting there. This also has a second interesting attribute when used as part of a physical system authentication flow, this becomes a logical place to inject access control, being able to determine if some person is permitted to operate some device at that particular time (Is Joe current on his Laser Cutter certifications?) I think of the ideas I landed on, while conceptually interesting (using an employee id card as a 2FA token, it s very fast), this one is the least likely to turn into something real.

The takeover This time, let s say the computer attached to the NFC reader ( reader machine ) is semi-trusted. For this scheme, our trusted remote machine and the reader machine pass messages over the network to handle authentication to the card (as above), where the handshake data is being decrypted, encrypted and processed by the trusted remote machine as usual. However, once the authentication handshake is complete and a session key has been derived, the remote system return the session key to the reader machine , giving it a one-time-use key and authenticated session to the card. We need to be careful about global/application permissions and key access control to files but in this construction, we can allow the reader machine to take over privileged actions using a scope-limited DESFire key without handing over the card s true keying material (preventing cloning of the card). This can be helpful to ensure messages to/from the card are truely from the card (verifying CMAC signatures), enables the reader machine to directly read/write to/from encrypted file(s), but allows the symmetric key material to remain in as few places as possible which is critical given compromising that secret will undermine the security of the entire system.

Reproducible Builds: Supporter spotlight: Jochen Sprickerhof on ... Reproducible Builds!

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the ninth installment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. We started this series by featuring the Civil Infrastructure Platform project, and followed this up with a post about the Ford Foundation as well as recent ones about ARDC, the Google Open Source Security Team (GOSST), Bootstrappable Builds, the F-Droid project, David A. Wheeler, Simon Butler and Kees Cook. Today, however, we will be talking with Jochen Sprickerhof, one of the newer members of the Reproducible Builds project core team.

Vagrant Cascadian: Could you tell me a bit about yourself? What sort of things do you work on? Jochen Sprickerhof: I am a freelance programmer working on Open Source. Mainly doing Debian, F-Droid and some smaller software projects. In general I made it a habit to look into every software I use and try to fix bugs or add features I need. In Debian, I maintain about 180 packages with topics covering home banking, build systems and robotics. Most of my time, I currently work on reproduce.debian.net, where we try to bit-for-bit reproduce the packages distributed by Debian.
Vagrant: Could you describe the path that lead you to working on reproducible builds? Jochen: I started my Debian journey as a teenager, converting my school to Debian and serving as its system administrator for 13 years. After studying Applied System Science, I joined the university s robotics labs, where I worked on the Robot Operating System (ROS) and the Point Cloud Library (PCL). In the end, I enjoyed programming more than writing papers, so I eventually left academia for a robotics startup. Some years ago, I realized that the open source work I was doing in my spare time was actually the work I cared most about. Nowadays I am really grateful that I can spend my days working on things I find important and have lots of fun with.
Vagrant: What projects did you recently make big progress on? Jochen: A recent example is metasnap.debian.net. It is a meta archive of snapshot.debian.org which is itself archive of all packages in Debian. But let me explain it the other way round: with reproduce.debian.net, we try to reproduce the packages as they are distributed by the Debian archive. For that, we need the same build environment (compilers, libraries, build tools, etc) that was used by Debian back when the original package was compiled. Luckily, snapshot.debian.org has all those packages, but they are not easily accessible via apt, Debian s package manager. So, metasnap provides a mapping from a package name and version pair to the APT repo on snapshot.debian.org needed to download it from. It was created by josch some time ago, and it s awesome work. But when we tried to reproduce more and more packages on reproduce.debian.net, we found that some were missing packages from the build environment even though they where visible on snapshot.debian.org. We found that metasnap excluded some archive areas because they where not expected to be needed. Reimporting all the data took more than two months and surfaced a couple more flaws. With this fixed, we were able to build more packages, only to find out that metasnap also needs better support for version numbers. Luckily we were able to rewrite the data in a day instead of starting the import again.
Vagrant: You have been working on infrastructure to support reproducible builds for a while. Has recent adoption of reproduce.debian.net into the Debian release tooling changed the focus of your work? Jochen: Quite a bit. When we started reproduce.debian.net in 2024, only around 33% of the packages could be reproduced successfully. Today we are above 98%. Most were not bugs in the packages themselves but in the infrastructure. Similar to the metasnap issue I reference above, packages just needed a rebuild because something else, like the toolchain, was fixed in the meantime. In May, people from the Debian release team and the Reproducible Builds project sat together and decided that the overall state is good enough, and now packages that regress on reproducibility are blocked from entering the next Debian release. But that does not mean all the work is on the shoulders of Debian package maintainers. Since then I have been constantly looking at the migration tooling to spot regressions and provide fixes. Furthermore, a couple of maintainers reached out to us for help and I hope more will do so in future.
Vagrant: What is one small thing you (or others) have not yet gotten to that you would really like to see? Jochen: The central tool to reproduce Debian packages is debrebuild, also written by josch. Currently it has two ways to retrieve the build dependencies of a package. Either it uses metasnap.debian.net (as explained above), or it can access the Debian unstable APT repository directly. This allows to test packages locally before everything is indexed on metasnap by compiling against Debian unstable. But actually there are many other APT repositories to query, like Debian stable or even derivatives. Adding support for an optional list of APT repositories in debrebuild would be great. That would also be a big step to support reproducing other Debian based distributions.
Vagrant: and one big thing? Jochen: It would be great to integrate metasnap.debian.net into snapshot.debian.org. There is some discussion on it already in Debian bug #650783.
Vagrant: What are the tools you use the most? Jochen: According to my fish shell history:
$ history   cut -d' ' -f1   sort   uniq -c   sort -nr   head -10
  36199 git
  20941 vi
  12271 rm
   8599 cd
   7917 ls
   6407 apt
   5631 grep
   4249 mv
   3655 dpkg
   2873 cp

Vagrant: So, is the fish shell reproducible? I remember it did not used to be Jochen: You can check for yourself it was last time I checked. But looking through the other commands, neovim sadly is not. I hope we can fix that in future.
Vagrant: Oh, that s a nice URL to check for reproducible package you can just pass the source package name to check the current results? Jochen: Yes. Another one is udd.debian.org/reproducibility/, where you can list all packages of a Debian maintainer. It also lists source reproducibility and has nice filters as well.
Vagrant: What tools do you use specifically working on reproducible builds? Jochen: I don t have statistics for that, but I would say sbuild to build the package, debrebuild to reproduce it, and diffoscope to analyze the differences. Obviously I also need run apt source <package> or use git-buildpackage to get the sources and all the tools I mentioned above.
Vagrant: So how many packages are left to build reproducibly, and once those are finished, what is next? Jochen: Right now, reproduce.debian.net shows over 98% reproducibility, though there are still over 650 package left and some will probably need a lot of work. But actually I think making packages reproducible is just the first step. For me, this is a project to build confidence in the system. To reproduce a package we have two parts: the source of the package and the build environment. Fixing the packages means gaining confidence in the first part but we still rely on the individual build environments for each package as we need to use the same compiler that was used when the package was build initially. Because of this, we have to keep around every historical version of all toolchain packages. I really would like to remove this extra archive, which means we would have to rebuild all of Debian around release time. I am dreaming of a Debian release where you could bit-for-bit reproduce every package just from the released versions. Due to how Debian works, however, this is not a trivial rebuild and it would need some work on the infrastructure. By the way, initially there was a third component to pay attention to: any connection to the outside world during the build. Luckily we fixed the Debian build daemons to not allow network connections during the build some time ago.
Vagrant: Thanks for all that work, and taking the time to tell us a bit about yourself! Jochen: Thanks a lot for the interview!


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

Freexian Collaborators: Debian Contributions: Security-tracker git performance, OpenSSH GSS-API split, Incus replacing lxc in Debian CI and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-08 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Replacing lxc with Incus for Debian CI, by Antonio Terceiro At the beginning of this month, the default backend for tests was changed to incus-lxc, leaving only a few dozen packages explicitly configured to run as lxc. Those packages got bug reports filed and once those bugs are fixed they will be migrated over to incus-lxc. This marks an important milestone for Debian CI, as the low level of isolation between the worker host OS and the OS under test when using lxc was a significant source of instability in our platform. Common causes for test failures when comparing runs under plain lxc with runs with incus-lxc are documented in the wiki page linked from the bug reports.

security-tracker git performance, by Helmut Grohne Developers working with Debian s security-tracker have reported degrading performance for a while. The options for solving this are few with repository sizes now reaching 30GB for a repository whose working tree is a mere 60MB. While there have been a number of proposals for changing the storage layout, Helmut evaluated options not requiring such changes. Much of the problem hinges on the 50MB data/CVE/list file that is updated in most commits. Efficiency hinges on representing its content in git packs. Practically, git frequently fails to represent its content as a delta and stores a full copy that is typically compressed to 12MB. Add a few thousand 12MB full blobs and you quickly have a large repository. In particular, the copy at salsa.debian.org stores many such full blobs, so pulling from it consumes significant bandwidth. One might think that running git gc helps, but its utility is limited here. When git stores objects in packs, it stores the history in reverse. It starts with the current version and represents older objects as differences (deltas) to more recent objects. A delta effectively is a sequence of copying ranges from a base object and insertion of new content. Given that humans tend to add content over time, those additions are often represented as deletions. The crux here is finding that base object. Given that the data/CVE/list file is large, finding it involves comparing quite a few versions of it with each other. This requires both a significant amount of RAM and CPU time. How many objects git considers for this comparison is controlled with the --window option. It is beneficial if the base object does not come from a direct child commit but skips over commits. In doing so, long chains of deltas are avoided. The --depth option controls the maximum chain length. In this search, git combines all objects into a single window to facilitate file renames. As such, it tends to compare data/CVE/list with data/DSA/list, data/DLA/list and others. This is less than helpful and tends to evict all data/CVE/list versions from the comparison window such that a new full blob of it becomes required. Since the security-tracker repository rarely renames files, we can ask git to instead consider one window per filename via --path-walk. Once doing so, it becomes quite a bit better at finding suitable deltas. The technique is less applicable to older history (2025 and earlier), but given a lot of RAM and a bit of partitioning, git gc can shrink that as well. Combining these techniques, we can shrink the repository into 700MB and keep new growth somewhat under control. Temporarily, Helmut is providing a proof-of-concept mirror at git://git.subdivi.de/~helmut/security-tracker.git using these techniques. Avoid pulling from it directly as it does not provide a secure transport. While it does reduce the amount of data being downloaded, it does not resolve a number of related problems. After downloading, a git client will still expend considerable amounts of CPU on verifying received deltas and attempting to git blame data/CVE/list is not improved in any way. Still, there is work on integrating some of the improvements back into salsa.

OpenSSH GSS-API split, by Colin Watson In an option review Colin did in 2024, shortly after the xz-utils backdoor, he explained that having GSS-API authentication and key exchange support in the main OpenSSH packages is problematic. The key exchange patch is large and intrusive. Even linking to the necessary libraries isn t without risk: as the Ebury malware attack demonstrated way back in 2009, each extra library linked into security-critical daemons such as sshd (or nowadays into its privilege-separated helper programs) can modify the behaviour of the daemon even if you aren t doing anything that would involve calling into that library. Of course some of that risk remains, but as Damien Miller wrote, minimizing the number of libraries that end up in the address space of sshd and friends is still valuable. This split is now complete in testing. As of openssh 1:10.4p1-5, the OpenSSH client and server are built without GSS-API authentication and key exchange support. If you need those features, install openssh-client-gssapi or openssh-server-gssapi instead, as appropriate. Debian 13 (trixie) already has packages with those names that just depend on the regular openssh-client and openssh-server so that you can pre-emptively install them, as documented in the release notes. The new openssh-*-gssapi packages have relatively tight dependencies on openssh-common, in order for the testing migration system to ensure that we can t forget to keep them up to date. This will mean a bit more ongoing work on each new upstream version, but it should be manageable.

Catching up on DebConf video publication, by Stefano Rivera DebConf 25 videos suffered terribly from a bug in voctomix that stopped us from being able to publish the videos immediately after the conference. Ivo De Decker did some work on the videos earlier this year, fixing enough of the audio problems to make the videos at least intelligible. While at MiniDebConf Winterthur Stefano published all the videos from 2025 and 2026 to PeerTube and YouTube. DebConf 25 and DebConf 26 videos as well as all the videos from miniconfs that had got caught up in the backlog were published.

Miscellaneous contributions
  • Carles used po-debconf-manager to review and submit Catalan translations for six packages.
  • Carles prepared a prototype of building webwml and running tidy (linter) in Salsa.
  • Carles created different webwml merge requests with different fixes: invalid links to different architectures, 404s to external sites, fixed templates with invalid URL to favicon.ico, making USE_SAMPLE_FILES=1 to avoid fetching external files, typos in English, etc.
  • Carles updated the LibreOffice Wiki page.
  • Emilio managed several transitions, such as glibc 2.43, perl 5.42, kdepim, nginx, gnome-desktop 51, python3.14-only, and many others.
  • Emilio updated libxfont to 2.0.9, xorg-server to 21.1.24, xwayland to 24.1.13, and fixed a FTBFS bug in terminator.
  • Antonio deployed the website for MiniDebConf Beijing 2026, and archived the Hamburg 2026 and Kanpur 2026 MiniDebConf websites.
  • Antonio released auto-apt-proxy 18, adding new features and fixing bugs; that needed a followup 18.1 release to fix an issue identified in the testing migration tests.
  • Antonio did several Salsa maintenance tasks, including his first platform security update and investigating an issue that was causing the background tasks to be severely delayed, imparting the site usability.
  • Thorsten tried to fix some bugs in hplip and cups. Unfortunately this did not result in an upload this month, but stay tuned!
  • Helmut continued to report undeclared file conflicts and correspond about them.
  • Helmut reviewed and merged Johannes Schauer Marin Rodrigues work on adding hurd support to debvm.
  • Helmut fixed a pile of minor issues in the support libraries underpinning unschroot.
  • Helmut adapted rebootstrap to archive regressions and improved its handling of non-default gcc versions.
  • Helmut fixed the rendering of decompressed logs at crossqa.debian.net.
  • Helmut sent patches for two cross build failures.
  • Colin deployed the fix for Invalid link rel= canonical on bugs.debian.org. In the process he found a few bugs in recent undeployed code and fixed them.
  • Santiago continued helping Aryan Karamtoth with the GSoC project on introducing livepatching support for linux. Several challenges have been identified in the recent couple of months, and Santiago is trying to guide Aryan to address them and design the solution. The mentoring is done in collaboration with Emmanuel Arias.
  • Lucas onboarded a co-maintainer for Valkey.
  • Lucas has started to work on a draft for the Debian Outreach project for onboarding newcomers interested in Debian packaging via a video course.
  • Stefano worked on the after-math of DebConf 26, handling the bursary expense reimbursement process and winding down the conference finances.
  • Stefano uploaded Python 3.15 RC 1 to Debian unstable.
  • Stefano did some budgeting and travel planning for the DebConf 27 site-visit in Asahikawa, Japan. The DebConf committee sends a couple of members to meet with the local team and view the venue together, in advance of the next DebConf.

11 September 2026

Reproducible Builds: Reproducible Builds in August 2026

Welcome to the August 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. In this month s report, we cover:

  1. New updated SBOM specification from CISA.gov
  2. LWN on Bootstrappable builds at FOSSY 2026
  3. What s missing to have reproducible builds on PyPI?
  4. Distribution work
  5. Unreproducible builds under EROFS filesystem fixed
  6. Tool and documentation development
  7. Six new scholarly papers
  8. Patches

New updated SBOM specification from CISA.gov CISA, the Cybersecurity and Infrastructure Security Agency of the U.S. government published some the joint guidance entitled Minimum Elements for a Software Bill of Materials (SBOM), which updates and supersedes the baseline 2021 version covered in previous editions of these reports. Whilst the PDF is worth skimming, the interesting changes include that the specification now mandates standard cryptographic hashes: unlike earlier standards that allowed hash omission or manifest-only parsing, hashes must be computed from the output. This is is important for reproducible builds, as it ensures the recording of the metadata required to demonstrate the shipped software matches the build output precisely where applicable. In addition, where the top-level only dependency limitation that was present in the 2021 version has been removed in favour of complete coverage with no minimum depth. That is, SBOMs are expected to reflect all linked libraries, vendored dependencies and other build-time inclusions.

LWN on Bootstrappable builds at FOSSY 2026 In the Toolchains and Other Development Tools track at Software Freedom Conservancy s FOSSY 2026 in British Columbia, Canada, Timothy Sample gave a presentation on bootstrappable builds. This presentation was then covered in a Linux Weekly News article by Jake Edge entitled Bootstrappable builds: how and why, which serves as an excellent introduction to the concept:
The basic idea behind bootstrappable builds is to create a system that can be built without relying on pre-built artifacts. Can we go from zero to the modern day without having to just assume the existence of these already-built-for-us artifacts? The classic recipe for yogurt requires some yogurt to start the process, which is like how we normally build a C compiler today we start with an existing C compiler binary. You might think about making sourdough bread with your grandmother s starter brought over from the old country; we re basically making C compilers with Dennis Ritchie s starter carried over from Bell Labs .
The article, which goes on to cover GNU Mes and other projects that overlap with Reproducible Builds, also has a number of thought-provoking comments.

What s missing to have reproducible builds on PyPI? Core Python developer, Brett Cannon wrote an interesting blog post this month addressing What s missing to have reproducible builds on PyPI, the official public repository for third-party Python software packages:
The reason I like the idea of making reproducible builds work is that I think it can be done in such a way as to not require any work on the part of the producer of a distribution (which is a technical term for sdists or wheels, i.e., the people who upload stuff to PyPI), and thus make reproducible builds very low-friction for people to opt into supporting. [ ]
Brett goes on to outline What s missing from the specs and how reproducibility might be visible on PyPI to consumers:
Assuming all of this comes to pass and we record the where the source code is that went into a distribution and the software used to make the distribution, how do we make it useful to people? Does every person who cares about having a secure supply chain have to rebuild everything they use themselves? Is there some way for even people who don t care about this stuff to benefit? [ ]

Distribution work In Debian this month, 23 reviews of Debian packages were added, 28 were updated and 27 were removed this month adding to our knowledge about identified issues. A number of issue types have been updated as well, such as the addition of a new toolchain issue related to python-traitlets [ ], and the note for an existing issue related to texi2html was updated as well [ ]. Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.

Unreproducible builds under EROFS filesystem fixed Martin Pitt reported on Fosstodon that they had identified an issue where the mkfs ( make filesystem ) command for the EROFS (Enhanced Read-Only File System) subsystem of the Linux kernel did not have sorted extended file attributes, leading to reproducible builds. Thankfully, Martin also reported that they had fixed this in a commit to the kernel which order[s] each inode s xattrs by name so that images stay reproducible . [ ]

Tool and documentation development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 327, 328 and 329 to Debian. In particular, he ensured that diffoscope did not require python3-guestfs in the autopkgtests on 32-bit architectures in order to fix Debian bug (#1144372) [ ]. Colin Watson made an additional change, handling a potentially missing openssh-client package when running the autopkgtests [ ], and Jochen Sprickerhof made a similar change to cope with missing cpio and qemu-img functionality [ ] whilst also updating the XML comparator to be considered when comparing SVG images [ ].
Yet again, there were a number of improvements made to our website this month as well. For example:
  • Chris Lamb added draft for a Gothenburg summit-related news article. [ ][ ]
  • Holger Levsen then published the same article. [ ][ ]
  • Lastly, a large number of commits were pushed comprising an interview with Reproducible Builds developer Jochen Sprickerhof to be published within the next week. [ ][ ][ ][ ][ ][ ][ ]

Six new scholarly papers Jens Dietrich, Spencer Sun, Tim W. White and Behnaz Hassanshahi (the result of a collaboration between Victoria University of Wellington and Oracle Australia published a paper this month entitled No Snake Oil: Verifying Python Package Builds. Drawing on the metaphor of snake oil , that is, a fake or ineffective medicine or solution sold with exaggerated claims of curing or fixing everything, the authors write that
Two tools that are designed to automate [PyPI] rebuilds and run them at scale are macaron and oss-rebuild. We study 12,180 popular releases from PyPI and find that the byte-for-byte equivalence rate is generally low. We analyse the reasons why they produce different wheels, and find that equivalence between the original and rebuilt wheels can often still be established, preserving most of the guarantees users expect from rebuildable releases. We present and evaluate daleq4py, a tool to establish the equivalence of Python wheels through the kernel of a normalisation function that is based on provenance-preserving datalog rules. Experimental results show that daleq4py substantially expands the set of rebuilds that can be accepted as equivalent.
The full PDF of their paper can be viewed online, and Jens Dietrich to our mailing list to announce the availability of both the paper and the daleq4py tool itself.
Dimitri Kokkonis, Micha l Marcozzi and Stefano Zacchiroli published an article this month titled Not In My Git Yard: Catching Backdoors at Commit and Release Time on the topic of code-level backdoors that is, stealthy code changes that grant hidden privileges via secret triggers . These issues:
pose a persistent threat to opensource software. Known attempts to inject such backdoors into widely used projects through malicious commits, tampered release packages, or compromised third-party dependencies, were stopped only by luck and manual review. Existing Continuous Integration (CI) pipelines cannot detect these attacks, and downstream binary analysis tools require substantial manual effort. In this work, we present Lily, an automated approach that strengthens open-source development and release processes against backdoor injection. Lily integrates a backdoor detection mechanism into (1) CI pipelines to block malicious commits, and (2) release vetting workflows to prevent tampered releases or compromised dependencies from entering large ecosystems, such as Linux distributions.
The full PDF can be read online.
Ranindya Paramitha and Laurie Williams of North Carolina State University along with Christian K stner of Carnegie Mellon University published a paper this month with the title of The Software Supply Chain as a Market for Lemons: A Multivocal Review of Trust Signal Collapse. (A lemon in American English, is a vehicle that turns out to have several manufacturing defects .) Their abstract is as follows:
Practitioners evaluating open-source dependencies rely on cheap trust signals, e.g., stars, download counts, and contributor activity, as substitutes for direct code inspection, assuming those signals reflect genuine trustworthiness. Prior work has documented individual signal gaming, but the landscape of collapses across all dependency-adoption signals, as well as the ecosystem s response, remains unexplored. The goal of this study is to aid software practitioners in understanding the reliability of dependency adoption trust signals, such as download counts and contributor activity, by conducting a multivocal review of 252 Google Search sources and 870 Reddit threads.
Worryingly, after their review, the authors conclude that cheap trust signals collapse under three simultaneous forces: adversarial manipulation, gaming techniques indistinguishable from legitimate behavior, and non-adversarial AI-driven inflation. The full PDF of the paper is available online.
Julien Malka, Aman Sharma, Martin Monperrus, Stefano Zacchiroli and Th o Zimmermann published a paper this month on Trusting-Trust Attack against an Entire Linux Distribution through Binary Manipulation:
Ken Thompson s trusting-trust attack, in which a compromised compiler backdoors the programs it builds and reproduces the backdoor in subsequent rebuilds of itself, is widely regarded as a threat specific to compilers. We show that it is not. We construct a complete trusting-trust attack around GNU strip, an ordinary build utility that neither inspects nor generates source code, using only manipulations of finished ELF files.
Scarily, in the authors example, a single tampered strip in the binary seed implants a payload that propagates from one generation of strip to the next and survives into the final standard environment after the seed leaves the dependency closure [ ] without failures and backdoors . A full PDF of the paper is available for download online.
Mehdi Keshanimm, Amirhossein Rahmati, Mohammad Hossein Aref and Abbas Heydarnoori published a paper that is currently under review at Emperical Software Engineering titled AROMA+: A Study of Factors Affecting Reproducible Builds in the Maven Ecosystem. (Maven is a/the build automation tool used for Java projects.) In their paper, the authors note that
[ ] reusing external software in a project presents a security risk when the source of the component is unknown or the consistency of a component cannot be verified. The SolarWinds attack serves as a popular example in which the injection of malicious code into a library affected thousands of customers and caused a loss of billions of dollars. [ ] Our research aims to support [reproducibility] efforts in the Maven ecosystem through automation. We investigate the feasibility of automatically finding the source code of a library from its Maven release and recovering information about the original release environment. Our tool, AROMA+, can obtain this critical information from the artifact and the source repository through several heuristics and we use the results for reproduction attempts of packages on Maven Central.
The full PDF of their article can be downloaded online.
Lastly, Oreofe Solarin, Kelechi Kalu, James C. Davis and Paschal Amusuo published a paper this month titled Reproducibility is Not Enough: Artifact Verifiability in Decentralized-Build Package Ecosystems:
[A]rtifact verification requires more than deterministic builds: a verifier must also recover the source state, build environment, dependencies, and build instructions that produced the artifact. Decentralized-build ecosystems make this difficult because artifacts are produced through heterogeneous tools, maintainer-controlled workflows, and fragmented metadata. As a result, it remains unclear how often artifacts in these ecosystems can be independently verified. This paper studies artifact verifiability across four popular decentralized-build package ecosystems. We define an independent verifier model that relies only on registry-derivable metadata and an artifact comparison model with tiered equivalence levels. We implement these models in an Artifact Verification Pipeline and use it to measure artifact verifiability across the target ecosystems.
The authors conclude that beyond build determinism, verifiability is limited by missing source and build metadata, implicit release transformations, and unconventional build practices . A PDF of their paper can be reviewed online.

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

If you are interested in contributing to the project, please visit our Contribute page on our website.

9 September 2026

Matthew Garrett: SystemIO conflicts are not firmware bugs

I m looking at something entirely unrelated, but tripped over some search results that made me realise that a lot of people still think getting errors like ACPI Warning: SystemIO range 0x0000000000001828-0x000000000000182F conflicts with OpRegion 0x0000000000001800-0x000000000000187F indicate a firmware bug. This is generally untrue. We need to dive a little into what ACPI is to clarify why. The Advanced Configuration and Power Interface1 specification defines a whole bunch of stuff, but what s interesting to us here is the hardware abstraction it performs. While PCs are nominally a well-defined platform that s really not true at the hardware level once you get beyond a certain level of complexity. When you suspend a system you want to power down the hardware in the correct order, for instance, and knowing what that order is requires you to know details about the specific motherboard design. The approach taken in the embedded world is to just bake that knowledge into the OS in some form, which is how we end up with Devicetree. ACPI takes an alternative approach - rather than provide that information as data that has to be consumed by OS drivers, it distributes it as code. The ACPI Source Language, or ASL, is a simple language that gets compiled into a bytecode that s then interpreted by the OS at runtime. One of the features of this language is the ability to define Operation Regions , effectively structure definitions that describe access to underlying hardware. Let s imagine a simple device with two exposed registers. The first is an index register - it describes which internal register we want to access. The second is a data register, where reading it gives us the value of the internal register whose address is currently in the index register, and writing to it modifies that register. An example operation region declaration would look something like
1
2
3
4
5
6
OperationRegion(OPR1, SystemIO, 0x400, 0x2)
Field(OPR1, ByteAcc, NoLock, Preserve)
 
  INDX, 8
  DATA, 8
 
This defines an operation region called OPR1 at IO port 0x400, 2 bytes long. Inside it are two 8-bit fields, INDX and DATA. These are to be accessed one at a time, do not need the ACPI interpreter to take a global lock when accessing them, and if a subset of the register is modified then the other values should be preserved (irrelevant in this case since the fields are only a byte wide). Now any references to INDX or DATA in this scope will trigger accesses to those registers. So, a method to read the value of register 0x03 would look something like:
1
2
3
4
Method (RD03)  
  INDX = 0x3
  Return (DATA)
 
ie, set INDX to 3, and then read the value of DATA and return it. But! What if another ACPI method is running at the same time? Let s say we have one that writes to register 0x05:
1
2
3
4
Method (WR05, 1)  
  INDX = 0x05
  DATA = Arg1
 
What happens if RD03 executes while we re part-way through WR05? INDX might get reset to 0x03, and now WR05 will modify register 0x03 instead of 0x05. Oh no! But we can avoid this - we declare a mutex (Mutex (MUTX, 0x00)), and update our methods to be something like:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
Method (RD03)  
  Acquire (MUTX, 0xFFFF)
  INDX = 0x3
  Local0 = DATA
  Release (MUTX)
  Return (Local0)
 

Method (WR05, 1)  
  Acquire (MUTX, 0xFFFF)
  INDX = 0x05
  DATA = Arg1
  Release (MUTX)
 
Each method takes a lock (waiting up to 0xffff milliseconds and then erroring out if it doesn t), and performs the access. There s now no chance of a race. Phew! Now suppose someone writes a Linux driver for this piece of hardware. It accesses the hardware directly, with no knowledge of ACPI. What stops the driver from racing against one of the ACPI access methods? Nothing at all. Oh no! Again! This isn t hypothetical, by the way - here s a relatively harmless example, but back in the day we did trip over cases where temperature monitoring chips would be accessed by the firmware and Linux simultaneously and as a result you might end up thinking you re reading a temperature when you re actually reading a status flag, resulting in an impossibly high temperature and an immediate thermal shutdown. In this case, the kernel saves you from this (potentially hardware damaging) outcome by printing a message like ACPI Warning: SystemIO range 0x0000000000000400-0x000000000000401 conflicts with OpRegion 0x0000000000000400-0x0000000000000401 (OPR1), telling you that the kernel has detected that a driver is attempting to allocate IO ports 0x400-0x401, but that there s an ACPI operation region called OPR1 that is claiming the same addresses. The kernel isn t in a position to know what type of access the firmware might perform in that region, so assumes that it might be dangerous and blocks the driver from loading. But all is not lost! The kernel also prints some helpful advice, ACPI: If an ACPI driver is available for this device, you should use it instead of the native driver. And ACPI tables will often actually have a definition that looks like this:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
Device (HDW1)
 
  Name (_HID, "VEND0001")
  OperationRegion(OPR1, SystemIO, 0x400, 0x2)
  Field(OPR1, ByteAcc, NoLock, Preserve)
   
    INDX, 8
    DATA, 8
   
  Mutex (MUTX, 0)
  Method (RD03)  
    Acquire (MUTX, 0xFFFF)
    INDX = 0x3
    Local0 = DATA
    Release (MUTX)
    Return (Local0)
   

  Method (WR05, 1)  
    Acquire (MUTX, 0xFFFF)
    INDX = 0x05
    DATA = Arg1
    Release (MUTX)
   
 
which defines an ACPI device and associated methods. The _HID field defines the device type, and a Linux driver can be written that will be automatically loaded if a device with type VEND0001 is seen. That driver can then call ACPI methods associated with the device and access the resources in a way that matches the firmware s expectations. (Interested in writing such a driver? I wrote a guide back in 2009) The firmware did absolutely nothing wrong here2, but trying to load the native driver will generate an error and the internet will tell you that PC firmware developers are incompetent3 and you should pass a kernel argument that overrides this behaviour and it never did them any harm, and it probably won t do you any harm either but it might and you might never know why your system occasionally wedges or catches fire.

  1. The ACPI spec used to live at acpi.info, but sadly that seems to have vanished some time after UEFI took over stewardship of the spec
  2. You might argue that the firmware should simply not do anything at runtime because it is not the firmware s job to do that, and I do understand that and you can certainly boot with acpi=off if you want to and no ACPI code will be executed at runtime. Let me know how that goes.
  3. I m not going to present an opinion on that here, merely say that this provides no supporting evidence for that assertion

8 September 2026

Paul Tagliamonte: IP over Avian Carriers (Part 12/12)

This post is part of a series called "Pigeon". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
The final step to all of this was to tie together all my PHY RF code, Link layer parsers, and my background with operating systems to make this all feel like a normal thing my computer should be doing. At the end of the day, I want my host system to know how to talk with a pigeon daemon, so I don t have to reimplement basically everything else. My ability to use normal tools like curl or ping6 is pretty important here, so I need to reach for my old friend, the TUN interface. The TAP/TUN interface allows the kernel to route ethernet frames (TAP) or ip packets (TUN) to a userspace program responsible for handling delivery and reception avoiding the need for a kernelspace driver for something that can be handled in userland.
wondering if doing this violates FCC Part 97 rules? I wrote up notes on my test setup for exactly this question, but the short answer is "no"!
I m no stranger to playing with TAP/TUN, so this was pretty easy to snap together although this time I avoided the whole ethernet proxying thing (to side-step lossy translations, maintaining two sets of mac address tables, and handle proxying NDP/ARP messages) it was kinda a bad idea last time so I just used TUN and straight IP for now. While implementing this, I decided I d make a key assertion about all pigeon networks namely, all pigeon IPv6 networks are a /64 in size, no more, no less. The reason why I m doing this here is that, since pigeond does still does need a MAC address for the pigeon layer 2 protocol, we can write our daemon to always use SLAAC to set the TUN IP address without any new information. Which leads us to a bit of an aside, but I have a point, I swear. A few years ago, my recreational RF adventures have lead me down a path where I decided to engage with ARIN to solve (once and for all) the massive headache I was running into with IPv6 numbering (really: always renumbering) my multi-site radio processing networks. It s a lot of work to keep running correctly, but it s solved a huge amount of problems for me. The only internal thing we really need to outline for this post is that, at the highest level, my network (paultag.net) is split into an IP plan that looks roughly like:
Prefix Description
/44my full allocation of IP space
/4815 "regions"
/5464 "sites" per region. A "site" is assigned to a physical or logical location.
/641024 subnets per site. A subnet used by directly attached devices.
For this exercise, I used IP space from paultag.net s experimental region ( region 8 ), named side.band (2602:810:6008::/48) to connect my RF lab ( site 1 - 2602:810:6008:400::/54), and my two pigeon-specific subnets, subnet 0 (2602:810:6008:400::/64) and subnet 1 (2602:810:6008:401::/64) to my wider network. The first subnet ( subnet 0 ) is a simple ethernet network to enable my RF-only nodes to communicate with the side.band gateway. The second subnet ( subnet 1 ) is an RF-only pigeon network local to my lab.

back to radios With all that set up, I assigned my first two nodes their MAC addresses, and set up the local RF only network segment. The nodes I brought online were the following:
Callsign IP
K3XEC/MN2602:810:6008:401:8e1f:64ff:fe35:4001
K3XEC/TH2602:810:6008:401:8e1f:64ff:fe35:4002

testing the pigeon network And with that, I could begin to test that the host operating systems and RF links could properly exchange data locally from SDR to SDR. We can use ping6 to see if a plain-ole ICMPv6 ping round trips between hosts correctly:
$ ping6 2602:810:6008:401:8e1f:64ff:fe35:4001
PING 2602:810:6008:401:8e1f:64ff:fe35:4001 (2602:810:6008:401:8e1f:64ff:fe35:4001) 56 data bytes
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=1 ttl=64 time=426 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=2 ttl=64 time=397 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=3 ttl=64 time=419 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=4 ttl=64 time=418 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=5 ttl=64 time=436 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=6 ttl=64 time=391 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=7 ttl=64 time=397 ms
And it does! Latency is horrid (and there s a bunch of tx artifacts that cause issues for us) but both of those things are problems for later. Let s see how it handles a TCP connection by firing off a quick cURL across the Pigeon network:
$ curl http://[2602:810:6008:401:8e1f:64ff:fe35:4001]:8000/testing.txt
The rock dove (Columba livia), also known as the common pigeon or rock pigeon
(but see also Petrophassa), is a member of the bird family Columbidae (doves
and pigeons).
As expected, our remote end here running the server reports the correct peer IP address, which is another indication (beyond the log messages and blinking LEDs) that we re routing over our TUN interface.
Serving HTTP on 2602:810:6008:401:8e1f:64ff:fe35:4001 port 8000 (http://[2602:810:6008:401:8e1f:64ff:fe35:4001]:8000/) ...
2602:810:6008:401:8e1f:64ff:fe35:4002 - - [28/May/2026 12:53:21] "GET /testing.txt HTTP/1.1" 200 -
That worked? First shot! Nice! It s pretty slow and seems like we have a lot of packet loss, but it does, however, beg the question can it nethack?

nethack! Yes! It can nethack! No clickbait here. The way I went about this one is a bit anit-cimatic I set up a nethack server (using inetd in this case) on one of the hosts pigeon0 network interface, and hit that port over RF from the other: However, when playing it, it becomes very obvious (as you can likely see) that there s a fair amount of packet loss (understandable) and probably some packet collisions taking place.

iperf Let s try and put a number to exactly how bad the bandwidth and packet loss is by running iperf between the two pigeon hosts over rf:
$ iperf -c 2602:810:6008:401:8e1f:64ff:fe35:4002
------------------------------------------------------------
Client connecting to 2602:810:6008:401:8e1f:64ff:fe35:4002, TCP port 5001
TCP window size: 16.0 KByte (default)
------------------------------------------------------------
[ 1] local 2602:810:6008:401:: port 58248 connected with 2602:810:6008:401:8e1f:64ff:fe35:4002 port 5001
[ ID] Interval Transfer Bandwidth
[ 1] 0.0000-20.2348 sec 76.8 KBytes 31.1 Kbits/sec
Shockingly, not nearly as bad as I thought it was going to be. Given I ve spent exactly zero time making this operate to a level that I would call acceptable, this is a very fucking solid start. I expect I could get that number up if I spent a few weeks on it it s just not been a priority at any point yet (and the first time I ve instrumented it, even!). This ll be good enough to get started. Let s see what else we can pull off here.

IP multicast to some rtl-sdrs Back when I designed what I wanted Mode A to look like, I intentionally picked a signal bandwidth that could be received by an rtl-sdr so let s put that to use. It may go without saying, but just to say it the rtl-sdr can not transmit, so this will be capable of receiving pigeon frames but not sending any in reply. However, this means I can use a bunch of low-cost computers (raspberry pi-class), and low-cost SDRs (rtl-sdr) and still receive IP traffic from transmitting pigeon network stations. This could be a lot of fun for things like fountain coding a data stream, or adapting multicast streaming protocols to work over RF links. Anywho, I swapped my far end to an rtl-sdr (one config file change!), and figured I d start with some (basic) multicast traffic, transmitting the time once a second:
$ while [ true ]; do
 echo $(date +%s) \
   socat - UDP6-DATAGRAM:[ff02::114%pigeon0]:62804
 sleep 1
done
If I had more time to burn, I was planning on bridging APRS traffic to UDP multicast within a pigeon network subnet. However, since I m already 4 years late on this blog post, I figured this would be enough for now (and you can imagine that fun project in this space if you so wish!) I fired up pigeond again (except this time connected to an rtl-sdr), and was pleasantly surprised to be greeted by some decoded traffic right off the bat:
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
Of course, I took a tcpdump to confirm for completeness sake that the traffic actually made it out of our TUN interface:
$ tcpdump -i pigeon0
22:39:34.808705 IP6 (flowlabel 0x92a0e, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.35911 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:36.429887 IP6 (flowlabel 0x4dc84, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.50026 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:39.365977 IP6 (flowlabel 0x224d5, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.36308 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:40.944889 IP6 (flowlabel 0x4721c, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.35003 > ff02::114.62804: [udp sum ok] UDP, length 11
Looks great! tcpdump is showing multicast packets show up (as we assumed they would), on the pigeon0 interface, on the machine connected to an rtl-sdr. Of course, any replies will get sent to the bit bucket, but it can definitely decode things just fine! Very fucking cool. Well right, ok! Let s go back to two rx/tx radios, and see what we can do with our newfound network stack over ham radio frequencies let s try to do some fun (and traditional!) ham radio things with it!

Crossing the english channel in a bathtub Ok, ok. I decided to bury the lede a bit here I didn t mention that the side.band network is currently BGP announced. Although we haven t used it this does mean that we re most of the way to sending packets to the wider internet, and we should be able to just fix a few routing tables, and see packets begin to flow. After tweaking the local routing tables (and restarting pigeond for good measure), I decided to test my newfound connectivity by pinging something over our new network transport.

ping github Why don t we start with the world s premier software engineering platform, operated by one of the largest companies in the world, GitHub! After all, they have an all knowing (and, apparently, arguably sentiant?) AI on hand to instantly and automatically fix any stray reliability issues in the background, so we should definitely see replies right off the bat:
$ ping6 github.com
ping6: github.com: Address family for hostname not supported
Wait, oh no that can t be right? After all, it s 2026, and both Google and CloudFlare (in North America) are reporting over half of all traffic they see is IPv6 and GitHub still doesn t support IPv6? Definitely not, this is for sure a bug with my code or network.

lets ping something that supports ipv6 instead That being said, just for completeness sake, since that error is also given when there s no IPv6 DNS record, let s go ahead and double check with Hurricane Electric too, you know, just to be sure.
$ ping6 he.net
PING he.net (2001:470:0:503::2) 56 data bytes
64 bytes from he.net (2001:470:0:503::2): icmp_seq=1 ttl=53 time=514 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=2 ttl=53 time=230 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=3 ttl=53 time=248 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=4 ttl=53 time=246 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=5 ttl=53 time=265 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=6 ttl=53 time=240 ms
Well, shit. Right, OK, i ll be damned. 18 years in and GitHub still can t crack that nut.

cURL works! Right, anyway, yes, back on track good news! Our uplink is up and routing, and wait, holy shit! Check it out! pigeon is exchanging packets with the internet and no one is any the wiser! Literlaly amazing. Let s try a cURL across the internet now (although no TLS allowed, so, http only for now):
$ curl -6 -I http://facebook.com
HTTP/1.1 301 Moved Permanently
Location: https://facebook.com/
Content-Type: text/plain
Server: proxygen-bolt
Connection: keep-alive
Content-Length: 0

IRC works, too Sweeeeet. That all works! Forget HTTP, let s do some other 90 s era stuff, it s high-time to log into IRC with a quick /connect -notls, and see what s going on in the #debian-hams channel pleased that I got online fairly quickly, and was able to even talk to myself!

THE GOPHERSPACE Naturally, let s keep this train of nostalga running, and give the 2026 gopherspace a shot. I know the kind folks over at tilde.town (hello, townies!) have a robust gopherspace, so let s give it a dial! Let s try and see if we can load vilmibm s slug over gopher: Yes! I forgot to make this one a video, so no gif. I did wind up having a bit if trouble with a few gopher clients and IPv6 support I may send some patches if I can find the time.

So, what s next? Alright, that s it. I have a few more fun ideas but they re going to have to wait for another day. Carrying IP is fun and all but kinda not the point behind pigeon, after all. Rather than trying to make this into a thing , I m planning on exploring the loose ends first different types of modulation schemes (like QAM-NUC), implementing LDPC error correction and some layer 2 logic into the pigeond (like switching traffic, and gain control). I also plan on spending some time with my (currently, very basic) simulator to better dial in tradeoffs throughout the stack. Since, structurally, pigeon is something I feel like I can work with, I m hoping i ll be able to find the time for some (much smaller!) followup posts without it taking 4 years this time. If I do, they ll show up under the pigeon tag and I ll be sure to update this post with a link below (and the intro post). I m hoping that this series (which was supposed to be one post) was helpful to someone out there if it was, feel free to reach out and let me know!

Paul Tagliamonte: Mode A (Part 9/12)

This post is part of a series called "Pigeon". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.

If you're looking for it, the intro to the PHY (layer 1) that this belongs at a high level and listing of the parts that make it up (including this one) is on the phy post.
While developing Pigeon, I ve called the group of all the configuration of the Layer 1 PHY parameters the Mode . I ve experimented with a few different modes , but one in particular has been the most resilient to the innumerable mistakes and bugs i ve wrought into existence and that is the first mode I wrote down, Mode A . This is even (mostly) backwards compatible to my original Go implementation of Pigeon Mode A (back in 2022) over the air, and has largely withstood the problems I ve thrown at it. I ve removed the bulk of the support I wrote out for other modes, but i m likely to bring them back over time as I use pigeon to learn more (such as Mode B (QAM-16), Mode C (QAM-16 NUC), and Mode AW which is the exact same as Mode A, except 5MHz in bandwidth. More to come on those as I get further along but for now let s braindump the parameters i ve picked out for Mode A:
Attribute Value Description
Rate 2.5 MHz Sampling Rate / Bandwidth
LCG 3149721335 LCG "RNG" whitening constant (randomly selected)
Preamble seq=16, order=4, count=2 (this is as-written in the preamble post)
Modulation QPSK/QAM-4 2 bits per data subcarrier
FFT Size 64
Cyc Len 16 Cyclic Prefix length (16 IQ samples)
Symbols 168 Number of OFDM Symbols
LDPC Table 802.3an (this is as-written in the ldpc post)
Raw Bits 14448 1806 bytes (168 symbols, 86 data bits per symbol)
LDPC Count 7 Number of packed LDPC encoded messages
Data Bits 12061 1507 bytes
The last bit to describe here is the Subcarrier Plan. The plan is ordered negative first (meaning the 0th bin in-memory is the most negative frequency domain bin of the fft), and within a Mode A OFDM symbol, there are 64 frequency domain bins (so, just to make it explicit: 64 subcarrier usages that make up our Mode A subcarrier plan ). We ll follow the same structure and conventions that we went through in the post all about OFDM Symbols which means, we ll need to place our guard bins, data bins, and pilot bins. I ll include a copy-paste-able version of the images to follow at the end.

Guard Bins First up, let s place our guard bins. As we ve already gone over, we re looking to clear some space right up against the high and low end of the frequency range, so let s go ahead and do that: I gave up the center bin (0 Hz) and 8 of the 64 bits on each side (1/4 of the signal!) to give myself a bit of elbow room. This is perhaps definitely a bit overkill, but it s been an extremely robust choice. If you multiply that through, this accounts for 312.5 kHz of frequency domain padding at the high and low end of the bandwidth, or 625.0 kHz of bandwidth which is not to be used.

Pilot Bins Next up was the pilot bins. We ve already gone over the purpose (and use) of our pilots, but I ve found there to be an art to the placement of the pilots. Interpolation between pilot bins has turned out to be very reliable, but extrapolation, on the other hand, has been a major pain, for reasons I don t fully understand yet. My intent in placement was to pick out roughly even stretches of data bins bracketed between pilots, with as few data subcarriers as practical outside of a pilot (using extrapolation). I ve played a bit with my AGWN simulator(s), as well as logging errors between two SDRs, and the configuration I have this in has been fairly resillant (for whatever reason), and withstood a few rounds of tweaking.

Data Bins Almost as an afterthought all of the remaining bins become data bins. This puts the total number of data bins at 43, which, since Mode A carries data in QPSK/QAM-4 (two bits per data subcarrier), means we can carry 86 bits of data per OFDM symbol. That fairly modest capacity is largely due to the modulation scheme (or fft size, but increasing that has been fraught) we re using for Mode A but I ve made up for it by including 168 OFDM symbols in a single burst in order to have enough data to carry IP traffic without splitting the packet into two bursts. With all that designed and on paper, we re ready to start to tackle the next layer up our Layer 2, named, creatively, link . Let s send some link layer data
Following along at home? Nice! As promised, I've put the full plan copy-pasted from the pigeon source tree below so that no one has to feel the need to transcribe this from the images above. Unlike most of the things I've "left to the reader", manual transcription from images is not a particularly useful task for anyone to do.
The following table is Mode A s OFDM Subcarrier Plan. This is in negative first ordering (meaning the 0th member is the most negative fft bin, and the Nth is the highest frequency fft bin).
SubcarrierPlan([
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Data,
 Data,
 Data,
 Pilot(iq!(-1.0, 0.0)),
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Pilot(iq!(1.0, 0.0)),
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Guard,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Pilot(iq!(0.0, -1.0)),
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Pilot(iq!(0.0, 1.0)),
 Data,
 Data,
 Data,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
])
Still following along at home? Nicer! I've put the preamble sequence promised previously copy-pasted from the pigeon source tree below in case that's actually important (I don't think it is, but...).
The following table is Mode A s frequency-domain preamble. This is, as above, in negative first ordering. I don t actually think these values matter much (at all)? but in case they do, here s what I have. I muck with these a lot and haven t found many changes in quality of detection or frequency correction yet.
[
 IQ::new(0.0, 0.0),
 IQ::new(0.0, 0.0),
 IQ::polar((TAU / 13.0) * 2.0, 1.0),
 IQ::polar((TAU / 13.0) * 3.0, 1.0),
 IQ::polar((TAU / 13.0) * 4.0, 1.0),
 IQ::polar((TAU / 13.0) * 5.0, 1.0),
 IQ::polar((TAU / 13.0) * 6.0, 1.0),
 IQ::polar((TAU / 13.0) * 7.0, 1.0),
 IQ::polar((TAU / 13.0) * 8.0, 1.0),
 IQ::polar((TAU / 13.0) * 9.0, 1.0),
 IQ::polar((TAU / 13.0) * 10.0, 1.0),
 IQ::polar((TAU / 13.0) * 11.0, 1.0),
 IQ::polar((TAU / 13.0) * 12.0, 1.0),
 IQ::polar((TAU / 13.0) * 13.0, 1.0),
 IQ::new(0.0, 0.0),
 IQ::new(0.0, 0.0),
]
Let s send some link layer data

Paul Tagliamonte: wrapping it all up (Part 8/12)

This post is part of a series called "Pigeon". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.

If you're looking for it, the intro to the PHY (layer 1) that this belongs at a high level and listing of the parts that make it up (including this one) is on the phy post.
The time has come. If you re following along at home, we now have all the basics we need to glue these parts together and see what this looks like. We re going to build the highest-level constructs for the PHY in code something that takes some number of bytes in and writes out IQ samples fit for transmit over the airwaves (we ll call this the Encoder), and something that takes chunks of IQ samples in, writing out decoded bytes (which we ll call the Decoder).

Encoder Let s begin with the Encoder, since it s slightly less involved. I ve tried to make this a bit more accessible by drawing a diagram out before describing the order of operations, so that it s possible to follow along visually. While the process here can look like a lot, it s really not that bad. We begin by taking the incoming bytes, converting the bytes into bits, and chunk those bits into parts which are sized to fit completely within an LDPC message. We will then encode incoming data into LDPC messages, using our configured LDPC Matrix (the table we appropriated from 802.3an). Next, we apply whitning over all the bits in our encoded (and packed) LDPC messages, using our configured whitening constant. In the case of QPSK, pairs of bits will then be modulated into a QAM subcarrier, where each QAM point represents a range of bits in the message. We ll go through each of those modulated IQ subcarriers, and set each corresponding data subcarrier in order, for each OFDM symbol contained in the pigeon Burst. The preamble configuration is then used to generate (or, more likely, can be used at startup to precompute) the Schmidl-Cox preamble, which is written to the first IQ samples in our output IQ buffer. Finally, we will do a series of inverse FFT operations to convert each OFDM symbol to the time domain, including their cyclic prefix. Let s take a look at doing that, but in code this time now:
// (lightly edited for clarity)
impl Encoder  
 ..

 /// Encode the provided bits into the output time-domain IQ samples.
 fn encode(
 &mut self,
 dst: &mut [IQ],
 src: &Vector,
 ) -> Result<Burst, Error>  
 let src =  
 let mut raw = Vector::new(self.fec.message_len());

 // Set  raw 's data bits, compute and set LDPC
 // checkbits.
 self.fec.add(&mut raw, src);

 // Apply whitening, and return
 raw.xor(&self.whitening)
  ;

 // copy in the precomputed schmidl-cox preamble to  dst 
 let preamble_len = self.preamble_iq.len();
 dst[..preamble_len].copy_from_slice(&self.preamble_iq);

 // allocate a new (frequency domain) 'Burst' container.
 let mut burst = Burst::new(
 &self.mode.ofdm.plan,
 self.mode.ofdm.symbols
 );

 // modulate bits from 'src' as iq, and set each
 // data subcarrier for each ofdm symbol in the
 // burst.
 self.burst_encoder.multiplex(&mut burst, &src);

 // convert from frequency-domain data into time
 // domain iq samples, writing out ofdm symbols
 // and cyclic prefixes to  dst .
 self.burst_encoder
 .transform(&mut dst[preamble_len..], &burst)?;

 // normalize all IQ samples; the maximum magnitude
 // in the IQ buffer may be very small, which weakens
 // our transmitted signal. Scale all IQ samples such
 // that the maximum IQ sample magnitude will be '1.0'.
 dst.norm();

 Ok(burst)
  
 
Using the Encoder should hopefully be fairly straightforward we ll give it a bag of bytes, and get back some IQ samples that we can ask our nearest SDR to transmit. As for what happens on the other end?

Decoder Next up is the mirror image of our Encoder the, imaginatively named, Decoder. The Decoder is slightly more involved (since it has to find the packet in the IQ stream, as well as correct for channel error(s)), so we ll do the same thing as above start with a diagram. My hope is going over the Encoder first helps us only really focus on the new stuff, otherwise it should feel like running the Encoder backwards. Here, we start with an incoming stream of IQ, where we will process scan detections as they come in from our Schmidl-Cox detector and burst Scanner. This will give us a snippit of IQ, sized to exactly our Burst. We ll begin to correct our IQ samples by first doing frequency estimation and correction in the time domain using our preamble and ofdm configuration. We ll then do a series of inverse FFTs to extract each OFDM symbol in our Burst, where we can then do channel estimation and correction. With the OFDM symbols (hopefully) good enough, we can now map each data subcarrier back to bits, and unapply whitning. The resulting bits are then chunked back up into LDPC messages, which are then checked, and concatanated data extracted. Finally the bits are turned back into bytes, which are written to our output buffer. However, before we get into the code to do this there s one last detail. We know bursts won t overlap (if they do, it s likely not possible to recover right now even though other PHYs can and do), so any time we see something we believe to be a burst, we can skip ahead by the burst s (constant) length within the IQ, and avoid trying to decode anything else in there. The nice side-effect here is this also gives us an interesting property for the Decoder namely, we know the maximum number of Burst detections we can get for a given block of incoming IQ data if they were packed end-to-end and we can pre-allocate the memory we need, avoiding allocations for every demodulation attempt (which may or may not even be a valid Burst). This pre-allocated block of memory to hold the burst s data is something that I ve called a frame buffer internally. Each frame buffer contains exactly sized buffers to hold decoded information from the burst an iq buffer that is exactly the same number of samples required to encode the preamble and data, exactly the number of bits needed to store pre and post FEC data, pre-allocated byte array, etc. Not shockingly, the code looks like this:
#[derive(Clone)]
pub struct FrameBuffer  
 /// Corrected IQ samples
 pub samples: Samples,

 /// post-correction OFDM burst
 pub burst: Burst,

 /// demodulated bits from the OFDM burst
 pub bits: Vector,

 /// demodulated bits from the OFDM burst,
 /// after FEC, and cleaned
 pub raw_bits: Vector,

 /// Layer 2 contents of the Frame
 pub contents: Vec<u8>,
 
Of course, that alone is handy but we need to use them. So let s go ahead and do what we promised above each Decoder uses a fixed number of pre-allocated FrameBuffers to store packets in-flight, packed into what is, creatively, called FrameBuffers within my code. As an aside, I likely should have called this a Memory Pool, since that s the common and accepted name for this design pattern but being stuck with unfortunate names is the burden of those of us who stumble into sensible ideas over time. The only nuance here is that I use the pools strictly sequentially we only save the FrameBuffer if the LDPC checksum is correct, allowing us to only keep track of how many successful packets we have and being able to get the valid FrameBuffers, rather than storing a handle to each FrameBuffer as we go a promise that most memory pools do not make, since blocks can usually be taken and returned in any order. Let s go ahead and do the whole Decoder dance now:
// (lightly edited for clarity)

impl Decoder  
 ..

 /// Process incoming IQ for Pigeon Bursts, and
 /// demodulate them.
 pub fn decode(
 &mut self,
 buf: &[IQ],
 ) -> Result<Vec<(Detection, &FrameBuffer)>, Error>  
 let mut ret = Vec::new();
 let mode = self.scanner.mode().clone();

 // reset the "valid frame buffer count" back to 0
 self.frames.reset();

 // call the scanner and get scan detections for
 // this block of iq ( buf )
 for detection in self.scanner.scan(buf)  
 // for each detection, we're (only) going to process
 // the iq snippit, but pass along the metadata
 // such as SNR.
 let ScanDetection  
 snippit,
 snr,
 range,
 m,
   = detection;

 // grab the next free frame buffer to work within.
 let frame_buffer = self.frames.next_mut();

 // Copy the snippit into the frame buffer (a mutable
 // location)
 frame_buffer.samples.copy_from_slice(snippit);

 // estimate the frequency offset based on the
 // Burst's Schmidl-Cox preamble.
 let preamble_fo = preamble::estimate_frequency_offset(
 &mode.preamble,
 mode.rate,
 &frame_buffer.samples[..mode.preamble.samples()],
 );

 // Shift the IQ stream by the estimated frequency
 // offset -- hopefully we're closer to 0Hz
 frame_buffer.samples.shift(mode.rate, preamble_fo);

 // estimate the frequency offset based on the
 // each burst's **cyclic prefix** -- exactly like
 // we did with the Burst Schmidl-Cox preamble,
 // but this time on each OFDM symbol.
 let ofdm_fo = ofdm::estimate_frequency_offset(
 &mode.ofdm,
 mode.rate,
 &frame_buffer.samples[mode.preamble.samples()..],
 );

 // Shift the IQ stream closer yet; hopefully this
 // is a very small nudge even closer still to 0Hz.
 frame_buffer.samples.shift(mode.rate, ofdm_fo);

 // Do a bunch of inverse fft operations for each
 // OFDM symbol, filling the frequency-domain Symbol
 // structs in  frame_buffer.burst  (Burst) struct.
 //
 // this will also do channel estimation and
 // correction before returning.
 self
 .decoder
 .transform(
 &mut frame_buffer.burst,
 &frame_buffer.samples[mode.preamble.samples()..],
 )?;

 // "demultiplex" each data subcarrier's frequency-domain
 // IQ constellation point, setting the correct bit range.
 self.decoder.demultiplex(
 &mut frame_buffer.raw_bits,
 &frame_buffer.burst
 );

 // unapply whitening by XOR-ing the buffer with
 // the well-known whitening vector.
 frame_buffer.raw_bits = frame_buffer.raw_bits.xor(
 &self.whitening);

 // verify that the LDPC message(s) are all correct,
 // and if so, concatanate the the data bits (no check
 // bits) to the  bits  vector.
 if self.fec.decode(
 &mut frame_buffer.bits,
 &frame_buffer.raw_bits
 ).is_err()  
 // this is where invalid packets fail. we gave it a good go.
 // next packet please.
 continue;
  

 // copy the raw bits out, as bytes, to the  contents  buffer.
 frame_buffer.bits.copy_as_bytes(&mut frame_buffer.contents);

 // store metadata/metrics on the demodulation.
 ret.push(Detection  
 m,
 snr,
 index: range.start,
  );

 // save the contents of this frame buffer (don't
 // reuse this buffer next go-around).
 self.frames.save();
  

 // We're going to take out the borrow on the frame at
 // the end since we don't want to deal with telling the
 // compiler via code gymnastics that the mut and non-mut
 // borrows are OK since they're non-overlapping.
 Ok(ret.into_iter().zip(self.frames.iter()).collect())
  
 
Phew. That was kinda a lot. In fact it s basically the whole thing. This function is as close to how do you read an OFDM packet as it gets, and perhaps the most important part of this whole series. Beyond that, though, this is a huge conceptual unlock. This means we now have an incredibly powerful primitive; the ability to take bytes and go to/from IQ samples over the air. Let s talk about pigeon modes

7 September 2026

Colin Watson: Free software activity in August 2026

My Debian contributions this month were all sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. Personal note This month, my Dad unexpectedly passed away after a short illness. As a result I obviously got less work done than usual, and I still have a lot to take care of (since I m the executor of his will, as well as helping with funeral arrangements) while grieving and generally having less focus and energy. Having routine work to do is one of the ways I cope with this sort of thing, but all the same, I hope people will bear with me and maybe remind me if I seem to be dropping the ball on something you especially need. LLM vote [Content note: strong opinions.] I voted in General Resolution: LLM usage in Debian. My vote was pretty much the opposite of what ended up winning, so I m quite disappointed. My personal opinion is that LLMs are cognitive hazards to their users that impose ecological costs far out of proportion to their utility at a time when the world absolutely cannot afford them. When the impossible economics of the large commercial models are finally allowed to catch up with reality, I expect there to be significant macroeconomic consequences, and that people who have become dependent on them will have problems; and who knows what the copyright situation on their output really is. I m not convinced that local models are better enough on these axes to be worth the costs. Debian s direct contribution to all that will be negligible on a global scale, and even the most radical proposals in the GR didn t expect that we could do much about upstreams that have gone all-in on LLMs. Even so, I d hoped that my fellow developers might be more willing to lean on our position in the free software ecosystem to make at least a moderately radical statement. Instead, we ve at best presented an undistinguished fence-sitting position to the world, and further entrenched the idea that humans can reliably do a good job of reviewing the output of tools that are designed to produce output plausible to humans. I certainly don t trust my own code review skills that far. Since I ve never voluntarily used an LLM (not counting LLMs being foisted on me by things like search results, support chatbots, or incoming pull requests, regardless of whether I asked for them), and don t intend to for the foreseeable future, I doubt this will change much for me in terms of the way I work. The winning option is a very weak one that imposes no new requirements on developers, which means that it also does nothing to stop me continuing to reject LLM-generated material from Debian bug reports and merge requests in my areas of responsibility. I know this probably won t do much to satisfy people who have decided that Debian is slop now, but it s the best I can do. OpenSSH I finally landed the GSS-API key exchange package split in our OpenSSH packaging. Here s the NEWS entry:
openssh (1:10.4p1-5) unstable; urgency=medium
  The openssh-client and openssh-server packages no longer include GSS-API
  authentication and key exchange support; this adds pre-authentication
  attack surface and generally increases complexity, and should only be used
  where specifically needed.  Users who need these features should install
  openssh-client-gssapi or openssh-server-gssapi instead.
 -- Colin Watson <cjwatson@debian.org>  Sun, 23 Aug 2026 17:39:55 +0100
I fixed a flaky autopkgtest. I upgraded from 10.4p1 to 10.5p1, which was a good test of keeping openssh and the new openssh-gssapi source package in sync. PuTTY I upgraded from 0.84 to 0.85. Python packaging New upstream versions: The version treadmill continues: we ve just finished dropping Python 3.13 as a supported version, so now we ve started working on enabling Python 3.15 as a supported version. Maximiliano Curia has been very helpfully driving this. I didn t get as much done here as I d have liked (see the top of this post), but I fixed a couple of packages: Other build/test failures: I fixed some other bugs: bugs.debian.org I deployed the fix for Invalid link rel= canonical on bugs.debian.org. In the process I found a few bugs in recent undeployed code and fixed them.

Vincent Bernat: Sidenotes with CSS anchor positioning

I am a heavy user of sidenotes:1 they keep optional content next to the text instead of sending the reader to the bottom of the page and back. Tufte CSS renders them without JavaScript but only accepts inline content. CSS anchor positioning, now supported by recent browsers,2 is an elegant alternative. Sidenotes can hold several blocks, still without JavaScript, and fall back below the paragraph referencing them on narrow viewports and older browsers. In 2023, Eric Meyer demonstrated this technique in Nuclear Anchored Sidenotes. The main improvement over other solutions is that the notes can sit anywhere in the HTML document. You can place them after the paragraph referencing them, as regular block elements for text browsers, screen readers, feed readers, and reader mode to render them properly:
Sidenotes rendered in Lynx appear after the paragraph they are called from.
Rendering in Lynx, a text browser
When the viewport is too narrow or the browser does not support CSS anchor positioning, you can style them so the reader can skip them or glance at them without losing their position in the text:
Sidenotes rendered on a narrow viewport appear with a distinctive typography after the paragraph they are called from.
Rendering below the paragraph on a narrow viewport
Once the viewport is large enough, they appear in the margin, at the same vertical position as the matching reference mark, unless they would collide with a previous sidenote, as in the example below:3
Sidenotes rendered on a large viewport appear in the margin. There are two of them. The first one is vertically aligned with the matching reference mark, while the second is rendered below as it would collide with the first otherwise.
Rendering in the margin on a large viewport
The gist of CSS anchoring is to position an element relative to another element the anchor. For the sidenotes, the anchor is the reference mark. I use the following markup, with a data attribute to specify the anchor name:
<sup id="fnref:YYY" data-anchor="--lf-sn-YYY">
  <a href="#sidenote-YYY">1</a>
</sup>
The matching note is an <aside> element carrying the same data attribute for the anchor name. We put it after the paragraph holding the reference mark:
<aside role="note" id="sidenote-YYY" data-anchor="--lf-sn-YYY">
  <sup>1</sup>
  <p>A first paragraph.</p>
  <p>A second paragraph.</p>
</aside>
On a narrow viewport or when the browser is too old for CSS anchoring, we style the sidenote, which stays below its paragraph, with a muted color:
aside[role="note"]  
  margin-block: 1rlh;
  color: #444;
 
On a wide viewport and when the browser is recent enough, we move the sidenote to the right margin:
@supports (anchor-name: attr(data-anchor type(<custom-ident>)))  
  @media (min-width: 72rem)  
    main  
      position: relative;
      sup[data-anchor]  
        anchor-name: attr(data-anchor type(<custom-ident>));
        /*   anchor-name: --lf-sn-YYY */
       
      aside[role="note"][data-anchor]  
        anchor-name: --lf-sidenote;
        position: absolute;
        position-anchor: attr(data-anchor type(<custom-ident>));
        /*   position-anchor: --lf-sn-YYY */
        top: max(anchor(top), anchor(--lf-sidenote bottom, -1rlh) + 1rlh);
        left: 100%;
        margin: 0 2rem;
        width: 18rem;
        color: inherit;


attr() extracts the anchor name for the reference mark from the data-anchor attribute. It returns a string, unless we specify a CSS unit or a type, like here: the browser parses the data attribute as a custom identifier, which anchor-name validates as a dashed identifier, a custom identifier starting with two dashes.4 The note itself is absolutely positioned past the right edge of the main block. It selects the matching reference mark as its anchor with position-anchor set to the value of the data-anchor attribute. Each note is also an anchor named --lf-sidenote. We use it to keep the next note from colliding with this one. The anchor() CSS function lets us position the note s top edge relative to its anchor: anchor(top) aligns the top edge of the note with the top edge of the reference mark. It can also take another anchor as a parameter: anchor(--lf-sidenote bottom) would align the top edge of the note with the bottom edge of the closest preceding anchor named --lf-sidenote so the previous note.5 Like attr(), anchor() accepts a fallback value as its second parameter and use it when the named anchor does not exist. The top property handles three cases, illustrated in the following diagram:
Diagram of three sidenotes anchored to their reference marks. The first one is aligned with the top of its own reference mark, as no note comes before it. The second one would overlap the first, so it takes the bottom of the first note as anchor and sits one line below it. The third one comes far enough down the page to align with its own reference mark again.
The three cases for the vertical position of a note
  1. The first note s top edge aligns with the top edge of its reference mark: as there is no previous note, anchor(--lf-sidenote bottom, -1rlh) + 1rlh resolves to 0 and max() returns anchor(top).
  2. When the reference mark of a later note sits above the bottom of the previous note, plus some vertical space, the note goes below the previous one to avoid a collision. max() returns anchor(--lf-sidenote bottom) + 1rlh.
  3. Otherwise, the note s top edge aligns with the reference mark s top edge, as max() returns anchor(top).

Have a look at the complete stylesheet, which also adapts the reference mark to the location of the note: a arrow when the note sits below the paragraph, a arrow when it moves to the margin. Gwern s Sidenotes In Web Design lists more implementations and their trade-offs. Some bloggers aim to write a post in 30 minutes. I planned to publish three web-related articles this weekend. Instead, I spent an inordinate amount of time elsewhere: about 15 commits on the build system, a pull request to update CSS highlighting for nested selectors in Pygments, and a small correction to MDN s article on the anchor() CSS function. The SVG illustration took a bit less than an hour and the article itself a handful of hours. The attr() function came in after I thought inline style looks ugly, isn t there a better way? But, hey, I still think this is worth it!

  1. My PhD advisor told me this is unwise.
  2. The first bits of anchor positioning are supported from Chrome 125 (May 2024), Firefox 147 (January 2026), and Safari 26 (September 2025). Before Safari 26.5, sidenotes may collide due to a bug in how dependency chains are handled. You can detect this situation with some JavaScript. It is, however, not needed in the solution described here as we depend on a more recent feature.
  3. If you noticed the runt in the first note, I share your pain and lament that Firefox does not implement text-wrap: pretty.
  4. Typed attr() is supported from Chrome 133 (February 2025), Firefox 155 (September 2026), and Safari 27 (September 2026). Check Una Kravets article for details. To support more browsers, you can inline the anchor name and the position anchor directly in the HTML:
    <sup id=" " style="anchor-name: --lf-sn- ">
      <a href="#sidenote- ">1</a>
    </sup>
    
    Managing Anchor Associations With Data Attributes and Advanced attr(), by Daniel Schwarz, explores CSS anchors and typed attr() in more detail.
  5. The exact rule for the target anchor element is more complex: if an ancestor of [the note] satisfies the following conditions, return the nearest such element to [the note]. Otherwise, return the last element in tree order that satisfies the conditions. One of these conditions is that [the candidate] is an acceptable anchor element for [the note], which requires that [the candidate] is laid out strictly before [the note], where the relevant clause is that [the candidate] is either not absolutely positioned or occurs earlier in the flat tree order than [the note].

Freexian Collaborators: Debusine can now hand you debug symbols! (by Jugal Patel)

Contributor: Jugal Patel (Jugal59)
Organization: Debian
Project: Provide debuginfod server
Mentor: Colin Watson

About the project and me Your program crashes. You open gdb and get ?? instead of a stack trace. So you go find the right -dbgsym package, for the right version, for the right architecture, install it, and start again. Debuginfod removes that entire detour: gdb asks a server for symbols by the build-ID baked into the binary. Debusine already built packages, already produced -dbgsym files, and already hosted the archives; it just couldn t answer the question. This summer I made it answer. My project was to add debuginfod server functionality to Debusine so that it not only hosts -dbgsym packages, but also serves their debug symbols over the debuginfod(8) protocol. Debian developers can then debug binaries by setting a single URL that gdb uses to fetch the matching debug symbols. This project took me through design, backend work, an extraction pipeline on the worker, HTTP serving, documentation, and testing from the first blueprint all the way to a live demo on debusine.debian.net.

Initial planning and design changes A design first, in !3030. The proposal submitted for GSoC 2026 was just an overview of how things will work, but in reality there were a lot of design questions which needed to be answered before starting with contribution. Debusine keeps development blueprints in its docs tree, reviewed like code, it s basically a blueprint of what feature or new changes are we going to make. I was assigned the work item #957, which was basically about how the idea of implementing a debuginfod server functionality inside Debusine was initially proposed by a fellow member which later became a project idea under GSoC 2026. My developer blueprint pinned down the four decisions everything else depends on: extraction happens on the worker after the build, symbols are stored as artifacts keyed by build-ID, they re published into suites alongside their binaries, and they re served from the archive root rather than per-suite. Settling that up front meant the design discussions happened in a document instead of across three merged branches. Provide debuginfod server work item and all my merged PRs till now One of those arguments became its own fix. My wording implied symbols were unpacked inside the isolated sbuild environment (the consequence was I was handed a bug to be solved in the first week of contribution period), when they re actually extracted afterwards on the worker, where the build output already sits, a distinction that matters, because doing work inside the unshare environment means extra tooling in the chroot and more ways to affect the build. !3119 corrected it before the wrong model spread into the code. Bug raised for inconsistent wordings in developer blueprint

A new artifact type Artifacts are a major concept in Debusine overall, so as per the developer blueprint we introduced a new artifact which was debian:debug-symbols. It holds every .debug file from one -dbgsym package. Its data is a validated list of lowercase 40-character build-IDs, and each file is stored under its build-ID as the path, so answering what are the symbols for this ID? is a direct lookup, with no path translation in the request handler. One artifact per package rather than per file: a util-linux build would otherwise spray hundreds of artifacts, collection items and relations across the database for no benefit. For implementing debian:debug-symbols artifact, I changed the main models.py file, along with that since it s a norm to write unit tests, all mentioned under !3088. sbuild task output showing the new debian:debug-symbols artifact

Publishing workflow and solving a bug Extracting symbols is only useful if they reach the archive people actually install from, so !3180 taught package_publish to follow the relates-to relation: copying binaries into a suite now brings their debug symbols along automatically, with nothing extra for the publisher to configure. Each build-ID becomes its own collection item, for example debugsym:hello_2.10-5_amd64_fcc9064 each carrying the package name, version and architecture copied from the binary, so the item is meaningful on its own without dereferencing anything. Uniqueness is enforced at both the suite and archive level, because the serving URLs are archive-wide and two suites must never disagree about what a build-ID means: republishing an identical file is accepted quietly, while two different files claiming the same ID is an error worth failing on. A partial index on the build-ID keeps the eventual HTTP lookup fast. That looked finished until symbols started arriving in target suites disconnected from their binaries published, but unfindable, because copying items between collections silently dropped their artifact relations, and that relation is the only thing tying the two together. The fix sat one level above my feature, in the generic CopyCollectionItems task that does the copying, and since it was reusable infrastructure rather than anything debuginfod-specific, Colin implemented it himself in !3228. My project needed it to work at all; every other Debusine feature that copies items now gets it for free.

Endpoint and CI tests With symbols in the archive, !3212 added the part users actually touch: GET / scope / workspace /buildid/<build-id>/debuginfo looks the ID up across every suite in that workspace s archive, streams the file, and sets the X-DEBUGINFOD-FILE and X-DEBUGINFOD-SIZE headers the protocol expects. It also handles the two things gdb actually does: a HEAD probe before committing to a download, and ranged requests to pull individual ELF sections instead of the whole file. Scoping it to the archive rather than the suite is what lets one URL cover a whole workspace, so the developer never has to know which suite their binary came from. Fetching debug files from debusine.debian.net Every merge request above landed with unit tests, but those only tell you that the pieces behave correctly. What Colin and I wanted was a real gdb fetching real symbols from a real instance, so !3261 adds an autopkgtest that builds a package, publishes it, checks the HTTP headers, then sets DEBUGINFOD_URLS and makes gdb go and get the symbols, wired into the CI integration tests so it runs on every change. It took me a day to learn that skipping the signing worker doesn t simplify that test, it just hangs until the 30-minute timeout, because update_suites needs signing to produce a usable repository. The last piece, !3301 covers the new artifact, the suite and archive changes, the new archive URL, and a how-to for using it. My first how-to draft explained how everything worked and offered four ways to set DEBUGINFOD_URLS; the version that shipped gives one recommended setup and gets out of the way. The same pass trimmed the blueprint down to only what s still unimplemented, since a design document describing merged code is just an obstacle for the next reader. Setting debuginfod url for gdb and debugging session!

What s left Only one item on my original plan didn t land: an archive-level build_debug_symbols switch, modelled on Launchpad s equivalent, letting an archive skip building -dbgsym packages entirely by passing DEB_BUILD_OPTIONS=noautodbgsym to sbuild. It was always the stretch goal rather than core scope, landing the extract-publish-serve path solidly mattered more than landing it broadly. The design is written up in the blueprint, and I intend to implement it myself. The other gaps were deliberately out of scope from the start, and the blueprint says so. DWZ supplement files aren t ingested, so packages using compressed debug info may render without the alternate strings table; debugging still works, it s just less complete. Source-file serving runs into the same Debian packaging limits that constrain debuginfod.debian.net today, making it a design question rather than a coding one. Executable serving, the metrics and metadata endpoints, and federation to upstream debuginfod servers were excluded for similar reasons, none of them are needed for Debusine s core use case, and each would have crowded out the parts that are. One open bug is left too. On the last day of the coding period, Stefano Rivera found that publishing ledger and linux was failing, because I had told the database that a build-ID identifies one exact debug file which isn t true in Debian, since dh_dwz runs once per binary package, so when one object ships in two binary packages their .debug files differ while describing identical code. How to fix it is still an open discussion #1582, though it may not land before the formal end of the project. None of that is a handoff. GSoC s timeline is ending, my involvement isn t, I m carrying on with Debusine until both the build_debug_symbols switch and DWZ supplement support are merged, and I expect to keep contributing beyond that. This project got me familiar with a codebase I enjoy working in, and the remaining pieces are mine to finish.

Thanks! The biggest thanks go to my mentor, Colin Watson, whose reviews consistently found the thing I hadn t thought about. He also gave me room to get things wrong first and understand why, which taught me more than being handed the answer would have. Thanks as well to Rapha l Hertzog, Enrico Zini, Stefano Rivera, Carles Pina i Estany and Helmut Grohne and everyone else around Debusine and Freexian for reviews, comments and patience with my questions. Special thanks to Freexian for developing Debusine in the open and for giving me access to test on debusine.debian.net. Finally, thanks to the wider Debian community, whose build-ID and -dbgsym conventions did most of the hard work before I arrived and to Google Summer of Code for providing a platform and the time to do this properly.

6 September 2026

Iustin Pop: AI agents aha moment

Looking at the reactions to the Debian AI vote, I think some people still think the clock can be turned back, as if that ever worked in history. Rather than cry about spilled milk, I prefer to find a path forward in the new world. There are many ways to use LLMs, some of them are straightforward, others not so much. One of the not so clear areas for me is the focus on agentic workloads. For complex tasks, sure, you want something that can work in the background, but in general, why does every single tool go the agentic way? I much prefer the chat/ask approach, or even the code one, but if I m at the keyboard, why would I send a task to an agent, and see it work, instead of directly implementing it? And then, this past Friday, I finally understood one part of that. I was in the airport, sitting at the gate and waiting to board a flight, and because I arrived much earlier at the airport (fearing crowds due to Labour Day weekend), I got one hour of work before boarding started. As the time for boarding approached, I did one more commit after making sure tests pass, pushed, closed laptop, and went to walk a bit before getting on the plane. As I was getting up, I get a phone notification from GitHub that the CI run failed. I was quite surprised, as the local tests passed, so I open the notification, and realize that tests via make test vs CI (which additionally uses --pedantic) had slightly different settings, and of course I missed a build warning (which in CI is an error). I thought I d fix that on the plane, but then I saw a Copilot agent button in the mobile app. I was curious what it did, I click it, and I see Copilot starting a draft pull request, and saying:
Thanks for asking me to work on this. I will get started on it and keep this PR s description up to date as I form a plan and make progress. Fix the failing GitHub Actions job. Analyze the Actions logs, identify the root cause of the failure, and implement a fix.
Then it goes, finds the failure, writes the fix, and tries to run the tests. Well, it can t do it (it runs in a restricted container, so no network, so stack install couldn t actually work). The agent sees that, acknowledges it has no way to validate the fix, but the error message was clear enough that it was confident the fix is mostly correct, so it sends the pull request. I allow full CI to run on the pull request, and go buy a bottle of water. After that, I check and see that the CI failed again, as not one but two test files were broken, and I didn t have --keep-going, so the build stopped at the first failure. I write a comment in the pull request, no reaction, I realize I need to tag Copilot explicitly, I do that, and it starts another investigation. I m waiting now in the boarding queue, with phone in hand, while Copilot is fixing my bug. While I scan my boarding pass and walk towards the plane, the pull request is updated, I trigger another CI, it passes, and I merge it. And then, it hit me. Agents allow me to make progress while being not at keyboard , whether that s physically not at keyboard , or while working on something else. Fixing a simple test failure is not something that needs human attention per se, whereas improving the test layout might be. In that airport, using otherwise-unusable downtime, and without explicitly intending to, I made progress in understanding a different way to use AI. Now I have three ways to work with LLMs: ask (tutor mode), code (implement my request), and agent (fix simple or complex problems, autonomously). I still don t know about plan mode and really complex tasks, like asking it to implement features from scratch. That will probably be the next area to tackle. And today (Sunday), while waiting for a running race to start, I opened GitHub, and asked Copilot to increase test coverage for a simple module. It did, and yes it still can t run tests (I learned in the meantime that you can configure the environment in which the agent runs, nice), but after two back-and-forth messages, I have a pull request ready to review. All in the 20 minutes before a race, where I could either browse social media or actually do some meaningful work. Checking now my GitHub billing, it looks like all of this Copilot use only cost $1.92. Yes, that is under two dollars! And while it did use compute resources, the person across the aisle who watched TikTok or Instagram for half an hour while waiting for takeoff also consumed a lot of compute, and so do the gazillion cat videos uploaded to YouTube every day. To me, this is another tool in the toolbox, that might one day replace me (as it did to the 19th-century textile workers), or make me five times more productive we ll see where we end up. In the meantime, I can move faster, and make better use of my limited free time. Enjoy the ride!

Enrico Zini: Migrating away from .org/.net/.com domains

After having witnessed how easy it is for good people to lose a .org domain over a fascist tantrum (you can follow the Autistici/Inventati story here and here), I've started moving all my infrastructure to differently managed TLDs. enricozini.org and enricozini.com will keep being functional for the time being, as dropping a domain makes it available for squatting and impersonation. These new domains are now online, with working web and emails: It will take ages to migrate countless accounts that are tied to my primary email address, so better start early. Waiting to see what will happen with .meow domains, which I supported despite not identifying as a cat.

Next.

Previous.