Search Results: "spa"

22 August 2026

Russell Coker: Links August 2026

This YouTube video about the Cashier Girl Meme is interesting in the context of AI systems that generate images of people and can communicate with people, hotter than any real human is an achievable goal [1]. Stand Up Maths has an interesting Youtube video about LLMs solving maths problems which I highly recommend watching (it does not require any real knowledge of maths), I think this opens the door to attacks on well established cryptologic systems [2]. Adam Conover made an insightful YouTube video about how and why Hollywood is now unable to make good sitcoms and why this is bad for society [3]. Sky Croeser wrote an interesting and insightful blog post about topics covered at the Digital and sexual citizenship in an age of social media bans: Interrogating the rights of children and young people conference [4]. Zane wrote a very informative blog post about reverse engineering a trojaned Android projector with Claude Code [5]. We need much better security on home networks to break the business model for this sort of thing. Renee Stonebraker s article Puritans Wouldn t Eat Pussy, So They Invented the Western has a lot of interesting information about early days of colonising the US, and not much about eating pussy [6]. IFLScience has an interesting article about brinicles, icicles of brine that form under sea ice [7]. Nautilus has an interesting article about the Silurian Hypothesis [8]. The Conversation has an intersting article about the pros and cons of no-till farming [9]. Cold War is a 365tomorrows story about bio-warfare which raises several disturbing possibilities we need to guard against [10]. Scott Santens wrote an insightful article describing how a land value tax would reduce rent and solve the housing shortages [11]. Positive News has an interesting article about using OnlyFans to teach people about climate change [12]. The Conversation has an interesting article about cultural safety in healthcare, sounds good, and while we are at it lets deal with sexism [13]. Doctoreww has an interesting web page about ways of displaying different strings to humans and machines, this could result in you running a different command to what you thought you copied from a web site or defeating tools designed to block hostile content [14]. Cory Doctorow wrote an insightful article Commentary Hell is Other People about the way rich people want to use AI to replace all people [15]. Also psychologists who help rich people accept being greedy are worthy of a Luigi The research article Worship me at the office altar: Why narcissistic leaders resist remote work is interesting, yet another reason to get rid of narcissistic executives [16]. Renew Economy has an interesting article about clean up costs for mining (which is usually left for the government to pay) and how this could impact renewable energy production facilities [17]. Elvira Bary wrote an insightful article on the Russian financial collapse that is happening now [18]. The Guardian has an interesting article about Afro-American women who travel to South Korea for healthcare because of problems with racism and sexism in American hospitals [19]. The Conversation has an interesting article about the potential for disabled people to be more productive in space than non-disabled people [20]. Krebs has an interesting article about LG banning residential proxy code from apps after the LG store was found to have such code in 42% of it s apps [21]. Robert B Shpiner wrote an insightful article for The Guardian about the death of democracy in the US [22].

19 August 2026

Antoine Beaupr : The people vs the AI overlords

Also in this series:
In a post to oss-security, my (Debian) co-developer Russ Allbery stated that "open source software [OSS] is coming face to face with a motivation crisis that has been building for a long time". His point is essentially that large language models (LLMs1) are making the existing OSS community crisis worse. For him, it's the flood of code reviews, but he argues that varies according to people's desires, for others it's security issues and so on. I think Russ is right, but I would argue there's something much bigger than our open communities going on here, and it's about the entire field of computing. This pressure is on all of us, regardless of whether we work on open source software or not.

How people use models People using LLMs in their workflow have radically changed how programming works, even for people who claim to avoid vibe-coding. And I'm sorry to single out one poor maintainer here: it's not you, Brian, you're just one example among many. But this is typical use of those models nowadays:
Once it s done, I ll use /code-review and let Claude spawn sub-agents to do a full review of the new code. This usually finds some problems, even problems that the main Claude instance didn t find during its validation. I usually keep running /code-review again and again after finding and fixing issues, until there aren t any left.
Think about what that means for a minute. This is automation built to fire up dozens of agents crunching at a problem for minutes if not hours of GPU compute time, in parallel. This is essentially a couple of shelves in a datacenter rack, totally maxed out on power and cooling, abstracted behind a cute little /code-review command. The author, here, is rightly concerned that "Anthropic could pull the rug out and require API pricing", which is perhaps a code word for "charging something closer to actual costs". Brian also pays lip service to environmental and societal costs but those are largely abstracted away, so let's keep that conversation aside here as well, as we have discussed it before anyways. But clearly, this way of working has an (externalized) cost, to say the least.

Paying for non-free tools For decades my work has been focused on free and open source software. I've long stopped using proprietary operating systems like Windows or Mac, and even before that switch, I was mostly using free software on those platforms, partly out of principle, but also because I was too poor. So the tools of my trade are free, and I build free tools with them. It feels like we're going backwards: when I was in school, a millennia ago, my classmates didn't have access to a compiler and were wondering how they would scrape the money to buy a compiler like Borland's or Microsoft's. I had a compiler built into my operating system (FreeBSD at the time), so that wasn't a problem for me. For them, it was a significant expense, but at least those expenses (or more shady sourcing of programs) were a one-shot deal. Fast forward 30 years, and software is rented: you pay monthly for Adobe's Photoshop and Microsoft's office suite just like you pay for Netflix, Disney+ or Spotify2. And now you need to add dozens (if not hundreds of dollars) of monthly credits to access LLMs on top of that. So, now we have to pay to get anything done? This is peak enshitification of our job: first they steal our work to train their models, and then they sell it back to us at a profit.

Attacking the engineers AI is coming for our jobs, as engineers, if not everyone, according to the narrative. For a while now, our job market has deteriorated: less jobs, for less pay. Lots of skilled engineers looking for work and finding crap jobs then still looking while working. This is not by accident.3 We engineers have a lot of power, it is not organized, but that's just a couple of unions away (easy!). Tech overlords know this, so they are attacking our profession, directly, by forcing us to train and use models that they can control. Even in environments where programmers are not forced to use LLMs, the mere pressure of other people's LLM-generated work is huge. One can be forced to review LLM outputs, or just peer pressured you into producing more. We're now supposed to accelerate delivery, because models can presumably do things so much better and faster. With supply chain security becoming such a large vector that we now have worms crawling around developers accounts on NPM, increasing the delivery cadence seems like a really bad idea.4 The LLM hype is part of the larger wave of cyberwar against workers, against water, against the Earth, against all the people. This is not a matter of individually "adapting to the reality" or personal choice, but a political, social, hard problem we need to address collectively.

  1. I again prefer the term LLM to "AI" because models do not possess intelligence. I did use it in the title because click baiting is apparently important, but I stopped short of calling this one "Rage Against the Machines" because that would be the title of every blog post I have ever made.
  2. Yes, I know that Visual Studio is kind of free now, but I wouldn't be surprised if they turn that into a rental as well, because why not.
  3. Beyond sabotaging the job market, Sam Altman event wants to sell "intelligence as a utility" something that is just a really bad idea but especially shows how megalomaniac those people are.
  4. This brings back memories of another era, walking us back decades in terms of computer security.

18 August 2026

Andy Simpkins: My first go at tracking down a kernel bug

A couple of weekends back, I upgraded my home sever. It failed to restart after running apt dist-upgrade The only update that was performed was to the kernel, it went from 6.12.88+deb13-amd64 to 6.12.100+deb13-amd64. I had previously performed an apt-get upgrade, and rebooted the machine, so I was pretty sure that this was to blame. This blog entry (is a late) attempt to document how I went about finding a fix for this issue so that next time I don t need as much hand holding as I did this time around :-) (1)

Having my machine not boot following an upgrade is pretty rare, but has happened before. Usually it is because I have done something wrong so as always confirming I haven t broken something by accident is always my first step I plugged in a keyboard an monitor to the machine and watched it boot. Being a server this takes a long time (I guess because at this stage of system initialisation we want to test things sequentially) Watching the system boot I see the usual BIOS/UEFI stages for this machine, followed by the grub menu and the the local screen showed:
            Loading Linux 6.12.100+deb13-amd64 ...
            Loading initial ramdisk ...
Nothing else. That was it. OK that looks like I have a broken system all right, and at very early stage of the boot process process. (2)
Breaking into the grub menu and removing the quiet option yields a little more information (but not much):
            Loading Linux 6.12.100+deb13-amd64  
            Loading initial ramdisk ...
            
            	EFI stub: Loaded initrd from LINUX_EFI_INITRD_MEDIA_GUID d
            	evice path
            		EFI stub: Measured initrd data into PCR 9
and nothing else. (3) Initial debugging (4) Triage Start looking for where the fault first occurred. At this point I needed help, and given that Sledge was visiting I asked if he would sanity check what I was doing. His initial thoughts were that that /boot had run out of space, but replaying my step (3) with him acting as a rubber duck showed that this was something other than PBKAC Sledge had a quick look, then informed me that between kernel images 6.12.88+deb13 and 6.12.100+deb13 Debian stable has only had shipped .90 .94 .95 and .96 kernels. We could easily try them all: OK I now have the first kernel image that doesn t boot on my system, time to raise a bug

Up until now I have been walking to my garage where the server is located and standing in front of a rack
with a monitor and keyboard plugged into the machine. However this machine supports IPMI so I spent a little time getting that up and running so that I can continue from the relative comfort of my desk (with lights, a chair and not needing to hold the keyboard with one hand)
Great I can now grab screen shots from the confort of my desk (unfortunatly they are only screen shots not text files, but at least we can seen the early stage of boot, Post, grub menu and then initramfs before system log happens) (5) Collating information for the initial bug report Sledge had mentioned my problem in irc/#debain-kernal where iam_tj suggested that we try appending
debug earlycon=efifb to the kernal command line. This yielded 15 seconds worth of messages before the system locked up the last few messages being (vmlinuz-6.12.96+deb13-amd64):

[ 14.663477] RCU Tasks: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
[ 14.750474] RCU Tasks Rude: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
[ 14.838024] RCU Tasks Trace: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
[ 14.929752] NR_IRQS: 524544, nr_irqs: 584, preallocated irqs: 16
[ 15.016814] rcu: srcu_init: Setting srcu_struct sizes based on contention.
[ 15.104011] Console: colour dummy device 80 25
[ 15.191236] printk: legacy console [tty0] enabled
[ 15.278249] printk: legacy bootconsole [efifb0] disabled Booting the working kernel with the same kernel options yields the SAME messages with slightly differing times, but then continues to login prompt:

 [   14.697466] RCU Tasks: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
 [   14.784936] RCU Tasks Rude: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
 [   14.872067] RCU Tasks Trace: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
 [   14.964000] NR_IRQS: 524544, nr_irqs: 584, preallocated irqs: 16
 [   15.051482] rcu: srcu_init: Setting srcu_struct sizes based on contention.
 [   15.226079] printk: legacy console [tty0] enabled
 [   15.313751] printk: legacy bootconsole [efifb0] disabled
 [   15.400831] ACPI: Core revision 20240827
 [   15.401415] clocksource: hpet: mask: 0xffffffff max_cycles: 0xffffffff, max_idle_ns: 79635855245 ns
 [   15.401464] APIC: Switch to symmetric I/O mode setup
 
... and so on
iam_tj also suggested adding keep_bootcon with debug earlycon=efifb keep_bootcon on vmlinuz-6.12.96+deb13-amd64:
We get a LOT further and we see a crash / trace-back:
[ 34.285342] BUG: kernel NULL pointer dereference, address: 0000000000000000
I raised bug #1143721 and followed it up with screen captures of the boot sequence (captured from the IPMI client) and files containing the output of dmidecode, lscpu and lspci to kive the kernel team as much information as possible:
[6.12.96+deb13-amd64 debug earlycon=efifb keep_bootcon.tar.gz (application/gzip, attachment)]
[dmidecode.txt (text/plain, attachment)]
[lscpu.txt (text/plain, attachment)]
[lspci.txt (text/plain, attachment)]
(6) Tracking down the bug Git Bisect The problem with this type of bug is that it is hardware (class) specific, whilst the kernel doesn t boot on my system, it clearly has worked on machines used by the kernel team, the Debian test and build infrastructure, (otherwise this kernel would never have been released) and everyone else who has upgraded to the newer kernel before I did (otherwise we would be drowning in fails to boot bug reports). Carnil s excellent response to my bug: Message #15 (and help in IRC) provided me with a detailed step by step guide in how to track down the individual git commit that fails on my system. I had already (with Sledge s suggestion) made a clone of the stable branch, but was struggling to follow the steps in the Debian Linux Kernel Handbook to re-build a duplicate kernel because I didn t understand how to obtain the same configuration that Debian used to build the kernel; Carnil s email provided me the missing steps (Highlighted).
git clone --single-branch -b linux-6.12.y https://git.kernel.org/pub/scm/linux/kernel/git/stable/linux-stable.git
cd linux-stable
git checkout v6.12.95
cp /boot/config-$(uname -r) .config
yes ''   make localmodconfig
make savedefconfig
mv defconfig arch/x86/configs/my_def
test 6.12.96 to ensure this is "bad"
git checkout v6.12.96
make my_defconfig
make -j $(nproc) bindeb-pkg
  install the resulting .deb package and confirm it fails to boot and triggers the NULL pointer dereference.
Right I can now start to Bisect the problem:
git bisect start
git bisect good v6.12.95
git bisect bad v6.12.96
Rather than use the half step point s git bisect suggested I was advised in irc to jump straight to the a given commit that from the git log was suspected as the culprit:

git checkout 977855894bca4b87afa50d21e3f3e85a5a0e901f
build and install .
fails
git bisect bad

git checkout 977855894bca4b87afa50d21e3f3e85a5a0e901f~1 ## ~1 is the commit beforehand
build and install .
fails
git bisect good The entire test tree can shown with git bisect log and this was submitted as an email to the bug report, we have found our smoking gun :-) Finally I would like to thank Carnil, Iam_tj for their time patience and fantastic support in guiding me through finding this regression. Right now kernel bugs are coming in thick and fast with a lot of AI assisted bug hunting, the increased numbers of bugs mean that the kernel team are especially busy. Hopefully our paths will cross and I ll be able to buy you some beers (or whatever) soon. thank you. Sledge also deserves thanks for putting up with me and pointing me in the right direction (as ever). Lucky for me that he lives nearby so I can provide beers on a regular basis :-)

16 August 2026

Vasudev Kamath: Releasing debvulns-exporter and debvulns CLI 0.2.2

I made another minor release with several enhancements: handling non-Debian origin vulnerabilities, improving data caching, and sharing the cache between the debvulns CLI and the exporter. Additionally, there are a few improvements on the dashboard front. Here is a breakdown of what changed.
Handling Vulnerabilities in Non-Debian Origin Packages During the previous release, I noticed that the grafana package which is not in Debian and was installed via an upstream repository was reported as vulnerable with multiple issues. Looking into why this happened, I found that all the CVEs reported in the dashboard were indeed listed on security-tracker.debian.org, but without a fixed version or status description. The logic assumed no fix was available and marked the package as vulnerable on the dashboard.
How Did I Solve This? Google maintains a distributed vulnerability database for open-source projects called osv.dev. I checked the generic vulnerability data for those CVEs on OSV (unbound to any specific distribution) and found that the issues were already fixed in the upstream version I was running. What I needed was a way to differentiate native Debian packages from non-Debian packages, which corresponds to the Origin field in APT metadata.
Pitfall The AI-generated code initially attempted to differentiate package origin using apt_pkg.PackageRecords and its origin field. However, many native Debian packages were incorrectly flagged as non-Debian. On closer inspection, when an upgrade is available for a package, the installed version's origin field can be unset. I had to resolve this by detecting available upgrades and inspecting the candidate version's origin instead, which was implemented in this patch. This solution was proudly crafted by me ;-) (partly because I ran out of API limits and had to wait 6 hours for the next reset).
Caching OSV Data Initially, the AI implemented the exporter to re-download the entire OSV dataset on every run, which was unnecessary. Since vulnerability data does not change rapidly once published, caching it on disk for longer than the standard 24-hour Debian/EPSS cache makes sense. OSV vulnerability data is now cached for 7 days before a refresh is triggered. All cache expiration thresholds remain configurable via CLI flags.
Catch One caveat with this approach: I have not yet verified whether every upstream CVE is tracked on security-tracker.debian.org. In the case of grafana, the entries existed. This feature operates on the assumption that security-tracker.debian.org indexes CVE metadata regardless of whether the package is native to Debian. I plan to re-evaluate this and add fallback handling if that assumption fails.
Unified Cache Directory for CLI and Exporter Another issue was cache segregation: the debvulns CLI utility defaulted to /var/cache/debvulns, while the Prometheus exporter used /var/cache/debvulns-exporter. While harmless when running only one tool, installing both led to duplicated cache storage and redundant network requests. Since the core evaluation logic is identical across both tools, they now share a unified cache directory to eliminate duplicate downloads.
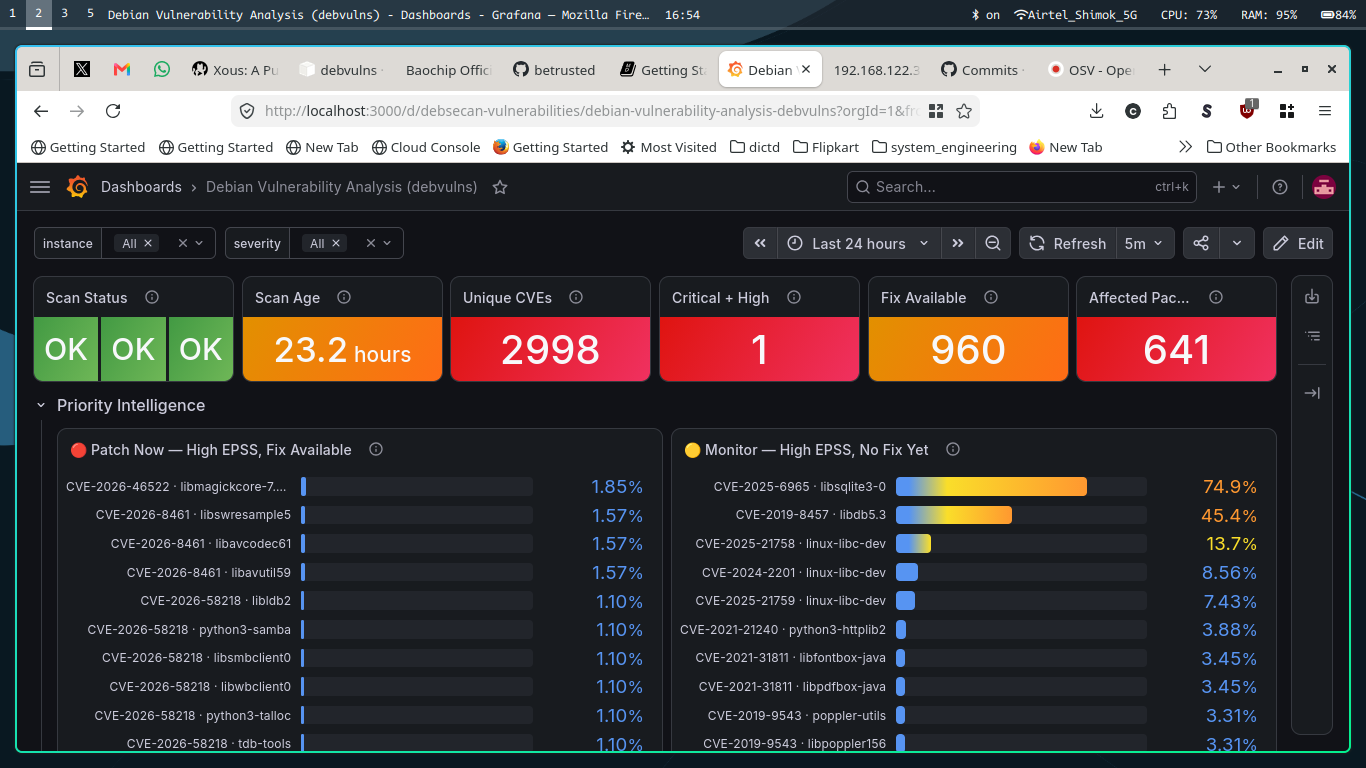
Dashboard Changes During the initial dashboard rollout, my test environment (my laptop alongside Debian 11 and Debian 12 VMs) reported a high aggregated vulnerability count. It was not immediately obvious whether these were distinct vulnerabilities or the same CVEs replicated across all three machines. This mirrors common questions raised during vulnerability reviews:
  • How many unique vulnerabilities are present across the fleet?
  • Which unique packages are affected?
The dashboard has been redesigned to surface unique vulnerability counts alongside affected package lists. The updated dashboard is shown below:
What's Next? A few planned items remain to make debvulns a comprehensive vulnerability reporting toolkit for Debian systems:
  1. Kernel Vulnerability Handling: Currently, installing a patched kernel marks the vulnerability as resolved, even if the system has not rebooted into it. The system remains exposed while the vulnerable kernel is executing in memory. Factoring in running kernel versions is crucial.
  2. Reboot and Service Restart Tracking: Similar to kernel upgrades requiring a reboot, userland library and binary fixes require running services to be restarted. This is typically detected via needrestart. Integrating this behavior directly into debvulns will provide complete visibility in a single dashboard metric.
  3. Debian Packaging: Once the above features are stable, the final step is packaging debvulns for Debian so it can be installed directly from the archive.
Until then, happy hacking.

Benjamin Mako Hill: Sad Story

Picture of a box in a fireplace saying:

Not a screenshot of despair. But only because it s not a screenshot.

15 August 2026

Russell Coker: AMD Video Drivers, LLMs, and Debian Kernels

The AMD GPU Problem For a while I ve been having issues with AMD GPUs, video locking up periodically. I blogged about this late last year but I first had noticeable problems early last year [1]. The problems hadn t only concerned my workstation but also my home server which is also used as a workstation. I ve recently upgraded my machines to Debian/Testing, my home server has been generally OK but my workstation has been crashing a lot. Every second day when on kernel 7.1.6 and then when on 7.1.7 it crashed at least once a day. The AMD GPUs I have are [AMD/ATI] Baffin [Radeon RX 460/560D / Pro 450/455/460/555/555X/560/560X] (rev e5) in my main desktop workstation, [AMD/ATI] Lexa [Radeon 540X/550X/630 / RX 640 / E9171 MCM] (rev c1) in my build server, and [AMD/ATI] Baffin [Radeon RX 460/560D / Pro 450/455/460/555/555X/560/560X] (rev cf) in my home server. They aren t new GPUs, but also aren t really old and they all support 4K and better resolution. Chat GPT Was Useful When I googled the errors I was seeing I found nothing useful. On the suggestion of a friend I tried asking ChatGPT. Generally I don t recommend asking LLMs about such things, but it can be a last resort as long as you know what you are doing. ChatGPT asked me to run a number of commands to get information for it to make more informed decisions. I know that the output of lspci and similar commands isn t a risk, but a novice could be tricked into running commands that expose sensitive data. ChatGPT did give me some useful information, not a solution but an indication that the problem was due to driver bugs. Upgrading to Experimental Debian/Experimental is for packages that are expected to have problems and generally aren t recommended even for the people who usually use Debian/Unstable. It s commonly used for packages that are needed to develop other packages, EG new libraries that aren t fully usable but which are needed to package newer versions of applications. I upgraded my workstation to the Debian/Experimental kernel 7.2~rc7-1~exp1 after having tried every other convenient option. Generally I wouldn t recommend that anyone run an Experimental kernel without a really good reason, but crashing more than once a day is a fairly good reason. That kernel has now given me over 4 days of uptime on a system that previously wouldn t last a day. I installed it on my dual-socket build server that has an old AMD GPU in it for test purposes and that also hasn t crashed since. I installed it on my ML test machine which has an Intel B580 Battlemage GPU with 16G of VRAM and was repeatedly getting a kernel panic related to the GPU a few seconds after boot and now it also works correctly. It seems that the 7.1.x kernels have bugs in the AMD video drivers and in some part of the code that affects Intel video drivers and that the bugs in question are fixed in the tree that will become 7.2. I would not recommend anyone who has a 7.1.x kernel working fine for them try 7.2 RC kernels at this time, but anyone who has GPU related problems (particularly Intel and AMD GPUs) should definitely test it out. I also don t recommend upgrading any system with an AMD GPU to Debian/Testing or Debian/Unstable at this time unless you are also prepared to install an Experimental kernel if it becomes necessary. There are a several kernel log dumps related to this after the break (which won t be in RSS feeds). This is mainly for Google so that other people who have such issues can get more useful results out of Google searches than I got. Future Support Options Separate from the issue of whether commercial LLMs like ChatGPT can be useful for solving technical problems there is the issue of whether they are desirable. I think that we really don t want people solving problems in FOSS systems with closed-source LLMs. This leads to loss of privacy, loss of the control users deserve to have over their own systems, and an implied promotion of non-fee software. I think that the ideal would be to have a cross distribution effort to generate training data for a support LLM system which can then be further trained by each distribution for a greater emphasis on distribution specific issues. Errors on AMD GPUs
2026-08-09T23:03:06.004792+10:00 xev kernel: amdgpu 0000:02:00.0: GPU fault detected: 147 0x00024802
2026-08-09T23:03:06.004792+10:00 xev kernel: amdgpu 0000:02:00.0: Process kscreenlocker_g pid 42037 thread kscreenloc:cs0 pid 42044
2026-08-09T23:03:06.004793+10:00 xev kernel: amdgpu 0000:02:00.0: VM_CONTEXT1_PROTECTION_FAULT_ADDR 0x00000800
2026-08-09T23:03:06.004794+10:00 xev kernel: amdgpu 0000:02:00.0: VM_CONTEXT1_PROTECTION_FAULT_STATUS 0x0F048002
2026-08-09T23:03:06.004795+10:00 xev kernel: amdgpu 0000:02:00.0: VM fault (0x02, vmid 7, pasid 130) at page 2048, write from 'TC0' (0x54433000) (72)
2026-08-09T23:03:06.008762+10:00 xev kernel: amdgpu 0000:02:00.0: GPU fault detected: 147 0x00004802
2026-08-09T23:03:06.008768+10:00 xev kernel: amdgpu 0000:02:00.0: Process kscreenlocker_g pid 42037 thread kscreenloc:cs0 pid 42044
2026-08-04T01:13:37.505839+10:00 xev kernel: ------------[ cut here ]------------ 
2026-08-04T01:13:37.505859+10:00 xev kernel: amdgpu 0000:02:00.0: [drm] drm_WARN_ON_ONCE(cur_vblank != vblank->last) 
2026-08-04T01:13:37.505862+10:00 xev kernel: WARNING: CPU: 6 PID: 210534 at drivers/gpu/drm/drm_vblank.c:362 drm_update_vblank_count+0x2f1/0x3c0 [drm] 
2026-08-04T01:13:37.505866+10:00 xev kernel: snd_intel_dspcfg wmi_bmof rc_core snd_intel_sdw_acpi drm_ttm_helper uas realtek snd_usbmidi_lib snd_hda_codec ttm mdio_devres snd_hda_core snd_seq_midi drm_kms_helper usb_storage mc snd_hwdep libphy snd_seq_midi_event intel_uncore snd_pcm_oss i2c_algo_bit serio_raw snd_rawmidi pcspkr snd_mixer_oss i2c_i801 video snd_seq snd_pcm i2c_smbus lpc_ich snd_seq_device mei_me e1000e snd_timer mei snd tpm_infineon soundcore joydev bnx2 wmi button nfsd auth_rpcgss nfs_acl lockd grace sunrpc coretemp br_netfilter bridge stp llc sg ghash_clmulni_intel loop msr i2c_dev drm efi_pstore configfs nfnetlink ip_tables x_tables autofs4 btrfs blake2b_generic dm_crypt dm_mod raid10 raid456 async_raid6_recov async_memcpy async_pq async_xor async_tx libcrc32c xor raid6_pq raid1 raid0 md_mod ext4 crc16 mbcache jbd2 crc32c_generic virtio_blk evdev hid_generic usbhid hid sd_mod xhci_pci xhci_hcd ahci ehci_pci ehci_hcd libahci crc32c_intel libata usbcore aesni_intel nvme psmouse scsi_mod gf128mul crypto_simd nvme_core cryptd 
2026-08-04T01:13:37.505879+10:00 xev kernel: nvme_auth scsi_common usb_common efivarfs 
2026-08-04T01:13:37.505880+10:00 xev kernel: CPU: 6 UID: 1008 PID: 210534 Comm: sshd-session Tainted: G D 6.12.88+deb13-amd64 #1 Debian 6.12.88-1 
2026-08-04T01:13:37.505881+10:00 xev kernel: Tainted: [D]=DIE 
2026-08-04T01:13:37.505883+10:00 xev kernel: Hardware name: Hewlett-Packard HP Z640 Workstation/212A, BIOS M60 v02.61 03/23/2023 
2026-08-04T01:13:37.505884+10:00 xev kernel: RIP: 0010:drm_update_vblank_count+0x2f1/0x3c0 [drm] 
2026-08-04T01:13:37.505885+10:00 xev kernel: Code: 48 8b 5f 50 48 85 db 75 03 48 8b 1f e8 68 eb 2b cf 48 c7 c1 70 3e cb c0 48 89 da 48 c7 c7 f9 6f cb c0 48 89 c6 e8 af d7 a6 ce <0f> 0b e9 4b fe ff ff 48 8b 4c 24 18 e9 31 fe ff ff 31 f6 48 85 db 
2026-08-04T01:13:37.505887+10:00 xev kernel: RSP: 0000:ffffd3cc8681fca0 EFLAGS: 00010082 
2026-08-04T01:13:37.505888+10:00 xev kernel: RAX: 0000000000000000 RBX: ffff8c6b42b13710 RCX: 0000000000000027 
2026-08-04T01:13:37.505889+10:00 xev kernel: RDX: ffff8c89ef521788 RSI: 0000000000000001 RDI: ffff8c89ef521780 
2026-08-04T01:13:37.505890+10:00 xev kernel: RBP: 0000000000000000 R08: 0000000000000000 R09: ffffd3cc8681fb20 
2026-08-04T01:13:37.505891+10:00 xev kernel: R10: ffff8c8a6fef3628 R11: 0000000000000003 R12: 0000000000000000 
2026-08-04T01:13:37.505892+10:00 xev kernel: R13: ffff8c6c07853828 R14: 0000000000000003 R15: 0000000000000000 
2026-08-04T01:13:37.505893+10:00 xev kernel: FS: 00007ffaf2fd5880(0000) GS:ffff8c89ef500000(0000) knlGS:0000000000000000 
2026-08-04T01:13:37.505895+10:00 xev kernel: CS: 0010 DS: 0000 ES: 0000 CR0: 0000000080050033 
2026-08-04T01:13:37.505896+10:00 xev kernel: CR2: 00007fb1718c8000 CR3: 000000074521a004 CR4: 00000000003706f0 
2026-08-04T01:13:37.505897+10:00 xev kernel: Call Trace: 
2026-08-04T01:13:37.505898+10:00 xev kernel:  
2026-08-04T01:13:37.505899+10:00 xev kernel: drm_crtc_accurate_vblank_count+0x41/0xc0 [drm] 
2026-08-04T01:13:37.505900+10:00 xev kernel: dm_pflip_high_irq+0x155/0x330 [amdgpu] 
2026-08-04T01:13:37.505901+10:00 xev kernel: amdgpu_dm_irq_handler+0x85/0x1f0 [amdgpu] 
2026-08-04T01:13:37.505902+10:00 xev kernel: amdgpu_irq_dispatch+0xd2/0x230 [amdgpu] 
2026-08-04T01:13:37.505903+10:00 xev kernel: amdgpu_ih_process+0x84/0x100 [amdgpu] 
2026-08-04T01:13:37.505904+10:00 xev kernel: amdgpu_irq_handler+0x23/0x60 [amdgpu] 
2026-08-04T01:13:37.505905+10:00 xev kernel: __handle_irq_event_percpu+0x4a/0x190
2026-08-04T01:13:37.505907+10:00 xev kernel: handle_irq_event+0x38/0x80 
2026-08-04T01:13:37.505908+10:00 xev kernel: handle_edge_irq+0x8b/0x230 
2026-08-04T01:13:37.505909+10:00 xev kernel: __common_interrupt+0x45/0xe0 
2026-08-04T01:13:37.505910+10:00 xev kernel: common_interrupt+0x42/0xa0 
2026-08-04T01:13:37.505911+10:00 xev kernel: asm_common_interrupt+0x26/0x40 
2026-08-04T01:13:37.505912+10:00 xev kernel: RIP: 0033:0x7ffaf3c5fd7b 
2026-08-04T01:13:37.505913+10:00 xev kernel: Code: 70 c7 00 66 0f 6e f8 c1 ef 02 66 0f 70 f7 e0 83 c7 01 66 0f ef ff 66 0f fa f2 0f 1f 44 00 00 f3 0f 7e 01 66 0f 6f ce 83 c6 01 <48> 83 e9 08 f2 0f 70 c0 1b 66 0f 6f e0 66 0f 6f e8 66 41 0f f9 c0 
2026-08-04T01:13:37.505915+10:00 xev kernel: RSP: 002b:00007fff86a5e0e0 EFLAGS: 00000202 
2026-08-04T01:13:37.505916+10:00 xev kernel: RAX: 0000000000008000 RBX: 0000562614a04050 RCX: 0000562614982ed8 
2026-08-04T01:13:37.505946+10:00 xev kernel: RDX: 0000000000007fe2 RSI: 0000000000000fad RDI: 0000000000002000 
2026-08-04T01:13:37.505948+10:00 xev kernel: RBP: 0000000000000000 R08: 000056261498ac40 R09: 0000000000008000 
2026-08-04T01:13:37.505949+10:00 xev kernel: R10: 0000000000000066 R11: 0000000000007fe1 R12: 0000000000007efa
2026-08-04T01:13:37.505950+10:00 xev kernel: R13: 0000000000008000 R14: 0000000000008000 R15: 000000000000ffe0 
2026-08-04T01:13:37.505951+10:00 xev kernel:  
2026-08-04T01:13:37.505953+10:00 xev kernel: ---[ end trace 0000000000000000 ]--- 
2026-08-04T01:55:40.844110+10:00 xev kernel: pcieport 0000:00:03.3: AER: Multiple Correctable error message received from 0000:00:03.3 
2026-08-04T01:55:40.844130+10:00 xev kernel: pcieport 0000:00:03.3: PCIe Bus Error: severity=Correctable, type=Data Link Layer, (Receiver ID) 
2026-08-04T01:55:40.844132+10:00 xev kernel: pcieport 0000:00:03.3: device [8086:6f0b] error status/mask=00000040/00002000 
2026-08-04T01:55:40.844134+10:00 xev kernel: pcieport 0000:00:03.3: [ 6] BadTLP
2026-08-11T09:33:33.473855+10:00 xev kernel: amdgpu 0000:02:00.0: GPU fault detected: 147 0x00024802
2026-08-11T09:33:33.473871+10:00 xev kernel: amdgpu 0000:02:00.0: Process kscreenlocker_g pid 150905 thread kscreenloc:cs0 pid 150912
2026-08-11T09:33:33.473871+10:00 xev kernel: amdgpu 0000:02:00.0: VM_CONTEXT1_PROTECTION_FAULT_ADDR 0x00000800
2026-08-11T09:33:33.473873+10:00 xev kernel: amdgpu 0000:02:00.0: VM_CONTEXT1_PROTECTION_FAULT_STATUS 0x0F048002
2026-08-11T09:33:33.473873+10:00 xev kernel: amdgpu 0000:02:00.0: VM fault (0x02, vmid 7, pasid 63) at page 2048, write from 'TC0' (0x54433000) (72)
2026-08-11T09:33:33.473874+10:00 xev kernel: amdgpu 0000:02:00.0: GPU fault detected: 147 0x00004802
2026-08-11T09:33:33.473874+10:00 xev kernel: amdgpu 0000:02:00.0: Process kscreenlocker_g pid 150905 thread kscreenloc:cs0 pid 150912
2026-08-11T09:33:33.473875+10:00 xev kernel: amdgpu 0000:02:00.0: VM_CONTEXT1_PROTECTION_FAULT_ADDR 0x00000800
2026-08-11T09:33:33.473876+10:00 xev kernel: amdgpu 0000:02:00.0: VM_CONTEXT1_PROTECTION_FAULT_STATUS 0x0E048002
2026-08-11T09:33:33.473876+10:00 xev kernel: amdgpu 0000:02:00.0: VM fault (0x02, vmid 7, pasid 63) at page 2048, read from 'TC0' (0x54433000) (72)
2026-08-11T09:33:35.481863+10:00 xev kernel: amdgpu 0000:02:00.0: Dumping IP State
2026-08-11T09:33:35.481875+10:00 xev kernel: amdgpu 0000:02:00.0: Dumping IP State Completed
2026-08-11T09:33:35.481875+10:00 xev kernel: amdgpu 0000:02:00.0: [drm] AMDGPU device coredump file has been created
2026-08-11T09:33:35.481876+10:00 xev kernel: amdgpu 0000:02:00.0: [drm] Check your /sys/class/drm/card0/device/devcoredump/data
2026-08-11T09:33:35.481877+10:00 xev kernel: amdgpu 0000:02:00.0: GPU fault detected: 146 0x0110040c
2026-08-11T09:33:35.481877+10:00 xev kernel: amdgpu 0000:02:00.0: Process kscreenlocker_g pid 150905 thread kscreenloc:cs0 pid 150912
2026-08-11T09:33:35.481878+10:00 xev kernel: amdgpu 0000:02:00.0: VM_CONTEXT1_PROTECTION_FAULT_ADDR 0x00000022
2026-08-11T09:33:35.481879+10:00 xev kernel: amdgpu 0000:02:00.0: VM_CONTEXT1_PROTECTION_FAULT_STATUS 0x0E00400C
2026-08-11T09:33:35.481879+10:00 xev kernel: amdgpu 0000:02:00.0: VM fault (0x0c, vmid 7, pasid 63) at page 34, read from 'TC3' (0x54433300) (4)
2026-08-11T09:33:35.489845+10:00 xev kernel: amdgpu 0000:02:00.0: ring gfx timeout, signaled seq=5123619, emitted seq=5123621
2026-08-11T09:33:35.489853+10:00 xev kernel: amdgpu 0000:02:00.0: Process kscreenlocker_g pid 150905 thread kscreenloc:cs0 pid 150912
2026-08-11T09:33:35.489854+10:00 xev kernel: amdgpu 0000:02:00.0: GPU reset begin!. Source: 1
2026-08-11T09:33:35.493839+10:00 xev kernel: amdgpu 0000:02:00.0: [drm] ERROR Failed to initialize parser -125!
2026-08-11T09:33:35.737848+10:00 xev kernel: amdgpu: cp is busy, skip halt cp
2026-08-11T09:33:35.897842+10:00 xev kernel: amdgpu: rlc is busy, skip halt rlc
2026-08-11T09:33:35.897852+10:00 xev kernel: amdgpu 0000:02:00.0: BACO reset
2026-08-11T09:33:36.485849+10:00 xev kernel: amdgpu 0000:02:00.0: GPU reset succeeded, trying to resume
2026-08-11T09:33:36.485859+10:00 xev kernel: amdgpu 0000:02:00.0: [drm] PCIE GART of 256M enabled (table at 0x000000F402000000).
2026-08-11T09:33:36.485860+10:00 xev kernel: amdgpu 0000:02:00.0: VRAM is lost due to GPU reset!
Errors on Battlemage
Aug 11 17:01:47 ami kernel: ------------[ cut here ]------------
Aug 11 17:01:47 ami kernel: xe 0000:23:00.0: [drm] DMC 1 mmio[0]/0x5f074 incorrect (expected 0x96fc0, current 0x0)
Aug 11 17:01:47 ami kernel: WARNING: drivers/gpu/drm/i915/display/intel_dmc.c:696 at assert_dmc_loaded+0x275/0x430 [xe], CPU#0: kworker/0:3/215
Aug 11 17:01:47 ami kernel: Modules linked in: intel_rapl_msr intel_rapl_common intel_uncore_frequency intel_uncore_frequency_common xe(+) skx_edac snd_h>
Aug 11 17:01:47 ami kernel:  msr i2c_dev configfs efi_pstore efivarfs autofs4 btrfs libblake2b raid6_pq xor mpt3sas raid_class scsi_transport_sas megarai>
Aug 11 17:01:47 ami kernel: CPU: 0 UID: 0 PID: 215 Comm: kworker/0:3 Not tainted 7.1.7+deb14-amd64 #1 PREEMPT(lazy)  Debian 7.1.7-1 
Aug 11 17:01:47 ami kernel: Hardware name: HP HP Z4 G4 Workstation/81C5, BIOS P61 v03.00 04/15/2026
Aug 11 17:01:47 ami kernel: Workqueue: sync_wq local_pci_probe_callback
Aug 11 17:01:47 ami kernel: RIP: 0010:assert_dmc_loaded+0x291/0x430 [xe]
Aug 11 17:01:47 ami kernel: Code: 24 10 e8 f2 e5 a3 ce 48 8d 3d bb 85 0d 00 8b 54 24 0c 45 89 e9 45 89 e0 48 89 c6 52 8b 4c 24 2c 51 8b 4c 24 30 48 8b 54>
Aug 11 17:01:47 ami kernel: RSP: 0018:ffffd27ac0b87b80 EFLAGS: 00010282
Aug 11 17:01:47 ami kernel: RAX: ffffffffc1743dfd RBX: ffff8c5b80e54000 RCX: 0000000000000001
Aug 11 17:01:47 ami kernel: RDX: ffff8c5b81df5a10 RSI: ffffffffc1743dfd RDI: ffffffffc1605860
Aug 11 17:01:47 ami kernel: RBP: ffff8c5b86955000 R08: 0000000000000000 R09: 000000000005f074
Aug 11 17:01:47 ami kernel: R10: 0000000000000000 R11: 0000000000091050 R12: 0000000000000000
Aug 11 17:01:47 ami kernel: R13: 000000000005f074 R14: 0000000000000001 R15: 0000000000000000
Aug 11 17:01:47 ami kernel: FS:  0000000000000000(0000) GS:ffff8c673e172000(0000) knlGS:0000000000000000
Aug 11 17:01:47 ami kernel: CS:  0010 DS: 0000 ES: 0000 CR0: 0000000080050033
Aug 11 17:01:47 ami kernel: CR2: 00007ffed1fdcd00 CR3: 0000000ae942a003 CR4: 00000000003706f0
Aug 11 17:01:47 ami kernel: Call Trace:
Aug 11 17:01:47 ami kernel:  
Aug 11 17:01:47 ami kernel:  intel_dmc_enable_pipe+0xe4/0x290 [xe]
Aug 11 17:01:47 ami kernel:  ? drm_crtc_vblank_reset+0x4d/0x120 [drm]
Aug 11 17:01:47 ami kernel:  intel_modeset_setup_hw_state+0xb50/0x1e10 [xe]
Aug 11 17:01:47 ami kernel:  ? intel_display_driver_probe_nogem+0x138/0x1a0 [xe]
Aug 11 17:01:47 ami kernel:  intel_display_driver_probe_nogem+0x138/0x1a0 [xe]
Aug 11 17:01:47 ami kernel:  xe_display_init_early+0xb2/0x140 [xe]
Aug 11 17:01:47 ami kernel:  xe_device_probe+0x3c8/0xb50 [xe]
Aug 11 17:01:47 ami kernel:  ? xe_pm_init_early+0x152/0x160 [xe]
Aug 11 17:01:47 ami kernel:  xe_pci_probe+0xc26/0x1150 [xe]
Aug 11 17:01:47 ami kernel:  local_pci_probe+0x3e/0x90
Aug 11 17:01:47 ami kernel:  local_pci_probe_callback+0x16/0x20
Aug 11 17:01:47 ami kernel:  process_one_work+0x19d/0x3a0
Aug 11 17:01:47 ami kernel:  worker_thread+0x1af/0x320
Aug 11 17:01:47 ami kernel:  ? __pfx_worker_thread+0x10/0x10
Aug 11 17:01:47 ami kernel:  kthread+0xe3/0x120
Aug 11 17:01:47 ami kernel:  ? __pfx_kthread+0x10/0x10
Aug 11 17:01:47 ami kernel:  ret_from_fork+0x2b2/0x340
Aug 11 17:01:47 ami kernel:  ? __pfx_kthread+0x10/0x10
Aug 11 17:01:47 ami kernel:  ret_from_fork_asm+0x1a/0x30
Aug 11 17:01:47 ami kernel:  
Aug 11 17:01:47 ami kernel: ---[ end trace 0000000000000000 ]---

13 August 2026

Jonathan Dowland: DIY skate punch-out

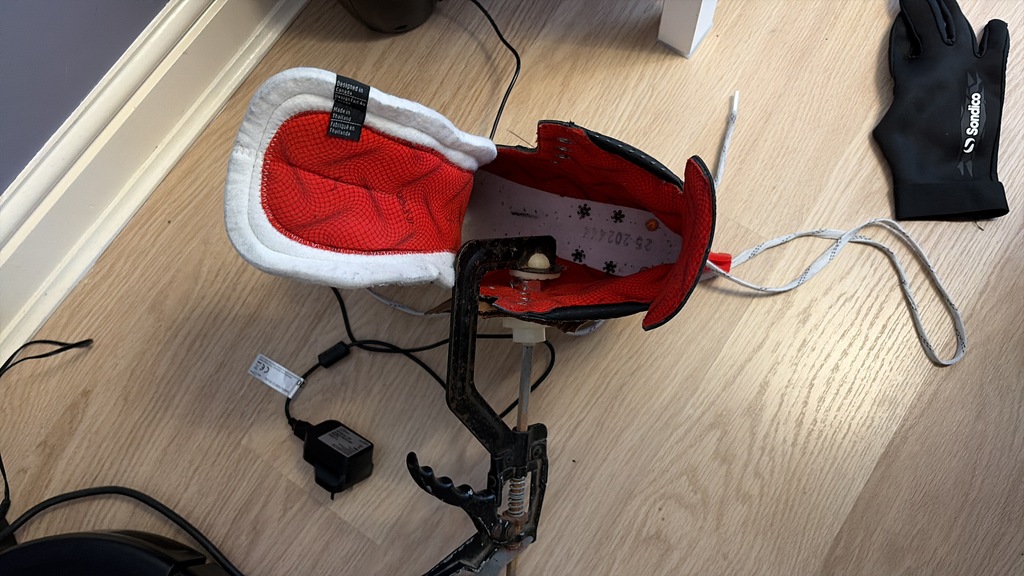
The punch set-up
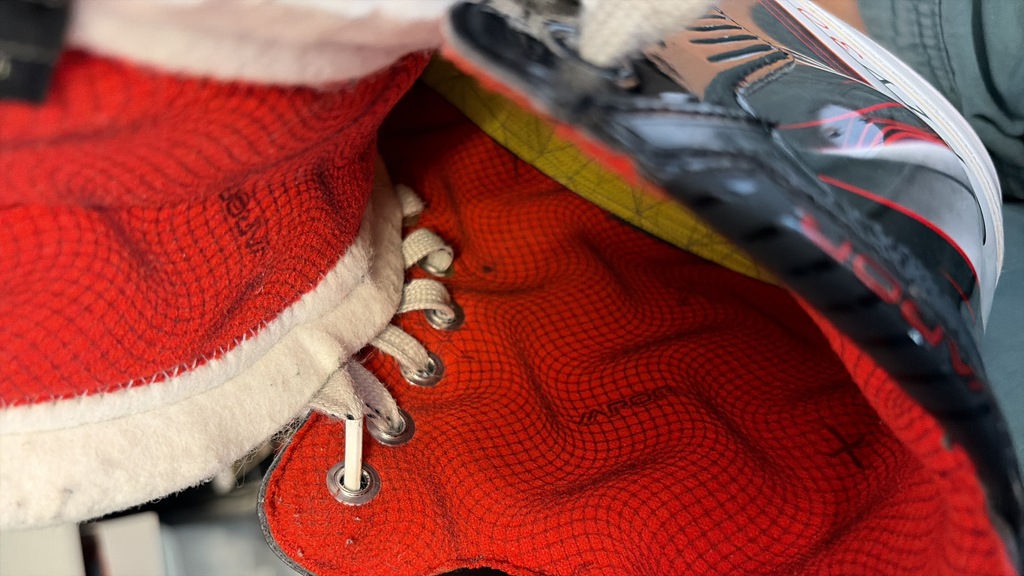
the punched boot
Since I wrote about my fly30 ice skates, I'd continued to battle pain around the navicular bone in my feet. The action that seems to have finally fixed it was to perform a "punch out": a very localized remoulding of the area of the boot that presses against the sore area. I basically followed the process from this helpful YouTube video. I narrowed down the exact spot by borrowing some lipstick and transferring it from my navicular bone to the boot lining, then making that more permanent with a sharpie. My punch was a spare part from a radiator valve which I packed with US cents (I couldn't fit any UK coins in). For the receiving-end, I tried another part from the radiator valve but I think it wasn't sufficiently larger than the punch to work well, so I swapped that out for a spoon.
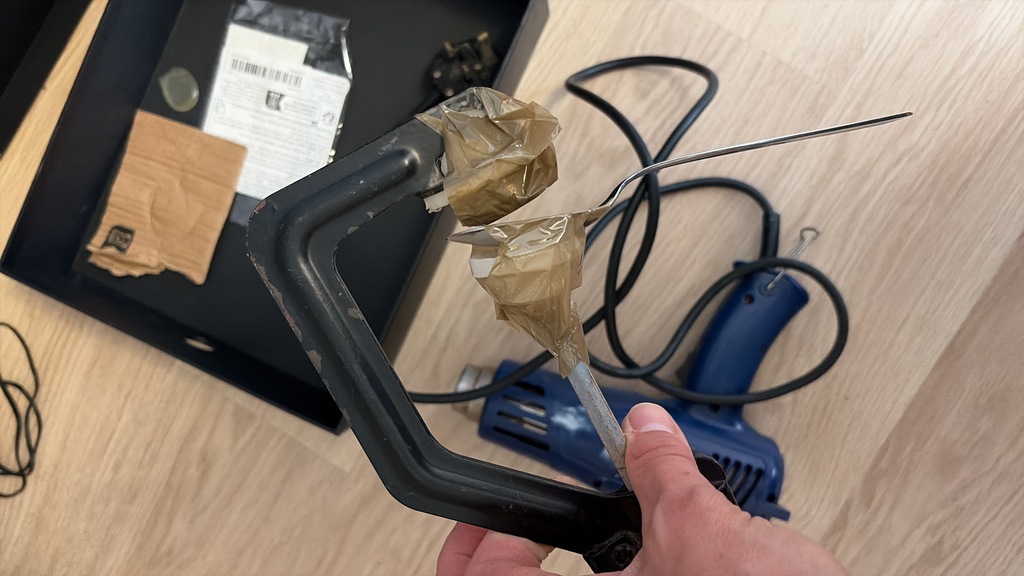
take 2 take 2
I didn't have a temperature sensor I could use and I used a heat gun rather than a hairdryer, so I YOLO'd it a little. Some of the wrap on one of my boots is now distorted from where I didn't move the heat gun enough. It only took a minute or two to get the boot hot enough to be flexible. I set a 15 minute timer once the clamp was in place. I've only skated one session since I did this but the pain seems to have gone! It's remarkably freeing to be skating without constantly trying to manage pain. Now I can focus on technique.

12 August 2026

Reproducible Builds: Reproducible Builds summit 2026 to take place in Gothenburg

This event is happening soon see below for registration instructions!

We are extremely pleased to announce the upcoming Reproducible Builds summit, which will take place from September 22nd 24th 2026 in the city of Gothenburg, Sweden. This year, we are thrilled to host the tenth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Vienna (2025), Hamburg (2023 2024), Venice (2022), Marrakesh (2019), Paris (2018), Berlin (2017), Berlin (2016) and Athens (2015). If you re excited about joining us this year, please make sure to read the event page which has more details about the event and location. As in previous years, we will be sending invitations to all those who attended our previous summit events or expressed interest to do so. However, even if you do not receive a personal invitation, please do email the organizers and we will find a way to accommodate you.

About the event The Reproducible Builds Summit is a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving.

Schedule Although the exact content of the meeting will be shaped by the participants, the main goals will include:
  • Update & exchange about the status of reproducible builds in various projects.
  • Improve collaboration both between and inside projects.
  • Expand the scope and reach of reproducible builds to more projects.
  • Work together and hack on solutions.
  • Establish space for more strategic and long-term thinking than is possible in virtual channels.
  • Brainstorm designs on tools enabling users to get the most benefits from reproducible builds.
  • Discuss how reproducible builds will be usable and meaningful to users and developers alike.
Logs and minutes will be published after the meeting.

Location & date

Registration instructions Please reach out if you d like to participate in hopefully interesting, inspiring and intense technical sessions about reproducible builds and beyond! We look forward to what we anticipate to be yet another extraordinary event!

11 August 2026

Colin Watson: Free software activity in July 2026

About 95% of my Debian contributions this month were sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH Now that Ubuntu 26.04 LTS has been released, I ve been getting back to the GSS-API key exchange package split in our OpenSSH packaging. Once I started testing my draft openssh-gssapi source package, I realized that I needed to make some changes in the main openssh source package first in order to support it. The dependency from openssh-server to openssh-client was awkward, as was the (related) fact that openssh-client contained shared documentation for other OpenSSH binary packages. After some thought, I created a new openssh-common binary package, moved shared documentation and the ssh-keygen program to that, and dropped dependencies on openssh-client which were no longer necessary (fixing #699473 and #1070098 in the process). This caused a couple of regressions (#1141420 and #1141550) that I had to fix, and more subtly it also caused a number of autopkgtest regressions in other packages because openssh-client is no longer in base images as a result of a dependency from openssh-server. I believe I have fixes for all of these either pending review or merged (one of which I did in August rather than July): I upgraded from 10.3p1 to 10.4p1, and in the process contributed a GSS-API option handling fix upstream. I made openssh-ssh1 s package description more accurately describe the package, thanks to suggestions from Matthias Lang. Installer team With support from a Freexian customer, I reviewed, tested, edited, and merged a patch to add VLAN support. I described the details of what I did in a comment. This has been vaguely on my to-do list since, er, about 2014, so it was very satisfying to get it sorted out. Python packaging New upstream versions: Other build/test failures: I fixed some other bugs: I adopted transaction for the Python team. I attended the Python BoF at DebConf remotely, although a badly-timed fibre outage in the village I live in really didn t help. Code reviews Other bits and pieces Dan Poltawski pointed out in a Fediverse post that the project history didn t list Sruthi as the current DPL. I fixed that, although it doesn t look as though the fix is in the published version yet. I upgraded yubihsm-shell to 2.8.0.

Freexian Collaborators: Debian Contributions: DebConf 26 organization, d-i VLAN support and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-07 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 26 organization, by Lucas Kanashiro, Santiago Ruano Rinc n, Stefano Rivera and Antonio Terceiro The 27th Annual Debian Conference was held in Santa Fe, Argentina, and several Freexian fellows were quite busy by being involved in the organization team.
  • Santiago continued helping with duties related to the local team, e.g. preparing or proof-reading some announcements, reviewing the proposed food and the menus for the different diet required.
  • During the conference, Kanashiro and Santiago also carried over tasks related to the content of the conference, including updating the schedule as it became necessary during the event.
  • Stefano worked within the core video team, setting up equipment in talk rooms and coordinating the live video streaming. Stefano also supported the front desk and local organisers as a website developer and conference book-keeper.
  • Antonio kept working on website maintenance, specially in support of the content team. During DebConf he also ran a hands-on workshop to help interested contributors get started with developing the DebConf websites.

d-i VLAN support, by Colin Watson In environments that use IEEE 802.1Q VLANs, some hosts (such as routers attached to trunk ports) may need to apply VLAN tags themselves rather than relying on switches to do so. There has been a long-running request to add support for these to the Debian installer with a proposed patch set put together by several people over the years, and a Freexian customer asked us to help get this over the line. Colin reviewed the latest version of the patch set, applied a number of corrections, added Netplan support, spent some time testing a variety of possible paths through the installer, and landed this. There s also now documentation for this in the next version of the installation guide.

Miscellaneous contributions
  • Carles wrote documentation for installing Mailman3 and migrating from Mailman2. Added it into Mailman3 upstream documentation.
  • Carles, using po-debconf-manager: reviewed 2 packages, submitted 2 packages
  • Carles organized Catalan translation update. Created a Debian Wiki page to have an overview of the work / coordination during next months. Reviewed and submitted some pages.
  • Carles improved the documentation for building the debian.org Web in MR 1154 and MR 1557. Fixed debian-reference documentation. Added sections on Mutt Wiki page (handling of mailto, viewing HTML parts web browser), update and improve bash-completion Wiki page. Added a troubleshooting section in Signal Wiki.
  • Thorsten did another upload of hplip to fix RC bugs. He also spent some time taking care of older bugs. Most of the time such bugs had been fixed in a previous upload but haven t been closed in the BTS. He also uploaded a new upstream version of foomatic-db. Last but not least, he gave some user support with the package epson-inkjet-printer-escpr. There seems to be a new software available for Epson printers. Unfortunately the license is not compatible with DFSG and so this software will never make it into Debian.
  • During DebCamp 26, the Golang team had a dedicated Sprint to transition the Golang toolchain (namely on dh-golang) to make builds aware of the module defined upstream with the aim of solving important issues. To help in these efforts, Santiago made changes in the Salsa CI pipeline and documented on how to use it to check if a package requires adjustments after the toolchain update.
  • Santiago continued co-mentoring Aryan Karamtoth on the Linux livepatching project, specifically providing feedback about the implementation of dlp-tools.
  • Stefano reviewed and merged a migration of Debian reimbursements from wkhtmltopdf to weasyprint, unblocking an upgrade to Debian trixie.
  • Stefano s cPython upstream merge request adding multiarch tags to stable ABI extensions was finally merged.
  • Stefano iterated on his upstream cPython merge request to add CI coverage for Debian s multi-arch expectations.
  • Stefano uploaded Python 3.15.0 beta 4 to Debian experimental.
  • Stefano uploaded Python 3.13 to trixie, fixing a regression in a previous trixie point update he made.
  • Helmut continued to report undeclared file conflicts.
  • Helmut sent patches for three cross build failures.
  • Helmut proposed a MR to port piuparts to pathlib.
  • Antonio has done quite some work on Debian CI, including rebuilding the Debian CI armhf/armel worker VMs, and releasing debci 4.2, implementing a backup scheme, and several improvements to the codebase such as improving the incus-lxc backend in preparation for switching to the upcoming switch to using it by default as announced in the latest bits from the ci.debian.net operators.
  • Emilio helped with transitions, particularly with Python 3.14 as default and Perl 5.42. During the Perl transition, an issue was identified with how britney schedules autopkgtests for binNMUs, and that testing was reverted for the time being.
  • Colin restructured openssh-* binary packages to better support the upcoming GSS-API package split. This caused several autopkgtest regressions in other packages because openssh-server no longer depends on openssh-client, all of which have fixes either pending review or merged now.
  • Lucas started a discussion around the creation of a Debian packaging video course for newcomers in the context of the Outreach team.
  • Lucas reviewed some contributions to ruby3.4 and provided feedback.
  • Anupa worked with Jean-Pierre Giraud on the point release announcements for Debian 13.6 and Debian 12.15.
  • Anupa joined Jean-Pierre Giraud to prepare the Micronews for DebConf 26 press coverage.

9 August 2026

Elana Hashman: Managing virtualenvs with a little bash

When you need to install something directly from PyPI, Python virtualenvs have been my go-to for over a decade. A quick virtualenv intro Most of my readers are probably already familiar with virtualenvs, but for completeness, I'll give you a brief introduction. A virtualenv (short for "virtual environment") is an isolated distribution of Python packages, where you can independently install packages without disturbing your system packages or other virtualenvs. You can set one up like this, assuming you are using Python 3.3 or higher:
python3 -m venv ~/.venv/my-virtualenv
The directory specified here is just a convention. I keep all my virtualenvs in the .venv folder in my home directory, but you can pick whatever location you like. To use the virtualenv, you must activate it:
source ~/.venv/my-virtualenv/bin/activate
This activation script is a special shell script that configures your current shell, pointing at all the right paths in order to use the virtual environment. source runs this script in your current shell session to set it up. You will notice that this adds (my-virtualenv) to the beginning of your shell prompt, reminding you that the "my-virtualenv" virtualenv is active. Now when you pip install amazing-package, the software will only be available in this virtual environment. When you're done, you can deactivate it like so:
deactivate
Wonderful! Managing many virtualenvs gets annoying Over time, I end up accumulating many virtualenvs, which can become harder to manage. Maybe something like this:
$ ls ~/.venv/
my-virtualenv cool-project snakes-ahoy
I also don't want to type source ~/.venv/my-virtualenv/bin/activate every time I use the virtualenv, because it gets very repetitive only the name of the venv is really needed. But luckily, we can write a little bit of bash to make managing this less annoying. (Or you can use one of many Python developer tools that are designed to manage this, like pipx, but when I merely want to consume Python software, I might not have a development environment set up. So that's beyond the scope of this post!) If you add the following shell function to your ~/.bashrc or ~/.bash_aliases file, it will nicely wrap our activation command:
setup-venv()  
        source "$HOME/.venv/$1/bin/activate"
 
Now all we need to run is
setup-venv my-virtualenv
So much quicker! Spicing it up with tab completion The first thing I noticed after writing this wrapper was that I started hitting tab on the virtual environment name, but... nothing happened. Wouldn't it be nice to know what virtualenvs I had available, and to not have to type out the whole long thing? Well, we can write it ourselves If for some reason you don't already have bash completion installed, on a Debian-based system, you will need to install it with
apt install bash-completion
In order to configure our bash completion, we will create a new file, /etc/bash_completion.d/venv, with the following contents:
_list_venvs()
 
    local cur prev opts
    COMPREPLY=()
    cur="$ COMP_WORDS[COMP_CWORD] "
    prev="$ COMP_WORDS[COMP_CWORD-1] "
    opts=$(find $HOME/.venv/ -mindepth 1 -maxdepth 1 -type d -printf "%f ")
    COMPREPLY=( $(compgen -W "$ opts " -- $ cur ) )
    return 0
 
complete -F _list_venvs setup-venv
This file defines another shell function order to determine how to autocomplete the options for our setup-venv function. $opts is where we define the options for our function. We generate it with a find command looking at the .venv folder in the current user's home directory, then only including child folders (excluding the current directory itself, .venv, in our results) by using the min/max depth and type arguments, and printing just the individual directory names, deliminated by spaces using our print formatter. Everything else is the standard scaffolding required to use bash completions. Once you save this file and reload your shell, you'll see that you are able to use completions as expected!
setup-venv <tab>
my-virtualenv cool-project snakes-ahoy
setup-venv s<tab>
setup-venv snakes-ahoy
Complaints, comments, questions? Hope this was helpful! If it wasn't, that's too bad. But don't worry you can safely ignore this post.

Reproducible Builds: Reproducible Builds in July 2026

Welcome to the July 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. If you are interested in contributing to the project, please visit the Contribute page on our website. In this month s report, we cover:

  1. Tool development
  2. Distribution work
  3. Three new scholarly papers
  4. Patches
  5. Misc news

Tool development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 324, 325 and 326 to Debian:
  • Fix tests to work with zipdetails 4.0008. (#1141359)
  • Bump debhelper compatibility level to 13. [ ]
  • Update copyright years. [ ]
In addition, Paul Spooren made changes to allow trailing garbage in Gzip files [ ] and Vagrant Cascadian added an external tool reference for the pedump binary to use the mono package under GNU Guix. [ ]
disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into system calls to reliably flush out reproducibility issues. This month, Christelle Gloor added the option to sort by ctime as returned by the lstat(2) syscall. [ ], which Chris Lamb uploaded whilst bumping the Standards-Version to version 4.7.4 [ ]. Bernhard Wiedemann also updated disorderfs to version 0.7.0 in openSUSE.
Yet again, there were a number of improvements made to our website this month as well. For example, Chris Lamb, by request of Digital Ocean, changed the target of a referral link so that they can manage incoming referrers [ ] and pushed a number of changes to the Tools page [ ].

Distribution work In Debian this month, 32 reviews of Debian packages were added, 26 were updated and a total of 21 were removed this month, adding to our extensive knowledge about identified issues. A number of issue types were added by Chris Lamb, including:
  • python_towncrier_build_date [ ][ ]
  • log_files_installed_in_package [ ]
  • fontforge_varies_by_timezone [ ][ ]
Chris also added a further note for the build_date_in_manpage_generated_by_spf13_cobra issue. [ ]
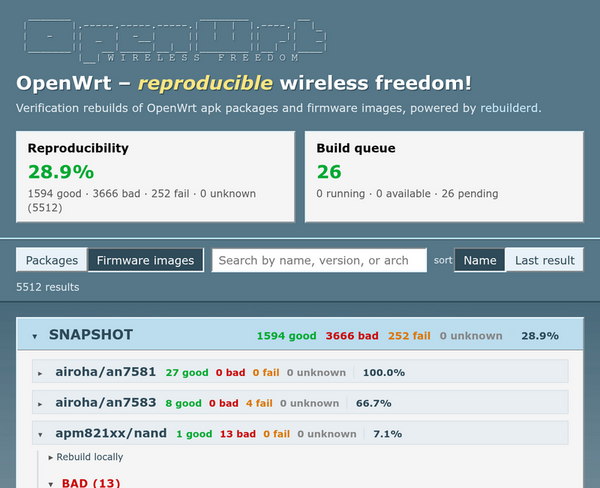
In addition, there is a new page showing verification rebuilds of OpenWrt APK packages and firmware images, powered by rebuilderd:

Three new scholarly papers Yan Li, Nan Jiang, Qihang Zhou, Shaowen Xu, Yamin Xie and Xiaoqi Jia of the Chinese Academy of Sciences published a paper titled VCAligner: Aligning Source Distribution Versions with Upstream Git Commits to Secure Supply Chain:
We present VCAligner, a content-based alignment methodology that constructs inverted indexes over VCS histories to precisely map released artifacts to their originating commits, independent of fragile version tags. We evaluated VCAligner on a dataset of 2,984 verifiable PyPI packages derived from the 4,000 most-downloaded projects linked to public GitHub upstreams. Our results reveal a critical weakness in conventional tag-based heuristics: while they appear effective on 85% of the dataset, the residual 15% failure rate generates a catastrophic downstream audit workload of over 10.3 million commits. In contrast, VCAligner reduces this burden by two orders of magnitude ( 158 ), bounding the total workload to under 65,000 commits. Furthermore, we provide the large-scale characterization of Packaging Noise, classifying artifact divergence into structural additions (Path Phantoms) and content mutations (Blob Phantoms), thereby isolating the distinct attack surfaces of malicious injection and code tampering.

Jens Dietrich and Spencer Sun from the Victoria University of Wellington together with Tim W. White and Behnaz Hassanshahi from Oracle Inc pre-published their paper No Snake Oil: Verifying Python Package Builds (PDF):
Python has become the default language for interacting with AI, with packages being distributed through registries like the Python Package Index (PyPI). This creates a need to analyse supply chains comprising such packages. One such analysis is to rebuild packages in order to identify compromised builds injecting malware. Independent rebuilds in hardened environments have the added advantage that they can generate and record provenance in order to increase the trustworthiness of packages. Two tools that are designed to automate such rebuilds and run them at scale are macaron and oss-rebuild. We study 12,180 popular releases from PyPI and find that the byte-for-byte equivalence rate is generally low. We analyse the reasons why they produce different wheels, and find that equivalence between the original and rebuilt wheels can often still be established, preserving most of the guarantees users expect from rebuildable releases. We present and evaluate daleq4py, a tool to establish the equivalence of Python wheels through the kernel of a normalisation function that is based on provenance-preserving datalog rules. Experimental results show that daleq4py substantially expands the set of rebuilds that can be accepted as equivalent. Although only 15.4% of macaron rebuilds and 19.1% of oss-rebuild rebuilds are byte-for-byte identical to the published PyPI wheels, daleq4py establishes wheel equivalence for 60.2% and 78.9% of source-equivalent rebuilds, respectively.

Denise Nanni, Julien Malka, Stefano Zacchiroli and Th o Zimmermann from T l com Paris together with Gabriele D Angelo from the University of Bologna pre-published their paper Understanding Build Reproducibility in the F-Droid Ecosystem (PDF), which was accepted at the 2026 ACM Conference on Reproducibility and Replicability:
The security of open source applications benefits considerably from the possibility of rebuilding their source and verifying the output. F-Droid, a prominent distribution for open source Android applications, systematically rebuilds them from source and tests their bitwise reproducibility at app publishing time. However, F-Droid offers no guarantee that app reproducibility will continue to hold in the future. As software ecosystems evolve, reproducibility may degrade, with potential negative consequences for software preservation and security. We present the first empirical study of build reproducibility in the F-Droid app ecosystem. Analyzing historical reproducibility logs, we find that the overall bitwise reproducibility rate has been steadily increasing over time (as new versions of apps are published). We then evaluate how reproducibility holds in time for fixed app versions, by attempting to rebuild 18 904 app versions that F-Droid had previously confirmed bitwise reproducible, published between September 2018 and February 2026, achieving an 83% rebuild success rate, and identify missing dependencies as the dominant cause of failure, accounting for 76% of non-rebuildable cases. Among successfully rebuilt apps, 94% are also bitwise reproducible-i.e., they still yield bitwise identical artifacts upon rebuild. Together, these results show that while bitwise reproducibility largely holds for apps that can be rebuilt, rebuildability itself is highly sensitive to temporal decay.

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

Misc news On our mailing list this month, Colin Winter of Markovian Protocol wrote to our mailing list on the topic of Reproducible verification for retained logs:
Reproducible builds remove trust in the builder: anyone re-derives the same artifact from the same source, byte for byte. The same shape applies one layer over, to a retained record. Most record-keeping regimes (the EU AI Act s Article 12 logging is the current example) require that events be recorded and logs retained, but not that a retained log be verifiable, by a party who was not present, as unaltered and existing when claimed. That leaves an integrity obligation resting on trusting the party being audited.
(Full thread)

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

6 August 2026

Bits from Debian: DebConf26 closes in Santa Fe and DebConf27 announced

DebConf26 group photo - click to enlarge On Saturday 25 July 2026, the annual Debian Developers and Contributors Conference came to a close. Over 270 attendees representing 35 countries from around the world came together for a combined 90 events (including some which took place during the DebCamp) including more than 27 Talks, 21 Short Talks, 29 Birds of a Feather sessions ("BoF" informal meeting between developers and users), 8 workshops, and activities in support of furthering our distribution and free software, learning from our mentors and peers, building our community, and having a bit of fun. The conference was preceded by the annual DebCamp hacking session held 13 through 19 July where Debian Developers and Contributors convened to focus on their individual Debian-related projects or work in team sprints geared toward in-person collaboration in developing Debian. As has been the case for several years, a special effort has been made to welcome newcomers and help them become familiar with Debian and DebConf by organizing a sprint "New Contributors Onboarding" every day of Debcamp, followed more informally by mentorship during DebConf. Half a dozen new contributors joined the sessions and learned about Debian, free software, packaging and much more. This year, a week-long DebCamp session was dedicated to auditing, patching, and modernizing the Go ecosystem in Debian and enable the transition triggered by the recent upload of dh-golang enabling GO111MODULE=on by default in Experimental. In order to make the conference more accessible for local participants, a local language track was included in the schedule for talks in Spanish, as was done at DebConf19 in Brazil. The actual Debian Developers Conference started on Monday 20 July 2026. In addition to the traditional "Bits from the DPL" talk, the continuous key-signing party, lightning talks, and the announcement of next year's DebConf27, there were several update sessions shared by internal projects and teams. Many of the hosted discussion sessions were presented by our technical core teams with the usual and useful "Meet the Technical Committee", three talks about Linux Kernel, early boot and improving Debian s kernel and installer support for Chromebooks, and about twenty BoFs and talks about Debian packaging policy, Debian infrastructure, security and privacy. This year, and echoing ongoing discussions within the Free Software community, Artificial Intelligence and Age Verification have been the subject of several talks. The Python, Perl, Ruby, Go, and Rust programming language teams also shared updates on their work and efforts. More than 17 BoFs and talks about community, diversity, and local outreach highlighted the work of various teams involved in not just the technical but also the social aspect of our community The schedule was updated each day with planned and ad hoc activities introduced by attendees over the course of the conference. Several traditional activities took place: a poetry performance, the traditional Cheese and Wine party, the Group Photos, and the Day Trip. For those who were not able to attend, most of the talks and sessions were broadcasted live and recorded. One can find the seventy hours of recorded videos available via the conference schedule, or alternatively through this link. Almost all of the sessions facilitated remote participation via IRC and Matrix messaging apps or online collaborative text documents which allowed remote attendees to "be in the room" and ask questions or share comments with the speaker or assembled audience. DebConf26 saw over 341 T-shirts, a day trip, and up to 130 meals planned per day. All of these events, activities, conversations, and streams coupled with our love, interest, and participation in Debian and F/OSS certainly made this conference an overall success both here in Santa Fe, Argentina and online around the world. The DebConf26 website will remain active for archival purposes and will continue to offer links to the presentations and videos of talks and events. Next year, DebConf27 will be held in Asahikawa, Hokkaido, Japan, from Sunday September 5th to Saturday September 11th, 2027. As tradition follows before the next DebConf the local organizers in Japan will start the conference activities with DebCamp with a particular focus on individual and team work towards improving the distribution. DebConf is committed to a safe and welcome environment for all participants. See the web page about the Code of Conduct on the DebConf26 website for more details on this. Debian thanks the commitment of numerous sponsors to support DebConf26, particularly our Platinum Sponsors: Infomaniak, and Proxmox, and our Gold Sponsors : Freexian, and Viridien. We also wish to thank our Video and Infrastructure teams, the DebConf26 and DebConf committees, our host nation of Argentina, and each and every person who helped contribute to this event and to Debian overall. Thank you all for your work in helping Debian continue to be "The Universal Operating System". See you next year! About Debian The Debian Project was founded in 1993 by Ian Murdock to be a truly free community project. Since then the project has grown to be one of the largest and most influential Open Source projects. Thousands of volunteers from all over the world work together to create and maintain Debian software. Available in 70 languages, and supporting a huge range of computer types, Debian calls itself the universal operating system. About DebConf DebConf is the Debian Project's developer conference. In addition to a full schedule of technical, social and policy talks, DebConf provides an opportunity for developers, contributors and other interested people to meet in person and work together more closely. It has taken place annually since 2000 in locations as varied as Scotland, Bosnia and Herzegovina, India, Korea, France. More information about DebConf is available from https://debconf.org/. About Infomaniak Infomaniak is an independent, employee-owned Swiss technology company that designs, develops, and operates its own cloud infrastructure and digital services entirely in Switzerland. With over 300 employees more than 70% engineers and developers the company reinvests all profits into R&D. Its public cloud is built on OpenStack, with managed Kubernetes, Database as a Service, object storage, and sovereign AI services accessible via OpenAI-compatible APIs, all running on its own Swiss infrastructure. Infomaniak also develops a sovereign collaborative suite messaging, email, storage, online office tools, videoconferencing, and a built-in AI assistant developed in-house and as a privacy-respecting solution to proprietary platforms. Open source is central to how Infomaniak operates. Its latest data center (D4) runs on 100% renewable energy and uses no traditional cooling: all the heat generated by its servers is captured and fed into Geneva's district heating network, supplying up to 6,000 homes in winter and hot water year-round. The entire project has been documented and open-sourced at d4project.org. About Proxmox Proxmox develops powerful, yet easy-to-use open-source server solutions. The comprehensive open-source ecosystem is designed to manage divers IT landscapes, from single servers to large-scale distributed data centers. Our unified platform integrates server virtualization, easy backup, and rock-solid email security ensuring seamless interoperability across the entire portfolio. With the Proxmox Datacenter Manager, the ecosystem also offers a "single pane of glass" for centralized management across different locations. Since 2005, all Proxmox solutions have been built on the rock-solid Debian platform. We are proud to return to DebConf26 as a sponsor because the Debian community provides the foundation that makes our work possible. We believe in keeping IT simple, open, and under your control. Contact Information For further information, please visit the DebConf26 web page at https://debconf26.debconf.org/ or send mail to press@debian.org.

Russell Coker: TV Control etc

In 2008 I wrote a blog post The Problem is Too Many Remote Controls [1] about the issues of controlling a TV and related things. It recently got some comments on Mastodon so I think it s time for an update. The first issue I raised was Now it s not uncommon to have separate remote controls for the TV, VCR, DVD player, and the Cable TV box a total of four remote controls which seems to have alleviated. VCRs seem to have almost entirely gone away. The VHS Wikipedia page [2] is worth reading for everyone who hasn t seen a VCR in operation, which I expect to be more than a few readers now and an increasing number over the next 18 years. I personally don t have Cable TV, I own a DVD player which isn t connected to my TV because I haven t used it for years, I don t own a VCR, and I don t watch free to air TV. So I have one remote control for the TV which I use for Netflix and sometimes YouTube. When viewing YouTube on TV there are significantly more adverts and longer adverts. I presume that is because installing an ad-blocker on my TV isn t a viable option for me and it s a total impossibility for most users. Generally my desktop PC is a much better platform for YouTube than my TV, it has a better quality display, is more user friendly (my previous post addressed the difficulty of getting to the data source that s desired), and doesn t require entering search terms via a slow on-screen keyboard. Netflix on Linux is limited to 720p at low bitrate which is obviously of low visual quality while on the TV it s in 4K. I have Netflix so I use that only on the TV. In my previous post I wrote a thought experiment on how to use a cheap laptop ($500 at the time equivalent to $777 in 2025 money according to the Reserve Bank of Australia) to control a $5000 TV ($7770 in 2025 money). Now you can buy a new 65 4K TV for under $800 and a new laptop capable of 4K output for under $400 so the options are very different. For a $800 TV the manufacturer isn t going to develop a remote control interface and Google (who develops the software the TVs run) won t do it because it could reduce their advertising revenue. But a typical home user could setup a cheap laptop connected to their TV via HDMI providing a familiar and efficient user interface for themselves and visitors. For a Windows laptop 4K Netflix should work and for a Linux laptop the options of a laptop for everything apart from Netflix and the TV for Netflix are bearable, two controls are worse than one but better than the 3+ that used to be common. In my previous post I raised the issue that it s often the case that you don t want to stop watching one show while trying to find another . This is still an unsolved problem and is not addressed in modern software. I am not aware of a Linux music player that supports such functionality and this would be much easier for a music player than for a video player where the screen would have to be shared between the interface for finding the next thing to play and the space for playing the end of the current one. Maybe I should file a bunch of wishlist bugs against music players asking for this. I suggested that cable modem and cable TV box could be integrated into a single device. That has not happened, in fact it s got worse. A relative who has Foxtel has a cable modem, a cable TV box, and a Wifi AP with VOIP to provide landline phone service and to make it more exciting the latter two both have bugs that require a periodic hardware reset to fix. Hopefully cable TV will go away in the next 18 years. Regular PCs have become less noisy in recent years. I am currently using a HP Z640 to write this post and I have HP Z840 and HP Z4G4 systems behind me running as servers and the background noise is still very low. The allegedly 8K TV [3] that I have in my lounge room has cooling fans that make more noise than those three high-end HP computers combined. Using a quiet PC like one of those HP systems to drive a TV is a very viable option and I did just that for a couple of years. Kogan has currently got a selection of refurbished Lenovo ThinkStation systems on sale for under $400, they are quiet and would do well for this, it s also nice that Kogan is selling systems with ECC RAM at home user prices. TV does seem to be going away. YouTube and streaming services seem to get more watching time and many people don t use TV at all. Since my previous post the number of streaming services has increased so torrenting offers increasing benefits as no-one wants to subscribe to 6+ services. For anyone who wants to get all the content that interests them while paying the user interface situation is much worse now than it used to be in 2008. If you use KDE on a PC then the kconnect program allows a phone to be used to remotely control some aspects of a PC and has a good interface for pause/resume of a video and seeking 10 seconds forwards/backwards. The interface for controlling volume is hard to get to and doesn t work on my installation. If you want to use a keyboard to start something playing and then a phone for pause control then kdeconnect is a decent option. A comment on my previous post by Michael Croes raised the issue of remote control which is now a solvable problem. Justin also wrote a comment suggesting a Nokia N800 as a remote. Jason suggested a programmable remote, which would be a good option for a power user and a viable option for someone setting things up for their grandparents. But the amount of pain is greater than I m interested in as lounge room TV isn t an important thing to me. It may appeal to more people than having a dedicated lounge room PC though.

5 August 2026

Enrico Zini: Gnome refusing to suspend

I'm tired, I want to do go bed. I click "sleep" on gnome shell, nothing happens. Swearwords. I want to go to bed. I might have want to put my laptop in a bag and run to catch a train. I hate when this happens. systemd-inhibit --list --mode=block doesn't help much:
$ systemd-inhibit --list --mode=block
WHO    UID  USER   PID  COMM            WHAT                                                     WHY                        MODE
enrico 1000 enrico 3042 gsd-power       handle-lid-switch                                        External monitor attached  block
enrico 1000 enrico 3037 gsd-media-keys  handle-power-key:handle-suspend-key:handle-hibernate-key GNOME handling keypresses  block
enrico 1000 enrico 2878 gnome-session-b sleep                                                    user session inhibited     block
After much googling I found out about gnome-session-inhibit:
$ gnome-session-inhibit  --list
mutter: idle-inhibit (idle)
/usr/lib/chromium/chromium: Playing audio (suspend)
Found the right tab in chromium, paused playing, sleep works again. My sleep was a good half an hour overdue, and all I got for it was to write this blog post. Of course Gnome could have shown me its inhibitor list instead of doing nothing, since it has that information, but it didn't. What I really would expect is that if I intentionally click a suspend button, audio and video playing wouldn't inhibit the suspend. Maybe in a future version of Gnome?

4 August 2026

Dirk Eddelbuettel: #058: Reverse Dependencies Made Easy, Fast, Reliable

Welcome to post 58 in the R4 series. R and the CRAN repositories maintain a very high level of what we might call quality assurrance by requiring that newly-added code does not break any existing dependencies. This is frequently called a reverse-dependency check . For any given CRAN package one can quickly determine it reverse dependencies. Calling tools::package_dependencies(pkgName, reverse=TRUE) will for a scalar or vector-valued argument return a named list with the reverse dependencies. It is then a matter of looping over this list. There are helper functions in base R as well as in contributed packages on and off CRAN. I also wrote my own with package prrd which, while possibly a wee bit specialised and under-documented has served me well to check on Rcpp and related packages which can indeed have a large number of reverse dependencies. I recently looked into one of these contributed runner packages, and while I will refrain from naming its implementation language let me just mention that the term cargo cult may be a real thing here. What go me interested in this was the fact that if one has a simple-to-use runner then the fact that r2u makes it fast, easy, reliable: pick all three (to borrow its slogan) to deal with actual depencies if Ubuntu has indeed been selected as the host. We will maintain the position that if you can in fact integrate with the system-wide package management then any alternative per-repo package management approach not doing so will likely be dominated by an approach that does integrate with the system facilities. Which is what precisely what r2u does, and offers. And why it is used enough to by now have shipped eighty eight million binary packages. So I tested it for the reverse-dependency check task. What I learned by looking into the (much more complicated) runner was that it at the end of the day it hands the actual task of running the reverse dependecies off to a helper function rev_check that is part of the xfun package by Yuhui. I quickly found that besides xfun we would also need its suggested dependency tinytex which in turn would error unless the tlmgr binary was present. So as the sole requirement (on an Ubuntu system with r2u) turns out to be
$ apt install r-cran-xfun r-cran-tinytex texlive-base
where we do it all in one apt call (as root in the container). (Given r2u we could also call install.packages(c("xfun","tinytext")) followed by apt install texlive-base but it is simpler for this setup step to be just one call). With that we are basically done. I did this (twice) using a rocker/r2u container with r2u preinstalled, mounting a local work and scrap directory for the container. In it we expand the package to be tested (i.e. tar xaf pkgName_*tar.gz for a given source package pkgName from CRAN) and then just call with the package name and expanded direcrtory. I.e. I used this call to test my package AsioHeaders (which has just three reverse dependencies) to both name it and to point to the expanded source directory created for this purposed:
> system.time( res <- xfun::rev_check("AsioHeaders", src="AsioHeaders") )
## ... earlier output omitted for brevity here ...
   user  system elapsed 
 35.732   3.333 149.683 
> res
   httpgd ipaddress websocket 
        0         0         0 
> 
and about a good two minutes later I would get the timing result and the summary in variable res. As I checked the current CRAN version, the check was as expected free of concerns or issues. To support this, r2u did indeed go off and install about sixty seven binary packages (and the total includes all binary dependencies fully resolved) delivering on the just works promise by the r2u documentation. As another check, I did the same for RcppAnnoy which has seven reverse dependencies and needed about two hundred CRAN packages to be installed. The full test took just over four minutes with the timing function reporting some nice gains from parallelisation as total user compute time was on the order of just under eight minutes. Again, test results were clean and free of worries as expected:
> system.time( res <- xfun::rev_check("RcppAnnoy", src="RcppAnnoy") )
## ... earlier output omitted for brevity here ...
   user  system elapsed 
471.765 378.220 266.855 
> res
   bbknnR  bigANNOY  blocking     scDHA    Seurat      uwot VectrixDB 
        0         0         0         0         0         0         0 
> 
Overall this was a rather useful quick excursion as it demonstrates that - existing functions can be used to orchestrate a reverse dependency check - with reasonable dependency scale we can do this on a single machine quite easily taking advantage of parallel computing on multi-core machines - using r2u gives us fast, easy, reliable package installation making testing of packages we might not otherwise use or know a breeze - doing this in an ephemeral Docker container facilitates easy build-up of required resources and leaves no side effects behind which might affect our normal development environment

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Anuradha Weeraman: Plan 9 from Bell Labs, the little OS that could

Plan 9 Fourth Edition showing the rio windowing systemScreenshot by VulcanSphere via Wikimedia Commons MIT License
I first heard of Plan 9 from my friend Vajra in 1999 or so, as we were distro-hopping on early Linux distributions and trying to find our way. Vajra is now a Nebula Award-winning science fiction author - have a look at his work. We had just been through Tom's Root Boot, a UNIX-like operating system crammed into a single floppy, and through it discovered a whole new world outside of DOS 6.22. Combing through old UNIX manuals, we went in search of the perfect OS, through Slackware, Caldera, TurboLinux, SUSE and Red Hat. I finally settled on Debian, which lived up to everything I stood for. Plan 9 was distinct. It came out of the Computing Sciences Research Center at Bell Labs, built by Rob Pike, Ken Thompson, Dave Presotto and Phil Winterbottom, with Dennis Ritchie heading the department. The name is a joke at their own expense, borrowed from Ed Wood's 1959 Plan 9 from Outer Space, routinely nominated as the worst film ever made. Thompson and Ritchie had, of course, built the original UNIX; it almost seemed as if they were building a new OS from the lessons learnt from building it - which was in turn built on the lessons from Multics. I remember the awe I felt playing around with Plan 9, and I've not been able to replicate it since. Plan 9 was different in a couple of fundamental ways: per-process namespaces, and a protocol that abstracted locality of resources to processes. As a consequence of these core primitives, the OS surface area was distinctly small. The entire system from the core kernel, to the system call interface, to the compiler, linker and shell was reduced to a form small enough that a single developer could hold it in their head. Lessons from the implementation of UNIX helped the designers make the system leaner, and in Ken Thompson's words, it's the "best operating system out except that it doesn't have the apps that everybody demands" [1]. It also took the concept of "everything is a file" in UNIX to a whole new level. The network stack is a filesystem (/net), processes are files, the display is a file (/dev/draw). Because every resource speaks 9P and every process has its own namespace, you can mount another machine's /net into your namespace and your program makes network calls through that machine's stack without knowing or caring. No sockets API, no RPC layer, just ordinary file system operations through a simple system call interface. Some would say that OS research is dead, and that backwards-compatibility and POSIX killed it. Rob Pike himself argued as much in his 2000 talk, "Systems Software Research is Irrelevant" - but we didn't care at the time. There was so much happening that we didn't have time to take it all in. And then Linux happened, and Software Freedom became a focal point (more on that in a later post). In the summer of 2020, with the world deep in Covid lockdowns, I decided to build a toy operating system, just to try my hand at the the thing that I had always wanted to do. I spent three feverish months working on Odyssey and, looking back, it is perhaps the most fun I have ever had. I would not dare compare it to the magnum opus that is Plan 9, but it gave me perspective: how hard it is to build an OS from scratch, and above all, how fun it is to build an OS from scratch, and why the original creators kept coming back to the same problem. The highlight of those three months was booting the OS and watching it render "The Great Wave off Kanagawa". Nothing in my professional achievements to date captures what that meant to me.
Odyssey rendering The Great Wave off Kanagawa during boot Odyssey displaying "The Great Wave Off Kanagawa"

Decades on from the first time I booted Plan 9, I look back with nothing but awe and respect for the creators of this little operating system and marvel at the foresight that went into it. While many readers will not have heard of Plan 9, they have almost certainly worked with the ideas that came from it: 9P (if you ever used the Windows Subsystem for Linux), UTF-8 (if you ever used any modern operating system), per-process namespaces (if you've ever run a container), Go (whose assembler still uses Plan 9 syntax). Plan 9 still lives on in 9front, a community-maintained fork. Separately, Yoann Padioleau [2] has produced a set of annotated books at principia-softwarica.org, presenting the Plan 9 source in the spirit of Donald Knuth's literate programming - an admirable effort to introduce new readers to the art of operating systems engineering. Pike thought systems research had become irrelevant, and Thompson thought Plan 9 would never "make it" [1]. Both were right about the industry, but may have been pessimistic about the impact. The system lost as a product but won as a set of ideas, assimilated one at a time by modern operating systems. Success is not always measured by popularity. The mark that Plan 9 left behind is greater than what's reflected in its current user base. To me, Plan 9 will always be the OS that punched above its weight class, the little OS that could. References [1] Ken Thompson Interview, March 6, 2024 [2] Yoann Padioleau Principia Softwarica, May 9, 2026

3 August 2026

John Goerzen: Celebrating 45 Years of Kermit with the First New C-Kermit Release in 15 Years (and working with a decades-old C codebase)

1981 was a different time for computing. It was expensive (both hardware and software), and it was far from a given that machines from one vendor would be able to talk to those from another. In fact, Columbia University had just such a problem, so in 1981, Frank da Cruz and Bill Catchings designed a serial protocol they called Kermit. Because of the many quirks of the DEC-20 and IBM mainframes, the Kermit protocol was highly adaptable from the start: able to handle systems that had trouble processing more than 96 bytes of data at once, able to transfer 8-bit files over 7-bit links, able to translate between character sets (ASCII and EBCDIC then; now also various Unicodes), and of course, handling of error-prone serial links. Kermit spread rapidly; by 1982, Kermit had been ported to MS-DOS and Unix. Eventually, C-Kermit (an implementation of Kermit in C) became the flagship Kermit. It gained TCP support, an interactive CLI, a powerful scripting language (with features from the shell, Lisp, and expect), and optimizations for today s high-speed links, such as jumbo packets, sliding windows, and streaming modes. Along the way, Kermit flew on the International Space Station, ran data collection from sensors during hurricanes, and many other uses including postal systems, Boeing 787 manufacturing, and more. Today, I use it as a powerful ssh wrapper (letting me easily transfer files through multiple nested ssh, sudo, su, etc. commands), a BBS client, to exchange data with me HP 48GX calculator, and so on. It s also used today to transmit firmware updates to embedded devices. And, of course, anyone that works with vintage systems is likely to use Kermit at some point. It wouldn t be until the late 1990s that the TCP/IP stack was finally adopted by most OS vendors, establishing something of a common basis for communication. Of course, we assume this today. Though transferring large files between OSs (say, Linux, Windows, MacOS, Android, iPad, etc.) is still a challenge, even though they all speak TCP/IP! I find that the easiest way to get large files from two computers is to spin up Kermit (see ckwin for a Windows fork of C-Kermit) and just set up a TCP connection over the LAN. In fact, I added a new show interfaces command in C-Kermit 11, making it easy to see your system s local IPs. For most of its history, Columbia s Kermit project was self-funded. Columbia charged for commercial use, which limited its inclusion in Linux distributions. In 2011, 30 years after its founding, Columbia canceled the Kermit Project and released C-Kermit as Open Source under a BSD license. Frank da Cruz, who had still been working with the Kermit project all those years, volunteered to continue maintaining Kermit outside Columbia, and continued development with alpha and beta releases through his retirement from the project in 2025. I dive into this C codebase As Debian maintainer of Kermit, I noticed some areas where it wasn t matching modern expectations. One area was, not surprising for a project of its age, security. Another area was that its character set or line-ending conversions are usually not desired now; we are used to byte-identical binary transfers, and the defaults caused confusion and even some rare instances of data corruption. So I started making a few patches last year. I ve worked with old C codebases before, such as Varnish. I ve generally hated it. You usually find a mix of bad and terrible practices, unclear memory management, and so forth. But I ve been living in the C-Kermit codebase for a few months now, and I enjoy it. Yes, this thing is still designed to build on VMS, OS/2, and with compilers that haven t heard of ANSI and those that require modern practices. (That em-dash was mine; I knew how to use them before LLMs existed and I m not going to stop just because LLMs have copied people like me! No AI was used for this post.) The there is an elegance in all of that. As I worked, I fixed a bunch more potential security issues, both with memory safety and with protecting against a malicious remote in roughly the same manner that some patches to scp did a few years back. I added IPv6 support, of course conditionally compiled because some systems C-Kermit builds on have never heard of IPv6 and never will. (And, of course, with fallback algorithms at runtime for systems that have IPv6 support but not IPv6 connectivity.) I added unit tests and Python-based end-to-end tests, running nearly 2000 test cases in total. Along the way, I found and fixed a number of bugs going back decades. I learned about FIONREAD being broken on macOS, about NetBSD s bugs in the pty driver, and fixed bugs in the Kermit protocol implementation itself. I added compatibility tests with the gkermit and ekermit (embedded) implementations, as well as the last full release, C-Kermit 9.0.302 from 2011 (which was difficult to get compiled on a modern system). There is an extensive changelog describing all the improvements in C-Kermit 11. C-Kermit development had never really used a VCS at any point, though Kermit veteran Jeffrey Altman imported historical releases into a Git repo, along with some patches that hadn t made it into a release (which I also pulled in.) There was a lot of disabled code behind COMMENT, along with commentary describing why it was no longer used. With Git, we would now generally just remove the old code and explain why in a commit message. I went through and did so with a lot of it, meaning that, at last check, C-Kermit actually has fewer lines of code now than it used to. Towards a new release It became apparent pretty quickly that I was making more changes than would make sense as a Debian patch series. Not only that, but they would be more widely applicable to more than just Debian and Ubuntu users. As Linux and BSD distributions were running everything from the last non-beta release (2011 s 9.0.302) to the last beta release (about 1.5 years ago), depending on their different policies about running betas, even sharing patches in a useful fashion was going to be quite difficult. So, I spun up a project at Open Kermit to coordinate future development in the open and keep Kermit going. With modern CI, I run that test suite on Linux (x86_64 and arm64), macOS, FreeBSD, NetBSD, and OpenBSD. It builds binary releases on all those platforms, plus a statically-linked Linux binary built with musl libc. You can download the latest C-Kermit release, and of course contribute to C-Kermit and its website. Dedication Frank da Cruz was directly involved with Kermit for 44 years. I m not aware of any other Open Source project founder being involved for so long. Richard Stallman started working on GNU Emacs in 1984, 3 years after Frank started working on Kermit, but Richard hasn t been in that role since around 2008. Accordingly, C-Kermit 11 bears this dedication:
I dedicate this release of C-Kermit to Frank da Cruz. Frank was directly involved with Kermit for 44 years, from its initial design in 1981 all the way through 2025. He maintained Kermit as an Open Source project after Columbia University ended its sponsorship. I know of no other Open Source project where the founder remains so personally involved for so long. When Kermit was begun, transfers between different hardware and operating systems were difficult or impossible. Frank helped build a bridge. Kermit glued systems together, from the International Space Station to pocket calculators, and set a new standard for interoperability. It continues to do so. Kermit is still one of the quietly-working pillars of computing today, enabling everything from firmware upgrades to radios. And, yes, it still reliably transfers files over serial lines. As we start to spend a lot of time in the Kermit codebase, we do so standing on the shoulders of a giant. Thanks, Frank, for your decades of work on Kermit. John Goerzen, July 2026

2 August 2026

Ben Hutchings: FOSS activity in July 2026

Russell Coker: Packet Edit Meme and Debian SE Linux

There s yet another Linux kernel exploit based on container functions, here s the result when run as user_t on a SE Linux system:
$ ./packet_edit_meme 
[*] target /bin/su as uid 1000; entry at file offset 0x4340; shellcode 48 bytes
unshare: Permission denied
[-] page-cache corruption failed
Here is the audit log entry for this failure:
type=AVC msg=audit(1785640621.498:1843): avc:  denied    create   for  pid=1770 comm="packet_edit_mem" scontext=user_u:user_r:user_t:s0 tcontext=user_u:user_r:user_t:s0 tclass=user_namespace permissive=0
Here s the result of running it from the unconfined_t domain:
$ ./packet_edit_meme 
[*] target /bin/su as uid 1001; entry at file offset 0x4340; shellcode 48 bytes
[+] su entry overwritten; exec'ing su -> interactive root shell
# id
uid=0(root) gid=0(root) groups=0(root),1001(test2) context=unconfined_u:unconfined_r:unconfined_t:s0-s0:c0.c1023
# 
Daniel Baumann wrote a blog post describing how this is fixed for Debian systems without SE Linux.

Next.

Previous.