Search Results: "blade"

24 December 2009

Clint Adams: Muppetry

I'm a notoriously late adopter of new technologies. Sure, if I think that something is potentially a good idea, I'll go for it, but for the most part, I assume that things are stupid. I refused to use the WWW for many years, thinking it was idiotic. Now I use the WWW. I find microblogging to be inane and narcissistic at best, but I have derived mild amusement from Shaq on Twitter. Microsoft Windows is something I thought would be ridiculously unsuccessful, because it didn't do anything I would find useful. The list goes on and on, and includes something known in the popular vernacular as configuration management . I've been hearing about BladeLogic and Opsware for quite some time, and idly wondering who the incompetent fools are that need something like this. Back in my day we could manage 100 servers with relative ease; no centralized authentication (because it was a running argument about whether NIS sucked more than NIS+ or vice-versa), no cfengine, no prebuilt server images or any of that jazz. If, for some reason, we needed to make the same change to all servers at once, or some subset thereof, we would just script it. So when one of my acquaintances started raving about Puppet, I assumed it was equally pointless. We'll call him Downs. Downs exhibits a pattern of behavior where he will rave about something for a few weeks, sometimes without having even tried it first, and then eventually become disillusioned with it and start ranting with the same fervor with which he had insisted that whatever fad of the week was the greatest thing ever. It came as no surprise to me when he fell out of love with Puppet and started raving about how much better Chef is. In case you're wondering, he still has not tried Chef to this day. Finally someone convinced me of the value of Puppet. I do not think it is the Way and the Light, but I do see a few situations wherein it makes sense to sacrifice efficiency, flexibility, sanity, and system resources to gain a way of building a near-identical machine from scratch. Now, beyond the flaws inherent to a solution like this, Puppet does have some annoying flaws which I find unnecessary, and which Downs ranted about back when I had absolutely no idea what he was talking about. I disregarded his alleged preference for Chef, but I have heard intelligent people extoll the virtues of Chef, and to a lesser extent Bcfg2. So I took a very brief look at each of those, and was pretty much horrified by what I found. If I need something Puppet-like in the very near future, I will probably be choosing Puppet. I have no intention of running Puppet on machines I manage all by myself though. For that eventuality I am NIHing something with what I consider a better design. The current code is published, but it does not do very much, and requires linking with libdpkg.a which does not exist in any package (but Guillem's working on that, I think). I have no idea whether or not I'll have the motivation to finish it all by myself, but it is Free Software. This post is intentionally weak on details, or deets as the kids call them.

23 November 2009

Martín Ferrari: Movies

Just wanted to share comments on some movies I've watched recently. Tags: Planet Lugfi, Planet Debian

13 October 2009

Russell Coker: New Servers a non-virtual Cloud

NewServers.com [1] provides an interesting service. They have a cloud computing system that is roughly comparable to Amazon EC2, but for which all servers are physical machines (blade servers with real disks). This means that you get the option of changing between servers and starting more servers at will, but they are all physical systems so you know that your system is not going to go slow because someone else is running a batch job. New Servers also has a bandwidth limit of 3GB per hour with $0.10 per GB if you transfer more than that. Most people should find that 3GB/hour is enough for a single server. This compares to EC2 where you pay $0.10 per GB to receive data and $0.17 to transmit it. If you actually need to transmit 2100GB per month then the data transfer fees from EC2 would be greater than the costs of renting a server from New Servers. When running Linux the EC2 hourly charges are (where 1ECU is provides the equivalent CPU capacity of a 1.0-1.2 GHz 2007 Opteron or 2007 Xeon processor):


NAMECostDesc
Small$0.101.7G, 160G, 32bit, 1ECU, 1core
Large$0.207.5G, 850G, 64bit, 4ECU, 2core
Extra Large$0.4015G, 1690G, 64bit, 8ECU, 4core
High CPU Medium$0.201.7G, 350G, 32bit, 5ECU, 2core
High CPU Extra Large$0.807G, 1690G, 64bit, 20ECU, 5core
The New Servers charges are:


NAMECostDesc
Small$0.111G, 36G, 32bit, Xeon 2.8GHz
Medium$0.172G, 2*73G, 32bit, 2*Xeon 3.2GHz
Large$0.254G, 250G, 64bit, E5405 Quad Core 2Ghz
Jumbo$0.388G, 2*500G, 64bit, 2 x E5405 Quad Core 2Ghz
Fast$0.534G, 2*300G, 64bit, E5450 Quad Core 3Ghz
The New Servers prices seem quite competitive with the Amazon prices. One down-side to New Servers is that you have to manage your own RAID, the cheaper servers have only a single disk (bad luck if it fails). The better ones have two disks and you could setup your own RAID. Of course the upside of this is that if you want a fast server from New Servers and you don t need redundancy then you have the option of RAID-0 for better performance. Also I don t think that there is anything stopping you from running Xen on a New Servers system. So you could have a bunch of Xen images and a varying pool of Dom0s to run them on. If you were to choose the Jumbo option with 8G of RAM and share it among some friends with everyone getting a 512M or 1G DomU then the cost per user would be a little better than Slicehost or Linode while giving better management options. One problem I sometimes have with virtual servers for my clients is that the disk IO performance is poorer than I expect. When running the server that hosts my blog (which is shared with some friends) I know the performance requirements of all DomUs and can diagnose problems quickly. I can deal with a limit on the hardware capacity, I can deal with trading off my needs with the needs of my friends. But having a server just go slow, not knowing why, and having the hosting company say I can move you to a different physical server (which may be better or worse) doesn t make me happy. I first heard about New Servers from Tom Fifield s LUV talk about using EC2 as a cluster for high energy physics [2]. According to the detailed analysis Tom presented using EC2 systems on demand can compete well with the costs of buying Dell servers and managing them yourself, EC2 wins if you have to pay Japanese prices for electricity but if you get cheap electricity then Dell may win. Of course a major factor is the amount of time that the servers are used, a cluster that is used for short periods of time with long breaks in between will have a higher cost per used CPU hour and thus make EC2 a better option.

6 October 2009

Steve Kemp: Poppa's got a brand new bang.

Recently I posted a brief tool for managing "dotfile collections". This tool was the rationalisation of a couple of adhoc scripts I already used, and was a quick hack written in nasty bash. I've updated my tool so that it is coded in slightly less nasty Perl. You can find the dotfile-manager repository online now. This tool works well with my dotfile repository, and the matching, but non-public dotfiles-private repository. I'm suspect that this post might flood a couple of feed agregators, because I've recently my chronicle blog compiler with a new release. This release has updated all the supplied themes/templates such that they validate strictly, and as part of that I had to edit some of my prior blog entries to remove bogus HTML markup. (Usually simple things suck as failing to escape & characters correctly, or using "[p][/P]" due to sloppy shift-driving.) I should probably update the way I post entries, and use markdown or textile instead of manually writing HTML inside Emacs, but the habit has been here for too long. Even back when I used wordpress I wrote my entries in HTML... Finally one other change in the most recent chronicle release is that the "mail-scanning.com theme" has been removed, as the service itself is no longer available. But all is not lost. ObFilm: Blade II

18 September 2009

Daniel Kahn Gillmor: Tools should be distinct from Services

Modern daemon implementations can be run in a variety of ways, in a range of contexts. The daemon software itself can be a useful tool in environments where the associated traditional system service is neither needed nor desired. Unfortunately, common debian packaging practice has a tendency to conflate the two ideas, leading to some potentially nasty problems where only the tool itself is needed, but the system service is set up anyway. How would i fix it? i'd suggest that we make a distinction between packages that provide tools and packages that provide system services. A package that provides the system service foo would need to depend on a package that provides the tool foo. But the tool foo should be available through the package manager without setting up a system service automatically. Bad Examples Here are some examples of this class of problem i've seen recently:
akonadi-server depends on mysql-server
akonadi is a project to provide extensible, cross-desktop storage for PIM data. It is a dependency of many pieces of the modern KDE4 desktop. Its current implementation relies on a private instantiation of mysqld, executed directly by the end user whose desktop is running. This means that a sysadmin who installs a graphical calendar application suddenly now has (in addition to the user-instantiated local mysqld running as the akonadi backend) a full-blown system RDBMS service running and potentially consuming resources on her machine.Wouldn't it be better if the /usr/sbin/mysqld tool itself was distinct from the system service?
puppetmaster depends on puppet
Puppet is a powerful framework for configuration management. A managed host installs the puppet package, which invokes a puppetd service to reconfigure the managed host by talking to a centralized server on the network. The central host installs the the puppetmaster package, which sets up a system puppetmasterd service. puppetmaster depends on puppet to make use of some of the functionality available in the package. But this means that the central host now has puppetd running, and is being configured through the system itself! While some people may prefer to configure their all-powerful central host through the same configuration management system, this presents a nasty potential failure mode: if the configuration management goes awry and makes the managed nodes inaccessible, it could potentially take itself out too. Shouldn't the puppet tools be distinct from the puppetd system service?
monkeysphere Build-Depends: openssh-server
The Monkeysphere is a framework for managing SSH authentication through the OpenPGP Web-of-Trust (i'm one of the authors). To ensure that the package interacts properly with the OpenSSH implementation, the monkeysphere source ships with a series of test suites that exercise both sshd and ssh.This means that anyone trying to build the monkeysphere package must pull in openssh-server to satisfy the build-depends, thereby inadvertently starting up a potentially powerful network service on their build machine and maybe exposing it to remote access that they didn't intend. Wouldn't it be better if the /usr/sbin/sshd tool was available without starting up the ssh system service?
Good ExamplesHere are some examples of debian packaging that already understand and implement this distinction in some way:
apache2.2-bin is distinct from apache2-mpm-foo
Debian's apache packaging recently transitioned to split the apache tool into a separate package (apache2.2-bin) from the packages that provide an apache system service (apache2-mpm-foo). So apache can now be run by a regular user, for example as part of gnome-user-share.
git-core is distinct from git-daemon-run
git-core provides the git daemon subcommand, which is a tool capable of providing network access to a git repo. However, it does not set up a system service by default. The git-daemon-run package provides a way for an admin to quickly set up a "typical" system service to offer networked git access.
vblade is distinct from vblade-persist
vblade offers a simple, powerful utility to export a single file or block device as an AoE device. vblade-persist (disclosure: i wrote vblade-persist) provides a system service to configure exported devices, supervise them, keep them in service across system reboots, etc.
Tools are not Services: a ProposalLet's consider an existing foo package which currently provides: I suggest that this should be split into two packages. foo-bin would contain the tool itself, and foo (which Depends: foo-bin) would contain the service configuration information, postinst scripts to set it up and start it, etc. This would mean that every instance of apt-get install foo in someone's notes would retain identical semantics to the past, but packages which need the tool (but not the service) can now depend on foo-bin instead, leaving the system with fewer resources consumed, and fewer unmanaged services running. For brand new packages (which don't have to account for a legacy of documentation which says apt-get install foo), i prefer the naming convention that the foo package includes the tool itself (after all, it does provide /usr/sbin/foo), and foo-service sets up a standard system service configured and running (and depends on foo). Side Effects This proposal would fix the problems noted above, but it would also offer some nice additional benefits. For example, it would make it easier to introduce an alternate system initialization process by creating alternate service packages (while leaving the tool package alone). Things like runit-services could become actual contenders for managing the running services, without colliding with the "stock" services installed by the bundled tool+service package. The ability to create alternate service packages would also mean that maintainers who prefer radically different configuration defaults could offer their service instantiations as distinct packages. For example, one system-wide foo daemon (foo-service) versus a separate instance of the foo daemon per user (foo-peruser-service) or triggering a daemon via inetd (foo-inetd-service). One negative side effect is that it adds some level of increased load on the package maintainers if the service package and the tool package both come from the same source package, then some work needs to be done to figure out how to split them. If the tool and service packages have separate sources (like vblade and vblade-persist) then some coordinating footwork needs to be done between the two packages when any incompatible changes happen. Questions? Disagreements? Next Steps? Do you disagree with this proposal? If so, why? Unfortunately (to my mind), Debian has a long history of packages which conflate tools with services. Policy section 9.3.2 can even be read as deliberately blurring the line (though i'd argue that a cautious reading suggests that my proposal is not in opposition to policy):
Packages that include daemons for system services should place scripts in /etc/init.d to start or stop services at boot time or during a change of runlevel.
I feel like this particular conflict must have been hashed out before at some level are there links to definitive discussion that i'm missing? Is there any reason we shouldn't push in general for this kind of distinction in debian daemon packages? Tags: daemons, packaging, policy

16 May 2009

Joey Hess: one of those days

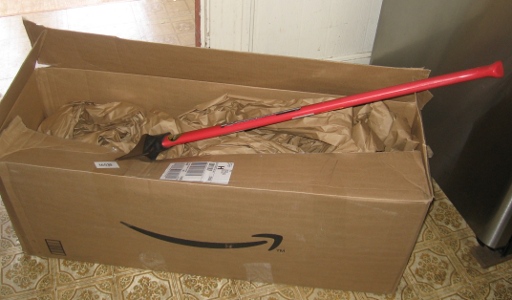
Some spring days just seem full to bursting with unusual experiences. I spent the night at the yurt and in just four hours today: big red axe Thanks to Iain M from Melbourne who writes, "We have never met. I have used your software and gained insight from your blog, over the years. So thanks. Also, I have never bought someone an axe before. This is cool." I forgot I had that in my wishlist, but now I can split wood with ease, when I run out of Amazon packaging material to burn.
Steve Kemp: Humans don't drink blood.

I've said it multiple times, but all mailing list managers suck. Especially mailman. (On that topic SELinux is nasty, Emacs is the one true editor, and people who wear furry boots are silly.) Having setup some new domains I needed a mailing list manager, and had to re-evaluate the available options. Mostly I want something nice and simple, that doesn't mess around with character sets, that requires no fancy deamons, and has no built in archiving solution. Really all we need is three basic operations: Using pipes we can easily arrange for a script to be invoked for different options:
# Aliases for 'list-blah' mailing list.
#
^list-blah-subscribe$:   " /sbin/skxlist --list=list-blah --domain=example.com --subscribe"
^list-blah-unsubscribe$: " /sbin/skxlist --list=list-blah --domain=example.com --unsubscribe"
^list-blah$:             " /sbin/skxlist --list=list-blah --domain=example.com --post"
The only remaining concerns are security related. The most obvious concern is that the script named will be launched by the mailserver user (Debian-exim in my case). That suggests that any files it creates (such as a list of email addresses - i.e. list members) will be owned by that user. That can be avoided with setuid-fu and having the mailing list manager be compiled. But compiled code? When there are so many lovely Perl modules out there? No chance! In conclusion, if you're happy for the exim user to own and be able to read the list data then you can use skxlist. It is in live use, allows open lists, member-only lists, and admin-only lists. It will archive messages in a maildir, but they are ignored for you to use if you see fit. List options are pretty minimal, but I do a fair amount of sanity checking and I see no weaknesses except for the use of the Debian-exim UID. ObFilm: Blade

20 April 2009

Adeodato Sim : Five films (#5)

Ok, here we go again. I do hope somebody, somewhere is finding these posts of some use. *g* Isaac watched Love Actually recently, and I oooh ed quite a bit when he told me, because that movie has one of my favourite or should I say powerful scenes of all times for me, and recalling it brings me instant joy and often instant tears. I think these three (spoiling) minutes are so powerful because, albeit they are fully anticipated for the spectator, they come as a complete surprise to both protagonists (obviously to her, but also to him, given the dialog that takes place once she gets down the stairs; that tiny dialog is in fact the most powerful bit of it all).

1 April 2009

Andrew Pollock: [life] Rollerblading to work

I've moved buildings again, and am now the closest to home physically possible, which makes self-powered commuting less of a drag. Sarah's restarting her Certified Nursing Assistant course, in an accelerated mode this time, and started clinicals this week, which is at a skilled nursing facility in the opposite direction to work, so I rollerbladed to work today and yesterday. I managed to convince my phone to get a GPS lock today, so I used the very cool Android app, GPS Tracker, which when enabled, will report to InstaMapper's website as well as record a track. Here is today's commute in. GPS tracking powered by InstaMapper.com
24 March 2009

Josselin Mouette: Dear lazyweb,

Due to the repeated tendency of our friends of the MPAA beloved government to create laws that turn computer and Internet users into criminals, I m considering to shutdown any kind of non-encrypted communications that I initiate from France. Therefore, I m looking for cheap dedicated hosting in an Internet-friendly country, in a way similar to what we have here with OVH or Iliad. My requirements are: I m fine with blades, but not with virtual hosting. Suggestions are welcome. I m currently considering hosting solutions in the Netherlands, but I d appreciate some advice.

20 March 2009

Russell Coker: Choosing a Server for CPU Intensive work

A client is considering some options for serious deployment of some CPU intensive work. The options that are being considered include cloud computing (Amazon EC2 [1]), virtual machines (Slicehost [2] and Linode [3]), and purchasing servers to install in racks at various locations. I can t disclose the criteria that will determine when each of those three options will be used (I expect that we will end up using all of them). But my research on the prices of various servers will hopefully be useful to someone. For the server vendor I chose Dell. I believe that HP offers slightly better quality hardware than Dell, but they cost more and are more difficult to deal with (I can t even get a price online). For this project I will be using a bunch of redundant servers (in a similar concept to the Google server array) so I m not going to be overly bothered about losing a server occasionally - therefore the slight benefit that HP offers for reliability does not make up for the expense. Dell has some 1RU servers that have two CPU sockets and allow eight CPU cores. It seems that the best value that Dell offers for a server without RAID (the entire server is redundant) is a PowerEdge SC1435 that has two Opteron 2352 quad-core CPUs running at 2.1GHz, 4G of RAM, a 1TB SATA disk, and a Broadcom PCIe Gig-e card for $3,816.50. That machine gives an option of 2.3GHz CPUs for an extra $621.50, I am not sure that increasing the clock speed by almost 10% for a 16% increase in system price is a good idea. The second best option was a PowerEdge 1950 III that has two Xeon E5420 2.5GHz quad-core CPUs with 12M of cache, 4G of RAM and a 1TB SATA disk for $4,302.30. The Intel option has 3 years of support included while the AMD option included 1 year of support and needed at least an extra $990 for 3 years of support. So it seems that if 3 years of support is desired then the Intel based server becomes significantly cheaper and is probably a better option. Dell s 2RU and 4RU servers are of no interest if you want CPU performance. The 2RU servers only support two processors and the 4RU servers only support four processors. So it s a ratio of 2 processors per RU for 1RU servers vs one processor per RU for 2RU and 4RU servers, and the 2RU and 4RU servers are a lot more expensive too. I am investigating the Dell blade server. Blade servers are great for CPU density and good for management. The Dell blade enclosure M1000e takes 10RU of space and supports 16 half-height blades or 8 full-height blades. The Dell M905 blade supports four AMD quad-core processors for a total of 128 cores in 10RU, there are also half-height blades that support two quad-core processors for the same CPU density. So in terms of CPU density it s an average of 12.8 cores per RU for the blade server vs 8 cores per RU for 1RU servers. While I haven t got a complete price yet, it seems that four CPUs suitable for the M905 will cost about as much as four 1RU servers. So the 1RU systems are definitely better value for money than the blade server. The difference is the management cost. N servers that have two CPUs will be more work than N/2 servers that have four CPUs, but on the other hand blade servers require some specialised skills to run them (which I don t have) and that might also cause problems. I don t think that blades will be part of this project.

7 March 2009

John Goerzen: My Week

It s been quite the week. Stomach Flu Last Friday, my stomach was just starting to feel a little odd. I didn t think much off it a little food that didn t go over well or stress, I thought. Saturday I got out of bed and almost immediately felt like throwing up. Ugh. I probably caught some sort of stomach flu. I was nauseous all day and had some terrible diarrhea to boot. I spent parts of Saturday, Saturday night, Sunday, and Sunday night supervising some emergency downloads as the BOFH would say. By Sunday afternoon, I thought I was doing good enough to attend a practice of the Kansas Mennonite Men s Choir. I made it through but it wasn t quite as up to it as I thought. Monday morning I woke up and thought the worst was behind me, so I went to work. By evening, the worst clearly was not behind me. I was extremely cold, and then got very hot a few hours later. Tuesday I left work a little early because of not feeling well. Servers Wednesday a colleague called me at home before I left to say that the ERP database had a major hiccup. That s never good. The database is this creaky old dinosaur thing that has a habit of inventing novel ways to fail (favorite pastime: exceeding some arbitrary limit to the size of files that no OS has cared about for 5 years, then hanging without telling anybody why). My coworkers had been working on it since 5. I went into the office and did what I could to help out, though they had mostly taken care of it. Then we went to reboot the server. It didn t come back. I/O error on sda just after init started, and it hung. Puzzled, as it just used that disk to boot from. Try rebooting again. This time, I/O error as the fibre channel controller driver loads. Again, puzzled as it just used that controller to load grub. Power cycle this time. And now the server doesn t see the fibre channel link at all. Eep. Check our fiber optic cables, and power cycle again. And THIS time, the server doesn t power back up. Fans whir for about a second, then an ominous red light I never knew was there shows up. Eeep! So I call HP. They want me to remove one CPU. Yes, remove one CPU. I tried, and long story short, they dispatch a local guy with a replacement motherboard. Can you send along a FC controller, in case it s dead too? Nope, not until we diagnose a problem with it. Local guy comes out. He s a sharp guy and I really like him. But the motherboard wasn t in stock at the local HP warehouse, so he had to have it driven in from Oklahoma City. He gets here with it by about 4:30. At this point the single most important server to the company s business has been down almost 12 hours. He replaces the motherboard. The server now powers up yay! And it POSTs, and it . doesn t see the disks. !#$!#$ He orders the FC controller, which is so very much not in stock that they can t get it to us until 8:30AM the next morning (keep in mind this thing is on a 4-hour 24/7 contract). Next morning rolls around. Outage now more than 24 hours. He pops the FC controller in, we tweak the SAN settings appropriately, we power up the machine, and . still doesn t see any disks, and the SAN switch still doesn t see any link. EEP! Even the BIOS firmware tool built into the controller doesn t see a link, so we KNOW it s not a software issue. We try plugging and unplugging cables, trying different ports, everything. Nothing makes a difference. At this point, while he ponders what else he can replace while we start migrating the server to a different blade. We get ERP back up on its temporary home an hour later, and he basically orders us every part he can think of while we ve bought him some room. Several additional trips later, he s replaced just about everything at least once, some things 2 or 3 times, and still no FC link. Meanwhile, I ve asked my colleague to submit a new ticket to HP s SAN team so we can try checking of the switch has an issue. They take their sweet time answering until he informs them this morning that it s been *48 HOURS* since we first reported the outage. All of a sudden half a dozen people at HP take a keen interest in our case. As if they could smell this blog post coming So they advise us to upgrade the firmware in the SAN switch, but they also say we really should send this to the blade group; the problem can t be with the SAN and of course the blade people are saying the problem s GOT to be with the SAN . We try to plan the firmware upgrade. In theory, we can lose a switch and nobody ever notices due to multipathing redundancy. In practice, we haven t tested that in 2 years. None of this equipment had even been rebooted in 390 days. While investigating this, we discovered that one of the blade servers could only see one path to its disks, not two. Strange. Fortunately, THAT blade wasn t mission-critical on a Friday, so I power cycled it. And it powered back up. And it promptly lost connection to its disks entirely, causing the SAN switches to display the same mysterious error they did with the first blade the one that nobody at HP had heard of, could find in their documentation, or even on Google. Yes, that s right. Apparently power cycling a server means it loses access to its disks. Faced with the prospect of our network coming to a halt if anything else rebooted (or worse, if the problem started happening without a reboot), we decided we d power cycle one switch now and see what would happen. If it worked out, our problems would be fixed. If not, at least things would go down in our and HP s presence. And that worked? What? Yes. Power cycling the switch fixed every problem over the course of about 2 minutes, without us having to do anything. Meanwhile, HP calls back to say, Uhm, that firmware upgrade we told you to do? DON T DO IT! We power cycle the other switch, and have a normal SAN life again. I let out a WOOHOO! My colleague, however, had the opposite reaction. Now we ll never be able to reproduce this problem to get it fixed! Fair point, I suppose. Then began the fairly quick job of migrating ERP back to its rightful home it s all on Xen already, designed to be nimble for just these circumstances. Full speed restored 4:55PM today. So, to cap it all off, within the space of four hours, we had fail: Murphy, I hate you. The one fun moment out of this was this conversation: Me to HP guy: So yeah, that machine you ve got open wasn t rebooted in 392 days until today. HP guy: WOW! That s INCRED oh wait, are you running Linux on it? Me: Yep. HP: Figures. No WAY you d get that kind of uptime from Windows. And here he was going to be all impressed.

2 March 2009

Bdale Garbee: TeleMetrum Power Supplies

After a long hiatus for various reasons, I finally had the chance to try my hand at loading a TeleMetrum board today! Sadly, I wasn't able to completely load any boards, because I somehow ended up with the wrong Digi-Key part numbers for 4 capacitors, one of which is a critical value. I placed an order for the missing parts and a few other bits we'll need eventually, hopefully they'll be here in a couple days and I can try to load a board with all the parts. Instead, what I did today was a a partial load of a board with the goal of testing the various power supplies. Seemed like a good idea, since I've had my share of odd problems with power supplies in the past. This also gave me a chance to try out my solder paste stencil, get some experience hand-placing the tiny 0402 passive parts, and an excuse to see if I could hit the solder reflow temperature profile adequately with my electric cooking skillet and IR non-contact thermometer. The good news is that it all worked right the first time! We're successfully charging a LiPo battery from USB power, and successfully making 3.3 volts for the electronics from that. The resistor divider designed to allow the LiPo battery voltage to be sampled by the CPU's analog to digital converter is also working fine. A few observations are in order, however. Getting the right amount of solder paste down on the board requires some finesse with the spreading blade and the stencil. I think the paste was a bit heavy around the CC1111 footprint, as I ended up with some bridged pads. Since I didn't load the actual CPU part, it could just be that not having something real there to wick up some solder meant there was enough to form the bridges. Don't know. The amount of solder on the ground pad in the middle of the chip looks good, though! The 0603 sized LED in the power supply circuit was the only part that didn't self-align correctly. I may have had it a bit too far to one side. The pads on the part have notches in the end, and it looks like one side of each is more or less centered, so I think surface tension did the best it could with what I gave it to work with. The LED soldered ok, isn't shorting to anything else, and clearly works fine... but I'd be happier if it were aligned better. Found and fixed a solder bridge between two pins on the surface-mount USB connector before first application of power. Could be further data that the paste layer was a bit too thick. On the other hand, I had to wiggle the connector around a bit to get it aligned correctly, so I may have smudged the paste into a bridge while doing that. I also note that there's some visible flux left on the surface of the solder, particularly on big paste areas like the feet of the USB connector. I suspect this means I didn't dwell long enough at either or both of the preheat or ultimate reflow temperatures. Since all the parts clearly soldered adequately to function, I'm still pretty happy... but since the rockets we fly experience violent accelerations during boost, this is something I'll play with on future reflows. All in all, a great way to spend an afternoon, and a big step forward for the TeleMetrum project!

15 February 2009

Michael Prokop: Debian GNU/Linux 5.0 codename Lenny - News for sysadmins

Alright, Debian GNU/Linux 5.0 AKA as Lenny has been released. Time for a Debian unstable unfreeze party! 8-) What does the new stable release bring for system administrators? I ll give an overview what news you might expect when upgrading from Debian GNU/Linux 4.0, codename Etch (released on 8th April 2007) to the current version Debian GNU/Linux 5.0, codename Lenny (released on 14th February 2009). I try to avoid duplicated information so make sure to read the release announcement and the official release notes for Lenny beforehand. Noteworthy Changes Virtualisation Virtualisation related new tools: Desktop oriented packages like virtualbox and qemu are available as well of course. Noteworthy Updates This is a (selective) list of some noteworthy updates: New packages Lenny ships over 7000 new packages. Lists of new/removed/replaced packages are available online. I ll name 238 sysadmin related packages that might be worth a look. (Note: I don t list addon stuff like optional server-modules, docs-only and kernel-source related packages. I plan to present some of the following packages in more detail in separate blog entries.) Further Ressources

12 February 2009

Sebastian Harl: Airport security ...

Supposedly, my low, casual shoes contain some longish and slender piece of metal in the sole. At least, that's what the X-rays at the airport detected when I was flying back from FOSDEM. While it isn't shaped like a typical knife, I didn't know how to tell it apart from a potentially hidden blade. Well, I guess that's what the people doing the security control are trained for ... Interestingly enough, it was only detected at the Zurich airport - neither the metal detectors in Nuremberg nor those in Brussels seemed to care about it.

23 January 2009

Daniel Kahn Gillmor: target disk mode (sbp-2 mass storage host mode?)

One very convenient feature of Apple's hardware is the ability for their workstations to enter target disk mode. This effectively transforms the machine into a glorified ieee1394 (firewire) block device, which can then be manipulated from outside the machine using the standard SBP-2 protocol. Is there a way to provide this same functionality from a running GNU/Linux machine? For example, i have a GNU/Linux system with a block device attached to it. I would prefer if the block device was available to a neighboring machine, but (for whatever reason) i'm unable to physically move it. However, i'm able to link the two machines via a simple ieee1394 connection. A "virtual target disk mode" server (or would it be better to say "an SBP-2 mass storage target service over an ieee1394 link"?) would be really useful. One thing that occurs to me is that i could do some sort of networking abstraction over the link (using eth1394?), and then use something like vblade (an ATA-over-Ethernet target service) to provide a virtual block device to the remote host. However, this requires the remote host to run an operating system capable of dealing with these (more obscure) protocols, and i'd like this to work for any remote machine that knows how to deal with generic SBP-2 ieee1394 mass storage. I know that in general GNU/Linux is at least as powerful and capable as the firmware that Apple ships ;) But it's possible that our community just hasn't gotten around to implementing something like this. Is this the case? My attempts to search for it haven't turned up anything, but it's entirely possible that i'm reading the wrong docs (or reading the docs wrong). Any pointers?Tags: firewire, ieee1394, sbp2, vblade

Robert McQueen: Auctions, Beards, Conferences and Devils

Tuz, coming soon to a Linux kernel near you
It s the last day of the most awesome linux.conf.au 2009 conference in Hobart, Tasmania. I ve just witnessed the a room full of 500 people sit with baited breath as Linus wielded a set of clippers to shave Bdale Garbee s beard, followed by Bdale (with a razor with 3 more blades than last time he shaved, a tiny bowl of water and a hand-mirror) trying to make it look neater. The LCA twitter feed was up on the projector, and someone rightly observed this whole event was actually pretty weird. There are already pictures on flickr too. However, well done to Bdale for being such a good sport, but it looks like his wife Karen will accompany him next year to make sure he doesn t agree to anything else like this, and supervise the waxing of Rusty s chest :) What s this all in aid of? After the incredible auction for this beautiful picture from Karen, and generous donations at the Penguin Dinner on Wednesday night, the conference has now raised between AU$ 35k and 40k towards the Save the Tasmanian Devil appeal. Around AU$ 1.3k of the nonsensical winning consortium s AU $10.6k bid came from the Collabora folks who were at the dinner, and AU$ 1.2k from Collabora and Collabora Multimedia directly. We were all set to place a winning AU$ 3k bid but then Matthew and Daniel came up with the Bdale shaving scheme, and then things really picked up. I m glad we took part - the lead scientist from the project was really grateful, and I hope the money can make a real difference to their great work.
Telepathy
On more mundane matters, I also gave my talk this morning, and my slides (Telepathy slides v2.0 thanks to Marco) are online. I also made a few demos of new awesome stuff you can do with Telepathy (most of the patches are already merged upstream or well on the way): On that note, these were just the five that I picked to try and fit into my talk. There are a load more demos in the pipeline from the other guys in Collabora of doing stuff with Telepathy, so keep a close look on Planet Collabora for the next cool thing.

11 December 2008

Russell Coker: Toy Helicopter


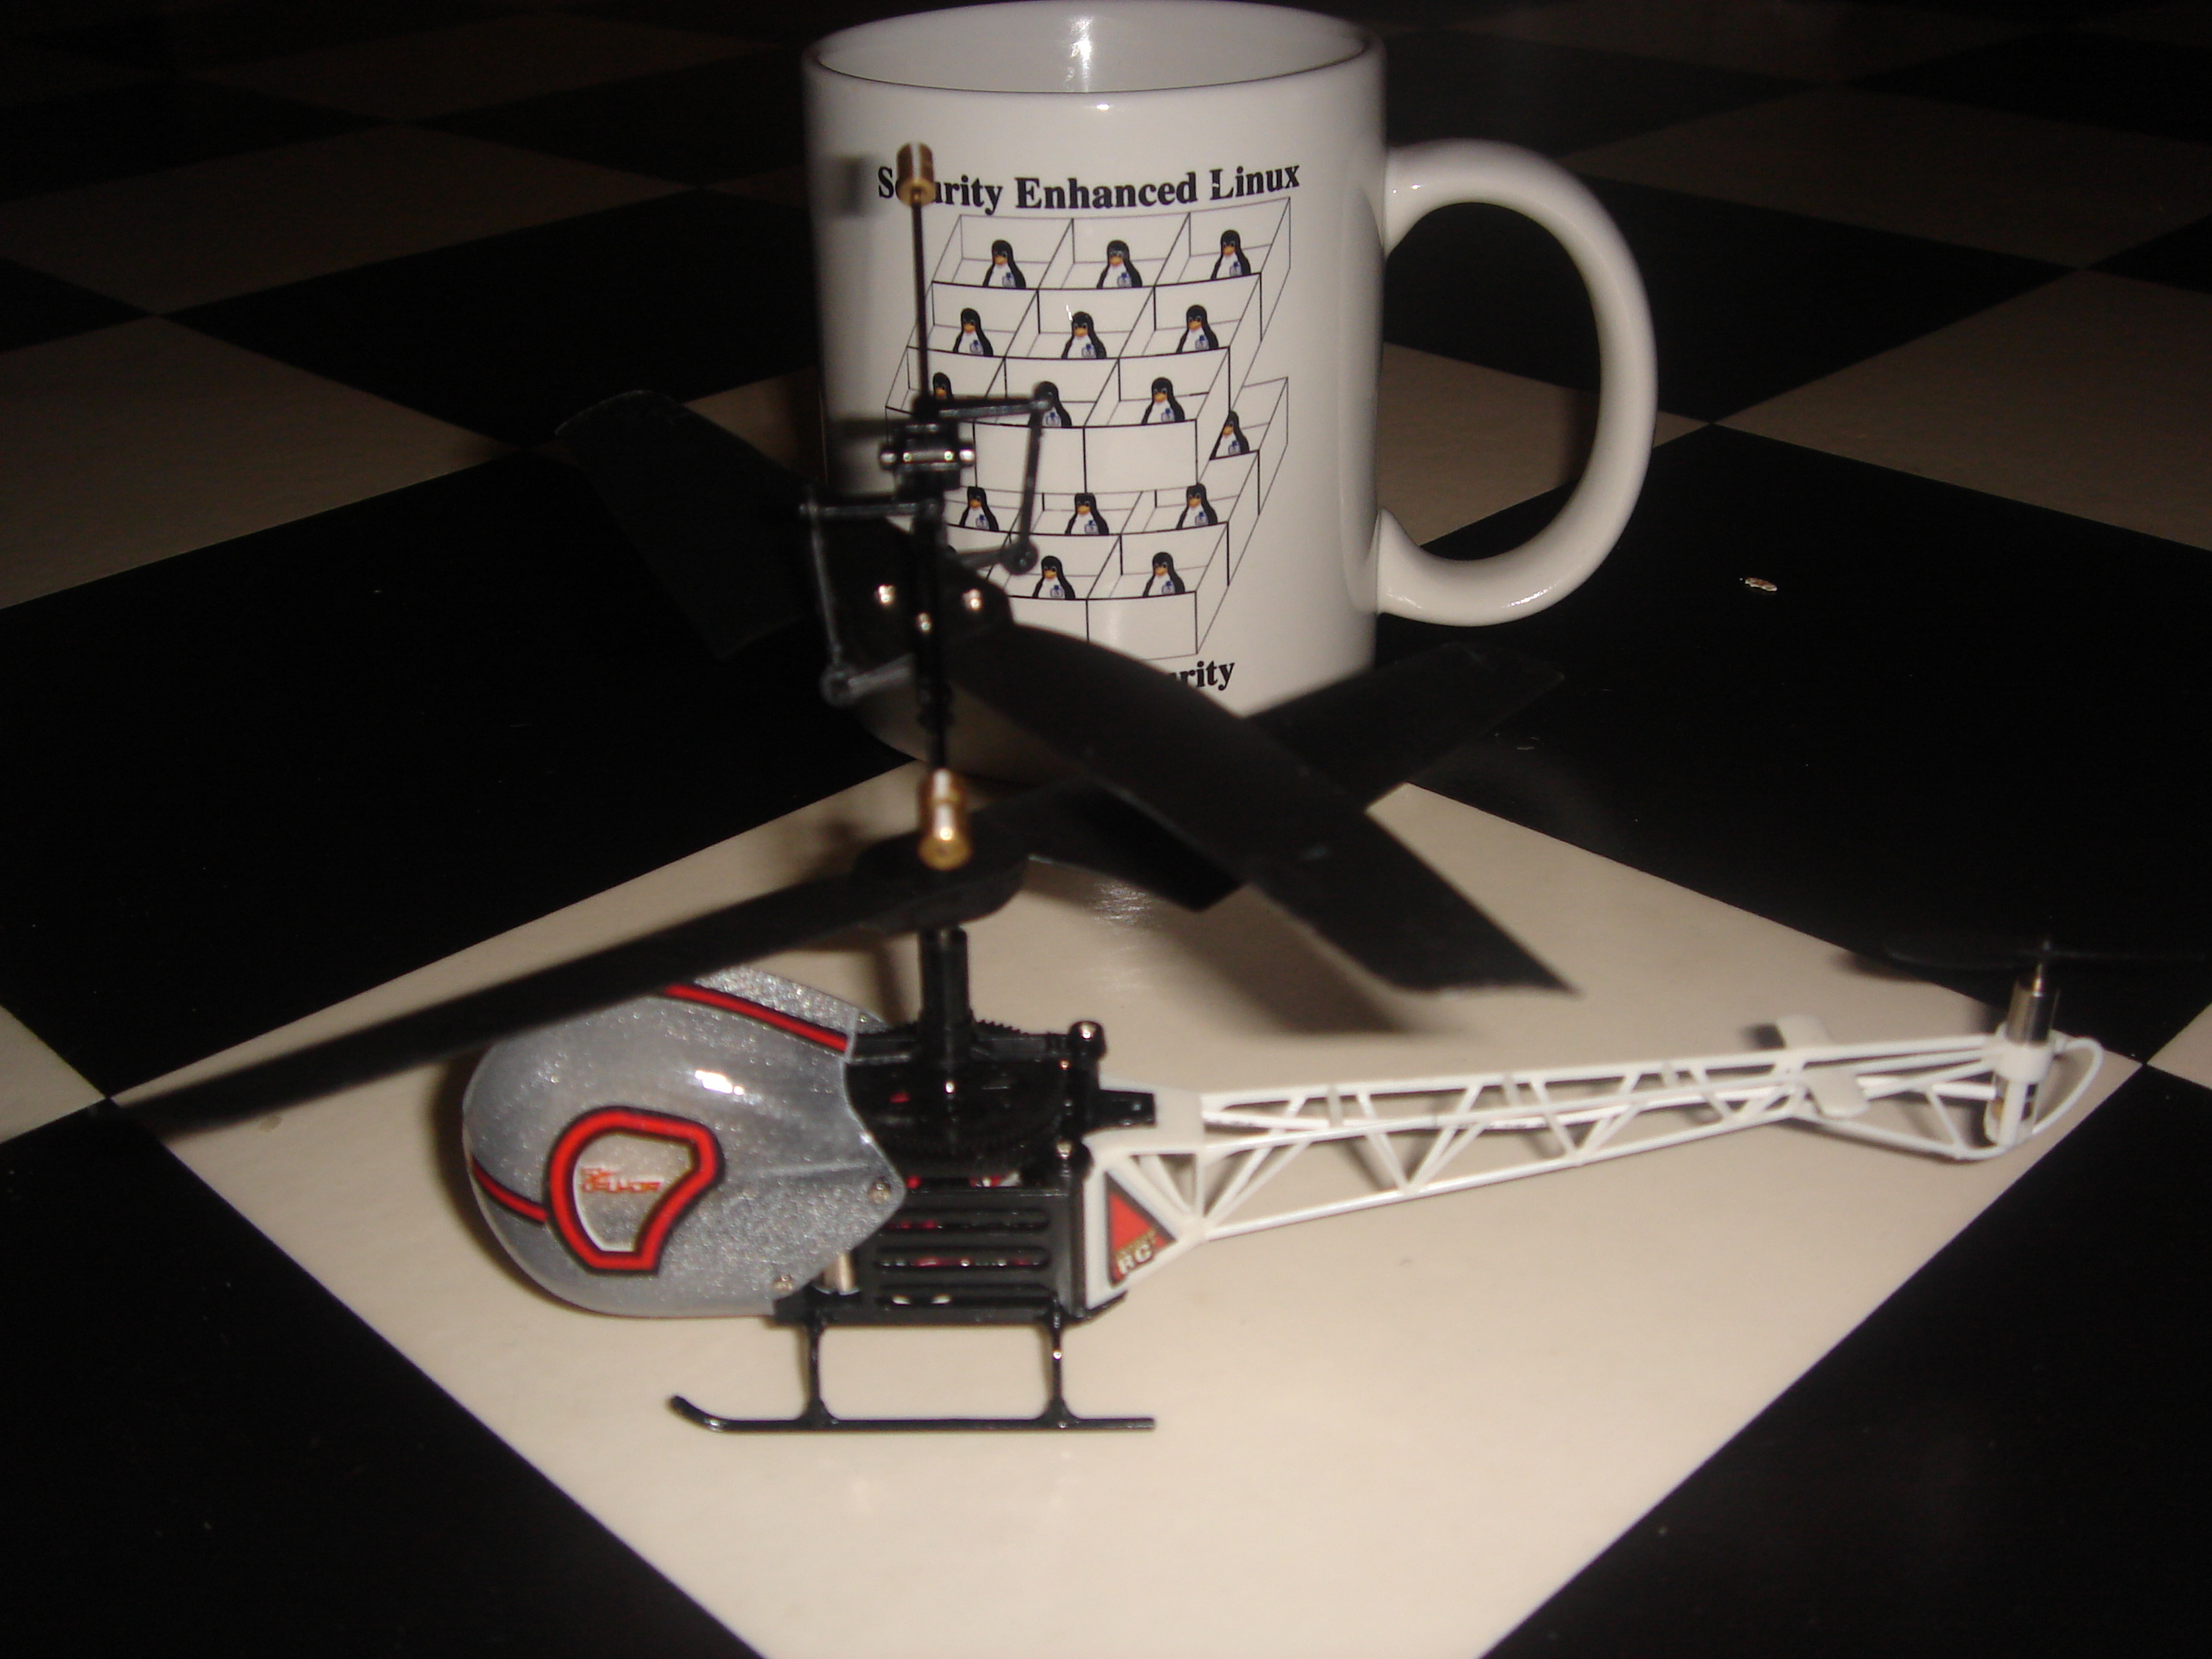
I have just bought myself a toy helicopter. I had been tempted to buy one for a while and when I saw them on sale for $30 I couldn’t resist. My helicopter is model FJ-702 from Flyor, it is controlled by infra-red and is designed for indoor use only. It seems that the trick to flying one is to control the rate of ascent and descent. If the helicopter rises too fast then it may bounce off the ceiling which results in it swaying uncontrollably and crash-landing. If it is allowed to descend too fast then it becomes impossible to slow the rate of descent, I suspect that this is the settling with power [2] problem that is documented in Wikipedia. The helicopter is very fragile, I broke one of the skids and part of the tail assembly before I learned how to control it properly. Probably the main thing to look for when buying a model helicopter is a solid design - some time after buying (and breaking) my helicopter I visited the shop which sold it and heard the owner advising other customers to buy the $45 model which is apparently more solid. It seems that an ideal design would be a frame made of spring-steel (not to make it springy but to avoid it breaking when it hits). I recommend flying in a room with a carpeted floor, bouncing off a solid surface such as a wood floor will break a helicopter. Controlling a helicopter is really difficult. The models that I have tried and seen demonstrated all have serious problems with unwanted rotation. My helicopter and the others I have seen have coaxial rotors to avoid rotation without a tail rotor. According to the Wikipedia page a lot of energy is used by a tail rotor [1], as there has been obvious difficulty in designing the helicopter with adequate power (in terms of the light and weak frame and the short battery life) it seems that they didn’t use the tail rotor design to save energy. It’s a pity that instead the designers couldn’t have skipped the flashing LEDs etc. One strange thing is that one pair of blades can have their angle changed (which appears to be similar to the “semirigid” design shown on the wikipedia page). I’m not sure how increasing the angle of one blade while simultaneously decreasing the angle of it’s pair will do any good. I expect that this has something to do with the fact that the helicopter will rotate at different rates when under different amounts of vertical thrust. This incidentally makes it almost impossible to maneuver the craft. It has a tail rotor on a vertical axis to control forward and reverse movements, but the extreme difficulty in keeping it facing in one direction makes this almost useless. I wonder what the minimum size at which a gyro-stabiliser becomes practical. But as Wikipedia doesn’t document the existence of an autopilot for full size helicopters the chance of getting one for a toy is small. In summary, while I have had $30 of fun, I think that a more solid helicopter would be a better investment.

11 November 2008

John Goerzen: Review: Silicon Mechanics

After some hilariously frightening reactions from Dell support to simple problems, and HP becoming aggressively competitive on price, we've been using HP servers for a few years now. The hardware is good, and the support, while reasonable, always... pauses... when I mention that we're running Debian. I try not to let it slip if I don't have to.

We put in some HP blades a couple of years ago, and I was annoyed to discover that they have discontinued that enclosure and all the blades in it. I decided this was a good time to look at their newer options, as well as at other companies.

Back in July, I had noticed a Silicon Mechanics booth at OSCon. I noticed their slogan "experts included." That sounds great; we've got software experts here, but not hardware experts, and I'd enjoy dealing with a company that knows more about their hardware than I do. I went up to their booth and asked what they'd say about us running Debian on their hardware. "That would be just fine." "So you'd fully support it when I'm running Debian?" "Sure." "What about management software - do you have any of that which I'd find annoying to port to Debian?" "Our servers don't need any management software other than what comes with your kernel." Good answers.

So, when it came time for us to decide what to do about getting a new server in here, I figured I'd call up Silicon Mechanics and see what they'd recommend. They put me on a conference call with a sales rep and an IT engineer, and wound up recommending a 1U server for us to start with, and an iSCSI storage device to address some of the storage needs we have (both for that server and others). I had heard of iSCSI only vaguely, and asked how it worked, and what the performance would be like compared to our 2Gb FC SAN. I got back intelligent (and correct) answers.

They probably spent 2 hours with me on the phone before we placed an order. I was incredibly happy with their service, level of expertise, and helpfulness. They even did a webinar to demo the management interface on the storage unit for me.

Today, the 1U server arrived. I unboxed it and set it on my desk to configure. First item: set an IP address for the IPMI card. That's the device that lets me connect to it over a web browser and interact with the console, power cycle it, etc. as if I was there. I set an IP, but somehow couldn't seem to figure out the username and password for the web interface.

So I called Silicon Mechanics support at the number that was included on the fridge magnet (!) that came with the shipment. Phone rang once. Then a live, capable American answered. No menus, no fuss. I asked my question. He apologized, saying, "I should know that, but I'll have to look it up... hold on just a bit." I had my answer about 90 seconds later. He offered to send me the full docs for the IPMI card if I wanted as well.

So I've been very impressed with them so far. From what I've heard, their iSCSI enclosure ought to be quite something as well. They even helped us spec out a switch that supports trunking for use with it.

I'll give them a "highly recommended".

11 September 2008

Russell Coker: Noise in Computer Rooms

Some people think that you can recognise a good restaurant by the presence of obscure dishes on the menu or having high prices. The reality is that there are two ways of quickly identifying a good restaurant, one is the Michelin Guide [1] (or a comparable guide - if such a thing exists), the other is how quiet the restaurant is. By a quiet restaurant I certainly don’t mean a restaurant with no customers (which may become very noisy once customers arrive). I mean a restaurant which when full will still be reasonably quiet. Making a restaurant quiet is not in itself a sufficient criteria to be a good restaurant - but it’s something that is usually done after the other criteria (such as hiring good staff and preparing a good menu) are met. The first thing to do to make a room quiet is to have good carpet. Floor boards are easy to clean and the ratio of investment to lifetime is very good (particularly for hard wood), but they reflect sound and the movement of chairs and feet makes noise. A thick carpet with a good underlay is necessary to absorb sound. Booths are also good for containing sound if the walls extend above head height. Decorations on the walls such as curtains and thick wallpaper also absorb sound. A quiet environment allows people to talk at a normal volume which improves the dining experience. It seems to me that the same benefits apply to server rooms and offices, with the benefit being more efficient work. I found it exciting when I first had my desk in a server room (surrounded by tens of millions of pounds worth of computer gear). But as I got older I found it less interesting to work in that type of environment just as I found it less interesting to have dinner in a noisy bar - and for the same reasons. For a server room there is no escaping the fact that it will be noisy. But if the noise can be minimised then it will allow better communication between the people who are there and less distraction which should result in higher quality of work - which matters if you want good uptime! One thing I have observed is that physically larger servers tend to make less noise per volume and per compute power. For example a 2RU server with four CPUs seems to always make less noise than two 1RU servers that each have two CPUs. I believe that this is because a fan with a larger diameter can operate at a lower rotational speed which results in less bearing noise and the larger fans also give less turbulence. While it’s obvious that using fewer servers via virtualisation has the potential to avoid noise (both directly through fans and disks and indirectly through the cooling system for the server room [2]). A less obvious way of reducing noise is to swap two 1RU servers for one 2RU server - although my experience is that for machines in a similar price band, a 2RU server often has comparable compute power (in terms of RAM and disk capacity) to three or four 1RU servers. To reduce noise both directly and indirectly it is a requirement to increase disk IO capacity (in terms of the number of random IOs per second) without increasing the number of spindles (disks). I just read an interesting Sun blog covering some concepts related to using Solid State Disks (SSDs) on ZFS for best performance [3]. It seems that using such techniques is one way of significantly increasing the IO capacity per server (and thus allowing more virtual servers on one physical machine) - it’s a pity that we currently don’t have access to ZFS or a similar filesystem for Linux servers (ZFS has license issues and the GPL alternatives are all in a beta state AFAIK). Another possibility that seems to have some potential is the use of NetApp Filers [4] for the main storage of virtual machines. A NetApp Filer gives a better ratio of IO requests per second to the number of spindles used than most storage array products due to the way they use NVRAM caching and their advanced filesystem features (which also incidentally gives some good options for backups and for detecting and correcting errors). So a set of 2RU servers that have the maximum amount of RAM installed and which use a NetApp Filer (or two if you want redundancy) for the storage with the greatest performance requirements should give the greatest density of virtual machines. Blade servers also have potential to reduce noise in the server room. The most significant way that they do this is by reducing the number of power supplies, instead of having one PSU per server (or two if you want redundancy) you might have three or five PSUs for a blade enclosure that has 8 or more blades. HP blade enclosures support shutting down some PSUs when the blades are idling and don’t need much power (I don’t know whether blade enclosures from other vendors do this - I expect that some do). A bigger problem however is the noise in offices where people work. It seems that the major responsible for this is the cheap cubicles that are used in most offices (and almost all computer companies). More expensive cubicles that are at almost head-height (for someone who is standing) and which have a cloth surface absorb sound better significantly improve the office environment, and separate offices are better still. One thing I would like to see is more use of shared desktop computers, it’s not difficult to set up a desktop machine with multiple video cards, so with appropriate software support (which is really difficult) you could have one desktop machine for two, or even four users which would save electricity and reduce noise. Better quality carpet on the floors would also be a good thing. While office carpet wears out fast adding some underlay would not increase the long-term cost (it can remain as the top layer gets replaced). Better windows in offices are necessary to provide a quiet working environment. The use of double-glazed windows with reflective plastic film significantly decreases the amount of heating and cooling that is required in the office. This would permit a lower speed of air flow for heating and cooling which means less noise. Also an office in a central city area will have a noise problem outside the building, again double (or even triple) glazed windows help a lot. Some people seem to believe that an operations room should have no obstacles (one ops room where I once worked had all desks facing a set of large screens that displayed network statistics and the desks were like school desks with no dividers), I think that even for an ops room there should be some effort made to reduce the ambient noise. If the room is generally reasonably quiet then it should be easy to shout the news of an outage so that everyone can hear it. Let’s assume for the sake of discussion that a quieter working environment can increase productivity by 5% (I think this is a conservative assumption). For an office full of skilled people who are doing computer work the average salary may be about $70,000, and it’s widely regarded that to factor in the management costs etc you should double the salary - so the average cost of an employee would be about $140,000. If there are 50 people in the office then the work of those employees has a cost of $7,000,000 per annum. A 5% increase in that would be worth $350,000 per annum - you could buy a lot of windows for that!

Next.

Previous.