Search Results: "tar"

26 August 2014

Daniel Pocock: GSoC talks at DebConf 14 today

This year I mentored two students doing work in support of Debian and free software (as well as those I mentored for Ganglia). Both of them are presenting details about their work at DebConf 14 today. While Juliana's work has been widely publicised already, mainly due to the fact it is accessible to every individual DD, Andrew's work is also quite significant and creates many possibilities to advance awareness of free software. The Java project that is not just about Java Andrew's project is about recursively building Java dependencies from third party repositories such as the Maven Central Repository. It matches up well with the wonderful new maven-debian-helper tool in Debian and will help us to fill out /usr/share/maven-repo on every Debian system. Firstly, this is not just about Java. On a practical level, some aspects of the project are useful for many other purposes. One of those is the aim of scanning a repository for non-free artifacts, making a Git mirror or clone containing a dfsg branch for generating repackaged upstream source and then testing to see if it still builds. Then there is the principle of software freedom. The Maven Central repository now requires that people publish a sources JAR and license metadata with each binary artifact they upload. They do not, however, demand that the sources JAR be complete or that the binary can be built by somebody else using the published sources. The license data must be specified but it does not appeared to be verified in the same way as packages inspected by Debian's legendary FTP masters. Thanks to the transitive dependency magic of Maven, it is quite possible that many Java applications that are officially promoted as free software can't trace the source code of every dependency or build plugin. Many organizations are starting to become more alarmed about the risk that they are dependent upon some rogue dependency. Maybe they will be hit with a lawsuit from a vendor stating that his plugin was only free for the first 3 months. Maybe some binary dependency JAR contains a nasty trojan for harvesting data about their corporate network. People familiar with the principles of software freedom are in the perfect position to address these concerns and Andrew's work helps us build a cleaner alternative. It obviously can't rebuild every JAR for the very reason that some of them are not really free - however, it does give the opportunity to build a heat-map of trouble spots and also create a fast track to packaging for those heirarchies of JARs that are truly free. Making WebRTC accessible to more people Juliana set out to update rtc.debian.org and this involved working on JSCommunicator, the HTML5/JavaScript softphone based on WebRTC. People attending the session today or participating remotely are advised to set up your RTC / VoIP password at db.debian.org well in advance so the server will allow you to log in and try it during the session. It can take 30 minutes or so for the passwords to be replicated to the SIP proxy and TURN server. Please also check my previous comments about what works and what doesn't and in particular, please be aware that Iceweasel / Firefox 24 on wheezy is not suitable unless you are on the same LAN as the person you are calling.

Christian Perrier: [life] Follow bubulle running adventures....

Just in case some of my free software friends would care and try understanding why I'm currently not attending my first DebConf since 2004... Starting tomorrow 07:00am EST (so, 22:00 PST for Debconfers), I'll be running the "TDS" race of the Ultra-Trail du Mont-Blanc races. Ultra-Trail du Mont-Blanc (UTMB) is one of the world famous long distance moutain trail races. It takes places in Chamonix, just below the Mont-Blanc, France's and Europe's highest moutain. The race is indeed simple : "go around the Mont-Blanc in a big circle, 160km long, with 10,000 meters positive climb cumulated on the climb of about 10 high passes between 2000 and 2700 meters altitude". "My" race is a shortened version of UTMB that does half of the full loop, from Courmayeur in Italy (just "the other side" of Mont-Blanc, from Chamonix) and goes back to Chamonix. It is "only" 120 kilometers long with 7200 meters of positive climb. Some of these are however know as more difficult than UTMB itself. Many firsts for me in this race : first "over 100km", first "over 24 hours running". Still, I trained hard for this, achieved a very though race in early July (60km, 5000m climb) with a very good result, and I expect to make it well. Top runners complete this in 17 hours.....last arrivals are expected after 33 hours "running" (often fast walking, indeed). I plan to achieve the race in 28 hours but, indeed, I have no idea..:-) So, in case you're boring in a night hacklab, or just want to draw your attention out of IRC, or don't have any package to polish...or just want to have a thought for an old friend, you can try to use the following link and follow all this live : http://utmb.livetrail.net/coureur.php?rech=6384 =en Race start : 7am EST, Wednesday Aug 27th. bubulle arrival: Thursday Aug. 28th, between 10am and 4pm (best projection is 11am). And there will be cheese at pit stops....

25 August 2014

Erich Schubert: Analyzing Twitter - beware of spam

This year I started to widen up my research; and one data source of interest was text because of the lack of structure in it, that makes it often challenging. One of the data sources that everybody seems to use is Twitter: it has a nice API, and few restrictions on using it (except on resharing data). By default, you can get a 1% random sample from all tweets, which is more than enough for many use cases.
We've had some exciting results which a colleague of mine will be presenting tomorrow (Tuesday, Research 22: Topic Modeling) at the KDD 2014 conference:
SigniTrend: Scalable Detection of Emerging Topics in Textual Streams by Hashed Significance Thresholds
Erich Schubert, Michael Weiler, Hans-Peter Kriegel
20th ACM SIGKDD Conference on Knowledge Discovery and Data Mining
You can also explore some (static!) results online at signi-trend.appspot.com

In our experiments, the "news" data set was more interesting. But after some work, we were able to get reasonable results out of Twitter as well. As you can see from the online demo, most of these fall into pop culture: celebrity deaths, sports, hip-hop. Not much that would change our live; and even less that wasn't before captured by traditional media.
The focus of this post is on the preprocessing needed for getting good results from Twitter. Because it is much easier to get bad results!
The first thing you need to realize about Twitter is that due to the media attention/hype it gets, it is full of spam. I'm pretty sure the engineers at Twitter already try to reduce spam; block hosts and fraud apps. But a lot of the trending topics we discovered were nothing but spam.
Retweets - the "like" of Twitter - are an easy source to see what is popular, but are not very interesting if you want to analyze text. They just reiterate the exact same text (except for a "RT " prefix) than earlier tweets. We found results to be more interesting if we removed retweets. Our theory is that retweeting requires much less effort than writing a real tweet; and things that are trending "with effort" are more interesting than those that were just liked.
Teenie spam. If you ever searched for a teenie idol on Twitter, say this guy I hadn't heard of before, but who has 3.88 million followers on Twitter, and search for Tweets addressed to him, you will get millions over millions of results. Many of these tweets look like this: Now if you look at this tweet, there is this odd "x804" at the end. This is to defeat a simple spam filter by Twitter. Because this user did not tweet this just once: instead it is common amongst teenie to spam their idols with follow requests by the dozen. Probably using some JavaScript hack, or third party Twitter client. Occassionally, you see hundreds of such tweets, each sent within a few seconds of the previous one. If you get a 1% sample of these, you still get a few then...
Even worse (for data analysis) than teenie spammers are commercial spammers and wannabe "hackers" that exercise their "sk1llz" by spamming Twitter. To get a sample of such spam, just search for weight loss on Twitter. There is plenty of fresh spam there, usually consisting of some text pretending to be news, and an anonymized link (there is no need to use an URL shortener such as bit.ly on Twitter, since Twitter has its own URL shortener t.co; and you'll end up with double-shortened URLs). And the hacker spam is even worse (e.g. #alvianbencifa) as he seems to have trojaned hundreds of users, and his advertisement seems to be a nonexistant hash tag, which he tries to get into Twitters "trending topics".
And then there are the bots. Plenty of bots spam Twitter with their analysis of trending topics, reinforcing the trending topics. In my opinion, bots such as trending topics indonesia are useless. No wonder there are only 280 followers. And of the trending topics reported, most of them seem to be spam topics...

Bottom line: if you plan on analyzing Twitter data, spend considerable time on preprocessing to filter out spam of various kind. For example, we remove singletons and digits, then feed the data through a duplicate detector. We end up discarding 20%-25% of Tweets. But we still get some of the spam, such as that hackers spam.
All in all, real data is just messy. People posting there have an agenda that might be opposite to yours. And if someone (or some company) promises you wonders from "Big data" and "Twitter", you better have them demonstrate their use first, before buying their services. Don't trust visions of what could be possible, because the first rule of data analysis is: Garbage in, garbage out.

24 August 2014

Vincent Sanders: Without craftsmanship, inspiration is a mere reed shaken in the wind.

While I imagine Johannes Brahms was referring to music I think the sentiment applies to other endeavours just as well. The trap of believing an idea is worth something without an implementation occurs all too often, however this is not such an unhappy tale.

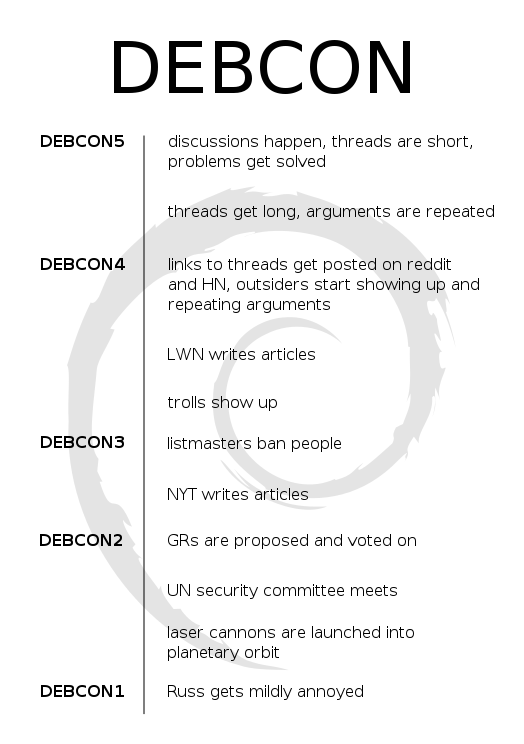
Lars original design idea
Lars Wirzenius, Steve McIntyre and myself were chatting a few weeks ago about several of the ongoing Debian discussions. As is often the case these discussions had devolved into somewhat unproductive noise and yet amongst all this was a voice of reason in Russ Allbery.

Lars decided that would take the opportunity of the upcoming opportunity of Debconf 14 to say thank you to Russ for his work. It was decided that a plaque would be a nice gift and I volunteered to do the physical manufacture. Lars came up with the idea of a DEBCON scale similar to the DEFCON scale and got some text together with an initial design idea.

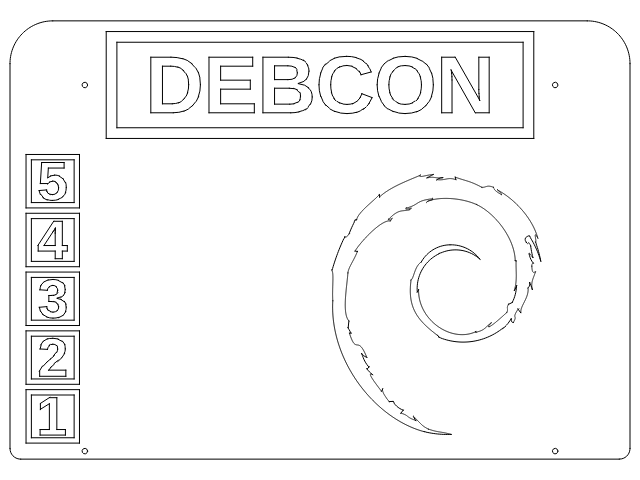
CAD drawing of cut paths in clear acrylic
I took the initial design and as is often the case what is practically possible forced several changes. The prototype was a steep learning curve on using the Cambridge makespace laser cutter to create all the separate pieces.

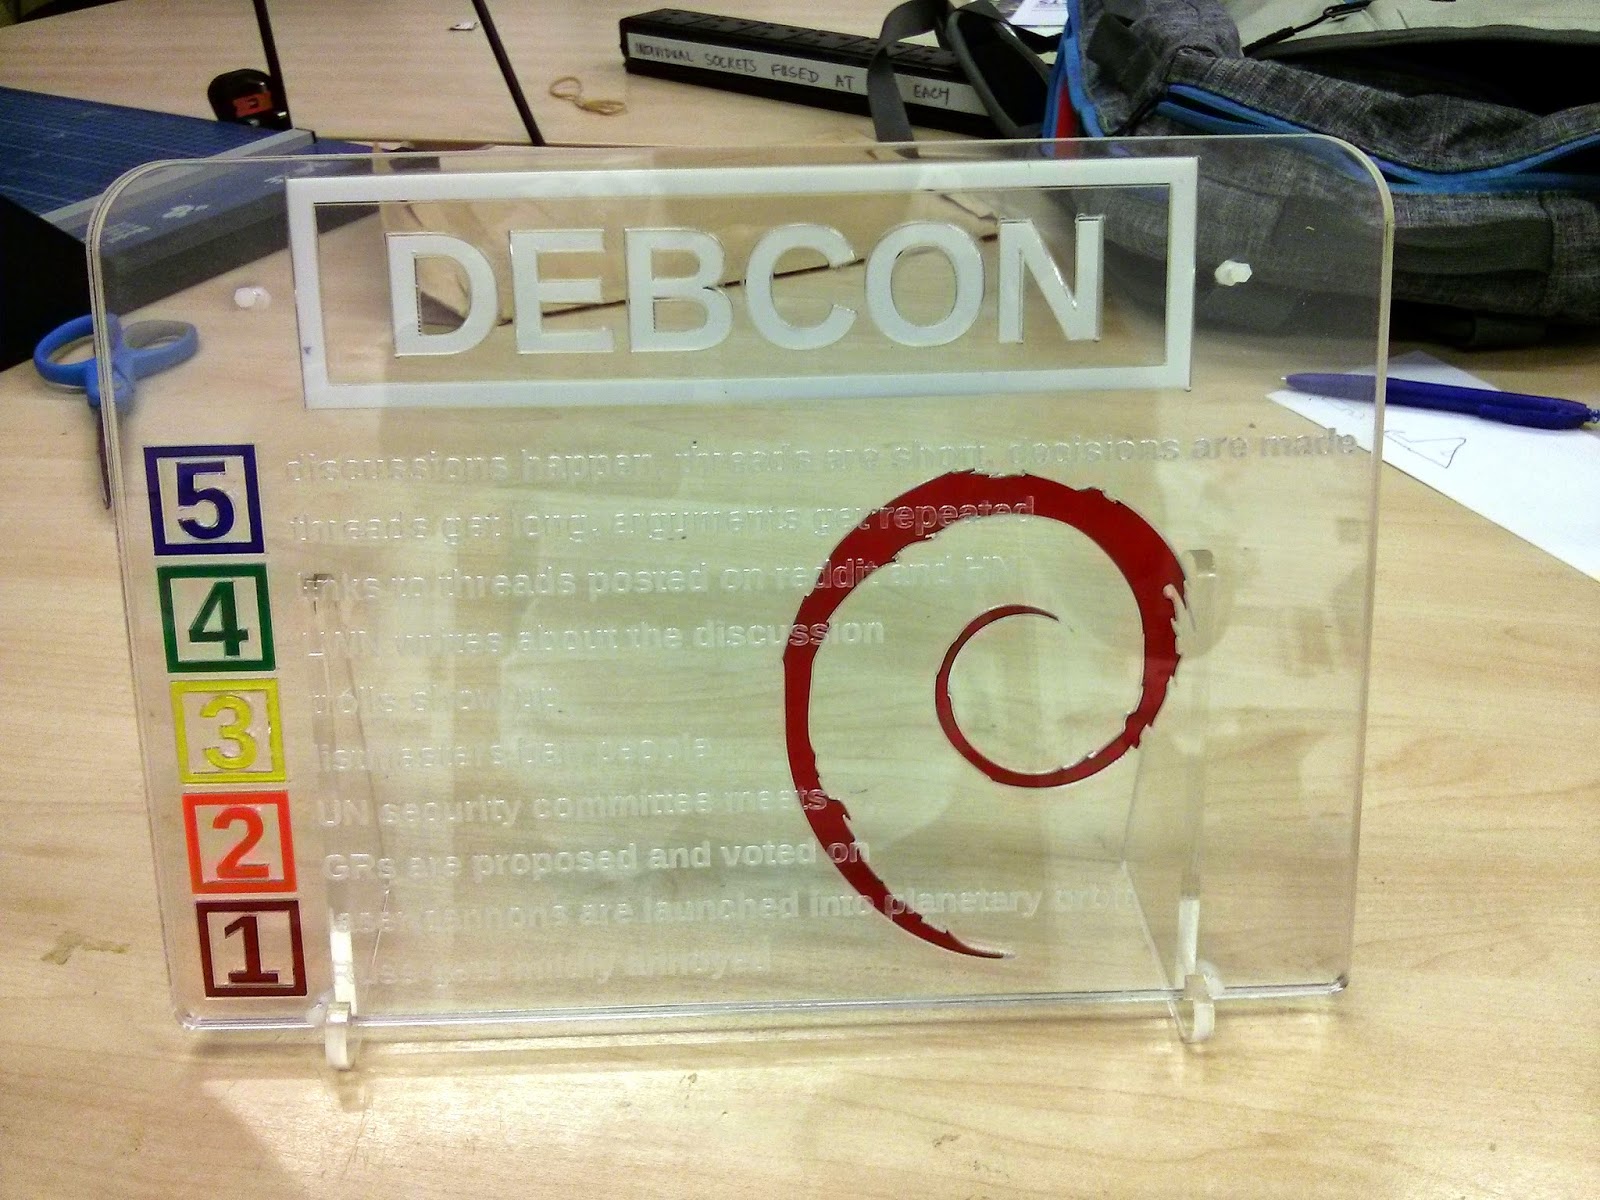
The construction is pretty simple and consisted of three layers of transparent acrylic plastic. The base layer is a single piece of plastic with the correct outline. The next layer has the DEBCON title, the Debian swirl and level numbers. The top layer has the text engraved in its back surface giving the impression the text floats above the layer behind it.

Failed prototype DEBCON plaqueFor the prototype I attempted to glue the pieces together. This was a complete disaster and required discarding the entire piece and starting again with new materials.

The final version with stand ready to be presented
For the second version I used four small nylon bolts to hold the sandwich of layers together which worked very well.

Presentation of plaque photo by Aigars Mahinovs
Yesterday at the Debconf 14 opening Steve McIntyre presented it to Russ and I think he was pleased, certainly he was surprised (photo from Aigars Mahinovs).

The design files are available from my design git repo, though why anyone would want to reproduce it I have no idea ;-)

Gregor Herrmann: Debian Perl Group Micro-Sprint

DebConf 14 has started earlier today with the first two talks in sunny portland, oregon. this year's edition of DebConf didn't feature a preceding DebCamp, & the attempts to organize a proper pkg-perl sprint were not very successful. nevertheless, two other members of the Debian Perl Group & me met here in PDX on wednesday for our informal unofficial pkg-perl -sprint, & as intended, we've used the last days to work on some pkg-perl QA stuff: as usual, having someone to poke besides you, & the opportunity to get a second pair of eyes quickly was very beneficial. & of course, spending time with my nice team mates is always a pleasure for me!

23 August 2014

Daniel Pocock: Want to be selected for Google Summer of Code 2015?

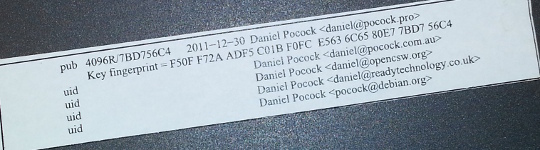
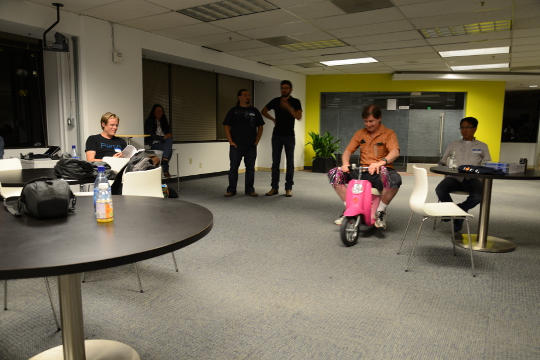
I've mentored a number of students in 2013 and 2014 for Debian and Ganglia and most of the companies I've worked with have run internships and graduate programs from time to time. GSoC 2014 has just finished and with all the excitement, many students are already asking what they can do to prepare and be selected in 2015. My own observation is that the more time the organization has to get to know the student, the more confident they can be selecting that student. Furthermore, the more time that the student has spent getting to know the free software community, the more easily they can complete GSoC. Here I present a list of things that students can do to maximize their chance of selection and career opportunities at the same time. These tips are useful for people applying for GSoC itself and related programs such as GNOME's Outreach Program for Women or graduate placements in companies. Disclaimers There is no guarantee that Google will run the program again in 2015 or any future year. There is no guarantee that any organization or mentor (including myself) will be involved until the official list of organizations is published by Google. Do not follow the advice of web sites that invite you to send pizza or anything else of value to prospective mentors. Following the steps in this page doesn't guarantee selection. That said, people who do follow these steps are much more likely to be considered and interviewed than somebody who hasn't done any of the things in this list. Understand what free software really is You may hear terms like free software and open source software used interchangeably. They don't mean exactly the same thing and many people use the term free software for the wrong things. Not all open source projects meet the definition of free software. Those that don't, usually as a result of deficiencies in their licenses, are fundamentally incompatible with the majority of software that does use genuinely free licenses. Google Summer of Code is about both writing and publishing your code and it is also about community. It is fundamental that you know the basics of licensing and how to choose a free license that empowers the community to collaborate on your code well after GSoC has finished. Please review the definition of free software early on and come back and review it from time to time. The The GNU Project / Free Software Foundation have excellent resources to help you understand what a free software license is and how it works to maximize community collaboration. Don't look for shortcuts There is no shortcut to GSoC selection and there is no shortcut to GSoC completion. The student stipend (USD $5,500 in 2014) is not paid to students unless they complete a minimum amount of valid code. This means that even if a student did find some shortcut to selection, it is unlikely they would be paid without completing meaningful work. If you are the right candidate for GSoC, you will not need a shortcut anyway. Are you the sort of person who can't leave a coding problem until you really feel it is fixed, even if you keep going all night? Have you ever woken up in the night with a dream about writing code still in your head? Do you become irritated by tedious or repetitive tasks and often think of ways to write code to eliminate such tasks? Does your family get cross with you because you take your laptop to Christmas dinner or some other significant occasion and start coding? If some of these statements summarize the way you think or feel you are probably a natural fit for GSoC. An opportunity money can't buy The GSoC stipend will not make you rich. It is intended to make sure you have enough money to survive through the summer and focus on your project. Professional developers make this much money in a week in leading business centers like New York, London and Singapore. When you get to that stage in 3-5 years, you will not even be thinking about exactly how much you made during internships. GSoC gives you an edge over other internships because it involves publicly promoting your work. Many companies still try to hide the potential of their best recruits for fear they will be poached or that they will be able to demand higher salaries. Everything you complete in GSoC is intended to be published and you get full credit for it. Imagine a young musician getting the opportunity to perform on the main stage at a rock festival. This is how the free software community works. It is a meritocracy and there is nobody to hold you back. Having a portfolio of free software that you have created or collaborated on and a wide network of professional contacts that you develop before, during and after GSoC will continue to pay you back for years to come. While other graduates are being screened through group interviews and testing days run by employers, people with a track record in a free software project often find they go straight to the final interview round. Register your domain name and make a permanent email address Free software is all about community and collaboration. Register your own domain name as this will become a focal point for your work and for people to get to know you as you become part of the community. This is sound advice for anybody working in IT, not just programmers. It gives the impression that you are confident and have a long term interest in a technology career. Choosing the provider: as a minimum, you want a provider that offers DNS management, static web site hosting, email forwarding and XMPP services all linked to your domain. You do not need to choose the provider that is linked to your internet connection at home and that is often not the best choice anyway. The XMPP foundation maintains a list of providers known to support XMPP. Create an email address within your domain name. The most basic domain hosting providers will let you forward the email address to a webmail or university email account of your choice. Configure your webmail to send replies using your personalized email address in the From header. Update your ~/.gitconfig file to use your personalized email address in your Git commits. Create a web site and blog Start writing a blog. Host it using your domain name. Some people blog every day, other people just blog once every two or three months. Create links from your web site to your other profiles, such as a Github profile page. This helps reinforce the pages/profiles that are genuinely related to you and avoid confusion with the pages of other developers. Many mentors are keen to see their students writing a weekly report on a blog during GSoC so starting a blog now gives you a head start. Mentors look at blogs during the selection process to try and gain insight into which topics a student is most suitable for. Create a profile on Github Github is one of the most widely used software development web sites. Github makes it quick and easy for you to publish your work and collaborate on the work of other people. Create an account today and get in the habbit of forking other projects, improving them, committing your changes and pushing the work back into your Github account. Github will quickly build a profile of your commits and this allows mentors to see and understand your interests and your strengths. In your Github profile, add a link to your web site/blog and make sure the email address you are using for Git commits (in the ~/.gitconfig file) is based on your personal domain. Start using PGP Pretty Good Privacy (PGP) is the industry standard in protecting your identity online. All serious free software projects use PGP to sign tags in Git, to sign official emails and to sign official release files. The most common way to start using PGP is with the GnuPG (GNU Privacy Guard) utility. It is installed by the package manager on most Linux systems. When you create your own PGP key, use the email address involving your domain name. This is the most permanent and stable solution. Print your key fingerprint using the gpg-key2ps command, it is in the signing-party package on most Linux systems. Keep copies of the fingerprint slips with you. This is what my own PGP fingerprint slip looks like. You can also print the key fingerprint on a business card for a more professional look. Using PGP, it is recommend that you sign any important messages you send but you do not have to encrypt the messages you send, especially if some of the people you send messages to (like family and friends) do not yet have the PGP software to decrypt them. If using the Thunderbird (Icedove) email client from Mozilla, you can easily send signed messages and validate the messages you receive using the Enigmail plugin. Get your PGP key signed Once you have a PGP key, you will need to find other developers to sign it. For people I mentor personally in GSoC, I'm keen to see that you try and find another Debian Developer in your area to sign your key as early as possible. Free software events Try and find all the free software events in your area in the months between now and the end of the next Google Summer of Code season. Aim to attend at least two of them before GSoC. Look closely at the schedules and find out about the individual speakers, the companies and the free software projects that are participating. For events that span more than one day, find out about the dinners, pub nights and other social parts of the event. Try and identify people who will attend the event who have been GSoC mentors or who intend to be. Contact them before the event, if you are keen to work on something in their domain they may be able to make time to discuss it with you in person. Take your PGP fingerprint slips. Even if you don't participate in a formal key-signing party at the event, you will still find some developers to sign your PGP key individually. You must take a photo ID document (such as your passport) for the other developer to check the name on your fingerprint but you do not give them a copy of the ID document. Events come in all shapes and sizes. FOSDEM is an example of one of the bigger events in Europe, linux.conf.au is a similarly large event in Australia. There are many, many more local events such as the Debian France mini-DebConf in Lyon, 2015. Many events are either free or free for students but please check carefully if there is a requirement to register before attending. On your blog, discuss which events you are attending and which sessions interest you. Write a blog during or after the event too, including photos. Quantcast generously hosted the Ganglia community meeting in San Francisco, October 2013. We had a wild time in their offices with mini-scooters, burgers, beers and the Ganglia book. That's me on the pink mini-scooter and Bernard Li, one of the other Ganglia GSoC 2014 admins is on the right. Install Linux GSoC is fundamentally about free software. Linux is to free software what a tree is to the forest. Using Linux every day on your personal computer dramatically increases your ability to interact with the free software community and increases the number of potential GSoC projects that you can participate in. This is not to say that people using Mac OS or Windows are unwelcome. I have worked with some great developers who were not Linux users. Linux gives you an edge though and the best time to gain that edge is now, while you are a student and well before you apply for GSoC. If you must run Windows for some applications used in your course, it will run just fine in a virtual machine using Virtual Box, a free software solution for desktop virtualization. Use Linux as the primary operating system. Here are links to download ISO DVD (and CD) images for some of the main Linux distributions: If you are nervous about getting started with Linux, install it on a spare PC or in a virtual machine before you install it on your main PC or laptop. Linux is much less demanding on the hardware than Windows so you can easily run it on a machine that is 5-10 years old. Having just 4GB of RAM and 20GB of hard disk is usually more than enough for a basic graphical desktop environment although having better hardware makes it faster. Your experiences installing and running Linux, especially if it requires some special effort to make it work with some of your hardware, make interesting topics for your blog. Decide which technologies you know best Personally, I have mentored students working with C, C++, Java, Python and JavaScript/HTML5. In a GSoC program, you will typically do most of your work in just one of these languages. From the outset, decide which language you will focus on and do everything you can to improve your competence with that language. For example, if you have already used Java in most of your course, plan on using Java in GSoC and make sure you read Effective Java (2nd Edition) by Joshua Bloch. Decide which themes appeal to you Find a topic that has long-term appeal for you. Maybe the topic relates to your course or maybe you already know what type of company you would like to work in. Here is a list of some topics and some of the relevant software projects:
  • System administration, servers and networking: consider projects involving monitoring, automation, packaging. Ganglia is a great community to get involved with and you will encounter the Ganglia software in many large companies and academic/research networks. Contributing to a Linux distribution like Debian or Fedora packaging is another great way to get into system administration.
  • Desktop and user interface: consider projects involving window managers and desktop tools or adding to the user interface of just about any other software.
  • Big data and data science: this can apply to just about any other theme. For example, data science techniques are frequently used now to improve system administration.
  • Business and accounting: consider accounting, CRM and ERP software.
  • Finance and trading: consider projects like R, market data software like OpenMAMA and connectivity software (Apache Camel)
  • Real-time communication (RTC), VoIP, webcam and chat: look at the JSCommunicator or the Jitsi project
  • Web (JavaScript, HTML5): look at the JSCommunicator
Before the GSoC application process begins, you should aim to learn as much as possible about the theme you prefer and also gain practical experience using the software relating to that theme. For example, if you are attracted to the business and accounting theme, install the PostBooks suite and get to know it. Maybe you know somebody who runs a small business: help them to upgrade to PostBooks and use it to prepare some reports. Make something Make some small project, less than two week's work, to demonstrate your skills. It is important to make something that somebody will use for a practical purpose, this will help you gain experience communicating with other users through Github. For an example, see the servlet Juliana Louback created for fixing phone numbers in December 2013. It has since been used as part of the Lumicall web site and Juliana was selected for a GSoC 2014 project with Debian. There is no better way to demonstrate to a prospective mentor that you are ready for GSoC than by completing and publishing some small project like this yourself. If you don't have any immediate project ideas, many developers will also be able to give you tips on small projects like this that you can attempt, just come and ask us on one of the mailing lists. Ideally, the project will be something that you would use anyway even if you do not end up participating in GSoC. Such projects are the most motivating and rewarding and usually end up becoming an example of your best work. To continue the example of somebody with a preference for business and accounting software, a small project you might create is a plugin or extension for PostBooks. Getting to know prospective mentors Many web sites provide useful information about the developers who contribute to free software projects. Some of these developers may be willing to be a GSoC mentor. For example, look through some of the following: Getting on the mentor's shortlist Once you have identified projects that are interesting to you and developers who work on those projects, it is important to get yourself on the developer's shortlist. Basically, the shortlist is a list of all students who the developer believes can complete the project. If I feel that a student is unlikely to complete a project or if I don't have enough information to judge a student's probability of success, that student will not be on my shortlist. If I don't have any student on my shortlist, then a project will not go ahead at all. If there are multiple students on the shortlist, then I will be looking more closely at each of them to try and work out who is the best match. One way to get a developer's attention is to look at bug reports they have created. Github makes it easy to see complaints or bug reports they have made about their own projects or other projects they depend on. Another way to do this is to search through their code for strings like FIXME and TODO. Projects with standalone bug trackers like the Debian bug tracker also provide an easy way to search for bug reports that a specific person has created or commented on. Once you find some relevant bug reports, email the developer. Ask if anybody else is working on those issues. Try and start with an issue that is particularly easy and where the solution is interesting for you. This will help you learn to compile and test the program before you try to fix any more complicated bugs. It may even be something you can work on as part of your academic program. Find successful projects from the previous year Contact organizations and ask them which GSoC projects were most successful. In many organizations, you can find the past students' project plans and their final reports published on the web. Read through the plans submitted by the students who were chosen. Then read through the final reports by the same students and see how they compare to the original plans. Start building your project proposal now Don't wait for the application period to begin. Start writing a project proposal now. When writing a proposal, it is important to include several things:
  • Think big: what is the goal at the end of the project? Does your work help the greater good in some way, such as increasing the market share of Linux on the desktop?
  • Details: what are specific challenges? What tools will you use?
  • Time management: what will you do each week? Are there weeks where you will not work on GSoC due to vacation or other events? These things are permitted but they must be in your plan if you know them in advance. If an accident or death in the family cut a week out of your GSoC project, which work would you skip and would your project still be useful without that? Having two weeks of flexible time in your plan makes it more resilient against interruptions.
  • Communication: are you on mailing lists, IRC and XMPP chat? Will you make a weekly report on your blog?
  • Users: who will benefit from your work?
  • Testing: who will test and validate your work throughout the project? Ideally, this should involve more than just the mentor.
If your project plan is good enough, could you put it on Kickstarter or another crowdfunding site? This is a good test of whether or not a project is going to be supported by a GSoC mentor. Learn about packaging and distributing software Packaging is a vital part of the free software lifecycle. It is very easy to upload a project to Github but it takes more effort to have it become an official package in systems like Debian, Fedora and Ubuntu. Packaging and the communities around Linux distributions help you reach out to users of your software and get valuable feedback and new contributors. This boosts the impact of your work. To start with, you may want to help the maintainer of an existing package. Debian packaging teams are existing communities that work in a team and welcome new contributors. The Debian Mentors initiative is another great starting place. In the Fedora world, the place to start may be in one of the Special Interest Groups (SIGs). Think from the mentor's perspective After the application deadline, mentors have just 2 or 3 weeks to choose the students. This is actually not a lot of time to be certain if a particular student is capable of completing a project. If the student has a published history of free software activity, the mentor feels a lot more confident about choosing the student. Some mentors have more than one good student while other mentors receive no applications from capable students. In this situation, it is very common for mentors to send each other details of students who may be suitable. Once again, if a student has a good Github profile and a blog, it is much easier for mentors to try and match that student with another project. GSoC logo generic Conclusion Getting into the world of software engineering is much like joining any other profession or even joining a new hobby or sporting activity. If you run, you probably have various types of shoe and a running watch and you may even spend a couple of nights at the track each week. If you enjoy playing a musical instrument, you probably have a collection of sheet music, accessories for your instrument and you may even aspire to build a recording studio in your garage (or you probably know somebody else who already did that). The things listed on this page will not just help you walk the walk and talk the talk of a software developer, they will put you on a track to being one of the leaders. If you look over the profiles of other software developers on the Internet, you will find they are doing most of the things on this page already. Even if you are not selected for GSoC at all or decide not to apply, working through the steps on this page will help you clarify your own ideas about your career and help you make new friends in the software engineering community.
Steve Kemp: Updating Debian Administration, the code

So I previously talked about the setup behind Debian Administration, and my complaints about the slownes. The previous post talked about the logical setup, and the hardware. This post talks about the more interesting thing. The code. The code behind the site was originally written by Denny De La Haye. I found it and reworked it a lot, most obviously adding structure and test cases. Once I did that the early version of the site was born. Later my version became the official version, as when Denny setup Police State UK he used my codebase rather than his. So the code huh? Well as you might expect it is written in Perl. There used to be this layout:
]
yawns/cgi-bin/index.cgi
yawns/cgi-bin/Pages.pl
yawns/lib/...
yawns/htdocs/
Almost every request would hit the index.cgi script, which would parse the request and return the appropriate output via the standard CGI interface. How did it know what you wanted? Well sometimes there would be a paramater set which would be looked up in a dispatch-table:
/cgi-bin/index.cgi?article=40         - Show article 40
/cgi-bin/index.cgi?view_user=Steve    - Show the user Steve
/cgi-bin/index.cgi?recent_comments=10 - Show the most recent comments.
Over time the code became hard to update because there was no consistency, and over time the site became slow because this is not a quick setup. Spiders, bots, and just average users would cause a lot of perl processes to run. So? What did I do? I moved the thing to using FastCGI, which avoids the cost of forking Perl and loading (100k+) the code. Unfortunately this required a bit of work because all the parameter handling was messy and caused issues if I just renamed index.cgi -> index.fcgi. The most obvious solution was to use one parameter, globally, to specify the requested mode of operation. Hang on? One parameter to control the page requested? A persistant environment? What does that remind me of? Yes. CGI::Application. I started small, and pulled some of the code out of index.cgi + Pages.pl, and over into a dedicated CGI::Application class: So now every part of the site that is called by Ajax has one persistent handler, and every part of the site which returns RSS feeds has another. I had some fun setting up the sessions to match those created by the old stuff, but I quickly made it work, as this example shows: The final job was the biggest, moving all the other (non-feed, non-ajax) modes over to a similar CGI::Application structure. There were 53 modes that had to be ported, and I did them methodically, first porting all the Poll-related requests, then all the article-releated ones, & etc. I think I did about 15 a day for three days. Then the rest in a sudden rush. In conclusion the code is now fast because we don't use CGI, and instead use FastCGI. This allowed minor changes to be carried out, such as compiling the HTML::Template templates which determine the look and feel, etc. Those things don't make sense in the CGI environment, but with persistence they are essentially free. The site got a little more of a speed boost when I updated DNS, and a lot more when I blacklisted a bunch of IP-space. As I was wrapping this up I realized that the code had accidentally become closed - because the old repository no longer exists. That is not deliberate, or intentional, and will be rectified soon. The site would never have been started if I'd not seen Dennys original project, and although I don't think others would use the code it should be possible. I remember at the time I was searching for things like "Perl CMS" and finding Slashcode, and Scoop, which I knew were too heavyweight for my little toy blog. In conclusion Debian Administration website is 10 years old now. It might not have changed the world, it might have become less relevant, but I'm glad I tried, and I'm glad there were years when it really was the best place to be. These days there are HowtoForges, blogs, spam posts titled "How to install SSH on Trusty", "How to install SSH on Wheezy", "How to install SSH on Precise", and all that. No shortage of content, just finding the good from the bad is the challenge. Me? The single best resource I read these days is probably LWN.net. Starting to ramble now. Go look at my quick hack for remote command execution https://github.com/skx/nanoexec ?

22 August 2014

Russell Coker: Men Commenting on Women s Issues

A lecture at LCA 2011 which included some inappropriate slides was followed by long discussions on mailing lists. In February 2011 I wrote a blog post debunking some of the bogus arguments in two lists [1]. One of the noteworthy incidents in the mailing list discussion concerned Ted Ts o (an influential member of the Linux community) debating the definition of rape. My main point on that issue in Feb 2011 was that it s insensitive to needlessly debate the statistics. Recently Valerie Aurora wrote about another aspect of this on The Ada Initiative blog [2] and on her personal blog. Some of her significant points are that conference harassment doesn t end when the conference ends (it can continue on mailing lists etc), that good people shouldn t do nothing when bad things happen, and that free speech doesn t mean freedom from consequences or the freedom to use private resources (such as conference mailing lists) without restriction. Craig Sanders wrote a very misguided post about the Ted Ts o situation [3]. One of the many things wrong with his post is his statement I m particularly disgusted by the men who intervene way too early without an explicit invitation or request for help or a clear need such as an immediate threat of violence in womens issues . I believe that as a general rule when any group of people are involved in causing a problem they should be involved in fixing it. So when we have problems that are broadly based around men treating women badly the prime responsibility should be upon men to fix them. It seems very clear that no matter what scope is chosen for fixing the problems (whether it be lobbying for new legislation, sociological research, blogging, or directly discussing issues with people to change their attitudes) women are doing considerably more than half the work. I believe that this is an indication that overall men are failing. Asking for Help I don t believe that members of minority groups should have to ask for help. Asking isn t easy, having someone spontaneously offer help because it s the right thing to do can be a lot easier to accept psychologically than having to beg for help. There is a book named Women Don t Ask which has a page on the geek feminism Wiki [4]. I think the fact that so many women relate to a book named Women Don t Ask is an indication that we shouldn t expect women to ask directly, particularly in times of stress. The Wiki page notes a criticism of the book that some specific requests are framed as complaining , so I think we should consider a complaint from a woman as a direct request to do something. The geek feminism blog has an article titled How To Exclude Women Without Really Trying which covers many aspects of one incident [5]. Near the end of the article is a direct call for men to be involved in dealing with such problems. The geek feminism Wiki has a page on Allies which includes Even a blog post helps [6]. It seems clear from public web sites run by women that women really want men to be involved. Finally when I get blog comments and private email from women who thank me for my posts I take it as an implied request to do more of the same. One thing that we really don t want is to have men wait and do nothing until there is an immediate threat of violence. There are two massive problems with that plan, one is that being saved from a violent situation isn t a fun experience, the other is that an immediate threat of violence is most likely to happen when there is no-one around to intervene. Men Don t Listen to Women Rebecca Solnit wrote an article about being ignored by men titled Men Explain Things to Me [7]. When discussing women s issues the term Mansplaining is often used for that sort of thing, the geek feminism Wiki has some background [8]. It seems obvious that the men who have the greatest need to be taught some things related to women s issues are the ones who are least likely to listen to women. This implies that other men have to teach them. Craig says that women need space to discover and practice their own strength and their own voices . I think that the best way to achieve that goal is to listen when women speak. Of course that doesn t preclude speaking as well, just listen first, listen carefully, and listen more than you speak. Craig claims that when men like me and Matthew Garrett comment on such issues we are making women s spaces more comfortable, more palatable, for men . From all the discussion on this it seems quite obvious that what would make things more comfortable for men would be for the issue to never be discussed at all. It seems to me that two of the ways of making such discussions uncomfortable for most men are to discuss sexual assault and to discuss what should be done when you have a friend who treats women in a way that you don t like. Matthew has covered both of those so it seems that he s doing a good job of making men uncomfortable I think that this is a good thing, a discussion that is comfortable and palatable for the people in power is not going to be any good for the people who aren t in power. The Voting Aspect It seems to me that when certain issues are discussed we have a social process that is some form of vote. If one person complains then they are portrayed as crazy. When other people agree with the complaint then their comments are marginalised to try and preserve the narrative of one crazy person. It seems that in the case of the discussion about Rape Apology and LCA2011 most men who comment regard it as one person (either Valeria Aurora or Matthew Garrett) causing a dispute. There is even some commentary which references my blog post about Rape Apology [9] but somehow manages to ignore me when it comes to counting more than one person agreeing with Valerie. For reference David Zanetti was the first person to use the term apologist for rapists in connection with the LCA 2011 discussion [10]. So we have a count of at least three men already. These same patterns always happen so making a comment in support makes a difference. It doesn t have to be insightful, long, or well written, merely I agree and a link to a web page will help. Note that a blog post is much better than a comment in this regard, comments are much like conversation while a blog post is a stronger commitment to a position. I don t believe that the majority is necessarily correct. But an opinion which is supported by too small a minority isn t going to be considered much by most people. The Cost of Commenting The Internet is a hostile environment, when you comment on a contentious issue there will be people who demonstrate their disagreement in uncivilised and even criminal ways. S. E. Smith wrote an informative post for Tiger Beatdown about the terrorism that feminist bloggers face [11]. I believe that men face fewer threats than women when they write about such things and the threats are less credible. I don t believe that any of the men who have threatened me have the ability to carry out their threats but I expect that many women who receive such threats will consider them to be credible. The difference in the frequency and nature of the terrorism (and there is no other word for what S. E. Smith describes) experienced by men and women gives a vastly different cost to commenting. So when men fail to address issues related to the behavior of other men that isn t helping women in any way. It s imposing a significant cost on women for covering issues which could be addressed by men for minimal cost. It s interesting to note that there are men who consider themselves to be brave because they write things which will cause women to criticise them or even accuse them of misogyny. I think that the women who write about such issues even though they will receive threats of significant violence are the brave ones. Not Being Patronising Craig raises the issue of not being patronising, which is of course very important. I think that the first thing to do to avoid being perceived as patronising in a blog post is to cite adequate references. I ve spent a lot of time reading what women have written about such issues and cited the articles that seem most useful in describing the issues. I m sure that some women will disagree with my choice of references and some will disagree with some of my conclusions, but I think that most women will appreciate that I read what women write (it seems that most men don t). It seems to me that a significant part of feminism is about women not having men tell them what to do. So when men offer advice on how to go about feminist advocacy it s likely to be taken badly. It s not just that women don t want advice from men, but that advice from men is usually wrong. There are patterns in communication which mean that the effective strategies for women communicating with men are different from the effective strategies for men communicating with men (see my previous section on men not listening to women). Also there s a common trend of men offering simplistic advice on how to solve problems, one thing to keep in mind is that any problem which affects many people and is easy to solve has probably been solved a long time ago. Often when social issues are discussed there is some background in the life experience of the people involved. For example Rookie Mag has an article about the street harassment women face which includes many disturbing anecdotes (some of which concern primary school students) [12]. Obviously anyone who has lived through that sort of thing (which means most women) will instinctively understand some issues related to threatening sexual behavior that I can t easily understand even when I spend some time considering the matter. So there will be things which don t immediately appear to be serious problems to me but which are interpreted very differently by women. The non-patronising approach to such things is to accept the concerns women express as legitimate, to try to understand them, and not to argue about it. For example the issue that Valerie recently raised wasn t something that seemed significant when I first read the email in question, but I carefully considered it when I saw her posts explaining the issue and what she wrote makes sense to me. I don t think it s possible for a man to make a useful comment on any issue related to the treatment of women without consulting multiple women first. I suggest a pre-requisite for any man who wants to write any sort of long article about the treatment of women is to have conversations with multiple women who have relevant knowledge. I ve had some long discussions with more than a few women who are involved with the FOSS community. This has given me a reasonable understanding of some of the issues (I won t claim to be any sort of expert). I think that if you just go and imagine things about a group of people who have a significantly different life-experience then you will be wrong in many ways and often offensively wrong. Just reading isn t enough, you need to have conversations with multiple people so that they can point out the things you don t understand. This isn t any sort of comprehensive list of ways to avoid being patronising, but it s a few things which seem like common mistakes. Anne Onne wrote a detailed post advising men who want to comment on feminist blogs etc [13], most of it applies to any situation where men comment on women s issues.

Ian Donnelly: Wrapping Up

Hi Everybody! I have been keeping very busy on this blog the past few days with some very exciting updates! Everything is now in place for my Google Summer of Code project! Elektra now has the ability to merge KeySets, ucf has been patched to allow custom merge commands, we included a new elektra-merge script to use in conjunction with the new ucf command, and we wrote a great tutorial on how to use Elektra to merge configuration files in any package using ucf. There are few things I have missed updating you all on or are still wrapping up. First of all, I would like to address the Debian packages. While Elektra includes everything needed for my Google Summer of Code Project, it must be built from source right now. Unfortunately, with the rapid development Elektra has seen the past few months, we did not pay enough attention to the Debian packages and they became dusty and riddles with bugs. Fortunately, we have a solution and his name is Pino Toscano. Pino has, very graciously, agreed to help us fix our Debian packages back into shape. If you wish to see the current progress of the packages, you can check his repo. Pino has already made fantastic progress creating the Debian packages. I will post here when packages are all fixed up and the latest versions of Elektra are into the Debian repo. Some great news that we just received is that Elektra 0.8.7 has just been accepted into Debian unstable! This is huge progress for our team and means that users can now download our packages directly from Debian s unstable repo and test out these new features. Obviously, the normal caveats apply for any packages in unstable but this is still an amazing piece of news and I would like to thank Pino again for all the support he has provided. Another worthy piece of news that I unfortunately haven t had time to cover is that thanks to Felix Berlakovich Elektra has a new plug-in called ini. In case you couldn t guess, this new plug-in is used to mount ini files and the good news is that it is a vast improvement on our older simpleini plug-in. While it is still a work in progress, this new plug-in is much more powerful than simpleini. The new plug-in supports section and comments and works with many more ini files than the old plug-in. You may have noticed that I used this new plug-in to mount smb.conf in my technical demo of Samba using Elektra from configuration merging. Since smb.conf follows the same syntax as an ini file this new plug-in works great for mounting this file into the Elektra Key Database. I hope my blogs so far have been very informative and helpful. Sincerely,
Ian S. Donnelly

21 August 2014

Wouter Verhelst: Multiarchified eID libraries, now public

Yesterday, I spent most of the day finishing up the multiarch work I'd been doing on introducing multiarch to the eID middleware, and did another release of the Linux builds. As such, it's now possible to install 32-bit versions of the eID middleware on a 64-bit Linux distribution. For more details, please see the announcement. Learning how to do multiarch (or biarch, as the case may be) for three different distribution families has been a, well, learning experience. Being a Debian Developer, figuring out the technical details for doing this on Debian and its derivatives wasn't all that hard. You just make sure the libraries are installed to the multiarch-safe directories (i.e., /usr/lib/<gnu arch triplet>), you add some Multi-Arch: foreign or Multi-Arch: same headers where appropriate, and you're done. Of course the devil is in the details (define "where appropriate"), but all in all it's not that difficult and fairly deterministic. The Fedora (and derivatives, like RHEL) approach to biarch is that 64-bit distributions install into /usr/lib64 and 32-bit distributions install into /usr/lib. This goes for any architecture family, not just the x86 family; the same method works on ppc and ppc64. However, since fedora doesn't do powerpc anymore, that part is a detail of little relevance. Once that's done, yum has some heuristics whereby it will prefer native-architecture versions of binaries when asked, and may install both the native-architecture and foreign-architecture version of a particular library package at the same time. Since RPM already has support for installing multiple versions of the same package on the same system (a feature that was originally created, AIUI, to support the installation of multiple kernel versions), that's really all there is to it. It feels a bit fiddly and somewhat fragile, since there isn't really a spec and some parts seem fairly undefined, but all in all it seems to work well enough in practice. The openSUSE approach is vastly different to the other two. Rather than installing the foreign-architecture packages natively, as in the Debian and Fedora approaches, openSUSE wants you to take the native foo.ix86.rpm package and convert that to a foo-32bit.x86_64.rpm package. The conversion process filters out non-unique files (only allows files to remain in the package if they are in library directories, IIUC), and copes with the lack of license files in /usr/share/doc by adding a dependency header on the native package. While the approach works, it feels like unnecessary extra work and bandwidth to me, and obviously also wouldn't scale beyond biarch. It also isn't documented very well; when I went to openSUSE IRC channels and started asking questions, the reply was something along the lines of "hand this configuration file to your OBS instance". When I told them I wasn't actually using OBS and had no plans of migrating to it (because my current setup is complex enough as it is, and replacing it would be far too much work for too little gain), it suddenly got eerily quiet. Eventually I found out that the part of OBS which does the actual build is a separate codebase, and integrating just that part into my existing build system was not that hard to do, even though it doesn't come with a specfile or RPM package and wants to install files into /usr/bin and /usr/lib. With all that and some more weirdness I've found in the past few months that I've been building packages for openSUSE I now have... Ideas(TM) about how openSUSE does things. That's for another time, though. (disclaimer: there's a reason why I'm posting this on my personal blog and not on an official website... don't take this as an official statement of any sort!)

Gunnar Wolf: Walking without crutches

Walking without crutches
I still consider myself a newbie teacher. I'm just starting my fourth semester. And yes, I really enjoy it. Now, how did I come to teaching? Well, my training has been mostly on stages for different conferences. More technical, more social, whatever I have been giving ~10 talks a year for ~15 years, and I must have learnt something from that. Some good things, some bad habits. When giving presentations, a most usual technique is to prepare a set of slides to follow/support the ideas. And yes, that's what I did for my classes: Since my first semester, I prepared a nice set of slides, thematically split in 17 files, with ~30 to ~110 pages each (yes, huge variation). Given the course spans 32 classes (72 hours, 2 hours per class), each slide lasts for about two classes. But, yes, this tends to make the class much less dynamic, much more scripted, rigid, and... Boring. From my feedback, I understand the students don't think I am a bad teacher, but still, I want to improve! So, today I was to give the introduction to memory management. Easy topic, with few diagrams and numbers, mostly talking about the intuitive parts of a set of functions. I started scribbling and shortening the main points on a piece of paper (yes, the one on the picture). I am sure I can get down to more reduction But this does feel like an improvement! The class was quite successful. I didn't present the 100% of the material (which is one of the reasons I cling to my presentations I don't want to skip important material), and at some point I do feel I was a bit going in circles. However, Operating Systems is a very intuitive subject, and getting the students to sketch by themselves the answers that describe the working of real operating systems was a very pleasant experience! Of course, when I use my slides I do try to make it as interactive and collaborative as possible. But it is often unfeasible when I'm following a script. Today I was able to go around with the group's questions, find my way back to the outline I prepared. I don't think I'll completely abandon my slides, specially for some subjects which include many diagrams or pictures. But I'll try to have this alternative closer to my mind.

20 August 2014

Olivier Berger: Building a lab VM based on Debian for a MOOC, using Vagrant + VirtualBox

We ve been busy setting up a Virtual Machine (VM) image to be used by participants of a MOOC that s opening in early september on Relational Databases at Telecom SudParis. We ve chosen to use Vagrant and VirtualBox which are used to build, distribute and run the box, providing scriptability (reproducibility) and making it portable on most operating systems. The VM itself contains a Debian (jessie) minimal system which runs (in the background) PostgreSQL, Apache + mod_php, phpPgAdmin, and a few applications of our own to play with example databases already populated in PostgreSQL.
As the MOOC s language will be french, we expect the box to be used mostly on machines with azerty keyboards. This and other context elements led us to add some customizations (locale, APT mirror) in provisioning scripts run during the box creation. At the moment, we generate 2 variants of the box, one for 32 bits kernel (i686) and one for 64 bits kernel (amd64) which (once compressed) represent betw. 300 and 350 Mb. The resulting boxes are uploaded to a self-hosting site, and distributed through vagrantcloud. Once the VM are created in VirtualBox, the typical VMDK drives file is around 1.3Gb. We use our own Debian base boxes containing a minimal Debian jessie/testing, instead of relying on someone else s, and recreate them using (the development branch version of) bootsrap-vz. This ensure we can put more trust in the content as it s a native Debian package installation without MITM intervention. The VM are meant to be run headless for the moment, keeping their size to the minimum, even though we also provide a script to install and configure a desktop environment based on XFCE4. The applications are either used through vagrant ssh, for instance for SQL command-line in psql, or in the Web browser, for our own Web based SQL exerciser, or phpPgAdmin (see a demo screencast (in french, w/ english subtitles)), which can then be used even off-line by the participants, which also means this requires no servers availability for our IT staff.
The MOOC includes a section on PHP + SQL programming, whose exercises can be performed using a shared sub-folder of /vagrant/ which allows editing on the host with the favourite native editor/IDE, while running PHP inside the VM s Apache + mod_php. The sources of our environment are available as free software, if you re interested to replicate a similar environment for another project. As we re still polishing the environment before the MOOC opening (on september 10th), I m not mentioning the box URLs but they shouldn t be too hard to find if you re investigating (refering to the fusionforge project s web site). We don t know yet how suitable this environment will be for learning SQL and database design and programming, and if Vagrant will bring more difficulties than benefits. Still we hope that the participants will find this practical, allowing them to work on the lab / exercises whenever and wherever they chose, removing the pain of installing and configuring a RDBMS on their machines, or the need to be connected to a cloud or to our overloaded servers. Of course, one limitation will be the requirements on the host machines, that will need to be reasonably modern, in order to run a virtualized Linux system. Another is access to high bandwidth for downloading the boxes, but this is kind of a requirement already for downloading/watching the videos of the MOOC classes ;-) Big thanks go to our intern St phane Germain, who joined us this summer to work on this virtualized environment.

Gunnar Wolf: Bigger than the cloud

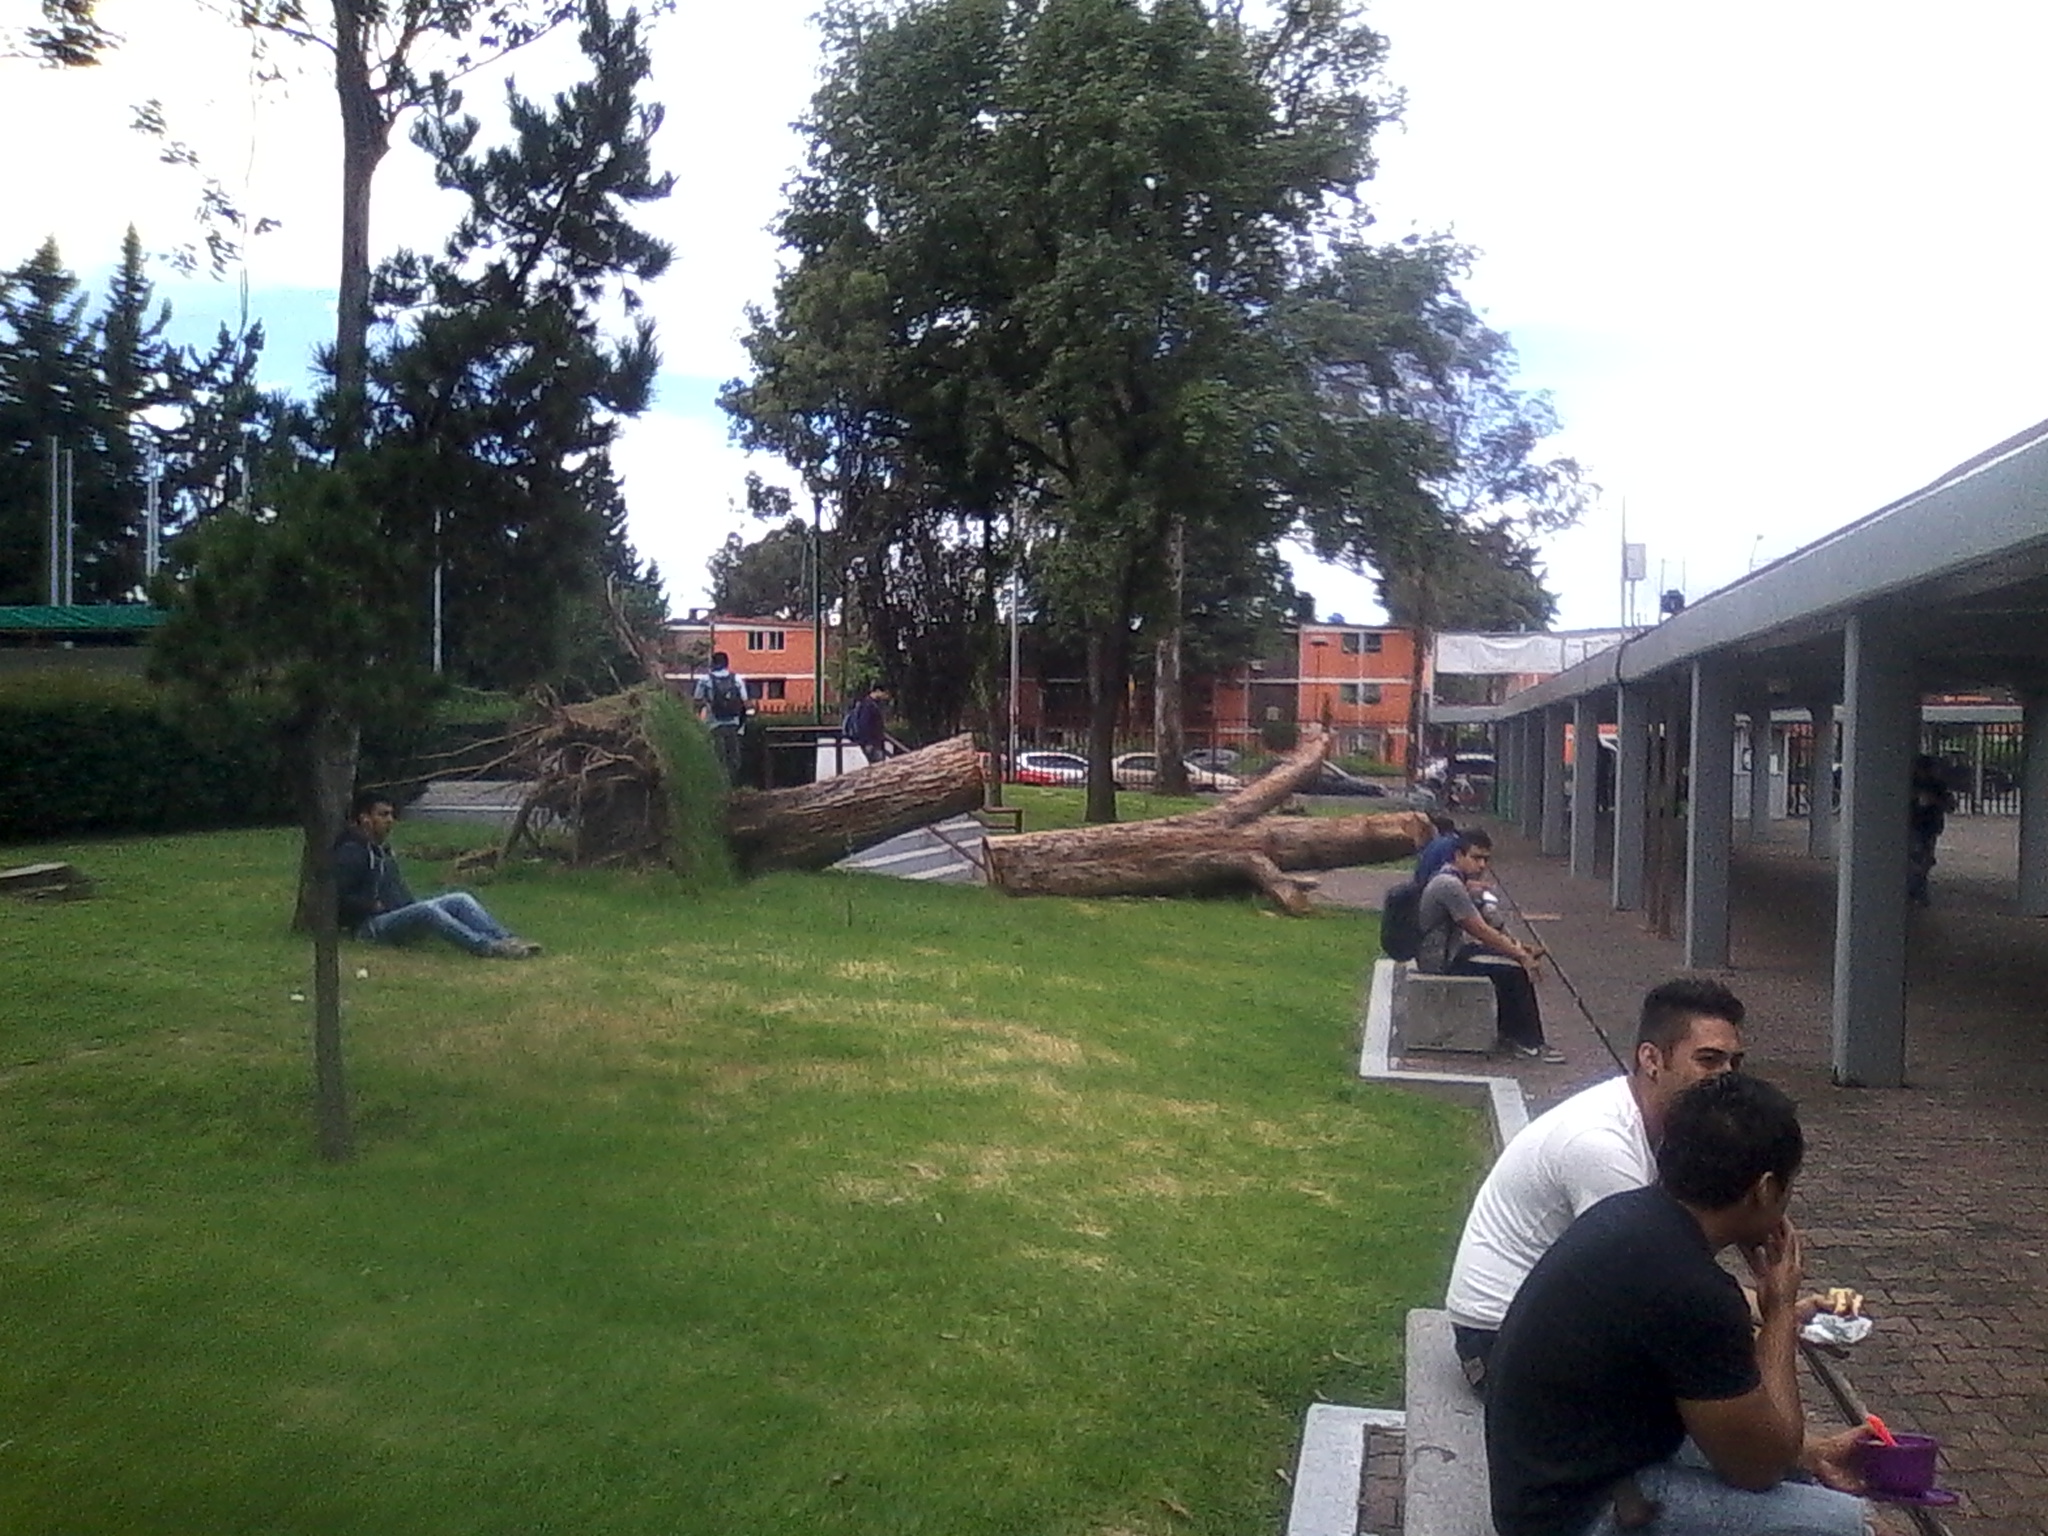
Summer is cool in Mexico City. It is cool because, unlike Spring, this is our rainy season And rains are very predictable. Almost every day we wake up with a gorgeous, clean, blue sky. Cool, nice temperature, around 15 C. The sun slowly evaporates the rain throughout the morning; when I go out for lunch, the sky is no longer so blue, giving way to a seemingly dirty white/grayish tint. No, it's not our world-famous pollution: It's just yesterday's rain. Rain starts falling usually between 4 and 7 PM. Sometimes it starts as a light rain, sometimes it starts with all of its thunder, all of its might. But anyway, almost every night, there is a moment of awe, of not believing how much rain we are getting today. It slowly fades away during the late night. And when I wake up, early next morning, everything is wet and still smells fresh. Yes, I love our summer, even though it makes shy away from my much enjoyed cycling to work and school. And I love taking some minutes off work, look through the window of my office (located ~70m over the level of our mostly flat city) and watching how different parts of the city have sun or rain; learning to estimate the distance to the clouds, adding it to the direction and guessing which of my friends have which weather. But I didn't realize our city had so clearly defined micro-climates... (would they really be *micro*-climates?) In fact, it even goes against my knowledge of Mexico City's logic I always thought Coyoac n, towards the South of the city, got more rain than the Center and North because we are near the mountains, and the dominant air currents go Southwards, "clumping" the clouds by us. But no, or at least, not this year. Regina (still in the far South Far because she's too far away from me and I'm too egocentric; she returns home after DebConf) often asks me about the weather, as our friends working nearer the center of the city. According to the photos they post on their $social_media_of_the_day accounts, rains are really heavier there. Today I heard on the radio accounts of yesterday's chaos after the rain. This evening, at ESIME-Culhuac n, I saw one of the reported fallen trees (of course, I am not sure if it's from yesterday's rain). And the media pushes galleries of images of a city covered in hail... While in Copilco we only had a regular rain, I'd even say a mild one. This city is bigger than any cloud you can throw at it.
AttachmentSize
IMG_20140819_155052.jpg929.69 KB

Holger Levsen: 20140819-lts-july-2014

Debian LTS - impressions and thoughts from my first month involvement About LTS - we want feedback and more companies supporting it financially Squeeze LTS, and even more Debian LTS, is a pretty young project, started in May 2014, so it's still a bit unclear where exactly we'll be going :) One purpose of this post is to spread some information about the initiative and invite you to tell us what you think about it or what your needs are. LTS stands for "Long Term Support" and the goal of the project is to extend the security support for Squeeze (aka the current oldstable distribution) by two years. If it weren't for Squeeze LTS, the security support for it would have been stopped in May 2014 (=one year after the release of the current stable distribution), which for many is a too short timespan after it's release in February 2011. It's an experiment, we hope that there will be a similar Wheezy LTS initiative in future, but the future is unwritten and things will change based on our experiences and your needs. If you have feedback on the direction LTS should take (or anything else LTS related), please comment on the lts mailing list. For immediate feedback there is also the #debian-lts IRC channel. Another quite pragmatic way to express your needs is to read more about how to financially contribute to LTS and then doing exactly that - and unsurprisingly we are prioritizing the updates based on the needs expressed from our paying customers. My LTS work in July 2014 So, "somehow" I started working for money on Debian LTS in July, which means there were 10h I got paid, and probably another 10h where I did LTS related work unpaid. I used those to release four updates for squeeze-lts (linux-2.6, file, munin and reportbug) fixing 22 CVEs in total. The unpaid work was mostly spent on unsuccessfully working on security updates and on adding support for LTS to the security team tracker, which I improved but couldn't fully address and which I haven't properly shared / committed yet... but at least I have a local instance of the tracker now, which - for LTS - is more useful than the .debian.org one. Hopefully during DebConf14 we'll manage to fix the tracker for good. Without success I've looked at libtasn1-3 (where the first fixes applied easily but then the code had changed too much from what was in squeeze compared to the available patches that I gave up) and libxstream-java (which is at version 1.3, while patches exist for upstream branches 1.4 and 2.x, but those need newer java to build and maybe if I'll spend two more hours I'll can get it build and then I'll have to find a useful test case, which looked quite difficult on a brief look.. so maybe I give up on libxstream-java too.... OTOH, if you use it and can do some testing, please do tell me. Working on all these updates turned out to be more team work than expected and a lot of work involving code (which I did expect), and often code which I'd normally not look at... similarily with tools: one has to deal with tools one doesnt like, eg I had to install cdbs... :-) And as I usually like challenges, this has actually been a lot of fun! Though it's also pretty cool to use common best practices, easy and understandable workflows. I love README.Source (or better yet, when it's not needed). And while git is of course really really great, it's still very desirable if your package builds twice (=many times) in a row, without resetting it via git. Some more observations The first 16 updates (until July 19th) didn't have a DLA ID, until I suggested to introduce them and insisted until we agreed. So now we agreed to put the DLA ID in the subject of the announcement mails and there is also some tool support for generating the templates/mails, but enforcing proper subjects is not done, as silent bounces are useless (and non silent ones can be abused too easily). I'm not really happy about this, but who is happy with the way email works today? And I agree, it's not the end of the world if an LTS announcement is done without a proper ID, but it looks unprofessional and could be avoided, but we have more important work to do. But one day we should automate this better. Another detail I'm not entirely happy is the policy/current decision that "almost everything is fine to upload if deemed sensible by the uploader" (which is everyone in the Debian upload keyring(s)). In discussions before actually having the archive some people suggested the desire to upload new upstream versions too (eg newer kernels, iceweasel or other software to keep running a squeeze desktop in the modern world were discussed). I sincerely hope for most intrusive new upstream versions squeeze-(sloppy-)backports is used instead, and squeeze-lts rather not. Luckily so far all uploads were (IMHO) sensible and so, right now, I will just say that I hope it will stay this way. And it's true, one also has to install these upgrades in the first place. But people do that blindly all the time... So by design/desire currently there is no gatekeeping mechanism whatsover (no NEW, no proposed updates), except that only some selected "few" can upload. What is uploaded (and signed correctly), gets pushed to archive, buildds and the mirrors, and hopefully maybe someone will send an announcement. So far this has worked remarkedly well - and it's also the way the Debian Security team works, as I'm told. Looking at this from a process quality / automatisation perspective, all this manual and errorprone labour seems very strange to me. ;-) And then there is another thing: as already mentioned, the people working paid hours for this, are prioritizing their work based on customer requests. So we did two updates (python-scipy and file), which are not fixed in wheezy yet. I think this is unfortunate and while I could probably prepare the wheezy DSA for file, I don't really want to join the Security Team... or maybe I want/should join the Security Team and be a seldomly active member (eg fixing file in wheezy now....) A note related to this: out of those 37 uploads done until today, 16 were done by those two people being paid, while the other 21 uploads were done by 10 volunteers (or at least not paid by Debian LTS). It will be interesting to see how this statistics evolves over time. Last, but not least, there is also this can of worms (aka: the discussion) about paying people to work on Debian... I do agree it's work we didnt find volunteers for and I also see how the (financial side of the) setup is done outside of Debian (and well too, btw!), but... then we also use Debian ressources like buildds, the archive itself and official mailing lists. Also I'm currently biased in this discussion, as I directly (and happily) profit from it. I'm mentioning this here, because I believe it's important we discuss this and come to both good and practical conclusions. FWIW, we have also discussed this on the list, feel free to search the archives for it. To bring this post to an end: for those attending DebConf14 (directly or thanks to some ninjas), there will be an event about LTS in Portland, though I'm not sure yet what I will have to talk about what hasn't been already covered here :-) But this probably means that will be a good opportunity for you to do lots of talking instead! I'm curious what you will have to say! Thanks for reading this far. I think I can promise that my next LTS report will be shorter :-D

19 August 2014

Julien Danjou: Tracking OpenStack contributions in GitHub

I've switched my Git repositories to GitHub recently, and started to watch my contributions statistics, which were very low considering I spend my days hacking on open source software, especially OpenStack.
OpenStack hosts its Git repositories on its own infrastructure at git.openstack.org, but also mirrors them on GitHub. Logically, I was expecting GitHub to track my commits there too, as I'm using the same email address everywhere. It turns out that it was not the case, and the help page about that on GitHub describes the rule in place to compute statistics. Indeed, according to GitHub, I had no relations to the OpenStack repositories, as I never forked them nor opened a pull request on them (OpenStack uses Gerrit). Starring a repository is enough to build a relationship between a user and a repository, so this is was the only thing needed to inform GitHub that I have contributed to those repositories. Considering OpenStack has hundreds of repositories, I decided to star them all by using a small Python script using pygithub.
And voil , my statistics are now including all my contributions to OpenStack!

18 August 2014

Daniel Pocock: Is WebRTC private?

With the exciting developments at rtc.debian.org, many people are starting to look more closely at browser-based real-time communications. Some have dared to ask: does it solve the privacy problems of existing solutions? Privacy is a relative term Perfect privacy and its technical manifestations are hard to define. I had a go at it in a blog on the Gold Standard for free communications technology on 5 June 2013. By pure co-incidence, a few hours later, the first Snowden leaks appeared and this particular human right was suddenly thrust into the spotlight. WebRTC and ICE privacy risk WebRTC does not give you perfect privacy. At least one astute observer at my session at Paris mini-DebConf 2014 questioned the privacy of Interactive Connectivity Establishment (ICE, RFC 5245). In its most basic form, ICE scans all the local IP addresses on your machine and NAT gateway and sends them to the person calling you so that their phone can find the optimal path to contact you. This clearly has privacy implications as a caller can work out which ISP you are connected to and some rough details of your network topology at any given moment in time. What WebRTC does bring to the table Some of this can be mitigated though: an ICE implementation can be tuned so that it only advertises the IP address of a dedicated relay host. If you can afford a little latency, your privacy is safe again. This privacy protecting initiative could be made by a browser vendor such as Mozilla or it can be done in JavaScript by a softphone such as JSCommunicator. Many individuals are now using a proprietary softphone to talk to family and friends around the world. The softphone in question has properties like a virus, siphoning away your private information. This proprietary softphone is also an insidious threat to open source and free operating systems on the desktop. WebRTC is a positive step back from the brink. It gives people a choice. WebRTC is a particularly relevant choice for business. Can you imagine going to a business and asking them to make all their email communication through hotmail? When a business starts using a particular proprietary softphone, how is it any different? WebRTC offers a solution that is actually easier for the user and can be secured back to the business network using TLS. WebRTC is based on open standards, particularly HTML5. Leading implementations, such as the SIP over WebSocket support in reSIProcate, JSCommunicator and the DruCall module for Drupal are fully open source. Not only is it great to be free, it is possible to extend and customize any of these components. What is missing There are some things that are not quite there yet and require a serious effort from the browser vendors. At the top of the list for privacy:
  • ZRTP support - browsers currently support DTLS-SRTP, which is based on X.509. ZRTP is more like PGP, a democratic and distributed peer-to-peer privacy solution without needing to trust some central certificate authority.
  • TLS with PGP - the TLS protocol used to secure the WebSocket signalling channel is also based on X.509 with the risk of a central certificate authority. There is increasing chatter about the need for TLS to use PGP instead of X.509 and WebRTC would be a big winner if this were to eventuate and be combined with ZRTP.
You may think "I'll believe it when I see it". Each of these features, including WebRTC itself, is a piece of the puzzle and even solving one piece at a time brings people further out of danger from the proprietary mess the world lives with today. To find out more about practical integration of WebRTC into free software solutions, consider coming to my talk at xTupleCon in October.

Julien Danjou: OpenStack Ceilometer and the Gnocchi experiment

A little more than 2 years ago, the Ceilometer project was launched inside the OpenStack ecosystem. Its main objective was to measure OpenStack cloud platforms in order to provide data and mechanisms for functionalities such as billing, alarming or capacity planning. In this article, I would like to relate what I've been doing with other Ceilometer developers in the last 5 months. I've lowered my involvement in Ceilometer itself directly to concentrate on solving one of its biggest issue at the source, and I think it's largely time to take a break and talk about it. Ceilometer early design For the last years, Ceilometer didn't change in its core architecture. Without diving too much in all its parts, one of the early design decision was to build the metering around a data structure we called samples. A sample is generated each time Ceilometer measures something. It is composed of a few fields, such as the the resource id that is metered, the user and project id owning that resources, the meter name, the measured value, a timestamp and a few free-form metadata. Each time Ceilometer measures something, one of its components (an agent, a pollster ) constructs and emits a sample headed for the storage component that we call the collector. This collector is responsible for storing the samples into a database. The Ceilometer collector uses a pluggable storage system, meaning that you can pick any database system you prefer. Our original implementation has been based on MongoDB from the beginning, but we then added a SQL driver, and people contributed things such as HBase or DB2 support. The REST API exposed by Ceilometer allows to execute various reading requests on this data store. It can returns you the list of resources that have been measured for a particular project, or compute some statistics on metrics. Allowing such a large panel of possibilities and having such a flexible data structure allows to do a lot of different things with Ceilometer, as you can almost query the data in any mean you want. The scalability issue We soon started to encounter scalability issues in many of the read requests made via the REST API. A lot of the requests requires the data storage to do full scans of all the stored samples. Indeed, the fact that the API allows you to filter on any fields and also on the free-form metadata (meaning non indexed key/values tuples) has a terrible cost in terms of performance (as pointed before, the metadata are attached to each sample generated by Ceilometer and is stored as is). That basically means that the sample data structure is stored in most drivers in just one table or collection, in order to be able to scan them at once, and there's no good "perfect" sharding solution, making data storage scalability painful. It turns out that the Ceilometer REST API is unable to handle most of the requests in a timely manner as most operations are O(n) where n is the number of samples recorded (see big O notation if you're unfamiliar with it). That number of samples can grow very rapidly in an environment of thousands of metered nodes and with a data retention of several weeks. There is a few optimizations to make things smoother in general cases fortunately, but as soon as you run specific queries, the API gets barely usable. During this last year, as the Ceilometer PTL, I discovered these issues first hand since a lot of people were feeding me back with this kind of testimony. We engaged several blueprints to improve the situation, but it was soon clear to me that this was not going to be enough anyway.
Thinking outside the box Unfortunately, the PTL job doesn't leave him enough time to work on the actual code nor to play with anything new. I was coping with most of the project bureaucracy and I wasn't able to work on any good solution to tackle the issue at its root. Still, I had a few ideas that I wanted to try and as soon as I stepped down from the PTL role, I stopped working on Ceilometer itself to try something new and to think a bit outside the box. When one takes a look at what have been brought recently in Ceilometer, they can see the idea that Ceilometer actually needs to handle 2 types of data: events and metrics. Events are data generated when something happens: an instance start, a volume is attached, or an HTTP request is sent to an REST API server. These are events that Ceilometer needs to collect and store. Most OpenStack components are able to send such events using the notification system built into oslo.messaging. Metrics is what Ceilometer needs to store but that is not necessarily tied to an event. Think about an instance CPU usage, a router network bandwidth usage, the number of images that Glance is storing for you, etc These are not events, since nothing is happening. These are facts, states we need to meter. Computing statistics for billing or capacity planning requires both of these data sources, but they should be distinct. Based on that assumption, and the fact that Ceilometer was getting support for storing events, I started to focus on getting the metric part right. I had been a system administrator for a decade before jumping into OpenStack development, so I know a thing or two on how monitoring is done in this area, and what kind of technology operators rely on. I also know that there's still no silver bullet this made it a good challenge. The first thing that came to my mind was to use some kind of time-series database, and export its access via a REST API as we do in all OpenStack services. This should cover the metric storage pretty well. Cooking Gnocchi
A cloud of gnocchis!
At the end of April 2014, this led met to start a new project code-named Gnocchi. For the record, the name was picked after confusing so many times the OpenStack Marconi project, reading OpenStack Macaroni instead. At least one OpenStack project should have a "pasta" name, right? The point of having a new project and not send patches on Ceilometer, was that first I had no clue if it was going to make something that would be any better, and second, being able to iterate more rapidly without being strongly coupled with the release process. The first prototype started around the following idea: what you want is to meter things. That means storing a list of tuples of (timestamp, value) for it. I've named these things "entities", as no assumption are made on what they are. An entity can represent the temperature in a room or the CPU usage of an instance. The service shouldn't care and should be agnostic in this regard. One feature that we discussed for several OpenStack summits in the Ceilometer sessions, was the idea of doing aggregation. Meaning, aggregating samples over a period of time to only store a smaller amount of them. These are things that time-series format such as the RRDtool have been doing for a long time on the fly, and I decided it was a good trail to follow. I assumed that this was going to be a requirement when storing metrics into Gnocchi. The user would need to provide what kind of archiving it would need: 1 second precision over a day, 1 hour precision over a year, or even both. The first driver written to achieve that and store those metrics inside Gnocchi was based on whisper. Whisper is the file format used to store metrics for the Graphite project. For the actual storage, the driver uses Swift, which has the advantages to be part of OpenStack and scalable. Storing metrics for each entities in a different whisper file and putting them in Swift turned out to have a fantastic algorithm complexity: it was O(1). Indeed, the complexity needed to store and retrieve metrics doesn't depends on the number of metrics you have nor on the number of things you are metering. Which is already a huge win compared to the current Ceilometer collector design. However, it turned out that whisper has a few limitations that I was unable to circumvent in any manner. I needed to patch it to remove a lot of its assumption about manipulating file, or that everything is relative to now (time.time()). I've started to hack on that in my own fork, but then everything broke. The whisper project code base is, well, not the state of the art, and have 0 unit test. I was starring at a huge effort to transform whisper into the time-series format I wanted, without being sure I wasn't going to break everything (remember, no test coverage). I decided to take a break and look into alternatives, and stumbled upon Pandas, a data manipulation and statistics library for Python. Turns out that Pandas support time-series natively, and that it could do a lot of the smart computation needed in Gnocchi. I built a new file format leveraging Pandas for computing the time-series and named it carbonara (a wink to both the Carbon project and pasta, how clever!). The code is quite small (a third of whisper's, 200 SLOC vs 600 SLOC), does not have many of the whisper limitations and it has test coverage. These Carbonara files are then, in the same fashion, stored into Swift containers. Anyway, Gnocchi storage driver system is designed in the same spirit that the rest of OpenStack and Ceilometer storage driver system. It's a plug-in system with an API, so anyone can write their own driver. Eoghan Glynn has already started to write a InfluxDB driver, working closely with the upstream developer of that database. Dina Belova started to write an OpenTSDB driver. This helps to make sure the API is designed directly in the right way. Handling resources Measuring individual entities is great and needed, but you also need to link them with resources. When measuring the temperature and the number of a people in a room, it is useful to link these 2 separate entities to a resource, in that case the room, and give a name to these relations, so one is able to identify what attribute of the resource is actually measured. It is also important to provide the possibility to store attributes on these resources, such as their owners, the time they started and ended their existence, etc.
Relationship of entities and resources
Once this list of resource is collected, the next step is to list and filter them, based on any criteria. One might want to retrieve the list of resources created last week or the list of instances hosted on a particular node right now. Resources also need to be specialized. Some resources have attributes that must be stored in order for filtering to be useful. Think about an instance name or a router network. All of these requirements led to to the design of what's called the indexer. The indexer is responsible for indexing entities, resources, and link them together. The initial implementation is based on SQLAlchemy and should be pretty efficient. It's easy enough to index the most requested attributes (columns), and they are also correctly typed. We plan to establish a model for all known OpenStack resources (instances, volumes, networks, ) to store and index them into the Gnocchi indexer in order to request them in an efficient way from one place. The generic resource class can be used to handle generic resources that are not tied to OpenStack. It'd be up to the users to store extra attributes. Dropping the free form metadata we used to have in Ceilometer makes sure that querying the indexer is going to be efficient and scalable.
The indexer classes and their relations
REST API All of this is exported via a REST API that was partially designed and documented in the Gnocchi specification in the Ceilometer repository; though the spec is not up-to-date yet. We plan to auto-generate the documentation from the code as we are currently doing in Ceilometer. The REST API is pretty easy to use, and you can use it to manipulate entities and resources, and request the information back.
Macroscopic view of the Gnocchi architecture
Roadmap & Ceilometer integration All of this plan has been exposed and discussed with the Ceilometer team during the last OpenStack summit in Atlanta in May 2014, for the Juno release. I led a session about this entire concept, and convinced the team that using Gnocchi for our metric storage would be a good approach to solve the Ceilometer collector scalability issue. It was decided to conduct this project experiment in parallel of the current Ceilometer collector for the time being, and see where that would lead the project to. Early benchmarks Some engineers from Mirantis did a few benchmarks around Ceilometer and also against an early version of Gnocchi, and Dina Belova presented them to us during the mid-cycle sprint we organized in Paris in early July. The following graph sums up pretty well the current Ceilometer performance issue. The more you feed it with metrics, the more slow it becomes.
For Gnocchi, while the numbers themselves are not fantastic, what is interesting is that all the graphs below show that the performances are stable without correlation with the number of resources, entities or measures. This proves that, indeed, most of the code is built around a complexity of O(1), and not O(n) anymore.
Next steps
Cl ment drawing the logo
While the Juno cycle is being wrapped-up for most projects, including Ceilometer, Gnocchi development is still ongoing. Fortunately, the composite architecture of Ceilometer allows a lot of its features to be replaced by some other code dynamically. That, for example, enables Gnocchi to provides a Ceilometer dispatcher plugin for its collector, without having to ship the actual code in Ceilometer itself. That should help the development of Gnocchi to not be slowed down by the release process for now. The Ceilometer team aims to provide Gnocchi as a sort of technology preview with the Juno release, allowing it to be deployed along and plugged with Ceilometer. We'll discuss how to integrate it in the project in a more permanent and strong manner probably during the OpenStack Summit for Kilo that will take place next November in Paris.

17 August 2014

Andrew Pollock: [tech] Solar follow up

Now that I've had my solar generation system for a little while, I thought I'd write a follow up post on how it's all going. Energex came out a week ago last Saturday and swapped my electricity meter over for a new digital one that measures grid consumption and excess energy exported. Prior to that point, it was quite fun to watch the old analog meter going backwards. I took a few readings after the system was installed, through to when the analog meter was disconnected, and the meter had a value 26 kWh lower than when I started. I've really liked how the excess energy generated during the day has effectively masked any relatively small overnight power consumption. Now that I have the new digital meter things are less exciting. It has a meter measuring how much power I'm buying from the grid, and how much excess power I'm exporting back to the grid. So far, I've bought 32 kWh and exported 53 kWh excess energy. Ideally I want to minimise the excess because what I get paid for it is about a third of what I have to pay to buy it from the grid. The trick is to try and shift around my consumption as much as possible to the daylight hours so that I'm using it rather than exporting it. On a good day, it seems I'm generating about 10 kWh of energy. I'm still impatiently waiting for PowerOne to release their WiFi data logger card. Then I'm hoping I can set up something automated to submit my daily production to PVOutput for added geekery.
Jamie McClelland: Getting to know systemd

Update 2014-08-20: apcid needs tweaking. See update section below. Somehow both my regular work laptop and home entertainment computers (both running Debian Jessie) were switched to systemd without me noticing. Judging from by dpkg.log it may have happened quite a while ago. I'm pretty sure that's a compliment to the backwards compatibility efforts made by the systemd developers and a criticism of me (I should be paying closer attention to what's happening on my own machines!). In any event, I've started trying to pay more attention now - particularly learning how to take advantage of this new software. I'll try to keep this blog updated as I learn. For now, I have made a few changes and discoveries. First - I have a convenient bash wrapper I use that both starts my OpenVPN client to a samba server and then mounts the drive. I only connect when I need to and rarely do I properly disconnect (the OpenVPN connection does not start automatically). So, I've written the script to carefully check if my openvpn connection is present and either restart or start depending on the results. I had something like this:
if ps -eFH   egrep [o]penvpn; then
  sudo /etc/init.d/openvpn restart
else
  sudo /etc/init.d/openvpn start
fi
One of the advertised advantages of systemd is the ability to more accurately detect if a service is running. So, first I changed this to:
if systemctl -q is-active openvpn.service; then
  sudo systemctl restart openvpn.service
else
  sudo systemctl start openvpn.service
fi
However, after reviewing the man page I realized I can shorten if further to simply:
  sudo systemctl restart openvpn.service
According to the man page, restart means:
Restart one or more units specified on the command line. If the units are not
running yet, they will be started.
After discovering this meaning for "restart" in systemd, I tested and realized that "restart" works the same way for openvpn using the old sysv style init system. Oh well. At least there's a man page and a stronger guarantee that it will work with all services, not just the ones that happen to respect that convention in their init.d scripts. The next step was to disable openvpn on start up. I confess, I never bothered to really learn update-rc.d. Everytime I read the manpage I ended up throwing up my hands and renaming symlinks by hand. In the case of openvpn I had previously edited /etc/default/openvpn to indicate that "none" of the virtual private networks should be started. Now, I've returned that file to the default configuration and instead I ran:
systemctl disable openvpn.service
UPDATES 2014-08-20: I've recently noticed strange behavior when I wake my laptop. Seems to sometimes go right back to sleep. After doing some digging I traced the problem to some customizations I have made to my laptop's acpid behavior combined with systemd taking over some apci events. Up to now, I have created my own /etc/acpi files so I have full control over the acpi events. In particular, I don't want my laptop to suspend when I close the lid. I only want it to suspend when I press the suspend key. And, when it does suspend, I want it to run my own personal suspend script so I can do things like lock the screen and restart tint2. I've found that systemd launches it's own acpi event monitoring that ignores my /etc/acpid rules (the systemd "unit" that monitors events is called acpid.socket which exists in addition to acpid.service). The systemd reaction to events is controlled by the systemd-logind.service which has a configuration file: /etc/systemd/logind.conf. By default, systemd-logind.service will put my laptop to sleep when the lid is closed and when the suspend button is pushed. systemd seems to get the signal first, putting the laptop to sleep. After I wake it up, acpid gets the signal - so it goes right back to sleep. Reading man logind.conf helps. I was able to restore my desired behavior by adding these lines to /etc/systemd/logind.conf:
HandleSuspendKey=ignore
HandleLidSwitch=ignore
Then: sudo systemctl restart systemd-logind.service.

16 August 2014

loldebian - Can I has a RC bug?: True Debian Stable

loldebian21 Loled by MadameZou (inspired by this tweet)

Next.

Previous.