Search Results: "nate"

28 November 2007

Andrew Pollock: [tech] Two years of Python

As last Wednesday was the second anniversary of me joining Google, I thought it an opportune time to reflect on how I've found learning Python. It's no big secret that Google is a Python shop. I'd been meaning to learn it a for a while prior to joining Google, but never found enough reason to other than because it seemed to be the cool new language. If I had a task that required me to write a script, I could do it in Perl in 30 minutes, or spend a day trying to wrap my head around how to do it Python. I think I'd known and been writing Perl in some form or other for about 9 years. I've hardly written any in the last two, which is a bit sad. I even bought Perl Best Practices shortly after moving over here, and haven't gotten around to reading it. The only Perl I write these days is for personal tasks to try and stop myself from going totally rusty. Anyway, I thought I'd write down some of my observations of Python, from a "veteran" Perl programmer's perspective. Not that I consider myself to be a shit-hot Perl coder by any stretch of the imagination... No punctuation I really like the lack of punctuation. It makes the code look a lot cleaner. I go back to Perl and my eyes bleed after trying to dereference a reference to a scalar, or something like that. It's just ugly in Perl. No curly braces/indentation for blocks The indentation thing isn't so bad. If you're using vi, you really need something along the lines of
set shiftwidth=2
set smarttab
set autoindent
set expandtab
in your ~/.vimrc What I do miss is being able to bounce on the % key to find the beginning and ending of a block. I've heard rumours of a way to configure vi to do something similar for Python code, but I haven't gotten around to finding out. There seems to a general opinion that if you're writing a block that is so big you can't find the beginning and end of it, you're probably doing something wrong. String concatenation It's always struck me as bizarre how the most obvious way to concatenate a string in Python is also one of the least efficient. In fact, there's whole studies been done into different methods of string concatenation and their efficiencies. Prototyping is easy Now I may just be ignorant of some Perl shell here, but the number of times I've written a quick Perl script in /tmp to do some proof-of-concept thing is immeasurable. The fact that you can just fire up a Python interpreter and try something quick and dirty to see if it's syntactically sane, or does what you expect is fantastic time saver. ipython makes it an even more pleasant an experience. No CPAN I was initially a bit disappointed that there wasn't something like CPAN for Python modules. In practice, using Debian, I haven't found this to be that big a problem though. List joining is wacky I still find it weird that you don't join a list by a method of the list, you do it by a method of the string you want to use to join the list together with, that is, I think it should be mylist.join(" ") when it's really " ".join(mylist). That's just always struck me as unintuitive. urllib2 doesn't hold a candle to libwww-perl I think even last time I checked with Python 2.5, it's impossible to make a HEAD request. The mind boggles. No setuid support I can't complain too much, I think I heard somewhere it's going away in Perl as well, but it was certainly very convenient to be able to write setuid Perl scripts. I miss that convenience in Python. Not that one has to write setuid scripts all that often. Regular expression handling is painful It's about on a par with Java. You just can't beat Perl's =~ operator. "There's more than one way to do it" versus only one way to do it Perl's always had the adage of there being more than one way to do things. I think that has been its downfall in terms of readability. Heck, I've written some monstrosities that I've looked back on in a month's time and wondered what on earth I was thinking at the time. I think it's far easier to write readable Python than it is to write readable Perl. I think that's about everything. I never did any real object-oriented programming in Perl, and so I tend to take a procedural approach to things in Python as well. I haven't written any massive bodies of code in Python (although I did help maintain one for about 18 months). I like Python. It's become my first choice for writing random scripts now. Now I look at Ruby like I used to look at Python when I knew Perl quite well. Ruby has some nice things (like Perlish regular expression handling), but it brings back all that punctuation noise again. I'm not in a huge rush to learn it, even though there's a lot of hype around Ruby on Rails. I think I'd rather investigate Django or Pylons

27 November 2007

Daniel Leidert: LDFLAGS = -Wl, as-needed

Now that I discovered this nice flag I checked a few of my packages. It works nice for the gnome-chemistry-utils application packages. Unfortunately libgcu0 does not benefit from the flag because of libtool bug #347650. However there is an appreciably difference in the dependencies for the plugin and application packages, where the amount of dependencies decreased. For example compare the old
Depends: iceweasel   iceape-browser   xulrunner, libart-2.0-2 (>= 2.3.18),
libatk1.0-0 (>= 1.20.0), libc6 (>= 2.6.1-1), libcairo2 (>= 1.4.0), libgcc1 (>= 1:4.2.1), libgconf2-4 (>= 2.13.5),
libgcu0 (<< 0.9), libgcu0 (>= 0.8), libgl1-mesa-glx   libgl1, libglade2-0 (>= 1:2.6.1), libglib2.0-0 (>= 2.14.0),
libglu1-mesa   libglu1, libgnomecanvas2-0 (>= 2.11.1), libgnomeprint2.2-0 (>= 2.17.0),
libgnomeprintui2.2-0 (>= 2.17.0), libgnomevfs2-0 (>= 1:2.17.90), libgoffice-0-4 (>= 0.4.2),
libgsf-1-114 (>= 1.14.7), libgtk2.0-0 (>= 2.12.0), libgtkglext1, libice6 (>= 1:1.0.0), libnspr4-0d (>= 1.8.0.10),
libopenbabel2, liborbit2 (>= 1:2.14.1), libpango1.0-0 (>= 1.18.3), libsm6, libstdc++6 (>= 4.2.1), libx11-6,
libxml2 (>= 2.6.27), libxmu6, libxt6, zlib1g (>= 1:1.2.3.3.dfsg-1)
and the new Depends field for gcu-plugin:
Depends: libc6 (>= 2.6.1-1), libgcc1 (>= 1:4.2.1), libgcu0 (<< 0.9),
libgcu0 (>= 0.8), libglib2.0-0 (>= 2.14.0), libgnomevfs2-0 (>= 1:2.17.90), libgtk2.0-0 (>= 2.12.0),
libnspr4-0d (>= 1.8.0.10), libstdc++6 (>= 4.2.1), libx11-6, libxml2 (>= 2.6.29), iceweasel   iceape-browser  
xulrunner
As another example bluefish now (the next upload) really only shows the necessary dependencies. Compare the current:
Depends: libart-2.0-2 (>= 2.3.18), libaspell15 (>= 0.60),
libatk1.0-0 (>= 1.20.0), libbonobo2-0 (>= 2.15.0), libbonoboui2-0 (>= 2.15.1), libc6 (>= 2.6.1-1),
libcairo2 (>= 1.4.0), libfontconfig1 (>= 2.4.0), libgconf2-4 (>= 2.13.5), libglib2.0-0 (>= 2.14.0),
libgnome2-0 (>= 2.17.3), libgnomecanvas2-0 (>= 2.11.1), libgnomeui-0 (>= 2.17.1),
libgnomevfs2-0 (>= 1:2.17.90), libgtk2.0-0 (>= 2.12.0), libice6 (>= 1:1.0.0), liborbit2 (>= 1:2.14.1),
libpango1.0-0 (>= 1.18.2), libpcre3 (>= 6.0), libpopt0 (>= 1.10), libsm6, libx11-6, libxcomposite1 (>= 1:0.3-1),
libxcursor1 (>> 1.1.2), libxdamage1 (>= 1:1.1), libxext6, libxfixes3 (>= 1:4.0.1), libxi6, libxinerama1,
libxrandr2 (>= 2:1.2.0), libxrender1
to the “upcoming” Depends field:
Depends: libaspell15 (>= 0.60), libc6 (>= 2.7-1), libglib2.0-0 (>= 2.14.0),
libgnomeui-0 (>= 2.17.1), libgnomevfs2-0 (>= 1:2.17.90), libgtk2.0-0 (>= 2.12.0), libpango1.0-0 (>= 1.18.3),
libpcre3 (>= 6.0)
Nice result. I should check (my) other packages too :) Maybe that’s also something for debichems TODO list.

26 November 2007

Rob Taylor: In Critique of Git

Now as anyone who knows me knows, I love Git. I find it gives a very productive and comfortable workflow. One of my favourite new(ish) features is git rebase --interactive, which along with cheap’n'fast branching gives a great way to hack and commit as you go and then later on refactor your work into sets of nice orthogonal patches. However, there I do still find a good few things wrong with git, so I’d like to discuss these problems and possible solutions:
  1. Error Messages In general git has some terrible cryptic error messages. My favourite example is if you modify a file and then pull a change that modifies that file before you commit it: Updating beb8c37..b953e6f
    test: needs update
    fatal: Entry 'test' not uptodate. Cannot merge.
    WTF? what does uptodate mean? why isn’t it up to date? whats gone wrong? what should i do?
    Surely something like: Cancelling pull as 'test' has changes that would be overwritten by this pull. Please commit your changes or force an overwrite using the '--force' flag would be a lot better? I leave it as a reader excercise to repeat this process for most error messages…
  2. The index Why oh why oh why is it called the index? It does no indexing as far as the user is concerned. Its name gives you no clue to what it is, you don’t know when or how you’re supposed to use it. git add and git rm modify it and it’s used all over the place by the obscure low-level git helpers that you stumble over. How about commit staging area, that being what it actually is. You could have nice commands like git stage and git unstage and git stage --interactive. That’d make more sense, right? Then git add and git rm would be a lot more meaningful, being only used when you actually want add or remove a file.
  3. Remotes With git remote this is a lot better than it used to be - having to use cryptic refspecs (see git-pull manpage for the gory details). Unfortunately refspecs are still scattered all over the documentation just to confuse you… That should almost certainly be moved out to less user-visible documentation. The main issues I have now are:
    • Remote branches don’t always behave like local branches when they should. In particular git pull . <remote branch name> doesn’t work (and gives an obscure error) but git merge <remote branch name> does. remote branches should act just like local branches you can’t modify.
    • I’m not sure I like git branch -r to list remote branches, maybe git remote branches would be nicer and more obvious, or even git branch --remote
  4. Lots of git-* commands that confuse people This is a common complaint, and I have to say that I agree. Why not put all the low-level commands in libexec? People who really use them often (which can’t be many!) can always add it to their path.
  5. No bug tracker! For such a user-facing tool, a bug tracker would be very useful for users who lack the experience or time to get their hands dirty in the codebase. It certainly seems that just taking bugs to the mailinglist without a patch isn’t generally useful.
So, what do people think? What other bugbears do beginners and experienced git users see? Are these useful ideas? After some discussion, I’ll happily take these to the git mailing list and come up with some patches! Update:
Looks like people had some problems with my OpenID based login. Comments are now open.

24 November 2007

Adam Rosi-Kessel: ADR for Property Damage in China

As a litigator, I’m always interested in novel and more efficient mechanism for resolving disputes, especially where the transaction costs of fighting it out in court can trump the benefits to either party. This process (full article not available online) for resolving property damage claims in China is about as streamlined as it gets:
Near the Lama Temple, as we waited to make the last left turn of the day, we were hit by another car. The driver backed into our side and then pulled away. There wasn’t time to fumble with my crutches, so I hopped out on my good leg. Fortunately, traffic was backed up, and I caught him in about seven hops. I pounded on the window. “You hit my car!” The driver looked up, surprised: a one-legged foreigner, hopping mad and smacking the glass. He stepped out and apologized, saying that he hadn’t felt the impact. Together, we inspected the Jetta–fresh dent above the left rear wheel. The man said, “I’ll give you a hundred.” That was about thirteen dollars. In China, after a minor accident people usually settle the matter on the street, in cash. This routine has become a standard part of life–once, I saw two small children playing a game in which they repeatedly rammed their bikes and shouted, “Pei qian! Pei qian!” — “Compensate! Compensate!” Leslie used her cell phone to call the rental company. Mr. Liu didn’t sound the least bit surprised to hear that we’d had another accident. All he said was “Ask for two hundred.” “That’s too much,” the other driver said. “This is really minor.” “It’s not our decision.” “Well, then, we’ll have to call the police,” he said, but it was clear that he didn’t want to do this. A dozen bystanders had gathered around the cars, which were parked in the middle of the snowy street. With Chinese accidents, the crowd is more like a jury than an audience, and a middle-aged woman bent over to inspect the dent. She stood up and announced, “A hundred is enough.” “What do you have to do with it?” Leslie snapped. “You can’t even drive!” That must have been correct, because the woman shut up. But the driver refused to pay two hundred. “Should we accept one-fifty?” Leslie asked me, in English. Lao-tzu said it best: A man standing on crutches in the snow will not bargain long over a dent to a crappy Jetta rental. Later that day, Leslie returned the car and the one-fifty in cash. Mr. Liu noticed that another light cover had been broken when she hit the brick wall. He said, happily, “What did you kill this time?” When I hit the dog, the same cover was twelve dollars; this time, he asked for only three. It must have been a special price because we did so well at the Lama Temple.
I don’t think this system would work to resolve patent infringement disputes, but it might make sense for some of our domestic fender-benders. Technorati Tags: ,

Michal &#268;iha&#345;: I hate this system

My girlfriend has to use Windows, because university she studies does not give her another option. Now she got some crap on which she should do some statistics. This crap is being called SAS. I have not yet seen how does it look like, but I already enjoyed funny hours with it's installer. As I'm currently on the other side of world, I have to do all remotely... The basic problem is simple: I do not have much space on C: drive and it does not provide option to install on another drive. First she tried to install it herself, the setup fucked up so much, that it deleted NTLDR and friends from root folder, so Windows didn't boot up again. Fortunately there is also Debian on that machine, so she booted to it, I installed ntfs-3g and restored needed files from Windows XP installation CD (the recovery console did not work, don't ask me why). So great, after about one hour we have back working Windows! Now I still did not have idea what is the problem. However the failure appeared when the crap was trying to install some special JRE it has included. When I started the installer for this JRE manually, it showed that there is not enough space. Why the hell did not the original installer show this? Well I did some cleanup on the disk and I got 1GB of free space. Hope that it will be enough. No. Somewhere near 58% installation is fucked up again with error -2147483648. Wow nice number! Looking at disk space, it's down to few kilobytes. So again the same problem! Okay, let's clean it up more and hopefully installer will resume. But I should not hope for anything good from this installer. The only option it now gives me is to reboot. Reboot, start again installer and let's see what will break this time. Now it found out that some Microsofts runtime is missing. Why it was not missing last time? Okay, let's install it and (of course) we need another reboot. System started up, installer launched and it seems to go on quite well, only the last few percents are taking incredibly long, but the crap seems to finally installed and it even runs! Few questions: Why they do not check for required space in installer? Why do they force me to disable anti virus during installation? Why does not remote desktop from Windows work? Why is there such mess in Windows, especially in Windows folder? Why are temporary files located all over the disk? As last but not least thing I would like to thanks everybody who made ntfs-3g and VNC work, I would never fix this without these tools.

23 November 2007

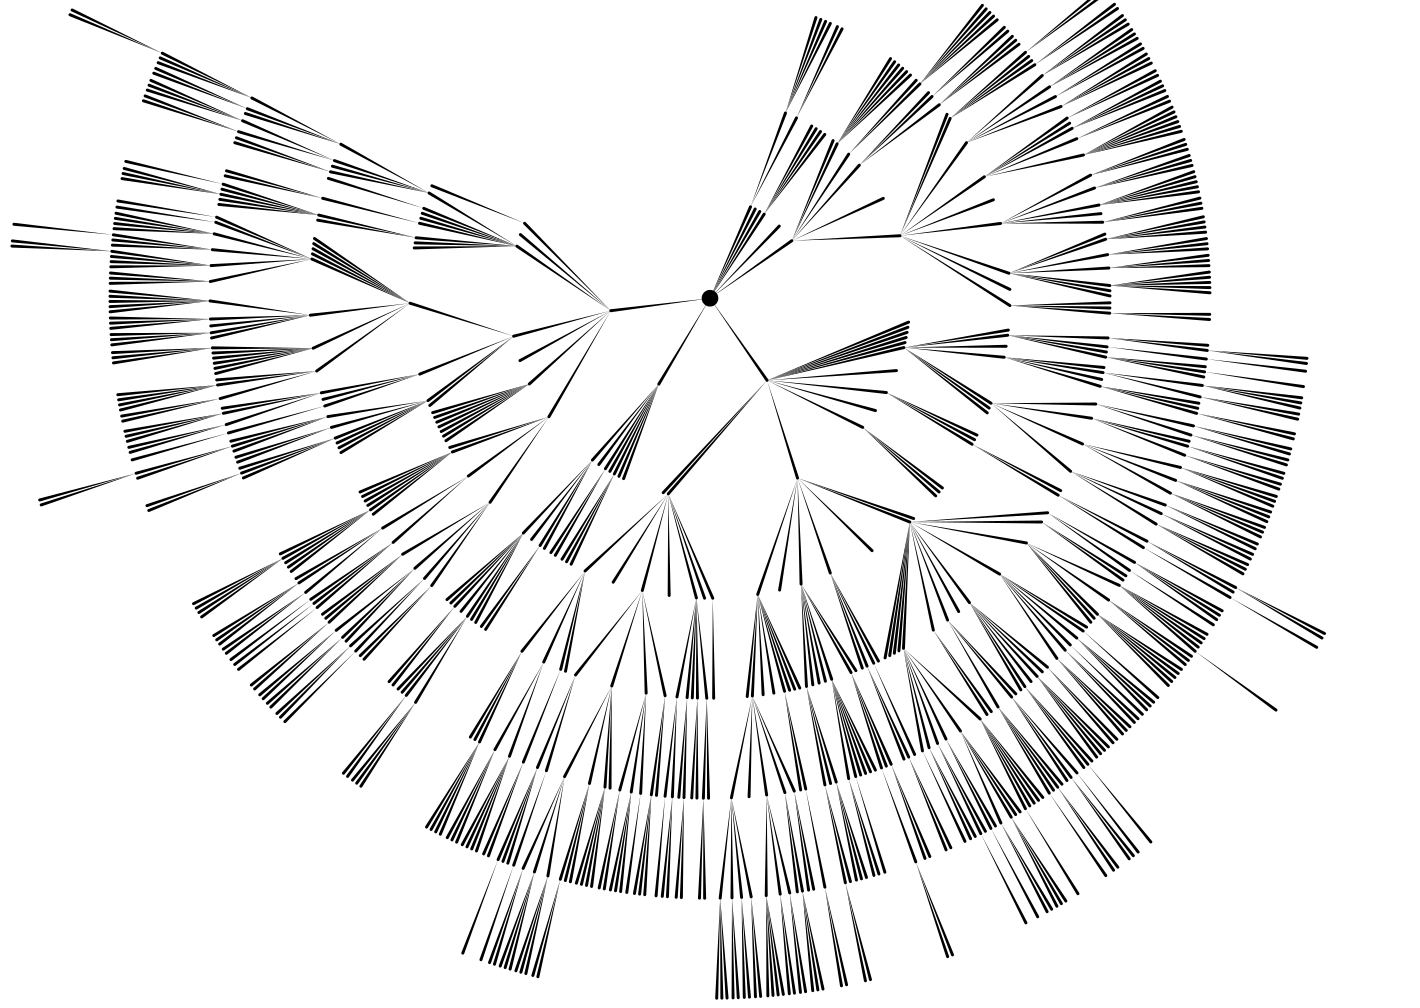
Joachim Breitner: Descendant tree drawing problem

For a geneaology project of my familiy, I generated this fairly straight forward drawing of my Grand-Grand-Grand-Grandfather s descendants (click for full image): Unfortunately, this representation does not give any information about when someone lived, or how long. I tried to add this information to the graph, and I coudn t think of anything better than drawing each person as a rectangle whose upper edge lies above the parent s rectangle, and whose height and vertical possition represent the life span. This is the result (here you really have to click for a full view): This is obviouly not very helpful. Does anyone have a better idea how to draw this?By the way, these graphs are generated using haskell and the cairo bindings provided by gtk2hs very handy, as I also get svg output and pdf output for free.

Russell Coker: Election 2007

I am a member of the Greens. The main reason for joining them is that they have principles. The Greens Charter [1] guides everything, policy must comply with the charter and candidates agree to uphold the policies which have been ratified if they get elected. There are no “non-core promises“. The policies of the Greens are all positive. The major parties have some mean-spirited policies that aim to help Australians by making things worse for people in other countries. Unfortunately for them the world is very inter-connected at the moment, so it’s difficult to harm other countries without harming yourself in the process. As you might expect the Greens are very positive towards the environment. Anyone who expects to live for more than 30 years (or who has children) should be very concerned about this. Currently even the most cautious estimates of the scope of the climate change problem by reputable scientists suggest that there will be serious problems in the next few decades. If you are young or have children then you should vote for the Greens (that covers most people). Many religious groups have determined that God wants them to help the environment, for example the Australian Anglican Church General Synod 2007 resolved that “the Anglican Communion’s 5th mark of mission to safeguard the integrity of creation and sustain and renew the life of the earth; and recognises that human activity contributing to Climate change is one of the most pressing ethical issues of our time”. Anglicans and believers in other religions that have similar ideas should vote for the Greens. The Greens have policies that are very positive towards minority groups. If you are not a straight-white-Christian then this is a strong reason for voting for the Greens. If you are a straight-white-Christian but have compassion for others (as advocated in the Bible) then again voting for the Greens is the right thing to do. The Greens policies are humane towards people in unfortunate situations, including drug addicts, the mentally ill, and the unemployed. When considering who to vote for keep in mind that at some future time you or a close friend or relative may fall into one of those categories. Finally the Howard government’s industrial relations legislation is very bad for the majority of workers. If the Greens get the balance of power in the Senate then they will be able to get such laws significantly changed or removed. The Greens election web site is here [2]. As an aside, I never liked Paul Keating (our last Prime Minister) until I read his op-ed piece in The Age about John Howard [3]. Also here is an interesting article on preferences and why the major parties want people to misunderstand the Australian electoral system [4]. In summary if you vote for the Greens as your first preference and they don’t win, then your second preference gets counted, and if that party doesn’t win then the third preference counts, etc. So if you have the two major parties in last and second-last position then your second-last preference may make an impact on the result! Putting Greens in the #1 position does not “waste” your vote. Parties get government funding based on the number of #1 votes, vote for the Greens as your first preference and you effectively give them $2 for their next campaign. Finally when a party wins an election they immediately look at where the #1 votes went and often adjust their policies to please the people. Vote #1 for the Greens and if Labour wins they will have more of an incentive to adopt policies that are similar to those of the Greens.

22 November 2007

Russell Coker: Drugs and an Election

As mentioned in my previous post [1] the government is using our money to advertise its policies. I previously covered the “Internet as a threat to children” issue, the other big one is drugs. The first significant message in the “Talking with your kids about drugs” document concerns the criminal penalties for drug use. That could largely be removed if the penalties were dramatically decreased and if hard drugs were administered to registered addicts for a nominal fee. Forcing addicts to commit crimes or work as prostitutes to pay for their addiction just doesn’t work, economically or socially. The next message is that parents should be involved in their children’s lives and be trusted enough that their children will accept advice. A large part of this would be related to the amount of time spent with children which is determined to a large degree by the amount of time not spent working. As I mentioned in my previous post it seems that the actions of the Howard government over the last 10 years has made things significantly worse in this regard by forcing more parents to spend large amounts of their time working (including situations where both parents work full-time) just to pay for a home. One notable omission from the document was any mention of alcohol problems (apart from when mixed with illegal drugs). By many metrics alcohol causes more harm than all the illegal drugs combined. The US attempted to prohibit alcohol and failed dismally, and alcohol is legal in most countries. The government doesn’t want to adopt a harm-minimisation approach to drugs (which bears some similarities to the approach taken to alcohol) and therefore is stuck trying to claim that one somewhat addictive mind-altering substance is somehow inherently different to all other mind-altering substances. The document provided no information at all on harm minimisation. The idea seems to be that it’s better for some children to die of overdoses than for other children to potentially be less scared of the consequences of drug use. The problem is that children are very bad at assessing personal risk so they simply won’t be scared off. It’s best to provide equipment for testing drug purity etc to reduce the harm. The list of reasons for young people to try drugs starts with “availability and acceptability of the drug“, Parmesan cheese is more available and acceptable than any drug but I’ve been avoiding it at every opportunity since I was very young. :-# More serious reasons in the list include “rebellion“, “depression“, “as a way to relax or cope with stress, boredom or pain“, and “to feel OK, at least temporarily (self-medication)“. But predictably there was nothing in the document about why children might consider that their life sucks to badly that they want to rebel in that way, be depressed, stressed, bored, or in pain to a degree that drugs seem like the solution. It seems unreasonable to believe that the school system isn’t a significant part of the cause of teenage problems. Flag poles for flying the Australian Flag [2] seems to be John Howard’s idea of a solution to school problems. I believe that the solution to school problems (both in terms of education and protection of children) is smaller classes, better supervision, an active program to eradicate bullying, and better salaries for teachers. I’ve written about related issues in my school category. I believe that the best thing for individual families to do is to home-school their children from the age of 12 instead of sending them to a high-school (which is much more damaging than a primary school). Another significant issue is drug pushers. They are usually drug users who try to finance their own drug use by selling to others. As most drug users get the same idea there is a lot of competition for sales and therefore they try to encourage more people to use drugs to get more customers. In the Netherlands, Coffee Shops sell a range of the milder drugs at reasonable prices which removes the street market and therefore the pushers. When drugs are produced commercially the quality is standardised which dramatically reduces the risk of infection and overdoses. When drugs are sold by legal companies they are not sold to children (a typical pusher can be expected to sell to anyone). The document has 3.5 pages of information about some of the illegal drugs (out of 23 pages total). They include all the most severe symptoms that most users don’t encounter. If someone reads that information and then talks to a drug user they will be laughed at. They also group drugs in an unreasonable way, for example listing “marijuana” and “hashish” as synonyms and list problems that are caused indirectly. If alcohol was included in that list it would include beer and methylated spirits (ethanol mixed with methanol to supposedly make it undrinkable - rumoured to be consumed by homeless people) in the same section and imply that blindness and other bad results of drinking “metho” apply to beer. It would also say that alcohol kills many people through drunk-driving and is responsible for rapes, wife-beating, and any other crime which can statistically shown to be more likely to be committed by a drunk person. A final issue with the document is that it advises parents to be “informed, up-front and honest” when talking to their children about drugs. Unfortunately the document itself doesn’t demonstrate such qualities. By omitting all information on harm minimisation it is not being up-front at all, and by not mentioning alcohol it’s simply being dishonest. Anyone who tries to convince someone else to not use illegal drugs can expect to hear “but you drink alcohol” as the immediate response from the drug user, it’s necessary to have sensible answers to that issue if you want to be effective in discouraging drug use.

David Welton: Android, Hecl and scripting

Aside from my hard drive crash, I've been working to figure out the best way to integrate Android and Hecl. Since Hecl has been a small, simple, humble language suitable for J2ME (or JavaME or whatever), that has meant in the past that it hasn't really been able to utilize more complex or advanced Java features like reflection, because they aren't present in the J2ME API. Android's more complete implementation of "Java" (yes, I know about the VM, but the programming language I'm writing in is still Java) opens up a number of possibilities. First on my list of things to do was aim for a generic access layer for Java objects using reflection, so that you can do things like this:
$button settext "blah blah"
Now that we have that working, I also wanted to be able to create new Android widgets from Hecl, which is where things get tricky. The "problem" is that I want something that feels like a scripting language, not simply a reflection of the underlying Java. For instance, the XML description of a button looks like this:
<Button id="@+id/execute"
android:layout_width="fill_parent"
android:layout_height="wrap_content"
android:text="Execute"
/>
Which is actually not so bad in terms of verbosity. The Java code is uglier, in my opinion:
Button button = new Button(activity);
button.setLayoutParams(new LinearLayout.LayoutParams(LayoutParams.FILL_PARENT, LayoutParams.WRAP_CONTENT));
button.setText("Execute");
Especially the LayoutParams business, that is nowhere near as clear as the XML, where it's very obvious what values you're giving to what parameters. You wouldn't know that from the Java code without looking up the constructor for the LinearLayout.LayoutParams class. Now, with Hecl I could of course write the code by hand to make things 'friendlier', but I'm worried that if I have to do that too much, it will take a long time to cover the rather extensive API, and it will also bloat the code. The ideal solution would be subvert the XML stuff for my own purposes, however, that's proving tricky. My first idea was to utilize the AttributeSet parameter that you pass to many View derived objects' constructors, in order to transform code like this:
button -text hello -layout_width 100 -layout_height 34
Into something that Android can digest. Unfortunately, that's proving difficult, as the internals of Android barf on the class I'm passing them, even though it, to my knowledge, implements the AttributeSet interface without any problems. This really made me wish that they would hurry up and release the source code, because I would have a far better understanding of the relationship between the XML attributes and the Java methods if I had access to what's going on under the hood. Harumph. My next attempt was a hack that takes things like -text and transforms them into calls to setText, but that isn't as good, because you need a little bit more custom code for things like the layout parameters, which require special handling. However, lacking the source code, or some help from the Google folks with access to it (which isn't likely over the next few days as they're doubtless off consuming turkeys), it looks like that's what I'll have to do.

21 November 2007

Wouter Verhelst: Debian work

Been a while since I did so much Debian work in a fairly short time. Today, I finished work on belpic 2.6.0, the support software for the Belgian electronic ID card. My initial builds wouldn't work since I made some stupid (no, really, stupid) errors in properly using that ugly beast, but eventually I saw the light. Working packages are now in incoming, and will soon be on a Debian Mirror Near You(TM). Oh, in case you wonder: the difference between 2.6.0 upstream and 2.5.9 upstream is pretty small, mostly some housekeeping bugfixes; meaning, if 2.5.9 is working for you, there's probably no need to worry about getting the update. I've also added some extra changes to the packaging bits, so that you now no longer have to install the -dev packages just so you can use the browser plugins. Isn't that nice. I did some more work on getting emile, the Early Mac Image LoadEr, to work properly again. Unfortunately, after the initial 0.10-1 upload that I did to Debian, none of my other builds managed to actually work on my test machine. Since I don't want to break existing machines that are using emile, I didn't think to upload those non-working binaries; but now with #451415, I can't ignore that problem any longer. I think I've nailed it now, though, and once barok (my IIci) has finished building (which will take a few hours), the packages should work. Cross your fingers. Finally, I've also prepared an upstream bugfix update of nbd, the userland support tools for the Network Block Device in the Linux kernel, and have uploaded a package from that release into Debian. As if that wasn't enough, and since I genuinely care about the state of my packages in Debian derivatives, I've poked some Ubuntu-people to get it synced there, too. I guess I'm back in shape now.

20 November 2007

Benjamin Mako Hill: Free Culture Distilled for Free Software Folks

I've posted an an article on my website called Free Culture Advanced which I wrote for the last edition of the Free Software Foundation Members' Bulletin which went out several months ago. The bulletin is one of things you get when you become an associate member of the FSF. The article makes the case for free culture and a freedom definition in terms that are directed to and I hope will resonate with folks from the free software community. I've posted versions of the article in HTML, PDF, and LaTeX.

Russell Coker: Perfect Code vs Quite Good Code

Some years ago I worked on a project where software reliability should have been a priority (managing data that was sometimes needed by the police, the fire brigade, and the ambulance service). Unfortunately the project had been tainted by a large consulting company that was a subsidiary of an accounting firm (I would never have expected accountants to know anything about programming and several large accounting firms have confirmed my expectations). I was hired to help port the code from OS/2 1.2 to NT 4.0. The accounting firm had established a standard practice of never calling free() because “you might call free() on memory that was still being used”. This was a terribly bad idea at the best of times and on a 16 bit OS with memory being allocated in 64K chunks the problems were quite obvious to everyone who had any programming experience. The most amusing example of this was a function that allocated some memory and returned a pointer which was being called as if it returned a boolean, one function had a few dozen lines of code similar to if(allocate_some_memory()). I created a second function which called the first, free’d any memory which had been allocated and then returned a boolean. Another serious problem with that project was the use of copy and paste coding. A section of code would perform a certain task and someone would need it elsewhere. Instead of making it a function and calling it from multiple places the code would be copied. Then one copy would be debugged or have new features added and the other copy wouldn’t. One classic example of this was a section of code that displayed an array of data points where each row would be in a colour that indicated it’s status. However setting a row to red would change the colour of all it’s columns, setting a row to blue would change all except the last, and changing it to green would change all but the second-last. The code in question had been copied and pasted to different sections with the colours hard-coded. Naturally I wrote a function to change the colour of a row and made it take the colour as a parameter, the program worked correctly and was smaller too. The next programmer who worked on that section of code would only need to make one change - instead of changing code in multiple places and maybe missing one. Another example of the copy/paste coding was comparing time-stamps. Naturally using libc or OS routines for managing time stamps didn’t occur to them so they had a structure with fields for the year, month, day, hours, minutes, and seconds that was different from every other such structure that is in common use and had to write their own code to compare them, for further excitement some comparisons were only on date and some were on date and time. Many of these date comparisons were buggy and often there were two date comparisons in the same function which had different bugs. I created functions for comparing dates and the code suddenly became a lot easier to read, less buggy, and smaller. I have just read an interesting post by Theodore Ts’o on whether perfect code exists [1]. While I understand both Theodore’s and Bryan’s points of view in this discussion I think that a more relevant issue for most programmers is how to create islands of reasonably good code in the swamp that is a typical software development project. While it was impossible for any one person to turn around a badly broken software development project such as the one I describe, it is often possible to make some foundation code work well which gives other programmers a place to start when improving the code quality. Having the worst of the memory leaks fixed meant that memory use could be analysed to find other bugs and having good functions for comparing dates made the code more readable and thus programmers could understand what they were looking at. I don’t claim that my code was perfect, even given the limitations of the data structures that I was using there was certainly scope for improvement. But my code was solid, clean, commented, and accepted by all members of the team (so they would continue writing code in the same way). It might even have resulted in saving someone’s life as any system which provides data to the emergency services can potentially kill people if it malfunctions. Projects based on free software tend not to be as badly run, but there are still some nasty over-grown systems based on free software where no-one seems able to debug them. I believe that the plan of starting with some library code and making it reasonably good (great code may be impossible for many reasons) and then trying to expand the sections of good code is a reasonable approach to many broken systems. Of course the ideal situation would be to re-write such broken systems from scratch, but as that is often impossible rewriting a section at a time often gives reasonable results.

19 November 2007

Benjamin Mako Hill: Affero General Public License Version 3

The Free Software Foundation sent out a press release today announcing a new addition to the FSF stable of licenses: the Affero General Public License or AGPL. The FSF has also published a set of answers to anticipated questions in the GPL FAQ. The first paragraph of the release explains what the AGPL is:
This is a new license; it is based on version 3 of the GNU General Public License (GNU GPLv3), but has an additional term to ensure that users who interact with the licensed software over a network can receive the source for that program. By publishing this license, the FSF aims to begin fostering user and development communities around free software web services and other network-oriented software.
The GPL is designed to ensure that users of software have access to the source code -- source is prerequisite to freedom and to the type of collaboration that has made free software successful. However, the GPL doesn't say "users" when it talks about who gets freedom; instead, it references people to whom the software is distributed. It doesn't say users for two reasons. The first is that, under copyright, "distribution" is a much more meaningful term and a powerful hook than "use" which is not, in most cases, one of the copyright holder's exclusive rights. The second is that, until very recently, having a copy of software was prerequisite to using it; possession was prerequisite to use. Things have changed. A large part of many people's computing experience involves running web applications. These include email clients (e.g., GMail or other webmails), office applications (e.g., Google Docs), social network systems, and others. These applications all run on servers -- i.e., on other people's computers. The providers of these services, the Googles and the FaceBooks, build upon, modify and improve GPL software without giving back to their users or the community that they took their software from. The AGPL was created several years ago by FSF board member Henri Poole as a way to address this issue. The license took the form of the GPLv2 with one extra clause. It was a first stab at a license and was imperfect. The language and methods were clunky and, most problematically, the license was incompatible with software under the GPL. The new AGPL is based on the GPLv3 and the extra clause has been rethought and rewritten. It has been vetted using the GPLv3 comment process and dozens of insightful comments from dozens of lawyers, hackers, and users of free software have been incorporated. The new license fixes the issues that many folks -- including myself -- had with the first version of the license. More importantly it can now be linked to GPLv3 code which makes the license a whole lot more practical. I am quoted in the release being excited about the license and I really am. I've got 2-3 major development projects (including Selectricity) which I've been waiting to distribute so that I could do so under the AGPLv3. The AGPL isn't a complete answer to the problem faced by disempowered users of web services. Without data or the capacity (in terms of servers, money, and expertise) to run web applications, the state and quality of these users' freedom remains far from clear. Thankfully, there are a whole bunch of folks thinking about what freedom for users of services might be -- it's a conversation that I'm going to push the FSF to participate in and pursue moving forward. The AGPLv3 marks a first solid contribution to the process of answering that question. If you'd like to help supporting or assisting the FSF in this effort, please consider becoming an associate member or donating.

Steve McIntyre: Happy Birthday ORG!

Wow, time flies when you're not paying much attention. It seems that the Open Rights Group is two years old. I was one of the original thousand people who pledged to support ORG financially (a fiver per month), hoping that they would help us stand up for our digital rights in the UK in much the same way as the EFF do in the US. The group have done a good job so far, facing off against the big corporates and the government on key subjects like DRM, electronic voting, ID cards and data protection. Unfortunately, it seems that there are more and more of these fights coming and they are gaining in importance as more and more of our lives are lived online. ORG are always looking for more support; please help if you can.

Julien Blache: pommed v1.12: oops

That’s a bugfix release for MacBook, PowerBook and iBook users. Pommed v1.11 will refuse to start on these machines claiming it didn’t find any event devices to use; I raised the number of expected event devices in v1.11, but unfortunately that number is only correct for the MacBook Pro. So, here is v1.12 to fix that, and sorry :-)

Russell Coker: WTF - Let s write all the code twice

There is an interesting web site WorseThanFailure.com (with the slogan “Curious Perversions in Information Technology”) that documents amusingly failed projects. The name used to be TheDailyWTF.com but changed due to the idea that for some projects success (interpreted to mean limping along in production) is worse than failure (being scrapped and re-written). I’ve created a new category WTF [1] on my blog to document such projects, both ones that I have personally witnessed and ones that friends and colleagues have seen. In the 90’s I spent some time working on an OS/2 GUI program to be the front-end for a mainframe backed system used by call-center workers. The first thing that they did was to develop a file naming scheme, they decided that all source files should be in the same directory (not unreasonable), but that 8.3 should be the limit of file name lengths in case there was a need to port the system to Windows 95. The fact that porting a program which did little other than display a GUI and talk to a S/390 server to a different OS was difficult (given the large amount of platform specific GUI code) was lost on them. Then they decided that the first two letters would be “FE” in case the source was merged with another bank project (of course the bank had many “Front End” systems talking to mainframes - so even this didn’t guarantee that they would be free of name clashes). Characters 3 and 4 were to represent the section of the program, and as the 3 character extension was one of “.h” or “.cpp” that left exactly 4 characters to name the file - we may as well have numbered the source files. Eventually one of the guys started making jokes about the file names by trying to pronounce them as words and that convinced a majority of the developers that the files should have long human-readable names. As the NMAKE expert (they insisted on not using unsupported software such as GNU make) it was my job to fix all the file names. The bank had an internal users’ group for the C++ development environment, but the contractors were not invited to attend. You might think that it would make sense to have the most skillful C++ programmers attend the meetings and share their knowledge, but apparently attending such meetings was a perk of being a permanent employee. What do you do when you have a C++ development project running behind schedule and a permanent employee who has had no prior exposure to C++ and wants to learn? One manager believed that assigning the junior programmer to the project is a solution to both problems - it was good for teaching the programmer C++ in a hurry but not so good for the deadline. There was a lot of excitement related to the back-end development. The mainframe guys assured me that CICS could never handle bad data and it totally wasn’t their fault if my program sent bad data to them and the region crashed. The first CICS region crash occurred when the mainframe guys told me to make the unused space in text fields “empty” - to a C programmer this means filling them with the 0 character but it killed the CICS region (apparently “empty” means filled with spaces to CICS programmers). A later region crash came when they told me to change the field length for the account name everywhere that it occurred - they told me that they wanted the change immediately - so I changed a macro definition, ran “make”, and sent a transaction with the changed size. Apparently “immediately” really meant “after we have spent an hour of software development changing magic numbers throughout our system”. I’m assuming that COBOL has some facility that roughly compares to C macros for defining field lengths and that it was the programmers not the language that was at fault. When the project became seriously behind schedule they hired some expert programmers from another country to help with the development. The experts decided that we needed to redesign the system (not that it had been designed in the first place) to use a “model view controller” architecture. When the real business logic is all on a S/390 and the only logic in the front end is to combine the contents of some screen-scrapes from a virtual 3270 terminal into a single GUI dialogue (with the first screen occasionally getting data from the IVR system) the benefits of MVC seem rather small. The new MVC version of the system was dubbed “phase 2″ and there were a series of deadlines for changing over from “phase 1″ which were missed. So the original team of developers continued on their project without any help from the “experts”. The last report I heard (some time after leaving the project) was that Phase 1 had gone live in production while Phase 2 was still being developed (at that time Phase 2 had a year of development and Phase 1 had about 15 months). The lesson to be learned from this is that management should only hire people that they can control. If you hire a consulting company and then let them do whatever they want (as opposed to solving the problem that they were hired to solve) then at best they will do no good and they may just slow things down. One of the more memorable incidents was when the project manager was talking to his 2IC, he said “I think we’re really breaking ground, [pause] I’m breaking wind and we’re breaking ground”. My desk was a few meters from where the wind (and ground) were being broken, I unfortunately was able to verify that wind was being broken but was not as certain about the ground. I did learn some useful things during this project, one was the fact that sample code from library vendors should not be trusted and ideally should be read from a print-out not pasted into the project source tree. The CTI library vendor had buffer overflows in their sample code. Another useful thing was the coin-tossing method of dispute resolution. If two good programmers have a disagreement about how to implement something tossing a coin is a quick way of resolving the dispute - this only works with two good programmers (in which case either idea will work). The project in question was messed up in many ways. I may write another post in the WTF category about it.

18 November 2007

Russell Coker: Everyone Should Blog

At this month’s meeting of the Linux Users of Victoria [1] I gave a talk titled Everyone Should Blog (unfortunately the title was missed in the meeting announcement). I’ve been meaning to write about this but was finally prodded into writing by a ProBlogger post about overcrowding in the blog market [2]. Darren (the ProBlogger) suggests that the blog space is overcrowded, blogs are being sold for unreasonably high prices, and a bust similar to the dot-com bust may occur. I agree that there is some over-commercialisation, and that for Darren’s core market (people who want to make money directly from blogging) this is a serious issue to consider. However I believe that there is a lot of scope for more blogs. Firstly all of the services in the social networking space seem to have some feature that resembles a blog in some way (the online diary if not the RSS feed part of the definition). I have previously blogged about some ideas for an open social networking system [3]. A reform of the social networking scene should have the possibility of adding even more users and having them all be bloggers. While not everyone is capable of writing a blog that is of interest to a large audience, everyone who is capable of writing is capable of writing (or contributing to) a blog that is of interest to some people. The next potential area for expansion is in sales/marketting blogs. An example of this is car sales, it seems that every web site run by a car manufacturer only has information on the current model and at best only has information on prices of second-hand cars. There is a real need for authoritative information on older cars, it helps customers and it helps the car companies. If Ford was to provide good information on the cars they manufactured a few years ago it would increase the chance that I would buy a second-hand Ford and if enough people made similar decisions then it would increase the prices of such cars (basic rules of supply and demand). Increasing the second-hand price increases the price that people are prepared to pay for new cars and also allows them to buy a new car sooner - both of which are benefits to the manufacturer. It wouldn’t be difficult to use a blog server for all the information on new cars, you could have a front page that lists the available marques and links to the posts announcing the latest models of those marques. With a small amount of work writing a theme you could have Wordpress giving an appearance that’s almost indistinguishable from any of the major car companies web sites - apart from the fact that every car’s technical data would have a permanent URL of the form www.carcompany.com.au/2007/MARQUE/CODE which would be obviously a permanent link (unlike the Java servlet and ASP URLs you currently see) and therefore would encourage deep links by enthusiasts. This would also give RSS feeds for free (I would be interested in adding RSS feeds for several of the Australian car companies to my Planet installation if possible). A final benefit is the issue of ethics. When car companies remove data about cars they sold the previous year you have to wonder whether they have unreasonable price increases or whether the new cars have some specs that are lesser than the current cars. The general trend is slow and steady increases in features and performance at each price point, the number of people who are more likely to buy from an ethical (trustworthy) company is probably greater than the number of people who will look for details to nit-pick (and such people will find out anyway). Another use for blogs is for public events. It’s not uncommon for people to want to get some background information on an event that they attended years ago. If all the information was archived in the blog of the organisation that hosted the event then it would be easy for everyone to access. This would give additional promotion opportunities for the hosting organisation at almost no cost. Anyone who is announcing a future event should have an RSS feed for new information related to it, then as information is released all the interested people can see it in their favourite feed reader. Many people refuse to subscribe to announcement lists due to fear of spam and the fact that it is often inconvenient or impossible to unsubscribe (sometimes a list server regards unsubscribe requests as spam). Corporations have many potential uses of blogs, Google announces news about all their products via blogs and Microsoft has a good recruiting blog. Smaller companies can still achieve some of the same benefits via blogging. Also it’s well known that a blog which provides useful information about products in a field (not just the products being sold) can really attract potential customers who then react to the adverts in the blog. The same technique can be used by job seekers. Blog well and mention that you are looking for work and you will get offers of interviews. There is also no shortage of political and lobbying blogs as well, they don’t tend to convince the opposition but they are good for converting people who are ambivalent about an issue. As the people who read blogs get older (and therefore richer and more influential) such blogs will become increasingly important. I think that I have demonstrated the potential for a significant number of new blogs, some of which would have large subscriber bases and a lot of influence (which means a lot of potential profit for the Problogger crowd). Have I missed any major areas for developing new blogs?

Theodore Ts'o: Does perfect code exist? (Abstractions, Part 1)

Bryan Cantrill recently wrote a blog entry, where among other things, he philosophized on the concept of “perfect code”. He compares software to math, arguing that Euclid’s greatest common denominator algorithm shows no sign of wearing out, and that when code achieves perfection (or gets close to perfection), “it sediments into the information infrastructure” and the abstractions defined by that code becomes “the bedrock that future generations may build upon”. Later, in the comments of his blogs, when pressed to give some examples of such perfection, he cites a clever algorithm coded by his mentor to divide a high resolution timestamp by a billion extremely efficiently, and Solaris’s “cyclic subsystem”, a timer dispatch function. Watching his talk at Google where his introduction and sidebar book review on Scott Rosenberg’s “On Dreaming in Code”, it’s clear that he very passionately believes that it is possible to write perfect code, and that one should strive for that at all times. Perhaps that’s because he mostly writes code for operating systems, where the requirements change slowly, and for one OS in particular, Solaris, which tries far harder than most software projects to keep published interfaces stable for as long as possible. In contrast, the OS I’ve spent a lot of time hacking around, Linux, quite proudly states that at least inside the kernel, interfaces can not and should not be stable. Greg Kroah-Hart’s “Stable API Nonsense” is perhaps one of the strongly and most passionate expositions of that philosophy. I can see both sides of the argument, and in their place, both have something to offer. To Bryan’s first point, it is absolutely true that interfaces can become “bedrock” upon which entire ecosystems are built. Perhaps one of the most enduring and impactful example would be the Unix programming interface, which has since become enshrined by POSIX.2 and successor standards. I would argue, though, that it is the interface that is important, and not the code which initially implemented it. If the interface is powerful enough, and if it appears at the right time, and the initial implementation is good enough (not perfect!), then it can establish itself by virtue of the software which uses it becoming large enough that it assumes an important all out of scale with its original intention. Of course, sometimes such an interface is not perfect. There is an apocryphal story that when S. Feldman at AT&T labs first wrote the ‘make’ utility, that he did so rather quickly, and then put it available for his fellow lab members to use, and then went home to sleep. In some versions of the story he had stayed up late and/or pulled an all-nighter to write it, so he slept a long time. When he came back to work, he had come up with a number of ways to improve the syntax of the Makefile. Unfortunately, (so goes the story) that too many teams were already using the ‘make’ utility, so he didn’t feel he could change the Makefile syntax. I have no evidence that this ever took place, and I suspect it is an urban myth that was invented to explain why Makefiles have a rather ugly and unfortunate syntax that many would call defects, including the use of syntactically significant tab characters which are indistinguishable from other forms of leading whitespace. Another example which is the bane of filesystem designers everywhere are the Unix readdir(2), telldir(2), and seekdir(2) interfaces. These interfaces fundamentally assume that directories are stored in linear linked lists, and filesystems that wish to use more sophisticated data structures, such as b-trees, have to go to extraordinary lengths in order support these interfaces. Very few programs use telldir(2) and seekdir(2), but some filesystems such as JFS maintain two b-trees instead of one just to cater to telldir/seekdir. And yet, it is absolutely true that interfaces can be the bedrock for an entire industry. Certainly no matter what its warts, the Unix/Posix interface has proven the test of time, and it has been responsible for the success of many a company and many billions of dollars of market capitalization. But is this the same as perfect code? No, but if billions of dollars of user applications are going to be depending on that code, it’s best if code which implement such an interface be high quality, and should attempt to achieve perfection. But what does it mean for code to be perfect? For a particular environment, if the requirements can be articulated clearly, I can accept that code can reach perfection, in that it becomes as fast as possible (for the given computer platform), and it handles all exception cases, etc., etc. Unfortunately, in the real world, the environment and the requirements inevitably change over time. For example, Bryan’s cyclic subsystem, which he proudly touts as being if not perfect, almost so, and which executes at least 100 times a second on every Solaris system in the world. I haven’t looked at the cyclic system in any detail, since I don’t want to get myself contaminated (the CDDL and GPLv2 licenses are intentionally incompatible, and given that companies — including Sun — have sued over IPR issues, well, one can’t be too careful), but waking up the CPU from its low-power state 100 times a second isn’t a good thing at all if you are worried about energy conservation in data centers — or in laptops. For example, on my laptop, it is possible to keep wakeups down to no more than 30-35 times a second and it would be possible to do more but for an abstraction limitation. Suppose for example an process wants to be sleep and then receive a wakeup 1 milliseconds later, and so requests this via usleep(). At the same time, another application wants to sleep until some file descriptor activity takes place, or after 1.2 milliseconds takes place. 0.3 milliseconds later, a third process requests a sleep, this time for 0.8 milliseconds. Now, it could be that in all of the above cases, the applications don’t actually need exact timing; if they all get their wakeups plus or minus some fraction of a millisecond, they would be quite cool with that. Unfortunately, the standard timer interfaces have no way of expressing this, and so the OS can’t combine the three wakeups at T+1.0, T+1.1, and T+1.2 milliseconds into one wakeup at T+1.1ms. So this is where Greg K-H’s “Stable API Nonsense” comes into play. We may not be able to solve this problem at the userspace level, but we darn well can solve this problem inside the kernel. Inside the kernel, we can change the timer abstraction to allow device drivers and kernel routines to provide a timer delta plus a notion of how much accuracy is required for a particular timer request. Doing so might change a timer structure that previously external device drivers had depended upon — but too bad, that’s why stable ABI/API’s are not supported for internal kernel interfaces. Is this that the interface could have been extended? Well, perhaps, and perhaps not; if an interface is well designed, it is possible it can be extended in an API and/or ABI compatible way. There usually is a performance cost to doing so, and sometimes it may make sense to pay that that cost, and sometimes it may not. I’ll talk more about that in a future essay. Yet note what happened to the timer implementation. We have a pretty sophisticated timer implementation inside Linux, that uses heap data structures and buckets of timers for efficiency. So while I might not call it perfect, it is pretty good. But, oops! Thanks to this new requirement of energy efficiency, it will likely need to get changed to support variable levels of accuracy and the ability to fire multiple timers that are (more or less) coming due in a single CPU wakeup cycle. Does that make it no longer perfect, or no longer pretty good? Well, it just had a new requirement impact the code, and if criteria for perfection is for the abstraction defined by the code to be “bedrock” and never-changing, and no need to make any changes in said code over multiple years, I would argue that little to no code, even OS code, can ever achieve perfection by that definition — unless that code is no longer being used. (This is the first of a multi-part series of essays on abstractions that I have planned. The next essay which I plan to write will be entitled “Layer surfing, or jumping between layers”, and will be coming soon to a blog near you….)

16 November 2007

Ond&#345;ej &#268;ert&iacute;k: SAGE Days 6

From November 9 till November 15 I attended SAGE Days 6 in Bristol, UK. It was a conference and a coding sprint for the SAGE project, which wants to build something comparable to Mathematica, Maple, Matlab and Magma built only from open source components without reinventing the wheel. Sage also provides excellent novel implementations for many mathematical algorithms (not found in Mathematica/Maple etc.).

I was invited to give a talk about SymPy, which is a Python library for symbolic mathematics, that we are doing.

Here are my notes from each day:

Saturday: one, two
Sunday: one, two
Monday, Tuesday, Wednesday: one

Impressions

Very positive. I started SymPy two years ago, because I wanted to play with symbolic mathematics in Python, see for example my presentation I gave at this conference for details. SAGE at that time was just able to do some mathematics things, but it was very weak in calculus, which is the SymPy's main domain. This has changed last half a year, when SAGE people managed to wrap Maxima in Python (which I thought to be completely impossible), so I started to follow SAGE development more closely. After the SD6, I must say I became very excited about the project.

One problem with mailinglists, IRC and other online interaction is that it's very difficult for me to get an impression about the people and the project. Being able to meet the developers and discuss with them face to face gives me the impression very quickly and very accurately.

By far the biggest guarantee, why it is worthy for me to contribute to SAGE, is the project leader, William Stein. He is very rational and pragmatic (I like these two properties) and after many discussions with him, I came to realize that he has basically identical views on the important things as I do and were I on his place, I would do the same decisions as he did and does. That's very nice, because I can concentrate my energy on things that I like to improve and don't have to worry about other things, because I know he will do it right.

The other SAGE developers are experts and with similar attitude as William has. It's enthusiastic to be among people who make things happen. For example one of the authors of Cython, Robert, implemented during SD6 a very nice HTML output, that shows Cython code, with colors according to how many Python API calls are called on that particular line, and by clicking that line it shows the corresponding C code.

SAGE project has a high aim and it stricly goes for it, without looking too much to the right or left, and that's how it should be. And it does produce a lot of very useful and high quality stuff along the way, for example Cython (probably the best wrapper for C/C++ things now, only pypy could possibly beat it, but that's still more a research project) or the SAGE notebook, which looks like a Mathematica notebook, but better and in a browser (together with a revision history, sharing, SSL encryption, etc.).

The only little problem is that currently SAGE developers are all mathematicians and as is well-known, mathematicians looks at mathematic from a very different prospective than physicists. :) And so I need calculus, advanced calculus and only when this is working, and working well, I can build on it some more advanced features. SAGE currently goes a little the other way - it has a lot of advanced features, from number theory, modular forms, elliptic curves, etc., but the basic calculus still needs a lot of improvements. SAGE wraps Maxima, because Maxima is quite fast, very well tested, so it works well. It's difficult to extend and written in LISP and that's very bad. That's where SymPy could help - it's in Python, very easy to extend, but currently slower than Maxima (rewriting parts of SymPy using Cython, or even C directly, will make it faster, hopefully as fast as Maxima or faster).

It's not yet in Debian, but SAGE people are working on it. It's not an easy task unfortunately.

Conclusion

SAGE is a very promising young project and I think it will succeed to provide an open source alternative to Maple, Matlab, Mathematica and Magma.

Michal &#268;iha&#345;: Lets automate the work

Fixing bugs in code and committing it to VCS usually also means that you need to interact somehow with BTS you use to let it know that the bug has been fixed. This is manual work which could be done by some clever commit scripts, right? All what is needed is just spend some time to set it up. Most of my development currently goes to Gammu/Wammu which uses own Mantis bug tracker. It is already a bit prepared for integration with VCS, but I never found their documentation sufficient. Fortunately somebody wrote tutorial on integrating Mantis and Subversion, which made it quite easy to set up. All what was needed was to put little commit hook into SVN. Now the logical step was to make it also for Debian packages. A bit of Googling revealed discussion on debian-devel. Unfortunately no example for SVN, but ripping out needed things from Manoj's script for Arch was quite easy and I made my own commit hook. While looking at this, I also found wonderful tool called debcommit, which commits changes to Debian package using changelog entries as commit message. I still wonder how many useful tools are hidden to me. The only thing I don't know is why Google didn't show me yesterday svnlog, which seems to have support for Debian BTS out of the box. Maybe I just entered slightly different keywords than today when trying to find the mentioned thread on debian-devel.

Next.

Previous.