Search Results: "ag"

6 September 2017

Mike Gabriel: MATE 1.18 landed in Debian testing

This is to announce that finally all MATE Desktop 1.18 components have landed in Debian testing (aka buster). Credits Again a big thanks to the packaging team (esp. Vangelis Mouhtsis and Martin Wimpress, but also to Jeremy Bicha for constant advice and Aron Xu for joining the Debian+Ubuntu MATE Packaging Team and merging all the Ubuntu zesty and artful branches back to master). Fully Available on all Debian-supported Architectures The very special thing about this MATE 1.18 release for Debian is that MATE is now available on all Debian hardware architectures. See "Buildd" column on our DDPO overview page [1]. Thanks to all the people from the Debian porters realm for providing feedback to my porting questions. References

5 September 2017

Kees Cook: security things in Linux v4.13

Previously: v4.12. Here s a short summary of some of interesting security things in Sunday s v4.13 release of the Linux kernel: security documentation ReSTification
The kernel has been switching to formatting documentation with ReST, and I noticed that none of the Documentation/security/ tree had been converted yet. I took the opportunity to take a few passes at formatting the existing documentation and, at Jon Corbet s recommendation, split it up between end-user documentation (which is mainly how to use LSMs) and developer documentation (which is mainly how to use various internal APIs). A bunch of these docs need some updating, so maybe with the improved visibility, they ll get some extra attention. CONFIG_REFCOUNT_FULL
Since Peter Zijlstra implemented the refcount_t API in v4.11, Elena Reshetova (with Hans Liljestrand and David Windsor) has been systematically replacing atomic_t reference counters with refcount_t. As of v4.13, there are now close to 125 conversions with many more to come. However, there were concerns over the performance characteristics of the refcount_t implementation from the maintainers of the net, mm, and block subsystems. In order to assuage these concerns and help the conversion progress continue, I added an unchecked refcount_t implementation (identical to the earlier atomic_t implementation) as the default, with the fully checked implementation now available under CONFIG_REFCOUNT_FULL. The plan is that for v4.14 and beyond, the kernel can grow per-architecture implementations of refcount_t that have performance characteristics on par with atomic_t (as done in grsecurity s PAX_REFCOUNT). CONFIG_FORTIFY_SOURCE
Daniel Micay created a version of glibc s FORTIFY_SOURCE compile-time and run-time protection for finding overflows in the common string (e.g. strcpy, strcmp) and memory (e.g. memcpy, memcmp) functions. The idea is that since the compiler already knows the size of many of the buffer arguments used by these functions, it can already build in checks for buffer overflows. When all the sizes are known at compile time, this can actually allow the compiler to fail the build instead of continuing with a proven overflow. When only some of the sizes are known (e.g. destination size is known at compile-time, but source size is only known at run-time) run-time checks are added to catch any cases where an overflow might happen. Adding this found several places where minor leaks were happening, and Daniel and I chased down fixes for them. One interesting note about this protection is that is only examines the size of the whole object for its size (via __builtin_object_size(..., 0)). If you have a string within a structure, CONFIG_FORTIFY_SOURCE as currently implemented will make sure only that you can t copy beyond the structure (but therefore, you can still overflow the string within the structure). The next step in enhancing this protection is to switch from 0 (above) to 1, which will use the closest surrounding subobject (e.g. the string). However, there are a lot of cases where the kernel intentionally copies across multiple structure fields, which means more fixes before this higher level can be enabled. NULL-prefixed stack canary
Rik van Riel and Daniel Micay changed how the stack canary is defined on 64-bit systems to always make sure that the leading byte is zero. This provides a deterministic defense against overflowing string functions (e.g. strcpy), since they will either stop an overflowing read at the NULL byte, or be unable to write a NULL byte, thereby always triggering the canary check. This does reduce the entropy from 64 bits to 56 bits for overflow cases where NULL bytes can be written (e.g. memcpy), but the trade-off is worth it. (Besdies, x86_64 s canary was 32-bits until recently.) IPC refactoring
Partially in support of allowing IPC structure layouts to be randomized by the randstruct plugin, Manfred Spraul and I reorganized the internal layout of how IPC is tracked in the kernel. The resulting allocations are smaller and much easier to deal with, even if I initially missed a few needed container_of() uses. randstruct gcc plugin
I ported grsecurity s clever randstruct gcc plugin to upstream. This plugin allows structure layouts to be randomized on a per-build basis, providing a probabilistic defense against attacks that need to know the location of sensitive structure fields in kernel memory (which is most attacks). By moving things around in this fashion, attackers need to perform much more work to determine the resulting layout before they can mount a reliable attack. Unfortunately, due to the timing of the development cycle, only the manual mode of randstruct landed in upstream (i.e. marking structures with __randomize_layout). v4.14 will also have the automatic mode enabled, which randomizes all structures that contain only function pointers. A large number of fixes to support randstruct have been landing from v4.10 through v4.13, most of which were already identified and fixed by grsecurity, but many were novel, either in newly added drivers, as whitelisted cross-structure casts, refactorings (like IPC noted above), or in a corner case on ARM found during upstream testing. lower ELF_ET_DYN_BASE
One of the issues identified from the Stack Clash set of vulnerabilities was that it was possible to collide stack memory with the highest portion of a PIE program s text memory since the default ELF_ET_DYN_BASE (the lowest possible random position of a PIE executable in memory) was already so high in the memory layout (specifically, 2/3rds of the way through the address space). Fixing this required teaching the ELF loader how to load interpreters as shared objects in the mmap region instead of as a PIE executable (to avoid potentially colliding with the binary it was loading). As a result, the PIE default could be moved down to ET_EXEC (0x400000) on 32-bit, entirely avoiding the subset of Stack Clash attacks. 64-bit could be moved to just above the 32-bit address space (0x100000000), leaving the entire 32-bit region open for VMs to do 32-bit addressing, but late in the cycle it was discovered that Address Sanitizer couldn t handle it moving. With most of the Stack Clash risk only applicable to 32-bit, fixing 64-bit has been deferred until there is a way to teach Address Sanitizer how to load itself as a shared object instead of as a PIE binary. early device randomness
I noticed that early device randomness wasn t actually getting added to the kernel entropy pools, so I fixed that to improve the effectiveness of the latent_entropy gcc plugin. That s it for now; please let me know if I missed anything. As a side note, I was rather alarmed to discover that due to all my trivial ReSTification formatting, and tiny FORTIFY_SOURCE and randstruct fixes, I made it into the most active 4.13 developers list (by patch count) at LWN with 76 patches: a whopping 0.6% of the cycle s patches. ;) Anyway, the v4.14 merge window is open!

2017, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

Gunnar Wolf: Made with Creative Commons: Over half translated, yay!

An image speaks for a thousand words...

And our translation project is worth several thousand words!
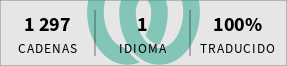
I am very happy and surprised to say we have surpassed the 50% mark of the Made with Creative Commons translation project. We have translated 666 out of 1210 strings (yay for 3v1l numbers)!
I have to really thank Weblate for hosting us and allowing for collaboration to happen there. And, of course, I have to thank the people that have jumped on board and helped the translation We are over half way there! Lets keep pushing!

Translation status

PS - If you want to join the project, just get in Weblate and start translating right away, either to Spanish or other languages! (Polish, Dutch and Norwegian Bokm l are on their way) If you translate into Spanish, *please* read and abide by the specific Spanish translation guidelines.

Chris Lamb: Ask the dumb questions

In the same way it vital to ask the "smart questions", it is equally important to ask the dumb ones. Whilst your milieu might be say comparing and contrasting the finer details of commission structures between bond brokers, if you aren't quite sure of the topic learn to be bold and confident enough to boldly ask: I'm sorry, but what actually is a bond? Don't consider this to be an all-or-nothing affair. After all, you might have at least some idea about what a bond is. Rather, adjust your tolerance to also ask for clarification when you are merely slightly unsure or merely slightly uncertain about a concept, term or reference.
So why do this? Most obviously, you are learning something and expanding your knowledge about the world, but a clarification can avoid problems later if you were mistaken in your assumptions. Not only that, asking "can you explain that?" or admitting "I don't follow " is not only being honest with yourself, the vulnerability you show when admitting one's ignorance opens yourself to others leading to closer friendships and working relationships. We clearly have a tendency to want to come across as knowledgable or perhaps more honestly we don't want to appear dumb or uninformed as it will bruise our ego. But the precise opposite is true: nodding and muddling your way through conversations you only partly understand is unlikely to cultivate true feelings of self-respect and a healthy self-esteem. Since adopting this approach I have found I've rarely derailed the conversation. In fact, speaking up not only encourages and flatters others that you care about their subject, it has invariably lead to related matters which are not only more inclusive but actually novel and interesting to all present.
So push through the voice in your head and be that elephant in the room. After all, you might not the only person thinking it. If it helps, try reframing it to yourself as helping others You'll be finding it effortless soon enough. Indeed, asking the dumb question is actually a positive feedback loop where each question you pose helps you make others in the future. Excellence is not an act, but a habit.

4 September 2017

Jonathan Dowland: Sortpaper: 16:9 edition

sortpaper 16:9 sortpaper 16:9
Back in 2011 I stumbled across a file "sortpaper.png", which was a hand-crafted wallpaper I'd created some time in the early noughties to help me organise icons on my computer's Desktop. I published it at the time in the blog post sortpaper. Since then I rediscovered the blog post, and since I was looking for an excuse to try out the Processing software, I wrote a Processing Sketch to re-create it, but with the size and colours parameterized: sortpaper.pde.txt. The thumbnail above links to an example 1920x1080 rendering.

Dominique Dumont: cme: some read-write backend features are being deprecated

Hello Config::Model and cme read and write configuration data with a set of backend classes, like Config::Model::Backend::IniFile. These classes are managed by Config::Model::BackendMgr. Well, that s the simplified view. Actually, the backend manager can handle several different backends to read and write data: read backends are tried until one of them succeeds to read configuration data. And write backend cen be different from the read backend, thus offering the possibility to migrare from one format to another. This feature came at the beginning of the project, back in 2005. This felt like a good idea to let user migrate from one data format to another. More than 10 years later, this feature has never been used and is handled by a bunch of messy code that hampers further evolution of the backend classes. So, without further ado, I m going to deprecate the following features in order to simplify the backend manager: Unless someone objects, actual removal of these feature will be done in the next few months, after a quite short deprecation period. All the best
Tagged: cme, config-model, Config::Model, configuration

Alessio Treglia: MeteoSurf: a free App for the Mediterranean Sea

meteosurf

MeteoSurf is a free multi-source weather forecasting App designed to provide wind and wave conditions of the Mediterranean Sea. It is an application for smartphones and tablets, built as a Progressive Web App able to supply detailed and updated maps and data showing heights of sea waves (and other information) in the Central Mediterranean. It is mainly targeted for surfers and wind-surfers but anyone who needs to know the sea conditions will take advantage from this app.

Data can be displayed as animated graphical maps, or as detailed table data. The maps refer to the whole Mediterranean Sea, while the table data is able to provide specific information for any of the major surf spots in the Med.

As of current version, MeteoSurf shows data collecting them from 3 different forecasting systems Read More [by Fabio Marzocca]

Lior Kaplan: FOSScamp Syros 2017 day 2

The morning stated by taking the bus to Kini beach. After some to enjoy the water (which were still cold in the morning), we sat for talking about the local Debian community and how can we help it grow. The main topic was localization (l10n), but we soon started to check other options. I reminded them that l10n isn t only translation and we also talked about dictionaries for spell checking, fonts and local software which might be relevant (e.g. hdate for the Jewish/Hebrew calendar or Jcal for the Jalali calendar). For example it seems that regular Latin fonts are missing two Albanian characters. We also talked about how to use Open Labs to better work together with two hats member of the local FOSS community and also as members of various open source projects (not forgetting open content / data ones projects as well). So people can cooperate both on the local level, the international level or to mix (using the other s project international resources). In short: connections, connections, connections. Another aspect I tried to push the guys toward is cooperating with local companies about open source, whether it s the local market, the municipal and general government. Such cooperation can take many forms, sponsoring events / giving resources (computers, physical space or employee s time) and of course creating more jobs for open source people, which in turn will support more people doing open source for longer period. One of the guys thought benefit the local community will benefit from a mirror server, but that also requires to see the network topology of Albania to make sure it makes sense to invest in one (resources and effort). We continued to how it would be best to contribute to open source, mostly that Debian, although great isn t always the best target, and they should always try to work with the relevant upstream. It s better to translate gnome upstream then sending the Debian maintainer the translation to be included in the package. That shortcut can work if there s something urgent like a really problematic typo or something what unless done before the release would require a long long wait (e.g. the next Debian release). I gave an example that for important RTL bugs in LibreOffice I ve asked Rene Engelhard to include the patch instead of waiting for the next release and its inclusion in Debian. When I started the conversation I mentioned that we have 33% females out of the 12 participants. And that s considered good comparing to other computer/technical events, especially open source. To my surprise the guys told me that in the Open Labs hackerspace the situation is the opposite, they have more female members than male (14 female to 12 male). Also in their last OSCAL event they had 220 women and 100 men. I think there s grounds to learn what happens there, as the gals do something damn right over there. Maybe Outreachy rules for Albania should be different (: Later that day I did another session with Redon Skikuli to be more practical, so I started to search on an Albanian dictionary for spell checking, found an old one and asked Redon to check the current status with the guy. And also check info about such technical stuff with Social Sciences and Albanological Section of the Academy of Sciences of Albania, who is officially the regulator for Albanian. In parallel I started to check how to include the dictionary in LibreOffice, and asked Rene Engelhard to enable Albanian language pack in Debian (as upstream already provide one). Checking the dictionaries I ve took the opportunity to update the Hebrew. It took me a little longer as I needed to get rust off my LibreOffice repositories (dictionaries is a different repository) and also the gerrit setup. But in the end: https://gerrit.libreoffice.org/#/c/41864/ With the talks toady and the starting to combine both Debian and LibreOffice work today (although much of it was talking) I felt like I m the right person on the right place. I m happy to be here and contribute to two projects in parallel (:
Filed under: Debian GNU/Linux, i18n & l10n, LibreOffice

Daniel Pocock: Spyware Dolls and Intel's vPro

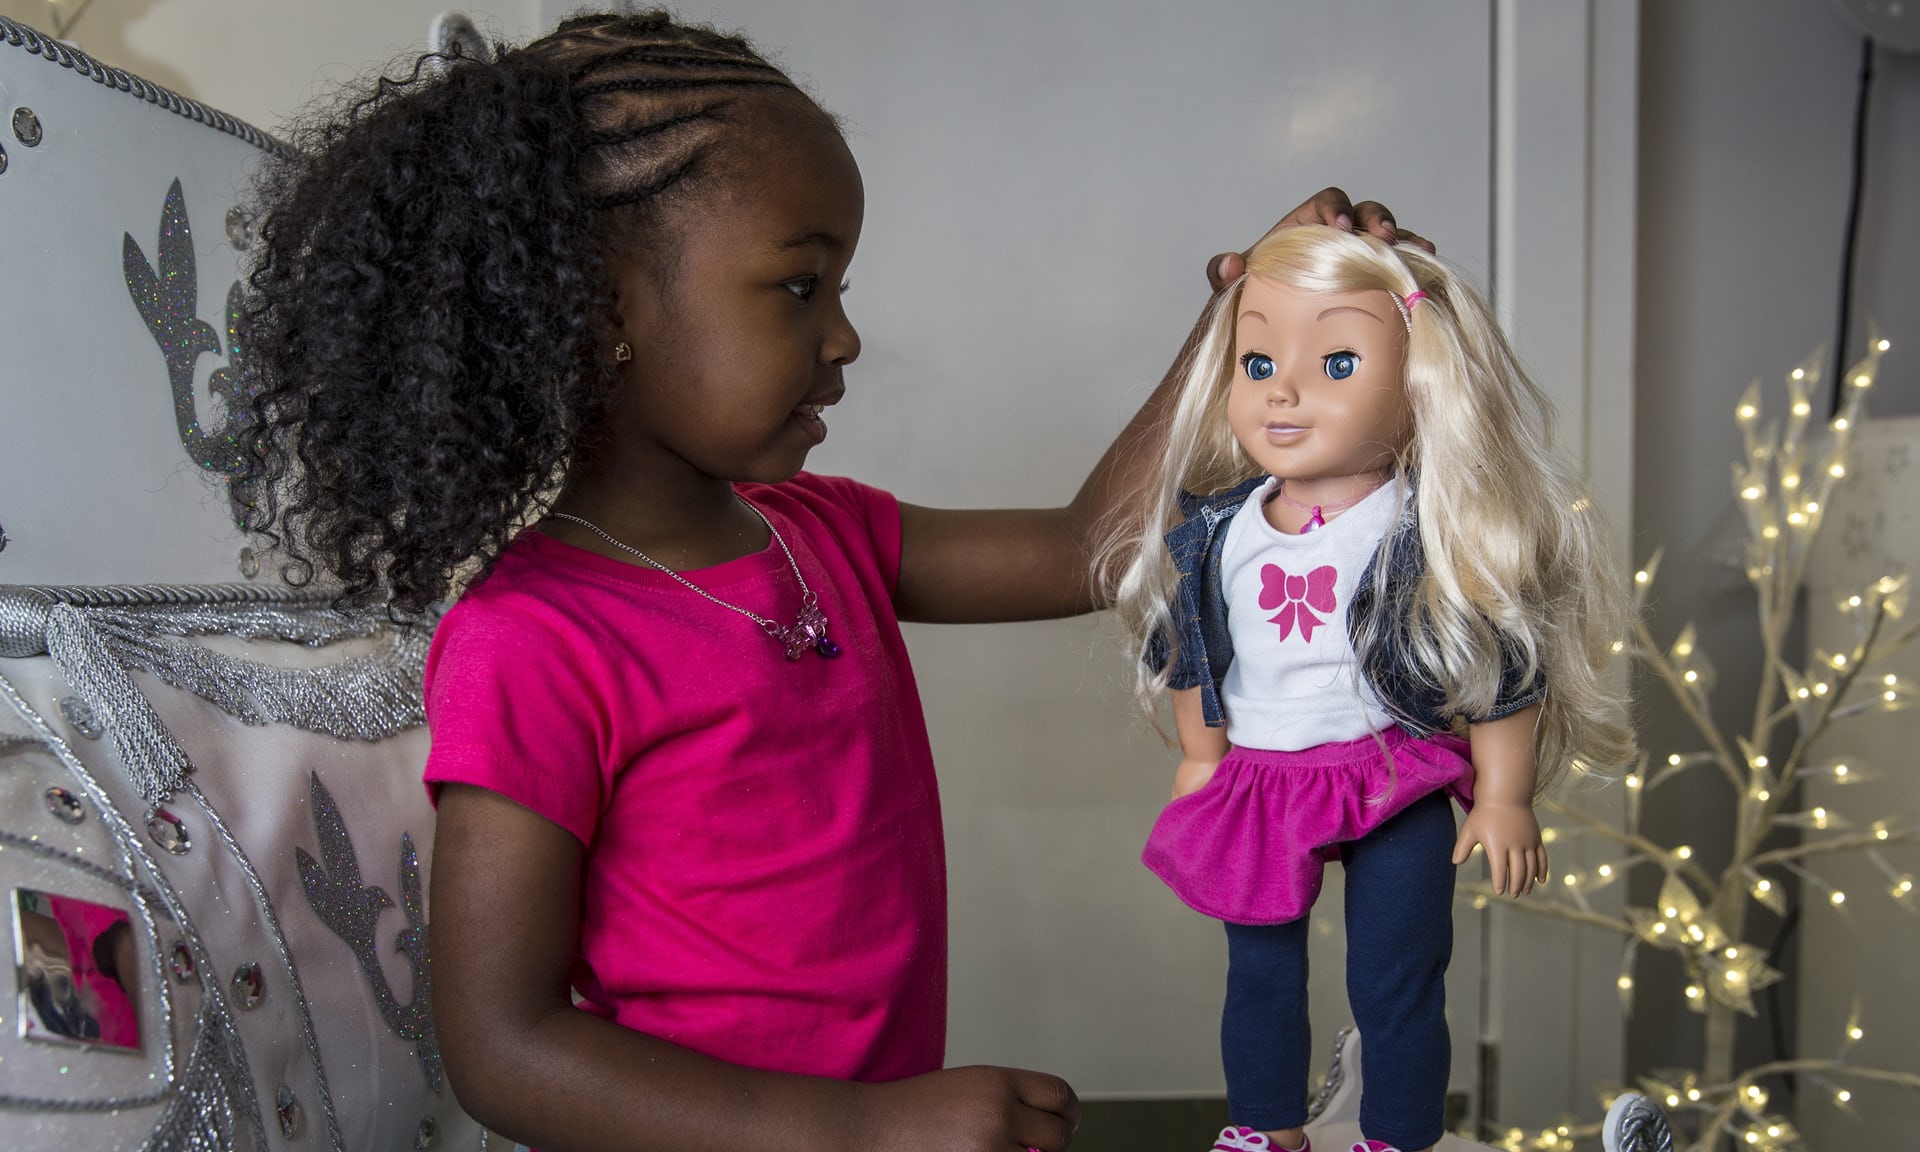
Back in February, it was reported that a "smart" doll with wireless capabilities could be used to remotely spy on children and was banned for breaching German laws on surveillance devices disguised as another object. Would you trust this doll? For a number of years now there has been growing concern that the management technologies in recent Intel CPUs (ME, AMT and vPro) also conceal capabilities for spying, either due to design flaws (no software is perfect) or backdoors deliberately installed for US spy agencies, as revealed by Edward Snowden. In a 2014 interview, Intel's CEO offered to answer any question, except this one. The LibreBoot project provides a more comprehensive and technical analysis of the issue, summarized in the statement "the libreboot project recommends avoiding all modern Intel hardware. If you have an Intel based system affected by the problems described below, then you should get rid of it as soon as possible" - eerily similar to the official advice German authorities are giving to victims of Cayla the doll. All those amateur psychiatrists suggesting LibreBoot developers suffer from symptoms of schizophrenia have had to shut their mouths since May when Intel confirmed a design flaw (or NSA backdoor) in every modern CPU had become known to hackers. Bill Gates famously started out with the mission to put a computer on every desk and in every home. With more than 80% of new laptops based on an Intel CPU with these hidden capabilities, can you imagine the NSA would not have wanted to come along for the ride? Four questions everybody should be asking
  • If existing laws can already be applied to Cayla the doll, why haven't they been used to alert owners of devices containing Intel's vPro?
  • Are exploits of these backdoors (either Cayla or vPro) only feasible on a targeted basis, or do the intelligence agencies harvest data from these backdoors on a wholesale level, keeping a mirror image of every laptop owner's hard disk in one of their data centers, just as they already do with phone and Internet records?
  • How long will it be before every fast food or coffee chain with a "free" wifi service starts dipping in to the data exposed by these vulnerabilities as part of their customer profiling initiatives?
  • Since Intel's admissions in May, has anybody seen any evidence that anything is changing though, either in what vendors are offering or in terms of how companies and governments outside the US buy technology?
Share your thoughts This issue was recently raised on the LibrePlanet mailing list. Please feel free to join the list and click here to reply on the thread.

3 September 2017

Lior Kaplan: FOSScamp Syros 2017 day 1

During Debconf17 I was asked by Daniel Pocock if I can attend FOSScamp Syros to help with Debian s l10n in the Balkans. I said I would be happy to, although my visit would be short (2.5 days) due to previous plans. The main idea of camp is to have FOSS people meet for about 1 week near a beach. So it s sun, water and free software. This year it takes place in Syros, Greece. After take the morning ferry, I met with the guys at noon. I didn t know how would it be, as it s my first time with this group/meeting, but they were very nice and welcoming. 10 minutes after my arrival I found myself setting with two of the female attendees starting to work on Albanian (sq) translation of Debian Installer. It took my a few minutes to find my where to check out the current level1 files, as I thought they aren t in SVN anymore, but ended up learning the PO files is the only part of the installer still on SVN. As the girls were quick with the assinged levle1 sublevels, I started to look for the level2 and level3 files, and it was annoying to have the POT files very accessible, but no links to the relevant git repositories. I do want to have all the relevant links in one central place, so people who want to help with translation could do that. While some of the team member just used a text editor to edit the files, I suggested to them using either poedit or granslator, both I used a few years ago. Yaron Shahrabani also recommended virtaal to me, but after trying it for a while I didn t like it (expect it s great feature showing the diff with fuzzy messages). For the few people who also have Windows on their machine, both poedit and Virtaal have windows binaries for download. So you don t have to have Linux in order to help with translations. In parallel, I used the free time to work on the Hebrew translation for level1, as it s been a while since either me or Omer Zak worked on it. Quite soon the guys started to send me the files for review, and I did find some errors using diff. Especially when not everyone use a PO editor. I also missed a few strings during the review, which got fixed later on by Christian Perrier. Team work indeed (: I found it interesting to see the reactions and problems for the team to work with the PO files, and most projects now use some system (e.g. Pootle) for online web translation. Which saves some of the head ace, but also prevents from making some review and quality check before submitting the files. It s a good idea to explore this option for Debian as well. A tip for those who do want to work with PO files, either use git s diff features or use colordiff to check your changes (notice less will require -R parameter to keep the color). Although I met the guys only at noon, the day was very fruitful for Debian Installer l10n: Some files are still work in progress and will be completed tomorrow. My goal is to have Albanian at 100% during the camp and ready for the next d-i alpha. I must admit that I remember d-i to have many more strings as part of the 3 levels, especially levels 2+3 which were huge (e.g. the iso codes). Except all the work and FOSS related conversations, I found a great group who welcomed me quickly, made me feel comfortable and taught me a thing or two about Greece and the Syros specifically. TIP: try the dark chocolate with red hot chili pepper in the icecream shop.
Filed under: Debian GNU/Linux, i18n & l10n

Thorsten Alteholz: My Debian Activities in August 2017

FTP assistant This month I accepted 217 packages and rejected 16 uploads. Though this might seem to be a low number this month, I am very pleased about the total number of packages that have been accepted: 558. Debian LTS This was my thirty-eight month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 20.25h. During that time I did LTS uploads of: I also did the upload and sent the DLA for [DLA 1061-1] newsbeuter security update Last but not least I also spent some time for frontdesk duties. Other stuff As announced last month I finished uploading all dependencies of glewlwyd and now we have an oauth2 server available in Debian. This month I am trying to really use it and will tell you about my experiences. As the severity of the gcc-7 bugs have been raised, I took care of: #853501, #853304, #853305, #853306, #853307, #853308 and #871088 I also uploaded a new version of duktape and now try to also provide a library that can be used in other packages. Last but not least my DOPOM of this month has been oysttyer. Actually it is a new package, but as ttytter has been abandonded upstream, this is the replacement. It is a fork so you should only get a new authorization key and simply use it as ttytter before.

2 September 2017

David Bremner: Indexing Debian's buildinfo

Introduction Debian is currently collecting buildinfo but they are not very conveniently searchable. Eventually Chris Lamb's buildinfo.debian.net may solve this problem, but in the mean time, I decided to see how practical indexing the full set of buildinfo files is with sqlite.

Hack
  1. First you need a copy of the buildinfo files. This is currently about 2.6G, and unfortunately you need to be a debian developer to fetch it.
     $ rsync -avz mirror.ftp-master.debian.org:/srv/ftp-master.debian.org/buildinfo .
    
  2. Indexing takes about 15 minutes on my 5 year old machine (with an SSD). If you index all dependencies, you get a database of about 4G, probably because of my natural genius for database design. Restricting to debhelper and dh-elpa, it's about 17M.
     $ python3 index.py
    
    You need at least python3-debian installed
  3. Now you can do queries like
     $ sqlite3 depends.sqlite "select * from depends where depend='dh-elpa' and depend_version<='0106'"
    
    where 0106 is some adhoc normalization of 1.6

Conclusions The version number hackery is pretty fragile, but good enough for my current purposes. A more serious limitation is that I don't currently have a nice (and you see how generous my definition of nice is) way of limiting to builds currently available e.g. in Debian unstable.

Antoine Beaupr : My free software activities, August 2017

Debian Long Term Support (LTS) This is my monthly Debian LTS report. This month I worked on a few major packages that took a long time instead of multiple smaller issues. Affected packages were Mercurial, libdbd-mysql-perl and Ruby.

Mercurial updates Mercurial was vulnerable to two CVEs: CVE-2017-1000116 (command injection on clients through malicious ssh URLs) and CVE-2017-1000115 (path traversal via symlink). The former is an issue that actually affects many other similar software like Git (CVE-2017-1000117), Subversion (CVE-2017-9800) and even CVS (CVE-2017-12836). The latter symlink issue is a distinct issue that came up during an internal audit. The fix, shipped as DLA-1072-1, involved a rather difficult backport, especially because the Mercurial test suite takes a long time to complete. This reminded me of the virtues of DEB_BUILD_OPTIONS=parallel=4, which sped up the builds considerably. I also discovered that the Wheezy build chain doesn't support sbuild's --source-only-changes flag which I had hardcoded in my sbuild.conf file. This seems to be simply because sbuild passes --build=source to dpkg-buildpackage, an option that is supported only in jessie or later.

libdbd-mysql-perl I have worked on fixing two issues with the libdbd-mysql-perl package, CVE-2017-10788 and CVE-2017-10789, which resulted in the DLA-1079-1 upload. Behind this mysteriously named package sits a critical piece of infrastructure, namely the mysql commandline client which is probably used and abused by hundreds if not thousands of home-made scripts, but also all of Perl's MySQL support, which is probably used by even a larger base of software. Through the Debian bug reports (Debian bug #866818 and Debian bug #866821), I have learned that the patches existed in the upstream tracker but were either ignored or even reverted in the latest 4.043 upstream release. It turns out that there are talks of forking that library because of maintainership issue. It blows my mind that such an important part of MySQL is basically unmaintained. I ended up backporting the upstream patches, which was also somewhat difficult because of the long-standing issues with SSL support in MySQL. The backport there was particularly hard to test, as you need to run that test suite by hand, twice: once with a server configured with a (valid!) SSL certificate and one without (!). I'm wondering how much time it is really worth spending on trying to fix SSL in MySQL, however. It has been badly broken forever, and while the patch is an improvement, I would actually still never trust SSL transports in MySQL over an untrusted network. The few people that I know use such transports wrap their connections around a simpler stunnel instead. The other issue was easier to fix so I submitted a pull request upstream to make sure that work isn't lost, although it is not clear what the future of that patch (or project!) will be at this point.

Rubygems I also worked on the rubygems issues, which, thanks to the "vendoring" practice of the Ruby community, also affects the ruby1.9 package. 4 distinct CVEs were triaged here (CVE-2017-0899, CVE-2017-0900, CVE-2017-0901 and CVE-2017-0902) and I determined the latter issue didn't affect wheezy as rubygems doesn't do its own DNS resolution there (later versions lookup SRV records). This is another package where the test suite takes a long time to run. Worse, the packages in Wheezy actually fails to build from source: the test suites just fail in various steps, particularly because of dh key too small errors for Rubygems, but also other errors for Ruby. I also had trouble backporting one test which I had to simply skip for Rubygems. I uploaded and announced test packages and hopefully I'll be able to complete this work soon, although I would certainly appreciate any help on this...

Triage I took a look at the sox, libvorbis and exiv2 issues. None had fixes available. sox and exiv2 were basically a list of fuzzing issues, which are often minor or at least of unknown severity. Those would have required a significant amount of work and I figured I would prioritize other work first. I also triaged CVE-2017-7506, which doesn't seem to affect the spice package in wheezy, after doing a fairly thorough audit of the code. The vulnerability is specifically bound to the reds_on_main_agent_monitors_config function, which is simply not present in our older version. A hostile message would fall through the code and not provoke memory allocation or out of bounds access, so I simply marked the wheezy version as not-affected, something which usually happens during the original triage but can also happen during the actual patching work, as in this case.

Other free software work This describes the volunteer work I do on various free software projects. This month, again, my internal reports show that I spent about the same time on volunteer and paid time, but this is probably a wrong estimate because I spent a lot of time at Debconf which I didn't clock in...

Debconf So I participated in the 17th Debian Conference in Montreal. It was great to see (and make!) so many friends from all over the world in person again, and I was happy to work on specific issues together with other Debian developers. I am especially thankful to David Bremner for fixing the syncing of the flagged tag when added to new messages (patch series). This allows me to easily sync the one tag (inbox) that is not statically assigned during notmuch new, by using flagged as a synchronization tool. This allows me to use notmuch more easily across multiple machines without having to sync all tags with dump/restore or using muchsync which wasn't working for me (although a new release came out which may fix my issues). The magic incantation looks something like this:
notmuch tag -inbox tag:inbox and not tag:flagged
notmuch tag +inbox not tag:inbox and tag:flagged
However, most of my time in the first week (Debcamp) was spent trying to complete the networking setup: configure switches, setup wiring and so on. I also configured an apt-cacher-ng proxy to serve packages to attendees during the conference. I configured it with Avahi to configure clients automatically, which led me to discover (and fix) issue Debian bug #870321) although there are more issues with the autodiscovery mechanism... I spent extra time to document the (somewhat simple) configuration of such a server in the Debian wiki because it was not the first time I had research that procedure... I somehow thought this was a great time to upgrade my laptop to stretch. Normally, I keep that device running stable because I don't use it often and I don't want to have major traumatizing upgrades every time I leave with it on a trip. But this time was special: there were literally hundreds of Debian developers to help me out if there was trouble. And there was, of course, trouble as it turns out! I had problems with the fonts on my display, because, well, I had suspended (twice) my laptop during the install. The fix was simply to flush the fontconfig cache, and I tried to document this in the fonts wiki page and my upgrades page. I also gave a short training called Debian packaging 101 which was pretty successful. Like the short presentation I made at the last Montreal BSP, the workshop was based on my quick debian development guide. I'm thinking of expanding this to a larger audience with a "102" course that would discuss more complex packaging problems. But my secret plan (well, secret until now I guess) is to make packaging procedures more uniform in Debian by training new Debian packagers using that same training for the next 2 decades. But I will probably start by just trying to do this again at the next Debconf, if I can attend.

Debian uploads I also sponsored two packages during Debconf: one was a "scratch an itch" upload (elpa-ivy) which I requested (Debian bug #863216) as part of a larger effort to ship the Emacs elisp packages as Debian packages. The other was an upload of diceware to build the documentation in a separate package and fix other issues I have found in the package during a review. I also uploaded a bunch of other fixes to the Debian archive:

Signing keys rotation I also started the process of moving my main OpenPGP certification key by adding a signing subkey. The subkey is stored in a cryptographic token so I can sign things on more than one machine without storing that critical key on all those devices physically. Unfortunately, this meant that I need to do some shenanigans when I want to sign content in my Debian work, because the new subkey takes time to propagate to the Debian archive. For example, I have to specify the primary key with a "bang" when signing packages (debsign -k '792152527B75921E!' ...) or use inline signatures in email sent for security announcement (since that trick doesn't work in Mutt or Notmuch). I tried to figure out how to better coordinate this next time by reading up documentation on keyring.debian.org, but there is no fixed date for key changes on the rsync interface. There are "monthly changes" so one's best bet is to look for the last change in their git repository.

GitLab.com and LFS migration I finally turned off my src.anarc.at git repository service by moving the remaining repos to GitLab. Unfortunately, GitLab removed support for git-annex recently, so I had to migrate my repositories to Git-LFS, which was an interesting experience. LFS is pretty easy to use, definitely simpler than git-annex. It also seems to be a good match for the use-case at hand, which is to store large files (videos, namely) as part of slides for presentations. It turns out that their migration guide could have been made much simpler. I tried to submit those changes to the documentation but couldn't fork the GitLab EE project to make a patch, so I just documented the issue in the original MR for now. While I was there I filed a feature request to add a new reference shortcut (GL-NNN) after noticing a similar token used on GitHub. This would be a useful addition because I often have numbering conflicts between Debian BTS bug numbers and GitLab issues in packages I maintain there. In particular, I have problems using GitLab issue numbers in Monkeysign, because commit logs end up in Debian changelogs and will be detected by the Debian infrastructure even though those are GitLab bug numbers. Using such a shortcut would avoid detection and such a conflict.

Numpy-stats I wrote a small tool to extract numeric statistics from a given file. I often do ad-hoc benchmarks where I store a bunch of numbers in a file and then try to make averages and so on. As an exercise in learning NumPy, I figured I would write such a simple tool, called numpy-stats, which probably sounds naive to seasoned Python scientists. My incentive was that I was trying to figure out what was the distribution of password length in a given password generator scheme. So I wrote this simple script:
for i in seq 10000 ; do
    shuf -n4 /usr/share/dict/words   tr -d '\n'
done > length
And then feed that data in the tool:
$ numpy-stats lengths 
 
  "max": 60, 
  "mean": 33.883293722913464, 
  "median": 34.0, 
  "min": 14, 
  "size": 143060, 
  "std": 5.101490225062775
 
I am surprised that there isn't such a tool already: hopefully I am wrong and will just be pointed towards the better alternative in the comments here!

Safe Eyes I added screensaver support to the new SafeEyes project, which I am considering as a replacement to the workrave project I have been using for years. I really like how the interruptions basically block the whole screen: way more effective than only blocking the keyboard, because all potential distractions go away. One feature that is missing is keystrokes and mouse movement counting and of course an official Debian package, although the latter would be easy to fix because upstream already has an unofficial build. I am thinking of writing my own little tool to count keystrokes, since the overlap between SafeEyes and such a counter isn't absolutely necessary. This is something that workrave does, but there are "idle time" extensions in Xorg that do not need to count keystrokes. There are already certain tools to count input events, but none seem to do what I want (most of them are basically keyloggers). It would be an interesting test to see if it's possible to write something that would work both for Xorg and Wayland at the same time. Unfortunately, preliminary research show that:
  1. in Xorg, the only way to implement this is to sniff all events, ie. to implement a keylogger
  2. in Wayland, this is completely unsupported. it seems some compositors could implement such a counter, but then it means that this is compositor specific, or, in other words, unportable
So there is little hope here, which brings to my mind "painmeter" as an appropriate name for this future programming nightmare.

Ansible I sent my first contribution to the ansible project with a small documentation fix. I had an eye opener recently when I discovered a GitLab ansible prototype that would manipulate GitLab settings. When I first discovered Ansible, I was frustrated by the YAML/Jinja DSL: it felt silly to write all this code in YAML when you are a Python developer. It was great to see reasonably well-written Python code that would do things and delegate the metadata storage (and only that!) to YAML, as opposed to using YAML as a DSL. So I figured I would look at the Ansible documentation on how this works, but unfortunately, the Ansible documentation is severly lacking in this area. There are broken links (I only fixed one page) and missing pieces. For example, the developing plugins page doesn't explain how to program a plugin at all. I was told on IRC that: "documentation around developing plugins is sparse in general. the code is the best documentation that exists (right now)". I didn't get a reply when asking which code in particular could provide good examples either. In comparison, Puppet has excellent documentation on how to create custom types, functions and facts. That is definitely a turn-off for a new contributor, but at least my pull request was merged in and I can only hope that seasoned Ansible contributors expand on this critical piece of documentation eventually.

Misc As you can see, I'm all over the place, as usual. GitHub tells me I "Opened 13 other pull requests in 11 repositories" (emphasis mine), which I guess means on top of the "9 commits in 5 repositories" mentioned earlier. My profile probably tells a more detailed story that what would be useful to mention here. I should also mention how difficult it is to write those reports: I basically do a combination of looking into my GitHub and GitLab profiles, the last 30 days of emails (!) and filesystem changes (!!). En vrac, a list of changes which may be of interest:
  • font-large (and its alias, font-small): shortcut to send the right escape sequence to rxvt so it changes its font
  • fix-acer: short script to hardcode the modeline (you remember those?!) for my screen which has a broken EDID pin (so autodetection fails, yay Xorg log files...)
  • ikiwiki-pandoc-quickie: fake ikiwiki renderer that (ab)uses pandoc to generate a HTML file with the right stylesheet to preview Markdown as it may look in this blog (the basic template is missing still)
  • git-annex-transfer: a command I've often been missing in git-annex, which is a way to transfer files between remotes without having to copy them locally (upstream feature request)
  • I linked the graphics of the Debian archive software architecture in the Debian wiki in the hope more people notice it.
  • I did some tweaks on my Taffybar to introduce a battery meter and hoping to have temperature sensors, which mostly failed. there's a pending pull request that may bring some sense into this, hopefully.
  • I made two small patches in Monkeysign to fix gpg.conf handling and multiple email output, a dumb bug I cannot believe anyone noticed or reported just yet. Thanks Valerie for the bug report! The upload of this in Debian is pending a review from the release team.

Wouter Verhelst: Playing with Moose and FFmpeg

As I've blogged before, I've been on and off working on SReview, a video review system. Development over the past year has been mostly driven by the need to have something up and running for first FOSDEM 2017, and then DebConf17, and so I've cut corners left and right which made the system, while functional, not quite entirely perfect everywhere. For instance, the backend scripts were done in ad-hoc perl, each reinventing their own wheel. Doing so made it easier for me to experiment with things and figure out where I want them to go, without immediately creating a lot of baggage that is not necessarily something I want to be stuck to. This flexibility has already paid off, in that I've redone the state machine between FOSDEM and DebConf17 and all it needed was to update a few SQL statements here and there. Well, and add a few of them, too. It was always the intent to replace most of the ad-hoc perl with something better, however, once the time was ripe. One place where historical baggage is not so much of a problem, and where in fact abstracting away the complexity would now be an asset, is in the area of FFmpeg command lines. Currently, these are built by simple string expansion. For example, we do something like this (shortened for brevity):
system("ffmpeg -y -i $outputdir/$slug.ts -pass 1 -passlogfile ...");
inside an environment where the $outputdir and $slug variables are set in a perl environment. That works, but it has some downsides; e.g., adding or removing options based on which codecs we're using is not so easy. It would be much more flexible if the command lines were generated dynamically based on requested output bandwidth and codecs, rather than that they be hardcoded in the file. Case in point: currently there are multiple versions of some of the backend scripts, that only differ in details mostly the chosen codec on the ffmpeg command line. Obviously this is suboptimal. Instead, we want a way where video file formats can be autodetected, so that I can just say "create a file that uses encoder etc settings of this other file here". In addition, we also want a way where we can say "create a file that uses encoder etc settings of this other file here, except for these one or two options that I want to fine-tune manually". When I first thought about doing that about a year ago, that seemed complicated and not worth it or at least not to that extent. Enter Moose. The Moose OO system for Perl 5 is an interesting way to do object orientation in Perl. I knew Perl supports OO, and I had heard about Moose, but never had looked into it, mostly because the standard perl OO features were "good enough". Until now. Moose has a concept of adding 'attributes' to objects. Attributes can be set at object construction time, or can be accessed later on by way of getter/setter functions, or even simply functions named after the attribute itself (the default). For more complicated attributes, where the value may not be known until some time after the object has been created, Moose borrows the concept of "lazy" variables from Perl 6:
package Object;
use Moose;
has 'time' => (
    is => 'rw',
    builder => 'read_time',
    lazy => 1,
);
sub read_time  
    return localtime();
 
The above object has an attribute 'time', which will not have a value initially. However, upon first read, the 'localtime()' function will be called, the result is cached, and then (and on all further calls of the same function), the cached result will be returned. In addition, since the attribute is read/write, the time can also be written to. In that case, any cached value that may exist will be overwritten, and if no cached value exists yet, the read_time function will never be called. (it is also possible to clear values if needs be, so that the function would be called again). We use this with the following pattern:
package SReview::Video;
use Moose;
has 'url' => (
    is => 'rw',
)
has 'video_codec' => (
    is => 'rw',
    builder => '_probe_videocodec',
    lazy => 1,
);
has 'videodata' => (
    is => 'bare',
    reader => '_get_videodata',
    builder => '_probe_videodata',
    lazy => 1,
);
has 'probedata' => (
    is => 'bare',
    reader => '_get_probedata',
    builder => '_probe',
    lazy => 1,
);
sub _probe_videocodec  
    my $self = shift;
    return $self->_get_videodata-> codec_name ;
 
sub _probe_videodata  
    my $self = shift;
    if(!exists($self->_get_probedata-> streams ))  
        return  ;
     
    foreach my $stream(@ $self->_get_probedata-> streams )  
        if($stream-> codec_type  eq "video")  
            return $stream;
         
     
    return  ;
 
sub _probe  
    my $self = shift;
    open JSON, "ffprobe -print_format json -show_format -show_streams " . $self->url . " "
    my $json = "";
    while(<JSON>)  
        $json .= $_;
     
    close JSON;
    return decode_json($json);
 
The videodata and probedata attributes are internal-use only attributes, and are therefore of the 'bare' type that is, they cannot be read nor written to. However, we do add 'reader' functions that can be used from inside the object, so that the object itself can access them. These reader functions are generated, so they're not part of the object source. The probedata attribute's builder simply calls ffprobe with the right command-line arguments to retrieve data in JSON format, and then decodes that JSON file. Since the passed JSON file contains an array with (at least) two streams one for video and one for audio and since the ordering of those streams depends on the file and is therefore not guaranteed, we have to loop over them. Since doing so in each and every attribute of the file we might be interested in would be tedious, we add a videodata attribute that just returns the data for the first found video stream (the actual source also contains a similar one for audio streams). So, if you create an SReview::Video object and you pass it a filename in the url attribute, and then immediately run print $object->video_codec, then the object will However, if the caller first calls $object->video_codec('h264'), then the ffprobe and most of the caching will be skipped, and instead the h265 data will be returned as video codec name. Okay, so with a reasonably small amount of code, we now have a bunch of attributes that have defaults based on actual files but can be overwritten when necessary. Useful, right? Well, you might also want to care about the fact that sometimes you want to generate a video file that uses the same codec settings of this other file here. That's easy. First, we add another attribute:
has 'reference' => (
    is => 'ro',
    isa => 'SReview::Video',
    predicate => 'has_reference'
);
which we then use in the _probe method like so:
sub _probe  
    my $self = shift;
    if($self->has_reference)  
        return $self->reference->_get_probedata;
     
    # original code remains here
 
With that, we can create an object like so:
my $video = SReview::Video->new(url => 'file.ts');
my $generated = SReview::Video->new(url => 'file2.ts', reference => $video);
now if we ask the $generated object what the value of its video_codec setting is without telling it ourselves first, it will use the $video object for its probed data, and use that. That only misses generating the ffmpeg command line, but that's all fairly straightforward and therefore left as an exercise to the reader. Or you can cheat, and look it up.

Daniel Silverstone: F/LOSS activity, August 2017

Shockingly enough, my focus started out on Gitano once more. We managed a 1.1 release of Gitano during the Debian conference's "camp" which occurs in the week before the conference. This was a joint effort of myself, Richard Maw, and Richard Ipsum. I have to take my hat off to Richard Maw, because without his dedication to features, 1.1 would lack some stuff which Richard Ipsum proposed around ruleset support for basic readers/writers and frankly 1.1 would be a weaker release without it. Because of the debconf situation, we didn't have a Gitano developer day which, while sad, didn't slow us down much...

Not Gitano Of course, not everything I did in August was Gitano related. In fact once I had completed the 1.1 release and uploaded everything to Debian I decided that I was going to take a break from Gitano until the next developer day. (In fact there's even some patch series still unread on the mailing list which I will get to when I start the developer day.) I have long been interested in STM32 microcontrollers, using them in a variety of projects including the Entropy Key which some of you may remember. Jorge Aparicio was working on Cortex-M3 support (among other microcontrollers) in Rust and he then extended that to include a realtime framework called RTFM and from there I got interested in what I might be able to do with Rust on STM32. I noticed that there weren't any pure Rust implementations of the USB device stack which would be necessary in order to make a device, programmed in Rust, appear on a USB port for a computer to control/use. This tweaked my interest. As many of my readers are aware, I am very bad at doing things without some external motivation. As such, I then immediately offered to give a talk at a conference which should be happening in November, just so that I'd be forced to get on with learning and implementing the stack. I have been chronicling my work in this blog, and you're encouraged to go back and read them if you have similar interests. I'm sure that as my work progresses, I'll be doing more and more of that and less of Gitano, for at least the next two months. To bring that into context as F/LOSS work, I did end up submitting some patches to Jorge's STM32F103xx repository to support a couple more clock configuration entries so that USB and ADCs can be set up cleanly. So at least there's that.

Clint Adams: Litigants

Bronwyn s mom got hit by a semi. She was on the passenger side of the car, the side of impact, and she did not rebound with extreme resilience. The family sued the trucking company and came away with a settlement of roughly $10 million. The lawyers took $6.5 million of that: quite a deal. Bronwyn learned two things from this, and neither one was about Christopher Lloyd.
Posted on 2017-09-02
Tags: mintings

1 September 2017

Clint Adams: Good night moon and spoon balloon

Hello, said Adrian, but Adrian was lying. My name is Adrian, said Adrian, but Adrian was lying.
Posted on 2017-09-01
Tags: bgs

Rapha&#235;l Hertzog: My Free Software Activities in August 2017

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donors (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Debian LTS This month I was allocated 12h and during this time I did 4 days of front desk handling CVE triage (28 commits to the security tracker). I had a bit of time left and I opted to work on a package that had been lingering for a while: exiv2. It turns out the security researchers who requested the CVE did not even contact the upstream author so I opened 12 tickets on GitHub. The upstream author was unaware of those issues and is relatively unfamiliar with the general process of handling security updates. I started the work of reproducing each issue and so far they only affect the version 0.26 in experimental. Misc Debian/Kali work live-build and live-config. I pushed a few updates: dropping the useless xorriso hardlinks option (as discussed in https://bugs.kali.org/view.php?id=4109), adding a .disk/mkisofs file on request of Thomas Schmitt, fixing a severe issue with the handling of locales configuration that broke wayland sessions entirely. open-vm-tools and vmwgfx. The switch of GNOME to Wayland by default resulted in multiple regressions reported by Kali users, in particular for VMWare users where desktop resizing was no longer working. There was a patch available but it did not work for me, so I worked with Thomas Hellstrom (of VMWare) to identify the problems and he provided me an updated patch. I submitted this patch to Debian too (bug report, pull request). Linux 4.12 also showed another regression for VMWare users where the screen would not be refreshed/updated when you are using Wayland/KMS. I did multiple tests for Thomas and provided the requested data so that they could create a fix (which I incorporated into Kali and should come to Debian through the upstream stable tree). Packaging. I uploaded zim 0.67 to unstable. I fixed an RC bug on shiboken to get pyside and ubertooth back into testing. I had to hack the package to use gcc-6 on mips64el because that architecture is suffering from a severe gcc bug which probably broke a large part of the code compiled since the switch to gcc-7 (and which triggered a test failure in shiboken, fortunately) I wonder if anybody will make sure to recompile all packages that might have been misbuilt. Infrastructure. In a discussion on debian-devel, the topic of using tracker.debian.org to store who is maintaining what came up again. I responded to let know that this is something that I d like to see done and that I have already taken measures to go into this direction. I wanted to make an experiment with my zim package but quickly came on a problem with ftpmaster s lintian auto-rejects (which I submitted in #871575). The BTS is now linking to tracker.debian.org on its web interface. To continue and give a push to this move, I scanned all the files in the qa SVN repository and updated many occurrences of packages.qa.debian.org with tracker.debian.org. I also spotted a small problem in the way we handle autoremovals mails in tracker.debian.org, we often get them twice: I filed #871683 to get this fixed on release.debian.org. Bug reports. vmdebootstrap creates unbootable qemu image (#872999). bugs in udebs are not shown on view by source package (#872784). New upstream release of ethtool (#873692). Upstream bugreport on systemd: support a systemd.swap=no boot command-line option. I also shared some of my ideas/dreams in #859867 speaking of a helper tool to setup and maintain up-to-date build chroots and autopkgtest qemu images. More bug fixes and pull requests. I created a patch to fix a build failure of systemd when /tmp is an overlayfs (#854400, the pull request has been discarded). I fixed the RC bug #853570 on ncrack and forwarded my changes upstream (here and here). Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Russ Allbery: Review: Regeneration

Review: Regeneration, by Julie E. Czerneda
Series: Species Imperative #3
Publisher: DAW
Copyright: 2006
ISBN: 0-7564-0345-6
Format: Hardcover
Pages: 543
This is the third book of the Species Imperative trilogy, and this is the type of trilogy that's telling a single story in three books. You don't want to read this out of order, and I'll have to be cautious about aspects of the plot to not spoil the earlier books. Mac is still recovering from the effects of the first two books of the series, but she's primarily worried about a deeply injured friend. Worse, that friend is struggling to explain or process what's happened, and the gaps in her memory and her very ability to explain may point at frightening, lingering risks to humanity. As much as she wants to, Mac can't give her friend all of her focus, since she's also integral to the team trying to understand the broader implications of the events of Migration. Worse, some of the non-human species have their own contrary interpretations that, if acted on, Mac believes would be desperately risky for humanity and all the other species reachable through the transects. That set of competing priorities and motivations eventually sort themselves out into a tense and rewarding multi-species story, but they get off to an awkward start. The first 150 pages of Regeneration are long on worry, uncertainty, dread, and cryptic conversations, and short on enjoyable reading. Czerneda's recaps of the previous books are appreciated, but they weren't very smoothly integrated into the story. (I renew my occasional request for series authors to include a simple plot summary of the previous books as a prefix, without trying to weave it into the fiction.) I was looking forward to this book after the excellent previous volumes, but struggled to get into the story. That does change. It takes a bit too long, with a bit too much nameless dread, a bit too much of an irritating subplot between Fourteen and Oversight that I didn't think added anything to the book, and not enough of Mac barreling forward doing sensible things. But once Mac gets back into space, with a destination and a job and a collection of suspicious (or arrogant) humans and almost-incomprehensible aliens to juggle, Czerneda hits her stride. Czerneda doesn't entirely avoid Planet of the Hats problems with her aliens, but I think she does better than most of science fiction. Alien species in this series do tend to be a bit all of a type, and Mac does figure them out by drawing conclusions from biology, but those conclusions are unobvious and based on Mac's mix of biological and human social intuition. They refreshingly aren't as simple as biology completely shaping culture. (Czerneda's touch is more subtle than James White's Sector General, for example.) And Mac has a practical, determined, and selfless approach that's deeply likable and admirable. It's fun as a reader to watch her win people over by just being competent, thoughtful, observant, and unrelentingly ethical. But the best part of this book, by far, are the Sinzi. They first appeared in the second book, Migration, and seemed to follow the common SF trope of a wise elder alien race that can bring some order to the universe and that humanity can learn from. They, or more precisely the one Sinzi who appeared in Migration, was very good at that role. But Czerneda had something far more interesting planned, and in Regeneration they become truly alien in their own right, with their own nearly incomprehensible way of viewing the universe. There are so many ways that this twist can go wrong, and Czerneda avoids all of them. She doesn't undermine their gravitas, nor does she elevate them to the level of Arisians or other semi-angelic wise mentors of other series. Czerneda makes them different in profound ways that are both advantage and disadvantage, pulls that difference into the plot as a complicating element, and has Mac stumble yet again into a role that is accidentally far more influential than she intends. Mac is the perfect character to do that to: she has just the right mix of embarrassment, ethics, seat-of-the-pants blunt negotiation skills, and a strong moral compass. Given a lever and a place to stand, one can believe that Mac can move the world, and the Sinzi are an absolutely fascinating lever. There are also three separate, highly differentiated Sinzi in this story, with different goals, life experience, personalities, and levels of gravitas. Czerneda's aliens are good in general, but her focus is usually more on biology than individual differentiation. The Sinzi here combine the best of both types of character building. I think the ending of Regeneration didn't entirely work. After all the intense effort the characters put into understanding the complexity of the universe over the course of the series, the denouement has a mopping-up feel and a moral clarity that felt a bit too easy. But the climax has everything I was hoping for, there's a lot more of Mac being Mac, and I loved every moment of the Sinzi twist. Now I want a whole new series exploring the implications of the Sinzi's view of the universe on the whole history of galactic politics that sat underneath this story. But I'll settle for moments of revelation that sent shivers down my spine. This is a bit of an uneven book that falls short of its potential, but I'll remember it for a long time. Add it on to a deeply rewarding series, and I will recommend the whole package unreservedly. The Species Imperative is excellent science fiction that should be better-known than it is. I still think the romance subplot was unfortunate, and occasionally the aliens get too cartoony (Fourteen, in particular, goes a bit too far in that direction), but Czerneda never lingers too long on those elements. And the whole work is some of the best writing about working scientific research and small-group politics that I've read. Highly recommended, but read the whole series in order. Rating: 9 out of 10

Dirk Eddelbuettel: RcppAnnoy 0.0.9

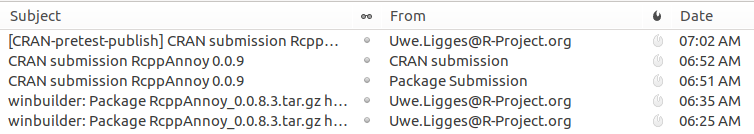
An new version 0.0.9 of RcppAnnoy, our Rcpp-based R integration of the nifty Annoy library by Erik, is now on CRAN. Annoy is a small and lightweight C++ template header library for very fast approximate nearest neighbours. This release corrects an issue for Windows users discovered by GitHub user 'khoran' who later also suggested the fix of binary mode. It upgrades to Annoy release 1.9.1 and brings its new Manhattan distance to RcppAnnoy. A number of unit tests were added as well, and we updated some packaging internals such as symbol registration. And I presume I had a good streak emailing with Uwe's robots as the package made it onto CRAN rather smoothly within ten minutes of submission:
RcppAnnou to CRAN
Changes in this version are summarized here:

Changes in version 0.0.9 (2017-08-31)
  • Synchronized with Annoy upstream version 1.9.1
  • Minor updates in calls and tests as required by annoy 1.9.1
  • New Manhattan distance modules along with unit test code
  • Additional unit tests from upstream test code carried over
  • Binary mode is used for save (as suggested by @khoran in #21)
  • A new file init.c was added with calls to R_registerRoutines() and R_useDynamicSymbols()
  • Symbol registration is enabled in useDynLib

Courtesy of CRANberries, there is also a diffstat report for this release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.