Search Results: "cts"

19 November 2024

Melissa Wen: Display/KMS Meeting at XDC 2024: Detailed Report

XDC 2024 in Montreal was another fantastic gathering for the Linux Graphics community. It was again a great time to immerse in the world of graphics development, engage in stimulating conversations, and learn from inspiring developers. Many Igalia colleagues and I participated in the conference again, delivering multiple talks about our work on the Linux Graphics stack and also organizing the Display/KMS meeting. This blog post is a detailed report on the Display/KMS meeting held during this XDC edition. Short on Time?
  1. Catch the lightning talk summarizing the meeting here (you can even speed up 2x):
  1. For a quick written summary, scroll down to the TL;DR section.

TL;DR This meeting took 3 hours and tackled a variety of topics related to DRM/KMS (Linux/DRM Kernel Modesetting):
  • Sharing Drivers Between V4L2 and KMS: Brainstorming solutions for using a single driver for devices used in both camera capture and display pipelines.
  • Real-Time Scheduling: Addressing issues with non-blocking page flips encountering sigkills under real-time scheduling.
  • HDR/Color Management: Agreement on merging the current proposal, with NVIDIA implementing its special cases on VKMS and adding missing parts on top of Harry Wentland s (AMD) changes.
  • Display Mux: Collaborative design discussions focusing on compositor control and cross-sync considerations.
  • Better Commit Failure Feedback: Exploring ways to equip compositors with more detailed information for failure analysis.

Bringing together Linux display developers in the XDC 2024 While I didn t present a talk this year, I co-organized a Display/KMS meeting (with Rodrigo Siqueira of AMD) to build upon the momentum from the 2024 Linux Display Next hackfest. The meeting was attended by around 30 people in person and 4 remote participants. Speakers: Melissa Wen (Igalia) and Rodrigo Siqueira (AMD) Link: https://indico.freedesktop.org/event/6/contributions/383/ Topics: Similar to the hackfest, the meeting agenda was built over the first two days of the conference and mixed talks follow-up with new ideas and ongoing community efforts. The final agenda covered five topics in the scheduled order:
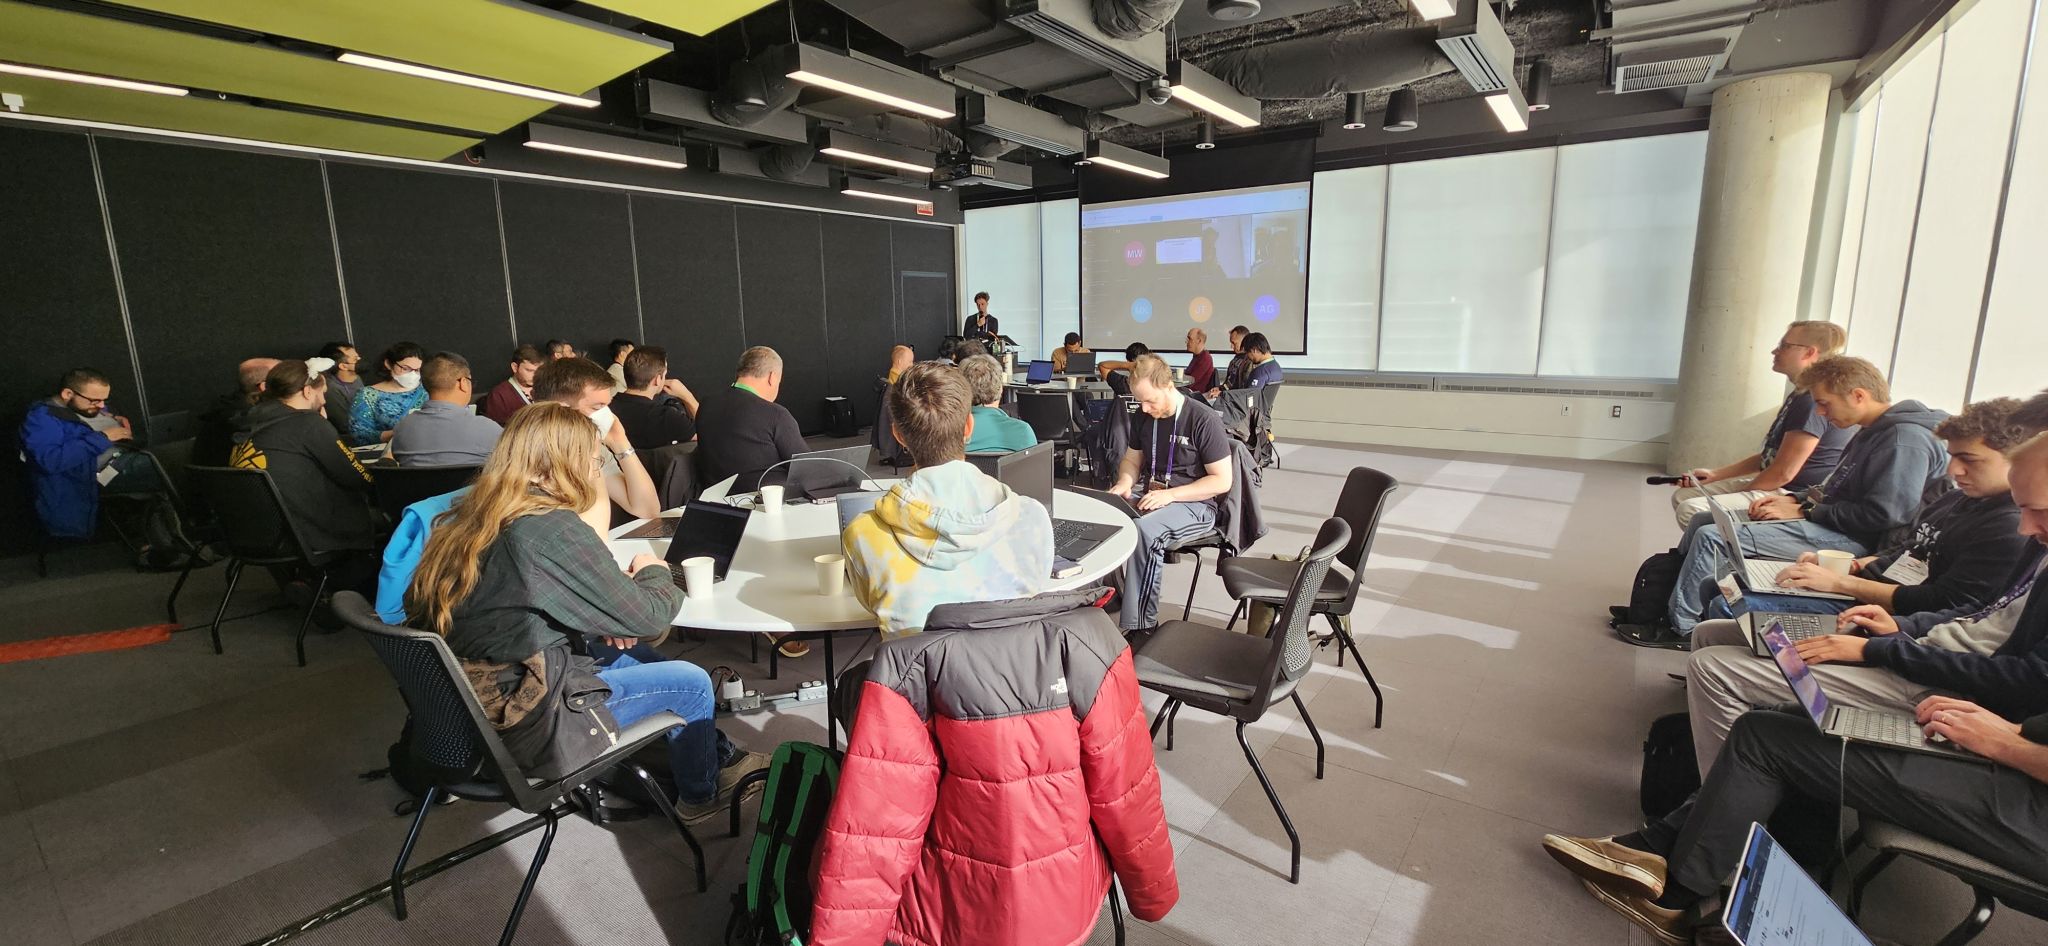
  1. How to share drivers between V4L2 and DRM for bridge-like components (new topic);
  2. Real-time Scheduling (problems encountered after the Display Next hackfest);
  3. HDR/Color Management (ofc);
  4. Display Mux (from Display hackfest and XDC 2024 talk, bringing AMD and NVIDIA together);
  5. (Better) Commit Failure Feedback (continuing the last minute topic of the Display Next hackfest).

Unpacking the Topics Similar to the hackfest, the meeting agenda evolved over the conference. During the 3 hours of meeting, I coordinated the room and discussion rounds, and Rodrigo Siqueira took notes and also contacted key developers to provide a detailed report of the many topics discussed. From his notes, let s dive into the key discussions!
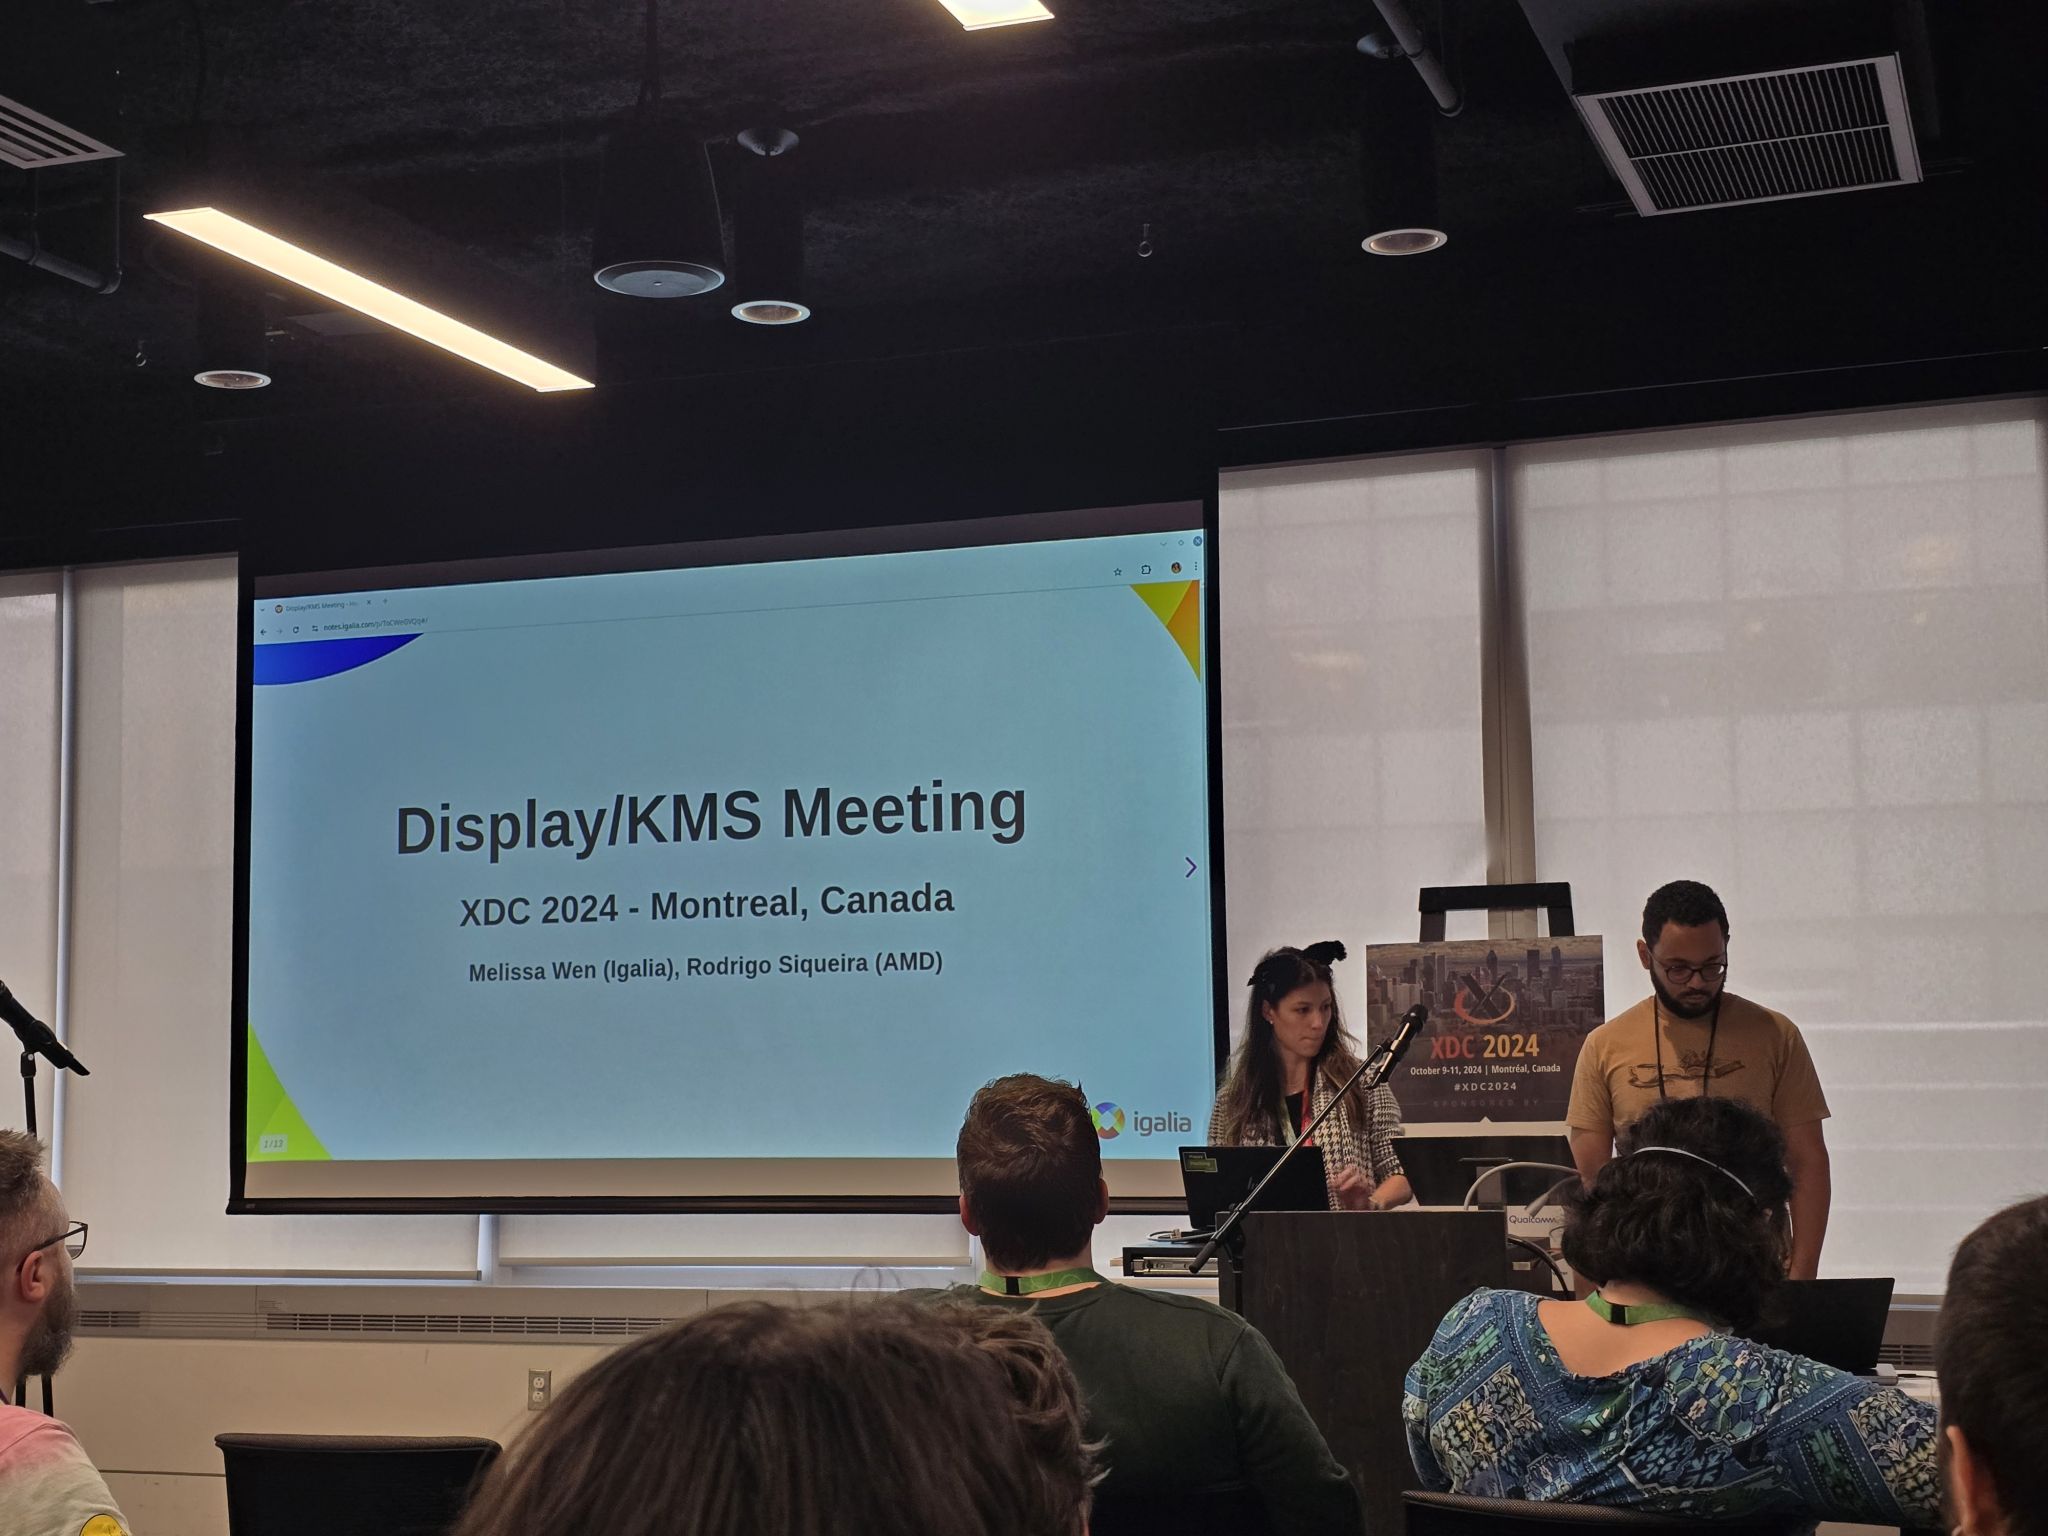
How to share drivers between V4L2 and KMS for bridge-like components. Led by Laurent Pinchart, we delved into the challenge of creating a unified driver for hardware devices (like scalers) that are used in both camera capture pipelines and display pipelines.
  • Problem Statement: How can we design a single kernel driver to handle devices that serve dual purposes in both V4L2 and DRM subsystems?
  • Potential Solutions:
    1. Multiple Compatible Strings: We could assign different compatible strings to the device tree node based on its usage in either the camera or display pipeline. However, this approach might raise concerns from device tree maintainers as it could be seen as a layer violation.
    2. Separate Abstractions: A single driver could expose the device to both DRM and V4L2 through separate abstractions: drm-bridge for DRM and V4L2 subdev for video. While simple, this approach requires maintaining two different abstractions for the same underlying device.
    3. Unified Kernel Abstraction: We could create a new, unified kernel abstraction that combines the best aspects of drm-bridge and V4L2 subdev. This approach offers a more elegant solution but requires significant design effort and potential migration challenges for existing hardware.

Real-Time Scheduling Challenges We have discussed real-time scheduling during this year Linux Display Next hackfest and, during the XDC 2024, Jonas Adahl brought up issues uncovered while progressing on this front.
  • Context: Non-blocking page-flips can, on rare occasions, take a long time and, for that reason, get a sigkill if the thread doing the atomic commit is a real-time schedule.
  • Action items:
    • Explore alternative backtraces during the busy wait (e.g., ftrace).
    • Investigate the maximum thread time in busy wait to reproduce issues faced by compositors. Tools like RTKit (mutter) can be used for better control (Michel D nzer can help with this setup).

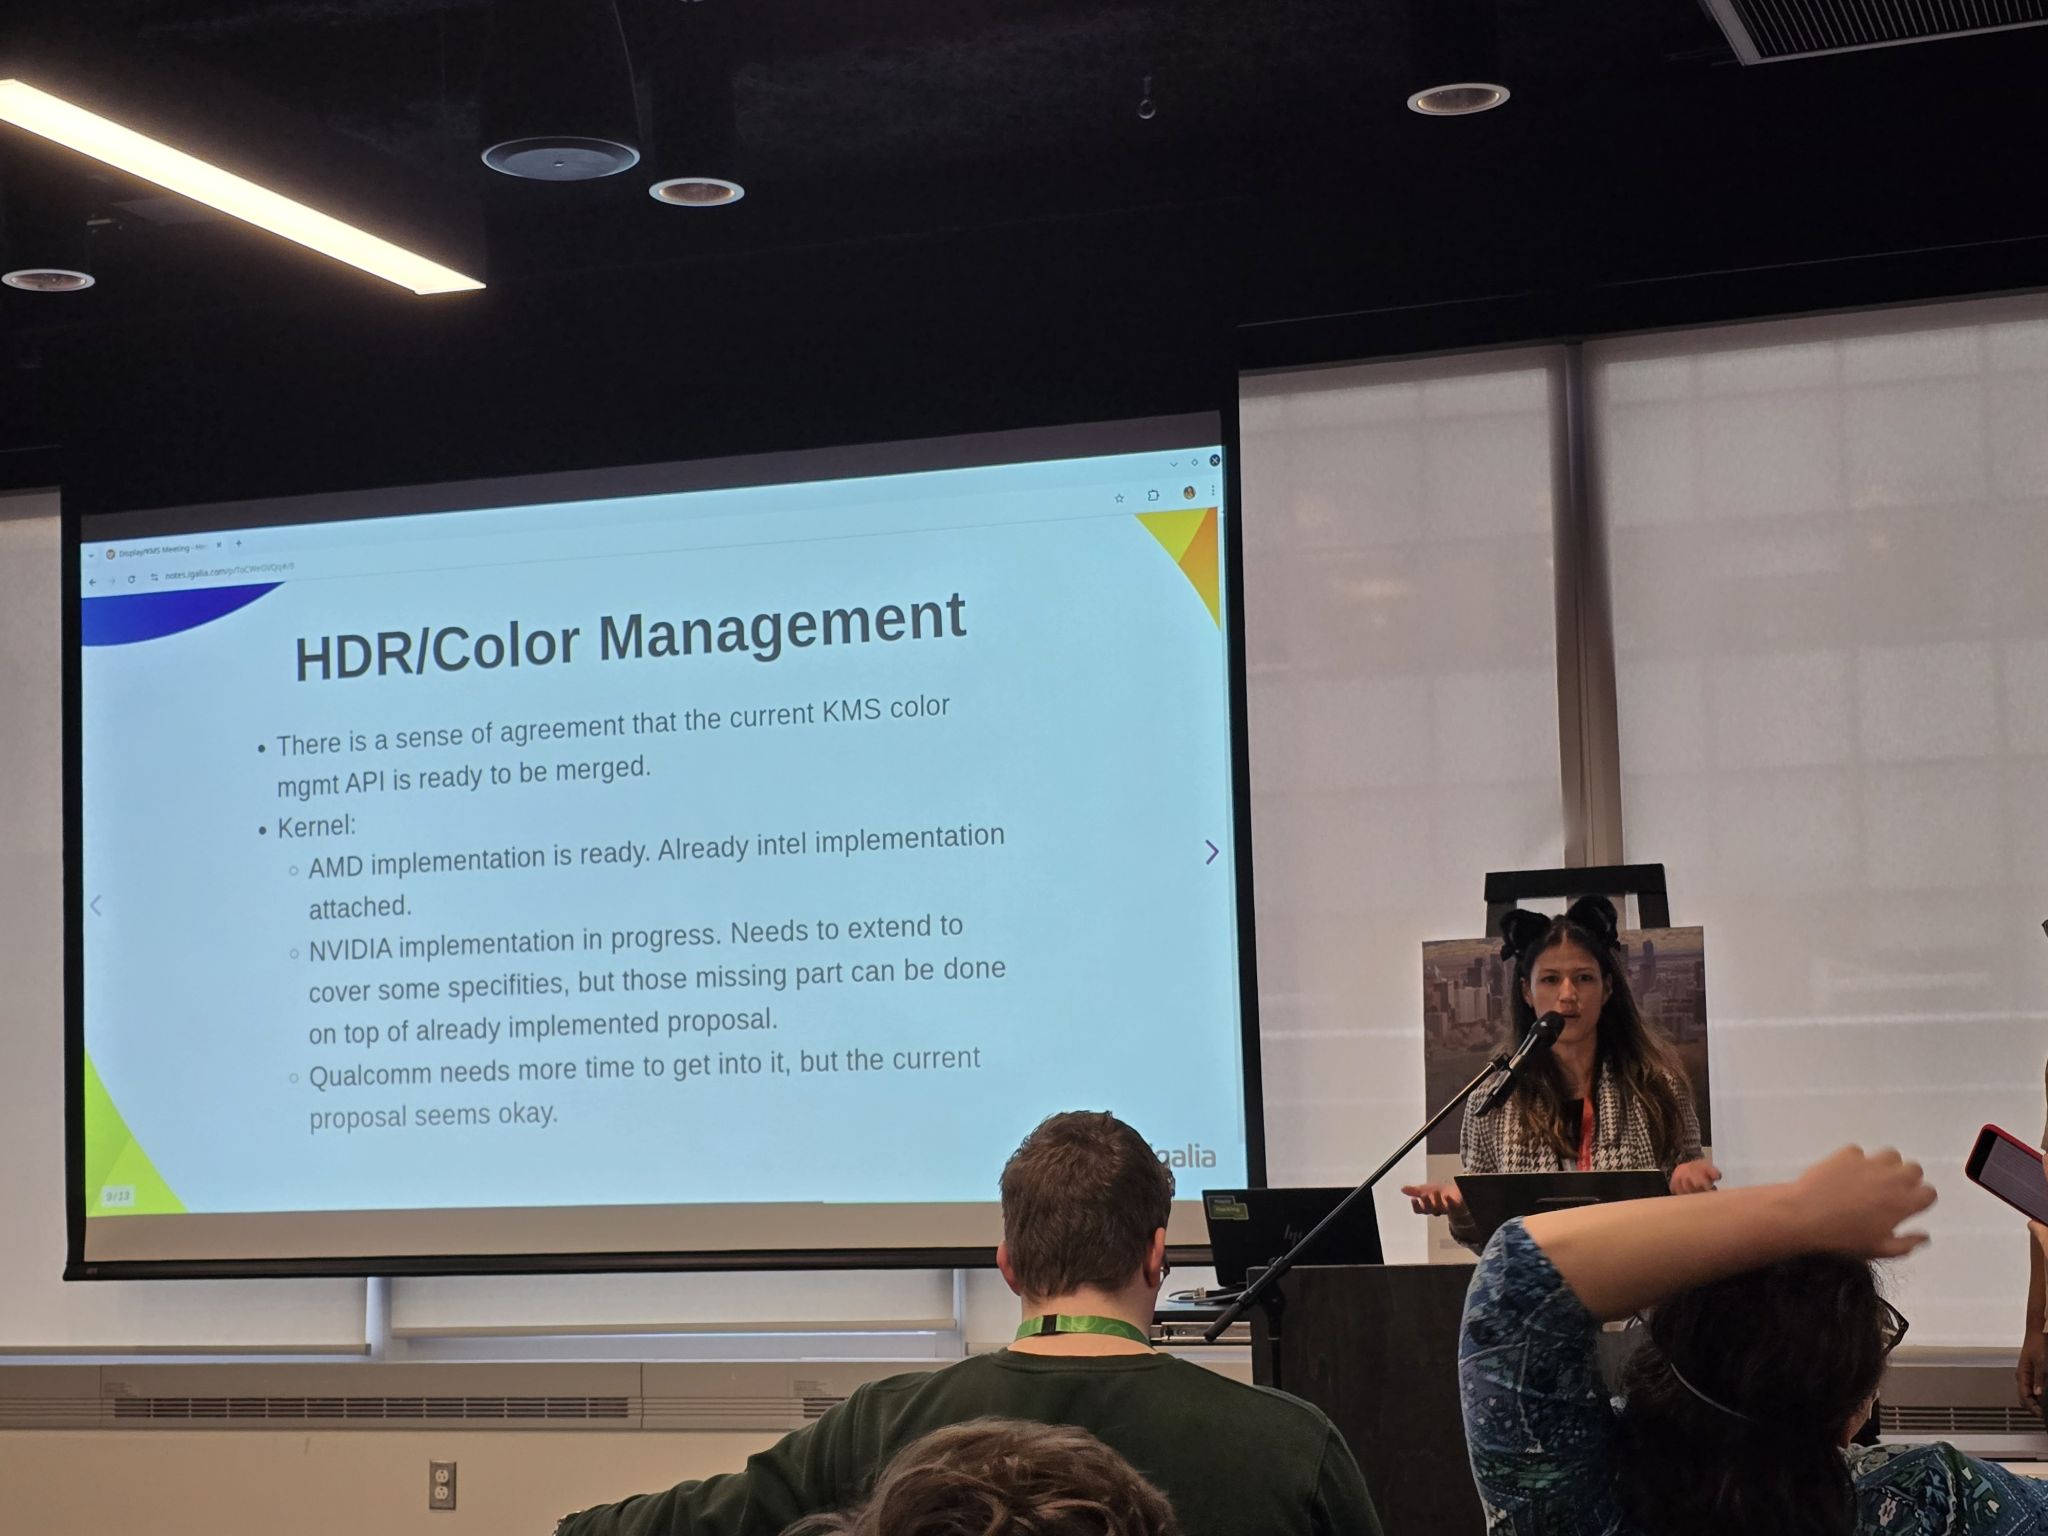
HDR/Color Management This is a well-known topic with ongoing effort on all layers of the Linux Display stack and has been discussed online and in-person in conferences and meetings over the last years. Here s a breakdown of the key points raised at this meeting:
  • Talk: Color operations for Linux color pipeline on AMD devices: In the previous day, Alex Hung (AMD) presented the implementation of this API on AMD display driver.
  • NVIDIA Integration: While they agree with the overall proposal, NVIDIA needs to add some missing parts. Importantly, they will implement these on top of Harry Wentland s (AMD) proposal. Their specific requirements will be implemented on VKMS (Virtual Kernel Mode Setting driver) for further discussion. This VKMS implementation can benefit compositor developers by providing insights into NVIDIA s specific needs.
  • Other vendors: There is a version of the KMS API applied on Intel color pipeline. Apart from that, other vendors appear to be comfortable with the current proposal but lacks the bandwidth to implement it right now.
  • Upstream Patches: The relevant upstream patches were can be found here. [As humorously notes, this series is eagerly awaiting your Acked-by (approval)]
  • Compositor Side: The compositor developers have also made significant progress.
    • KDE has already implemented and validated the API through an experimental implementation in Kwin.
    • Gamescope currently uses a driver-specific implementation but has a draft that utilizes the generic version. However, some work is still required to fully transition away from the driver-specific approach. AP: work on porting gamescope to KMS generic API
    • Weston has also begun exploring implementation, and we might see something from them by the end of the year.
  • Kernel and Testing: The kernel API proposal is well-refined and meets the DRM subsystem requirements. Thanks to Harry Wentland effort, we already have the API attached to two hardware vendors and IGT tests, and, thanks to Xaver Hugl, a compositor implementation in place.
Finally, there was a strong sense of agreement that the current proposal for HDR/Color Management is ready to be merged. In simpler terms, everything seems to be working well on the technical side - all signs point to merging and shipping the DRM/KMS plane color management API!
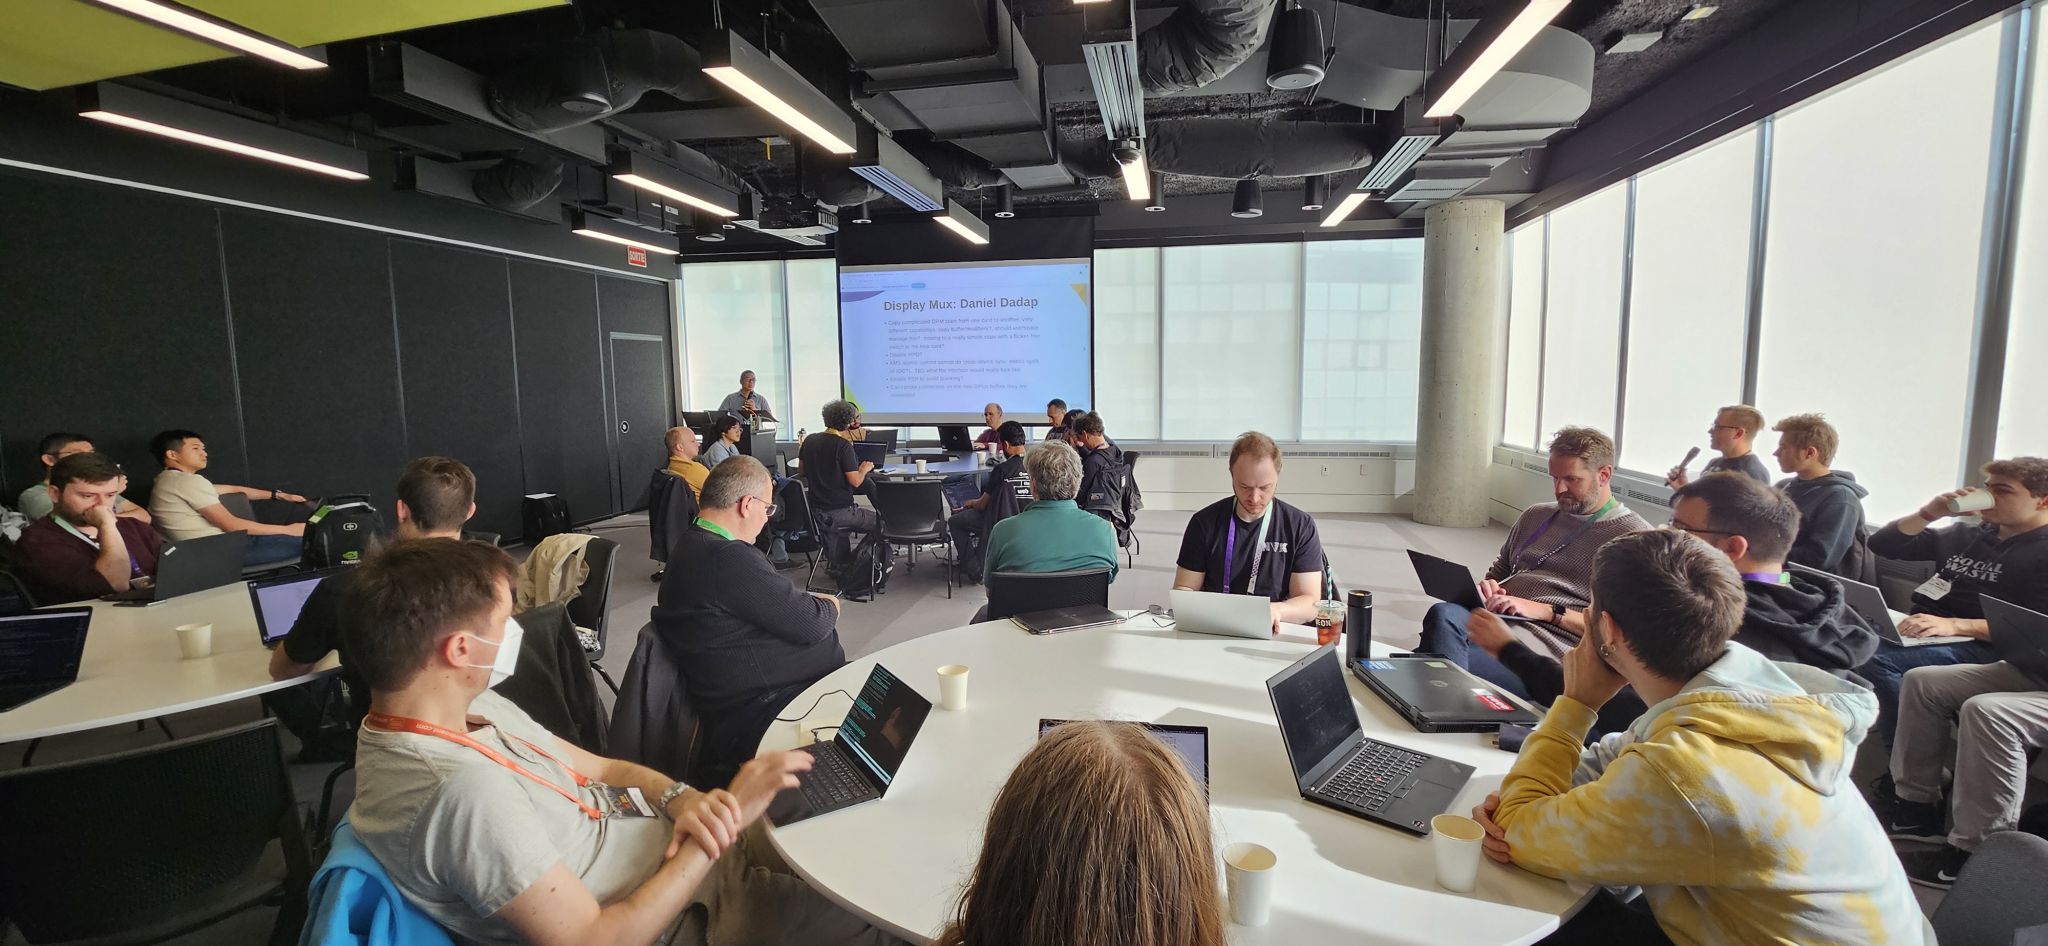
Display Mux During the meeting, Daniel Dadap led a brainstorming session on the design of the display mux switching sequence, in which the compositor would arm the switch via sysfs, then send a modeset to the outgoing driver, followed by a modeset to the incoming driver.
  • Context:
  • Key Considerations:
    • HPD Handling: There was a general consensus that disabling HPD can be part of the sequence for internal panels and we don t need to focus on it here.
    • Cross-Sync: Ensuring synchronization between the compositor and the drivers is crucial. The compositor should act as the drm-master to coordinate the entire sequence, but how can this be ensured?
    • Future-Proofing: The design should not assume the presence of a mux. In future scenarios, direct sharing over DP might be possible.
  • Action points:
    • Sharing DP AUX: Explore the idea of sharing DP AUX and its implications.
    • Backlight: The backlight definition represents a problem in the mux switch context, so we should explore some of the current specs available for that.
Towards Better Commit Failure Feedback In the last part of the meeting, Xaver Hugl asked for better commit failure feedback.
  • Problem description: Compositors currently face challenges in collecting detailed information from the kernel about commit failures. This lack of granular data hinders their ability to understand and address the root causes of these failures.
To address this issue, we discussed several potential improvements:
  • Direct Kernel Log Access: One idea is to directly load relevant kernel logs into the compositor. This would provide more detailed information about the failure and potentially aid in debugging.
  • Finer-Grained Failure Reporting: We also explored the possibility of separating atomic failures into more specific categories. Not all failures are critical, and understanding the nature of the failure can help compositors take appropriate action.
  • Enhanced Logging: Currently, the dmesg log doesn t provide enough information for user-space validation. Raising the log level to capture more detailed information during failures could be a viable solution.
By implementing these improvements, we aim to equip compositors with the necessary tools to better understand and resolve commit failures, leading to a more robust and stable display system.

A Big Thank You! Huge thanks to Rodrigo Siqueira for these detailed meeting notes. Also, Laurent Pinchart, Jonas Adahl, Daniel Dadap, Xaver Hugl, and Harry Wentland for bringing up interesting topics and leading discussions. Finally, thanks to all the participants who enriched the discussions with their experience, ideas, and inputs, especially Alex Goins, Antonino Maniscalco, Austin Shafer, Daniel Stone, Demi Obenour, Jessica Zhang, Joan Torres, Leo Li, Liviu Dudau, Mario Limonciello, Michel D nzer, Rob Clark, Simon Ser and Teddy Li. This collaborative effort will undoubtedly contribute to the continued development of the Linux display stack. Stay tuned for future updates!

18 November 2024

Dirk Eddelbuettel: RcppArmadillo 14.2.0-1 on CRAN: New Upstream Minor

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1191 other packages on CRAN, downloaded 37.2 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 603 times according to Google Scholar. Conrad released a minor version 14.2.0 a few days ago after we spent about two weeks with several runs of reverse-dependency checks covering corner cases. After a short delay at CRAN due to a false positive on a test, a package failing tests we also failed under the previous version, and some concern over new deprecation warnings _whem using the headers directly as _e.g. mlpack R package does we are now on CRAN. I noticed a missing feature under large 64bit word (for large floating-point matrices) and added an exporter for icube going to double to support the 64-bit integer range (as we already did, of course, for vectors and matrices). Changes since the last CRAN release are summarised below.

Changes in RcppArmadillo version 14.2.0-1 (2024-11-16)
  • Upgraded to Armadillo release 14.2.0 (Smooth Caffeine)
    • Faster handling of symmetric matrices by inv() and rcond()
    • Faster handling of hermitian matrices by inv(), rcond(), cond(), pinv(), rank()
    • Added solve_opts::force_sym option to solve() to force the use of the symmetric solver
    • More efficient handling of compound expressions by solve()
  • Added exporter specialisation for icube for the ARMA_64BIT_WORD case

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

14 November 2024

Reproducible Builds: Reproducible Builds mourns the passing of Lunar

The Reproducible Builds community sadly announces it has lost its founding member. J r my Bobbio aka Lunar passed away on Friday November 8th in palliative care in Rennes, France. Lunar was instrumental in starting the Reproducible Builds project in 2013 as a loose initiative within the Debian project. Many of our earliest status reports were written by him and many of our key tools in use today are based on his design. Lunar was a resolute opponent of surveillance and censorship, and he possessed an unwavering energy that fueled his work on Reproducible Builds and Tor. Without Lunar s far-sightedness, drive and commitment to enabling teams around him, Reproducible Builds and free software security would not be in the position it is in today. His contributions will not be forgotten, and his high standards and drive will continue to serve as an inspiration to us as well as for the other high-impact projects he was involved in. Lunar s creativity, insight and kindness were often noted. He will be greatly missed.

Other tributes:

12 November 2024

Paul Tagliamonte: Complex for Whom?

In basically every engineering organization I ve ever regarded as particularly high functioning, I ve sat through one specific recurring conversation which is not a conversation about complexity . Things are good or bad because they are or aren t complex, architectures needs to be redone because it s too complex some refactor of whatever it is won t work because it s too complex. You may have even been a part of some of these conversations or even been the one advocating for simple light-weight solutions. I ve done it. Many times. Rarely, if ever, do we talk about complexity within its rightful context complexity for whom. Is a solution complex because it s complex for the end user? Is it complex if it s complex for an API consumer? Is it complex if it s complex for the person maintaining the API service? Is it complex if it s complex for someone outside the team maintaining it to understand? Complexity within a problem domain I ve come to believe, is fairly zero-sum there s a fixed amount of complexity in the problem to be solved, and you can choose to either solve it, or leave it for those downstream of you to solve that problem on their own. That being said, while I believe there is a lower bound in complexity to contend with for a problem, I do not believe there is an upper bound to the complexity of solutions possible. It is always possible, and in fact, very likely that teams create problems for themselves while trying to solve a problem. The rest of this post is talking to the lower bound. When getting feedback on an early draft of this blog post, I ve been informed that Fred Brooks coined a term for what I call lower bound complexity Essential Complexity , in the paper No Silver Bullet Essence and Accident in Software Engineering , which is a better term and can be used interchangeably.

Complexity Culture In a large enough organization, where the team is high functioning enough to have and maintain trust amongst peers, members of the team will specialize. People will begin to engage with subsets of the work to be done, and begin to have their efficacy measured against that part of the organization s problems. Incentives shift, and over time it becomes increasingly likely that two engineers may have two very different priorities when working on the same system together. Someone accountable for uptime and tasked with responding to outages will begin to resist changes. Someone accountable for rapidly delivering features will resist gates between them and their users. Companies (either wittingly or unwittingly) will deal with this by tasking engineers with both production (feature development) and operational tasks (maintenance), so the difference in incentives isn t usually as bad as it could be. When we get a bunch of folks from far-flung corners of an organization in a room, fire up a slide deck and throw up some aspirational to-be architecture diagram in order to get a sign-off to solve some problem (be it someone needs a credible promotion packet, new feature needs to get delivered, or the system has begun to fail and needs fixing), the initial reaction will, more often than I d like, start to devolve into a discussion of how this is going to introduce a bunch of complexity, going to be hard to maintain, why can t you make it less complex? Right around here is when I start to try and contextualize the conversation happening around me understand what complexity is that being discussed, and understand who is taking on that burden. Think about who should be owning that problem, and work through the tradeoffs involved. Is it best solved here, or left to consumers (be them other systems, developers, or users). Should something become an API call s optional param, taking on all the edge-cases and on, or should users have to implement the logic using the data you return (leaving everyone else to take on all the edge-cases and maintenance)? Should you process the data, or require the user to preprocess it for you? Frequently it s right to make an active and explicit decision to simplify and leave problems to be solved downstream, since they may not actually need to be solved or perhaps you expect consumers will want to own the specifics of how the problem is solved, in which case you leave lots of documentation and examples. Many other times, especially when it s something downstream consumers are likely to hit, it s best solved internal to the system, since the only thing that can come of leaving it unsolved are bugs, frustration and half-correct solutions. This is a grey-space of tradeoffs, not a clear decision tree. No one wants the software manifestation of a katamari ball or a junk drawer, nor does anyone want a half-baked service unable to handle the simplest use-case.

Head-in-sand as a Service Popoffs about how complex something is, are, to a first approximation, best understood as meaning complicated for the person making comments . A lot of the #thoughtleadership believe that an AWS hosted EKS k8s cluster running images built by CI talking to an AWS hosted PostgreSQL RDS is not complex. They re right. Mostly right. This is less complex less complex for them. It s not, however, without complexity and its own tradeoffs it s just complexity that they do not have to deal with. Now they don t have to maintain machines that have pesky operating systems or hard drive failures. They don t have to deal with updating the version of k8s, nor ensuring the backups work. No one has to push some artifact to prod manually. Deployments happen unattended. You click a button and get a cluster. On the other hand, developers outside the ops function need to deal with troubleshooting CI, debugging access control rules encoded in turing complete YAML, permissions issues inside the cluster due to whatever the fuck a service mesh is, everyone needs to learn how to use some k8s tools they only actually use during a bad day, likely while doing some x.509 troubleshooting to connect to the cluster (an internal only endpoint; just port forward it) not to mention all sorts of rules to route packets to their project (a single repo s binary being run in 3 containers on a single vm host). Beyond that, there s the invisible complexity complexity on the interior of a service you depend on. I think about the dozens of teams maintaining the EKS service (which is either run on EC2 instances, or alternately, EC2 instances in a trench coat, moustache and even more shell scripts), the RDS service (also EC2 and shell scripts, but this time accounting for redundancy, backups, availability zones), scores of hypervisors pulled off the shelf (xen, kvm) smashed together with the ones built in-house (firecracker, nitro, etc) running on hardware that has to be refreshed and maintained continuously. Every request processed by network ACL rules, AWS IAM rules, security group rules, using IP space announced to the internet wired through IXPs directly into ISPs. I don t even want to begin to think about the complexity inherent in how those switches are designed. Shitloads of complexity to solve problems you may or may not have, or even know you had. What s more complex? An app running in an in-house 4u server racked in the office s telco closet in the back running off the office Verizon line, or an app running four hypervisors deep in an AWS datacenter? Which is more complex to you? What about to your organization? In total? Which is more prone to failure? Which is more secure? Is the complexity good or bad? What type of Complexity can you manage effectively? Which threaten the system? Which threaten your users?

COMPLEXIVIBES This extends beyond Engineering. Decisions regarding what tools are we able to use be them existing contracts with cloud providers, CIO mandated SaaS products, a list of the only permissible open source projects will incur costs in terms of expressed complexity . Pinning open source projects to a fixed set makes SBOM production less complex . Using only one SaaS provider s product suite (even if its terrible, because it has all the types of tools you need) makes accreditation less complex . If all you have is a contract with Pauly T s lowest price technically acceptable artisinal cloudary and haberdashery, the way you pay for your compute is less complex for the CIO shop, though you will find yourself building your own hosted database template, mechanism to spin up a k8s cluster, and all the operational and technical burden that comes with it. Or you won t and make it everyone else s problem in the organization. Nothing you can do will solve for the fact that you must now deal with this problem somewhere because it was less complicated for the business to put the workloads on the existing contract with a cut-rate vendor. Suddenly, the decision to reduce complexity because of an existing contract vehicle has resulted in a huge amount of technical risk and maintenance burden being onboarded. Complexity you would otherwise externalize has now been taken on internally. With a large enough organizations (specifically, in this case, i m talking about you, bureaucracies), this is largely ignored or accepted as normal since the personnel cost is understood to be free to everyone involved. Doing it this way is more expensive, more work, less reliable and less maintainable, and yet, somehow, is, in a lot of ways, less complex to the organization. It s particularly bad with bureaucracies, since screwing up a contract will get you into much more trouble than delivering a broken product, leaving basically no reason for anyone to care to fix this. I can t shake the feeling that for every story of technical mandates gone awry, somewhere just out of sight there s a decisionmaker optimizing for what they believe to be the least amount of complexity least hassle, fewest unique cases, most consistency as they can. They freely offload complexity from their accreditation and risk acceptance functions through mandates. They will never have to deal with it. That does not change the fact that someone does.

TC;DR (TOO COMPLEX; DIDN T REVIEW) We wish to rid ourselves of systemic Complexity after all, complexity is bad, simplicity is good. Removing upper-bound own-goal complexity ( accidental complexity in Brooks s terms) is important, but once you hit the lower bound complexity, the tradeoffs become zero-sum. Removing complexity from one part of the system means that somewhere else maybe outside your organization or in a non-engineering function must grow it back. Sometimes, the opposite is the case, such as when a previously manual business processes is automated. Maybe that s a good idea. Maybe it s not. All I know is that what doesn t help the situation is conflating complexity with everything we don t like legacy code, maintenance burden or toil, cost, delivery velocity.
  • Complexity is not the same as proclivity to failure. The most reliable systems I ve interacted with are unimaginably complex, with layers of internal protection to prevent complete failure. This has its own set of costs which other people have written about extensively.
  • Complexity is not cost. Sometimes the cost of taking all the complexity in-house is less, for whatever value of cost you choose to use.
  • Complexity is not absolute. Something simple from one perspective may be wildly complex from another. The impulse to burn down complex sections of code is helpful to have generally, but sometimes things are complicated for a reason, even if that reason exists outside your codebase or organization.
  • Complexity is not something you can remove without introducing complexity elsewhere. Just as not making a decision is a decision itself; choosing to require someone else to deal with a problem rather than dealing with it internally is a choice that needs to be considered in its full context.
Next time you re sitting through a discussion and someone starts to talk about all the complexity about to be introduced, I want to pop up in the back of your head, politely asking what does complex mean in this context? Is it lower bound complexity? Is this complexity desirable? Is what they re saying mean something along the lines of I don t understand the problems being solved, or does it mean something along the lines of this problem should be solved elsewhere? Do they believe this will result in more work for them in a way that you don t see? Should this not solved at all by changing the bounds of what we should accept or redefine the understood limits of this system? Is the perceived complexity a result of a decision elsewhere? Who s taking this complexity on, or more to the point, is failing to address complexity required by the problem leaving it to others? Does it impact others? How specifically? What are you not seeing? What can change? What should change?

Sven Hoexter: fluxcd: Validate flux-system Root Kustomization

Not entirely sure how people use fluxcd, but I guess most people have something like a flux-system flux kustomization as the root to add more flux kustomizations to their kubernetes cluster. Here all of that is living in a monorepo, and as we're all humans people figure out different ways to break it, which brings the reconciliation of the flux controllers down. Thus we set out to do some pre-flight validations. Note1: We do not use flux variable substitutions for those root kustomizations, so if you use those, you've to put additional work into the validation and pipe things through flux envsubst. First Iteration: Just Run kustomize Like Flux Would Do It With a folder structure where we've a cluster folder with subfolders per cluster, we just run a for loop over all of them:
for CLUSTER in $ CLUSTERS ; do
    pushd clusters/$ CLUSTER 
    # validate if we can create and build a flux-system like kustomization file
    kustomize create --autodetect --recursive
    if ! kustomize build . -o /dev/null 2> error.log; then
        echo "Error building flux-system kustomization for cluster $ CLUSTER "
        cat error.log
    fi
    popd
done
Second Iteration: Make Sure Our Workload Subfolder Have a kustomization.yaml Next someone figured out that you can delete some yaml files from a workload subfolder, including the kustomization.yaml, but not all of them. That left around a resource definition which lacks some other referenced objects, but is still happily included into the root kustomization by kustomize create and flux, which of course did not work. Thus we started to catch that as well in our growing for loop:
for CLUSTER in $ CLUSTERS ; do
    pushd clusters/$ CLUSTER 
    # validate if we can create and build a flux-system like kustomization file
    kustomize create --autodetect --recursive
    if ! kustomize build . -o /dev/null 2> error.log; then
        echo "Error building flux-system kustomization for cluster $ CLUSTER "
        cat error.log
    fi
    # validate if we always have a kustomization file in folders with yaml files
    for CLFOLDER in $(find . -type d); do
        test -f $ CLFOLDER /kustomization.yaml && continue
        test -f $ CLFOLDER /kustomization.yml && continue
        if [[ $(find $ CLFOLDER  -maxdepth 1 \( -name '*.yaml' -o -name '*.yml' \) -type f wc -l) != 0 ]]; then
            echo "Error Cluster $ CLUSTER  folder $ CLFOLDER  lacks a kustomization.yaml"
        fi
    done
    popd
done
Note2: I shortened those snippets to the core parts. In our case some things are a bit specific to how we implemented the execution of those checks in GitHub action workflows. Hope that's enough to transport the idea of what to check for.

11 November 2024

Gunnar Wolf: Why academics under-share research data - A social relational theory

This post is a review for Computing Reviews for Why academics under-share research data - A social relational theory , a article published in Journal of the Association for Information Science and Technology
As an academic, I have cheered for and welcomed the open access (OA) mandates that, slowly but steadily, have been accepted in one way or another throughout academia. It is now often accepted that public funds means public research. Many of our universities or funding bodies will demand that, with varying intensities sometimes they demand research to be published in an OA venue, sometimes a mandate will only prefer it. Lately, some journals and funder bodies have expanded this mandate toward open science, requiring not only research outputs (that is, articles and books) to be published openly but for the data backing the results to be made public as well. As a person who has been involved with free software promotion since the mid 1990s, it was natural for me to join the OA movement and to celebrate when various universities adopt such mandates. Now, what happens after a university or funder body adopts such a mandate? Many individual academics cheer, as it is the right thing to do. However, the authors observe that this is not really followed thoroughly by academics. What can be observed, rather, is the slow pace or feet dragging of academics when they are compelled to comply with OA mandates, or even an outright refusal to do so. If OA and open science are close to the ethos of academia, why aren t more academics enthusiastically sharing the data used for their research? This paper finds a subversive practice embodied in the refusal to comply with such mandates, and explores an hypothesis based on Karl Marx s productive worker theory and Pierre Bourdieu s ideas of symbolic capital. The paper explains that academics, as productive workers, become targets for exploitation: given that it s not only the academics sharing ethos, but private industry s push for data collection and industry-aligned research, they adapt to technological changes and jump through all kinds of hurdles to create more products, in a result that can be understood as a neoliberal productivity measurement strategy. Neoliberalism assumes that mechanisms that produce more profit for academic institutions will result in better research; it also leads to the disempowerment of academics as a class, although they are rewarded as individuals due to the specific value they produce. The authors continue by explaining how open science mandates seem to ignore the historical ways of collaboration in different scientific fields, and exploring different angles of how and why data can be seen as under-shared, failing to comply with different aspects of said mandates. This paper, built on the social sciences tradition, is clearly a controversial work that can spark interesting discussions. While it does not specifically touch on computing, it is relevant to Computing Reviews readers due to the relatively high percentage of academics among us.

10 November 2024

Dirk Eddelbuettel: inline 0.3.20: Mostly Maintenance

A new release of the inline package got to CRAN today marking the first release in three and half years. inline facilitates writing code in-line in simple string expressions or short files. The package was used quite extensively by Rcpp in the very early days before Rcpp Attributes arrived on the scene providing an even better alternative for its use cases. inline is still used by rstan and a number of other packages. This release was tickled by changing in r-devel just this week, and the corresponding please fix or else email I received this morning. R_NO_REMAP is now the default in r-devel, and while we had already converted most (old-style) calls into the API to using the now mandatory Rf_ prefix, the package contained few remaining cases in examples as well as one in code generation. The release also contains a helpful contributed PR making an error message a little clearer, plus several small and common maintenance changed around continuous integration, package layout and the repository. The NEWS extract follows and details the changes some more.

Changes in inline version 0.3.20 (2024-11-10)
  • Error message formatting is improved for compileCode (Alexis Derumigny in #25)
  • Switch to using Authors@R, other general packaging maintenance for continuous integration and repository
  • Use Rf_ in a handful of cases as R-devel now mandates it

Thanks to my CRANberries, you can also look at a diff to the previous release Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues). If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Reproducible Builds: Reproducible Builds in October 2024

Welcome to the October 2024 report from the Reproducible Builds project. Our reports attempt to outline what we ve been up to over the past month, highlighting news items from elsewhere in tech where they are related. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. Table of contents:
  1. Beyond bitwise equality for Reproducible Builds?
  2. Two Ways to Trustworthy at SeaGL 2024
  3. Number of cores affected Android compiler output
  4. On our mailing list
  5. diffoscope
  6. IzzyOnDroid passed 25% reproducible apps
  7. Distribution work
  8. Website updates
  9. Reproducibility testing framework
  10. Supply-chain security at Open Source Summit EU
  11. Upstream patches

Beyond bitwise equality for Reproducible Builds? Jens Dietrich, Tim White, of Victoria University of Wellington, New Zealand along with Behnaz Hassanshahi and Paddy Krishnan of Oracle Labs Australia published a paper entitled Levels of Binary Equivalence for the Comparison of Binaries from Alternative Builds :
The availability of multiple binaries built from the same sources creates new challenges and opportunities, and raises questions such as: Does build A confirm the integrity of build B? or Can build A reveal a compromised build B? . To answer such questions requires a notion of equivalence between binaries. We demonstrate that the obvious approach based on bitwise equality has significant shortcomings in practice, and that there is value in opting for alternative notions. We conceptualise this by introducing levels of equivalence, inspired by clone detection types.
A PDF of the paper is freely available.

Two Ways to Trustworthy at SeaGL 2024 On Friday 8th November, Vagrant Cascadian will present a talk entitled Two Ways to Trustworthy at SeaGL in Seattle, WA. Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture. Vagrant s talk:
[ ] delves into how two project[s] approaches fundamental security features through Reproducible Builds, Bootstrappable Builds, code auditability, etc. to improve trustworthiness, allowing independent verification; trustworthy projects require little to no trust. Exploring the challenges that each project faces due to very different technical architectures, but also contextually relevant social structure, adoption patterns, and organizational history should provide a good backdrop to understand how different approaches to security might evolve, with real-world merits and downsides.

Number of cores affected Android compiler output Fay Stegerman wrote that the cause of the Android toolchain bug from September s report that she reported to the Android issue tracker has been found and the bug has been fixed.
the D8 Java to DEX compiler (part of the Android toolchain) eliminated a redundant field load if running the class s static initialiser was known to be free of side effects, which ended up accidentally depending on the sharding of the input, which is dependent on the number of CPU cores used during the build.
To make it easier to understand the bug and the patch, Fay also made a small example to illustrate when and why the optimisation involved is valid.

On our mailing list On our mailing list this month:

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 279, 280, 281 and 282 to Debian:
  • Ignore errors when listing .ar archives (#1085257). [ ]
  • Don t try and test with systemd-ukify in the Debian stable distribution. [ ]
  • Drop Depends on the deprecated python3-pkg-resources (#1083362). [ ]
In addition, Jelle van der Waa added support for Unified Kernel Image (UKI) files. [ ][ ][ ] Furthermore, Vagrant Cascadian updated diffoscope in GNU Guix to version 282. [ ][ ]

IzzyOnDroid passed 25% reproducible apps The IzzyOnDroid project has reached a good milestone by reaching over 25% of the ~1,200 Android apps provided by their repository (of official APKs built by the original application developers) having been confirmed to be reproducible by a rebuilder.

Distribution work In Debian this month:
  • Holger Levsen uploaded devscripts version 2.24.2, including many changes to the debootsnap, debrebuild and reproducible-check scripts. This is the first time that debrebuild actually works (using sbuild s unshare backend). As part of this, Holger also fixed an issue in the reproducible-check script where a typo in the code led to incorrect results [ ]
  • Recently, a news entry was added to snapshot.debian.org s homepage, describing the recent changes that made the system stable again:
    The new server has no problems keeping up with importing the full archives on every update, as each run finishes comfortably in time before it s time to run again. [While] the new server is the one doing all the importing of updated archives, the HTTP interface is being served by both the new server and one of the VM s at LeaseWeb.
    The entry list a number of specific updates surrounding the API endpoints and rate limiting.
  • Lastly, 12 reviews of Debian packages were added, 3 were updated and 18 were removed this month adding to our knowledge about identified issues.
Elsewhere in distribution news, Zbigniew J drzejewski-Szmek performed another rebuild of Fedora 42 packages, with the headline result being that 91% of the packages are reproducible. Zbigniew also reported a reproducibility problem with QImage. Finally, in openSUSE, Bernhard M. Wiedemann published another report for that distribution.

Website updates There were an enormous number of improvements made to our website this month, including:
  • Alba Herrerias:
    • Improve consistency across distribution-specific guides. [ ]
    • Fix a number of links on the Contribute page. [ ]
  • Chris Lamb:
  • hulkoba
  • James Addison:
    • Huge and significant work on a (as-yet-merged) quickstart guide to be linked from the homepage [ ][ ][ ][ ][ ]
    • On the homepage, link directly to the Projects subpage. [ ]
    • Relocate dependency-drift notes to the Volatile inputs page. [ ]
  • Ninette Adhikari:
    • Add a brand new Success stories page that highlights the success stories of Reproducible Builds, showcasing real-world examples of projects shipping with verifiable, reproducible builds . [ ][ ][ ][ ][ ][ ]
  • Pol Dellaiera:
    • Update the website s README page for building the website under NixOS. [ ][ ][ ][ ][ ]
    • Add a new academic paper citation. [ ]
Lastly, Holger Levsen filed an extensive issue detailing a request to create an overview of recommendations and standards in relation to reproducible builds.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In October, a number of changes were made by Holger Levsen, including:
  • Add a basic index.html for rebuilderd. [ ]
  • Update the nginx.conf configuration file for rebuilderd. [ ]
  • Document how to use a rescue system for Infomaniak s OpenStack cloud. [ ]
  • Update usage info for two particular nodes. [ ]
  • Fix up a version skew check to fix the name of the riscv64 architecture. [ ]
  • Update the rebuilderd-related TODO. [ ]
In addition, Mattia Rizzolo added a new IP address for the inos5 node [ ] and Vagrant Cascadian brought 4 virt nodes back online [ ].

Supply-chain security at Open Source Summit EU The Open Source Summit EU took place recently, and covered plenty of topics related to supply-chain security, including:

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Finally, If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

8 November 2024

Thomas Lange: Using NIS (Network Information Service) in 2024

The topic of this posting already tells you that an old Unix guy tells stories about old techniques. I'm a happy NIS (formerly YP) user since 30+ years. I started using it with SunOS 4.0, later using it with Solaris and with Linux since 1999. In the past, a colleague wasn't happyly using NIS+ when he couldn't log in as root after a short time because of some well known bugs and wrong configs. NIS+ was also much slower than my NIS setup. I know organisations using NIS for more than 80.000 user accounts in 2024. I know the security implications of NIS but I can live with them, because I manage all computers in the network that have access to the NIS maps. And NIS on Linux offers to use shadow maps, which are only accessible to the root account. My users are forced to use very long passwords. Unfortunately NIS support for the PAM modules was removed in Debian in pam 1.4.0-13, which means Debian 12 (bookworm) is lacking NIS support in PAM, but otherwise it is still supported. This only affects changing the NIS password via passwd. You can still authenticate users and use other NIS maps. But yppasswd is deprecated and you should not use it! If you use yppasswd it may generate a new password hash by using the old DES crypt algorithm, which is very weak and only uses the first 8 chars in your password. Do not use yppasswd any more! yppasswd only detects DES, MD5, SHA256 and SHA512 hashes, but for me and some colleagues it only creates weak DES hashes after a password change. yescrypt hashes which are the default in Debian 12 are not supported at all. The solution is to use the plain passwd program. On the NIS master, you should setup your NIS configuration to use /etc/shadow and /etc/passwd even if your other NIS maps are in /var/yp/src or similar. Make sure to have these lines in your /var/yp/Makefile:

PASSWD      = /etc/passwd
SHADOW      = /etc/shadow
Call make once, and it will generate the shadow and passwd map. You may want to set the variable MINUID which defines which entries are not put into the NIS maps. On all NIS clients you still need the entries (for passwd, shadow, group,...) that point to the nis service. E.g.:
passwd:         files nis systemd
group:          files nis systemd
shadow:         files nis
You can remove all occurences of "nis" in your /etc/pam.d/common-password file. Then you can use the plain passwd program to change your password on the NIS master. But this does not call make in /var/yp for updating the NIS shadow map. Let's use inotify(7) for that. First, create a small shell script /usr/local/sbin/shadow-change:
#! /bin/sh
PATH=/usr/sbin:/usr/bin
# only watch the /etc/shadow file
if [ "$2" != "shadow" ]; then
  exit 0
fi
cd /var/yp   exit 3
sleep 2
make
Then install the package incron.
# apt install incron
# echo root >> /etc/incron.allow
# incrontab -e
Add this line:
/etc    IN_MOVED_TO     /usr/local/sbin/shadow-change $@ $# $%
It's not possible to use IN_MODIFY or watch other events on /etc/shadow directly, because the passwd command creates a /etc/nshadow file, deletes /etc/shadow and then moves nshadow to shadow. inotify on a file does not work after the file was removed. You can see the logs from incrond by using:
# journalctl _COMM=incrond
e.g.
Oct 01 12:21:56 kueppers incrond[6588]: starting service (version 0.5.12, built on Jan 27 2023 23:08:49)
Oct 01 13:43:55 kueppers incrond[6589]: table for user root created, loading
Oct 01 13:45:42 kueppers incrond[6589]: PATH (/etc) FILE (shadow) EVENT (IN_MOVED_TO)
Oct 01 13:45:42 kueppers incrond[6589]: (root) CMD ( /usr/local/sbin/shadow-change /etc shadow IN_MOVED_TO)
I've disabled the execution of yppasswd using dpkg-divert
# dpkg-divert --local --rename --divert /usr/bin/yppasswd-disable /usr/bin/yppasswd
chmod a-rwx /usr/bin/yppasswd-disable
Do not forget to limit the access to the shadow.byname map in ypserv.conf and general access to NIS in ypserv.securenets. I've also discovered the package pamtester, which is a nice package for testing your pam configs.

Freexian Collaborators: Debian Contributions: October s report (by Anupa Ann Joseph)

Debian Contributions: 2024-10 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

rebootstrap, by Helmut Grohne After significant changes earlier this year, the state of architecture cross bootstrap is normalizing again. More and more architectures manage to complete rebootstrap testing successfully again. Here are two examples of what kind of issues the bootstrap testing identifies. At some point, libpng1.6 would fail to cross build on musl architectures whereas it would succeed on other ones failing to locate zlib. Adding --debug-find to the cmake invocation eventually revealed that it would fail to search in /usr/lib/<triplet>, which is the default library path. This turned out to be a bug in cmake assuming that all linux systems use glibc. libpng1.6 also gained a baseline violation for powerpc and ppc64 by enabling the use of AltiVec there. The newt package would fail to cross build for many 32-bit architectures whereas it would succeed for armel and armhf due to -Wincompatible-pointer-types. It turns out that this flag was turned into -Werror and it was compiling with a warning earlier. The actual problem is a difference in signedness between wchar_t and FriBidChar (aka uint32_t) and actually affects native building on i386.

Miscellaneous contributions
  • Helmut sent 35 patches for cross build failures.
  • Stefano Rivera uploaded the Python 3.13.0 final release.
  • Stefano continued to rebuild Python packages with C extensions using Python 3.13, to catch compatibility issues before the 3.13-add transition starts.
  • Stefano uploaded new versions of a handful of Python packages, including: dh-python, objgraph, python-mitogen, python-truststore, and python-virtualenv.
  • Stefano packaged a new release of mkdocs-macros-plugin, which required packaging a new Python package for Debian, python-super-collections (now in NEW review).
  • Stefano helped the mini-DebConf Online Brazil get video infrastructure up and running for the event. Unfortunately, Debian s online-DebConf setup has bitrotted over the last couple of years, and it eventually required new temporary Jitsi and Jibri instances.
  • Colin Watson fixed a number of autopkgtest failures to get ansible back into testing.
  • Colin fixed an ssh client failure in certain cases when using GSS-API key exchange, and added an integration test to ensure this doesn t regress in future.
  • Colin worked on the Python 3.13 transition, fixing problems related to it in 15 packages. This included upstream work in a number of packages (postgresfixture, python-asyncssh, python-wadllib).
  • Colin upgraded 41 Python packages to new upstream versions.
  • Carles improved po-debconf-manager: now it can create merge requests to Salsa automatically (created 17, new batch coming this month), imported almost all the packages with debconf translation templates whose VCS is Salsa (currently 449 imported), added statistics per package and language, improved command line interface options. Performed user support fixing different issues. Also prepared an abstract for the talk at MiniDebConf Toulouse.
  • Santiago Ruano Rinc n continued the organization work for the DebConf 25 conference, to be held in Brest, France. Part of the work relates to the initial edits of the sponsoring brochure. Thanks to Benjamin Somers who finalized the French and English versions.
  • Rapha l forwarded a couple of zim and hamster bugs to the upstream developers, and tried to diagnose a delayed startup of gdm on his laptop (cf #1085633).
  • On behalf of the Debian Publicity Team, Anupa interviewed 7 women from the Debian community, old and new contributors. The interview was published in Bits from Debian.

6 November 2024

Bits from Debian: Bits from the DPL

Dear Debian community, this is Bits from DPL for October. In addition to a summary of my recent activities, I aim to include newsworthy developments within Debian that might be of interest to the broader community. I believe this provides valuable insights and foster a sense of connection across our diverse projects. Also, I welcome your feedback on the format and focus of these Bits, as community input helps shape their value. Ada Lovelace Day 2024 As outlined in my platform, I'm committed to increasing the diversity of Debian developers. I hope the recent article celebrating Ada Lovelace Day 2024 featuring interviews with women in Debian will serve as an inspiring motivation for more women to join our community. MiniDebConf Cambridge This was my first time attending the MiniDebConf in Cambridge, hosted at the ARM building. I thoroughly enjoyed the welcoming atmosphere of both MiniDebCamp and MiniDebConf. It was wonderful to reconnect with people who hadn't made it to the last two DebConfs, and, as always, there was plenty of hacking, insightful discussions, and valuable learning. If you missed the recent MiniDebConf, there's a great opportunity to attend the next one in Toulouse. It was recently decided to include a MiniDebCamp beforehand as well. FTPmaster accepts MRs for DAK At the recent MiniDebConf in Cambridge, I discussed potential enhancements for DAK to make life easier for both FTP Team members and developers. For those interested, the document "Hacking on DAK" provides guidance on setting up a local DAK instance and developing patches, which can be submitted as MRs. As a perfectly random example of such improvements some older MR, "Add commands to accept/reject updates from a policy queue" might give you some inspiration. At MiniDebConf, we compiled an initial list of features that could benefit both the FTP Team and the developer community. While I had preliminary discussions with the FTP Team about these items, not all ideas had consensus. I aim to open a detailed, public discussion to gather broader feedback and reach a consensus on which features to prioritize. Sometimes, packages are rejected not because of DFSG-incompatible licenses but due to other issues that could be resolved within an existing package (as discussed in my DebConf23 BoF, "Chatting with ftpmasters"[1]). During the "Meet the ftpteam" BoF (Log/transcription of the BoF can be found here), for the moment until the MR gets accepted, a new option was proposed for FTP Team members reviewing packages in NEW:

Accept + Bug Report This option would allow a package to enter Debian (in unstable or experimental) with an automatically filed RC bug report. The RC bug would prevent the package from migrating to testing until the issues are addressed. To ensure compatibility with the BTS, which only accepts bug reports for existing packages, a delayed job (24 hours post-acceptance) would file the bug.

When binary package names change, currently the package must go through the NEW queue, which can delay the availability of updated libraries. Allowing such packages to bypass the queue could expedite this process. A configuration option to enable this bypass specifically for uploads to experimental may be useful, as it avoids requiring additional technical review for experimental uploads. Previously, I believed the requirement for binary name changes to pass through NEW was due to a missing feature in DAK, possibly addressable via an MR. However, in discussions with the FTP Team, I learned this is a matter of team policy rather than technical limitation. I haven't found this policy documented, so it may be worth having a community discussion to clarify and reach consensus on how we want to handle binary name changes to get the MR sensibly designed. When a developer requests the removal of a package whether entirely or for specific architectures RM bugs must be filed for the package itself as well as for each package depending on it. It would be beneficial if the dependency tree could be automatically resolved, allowing either:
a) the DAK removal tooling to remove the entire dependency tree
   after prompting the bug report author for confirmation, or
b) the system to auto-generate corresponding bug reports for all
   packages in the dependency tree.
The latter option might be better suited for implementation in an MR for reportbug. However, given the possibility of large-scale removals (for example, targeting specific architectures), having appropriate tooling for this would be very beneficial. In my opinion the proposed DAK enhancements aim to support both FTP Team members and uploading developers. I'd be very pleased if these ideas spark constructive discussion and inspire volunteers to start working on them--possibly even preparing to join the FTP Team. On the topic of ftpmasters: an ongoing discussion with SPI lawyers is currently reviewing the non-US agreement established 22 years ago. Ideally, this review will lead to a streamlined workflow for ftpmasters, removing certain hurdles that were originally put in place due to legal requirements, which were updated in 2021. Contacting teams My outreach efforts to Debian teams have slowed somewhat recently. However, I want to emphasize that anyone from a packaging team is more than welcome to reach out to me directly. My outreach emails aren't following any specific orders--just my own somewhat na ve view of Debian, which I'm eager to make more informed. Recently, I received two very informative responses: one from the Qt/KDE Team, which thoughtfully compiled input from several team members into a shared document. The other was from the Rust Team, where I received three quick, helpful replies one of which included an invitation to their upcoming team meeting. Interesting readings on our mailing lists I consider the following threads on our mailing list some interesting reading and would like to add some comments. Sensible languages for younger contributors Though the discussion on debian-devel about programming languages took place in September, I recently caught up with it. I strongly believe Debian must continue evolving to stay relevant for the future. "Everything must change, so that everything can stay the same." -- Giuseppe Tomasi di Lampedusa, The Leopard I encourage constructive discussions on integrating programming languages in our toolchain that support this evolution. Concerns regarding the "Open Source AI Definition" A recent thread on the debian-project list discussed the "Open Source AI Definition". This topic will impact Debian in the future, and we need to reach an informed decision. I'd be glad to see more perspectives in the discussions particularly on finding a sensible consensus, understanding how FTP Team members view their delegated role, and considering whether their delegation might need adjustments for clarity on this issue. Kind regards Andreas.

2 November 2024

Dirk Eddelbuettel: Rcpp 1.0.13-1 on CRAN: Hot Fix

rcpp logo A hot-fix release 1.0.13-1, consisting of two small PRs relative to the last regular CRAN release 1.0.13, just arrived on CRAN. When we prepared 1.0.13, we included a change related to the tightening of the C API of R itself. Sadly, we pinned an expected change to comes with next (minor) release 4.4.2 rather than now next (normal aka major) release 4.5.0 . And now that R 4.4.2 is out (as of two days ago) we accidentally broke building against the header file with that check. Whoops. Bugs happen, and we are truly sorry but this is now addressed in 1.0.13-1. The normal (bi-annual) release cycle will resume with 1.0.14 slated for January. As you can see from the NEWS file of the development branch, we have a number of changes coming. You can safely access that release candidate version, either off the default branch at github or via r-universe artifacts. The list below details all changes, as usual. The only other change concerns the now-mandatory use of Authors@R.

Changes in Rcpp release version 1.0.13-1 (2024-11-01)
  • Changes in Rcpp API:
    • Use read-only VECTOR_PTR and STRING_PTR only with with R 4.5.0 or later (Kevin in #1342 fixing #1341)
  • Changes in Rcpp Deployment:
    • Authors@R is now used in DESCRIPTION as mandated by CRAN

Thanks to my CRANberries, you can also look at a diff to the previous release Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues). If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Russell Coker: Moving Between Devices

I previously wrote about the possibility of transferring work between devices as an alternative to convergence (using a phone or tablet as a desktop) [1]. This idea has been implemented in some commercial products already. MrWhosTheBoss made a good YouTube video reviewing recent Huawei products [2]. At 2:50 in that video he shows how you can link a phone and tablet, control one from the other, drag and drop of running apps and files between phone and tablet, mirror the screen between devices, etc. He describes playing a video on one device and having it appear on the other, I hope that it actually launches a new instance of the player app as the Google Chromecast failed in the market due to remote display being laggy. At 7:30 in that video he starts talking about the features that are available when you have multiple Huawei devices, starting with the ability to move a Bluetooth pairing for earphones to a different device. At 16:25 he shows what Huawei is doing to get apps going including allowing apk files to be downloaded and creating what they call Quick Apps which are instances of a web browser configured to just use one web site and make it look like a discrete app, we need something like this for FOSS phone distributions does anyone know of a browser that s good for it? Another thing that we need is to have an easy way of transferring open web pages between systems. Chrome allows sending pages between systems but it s proprietary, limited to Chrome only, and also takes an unreasonable amount of time. KDEConnect allows sharing clipboard contents which can be used to send URLs that can then be pasted into a browser, but the process of copy URL, send via KDEConnect, and paste into other device is unreasonably slow. The design of Chrome with a Send to your devices menu option from the tab bar is OK. But ideally we need a Send to device for all tabs of a window as well, we need it to run from free software and support using your own server not someone else s server (AKA the cloud ). Some of the KDEConnect functionality but using a server rather than direct connection over the same Wifi network (or LAN if bridged to Wifi) would be good. What else do we need?

1 November 2024

Russ Allbery: Review: Overdue and Returns

Review: Overdue and Returns, by Mark Lawrence
Publisher: Mark Lawrence
Copyright: June 2023
Copyright: February 2024
ASIN: B0C9N51M6Y
ASIN: B0CTYNQGBX
Format: Kindle
Pages: 99
Overdue is a stand-alone novelette in the Library Trilogy universe. Returns is a collection of two stories, the novelette "Returns" and the short story "About Pain." All of them together are about the length of a novella, so I'm combining them into a single review. These are ancillary stories in the same universe as the novels, but not necessarily in the same timeline. (Trying to fit "About Pain" into the novel timeline will give you a headache and I am choosing to read it as author's fan fiction.) I'm guessing they're part of the new fad for releasing short fiction on Amazon to tide readers over and maintain interest between books in a series, a fad about which I have mixed feelings. Given the total lack of publisher metadata in either the stories or on Amazon, I'm assuming they were self-published even though the novels are published by Ace, but I don't know that for certain. There are spoilers for The Book That Wouldn't Burn, so don't read these before that novel. There are no spoilers for The Book That Broke the World, and I don't think the reading order would matter. I found all three of these stories irritating and thuddingly trite. "Returns" is probably the best of the lot in terms of quality of storytelling, but I intensely dislike the structural implications of the nature of the book at its center and am therefore hoping that it's non-canonical. I would not waste your time with these even if you are enjoying the novels. "Overdue": Three owners of the same bookstore at different points in time have encounters with an albino man named Yute who is on a quest. One of the owners is trying to write a book, one of them is older, depressed, and closed off, and one of them has regular conversations with her sister's ghost. The nature of the relationship between the three is too much of a spoiler, but it involves similar shenanigans as The Book That Wouldn't Burn. Lawrence uses my least favorite resolution of benign ghost stories. The story tries very hard to sell it as a good thing, but I thought it was cruel and prefer fantasy that rejects both branches of that dilemma. Other than that, it was fine, I guess, although the moral was delivered with all of the subtlety of the last two minutes of a Saturday morning cartoon. (5) "Returns": Livira returns a book deep inside the library and finds that she can decipher it, which leads her to a story about Yute going on a trip to recover another library book. This had a lot of great Yute lines, plus I always like seeing Livira in exploration mode. The book itself is paradoxical in a causality-destroying way, which is handwaved away as literal magic. I liked this one the best of the three stories, but I hope the world-building of the main series does not go in this direction and I'm a little afraid it might. (6) "About Pain": A man named Holden runs into a woman named Clovis at the gym while carrying a book titled Catcher that his dog found and that he's returning to the library. I thoroughly enjoy Clovis and was happy to read a few more scenes about her. Other than that, this was fine, I guess, although it is a story designed to deliver a point and that point is one that appears in every discussion of classics and re-reading that has ever happened on the Internet. Also, I know I'm being grumpy, but Lawrence's puns with authors and character names are chapter-epigraph amusing but not short-story-length funny. Yes, yes, his name is Holden, we get it. (5) Rating: 5 out of 10

Taavi V n nen: Custom domains on the Wikimedia Cloud VPS web proxy

The shared web proxy used on Wikimedia Cloud VPS now has technical support for using arbitrary domains (and not just wmcloud.org subdomains) in proxy names. I think this is a good example of how software slowly evolves over time as new requirements emerge, with each new addition building on top of the previous ones. According to the edit history on Wikitech, the web proxy service has its origins in 2012, although the current idea where you create a proxy and map it to a specific instance and port was only introduced a year later. (Before that, it just directly mapped the subdomain to the VPS instance with the same name). There were some smaller changes in the coming years like the migration to acme-chief for TLS certificate management, but the overall logic stayed very similar until 2020 when the wmcloud.org domain was introduced. That was implemented by adding a config option listing all possible domains, so future domain additions would be as simple as adding the new domain to that list in the configuration. Then the changes start becoming more frequent:

30 October 2024

Russell Coker: Links October 2024

Dacid Brin wrote an interesting article about AI ecosystems and how humans might work with machines on creative projects [1]. Also he s right about influencers being like funghi. Cory Doctorow wrote an interesting post about DRM, coalitions, and cheating [2]. It seems that people like me who want trusted computing to secure their own computers don t fit well in any of the coalitions. The CHERI capability system for using extra hardware to validate jump addresses is an interesting advance in computer science [3]. The lecture is froim the seL4 Summit, this sort of advance in security goes well with a formally proven microkernel. I hope that this becomes a checkbox when ordering a custom RISC-V design. Bunnie wrote an insightful blog post about how the Mossad might have gone about implementing the exploding pager attack [4]. I guess we will see a lot more of this in future, it seems easy to do. Interesting blog post about Control Flow Integrity in the V8 engine of Chrome [5]. Interesting blog post about the new mseal() syscall which can be used by CFI among other things [6]. This is the Linux kernel documentation about the Control-flow Enforcement Technology (CET) Shadow Stack [7]. Unfortunately not enabled in Debian/Unstable yet. ARM added support for Branch Target Identification in version 8.5 of the architecture [8]. The CEO of Automatic has taken his dispute with WPEngine to an epic level, this video catalogues it, I wonder what is wrong with him [9]. NuShell is an interesting development in shell technology which runs on Linux and Windows [10]. Interesting article about making a computer game without coding using ML [11]. I doubt that it would be a good game, but maybe educational for kids. Krebs has an insightful article about location tracking by phones which is surprisingly accurate [12]. He has provided information on how to opt out of some of it on Android, but we need legislative action! Interesting YouTube video about how to make a 20kW microwave oven and what it can do [13]. Don t do this at home, or anywhere else! The Void editor is an interesting project, a fork of VSCode that supports DIRECT connections to LLM systems where you don t have their server acting as a middle-man and potentially snooping [14].

28 October 2024

Thomas Lange: 30.000 FAIme jobs created in 7 years

The number of FAIme jobs has reached 30.000. Yeah!
At the end of this November the FAIme web service for building customized ISOs turns 7 years old. It had reached 10.000 jobs in March 2021 and 20.000 jobs were reached in June 2023. A nice increase of the usage. Here are some statistics for the jobs processed in 2024: Type of jobs
3% cloud image
11% live ISO
86% install ISO
Distribution
2% bullseye
8% trixie
12% ubuntu 24.04
78% bookworm
Misc Execution Times The cloud and live ISOs need more time for their creation because the FAIme server needs to unpack and install all packages. For the install ISO the packages are only downloaded. The amount of software packages also affects the build time. Every ISO is build in a VM on an old 6-core E5-1650 v2. Times given are calculated from the jobs of the past two weeks.
Job type Avg Max
install no desktop 1 min 2 min
install GNOME 2 min 5 min
The times for Ubuntu without and with desktop are one minute higher than those mentioned above.
Job type Avg Max
live no desktop 4 min 6 min
live GNOME 8 min 11 min
The times for cloud images are similar to live images. A New Feature For a few weeks now, the system has been showing the number of jobs ahead of you in the queue when you submit a job that cannot be processed immediately. The Next Milestone At the end of this years the FAI project will be 25 years old. If you have a success story of your FAI usage to share please post it to the linux-fai mailing list or send it to me. Do you know the FAI questionnaire ? A lot of reports are already available. Here's an overview what happened in the past 20 years in the FAI project. About FAIme FAIme is the service for building your own customized ISO via a web interface. You can create an installation or live ISO or a cloud image. Several Debian releases can be selected and also Ubuntu server or Ubuntu desktop installation ISOs can be customized. Multiple options are available like selecting a desktop and the language, adding your own package list, choosing a partition layout, adding a user, choosing a backports kernel, adding a postinst script and some more.

26 October 2024

Steve McIntyre: Mini-Debconf in Cambridge, October 10-13 2024

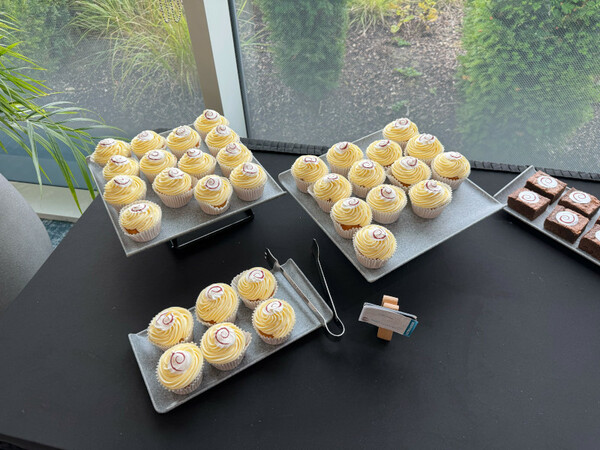
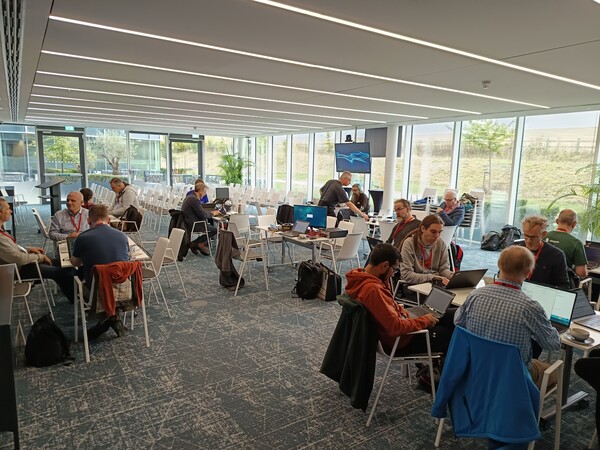
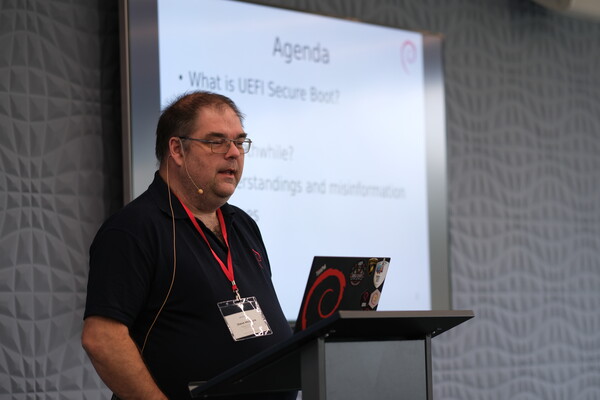
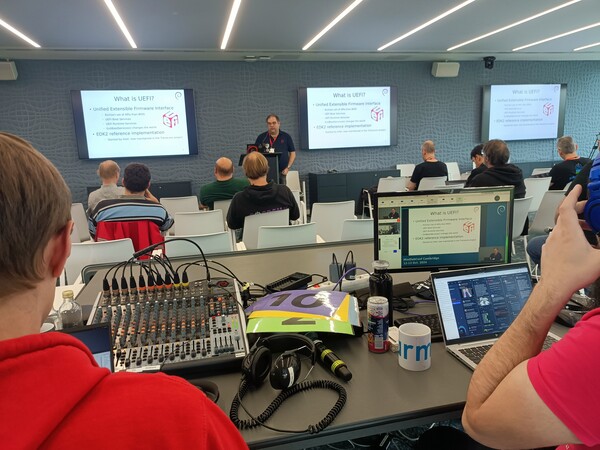
Group photo Again this year, Arm offered to host us for a mini-debconf in Cambridge. Roughly 60 people turned up on 10-13 October to the Arm campus, where they made us really welcome. They even had some Debian-themed treats made to spoil us! Cakes Hacking together minicamp For the first two days, we had a "mini-debcamp" with disparate group of people working on all sorts of things: Arm support, live images, browser stuff, package uploads, etc. And (as is traditional) lots of people doing last-minute work to prepare slides for their talks. Sessions and talks Secure Boot talk Saturday and Sunday were two days devoted to more traditional conference sessions. Our talks covered a typical range of Debian subjects: a DPL "Bits" talk, an update from the Release Team, live images. We also had some wider topics: handling your own data, what to look for in the upcoming Post-Quantum Crypto world, and even me talking about the ups and downs of Secure Boot. Plus a random set of lightning talks too! :-) Video team awesomeness Video team in action Lots of volunteers from the DebConf video team were on hand too (both on-site and remotely!), so our talks were both streamed live and recorded for posterity - see the links from the individual talk pages in the wiki, or http://meetings-archive.debian.net/pub/debian-meetings/2024/MiniDebConf-Cambridge/ for the full set if you'd like to see more. A great time for all Again, the mini-conf went well and feedback from attendees was very positive. Thanks to all our helpers, and of course to our sponsor: Arm for providing the venue and infrastructure for the event, and all the food and drink too! Photo credits: Andy Simpkins, Mark Brown, Jonathan Wiltshire. Thanks!

Russell Coker: The CUPS Vulnerability

The Announcement Late last month there was an announcement of a severity 9.9 vulnerability allowing remote code execution that affects all GNU/Linux systems (plus others) [1]. For something to affect all Linux systems that would have to be either a kernel issue or a sshd issue. The announcement included complaints about the lack of response of vendors and And YES: I LOVE hyping the sh1t out of this stuff because apparently sensationalism is the only language that forces these people to fix . He seems to have a different experience to me of reporting bugs, I have had plenty of success getting bugs fixed without hyping them. I just report the bug, wait a while, and it gets fixed. I have reported potential security bugs without even bothering to try and prove that they were exploitable (any situation where you can make a program crash is potentially exploitable), I just report it and it gets fixed. I was very dubious about his ability to determine how serious a bug is and to accurately report it so this wasn t a situation where I was waiting for it to be disclosed to discover if it affected me. I was quite confident that my systems wouldn t be at any risk. Analysis Not All Linux Systems Run CUPS When it was published my opinion was proven to be correct, it turned out to be a series of CUPS bugs [2]. To describe that as all GNU/Linux systems (plus others) seems like a vast overstatement, maybe a good thing to say if you want to be a TikTok influencer but not if you want to be known for computer security work. For the Debian distribution the cups-browsed package (which seems to be the main exploitable one) is recommended by cups-daemon, as I have my Debian systems configured to not install recommended packages by default that means that it wasn t installed on any of my systems. Also the vast majority of my systems don t do printing and therefore don t have any part of CUPS installed. CUPS vs NAT The next issue is that in Australia most home ISPs don t have IPv6 enabled and CUPS doesn t do the things needed to allow receiving connections from the outside world via NAT with IPv4. If inbound port 631 is blocked on both TCP and USP as is the default on Australian home Internet or if there is a correctly configured firewall in place then the network is safe from attack. There is a feature called uPnP port forwarding [3] to allow server programs to ask a router to send inbound connections to them, this is apparently usually turned off by default in router configuration. If it is enabled then there are Debian packages of software to manage this, the miniupnpc package has the client (which can request NAT changes on the router) [4]. That package is not installed on any of my systems and for my home network I don t use a router that runs uPnP. The only program I knowingly run that uses uPnP is Warzone2100 and as I don t play network games that doesn t happen. Also as an aside in version 4.4.2-1 of warzone2100 in Debian and Ubuntu I made it use Bubblewrap to run the game in a container. So a Remote Code Execution bug in Warzone 2100 won t be an immediate win for an attacker (exploits via X11 or Wayland are another issue). MAC Systems Debian has had AppArmor enabled by default since Buster was released in 2019 [5]. There are claims that AppArmor will stop this exploit from doing anything bad. To check SE Linux access I first use the semanage fcontext command to check the context of the binary, cupsd_exec_t means that the daemon runs as cupsd_t. Then I checked what file access is granted with the sesearch program, mostly just access to temporary files, cupsd config files, the faillog, the Kerberos cache files (not used on the Kerberos client systems I run), Samba run files (might be a possibility of exploiting something there), and the security_t used for interfacing with kernel security infrastructure. I then checked the access to the security class and found that it is permitted to check contexts and access-vectors not access that can be harmful. The next test was to use sesearch to discover what capabilities are granted, which unfortunately includes the sys_admin capability, that is a capability that allows many sysadmin tasks that could be harmful (I just checked the Fedora source and Fedora 42 has the same access). Whether the sys_admin capability can be used to do bad things with the limited access cupsd_t has to device nodes etc is not clear. But this access is undesirable. So the SE Linux policy in Debian and Fedora will stop cupsd_t from writing SETUID programs that can be used by random users for root access and stop it from writing to /etc/shadow etc. But the sys_admin capability might allow it to do hostile things and I have already uploaded a changed policy to Debian/Unstable to remove that. The sys_rawio capability also looked concerning but it s apparently needed to probe for USB printers and as the domain has no access to block devices it is otherwise harmless. Below are the commands I used to discover what the policy allows and the output from them.
# semanage fcontext -l grep bin/cups-browsed
/usr/bin/cups-browsed                              regular file       system_u:object_r:cupsd_exec_t:s0 
# sesearch -A -s cupsd_t -c file -p write
allow cupsd_t cupsd_interface_t:file   append create execute execute_no_trans getattr ioctl link lock map open read rename setattr unlink write  ;
allow cupsd_t cupsd_lock_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t cupsd_log_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t cupsd_runtime_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t cupsd_rw_etc_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t cupsd_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t cupsd_tmp_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t faillog_t:file   append getattr ioctl lock open read write  ;
allow cupsd_t init_tmpfs_t:file   append getattr ioctl lock read write  ;
allow cupsd_t krb5_host_rcache_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ; [ allow_kerberos ]:True
allow cupsd_t print_spool_t:file   append create getattr ioctl link lock open read relabelfrom relabelto rename setattr unlink write  ;
allow cupsd_t samba_var_t:file   append getattr ioctl lock open read write  ;
allow cupsd_t security_t:file   append getattr ioctl lock open read write  ;
allow cupsd_t security_t:file   append getattr ioctl lock open read write  ; [ allow_kerberos ]:True
allow cupsd_t usbfs_t:file   append getattr ioctl lock open read write  ;
# sesearch -A -s cupsd_t -c security
allow cupsd_t security_t:security check_context; [ allow_kerberos ]:True
allow cupsd_t security_t:security   check_context compute_av  ;
# sesearch -A -s cupsd_t -c capability
allow cupsd_t cupsd_t:capability net_bind_service; [ allow_ypbind ]:True
allow cupsd_t cupsd_t:capability   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock kill net_bind_service setgid setuid sys_admin sys_rawio sys_resource sys_tty_config  ;
# sesearch -A -s cupsd_t -c capability2
allow cupsd_t cupsd_t:capability2   block_suspend wake_alarm  ;
# sesearch -A -s cupsd_t -c blk_file
Conclusion This is an example of how not to handle security issues. Some degree of promotion is acceptable but this is very excessive and will result in people not taking security announcements seriously in future. I wonder if this is even a good career move by the researcher in question, will enough people believe that they actually did something good in this that it outweighs the number of people who think it s misleading at best?

25 October 2024

Jonathan Dowland: Behringer Model-D (synths I didn't buy)

Whilst researching what synth to buy, I learned of the Behringer1 Model-D2: a 2018 clone of the 1970 Moog Minimoog, in a desktop form factor.
Behringer Model-D Behringer Model-D
In common with the original Minimoog, it's a monophonic analogue synth, featuring three audible oscillators3 , Moog's famous 12-ladder filter and a basic envelope generator. The model-d has lost the keyboard from the original and added some patch points for the different stages, enabling some slight re-routing of the audio components.
1970 Moog Minimoog 1970 Moog Minimoog
Since I was focussing on more fundamental, back-to-basics instruments, this was very appealing to me. I'm very curious to find out what's so compelling about the famous Moog sound. The relative lack of features feels like an advantage: less to master. The additional patch points makes it a little more flexible and offer a potential gateway into the world of modular synthesis. The Model-D is also very affordable: about 200 GBP. I'll never own a real Moog. For this to work, I would need to supplement it with some other equipment. I'd need a keyboard (or press the Micron into service as a controller); I would want some way of recording and overdubbing (same as with any synth). There are no post-mix effects on the Model-D, such as delay, reverb or chorus, so I may also want something to add those. What stopped me was partly the realisation that there was little chance that a perennial beginner, such as I, could eek anything novel out of a synthesiser design that's 54 years old. Perhaps that shouldn't matter, but it gave me pause. Whilst the Model-D has patch points, I don't have anything to connect to them, and I'm firmly wanting to avoid the Modular Synthesis money pit. The lack of effects, and polyphony could make it hard to live-sculpt a tone. I started characterizing the Model-D as the "heart" choice, but it seemed wise to instead go for a "head" choice. Maybe another day!

  1. There's a whole other blog post of material I could write about Behringer and their clones of classic synths, some long out of production, and others, not so much. But, I decided to skip on that for now.
  2. taken from the fact that the Minimoog was a productised version of Moog's fourth internal prototype, the model D.
  3. 2 oscillators is more common in modern synths

Next.

Previous.