Search Results: "xam"

2 March 2008

Stefano Zacchiroli: indeed we should use doc-base more

Long live to doc-base Runa wonders: Why aren't we using doc-base? . It's indeed a good question. In the past I've pushed for using doc-base in several places, including obviously packages of mine, but also recently generating by default doc-base entries from OCaml libraries using debpkg ocamldoc, and finally also more than 100 doc-base entries shipped by w3-recs alone for the contained W3C recommendations. doc-base is based on a good idea, i.e. annotating the doc we ship with metadata so that it can be more easily browsed, and is (potentially) far better than asking our users to dig into /usr/share/doc/foo. Still, it is sadly true that in Debian is way underused. My best bet at the reason is that in the past the tools floating around doc-base were sucky. However, in 2007 some of them has dramatically improved their quality, with the noteworthy example of dhelp which has been rewritten from scratch in Ruby by Esteban Manchado Vel zquez closing tens and tens of bugs. My exhortation: please, maintainers, go back and consider (again, if needed) to register your documentation with doc-base, it is helpful and it does work. The next (needed) step for the doc-base world domination will be decoupling its classification hierarchy from that of the Debian menu system, keeping the 2 bound is nonsense. Update Runa submitted bug #469018; cool, because I was just going to do that by myself :-)

Adeodato Sim : Making EnhancedCommentify.vim more useable for me

I use the enhanced commentify script from vim.org to easily comment and decomment parts of code. It knows about comment delimiters in a ton of languages, and it’s generally nice. Lately, I’ve been a bit annoyed about commenting several lines with different indent levels. In particular, given for example this snippet:
  def foo():
      if duck.is_hungry():
          grab_food()
          feed_duck()
If one instructs the script to comment the three last lines, the result is:
  def foo():
      # if duck.is_hungry():
          # grab_food()
          # feed_duck()
When what I would like is:
  def foo():
      # if duck.is_hungry():
      #     grab_food()
      #     feed_duck()
There is one variable one can set to achieve this behavior: EnhCommentifyUseBlockIndent. However, it only works when commenting from visual mode. From normal mode (what I normally use — that is, going to e.g. line 2 above, and pressing 3,c), it doesn’t work, because from normal mode the commenting function does not receive the block, it just gets called three times, once per line. To solve this, the solution I found was to create a custom command that accepts a range, and calls the function exactly once, for the whole block. In particular, this is all my enhanced commentify configuration from ~/.vimrc:
  let EnhCommentifyPretty = "yes"
  let EnhCommentifyUserBindings = "yes"
  let EnhCommentifyRespectIndent = "yes"
  let EnhCommentifyUseBlockIndent = "yes"
  " The MyEnhancedCommentify bit is needed because the normal nmap just
  " calls EnhancedCommentify() <count> times, thus UseBlockIndent can't
  " work.
  nmap <Leader>c :MyEnhancedCommentify<CR>
  vmap <Leader>c <Plug>VisualTraditional
  command! -range MyEnhancedCommentify 
      \ call EnhancedCommentify('', 'guess', <line1>, <line2>)

28 February 2008

Filip Van Raemdonck: PyGTK/glade object reuse

Someone asked on the PyGTK mailinglist if it is possible to reuse certain parts of a libglade window several times within an application.
It certainly is, and it's not even hard to do!

I've quickly written a demo application to show how it's done.
The user interface designed in glade is really simple, a textbox with two toggle buttons underneath. Activating one button will display a second, disparate textbox beside the original one. Deactivating it will remove that second textarea.
The other button will display and remove a copy of the first textbox which was there from application startup.
The full widget tree of this interface is shown in the first screenshot. Glade widget tree The actual code to the demo application is rather brief.
The main point to keep in mind is that you can't actually reuse the same widget, more than once, at one time. You could reuse it if you'd make sure it's never used more than once at the same time, and keep track of it (you also have to make certain it doesn't get accidentally destroyed along the way!)

What the demo really does, and what libglade allows you to do, is use (parts of) the same interface definition over and over again to build distinct PyGTK objects and add them to the existing interface. At least the PyGTK implementation of libglade, and possibly the native C libglade as well, actually caches the interface definition in case you'd want to reuse parts of it for additional object creation.

Let's have a closer look at how it's done:
import gtk, gtk.glade
class ReuseDemo:
  def __init__ (self):
    self.gladefile = 'glade-reuse-demo.glade'
    self.xml = gtk.glade.XML (self.gladefile)
    self.win = self.xml.get_widget ('firstWindow')
    self.theContainer = self.xml.get_widget ('theHBox')
    self.xml.signal_autoconnect (
                     dict (gtk_main_quit=gtk.main_quit,
                     btn1_toggled=self.toggle1,
                     btn2_toggled=self.toggle2))
    self.buttons = (self.xml.get_widget ('tbtn1'), self.xml.get_widget ('tbtn2'))
    self.childTree = None
    self.win.show_all()
Demo application window First step is to import the gtk and gtk.glade modules.
The actual demo is in a little class; it's constructor starts by storing the name of the glade file, because it's needed later to construct the additional objects from (even if the caching should mean it isn't really re-read anymore). The xml tree from this file is parsed by pyglade and the window object is retrieved from the first of the two windows defined in it. At this point the window is already a PyGTK object!

The container that needs to have objects added to and removed from is also retrieved and stored as a class attribute. The signals for the two toggle buttons and to allow a graceful exit by means of the windowmanager close button are connected to their handlers, and the two togglebuttons' objects are also retrieved and stored away for later reference. Finally, a variable to hold a reference to the secondary textbox objects is initiated, and the window is shown.
  def toggle1 (self, btn):
    self.toggle (btn, 'txtContent', 1)
  def toggle2 (self, btn):
    self.toggle (btn, 'txtOther', 2)
The two toggle button callbacks call a single method, with the gladeXML tagname for the respective textbox object each one needs to display or remove and an index number for arguments (in addition to the togglebutton object reference that the callback received as it's first argument).
  def toggle (self, btn, tagname, idx):
    self.buttons[(idx%2)].set_sensitive (not btn.get_active())
    if not btn.get_active():
      if self.childTree:
        self.theContainer.remove (self.childTree)
        self.childTree = None
    else:
      objXML = gtk.glade.XML (self.gladefile, root=tagname)
      self.childTree = objXML.get_widget (tagname)
      self.theContainer.pack_end (self.childTree)
The important logic is in the final method. First, the button which is not toggled is disabled or enabled for user interaction, depending on the activated state of the toggled button. Because the indices passed on by the two toggle buttons' callbacks were one-based, while the python tuple that holds references to the toggle buttons is zero-based, the remainder of a division by two of the callback index will automatically point to the button that was not toggled. Alternatively the values 1 and 0, in that order, and thus pointing directly to the tuple indices could also have been used as index arguments for the two callbacks.

The necessity of disabling the other button when one is activated, and therefore two textboxes are displayed, is because the demo isn't written to support displaying more than two textboxes at the same time, but especially removing the correct textbox when three would be visible. If it were extended in that sense, the need to disable the other button would disappear.

Next the activated state is tested; if the button is deactivated, the second textbox is removed from the container and the reference to it removed, while if it's activated, a new object is instantiated from the gladeXML description and added to the container.
Here's where the gladeXML tagnames come in: to recreate only part of the widget tree, and retrieve the actual widget from the parsed tree. Note that you must reconstruct the parse tree here; retrieving the same object from the original parsetree and trying to add it a second time to the container will result in a GTK+ warning (on the console) and nothing being added at all.

That's all there is to it, really. All that is left is to instantiate a class instance and start the GTK+ mainloop:
if __name__ == '__main__':
  ReuseDemo()
  gtk.main()
The second screenshot is an example of how the application might look in one specific state.

A tarball with the glade and python code is available from the sysfs download area.

27 February 2008

Sergio Talens-Oliag: Tips &#x26; Tricks: plone, nginx and path rewriting

The problem On a couple of Debian Etch systems we have a plone-site that is published using a backport of the nginx web server. The Zope instance is running on the standard port and serves the Plone contents under the /plone path. Initially we were publishing the site to the external world using an https site served by nginx using the following entry on the configuration:

  location /plone/  
    proxy_pass http://plone:9673;
    include    /etc/nginx/proxy.conf;
   
The proxy.conf contents are quite standard:
  # proxy.conf
  proxy_redirect                  off;
  proxy_set_header                Host $host;
  proxy_set_header                X-Real-IP $remote_addr;
  proxy_set_header                X-Forwarded-For $proxy_add_x_forwarded_for;
  client_max_body_size            0;
  client_body_buffer_size         128k;
  proxy_connect_timeout           90;
  proxy_send_timeout              90;
  proxy_read_timeout              90;
  proxy_buffer_size               4k;
  proxy_buffers                   4 32k;
  proxy_busy_buffers_size         64k;
  proxy_temp_file_write_size      64k;
With this settings we see the /plone contents using the same path that is used by the Zope instance, but after testing we have decided to change the /plone path and server the contents under the /web path. The Wrong Solution The fist option I though about was quite simple, rename the Zope's plone object to web. Seems reasonable and simple for someone without Zope experience (I don't administer the internals of the Zope/Plone site), but now I know that it is a very big mistake, because renaming objects in Zope in not cheap, as it implies that the server has to modify all the contents of the renamed object and the operation can take a very long time. With my ignorance I tried to rename the plone object using the Zope administrative interface and after a minute or so I cancelled the page loading that was running on my browser, thinking that I had cancelled the rename operation. To make a long story short I'll tell you that the operation was still running and after several hours the folder was renamed (in fact I noticed when the good solution broke, as I had already solved the problem using the next method), but something went wrong and part of the site functionality was broken... the final solution to the debacle has been to recover a backup of the Zope instance older than the rename operation and continue from that copy. The Right Solution (TM) It seems that Zope has a couple of systems to do Virtual Hosting and the best option is the use of the product called Virtual Host Monster, a weird and confusing system (IMHO, of course), that does the job once the right configuration settings are in place. The best solution to our problem was to modify the requests done by the reverse proxy without touching anything on the Plone site (the original one already had a Virtual Host Monster object installed and that was the only thing that we needed to add). The nginx configuration for the new /web path is the following:
  location /web/  
    proxy_pass http://plone:9673/plone/VirtualHostRoot/_vh_web/;
    include    /etc/nginx/proxy.conf;
   
With this change, when the user asks for anything under the /web/ path the Zope server gets the contents traversing the /plone object and adding to it the elements that appear after the VirtualHostRoot component, ignoring components that start with the _vh_ prefix (the protocol and host name of the requests are not modified, as we did not touched that). Once the object is found, the server rewrites the URLs included on the HTML files using the path components that appear after the VirtualHostRoot one, including the suffix of the components that start with the prefix _vh_. For example, when the Zope server receives a request for an URL like:
  http://plone:9673/plone/VirtualHostRoot/_vh_web/home
it publishes the content found on:
  http://plone:9673/plone/home
but the HTML files returned assume that their base URL is:
  http://plone:9673/web/home

Steve Kemp: I'm wearing my heart like a crown

For the past couple of days I've been working on some "easy hosting" setup for Debian. This is a continuation of my shell-script based solution, but intended to be much more dynamic. The system makes it simple for us to deploy a Debian Etch installation, and allow users to create virtualhosts easily. (And by easily I mean by creating directories, and very little else.) So, for example, to create a new website simple point the IP address of your domain example.org to the IP of your machine. Then run:
mkdir -p /srv/example.com/cgi-bin
mkdir -p /srv/example.com/htdocs
If you then want to allow FTP access to upload you may run:
echo "mysecretpass" > /srv/example.com/ftp-password
This will give you FTP access, username "example.com", password "mysecretpass". You'll be chrooted into the /srv/example.com/ directory. All of this is trivial. Via Apache's mod_vhost_alias, and a simple script to split logfiles and generate statistics via webalizer for each domain. The only thing that I really needed to do was to come up with a simple shell script & cron entry to build up an FTP password file for pure-ftpd. So here's where it gets interesting. The next job, obviously, is to handle mail for the domains. Under Debian it should be a matter of creating an appropriate /etc/exim/exim4.conf - and ignoring the rest of the setup. I'm getting some help with that, because despite knowing almost too much about SMTP these days I'm still a little hazy on Exim4 configuration. I'm watching the recent debian configuration packages system with interest, because right now I'm not touching any configuration files I'm sure that it is only a matter of time.
In other news I cut prices, and am seeing a lot of interest in my mail-scanning. Finally my .emacs file has been tweaked a lot over the previous few days. Far too much fun. (support files.)

Russell Coker: Redirecting Output from a Running Process

Someone asked on a mailing list how to redirect output from a running process. They had a program which had been running for a long period of time without having stdout redirected to a file. They wanted to logout (to move the laptop that was used for the ssh session) but not kill the process (or lose output). Most responses were of the form “you should have used screen or nohup” which is all very well if you had planned to logout and leave it running (or even planned to have it run for a long time). Fortunately it is quite possible to redirect output of a running process. I will use cat as a trivial example but the same technique will work for most programs that do simple IO (of course programs that do terminal IO may be more tricky - but you could always redirect from the tty device of a ssh session to the tty device of a screen session). Firstly I run the command “cat > foo1” in one session and test that data from stdin is copied to the file. Then in another session I redirect the output: Firstly find the PID of the process:
$ ps aux grep cat
rjc 6760 0.0 0.0 1580 376 pts/5 S+ 15:31 0:00 cat Now check the file handles it has open:
$ ls -l /proc/6760/fd
total 3
lrwx—— 1 rjc rjc 64 Feb 27 15:32 0 -> /dev/pts/5
l-wx—— 1 rjc rjc 64 Feb 27 15:32 1 -> /tmp/foo1
lrwx—— 1 rjc rjc 64 Feb 27 15:32 2 -> /dev/pts/5 Now run GDB:
$ gdb -p 6760 /bin/cat
GNU gdb 6.4.90-debian
Copyright (C) 2006 Free Software Foundation, Inc
[lots more license stuff snipped]
Attaching to program: /bin/cat, process 6760
[snip other stuff that’s not interesting now]
(gdb) p close(1)
$1 = 0
(gdb) p creat(”/tmp/foo3″, 0600)
$2 = 1
(gdb) q
The program is running. Quit anyway (and detach it)? (y or n) y
Detaching from program: /bin/cat, process 6760 The “p” command in GDB will print the value of an expression, an expression can be a function to call, it can be a system call… So I execute a close() system call and pass file handle 1, then I execute a creat() system call to open a new file. The result of the creat() was 1 which means that it replaced the previous file handle. If I wanted to use the same file for stdout and stderr or if I wanted to replace a file handle with some other number then I would need to call the dup2() system call to achieve that result. For this example I chose to use creat() instead of open() because there are fewer parameter. The C macros for the flags are not usable from GDB (it doesn’t use C headers) so I would have to read header files to discover this - it’s not that hard to do so but would take more time. Note that 0600 is the octal permission for the owner having read/write access and the group and others having no access. It would also work to use 0 for that parameter and run chmod on the file later on. After that I verify the result:
ls -l /proc/6760/fd/
total 3
lrwx—— 1 rjc rjc 64 2008-02-27 15:32 0 -> /dev/pts/5
l-wx—— 1 rjc rjc 64 2008-02-27 15:32 1 -> /tmp/foo3 <====
lrwx—— 1 rjc rjc 64 2008-02-27 15:32 2 -> /dev/pts/5 Typing more data in to cat results in the file /tmp/foo3 being appended to. Update: If you want to close the original session you need to close all file handles for it, open a new device that can be the controlling tty, and then call setsid().

26 February 2008

Russell Coker: Future Versions of Windows

There is currently a lot of speculation about the future of Windows following the massive failure of Vista in the market. One theory that is being discussed is that Microsoft will cease kernel development and adopt a Unix kernel in the same way that Apple adopted a BSD based kernel. I predict that MS in it’s current incarnation (*) will never do that. Having an OS kernel that enables easy porting of code to/from other platforms is entirely against their business model which relies on incompatibility to lock customers in. Whatever kernel MS use, it has to be incompatible in some ways with everything else. One easy way of achieving this would be to have a shared object (DLL) interface published and have the interface between the libc and other libraries and the kernel be undocumented and ever-changing (simply renumbering the system calls on every minor version increment would be a good start). The DLL interface could then have the complex APIs that MS loves to force on their victims (see Stewart Smith’s post about getting a file size in Windows for an example of the horror [1]). The advantage of this approach would be that MS could cease developing an OS kernel (something that they were never much good at) and concentrate on owning the proprietary DLLs. There would be nothing stopping them from using a Linux kernel for this, as long as they release all source to the kernel they use (including the patch to renumber the system calls) they would be within the terms of the GPL. My specific prediction is that some time between Jan 2011 and Dec 2016 Microsoft will release systems with the majority of the kernel code coming from BSD or Linux as their primary desktop and server operating systems. Could people who disagree please make specific predictions for the future (including dates and actions) so that we can determine who was most accurate. (*) For future incarnations of Microsoft after chapter 11 or being split in the way that AT&T was there seems no possibility to predict their actions.

MJ Ray: Work Trip Goes Wrong

Yesterday really didn't go to plan. The plan was to clear a few work tasks and then travel to London for an early afternoon Koha-related meeting, then fix some other problems on site before travelling home this evening. Unusually, this trip involved bike, train, tube coach and bus. Everything but the car, indeed, so a pretty good example of using greener transport for TTLLP. Got about 80% of the work tasks done (not bad), biked to Worle station and caught the train, then changed to a high-speed train at Bristol. So far, so good. I spotted our Member of Parliament changing trains in Bristol too. I did a double-take, which I think he noticed - he's in the local papers every week or two, but he's not that visually distinctive and looks superficially similar to my last MP. Didn't harangue him this time - he was queuing for coffee, while I wanted to visit the buffet. Anyway, about 10 minutes before arrival in London, someone walked onto the tracks near Southall. We reversed into Slough and were eventually told to travel via Windsor into Waterloo (I think if they'd been a bit quicker, I could have saved 30 minutes). I planned to arrive in London 75 minutes before my meeting, but this happened at about the most delaying point, so I was actually 70 minutes late and missed the whole thing. Damn. Of the three on-site problems, I fixed one and made progress on one, but that fixed one means that we can continue working remotely on the others, so not a total failure. The coach back to Bristol was fine - once it stops weaving around London, it's as comfortable as an unrefurbished HST (not quite as much leg or arm room as a current one). The bus to Worle was awful, bouncy as hell and badly-driven, stopping ahead of the lines at red lights. It's also expensive (thanks to First's route monopoly?) - in future, I'd walk 15 minutes and pay 30p more for the train. The above was written on the return journey, then bluetoothed here. Now it's time to catch up with the stack of emails and back to work.

25 February 2008

Matthew Palmer: IEEE, Thou Art Clowns

Ever since I started University, I've been a member of the Institution of Electrical and Electronic Engineers. Although I don't really do what you would call "Engineering" any more, I like to read the IEEE Spectrum magazine and some of the Computer society journals are quite relevant to what I do. However, this year the IEEE have produced what is, without a doubt, one of the most shithouse online ordering systems I have ever had the misfortune of trying to use. To start with, if you happen to go to the account login screen with cookies disabled, you get a page that is utterly blank. I've seen a lot of ways to fail to handle cookies, but I think the completely blank page is a first for me. Once you work out what's going on and log in, you're presented with a long and painful journey through a series of "checkout" pages, mostly alike. I think I got presented with my list of journals about four times. After navigating that pest, it comes up with this little gem when you start the credit card processing step: To Back, or Not
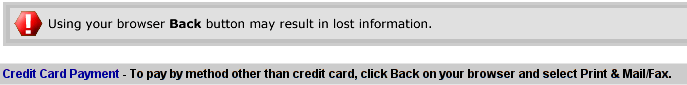
  To Back Then, every time you input practically anything into the form, it does a Javascript submit and does things to the form. For example, when you enter your credit card number, you get a form back that has blanked out all but the last four digits of the card number. OK, a little dumb, but not spectacularly so. Although, when you're a quick typist and have filled in the next three fields while the web browser was playing footsie with the slow-as-molasses web server, only to have that data wiped out when the page refreshes, is a bit of a pest. Far more annoying is when you start entering your address "for verification purposes". Here, you get a form resubmit every time, presumably to update the form based on (for example) your selected country, but not a lot changes. Even though I picked Australia, I still got a pull-down with all of the the US states in it. You could short-circuit all this with the "choose existing address" option, except that (despite me being logged in) my existing addresses aren't in a select box, but in a separate pop-up window (which didn't actually display anything after all). In short, the IEEE's online renewal system is a disgrace, and is an embarrassment to what is purportedly a technical organisation.

Julian Andres Klode: debimg - debian-cd in Python


I’m currently working on a rewrite of debian-cd in Python. Although there is already deb-imgs-gen, I decided to start from scratch, because deb-imgs-gen is more than 1 year old. debimg’s main features are Speed debimg should be able to build netinst disks in less than 20 seconds Free Software This program is free software: you can redistribute it and/or modify it under the terms of the GNU General Public License as published by the Free Software Foundation, either version 3 of the License, or (at your option) any later version. Easy Configuration
  • Packages can be included based on their priority, tasks or name (no manually created task files)
  • All packages are defined in one file,which is based on the format on debian/control. You can even use the “package [architectures]” syntax from Build-Depends
Based on python-apt
  • Highspeed dependency solver written in C (or C++ ?)
  • Used for downloading all kind of data in debimg
  • Packages ,.gz files are created from the apt cache instead of scanning the disk
many features are missing at the moment, and no code has been released. I will send an email containing more details, like configuration file examples, to the MLs in a few days.

Benjamin Mako Hill: Still Seeing Yellow

Recently, the EFF reported that the European commission had responded to a request by European Parliament member Satu Hassi about tracking dots in printers. European Commissioner Franco Frattini replied that tracking dots may constitute a human rights violation saying that:
"..to the extent that individuals may be identified through material printed or copied using certain equipment, such processing may give rise to the violation of fundamental human rights, namely the right to privacy and private life. It also might violate the right to protection of personal data."
Intriguingly, the request text includes a mention to and link to the Seeing Yellow project I started last year as an example of the fact that consumers have complained to printer manufacturers and that these complaints have fallen upon deaf ears. Everyone who called their printer manufacturer in response to Seeing Yellow deserves come credit for the raised visibility to the issue that we've created and the set of actions that have brought the issue this far. Please, keep it up! If you've not complained to your printer manufacturer, visit Seeing Yellow and call today.

24 February 2008

Russell Coker: EeePC for a Teenager

I was asked for advice from a non-technical person about buying a laptop for their 15yo daughter. They were looking to spend $200 or $300. I suggested that stretching their budget to $500 for a new EeePC would be a better option than the risks associated with a second-hand laptop (laptops are all different in their hardware). I also suggested that waiting a few months to see what happens with the new EeePCs might be a good idea. There are rumours about the development of new EeePC models with bigger screens, this would be a benefit for those who can afford it, and for those who can’t the current model may drop in price. They took that suggestion very well and I suspect that they weren’t planning to purchase in the near future anyway. I asked for advice on the LUV mailing list [1] for further suggestions that I could offer. One suggestion was that larger laptops of a more traditional design have been driven down in price recently and might be worth considering. I will have to mention it, but suggesting that someone who wants to spend $200 should spend $500 seemed enough of a stretch, suggesting that they spend $700 or more might not be taken well. Of course there is the weight issue that Matt raised in a blog post [2]. The last thing I want to do is to convince people not to buy computers for their children! A complaint was raised about the size of the keyboard in the EeePC (personally I wouldn’t want to use anything smaller than the T series Thinkpad I’m using now). In a quick google search the best information I could find about average finger sizes was the Danforth Diamond blog [3] which says that in the US women average a ring size of 6 while men average 10. According to the ring sizing page on the same site [4] that means ring finger diameter of 16.5 and 19.8mm respectively. So it seems likely that given the same level of typing skill an average woman could happily use a keyboard that’s 83% the size of the keyboard that an average man uses. Of course there’s a lot of variation between individuals, for example my fingers are thinner than average and I prefer a full-sized keyboard. One thing I recommend when considering a keyboard (or a laptop) is to type your name a few times quickly. Typing something about a quick brown fox will take some thought, but typing your own name requires no thought so you can concentrate on the feel of the keyboard. Using this method it is very easy to go to a store and determine whether a laptop is likely to suit you. The screen resolution and size is a significant issue, one EeePC owner described it as “too small to do anything useful“. Rumour has it that the next version will have a screen that’s a significant increase in size and resolution. A final interesting comment was about the social aspect of owning a laptop. The suggestion was made that a teenager who owned the smallest (and possibly cheapest) laptop in class might have other kids tease them about it. I will be interested to see comments on this issue, it had never occurred to me that the laptop use in schools would be high enough for the ownership of any type of laptop to be a cause for harassment. Also I’m not sure which would be considered as being of lower status, an old second-hand laptop or a new low-end laptop. I’m pretty sure that owning either would be considered to have higher status than having no laptop. A quick scan of the GraysOnline.com.au auction site suggests that a second-hand Pentium-M laptop (a few years old) could be purchased for about $550 and a Core 2 Duo based laptop might go for about $700. So it seems unlikely that for less than $500 you could buy something suitable for a novice user (something that will just work with recent software). I’m not planning on offering the full IT support package that I offer to my relatives so I can only recommend things that can be self-supported. Of course as the people doing the buying seem to have no definite plans for the use of the computer then anything they buy will fail in some way to meet the requirements that they discover. :-# Update: fixed a bad link.

Benjamin Mako Hill: Still Seeing Yellow

Recently, the EFF reported that the European commission had responded to a request by European Parliament member Satu Hassi about tracking dots in printers. European Commissioner Franco Frattini replied that tracking dots may constitute a human rights violation saying that:
"..to the extent that individuals may be identified through material printed or copied using certain equipment, such processing may give rise to the violation of fundamental human rights, namely the right to privacy and private life. It also might violate the right to protection of personal data."
Intriguingly, the request text includes a mention to and link to the Seeing Yellow project I started last year as an example of the fact that consumers have complained to printer manufacturers and that these complaints have fallen upon deaf ears. Everyone who called their printer manufacturer in response to Seeing Yellow deserves come credit for the raised visibility to the issue that we've created and the set of actions that have brought the issue this far. Please, keep it up! If you've not complained to your printer manufacturer, visit Seeing Yellow and call today.

22 February 2008

Marc 'Zugschlus' Haber: Bounce from BTS to BTS

Sometimes a bug report is a labyrinth. #348046 is an example of this. It is a horrible mess of at least three different issues with half of the original participants having become unresponsive. I would like to pull the issues apart into different bug reports to be able to deal with them (and their probably unresponsive submitters) individually. Obviously, cloning and renaming is not an option since this copies the mess. So, it would probably be desireable to download the bug mbox and to bounce individual messages to new bugs (that have been created before), but the BTS recognizes the dupes and bins them. Blars has helped me by looking at BTS mail log, so it was clear that removing the X-Loop, X-Debian-PR, X-Spam, Resent- and Received headers from the mbox before loading it into mutt to do the actual bouncing works fine. A command line to do this:
rm -f mboxout; mboxbug formail -d -I Received -I X-Debian-PR -I X-Loop -I X-Spam -I Resent -s >> mboxout
After trying this in “production”, one needs to send one message per BTS pulse, or one will totally mess up the order of the messages. That’s a real pity and an annoyance.

Russell Coker: Service Videos

I just read interesting blog post about Lenovo service information [1]. They have huge documents about how to service their machines as well as apparently having videos in flash format to show how to perform various tasks. The first thing I’d like to see is other companies following this example. I clearly recall one time when I had an IBM 2RU server apart and I couldn’t work out how to get the power cable for the tape drive installed, a video of how to do so would surely have saved me some time then, I was working for a law firm and had a small outage window - not a situation where I wanted to waste any time. The next thing I would like to see is Lenovo not using Flash for this, but instead allow download of MP4 and/or OGG video. When doing a job in a tight time window with a demanding client I would like to have all the relevant documentation (including videos) on my laptop before I visit their site.

21 February 2008

David Welton: Android - commercial meets open source

One of the interesting things about Google's Android project is the mix of cultures. There are a number of people like me, firmly grounded in the open source world, who are happy to get something that 1) works, 2) looks to have legs in terms of popularity, and 3) will be open source. Think of a lot of your favorite open source projects when they first launched. "Polished" isn't a word you would probably use to describe them, although it usually happens in later releases (Ubuntu looks better and better, for example). There are also a lot of people who come from a 'commercial' background, who expect to see everything ready and waiting on a plate for them, which isn't a mistaken expectation if you're used to using products from big companies who are staking their reputations on them. They want nice, thorough docs for everything, almost all bugs worked out, and lots of easy to use tools. Android lies in a middle ground somewhere between these two camps, which I think at times makes people uneasy. It's not open source yet. You can't hack it as much as you may want. You can't rebuild it from the ground up. You don't get access to the communication between the developers working on it, and cannot participate in that development. However, there is a promise to open source it that would reflect very, very poorly on Google were it not met and is therefore pretty credible. The developers and many people involved with it certainly seem to "get" open source, and are taking good steps to create a community around Android (a few even hang out in the #android IRC channel on Freenode) that will most likely not take too long to start assimilating interested outsiders once the code is open. In terms of quality, it wasn't bad when it came out, but it was very definitely an "early look", put out there to solicit feedback and change according to it, something that's part and parcel of a release early, release often open source model. On the other side, Android looks to be a big effort from a big company to get into a big market in a big way - it's not a "under the radar" type of strategy that the open source world is often constrained to follow for lack of monetary and marketing resources to do it any other way. This has attracted a number of developers who either don't see or don't really get some of the "open source" aspects of what we have so far: it's still changing! The docs aren't complete! The emulator is still ugly in places! And from their point of view, it must seem odd to getting something that's obviously not a finished product, without crystal clear direction and goals and a roadmap, and without actual hardware only available in the distant (well, in internet terms! - 8 months or so) future. That kind of thing probably isn't done very often in their world, or where it's done, is certainly kept quieter and perhaps restricted to registered developers. They came over to have a look at something that was ready to go, and it isn't, yet. This has caused some disappointment for people who expected to see something ready to go out of the box. Perhaps Google needed to manage their initial communications slightly better in order to manage the second group's expectations more carefully. In terms of us open source folks, I think that what we want is more access, as soon as Google is willing to hand it out. More source code access, but also access to the development process and people. "Real" open source isn't just about the code, it's about being more or less equal participants in a community. Luckily, I think the people at Google get this, which is one of the reasons I'm enthusiastic about Android, even if I wish we didn't have to wait so long for the source code.

MJ Ray: Local Strategic Partnerships and Strategic Economic Partnerships

Are any worker cooperatives reading this involved in any Local Strategic Partnerships or Strategic Economic Partnerships? If so, please contact me (use the contact form on the page for this post and mark it "not for publication"). I've some questions about it from a Regional Cooperative Council. Any other comments about LSPs and SEPs can be fed back if you want to send them to me. As an example, our local LSP is http://www.northsomersetpartnership.co.uk/

Peter Makholm: AcmeCal: The world needs a new calendar system

What do you do when you suddenly get a free evening? Writing a calendar system seemed the obvious thing to do. Neither Google Calendar nor flat unstructured text files seemed to fit my needs. So I proudly present: AcmeCal version 0.1. The main novelties includes: And all that in just under 400 lines of code. As of version 0.1 some important features remains to be implemented, for example documentation. Warning: Neither the comand line interface, nor the perl API, nor plutonium is stable. Download AcmeCal -0.1

20 February 2008

Neil Williams: emdebian-tools 0.8.2 in Emdebian

Although an interim release, there are a number of new features in 0.8.2 that are worth noting.

  1. emrecent - possible candidate for a rename to emdput, this script started off just as a review tool for recent builds (hence the current name). Finds recent .changes files in the Emdebian working directory, collates them, provides a viewer for the debc -a $ARCHcontents using whiptail or zenity along with error logging. If the default zenity frontend is installed, you can still select to use whiptail (e.g. when over an SSH connection) using the -w option to emrecent. Further checks are run using the second script:

  2. emdebcheck - a local Emdebian version of the debcheck that runs on the Debian archive using edos-debcheck to highlight non-installable packages before an upload breaks the archive. This isn't such a problem in Debian but Emdebian needs to build installer images and similar tools from packages in unstable so an installability check is very useful. Certain packages are expected to be non-installable due to dependencies that are removed in Emdebian so emrecent supports a --skip option to omit the emdebcheck run for such builds.

  3. emsource --status now reports errors logged by emrecent or emdebcheck.

  4. Unpacking support in emsandbox - EXPERIMENTAL!. debootstrap --foreign puts a higher-than-necessary burden on the host device when running the default --second-stage - not just in CPU workload but in the amount of free space required to copy and unpack all the .deb files. The original debootstrap tarball contains the downloaded .deb archives and only a few packages are actually unpacked manually. Unpacking support in emsandbox adds a handler using dpkg to unpack ALL .deb files in .$BUILDPLACE/var/cache/apt/archives/ using dpkg -e and dpkg -x, creates a suitable status file for dpkg and removes the .deb packages for a smaller tarball. The result is (almost) a foreign filesystem image that can be copied directly onto the host device. The remaining tasks are only:
    • /sbin/ldconfig
    • /usr/bin/dpkg --configure -a
    . Depending on how well this works in real situations, unwrap could become the default handler for debootstrap --second-stage --foreign in emdebian-tools. Unpack support is enabled via the debootstrap suite scripts which define the package set, the first_stage_install and the (much reduced) second_stage, replacing the sequence of install commands with a single function provided by emdebian-tools. See /usr/lib/emdebian-tools/emdebian.gpe for an example.


In common with all previous interim Emdebian releases, 0.8.2 has been uploaded to the Emdebian tools repository already added to your apt sources when installing emdebian-tools so apt will be able to upgrade seamlessly.
(0.8.0 introduced a check in emsetup to ensure that the latest version has actually been installed.)
Once features have stabilised (probably after testing at Fosdem), I'll upload 0.9.0 to Debian unstable, as usual, or maybe one or two more interim releases to Emdebian.

Vincent Fourmond: pdfnup and page size

I use a combination of pdftk and pdfnup, from the pdfjam package to arrange (PDF) graphs produced by ctioga into an array for printing. However, I find that a simple
pdfnup --nup 3x3 concatenated_graphs.pdf
does not produce an A4 output (even with --paper a4paper), but a PDF who has the same size as individual graphs. Painful. It did take me long to realize it is a feature of pdfnup, who asks pdfTeX to have the paper size adjusted to that of the input when the layout is symmetric and no orientation has been provided. To disable that, and get a real A4 paper, specify the orientation:
pdfnup --orient portrait --nup 3x3 concatenated_graphs.pdf

Next.

Previous.