Search Results: "reg"

25 July 2010

Russell Coker: Links July 2010

David Byrne gave an interesting TED talk about how changes to architecture drove changes to musical styles [1]. I think he does stretch the point a little. To a certain extent people develop the most complex instruments and the largest music halls that can be supported by the level of technology in their society people with a hunter-gatherer civilisation play drums because they can build them and can carry them. The NY Times has an interesting article about paternity leave in Sweden [2]. The Swedish government pays for a total of 13 months leave that can be split between parents for every child. Of those 13 months 2 months can only be taken by the father and that is likely to increase to a minimum of 4 months of paternity leave after the next election. Dan Meyer gave an interesting TEDX talk about how the current math curriculum in the US (as well as Australia and lots of other countries that do the same thing) is totally wrong [3]. His main point is that maths problems should be based on real-world use cases where not all needed data is immediately available and there is also useless data that must be discarded. He believes that the most important thing is developing mathematical problem solving skills basically the things that I did for fun when I was in primary school are skills that need to be taught to high-school students The Atlantic magazine has an amusing article by Daniel Byman and Christine Fair about the incompetent Islamic terrorists [4]. In Afghanistan half the suicide bombers kill only themselves and the US government has a lot of evidence of Taliban soldiers practicing bestiality and collecting porn. Islamic extremist groups are staffed by people who are bad soldiers and bad Muslims. Jon Masters wrote an interesting post titled What Would Jesus Buy about ethical purchasing decisions [5]. Jon references The Church of Stop Shopping which isn t a real religious organisation but a street theatre activist group. ZeroHedga has an insightful article comparing corporations and the US government to street gangs [6]. The conclusion is that when gangs take over a neighbourhood everyone has to join a gang for their own protection. Hillel Cooperman gave an interesting TED talk about being obsessed with Lego [7]. He compares Lego fans to Furries and makes a good case for this comparison. Marian Bantjes gave an interesting TED talk about her graphic art / graphic design work [8]. I ve never seen anything quite like this. Business Insider has an interesting article about oil cleanup, it seems that most people who worked on the Exxon Valdez disaster are now dead [9], s opposed to most people who worked in almost every other occupation at that time who are either still working or enjoying their retirement. The current gulf disaster is bigger, will require more workers for the cleanup, and can be expected to have a higher death toll. Some people claim that measures to reduce oil efficiency will impact the economy, how will millions of people who are chronically ill for the rest of their lives impact the economy? The NY Times has an interesting article on circle lenses [10], contact lenses designed to make the eyes look larger. It s illegal to sell contact lenses in the US without a prescription, but the latest trend is for women to buy them online in a variety of colors. The FDA should probably approve them, it would be better to have the quality controls you expect from a medical supply company instead of having people rely on Malaysian mail-order companies for the safety of their eyes. Don Marti has written an interesting article about the economic decline in the US, he suggests making pension funds invest in local jobs [11]. Companies are supposed to act on behalf of their stock-holders, but US companies often have the majority of their stock owned by the pension funds of workers but they act on behalf of a small number of rich people who own a minority of the stock. Don s article was inspired by Andy Grove s article in Bloomberg about the stagnation in technological development that has been caused by off-shoring the manufacturing [12]. Neil Brown has completed a test release of a new Linux software RAID feature for arrays with multiple redundancy that have bad sectors [13]. When a disk gets a bad sector the current behavior is to kick it out of the array, if you have two such errors on a 3 disk RAID-1 or a RAID-6 array then you lose all redundancy and are at risk of catastrophic failure even though in most cases both disks will still mostly work. With this patch some regions of the disk may be excluded but it can provide redundancy for other stripes. Thanks Neil for your great work here, and all your previous work over the last 10+ years! The RSPCA has a new campaign titled Close the Puppy Factories [14]. Dogs are kept in very poor conditions and forced to churn out puppies for their entire lives to supply pet stores. The RSPCA recommends that people buy puppies from registered dog breeders (not registered dog breeding companies ) and ask to see the dog s parents. They also recommend not buying from classified adverts or pet stores. Animal shelters have to euthenise huge numbers of unwanted animals, you can buy a pet dog or cat from an animal shelter for a small fee that covers the expenses related to housing and spaying it and save that animal from being euthenised! Maureen Dowd criticises the Catholic Church properly in an article for the New York Times [15]. The Catholic Church officially regards ordaining a woman and raping a child to be equally bad offenses. Frank Rich wrote an interesting column for the New York Times about Mel Gibson [16]. He describes the destruction of Mel Gibson s reputation as a symptom of changes in the culture in the US and also links it to the fall of Ted Haggard (who supported Gibson s most notorious movie The Passion of the Christ).

Russell Coker: SE Linux status in Debian/Squeeze

ffmpeg I ve updated my SE Linux repository for Squeeze to include a modified version of the ffmpeg packages without MMX support for the i386 architecture. When MMX support is enabled it uses assembler code which requires text relocations (see Ulrich Drepper s documentation for the explanation of this [1]). This makes it possible to run programs such as mplayer under SE Linux without granting excessive access something which we really desire because mplayer will usually be dealing with untrusted data. In my past tests with such changes to ffmpeg on my EeePC701 have resulted in no difference to my ability to watch movies from my collection, the ones that could be played without quality loss on a system with such a slow CPU could still be viewed correctly with the patched ffmpeg. $ mplayer
mplayer: error while loading shared libraries: /usr/lib/i686/cmov/libswscale.so.0: cannot restore segment prot after reloc: Permission denied The AMD64 architecture has no need for such patches, presumably due to having plenty of registers. I don t know whether other architectures need such patches, they might the symptom is having mplayer abort with an error such as the above when running in Enforcing Mode. The below apt sources.list line can be used to add my SE Linux repository: deb http://www.coker.com.au squeeze selinux dpkg In my repository for i386 and AMD64 architectures I have included a build of dpkg that fixes bug #587949. This bug causes some sym-links and directories to be given the wrong label by dpkg when a package is installed. Usually this doesn t impact the operation of the system and I was unable to think of a situation where it could be a security hole, but it can deny access in situations where it should be granted. I would appreciate some help in getting the patch in a form that can be accepted by the main dpkg developers, the patch I sent in the bug report probably isn t ideal even though it works quite well someone who knows absolutely nothing about SE Linux but is a good C coder with some knowledge of dpkg could beat it into shape. In my repository I don t currently provide any support for architectures other than i386 and AMD64. I could be persuaded to do so if there is a demand. How many people are using Debian SE Linux on other architectures? Of course there s nothing stopping someone from downloading the source from my AMD64 repository and building it for another architecture, I would be happy to refer people to an APT repository that someone established for the purpose of porting my SE Linux packages to another architecture. Policy selinux-policy-default version 20100524-2 is now in Testing. It s got a lot of little fixes and among other things allows sepolgen-ifgen to work without error which allows using the -R option of audit2allow see my post about audit2allow and creating the policy for milters for defails [2]. I have uploaded selinux-policy-default version 20100524-3 to Unstable. It has a bunch of little fixes that are mostly related to desktop use. You can now run KDE4 on Unstable in enforcing mode, login via kdm and expect that everything will work probably some things won t work, but some of my desktop systems work well with it. I have to admit that not all of my desktop systems run my latest SE Linux code, I simply can t have all my systems run unstable and risk outages. Let me know if you find any problems with desktop use of the latest SE Linux code, it s the focus of my current work. But if you find problems with chrome (from Google) or the Debian package chromium-browser then don t report them to me. They each use their own version of ffmpeg in the shared object /usr/lib/chromium-browser/libffmpegsumo.so which has text relocations and I don t have time to rebuild chromium-browser without text relocations I ll make sure it does the right thing when they get it working with the standard ffmpeg libraries. That said the text relocation problem doesn t seem to impact the use of Chromium, Youtube doesn t work even when the browser is run in permissive mode. GNOME is a lower priority than KDE for me at this time. But the only area where problems are likely to occur is with gdm and everything associated with logging in. Once your X session starts up GNOME and KDE look pretty similar in terms of access control. I would appreciate it if someone could test gdm and let me know how it goes. I ll do it eventually if no-one else does, but I ve got some other things to fix first.

Stefano Zacchiroli: RCBC - release critical bugs contest

Recipe for RCBC - Release Critical Bug squashing Contest:
squash RC bugs for 2 weeks , from July 25th to August 7th
help the release of Debian Squeeze
earn fame and glory (for sure)
win a GuruPlug and other geeky gadgets (maybe)
read on for more info ...
It has been a while since my last post in the RCBW tradition. Luckily, the tradition is in very good health of its own, thanks to many others that have picked up the habit of SPAM-ing planet with good news for Debian, encouraging others to do the same. With all that RC-obsessed people around and with the Squeeze release forthcoming, can DebConf10 be devoid of geeky RC-squashing activities? Of course not! Thanks to the orga team we expect the conference to contain a 2-week long RC bug squashing pride with tutorials, BoFs, a permanent bug squashing party, ... and a contest! I won't indulge much on the contest as the wiki page contains all rules and gory details. Obviously, all usual rules and best practices of bug squashing parties will apply; coordination will happen on #debian-bugs. Get involved, it starts today, and it's open to everyone (DebConf10 attendees as well as Debian enthusiasts abroad, regular RC squashers as well as casual bystanders, etc). All this wouldn't have been possible without the help of many people that love Debian, so many thanks to: PS a corresponding announcement is in the debconf-announce pipeline already

23 July 2010

Joey Hess: Flattr FOSS

Raphael's Flattr FOSS is a good idea: Make it really easy for users to pay tips for free software and maybe users who otherwise wouldn't express their appreciation will. I've added Flattr buttons for a few of my Free Software packages. Am interested to see how it works out.
Flattr this
Regarding Flattr itself, I have always wanted a way to easily micropay artists, coders, etc online. Especially musicians like Mosaik! The way it splits your monthly payment amoung everyone you've Flattr'd that month is smart; it takes money out of the picture when deciding whether to click on a Flattr button. I think it would be more honest, though, if rather than taking 10% of everything (which would be just absurd and indefensible if this were used on a large scale, and whiffs faintly of pyramid scheme even now), Flattr took one share of your monthly payment (as if you automatically Flattr'd them each month). That would provide even more incentive to Flattr lots of other things. And if lots of people were Flattring lots of things, Flattr would still make plenty of money.

22 July 2010

Erich Schubert: Dropbox revisited

Like one or two years ago, I got myself a free Dropbox account. I use it occasionally to exchange files with some friends. It does an excellent job at that. Basically, it works like any network folder. Except it is not within a local network, but over the internet.Dropbox serves me as an occasional replacement for both email and USB pen drive. Instead of sending a modified file by email or bringing around a dozen of photos on a USB stick, I just put them into the shared folder. This also very useful for files such as flyers, templates. They may easily grow to big to be sensibly sent by email.For all my use, a regular free Dropbox account is more than enough. As in, I have less than 1 GB in use, and I could easily free some of that space. You start at 2 GB, and can currently get up to 10 GB free (+250 MB for each referrer; if you use the link above you'll already start at 2.25 GB). But for my use, this is already a lot.Note that there are a couple of alternatives around. For Linux (only) there is Ubuntu One, and there is Zumo Drive and Box.net just to name a few. I havn't tried them, given that Dropbox works for me well enough.
20 July 2010

Ondřej Čertík: Theoretical Physics Reference Book

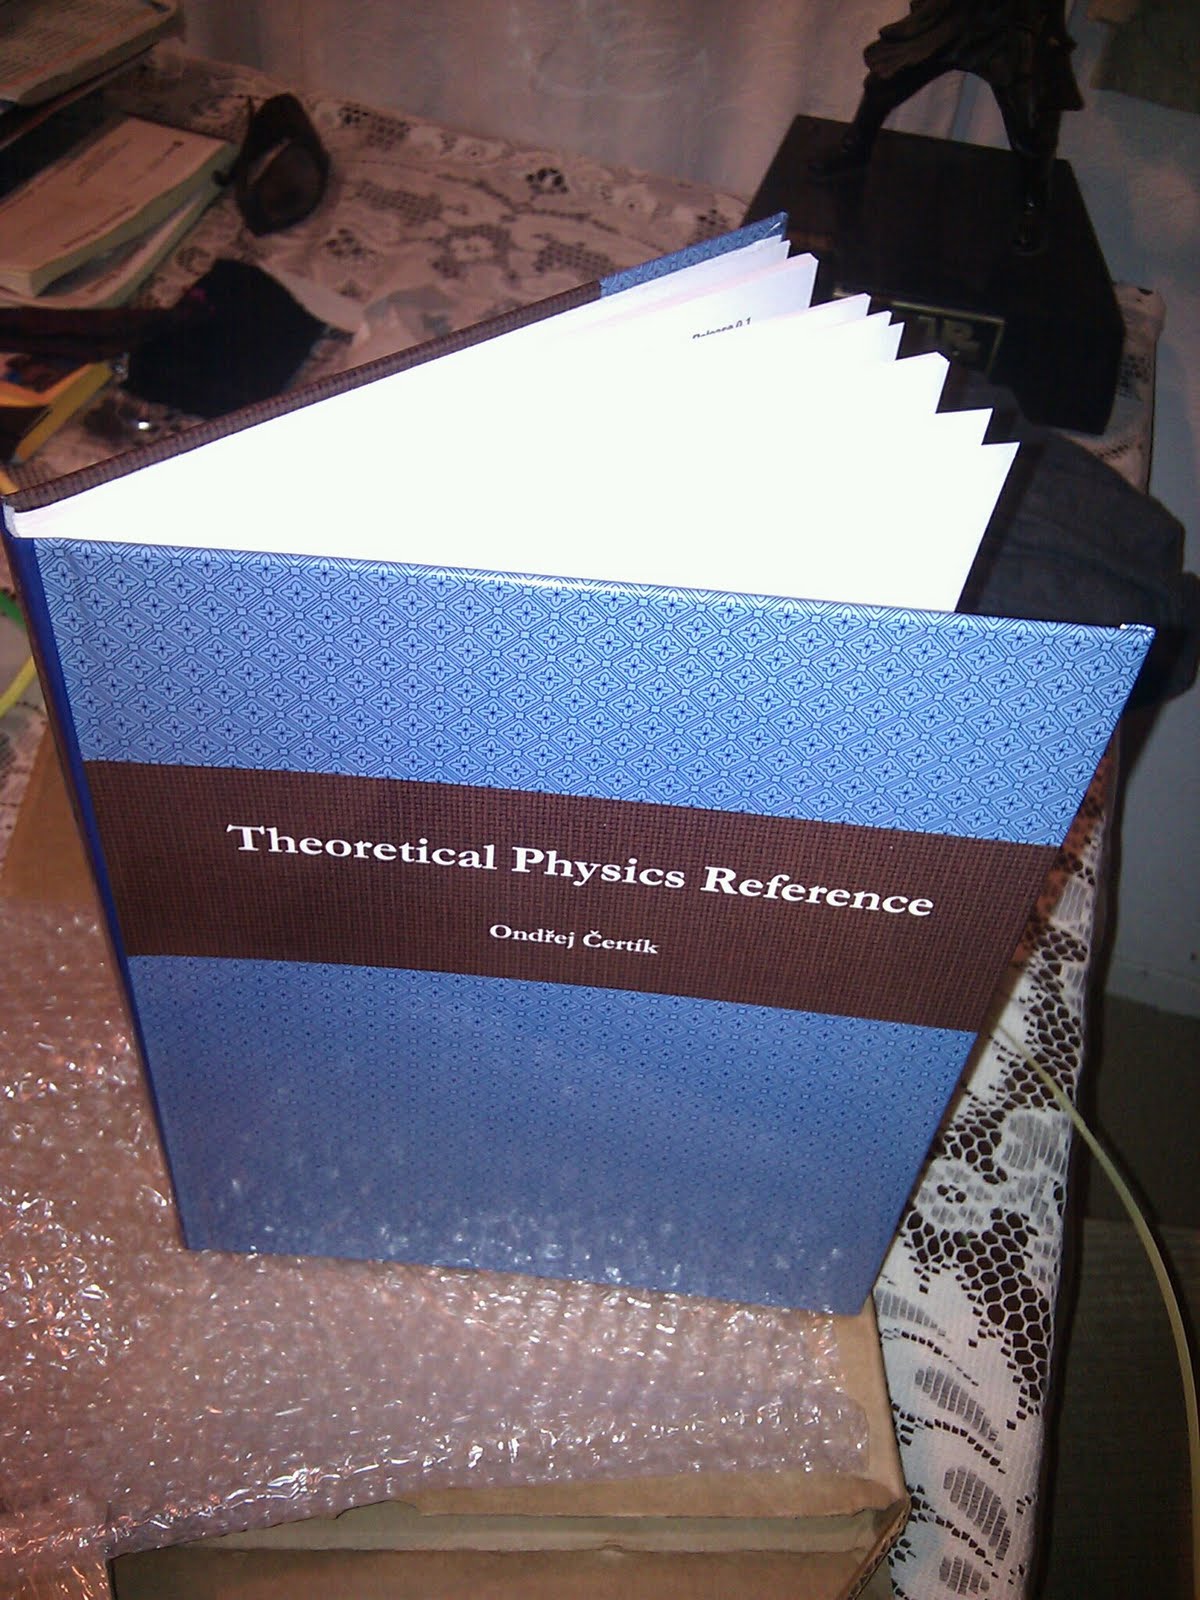
Today I fulfilled my old dream --- I just created my first book! Here is how it looks like:

More images
here.

Here is the source code of the book: http://github.com/certik/theoretical-physics, the repository contains a branch 'master' with the code and 'gh-pages' with the generated html pages, that are hosted at github, at the url theoretical-physics.net.

Then I published the book at Lulu: http://www.lulu.com/product/hardcover/theoretical-physics-reference/11612144, I wanted a hardcover book, so I setup a project at Lulu, used some Lulu templates for the cover and that was it. Lulu's price for the book is $19.20 (166 black & white pages, hardcover), then I can set my own price and the rest of the money probably goes to me. I set the price to $20, because Lulu has free shipping for orders $20 or more. You can also download the pdf (for free) at the above link (or just use my git repository). So far this didn't cost me anything.

I have then ordered the book myself (just like anybody else would, at the above address) and it arrived today. It's a regular hardcover book. Beautiful, you can browse the pictures above. It smells deliciously (that you have to believe me). And all that it cost me was $19.20.

As for the contents itself, you can browse it online at theoretical-physics.net, essentially it's most of my physics notes, that I collected over the years. I'd like to treat books like software --- release early release often. This is my first release and I would call it beta. The main purpose of it was to see if everything goes through, how long it takes (the date inside the book is July 4, 2010, I created and ordered it on July 5, got the physical book on July 19) and what the quality is (excellent). I also wanted to see how the pages correspond to the pdf (you can see for yourself on the photos, click on the picasa link above).

Now I need to improve the first pages a bit, as well as the last pages, improve the index, write some foreword and so on. I also need to think how to better organize the contents itself and generally improve it. I also need to figure out some versioning scheme, so far this is version 0.1. I think I'll do edition 1, edition 2, edition 3, and so on. And whenever I feel that I have added enough new content, I'll just publish it as a new edition. So if you want to buy it, I suggest to wait for my 1.0 version, that will have the mentioned improvements.

It'd be also cool to have all the editions online somehow and create nice webpages for it (currently theoretical-physics.net points directly to the book html itself).

So far the book is just text. I still need to figure out how to handle pictures and also whether or not to use program examples (in Python, using sympy, scipy, etc.). So far I am inclining not to put there any program codes, as then I don't need to maintain them.

Overall I am very pleased with the quality, up to some minor issues that I mentioned above, everything else end up just fine. I think we have come a long way from the discovery of the printing press. Anybody can now create a book for free, and if you want to hold the hardcopy in your hands, it costs around $20. You don't need to order certain amounts of books, nor partner with some publisher etc. I think that's just awesome.

19 July 2010

Tim Retout: Gnash and BBC glow

One thing I noticed having started to use gnash is that the BBC's iPlayer website (UK-only, I believe) gives a message like "You do not have Flash player installed" - not merely complaining about the version, but actually not recognising gnash as a Flash player at all. Cue some digging. The BBC's pages use glow, an in-house JavaScript library (available under the Apache 2.0 License) to detect whether Flash is installed. The documentation was really easy to follow - I had a test page going quicker than you can say "Hello, World!" The bottom line is, glow uses this regex:
var regexFLASH_VERSION = /^Shockwave Flash\s*(\d+)\.(\d+)\s*\w(\d+)$/;
and gnash uses a description like this:
Shockwave Flash 10.1 r999.
Gnash trunk, the GNU SWF Player. Copyright (C) 2006, 2007, 2008, 2009,
2010 Free Software Foundation, Inc.
Gnash comes with NO WARRANTY, to the extent permitted by law. You may
redistribute copies of Gnash under the terms of the GNU General Public
License. For more information about Gnash, see
http://www.gnu.org/software/gnash.
Compatible Shockwave Flash 10.1 r999.
Note the dollar sign at the end of the regex. Indeed, rebuilding gnash without all the notices at the end of the description lets you see the iPlayer UI. (It doesn't actually play anything, don't get your hopes up.) Interestingly, different parts of iPlayer require different minimum versions of Flash. Clips of radio programmes tend to be more liberal with what they will accept - right down to version 7. Most TV streams and clips require at least version "9.0 r115", and I've heard they use SWF verification. I'm not sure how legal it is to implement that, although apparently code exists.

Gerfried Fuchs: BTS Talk on 22nd, 18:00 UTC

I got convinced to hold an IRC talk on usage of the Debian BTS in #ubuntu-classroom and thought it might be interested to other children distributions of Debian, too also for regular Debian users. So feel invited to attend it. It will be held in #ubuntu-classroom on irc.freenode.net on Thursday, 22nd of July, at 18:00 UTC. For those who have never attended such a session yet, you might want/need to also join #ubuntu-classroom-chat too and raise questions in there, the main channel will be set to moderated. I will try to cover basic usage like querying the web interface, reporting new bugs and also more deeper handling of bugs, including version tracking issues, and will try to address raised questions as good as possible. Hope the session will be helpful to some and be able to address some questions like why some bugs aren't getting archived even though they are closed for ages. :) IRC logs will be available for the convenience of those who can't make it. So long!

18 July 2010

Gregor Herrmann: Let's freeze!

I spent the last two days at the BSP in Munich thanks to everyone for inviting & feeding me, & especially to Stefan for hosting me again!
Unfortunately the weather was not good enough for an excursion to a Biergarten but the local chefs at the LiMux office delighted us with self-made spaghetti salmone & self-rolled sushi, & we spent quite some time behind our laptops.

The main results can be seen on the wiki page; my personal conclusion is that the list of remaining RC bugs contains mostly "hard stuff" (e.g. architecture-, hardware-, or desktop-specific bugs). Probably some packages will need to be kicked out of squeeze & some bugs might get a squeeze-ignore tag ... To put it positively: I have a gut feeling that the freeze is getting closer :)

Torsten Werner: Monday: Debian bug squashing party in Berlin


This is just a reminder that we will have a small bug squashing party in Berlin. It will take place on monday 19th july starting at 16:00 with open end in the rooms of B ro 2.0 in Neuk lln. You have to organize your accomodation by yourself if you do not live in Berlin. More information is available in the Debian Wiki. Please register there if you are planning to attend.

17 July 2010

Petter Reinholdtsen: What are they searching for - PowerDNS and ISC DHCP in LDAP

This is a followup on my previous work on merging all the computer related LDAP objects in Debian Edu. As a step to try to see if it possible to merge the DNS and DHCP LDAP objects, I have had a look at how the packages pdns-backend-ldap and dhcp3-server-ldap in Debian use the LDAP server. The two implementations are quite different in how they use LDAP. To get this information, I started slapd with debugging enabled and dumped the debug output to a file to get the LDAP searches performed on a Debian Edu main-server. Here is a summary. powerdns Clues on how to set up PowerDNS to use a LDAP backend is available on the web. PowerDNS have two modes of operation using LDAP as its backend. One "strict" mode where the forward and reverse DNS lookups are done using the same LDAP objects, and a "tree" mode where the forward and reverse entries are in two different subtrees in LDAP with a structure based on the DNS names, as in tjener.intern and 2.2.0.10.in-addr.arpa. In tree mode, the server is set up to use a LDAP subtree as its base, and uses a "base" scoped search for the DNS name by adding "dc=tjener,dc=intern," to the base with a filter for "(associateddomain=tjener.intern)" for the forward entry and "dc=2,dc=2,dc=0,dc=10,dc=in-addr,dc=arpa," with a filter for "(associateddomain=2.2.0.10.in-addr.arpa)" for the reverse entry. For forward entries, it is looking for attributes named dnsttl, arecord, nsrecord, cnamerecord, soarecord, ptrrecord, hinforecord, mxrecord, txtrecord, rprecord, afsdbrecord, keyrecord, aaaarecord, locrecord, srvrecord, naptrrecord, kxrecord, certrecord, dsrecord, sshfprecord, ipseckeyrecord, rrsigrecord, nsecrecord, dnskeyrecord, dhcidrecord, spfrecord and modifytimestamp. For reverse entries it is looking for the attributes dnsttl, arecord, nsrecord, cnamerecord, soarecord, ptrrecord, hinforecord, mxrecord, txtrecord, rprecord, aaaarecord, locrecord, srvrecord, naptrrecord and modifytimestamp. The equivalent ldapsearch commands could look like this:
ldapsearch -h ldap \
  -b dc=tjener,dc=intern,ou=hosts,dc=skole,dc=skolelinux,dc=no \
  -s base -x '(associateddomain=tjener.intern)' dNSTTL aRecord nSRecord \
  cNAMERecord sOARecord pTRRecord hInfoRecord mXRecord tXTRecord \
  rPRecord aFSDBRecord KeyRecord aAAARecord lOCRecord sRVRecord \
  nAPTRRecord kXRecord certRecord dSRecord sSHFPRecord iPSecKeyRecord \
  rRSIGRecord nSECRecord dNSKeyRecord dHCIDRecord sPFRecord modifyTimestamp
ldapsearch -h ldap \
  -b dc=2,dc=2,dc=0,dc=10,dc=in-addr,dc=arpa,ou=hosts,dc=skole,dc=skolelinux,dc=no \
  -s base -x '(associateddomain=2.2.0.10.in-addr.arpa)'
  dnsttl, arecord, nsrecord, cnamerecord soarecord ptrrecord \
  hinforecord mxrecord txtrecord rprecord aaaarecord locrecord \
  srvrecord naptrrecord modifytimestamp
In Debian Edu/Lenny, the PowerDNS tree mode is used with ou=hosts,dc=skole,dc=skolelinux,dc=no as the base, and these are two example LDAP objects used there. In addition to these objects, the parent objects all th way up to ou=hosts,dc=skole,dc=skolelinux,dc=no also exist.
dn: dc=tjener,dc=intern,ou=hosts,dc=skole,dc=skolelinux,dc=no
objectclass: top
objectclass: dnsdomain
objectclass: domainrelatedobject
dc: tjener
arecord: 10.0.2.2
associateddomain: tjener.intern
dn: dc=2,dc=2,dc=0,dc=10,dc=in-addr,dc=arpa,ou=hosts,dc=skole,dc=skolelinux,dc=no
objectclass: top
objectclass: dnsdomain2
objectclass: domainrelatedobject
dc: 2
ptrrecord: tjener.intern
associateddomain: 2.2.0.10.in-addr.arpa
In strict mode, the server behaves differently. When looking for forward DNS entries, it is doing a "subtree" scoped search with the same base as in the tree mode for a object with filter "(associateddomain=tjener.intern)" and requests the attributes dnsttl, arecord, nsrecord, cnamerecord, soarecord, ptrrecord, hinforecord, mxrecord, txtrecord, rprecord, aaaarecord, locrecord, srvrecord, naptrrecord and modifytimestamp. For reverse entires it also do a subtree scoped search but this time the filter is "(arecord=10.0.2.2)" and the requested attributes are associateddomain, dnsttl and modifytimestamp. In short, in strict mode the objects with ptrrecord go away, and the arecord attribute in the forward object is used instead. The forward and reverse searches can be simulated using ldapsearch like this:
ldapsearch -h ldap -b ou=hosts,dc=skole,dc=skolelinux,dc=no -s sub -x \
  '(associateddomain=tjener.intern)' dNSTTL aRecord nSRecord \
  cNAMERecord sOARecord pTRRecord hInfoRecord mXRecord tXTRecord \
  rPRecord aFSDBRecord KeyRecord aAAARecord lOCRecord sRVRecord \
  nAPTRRecord kXRecord certRecord dSRecord sSHFPRecord iPSecKeyRecord \
  rRSIGRecord nSECRecord dNSKeyRecord dHCIDRecord sPFRecord modifyTimestamp
ldapsearch -h ldap -b ou=hosts,dc=skole,dc=skolelinux,dc=no -s sub -x \
  '(arecord=10.0.2.2)' associateddomain dnsttl modifytimestamp
In addition to the forward and reverse searches , there is also a search for SOA records, which behave similar to the forward and reverse lookups. A thing to note with the PowerDNS behaviour is that it do not specify any objectclass names, and instead look for the attributes it need to generate a DNS reply. This make it able to work with any objectclass that provide the needed attributes. The attributes are normally provided in the cosine (RFC 1274) and dnsdomain2 schemas. The latter is used for reverse entries like ptrrecord and recent DNS additions like aaaarecord and srvrecord. In Debian Edu, we have created DNS objects using the object classes dcobject (for dc), dnsdomain or dnsdomain2 (structural, for the DNS attributes) and domainrelatedobject (for associatedDomain). The use of structural object classes make it impossible to combine these classes with the object classes used by DHCP. There are other schemas that could be used too, for example the dnszone structural object class used by Gosa and bind-sdb for the DNS attributes combined with the domainrelatedobject object class, but in this case some unused attributes would have to be included as well (zonename and relativedomainname). My proposal for Debian Edu would be to switch PowerDNS to strict mode and not use any of the existing objectclasses (dnsdomain, dnsdomain2 and dnszone) when one want to combine the DNS information with DHCP information, and instead create a auxiliary object class defined something like this (using the attributes defined for dnsdomain and dnsdomain2 or dnszone):
objectclass ( some-oid NAME 'dnsDomainAux'
    SUP top
    AUXILIARY
    MAY ( ARecord $ MDRecord $ MXRecord $ NSRecord $ SOARecord $ CNAMERecord $
          DNSTTL $ DNSClass $ PTRRecord $ HINFORecord $ MINFORecord $
          TXTRecord $ SIGRecord $ KEYRecord $ AAAARecord $ LOCRecord $
          NXTRecord $ SRVRecord $ NAPTRRecord $ KXRecord $ CERTRecord $
          A6Record $ DNAMERecord
    ))
This will allow any object to become a DNS entry when combined with the domainrelatedobject object class, and allow any entity to include all the attributes PowerDNS wants. I've sent an email to the PowerDNS developers asking for their view on this schema and if they are interested in providing such schema with PowerDNS, and I hope my message will be accepted into their mailing list soon. ISC dhcp The DHCP server searches for specific objectclass and requests all the object attributes, and then uses the attributes it want. This make it harder to figure out exactly what attributes are used, but thanks to the working example in Debian Edu I can at least get an idea what is needed without having to read the source code. In the DHCP server configuration, the LDAP base to use and the search filter to use to locate the correct dhcpServer entity is stored. These are the relevant entries from /etc/dhcp3/dhcpd.conf:
ldap-base-dn "dc=skole,dc=skolelinux,dc=no";
ldap-dhcp-server-cn "dhcp";
The DHCP server uses this information to nest all the DHCP configuration it need. The cn "dhcp" is located using the given LDAP base and the filter "(&(objectClass=dhcpServer)(cn=dhcp))". The search result is this entry:
dn: cn=dhcp,dc=skole,dc=skolelinux,dc=no
cn: dhcp
objectClass: top
objectClass: dhcpServer
dhcpServiceDN: cn=DHCP Config,dc=skole,dc=skolelinux,dc=no
The content of the dhcpServiceDN attribute is next used to locate the subtree with DHCP configuration. The DHCP configuration subtree base is located using a base scope search with base "cn=DHCP Config,dc=skole,dc=skolelinux,dc=no" and filter "(&(objectClass=dhcpService)( (dhcpPrimaryDN=cn=dhcp,dc=skole,dc=skolelinux,dc=no)(dhcpSecondaryDN=cn=dhcp,dc=skole,dc=skolelinux,dc=no)))". The search result is this entry:
dn: cn=DHCP Config,dc=skole,dc=skolelinux,dc=no
cn: DHCP Config
objectClass: top
objectClass: dhcpService
objectClass: dhcpOptions
dhcpPrimaryDN: cn=dhcp, dc=skole,dc=skolelinux,dc=no
dhcpStatements: ddns-update-style none
dhcpStatements: authoritative
dhcpOption: smtp-server code 69 = array of ip-address
dhcpOption: www-server code 72 = array of ip-address
dhcpOption: wpad-url code 252 = text
Next, the entire subtree is processed, one level at the time. When all the DHCP configuration is loaded, it is ready to receive requests. The subtree in Debian Edu contain objects with object classes top/dhcpService/dhcpOptions, top/dhcpSharedNetwork/dhcpOptions, top/dhcpSubnet, top/dhcpGroup and top/dhcpHost. These provide options and information about netmasks, dynamic range etc. Leaving out the details here because it is not relevant for the focus of my investigation, which is to see if it is possible to merge dns and dhcp related computer objects. When a DHCP request come in, LDAP is searched for the MAC address of the client (00:00:00:00:00:00 in this example), using a subtree scoped search with "cn=DHCP Config,dc=skole,dc=skolelinux,dc=no" as the base and "(&(objectClass=dhcpHost)(dhcpHWAddress=ethernet 00:00:00:00:00:00))" as the filter. This is what a host object look like:
dn: cn=hostname,cn=group1,cn=THINCLIENTS,cn=DHCP Config,dc=skole,dc=skolelinux,dc=no
cn: hostname
objectClass: top
objectClass: dhcpHost
dhcpHWAddress: ethernet 00:00:00:00:00:00
dhcpStatements: fixed-address hostname
There is less flexiblity in the way LDAP searches are done here. The object classes need to have fixed names, and the configuration need to be stored in a fairly specific LDAP structure. On the positive side, the invidiual dhcpHost entires can be anywhere without the DN pointed to by the dhcpServer entries. The latter should make it possible to group all host entries in a subtree next to the configuration entries, and this subtree can also be shared with the DNS server if the schema proposed above is combined with the dhcpHost structural object class. Conclusion The PowerDNS implementation seem to be very flexible when it come to which LDAP schemas to use. While its "tree" mode is rigid when it come to the the LDAP structure, the "strict" mode is very flexible, allowing DNS objects to be stored anywhere under the base cn specified in the configuration. The DHCP implementation on the other hand is very inflexible, both regarding which LDAP schemas to use and which LDAP structure to use. I guess one could implement ones own schema, as long as the objectclasses and attributes have the names used, but this do not really help when the DHCP subtree need to have a fairly fixed structure. Based on the observed behaviour, I suspect a LDAP structure like this might work for Debian Edu:
ou=services
  cn=machine-info (dhcpService) - dhcpServiceDN points here
    cn=dhcp (dhcpServer)
    cn=dhcp-internal (dhcpSharedNetwork/dhcpOptions)
      cn=10.0.2.0 (dhcpSubnet)
        cn=group1 (dhcpGroup/dhcpOptions)
    cn=dhcp-thinclients (dhcpSharedNetwork/dhcpOptions)
      cn=192.168.0.0 (dhcpSubnet)
        cn=group1 (dhcpGroup/dhcpOptions)
    ou=machines - PowerDNS base points here
      cn=hostname (dhcpHost/domainrelatedobject/dnsDomainAux)
This is not tested yet. If the DHCP server require the dhcpHost entries to be in the dhcpGroup subtrees, the entries can be stored there instead of a common machines subtree, and the PowerDNS base would have to be moved one level up to the machine-info subtree. The combined object under the machines subtree would look something like this:
dn: dc=hostname,ou=machines,cn=machine-info,dc=skole,dc=skolelinux,dc=no
dc: hostname
objectClass: top
objectClass: dhcpHost
objectclass: domainrelatedobject
objectclass: dnsDomainAux
associateddomain: hostname.intern
arecord: 10.11.12.13
dhcpHWAddress: ethernet 00:00:00:00:00:00
dhcpStatements: fixed-address hostname.intern
One could even add the LTSP configuration associated with a given machine, as long as the required attributes are available in a auxiliary object class.

Gregory Colpart: Network connection with HTC Hero and Debian

I have an HTC Hero, an Android phone, for one year. But I never tried to share his network connection with my Debian laptop. To prepare my trip to Debconf10, I try it today and I m surprised because it s so easy! 1. Plug your phone on USB
2. Active Share your phone network on phone (in french: Partage du r seau mobile )
3. You see now an usb0 ethernet device:
usb0  Link encap:Ethernet  HWaddr a2:17:af:4f:fa:da
BROADCAST MULTICAST  MTU:1500  Metric:1
RX packets:0 errors:0 dropped:0 overruns:0 frame:0
TX packets:0 errors:0 dropped:0 overruns:0 carrier:0
collisions:0 lg file transmission:1000
RX bytes:0 (0.0 B)  TX bytes:0 (0.0 B)
4. Configure usb0 to have the network configuration 192.168.100.100/24 with your favorite tool (ifconfig for example).
5. Now you can ping your phone with 192.168.100.254. Use it as gateway and enjoy: your laptop is now connected with Wi-Fi, GPRS or 3G+! Note: I use HTC Hero with Android 1.5 (build number: 2.73.61.5) and the french mobile phone provider Orange.

16 July 2010

Gustavo Noronha Silva: WebKitGTK+ 1.2.2 and 1.2.3 released!

Some of you may have noticed WebKitGTK+ 1.2.2 and 1.2.3 have been uploaded recently. Here s their announcement =). A quick summary: if you re running the 1.2.x series upgrade to 1.2.3. Here s some information regarding 1.2.2: 1.2.2 is an update to the 1.2.x stable series; along with a lot of crash, and misc fixes the biggest changes are: 1) the inclusion of a new API from the development branch (webkit_back_forward_list_clear()),
because it s simple and will help with fixing a problem in Epiphany stable, and 2) lots of drag and drop, and clipboard related work by Martin Robinson. Despite not being strictly fixes, we believe the stable series has a lot to gain from this work; a couple examples should illustrate this better: the changes included fix both a crash when dragging links from WebKit into other browsers, and the annoying bug that made the cursor get stuck in a grab when dragging, sometimes.
http://webkitgtk.org/webkit-1.2.2.tar.gz
MD5: 40338001324a38b977c163291e8816d3
Here s some information regarding 1.2.3: To some such a quick succession in releases may look like a brown paper bag was in order. Not strictly, but indeed 1.2.3 aims to fix some oversights with easy fixes. First of all, WebKit was not buildable with ICU 4.4.1, but thankfully a fix had already been checked in to trunk, so 1.2.3 includes that fix. Secondly, Debian s Michael Gilbert has done a great job going through all CVEs released about WebKit, and including patches in the Debian package. 1.2.3 includes all of the commits from trunk to fix those, too.
http://webkitgtk.org/webkit-1.2.3.tar.gz
MD5: 0ab5c478a6f5b74a1ae96bf13a456662
You can read some more details, including the list of CVEs that were addressed, in the NEWS file:
http://gitorious.org/webkitgtk/stable/blobs/master/WebKit/gtk/NEWS
Enjoy!

15 July 2010

Raphaël Hertzog: Social Micropayment Can Foster Free Software, Discover Flattr

Social Micropayment Flattr LogoA social micropayment system allows you to donate a small amount of money (a few pennies/cents) to thank someone else for a good blog post, piece of music, or for a free software that you enjoy. That s what Flattr is all about. How Flattr works With Flattr, donating is as easy as a single click on a Flattr button that content providers (read free software developers ) embed on their websites. A Flattr button is very similar to a Digg button or other social buttons (you can look at the end of this blog post for a sample). The amount donated per flattr varies from month to month because you define a fixed amount of money to spend each month (minimum 2 ) and it s split evenly between all the things that you appreciated. You can flattr as much as you want, it won t cost you more. Support Free Software with Flattr Free Software lacks a good business model to fund the creation of software, yet someone has to pay the time spent in writing the code. Many projects have tried to ask for donations but the amount collected rarely covers more than the expenses for the website hosting. Flattr makes it so easy to donate that this is possibly about to change. Flattr users have to spend their monthly amount each month, otherwise it gets donated to charity. Thus if it takes off, most Flattr users will grow the habit of doing regular donations to projects that they use and appreciate. Bootstrapping the Process Flattr FLOSS LogoFlattr is a new service, not many projects are using it to accept donations and not many users are participating yet. But it s growing quickly on both sides. In order to help users who want to support Free Software with Flattr, I have started the Flattr Free and Open Source Software project. You can subscribe to a newsletter to receive a monthly reminder with recommendations of Free Software to Flattr. If you have more time, you can also browse public directories listing various Free Software projects using Flattr so that you can manually pick your favorites. To learn more about the Flattr FOSS project, click here. I also invite Free Software developers to setup Flattr on their websites, blogs, and to register those sites so that Flattr users can easily find them. To learn more about this, check out the Earn a Living With Free Software page. Share the News Flattr can change the situation of many small but popular free software projects struggling with a single developer who started it as a hobby and who can t afford to spend more free time on it. But this can only happen if lots of users start using Flattr to support the Free Software that they benefit from. So share the news, tell the friends, join Flattr FOSS and give some Flattr-love every month. Get Your Free Flattr Invite! Flattr is still in beta, but they like Free Software a lot and have offered 30 invites for the launch of Flattr FOSS. You can get yours by subscribing either to my main newsletter or to the Flattr FOSS one. Just reply to the welcome email you get after having subscribed and ask for your invite. Flattr this Share/Bookmark No comment Support my work
Uwe Hermann: Using the HP Pavilion dv7-3127eg laptop with Debian GNU/Linux

HP Pavilion dv7-3127eg Yep, so I bought a new laptop recently, my IBM/Lenovo Thinkpad T40p was slowly getting really unbearably sloooow (Celeron 1.5 GHz, 2 GB RAM max). After comparing some models I set out to buy a certain laptop in a local store, which they didn't have in stock, so I spontaneously got another model, the HP Pavilion dv7-3127eg (HP product number VY554EA). Why this one? Well, the killer feature for me was that it has two SATA disks, hence allows me to run a RAID-1 in my laptop. This allows me to sleep better at night, knowing that the next dying disk will not necessarily lead to data loss (yes, I do still perform regular backups, of course). Other pros: Much faster than the old notebook, this one is an AMD Turion II Dual-Core Mobile M520 at 2.3 GHz per core, it has 4 GB RAM (8 GB max), and uses an AMD RS780 / SB700 chipset which is supported by the Free-Software / Open-Source BIOS / firmware project coreboot, so this might make the laptop a good coreboot-target on the long run. I'll probably start working on that when I'm willing to open / dissect it or when the warranty expires, whichever happens first. Anyway, I set up a page at randomprojects.org which contains lots more details about using Linux on this laptop:
http://randomprojects.org/wiki/HP_Pavilion_dv7-3127eg
Most of the hardware is supported out of the box, though I haven't yet tested everything. There may be issues with suspend-to-disk / suspend-to-RAM, sometimes it seems to hang (may be just a simple config change is needed in /etc/hibernate/disk.cfg). Cons: Pretty big and heavy (but that's OK, I use it mostly as "semi-mobile desktop replacement"), glossy screen, loud fans (probably due to the two disks). For reference, here's an lspci of the box:
  $ lspci -tvnn
  -[0000:00]-+-00.0  Advanced Micro Devices [AMD] RS780 Host Bridge Alternate [1022:9601]
           +-02.0-[01]--+-00.0  ATI Technologies Inc M96 [Mobility Radeon HD 4650] [1002:9480]
                        \-00.1  ATI Technologies Inc RV710/730 [1002:aa38]
           +-04.0-[02-07]--
           +-05.0-[08]----00.0  Atheros Communications Inc. AR9285 Wireless Network Adapter (PCI-Express) [168c:002b]
           +-06.0-[09]----00.0  Realtek Semiconductor Co., Ltd. RTL8111/8168B PCI Express Gigabit Ethernet controller [10ec:8168]
           +-0a.0-[0a]--
           +-11.0  ATI Technologies Inc SB700/SB800 SATA Controller [AHCI mode] [1002:4391]
           +-12.0  ATI Technologies Inc SB700/SB800 USB OHCI0 Controller [1002:4397]
           +-12.1  ATI Technologies Inc SB700 USB OHCI1 Controller [1002:4398]
           +-12.2  ATI Technologies Inc SB700/SB800 USB EHCI Controller [1002:4396]
           +-13.0  ATI Technologies Inc SB700/SB800 USB OHCI0 Controller [1002:4397]
           +-13.1  ATI Technologies Inc SB700 USB OHCI1 Controller [1002:4398]
           +-13.2  ATI Technologies Inc SB700/SB800 USB EHCI Controller [1002:4396]
           +-14.0  ATI Technologies Inc SBx00 SMBus Controller [1002:4385]
           +-14.2  ATI Technologies Inc SBx00 Azalia (Intel HDA) [1002:4383]
           +-14.3  ATI Technologies Inc SB700/SB800 LPC host controller [1002:439d]
           +-14.4-[0b]--
           +-18.0  Advanced Micro Devices [AMD] K10 [Opteron, Athlon64, Sempron] HyperTransport Configuration [1022:1200]
           +-18.1  Advanced Micro Devices [AMD] K10 [Opteron, Athlon64, Sempron] Address Map [1022:1201]
           +-18.2  Advanced Micro Devices [AMD] K10 [Opteron, Athlon64, Sempron] DRAM Controller [1022:1202]
           +-18.3  Advanced Micro Devices [AMD] K10 [Opteron, Athlon64, Sempron] Miscellaneous Control [1022:1203]
           \-18.4  Advanced Micro Devices [AMD] K10 [Opteron, Athlon64, Sempron] Link Control [1022:1204]
Full lspci -vvvxxxxnnn, lsusb -vvv, and a much more detailed list of tested hardware components is available in the wiki.

14 July 2010

Mike Hommey: I/O patterns on ELF binary initialization

[ I meant to finish this article much earlier, but i had to leave it in a half-written draft state for quite some time due to other activities ] One particular issue that arises with big binary files is that of I/O patterns. It looks like it is not something under the usual scope for both ld.so and programs/libraries, but it can have a dramatic influence on startup times. My analysis is far from complete, would need to be improved by actually investigating ld.so code further, and so far has been limited to libxul.so built from mozilla-central, with the help of icegrind, on x86-64 linux. As I wrote recently, icegrind allows to track memory accesses within mmap()ed memory ranges. As ld.so does mmap() the program and library binaries, tracking the memory accesses within these mmap()s allows to get a better idea at I/O patterns when an ELF binary is initialized. I only focused on local accesses within a single given binary file (libxul.so) because the case of Firefox loading many files at startup is already being scrutinized, and because most of the non-Firefox files being read at Firefox startup (system and GNOME libraries) are most likely already in the page cache. I also focused on that because it was an interesting case that could be helpful to understand how big (and maybe less big) binaries may be affected by the toolchain (compiler, linker and dynamic linker) and possibly by some coding practices. For the record, what I did to get these results is to use icegrind and elflog, with further additions to the sections file with some output from objdump -h : I added sections that elflog wouldn t give (such as .plt, .hash, .dynsym, etc.), and even down to the entry level for the .rela.dyn section. The latter is particularly interesting because icegrind only outputs the first access for any given section. To see sequential accesses within that section, you need to split it in smaller pieces, which I did for .rela.dyn entries (each one being 24 bytes on x86-64). Uncommenting some parts of the icegrind code was also useful to track where some accesses were made from, code-wise. Now, the interesting data: One of the first accesses is a nullification of a few variables within the .bss section. The .bss section is usually an anonymous piece of memory, that is, a range of mmap()ed memory that is not backed by a file, and filled with zeroes by the kernel (I think it even does that lazily). It is used for e.g. variables that are initialized with zeroes in the code, and obviously, any code accessing these variables would be addressing at some offset of the .bss section. It means the section needs to start in memory at the offset it has been assigned by the linker at build time. This is actually where problems begin. When the .bss section offset as assigned by the linker doesn t align on a page (usually 4KB), the mmap()ed .bss can t be at that location, and really starts on the next page. The remainder is still mmap()ed from the binary file, and ld.so will itself fill that part. As the .bss section doesn t start on a page boundary, any write at this location will trigger the kernel reading the entire page. This means one of the first set of data being read from the file is the end of the section preceding .bss, and the beginning of the following one. Most likely, respectively the .data and .comment sections. While this probably doesn t matter much when the binary file is small, when it is big enough, reading in a non sequential manner will trigger hard disk seeks, and we all know how they can hurt performance. Although thankfully, cheap SSDs should be coming some day, in the meanwhile, we still need to cope with the bad performance. The interesting part is, the .bss section is really empty in the binary file, so its virtual memory address could be anywhere. Why the linker wouldn t align it at a page boundary without having to resort to a linker script is beyond me. The next accesses go back and forth between .dynamic, .gnu.hash, .dynstr, .gnu.version_r, .gnu.version and .dynsym. These are probably all related to symbol version resolution and DT_NEEDED library loading. While most of these sections are at the beginning of the file (not necessarily in the order they are read from), the .dynamic section is much nearer to the end, but way before .data, so that it won t even have been loaded as a by-product of the .bss section loading. After that, the .rela.dyn section is read, and for each relocation entry it contains, the relocations are being applied. Relocations is one of the mechanisms by which position independent code (PIC) is made possible. When a library is loaded in memory, it is not necessarily loaded at the same address every time. The code and data contained in the library thus need to cope with that constraint. Fortunately, while the base address where the library is mmap()ed in memory is not necessary constant, the offsets of the various sections are still as codified in the binary. The library code can thus directly access data at the right offset if it knows the base offset of the library (which is what is done on the x86 ABI), or if it knows where the current instruction is located (which is what is done on the x86-64 ABI). Static data (initialized in e.g. a const or a global variable, or, in C++ case, vtables), on the other hand, may contain pointers to other locations. This is where relocation enters the scene. The .rela.dyn section contains a set of rules describing where in the binary some pointers need to be adjusted depending on the base library offset (or some other information), and how they should be updated. ld.so thus reads all .rela.dyn entries, and applies each relocation, which means that while .rela.dyn is being read sequentially, reads and writes are also performed at various places of the binary, depending on the content of the .rela.dyn entries. This is where this gets ugly for Firefox: there are near 200000 such relocations. On x86-64 an entry is 24 bytes (12 on x86), and each of these is going to read/write a pointer (8 bytes on x86-64, 4 on x86) at some random (though mostly ordered) location. The whole .rela.dyn section not being read ahead, what actually happens is that it is read in small batches, with seeks and reads of other data at various locations in between. In libxul.so case, this spreads over .ctors, .data.rel.ro, .got, and .data. The relocation entries are somehow ordered by address to be rewritten, though they occasionally jump backwards. Some of these relocations also appear to be touching to .gnu.version, .dynsym and .dynstr, because their type involves a symbol resolution. Once .rela.dyn relocation have been dealt with comes .rela.plt s turn. The principle is the same for this section: entries describe what kind of relocation must be done where, and how the result must be calculated. The scope of this section, though, is apparently limited to .got.plt. But before explaining these relocations, I ll explain what happens with the PLT. The PLT (Procedure Linkage Table) is used when calling functions from external libraries. For example, in a Hello World example, the PLT would be used for calls to the puts function. The function making the call would in fact call the corresponding PLT location. The PLT itself, on x86 and x86-64, at least, consists of 3 instructions (I ll skip the gory details, especially for x86, where the caller needs to also set some register before calling the PLT). The first instruction is the only one to be called most of the time: it reads the final destination in the .got.plt section, and jumps there. That final destination, obviously, is not fixed in the library file, since it needs to be resolved by its symbol. This is why the two subsequent instructions exist : originally, the destination stored in the .got.plt section points back to the second instruction ; the first instruction will effectively be a nop (no operation), and the following instructions will be executed. They will jump into code responsible for symbol resolution, update of the .got.plt entry for the next call, and call of the real function. But pointing back to the second instruction is like the pointers in static data we saw above : it s not possible in position independent code. So, the .rela.plt relocations are actually filling the .got.plt section with these pointers back to the PLT. There are a tad more than 3000 such relocations. All these relocations should be going away when prelinking the binaries, but from my several experimentations, it looks like prelinking only avoids relative relocations, and not the others, while it technically could skip all of them. prelink even properly applies all the relocations in the binary, but executing the binary rewrites the same information at startup for all but relative relocations. That could well be a bug in either ld.so not skipping enough relocations or prelink not marking enough relocations to be skipped. I haven t dug deep enough in the code to know how prelinking works exactly. Anyways, prelinking is not a perfect solution, as it also breaks ASLR. Sure, prelink can randomize library locations, but it relies on the user or a cron job doing so at arbitrary times, but that s far from satisfying. An interesting thing to note, though, is that a good part of the relocations prelinking doesn t rid us of in libxul.so (more than 25000) are due to the __cxa_pure_virtual symbol, which is used for, well, pure virtual methods. In other words, virtual methods that don t have an implementation in a given class. The __cxa_pure_virtual function is set as method in the corresponding field(s) of the class VTABLE in the .data.rel.ro section. This function is provided by libstdc++, and as such, is dynamically linked. But this function is just a dummy function, doing nothing. Defining an empty __cxa_pure_virtual function to be included in libxul.so makes these relocations become relative, thus taken care of by prelinking. After all relocations occur, the library initialization itself can begin, and the content of the .init section is executed. That section, indirectly, executes all functions stored in the .ctors section. This includes static initializers, which are unfortunately called backwards, as Taras pointed out already. Each of these static initializers are also accessing various locations in the .data or .bss sections, which may or may not have already been loaded during the relocation phase. The execution of these initializers will also (obviously) read various pieces of the .text section (despite its name, it contains executable sections, i.e. functions code). The initialization of the library ends there, and no access should happen until a function from the library is called. In libxul.so case, XRE_main is first called, then many other functions, but that s another story. All that needs to be remembered about the startup process past this point is that the .text section will be read heavily, as well as the various data, got, plt and dynamic symbol sections, in a very scattered way. While most of these sections may have been retrieved in memory already, as a byproduct of the various initialization processes described above, some may have not, increasing even more the need to seek at all places in the binary file. Now the main problem with all these I/O patterns at startup, is that it seems the only way reorganizing the binary layout may have a visible impact is by considering all the above, and not only a part of it, because only addressing a part of it is very likely to only move part of the problem to a different layer. All in all, making sure the relevant sections of libxul.so are read by the kernel before ld.so enters the game is a good short-term solution to avoid many seeks at startup.

13 July 2010

DebConf team: Debian Day at DebConf10 (Posted by Michael Schultheiss)

Debian Day will take place on the first day of DebConf10, Sunday, August 1, 2010 from 10:00 AM to 6:40 PM at Columbia University, New York City, New York. We would love to see you join us at Debian Day. Registration is required but is free. If you are not already registered for DebConf10, please send an e-mail with your intent to attend to debianday@debconf.org. Debian Day and DebConf10 are going to be great. We re looking forward to seeing you in New York on August 1! More information on Debian Day is available at DebianDay.org. the DebConf team

12 July 2010

Thorsten Glaser: On ASLR (Address Space Layout Randomisation)

I ve got some interesting results using r1.1 of an example test programme (r1.2 got cleaned up and more output) on various systems, regarding ASLR. The 1.1 revision tests everything mksh R40+ will use (except there will probably no larger than page sized allocations) for its LCG PRNG. On OpenBSD (MirBSD, rieBSD) malloc(3) uses in fact mmap(2), which is randomised. (Though -pie doesn t yet work as it s supposed to.) Some OSes are better than others but look for yourself. (Read on to continue, not part of the RSS for size reasons. This wlog entry may be updated with bumped date unperiodically.)

Andreas Schuldei: Spotify on Linux

After several years of only having Windows and Mac clients, we at Spotify are really excited to release a qt-based Linux desktop client. The port was quite smooth after all the work we ve done for other platforms that we ve developed (iPhone, Android, several set-top boxes with Linux, Symbian, etc).

Being the Debian shop we are, we packaged it right away and are now happy to provide the client as a deb. It is regularly auto-built and tested by all our developers working on debian (and even ubuntu) whenever they want to listen to one or more of our 8*10^6 tracks. (One lonely fedora college prepared a rpm, too! Its not up yet, though.)

Add this to your sources.list files and aptitude install spotify-client-qt to check it out:

deb http://repository.spotify.com stable non-free

There is some additional infrastructure in the package spotify-client-gnome-support (same repository) so that you can click on links to open tracks, interact with Facebook and other, useful websites etc.

As we haven t found a reliable way to display ads yet, this version is only available to Spotify Premium subscribers.

Additional information about the archive key etc can be found here: http://www.spotify.com/se/download/previews/.

Russell Coker: Tracking down Write/Execute mmap() calls with LD_PRELOAD

One of the access controls in SE Linux is for execmem which is used to stop processes from creating memory regions that are writable and executable (as they make it easier to compromise programs and get them to execute supplied code). When the SE Linux audit log tells you that a program is attempting such access it s sometimes difficult to discover where in the code such an access occurs, for example if you have a large code base and mmap() is called in many places it can be difficult to determine which one is the culprit. Especially if you have a source package that contains multiple binaries that use a common shared library and you don t know which bits of library code are called by each executable. To solve this problem in the case of freshclam to provide extra information for Debian bug report #588599 [1] I wrote the following little shared object which can be compiled with gcc -shared -g -fPIC mmap.c -o mmap.so and used with LD_PRELOAD=./mmap.so whatever . Then when the program in question (or any non-SUID program it executes) calls mmap() with both PROT_EXEC and PROT_WRITE set the program will abort. If you run this through gdb then the program will break and you will get a back-trace of the function calls that led to the undesired mmap(). One thing to note is that this method only catches direct calls to a library function outside libc. When the libc code calls the library function (EG all the fwrite() etc code that calls mmap()) the LD_PRELOAD hack won t catch it. Thanks to Keith Owens for pointing this out. #include <dlfcn.h>
#include <stdio.h>
#include <sys/mman.h>
#include <stdlib.h>
#undef NDEBUG
#include <assert.h> void *libc6 = NULL; void *(*real_mmap)(void *, size_t, int, int, int, off_t); void do_init()

libc6 = dlopen("libc.so.6", RTLD_LAZY RTLD_GLOBAL);
if(!libc6)

printf("Aieee\n");
exit(1);

real_mmap = (void * (*)(void *, size_t, int, int, int, off_t))dlsym(libc6, "mmap");
void *mmap(void *addr, size_t length, int prot, int flags, int fd, off_t offset)

if(!real_mmap)
do_init();
assert(!(prot & PROT_EXEC) !(prot & PROT_WRITE));
return real_mmap(addr, length, prot, flags, fd, offset);

Next.

Previous.
