Search Results: "will"

24 September 2014

Russell Coker: Cheap 3G Data in Australia

The Request I was asked for advice about cheap 3G data plans. One of the people who asked me has a friend with no home Internet access, the friend wants access but doesn t want to pay too much. I don t know whether the person in question can t use ADSL/Cable (maybe they are about to move house) or whether they just don t want to pay for it. 3G data in urban areas in Australia is fast enough for most Internet use. But it s not good for online games or VOIP. It s also not very useful for Youtube and other online video. There is a variety of 3G speed testing apps for Android phones and there are presumably similar apps for the iPhone. Before signing up for 3G at home it s probably best to get a friend who s on the network in question to test Internet speed at your house, it would be annoying to sign up for an annual contract and then discover that your home is in a 3G dead spot. Cheapest Offers The best offer at the moment for moderate data use seems to be Amaysim with 10G for $99.90 and an expiry time of 365 days [1]. 10G in a year isn t a lot, but it s pre-paid so the user can buy another 10G of data whenever they want. At the moment $10 for 1G of data in a month and $20 for 2G of data in a month seem to be common offerings for 3G data in Australia. If you use exactly 1G per month then Amaysim isn t any better than a number of other telcos, but if your usage varies (as it does with most people) then spreading the data use over several months offers significant savings without the need to save big downloads for the last day of the month. For more serious Internet use Virgin has pre-paid offerings of 6G for $30 and 12G for $40 which has to be used in a month [2]. Anyone who uses an average of more than 3G per month will get better value from the Virgin offers. If anyone knows of cheaper options than Amaysim and Virgin then please let me know. Better Coverage Both Amaysim and Virgin use the Optus network which covers urban areas quite well. I used Virgin a few years ago (and presume that it has only improved since then) and my wife uses Amaysim now. I haven t had any great problems with either telco. If you need better coverage than the Optus network provides then Telstra is the only option. Telstra have a number of prepaid offers, the most interesting is $100 for 10G of data that expires in 90 days [3]. That Telstra offer is the same price as the Amaysim offer and only slightly more expensive than Virgin if you average 3.3G per month. It s a really good deal if you average 3.3G per month as you can expect it to be faster and have better coverage. Which One to Choose? I think that the best option for someone who is initially connecting their home via 3g is to start with Amaysim. Amaysim is the cheapest for small usage and they have an Amaysim Android app and web page for tracking usage. After using a few gig of data on Amaysim it should be possible to determine which plan is going to be most economical in the long term. Connecting to the Internet To get the best speed you need a 4G AKA LTE connection. But given that 3G speed is great enough to use expensive amounts of data it doesn t seem necessary to me. I ve done a lot of work over the Internet with 3G from Virgin, Kogan, Aldi, and Telechoice and haven t felt a need to pay for anything faster. I think that the best thing to do is to use an old phone running Android 2.3 or iOS 4.3 as a Wifi access point. The cost of a dedicated 3G Wifi AP is enough to significantly change the economics of such Internet access and most people have access to old smart phones.

Matthew Garrett: My free software will respect users or it will be bullshit

I had dinner with a friend this evening and ended up discussing the FSF's four freedoms. The fundamental premise of the discussion was that the freedoms guaranteed by free software are largely academic unless you fall into one of two categories - someone who is sufficiently skilled in the arts of software development to examine and modify software to meet their own needs, or someone who is sufficiently privileged[1] to be able to encourage developers to modify the software to meet their needs.

The problem is that most people don't fall into either of these categories, and so the benefits of free software are often largely theoretical to them. Concentrating on philosophical freedoms without considering whether these freedoms provide meaningful benefits to most users risks these freedoms being perceived as abstract ideals, divorced from the real world - nice to have, but fundamentally not important. How can we tie these freedoms to issues that affect users on a daily basis?

In the past the answer would probably have been along the lines of "Free software inherently respects users", but reality has pretty clearly disproven that. Unity is free software that is fundamentally designed to tie the user into services that provide financial benefit to Canonical, with user privacy as a secondary concern. Despite Android largely being free software, many users are left with phones that no longer receive security updates[2]. Textsecure is free software but the author requests that builds not be uploaded to third party app stores because there's no meaningful way for users to verify that the code has not been modified - and there's a direct incentive for hostile actors to modify the software in order to circumvent the security of messages sent via it.

We're left in an awkward situation. Free software is fundamental to providing user privacy. The ability for third parties to continue providing security updates is vital for ensuring user safety. But in the real world, we are failing to make this argument - the freedoms we provide are largely theoretical for most users. The nominal security and privacy benefits we provide frequently don't make it to the real world. If users do wish to take advantage of the four freedoms, they frequently do so at a potential cost of security and privacy. Our focus on the four freedoms may be coming at a cost to the pragmatic freedoms that our users desire - the freedom to be free of surveillance (be that government or corporate), the freedom to receive security updates without having to purchase new hardware on a regular basis, the freedom to choose to run free software without having to give up basic safety features.

That's why projects like the GNOME safety and privacy team are so important. This is an example of tying the four freedoms to real-world user benefits, demonstrating that free software can be written and managed in such a way that it actually makes life better for the average user. Designing code so that users are fundamentally in control of any privacy tradeoffs they make is critical to empowering users to make informed decisions. Committing to meaningful audits of all network transmissions to ensure they don't leak personal data is vital in demonstrating that developers fundamentally respect the rights of those users. Working on designing security measures that make it difficult for a user to be tricked into handing over access to private data is going to be a necessary precaution against hostile actors, and getting it wrong is going to ruin lives.

The four freedoms are only meaningful if they result in real-world benefits to the entire population, not a privileged minority. If your approach to releasing free software is merely to ensure that it has an approved license and throw it over the wall, you're doing it wrong. We need to design software from the ground up in such a way that those freedoms provide immediate and real benefits to our users. Anything else is a failure.

(title courtesy of My Feminism will be Intersectional or it will be Bullshit by Flavia Dzodan. While I'm less angry, I'm solidly convinced that free software that does nothing to respect or empower users is an absolute waste of time)

[1] Either in the sense of having enough money that you can simply pay, having enough background in the field that you can file meaningful bug reports or having enough followers on Twitter that simply complaining about something results in people fixing it for you

[2] The free software nature of Android often makes it possible for users to receive security updates from a third party, but this is not always the case. Free software makes this kind of support more likely, but it is in no way guaranteed.

comment count unavailable comments

Robert Collins: what-poles-for-the-tent

So Monty and Sean have recently blogged about about the structures (1, 2) they think may work better for OpenStack. I like the thrust of their thinking but had some mumblings of my own to add. Firstly, I very much like the focus on social structure and needs what our users and deployers need from us. That seems entirely right. And I very much like the getting away from TC picking winners and losers. That was never an enjoyable thing when I was on the TC, and I don t think it has made OpenStack better. However, the thing that picking winners and losers did was that it allowed users to pick an API and depend on it. Because it was the X API for OpenStack . If we don t pick winners, then there is no way to say that something is the X API for OpenStack , and that means that there is no forcing function for consistency between different deployer clouds. And so this appears to be why Ring 0 is needed: we think our users want consistency in being able to deploy their application to Rackspace or HP Helion. They want vendor neutrality, and by giving up winners-and-losers we give up vendor neutrality for our users. Thats the only explanation I can come up with for needing a Ring 0 because its still winners and losers (e.g. picking an arbitrary project) keystone, grandfathering it in, if you will. If we really want to get out of the role of selecting projects, I think we need to avoid this. And we need to avoid it without losing vendor neutrality (or we need to give up the idea of vendor neutrality). One might say that we must pick winners for the very core just by its, but I don t think thats true. If the core is small, many people will still want vendor neutrality higher up the stack. If the core is large, then we ll have a larger % of APIs covered and stable granting vendor neutrality. So a core with fixed APIs will be under constant pressure to expand: not just from developers of projects, but from users that want API X to be fixed and guaranteed available and working a particular way at [most] OpenStack clouds. Ring 0 also fulfils a quality aspect we can check that it all works together well in a realistic timeframe with our existing tooling. We are essentially proposing to pick functionality that we guarantee to users; and an API for that which they have everywhere, and the matching implementation we ve tested. To pull from Monty s post: What does a basic end user need to get a compute resource that works and seems like a computer? (end user facet) What does Nova need to count on existing so that it can provide that. He then goes on to list a bunch of things, but most of them are not needed for that: We need Nova (its the only compute API in the project today). We don t need keystone (Nova can run in noauth mode and deployers could just have e.g. Apache auth on top). We don t need Neutron (Nova can do that itself). We don t need cinder (use local volumes). We need Glance. We don t need Designate. We don t need a tonne of stuff that Nova has in it (e.g. quotas) end users kicking off a simple machine have -very- basic needs. Consider the things that used to be in Nova: Deploying containers. Neutron. Cinder. Glance. Ironic. We ve been slowly decomposing Nova (yay!!!) and if we keep doing so we can imagine getting to a point where there truly is a tightly focused code base that just does one thing well. I worry that we won t get there unless we can ensure there is no pressure to be inside Nova to win . So there s a choice between a relatively large set of APIs that make the guaranteed available APIs be comprehensive, or a small set that that will give users what they need just at the beginning but might not be broadly available and we ll be depending on some unspecified process for the deployers to agree and consolidate around what ones they make available consistently. In sort one of the big reasons we were picking winners and losers in the TC was to consolidate effort around a single API not implementation (keystone is already on its second implementation). All the angst about defcore and compatibility testing is going to be multiplied when there is lots of ecosystem choice around APIs above Ring 0, and the only reason that won t be a problem for Ring 0 is that we ll still be picking winners. How might we do this? One way would be to keep picking winners at the API definition level but not the implementation level, and make the competition be able to replace something entirely if they implement the existing API [and win hearts and minds of deployers]. That would open the door to everything being flexible and its happened before with Keystone. Another way would be to not even have a Ring 0. Instead have a project/program that is aimed at delivering the reference API feature-set built out of a single, flat Big Tent and allow that project/program to make localised decisions about what components to use (or not). Testing that all those things work together is not much different than the current approach, but we d have separated out as a single cohesive entity the building of a product (Ring 0 is clearly a product) from the projects that might go into it. Projects that have unstable APIs would clearly be rejected by this team; projects with stable APIs would be considered etc. This team wouldn t be the TC : they too would be subject to the TC s rulings. We could even run multiple such teams as hinted at by Dean Troyer one of the email thread posts. Running with that I d then be suggesting So OpenStack/NaaS would have an API or set of APIs, and they d be responsible for considering maturity, feature set, and so on, but wouldn t own Neutron, or Neutron incubator or any other component they would be a *cross project* team, focused at the product layer, rather than the component layer, which nearly all of our folk end up locked into today. Lastly Sean has also pointed out that we have large N N^2 communication issues I think I m proposing to drive the scope of any one project down to a minimum, which gives us more N, but shrinks the size within any project, so folk don t burn out as easily, *and* so that it is easier to predict the impact of changes clear contracts and APIs help a huge amount there.

Russ Allbery: Review: 2014 Hugos: Short Story Nominees

Review: 2014 Hugos: Short Story Nominees, edited by Loncon 3
Publisher: Loncon 3
Copyright: 2014
Format: Kindle
This is a bit of a weird "book review," since this is not a book. Rather, it's the collection of Hugo-nominated short stories for the 2014 Hugos (given for works published in 2013) at Loncon 3, the 2014 Worldcon. As such, the "editor" is the pool of attendees and supporting members who chose to nominate works, all of which had been previously edited by other editors in their original publication. This is also not something that someone else can acquire; if you were not a supporting or attending member, you didn't get the voting packet. But I believe all of the stories here are available on-line for free in some form, a short search away. "If You Were a Dinosaur, My Love" by Rachel Swirsky: The most common complaint about this story is that it's not really a story, and I have to agree. It's a word image of an alternate world in which the narrator's love is a human-sized dinosaur, starting with some surreal humor and then slowly shifting tone as it reveals the horrible event that's happened to the narrator's actual love, and that's sparked the wish for her love to have claws and teeth. It's reasonably good at what it's trying to do, but I wanted more of a story. The narrator's imagination didn't do much for me. (5) "The Ink Readers of Doi Saket" by Thomas Olde Heuvelt: At least for me, this story suffered from being put in the context of a Hugo nominee. It's an okay enough story about a Thai village downstream from a ritual that involves floating wishes down the river, often with offerings in the improvised small boats. The background of the story is somewhat cynical: the villagers make some of the wishes come true, sort of, while happily collecting the offerings and trying to spread the idea that the wishes with better offerings are more likely to come true. The protagonist follows a familiar twist: he actually can make wishes come true, maybe, but is very innocent about his role in the world. This is not a bad story, although stories written by people with western-sounding names about non-western customs worry me, and there were a few descriptions and approaches here (such as the nickname translations in footnotes and the villager archetypes) that made my teeth itch. But it is not a story that belongs on the Hugo nomination slate, at least in my opinion. It's either cute or mildly irritating, depending on one's mood when one meets it, not horribly original, and very forgettable. (5) "Selkie Stories Are for Losers" by Sofia Samatar: I really liked this story for much of its length. It features a couple of young, blunt, and bitter women, and focuses on the players in the typical selkie story that don't get much attention. The selkie's story is one of captivity or freedom; her lover's story is the inverse, the captor or the lover. But I don't recall a story about the children before, and I think Samatar got the tone right. It has the bitterness of divorce and abandonment mixed with the disillusionment of fantasy turned into pain. My problem with this story is the ending, or rather, the conclusion, since the story doesn't so much end as stop. There's a closing paragraph that gives some hint of the shape to come, but it gave me almost no closure, and it didn't answer any of the emotional questions that the rest of the story raised for me. I wanted something more, some sort of epiphany or clearer determination. (7) "The Water That Falls on You from Nowhere" by John Chu: This was by far my favorite of the nominees, which is convenient since it won. I thought it was the only nominee that felt in the class of stories I would expect to win a Hugo. I think this story needs one important caveat up front. The key conceit of the story is that, in this world, water falls on you out of nowhere if you tell any sort of lie. It does not explore the practical impact on that concept for the broader world. That didn't bother me; for some reason, I wasn't really expecting it to do so. But it did bother several other people I've seen comment on this story. They were quite frustrated that the idea was used primarily to shape a personal and family emotional dilemma, not to explore the impact on the world. So, go into this with the right expectations: if you want world-building or deep exploration of a change in physical laws, you will want a different story. This story, instead, is a beautiful gem about honesty in relationships, about communication about very hard things and very emotional things, about coming out, about trusting people, and about understanding people. I thought it was beautiful. If you read Captain Awkward, or other discussion of how to deal with difficult families and the damage they cause to relationships, seek this one out. It surprised me, and delighted me, and made me cry in places, and I loved the ending. It's more fantasy than science fiction, and it uses the conceit as a trigger for a story about people instead of a story about worlds and technology, but I'm still very happy to see it win. (9) Rating: 7 out of 10

23 September 2014

Steve Kemp: Waiting for features upstream

I (grudgingly) use the Calibre e-book management software to handle my collection of books, and copy them over to my kindle-toy. One thing that has always bothered me was the fact that when books are imported their ratings are too. If I receive a small sample of ebooks from a friend their ratings are added to my collections. I've always regarded ratings as things personal to me, rather than attributes of a book itself; as my tastes might not match yours, and vice-versa. On that basis the last time I was importing a small number of books and getting annoyed at having to manually reset all the imported ratings I decided to do something about it. I started hacking and put together a simple Calibre plugin to automatically zero ratings when books are imported to the collection (i.e. set the rating to be zero). Sadly this work wasn't painless, despite the small size, as an unfortunate bug in Calibre meant my plugin method wasn't called. Happily Kovid Goyal helped me work through the problem, and he committed a fix that will be in the next Calibre release. For the moment I'm using today's git-snapshot and it works well. Similarly I've recently started using extended file attributes to store metadata on my desktop system. Unfortunately the GNU findutils package doesn't allow you to do the obvious thing:
$ find ~/foo -xattr user.comment
/home/skx/foo/bar/t.txt
/home/skx/foo/bar/xc.txt
/home/skx/foo/bar/x.txt
There are several xattr patches floating around, but I had to bundle my own in debian/patches to get support for finding files that have particular attribute names. Maybe one day extended attributes will be taken seriously. (rsync, cp, etc will preserve them. I'm hazy on the compatibility with tar, but most things seem to be working.)

Keith Packard: easymega-118k

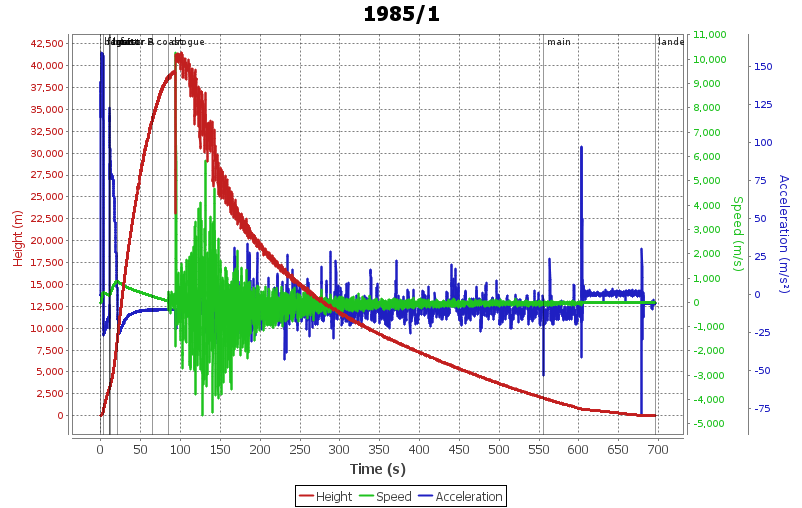
Neil Anderson Flies EasyMega to 118k' At BALLS 23 Altus Metrum would like to congratulate Neil Anderson and Steve Cutonilli on the success the two stage rocket, A Money Pit , which flew on Saturday the 20th of September on an N5800 booster followed by an N1560 sustainer. A Money Pit used two Altus Metrum EasyMega flight computers in the sustainer, each one configured to light the sustainer motor and deploy the drogue and main parachutes. Safely Staged After a 7 Second Coast After the booster burned out, the rocket coasted for 7 seconds to 250m/s, at which point EasyMega was programmed to light the sustainer. As a back-up, a timer was set to light the sustainer 8 seconds after the booster burn-out. In both cases, the sustainer ignition would have been inhibited if the rocket had tilted more than 20 from vertical. During the coast, the rocket flew from 736m to 3151m, with speed going from 422m/s down to 250m/s. This long coast, made safe by EasyMega's quaternion-based tilt sensor, allowed this flight to reach a spectacular altitude. Apogee Determined by Accelerometer Above 100k', the MS5607 barometric sensor is out of range. However, as you can see from the graph, the barometric sensor continued to return useful data. EasyMega doesn't expect that to work, and automatically switched to accelerometer-only apogee determination mode. Because off-vertical flight will under-estimate the time to apogee when using only an accelerometer, the EasyMega boards were programmed to wait for 10 seconds after apogee before deploying the drogue parachute. That turned out to be just about right; the graph shows the barometric data leveling off right as the apogee charges fired. Fast Descent in Thin Air Even with the drogue safely fired at apogee, the descent rate rose to over 200m/s in the rarefied air of the upper atmosphere. With increasing air density, the airframe slowed to 30m/s when the main parachute charge fired at 2000m. The larger main chute slowed the descent further to about 16m/s for landing.
Dirk Eddelbuettel: RcppArmadillo 0.4.450.1.0

Continuing with his standard pace of approximately one new version per month, Conrad released a new minor release of Armadillo a few days ago. As before, I had created a GitHub-only pre-release which was tested against all eighty-seven (!!) CRAN dependents of our RcppArmadillo package and then uploaded RcppArmadillo 0.4.450.0 to CRAN. The CRAN maintainers pointed out that under the R-development release, a NOTE was issued concerning the C-library's rand() call. This is a pretty new NOTE, but it means using the (sometimes poor quality) rand() generator is now a no-no. Now, Armadillo being as robustly engineered as it is offers a new random number generator based on C++11 as well as a fallback generator for those unfortunate enough to live with an older C++98 compiler. (I would like to note here that I find Conrad's continued support for both C++11, offering very useful modern language idioms, as well as the fallback code for continued deployment and usage by those constrained in their choice of compilers rather exemplary --- because contrary to what some people may claim, it is not a matter of one or the other. C++ always was, and continues to be, a multi-paradigm language which can be supported easily by several standard. But I digress...) In any event, one cannot argue with CRAN about their prescription of a C++98 compiler. So Conrad and I discussed this over email, and came up with a scheme where a user-package (such as RcppArmadillo) can provide an alternate generator which Armadillo then deploys. I implemented a first solution which was then altered / reflected by Conrad in a revised version 4.450.1 of Armadillo. I packaged, and now uploaded, that version as RcppArmadillo 0.4.450.1.0 to both CRAN and into Debian. Besides the RNG change already discussed, this release brings a few smaller changes from the Armadillo side. These are detailed below in the extract from the NEWS file. On the RcppArmadillo side, we now have support for pkgKitten which is both very exciting and likely the topic of another blog post with an example of creating an RcppArmadillo package that purrs. In the process, I overhauled and polished how new packages are created by RcppArmadillo.package.skeleton(). An upcoming blog post may provide an example.
Changes in RcppArmadillo version 0.4.450.1.0 (2014-09-21)
  • Upgraded to Armadillo release Version 4.450.1 (Spring Hill Fort)
    • faster handling of matrix transposes within compound expressions
    • expanded symmatu()/symmatl() to optionally disable taking the complex conjugate of elements
    • expanded sort_index() to handle complex vectors
    • expanded the gmm_diag class with functions to generate random samples
  • A new random-number implementation for Armadillo uses the RNG from R as a fallback (when C++11 is not selected so the C++11-based RNG is unavailable) which avoids using the older C++98-based std::rand
  • The RcppArmadillo.package.skeleton() function was updated to only set an "Imports:" for Rcpp, but not RcppArmadillo which (as a template library) needs only LinkingTo:
  • The RcppArmadillo.package.skeleton() function will now prefer pkgKitten::kitten() over package.skeleton() in order to create a working package which passes R CMD check.
  • The pkgKitten package is now a Suggests:
  • A manual page was added to provide documentation for the functions provided by the skeleton package.
  • A small update was made to the package manual page.
Courtesy of CRANberries, there is also a diffstat report for the most recent release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

22 September 2014

Gunnar Wolf: One month later: How is the set of Debian keyrings faring?

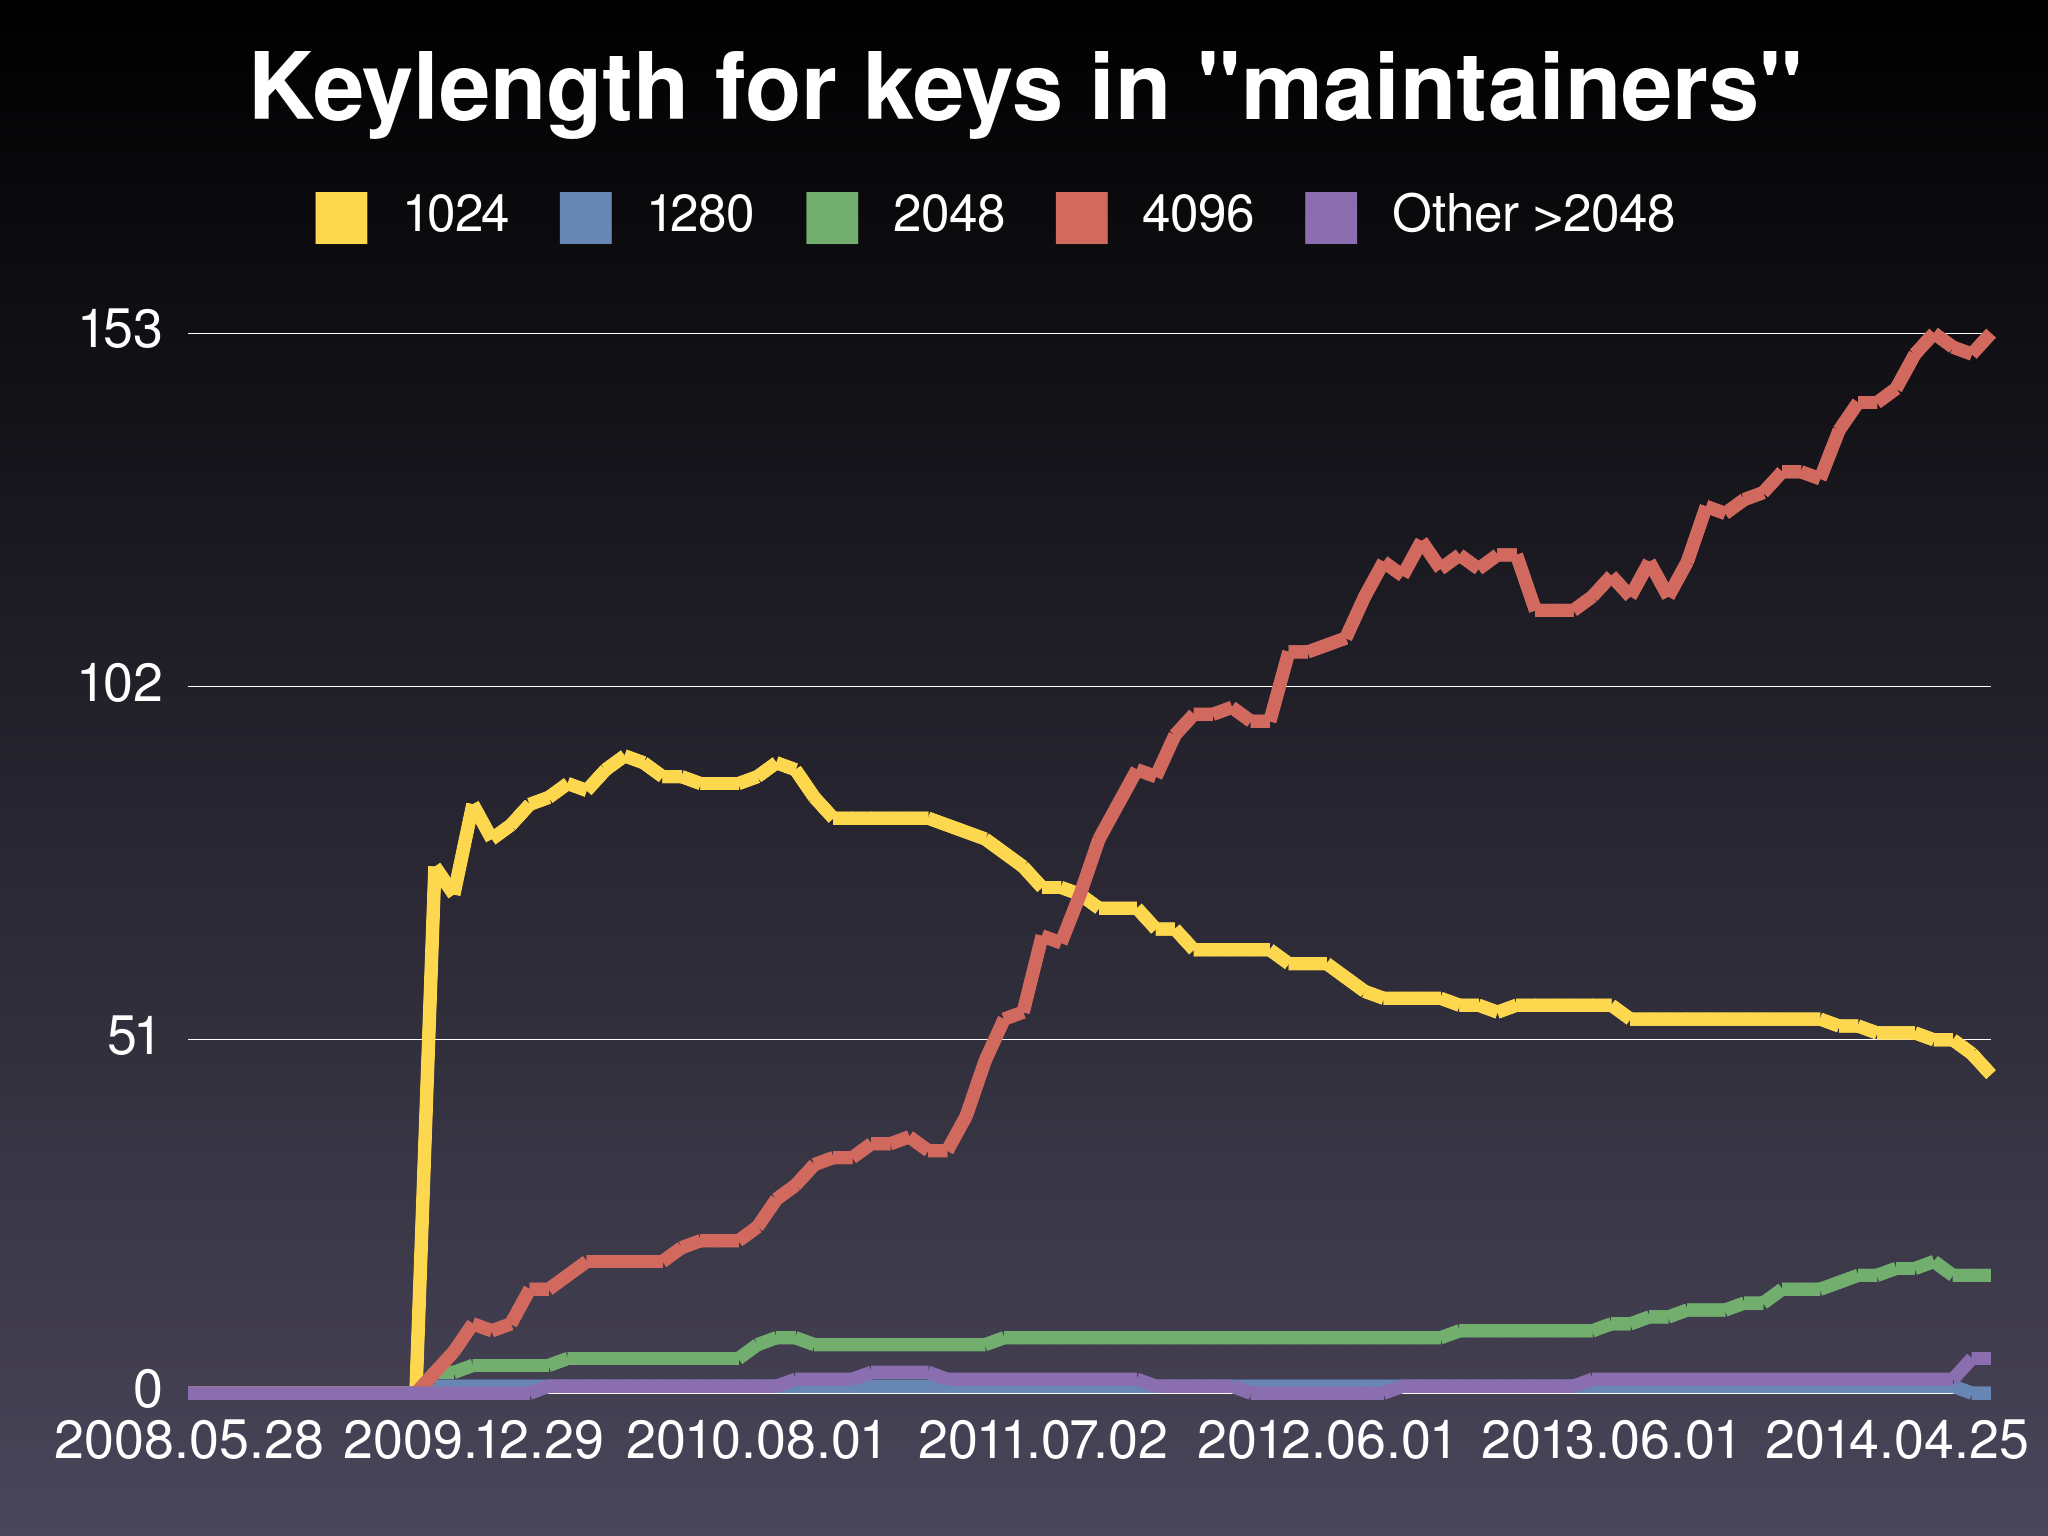
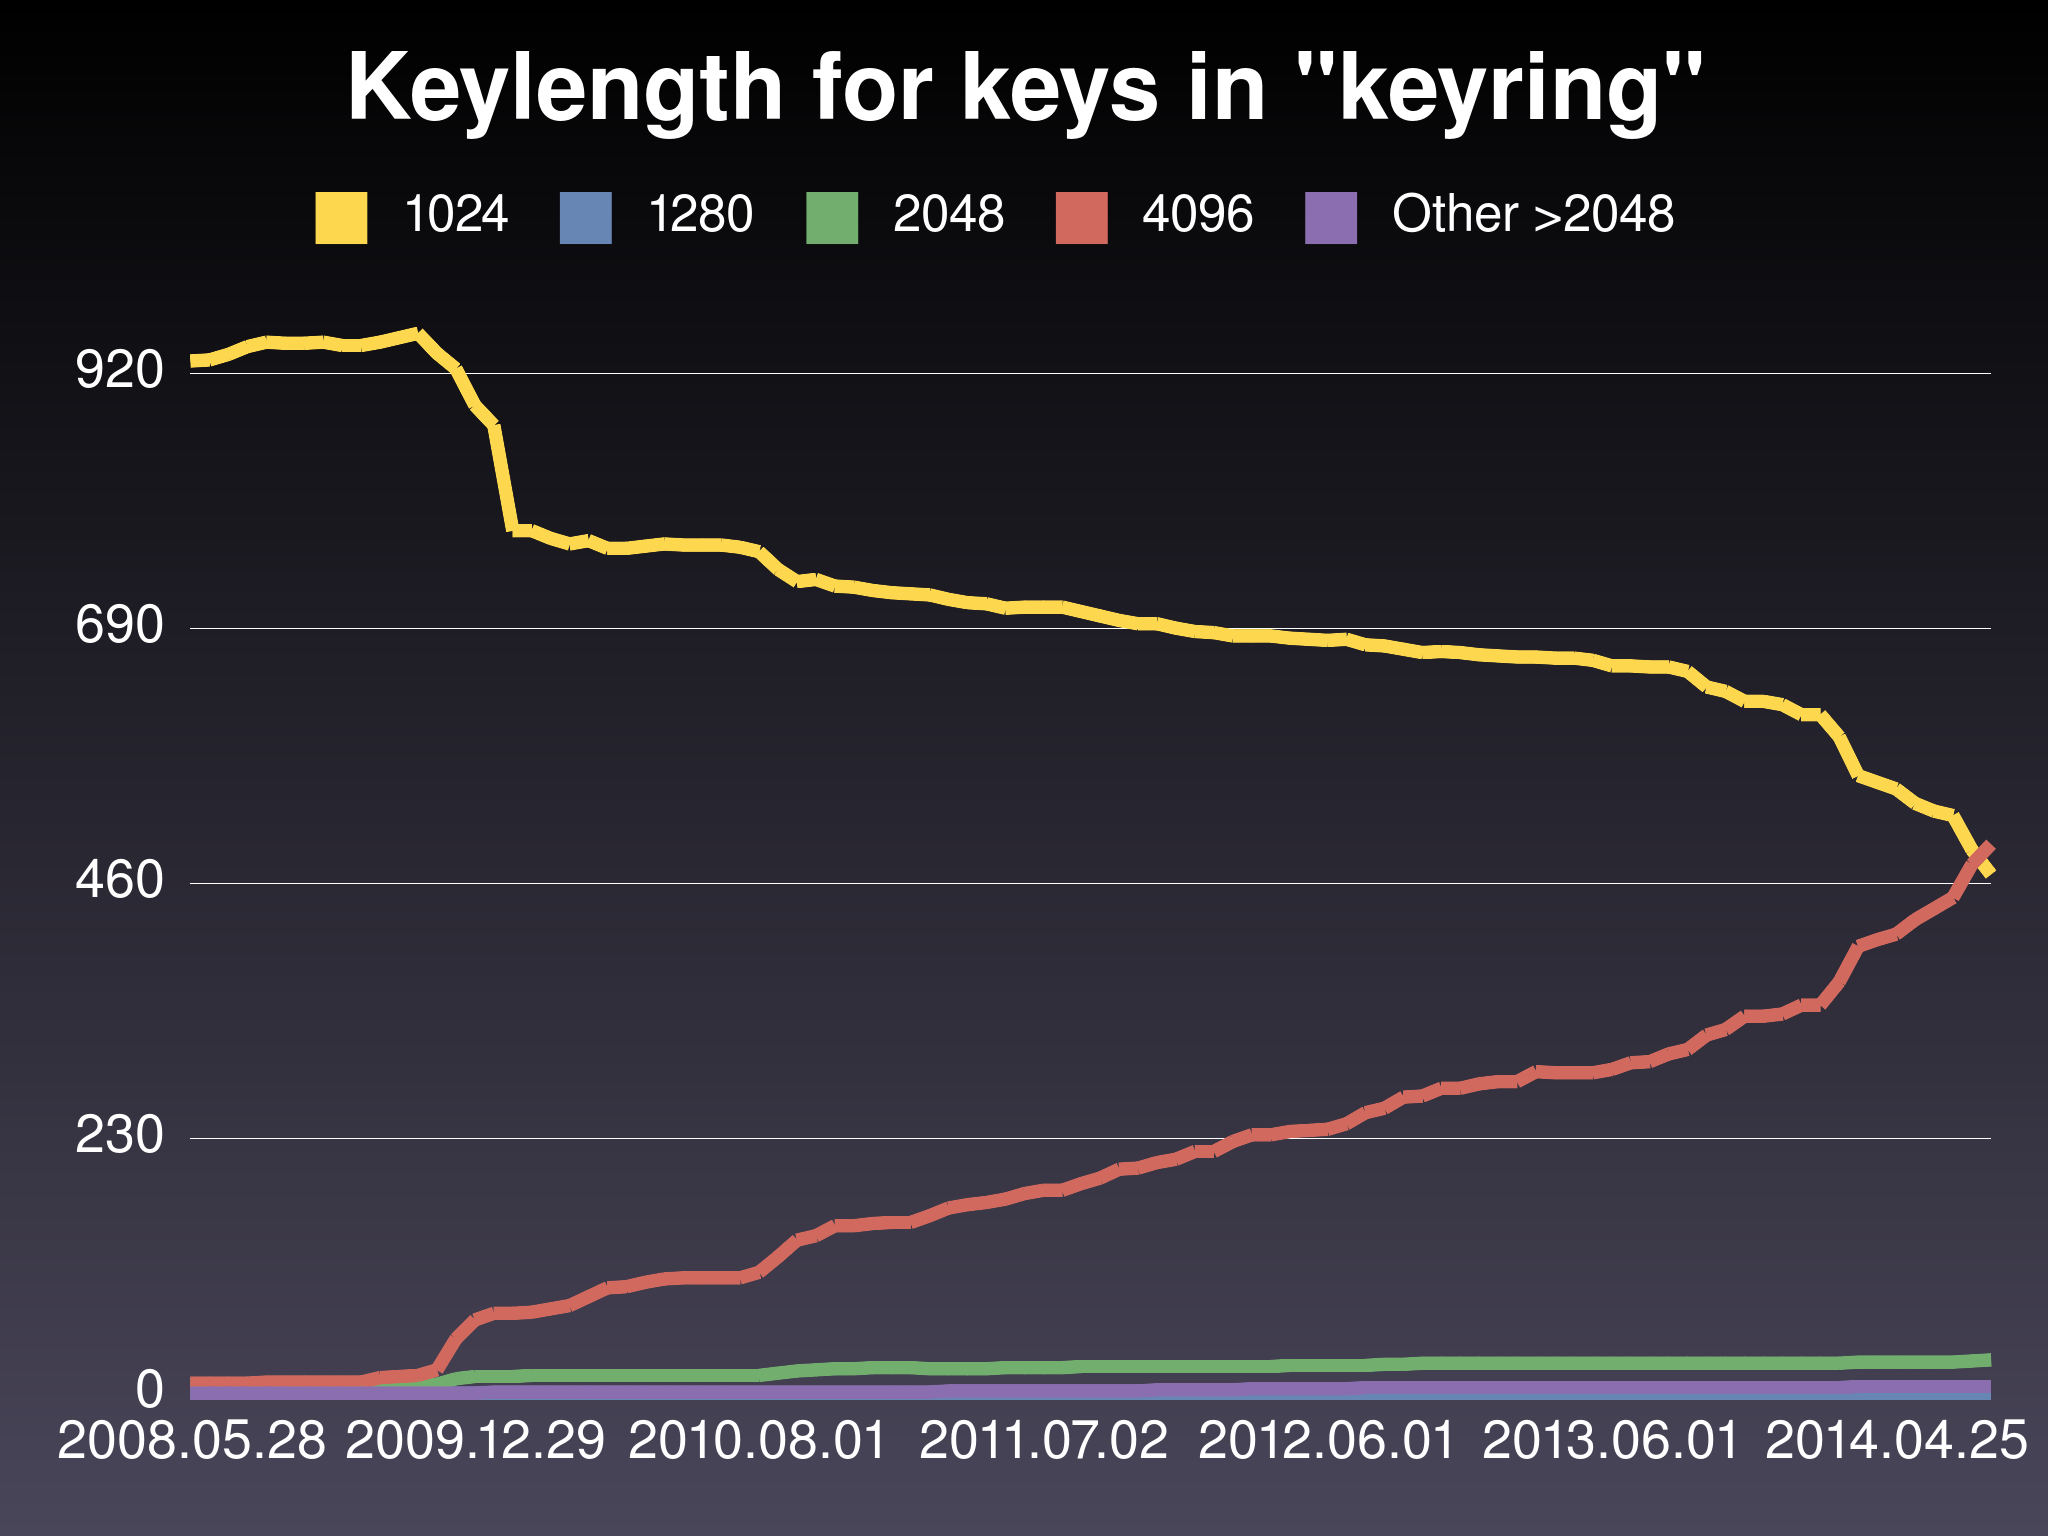
OK, it's almost one month since we (the keyring-maintainers) gave our talk at DebConf14; how are we faring regarding key transitions since then? You can compare the numbers (the graphs, really) to those in our DC14 presentation. Since the presentation, we have had two keyring pushes: First of all, the Non-uploading keyring is all fine: As it was quite recently created, and as it is much smaller than our other keyrings, it has no weak (1024 bit) keys. It briefly had one in 2010-2011, but it's long been replaced. Second, the Maintainers keyring: In late July we had 222 maintainers (170 with >=2048 bit keys, 52 with weak keys). By the end of August we had 221: 172 and 49 respectively, and by September 18 we had 221: 175 and 46. As for the Uploading developers, in late July we had 1002 uploading developers (481 with >=2048 bit keys, 521 with weak keys). By the end of August we had 1002: 512 and 490 respectively, and by September 18 we had 999: 531 and 468. Please note that these numbers do not say directly that six DMs or that 50 uploading DDs moved to stronger keys, as you'd have to factor in new people being added, keys migrating between different keyrings (mostly DM DD), and people retiring from the project; you can get the detailed information looking at the public copy of our Git repository, particularly of its changelog. And where does that put us? Of course, I'm very happy to see that the lines in our largest keyring have already crossed. We now have more people with >=2048 bit keys. And there was a lot of work to do this processing done! But that still means... That in order not to lock a large proportion of Debian Developers and Maintainers out of the project, we have a real lot of work to do. We would like to keep the replacement slope high (because, remember, in January 1st we will remove all small keys from the keyring). And yes, we are willing to do the work. But we need you to push us for it: We need you to get a new key created, to gather enough (two!) DD signatures in it, and to request a key replacement via RT. So, by all means: Do keep us busy!
AttachmentSize
Debian Developers (uploading)266.66 KB
Debian Developers (non-uploading)204.17 KB
Debian Maintainers296.73 KB

21 September 2014

Joachim Breitner: Using my Kobo eBook reader as an external eInk monitor

I have an office with a nice large window, but more often than not I have to close the shades to be able to see something on my screen. Even worse: There were so many nice and sunny days where I would have loved to take my laptop outside and work there, but it (a Thinkpad T430s) is simply not usable in bright sun. I have seen those nice eInk based eBook readers, who are clearer the brighter they are. That s what I want for my laptop, and I am willing to sacrifice color and a bit of usability due to latency for being able to work in the bright daylight! So while I was in Portland for DebConf14 (where I guess I felt a bit more like tinkering than otherwise) I bought a Kobo Aura HD. I chose this device because it has a resolution similar to my laptop (1440 1080) and I have seen reports from people running their own software on it, including completely separate systems such as Debian or Android. This week, I was able to play around with it. It was indeed simple to tinker with: You can simply copy a tarball to it which is then extracted over the root file system. There are plenty of instructions online, but I found it easier to take them as inspiration and do it my way with basic Linux knowledge that s possible. This way, I extended the system boot script with a hook to a file on the internal SD card, and this file then runs the telnetd daemon that comes with the device s busybox installation. Then I just have to make the device go online and telnet onto it. From there it is a pretty normal Linux system, albeit without an X server, using the framebuffer directly. I even found an existing project providing a VNC client implementation for this and other devices, and pretty soon I could see my laptop screen on the Kobo. Black and white worked fine, but colors and greyscales, including all anti-aliased fonts, were quite broken. After some analysis I concluded that it was confusing the bit pattern of the pixels. Luckily kvncclient shares that code with koreader, which worked fine on my device, so I could copy some files and settings from there et voil : I now have an eInk monitor for my laptop. As a matter of fact, I am writing this text with my Kobo sitting on top of the folded-back laptop screen! I did some minor adjustments to my laptop: All this is still very manual (going online with the kobo, finding its IP address, logging in via telnet, killing the Kobo's normal main program, starting x11vnc, finding my ip address, starting the vnc client, doing the adjustments mentioned above), so I need to automate it a bit. Unfortunately, there is no canonical way to extend the Kobo by your own application: The Kobo developers made their device quite open, but stopped short from actually encouraging extensions, so people have created many weird ways to start programs on the Kobo dedicated start menus, background programs observing when the regular Kobo app opens a specific file, complete replacements for the system. I am considering to simply run an SSH server on the device and drive the whole process from the laptop. I ll keep you up-to-date. A dream for the future would be to turn the kobo into a USB monitor and simply connect it to any computer, where it then shows up as a new external monitor. I wonder if there is a standard for USB monitors, and if it is simple enough (but I doubt it). A word about the kobo development scene: It seems to be quite active and healthy, and a number of interesting applications are provided for it. But unfortunately it all happens on a web forum, and they use it not only for discussion, but also as a wiki, a release page, a bug tracker, a feature request list and as a support line often on one single thread with dozens of posts. This makes it quite hard to find relevant information and decide whether it is still up-to-date. Unfortunately, you cannot really do without it. The PDF viewer that comes with the kobo is barely okish (e.g. no crop functionality), so installing, say, koreader is a must if you read more PDFs than actual ebooks. And then you have to deal with the how-to-start-it problem. That reminds me: I need to find a decent RSS reader for the kobo, or possibly a good RSS-to-epub converter that I can run automatically. Any suggestions? PS and related to this project: Thanks to Kathey!

Dariusz Dwornikowski: statistics of RFS bugs and sponsoring process

For some days I have been working on statistics of the sponsoring process in Debian. I find this to be one of the most important things that Debian has to attract and enable new contributions. It is important to know how this process works, whether we need more sponsors, how effective is the sponsoring and what are the timings connected to it. How I did this ? I have used Debbugs SOAP interface to get all bugs that are filed against sponsorship-requests pseudo package. SOAP gives a little bit of overhead because it needs to download a complete list of bugs for the sponsorship-requests package, and then process them according to given date ranges. The same information can be easily extracted from the UDD database in the future, it will be faster because SQL is better when working with date ranges than python obviously. The most problematic part was getting the "real done date" of a particular bug, and frankly most of my time I have spent on writing a rather dirty and complicated script. The script gets a log for a particular bug number and returns a "real done date". I have published a proof of concept in a previous post.. What I measured ? RFSs is a queue, and in every queue one is interested in a mean time to get processed. In this case I called the metric global MTTGS (mean time to get sponsored). This is a metric that gives the overall performance insight in RFS queue. Time to get sponsored (TTGS) for a bug is a number of days that passed between filing an RFS bug and closing it (bug was sponsored). Mean time to get sponsored is calculated as a sum of TTGSs of all bugs divided by number of bugs (in a given period of time). Global MTTGS is MTTGS calculated for a period of time 2012-1-1 until today(). Besides MTTGS I have also measured typical bug related metrics: Plots and graphs Below is a plot of global MTTGS vs. time (click for a larger image). mttgs plot As you can see, the trend is roughly exponential and MTTGS tends to settle around 60 days at the end of the year 2013. This does not mean that your package will wait 60 days on average nowadays to get sponsored. I remind that this is a global MTTGS, so even if the MTTGS of last month was very low, the global MTTGS would decrease just slightly. It gives, however, a good glance in performance of the process. Even that more packages are filed for sponsoring (see next graphs) now, than in the beginning of the epoch, the sponsoring rate is high enough to flatten the global MTTGS, and with time maybe decrease it. The image below (click for a larger one) shows how many bugs reside in a queue with status open or closed (calculated for each day). For closed we have an almost linear function, so each day more or less the same amount of bugs are closed and they increase the pool of bugs with status closed. For bugs with status open the interesting part begins around May 2012 after the system is saturated or gets popular. It can be interpreted as a plot of how many bugs reside in the queue, the important part is that it is stable and does not show clear increasing trend. open done plot The last plot shows arrival and departure rate of bugs from RFS queue, i.e. how many bugs are opened and closed each day. The interesting part here are the maxima. Let's look at them. opened closed plot Maximal number of opened bugs (21) was on 2012-05-06. As it appears it was a bunch upload of RFSs for tryton-modules-*..
  706953  RFS: tryton-modules-account-stock-anglo-saxon/2.8.0-1 
  706954  RFS: tryton-modules-purchase-shipment-cost/2.8.0-1 
  706948  RFS: tryton-modules-production/2.8.0-1 
  706969  RFS: tryton-modules-account-fr/2.8.0-1 
  706946  RFS: tryton-modules-project-invoice/2.8.0-1 
  706950  RFS: tryton-modules-stock-supply-production/2.8.0-1 
  706942  RFS: tryton-modules-product-attribute/2.8.0-1 
  706957  RFS: tryton-modules-stock-lot/2.8.0-1 
  706958  RFS: tryton-modules-carrier-weight/2.8.0-1 
  706941  RFS: tryton-modules-stock-supply-forecast/2.8.0-1 
  706955  RFS: tryton-modules-product-measurements/2.8.0-1 
  706952  RFS: tryton-modules-carrier-percentage/2.8.0-1 
  706949  RFS: tryton-modules-account-asset/2.8.0-1 
  706904  RFS: chinese-checkers/0.4-1 
  706944  RFS: tryton-modules-stock-split/2.8.0-1 
  706981  RFS: distcc/3.1-6 
  706945  RFS: tryton-modules-sale-supply/2.8.0-1 
  706959  RFS: tryton-modules-carrier/2.8.0-1 
  706951  RFS: tryton-modules-sale-shipment-cost/2.8.0-1 
  706943  RFS: tryton-modules-account-stock-continental/2.8.0-1 
  706956  RFS: tryton-modules-sale-supply-drop-shipment/2.8.0-1
Maximum number of closed bugs (18) was on 2013-09-24, and as you probably guessed right also tryton modules had impact on that.
  706953  RFS: tryton-modules-account-stock-anglo-saxon/2.8.0-1 
  706954  RFS: tryton-modules-purchase-shipment-cost/2.8.0-1 
  706948  RFS: tryton-modules-production/2.8.0-1 
  706969  RFS: tryton-modules-account-fr/2.8.0-1 
  706946  RFS: tryton-modules-project-invoice/2.8.0-1 
  706950  RFS: tryton-modules-stock-supply-production/2.8.0-1 
  706942  RFS: tryton-modules-product-attribute/2.8.0-1 
  706958  RFS: tryton-modules-carrier-weight/2.8.0-1 
  706941  RFS: tryton-modules-stock-supply-forecast/2.8.0-1 
  706955  RFS: tryton-modules-product-measurements/2.8.0-1 
  706952  RFS: tryton-modules-carrier-percentage/2.8.0-1 
  706949  RFS: tryton-modules-account-asset/2.8.0-1 
  706944  RFS: tryton-modules-stock-split/2.8.0-1 
  706959  RFS: tryton-modules-carrier/2.8.0-1 
  723991  RFS: mapserver/6.4.0-2 
  706951  RFS: tryton-modules-sale-shipment-cost/2.8.0-1 
  706943  RFS: tryton-modules-account-stock-continental/2.8.0-1 
  706956  RFS: tryton-modules-sale-supply-drop-shipment/2.8.0-1
The software Most of the software was written in Python. Graphs were generated in R. After a code cleanup I will publish a complete solution on my github account, free to use by everybody. If you would like to see another statistics, please let me know, I can create them if the data provides sufficient information.

20 September 2014

Laura Arjona: Happy Software Freedom Day!

Today we celebrate the day of free software (each year, a saturday around mid-September) More info at softwarefreedomday.org There are no public events in Madrid, but I m going to try to hack and write a bit more this weekend, as my personal celebration. In this blog post you can find some of my very very recent activities on free software, and my plans for this weekend of celebration! Debian Children distros aka Derivatives I had the translation/update of the page www.debian.org/misc/children-distros pending since long time. It s a long page, and I was not sure what was better: if picking up the too-outdated last translation, and review it carefully in order to update it, or starting from scratch. I decided to reuse the last translation (thanks Luis Uribe!) and after some days dedicating my commuting time on it, finally, yesterday evening I finished it at home. Now it s in the review queue, and I hope in 10 days or so it will be uploaded. In the meantime, I have learned a bit about the Debian Derivatives subproject and census, I have watched the Derivatives Panel at DebConf13, and had a look at the bug #723069 about keeping the children-distros page up to date. So now that I m liberated about this translation, I m going to put some time in keeping up to date the original English page (I m part of the www and publicity team, so I think it makes sense). My goal is to review at least one Debian derivative each two days, and when I finish the list, start again. I can update the wiki myself, and for the www, I ll send patches against #723069, unless I m told to do it other way. BTW, wouldn t be nice to mark web/wiki pages as RFH the same as packages?, so other people can easily decide to put some time on them, and make http://www.debian.org even more awesome! Or make them appear in the how-can-i-help reminders :) Mmm maybe it s just a matter of filing a bug and tagging it as gift ? I think no, because nobody has the package www.debian.org installed in their system I ll talk with the maintainer about this. New Member process I promised myself to try to work a bit more in Debian during the summer and September, and if everything goes well, try to apply to the new member process in October. I wanted to read all the documentation first, and one challenge is to review/update the translations of www.debian.org/devel/join folder. This way, both myself and the Spanish speaking community benefit from the effort. Yesterday I translated one of those pending pages and I hope during the weekend I can translate/update the rest. When I finish that, I ll keep reading the other documentation. DebConf15 This summer I was invited to join the DebConf15 organization team and pick up tasks in the publicity area. I was very happy to join, I m not sure at all that I can go to DebConf15 in Heidelberg (Germany), in fact I m quite sure I will not go since mid-August is the only opportunity to visit family who lives far away, but anyway, there are things that we can do before DebConf15 and I can contribute. For now, I attended last Monday to the meeting at IRC, and I m finishing a short blogpost about the DebConf14 talk presenting DebConf15, that will be published in the DebConf15 blog. Android, F-Droid I keep on trying to spread the word about F-Droid and the free software available for Android, last week some of my friends updated Kontalk to the 3.0.b1 version (I had updated at the beginning of September) and they liked that now, the images are sent encrypted as well as the text messages :) Some friends also liked the 2048 game, since it can be played offline, without ads, and so. I decided to spend some time this weekend contributing translations to the Android apps that I use. A long pending issue is to try to put workforce in the F-Droid project itself so apps descriptions are internationalized (the program is fully translatable, but the categories of apps and the descriptions themselves, are not). This is a complicated issue, it requires to take some design decisions, and later, of course, the implementation. I cannot do it alone, and I cannot do it in the short time. But today I have filed a bug report (#35) so maybe I find other people able to help. Jabber/XMPP and the RedesLibres chatroom Since several months I ve been using more often my Jabber/XMPP account to join the chatroom redeslibres@salas.mijabber.es I meet there some people that I follow in Pump.io (for example, the people that write in the Comun cate Libremente or Lignux blogs) and we talk about pump.io, free software, free services, and other things. I feel very comfortable there, it s nice to have a Spanish speaking group inside the Free Software community, and I m also learning a bit about XMPP (I ve tried a lot of desktop and Android clients, just for fun!), free networks, and so. So today I wanted to publicly thank you everybody in that chatroom, that welcomed me so well :) Thank you, free software friends And, by extension, I want to thank you all the people that work and have fun in the Free Software communities, in the projects where I contribute or others. They (we) hack to make the world better, and to allow others join to this beautiful challenge that is making machines do what their (final) users wants. Comments? You can comment on this post in this Pump.io thread.
Filed under: My experiences and opinion Tagged: Android, Communities, Contributing to libre software, Debian, English, F-Droid, federation, Free Software, Freedom, internationalization, libre software, localization, translations

19 September 2014

Dariusz Dwornikowski: getting real "done date" of a bug from Debian BTS

As I wrote in my last post currently, SOAP interface, nor Ultimate Debian Database do not provide a date when a given bug was closed (done date). It is quite hard to calculate statistics on a bug tracker when you do not know when a bug was closed (!!). Done date of bug can be found in its log. The log itself can be downloaded by SOAP method get_bug_log but the processing of it is quite complicated. The same comes to web scrapping of a BTS's web interface. Fortunatelly the web interface gives a possibility to download a log in an mbox format. Below is a script that extracts the done date of a bug from its log in mbox format. It uses requests to download the mbox and caches the result in ~/.cache/rfs_bugs, which you need to create. It performs different checks:
  1. Check existence of a header e.g. Received: (at 657783-done) by bugs.debian.org; 29 Jan 2012 13:27:42 +0000
  2. Check for header CC: NUMBER-close done
  3. Check for header TO: NUMBER-close done
  4. Check for Close: NUMBER in body.
The code is below:
import requests
from datetime import datetime
import mailbox
import re
import os
import tempfile
def get_done_date(bug_num):
    CACHE_DIR = os.path.expanduser("~") + "/.cache/rfs_bugs/"
    def get_from_cache():
        if os.path.exists(" ".format(CACHE_DIR, bug_num)):
            with open(" ".format(CACHE_DIR, bug_num)) as f:
                return datetime.strptime(f.readlines()[0].rstrip(), "%Y-%m-%d").date()
        else:
            return None
    done_date = get_from_cache()
    if done_date is not None:
        return done_date
    else:
        r = requests.get("https://bugs.debian.org/cgi-bin/bugreport.cgi?mbox=yes;bug= ;mboxstatus=yes".format(self._num))
        d = try_header(r.text)
        if d is None:
            d = try_cc(r.text)
        if d is None:
            d = try_body(r.text)
        if d is not None:
            with open(" ".format(CACHE_DIR, bug_num), "w") as f:
                f.write(" ".format(d.date()))
        else:
            return None
        return d.date()
    def try_body(text):
        reg = "\(at\s.+\)\s+by\sbugs\.debian\.org;\s(\d 1,2 \s\w\w\w\s\d\d\d\d)"
        handle, name = tempfile.mkstemp()
        with open(name, "w") as f:
            f.write(text.encode('latin-1'))
        mbox = mailbox.mbox(name)
        for i in mbox.items():
            if i[1].is_multipart():
                for m in i[1].get_payload():
                    if "close" in str(m) or "done" in str(m):
                        try:
                            result = re.search(reg, i[1]['Received'])
                            return datetime.strptime(result.group(1), "%d %b %Y")
                        except:
                            return None
            else:
                if "close" in i[1].get_payload() or "done" in i[1].get_payload():
                    try:
                        result = re.search(reg, i[1]['Received'])
                        return datetime.strptime(result.group(1), "%d %b %Y")
                    except:
                        return None
        return None
    def try_header(text):
        reg = "Received:\s\(at\s\d\d\d\d\d\d-(close done)\)\s+by.+"
        try:
            result = re.search(reg, r.text)
            line = result.group(0)
            reg2 = "\d 1,2 \s\w\w\w\s\d\d\d\d"
            result = re.search(reg2, line)
            d = datetime.strptime(result.group(0), "%d %b %Y")
            return d
        except:
            return None
    def try_cc(text):
        reg = "\(at\s.+\)\s+by\sbugs\.debian\.org;\s(\d 1,2 \s\w\w\w\s\d\d\d\d)"
        handle, name = tempfile.mkstemp()
        with open(name, "w") as f:
            f.write(text.encode('latin-1'))
        mbox = mailbox.mbox(name)
        for i in mbox.items():
            if ('CC' in i[1] and "done" in i[1]['CC']) or ('To' in i[1] and "done" in i[1]['To']):
                try:
                    result = re.search(reg, i[1]['Received'])
                    return datetime.strptime(result.group(1), "%d %b %Y")
                except:
                    return None
if __name__ == "__main__":
    print get_done_date(752210)
PS: I hope that the script will be not needed in the near future, as Don Armstrong plans a new BTS database, a Debconf14 video is here.

Paul Tagliamonte: Docker PostgreSQL Foreign Data Wrapper

For the tl;dr: Docker FDW is a thing. Star it, hack it, try it out. File bugs, be happy. If you want to see what it's like to read, there's some example SQL down below. The question is first, what the heck is a PostgreSQL Foreign Data Wrapper? PostgreSQL Foreign Data Wrappers are plugins that allow C libraries to provide an adaptor for PostgreSQL to talk to an external database. Some folks have used this to wrap stuff like MongoDB, which I always found to be hilarous (and an epic hack). Enter Multicorn During my time at PyGotham, I saw a talk from Wes Chow about something called Multicorn. He was showing off some really neat plugins, such as the git revision history of CPython, and parsed logfiles from some stuff over at Chartbeat. This basically blew my mind. All throughout the talk I was coming up with all sorts of things that I wanted to do -- this whole library is basically exactly what I've been dreaming about for years. I've always wanted to provide a SQL-like interface into querying API data, joining data cross-API using common crosswalks, such as using Capitol Words to query for Legislators, and use the bioguide ids to JOIN against the congress api to get their Twitter account names. My first shot was to Multicorn the new Open Civic Data API I was working on, chuckled and put it aside as a really awesome hack. Enter Docker It wasn't until tianon connected the dots for me and suggested a Docker FDW did I get really excited. Cue a few hours of hacking, and I'm proud to say -- here's Docker FDW. This lets us ask all sorts of really interesting questions out of the API, and might even help folks writing webapps avoid adding too much Docker-aware logic. Abstractions can be fun! Setting it up I'm going to assume you have a working Multicorn, PostgreSQL and Docker setup (including adding the postgres user to the docker group) So, now let's pop open a psql session. Create a database (I called mine dockerfdw, but it can be anything), and let's create some tables. Before we create the tables, we need to let PostgreSQL know where our objects are. This takes a name for the server, and the Python importable path to our FDW.
CREATE SERVER docker_containers FOREIGN DATA WRAPPER multicorn options (
    wrapper 'dockerfdw.wrappers.containers.ContainerFdw');
CREATE SERVER docker_image FOREIGN DATA WRAPPER multicorn options (
    wrapper 'dockerfdw.wrappers.images.ImageFdw');
Now that we have the server in place, we can tell PostgreSQL to create a table backed by the FDW by creating a foreign table. I won't go too much into the syntax here, but you might also note that we pass in some options - these are passed to the constructor of the FDW, letting us set stuff like the Docker host.
CREATE foreign table docker_containers (
    "id"          TEXT,
    "image"       TEXT,
    "name"        TEXT,
    "names"       TEXT[],
    "privileged"  BOOLEAN,
    "ip"          TEXT,
    "bridge"      TEXT,
    "running"     BOOLEAN,
    "pid"         INT,
    "exit_code"   INT,
    "command"     TEXT[]
) server docker_containers options (
    host 'unix:///run/docker.sock'
);
CREATE foreign table docker_images (
    "id"              TEXT,
    "architecture"    TEXT,
    "author"          TEXT,
    "comment"         TEXT,
    "parent"          TEXT,
    "tags"            TEXT[]
) server docker_image options (
    host 'unix:///run/docker.sock'
);
And, now that we have tables in place, we can try to learn something about the Docker containers. Let's start with something fun - a join from containers to images, showing all image tag names, the container names and the ip of the container (if it has one!).
SELECT docker_containers.ip, docker_containers.names, docker_images.tags
  FROM docker_containers
  RIGHT JOIN docker_images
  ON docker_containers.image=docker_images.id;
     ip                   names                               tags                   
-------------+-----------------------------+-----------------------------------------
                                              ruby:latest 
                                              paultag/vcs-mirror:latest 
                /de-openstates-to-ocd         sunlightlabs/scrapers-us-state:latest 
                /ny-openstates-to-ocd         sunlightlabs/scrapers-us-state:latest 
                /ar-openstates-to-ocd         sunlightlabs/scrapers-us-state:latest 
 172.17.0.47    /ms-openstates-to-ocd         sunlightlabs/scrapers-us-state:latest 
 172.17.0.46    /nc-openstates-to-ocd         sunlightlabs/scrapers-us-state:latest 
                /ia-openstates-to-ocd         sunlightlabs/scrapers-us-state:latest 
                /az-openstates-to-ocd         sunlightlabs/scrapers-us-state:latest 
                /oh-openstates-to-ocd         sunlightlabs/scrapers-us-state:latest 
                /va-openstates-to-ocd         sunlightlabs/scrapers-us-state:latest 
 172.17.0.41    /wa-openstates-to-ocd         sunlightlabs/scrapers-us-state:latest 
                /jovial_poincare              <none>:<none> 
                /jolly_goldstine              <none>:<none> 
                /cranky_torvalds              <none>:<none> 
                /backstabbing_wilson          <none>:<none> 
                /desperate_hoover             <none>:<none> 
                /backstabbing_ardinghelli     <none>:<none> 
                /cocky_feynman                <none>:<none> 
                                              paultag/postgres:latest 
                                              debian:testing 
                                              paultag/crank:latest 
                                              <none>:<none> 
                                              <none>:<none> 
                /stupefied_fermat             hackerschool/doorbot:latest 
                /focused_euclid               debian:unstable 
                /focused_babbage              debian:unstable 
                /clever_torvalds              debian:unstable 
                /stoic_tesla                  debian:unstable 
                /evil_torvalds                debian:unstable 
                /foo                          debian:unstable 
(31 rows)
OK, let's see if we can bring this to the next level now. I finally got around to implementing INSERT and DELETE operations, which turned out to be pretty simple to do. Check this out:
DELETE FROM docker_containers;
DELETE 1
This will do a stop + kill after a 10 second hang behind the scenes. It's actually a lot of fun to spawn up a container and terminate it from PostgreSQL.
INSERT INTO docker_containers (name, image) VALUES ('hello', 'debian:unstable') RETURNING id;
                                id                                
------------------------------------------------------------------
 0a903dcf5ae10ee1923064e25ab0f46e0debd513f54860beb44b2a187643ff05
INSERT 0 1
(1 row)
Spawning containers works too - this is still very immature and not super practical, but I figure while I'm showing off, I might as well go all the way.
SELECT ip FROM docker_containers WHERE id='0a903dcf5ae10ee1923064e25ab0f46e0debd513f54860beb44b2a187643ff05';
     ip      
-------------
 172.17.0.12
(1 row)
Success! This is just a taste of what's to come, so please feel free to hack on Docker FDW, tweet me @paultag, file bugs / feature requests. It's currently a bit of a hack, and it's something that I think has long-term potential after some work goes into making sure that this is a rock solid interface to the Docker API.

18 September 2014

Jonathan McDowell: Automatic inline signing for mutt with RT

I spend a surprising amount of my time as part of keyring-maint telling people their requests are badly formed and asking them to fix them up so I can actually process them. The one that's hardest to fault anyone on is that we require requests to be inline PGP signed (i.e. the same sort of output as you get with "gpg --clearsign"). That's because RT does various pieces of unpacking[0] of MIME messages that mean that a PGP/MIME signatures that have passed through it are no longer verifiable. Daniel has pointed out that inline PGP is a bad idea and got as far as filing a request that RT handle PGP/MIME correctly (you need a login for that but there's a generic read-only one that's easy to figure out), but until that happens the requirement stands when dealing with Debian's RT instance. So today I finally added the following lines to my .muttrc rather than having to remember to switch Mutt to inline signing for this one special case:
send-hook . "unset pgp_autoinline; unset pgp_autosign"
send-hook rt.debian.org "set pgp_autosign; set pgp_autoinline"
i.e. by default turn off auto inlined PGP signatures, but when emailing anything at rt.debian.org turn them on. (Most of the other things I tell people to fix are covered by the replacing keys page; I advise anyone requesting a key replacement to read that page. There's even a helpful example request template at the bottom.) [0] RT sticks a header on the plain text portion of the mail, rather than adding a new plain text part for the header if there are multiple parts (this is something Mailman handles better). It will also re-encode received mail into UTF-8 which I can understand, but Mutt will by default try to find an 8 bit encoding that can handle the mail, because that's more efficient, which tends to mean it picks latin1. Update: Apparently Mutt in Jessie and beyond doesn't have the pgp_autosign option; you want crypt_autosign instead (and maybe crypt_autopgp but that defaults to yes so unless you've configured your setup to do S/MIME by default you should be fine). Thanks to Luca Capello for pointing this out.

Jaldhar Vyas: Scotland: Vote NO

        _  __<;
      </_/ _/__   
     /> >  7   )  
     ~;</7    /   
     /> /   _*<---- Perth    
     ~ </7  7~\_  
        </7     \ 
         /_ _ _   
If you don't, the UK will have to rename itself the K. And that's just silly. Also vote yes on whether Alex Trebek should keep his mustache.

17 September 2014

Steve Kemp: If this goes well I have a new blog engine

Assuming this post shows up then I'll have successfully migrated from Chronicle to a temporary replacement. Chronicle is awesome, and despite a lack of activity recently it is not dead. (No activity because it continued to do everything I needed for my blog.) Unfortunately though there is a problem with chronicle, it suffers from a bit of a performance problem which has gradually become more and more vexing as the nubmer of entries I have has grown. When chronicle runs it : In the general case you rebuild a blog because you've made a entry, or received a new comment. There is some code which tries to use memcached for caching, but in general chronicle just isn't fast and it is certainly memory-bound if you have a couple of thousand entries. Currently my test data-set contains 2000 entries and to rebuild that from a clean start takes around 4 minutes, which is pretty horrific. So what is the alternative? What if you could parse each post once, add it to an SQLite database, and then use that for writing your output pages? Instead of the complex data-structure in-RAM and the need to parse a zillion files you'd have a standard/simple SQL structure you could use to build a tag-cloud, an archive, & etc. If you store the contents of the parsed-blog, along with the mtime of the source file you can update it if the entry is changed in the future, as I sometimes make typos which I only spot once Ive run make steve on my blog sources. Not surprisingly the newer code is significantly faster if you have 2000+ posts. If you've imported the posts into SQLite the most recent entries are updated in 3 seconds. If you're starting cold, parsing each entry, inserting it into SQLite, and then generating the blog from scratch the build time is still less than 10 seconds. The downside is that I've removed features, obviously nothing that I use myself. Most notably the calendar view is gone, as is the ability to use date-based URLs. Less seriously there is only a single theme, which is what is used upon this site. In conclusion I've written something last night which is a stepping stone between the current chronicle and chronicle2 which will appear in due course.
PS. This entry was written in markdown, just because I wanted to be sure it worked.

NOKUBI Takatsugu: Met with a debian developer from Germany

Last weekend, I (knok), Hideki (henrich) and Yutaka (gniibe) met with John Paul Adrian Glaubitz (glaubitz). In the past, I had met with another Germany developer Jens Schmalzing (jensen) in Japan. He was a good guy, but unfortunately he gone in 2005. I had an old OpenPGP key with his sign. It is a record of his activity, but the key is weak nowaday (1024D), so I stop to use the key but don t issue revoke. Anyway glaubitz is also a good guy, and he loves old videogame console. gniibe gave him five DreamCast consoles. I bring him to SUPER POTATO, a old videogame shop. He bought some software for Virtual Boy. DebConf 2015 will hold in Germany, I want to go for it if I can.

16 September 2014

Matthew Garrett: ACPI, kernels and contracts with firmware

ACPI is a complicated specification - the latest version is 980 pages long. But that's because it's trying to define something complicated: an entire interface for abstracting away hardware details and making it easier for an unmodified OS to boot diverse platforms.

Inevitably, though, it can't define the full behaviour of an ACPI system. It doesn't explicitly state what should happen if you violate the spec, for instance. Obviously, in a just and fair world, no systems would violate the spec. But in the grim meathook future that we actually inhabit, systems do. We lack the technology to go back in time and retroactively prevent this, and so we're forced to deal with making these systems work.

This ends up being a pain in the neck in the x86 world, but it could be much worse. Way back in 2008 I wrote something about why the Linux kernel reports itself to firmware as "Windows" but refuses to identify itself as Linux. The short version is that "Linux" doesn't actually identify the behaviour of the kernel in a meaningful way. "Linux" doesn't tell you whether the kernel can deal with buffers being passed when the spec says it should be a package. "Linux" doesn't tell you whether the OS knows how to deal with an HPET. "Linux" doesn't tell you whether the OS can reinitialise graphics hardware.

Back then I was writing from the perspective of the firmware changing its behaviour in response to the OS, but it turns out that it's also relevant from the perspective of the OS changing its behaviour in response to the firmware. Windows 8 handles backlights differently to older versions. Firmware that's intended to support Windows 8 may expect this behaviour. If the OS tells the firmware that it's compatible with Windows 8, the OS has to behave compatibly with Windows 8.

In essence, if the firmware asks for Windows 8 support and the OS says yes, the OS is forming a contract with the firmware that it will behave in a specific way. If Windows 8 allows certain spec violations, the OS must permit those violations. If Windows 8 makes certain ACPI calls in a certain order, the OS must make those calls in the same order. Any firmware bug that is triggered by the OS not behaving identically to Windows 8 must be dealt with by modifying the OS to behave like Windows 8.

This sounds horrifying, but it's actually important. The existence of well-defined[1] OS behaviours means that the industry has something to target. Vendors test their hardware against Windows, and because Windows has consistent behaviour within a version[2] the vendors know that their machines won't suddenly stop working after an update. Linux benefits from this because we know that we can make hardware work as long as we're compatible with the Windows behaviour.

That's fine for x86. But remember when I said it could be worse? What if there were a platform that Microsoft weren't targeting? A platform where Linux was the dominant OS? A platform where vendors all test their hardware against Linux and expect it to have a consistent ACPI implementation?

Our even grimmer meathook future welcomes ARM to the ACPI world.

Software development is hard, and firmware development is software development with worse compilers. Firmware is inevitably going to rely on undefined behaviour. It's going to make assumptions about ordering. It's going to mishandle some cases. And it's the operating system's job to handle that. On x86 we know that systems are tested against Windows, and so we simply implement that behaviour. On ARM, we don't have that convenient reference. We are the reference. And that means that systems will end up accidentally depending on Linux-specific behaviour. Which means that if we ever change that behaviour, those systems will break.

So far we've resisted calls for Linux to provide a contract to the firmware in the way that Windows does, simply because there's been no need to - we can just implement the same contract as Windows. How are we going to manage this on ARM? The worst case scenario is that a system is tested against, say, Linux 3.19 and works fine. We make a change in 3.21 that breaks this system, but nobody notices at the time. Another system is tested against 3.21 and works fine. A few months later somebody finally notices that 3.21 broke their system and the change gets reverted, but oh no! Reverting it breaks the other system. What do we do now? The systems aren't telling us which behaviour they expect, so we're left with the prospect of adding machine-specific quirks. This isn't scalable.

Supporting ACPI on ARM means developing a sense of discipline around ACPI development that we simply haven't had so far. If we want to avoid breaking systems we have two options:

1) Commit to never modifying the ACPI behaviour of Linux.
2) Exposing an interface that indicates which well-defined ACPI behaviour a specific kernel implements, and bumping that whenever an incompatible change is made. Backward compatibility paths will be required if firmware only supports an older interface.

(1) is unlikely to be practical, but (2) isn't a great deal easier. Somebody is going to need to take responsibility for tracking ACPI behaviour and incrementing the exported interface whenever it changes, and we need to know who that's going to be before any of these systems start shipping. The alternative is a sea of ARM devices that only run specific kernel versions, which is exactly the scenario that ACPI was supposed to be fixing.

[1] Defined by implementation, not defined by specification
[2] Windows may change behaviour between versions, but always adds a new _OSI string when it does so. It can then modify its behaviour depending on whether the firmware knows about later versions of Windows.

comment count unavailable comments

Petter Reinholdtsen: Speeding up the Debian installer using eatmydata and dpkg-divert

The Debian installer could be a lot quicker. When we install more than 2000 packages in Skolelinux / Debian Edu using tasksel in the installer, unpacking the binary packages take forever. A part of the slow I/O issue was discussed in bug #613428 about too much file system sync-ing done by dpkg, which is the package responsible for unpacking the binary packages. Other parts (like code executed by postinst scripts) might also sync to disk during installation. All this sync-ing to disk do not really make sense to me. If the machine crash half-way through, I start over, I do not try to salvage the half installed system. So the failure sync-ing is supposed to protect against, hardware or system crash, is not really relevant while the installer is running. A few days ago, I thought of a way to get rid of all the file system sync()-ing in a fairly non-intrusive way, without the need to change the code in several packages. The idea is not new, but I have not heard anyone propose the approach using dpkg-divert before. It depend on the small and clever package eatmydata, which uses LD_PRELOAD to replace the system functions for syncing data to disk with functions doing nothing, thus allowing programs to live dangerous while speeding up disk I/O significantly. Instead of modifying the implementation of dpkg, apt and tasksel (which are the packages responsible for selecting, fetching and installing packages), it occurred to me that we could just divert the programs away, replace them with a simple shell wrapper calling "eatmydata $program $@", to get the same effect. Two days ago I decided to test the idea, and wrapped up a simple implementation for the Debian Edu udeb. The effect was stunning. In my first test it reduced the running time of the pkgsel step (installing tasks) from 64 to less than 44 minutes (20 minutes shaved off the installation) on an old Dell Latitude D505 machine. I am not quite sure what the optimised time would have been, as I messed up the testing a bit, causing the debconf priority to get low enough for two questions to pop up during installation. As soon as I saw the questions I moved the installation along, but do not know how long the question were holding up the installation. I did some more measurements using Debian Edu Jessie, and got these results. The time measured is the time stamp in /var/log/syslog between the "pkgsel: starting tasksel" and the "pkgsel: finishing up" lines, if you want to do the same measurement yourself. In Debian Edu, the tasksel dialog do not show up, and the timing thus do not depend on how quickly the user handle the tasksel dialog.
Machine/setup Original tasksel Optimised tasksel Reduction
Latitude D505 Main+LTSP LXDE 64 min (07:46-08:50) <44 min (11:27-12:11) >20 min 18%
Latitude D505 Roaming LXDE 57 min (08:48-09:45) 34 min (07:43-08:17) 23 min 40%
Latitude D505 Minimal 22 min (10:37-10:59) 11 min (11:16-11:27) 11 min 50%
Thinkpad X200 Minimal 6 min (08:19-08:25) 4 min (08:04-08:08) 2 min 33%
Thinkpad X200 Roaming KDE 19 min (09:21-09:40) 15 min (10:25-10:40) 4 min 21%
The test is done using a netinst ISO on a USB stick, so some of the time is spent downloading packages. The connection to the Internet was 100Mbit/s during testing, so downloading should not be a significant factor in the measurement. Download typically took a few seconds to a few minutes, depending on the amount of packages being installed. The speedup is implemented by using two hooks in Debian Installer, the pre-pkgsel.d hook to set up the diverts, and the finish-install.d hook to remove the divert at the end of the installation. I picked the pre-pkgsel.d hook instead of the post-base-installer.d hook because I test using an ISO without the eatmydata package included, and the post-base-installer.d hook in Debian Edu can only operate on packages included in the ISO. The negative effect of this is that I am unable to activate this optimization for the kernel installation step in d-i. If the code is moved to the post-base-installer.d hook, the speedup would be larger for the entire installation. I've implemented this in the debian-edu-install git repository, and plan to provide the optimization as part of the Debian Edu installation. If you want to test this yourself, you can create two files in the installer (or in an udeb). One shell script need do go into /usr/lib/pre-pkgsel.d/, with content like this:
#!/bin/sh
set -e
. /usr/share/debconf/confmodule
info()  
    logger -t my-pkgsel "info: $*"
 
error()  
    logger -t my-pkgsel "error: $*"
 
override_install()  
    apt-install eatmydata   true
    if [ -x /target/usr/bin/eatmydata ] ; then
        for bin in dpkg apt-get aptitude tasksel ; do
            file=/usr/bin/$bin
            # Test that the file exist and have not been diverted already.
            if [ -f /target$file ] ; then
                info "diverting $file using eatmydata"
                printf "#!/bin/sh\neatmydata $bin.distrib \"\$@\"\n" \
                    > /target$file.edu
                chmod 755 /target$file.edu
                in-target dpkg-divert --package debian-edu-config \
                    --rename --quiet --add $file
                ln -sf ./$bin.edu /target$file
            else
                error "unable to divert $file, as it is missing."
            fi
        done
    else
        error "unable to find /usr/bin/eatmydata after installing the eatmydata pacage"
    fi
 
override_install
To clean up, another shell script should go into /usr/lib/finish-install.d/ with code like this:
#! /bin/sh -e
. /usr/share/debconf/confmodule
error()  
    logger -t my-finish-install "error: $@"
 
remove_install_override()  
    for bin in dpkg apt-get aptitude tasksel ; do
        file=/usr/bin/$bin
        if [ -x /target$file.edu ] ; then
            rm /target$file
            in-target dpkg-divert --package debian-edu-config \
                --rename --quiet --remove $file
            rm /target$file.edu
        else
            error "Missing divert for $file."
        fi
    done
    sync # Flush file buffers before continuing
 
remove_install_override
In Debian Edu, I placed both code fragments in a separate script edu-eatmydata-install and call it from the pre-pkgsel.d and finish-install.d scripts. By now you might ask if this change should get into the normal Debian installer too? I suspect it should, but am not sure the current debian-installer coordinators find it useful enough. It also depend on the side effects of the change. I'm not aware of any, but I guess we will see if the change is safe after some more testing. Perhaps there is some package in Debian depending on sync() and fsync() having effect? Perhaps it should go into its own udeb, to allow those of us wanting to enable it to do so without affecting everyone. Update 2014-09-24: Since a few days ago, enabling this optimization will break installation of all programs using gnutls because of bug #702711. An updated eatmydata package in Debian will solve it.

15 September 2014

Ritesh Raj Sarraf: apt-offline 1.5

I am very pleased to announce the release of apt-offline, version 1.5. In version 1.4, the offline bug report functionality had to be dropped. In version 1.5, it is back again. apt-offline now uses the new Debian native BTS library. Thanks to its developers, this library is much more slim and neat. The only catch is that it depends on the SOAPpy library which currently is not stock in Python. If you run apt-offline of Debian, you may not have to worry as I will add a Recommends on that package. For users using it on Microsoft Windows, please ensure that you have the SOAPpy library installed. It is available on pypi. The old bundled magic library has been replaced with the version of python magic library that Debian ships. This library is derived from the file package and is portable on almost all Unixes. For Debian users, there will be a Recommends on it too. There were also a bunch of old, outstanding, and annoying bugs that have been fixed in this release. For a full list of changes, please refer to the git logs. With this release, apt-offline should be in good shape for the Jessie release. apt-offline is available on Alioth @ https://alioth.debian.org/projects/apt-offline/

AddThis:

Categories:

Keywords:

Next.

Previous.