Search Results: "reg"

13 September 2010

Amaya Rodrigo: Of inner peace and struggle

[Nothing related to Debian here, move on if you don't care about my recurring obsession with the end of the world, Cassandra pains, or Big Phat Living Room Revolution yearnings].

Although I am still looking for a community of anarcho-primitivists that want to accept me joining their frugal living, and simply slip off the social construct, the system, the fucking face of earth, call it what you will, I could find some comfort in my favourite feminist blogger's take on the subject of my midlife crisis regarding ecology, capitalism, patriarchy, child bearing, overpopulation, meat consumption and all the rumination of consuming thoughts that (still) make my life miserable and have kept me running away from human contact for a year.

[Emphasis mine]

At what point does human culture depart from the Natural? With the invention of computers? TV? Cars? The cotton gin? Electricity? Taco stands? Gunpowder? The printing press? Written language? Shoes? Crop cultivation? Yurts? The wheel? Did humans become unnatural when the good old days of picturesque, endless agrarian toil, feudal oppression, unchecked disease, ignorance, and death from dysentery at 35 turned into the bad new days of urban post-industrial capitalism where a pound of fair-trade organic coffee costs $12.99 and your email inbox is full of spam?

ah. Everything humans do, or have ever done, is natural. We can t do anything else. The idea that modern culture is un-natural is nostalgic and inaccurate. Living off the grid in a yurt is good in some absolute sense, whereas driving an SUV from a suburban bungalow to the stripmall is bad ? Come on. This a romantic, but misguided view. The cosmic reaction to a 20 Ford Expedition is the same as to a sanctimonious Prius: bupkis. The universe doesn t give a fuck about you or your lifestyle choices. It doesn t give a fuck about the economy, oil spills, or civil unrest in Blargistan. It doesn t give a fuck about katydids. Eventually our whole planet will be erased from space, and the galaxy won t bat an eye. The inevitable extinction of our species (imminent, according to research here at Spinster Laboratories) via the exhaustion of available resources is as natural as a fresh-picked peach. As Andre 3000 and other dude philosophers have observed, nothing is forever.

Yes, yes, when people use the word natural what they really mean is free of chemical additives and maybe some of the assorted hippie concepts that go with that narrative. Barter economies, home furnishings made from bamboo, vegan cookbooks, living in the country. While I would argue that it is just as natural for people to put chemical additives in things as it is to not put chemical additives in things, I admit that it is appealing to fantasize that the source of human misery is an unnatural isolation from Nature, and that doing yoga on an organic rubber mat and drinking organic spinach smoothies will put me back in sync with the cosmos.

But alas, I m already in sync with the cosmos, and so are you. In other words, this is it. This is what we ve become, and this is what we get. Which is not to say that a person can t fantasize about a verdant paradise full of songbirds and polar bears and Bengal tigers, untouched by human influence. Only, that world isn t a world we could actually live in. The minute you add contented children, lazy from a carefree day at the swimming hole, eating ripe plums on the porch at sunset to that scenario, natural history changes, and it s right back to our scorched-earth dystopia. Our giant brains use up resources, it s as simple as that.

As long as we re still here, though, we might as well try to make the best of it.

http://blog.iblamethepatriarchy.com/2010/06/19/heads-up-art-week-starts-on-monday/


Though the comfort is somewhat ephemeral, because deep inside, I know she's wrong, I know another way is feasible, but I have given up already, I have very well come to terms with extiction, I get an enormous pleasure from the thought of the very well deserved human mass suicide-by-cop^Wnature, and in fact, I trust and hope it will save me personally from facing the hard times ahead, as I am a damn coward, paralized by fear, hopeless about the flock ever getting it (is it so hard, really?), while doing as much as I can but completely overwhelmed by the need of changing a world everyone seems to like just as it is. I can certainly empathize with much more disturbed ways of airing similar anguish, among many other examples, such as The Unabomber, or The Weather Underground. I don't even want to go there as I know violence all too well and it is not fun to be on the receiving end. But I see the screaming desperation behind the motives of acts I am not at the liberty to discuss here. I wonder if consumption of resources in the form of books will numb the disorder or make it worse and what sort of medical arrangement the stablishment has for it. As you click away the previous links will mean nothing to you because a)it is Wikipedia after all, and b)you probably don't even understand what the problem of eating animal corpses is, humans are omnivores after all, and what is all this nonsense about dropping language altogether.

WTF, there was no comfort after all, and I am still a nutjob.

Robert Collins: What do I do @ work?

I recently moved withing Canonical from being a paid developer of Bazaar to take on a larger challenge Technical Architect for Launchpad. Its been two months now, and its time to put my head up out of the coal face, have a look around and regroup. When I worked on Bazaar, every day when I started work got up I was working on a tool anyone can use, designed for collaboration upon sourcecode, for people writing software. This is a toolchain component right at the heart of the free software world. Bazaar and tools like it get used everyday to manage, distribute and collaborate on the sourcecode that makes up the components of Ubuntu, Debian, Fedora and so forth. Every time someone new starts using Bazaar for a new free or open source project, well I felt happy happy that in my small part I m helping with this revolution we re carrying out. Launchpad is pretty similar to Bazaar in some ways. Obviously they are both free software, both are written in Python, and both are sponsored by Canonical, my employer. And they both are designed to assist in collaboration and communication between free software developers albeit in rather different ways. Bazaar is a tool anyone can install locally, run as a command line, GUI, or local webserver, and share code either centrally (e.g. by pushing to Launchpad), or in a peer to peer fashion, acting as their own server. Launchpad, by contrast is a website which (usually) folk will use as a service in their browser, from the comand line FTP (for package building), ssh (for Bazaar branch pushing or pulling), or even local GUI programs using the Launchpad API service. This makes it more approachable for first time collaborators, but its less able to be used offline, and it has all the usual caveats of web sites : it needs a username and password, it s availability depends on the operators on the team I m part of. So there s a lot less room for error: if we do something wrong, the system is unavailable, and users can t just apt-get install an older release. With Launchpad our goal is to to get all the infrastructure that open source need out of the way, so that they can focus on their code, collaboration within their team and almost uniquely collaboration with other teams. As well as being open source, Launchpad is free for all open source projects to use Ubuntu is our single biggest user they use it for all bugtracking, translation and package building, and have a hugefraction of the total storage overhead in the database. Launchpad is a pretty nice system, so people use it, and as a result (on a technical basis) it is suffering from its own success: small corner cases in the code turn up every day or two, code written years ago to deal with a relatively small data set now has to deal with data sets a thousand or more times larger (one table, for instance, has over 600,000,000 rows in it. For the last two months then, I ve been working on Launchpad. As Technical Architect, I need to ensure that the things that we (users, stakeholders and developers of Launchpad) want to do are supported by the structure of the system : the platform(s) we re building on, the way we approach problems, coding standards and diagnostic tools. That sounds pretty dry and hands off, but I m finding its actually very balanced. I wrote a presentation when I started the job, which encapsulated the challenges I saw in front of the team on this purely technical front, and what I thought I needed to do. I think I was about right in my expectations: On a typical day, I ll be hands on in a problem helping get it diagnosed, talking long term structural changes with someone around how to make things more efficient / flexible / maintainable, and writing a small patch here or there to help move things along. In the two months since I took on this challenge, we ve made significant headway on the problem of performance for Launchpad : many inefficient code paths have been identified and removed, some new infrastructure has been created as is being rolled out to make individual pages faster, and we ve massively increased the diagnostic data we get when things go wrong. We ve introduced facilities for responding more rapidly to issues in the software (but they have to be rolled out across the system) and I hope, over the next 4 months we ll reach the first of my performance goals: for any webpage in Launchpad, it will complete rendering in 99% of the time. (Note that we already meet this goal if you measure the whole system, but this is biased by some pages being very frequently hit and also being very small).

Eddy Petrișor: Fixing a bookmark corruption in Iceweasel/Firefox

At some point in the past my bookmarks broke in such a way that I wasn't able anymore to alter in any way the bookmarks, deletions, additions, reorganisation, nothing worked.

Way before this event I set up a git repo in my .mozilla directory and committed everything in the directory (except obvious cache files and such) in the repo. I didn't make a cronjob with this since I didn't thought of a proper way to make sure the browser wasn't started (the data might have been inconsistent at commit time), and, since most of the time I have the browser started, it seemed rather useless to try to automate for a very, very small window of time when the browser data would be in a consistent state. As a consequence, I did occasional manual commits in the git repo.

When the bookmarks issue appeared I realised that my last git commit was so old that it didn't made any sense to try to restore since I would have had lost bookmarks, passwords and plugins. So I made a checkpoint commit os the broken profile and resorted to all sorts of manual attempts at fixing the issue, but all my efforts of playing with the bookmarks.* files proved to be useless.

I concluded that icewesel/firefox 3.5.x was using some other mechanism and decided to dig into the issue at some latter time when time allowed me to analyse and fix it. Today was that day.

I began by creating a backup for the bookmarks via the Bookmarks Manager export function. After a hickup, it managed to save a proper bookmarks.html file. I tried to import that file, but the breakage remained.

Then I decided I should prepare for the worst, installed an addon which allowed me to save all stored passwords and created a new account (started firefox from the command line with 'firefox -ProfileManager') with the intention to transplant files from the old files into the new one. Short after that I realised that it would be smarter to commit the new profile, too, import the bookmarks from the backup file and replace the touched files back into the old profile.

After the import and closing the browser, git informed me that the modified files were:
XPC.mfasl
XUL.mfasl
cookies.sqlite
localstore.rdf
places.sqlite
pluginreg.dat
urlclassifier3.sqlite


At this point the modification of the binary .mfasl files looked very ugly to me, but I had a hunch that the only relevant file to my problem was the places.sqlite file and I went on to check the contents of the file with sqlitebrowser. After inspecting also the urlclassifier3.sqlite file (whose contents were unreadable), I decided to give it a try at simply placing the places.sqlite file in the old profile and see if the problem would be fixed that way. After all, I had the whole profile's state in git so any breakage could have been undone easily.

I started firefox using the old profile and the problem was fixed. Yay!

Now I have my bookmarks back and a suggestion for the mozilla people: please don't keep useless files like bookmarks.html in the profile once they become outdated, they are misleading.

P.S.: I still have to think of a way to make automated sane commits. Maybe I'll try to make an iceweasel/firefox addon. This could be a nice idea since I could learn something new, too.

12 September 2010

Theodore Ts'o: Moderate Muslims need a better PR Agency

There has been much made of recent reports that roughly half of Americans have an unfavorable view of Islam. And as usual, there are those who will try to claim that Muslims really aren t all that bad, and that Sharia is just set of nice, abstract principles which are all about the protection of life, family, education, religion, property, and human dignity. And on the other side, we have people pointing out that using Sharias as justification, there are countries which are stoning women and chopping off poor people s hands and then forbidding Muslims from arguing about whether such things are just. Worst yet, some of the more public moderate Muslims , such as Iman Rauf, refuse to criticize organizations such as Hamas, on the ground that he is a bridge builder , and it wouldn t help to criticize Hamas s terrorist activities as being anti-Isalmic. OK, so let s grant for the sake of argument the claims that Shariah really is far more than just criminal sanctions, but mainly about exhorting people to live a moral life, and that of the 1,081 pages of the two-volume Arabic text which Sherman A. Jackson (the Arthur F. Thurnau Prfessor of Arabic and Isalamic Studies at the University of Michigan) used to study Shariah, only 60 pages were devoted to criminal sanctions (i.e., the stoning and the cutting off of hands), and only 19 were devoted to Jihad. Let s even further grant the claims made by Humaira Awais Shahid that most Muslims reject Political Islam and are not even arabs. OK. But that case, wouldn t there be more Imans publically disavowing the people who advocate terrorism and suicide bombs as not being Islamic? Not all of them are bridge-builders, are they? And if so, some of them might be better deployed towards saying what Islam is not, and saying that perhaps people who espouse those beliefs are being profoundly unIslamic and saying this loudly outside of their Mosques. Oh, I understand that many Muslims feel that they shouldn t be asked to repudiate the sins of a few crazy terrorists ; just as all Christians shouldn t be held accountable for disturbed crazy rants of a small-time pastor from Gainsville, Florida. But at the same time, it seems to me that Islamic leaders should be eager to say, loudly, that what is being done in the name of their religion in Iran and Nigeria is wrong, and to denounce it. Maybe, some would say, that they are doing that and the media isn t paying attention to them. Well, the Media is surely paying attention to people like Iman Rauf, and he refuses to denounce Hamas! I would gently suggest to those Islamic leaders who feel that they and their faith haven t been given a fair shake, to hire a better PR agency; and make sure that active denunciations of that which they claim does not represent true Islam is shouted from the rooftops; published in press releases; made in press conferences. And actively denounce your fellow Muslims that you feel are shaming your religion, instead of complaining about American Islamophobia. Trying to pretend that there is absolutely no truth in why Americans might be afraid of terrorists who have been hiding under the mantle of your religion is not going to help your cause. There may be truth in the fact that many Americans don t know as much as they should about Islam and Shariah. And there may be truth that American unswerving support of Israel, despite the fact that they acted in profound and unjust ways against the Palestinians, is not only morally and ethically wrong, but has hurt American interests. I certainly believe that to be to true; I am no friend to fundamentalists of any stripe, whether they are Christian, Jewish, or Islamic; and I think the Jewish fundamentalists have almost completely taken over the Israeli political discourse. But all of that is irrelevant if the goal is reduce people e negative views towards Islam. And in any case, if you really believe that attacking innocents, and coercing religion by threatening Muslims who have fallen away from their faith with the death penalty is wrong, then it s wrong regardless of whether those innocents happened to vote for politicians who have been influenced by way too much money from AIPAC. So instead of trying to lecture Americans about their uncritical support of Israel, why not just stand witness to the fact that killing innocents is wrong, and that people who do that are not Islamic, no matter what they claim or how impressive their turban might happen to be? And maybe it might be a good idea to speak out against those who would lend support, whether moral, or financial or logistical, to people who do these unIslamic things in the name of Islam? And it may not be enough to say it once; it needs to be said again and again. Which is why it s important to hire a good PR agency. No related posts.

Gregor Herrmann: RC bugs 2010/34 - 2010/36

I thought it's about time to write a short report on my RC bug squashing activities again; nothing spectacular, but maybe it motivats others *hint*

Lucas Nussbaum: Ruby packaging in Debian and Ubuntu: Mythbusting and FAQ

A lot is being said on how Ruby is packaged in Debian and Ubuntu. In this post, I m trying to go through the most common myths and give my position as a Debian Ruby maintainer. Note that those are my views, not necessarily those of the other Debian Ruby maintainers. Myth: Ruby is completely outdated in Debian and Ubuntu There s a culture in the Ruby community of always using the latest bleeding-edge version. There s also a culture (though this one has recessed a bit, I think) that it s perfectly fine to change APIs in incompatible ways if it makes the software slightly better. In Debian (and Ubuntu) stable releases, we try to provide a rock-solid version of Ruby that won t be allowed to change API during the support lifetime of a release. Bugfixes for important bugs can be applied, but that s basically all. So it s not surprising that Ruby in released versions of Debian and Ubuntu is behind the latest upstream version. In development branches, we are following the latest upstream versions quite closely. Debian 6.0 squeeze , to be released by the end of the year, includes Ruby 1.8.7-p302, and will include 1.9.2-p0 (the currently of Ruby 1.9.2 in squeeze is currenty a SVN snapshot from beginning of august). There are people interested in installing a packaged Ruby that just works, and other people interested in installing their own version of Ruby (through RVM and such). People in the Ruby community tend to forget about the first category, and consider that, because they install Ruby from source or with RVM, that should be the solution for everybody. We need the Ruby community to respect that different people have different ways of using Ruby, and to stop recommending that everyone using Debian and Ubuntu should install Ruby from source. We also need to leverage the backports services for both Debian and Ubuntu to provide a way to install the latest upstream version on stable releases. The only reason why we are not doing it yet is lack of time. Myth: Ruby is split into a myriad of packages in Debian In the past (pre-2005), a decision was made to split some libraries from the standard library into separate packages. This was motivated by: Most of the split was undone a very long time ago, and the readline and openssl splits were undone this year. The current package in Debian squeeze has: It is always possible to merge more packages, but merging any of the other packages would significantly increase the size of what you get by default, and might discourage people to use it in some contexts (disk space is not always cheap. Think embedded systems and smartphones). Myth: Rubygems is crippled in Debian There are two differences in the rubygems Debian packages. First, gems are installed in /var/lib/gems, not /usr/local/lib/gems. That is because rubygems are seen as state for the Rubygems package, not independant software installed separately. A change for this is currently being discussed, and should be done after the squeeze release. (I don t think that it s reasonable to push that change now). A consequence of installing to /var/lib/gems is that gems binary are outside of $PATH. After the change, gems binary would also be installed in /usr/local/bin. Second, gem update --sytem is disabled in the Debian package, because that would replace code from the Rubygems Debian package with code downloaded from the Internet, and can break your system in subtle ways. We have changed this (in SVN, not in any package in the archive yet) to allow gem update --system if a specific environment variable is set, which gives us the opportunity to display a warning message. Myth: Ruby is slow on Debian Ruby is built with the pthread threading code, because not using it breaks many native Ruby libraries (Ruby-gnome2, for example). And other Linux distributions are doing the same. There are some very old benchmark results floating around in some blogs that show that the pthread code has a performance impact of about 20%. There are been patches for that for a long time (applied in Ruby Enterprise Edition), but they were never properly sent back. Actually, all the discussions about this issue were rumors and blog posts, and there wasn t even a bug report about it! After the bug was reported properly, it was fixed in a timely manner. The fix is not yet included in the Ruby 1.8.7, but is being applied as a patch to the Debian package since 1.8.7.299-2. (So the Debian package is actually newer and faster than upstream Ruby in that regard). What makes Ruby so difficult to maintain in Debian? The main problems we have with Ruby are portability issues. The only officially supported platform for Ruby is IA32 (i386 in Debian), and everything else is best effort. It means that it is not even supported officially on x86_64/amd64! Debian supports a dozen of architectures, and the Ruby package has to work on each of them. Ruby 1.8 is mostly OK nowadays thanks to the help of Debian porters, but we still have serious problems with 1.9.2, since the test suite fails on sparc, hppa, ia64 and Debian GNU/kFreeBSD. Why doesn t Ruby use the alternatives system on Debian? The alternatives system provides a way to switch between different software providing the same functionality. Currently, if you want to use Ruby 1.9.2, you need to use the ruby1.9.1 executable (1.9.1 = ruby compatibility version here). The alternatives system would allow to switch ruby to ruby1.9.1 on a system-wide basis. However, the situation of applications and libraries working only with Ruby 1.8 should be clarified: those should use /usr/bin/ruby1.8 instead of /usr/bin/ruby. Another problem is that the way to specify packages dependencies still need to be determined. There s nothing impossible to do about that, it just needs someone to do the work. Where do we go from here? The Ruby developers (or expert users) community is generally very hostile towards Debian. Many harsh words and insults are used in discussions mentioning Debian in the ruby-core@ mailing list, and there are frequent recommendations to avoid the Debian packages and install from sources, which is quite demotivating (Actually, what prompted that blog post is someone calling Debian-specific changes unforgivable). This atmosphere makes it hard to recruit people, and the Debian Ruby teams are completely understaffed, which is clearly the major blocker to improving the situation further. We are 3 co-maintainers for the interpreter packages, and I m the only Debian Developer that is really active on a regular basis in the pkg-ruby-extras team (that does libraries and applications packaging). We desperately need help, but at the same time I have no time to improve our documentation and make it easier to join the team. While I haven t reached a final decision yet, I am also likely to stop doing Ruby work in Debian after squeeze is released, as I am getting increasingly tired and demotivated.

Alastair McKinstry: Exoclimes: the diversity of planetary scientists

I'm just back from ExoClimes 2010: Exploring the Diversity of Planetary Atmospheres. An excellent conference: the PDFs of the talks and posters are now online, and they are putting the videos of the talks up soon. But in particular the organizers deserves thanks for bringing exoplanetary scientists and observers together with climate modelers doing Earth (and Mars, Titan, Venus, ...) models.
Model complexity graph Peter Cox on model complexity
The last talk on Friday was by Peter Cox on Climate change and exoplanet sciences that was far better than expected for the "graveyard shift". One theme of the conference was the need for a 'heirarchy' of models, from simple energy-balance models to full circulation (GCM) models: using progressively more complex models to understand more bits of whats going on. Exoplanet workers mostly use simpler models, progressing now to GCMs, while Earth modellers are moving beyond GCMs to "Earth system" models including biology, etc. Peter pointed out the two styles of work: the exoplanet modelers are short of data, and risk being too speculative. We know little of what the planets are like, and concentrate on implementing physics in the models to see what they might be like. Earth modelers on the other hand are if anything swamped with data: the tendency here is to make the model fit the data, by adjusting parameters until it does so. The danger of this approach is that the model will then not work away from current present-Earth conditions. Tim Lenton pointed out some work that was done with the Met Office model, where they took the radiative transfer part of the model and tested it for other planets, and paleo-Earth conditions. The model blew up : it wasn't capable of x2 or x4 current CO2 levels. (This has since been corrected). Over dinner there were interesting discussions on the different styles within the communities. While the underlying GCMs used come from the Earth sciences, its quite common within the exoplanetary community for a researcher to work on all parts of the model: dynamics one day, radiative transfer the next. In Earth climate work people have become more specialized and someone is a 'radiative transfer' person, and won't touch other parts of the code (even if they can follow them in the huge codes we have today!). On the other hand, there is a greater tradition of model inter-comparison in Earth sciences, where we compare the model outputs to each other for some known test cases ( Held & Suarez, the CMIP5 project, etc.) Apart from some initial work by Emily Rauscher, little has been done on this in exoplanetary models; it was agreed more of this would be a good idea. Radiative transfer (the interaction of 'sunlight' with the atmosphere, where it gets absorbed, scattered and re-radiated) in particular seems to be an area that could benefit from this. In this middle ground Francois Forget showed the work on the LMDZ model and applying GCMs to terrestrial planets. They've successfully applied this model to Mars, Titan, and partially to Venus (a much tougher problem, due to its heavy clouds giving a long radiative timescale). There are problems with correctly explaining super-rotation though. This is where the atmosphere rotates faster than the planet: on Venus for example the planet rotates every 243 days, while the clouds rotate around the planet every 4 days. Sebastian Lebonnois described the possible mechanisms for Venus and Titan; Johnathan Mitchell so did some interesting work on this recently. Different regimes are involved for different rotation rates of the planet. Ralph Lorenz pointed out the lack of "real paleo-Earth" climate work at the moment. While geology has inspired a lot of work on the atmospheric composition, what with the different gas mixtures (meaning earth-model radiative transfer codes don't work) and the faster dynamics meaning super-rotation could apply (Earth's day was about 8 hours long in the Archean era), we don't have a model of the climate yet. It looks like we should treat Earth as an exoplanet. Tags , , ,

Francois Marier: Setting up your own DNSSEC-aware resolver using Unbound

Now that the root DNS servers are signed, I thought it was time I started using DNSSEC on my own PC. However, not wanting to wait for my ISP to enable it, I decided to setup a private recursive DNS resolver for myself using Unbound.

Installing UnboundBeing already packaged in Debian and Ubuntu, unbound is only an apt-get away:
apt-get install unbound
though if you are running lenny, I suggest you grab the latest backport.

Once unbound is installed, follow these instructions to enable DNSSEC.

Optional settingsIn my /etc/unbound/unbound.conf, I enabled the following security options:
harden-referral-path: yes
use-caps-for-id: yes
and turned on prefetching to hopefully keep in cache the sites I visit regularly:
prefetch: yes
prefetch-key: yes
Finally, I also enabled statistics:
extended-statistics: yes
control-enable: yes
control-interface: 127.0.0.1
and ran sudo unbound-control-setup to generate the necessary keys.

Once unbound is restarted (sudo /etc/init.d/unbound restart) stats can be queried to make sure that the DNS resolver is working:
unbound-control stats

Overriding DHCP settingsIn order to use my own unbound server for DNS lookups and not the one received via DHCP, I added this line to /etc/dhcp/dhclient.conf:
supersede domain-name-servers 127.0.0.1;
and restarted dhclient:
sudo killall dhclient
sudo /etc/init.d/network-manager restart
If you're not using DHCP, then you simply need to put this in your /etc/resolv.conf:
nameserver 127.0.0.1

Testing DNSSEC resolutionOnce everything is configured properly, the best way I found to test that this setup was actually working is to use a web browser to visit these sites:
and using dig:
$ dig +dnssec A www.dnssec.cz   grep ad
;; flags: qr rd ra ad; QUERY: 1, ANSWER: 2, AUTHORITY: 3, ADDITIONAL: 1

Are there any other ways of making sure that DNSSEC is fully functional?

11 September 2010

Iustin Pop: New harddrive: WD6000HLHX

While SSDs are all the rage nowadays (and for good reason), I don't trust them yet for my important storage, as I'm not familiar with their failure behaviour. So when one of my hard-drives recently started misbehaving, I bought the new WD Raptor model. Since some people might be interested in how it performs in some synthetic tests under Linux, here are some fio results. Now, I admit that 10K RPM for desktop is a want versus need discussion, but nevertheless, these hard-drives are (for their capacity) quite affordable, compared to SSDs, and faster than a regular 7200 RPM drive. So:
# smartctl -i /dev/ 
 
Device Model:     WDC WD6000HLHX-01JJPV0
Serial Number:    WD-WXA1C20U0627
Firmware Version: 04.05G04
User Capacity:    600,127,266,816 bytes
The older hard-drive I'm comparing to is also a WD Raptor, the WD3000GLFS model (yes, I'm a sucker for shiny hardware). A few of the SMART capabilities seems to have changed (e.g. a new Phy Event Counter has been added, CRC errors within host-to-device FIS, and the SCT Status Version is now 3 instead of 2, the Temperature History Size is now 478 instead of 128), but nothing significantly different that I can see. First, the IOPS test: nothing changed here. To be honest, even the WD3000 model had pretty good performance. The fio job definition is:
[global]
filename=$ DRIVE 
iodepth=$ IODEPTH 
bs=$ BS 
ramp_time=10
runtime=120
[rate-iops]
rw=randread
ioscheduler=noop
ioengine=libaio
direct=1
I did tests for block sizes of 512 and 4096 bytes (but the results were so close that I only used the 512 bytes ones), and at queue depths of 1, 2, 4, 8, 16 and 24 (not 32 as AFAIK the SATA protocol only allows a max queue depth of 31, and I wanted to test only the drive's queue). So: IOPS graph As I said, nothing really changed, but starting at 130 IOPS and reaching more than 200 IOPS at queue depth 8 (which again, is not so much used at home) is nice. Next, the bandwidth tests. This uses the standard disk-zone-profile job shipped with fio:
[global]
bs=64k
direct=1
rw=read
ioengine=libaio
iodepth=2
zonesize=256m
zoneskip=2g
write_bw_log
[disk_zoning]
filename=$ DRIVE 
Here the changes are significant. Whereas the previous generation topped at around 110MB/s, the new model tops at over 140MB/s: Bandwidth graph I'm not sure what makes the old model vary so much at the start of the test (I repeated the measurement twice, and it looks the same), but in any case, there a few conclusions to be drawn: So, I can say I'm pretty happy. The 300GB model was a tiny bit too small for me, but the new size is great, and it seems the sequential read/write speed is also good. Let's see how long they will last though, HDD failures are (unwanted) friends of mine

10 September 2010

Sylvain Le Gall: Dirty fix for omlet vim extension

omlet (or here) is a vim extension for writing OCaml code. In my opinion, it has a better indentation than the standard OCaml vim support. Unfortunately, it has a cost: the indentation vim code is more complex. And it has a few bugs :-( The main bug is that it doesn't like unbalanced comment opening "(*" and closing "*)" tags. From time to time, it enters an infinite (or very long) loop when there such a tag left in your file. It can be very far away from the point you are editing. It isn't too problematic, because unbalanced tags are a syntax error. But the problem is that it matches these tags inside strings also. So whenever you start using regular expression like "(.*)" the whole indentation fails. But there is a very ugly solution to this problem! Problematic code:
 let parse_rgxp =
   Pcre.regexp ~flags:[ CASELESS] 
     "^(?<license>[A-Z0-9\\-]*[A-Z0-9]+)\
      (?<version>-[0-9\\.]+)?(?<later>\\+)?\
      ( *with *(?<exception>.*) *exception)?$"
Solution, add ignore"(*":
 let parse_rgxp =
   ignore "(*";
   Pcre.regexp ~flags:[ CASELESS] 
     "^(?<license>[A-Z0-9\\-]*[A-Z0-9]+)\
      (?<version>-[0-9\\.]+)?(?<later>\\+)?\
      ( *with *(?<exception>.*) *exception)?$"
Very very ugly coder: you balance comment tags in dead code -- very very bad ;-) ps: another solution when the plugin enters the infinite loop, hit Ctrl-C. This will stop it and let you define your own indentation.

Lior Kaplan: Hebrew translation and Bidi issues in Openoffice 3.3 (beta)

In the last few years the Israeli government founded some work on openoffice.org by Tk Open Systems Ltd. During the years, the work has resulted with an Israeli version , released after the official release and includes a lot of patches to improve support for Bidi and Hebrew specifically. Although most patches were submitted to the hamburg , a lot of them weren t used and are still waiting for inclusion. The funding the that projects stopped a year ago (9/2009), and the last release of the Israeli version is 3.1.1. Since then we had a quiet period in which 3.2 and 3.2.1 were released. While still enjoying the fruits of the projects in these version, it seems that it s time for the community to take over, as we lost hopes for yet another funds from the government. In may Netanel and I started talking about taking over the Hebrew translation, and in June we got Hebrew added to the openoffice.org pootle server. We started with about 80%, and got to 86% in time to get to the list of languages getting a language pack built for. This was a first achievement as Hebrew didn t have a language pack since early on the 2.x versions. I believe that working as part of the openoffice.org l10n group and with openoffice.org release schedule will only benefit for the Hebrew translation process. We used the language pack to test the translation and improve it. We also were able to get to 89% with the help of more volunteers.I believe it s now much more consistent than before. In the process with manually checked Writer thoroughly, while Calc and Impress got less attention due to the time frame. But we fixed some major translation issues in all of the three components. While testing the translation we also started to report Bidi issues we saw in 3.3 beta, hoping they will be fixed for the final release. For example, the main openoffice.org screen on windows has is getting repainted wrongly when moving the mouse over the options (text, spreadsheet..). This looks very badly as this is the main screen! See issue #97556 for details
Openoffice.org main screen in RTL UI

In RTL UI the main screen doesn't get repaited properly.

In addition to report new issues, we also started to keep track of the already opened issues regarding Bidi and Hebrew. I m following the issue system for a few years now, but seeing the list of issues organized in the wiki gave me a better orientation in the problems we have. E.g. finding some related or similar issues and mention each other in the comments, when someone goes to first one, he could also fixed the other as the problem is similar and probably comes from the same code. Organizing also the already closed bugs in 3.x, gave me a some kind of a changelog for the Bidi and Hebrew related issues. In that manner, version 3.1 was a very good for Bidi, thanks for a lot of efforts and work with the Bidi meta issue #79434. The wiki page is in Hebrew, but looks quite OK with Google translate (see here). Hoping to have 3.4 a major release (Bidi wise), I ve opened issue #114236 as another meta issue for Bidi related issues. I ve kept Hebrew specific issues out, as to get it more general and also relevant for Bidi users in other languages. Any help of those issues will be more than welcome (starting with votes and ending with patches).
Filed under: i18n & l10n, Israeli Community, Openoffice.org

Keith Packard: altos-release

AltOS The Altus Metrum Operating System Altos is the core of the software for all of the Altus Metrum products. It runs on the 8051-based micro-controllers within both the flight computer and the ground station devices. AltOS a small cooperatively multi-tasking operating system. AltOS Version 0.7.1 Released Bdale and I have just released AltOS version 0.7.1. Version 0.7.1 is the first release to include the new Java-based ground station software which runs on Linux, Mac OS X and various Windows flavors. AltOS Changes in 0.7.1
  1. Deal with Windows and Mac OSX USB stacks. These two operating systems do interesting things with USB and found some boundary conditions within the AltOS USB stack which couldn t be tested on Linux. With test cases discovered, the panic calls were turned into code that dealt with these cases correctly.
  2. Increase packet mode payload size and add callsigns. The callsigns are set by the master end of the packet link (normally the TeleDongle) so that the entire radio conversation conforms to regulatory requirements. Increasing the payload size makes data transfers go faster.
  3. Place configuration data in fixed flash addresses. This change makes it possible to read the serial number and radio calibration data back out of the flash data when reprogramming a device.
TeleMetrum Changes in 0.7.1
  1. Ensure GPS date information is written to on-board data logger. The GPS date information is used when constructing eeprom log file names; without this, the eeprom downloading tool would generate a filename based on the current date.
  2. Allow TeleMetrum to be used as a programming dongle. This means the user can reprogram a TeleDongle or another TeleMetrum using the TeleMetrum as a programming dongle. Before this, only the TeleDongle could be used to program other devices.
AltosUI - Ground Station Software for Altus Metrum devices Version 0.7.1 is the first release containing our new cross-platform Java-based user interface. AltosUI can: Three Operating Systems, One AltosUI AltosUI provides all of these features on the three target operating systems, Linux, Mac OS X (version 10.5 or newer) and Windows (XP, Vista or 7). The bulk of the software is written in Java and is built once and tested and delivered on all three target platforms. A tiny shim library is built on each system to provide access to the Altus Metrum devices connected over the USB link. Thanks to our contributors! We ve gotten lots of help getting this software built and tested: Future Plans With the basic AltOS and AltosUI functionality running, we ve got lots of ideas about where to take the system in the future. And, we d love to hear ideas from you as well. Some of the ideas we ve like to get done include:
  1. Google Earth file export. We had a Linux-based C program to export a KML (Keyhole Markup Language) file that Google Earth can read and present to the user overlayed on satellite photo data.
  2. Data Plotting. Being able to plot flight data right in the UI would be nice, and there are several Java plotting packages available to try out.
  3. State-dependent display. When the rocket is on the pad, you only want to know if it s ready to fly. When the rocket is descending on a chute, you want to know where it is in the sky and how fast its falling. Presenting a limited amount of information that is most likely interesting to the user should make the display more useful.
  4. Ejection charge testing. The TeleMetrum firmware has the ability to fire ejection charges over the USB or radio links. Safely hooking this up to the user interface will allow for wireless ejection system testing. The key here is safely , of course, which means figuring out a fool proof user interface.
I m sure there are any number of additions that could be made to this list; feel free to send along ideas that you ve got. Of course, all of this software is licensed under the GNU General Public License, so you can get the source and hack on it in the comfort of your own home.

9 September 2010

Cyril Brulebois: SD: Bugzilla gets history support

(Disclaimer: Possibly one of my longest post ever, you may want to scroll to the bottom and only look at the pictures.) So, what s new in SD since last week? Fetching everything From http://bugs.freedesktop.org/, it was possible to download all the bugs I reported there (that means 2 ), but trying to download those reported by Julien led to a crash without any trace. Dichotomy FTW, I came up with a bunch of bugs which would lead to the same result, which confirmed that the amount of bugs processed at once wasn t the issue. Playing around with strace, it appeared that exchanges with the remote server were apparently fine, so an issue on the client-side SOAP machinery got suspected. So let s enable tracing:
use SOAP::Lite +trace => 'all';
Tada! The issue was indeed local: malformed XML got received, leading to a die call issued from the XML-RPC layer. Thankfully, one can set up a fault handler, which I used to display the range of bug IDs which triggered that bug, so that people can look into it and determine what to add to the blacklist until the underlying issue s been investigated (presumably, bugzilla s at fault). Speeding things up With that blacklisting of buggy bugs, one can then try to move to other queries, dealing with more bugs. Some examples follow:
reporter=kibi@d.o
product=xorg&component=Driver/VMWare
product=xorg&component=Driver/nouveau
product=xorg&component=Server/general
product=xorg&component=Driver/intel
Moving from 2 bugs to 10-100 bugs (Julien s or VMWare s) was OK. But then moving to several hundreds of bugs (Driver/nouveau = 500+ bugs) led to noticeable performance issues. Not to mention what happened when one reaches several thousands of bugs (Driver/intel = 2500+ bugs). Indeed, even with network exchanges cached into a local file, processing data was taking up to several dozens of minutes. I knew about Perl s -d:DProf, which helps figuring out where time is spent, but was pointed to -d:NYTProf (and its accompanying tool, nytprofhtml). Some hotspots got noticed: Things got better, but not good enough. There are several Prophet (the engine under the hood) backends, so one can play with:
PROPHET_REPLICA_TYPE=sqlite   # the default for SD
PROPHET_REPLICA_TYPE=prophet
Switching to prophet was a big win, but still not good enough. Indeed, many tiny files are written, and most of the time is spent in I/O. Although I m nothing like a performance guru, I guessed that running on an average laptop, with ext3 and its default commit interval of 5 seconds might not be helping, so I gave a quick try to -o remount,commit=60, and that seemed to help. Even though there are probably other tricks to find in that area (which hopefully won t require root privileges ), there s already a patch which landed in prophet s master branch, replacing File::Spec->catfile with an optimized version: that function alone was eating 10% of runtime In the sqlite case, disabling the auto-commit feature helped reducing the I/O load, but a proper patch is still lacking for now (running into locked database issues, or into missing tables after having created them isn t fun, so I postponed debugging that). Since performance issues looked like they could be solved eventually, I switched back to implementing missing features. Handling more than comments Currently 3 types of stuff are currently fetched from the bugzilla server: (Yes, that means that attachments are totally ignored for now.) Until now, only bug comments were considered. The first comment was used to determine a pseudo-title (using its first line), the reporter, and the creation date. This approach was chosen to try and get a basic sync working quickly, so as to get: Now, the algorithm is the following: from the bug status, determine a set of properties of interest; then walk the history backwards, and update the properties incrementally until the (presumed) initial state is reached. Then create the ticket using this initial state . Adding the incremental property changes to that initial ticket makes it possible to represent the bug s life as a list of Prophet::ChangeSet objects. That s where the fun begins, since properties in the bug status may not match properties in the bug history, so one needs to establish property correspondence. Also, some properties can be multivalued for added fun. I believe that s where most of the time is going to be spent while developing a new replica type in SD: once one knows how to get a hand on needed info on the remote server, the main question is what to do with it. For now, I decided to ignore many fields to make it possible to do a big sync like Server/general, property support will be improved later on. Screenshots Instead of pasting lengthy terminal excerpt, let s use some screenshots instead (sorry, I m not sure how to present such things in an accessible way, suggestions welcome). Cloning Julien s bugs, listing all open tickets, listing all tickets, searching using a regular expression: Cloning, listing, searching Displaying bug 42 (that s the local ID): Displaying Now, let s start the embedded web server through sd server --port 1234 and point the browser there. List of RESOLVED bugs: List of RESOLVED bugs Status and comments for bug 42: Status and comments for bug 42 History for bug 42: History for bug 42 Compared to the original bugzilla page: Same bug on FreeDesktop.org Next time Some items which need work: Flattr this!

Matthew Garrett: Linux backlight control

Backlight control is one of those things that you'd think would be simple, but ha ha this is computing so of course it's an utter disaster and everything is a huge mess. There's three main classes of backlight control in the x86 world, all of which have drawbacks:

Right now, if there's an ACPI backlight interface then that's usually the only thing we'll show you. We can do that because we can identify if there's an ACPI backlight interface when we parse the ACPI tables at the start of booting, and that information can be registered before we start setting up any other backlights. The problem comes when we have no ACPI backlight interface. We don't have any idea whether there's a platform mechanism until a platform driver loads, which could be at any time. As a result, we've been reluctant to expose GPU-level backlight control because doing so would often give you two separate backlight controls and no indication as to which should be used. Userspace doesn't really have a way to make that decision either, so everyone ends up unhappy.

This is especially problematic with some machines which provide no ACPI or known platform control (or, in the case of some Samsungs, only provide platform control if you have a special Linux BIOS that Samsung won't give you) but can control the backlight via the gpu. Right now you get nothing, because giving you something would potentially break other systems and the needs of the many etc. Sorry! But this is obviously problematic in the long term, especially because multi-GPU machines tend to have multiple ACPI backlight interfaces, so I've been working on a better approach.

When a backlight device is registered, it appears under /sys/class/backlight. If it's an ACPI device it has a symlink pointing to some random ACPI device. If it's a platform device it's pointing at something like "dell-laptop" which is approximately unhelpful when it comes to figuring out what it controls. If it's a GPU-level device then it probably points at the PCI device, which is helpful except in the case where you have multiple backlight controls on a single GPU. So, by and large, you have no good way to identify which backlight control is preferable unless you keep a huge list of all possible backlights along with some scoring.

The first thing I've added to improve this is a "type" attribute. This tells you whether a given backlight is firmware-level (like ACPI), platform-level (like the various laptop drivers) or performs raw register writes (like a GPU driver). That lets userspace decide which interface is preferable. It'll typically be the ACPI interface, because that's the most likely to keep synchronisation and so avoid bizarre brightness bugs. The next thing has been to start fixing up the parent links. There's nothing we can do for the platform level devices, but the ACPI drivers could at least point at PCI devices rather than into ACPI space. That means that multi-GPU systems can now identify which interface to use based on the currently active GPU. Finally, I've started pointing the GPU-level backlight controls at the specific output rather than merely at the PCI device. This probably makes little difference for laptops as such, but once we start exposing backlight control for monitors that support ddcci it'll make things much easier as we'll know which backlight control corresponds to which monitor.

I've then written a small library that accepts information about the output and picks the "best" backlight for the device. It's obviously based on a pile of heuristics and there's a couple of bits of API that I suspect need to be nailed down yet, but it means that this code only needs to be written once. It's then simple to glue this into X drivers, which means that they can expose a "Backlight" xrandr property on each relevant display. That means that backlight control is then handled at the session level with the X server acting as the privileged agent, which simplifies a bunch of things and means we can finally let hal die entirely. Long-term this means we'll have unified backlight control for all of your displays, which is a wonderful thing.

Summary: We kind of suck right now, but there's a reasonably clear path to getting better.

Biella Coleman: Experiential Amnesia

So, conventional wisdom is that once you experience something first hand, it sits close to you, so that you can learn from it, think about it, and possibly invoke it. This rings true for me, except for one particular type of experience finishing a large and complicated project like writing a dissertation, taking PhD qualifying exams, like writing a very complicated review article. Once it is done and over with and a few months have walked away, I no longer can fathom, at all, how I even did it. It is as if I went through the experience and then amnesia set in, erasing and wiping out the fibers of events, emotions, and thoughts that went into making and finishing the project. I find this unnerving, for various reasons. First, this di-juncture is not one I experience with other experiences, even unpleasant ones, like pain (broken collarbone, burnt hand, terrible earache), for I am able, nearly always, to shore up some shadow of those experience. More practically, when I am faced again with needing to conquer what feels unconquerable (which, unsurprisingly, is my current predicament), I have no experiential reserve to guide me. Instead, it is like I am standing at a new shore, for the first time. I tell myself, I have done and I can do it but there is no concomitant emotional register or memory that assures me that this is in fact true. Maybe a few more projects like these and there will be some imprint to steer me in the future but somehow I suspect my experiential amnesia will remain the same.

Christian Perrier: Care about samba in squeeze?

If you do care about having good samba packages in squeeze, you can help. If you're in a hurry and don't want to read the blah-blah, just skip to the end of this story and read the last paragraph. Thanks to the confidence of the release team, we (samba packagers) have been "authorized" to upload samba 3.5.4 in unstable, thus targeting having that version in squeeze. Up to July, we were indeed targeting 3.4.8 for squeeze, on the assumption that, as usual, samba upstream releases need some maturation before being strong guarantee that no regression happens. In July we were ready to move and finally upload in unstable the 3.5 packages we kept in experimental until then. The final decision was to be taken during DebConf10. It was roughly taken with Steve Langasek, but....I couldn't upload immediately (most people know that working on major packages during DebConf is a dream)...and had holidays afteer. In the meantime, the freeze happened so we got theoretically screwed... Still, I could manage to convince the release team that long term support for samba 3.5 will certainly be better than 3.4...and that functionality in that version (particularly several Win7-related fixes and a much improved code for printing support) and we got a notice "please upload to unstable and come back to us in a few weeks". That happened, finally. So, now, we need YOU, samba users and admins, to test these packages. Merging our packaging branches was hard (thanks, Steve Langasek, for your help) and glitches are always possible. So, please TEST these packages by installing samba, winbind, libsmbclient and friends from unstable....and report bugs, preferrably the release critical ones....

Rapha&#235;l Hertzog: Can Debian achieve world domination without being on Facebook?

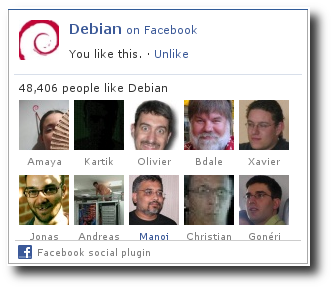
Debian Developers who like Debian on FacebookFacebook is not very popular among free software hackers. When I announced my Facebook page on identi.ca (see here) I got a few replies suggesting it was odd for me to use Facebook. Indeed there are many good reasons why Facebook should be avoided: it is a centralized and proprietary service that is not very privacy-friendly. But the truth is that lots of people are using it (even Debian developers, can you recognize them on the picture?) and some are using their Facebook news feed as their main source of news. You might wonder how many persons that represents, so here are the figures: the Debian Facebook page has 48,361 fans and the Ubuntu one has 247,932 fans. That s right, an announce put on the Debian facebook page would reach more persons than the most popular announce list that Debian is currently running (debian-announce@lists.debian.org has about 29,000 subscribers). Unfortunately that Debian Facebook page is empty and I don t even know who the administrator is. The Ubuntu page on the contrary is properly configured to relay news from The Fridge and Jono Bacon is posting some custom updates from time to time. Debian contributors regularly mention world domination as the ultimate goal of the universal operating system (I even feature this in my blog header banner! :-) ). But working towards world domination means in my opinion that we should communicate our ideals of freedom to as many people as possible, even if they are using a service that we don t want to promote. The Debian social contract acknowledges that some users have to use non-free software and we provide the non-free section for them. In the same spirit, I believe we must have a presence on Facebook. That does not mean that we endorse Facebook, and we should surely promote Joindiaspora once it s usable. But in the mean time we should reach out to Facebook users and allow them to follow us with the platform of their choice. That s the choice I recently made when I decided to setup a public facebook page featuring my free software work, my blog and my book. So if you are a Facebook user, click here to visit my page and click on Like if you want to follow this blog in your Facebook news feed. I also share interesting Debian or Ubuntu related articles that I discover while reading my RSS subscriptions. Below are the usual facebook widgets for the 3 pages quoted in this article (they might not show up if you read this article through an RSS feed):
<iframe allowtransparency="true" frameborder="0" scrolling="no" src="http://www.facebook.com/plugins/likebox.php?id=103161013077063&amp;width=292&amp;connections=0&amp;stream=false&amp;header=false&amp;height=62" style="border:none; overflow:hidden; width:292px; height:62px;"></iframe>
<iframe allowtransparency="true" frameborder="0" scrolling="no" src="http://www.facebook.com/plugins/likebox.php?id=9801962186&amp;width=292&amp;connections=0&amp;stream=false&amp;header=false&amp;height=62" style="border:none; overflow:hidden; width:292px; height:62px;"></iframe>
<iframe allowtransparency="true" frameborder="0" scrolling="no" src="http://www.facebook.com/plugins/likebox.php?id=6723083591&amp;width=292&amp;connections=0&amp;stream=false&amp;header=false&amp;height=62" style="border:none; overflow:hidden; width:292px; height:62px;"></iframe> Flattr this Share/Bookmark 14 comments Support my work

8 September 2010

Julien Danjou: Emacs, Org, whatever the weather!

Another week, another Emacs extension! I had (once again) a wonderful idea: what if I could have the weather forecasts in my Org agenda? Wouldn't that be wonderful? My quest started by looking for a service offering a good weather forecast API. I found nothing simple as the hidden Google Weather API, which is nice, but not documented. Not at all. Not a single line. Nah. Then, I wrote a google-weather extension, implementing a basic Emacs Lisp API to retrieve data from the Google service:

ELISP> (google-weather-data->forecast (google-weather-get-data "Paris"))
(((9 8 2010)
  (low "53")
  (high "63")
  (icon "http://www.google.com/ig/images/weather/rain.gif")
  (condition "Rain"))
 ((9 9 2010)
  (low "53")
  (high "69")
  (icon "http://www.google.com/ig/images/weather/chance_of_rain.gif")
  (condition "Scattered Showers"))
 ((9 10 2010)
  (low "54")
  (high "72")
  (icon "http://www.google.com/ig/images/weather/partly_cloudy.gif")
  (condition "Partly Cloudy"))
 ((9 11 2010)
  (low "55")
  (high "75")
  (icon "http://www.google.com/ig/images/weather/partly_cloudy.gif")
  (condition "Partly Cloudy")))
My API even implements data caching, which is nice to speed up the agenda display. By the way, I think my next job will be to hack on the url-cache feature of Emacs, which is utterly buggy and has probably never be used. But that's another topic. Finally, I just had to write another module on top of that to export the forecasts to Org. A screen shot is probably better than a long and boring explanation, so here's the result. My only regret is that the icons provided by Google are ugly squares, so I did not want to use them. On the other hand, I did not found any icon set that would have all the icons Google provides (around 20). So I felt back on the icon naming specification to map the Google images to standard images. Any better idea would be welcome, of course. All the information can be found on the Google Weather for Emacs extension homepage. Flattr this

Roland Mas: Gnus, Dovecot, OfflineIMAP, search: a HOWTO

A long time ago, when I was first introduced to email, I was using the Mail program from Unix. I quickly converted to Elm, then Mutt, which were both better in terms of interface. Then I found out about Gnus, and I wouldn't dream of letting it go now. However, Gnus has started showing its age several times, and several times have I needed to upgrade the way I was using it: first because I needed to sort and split email, then because I took the sorting out of Gnus and into Procmail for more advanced filtering (including spam filtering), then because I switched to storing the emails on an IMAP server so I could read them remotely from several computers. My setup as of a few days ago was functional, but since I have grown over time to splitting emails into several hundred folders, checking for new messages was becoming more and more boring. So it's time to jump in with all the cool kids and switch to a modern solution: still Gnus of course, but with Dovecot, OfflineIMAP for synchronisation, and let's add email searches into the mix while we're at it. My web searches didn't turn up a simple step-by-step HOWTO, but I assembled bits from different places, and here's my attempt at documenting my new setup. Goals Assumptions Dovecot setup We'll use Dovecot as a local IMAP server. And since we're lazy, we'll access it over a pipe, and dispense with the network part. OfflineIMAP setup OfflineIMAP is basically an optimised two-way synchronisation mechanism between two email repositories . We'll use it in IMAP-to-IMAP mode.
 [general]
 accounts = MyAccount
 pythonfile = .offlineimap.py
 [Account MyAccount]
 localrepository = LocalIMAP
 remoterepository = RemoteIMAP
 # autorefresh = 5
 # postsynchook = notmuch new
 [Repository LocalIMAP]
 type = IMAP
 preauthtunnel = MAIL=maildir:$HOME/Maildir /usr/lib/dovecot/imap
 holdconnectionopen = yes
 [Repository RemoteIMAP]
 type = IMAP
 remotehost = mail.example.com
 remoteuser = jsmith
 remotepass = swordfish
 ssl = yes
 nametrans = lambda name: re.sub('^INBOX.', '', name)
 # folderfilter = lambda name: name in [ 'INBOX.important', 'INBOX.work' ]
 # folderfilter = lambda name: not (name in [ 'INBOX.spam', 'INBOX.commits' ])
 # holdconnectionopen = yes
 maxconnections = 3
 # foldersort = lld_cmp
 # Propagate gnus-expire flag
 from offlineimap import imaputil
 def lld_flagsimap2maildir(flagstring):
   flagmap =  '\\seen': 'S',
              '\\answered': 'R',
              '\\flagged': 'F',
              '\\deleted': 'T',
              '\\draft': 'D',
              'gnus-expire': 'E' 
   retval = []
   imapflaglist = [x.lower() for x in flagstring[1:-1].split()]
   for imapflag in imapflaglist:
       if flagmap.has_key(imapflag):
           retval.append(flagmap[imapflag])
   retval.sort()
   return retval
 def lld_flagsmaildir2imap(list):
   flagmap =  'S': '\\Seen',
              'R': '\\Answered',
              'F': '\\Flagged',
              'T': '\\Deleted',
              'D': '\\Draft',
              'E': 'gnus-expire' 
   retval = []
   for mdflag in list:
       if flagmap.has_key(mdflag):
           retval.append(flagmap[mdflag])
   retval.sort()
   return '(' + ' '.join(retval) + ')'
 imaputil.flagsmaildir2imap = lld_flagsmaildir2imap
 imaputil.flagsimap2maildir = lld_flagsimap2maildir
 # Grab some folders first, and archives later
 high = ['^important$', '^work$']
 low = ['^archives', '^spam$']
 import re
 def lld_cmp(x, y):
   for r in high:
       xm = re.search (r, x)
       ym = re.search (r, y)
       if xm and ym:
           return cmp(x, y)
       elif xm:
           return -1
       elif ym:
           return +1
   for r in low:
       xm = re.search (r, x)
       ym = re.search (r, y)
       if xm and ym:
           return cmp(x, y)
       elif xm:
           return +1
       elif ym:
           return -1
   return cmp(x, y)
The first part of this file adds a new flag that OfflineIMAP will propagate back and forth. By default, only the standard IMAP flags are propagated; we also want to synchronize the gnus-expire flag that Gnus uses to mark expirable articles. It's a hack, but it works for now (maybe someday OfflineIMAP will propagate all the flags it finds?). The second part of that file can be dispensed with (and won't be used unless the foldersort option is uncommented in .offlineimaprc): it's only there to ensure that some important folders are propagated first, and some others go last. I don't know exactly how they are sorted by default, but I'd like the most important ones to come first, so I can start reading them while the archives and the spam are still being fetched. Gnus configuration
(require 'offlineimap)
(add-hook 'gnus-before-startup-hook 'offlineimap)
Bonus: email searches The simple way:
(require 'nnir)
This goes in your .gnus. Then your group buffer will get a new command. Mark some folders with #, then M-x gnus-group-make-nnir-group (or use the G G shortcut), and type in a set of keywords. This search is performed by the IMAP server (Dovecot), which may or may not be very efficient, especially if you select many folders. Bonus+: email searches, faster The real cool kids use Notmuch nowadays, at least for email indexing and searching. It's fast, it allows complex queries, and it's generally cool. The downside is that it uses up quite some disk space for its indices, in addition to the actual emails. For that reason I'll keep it to my main computer, and I'll stick to nnir on my laptop (which has the same setup apart from that).
(require 'notmuch)
(add-hook 'gnus-group-mode-hook 'lld-notmuch-shortcut)
(require 'org-gnus)
(defun lld-notmuch-shortcut ()
(define-key gnus-group-mode-map "GG" 'notmuch-search)
)
(defun lld-notmuch-file-to-group (file)
"Calculate the Gnus group name from the given file name.
"
(let ((group (file-name-directory (directory-file-name (file-name-directory file)))))
  (setq group (replace-regexp-in-string ".*/Maildir/" "nnimap+local:" group))
  (setq group (replace-regexp-in-string "/$" "" group))
  (if (string-match ":$" group)
      (concat group "INBOX")
    (replace-regexp-in-string ":\\." ":" group))))
(defun lld-notmuch-goto-message-in-gnus ()
"Open a summary buffer containing the current notmuch
article."
(interactive)
(let ((group (lld-notmuch-file-to-group (notmuch-show-get-filename)))
      (message-id (replace-regexp-in-string
                   "^id:" "" (notmuch-show-get-message-id))))
  (if (and group message-id)
      (progn 
  (switch-to-buffer "*Group*")
  (org-gnus-follow-link group message-id))
    (message "Couldn't get relevant infos for switching to Gnus."))))
(define-key notmuch-show-mode-map (kbd "C-c C-c") 'lld-notmuch-goto-message-in-gnus)
Wrap-up This setup can be replicated on several computers, of course. I have it on two, and there's no reason I couldn't have more. The flags do get propagated back and forth, including the Gnus-specific expirable flag. Accessing the local Dovecot is much faster than going through the DSL to the master IMAP server, and I'm pretty convinced that OfflineIMAP and its multi-threading is also faster than Gnus is, even talking to the same remote server. The email searching with Notmuch is a nice bonus, especially since they're fast too (and this despite my 8-year-old computer). There are a few minor glitches. I can live with them, but I should let you know anyway. Apart from that, I'm pretty happy with this new setup. So I hope this documentation will be useful to others, so I can spread the happiness around. Send your thanks to the authors of the software involved (Gnus, Dovecot, OfflineIMAP, offlineimap.el, Procmail, and so on). Let's see how many years I'll keep that system!

Michal &#268;iha&#345;: Let's try flattr too

It looks like quite popular thing on Planet Debian to start using flattr. I registered most of software on which I'm involved already week ago, but I did not have much time publicizing it. Surprisingly people have found things just on flattr without any external links. You can see all of them listed on my flattr profile. Today I decided to add my blog as a thing and integrated it to my blog, so you can now see flattr button under each post. I decided not to spread this into RSS, at least for now :-). If you have not yet heard about flattr it is social micropayment site (lot of buzzwords included, so it has to be cool, right?), where you need to register, put there little amount of money and it will be spread each month among projects you "flattr". Sounds like a nice idea for appreciating free software.

Next.

Previous.