Search Results: "tar"

25 December 2014

Russ Allbery: Review: Bad Pharma

Review: Bad Pharma, by Ben Goldacre
Publisher: Faber and Faber
Copyright: 2012, 2013
Printing: 2014
ISBN: 0-86547-806-6
Format: Trade paperback
Pages: 397
If you have previously read Bad Science by Ben Goldacre, it's doubtful you need me to do anything other than point out that he has a new book. Oh, and it's subtitled How Drug Companies Mislead Doctors and Harm Patients, and it's written with the same indignant determination, clear explanation, and appreciation for real science as Bad Science. If you haven't read Bad Science, I recommend it. You don't have to read it before Bad Pharma, but it's a more approachable start, and a funnier book. Bad Science opens with some obviously horrible examples, and slowly develops the tools required to analyze more advanced and deceptive quackery. Bad Pharma jumps straight into the deep end of statistical biases in data, how and why they're introduced, and why they undermine your health care. This is a more serious book than Bad Science, since it lacks the medical quackery that is so ludicrous it's funny. Everything in Bad Science is successfully sold to someone there are people who believe in candling but most readers of the book can laugh a bit that anyone would believe in such things before getting to the parts of the book where the quackery is widespread and kills people. Bad Pharma focuses on the mainstream pharmaceutical industry and the way that it distorts the scientific process, which leads to serious consequences quite quickly. Goldacre is more pointedly on a mission here than in his previous book. This is not just an expos . It includes detailed recommendations for how to make the drug evaluation process better, and some specific ethical recommendations for doctors to avoid being unduly influenced by drug company marketing. But before that, he provides the best detailed explanation of how the drug research and approval process is supposed to work that I've seen. There's also a lot of good information about how to detect trials and related studies that haven't been done properly, and how to separate marketing language from scientific evidence. Goldacre wisely does not get into all the details of how to do a trial properly, which would be way beyond the scope of this book, but he does provide valuable rules of thumb and red flags that indicate when someone is probably not doing the trial properly. A point that's both frustrating and enlightening, and made very well by this book, is that fixing many of the problems with the drug approval process is not that difficult. Fixing all of them would be exceedingly difficult, of course, since they involve humans, complex financial motivations, the effectiveness of propaganda, and talented people who are paid well to create favorable impressions for new drugs. But we could get quite significant benefits from a few straightforward enhancements of the existing drug approval process, such as requiring that all clinical trials be pre-registered and all trial results published as a prerequisite for any drug approval. Goldacre makes his case for these changes forcefully and persuasively, and with justified anger. The current situation is bad enough for people like me who are only potential patients with no urgent medical issues. For a practicing doctor like Goldacre, it's infuriating to be actively denied the information required to effectively save people's lives. Normally, I find books like this interesting, but depressing and frustratingly limited. It's easy to write books about abuses that currently exist, or the limitations of the current approach. It's much harder to do what Goldacre does here: clearly describe the goals and ideals of drug testing for the lay reader, detail how the current approaches fall short of that goals, and then propose practical and concrete ways to correct the situation. And keep the details interesting and entertaining enough that I enjoyed reading every page of a nearly 400 page book. This is not a book that will fill you with trust or enthusiasm for the medical establishment (anywhere in the world). But it's still oddly comforting: we do know how to do these things properly, and occasionally we even act on that knowledge. These problems are serious, but they should provoke outrage partly because they're correctable and yet aren't being corrected. And there are doctors like Goldacre who are trying to push medicine towards proper use of evidence, research, and knowledge, instead of commercial manipulation. Recommended if you have any interest at all in how medicine or scientific research is actually done, and what its pitfalls look like. Rating: 8 out of 10

24 December 2014

Chris Lamb: 8:20AM. Sunday, 22 December 2013

Running east into the sun, he hadn't seen another human for over half an hour. He navigates Westferry Circus and heads south, cutting from the road through to the riverside pathway. He keeps is breathing steady - no reason to hurry. The wind catches him from Westminster. It smells slightly salty but it's an ersatz attempt, nowhere near bracing enough to be a real sea breeze. Pressing on, the vacant citadel of Canary Wharf disappears behind him. But as the peninsula curves around, a man appears in the distance. Even half a mile away he looks out of place, or rather given the hour time. He's walking purposefully, but it doesn't feel the kind of route someone would be taking to work. He's not wearing quite enough clothes for the weather either, and homeless people are rarely made to feel welcome in the Docklands. His supermarket denim visibly flaps in the breeze. "Relaxed fit", they call it. When he gets within earshot the man cocks his head, not expecting to hear the regular cadence of approaching footsteps. He turns slightly to reveal he's cradling a large bottle of Coca-Cola, meekly wrapped in the swathing bands of two anonymously blue corner-shop plastic bags. The runner eyes the Coke greedily but can quickly see that it has already been opened, tainted. Although only a mouthful or so has gone, a brown froth sloshes against the top of the container. Amateur, he thinks. He'll regret that later. He looks back up to the man, who is now smiling at him. His left hand bccomes visible as he strides: a four-pack of Carling. The man laughs. "Oh, you and me mate are worlds apart!" the man shouts. It's immediately friendly. He starts to raise his Carling as but thinks better of it. It's momentarily awkward. "Worlds apart mate", the man continues. "Have a good one!" The runner smiles back. Only in time, the runner thinks. They both can't stop.

Gregor Herrmann: GDAC 2014/24

the last year hasn't been an easy one for debian. we've seen lots of fights, unproductive discussions, & in general behaviour which contributed to what enrico in his brilliant blog post called the "stink in the kitchen". people's feelings were hurt, some became less active, others resigned from a specific position or retired completely. it happened to me as well that reading through threads full of trolling, aggressiveness, finger-pointing, unrespectful or abusive behaviour, etc. made me frustrated, or sad, or angry, or all kinds of other negative feelings. but then I usually told myself: this is not the debian project as I know it; this is only a small part a part which urgently needs improvement! ; but if we only look at it alone, our picture of debian at large is distorted. the much bigger part of the debian life I know doesn't happen on this handful of high-profile mailing lists; it happens on dozens of specialized mailing lists, in many small IRC channels, in the BTS, & in in-person meetings. & what I see there is most of the time constructive, collaborative, respectful communication, & committed, helpful, funny, awesome people. the idea of this advent calendar was to give examples of some of my recent experiences which demonstrate what the bright side of debian is in my opinion & what contributes to my fun in debian. with the aim of sharing my impression that the proverbial "stink" is, if we take a step back, only one piece of the bigger picture, & that we shouldn't let ourselves get demotivated by only staring at this puzzle piece. thanks to all the awesome contributors for polishing existing & adding new shiny puzzle pieces to our common picture every day! finally: thanks for reading this series of posts, & especially thank you to all who provided positive feedback this in turn motivated me to follow through! & now: back to work, & don't forget to help cleaning the kitchen :)
this posting is part of GDAC (gregoa's debian advent calendar), a project to show the bright side of debian & why it's fun for me to contribute.

23 December 2014

Ulrike Uhlig: How to contribute to the AppArmor upstream profiles

If you want to contribute to existing/upstream AppArmor profiles, you need to create an account on Canonical s launchpad. You ll also need to upload an SSH key to be able to push your changes. You will also need to install Canonical s version control system, called Bazaar:
apt-get install bzr
Go or create a repository where you want to checkout the changes:
mkdir apparmor-dev
cd apparmor-dev
bzr branch lp:apparmor-profiles master
ls master
Define your identity like this:
bzr whoami "My Name <my@email.com>"
Bazaar does not handle branches like Git does, unfortunately. It is a little bit weird in first place that you will need to create a directory where you would create a copy of the master branch. You would then work on this branch and later ask for a merge and pull into the master branch.
mkdir myname
bzr branch master myname/pidgin
ls myname/pidgin
Then, start modifying the profiles using a test editor and test them. Testing is done through dis/enabling the profile.
Once done, you can push the changes to your distant repository:
bzr push
Then, you need to connect to Launchpad s web interface. Go to your page, and look for the branch you just pushed. Click on change branch details and link the branch to apparmor-profiles. Then you will be able to do a merge request through the webinterface.

Ulrike Uhlig: How does my AppArmor profile get into Debian?

I have spent the last days trying to understand the relationship between AppArmor, the AppArmor profiles and Debian s AppArmor profiles. Let me try to briefly introduce you to this. First of all, let me emphasize that one needs to distinguish between AppArmor, the kernel module, and the AppArmor profiles, which define rules for application confinement. As stated on the project s wiki:
The AppArmor project source is split between the kernel module, available in the Linux kernel and git development tree and the user space tools available in launchpad.
So, we can find the upstream AppArmor profile development taking place at Canonical s launchpad. The profiles which are developed there serve as a basis for those included in Debian. It is thus useful to try to contribute to this upstream when updating a profile for Debian. Since AppArmor 2.9 has been introduced, the rules of a profiles which are not applicable for a system are ignored. Thus, collaboration between different Linux distributions shipping AppArmor will become much simpler. In the aforementioned Ubuntu repository you can find the profiles that are currently in development. Once tested and ready, they are removed from this repository and finally included into the corresponding package. For example, the profile for Evince, the GNOME PDF viewer, is available in the evince package. In Debian on the contrary, there are only some packages which ship their own profiles. This concernes for example bind, clamav, cups, tor.
But many profiles are not yet included with their package, but instead delivered through the apparmor-profiles and apparmor-profiles-extra packages. These are maintained by the the Debian AppArmor packaging team. The team takes care of merging changes from the upstream profiles into Debian. Today, the relationship between Upstream and Debian looks like this:

Upstream/bzr

Debian source package

Debian binary package

Ubuntu source package

Ubuntu binary package

apparmor

apparmor

apparmor-profiles

-

-

apparmor-profiles

apparmor-profiles-extra

apparmor-profiles-extra

-

-

ubuntu-evince

apparmor-profiles-extra

apparmor-profiles-extra

evince

evince

In the future, this should change. It would indeed be desirable that package maintainers include profiles with the packages they maintain and take care of updating them accordingly when the package itself is updated. It is much more logical to to it that way, as changes in a package like Pidgin or Evince can occur at a different point in time then when the apparmor-profiles-extra package is updated. I started working on a documentation for Debian Package Maintainers which describes how to do this.

Vincent Bernat: Eudyptula Challenge: superfast Linux kernel booting

The Eudyptula Challenge is a series of programming exercises for the Linux kernel, that start from a very basic Hello world kernel module, moving on up in complexity to getting patches accepted into the main Linux kernel source tree.
One of the first tasks of this quite interesting challenge is to compile and boot your own kernel. eudyptula-boot is a self-contained shell script to boot any kernel image to a shell. It is packed with the following features: In the following video, eudyptula-boot is used to boot the host kernel and execute a few commands:
In the next one, we use it to boot a custom kernel with an additional system call. This is the fifteenth task of the Eudyptula Challenge. A test program is used to check that the system call is working as expected. Additionaly, we demonstrate how to attach a debugger to the running kernel.
While this hack could be used to run containers3 with an increased isolation, the performance of the 9p filesystem is unfortunately quite poor.

  1. The only requirement is to have 9p virtio support enabled. This can easily be enabled with make kvmconfig.
  2. Only udev is started.
  3. A good way to start a container is to combine --root, --force and --exec parameters. Add --readwrite to the mix if you want to keep the modifications.

Russ Allbery: Review: Wakulla Springs

Review: Wakulla Springs, by Andy Duncan & Ellen Klages
Publisher: Tor
Copyright: October, 2013
ASIN: B00EWZDPH4
Format: Kindle
Pages: 99
This is another nominee for the 2014 Hugo Awards (for works published in 2013), this time in the novella category. In this case, though, I read the free ebook version from Tor (Macmillan) rather than the version from the voter packet, since I usually grab all the free ebooks of Tor.com stories. (Even if I'm quite behind in reading them, since I don't read much short fiction.) As an independently-published novella, it gets its own review in the book category. Wakulla Springs is the story of three generations (and four protagonists) who lived near or visited Wakulla Springs in the Florida panhandle. This is a real place: a huge freshwater springs and underwater cave system, now protected as a national park. Two of the four episodes in this story revolve around the filming of movies: a Tarzan movie and Creature from the Black Lagoon. This actually happened as well, although of course the story takes liberties with the details. This is also the story of race relations in the American deep south: the tense and uncertain interactions between black locals and rich white people, both locals and people from the film industry who came for a brief time and then left again. It's also a story about water, swimming, and the sense of being part of the water and knowing it well. This story doesn't develop any particular point; rather, it's more of a collection of character sketches, grabbing moments in time, glimpsing what it's like to cross racial barriers and to feel at home with one's choices. It's also, in a nicely subtle way, about encountering mythical creatures that are not part of one's world. To the locals, the film stars who visit Wakulla Springs are as wild and strange as the imagined creatures of the swamp, and in their way even more foreign. What this is not, though, is science fiction, or even fantasy. One of the complaints I'd heard about Wakulla Springs in the context of the Hugos was that it didn't qualify as a genre story. I'm usually inclined to dismiss these sorts of complaints, since they're often put forth by people with a far narrower definition of genre than mine. But, having read this story, I have to concur. It's very well-written and engaging, but it's not genre in any sense that I'd define it. There are some rare mentions of mythical creatures, but only in ways that are part of the setting, and which are no more fantastic than I'd expect from many mainstream stories. I'm a bit baffled why an SFF publisher would have bought it for an explicitly SFF forum; I have to assume that it's just because it's well-written and the authors have both written SFF. That said, even though this is not the sort of story I'd normally seek out, I'm still glad I read it. I thought the best part of the story was the first, which follows a black woman who takes a job at the Wakulla Springs resort during the filming of a Tarzan movie. The color lines are simply taken for granted by everyone, but Johnny Weissmuller comes off very well in his fictional representation and adds an enthusiastic energy that plays off well against the thoughtful care of the protagonist. The second part echoes this with a boy as the protagonist, but shifts a generation later. This means the color line is fought instead of simply assumed, although with limited success. I thought this part of the story had the best descriptions of the joy of swimming, and once again the movie folks bring a disruptive and positive change to the tightly-drawn lines of local roles and politics. The third and fourth parts I found slighter, elaborating on the story by showing the reader glimpses of the later life of the first two protagonists, but not, I thought, adding anything fundamental to the story. I'm not sure this would be satisfying if you were looking for a science fiction or fantasy story, but it's a solid mainstream story about race, class, and the joy of knowing and feeling a place. It captures an angle of Hollywood that I've rarely seen in movies: a disruptive and almost subversive playfulness and energy that doesn't fix problems but that does provide moments of escape from the realities of the world, even outside of the film. Worth reading, particularly since it's free. Rating: 7 out of 10

22 December 2014

Michael Prokop: Ten years of Grml

* On 22nd of October 2004 an event called OS04 took place in Seifenfabrik Graz/Austria and it marked the first official release of the Grml project. Grml was initially started by myself in 2003 I registered the domain on September 16, 2003 (so technically it would be 11 years already :)). It started with a boot-disk, first created by hand and then based on yard. On 4th of October 2004 we had a first presentation of grml 0.09 Codename Bughunter at Kunstlabor in Graz. I managed to talk a good friend and fellow student Martin Hecher into joining me. Soon after Michael Gebetsroither and Andreas Gredler joined and throughout the upcoming years further team members (Nico Golde, Daniel K. Gebhart, Mario Lang, Gerfried Fuchs, Matthias Kopfermann, Wolfgang Scheicher, Julius Plenz, Tobias Klauser, Marcel Wichern, Alexander Wirt, Timo Boettcher, Ulrich Dangel, Frank Terbeck, Alexander Steinb ck, Christian Hofstaedtler) and contributors (Hermann Thomas, Andreas Krennmair, Sven Guckes, Jogi Hofm ller, Moritz Augsburger, ) joined our efforts. Back in those days most efforts went into hardware detection, loading and setting up the according drivers and configurations, packaging software and fighting bugs with lots of reboots (working on our custom /linuxrc for the initrd wasn t always fun). Throughout the years virtualization became more broadly available, which is especially great for most of the testing you need to do when working on your own (meta) distribution. Once upon a time udev became available and solved most of the hardware detection issues for us. Nowadays X.org doesn t even need a xorg.conf file anymore (at least by default). We have to acknowledge that Linux grew up over the years quite a bit (and I m wondering how we ll look back at the systemd discussions in a few years). By having Debian Developers within the team we managed to push quite some work of us back to Debian (the distribution Grml was and still is based on), years before the Debian Derivatives initiative appeared. We never stopped contributing to Debian though and we also still benefit from the Debian Derivatives initiative, like sharing issues and ideas on DebConf meetings. On 28th of May 2009 I myself became an official Debian Developer. Over the years we moved from private self-hosted infrastructure to company-sponsored systems, migrated from Subversion (brr) to Mercurial (2006) to Git (2008). Our Zsh-related work became widely known as grml-zshrc. jenkins.grml.org managed to become a continuous integration/deployment/delivery home e.g. for the dpkg, fai, initramfs-tools, screen and zsh Debian packages. The underlying software for creating Debian packages in a CI/CD way became its own project known as jenkins-debian-glue in August 2011. In 2006 I started grml-debootstrap, which grew into a reliable method for installing plain Debian (nowadays even supporting installation as VM, and one of my customers does tens of deployments per day with grml-debootstrap in a fully automated fashion). So one of the biggest achievements of Grml is from my point of view that it managed to grow several active and successful sub-projects under its umbrella. Nowadays the Grml team consists of 3 Debian Developers Alexander Wirt (formorer), Evgeni Golov (Zhenech) and myself. We couldn t talk Frank Terbeck (ft) into becoming a DM/DD (yet?), but he s an active part of our Grml team nonetheless and does a terrific job with maintaining grml-zshrc as well as helping out in Debian s Zsh packaging (and being a Zsh upstream committer at the same time makes all of that even better :)). My personal conclusion for 10 years of Grml? Back in the days when I was a student Grml was my main personal pet and hobby. Grml grew into an open source project which wasn t known just in Graz/Austria, but especially throughout the German system administration scene. Since 2008 I m working self-employed and mainly working on open source stuff, so I m kind of living a dream, which I didn t even have when I started with Grml in 2003. Nowadays with running my own business and having my own family it s getting harder for me to consider it still a hobby though, instead it s more integrated and part of my business which I personally consider both good and bad at the same time (for various reasons). Thanks so much to anyone of you, who was (and possibly still is) part of the Grml journey! Let s hope for another 10 successful years! Thanks to Max Amanshauser and Christian Hofstaedtler for reading drafts of this.

Dirk Eddelbuettel: BH release 1.55.0-1

A new release of BH, our package providing (a large part of the) Boost C++ libraries as a set of template headers for use by R, is now on CRAN. There are two changes. First, we upgraded to Boost 1.55. While Boost 1.57 is now current, I am playing it somewhat safe and conservative here by relying on what is the current version in Debian (and Ubuntu). I even started from the Debian tarball. This ensures we include nothing not in accordance with the Debian Free Software Guidelines (as they are a good proxy for what is acceptable to CRAN). The second change was the addition of Boost.Geometry as requested in issue ticket 5. This may be a good time to recall that best way to get in touch for desired additions in BH are the mailing list or the issue tracker at the GitHub repo. A brief summary of changes from the NEWS file (which we failed to update for the release; the text below is however now in the repo):
Changes in version 1.55.0-1 (2014-12-21)
Courtesy of CRANberries, there is also a (very long!) diffstat report for the most recent release. Comments and suggestions are welcome via the mailing list or the issue tracker at the GitHubGitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Craig Small: Mudlet 3 beta

A break from wordpress, I was trying to get the beta version of mudlet 3.0 compiling. On the surface the program looks a lot like the existing v2.0 that is currently within Debian. The developers have switched from qt4 to qt5 which means a lot of dependency fun for me but I got there in the end. As it is only a beta and not their final release, the package is located within the Debian experimental release. Once 3.0 hits a final release, I ll switch it to sid. If you do use the current mudlet, give 3.0 a try. I d be interested to know what you think. For people that have not heard of mudlet before, it is a mud client. mud stands for Multi User Dungeon, which is a multiplayer text-only game. While you can use something as simple as telnet to connect to a mud server, most people use some sort of specialised client. The advantages are you can display extra information (such a health stats) in a different window as well as aliases (macros or special commands, basically the same idea as a bash alias) and triggers (commands that are run depending on what the mud server sends you). The triggers take away some of the repeated things you may have to do, such as sipping a health tonic when your health level drops below some limit. One thing you might notice in the experimental 3.0 beta is that the icon is missing. lintian picked up that the license was wrong; it was by-nc which meant it can t go into main. I ve removed the icon until upstream sorts it out.

21 December 2014

Russ Allbery: Review: 2014 Hugos: Novelettes

Review: 2014 Hugos: Novelettes, edited by Loncon 3
Publisher: Loncon 3
Copyright: 2014
Format: Kindle
This is another weird "book review" covering the Hugo-nominated novelettes for the 2014 Hugos (given for works published in 2014) at Loncon 3, the 2014 Worldcon. The "editor" is the pool of attendees and supporting members who chose to nominate works, all of which had been previously edited by other editors in their original publication. I received all of these as part of the Hugo voter's packet for being a supporting member, but they all appear to be available for free on the Internet (at least at the time of this writing). "The Exchange Officers" by Brad Torgersen: An okay, if not particularly ground-breaking, military SF story, ruined for me by the ham-handed introduction of superficial jingoism. The protagonists are doing a tour as remote operators of humanoid battle suits in orbit: not a new premise, but a servicable one. Since this is military SF, they predictably have to defend a space installation against attackers. So we get a bit of drama, a bit of zero-g combat, and the fun of people learning how to remotely operate suits. You've probably read this before, but it passes the time reasonably well. Unfortunately, Torgersen decided to make the villains the Chinese military for no adequately-explained reason. (Well, I'm being kind; I suspect the reason is the standard yellow peril nonsense, but that's less generous.) So there is snide commentary about how only the military understand the Chinese threat and a fair bit of old-fashioned jingoism mixed in to the story, to its detriment. If you like this sort of thing, it's a typical example, although it escapes me why people thought it was exceptional enough to warrant nomination. (5) "The Lady Astronaut of Mars" by Mary Robinette Kowal: Once again, my clear favorite among the stories also won, which is a lovely pattern. Elma was the female astronaut in an alternate history in which manned space exploration continued to grow, leading to permanent settlement on Mars. She spent lots of time being photographed, being the smiling face of the space program, while her husband worked on the math and engineering of the launches. Now, she's an old woman, taking care of her failing and frail husband, her career behind her. Or so she thinks, before an offer that forces an impossible choice between space and staying with her husband for his final days. This is indeed the tear-jerker that it sounds like, but it's not as maudlin as it might sound. Kowal does an excellent job with Elma's characterization: she's no-nonsense, old enough to be confident in her opinions, and knows how to navigate through the world. The story is mixed with nostalgia and memories, including a reminder of just what Elma meant to others. It touches on heroism, symbolism, and the horrible choices around dying loved ones, but I thought it did so deftly and with grace. I was expecting the story to be too obvious, but I found I enjoyed the quotidian feel. It's not a story to read if you want to be surprised, but I loved the small touches. (9) "Opera Vita Aeterna" by Vox Day: Before the review, a note that I consider obligatory. The author of this story is an aggressively misogynistic white supremacist, well-known online for referring to black people as savages and arguing women should not be allowed to vote. To what extent you choose to take that into account when judging his fiction is up to you, but I don't think it should go unsaid. "Opera Vita Aeterna" is the story of a monastery in a typical fantasy world (at least as far as one can tell from this story; readers of Vox Day's fantasy series will probably know more background). At the start of the story, it gets an unexpected visit from an elf. Not just any elf, either, but one of the most powerful magicians of his society. He comes to the monastery out of curiousity about the god that the monks worship and stays for a project of illuminating their scriptures, while having theological debates with the abbot. This story is certainly not the offensive tirade that you might expect from its author. Its biggest problem is that nothing of substance happens in the story, either theologically or via more conventional action. It's a lot of description, a lot of talking, a lot of warmed-over Christian apologetics that dodges most of the hard problems, and a lot of assertions that the elf finds something of interest in this monastery. I can believe this could be the case, but Vox Day doesn't really show why. There is, at the end of the story, some actual drama, but I found it disappointing and pointless. It leads nowhere. The theology has the same problem: elves supposedly have no souls, which is should be the heart of a theological question or conflict Vox Day is constructing, but that conflict dies without any resolution. We know nothing more about the theology of this world at the end of the story than we do at the beginning. Some of the descriptions here aren't bad, and the atmosphere seems to want to develop into a story. But that development never happens, leaving the whole work feeling fundamentally pointless. (4) "The Truth of Fact, the Truth of Feelng" by Ted Chiang: This is another oddly-constructed story, although I think a bit more successful. It's a story in two interwoven parts. One is a fictional essay, told in a non-fiction style, about a man living in a future world with ubiquitous life recording and very efficient search software. Any part of one's life can be easily found and reviewed. The other is the story of a boy from a tribal culture during European colonialism. He learns to read and write, and from that a respect for written records, which come into conflict with the stories that the tribe elders tell about the past. The purpose of both of these stories is to question both the value and the implications of recording everything in a way that preserves and guarantees the facts instead of individual interpretations. The boy's story calls this into question; the narrator's story offers ambiguous support for its value and a deeper plea for giving people space to change. I found the style a bit difficult to get used to, since much of it did not feel like a story. But it grew on me as I read it, and the questions Chiang raises have stuck with me since. The problem of how and when to allow for change in others when we have perfect (or at least vastly improved) memory is both important and complicated, and this is one of the better presentations of the problem that I've seen. It's more of a think-y piece, and closer to non-fiction than a story, but I thought it was worth reading. (8) "The Waiting Stars" by Aliette de Bodard: I keep wanting to like de Bodard's space opera world of AIs and living ships, but it never quite works for me. I've read several stories set in this universe now, and it has some neat ideas, but I always struggle with the characters. This story at least doesn't have quite as much gruesome pregnancy as the previous ones (although there's still some). "The Waiting Stars" opens with a raid on a ship graveyard, an attempt to rescue and "reboot" an AI starship under the guidance of another Mind. This is intermixed with another story about a woman who was apparently rescued in childhood from birthing ship Minds and raised in a sort of foster institution. This feels like a flashback at first, but its interaction with the rest of the story is something more complicated. The conceptual trick de Bodard pulls here is thought-provoking, but once again I struggled to care about all of the characters. I also found the ending discouraging and unsatisfying, which didn't help. Someone who isn't me might really like this story, but it wasn't my thing. (6) Rating: 6 out of 10

Steve McIntyre: UEFI Debian installer work for Jessie, part 2

A month ago , I wrote about my plans for improved (U)EFI support in Jessie. It's about time I gave an update on progress! I spoke about adding support for installing grub-efi into the removable media path (#746662). That went into Debian's grub packages already, but there were a couple of bugs. First of all, the code could end up prompting people about EFI questions even when they didn't have any grub-efi packages installed. Doh! (#773004). Then there was an unexpected bug with case-insensitive file name handling on FAT/VFAT filesystems (#773092). I've posted (and tested!) patches to fix both, hopefully in an upload any day now. Next, I mentioned getting i386 UEFI support going again. This is a major feature that a lot of people have been asking for. It's also going to involve quite a bit of effort... Our existing (amd64) UEFI-capable images in Debian use the standard x86 El Torito CD boot method, with two boot images provided. One of these images gives us the traditional isolinux BIOS-boot support. The second option is an alternate El Torito image, including at a 64-bit version of grub-efi. For most machines, this works just fine - the BIOS or UEFI firmware will automatically pick the correct image and everybody's happy. This even works on our multi-arch i386/amd64 CDs and DVDs - isolinux will boot either kernel from the first El Torito image, or the alternate UEFI image is amd64 only. However, I can now see that there's been a long-standing issue with those multi-arch images, and it's to do with Macs. On the advice of Matthew Garrett, I've borrowed an old 32-bit Intel Mac to help testing, and it's quite instructive in terms of buggy firmware! The firmware on older 32-bit Intel Macs crashes hard when it detects more than one El Torito boot image, and I've now seen this happen myself. I've not had any bug reports about this, so I can only assume that we haven't had many users try that image. As far as I can tell, they've been using the normal i386 images in BIOS boot mode, and then struggling to get bootloaders working afterwards. There are a number of different posts on the net explaining how to do that. That's OK, but... If I now start adding 32-bit UEFI support to our standard set of i386 images, this will prevent users of old Macs from installing Debian. I could just say "screw it" and decide to not support those users at all, but that's not a very nice thing to do. If we want to continue to support them and add 32-bit UEFI support, I'll have to add another flavour of i386 image, either a "Mac special" or a "32-bit UEFI special". I'm not keen on doing that if I could avoid it, but the two options are mutually exclusive. Given the Mac problem is only on older hardware which (hopefully!) will be dying out, I'll probably pick that one as the special-case CD, and I'll make an extra netinst flavour only for those users to boot off. So, I've started playing with i386 UEFI stuff in the last couple of weeks too. I almost immediately found some showstopper behaviour bugs in the i386 versions of efivar and efibootmgr (#773412 and #773007), but I've debugged these with our Debian maintainer (Jared Dominguez) and the upstream developer (Peter Jones) and fixes should be in Jessie very soon. As I mentioned last month, the machines that most people have been requesting support for are the latest Bay Trail-based laptops and tablets. There are using 64-bit Intel Atom CPUs, but crippled with 32-bit UEFI firmware with no BIOS compatibility mode. This makes for some interesting issues. It's probably impossible to get a true answer why these machines are so broken by design, but there are several rumours. As far as I can see, most of these machines seem to ship with a limited version of 32-bit Windows 8.1. 32-bit Windows is smaller than 64-bit Windows, so fits much better in limited on-board storage space. But 32-bit Windows won't boot from 64-bit UEFI, so the firmware needed buggering to match. Ugh! To support these Bay Trail machines properly, we'll want to add a 32-bit UEFI installation option to our 64-bit images. I can tweak our CDs so that both 32-bit and 64-bit versions of grub-efi are included, and the on-board UEFI will load the right one needed. Then I'll need to make sure that all the 64-bit images also include grub-efi-ia32-bin from now on. With some extra logic, we'll need to remember that these new machines need that package installing instead of grub-efi-amd64-bin. It shouldn't be too hard, but let's see! :-) So, I've been out and bought one of these machines, an Asus X205TA. Lucas agreed that Debian will reimburse me (thanks!), so I'm not stuck with spending my own money on an otherwise unwanted machine! I can see via Google that none of the mainstream Linux distros support the Bay Trail machines fully yet, so there's not a lot of documentation yet. Initial boot on the new machine was easy using a quick-hack i386 UEFI image on USB, but from there everything went downhill quickly. I'll need to investigate some more, but the laptop's own keyboard and trackpad are not detected by the installer system. Neither is its built-in WiFi. Yay! I had to go and dig out a USB hub to connect the installer image USB key, a keyboard, mouse and a USB hard drive to the machine, as it only has 2 USB ports. I've taken a complete backup of the on-board 32GB flash before I start experimenting, so I can restore the machine back to its virgin state for future testing. I guess I now have a project to keep me busy over Christmas...! In other news, we've been continuing work on UEFI support for and within the new arm64 port. My ARM/Linaro colleague Leif Lindholm has been back-porting upstream kernel features and bug fixes to make d-i work, and filing Debian bugs when silly things break on arm64 because people don't think about other architectures (e.g #773311, doh!). As there are more and more people interested in (U)EFI support these days, I've also proposed that we create a new debian-efi mailing list to help focus discussion. See #773327 and follow up there if you think you'd use the list too! You can help! Same as 2 years ago, I'll need help testing some of these images. For the 32-bit UEFI support, I now have some relevant hardware myself, but testing on other machines too will be very important! I'll start pushing unofficial Jessie EFI test images shortly - watch this space.

20 December 2014

Mark Brown: Adventures with ARM server

I recently got a CubieTruck with a terabyte SSD to use as a general always on server. This being an ARM board rather than a PC (with a rather nice form factor it s basically the same size as a SSD) you d normally expect a blog post about it to include instructions for kernels and patches and so on but with these systems and current Debian testing there s no need Debian works out of the box (including our standard kernel) on it, the instructions worked easily and I now have a new machine sitting quietly in the corner serving away. Sadly it being a dual core A7 it s not got the grunt to replace my kernel build test system, an ARM allmodconfig takes eleven and a bit hours as opposed to a little less than twenty minutes on my desktop (which does draw well over an order of magnitude more power doing it), but otherwise you d never notice the difference when using the system. The upshot of all this is that actually there s no real adventure at all; for systems like these where the system vendors and the communities around them are doing the right things and working well with upstream things just work as you d expect with minimal effort. The one thing that s noticeably different from installing on a PC and really could do with improving is that instead of being shipped as part of the board the boot firmware has to be written to a SD card, something that could be addressed as easily as simply shipping a suitably programmed SD card in the box even without any other modification of the hardware, though on board flash would be even nicer.

Rudy Godoy: Apache Phoenix for Cloudera CDH

Apache Phoenix is a relational database layer over HBase delivered as a client-embedded JDBC driver targeting low latency queries over HBase data. Apache Phoenix takes your SQL query, compiles it into a series of HBase scans, and orchestrates the running of those scans to produce regular JDBC result sets. What the above statement means for developers or data scientists is that you can talk SQL to your HBase cluster. Sounds good right? Setting up Phoenix on Cloudera CDH can be really frustrating and time-consuming. I wrapped-up references from across the web with my own findings to have both play nice. Building Apache Phoenix Because of dependency mismatch for the pre-built binaries, supporting Cloudera s CDH requires to build Phoenix using the versions that match the CDH deployment. The CDH version I used is CDH4.7.0. This guide applies for any version of CDH4+. Note: You can find CDH components version in the CDH Packaging and Tarball Information section for the Cloudera Release Guide . Current release information (CDH5.2.1) is available in this link. Preparing Phoenix build environment Phoenix can be built using maven or gradle. General instructions can be found in the Building Phoenix Project webpage. Before building Phoenix you need to have: Checkout correct Phoenix branch Phoenix has two major release versions: Clone the Phoenix git repository
git clone https://github.com/apache/phoenix.git
Work with the correct branch
git fetch origin
git checkout 3.2
Modify dependencies to match CDH Before building Phoenix, you will need to modify the dependencies to match the version of CDH you are trying to support. Edit phoenix/pom.xml and do the following changes: Add Cloudera s Maven repository
+  <repository>
+  <id>cloudera</id>
+  https://repository.cloudera.com/artifactory/cloudera-repos/
+  </repository>
Change component versions to match CDH s.
  
-  <hadoop-one.version>1.0.4</hadoop-one.version>
-  <hadoop-two.version>2.0.4-alpha</hadoop-two.version>
+  <hadoop-one.version>2.0.0-mr1-cdh4.7.0</hadoop-one.version>
+  <hadoop-two.version>2.0.0-cdh4.7.0</hadoop-two.version>
  <!-- Dependency versions -->
-  <hbase.version>0.94.19
+  <hbase.version>0.94.15-cdh4.7.0
  <commons-cli.version>1.2</commons-cli.version>
-  <hadoop.version>1.0.4
+  <hadoop.version>2.0.0-cdh4.7.0
  <pig.version>0.12.0</pig.version>
  <jackson.version>1.8.8</jackson.version>
  <antlr.version>3.5</antlr.version>
  <log4j.version>1.2.16</log4j.version>
  <slf4j-api.version>1.4.3.jar</slf4j-api.version>
  <slf4j-log4j.version>1.4.3</slf4j-log4j.version>
-  <protobuf-java.version>2.4.0</protobuf-java.version>
+  <protobuf-java.version>2.4.0a</protobuf-java.version>
  <commons-configuration.version>1.6</commons-configuration.version>
  <commons-io.version>2.1</commons-io.version>
  <commons-lang.version>2.5</commons-lang.version>
Change target version, only if you are building for Java 6. CDH4 is built for JRE 6.
  <artifactId>maven-compiler-plugin</artifactId>
  <version>3.0</version>
  <configuration>
-  <source>1.7</source>
-  <target>1.7</target>
+  <source>1.6</source>
+  <target>1.6</target>
  </configuration>
Phoenix building Once, you have made the changes you are set to build Phoenix. Our CDH4.7.0 cluster uses Hadoop 2, so make sure to activate the hadoop2 profile.
mvn package -DskipTests -Dhadoop.profile=2
If everything goes well, you should see the following result:
[INFO] ------------------------------------------------------------------------
[INFO] Reactor Summary:
[INFO]
[INFO] Apache Phoenix .................................... SUCCESS [2.729s]
[INFO] Phoenix Hadoop Compatibility ...................... SUCCESS [0.882s]
[INFO] Phoenix Core ...................................... SUCCESS [24.040s]
[INFO] Phoenix - Flume ................................... SUCCESS [1.679s]
[INFO] Phoenix - Pig ..................................... SUCCESS [1.741s]
[INFO] Phoenix Hadoop2 Compatibility ..................... SUCCESS [0.200s]
[INFO] Phoenix Assembly .................................. SUCCESS [30.176s]
[INFO] ------------------------------------------------------------------------
[INFO] BUILD SUCCESS
[INFO] ------------------------------------------------------------------------
[INFO] Total time: 1:02.186s
[INFO] Finished at: Mon Dec 15 13:18:48 PET 2014
[INFO] Final Memory: 45M/1330M
[INFO] ------------------------------------------------------------------------
Phoenix Server component deployment Since Phoenix is a JDBC layer on top of HBase a server component has to be deployed on every HBase node. The goal is to have Phoenix server component added to HBase classpath. You can achieve this goal either by copying the server component directly to HBase s lib directory, or copy the component to an alternative path then modify HBase classpath definition. For the first approach, do:
cp phoenix-assembly/target/phoenix-3.2.3-SNAPSHOT-server.jar /opt/cloudera/parcels/CDH/lib/hbase/lib/
Note: In this case CDH is a synlink to the current active CDH version. For the second approach, do:
cp phoenix-assembly/target/phoenix-3.2.3-SNAPSHOT-server.jar /opt/phoenix/
Then add the following line to /etc/hbase/conf/hbase-env.sh
/etc/hbase/conf/hbase-env.sh
export HBASE_CLASSPATH_PREFIX=/opt/phoenix/phoenix-3.2.3-SNAPSHOT-server.jar
Wether you ve used any of the methods, you have to restart HBase. If you are using Cloudera Manager, restart the HBase service. To validate that Phoenix is on HBase class path, do:
sudo -u hbase hbase classpath   tr ':' '\n'   grep phoenix
Phoenix server validation Phoenix provides a set of client tools that you can use to validate the server component functioning. However, since we are supporting CDH4.7.0 we ll need to make few changes to such utilities so they use the correct dependencies. phoenix/bin/sqlline.py: sqlline.py is a wrapper for the JDBC client, it provides a SQL console interface to HBase through Phoenix.
index f48e527..bf06148 100755
--- a/bin/sqlline.py
+++ b/bin/sqlline.py
@@ -53,7 +53,8 @@ colorSetting = "true"
 if os.name == 'nt':
  colorSetting = "false"
-java_cmd = 'java -cp "' + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
+extrajars="/opt/cloudera/parcels/CDH/lib/hadoop/lib/commons-collections-3.2.1.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-auth-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-common-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcerls/CDH/lib/oozie/libserver/hbase-0.94.15-cdh4.7.0.jar"
+java_cmd = 'java -cp ".' + os.pathsep + extrajars + os.pathsep + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
  '" -Dlog4j.configuration=file:' + \
  os.path.join(phoenix_utils.current_dir, "log4j.properties") + \
  " sqlline.SqlLine -d org.apache.phoenix.jdbc.PhoenixDriver \
phoenix/bin/psql.py: psql.py is a wrapper tool that can be used to create and populate HBase tables.
index 34a95df..b61fde4 100755
--- a/bin/psql.py
+++ b/bin/psql.py
@@ -34,7 +34,8 @@ else:
 # HBase configuration folder path (where hbase-site.xml reside) for
 # HBase/Phoenix client side property override
-java_cmd = 'java -cp "' + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
+extrajars="/opt/cloudera/parcels/CDH/lib/hadoop/lib/commons-collections-3.2.1.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-auth-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-common-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcerls/CDH/lib/oozie/libserver/hbase-0.94.15-cdh4.7.0.jar"
+java_cmd = 'java -cp ".' + os.pathsep + extrajars + os.pathsep + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
  '" -Dlog4j.configuration=file:' + \
  os.path.join(phoenix_utils.current_dir, "log4j.properties") + \
  " org.apache.phoenix.util.PhoenixRuntime " + args
After you have done such changes you can test connectivity by issuing the following commands:
./bin/sqlline.py zookeeper.local
Setting property: [isolation, TRANSACTION_READ_COMMITTED]
issuing: !connect jdbc:phoenix:zookeeper.local none none org.apache.phoenix.jdbc.PhoenixDriver
Connecting to jdbc:phoenix:zookeeper.local
14/12/16 19:26:10 WARN conf.Configuration: dfs.df.interval is deprecated. Instead, use fs.df.interval
14/12/16 19:26:10 WARN conf.Configuration: hadoop.native.lib is deprecated. Instead, use io.native.lib.available
14/12/16 19:26:10 WARN conf.Configuration: fs.default.name is deprecated. Instead, use fs.defaultFS
14/12/16 19:26:10 WARN conf.Configuration: topology.script.number.args is deprecated. Instead, use net.topology.script.number.args
14/12/16 19:26:10 WARN conf.Configuration: dfs.umaskmode is deprecated. Instead, use fs.permissions.umask-mode
14/12/16 19:26:10 WARN conf.Configuration: topology.node.switch.mapping.impl is deprecated. Instead, use net.topology.node.switch.mapping.impl
14/12/16 19:26:11 WARN conf.Configuration: fs.default.name is deprecated. Instead, use fs.defaultFS
14/12/16 19:26:11 WARN util.NativeCodeLoader: Unable to load native-hadoop library for your platform... using builtin-java classes where applicable
14/12/16 19:26:12 WARN conf.Configuration: fs.default.name is deprecated. Instead, use fs.defaultFS
Connected to: Phoenix (version 3.2)
Driver: PhoenixEmbeddedDriver (version 3.2)
Autocommit status: true
Transaction isolation: TRANSACTION_READ_COMMITTED
Building list of tables and columns for tab-completion (set fastconnect to true to skip)...
77/77 (100%) Done
Done
sqlline version 1.1.2
0: jdbc:phoenix:zookeeper.local>
Then, you can either issue SQL-commands or Phoenix-commands.
0: jdbc:phoenix:zookeeper.local> !tables
+------------------------------------------+------------------------------------------+------------------------------------------+---------------------------+
  TABLE_CAT    TABLE_SCHEM    TABLE_NAME    TABLE_TYPE  
+------------------------------------------+------------------------------------------+------------------------------------------+---------------------------+
  null    SYSTEM    CATALOG    SYSTEM TABLE   
  null    SYSTEM    SEQUENCE    SYSTEM TABLE   
  null    SYSTEM    STATS    SYSTEM TABLE   
  null    null    STOCK_SYMBOL    TABLE   
  null    null    WEB_STAT    TABLE   
+------------------------------------------+------------------------------------------+------------------------------------------+---------------------------+

Craig Small: WordPress 4.1 for Debian

Release 4.1 of WordPress came out on Friday so after some work to fit in with the Debian standards, the Debian package 4.1-1 of WordPress will be uploaded shortly. WordPress have also updated their themes with a 14-day early theme called twentyfifteen. This is the default theme for WordPress 4.1 on-wards. I have also made some adjustments with the embedded code that WordPress ships. This is the usually JavaScript or PHP code that WordPress has in their release tarballs that comes from other projects. There is a fine line between keeping the WordPress install the same and having to deal with the maintenance of the embedded code. An example of a good one not to use embedded code is php-getid which the Debian maintainer has put in some additional patches for a better security fix while the alternative is jquery which is a little sad in the Debian-word being so many versions behind. php-snoopy got reverted to embedded code because its not exactly the same as upstream. A significant (or invisible, depends on your browser) is the mediaelement components now don t use the un-maintainable silverlight and flash plugins, which is the same how the libjs-mediaelement package works. In fact the code IS from that package. dh_linktree As I was looking into the embedded js/php code in WordPress, I also had to look into how the previous maintainer kept all the versions in order without some horrible mess of patchfiles and symlinks. The answer was dh_linktree. This program plugs into the standard debhelper rules file and can basically use symlinks in the package to use the standard Debian versions of files. It a bit cleverer than symlinks in that you can say use the link always or only if the files are the same. If you need to remove some of your embedded code out of Debian packages, have a look into it. It might save you a lot of agnst or hand-crafted rules files.

19 December 2014

Wouter Verhelst: joytest UI improvements

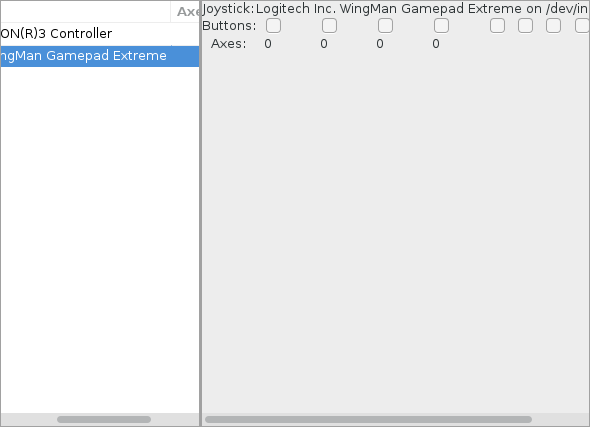
After yesterday's late night accomplishments, today I fixed up the UI of joytest a bit. It's still not quite what I think it should look like, but at least it's actually usable with a 27-axis, 19-button "joystick" (read: a PS3 controller). Things may disappear off the edge of the window, but you can scroll towards it. Also, I removed the names of the buttons and axes from the window, and installed them as tooltips instead. Few people will be interested in the factoid that "button 1" is a "BaseBtn4", anyway. The result now looks like this: If you plug in a new joystick, or remove one from the system, then as soon as udev finishes up creating the necessary device node, joytest will show the joystick (by name) in the treeview to the left. Clicking on a joystick will show that joystick's data to the right. When one pushes a button, the relevant checkbox will be selected; and when one moves an axis, the numbers will start changing. I really should have some widget to actually show the axis position, rather than some boring numbers. Not sure how to do that.
Steve Kemp: Switched to using attic for backups

Even though seeing the word attic reminds me too much of leaking roofs and CVS, I've switched to using the attic backup tool. I want a simple system which will take incremental backups, perform duplication-elimination (to avoid taking too much space), support encryption, and be fast. I stopped using backup2l because the .tar.gz files were too annoying, and it was too slow. I started using obnam because I respect Lars and his exceptionally thorough testing-regime, but had to stop using it when things started getting "too slow". I'll document the usage/installation in the future. For the moment the only annoyance is that it is contained in the Jessie archive, not the Wheezy one. Right now only 2/19 of my hosts are Jessie.

18 December 2014

Mario Lang: deluXbreed #2 is out!

The third installment of my crossbreed digital mix podcast is out! This time, I am featuring Harder & Louder and tracks from Behind the Machine and the recently released Remixes.
  1. Apolloud - Nagazaki
  2. Apolloud - Hiroshima
  3. SA+AN - Darksiders
  4. Im Colapsed - Cleaning 8
  5. Micromakine & Switch Technique - Ascension
  6. Micromakine - Cyberman (Dither Remix)
  7. Micromakine - So Good! (Synapse Remix)
How was DarkCast born and how is it done? I always loved 175BPM music. It is an old thing that is not going away soon :-). I recently found that there is a quite active culture going on, at least on BandCamp. But single tracks are just that, not really fun to listen to in my opinion. This sort of music needs to be mixed to be fun. In the past, I used to have most tracks I like/love as vinyl, so I did some real-world vinyl mixing myself. But these days, most fun music is only available digitally, at least easily. Some people still do vinyl releases, but they are actually rare. So for my personal enjoyment, I started to digitally mix tracks I really love, such that I can listen to them without "interruption". And since I am an iOS user since three years now, using the podcast format to get stuff onto my devices was quite a natural choice. I use SoX and a very small shell script to create these mixes. Here is a pseudo-template:
sox --combine mix-power \
" sox \" sox 1.flac -p\" \" sox 3.flac -p speed 0.987 delay 2:28.31 2:28.31\" -p" \
" sox \" sox 2.flac -p delay 2:34.1 2:34.1\" -p" \
mix.flac
As you can imagine, it is quite a bit of fiddling to get these scripts to do what you want. But it is a non-graphical method to get things done. If you know of a better tool, possibly with a bit of real-time controls, to get the same job done, wihtout having to resort to a damn GUI, let me know.

17 December 2014

Keith Packard: MST-monitors

Multi-Stream Transport 4k Monitors and X I'm sure you've seen a 4k monitor on a friends desk running Mac OS X or Windows and are all ready to go get one so that you can use it under Linux. Once you've managed to acquire one, I'm afraid you'll discover that when you plug it in, you're limited to 30Hz refresh rates at the full size, unless you're running a kernel that is version 3.17 or later. And then... Good Grief! What Is My Computer Doing! Ok, so now you're running version 3.17 and when X starts up, it's like you're using a gigantic version of Google Cardboard. Two copies of a very tall, but very narrow screen greets you. Welcome to MST island. In order to drive these giant new panels at full speed, there isn't enough bandwidth in the display hardware to individually paint each pixel once during each frame. So, like all good hardware engineers, they invented a clever hack. This clever hack paints the screen in parallel. I'm assuming that they've got two bits of display hardware, each one hooked up to half of the monitor. Now, each paints only half of the pixels, avoiding costly redesign of expensive silicon, at least that's my surmise. In the olden days, if you did this, you'd end up running two monitor cables to your computer, and potentially even having two video cards. Today, thanks to the magic of Display Port Multi-Stream Transport, we don't need all of that; instead, MST allows us to pack multiple cables-worth of data into a single cable. I doubt the inventors of MST intended it to be used to split a single LCD panel into multiple "monitors", but hardware engineers are clever folk and are more than capable of abusing standards like this when it serves to save a buck. Turning Two Back Into One We've got lots of APIs that expose monitor information in the system, and across which we might be able to wave our magic abstraction wand to fix this:
  1. The KMS API. This is the kernel interface which is used by all graphics stuff, including user-space applications and the frame buffer console. Solve the problem here and it works everywhere automatically.
  2. The libdrm API. This is just the KMS ioctls wrapped in a simple C library. Fixing things here wouldn't make fbcons work, but would at least get all of the window systems working.
  3. Every 2D X driver. (Yeah, we're trying to replace all of these with the one true X driver). Fixing the problem here would mean that all X desktops would work. However, that's a lot of code to hack, so we'll skip this.
  4. The X server RandR code. More plausible than fixing every driver, this also makes X desktops work.
  5. The RandR library. If not in the X server itself, how about over in user space in the RandR protocol library? Well, the problem here is that we've now got two of them (Xlib and xcb), and the xcb one is auto-generated from the protocol descriptions. Not plausible.
  6. The Xinerama code in the X server. Xinerama is how we did multi-monitor stuff before RandR existed. These days, RandR provides Xinerama emulation, but we've been telling people to switch to RandR directly.
  7. Some new API. Awesome. Ok, so if we haven't fixed this in any existing API we control (kernel/libdrm/X.org), then we effectively dump the problem into the laps of the desktop and application developers. Given how long it's taken them to adopt current RandR stuff, providing yet another complication in their lives won't make them very happy.
All Our APIs Suck Dave Airlie merged MST support into the kernel for version 3.17 in the simplest possible fashion -- pushing the problem out to user space. I was initially vaguely tempted to go poke at it and try to fix things there, but he eventually convinced me that it just wasn't feasible. It turns out that all of our fancy new modesetting APIs describe the hardware in more detail than any application actually cares about. In particular, we expose a huge array of hardware objects: Each of these objects exposes intimate details about the underlying hardware -- which of them can work together, and which cannot; what kinds of limits are there on data rates and formats; and pixel-level timing details about blanking periods and refresh rates. To make things work, some piece of code needs to actually hook things up, and explain to the user why the configuration they want just isn't possible. The sticking point we reached was that when an MST monitor gets plugged in, it needs two CRTCs to drive it. If one of those is already in use by some other output, there's just no way you can steal it for MST mode. Another problem -- we expose EDID data and actual video mode timings. Our MST monitor has two EDID blocks, one for each half. They happen to describe how they're related, and how you should configure them, but if we want to hide that from the application, we'll have to pull those EDID blocks apart and construct a new one. The same goes for video modes; we'll have to construct ones for MST mode. Every single one of our APIs exposes enough of this information to be dangerous. Every one, except Xinerama. All it talks about is a list of rectangles, each of which represents a logical view into the desktop. Did I mention we've been encouraging people to stop using this? And that some of them listened to us? Foolishly? Dave's Tiling Property Dave hacked up the X server to parse the EDID strings and communicate the layout information to clients through an output property. Then he hacked up the gnome code to parse that property and build a RandR configuration that would work. Then, he changed to RandR Xinerama code to also parse the TILE properties and to fix up the data seen by application from that. This works well enough to get a desktop running correctly, assuming that desktop uses Xinerama to fetch this data. Alas, gtk has been "fixed" to use RandR if you have RandR version 1.3 or later. No biscuit for us today. Adding RandR Monitors RandR doesn't have enough data types yet, so I decided that what we wanted to do was create another one; maybe that would solve this problem. Ok, so what clients mostly want to know is which bits of the screen are going to be stuck together and should be treated as a single unit. With current RandR, that's some of the information included in a CRTC. You pull the pixel size out of the associated mode, physical size out of the associated outputs and the position from the CRTC itself. Most of that information is available through Xinerama too; it's just missing physical sizes and any kind of labeling to help the user understand which monitor you're talking about. The other problem with Xinerama is that it cannot be configured by clients; the existing RandR implementation constructs the Xinerama data directly from the RandR CRTC settings. Dave's Tiling property changes edit that data to reflect the union of associated monitors as a single Xinerama rectangle. Allowing the Xinerama data to be configured by clients would fix our 4k MST monitor problem as well as solving the longstanding video wall, WiDi and VNC troubles. All of those want to create logical monitor areas within the screen under client control What I've done is create a new RandR datatype, the "Monitor", which is a rectangular area of the screen which defines a rectangular region of the screen. Each monitor has the following data: There are three requests to define, delete and list monitors. And that's it. Now, we want the list of monitors to completely describe the environment, and yet we don't want existing tools to break completely. So, we need some way to automatically construct monitors from the existing RandR state while still letting the user override portions of it as needed to explain virtual or tiled outputs. So, what I did was to let the client specify a list of outputs for each monitor. All of the CRTCs which aren't associated with an output in any client-defined monitor are then added to the list of monitors reported back to clients. That means that clients need only define monitors for things they understand, and they can leave the other bits alone and the server will do something sensible. The second tricky bit is that if you specify an empty rectangle at 0,0 for the pixel geometry, then the server will automatically compute the geometry using the list of outputs provided. That means that if any of those outputs get disabled or reconfigured, the Monitor associated with them will appear to change as well. Current Status Gtk+ has been switched to use RandR for RandR versions 1.3 or later. Locally, I hacked libXrandr to override the RandR version through an environment variable, set that to 1.2 and Gtk+ happily reverts back to Xinerama and things work fine. I suspect the plan here will be to have it use the new Monitors when present as those provide the same info that it was pulling out of RandR's CRTCs. KDE appears to still use Xinerama data for this, so it "just works". Where's the code As usual, all of the code for this is in a collection of git repositories in my home directory on fd.o:
git://people.freedesktop.org/~keithp/randrproto master
git://people.freedesktop.org/~keithp/libXrandr master
git://people.freedesktop.org/~keithp/xrandr master
git://people.freedesktop.org/~keithp/xserver randr-monitors
RandR protocol changes Here's the new sections added to randrproto.txt
                   
1.5. Introduction to version 1.5 of the extension
Version 1.5 adds monitors
   A 'Monitor' is a rectangular subset of the screen which represents
   a coherent collection of pixels presented to the user.
   Each Monitor is be associated with a list of outputs (which may be
   empty).
   When clients define monitors, the associated outputs are removed from
   existing Monitors. If removing the output causes the list for that
   monitor to become empty, that monitor will be deleted.
   For active CRTCs that have no output associated with any
   client-defined Monitor, one server-defined monitor will
   automatically be defined of the first Output associated with them.
   When defining a monitor, setting the geometry to all zeros will
   cause that monitor to dynamically track the bounding box of the
   active outputs associated with them
This new object separates the physical configuration of the hardware
from the logical subsets  the screen that applications should
consider as single viewable areas.
1.5.1. Relationship between Monitors and Xinerama
Xinerama's information now comes from the Monitors instead of directly
from the CRTCs. The Monitor marked as Primary will be listed first.
                   
5.6. Protocol Types added in version 1.5 of the extension
MONITORINFO   name: ATOM
          primary: BOOL
          automatic: BOOL
          x: INT16
          y: INT16
          width: CARD16
          height: CARD16
          width-in-millimeters: CARD32
          height-in-millimeters: CARD32
          outputs: LISTofOUTPUT  
                   
7.5. Extension Requests added in version 1.5 of the extension.
 
    RRGetMonitors
    window : WINDOW
      
    timestamp: TIMESTAMP
    monitors: LISTofMONITORINFO
 
    Errors: Window
    Returns the list of Monitors for the screen containing
    'window'.
    'timestamp' indicates the server time when the list of
    monitors last changed.
 
    RRSetMonitor
    window : WINDOW
    info: MONITORINFO
 
    Errors: Window, Output, Atom, Value
    Create a new monitor. Any existing Monitor of the same name is deleted.
    'name' must be a valid atom or an Atom error results.
    'name' must not match the name of any Output on the screen, or
    a Value error results.
    If 'info.outputs' is non-empty, and if x, y, width, height are all
    zero, then the Monitor geometry will be dynamically defined to
    be the bounding box of the geometry of the active CRTCs
    associated with them.
    If 'name' matches an existing Monitor on the screen, the
    existing one will be deleted as if RRDeleteMonitor were called.
    For each output in 'info.outputs, each one is removed from all
    pre-existing Monitors. If removing the output causes the list of
    outputs for that Monitor to become empty, then that Monitor will
    be deleted as if RRDeleteMonitor were called.
    Only one monitor per screen may be primary. If 'info.primary'
    is true, then the primary value will be set to false on all
    other monitors on the screen.
    RRSetMonitor generates a ConfigureNotify event on the root
    window of the screen.
 
    RRDeleteMonitor
    window : WINDOW
    name: ATOM
 
    Errors: Window, Atom, Value
    Deletes the named Monitor.
    'name' must be a valid atom or an Atom error results.
    'name' must match the name of a Monitor on the screen, or a
    Value error results.
    RRDeleteMonitor generates a ConfigureNotify event on the root
    window of the screen.
                   

15 December 2014

Thomas Goirand: Supporting 3 init systems in OpenStack packages

tl;dr: Providing support for all 3 init systems (sysv-rc, Upstart and systemd) isn t hard, and generating the init scripts / Upstart job / systemd using a template system is a lot easier than I previously thought. As always, when writing this kind of blog post, I do expect that others will not like what I did. But that s the point: give me your opinion in a constructive way (please be polite even if you don t like what you see I had too many times had to read harsh comments), and I ll implement your ideas if I find it nice. History of the implementation: how we came to the idea I had no plan to do this. I don t believe what I wrote can be generalized to all of the Debian archive. It s just that I started doing things, and it made sense when I did it. Let me explain how it happened. Since it s clear that many, and especially the most advanced one, may have an opinion about which init system they prefer, and because I also support Ubuntu (at least Trusty), I though it was a good idea to support all the main init system: sysv-rc, Upstart and systemd. Though I have counted (for the sake of being exact in this blog) : OpenStack in Debian contains currently 64 init scripts to run daemons in total. That s quite a lot. A way too much to just write them, all by hand. Though that s what I was doing for the last years until this the end of this last summer! So, doing all by hand, I first started implementing Upstart. Its support was there only when building in Ubuntu (which isn t the correct thing to do, this is now fixed, read further ). Then we thought about adding support for systemd. Gustavo Panizzo, one of the contributors in the OpenStack packages, started implementing it in Keystone (the auth server for OpenStack) for the Juno release which was released this October. He did that last summer, early enough so we didn t expect anyone to use the Juno branch Keystone. After some experiments, we had kind of working. What he did was invoking /etc/init.d/keystone start-systemd , which was still using start-stop-daemon. Yes, that s not perfect, and it s better to use systemd foreground process handling, but at least, we had a unique place where to write the startup scripts, where we check the /etc/default for the logging configuration, configure the log file, and so on. Then around in october, I took a step backward to see the whole picture with sysv-rc scripts, and saw the mess, with all the tiny, small difference between them. It became clear that I had to do something to make sure they were all the same, with the support for the same things (like which log system to use, where to store the PID, create /var/lib/project, /var/run/project and so on ). Last, on this month of December, I was able to fix the remaining issues for systemd support, thanks to the awesome contribution of Mikael Cluseau on the Alioth OpenStack packaging list. Now, the systemd unit file is still invoking the init script, but it s not using start-stop-daemon anymore, no PID file involved, and daemons are used as systemd foreground processes. Finally, daemons service files are also activated on installation (they were not previously). Implementation So I took the simplistic approach to use always the same template for the sysv-rc switch/case, and the start and stop functions, happening it at the end of all debian/*.init.in scripts. I started to try to reduce the number of variables, and I was surprised of the result: only a very small part of the init scripts need to change from daemon to daemon. For example, for nova-api, here s the init script (LSB header stripped-out):
DESC="OpenStack Compute API"
PROJECT_NAME=nova
NAME=$ PROJECT_NAME -api
That is it: only 3 lines, defining only the name of the daemon, the name of the project it attaches (eg: nova, cinder, etc.), and a long description. There s of course much more complicated init scripts (see the one for neutron-server in the Debian archive for example), but the vast majority only needs the above. Here s the sysv-rc init script template that I currently use:
#!/bin/sh
# The content after this line comes from openstack-pkg-tools
# and has been automatically added to a .init.in script, which
# contains only the descriptive part for the daemon. Everything
# else is standardized as a single unique script.
# Author: Thomas Goirand <zigo@debian.org>
# PATH should only include /usr/* if it runs after the mountnfs.sh script
PATH=/sbin:/usr/sbin:/bin:/usr/bin
if [ -z "$ DAEMON " ] ; then
	DAEMON=/usr/bin/$ NAME 
fi
PIDFILE=/var/run/$ PROJECT_NAME /$ NAME .pid
if [ -z "$ SCRIPTNAME " ] ; then
	SCRIPTNAME=/etc/init.d/$ NAME 
fi
if [ -z "$ SYSTEM_USER " ] ; then
	SYSTEM_USER=$ PROJECT_NAME 
fi
if [ -z "$ SYSTEM_USER " ] ; then
	SYSTEM_GROUP=$ PROJECT_NAME 
fi
if [ "$ SYSTEM_USER " != "root" ] ; then
	STARTDAEMON_CHUID="--chuid $ SYSTEM_USER :$ SYSTEM_GROUP "
fi
if [ -z "$ CONFIG_FILE " ] ; then
	CONFIG_FILE=/etc/$ PROJECT_NAME /$ PROJECT_NAME .conf
fi
LOGFILE=/var/log/$ PROJECT_NAME /$ NAME .log
if [ -z "$ NO_OPENSTACK_CONFIG_FILE_DAEMON_ARG " ] ; then
	DAEMON_ARGS="$ DAEMON_ARGS  --config-file=$ CONFIG_FILE "
fi
# Exit if the package is not installed
[ -x $DAEMON ]   exit 0
# If ran as root, create /var/lock/X, /var/run/X, /var/lib/X and /var/log/X as needed
if [ "x$USER" = "xroot" ] ; then
	for i in lock run log lib ; do
		mkdir -p /var/$i/$ PROJECT_NAME 
		chown $ SYSTEM_USER  /var/$i/$ PROJECT_NAME 
	done
fi
# This defines init_is_upstart which we use later on (+ more...)
. /lib/lsb/init-functions
# Manage log options: logfile and/or syslog, depending on user's choosing
[ -r /etc/default/openstack ] && . /etc/default/openstack
[ -r /etc/default/$NAME ] && . /etc/default/$NAME
[ "x$USE_SYSLOG" = "xyes" ] && DAEMON_ARGS="$DAEMON_ARGS --use-syslog"
[ "x$USE_LOGFILE" != "xno" ] && DAEMON_ARGS="$DAEMON_ARGS --log-file=$LOGFILE"
do_start()  
	start-stop-daemon --start --quiet --background $ STARTDAEMON_CHUID  --make-pidfile --pidfile $ PIDFILE  --chdir /var/lib/$ PROJECT_NAME  --startas $DAEMON \
			--test > /dev/null   return 1
	start-stop-daemon --start --quiet --background $ STARTDAEMON_CHUID  --make-pidfile --pidfile $ PIDFILE  --chdir /var/lib/$ PROJECT_NAME  --startas $DAEMON \
			-- $DAEMON_ARGS   return 2
 
do_stop()  
	start-stop-daemon --stop --quiet --retry=TERM/30/KILL/5 --pidfile $PIDFILE
	RETVAL=$?
	rm -f $PIDFILE
	return "$RETVAL"
 
do_systemd_start()  
	exec $DAEMON $DAEMON_ARGS
 
case "$1" in
start)
	init_is_upstart > /dev/null 2>&1 && exit 1
	log_daemon_msg "Starting $DESC" "$NAME"
	do_start
	case $? in
		0 1) log_end_msg 0 ;;
		2) log_end_msg 1 ;;
	esac
;;
stop)
	init_is_upstart > /dev/null 2>&1 && exit 0
	log_daemon_msg "Stopping $DESC" "$NAME"
	do_stop
	case $? in
		0 1) log_end_msg 0 ;;
		2) log_end_msg 1 ;;
	esac
;;
status)
	status_of_proc "$DAEMON" "$NAME" && exit 0   exit $?
;;
systemd-start)
	do_systemd_start
;;  
restart force-reload)
	init_is_upstart > /dev/null 2>&1 && exit 1
	log_daemon_msg "Restarting $DESC" "$NAME"
	do_stop
	case $? in
	0 1)
		do_start
		case $? in
			0) log_end_msg 0 ;;
			1) log_end_msg 1 ;; # Old process is still running
			*) log_end_msg 1 ;; # Failed to start
		esac
	;;
	*) log_end_msg 1 ;; # Failed to stop
	esac
;;
*)
	echo "Usage: $SCRIPTNAME  start stop status restart force-reload systemd-start " >&2
	exit 3
;;
esac
exit 0
Nothing particularly fancy here You ll noticed that it s really OpenStack centric (see the LOGFILE and CONFIGFILE things ). You may have also noticed the call to init_is_upstart which is needed for upstart support. I m not sure if it s at the correct place in the init script. Should I put that on top of the script? Was I right with the exit values for it? Please send me your comments Then I thought about generalizing all of this. Because not only the sysv-rc scripts needed to be squared-up, but also Upstart. The approach here was to source the sysv-rc script in debian/*.init.in, and then generate the Upstart job accordingly, using the above 3 variables (or more as needed). Here, the fun is that, instead of taking the approach of calculating everything at runtime with the sysv-rc, for Upstart jobs, many things are calculated at build time. For each debian/*.init.in script that the debian/rules finds, pkgos-gen-upstart-job is called. Here s pkgos-gen-upstart-job:
#!/bin/sh
INIT_TEMPLATE=$ 1 
UPSTART_FILE= echo $ INIT_TEMPLATE    sed 's/.init.in/.upstart/' 
# Get the variables defined in the init template
. $ INIT_TEMPLATE 
## Find out what should go in After=
#SHOULD_START= cat $ INIT_TEMPLATE    grep "# Should-Start:"   sed 's/# Should-Start://' 
#
#if [ -n "$ SHOULD_START " ] ; then
#	AFTER="After="
#	for i in $ SHOULD_START  ; do
#		AFTER="$ AFTER $ i .service "
#	done
#fi
if [ -z "$ DAEMON " ] ; then
        DAEMON=/usr/bin/$ NAME 
fi
PIDFILE=/var/run/$ PROJECT_NAME /$ NAME .pid
if [ -z "$ SCRIPTNAME " ] ; then
	SCRIPTNAME=/etc/init.d/$ NAME 
fi
if [ -z "$ SYSTEM_USER " ] ; then
	SYSTEM_USER=$ PROJECT_NAME 
fi
if [ -z "$ SYSTEM_GROUP " ] ; then
	SYSTEM_GROUP=$ PROJECT_NAME 
fi
if [ "$ SYSTEM_USER " != "root" ] ; then
	STARTDAEMON_CHUID="--chuid $ SYSTEM_USER :$ SYSTEM_GROUP "
fi
if [ -z "$ CONFIG_FILE " ] ; then
	CONFIG_FILE=/etc/$ PROJECT_NAME /$ PROJECT_NAME .conf
fi
LOGFILE=/var/log/$ PROJECT_NAME /$ NAME .log
DAEMON_ARGS="$ DAEMON_ARGS  --config-file=$ CONFIG_FILE "
echo "description \"$ DESC \"
author \"Thomas Goirand <zigo@debian.org>\"
start on runlevel [2345]
stop on runlevel [!2345]
chdir /var/run
pre-start script
	for i in lock run log lib ; do
		mkdir -p /var/\$i/$ PROJECT_NAME 
		chown $ SYSTEM_USER  /var/\$i/$ PROJECT_NAME 
	done
end script
script
	[ -x \"$ DAEMON \" ]   exit 0
	DAEMON_ARGS=\"$ DAEMON_ARGS \"
	[ -r /etc/default/openstack ] && . /etc/default/openstack
	[ -r /etc/default/\$UPSTART_JOB ] && . /etc/default/\$UPSTART_JOB
	[ \"x\$USE_SYSLOG\" = \"xyes\" ] && DAEMON_ARGS=\"\$DAEMON_ARGS --use-syslog\"
	[ \"x\$USE_LOGFILE\" != \"xno\" ] && DAEMON_ARGS=\"\$DAEMON_ARGS --log-file=$ LOGFILE \"
	exec start-stop-daemon --start --chdir /var/lib/$ PROJECT_NAME  \\
		$ STARTDAEMON_CHUID  --make-pidfile --pidfile $ PIDFILE  \\
		--exec $ DAEMON  -- --config-file=$ CONFIG_FILE  \$ DAEMON_ARGS 
end script
" >$ UPSTART_FILE 
The only thing which I don t know how to do, is how to implement the Should-Start / Should-Stop in an Upstart job. Can anyone shoot me a mail and tell me the solution? Then, I wanted to add support for systemd. Here, we cheated, since we only just called the sysv-rc script from the systemd unit, however, the systemd-start target uses exec, so the process stays in the foreground. It s also much smaller than the Upstart thing. However, here, I could implement the After thing, corresponding to the Should-Start:
#!/bin/sh
INIT_TEMPLATE=$ 1 
SERVICE_FILE= echo $ INIT_TEMPLATE    sed 's/.init.in/.service/' 
# Get the variables defined in the init template
. $ INIT_TEMPLATE 
if [ -z "$ SCRIPTNAME " ] ; then
	SCRIPTNAME=/etc/init.d/$ NAME 
fi
if [ -z "$ SYSTEM_USER " ] ; then
	SYSTEM_USER=$ PROJECT_NAME 
fi
if [ -z "$ SYSTEM_GROUP " ] ; then
	SYSTEM_GROUP=$ PROJECT_NAME 
fi
# Find out what should go in After=
SHOULD_START= cat $ INIT_TEMPLATE    grep "# Should-Start:"   sed 's/# Should-Start://' 
if [ -n "$ SHOULD_START " ] ; then
	AFTER="After="
	for i in $ SHOULD_START  ; do
		AFTER="$ AFTER $ i .service "
	done
fi
echo "[Unit]
Description=$ DESC 
$AFTER
[Service]
User=$ SYSTEM_USER 
Group=$ SYSTEM_GROUP 
WorkingDirectory=/var/lib/$ PROJECT_NAME 
PermissionsStartOnly=true
ExecStartPre=/bin/mkdir -p /var/lock/$ PROJECT_NAME  /var/log/$ PROJECT_NAME  /var/lib/$ PROJECT_NAME 
ExecStartPre=/bin/chown $ SYSTEM_USER :$ SYSTEM_GROUP  /var/lock/$ PROJECT_NAME  /var/log/$ PROJECT_NAME  /var/lib/$ PROJECT_NAME 
ExecStart=$ SCRIPTNAME  systemd-start
Restart=on-failure
[Install]
WantedBy=multi-user.target
" >$ SERVICE_FILE 
As you can see, it s calling /etc/init.d/$ SCRIPTNAME sytemd-start, which isn t great. I d be happy to have comments from systemd user / maintainers on how to fix it to make it better. Integrating in debian/rules To integrate with the Debian package build system, we only need had to write this:
override_dh_installinit:
	# Create the init scripts from the template
	for i in  ls -1 debian/*.init.in  ; do \
		MYINIT= echo $$i   sed s/.init.in//  ; \
		cp $$i $$MYINIT.init ; \
		cat /usr/share/openstack-pkg-tools/init-script-template >>$$MYINIT.init ; \
		pkgos-gen-systemd-unit $$i ; \
	done
	# If there's an upstart.in file, use that one instead of the generated one
	for i in  ls -1 debian/*.upstart.in  ; do \
		MYPKG= echo $$i   sed s/.upstart.in//  ; \
		cp $$MYPKG.upstart.in $$MYPKG.upstart ; \
	done
	# Generate the upstart job if there's no already existing .upstart.in
	for i in  ls debian/*.init.in  ; do \
		MYINIT= echo $$i   sed s/.init.in/.upstart.in/  ; \
		if ! [ -e $$MYINIT ] ; then \
			pkgos-gen-upstart-job $$i ; \
		fi \
	done
	dh_installinit --error-handler=true
	# Generate the systemd unit file
	# Note: because dh_systemd_enable is called by the
	# dh sequencer *before* dh_installinit, we have
	# to process it manually.
	for i in  ls debian/*.init.in  ; do \
		pkgos-gen-systemd-unit $$i ; \
		MYSERVICE= echo $$i   sed 's/debian\///'  ; \
		MYSERVICE= echo $$MYSERVICE   sed 's/.init.in/.service/'  ; \
		dh_systemd_enable $$MYSERVICE ; \
	done
As you can see, it s possible to use a debian/*.upstart.in and not use the templating system, in the more complicated case (I needed it mostly for neutron-server and neutron-plugin-openvswitch-agent). Conclusion I do not pretend that what I wrote in the openstack-pkg-tools is the ultimate solution. But I m convince that it answers our own need as the OpenStack maintainers in Debian. There s a lot of room for improvements (like implementing the Should-Start in Upstart jobs, or stop calling the sysv-rc script in the systemd units), but that this is a very good move that we did to use templates and generated scripts, as the init scripts are a way more easy to maintain now, in a much more unified way. As I m not completely satisfied for the systemd and Upstart implementation, I m sure that there s already a huge improvements on the sysv-rc script maintainability. Last and again: please send your comments and help improving the above! :)

Next.

Previous.