Search Results: "spa"

8 September 2011

Dirk Eddelbuettel: Faster (recursive) function calls: Another quick Rcpp case study

There was another question recently on StackOverflow that I had meant to discuss in a follow-up post here. User deltanovember asked about slow recursive functions and used the very classic Fibonacci number as an example. To recap, Fibonacci number are defined with two initial values F(0) = 0 and F(1) = 1; thereafter the Fibonacci number F(n) is defined as the sum of the two preceding numbers: F(n) = F(n-2) + F(n-1). This leads to very straightforward implementations using recursion:
## R implementation of recursive Fibonacci sequence
fibR <- function(n)  
    if (n == 0) return(0)
    if (n == 1) return(1)
    return (fibR(n - 1) + fibR(n - 2))
 
Unfortunately, this elegant implementation which remain close to the abtract formulation of the recurrence algorithm performs very poorly in R as there is noticeable overhead in function calls which becomes dominant in a recursion. This lead to the original question on StackOverflow, and the accepted answer uses a trick presented by Pat Burns in his lovely R Inferno: rewrite the solution using a computer science trick called memoization:
fibonacci <- local( 
    memo <- c(1, 1, rep(NA, 100))
    f <- function(x)  
        if(x == 0) return(0)
        if(x < 0) return(NA)
        if(x > length(memo))
        stop("'x' too big for implementation")
        if(!is.na(memo[x])) return(memo[x])
        ans <- f(x-2) + f(x-1)
        memo[x] <<- ans
        ans
     
 )
That is a fair answer, and even more was suggested with a link to a terrific analysis calling the Fibonacci recurrence the worst algorithm in the world. That is also fair, but all the basic research into better algorithms exploiting some structure of the problem to advance performance (and of course understanding) is overlooking one crucial part: algorithm analysis is essentially independent of the language. So whatever improvements we obtain by thinking really hard about a problem are then available for other implementations too. So with a tip of the hat to the old Larry Wall quote about Lazyness, Impatience and Hubris, I would like to suggest what I consider a much simpler route to much better performance: recode it in C++ using both Rcpp (for the R/C++ integration) and inline for the on-the-fly compilation, linking and loading of C++ code into R.
## inline to compile, load and link the C++ code
require(inline)
## we need a pure C/C++ function as the generated function
## will have a random identifier at the C++ level preventing
## us from direct recursive calls
incltxt <- '
  int fibonacci(const int x)  
     if (x == 0) return(0);
     if (x == 1) return(1);
     return (fibonacci(x - 1)) + fibonacci(x - 2);
   '
## now use the snippet above as well as one argument conversion
## in as well as out to provide Fibonacci numbers via C++
fibRcpp <- cxxfunction(signature(xs="int"),
                       plugin="Rcpp",
                       incl=incltxt,
                       body
                       ='
   int x = Rcpp::as<int>(xs);
   return Rcpp::wrap( fibonacci(x) );
')
This single R function call cxxfunction() takes the code embedded in the arguments to the body variable (for the core function) and the incltxt variable for the helper function we need to call. This helper function is needed for the recursion as cxxfunction() will use an randomized internal identifier for the function called from R preventing us from calling this (unknown) indentifier. But the rest of the algorithm is simple, and as beautiful as the initial recurrence. Three lines, three statements, and three cases for F(0), F(1) and the general case F(n) solved by recursive calls. This also illustrates how easy it is to get an integer from R to C++ and back: the as and wrap simply do the right thing converting to and from the SEXP types used internally by the C API of R. A performance comparison of the basic R version fibR, its byte-compiled variant fibRC and and the C++ version fibRcpp shown above is very compelling. We have added a file fibonacci.r to the large and still growing set of examples included with Rcpp, and we can just execute that script with Rscript or (as here) r from the littler package:
edd@max:~/svn/rcpp/pkg/Rcpp/inst/examples/Misc$ r fibonacci.r
Loading required package: inline
Loading required package: methods
Loading required package: compiler
        test replications elapsed relative user.self sys.self
3 fibRcpp(N)            1   0.092   1.0000      0.09     0.00
2   fibRC(N)            1  61.480 668.2609     61.47     0.00
1    fibR(N)            1  61.877 672.5761     61.83     0.02
edd@max:~/svn/rcpp/pkg/Rcpp/inst/examples/Misc$ 
So the recursion for the original argument of N=35 takes just over a minute at about 61.5 and 61.9 seconds, respectively, for the R version and its byte-compiled variant (as per the column titled elapsed). So byte-compilation essentially offers no help for the bottleneck of slow function calls. The C++ versions relying on Rcpp which created in a few lines of code and a single call to cxxfunction however takes just 92 milliseconds---or a relative gain of well over six-hundred times. That provides another nice demonstration of what Rcpp can do. Improved algorithms for well-understood problems are surely one way to accelerate solutions. But there are (many ?) times when we do not have the luxury of being able to think through to a new and improved approach. Or worse, such an approach may even introduce new errors or inaccurracies if we get it wrong on a first try. With Rcpp, we are able to the express the problem as written in its original statement: a simple recursion. The gain relative to a slow R implementation is noteworthy---and could of course be improved further if we really needed to by relying on better algorithms like memoization. But for day to day tasks, I gladly take speedups of (up to) a few hundred times thanks to Rcpp without having to do hard algorithmic work. Before closing, a quick reminder that I will be giving two classes on Rcpp in a few weeks. These will be in New York on September 24, and San Franciso on October 8, see this blog post as well as this page at Revolution Analytics (who are a co-organiser of the classes) for details and registration information.

Jose Luis Rivas Contreras: Moved from approx to apt-cacher-ng

I have been a long-time user of
approx
, I got used to it and knew how to configure it so all my machines + VMs used the same cache and saved me a lot of bandwidth. But that was when I got a stable connection at >100KiB/s in a daily-basis. Now I m with a mobile connection at <30KiB/s and sometimes is intermittent, so
approx
started giving me a lot of headaches. When
approx
tries to connect a host that can t be resolved its domain name, then gets 404. How does that reflects in the
/pool
? Well, you get a file
touch
d and 0 bytes size. When you try again,
approx
will find the same file with 0 bytes size and will gives you again a 404, even if you can now resolve the name address of that domain. And as I like to use what I know, then I made a workaround: Each time this happened I ran:
# find /var/cache/approx -size 0 xargs rm
So next time I requested a file to
approx
it tried to connect to the host. But I got tired. I installed
apt-cacher-ng
, tweaked a bit
/etc/apt-cacher-ng/acng.conf
so it uses port 9999 and the cache dir redirects to the same cache than
approx
and done.
apt-cacher-ng
returns 503 when it can t connect to the peer, even tries to several repositories with only a line in
/etc/apt/sources.list
in my clients. It makes me happy and keeps saving me a lot more of bandwidth than
approx
.

David Welton: Zero to Profitable - LiberWriter Lessons Learned

Here's how I have created the beginnings of a profitable Kindle formatting and conversion service, LiberWriter, from scratch. Last Winter, I read one of the best business books I have read in a long time, Rob Walling's Start Small, Stay Small: <iframe frameborder="0" marginheight="0" marginwidth="0" scrolling="no" src="http://rcm.amazon.com/e/cm?lt1=_blank&amp;bc1=000000&amp;IS2=1&amp;bg1=FFFFFF&amp;fc1=000000&amp;lc1=0000FF&amp;t=dedasys-20&amp;o=1&amp;p=8&amp;l=as4&amp;m=amazon&amp;f=ifr&amp;ref=ss_til&amp;asins=B003YH9MMI" style="width: 120px; height: 240px;"></iframe> Rather than being a "big idea" book that includes one big idea and lots of stories to support it, it's a very practical book on how to go about creating a small online business. I've always been someone who loves to build things, from various open source projects, to diverse web sites that people have found valuable. However, I am not a "business guy". I'm not that good at making money, so the simple approach in the book is really better for people like me: make something and sell it. Advertising can certainly work, but it's so much harder to figure out the numbers compared with a product, where you can compare the cost of providing the product to the price people will pay for it. And that's just one thing; the book has tons of ideas about practical ways of going about putting together a profitable small online business. It's not a "get rich quick" book - part of the idea is that if you are looking at a niche that is fairly small, it will simply not be of interest to larger companies, so you aren't going to get outspent and outcompeted by them. In any event, though, at about the same time I read the book, I was poking around looking at Amazon's KDP, which allows you to self publish for the Kindle, and noticing how difficult the process is. The native format of Amazon's books is HTML with several XML files thrown in for good measure. Now, for someone technical, that's certainly not an insurmountable obstacle, but for many authors, it's a very unpleasant prospect. Granted, you can also manipulate a Word file to make it suitable for the KDP, but even that is something that many people dont' find to be a productive use of their time. They're authors, and they want to write. Having spotted a niche that looked interesting - I love to read, and I like the idea of helping out authors - I discarded the book idea I was looking at myself and did some writing of my own: source code for a project that would automate the process of converting and formatting Kindle books. The core of the system was a fun evenings/weekends project, and soon it was able to produce pretty good books. After "inflicting" the beta version of the system on several people, such as Rich Bowen (thanks again, Rich!), I got it beat into shape and started accepting the first paying customers. It's very exciting to have those first few people pay for something you made - it's a great feeling! Initially, my thought was to sell it as a way to write books directly for the Kindle, however, it soon became evident that 99% of people have already written their books with Microsoft Word, so what they were really interested in was a conversion and formatting system that would take a Word document, poke and prod, stitch and stretch it some, and output a nice looking book for the Kindle. One of the lessons from Rob's book was that stuff doesn't have to be perfect if it works. Initially, I had people putting their word documents into LiberWriter not with the smooth(ish) upload process we have now, but by cutting and pasting in their documents! As a computer guy, doing things in a hacky way is sometimes very unpleasant, but you know what? It worked, and it was easy for people to handle, so I ran with it until a better system was in place. Writing code was the easy part, and definitely within my "comfort zone". Some of the other things I've had to do have been much more difficult, and as a consequence, more of a learning experience. For instance, I realized early on that the process would never be 100% automatic, so I'd have to get some people to work on the books, with the idea being to provide them tools to make the process as simple, quick, and easy as possible. I'm always on the lookout for new things to script within the system. However, need people it does, and finding them and engaging them has been a difficult process. As per the book's suggestion, I've primarily used oDesk to find contractors, and have grardually begun to find some people who work really well. It has taken time, and has not been easy, though. I'm not an introvert, but in some ways I'm happiest when doing my own thing. Being the 'boss' is new. One of the tricky aspects of oDesk is that pretty much any job posting gets tons of responses, some of them from people who appear to have barely read the posting. One trick I learned is to request that the potential contractor creates an account with LiberWriter. Very simple and not a waste of time, and yet a majority of applicants ignored the request. Through most of the spring and summer, LiberWriter remained something strictly for the evenings and weekends, as I was busy with client work during the days, and with my daughter during the afternoons, but as August rolled around, I found some more time on my hands, and really started investing more energy in LiberWriter. It has been very rewarding to see a corresponding increase in the number of customers. We (at this point, between myself and the contractors, LiberWriter is a group, and no longer "I") also raised prices - another valuable piece of advice from the book, and... pretty much anyone who writes for people jumping into online businesses. As tech people, we often tend to aim low in terms of prices. Indeed, soonish, prices will likely go up again. Another challenge has been turning it as much as possible into a "productized service". Since Kindle books are fairly simple in what you can do with them, as long as you don't get too fancy, it's possible to automate *most* things, but not everything, so it's not just a product that people buy and it works and that's that; there's a human element involved, which means more communication, and more potential for things to go off the rails. I've been investing time in automating the workflow of the system, but have a lot more to do on that front. Also, one of the things our customers love about the service is being able to deal with "real people", something that is more difficult at Amazon. That's good for us in one way, but in the future, it will be critical to document things and make them as simple as possible to avoid generating unneccessary support requests, as it can easily take up a lot of time. Indeed, because LiberWriter does attract customers who are often not all that technical, making the user experience as easy and straightforward for them as possible (and then some) is extremely important. It can be exasperating once in a while, but I do my best to channel any frustrated energy on my part into making the site ever easier and ever more straightforward. In other words, instead of "how the heck do they not get that?!" it's "what can I do to make sure the tools and information they need are even easier for them to get?". There's lots to do on that front, but on the whole it's actually part of the project that I've grown to like a lot. Rather than dealing with other techies like myself, our customers are people who really benefit from what we offer because we can save them so much time and frustration. Marketing the system is fun, but another area where I have a lot to learn: I'm not a natural when it comes to marketing or selling. One thing that has worked well so far is finding forums where your target users hang out, and then.... spam them as often as possible? No way! Be yourself, and provide genuine help and value to people in the forums. By being on the level, and not trying to sell! sell! sell! people are friendlier and more receptive to your message. It can be time consuming, but I suppose it's the sort of thing where taking the wrong short cut could be very detrimental over the long haul. Without disclosing too much, I don't think I'll ever get rich from LiberWriter, but it is incredibly satisfying to have created and marketed a product of my own that goes beyond just selling my own time. LiberWriter doesn't bring in as much as consulting, yet, but it feels like much more of an investment, something that will have some momentum of its own, and of course it has been an incredible learning experience. I like programming, but being outside of my "comfort zone", doing stuff that's new and challenging is also a very positive part of the project. If things continue to grow the way they have been, I could envision depending on LiberWriter as my primary source of income in the very near future. That's a bit of a jump into the unknown in some ways, but I'd love it. I have worked very hard on it lately, and one of the things I am enjoying is always having new ideas about how to improve every aspect of the system, from customer service to the mechanics of the conversion process, to tracking the finances. In some ways it's tiring because I'm thinking about it *all* the time, but it's that "good kind of tired". It's been a tumultous summer, and in the past few weeks we (well, my wife much more than me!) had a new baby boy, and bought a house here in Padova. To keep things interesting for the future, I applied to the Startup Chile program with LiberWriter. I suspect they're more interested in startups with high growth potential, but I feel strongly that the approach outlined in Rob's book is one that people outside of Silicon Valley, without easy access to venture capital and the huge talent pool that area has, should consider, rather than trying to copy what makes Silicon Valley work like it does. Whether I get accepted or not, LiberWriter will continue to grow, and, I sincerely hope, thrive. A big thanks to all our customers, and to my wife Ilenia, and children, Helen and Daniel for tollerating all the time I spend with the computer. I wrestled a bit with writing this post, as I don't want to "jinx things", and I've only just got a small taste of "success", but I've always enjoyed reading about how "ordinary people" have managed to create their own small businesses, people like those behind Balsamiq, "Bingo Card Creator", and the like, and I figure that writing up my own experiences is a way of "paying it forward".

Russell Coker: Moving from a Laptop to a Cloud Lifestyle

My Laptop History In 1998 I bought my first laptop, it was a Thinkpad 385XD, it had a PentiumMMX 233MHz CPU, 96M of RAM, and an 800*600 display. This was less RAM than I could have afforded in a desktop system and the 800*600 display didn t compare well to the 1280*1024 resolution 17 inch Trinitron monitor I had been using. Having only 1/3 the pixels is a significant loss and a 12.1 inch TFT display of that era compared very poorly with a good Trinitron monitor. In spite of this I found it a much better system to use because it was ALWAYS with me, I used it for many things that were probably better suited to a PDA (there probably aren t many people who have carried a 7.1 pound (3.2Kg) laptop to as many places as I did). But some of my best coding was done on public transport. But I didn t buy my first laptop for that purpose, I bought it because I was moving to another country and there just wasn t any other option for having a computer. In late 1999 I bought my second laptop, it was a Thinkpad 600E [1]. It had twice the CPU speed, twice the RAM, and a 1024*768 display that displayed color a lot better. Since then I had another three Thinkpads, a T21, a T43, and now a T61. One of the ways I measure a display is the number of 80*25 terminal windows that I can display at one time, my first Thinkpad could display four windows with a significant amount of overlap. My second could display four with little overlap, my third (with 1280*1024 resolution) could display four clearly and another two with overlap, and my current Thinkpad does 1680*1050 and can display four windows clearly and another five without excessive overlap. For most of the last 13 years my Thinkpads weren t that far behind what I could afford to get as a desktop system, until now. A Smart Phone as the Primary Computing Device For the past 6 months the Linux system I ve used most frequently is my Sony Ericsson Xperia X10 Android phone [2]. Most of my computer use is on my laptop, but the many short periods of time using my phone add up. This has forced some changes to the way I work. I now use IMAP instead of POP for receiving mail so I can use my phone and my laptop with the same mail spool. This is a significant benefit for my email productivity, instead of having 100 new mailing list messages waiting for me when I get home I can read them on my phone and then have maybe 1 message that can t be addressed without access to something better than a phone. My backlog of 10,000 unread mailing list messages lasted less than a month after getting an Android phone! A few years ago I got an EeePC 701 that I use for emergency net access when a server goes down. But even a 920g EeePC is more weight than I want to carry, as I need to have a mobile phone anyway there is effectively no extra mass or space used to have a phone capable of running a ssh client. My EeePC doesn t get much use nowadays. A Cheap 27 inch Monitor from Dell Dell Australia is currently selling a 27 inch monitor that does 2560*1440 (WQHD) for $899AU. Dell Australia offers a motor club discount which pretty much everyone in Australia can get as almost everyone is either a member of such a club or knows a member well enough to use their membership number for the discount. This discount reduces the price to $764.15. The availability of such a great cheap monitor has caused me to change my working habits. It doesn t make sense to have a reasonably powerful laptop used in one location for almost all the time when a desktop system with a much better monitor can be used. The Plan Now that my 27 inch monitor has arrived I have to figure out a way of making things work. I still need to work from a laptop on occasion but my main computer use is going to be a smart-phone and a desktop system. Email is already sorted out, I already have three IMAP client systems (netbook, laptop, and phone), adding a desktop system as a fourth isn t going to change anything. The next issue is software development. In the past I haven t used version control systems that much for my hobby work, I have just released a new version every time I had some significant changes. Obviously to support development on two or three systems I need to use a VCS rigorously. I m currently considering Subversion and Git. Subversion is really easy to use (for me), but it seems to be losing popularity. Git is really popular so if I use it for my own projects then I could allow anonymous access for anyone who s interested maybe that will encourage more people to contribute. One thing I haven t even investigated yet is how to manage my web browsing work-flow in a distributed manner. My pattern when using a laptop is to have many windows and tabs open at the same time for issues that I am researching and to only close them days or weeks later when I have finished with the issue. For example if I m buying some new computer gear I will typically open a web browser window with multiple tabs related to the equipment (hardware, software, prices, etc) and keep them all open until I have received it and got it working. Chromium, Mozilla, and presumably other modern web browsers have a facility to reopen windows after a crash. It would be ideal for me if there was some sort of similar facility that allowed me to open the windows that are open on another system and to push window open commands to another system. For example when doing web browsing on my phone I would like to be able to push the URLs of pages that can t be viewed on a phone to my desktop system and have them open waiting for me when I get home. It would be nice if web browsing could be conceptually similar to a remote desktop service in terms of what the user sees. Finally in my home directory there are lots of random files. Probably about half of them could be deleted if I was more organised (disk space is cheap and most of the files are small). For the rest it would be good if they could be accessed from other locations. I have read about people putting the majority of their home directory under version control, but I m not sure that would work well for me. It would be good if I could do something similar with editor sessions, if I had a file open in vi on my desktop before I left home it would be good if I could get a session on my laptop to open the same file (well the same named file checked out of the VCS). Configuring the Desktop System One of the disadvantages of a laptop is that RAID usually isn t viable. With a desktop system software RAID-1 is easy to configure but it results in two disks making heat and noise. For my new desktop system I m thinking of using a DRBD device for /home to store the data locally as well as almost instantly copying it to RAID-1 storage on the server. The main advantage of DRBD over NFS, NBD, and iSCSI is that I can keep working if the server becomes unavailable (EG use the desktop system to ask Google how to fix a server fault). Also with DRBD it s a configuration option to allow synchronous writes to return after the data is written locally which is handy if the server is congested. Another option that I m considering is a diskless system using NBD or iSCSI for all storage. This will prevent using swap (you can t swap to a network device to avoid deadlocks) but that won t necessarily be a problem given the decrease in RAM prices as I can just buy enough RAM to not need swap. The Future Eventually I want to be able to use a tablet for almost everything including software development. While a tablet display isn t going to be great for coding I m sure that I can make use of enough otherwise wasted time to justify the expense. I will probably need a tablet that acts like a regular Linux computer not an Android tablet.

7 September 2011

Soeren Sonnenburg: Shogun at Google Summer of Code 2011

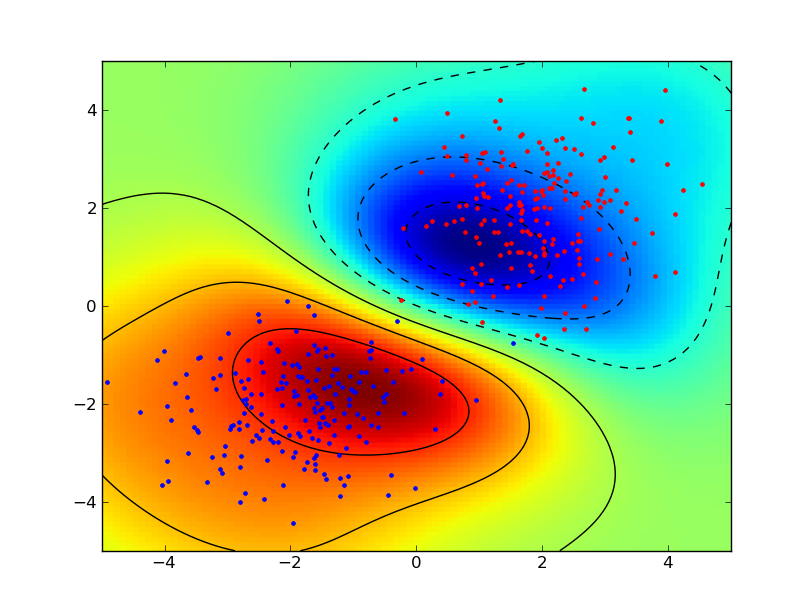
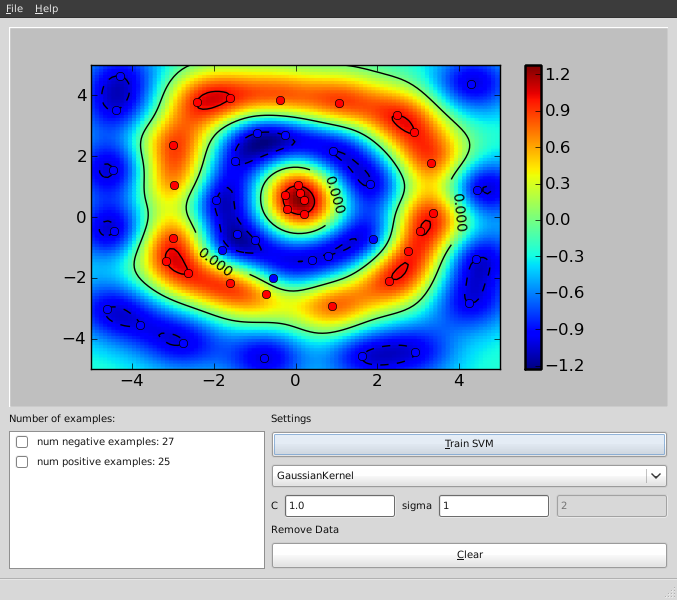
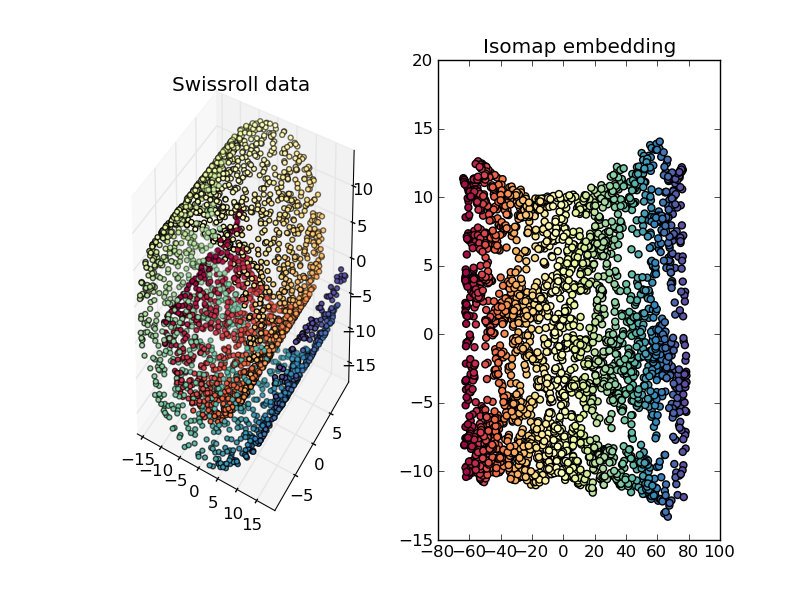
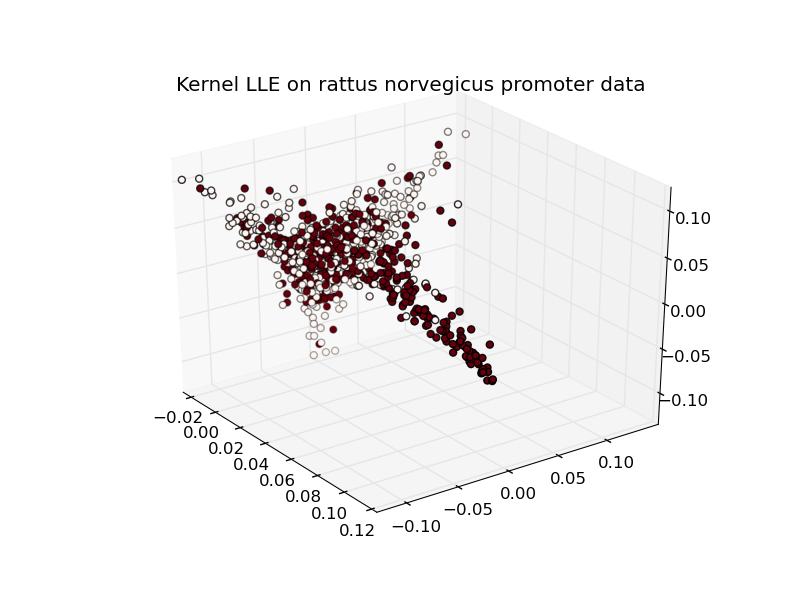
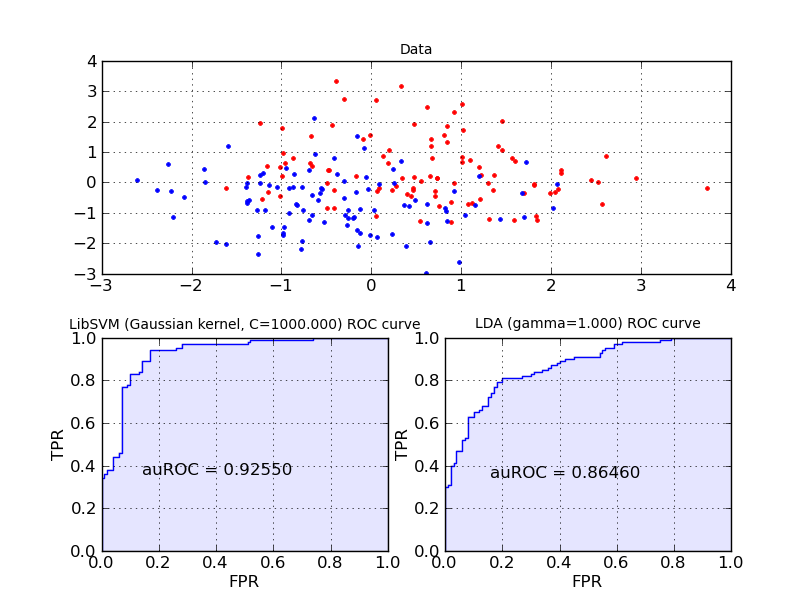
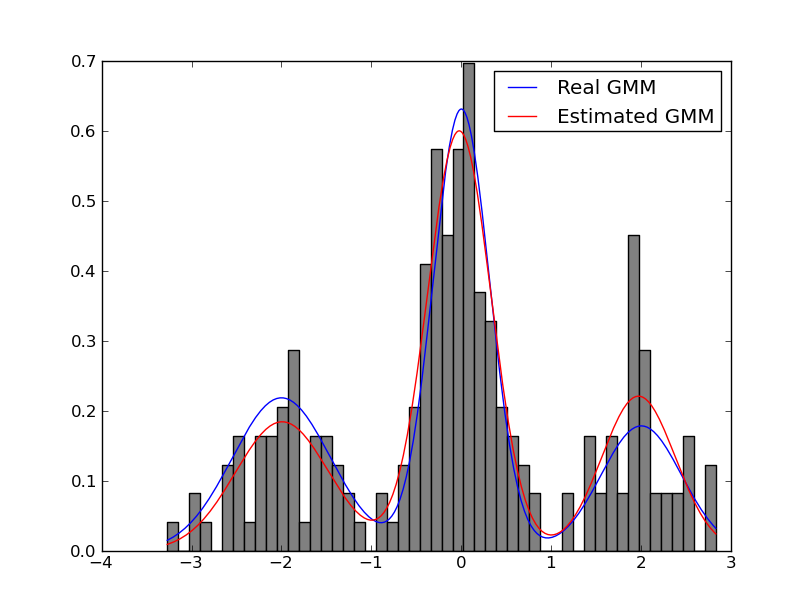
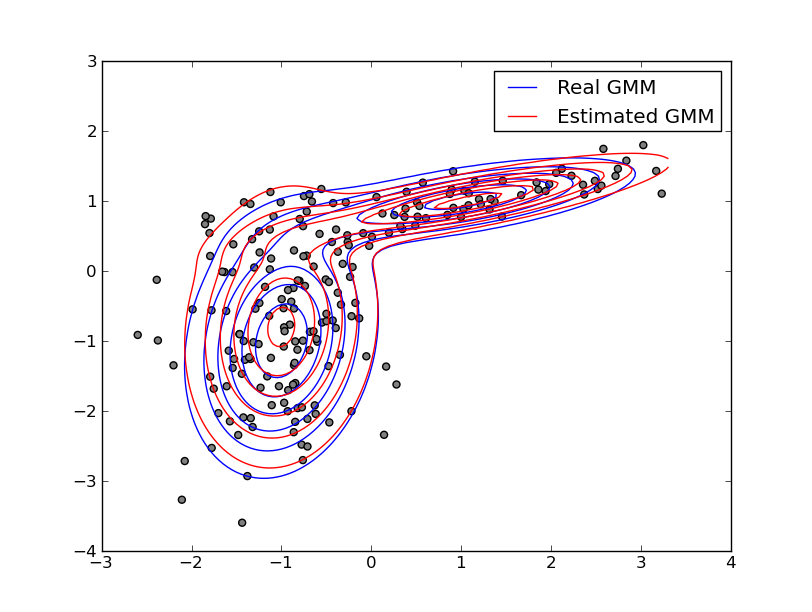
Google Summer of Code 2011 gave a big boost to the development of the shogun machine learning toolbox. In case you have never heard of shogun or machine learning: Machine Learning involves algorithms that do intelligent'' and even automatic data processing and is nowadays used everywhere to e.g. do face detection in your camera, compress the speech in you mobile phone, powers the recommendations in your favourite online shop, predicts solulabily of molecules in water, the location of genes in humans, to name just a few examples. Interested? Then you should give it a try. Some very simple examples stemming from a sub-branch of machine learning called supervised learning illustrate how objects represented by two-dimensional vectors can be classified in good or bad by learning a so called support vector machine. I would suggest to install the python_modular interface of shogun and to run the example interactive_svm_demo.py also included in the source tarball. Two images illustrating the training of a support vector machine follow (click to enlarge): svm svm interactive Now back to Google Summer of Code: Google sponsored 5 talented students who were working hard on various subjects. As a result we now have a new core developer and various new features implemented in shogun: Interfaces to new languages like java, c#, ruby, lua written by Baozeng; A model selection framework written by Heiko Strathman, many dimension reduction techniques written by Sergey Lisitsyn, Gaussian Mixture Model estimation written by Alesis Novik and a full-fledged online learning framework developed by Shashwat Lal Das. All of this work has already been integrated in the newly released shogun 1.0.0. In case you want to know more about the students projects continue reading below, but before going into more detail I would like to summarize my experience with GSoC 2011. My Experience with Google Summer of Code We were a first time organization, i.e. taking part for the first time in GSoC. Having received many many student applications we were very happy to hear that we at least got 5 very talented students accepted but still had to reject about 60 students (only 7% acceptance rate!). Doing this was an extremely tough decision for us. Each of us ended up in scoring students even then we had many ties. So in the end we raised the bar by requiring contributions even before the actual GSoC started. This way we already got many improvements like more complete i/o functions, nicely polished ROC and other evaluation routines, new machine learning algorithms like gaussian naive bayes and averaged perceptron and many bugfixes. The quality of the contributions and independence of the student aided us coming up with the selection of the final five. I personally played the role of the administrator and (co-)mentor and scheduled regular (usually) monthly irc meetings with mentors and students. For other org admins or mentors wanting into GSoC here come my lessons learned: Now please read on to learn about the newly implemented features: Dimension Reduction Techniques Sergey Lisitsyn (Mentor: Christian Widmer) Dimensionality reduction is the process of finding a low-dimensional representation of a high-dimensional one while maintaining the core essence of the data. For one of the most important practical issues of applied machine learning, it is widely used for preprocessing real data. With a strong focus on memory requirements and speed, Sergey implemented the following dimension reduction techniques: See below for the some nice illustrations of dimension reduction/embedding techniques (click to enlarge). isomap swissrollrno kllelocal tangent space alignment Cross-Validation Framework Heiko Strathmann (Mentor: Soeren Sonnenburg) Nearly every learning machine has parameters which have to be determined manually. Before Heiko started his project one had to manually implement cross-validation using (nested) for-loops. In his highly involved project Heiko extend shogun's core to register parameters and ultimately made cross-validation possible. He implemented different model selection schemes (train,validation,test split, n-fold cross-validation, stratified cross-validation, etc and did create some examples for illustration. Note that various performance measures are available to measure how good'' a model is. The figure below shows the area under the receiver operator characteristic curve as an example. foo Interfaces to the Java, C#, Lua and Ruby Programming Languages Baozeng (Mentor: Mikio Braun and Soeren Sonnenburg) Boazeng implemented swig-typemaps that enable transfer of objects native to the language one wants to interface to. In his project, he added support for Java, Ruby, C# and Lua. His knowlegde about swig helped us to drastically simplify shogun's typemaps for existing languages like octave and python resolving other corner-case type issues. The addition of these typemaps brings a high-performance and versatile machine learning toolbox to these languages. It should be noted that shogun objects trained in e.g. python can be serialized to disk and then loaded from any other language like say lua or java. We hope this helps users working in multiple-language environments. Note that the syntax is very similar across all languages used, compare for yourself - various examples for all languages ( python, octave, java, lua, ruby, and csharp) are available. Largescale Learning Framework and Integration of Vowpal Wabbit Shashwat Lal Das (Mentor: John Langford and Soeren Sonnenburg) Shashwat introduced support for 'streaming' features into shogun. That is instead of shogun's traditional way of requiring all data to be in memory, features can now be streamed from e.g. disk, enabling the use of massively big data sets. He implemented support for dense and sparse vector based input streams as well as strings and converted existing online learning methods to use this framework. He was particularly careful and even made it possible to emulate streaming from in-memory features. He finally integrated (parts of) vowpal wabbit, which is a very fast large scale online learning algorithm based on SGD. Expectation Maximization Algorithms for Gaussian Mixture Models Alesis Novik (Mentor: Vojtech Franc) The Expectation-Maximization algorithm is well known in the machine learning community. The goal of this project was the robust implementation of the Expectation-Maximization algorithm for Gaussian Mixture Models. Several computational tricks have been applied to address numerical and stability issues, like An illustrative example of estimating a one and two-dimensional Gaussian follows below. 1D GMM2D GMM Final Remarks All in all, this year s GSoC has given the SHOGUN project a great push forward and we hope that this will translate into an increased user base and numerous external contributions. Also, we hope that by providing bindings for many languages, we can provide a neutral ground for Machine Learning implementations and that way bring together communities centered around different programming languages. All that s left to say is that given the great experiences from this year, we d be more than happy to participate in GSoC2012.

Gunnar Wolf: Language designers, API designers, PHP and utter fails

After many years of successfully dodging doing any serious programming in PHP, I had to get my feet wet with PHP for my RL job: I was requested to develop a simple but non-trivial module for our Institute's Drupal-based webpage. It basically meant two and a half weeks devoted to head-scratching: I had read the very good John van Dyk's Pro Drupal Development book, and knew it would be an important resource were I to face writing a module or work on a theme beyond the most basic stuff So I checked it out of the library, and started basically writing something similar to my good and trusty Perl code. After all, PHP seems quite similar to Perl, although forcing you to write more for no gain (i.e. requiring an array() declaration whenever you want to store more than one value together) or lacking important and useful constructs (not having a sane way to prepare a SQL statement for multiple executions with different parameters Yes, there are DB access methods that do provide it, but Drupal 6 does not use them). Anyway, book in hand, I started understanding while implementing (which is way different than just reading the book, right?) Drupal's notions. I cannot say I like them, but it's ahem doable. Now, I hit a problem twice. I chose to ignore it the first time, as it was a corner case I'd look into later on, but had to devote for hours of my attention later on. When designing the menu (which for Drupal means not only the facility which prepares/displays links to the bits of functionality, but also the access control layer and the action dispatcher a huge yay! for responsability separation!), I had only two access levels: Public and administrator. So, this seemed like a good fit:

  1. $public = array('first/action', 'second/action',
  2. 'third/action', 'something/else');
  3. foreach (array_keys($items) as $item)
  4. if (array_search($item, $public))
  5. $items[$item]['access callback'] = TRUE
  6. else
  7. $items[$item]['access arguments'] = array('diradmin');
But... No matter what I did, the first element in $public refused to be publicly visible. It was not until after a severe amount of head-scratching I came across this jewel in the PHP online manual:
Warning This function may return Boolean FALSE, but may also return a non-Boolean value which evaluates to FALSE, such as 0 or "". Please read the section on Booleans for more information. Use the === operator for testing the return value of this function.
GRAH. Using a sane language for some time had made me forget about the problems of true/false sharing space with other meaningful values. So, yes, checking for inclusion of a value in an array in PHP this way should be compared with class-bound identity (that's what === means) to FALSE, or better yet, using a function that exclusively returns a boolean (as in_array()). Anyway While arrays (which in PHP are any kind of list, be it keyed as a hash or consecutive as a traditional array) are such an usual construct in any language, please do take a look at PHP's array-handling API. Too long. Too complex. Too many corner cases. I cannot but wonder what keeps PHP as a popular language. It hurts.

6 September 2011

Lars Wirzenius: Entropy key: a review

I recently bought a Simtec Entropy Key. It's a hardware randomness generator encapsulated as a USB device, the size of a flash drive. It's good for any host or cluster that uses a lot of kernel-provided random numbers (/dev/random), or does things that cause the kernel to use a lot of random numbers. Opening a lot of network connections, or generating session keys for public key encryption. That kind of stuff. If the kernel has too little entropy available to generate good random numbers, things will stall until it gets some more. The ekey gives you real random bits, not just software-produced pseudo-random numbers. In other words, it's some kind of magic. I got the device in a DVD box, with a leaflet explaining how to install stuff, a CD with the software, an envelope with a secret key, and the actual device itself. I read the leaflet, which said to install the ekeyd daemon first. I ignored the CD, since a) my laptop has no optical drive and b) the software is in Debian stable (squeeze) anyway, so apt-getting it is easier and faster. I was utterly disappointed with the software. I didn't have to edit a single hard disk sector, or do a BIOS upgrade, or anything. Utterly, totally, boring. I had reserved an afternoon and evening for this, but I had to find something else to do instead. After plugging in the device in a spare USB port, I opened the envelope and ran a command to specify the secret key. The key and host processors use encryption to make sure nobody can eavesdrop on the randomness -- that would give them an edge in cracking SSL and GPG encryption, I guess. Here's an example of how it works. Before I plug in the device, the kernel has some, but not too much entropy available:
liw@havelock$ cat /proc/sys/kernel/random/entropy_avail 
1053
A few seconds after the ekey is inserted:
liw@havelock$ cat /proc/sys/kernel/random/entropy_avail 
3968
And here's the kicker: pretty much regardless of what I do, the entropy stays at about 4 kilounits (I don't know if it's bits or bytes, and I'm too lazy to check). In the end, the only thing I can really complain about is the typography and layout of the leaflet. The text is clear enough, but it's laid out too densely. It needs more whitespace. Some pictures of bunnies or kittens would be nice, too.

Joey Hess: water

This was the second most rainy day of the year, so far. 28 hours of solid rain and counting. Good time to take stock of the water situation here at the cabin after a year's experience. The springs were as seasonal as I'd feared. After running strongly all Spring, the main spring ebbed and died in the Summer months. By mid-July there was no remaining source of potable water. If I had not been away so much over the summer it would have been worse. As it was, I needed only twenty gallons of water hauled from neighbor Lee's well. The large cistern was filled in a single night during the most rainy period this Spring, and provided wash water for two months of the summer, and that only lowered it by a quarter. So I could have been less sparing with it, and not relied so much on rain water catchment for supplimental wash water. Today I replaced the pump, so I can use the pressure tank and have running water in the house. I could have done this earlier, but what can I say; I enjoy hauling buckets of water, when it doesn't involve breaking ice. In the winter when there's firewood to haul instead, I'll enjoy the indoor plumbing. Also today, I may have finally fixed the pipe to the large cistern properly, so it won't only fill at the heaviest rain times. Along with the ability to cross-pump water from the small to the large cistern, it should be easier to keep it filled, and I might be able to reduce the turbidity enough that it's potable eventually. Will see. I don't live in a dry region, but this is a relatively dry place for the area. It's been interesting to get a taste of what it'd be like to live somewhere where water is actually scarce.

5 September 2011

Steve McIntyre: Armhf buildds and porter box hosted at ARM

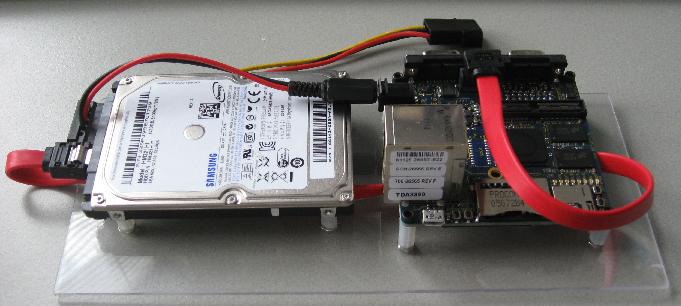
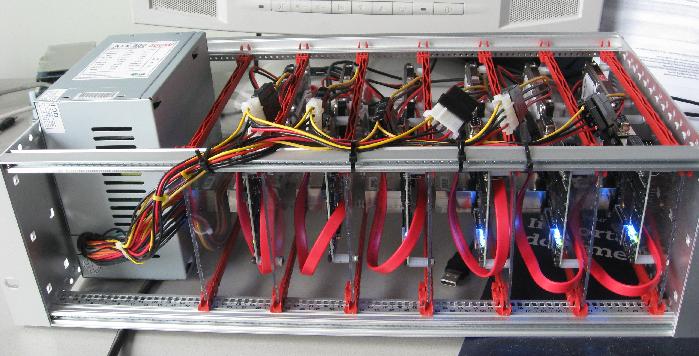
I'm in the middle of setting up new build machines for the armhf port (see the wiki for more details). We'll shortly have six machines set up in the machine room here at ARM in Cambridge: hartmann All of these machines are Freescale i.MX53 Quickstart (aka "loco") development boards. They include a 1GHz i.MX53 CPU (based around the ARM Cortex A8, one of the ARMv7-A family). They have 1GB of RAM and native SATA. They're lovely little machines, measuring just 3 inches square. To mount them usefully in a machine room, I've mounted each board with a 320GB notebook hard drive and the necessary cabling onto a small perspex card as you can see here. Then we can fit 6 such machines and a normal PC-style ATX PSU into a 3U mini-rack. Well, it almost fits - the power supply pokes out a little so we'll need 4U of space when we come to mount it. armhf mini rack The Quickstart boards have been sponsored by Linaro, and ditto my time setting up these machines. Thanks! As is common with new development boards, these machines are not quite fully supported in Debian yet. The kernels we're using are locally-built, using the sources supplied by Freescale. For now, that means a heavily-patched "2.6.35" kernel but we're expecting to be able to switch to mainline very soon. The .config I'm using is kernel.config, and I've built it natively on harris using fakeroot make -j2 deb-pkg DEBEMAIL=93sam@debian.org DEBFULLNAME="Steve McIntyre" KDEB_PKGVERSION=1buildd1 Similarly to the setup for the armel machines, for now I've tweaked things when installing the kernel: Finally, I've tweaked the uboot config on the machines to use the uImage and uInitrd files that are generated by flash-kernel:
MX53-LOCO U-Boot > setenv loadaddr 0x70800000
MX53-LOCO U-Boot > setenv initrdaddr 0x71000000
MX53-LOCO U-Boot > setenv bootargs_sata set bootargs \$\ bootargs\  root=/dev/sda2 rw rootwait
MX53-LOCO U-Boot > setenv load_sata_kernel ext2load sata 0:1 \$\ loadaddr\  /uImage
MX53-LOCO U-Boot > setenv load_sata_initrd ext2load sata 0:1 \$\ initrdaddr\  /uInitrd
MX53-LOCO U-Boot > setenv load_sata run load_sata_kernel load_sata_initrd
MX53-LOCO U-Boot > setenv bootcmd_sata sata init\; run bootargs_base bootargs_sata load_sata\; bootm \$\ loadaddr\  \$\ initrdaddr\ 
MX53-LOCO U-Boot > setenv bootcmd run bootcmd_sata
And I've added extra config into uboot to use the pre-installed Ubuntu system on the micro SD card as a fall-back:
MX53-LOCO U-Boot > setenv bootcmd_rescue sata init\; run bootargs_base bootargs_sata\; mmc read 0 \$\ loadaddr\  0x800 0x1800\; bootm

Tanguy Ortolo: Startup scripts of Bash and Zsh

Both Bash and Zsh use several startup scripts: profile, bashrc, zlogin, zshrc, etc. The existence of several startup scripts exists to allow you to apply specific actions for interactive or login shells. For instance, you may want to set up a fancy colour prompt or to enable a powerful completion system for interactive shells only, as it would be pointless to apply it to non-interactive shells (that is, for shell scripts). Or you may want to display a joke and the weather forecast at login, but not each time you spawn a shell by other means.Common Both Bash and Zsh first execute a system-wide file, then the corresponding user-specific one. For instance, /etc/profile then ~/.profile. For simplicity I shall only mention the files' base names. Bash At startup, depending on the case: At exit, it executes ~/.bash_logout (no system-wide version). Note the funny (read: insane) non-login condition for executing bashrc: it is often worked around by having the profile execute bashrc anyway. Zsh Zsh always executes zshenv. Then, depending on the case: At the end of a login session, it executes zlogout, but in reverse order, the user-specific file first, then the system-wide one, constituting a chiasmus with the zlogin files. Summary
Bash
login
yes no
interactiveyesprofilebashrc
no profile-
Zsh
login
yes no
interactiveyeszshenv zprofile zshrc zloginzshenv zshrc
no zshenv zprofile zlogin zshenv
I personally find the Zsh process much saner. To be honest I should rather say that I find Bash's behaviour insane, with an absurd process (bashrc for interactive, non-login shells ) that needs to be worked around, and an inconsistent naming and search convention (~/.bashrc vs. /etc/bash.bashrc, no system-wide version of bash_logout).

Kai Wasserb ch: What wasn't said about the Linux graphics stack

This post is a small follow-up on yesterday's post about the Linux graphics stack. I'm still keeping to high level stuff and won't dig too deep, but a few questions arose (others reached me by e-mail), so, here we go. Gallium3D is a framework, initially developed by Tungsten Graphics, which were bought by VMware. The idea behind Gallium3D is, that many functions can be shared between drivers for different GPUs and that the effort to support a new platform/system is for classic drivers pretty high. With Gallium3D you just need a state tracker and a target. The state tracker is code, that gives the pipeline of Gallium3D drivers access to a platform/system, like OpenGL or X on various operating systems. A target is the required as glue between a state tracker and the actual driver. For example: there is a state tracker for video playback acceleration (the recently added g3dvl). The state tracker itself offers the interface and common functions (with some help from the auxilliary stuff) between the Gallium3D pipeline and the userland libraries like libvdpau1. Targets like vdpau-[DRIVER] glue the driver and the state tracker together. The winsys part of Gallium3D is a similar concept but it abstracts the windowing system on the target platform away (e.g. Wayland, X or GDI). I didn't write about the proprietary drivers yesterday, as I don't consider them a real part of the Linux graphics stack, more like parasites, and didn't want to encourage anyone to use them (yes, I know, there are some cases in which you might be better off with them, but generally I'd avoid them). Anyway, I got some questions about those (some by e-mail, the other I'm aware off, can be found behind the link at the beginning of this entry). So, where do the proprietary drivers come in? They are basically the entire stack in a closed form, plugging into the public interfaces of the Kernel (whether that's legal is disputed), some other parts like X (by building a DDX) and building their own libGL. Especially the last part can be a cause for a lot of pain, when you don't use the proprietary driver packages offered by the distribution (e.g. Debian's fglrx packages divert the libGL and restore the default one on unistallation, with the vendor build scripts and tools this is not really guaranteed, which might leave you with a broken OpenGL setup). Another question was, why Mesa was lacking support for a recent OpenGL version (i.e. 4.x). In my opinion there are a few reasons, though I don't really feal like the best person to answer this. The first are design issues by some internal representations (e.g. missing integer support in the intermediate representations). The second is the available number of developers being able to implement new OpenGL functions. Apart from a not all too clear specification the Mesa code base is huge (even if you ignore most of the drivers), which makes it difficult for new developers to start coding away. Then you need an understanding of how modern GPUs operate to find good solutions for the problems faced. If you want to get an idea for this, take a look at Zack Rusin's or Alex Deucher's blog. Then, there is a sad split of developers, on the one hand we've got the Gallium3D-using developers on the other we've got the ones staying with the classic driver model. This means, that you have to implement e.g. GLSL extensions for TGSI and Mesa's IR respectivly. There might be other reasons, I'm totally missing, but this should give you some insight into why it takes so long, to get current OpenGL versions supported. I hope this clears some of the remaining questions, if not, feel free to write me an e-mail, but please remember, that this is not an in-depth analysis.

Kai Wasserb ch: Mesa packages on dev.carbon-project.org

Thanks to the awesome patent situation (if you're unaware of what I'm talking, you can catch up by listening to PRI's This American Life episode about patents, reading Florian Mueller's write-ups about the patent wars (current focus: mobile devices) or by having a look into my posts with the "patent-mess" tag), Debian will most likely be unable to distribute Mesa packages with ARB_texture_float enabled (if you want to build mesa yourself with this extension enabled, just add --enable-texture-float to confflags-dri in the Mesa source package's debian/rules). But some programs really like to have this extension, thus I started building Mesa myself. The resulting packages can be found on dev.carbon-project.org. Big fat warning: please check, whether you're affected by the US patent #6,650,327 (i.e. if it's a valid patent in your jurisdiction) before you use the packages. If in doubt, consult with your lawyer. By the way, if you're not working in an area where knowledge of the specifc claims/content of the patent might be harmful, you have some time on your hands and you want to learn, what's "patentworthy" these days, have a look at the claims of the patent. Otherwise the three links from the beginning must do. Before I end this post, just one more remark about my Mesa packages: they'll follow upstream's Git and thus might have problems from time to time. If Debian's Mesa packages suffice your needs, stay with them. If not, feel free to use my packages or use them as a base for your own packages.

4 September 2011

Kai Wasserb ch: Untangling the Linux graphics stack

[UPDATE 2011-09-05]I received some questions (or saw them), which I tried to answer with a follow-up entry.[/UPDATE] As I tried to explain this a few times in the past to others and had trouble myself, when I started using Linux, I thought I take some time today and write down what parts comprise the Linux graphics stack and how they interact. I'll ignore some parts which aren't too interesting to an average user at the moment, to keep this post as consise as possible. Apart from that, I hope I'm able to put all the relevant data into one spot. Let us start our little journey in the kernel. There, in a directory named gpu you'll find the drm directory, which contains all DRM drivers. In this post, we'll focus on those. The drivers in that directory are the kernel side of the Direct Rendering Infrastructure (DRI) and are responsible for managing concurrent access to the graphics hardware. They also provide interfaces to pass commands and data to the GPU. The DRI wiki explains the three main purposes of the DRM modules. The DRM module is also the part that decides whether KMS or UMS is used. Other acronyms you might hear with regard to graphics acceleration on Linux and are referring to the Kernel part are: Apart from that, every driver has its hardware-specific parts like utilizing power-saving functions of the respective GPUs, loading firmware, if required, etc. Now we move from Kernel space to user land. We'll ignore any non-X and non-Mesa parts (like acceleration for TTYs). That means, that our next GPU specific part is most likely the DDX. (Please note, that the classic DDX might be replaced by a Gallium3D state tracker, currently that would be the xorg state tracker, but xorg will be replaced by XA. This is only an option if the Gallium driver for your GPU supports one of those state trackers, see the Gallium status page for further details.) The DDX for your GPU offers plain (2D) X acceleration on your hardware. The respective DDX' are generally named xf86-video-[NAME], where [NAME] is replaced by e.g. ati or intel. The DDX decides which X acceleration paths are available. Acronyms you might hear, referring to the DDX part of the graphics stack, are: We're almost through: the last important part is the 3D acceleration offered by a Mesa driver. Mesa drivers come in two flavours: classic (e.g. all Intel drivers which are supported by Intel) and Gallium3D-based (like the drivers for Radeon chips from the R300 onwards). The difference here is, that the Gallium3D drivers try to share as much code as possible (and thus simplify writing a new driver supporting many platforms, systems and technologies), while the classic drivers are specific to certain platforms, chips, and technologies. They share much less code among each other. All parts of Mesa need direct access to the graphics hardware (DRI) The Mesa drivers use the 3D pipeline of the GPUs for accelerated drawing, even for non-3D applications like video acceleration (recently VDPAU, XvMC and VA support were added to Gallium3D, driver support followed quickly). Otherwise the Mesa drivers are mainly used for OpenGL acceleration. Users of OpenGL include scientific programs, CAD and of course games. This concludes our little journey through the various parts of the Linux graphics stack. I hope it helps in understanding the building blocks.

Rapha&#235;l Hertzog: My Debian activities in August 2011

This is my monthly summary of my Debian related activities. If you re among the people who made a donation to support my work (91.44 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. Dpkg work When I came back from Debconf, I merged my implementation of dpkg-source --commit (already presented last month). I continued some work on the hardening build flags but it s currently stalled waiting on Kees Cook to provide the required documentation to integrate in dpkg-buildflags(1). Following a discussion held during DebConf, Michael Prokop has been kind enough to setup a git-triggered auto-builder of dpkg (using Jenkins). You can now help us by testing the latest git version. Follow those instructions:

$ wget -O - http://jenkins.grml.org/debian/C525F56752D4A654.asc   sudo apt-key add -
$ sudo sponge /etc/apt/sources.list.d/dpkg-git <<END
deb http://jenkins.grml.org/debian dpkg main
END
$ sudo apt-get update && sudo apt-get upgrade
On the bug fixing side I took care of #640198 (minor man page update), #638291 (a fix to correctly handle hardlinks of conffiles), #637564 (the simplification logic of union dependencies was broken in some cases) and #631494 (interrupting dpkg-source while building a native source package left some temporary files around that should have been cleaned). WordPress update I released WordPress 3.2.1 in unstable (after having taken the time to test the updated package on my blog!) and fixed its RC bug (#625773). In the process I discovered a false positive in lintian (I reported it in 637473). Gnome-shell-timer package From time to time, I like to use the Pomodoro Technique. That s why I was an user of timer-applet in GNOME 2. Now with the switch to GNOME 3, I lost this feature. But I recently discovered gnome-shell-timer, a GNOME Shell extension that provides the same features. I created a Debian package of it and quickly filed some bugs while I was testing it (two usability issues and an encoding problem) QA Work During DebConf I met Giovanni Mascellani and he was interested to help the QA team. He started working on the backlog of bugs concerning the Package Tracking System (PTS) and submitted a bunch of patches. I reviewed them and merged them but since they were good, I quickly got lazy and got him added to the QA team so that he can commit his fixes alone. It also helps to build trust when you have had the opportunity to discuss face to face. :-) Vacation That s not so much compared to usual but to my defense I also took 2 weeks of vacation with my family. But somehow even in vacation I can t really forget Debian. Here s my son:
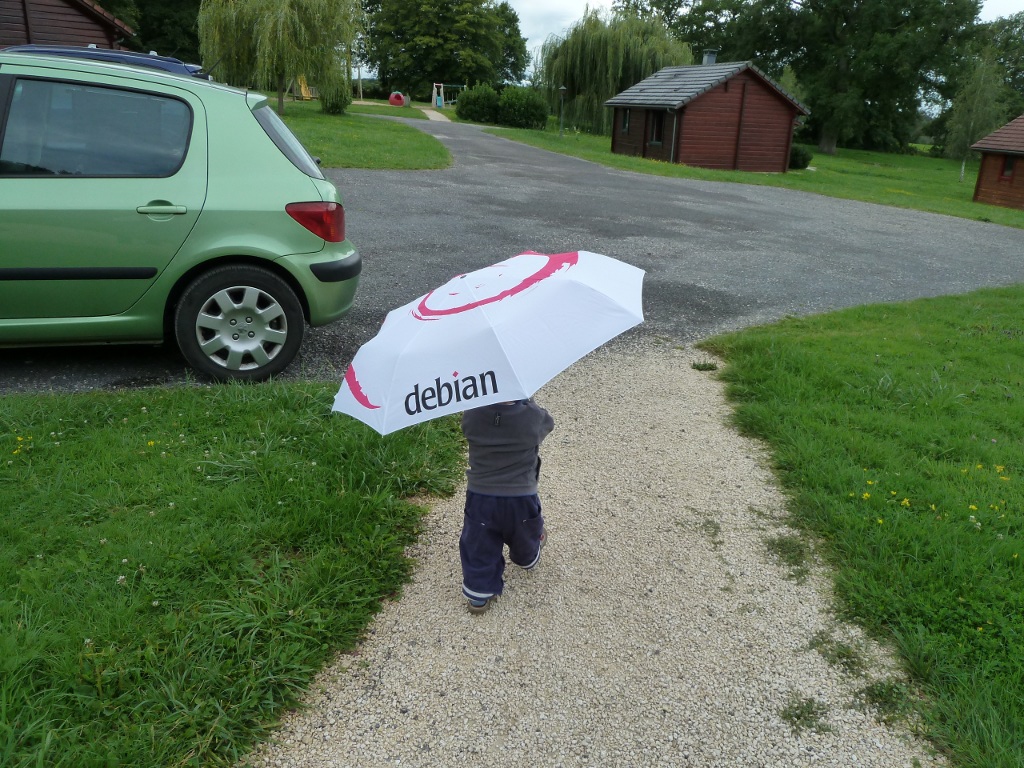
Thanks See you next month for a new summary of my activities.

3 comments Liked this article? Click here. My blog is Flattr-enabled.

2 September 2011

Asheesh Laroia: Debian bug squashing party at SIPB, MIT


(Photo credit: Obey Arthur Liu; originally on Picasa, license.) Three weekends ago, I participated in a Debian bug squashing party. It was more fun than I had guessed! The event worked: we squashed bugs. Geoffrey Thomas (geofft) organized it as an event for MIT's student computing group, SIPB. In this post, I'll review the good parts and the bad. I'll conclude with beaming photos of my two mentees and talk about the bugs they fixed. So, the good:

The event was a success, but as always, there are some things that could have gone more smoothly. Here's that list: Still, it turned out well! I did three NMUs, corresponding to three patches submitted for release-critical bugs by my two mentees. Those mentees were: Jessica enjoying herself Jessica McKellar is a software engineer at Ksplice Oracle and a recent graduate of MIT's EECS program. She solved three release-critical bugs. This was her first direct contribution to Debian. In particular: Jessica has since gotten involved in the Twisted project's personal package archive. Toward the end of the sprint, she explained, "I like fixing bugs. I will totally come to the next bug squashing party." Noah grinning Noah Swartz is a recent graduate of Case Western Reserve University where he studied Mathematics and played Magic. He is an intern at the MIT Media Lab where he contributes to DoppelLab in Joe Paradiso's Responsive Environments group. This was definitely his first direct contribution to Debian. It was also one of the most intense command-line experiences he has had so far. Noah wasn't originally planning to come, but we were having lunch together before the hackathon, and I convinced him to join us. Noah fixed #625177, a fails-to-build-from-source (FTBFS) bug in nslint. The problem was that "-Wl" was instead written in all lowercase in the debian/rules file, as "-wl". Noah fixed that, making sure the package properly built in pbuilder, and then spent some quality time with lintian figuring out the right way to write a debian/changelog. That's a wrap! We'll hopefully have one again in a few months, and before that, I hope to write up a guide so that we run things even more smoothly next time.

Tanguy Ortolo: rxvt-unicode: generate key symbols

rxvt-unicode is a terminal emulator with some interesting features. Here is one of them I find most amazing and elegant: it can generate the symbol characters corresponding to keyboard keys. It works by pressing and releasing + ( is the symbol for the Control key, and is Shift, of course), then the key which symbol you want to get. For instance, to get the Caps lock symbol, you type + , , which gives you the following symbol: . Here are some other nice examples: (Return) (AltGr aka Level3 Shift) (BackSpace) (Insert) (Delete) (Home) (End) (Prior) (Next). Beware that this will not cancel the effect of Caps, Num lock keys: you will get their symbols but also enter the corresponding mode.

Rapha&#235;l Hertzog: Google plus and server to give away

Just a quick note to let you know that (like many free software hackers apparently) I have an account on Google+. I m not using it much yet but I like it in general. It s interesting to see how Google transformed Joindiaspora s aspects into circles . When Google will make an API available, I ll probably setup it like my public Facebook page so that new blog posts are automatically announced. In the mean time, it s going to be very quiet on my Google+ profile. That said, I used it twice this week: the first time because I m looking for a French developer with sysadmin skills, and the second time because I have a server to give away (Pentium IV 3Ghz, 4 Gb RAM, 200 Gb of diskspace in RAID1 Hard). If you take the server for a free software project, it can be hosted for free where it currently is (courtesy of Julien Danjou). So if you re also a Google+ user, feel free to add me to one of your circles.

5 comments Liked this article? Click here. My blog is Flattr-enabled.

1 September 2011

Matthew Garrett: The Android/GPL situation

There was another upsurge in discussion of Android GPL issues last month, triggered by couple of posts by Edward Naughton, followed by another by Florian Mueller. The central thrust is that section 4 of GPLv2 terminates your license on violation, and you need the copyright holders to grant you a new one. If they don't then you don't get to distribute any more copies of the code, even if you've now come into compliance. TLDR; most Android vendors are no longer permitted to distribute Linux.

I'll get to that shortly. There's a few other issues that could do with some clarification. The first is Naughton's insinuation that Google are violating the GPL due to Honeycomb being closed or their "license washing" of some headers. There's no evidence whatsoever that Google have failed to fulfil their GPL obligations in terms of providing source to anyone who received GPL-covered binaries from them. If anyone has some, please do get in touch. Some vendors do appear to be unwilling to hand over code for GPLed bits of Honeycomb. That's an issue with the vendors, not Google.

His second point is more interesting, but the summary is "Google took some GPLed header files and relicensed them under Apache 2.0, and they've taken some other people's GPLv2 code and put it under Apache 2.0 as well". As far as the headers go, there's probably not much to see here. The intent was to produce a set of headers for the C library by taking the kernel headers and removing the kernel-only components. The majority of what's left is just structure definitions and function prototypes, and is almost certainly not copyrightable. And remember that these are the headers that are distributed with the kernel and intended for consumption by userspace. If any of the remaining macros or inline functions are genuinely covered by the GPLv2, any userspace application including them would end up a derived work. This is clearly not the intention of the authors of the code. The risk to Google here is indistinguishable from zero.

How about the repurposing of other code? Naughton's most explicit description is:

For example, Android uses bootcharting logic, which uses the 'bootchartd' script provided by www.bootchart.org, but a C re-implementation that is directly compiled into our init program. The license that appears at www.bootchart.org is the GPLv2, not the Apache 2.0 license that Google claims for its implementation.

, but there's no indication that Google's reimplementation is a derived work of the GPLv2 original.

In summary: No sign that Google's violating the GPL.

Florian's post appears to be pretty much factually correct, other than this bit discussing the SFLC/Best Buy case:

I personally believe that intellectual property rights should usually be enforced against infringing publishers/manufacturers rather than mere resellers, but that's a separate issue.

The case in question was filed against Best Buy because Best Buy were manufacturing infringing devices. It was a set of own-brand Blu Ray players that incorporated Busybox. Best Buy were not a mere reseller.

Anyway. Back to the original point. Nobody appears to disagree that section 4 of the GPLv2 means that violating the license results in total termination of the license. The disagreement is over what happens next. Armijn Hemel, who has done various work on helping companies get back into compliance, believes that simply downloading a new copy of the code will result in a new license being granted, and that he's received legal advice that supports that. Bradley Kuhn disagrees. And the FSF seem to be on his side.

The relevant language in v2 is:

You may not copy, modify, sublicense, or distribute the Program except as expressly provided under this License. Any attempt otherwise to copy, modify, sublicense or distribute the Program is void, and will automatically terminate your rights under this License.

The relevant language in v3 is:

You may not propagate or modify a covered work except as expressly provided under this License. Any attempt otherwise to propagate or modify it is void, and will automatically terminate your rights under this License

which is awfully similar. However, v3 follows that up with:

However, if you cease all violation of this License, then your license from a particular copyright holder is reinstated (a) provisionally, unless and until the copyright holder explicitly and finally terminates your license, and (b) permanently, if the copyright holder fails to notify you of the violation by some reasonable means prior to 60 days after the cessation.

In other words, with v3 you get your license back providing you're in compliance. This doesn't mesh too well with the assumption that you can get a new license by downloading a new copy of the software. It seems pretty clear that the intent of GPLv2 was that the license termination was final and required explicit reinstatement.

So whose interpretation is correct? At this point we really don't know - the only people who've tried to use this aspect of the GPL are the SFLC, and as part of their settlements they've always reinstated permission to distribute Busybox. There's no clear legal precedent. Which makes things a little awkward.

It's not possible to absolutely say that many Android distributors no longer have the right to distribute Linux. But nor is it possible to absolutely say that they haven't lost that right. Any sufficiently motivated kernel copyright holder probably could engage in a pretty effective shakedown racket against Android vendors. Whether they will do remains to be seen, but honestly if I were an Android vendor I'd be worried. There's plenty of people out there who hold copyright over significant parts of the kernel. Would you really bet on all of them being individuals of extreme virtue?

comment count unavailable comments

31 August 2011

Axel Beckert: Useful but Unknown Unix Tools: How wdiff and colordiff help to choose the right Swiss Army Knife

In light of the fact that it seems possible to fit the plastic caps of a Debian branded Swiss Army Knife (Last orders today!) on an existing Swiss Army Knife (German written howto as PDF), I started to think about which Victorinox Cybertool would be the best fitting for me. And because the Victorinox comparison page doesn t really show diffs, just columns with floating text which are not very helpful for generating diffs in your head, I used command line tools for that purpose: wdiff Because the floating texts are not line- but just whitespace-based, the tool of choice is not diff but wdiff, a word-based diff. It encloses additions and removals in + + and [- -] blocks. (No, those aren t Japanese smileys although they look a lot like some. ^^). The easiest and clearest way is to copy and paste the texts from Victorinox comparison page into some text files and compare them with wdiff:
$ wdiff cybertool34.txt cybertool41.txt
+Schraubendreher 2.5mm,+ Pinzette, N hahle mit Nadel hr, +Holzs ge,+ Bit-Schl ssel( 5 mm Innensechskant f r die D-SUB Steckverbinder, 4 mm Innensechskant f r Bits, Bit Phillips 0, Bit Phillips 1, Bit-Schlitzschrauben 4 mm, Bit Phillips 2, Bit Hex 4 mm, Bit Torx 8, Bit Torx 10, Bit Torx 15 ), Kombizange( H lsenpresser, Drahtschneider ), Stech-Bohrahle, Kugelschreiber( auch zum DIP-Switch verstellen ), Mehrzweckhaken (Pakettr ger), +Metalls ge( Metallfeile, Nagelfeile, Nagelreiniger ),+ Dosen ffner( kleiner Schraubendreher ), Kleine Klinge, Grosse Klinge, Ring, inox, Mini-Schraubendreher, Kapselheber( Schraubendreher, Drahtabisolierer ), +Holzmeissel / Schaber,+ Bit-Halter, Stecknadel, inox, Schere, Korkenzieher, Zahnstocher
So this already extracted the information which are the seven tools which are in the Cybertool 41, but not in the Cybertool 34. Nevertheless the diff is still not easily recognizable on the first glance. There are several ways to help here. First wdiff has an option --no-common (the according short option is -3) which just shows added and removed words:
$ wdiff -3 cybertool34.txt cybertool41.txt
======================================================================
 +Schraubendreher 2.5mm,+ 
======================================================================
  +Holzs ge,+ 
======================================================================
  +Metalls ge( Metallfeile, Nagelfeile, Nagelreiniger ),+ 
======================================================================
  +Holzmeissel / Schaber,+ 
======================================================================
This is already way better to quickly recognize the actual differences. But if you still also want to see the common tools of the two knifes you need some visual help: One option is to use wdiff s --terminal (or short -t) option. Added words are then displayed inverse and removed words are shown underlined (background and foreground colors hardcoded as there is no invert colors style in CSS or HTML):

$ wdiff -t cybertool34.txt cybertool41.txt
Schraubendreher 2.5mm, Pinzette, N hahle mit Nadel hr, Holzs ge, Bit-Schl ssel( 5 mm Innensechskant f r die D-SUB Steckverbinder, 4 mm Innensechskant f r Bits, Bit Phillips 0, Bit Phillips 1, Bit-Schlitzschrauben 4 mm, Bit Phillips 2, Bit Hex 4 mm, Bit Torx 8, Bit Torx 10, Bit Torx 15 ), Kombizange( H lsenpresser, Drahtschneider ), Stech-Bohrahle, Kugelschreiber( auch zum DIP-Switch verstellen ), Mehrzweckhaken (Pakettr ger), Metalls ge( Metallfeile, Nagelfeile, Nagelreiniger ), Dosen ffner( kleiner Schraubendreher ), Kleine Klinge, Druckkugelschreiber, Grosse Klinge, Ring, inox, Mini-Schraubendreher, Kapselheber( Schraubendreher, Drahtabisolierer ), Holzmeissel / Schaber, Bit-Halter, Stecknadel, inox, Schere, Korkenzieher, Zahnstocher

But some still like to to use color instead of the contrast-rich inverse and the easily to oversee underlining. This is where colordiff comes into play: colordiff colordiff is like syntax highlighting for diffs on the command line. I works with classic and unified diffs as well as with wdiffs and debdiffs (the debdiff command is part of the devscripts package).
$ wdiff cybertool34.txt cybertool41.txt colordiff
+Schraubendreher 2.5mm,+ Pinzette, N hahle mit Nadel hr, +Holzs ge,+ Bit-Schl ssel( 5 mm Innensechskant f r die D-SUB Steckverbinder, 4 mm Innensechskant f r Bits, Bit Phillips 0, Bit Phillips 1, Bit-Schlitzschrauben 4 mm, Bit Phillips 2, Bit Hex 4 mm, Bit Torx 8, Bit Torx 10, Bit Torx 15 ), Kombizange( H lsenpresser, Drahtschneider ), Stech-Bohrahle, Kugelschreiber( auch zum DIP-Switch verstellen ), Mehrzweckhaken (Pakettr ger), +Metalls ge( Metallfeile, Nagelfeile, Nagelreiniger ),+ Dosen ffner( kleiner Schraubendreher ), Kleine Klinge, Grosse Klinge, Ring, inox, Mini-Schraubendreher, Kapselheber( Schraubendreher, Drahtabisolierer ), +Holzmeissel / Schaber,+ Bit-Halter, Stecknadel, inox, Schere, Korkenzieher, Zahnstocher
$ wdiff cybertool29.txt cybertool41.txt colordiff
+Schraubendreher 2.5mm,+ Pinzette, N hahle mit Nadel hr, +Holzs ge,+ Bit-Schl ssel( 5 mm Innensechskant f r die D-SUB Steckverbinder, 4 mm Innensechskant f r Bits, Bit Phillips 0, Bit Phillips 1, Bit-Schlitzschrauben 4 mm, Bit Phillips 2, Bit Hex 4 mm, Bit Torx 8, Bit Torx 10, Bit Torx 15 ), +Kombizange( H lsenpresser, Drahtschneider ),+ Stech-Bohrahle, +Kugelschreiber( auch zum DIP-Switch verstellen ), Mehrzweckhaken (Pakettr ger), Metalls ge( Metallfeile, Nagelfeile, Nagelreiniger ),+ Dosen ffner( kleiner Schraubendreher ), Kleine Klinge, [-Druckkugelschreiber,-] Grosse Klinge, Ring, inox, Mini-Schraubendreher, Kapselheber( Schraubendreher, Drahtabisolierer ), +Holzmeissel / Schaber,+ Bit-Halter, Stecknadel, inox, +Schere,+ Korkenzieher, Zahnstocher
(Coloured Screenshots done with ANSI HTML Adapter from the package aha.) Some, especially those who are used to git, are probably confused by the default choice of diff colors. This is easily fixable by writing the following into you ~/.colordiffrc:
newtext=green
oldtext=red
diffstuff=darkblue
cvsstuff=darkyellow
(See also /etc/colordiff for the defaults and hints.) colordiff has by the way two operating modes: So now let us compare the Cybertool 29 with Cybertool 34 in a normal diff (by using the texts from above and replacing all commata with newline characters) with git-like colors:
$ colordiff cybertool29-lines.txt cybertool34-lines.txt
12a13,14
> Kombizange( H lsenpresser
> Drahtschneider )
13a16,17
> Kugelschreiber( auch zum DIP-Switch verstellen )
> Mehrzweckhaken (Pakettr ger)
16d19
< Druckkugelschreiber
25a29
> Schere
Or as unifed diff with some context:
$ colordiff -u cybertool29-lines.txt cybertool34-lines.txt
--- cybertool29-lines.txt     2011-08-31 20:55:37.195546238 +0200
+++ cybertool34-lines.txt   2011-08-31 20:55:11.667710504 +0200
@@ -10,10 +10,13 @@
 Bit Torx 8
 Bit Torx 10
 Bit Torx 15 )
+Kombizange( H lsenpresser
+Drahtschneider )
 Stech-Bohrahle
+Kugelschreiber( auch zum DIP-Switch verstellen )
+Mehrzweckhaken (Pakettr ger)
 Dosen ffner( kleiner Schraubendreher )
 Kleine Klinge
-Druckkugelschreiber
 Grosse Klinge
 Ring
 inox
@@ -23,5 +26,6 @@
 Bit-Halter
 Stecknadel
 inox
+Schere
 Korkenzieher
 Zahnstocher
So if you want nicely colored diffs with Subversion like you re used to with git, you can use svn diff colordiff.

30 August 2011

Keith Packard: TeleMini

TeleMini Dual-deploy altimeter with telemetry now available TeleMini is a miniature dual-deploy flight computer with data logging and radio telemetry. Small enough to fit comfortably in an 18mm tube, this powerful package does everything you need on a single board: I don t have anything in these images to show just how tiny this board is but the spacing between the screw terminals is 2.54mm (0.1in), and the whole board is only 13mm wide (1/2in). We ve been flying these for quite a while; testing the hardware and tuning the firmware. My new 29mm mmt airframe, Koala, sports a TeleMini board for apogee-only deployment. It s been really nice to have something flying on G s and H s that doesn t depend on the vagaries of delay grains.

Next.

Previous.