Search Results: "nate"

13 April 2008

Clint Adams: Write-in campaign

Since Ari was too incompetent to successfully complete a self-nomination this year, I have taken the liberty of writing his platform for him against his will.
Ari's Platform What follows is a grassroots movement for positive social change through fostering and giving voice to initiatives and local activism, civic engagement, volunteerism, taking trendy Whole Foods tote bags to supermarkets that are not Whole Foods, and the broader motif of green, eco-friendly, environmentally-sound, community-based, issue-driven, civic-minded focus on saving the environment through awareness of energy and power. Even though recycling consumes lots of energy and pollutes the ground and water, do it anyway. You can make up for it by buying carbon offsets. You don't need to buy carbon offsets for aluminum can recycling, since that is actually good for the environment on a long-term basis, but you should, since it's Fun. Always recycle!
The worst team dynamics can be found in appointed teams. The best team dynamics can be found in self-selecting teams.
Give some thought to the teams (Small or otherwise) you observe. The self-selecting teams are well-oiled machines, competent and effective in every way. In stark contrast, the appointed teams are vulnerable to cronyism, acceptance of bribes, poor communication, pettiness, abuse of power, tunnel vision, xenophobia, and egomania. Who is appointing these teams? It should be stopped, and all teams should be self-selecting to avoid these problems. Face-to-face meetings and events are very important, but we are being terribly irresponsible by using planes, trains, and automobiles. We need to reduce our carbon footprint, so bicycles should be the preferred tool of transportation, and therefore travel sponsorship should be allocated according to these categories: Spandex, Chamois, and Mudflap.
  • Self-nomination
Currently, too many people nominate others for tasks. This leads to an unfortunate mix of egoists and people that no one believes can do the job. Even the nominators have no faith; the only reason they are nominating others is that they know it would be necessary to nominate themselves otherwise. Instead, everyone should take it upon themselves to self-nominate for any position they can, whether they are qualified or not, as it will look good on college transcripts. Only this can ensure that we get the most qualified applicants. Remember, if you do not claim to know better than everyone else, no one can trust you. Relations with SPI have been strained for quite some time, probably because their routine operations resemble a bad episode of The Simpsons. This can be fixed by delegating five hundred people to show up to each month's meeting and bikeshed about American politics and modern fashions.
  • Conservation of power and hats
There have been many attempts to defang concentrations of power and influence and all this does is prevent things from getting done. The proper solution is to give as many hats as possible to the people who get things done. They have already demonstrated that they are trustworthy by getting things done and by having hats, so there is no problem with giving them more hats. Ideally the hats would be fashionable. In order to prevent territorialism and cabals, each person with a hat should be able to give hats to anyone else, but only if the recipient already has a hat. If anyone collects 15 or more hats, he may crown himself High Milliner and proceed to award himself additional hats. Since women do not, as a rule, wear hats, they cannot participate in the hat exchange.
I do not agree with Ari's platform; therefore I will not be writing him into my ballot.

Julien Blache: Getting things done on SANE again

There have been a number of discussions on sane-devel in the past months revolving around the SANE2 standard (still in development) and/or extensions to the current SANE1 standard. SANE2 is an effort that has been “ongoing” (on and off, mostly off, unfortunately) for a number of years already. This led to a number of questions being raised, most notably this one: do we need SANE2, or can we get away only with extensions to SANE1? Or should we just redesign the whole stack from the ground up?
This matter is undecided as of yet, but extensions to SANE1 are planned, being discussed or in the making for some of them. During the discussions, a fork of SANE has been announced, dubbed “SANE Evolution”. No idea where that is going, but it’ll probably end up being merged back into SANE in the end. So, in a nutshell, things are moving again (albeit slowly), which is good news considering the project was mostly asleep in recent times. To celebrate that (and because I now have total control over my free time again), I’ve been working on the network side of SANE again. In 2 weeks (3 week-ends, roughly): Turning saned into a regular daemon made it possible to clean up a good chunk of the code duplication that was introduced by my previous AF-indep/IPv6 work; the startup code is readable again. The Avahi support is (I hope) a very nice thing as, when enabled, configuration of the net backend on the client side is no longer needed. This is an experimental feature still and as such it’s disabled by default at build time. I have a couple of ideas to improve that feature, but this means saned will have to evolve even more so it’ll take some time. The WireShark dissector is a tool for working on enhancing the network protocol. It proved useful already with the information leak I spotted with it (though it’s minor). It’ll be a long work to extend the network protocol and implement that into saned and the net backend in a backward-compatible manner.

Russell Coker: Car Sharing in Melbourne

Recently I noticed that some parking spots in the city area are reserved for car sharing. There seems to be two car sharing companies operating. Flexicar [1] costs $50 to join, has a $10 per month membership fee (which includes one hour of driving at a value of $12), and costs $12 per hour or $80 per day to drive a car plus $0.15 per Km if you drive more than 100Km in a day. They also have pre-paid plans which bring all the guesswork and complexity of mobile phone bills to car rental. Also they give discounts to members of the City Rewards [2] program which are greater than the membership cost, so anyone who plans to join them should join City Rewards first. To use a car you phone up or use their web site to make a reservation. Then you find the car you reserved at it’s designated location and swipe your card across the windscreen to unlock the doors (presumably it’s an RFID card). The glovebox has the key for the ignition as well as fuel cards for any fuel you use a BP, Shell, and Caltex petrol stations (presumably if you run low on petrol when not near those ones you end up paying). All you pay is the rental rate and any tolls for toll roads you use. When someone doesn’t return the vehicle to it’s designated spot on time there are penalty rates, which may include the cost of a taxi fare for the next person who had booked it. It seems like a really good idea that can save significant amounts of money for people who live in the central areas (the costs of maintaining and insuring a car are significant, as is the depreciation on a new car as an asset). The competitor is Charterdrive [3] which costs $25 to join (less than Flexicar but the same once you consider the discount), the same $10 per hour for 8:30AM to 5:30PM hours, and then cheaper rates for evenings and weekends. $25 for a night (5:30PM to 8:30AM the next morning) is good value if you want to drive home from work and then return the next day (if you work late then you might expect to pay $30 or more for a single taxi ride to get home). The weekend rate of $90 for 5:30 Friday to 8:30 Monday is also quite competitive, I expect that there are many people who only use a car on the weekend who could benefit a lot from this. $90 per weekend for 40 weekends a year (some weekends you would stay home or just use public transport) is $3600, insurance, registration, and basic maintenance of a car that you would want to own would cover most of that. Charterdrive does charge $0.20 per Km though for all journeys (with a discount rate of $0.15 per Km for long journeys on some plans), as opposed to Flexicar only charging $0.15 per Km for distances in excess of 100Km per day. Charterdrive seems to be a newer company and has a far smaller presence. But it’s business model seems a little different and the focus on renting cars for people to drive home means that some people might benefit from being members of both companies. The $0.20 per Km makes Charterdrive more expensive more expensive for most city use, and the discounts offered for Flexicar seem to make it cheaper for use during business hours. Charterdrive states that they have a deal with Red Spot Car Rentals [4]. It is not stated on their web site if you want to use one of their cars and they are all in use, I wonder whether a Red Spot car would be provided for the same price. Flexicar however claims that they aim to have a ratio of cars to members sufficient to make such things unlikely. Maybe it would be prudent to join both organisations so that if one had no vehicles available then you could use the other? In one city car park that I often pass the Flexicar and Charterdrive parking spots are adjacent so there would be no difference in convenience in terms of which one you use. I wonder whether they will continue getting adjacent spots. If many people join both organisations then it would be more effective if they don’t get adjacent spots to get better aggregate coverage. I think that at the moment the main challenge for both companies is to grow the popularity of the car-sharing business. I expect that the real competition for who gets the biggest slice of that business will happen in a few years time. Update: There is another Australian car-share company in operation named GoGet [5], interestingly I discovered their existence when I reviewed the Google advertising on this post… GoGet has a significant presence in Sydney, a small presence in Melbourne, and is only making a start in Queensland. Their hourly rates are significantly lower than the others (as little as $4.40 per hour) but distance rates are as high as $0.35 per Km. One significant benefit is that they have plans for two or three drivers which could allow an entire family to sign up on one account. If you drive less than 20Km in an hour (which would not be uncommon in city driving) then GoGet would be cheapest.

12 April 2008

Russell Coker: A Bio-fuel Petrol Station

Today I happened to see a bio-fuel petrol station! I decided to check it out (even though I was traveling by tram in a part of town that I don’t normally visit so there was no possibility of any real purchase). The station is Conservo [1]. Their main products are E10 petrol (10% Ethanol and 90% Petrol), B20 bio-Diesel (20% bio-Diesel and 80% Petroleum based fuel oil), and B100 (100% bio-Diesel). All the fuel that they sell has a biological based component. The prices for the fuel seemed a little lower than is charged by other petrol stations, but it’s difficult to tell as fuel prices can change rapidly. I spoke to one customer who had just filled up his 4WD with bio-Diesel about his experiences. He said that he sometimes used B20 and sometimes B100. He had found no down-side to using such fuels but had noticed that when under hard acceleration the bio-Diesel fuel seemed to cause less dark smoke (IE less soot). All the fuels that they sell are produced in Australia. There are issues with imported bio-fuels which are sometimes produced with slash and burn agriculture and often increase the prices for essential food items (such as corn in South America). As the fuel is produced in Australia such issues should not apply. According to a brochure they have facilities to allow people to deposit used vegetable oil which can then be converted to bio-Diesel. Inside the store they sell a variety of organic foods and drinks, I bought a bottle of carbonated organic apple juice which was quite nice and at $3 was not outside the price range that I expect from a petrol station (which do tend to charge high rates for refreshments). It was not an unreasonably high price for an organic drink. In the store they sell and promote a range of producthttp://en.wikipedia.org/wiki/Flash_points that are positive for the environment. They have a display about using algae to produce bio-Diesel fuel which has some interesting information but unfortunately didn’t list the productivity of algae fields in terms of the number of tons per hectare per year (or month or other time period). One really interesting point I read on their web site concerns the flash point [2] of fuel. The flash-point is the temperature which allows enough of the flammable substance to evaporate to produce an ignitable mixture. Petrol is listed as less than -40C, fossil-Diesel fuel is greater than 62C according to Wikipedia (greater than 55C according to Conservo) while Conservo list the flash point of bio-Diesel as greater than 110C. Wikipedia lists the flash point of canola (rape seed) oil as 327C. This is described as being a benefit of bio-Diesel. While it’s obvious that this is a disadvantage for Petrol, I find it difficult to imagine a situation where a fuel tank could reach a temperature greater than 55C but less than 110C. In their Good for the Environment [3] page they claim that the exhaust from burning bio-Diesel is less harmful to human health than that from burning fossil fuels. My previous post about Vegie Cars [4] is getting some comments suggesting otherwise. So far I haven’t found good references either way, but the discussion has raised some really good issues. Update: Petrol’s flash-point is less than -40C not +40C.

11 April 2008

Evan Prodromou: 22 Germinal CCXVI

It's been a long time since I've written on my blog; longer than I'd like. I really want to get back in the swing of it, if only to keep this entire site from bitrotting interminably. My Alexa ranking has dropped to like >1M, which in my Web-addled state means that my personal worth has dropped, too. I know, I know. tags:

Conference of the Americas: Cancelled I was sorry to see that the Wikimedia Conference of the Americas, scheduled for mid-May, has been canceled. There was some controversy when this conference was announced last fall; it partly originated from a bid by the Atlanta Wikimedia community to host Wikimania. I'm kind of sad to see that it's not going to happen. I like Atlanta a lot, and I think there is a really good case to be made for regional (or at least continental) Wikimedia conferences. I hope this isn't a nail in the coffin for such a regional event in North America. On the flip side, it'd be really nice to see a more detailed explanation of what happened; of what future plans for the COTA are; and just generally a little more communication. tags:

Elsewhere in wikidom That all said, things are looking really cool for Wikimania over the next 12 months. I'm really glad to see that my South American home-away-from-home, Buenos Aires, won the chance to host the 2009 Wikimania event. With 2008's event in Alexandria, Egypt, I think we've got some seriously interesting ground to cover Wikimedia-wise. Also of importance: if you haven't received an invite yet, get yourself over to RecentChangesCamp 2008. The wiki unconference will be happening for the first time in the Bay Area (California). We'll be meeting over May 9-11 in the offices of SocialText in Palo Alto. I can't say enough good things about RecentChangesCamp. It has been instrumental in my understanding of wikis and my connection with the worldwide wiki community. If you are at all interested in wikis or related concepts, you should think hard about coming to this conference. tags:

Brain bits
  • I think microrevie.ws is pretty cool. I got the 100th review today! Yay for me.
  • Speaking of twitter stuff, I dig twittermap, but I don't always remember to update. IWBNI there was a portal to/from Fire Eagle.
tags:

10 April 2008

Russell Coker: Football Cards and Free Kittens

My cousin Greg Coker has created an eBay auction for Football cards with the proceeds going to a charity that protects animal welfare (I can’t remember the name - I’ll update this post later). He also has a bunch of other eBay auctions of football cards going which are not for charity. The charity auction is held in association with SEN (Sports Entertainment Network - a sports talk-back AM radio station) [1]. This afternoon Greg was interviewed on SEN about football cards in general. He gave a good talk, he could probably do some professional radio work if he was interested. Greg’s cards are from the VFL (Victorian Football League) before it became the AFL (Australian Football League) [2]. The cards used to be sold in “milk bars” (small stores that sold a variety of junk food and some essential food items including milk - most such stores are closed now as they have been replaced by petrol stations and supermarkets) and each pack of ~5 cards had some crewing gum included (which Greg often discarded because he didn’t like it - he should have given it to me, I was not so fussy). The back side of the cards had a jigsaw picture which I have never seen anyone complete (I expect that Greg has assembled at least one jigsaw as he has some sets). Probably the way the cards were collected, traded, etc is very similar to sports based cards from other countries (such as baseball cards in the US). On the animal front, I’ve had a mother cat and four kittens move into the shed in my back-yard. The mother cat has no collar and is not known by anyone in the area so she appears to have been dumped by her owner when she got pregnant. There are four kittens, one is ginger, one is black, and two are mottled part black and part ginger. They are all healthy and friendly and the kittens are all really cute. The kittens have become used to being patted and handled by humans so it will be easy to make them household pets. If an owner is not found for them then they will probably all end up being put to sleep (unfortunately I can’t keep them so I’ll have to deliver them to the local council). If anyone in Melbourne, Australia wants some free cats then I would be happy to deliver them. I’ll supply as many cats as desired. I can’t give away the mother until the kittens have been given away, so if you want the mother cat (dark coloured) then you may have to wait for a while. Judging by the date that I first noticed them (when they were walking around, had their eyes open, and ate solid food) the kittens would have to be at least 7 weeks old. It’s recommended that kittens not be given away before they are 8 weeks old and given that it will probably take a week to organise anything I expect that anyone who reads I don’t think that there is any risk of giving them away too early. Please let me know by email or a comment if you are in the vicinity of Melbourne, Australia and want a new pet (or several new pets).

9 April 2008

Anthony Towns: Select and Python Generators

One of the loveliest things about Unix is the select() function (or its replacement, poll()), and the way it lets a single thread handle a host of concurrent tasks efficiently by just using file descriptors as work queues. Unfortunately, it can be a nuisance to use – you end up having to structure your program as a state machine around the select() invocation, rather than the actual procedure you want to have happen. You can avoid that by not using select() and instead just having a separate thread/process for every task you want to do – but that creates a bunch of tedious overhead for the OS (and admin) to worry about. But magically making state machines is what Python’s generators are all about; so for my little pet project that involves forking a bunch of subprocesses to do the interesting computational work my python program wants done, I thought I’d see if I could use that to make my code more obvious. What I want to achieve is to have a bunch of subprocesses accepting some setup data, then a bunch of two byte ids, terminated by two bytes of 0xFF, and for each of the two byte inputs to output a line of text giving the calculation result. For the time being at least, I want the IO to be asynchronous: so I’ll give it as many inputs as I can, rather than waiting for the result before sending the next input. So basically, I want to write something like:

def send_inputs(f, s, n):
	f.write(s) # write setup data
	for i in xrange(n):
		f.write(struct.pack("!H", i))
	f.write(struct.pack("!H", 0xFFFF))
def read_output(f):
	for line in f:
		if is_interesting(line):
			print line
Except of course, that doesn’t work directly because writing some data or reading a line can block, and when it does, I want it to be doing something else (reading instead of writing or vice-versa, or paying attention to another process). Generators are the way to do that in Python, with the “yield” keyword passing control flow and some information back somewhere else, so adopting the theory that: (a) I’ll only resume from a “yield” when it’s okay to write some more data, (b) if I “yield None” there’s probably no point coming back to me unless you’ve got some more data for me to read, and (c) I’ll provide a single parameter which is an iterator that will give me input when it’s available and None when it’s not, I can code the above as:

def send_inputs(_):
	# s, n declared in enclosing scope
	yield s
	for i in xrange(n):
		yield struct.pack("!H", i))
	yield struct.pack("!H", 0xFFFF)
def read_output(f):
	for line in f:
		if line is None: yield None; continue
		if is_interesting(line):
			print line
There’s a few complications there. For one, I could be yielding more data than can actually be written, so I might want to buffer there to avoid blocking. (I haven’t bothered; just as I haven’t worried about “print” possibly blocking) Likewise, I might only receive part of a line, or I might receive more than one line at once, and afaics a buffer there is unavoidable. If I were doing fixed size reads (instead of line at a time), that might be different. So far, the above seems pretty pleasant to me – those functions describe what I want to have happen in a nice procedural manner (almost as if they had a thread all to themselves) with the only extra bit the “None, None, continue” line, which I’m willing to accept in order not to use threads. Making that actually function does need a little grunging around, but happily we can hide that away in a module – so my API looks like:

p = subprocess.Popen(["./helper"], stdin=PIPE, stdout=PIPE, close_fds=True)
comm = communicate.Communication()
comm.add(send_inputs, p.stdin, None)
comm.add(read_output, None, p.stdout, communicate.ByLine())
comm.communicate()
The comm.add() function takes a generator function, an output fd (ie, the subprocess’s stdin), an input fd (the subprocess’s output), and an (optional) iterator. The generator gets created when communication starts, with the iterator passed as the argument. The iterator needs to have an “add” function (which gets given the bytes received), a “waiting” function, which returns True or False depending on whether it can provide any more input for the generator, and a “finish” function that gets called once EOF is hit on the input. (Actually, it doesn’t strictly need to be an iterator, though it’s convenient for the generator if it is) The generator functions once “executed” return an object with a next() method that’ll run the function you defined until the next “yield” (in which case next() will return the value yielded), or a “return” is hit (in which case the StopIteration exception is raised). So what we then want to do to have this all work then, is this: (a) do a select() on all the files we’ve been given; (b) for the ones we can read from, read them and add() to the corresponding iterators; (c) for the generators that don’t have an output file, or whose output file we can write to, invoke next() until either: they raise StopIteration, they yield a value for us to output, or they yield None and their iterator reports that it’s waiting. Add in some code to ensure that reads from the file descriptors don’t block, and you get:

def communicate(self):
    readable, writable = [], []
    for g,o,i,iter in self.coroutines:
        if i is not None:
            fcntl.fcntl(i, fcntl.F_SETFL, 
                        fcntl.fcntl(i, fcntl.F_GETFL)   os.O_NONBLOCK)
            readable.append(i)
        if o is not None:
            writable.append(o)
    
    while readable != [] or writable != []:
        read, write, exc = select.select(readable, writable, [])
        for g,o,i,iter in self.coroutines:
            if i in read:
                x = i.read()
                if x == "": # eof
                    iter.finish()
                    readable.remove(i)
                else:
                    iter.add(x)
            if o is None or o in write:
                x = None
                try:
                    while x is None and not iter.waiting():
                        x = g.next()
                    if x is not None:
                        o.write(x)
                except StopIteration:
                    if o is not None:
                        writable.remove(o)
    return
You can break it by: (a) yielding more than you can write without blocking (it’ll block rather than buffer, and you might get a deadlock), (b) yielding a value from a generator that doesn’t have a file associated with it (None.write(x) won’t work), (c) having generators that don’t actually yield, and (d) probably some other ways. And it would’ve been nice if I could have somehow moved the “yield None” into the iterator so that it was implicit in the “for line in f”, rather than explicit. But even so, I quite like it.

7 April 2008

Russell Coker: Links April 2008

  • Interesting Rolling Stone article about the US government encouraging idiot “terrorists” [2].
  • Cory Doctorow predicts a poor future for hardware e-book readers [3]. For my personal use a laptop is better for reading. In most cases when I’m going to do some reading I’m likely to want to write notes or be in a situation where I need my laptop for other purposes. So a laptop plus an e-book reader would be more weight and more battery problems than having just a laptop.
  • On page 2 of this article about what might happen if the source code to Windows was released freely [4] I am quoted. One thing I should note is that I have nothing against OpenSolaris, it’s merely one large project for which I could inspect the source if I didn’t have legal advice to the contrary. The situation of OpenSolaris may have changed in recent times, but I have not felt the need to seek further legal advice as there seems no real benefit in viewing the source. There is no shortage of GPL source that I would like to read if I had the time…
  • Location Independent - a blog about working from no fixed address and how to live on the move [5]. Should be of interest to all the people who seem fascinated by my living in hotels for ~18 months.
  • Martin Luther King Jr’s letter from a Birmingham jail [6]. Inspirational and it is also relevant when considering the positions that churches take today on moral issues. I found the link from The Reid Report blog [7] which is an interesting analysis of US politics.
  • Scientific American has an article about high altitude destroying brain cells [8], apparently this can happen even when there is no noticable injury and it is permanent. It seems that it would be a good idea to try and locate conferences to minimise air travel by delegates and speakers…

  • 6 April 2008

    Mike Hommey: WebKit on the rocks

    I’m preparing a new upload for WebKit, which will be targetted at unstable. It is much easier to deal with than Gecko, fortunately, so it won’t take several months to get something in shape. The main “difficulties” here is that I’m dropping the Qt WebKit package, since this will be provided along Qt, and the upstream build system for the Gtk port switched from qmake to autotools, which is not a really bad thing ; so, nothing impossible. Note that switching to autotools also means using libtool, which means no way to use -Wl,–as-needed anymore :-/. Yes, libtool, by trying to be smart, puts it almost at the last position in the arguments list, making it useless. ACID3 in new GtkLauncher

    4 April 2008

    William Pitcock: Litigation vs. Innovation - further reflection on the state of SCO UnixWare, and what it could have been

    In my previous satire about SCO UnixWare, some SCO people of course didn’t think it was very nice. So, I guess I need to explain more about why I wrote the “review” the way I did. But, first the comment: SCO comments back! Obviously any human being can recognize satire. There is obvious motivation on behalf of SCO’s PR department (correct me if I am wrong on where this comment originated; I did just some basic Google lookups, and also, this is a PR tactic known as “dead agenting”) to ignore the fact that this was clearly a satirical review. I would say, “perhaps SCO doesn’t understand why it is criticized,” but I believe it is obvious that they know why people are being critical and satirical of their company and their efforts. I would like for everyone to think, for a moment, about how things could be if SCO didn’t take the litigious strategy that they have taken over the past 6 years. SCO UnixWare could have remained a successful product, and could have in reality become a major asset to the open source world. SCO could have been the good guys here, but instead they chose a path of litigation instead of innovation. In the Open Source and Free Software world, innovation is what is seen as important. Companies may be in some sense rival to each other, but when it comes down to it, everyone appreciates and respects the work that everyone else contributes to the ecosystem. When people do not contribute in a positive way, or worse, betray their peers like SCO has done, it opens them up for criticism. As I see the situation, I think that SCO’s current tactics as a company represent those of someone who is paranoid. People who are paranoid attack first, instead of defend their position. So, while I am sure this is a pointless question, I believe it must be asked anyway: “What would SCO UnixWare have been like if they did not take a litigious strategy against Linux users?” If you look at it like this, it doesn’t really matter if we’re right, or SCO is right on who has the basic cases (well, it does, but we all know how that’s going to come out anyway). Why does SCO keep pursuing a strategy of litigation when the feasibility of this strategy is at best, unknown? To some extent, I think it is now a matter of morale. After all, it’s bad if you have to admit that the strategy you have taken for the last six years, was wrong. In some ways, you could say that SCO’s current strategy is cult-like. Furthermore, if any SCO people are interested in doing an interview about this whole matter, I encourage you to comment back, and I’ll be happy to publicize SCO’s viewpoint of this. It’s only fair.

    3 April 2008

    Stefano Zacchiroli: moving well moved

    /me has moved to Paris Well, this is not really an "I'm moving" post, but rather a "I've moved" post: starting from past Tuesday I'm now living in Paris. I will be working as a post-doc in the mancoosi project, which is a wonderful occasion to merge my research work with my free software enthusiasm. I've also submitted a talk proposal about mancoosi for DebConf8, ... it will be a good occasion to chat about it if you are interested. My office is in the PPS lab, which was already quite packed of Debianers, /me is just one more, happy to join the crowd! The first day of shopping in Paris forces me to post a picture on the very same lines of Enrico's "how to freak out a French person". Mine below can be titled how to freak out an inhabitant of Modena: fake balsamic vinegar Here you are: balsamic vinegar flavoured with figs or honey ..., tasty eh? (dedicated to gareuselesinge) PS unfortunately at home I'm still without network connectivity (unless you count poorly working, up 1 random hour per day, stolen wi-fi as connectivity), so I won't be able to work on Debian et al. a lot from home in the next few weeks.

    Thijs Kinkhorst: Evaluating Fibre to the Home

    Since about half a year now we have a fibre to the home connection. This means that two fiber lines terminate at a box in our living room. It is a blown fibre which means that a tube is buried to your house, after which they use air pressure to put the actual fibre from the house to the POP. There are two fibers: one for bidirectional data (IP), and one that does nothing more than carry the analog cable TV signal. We started out with only the internet facility but now have so-called triple play: phone, analog tv and internet connectivity. The results are in: I find it to be just as good or better than the previous offerings: phone from KPN, tv from Casema or internet from Surfnet. But there's nothing revolutionary. Phone and tv just provide the same service over a different medium. The internet connection is with the standard of 24 Mb/s more than fast enough for any day to day use and an upgrade to 50 Mb/s is pending. A real improvement is that the upstream speed is just as high, very useful when uploading photos, packages or the text of this blog post. One drawback is that they only provide one IP address instead of 32. Also, the service provider (XMSnet) does seem to be a bit stuck in the late nineties with an unfriendly help desk telling you that your situation is impossible , and bad billing, There are plans however to open up the line to other providers in the future. So for now it's just a convenience bundling of services, but nothing really ground breaking. Let's see what the future brings.

    2 April 2008

    Francois Marier: Handling multiple identities/accounts in mutt

    Since mutt seems to be all the rage these days at work, I might as well document here a few things about my .muttrc that might be useful to others.

    (I recommend that you start off with the Debian or Ubuntu package for mutt since a large chunk of necessary customization work has already been done by the Debian maintainers.)

    Here is how I handle two user accounts. Let's start off by listing both of these addresses so that mutt can recognize emails using these as being sent by me:
    alternates "(fmarier@gmail\.com) (francois@debian\.org)"
    Now this is to allow me to change the From address within the editor, in case I forgot to set the right one before pressing 'm':
    set use_from
    Here are the two settings that I'm going to change when switching to a different identity (from address and status bar display).
    # default profile
    set from="fmarier@gmail.com"
    set status_format="-%r-fmarier@gmail.com: %f [Msgs:%?M?%M/?%m%?n? New:%n?%?o? Old:%o?%?d? Del:%d?%?F? Flag:%F?%?t? Tag:%t?%?p? Post:%p?%?b? Inc:%b?%?l? %l?]---(%s/%S)-%>-(%P)---"
    Here are the macros I use to switch from one account to the next (bound to ESC-1 and ESC-2):
    macro index \e1 ":set from=fmarier@gmail.com\n:set status_format=\"-%r-fmarier@gmail.com: %f [Msgs:%?M?%M/?%m%?n? New:%n?%?o? Old:%o?%?d? Del:%d?%?F? Flag:%F?%?t? Tag:%t?%?p? Post:%p?%?b? Inc:%b?%?l? %l?]---(%s/%S)-%>-(%P)---\"\n" "Switch to fmarier@gmail.com"
    macro index \e2 ":set from=francois@debian.org\n:set status_format=\"-%r-francois@debian.org: %f [Msgs:%?M?%M/?%m%?n? New:%n?%?o? Old:%o?%?d? Del:%d?%?F? Flag:%F?%?t? Tag:%t?%?p? Post:%p?%?b? Inc:%b?%?l? %l?]---(%s/%S)-%>-(%P)---\"\n" "Switch to francois@debian.org"
    And this is the code that uses these macros to switch to the right identity automatically:
    folder-hook =inbox 'push \e1oi'
    folder-hook =debian-inbox 'push \e2oi'
    (The 'oi' part at the end is there to restore the default sort order.)

    Finally, I've got this convenient shortcut which allows me to switch to my inbox quickly and to go from one inbox to the next:
    macro index I "c=inbox\n" "Switch to inbox"
    folder-hook =inbox 'macro index I "c=debian-inbox\n" "Switch to debian-inbox"'
    folder-hook =debian-inbox 'macro index I "c=inbox\n" "Switch to inbox"'
    Next up: indexing your emails using mairix.

    Martin F. Krafft: Adding proper IPv6 to my home network

    Dear lazyweb: I claim to know quite a bit about the IPv6 theory, but I lack experience. I have a couple of hosts out there which are already properly IPv6-addressable and work, but I don t have a network scenario. Unfortunately, I also don t have a lot of time available for this right now. I was thus wondering if anyone of you knew of a document that explained the Debian way of I know of documents like Juliusz Getting IPv6 connectivity under Linux (linked from the Debian IPv6 project page, and of course the work by Peter Bieringer (with whom I ve worked previously), but I have not found a concise explanation of how to set it all up with minimal hacks on a Debian system. If noone has such a document, I might have to bite the bullet. Ping me if you want to cooperate. Let me know! NP: The Phoenix Foundation: Pegasus Update: From Waikato, Matt Brown sent this howto on 6to4. I sent back a small number of corrections and hope he ll incorporate them soon. On a related note, I am making good progress getting my Debian systems linked up to the future. I used the excellent SixXS tunnel broker to route 2^80 addresses to my home router and set up another tunnel to one of my native IPv6 hosts in the net. I also added 6to4 to two of my servers. This should give me enough for further experimentation, and eventually for netconf testing. I ve been keeping notes and you can expect a document with simple explanations for everything that I did. But before that, I want to get behind some kernel bugs related to netfilter, such as state INVALID matching valid packets in kernel 2.6.24 and before and conntrack failing to treat ICMP replies as RELATED with kernels 2.6.18 and 2.6.22. The latter seems fixed in 2.6.24, which isn t backported yet, but which we can expect to be in Etch-And-A-Half and Debian lenny. Stay tuned

    1 April 2008

    Manoj Srivastava: Manoj: Migrating to Git

    I have been using Arch to package my Debian packages since 2003; which means that Arch has had a good long run as my SCM of choice. I have been using CVS for a few years before I moved to arch, and the migration took me about six months, since it involved a while new philosophy of packaging; I am hoping that migrating to git would not involve such a major paradigm shift, and thus be less disruptive and time consuming. What follows is a narrative of my efforts to get educated about Git. This article is meant to be an annotated, selective, organized set of links to information about Git. How does it differ from the myriad of other link collections about Git proliferating on the web? Well, the value add is in the annotations and the organization: while not quite a narrative of my exploration, this is an idealized version of what I think my discovery process should have been, to be most effective. Staging the information is important; google finds one lots of information that is incomprehensible to someone just coming to Git. This selection of links is actually selective; I have included only pointers to resources that fed me information at the level that I could handle at that stage, and I have eliminated links to information that was not new at that point. I have tried to select the best (in terms of information and clarity) of breed for each kind of information source I have come across so far. There is a caveat: while still a beginner, though I am able to better judge now what is confusing to a beginner than I shall be when I have become more familiar with the system, I am still enough of a novice not to trust my judgement on what really is best practice. I can fix the latter as I gain experience, but then I ll need to be careful not to overload on complexity too early in the learning curve. On the down side, this selection is subjective, and probably shall be even in the long term: I include what appealed to me, and will probably miss loads of pointers to information that I have not yet come across. However, I hope this will make it easier for other people to reach the same goal: use git for their version control needs. Have fun.

    31 March 2008

    Benjamin Mako Hill: Proven Wrong!

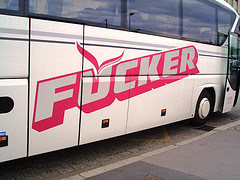
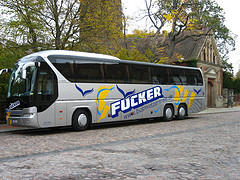
    Yesterday I speculated that Lamers Bus Lines was the most disproportionately photographed, unintentionally insulting, bus line name on the Internet. Apparently not. Several readers pointed out that, while a Flickr search for lamers bus returns 81 photographs, a search for f cker bus and fucker bus return a combined 84 photos not unlike these. With Lamers, PUTA, F cker, SCAT, and the SLUT, I'm beginning to wonder if something very fundamentally wrong with the way human society is choosing the names for its mass transit systems.

    Cyril Brulebois: Lufthansa machines landed!

    As outlined some days ago, patience is a requirement. That said, I'm glad that all things come to (s)he who waits, Lufthansa hardware finally landed! Ganneff, already very busy with his well-known DAM and ftpmaster hats, managed to also handle shipping some hardware donated by the Lufthansa some months ago. pkg-games was promised a powerful box, look: Pentium 4 (2400 MHz, 1024 MB); we will finally be able to try and provide backports in a semi-automated fashion, so as to ease stable users' life, when it comes to installing bleeding-edge versions of their favourite games! Thank you for making this possible and keeping everyone posted about the status of that hardware donation. Hopefully, it'll be possible to also communicate through bits of the DAMs , as suggested some weeks ago on debian-newmaint@. Yay for communication! \o/

    Lars Wirzenius: Progress bars everywhere!

    As I get older, and more impatient, I find myself wanting every program to give more or less accurate estimates of the remaining time until it has completed whatever it is doing. This applies to command line utilities as well. In fact, since most of my time is spent on the command line, it applies particularly to command line utilities. The thing I, as a user, want to know is how long I will still have to wait. I don't particularly care whether the program has completed 97.12765% of its job, I want to know whether it will still take seconds, minutes, hours, or longer to complete. Not remaining file counts. Not remaining byte counts. Time. I'm interested in the entire task. If each file takes 0.1 seconds to process, that's fine, but I don't want to estimate myself that with fourteen thousand remaining files it's going to to take around 25 minutes more. It doesn't have to be completely accurate; a reasonably good estimate is fine. It can fluctuate: when downloading over the Internet, transfer speeds sometimes vary. That's fine. Just give me the current estimate using the average recent speed. For various reasons, I often deal with large files, in the multi-gigabyte range. Copying them with cp seems to be pretty effective, but it's annoying to have to set up something like "watch du -sh source.file target.file" to be able to track progress. I could use "rsync --progress", but that only works well for a single file. Otherwise it reports remaining time for each file separately. I realize that rsync has a particularly difficult job for estimating the remaining time, since it is dependent on the contents of the files at either end. But it could try. Because of these, I tend to like Nautilus for copying files. It has a pretty good indicator for remaining time. Unfortunately, that isn't always practical to use, either, since I don't always copy file so that the local host is at least one end of the transfer, and I often really want rsync. One of the nice lesser-known utilities is pv (in Debian and Ubuntu in the package of the same name). It allows one to construct pipelines that estimate current remaining time. For example, I use this to fill a filesystem's empty space with zeroes:
    pv -petrb -s "$ guess k" /dev/zero > temp
    
    (where guess is the free space in kilobytes). Sometimes the pipelines need to be somewhat contrived to fit pv in. This can also make them slower than straightforward ones would be. But it's often nicer to get some progress reporting than to optimize for speed, at least for stuff that you have to actually wait for in real time.

    Marc 'Zugschlus' Haber: Does Debian need the local host name in /etc/hosts for IPv6?

    Exim has the habit of trying to find out about its host names and IP addresses when it starts up. This has, in the past, been an issue for the Debian packages, since a Debian system might be on a dial-on-demand modem line with expensive costs and thus should not do unnecessary DNS lookup when the MTA is started. This article tries to describe the issue and which countermeasures debian took, and asks for tips how to solve this in the case of IPv6, where our past measures unfortunately do not directly apply. I’d like to solicit opinions from people who are more experienced than me with Unix, the local resolver library including /etc/hosts and /etc/nsswitch.conf, DNS, and - especially - the customs that apply on a system running IPv6. To avoid the extra DNS lookups, the Exim packages have a Debconf option to configure exim for “minimal DNS usage”, which hardcodes the hostname into Exim’s configuration at package configuration time. This was necessary since - without this option - exim looks up its own host name in the DNS even when a completely local operation is invoked. In some cases, exim still looks up its IP address when a listening daemon starts up. This is why the Debian installer configures 127.0.1.1 (not 127.0.0.1) for the local hostname on installation, yielding /etc/hosts files like
    127.0.0.1       localhost
    127.0.1.1       myfoo.localdomain   myfoo
    # The following lines are desirable for IPv6 capable hosts
    ::1     ip6-localhost ip6-loopback
    fe00::0 ip6-localnet
    ff00::0 ip6-mcastprefix
    ff02::1 ip6-allnodes
    ff02::2 ip6-allrouters
    ff02::3 ip6-allhosts
    
    However, in the last few weeks I have heard a few cases where exim does IPv6 AAAA lookups when a listening daemon starts up. An strace shows a gethostbyname2 call for AF_INET6, and if we want to continue the line we went in the past, we’d need an IPv6 address for myfoo.localdomain in /etc/hosts as well. I am now wondering how this could be implemented. In IPv4, we have 127.0.0.0/8 available for the local host and could arbitrarily choose 127.0.1.1 to configure the local host name on. In IPv6, there is only ::1, which is a single address. Would it be possible to choose an arbitrary “link local” address on lo, the loopback interface? Or is there any better way? This being said, I consider the entire 127.0.1.1 business a horrible hack which is one of the most ugly things I have ever seen. Do we have a chance to implement this in a more cleaner way, or is it still the way to go for the distribution, where we don’t know zilch about the environment where an installed system is going to be used? This issue leads to people adding their local host name to ::1 in /etc/hosts, which might re-introduce other issues that we experienced in a phase when we did the same for 127.0.0.1, eventually ending up with 127.0.1.1, or to disabling IPv6 altogether, which is a bad thing in a time where IPv6 should be enabled, not disabled. So I’d like to find a clean solution which could then be implemented in whatever part of Debian might be responsible. I tried asking this question in other places, including Usenet, before pestering my Blog to ask the Lazyweb, but obviously the people I asked before do not care for the special environment that a Linux distribution has to take care of. The only answers I got were like “that would be the local administrator’s task to fix” and “this should be taken care of in the local DNS server/setup (maybe even on the local box being installed)”. A quite frustrating experience.

    David Pashley: Daylight Saving under Debian

    Unfortunately I live in the UK, where 6 months of the year, the time is GMT. Now is the time of year when I discover which of my servers don't have the right timezone configuration and show the wrong time during daylight saving. For future reference, here's how to set the timezone to Europe/London rather than UTC.
    root@cms01:/tmp/openssl-0.9.8g# date
    Mon Mar 31 08:23:35 GMT 2008
    root@cms01:/tmp/openssl-0.9.8g# tzconfig
    Your current time zone is set to GMT
    Do you want to change that? [n]: y
    Please enter the number of the geographic area in which you live:
       1) Africa         7) Australia
       2) America        8) Europe
       3) US time zones     9) Indian Ocean
       4) Canada time zones    10) Pacific Ocean
       5) Asia           11) Use System V style time zones
       6) Atlantic Ocean    12) None of the above
    Then you will be shown a list of cities which represent the time zone
    in which they are located. You should choose a city in your time zone.
    Number: 8
    Amsterdam Andorra Athens Belfast Belgrade Berlin Bratislava Brussels
    Bucharest Budapest Chisinau Copenhagen Dublin Gibraltar Guernsey Helsinki
    Isle_of_Man Istanbul Jersey Kaliningrad Kiev Lisbon Ljubljana London
    Luxembourg Madrid Malta Mariehamn Minsk Monaco Moscow Nicosia Oslo Paris
    Podgorica Prague Riga Rome Samara San_Marino Sarajevo Simferopol Skopje
    Sofia Stockholm Tallinn Tirane Tiraspol Uzhgorod Vaduz Vatican Vienna
    Vilnius Volgograd Warsaw Zagreb Zaporozhye Zurich
    Please enter the name of one of these cities or zones
    You just need to type enough letters to resolve ambiguities
    Press Enter to view all of them again
    Name: [] London
    Your default time zone is set to 'Europe/London'.
    Local time is now:      Mon Mar 31 09:23:48 BST 2008.
    Universal Time is now:  Mon Mar 31 08:23:48 UTC 2008.
    More information is available in the Debian System Administrator Manual.
    Read Comments (1)

    Next.

    Previous.