Search Results: "cas"

6 July 2011

John Goerzen: Geeks, Hobbies, and Free/Open Source: Feedback Wanted

I ve been thinking lately about ways to improve ways in which I interact with Free Software projects, and ways in which they interact with me. Before I proceed to take steps or make suggestions, I d like to see if others share my traits and observations. Here are some questions I have been thinking of. If you d like to help give me anecdotal evidence, please post a comment below this post. Identify the question numbers you are answering. It helps me if you can give specific examples, but if you don t have the time or memory for that, no problem. I will post my own answers in a day or two, but the point of this post is listening, not talking, so I ll not post them immediately. Hobbies (General any geeks) Examples: video games might be a challenging hobby (depending on the person) but in most cases aren t educational. A hobby might be video game playing or being a Debian developer. A sub-hobby might be playing GTA IV , playing RPGs , or maintaining mutt . Free/Open Source Hobbies Examples on F9: If, say, you are a long-time Perl user and have gone to Perl conferences, but now you are interested in Ruby, would your involvement with the Perl community cause you to avoid taking up the Ruby programming hobby? Or would it cause you to cut your ties with Perl less quickly than your changing interest might dictate? (This is a completely arbitrary example and isn t meant to start a $LANGUAGE thread.) Changes over time

Dirk Eddelbuettel: Even faster linear model fits with R using RcppEigen

Linear regression models are a major component of every applied researcher's toolbox. Obtaining results more quickly is therefore of central importance, particularly when many such models have to be fit. Common examples in this context are Monte Carlo simulation or bootstrapping. My talks introducing High Performance Computing with R (see e.g. these slides from a five-hour workshop at the ISM in Tokyo) frequently feature an example of how to extend R with dedicated compiled code for linear regressions. Romain and I also frequently use this a motivating examples with our Rcpp package for seamless R and C++ integration. In fact, the examples directory for Rcpp still contains an earlier version of a benchmark for fastLm(), a faster alternative for R's lm() and lm.fit() functions. We have also extended this with the RcppArmadillo package which brings Conrad Sanderson's excellent Armadillo library with templated C++ code for linear algebra to R, as well as a simple integration to the GNU GSL via our RcppGSL package. The Rcpp section on my blog contains several posts about fastLm benchmarks. Doug Bates has been a key Rcpp contributor, helping particularly with the initial Armadillo integration. His research, however, also requires highly performing sparse matrix operations which Armadillo does not yet offer. So Doug has started to explore the Eigen project---a free C++ template math library mainly focused on vectors, matrices, and linear algebra (note that we will refer to the Eigen, Eigen2 and Eigen3 APIs as just 'Eigen' here, focusing on the latest version, Eigen3). Better still, Doug went to work and pretty much single-handedly wrote a new package RcppEigen which integrates the templated C++ library Eigen with R using Rcpp. RcppEigen also provides a fastLm implementation and benchmark script. In fact, it contains a full six different implementations as Doug is keenly interested in rank-revealing decompositions which can guard against ill-conditioned model matrices. Some more background information on this is also available in Doug's article on Least Squares Calculations in R in R News 4(1). Doug's implementation also uses an elegant design. It comprises a base class with common functionality, and six subclasses which specialize accordingly for these six different decompositions approaches: On my server, the result of running the included benchmark script lmBenchmark is as follows:
lm benchmark for n = 100000 and p = 40: nrep = 20
     test   relative elapsed user.self sys.self
7     LLt   1.000000   0.918      0.91     0.00
3    LDLt   1.002179   0.920      0.92     0.00
5 SymmEig   3.021786   2.774      2.19     0.57
6      QR   5.136166   4.715      4.24     0.48
2   PivQR   5.303922   4.869      4.27     0.58
8    arma   6.592593   6.052      6.03     0.02
1  lm.fit   9.386710   8.617      7.14     1.45
4     SVD  33.858388  31.082     30.19     0.84
9     GSL 114.972767 105.545    104.79     0.63
From this first set of results, the preferred method may be 'PivQR', the pivoted QR. Strictly-speaking, it is the only one we can compare to lm.fit() which also uses a pivoting scheme. In the case of a degenerated model matrix, all the other methods, including the four fastest approaches, are susceptible to producing incorrect estimates. Doug plans to make SVD and SymmEig rank-revealing too. As for pure speed, the LL and LDL decomposition have almost identical performance, and are clearly faster than the other approaches. Compared to lm.fit(), which is the best one could do with just R, we see an improvement by a factor of eight which is quite impressive (albeit not robust to rank-deficient model matrices). Apart from the SVD, all approaches using Eigen are faster than the one using Armadillo, which itself is still faster than R's lm.fit(). Doug and I were very surprised by the poor performance of the GNU GSL (which also uses SVD) via RcppGSL. Now, Eigen uses its own code for all linear algebra operations, bypassing BLAS and LAPACK libraries. The results above were achieved with the current Atlas package in Ubuntu. If we take advantage of the BLAS / LAPACK plug-in architecture offered on Debian / Ubuntu systems (see the vignette in my gcbd package for more) and use Goto BLAS which provide tuning as well as parallelism on multi-core machines, the results are as follow:
lm benchmark for n = 100000 and p = 40: nrep = 20
     test   relative elapsed user.self sys.self
3    LDLt   1.000000   0.907      0.90     0.00
7     LLt   1.000000   0.907      0.91     0.00
5 SymmEig   2.981257   2.704      2.14     0.56
6      QR   5.004410   4.539      4.03     0.50
8    arma   5.072767   4.601     15.30     3.05
2   PivQR   5.307607   4.814      4.27     0.55
1  lm.fit   8.302095   7.530      9.55    12.25
4     SVD  33.015436  29.945     29.06     0.85
9     GSL 195.413451 177.240    244.64   319.89
We see that the BLAS-using Armadillo approach improves a little and moves just slightly ahead of the pivoted QR. On the other hand, lm.fit(), which also uses a pivoting scheme and hence only level 1 BLAS operations, changes less. GSL performs even worse (and it is unclear why). Doug's post announcing RcppEigen on the Eigen list has a few more sets of results. This post has illustrated some of the performance gains that can be obtained from using Eigen via RcppEigen. When not using rank-revealing methods, computing time can be reduced by up to eight times relative to lm.fit(). Rank-revealing method can still improve by almost a factor of two. The main disadvantage of Eigen may be one of the reasons behind its impressive performance: its heavily templated code does not use BLAS, and the resulting object code (as e.g. in RcppEigen) becomes enormous (when compiling with debugging symbols). As one illustration, the shared library for RcppEigen on my Ubuntu 64-bit system has a size of 24.6 mb whereas RcppArmadillo comes in at a mere 0.78 mb; without debugging symbols it is a more reasonable 0.52 mb. The performance of Eigen is certainly intriguiging, and its API is rather complete. It seems safe to say that we may see more R projects going to make use of Eigen thanks to the RcppEigen wrapper.

Update: Clarified statement about large object size which was entirely due to building with debugging support.

5 July 2011

MJ Ray: #coops14 continues: Guardian, Facebook, Cyberunions and Breakfast

Thanks to the Guardian for publishing Why co-operatives matter written by two members of our co-op. Co-operative Congress 2011Also today, I m pictured being given a share by Giles Simon of our national co-ordinating co-op on the Co-operatives Fortnight Facebook page. I m not a big fan of facebook and I still want to try the more sharing alternatives that cyberunions reviewed. Speaking of cyberunions, apparently they answer the criticisms from my review in episode six which I still haven t found time to listen to yet and there s an episode seven out already. Maybe I ll start to catch up later today (Tuesday), if I don t go to the Bristol Wireless Annual Meeting. Tomorrow is another busy day, hopefully including the Koha Town Hall Meeting. And there s still half a week of Co-operatives Fortnight to go, so we re not done by a long way yet! If you d like to take part, there s a Co-operative Business Breakfast in Weston-super-Mare on Friday morning at 9am please leave me a comment if you d like to come along.

Rudy Godoy: Compute Clusters Integration for Debian Development and Testing Report 3

Hello this is the third report regarding my project. As usual, quick
summary first. From my last report I have progressed much little than I
would like but, as stated previously also, I m finishing semester
and between exams and projects it takes almost all my time. However, I m
free of academic duties next week and I ll double the speed on the project. What was done so far

- Started working on the modifications to the Eucalyptus code, as
expected.
I ve almost complete the code for the Libvirt s XML Domain
definition. I ve abstracted the wrapper in order to support a broader
number of arches. Previously it was tailored for supporting x86/amd64
based machines. The idea is to have a list of supported arches and
generate the XML file according that. For ARM some parameters and
elements are different than for the others. This would allow for
people to support another architectures, given they are well supported
by KVM-Qemu.
Started working on changes to util/data.c to make sure the correct
parameters are being passed to the XML generator and to libvirt kvm
calls.
- Define and start to setup the testing / demo environment. Basically
involves having one machine to run KVM as hypervisor so the Eucalyptus
handler uses it to run ARM kvm-qemu images.
- Over this weekend I ll be publising the code changes on my
website. Steffen suggested to create some docs regarding the progress
too. I ll do that once I feel I m on track again for my current
pending work, that s coding. What I ll be working over the next two weeks

- My primary goal is to catch up on the work pace and finish the neccesary
code for Eucalyptus to support ARM images. This means to finish
modifications to:
node/handlers_kvm.c handling nc creation. Little changes are need
here from what I ve indentified already.
util/data. c,h handling instance creation. This is the part where
most of the work shall be done. I ve started to work here already.
- Test the code I ve complete already and send the patches to the teams
involved. To date I m still working on a local environment, because no
usable patches have been generated already, just little pieces here
and there.
- Since this is a sort of gluing project, that is code here and there
and make it work together. I m in the process of finding a machine to
be able to test parts of it once they are complete. I m still
contacting people to get such machine, in anycase I gues I can manage
to get one myself. I can t use my current machine since it involves
reinstalling and working at the OS level.
- For the project s demo I ll use both machines, one as the front-end
and the kvm one for NCs (nodes). That s the goal. What is required after that

- I d like to release a package that includes my changes, so it can be
installed either from official packages or my own packages, this
involves:
Updating the packaging bits to the pkg-Eucalyptus repo.
Talking to upstream about it.
- Write the reference Steffen suggested. I believe that I can finish the first part in one week, because of the
work I ve done in the past weeks to understand the Eucalyptus code. I m
also will be talking more to the Eucalyptus team and also to the
maintainers about such changes. I guess that s all for now.

John Goerzen: The Lives of Others

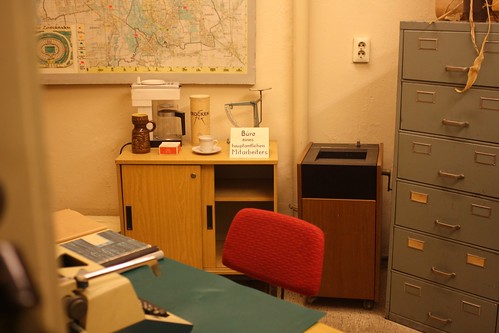
It s not very often that I watch a movie anymore. It s been a few years since I ve actually purchased one (normally I see them from Netflix). But yesterday I saw one that may change that. The Lives of Others is an incredible film set in the former East Germany (GDR/DDR) mostly in 1984. The authenticity of it is incredible and so is the story. It s subtitled, but if you re an American wary of subtitled European films, don t be wary of this one. It is easy to watch and worth every minute. The story revolves around the Stasi, the GDR Ministry for State Security ( secret police ). It is an incredible picture of what living in a police state was like, and how many of the informants were victims of the regime too. My breath caught near the beginning of the film, showing the inside of a Stasi building. A prisoner was being interrogated for helping someone attempt to escape to the west. But the reason my breath caught was this incredible feeling of I was there . Last year, Terah and I were in Leipzig and visited the Stasi museum there, Museum in der Runden Ecke . I always have an incredible sense of history when being in a preserved place, and this building was literally the Stasi headquarters for Leipzig. Much of it was preserved intact, and seeing it in the film brought home even more vividly the terrible things that happened in that building, and others like it, not so very long ago. IMG_2717 We watched the special features on the Blu-Ray disc, and one of them was an interview with director Florian Henckel von Donnersmarck. He described how he spent a lot of time interviewing both victims of the Stasi, as well as ex-Stasi officers. One of the most disturbing things to me was his almost offhand comment that most of the former Stasi officers still had some pride in performing their jobs well. Even now, freed of the state s ideology, they were proud of the work they did which could be put most charitably as ruining people s lives. What leads a person to view life that way? How can we try to make sure it doesn t happen again elsewhere? I am happy to say that most of us have never experienced anything like the Stasi. And yet, small reflections of that mindset can be seen almost everywhere. Societies at wartime or feeling under threat, even Western democracies, can drum up those feelings. In the USA, for instance, the McCarthyism era saw people s careers ruined for alleged anti-state behavior. Contemporary examples include the indefinite detention (I hate that word; shouldn t we say imprisonment ?) of terrorism suspects at Guantanamo Bay, and the terrible treatment of Bradley Manning, who revealed some true but embarrassing things about the US military which really needed to be revealed. Even tobacco farmers and companies are selling a product they know ruins lives, but somehow keep doing it. And there are still members of the public that try to make life difficult for people that don t think like they do. From organizing campaigns of telephone harassment of colleges that don t perform the American national anthem before sporting events, to tossing about the term un-American (a loaded McCarthyist one, which many may not even be aware) at an inflated rate, we are not immune from attempts at forcing conformity or silence in others, and blind loyalty to state. I am never in a particularly celebratory mood on July 4, the biggest day for American boasting, faux patriotism, militarism, and general flag-waving. We do have a lot to be proud of and thankful for, but it seems that we celebrate all the wrong things on July 4, and see it as an occasion to proclaim American exceptionalism rather than as one to see how far we ve come and bolster hope for how far we can, and should, yet go. No, I don t think that the land of the free ought to have operated secret prisons in Europe (nor the Europeans to have been complicit in it), or that the American military was defending our freedom 100% of the time they were deployed, or that it is right for governments to mandate daily recitation of an untrue document (the pledge of allegiance) in schools. And yet, I am mindful that I have a lot to be thankful for stability, lack of much internal violent conflict, etc. And this particular day I am happy that a post like this is not something that gets the attention of some government agency and mostly that I will have a handful of angry emails to delete.

4 July 2011

Lucas Nussbaum: Going to RMLL (LSM) and Debconf!

Next week, I ll head to Strasbourg for Rencontres Mondiales du Logiciel Libre 2011. On monday morning, I ll be giving my Debian Packaging Tutorial for the second time. Let s hope it goes well and I can recruit some future DDs! Then, at the end of July, I ll attend Debconf again. Unfortunately, I won t be able to participate in Debcamp this year, but I look forward to a full week of talks and exciting discussions. There, I ll be chairing two sessions about Ruby in Debian and Quality Assurance.

Lars Wirzenius: strncpy? just say no

This is a rant. I've made it in various forms in various places over the years, and I think it's time to put it somewhere so I can point people at it, and stop repeating myself. Here's the pebble in my shoe: people keep claiming that strncpy is a safer alternative to strcpy. It's not. It's a slower function that is not going to make you significantly safer. The problem with strcpy is that it's somewhat easy to overflow the target array:
char src[] = "hello, world";
char dst[5];
strcpy(dst, src); // Oops.
The suggested alternative with strncpy would be this:
strncpy(dst, src, sizeof(dst));
strncpy gets the size of the destination array as a parameter, and can therefore make sure the string will fit there. Problem solved? Not so much. Every time you do any string handling with C's native string types and functions, you need to make sure you have allocated enough memory for each string, you need to keep track of how much memory you've allocated, and you neet to make sure the zero byte ('NUL', '\0') is put there correctly. This is a lot of details to keep track of, and it's not surprising things sometimes go wrong. If your arrays are allocated statically, which is the simplest, but least useful case, you need to something like this with strcpy:
if (strlen(src) + 1 > sizeof(dst))
    panic(); // or however you want to handle your errors
strcpy(dst, src);
The +1 after strlen is to make room for the zero byte (NUL, '\0') that is used in C to indicate the end of a string. With strncpy, your code is slightly simpler. This is its attraction. Problem is, this only works if dst is an array defined within the scope of the code. If, as is common, you have received dst as an argument to a function, sizeof(dst) is the size of a pointer to an element of the array, not the size of the array. So now you need to track the size explicitly in a second variable:
strncpy(dst, src, dst_size);
Further, strncpy has an unfortunate error handling mode: it merely fills the destination array and stops. It does not indicate failure in any way. It does not terminate the target array with a zero byte. Since all C string processing assume the zero byte is there, as soon as you try to use dst as a string, you're in trouble. But luckily you can check for that before you call strncpy:
if (strlen(src) + 1 > dst_size)
    panic(); // or whatever
strncpy(dst, src, dst_size);
By this time, the code is equally hard whether you use strcpy or strncpy. With strncpy you often waste some extra time, though, filling the unused parts of the target array with zero bytes: they're almost never necessary. Alternatively, you can force the zero byte there yourself, silently truncating a string.
strncpy(dst, src, dst_size);
dst[dst_size - 1] = '\0'; // let's hope dst_size > 0
If your string handling is OK with strings being randomly shorter than they should be, possibly you could replace all of them with empty strings, and save yourself a world of pain. Instead of strncpy, use snprintf. It has sensible error behavior, and is much more versatile:
n = snprintf(dst, dst_size, "%s", src);
if (n >= dst_size)
    panic();
snprintf still isn't very nice to use. It still requires you to allocate memory yourself, and keep track of the size of each array manually. It's also slower for small destination buffers (but faster for large ones). The real solution is to abandon C's antiquated string handling, and use a more sensible helper library instead. There's a bunch of them around, though none have gained much popularity. I'm not going to name any of them, but just imagine how much nicer it would be to write code like this instead:
Dynstr *src = dynstr_new_from_cstring("hello, world\n");
Dynstr *cat = dynstr_cat_many(src, src, src, src, src, NULL);
Dynstr *dog = dynstr_substr(cat, 15, 5);
Let the library take care of memory allocations and related tracking, and concentrate on real problem solving instead. We did this in Kannel, back in 1999, and it wiped out all the buffer overflow problems (until a co-worker decided it was "more efficient" to use native C strings instead, promptly introducing a buffer overflow). All of this string handling is, of course, way nicer in higher level languages. In fact, whenever you need to deal with string handling in C, it is probably a sign that you should consider switching to a higher level language instead. But whatever you do, stop claiming that strncpy is safe or solves any real problems strcpy has. Update: Fixed "It does terminate" to say "It does not terminate". Thanks to Matthew Garrett for pointing that out. Update2: Fixed example call to snprintf. Update3: Fixed the test for snprintf example. Thanks, Redditor axylone. Also pointed out that snprintf is slower than the rest.

Joachim Breitner: gtk-vector-screenshot works with epiphany

Martin Borgert uses my gtk-vector-screenshot application to take screenshots of a web page opened in the browser, in his case, epiphany. I find this a very good idea and was surprised to hear that it works flawlessly: The rendered web page not only shows up, it even shows up as vector graphic with fully selectable text. It s also neat that a HTML5 video appears. One feature that is hard to replicate with regular screenshots is taking a shot of a window that is larger than the current screen. This PDF file (of which the image on the left is a thumbnail preview) contains a whole web page that would not fit on my screen. To achieve that you need a window manager that allows resizing windows beyond the size of your screen (e.g. xmonad). Then just keep resizing and moving the window until the scroll bar disappears and take the shot. BTW, gtk-vector-screenshot is available in Debian unstable.
Flattr this post

Raphaël Hertzog: How to prepare patches for Debian packages

You want to start contributing to Debian and/or Ubuntu, you decided to help a package maintainer and you re now looking for how to change a source package and how to submit your changes. 1. Retrieve the source package and install build-dependencies The first step is to retrieve the latest version of the source package and to install the required build-dependencies. I already covered how to do this with apt-get in the article explaining how to rebuild a source package. If you prefer, you can use dget (from the devscripts package) to directly grab the source package. You can find the URL of the .dsc files in the Package Tracking System for example. Sometimes apt-get will warn you that the source package is maintained in a VCS repository, like this:
$ apt-get source wordpress
[...]
NOTICE: 'wordpress' packaging is maintained in the 'Git' version control system at:
git://git.debian.org/git/collab-maint/wordpress.git
[...]
In that case, you can use debcheckout to retrieve the VCS repository instead (provided that you have the corresponding VCS installed):
$ debcheckout wordpress
declared git repository at git://git.debian.org/git/collab-maint/wordpress.git
git clone git://git.debian.org/git/collab-maint/wordpress.git wordpress ...
Cloning into wordpress...
Note however that some maintainers use their VCS in a way that s not really compatible with the explanations that I will give below. It s also a good idea to install the package packaging-dev . It s a meta-package depending on the most common tools that are used for Debian packaging work. 2. Do the changes Execute dch --nmu to record the fact that you re working on an update prepared by someone who is not the maintainer (NMU means Non Maintainer Upload). This also ensures that if we build the package, we won t overwrite the original source package that we downloaded, thus making it possible to generate a diff between both versions. 2.1. Modify Debian packaging files Now fire your text editor and do the required changes in the debian sub-directory. You will probably run dch -a multiple times to document each subsequent change. 2.2. Modify upstream files If you have to modify upstream files, the proper way to do it depends on the source package format ( 1.0 vs 3.0 (quilt) vs 3.0 (native) , see the debian/source/format file) and on the presence or not of a patch system (the what-patch can help you identify it). In this explanation, I ll assume that the package is using the recommended format: 3.0 (quilt) . (It also works for 1.0 if quilt is used and if you configured ~/.quiltrc as recommended by /usr/share/doc/quilt/README.source). First you should ensure that all patches have been applied with quilt push -a. If there s no patch yet, you want to create the debian/patches directory (with mkdir debian/patches). 2.2.1. Import a patch If the upstream changes are already in a patch file (say /tmp/patch that you downloaded from the upstream VCS repository) you can import that patch like this:
$ quilt import -P fix-foobar.patch /tmp/patch
Importing patch /tmp/patch (stored as fix-foobar.patch)
$ quilt push
Applying patch fix-foobar.patch
[...]
Now at patch fix-foobar.patch
The -P option allows to select the name of the patch file created in debian/patches/. As you see, the new patch file is recorded in debian/patches/series but not applied by default, we re thus doing it with quilt push. 2.2.1. Create a new patch If the upstream changes that you want to make are not in a patch yet, you should tell quilt that you re going to create one:
$ quilt new fix-foobar.patch
Patch fix-foobar.patch is now on top
Then you must record every file that you re going to modify with a quilt add invocation. quilt then makes a backup of those files so that it can generate the patch later on. If you re going to modify the files with your text editor you can just do quilt edit file-to-modify, it s the same than quilt add file-to-modify followed by sensible-editor file-to-modify.
$ quilt edit foobar.c
File foobar.c added to patch fix-foobar.patch
The last step is tell quilt to generate the patch:
$ quilt refresh
Refreshed patch fix-foobar.patch
3. Test your changes You should build your modified package with debuild -us -uc . You can easily install the resulting package with debi . Verify that everything works as expected. If not, continue your modifications until you re satisfied with the result. 4. Generate a patch and mail it If you followed the instructions, you should have two .dsc files in the parent directory, like this:
$ cd ..
$ ls wordpress_*.dsc
../wordpress_3.0.5+dfsg-1.1.dsc
../wordpress_3.0.5+dfsg-1.dsc
Generating the patch to send to the maintainer is then just a matter of running debdiff:
$ debdiff wordpress_3.0.5+dfsg-1.dsc wordpress_3.0.5+dfsg-1.1.dsc >/tmp/wp-debdiff
You can send the /tmp/wp-debdiff file to the wordpress maintainer. Usually you send it via the bugreport that your update is fixing and you add the patch tag to the report. This can be automated with the nmudiff utility. By default it assumes that you re using mutt but it can also directly feed the resulting mail to sendmail. The default text that nmudiff proposes assumes that you re actually performing an NMU and that the result has been uploaded. If that s not the case, you should edit the text and make it clear that you re just sending a patch. If you have been working in a VCS repository, instead of using debdiff you can simply use the diff feature integrated in your VCS (git diff, svn diff, etc.). But note that with a distributed VCS (like git/bzr/mercurial, unlike svn) you should probably have committed all individual changes in separate changesets. And instead of sending a single patch, you re probably going to send a series of patches (though it might be easier to just upload your branch in a public repository and give the corresponding URL to the maintainer).
Found it useful? Be sure to not miss other packaging tips (or lessons), click here to subscribe to my free newsletter and get new articles by email.

No comment Liked this article? Click here. My blog is Flattr-enabled.

3 July 2011

Iain Lane: Ubuntu upload history now available in UDD

There are two different uses (within Debian/Ubuntu) of the initialism UDD: Ubuntu Distributed Development and the Ultimate Debian Database. This article talks about the latter. At UDS-O in Budapest a few weeks ago we had a session (video) on DEX: an initiative to improve collaboration between Debian and its derivatives. There's an Ubuntu DEX subproject, and this is what the session was about, thinking up ideas. I thought of something that could possibly yield some results --- my action from the session was:

[laney] measure relative uploads between ubuntu and debian and see if anything interesting pops up: TODO
It seems to me that if we could tell which packages were uploaded with the most frequency to Ubuntu with respect to Debian, then we may be able to figure out why this is and if there's any way we can do the work in Debian instead. Clearly for this to happen we are going to need data! And where better to house a load of data than the Ultimate Debian Database itself? So I wrote some scripts to download the Ubuntu changes, handily made available as mbox archives, chop them around a bit and eventually split them out in a format that UDD can understand. Lucas Nussbaum then kindly integrated the output into UDD itself, and the end result is that an as-near-as-possible complete history of Ubuntu uploads is now available for your creative querying. For example, Wednesday sees the most uploads and Sunday the fewest:
udd=> SELECT EXTRACT (DOW FROM date) AS dow, COUNT(EXTRACT (DOW
FROM date)) AS count FROM ubuntu_upload_history GROUP BY dow ORDER
BY count DESC;
 dow   count 
-----+-------
   3   26739
   2   26699
   1   25361
   5   23497
   4   22154
   6    9687
   0    8752
(7 rows)

I'll lovingly craft a script to generate the data we need for the DEX project in the next few days. But I hope that the data proves useful for other things too. The three tables you want to look at (with \d+ at a psql prompt) are ubuntu_upload_history, ubuntu_upload_history_launchpad_closes (LP bugs closed by uploads) and ubuntu_upload_history_closes (Debian bugs closed, probably not so interesting). Information on how to use UDD yourself is on this wiki page.

Clint Adams: A very little bit about how herb works

This information is pieced together from no fewer than five informants. As such it is likely to contain inaccuracies. Every year, through the conference registration system, a fork of an old version of Pentabarf, attendees declare that they need sponsorship. They state their cost of travel as well as how much of this amount they can afford to pay themselves. In addition, there is a text field in which one is to answer what you do for Debian and why you request sponsorship. Next a committee is assembled. The head of the committee hand-picks its members. In 2011, twenty-four people were asked if they would like to participate, thirteen people were named to the committee, and twelve of those ended up voting. This committee is named herb , after Herbert Powell. The members of herb each individually rate the applicants on two factors: contribution to Debian and amount requested. Each factor is rated on a five-point scale (-2 to +2). Raters may leave, at their option, a comment regarding the applicant. The raters are able to see previous ratings and comments. In the interest of avoiding the appearance of conflict of interest, each rater will refrain voluntarily from self-rating. Individual raters use exercise judgment during this process.
Contribution to Debian is very subjective, and some raters will vote either on total travel cost, requested amount, the ratio of the two, or something else. At a certain point in time, a weighted average of all the ratings is used to order all the applicants into a list. At the top will be the people ranked most highly. The herb team will then conduct an IRC meeting in which ranking may be arbitrarily changed and two thresholds will be established. The result of this process is three lists of people: queue A, for people who should definitely get sponsorship; queue B, for people that might get sponsorship if people from queue A cancel or other circumstances arise; and queue C, which is not really a queue, but a rejection pile. In some cases, the structure of these queues are decided before definite budget numbers are known. Applicants are emailed to let them know which queues they are in, and their rankings within those queues.

Dominique Dumont: Generate a configuration editor from a config template file with Perl: lcdproc example

Hello Creating a configuration model for Config::Model can be a boring task: When a configuration system has a lot of parameters, a lot of details need to be specified to have a complete configuration validation tool. So, all tricks are permitted to make this task more bearable. Let s see how this can be applied to lcdproc. This project requires a configuration file that supports more than 40 drivers. Each driver has it own set of parameters for a total of about 250 parameters. That s a lot to specify.. Fortunately, LCDd.conf template file is written in a way which makes it relatively easy to parse and get all required information to build a model. All drivers are listed in this template file, most parameters have default values and legal values are written in comments in a uniform way. Hence this file (and comments) can be parsed to retrieve information required for the model. This blog will describe how this task can be implemented in Perl using Config::Model modules. The code will be slightly trimmed down to keep this blog (relatively) short. All initialisation code and error checks are removed. You can get the whole script on sourceforge. The main steps are:
  1. prepare a parser for LCDd.conf template
  2. parse LCDd.conf template
  3. prepare a LCDd model skeleton
  4. translate LCDd.conf template information in a format suitable to create a model.
  5. Write the resulting LCDd model
First, here s the necessary incantation to start properly a Perl program:
use strict;
use warnings;
Then load all required libraries. Their use will be described later:
use Config::Model;
use Config::Model::Itself 1.225;
use Config::Model::Backend::IniFile;
use 5.10.0;
use IO::File;
use IO::String;
Perform some initialisation to avoid upsetting the logging system:
use Log::Log4perl qw(:easy);
Log::Log4perl->easy_init($WARN);
Let s also initialize a model object that will be very useful later:
my $model = Config::Model->new();
Now we can really start the fun part. Step 1: Create a parser for LCDd.conf (INI file)
Problem: LCDd.conf comments must also be analysed to get more semantic information. The comments must be retrieved and associated with the INI classes and parameters found in this file. Fortunately, Config::Model::Backend::IniFile is able to associate comments with the relevant parameters. But Config::Model::Backend::IniFile must store its values in a configuration tree. So let s create a model suitable for LCDd.conf template that accepts any INI class and any INI parameter Dummy::Class is used to store any parameter found in an INI class. The accept keyword with .* regular expression means that any INI parameter will be accepted in each INI class.
$model->create_config_class(
  name   => 'Dummy::Class',
  accept => [
    '.*' =>  
       type => 'leaf',
       value_type => 'uniline'
        ,
    ],
);
Now the Dummy model must provide a configuration class to hold all INI classes:
$model->create_config_class(
    name   => 'Dummy',
    accept => [
       '.*' =>  
           type => 'node',
           config_class_name => 'Dummy::Class'
        ,
    ],
);
Note that an INI backend could be specified directly here. But, some useful parameters are commented out in LCD.conf. Some some processing is required to be able to create a model with these commented parameters. See below for this processing. Step 2: Parse LCDd.conf Now the dummy configuration class is created. Let s create a configuration tree from this dummy class to store the data from LCDd.conf
my $dummy = $model->instance(
    instance_name   => 'dummy',
    root_class_name => 'Dummy',
)-> config_root;
Now, read LCDd.conf:
my $lcd_file
  = IO::File->new('examples/lcdproc/LCDd.conf');
my @lines    = $lcd_file->getlines;
And perform the pre-processing on LCDd.conf mentioned above. Just un-commenting commented parameters is required:
foreach (@lines)   s/^#(\w+=)/$1/  
Store the pre-processed LCDd.conf in a IO::Handle usable by INI backend
my $ioh = IO::String->new( join( '', @lines ) );
Create an INI backend to read the data from pre-processed LCDd.conf and store it in the configuration tree:
my $ini_backend = Config::Model::Backend::IniFile
  ->new( node => $dummy );
$ini_backend->read( io_handle => $ioh );
Step 3: Prepare LCDd configuration model Your attention please. You may remember that we invoked instance on object to create the dummy configuration tree to hold LCDd.conf data. The instance method used the Dummy configuration class. Now, we must invoke instance again on object. But this time, instance will use Config::Model::Itself. This model is Config::Model s way of eating its own dog food. The configuration tree created there will be able to hold LCDd model. Hence the root of this special configuration tree will be called meta_root to avoid confusion with the other configuration root defined above (for the Dummy model). Still with me? Good, let s create this meta tree that will contain LCDd model:
my $meta_root = $model->instance(
    root_class_name => 'Itself::Model',
    instance_name   => 'meta_model',
) -> config_root;
Create the main LCDd configuration class and store the first comment from LCDd.conf as class description:
my $first_comment = $dummy->annotation ;
$meta_root
  ->grab("class:LCDd class_description")
  ->store( $first_comment );
Append my own text in this description:
my $extra_description =
    "Model information extracted from template /etc/LCDd.conf"
  . "\n\n=head1 BUGS\n\nThis model does not support to load "
  . "several drivers. Loading several drivers is probably a "
  . "marginal case. Please complain to the author if this "
  . "assumption is false";
$meta_root->load(
     qq!class:LCDd
        class_description.="\n\n$extra_description"!
);
Add legal stuff in the model:
$meta_root->load( qq!
  class:LCDd
    copyright:0="2011, Dominique Dumont"
    copyright:1="1999-2011, William Ferrell and others"
    license="GPL-2"
!
);
Add INI backend so configuration object created from LCDd model will be able to read user s INI files:
$meta_root->load( qq!
  class:LCDd
    read_config:0
      backend=ini_file
      config_dir="/etc"
      file="LCDd.conf"
!
);
Note that all the load calls above could be done as one call. They were split for better clarity. Step 4:Extracting LCDd.conf information Now that all information from LCDd.conf template file is stored in $dummy configuration tree, it s time to use this information to enhance the skeleton of LCDd model created above. Let s first find all the INI classes defined in LCDd.conf:
my @ini_classes = $dummy->get_element_name;
Now before actually mining LCDd.conf information, we must prepare several subs to handle them. This is done using a dispatch table:
my %dispatch;
First create the default entry which will be used for most parameters. This subs is passed: the INI class name, the INI parameter name, the comment attached to the parameter, the INI value, and an optional value type. It will return a string describing a model for simple elements. For instance: class:"LCDd::MD8800" element:Device type=leaf value_type=uniline default="/dev/ttyS1" description="device to use [default: /dev/ttyS1]" Here s the subroutine invoked by default. Let s create a an anonymous subroutine and store it in the dispatch table:
$dispatch _default_  = sub  
    my ( $ini_class, $ini_param, $ini_note,
         $ini_v, $value_type ) = @_;
    $value_type  = 'uniline';
Now, prepare a string that will be used later to create the ini_class model. This string uses Config::Model s serialisation format described in Config::Model::Loader:
    my $load = qq!class:"$ini_class"
                  element:$ini_param type=leaf !;
Get semantic information from LCDd.conf template comments (written between square brackets):
    my $info = $ini_note =~ /\[(.*)\]/ ? $1 : '';
    $info =~ s/\s+//g;
Use this semantic information to better specify the parameter:
    $load .=
        $info =~ /legal:(\d+)-(\d+)/
           ? " value_type=integer min=$1 max=$2"
      : $info =~ /legal:([\w\,]+)/
           ? " value_type=enum choice=$1"
      :    " value_type=$value_type";
    if ( $info =~ /default:(\w+)/ )  
        # specify upstream default value
        # if it was found in the comment
        $load .= qq! upstream_default="$1"!
           if length($1);
     
    else  
        # or use the value found in INI
        # file as default
        $ini_v =~ s/^"//g;
        $ini_v =~ s/"$//g;
        $load .= qq! default="$ini_v"!
           if length($ini_v);
     
The model (in serialised format) is ready, let s return it and exit the subroutine:
    return $load;
 ;
Now let s take care of the special cases. This one deals with Driver parameter found in INI [server] class. This sub will create a string for an enum element. The possible values of the enum are extracted from the comment found in the LCDd.conf file:
$dispatch "LCDd::server" Driver  = sub  
    my ( $class, $elt, $info, $ini_v ) = @_;
    my $load = qq!class:"$class"
                    element:$elt
                      type=leaf
                      value_type=enum
    !;
    my @drivers = split /\W+/, $info;
    while ( @drivers
            and ( shift @drivers ) !~ /supported/ )  
      # nothing, the work is done by shift operator
      # in loop test to skip all words in $info until
      # 'The following drivers are supported:'.
      # ok, that's a hack
     
    $load .= 'choice='
          . join( ',', @drivers ) . ' ';
    return $load;
 ;
This sub invokes the default sub and add a small feature to the model to ensure that DriverPath ends with / . This is ensured by the match="/$" snippet:
$dispatch "LCDd::server" DriverPath  = sub  
    my ( $class, $elt, $info, $ini_v ) = @_;
    return   $dispatch _default_ ->(@_)
           . q! match="/$" !;
 ;
Likewise, this sub invokes the default sub with the optional 4th parameter that forces the value_type of the element. In this case, we enforce an integer element:
 $dispatch "LCDd::server" WaitTime 
 = $dispatch "LCDd::server" ReportLevel 
 = $dispatch "LCDd::server" Port 
 = sub  
    my ( $class, $elt, $info, $ini_v ) = @_;
    return $dispatch _default_ ->( @_, 'integer' );
   ;
This sub returns a string for a list element with default values:
  $dispatch "LCDd::server" GoodBye 
= $dispatch "LCDd::server" Hello 
= sub  
    my ( $class, $elt, $info, $ini_v ) = @_;
    my $ret = qq( class:"$class"
                    element:$elt
                      type=list
                ) ;
    $ret .= 'cargo type=leaf
             value_type=uniline - ' ;
    $ret .= 'default_with_init:0="\" '.$elt.'\"" ' ;
    $ret .= 'default_with_init:1="\" LCDproc!\""';
    return $ret ;
 ;
Now that the dispatch table is ready, let s really mine LCDd.conf information. First handle all INI classes in the foreach loop:
foreach my $ini_class (@ini_classes)  
Let s retrieve parameters for this INI class from the LCDd.conf template:
  my $ini_obj = $dummy->grab($ini_class);
This will be the name of the lcdproc driver configuration class (e.g. LCDd::imonlcd):
  my $config_class   = "LCDd::$ini_class";
The configuration class will also be created in a serialised format. Let s create config class in case there s no parameter in INI file:
  $meta_root->load(qq!class:"LCDd::$ini_class"!);
Now, loop over all INI parameters and create LCDd::$ini_class elements:
  my @all_ini_params = $ini_obj->get_element_name ;
  foreach my $ini_param ( @all_ini_params )  
Retrieve the value provided in template LCDd.conf:
    my $ini_v = $ini_obj->grab_value($ini_param);
Retrieve the comment attached to the value provided in template LCDd.conf:
    my $ini_comment
      = $ini_obj->grab($ini_param)->annotation;
    # escape embedded quotes
    $ini_comment =~ s/"/\\"/g;
Retrieve the correct sub from dispatch table:
    my $sub = $dispatch $config_class $ini_param 
              $dispatch _default_ ;
Run the sub to get the model string:
    my $model_spec
      = $sub->( $config_class, $ini_param,
                   $ini_comment, $ini_v );
Attach the comment from LCDd.conf as class description:
    $model_spec .= qq! description="$ini_comment"!
      if length($ini_comment);
Then, last but not least, load class specification in the model, and end the loop aroung INI parameters:
    $meta_root->load($model_spec);
   
Now create a an $ini_class element in LCDd class (to link LCDd class and LCDd::$ini_class):
  my $driver_class_spec = qq!
    class:LCDd
      element:$ini_class
  ! ;
Since server and menu are not drivers, they have a special treatment:
  if (   $ini_class eq 'server'
      or $ini_class eq 'menu' )  
    $driver_class_spec .= qq!
      type=node
      config_class_name="LCDd::$ini_class"
    ! ;
   
Here s the treatment for LCDd drivers. Setup the model with a warped node so that a driver configuration class is shown only if the driver was selected in the [server] class:
  else  
    $driver_class_spec .= qq!
      type=warped_node
      config_class_name="LCDd::$ini_class"
      level=hidden
      follow:selected="- server Driver"
      rules:"\$selected eq '$ini_class'"
        level=normal
    !;
   
Now we can load the LCDd driver model in meta root:
  $meta_root->load($driver_class_spec);
 
Step 5: save LCDd model Still with me ? Good. Here s the last part, now that the model was created in memory, let s save it in files. Config::Model::Itself constructor returns an object to read or write the data:
my $rw_obj = Config::Model::Itself
     ->new( model_object => $meta_root );
say "Writing all models in file (please wait)";
$rw_obj->write_all(
    model_dir => 'lib/Config/Model/models/'
);
That s it. Once this script is run, the directory lib/Config/Model/models/ contains a bunch of files: You can see the resulting editor in my first blog on lcdproc. Conclusion and future steps (with you?) As mentioned at the end of this blog, the result of this model generation process is far from perfect, because the information retrieved from LCDd.conf template are not complete for this task (which is normal since these comments were targeted for users). Now, I d really like to discuss with project developers to improve configuration template to generate better models. For project owner, such an improvement would give them: Please leave a comment on this blog (or send a message to config-model-users at lists.sourceforge.net) if you are interested in configuration tool generation for a project you contribute to. All the best

Raphaël Hertzog: My Debian activities in June 2011

This is my monthly summary of my Debian related activities. If you re among the people who made a donation to support my work (195 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. Dropbox for Debian This is not free software but Dropbox is very popular and they did only provide an Ubuntu package that did not work on Debian. So I created an official package. I have been in touch with Dropbox developers and they have been very helpful. They ll shortly release a signature mechanism (with GPG) so that we can further improve the package by verifying the origin of the downloaded binaries. SAT Britney At the start of the month, I continued my work on the britney reimplementation (the software that creates testing out of unstable) but I quickly stalled it because the release managers asked the feedback of Stefano Zacchiroli and Ralf Treinen (who have extensive knowledge on the topic with their research work on Mancoosi) and I did not want to invest further work in case they would identify a major flow the feedback came only very late this month and while it was somewhat negative, I still think it s worth pursuing the effort for a bit longer. Converted ftplib to multiarch While dpkg still doesn t support multiarch (no news from Guillem and no visible sign of progress :-( ), unstable got all the remaining bits allowing us to convert libraries to multiarch (see the announce). As soon as the required libc6 landed in unstable, I looked into converting the only library package that I maintain. I had no major problem but I still identified 2 issues in Lintian (filed as #630164 and quickly fixed by Niels Thykier). build-arch / build-indep support For the 42th time in the last 10 years, the idea of using build-arch/build-indep targets in the rules file has surfaced again. I had already decided some time ago that I would accept a patch implementing a new field Build-Features to enable dpkg-buildpackage to use those targets and this time Bill Allombert completed such a patch so I merged it. The technical committee also decided that it would take a final decision on this topic (see #629385). Roger Leigh provided useful input by doing an archive-wide rebuild with the various solutions suggested. Given that the majority would like to make the target mandatory at some point in the future, I provided the dpkg patch for my preferred solution. We would use auto-detection as a temporary measure until all packages have been converted to have the targets. The technical committee has not yet taken any decision even though the discussion stalled since the 12th of June. But that s usual with that body. I m sure it will be solved during Debconf. ;-) Misc dpkg work Hamster applet update Hamster-applet is a GNOME application which did not have a 3.0 release, but it had a development release (2.91.x). I checked out whether it was possible to package this version for experimental and have the applet work with the GNOME fallback mode. Apparently not, the code was not yet updated to be compatible with the newer panel. Instead I uploaded the latest stable version (2.32.1) to unstable. It has some nice improvements in the standalone version (and the name of the executable changed). For usage with GNOME 3, I have created a custom shortcut to start it quickly (with gconf-editor set /apps/metacity/global_keybindings/run_command_1 to <Mod4>t and /apps/metacity/keybinding_commands/command_1 to hamster-time-tracker because the GNOME 3 control panel does not seem to work to set custom keybindings currently). Translated my professional website into English While I m grateful for all the people who are supporting my work, I m still far from my goal to have one third of my time funded through donations and sales of products on this blog. So I decided to also bring more visibility to my company and in particular to its Debian-related service offering. It was only available in French up to now so I translated it and expanded it a bit. My support page on this blog now also links to my company s website. If your company needs help to create Debian packages, or needs Debian technical support by email, you just found the right partner. :-) BTW, I have discounted prices for individuals and non-profits who would like to benefit from my help to create Debian packages. The Debian Administrator s Handbook This is the title of the upcoming translation of my book. The project now has a dedicated website: debian-handbook.info. You can subscribe to its RSS feed to keep up with the latest news. The full table of contents is online along with a FAQ. I m actively looking for partners to help me promote the fundraising once it goes live. If you can reach a large set of readers interested by a good Debian book, get in touch with me to join the affiliate program. Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Russell Coker: Can Online Dating make You Depressed?

Anne Rettenberg wrote an article for Psychology Today that is critical of the idea of online dating [1], she cites one example of a man who visited a prostitute due to being depressed at his lack of success in online dating to support her claim. The first big problem with her article is that she doesn t mention the different experiences that male and female customers presumably have on online dating sites. I don t know what it s like for women on the dating sites so I can t comment on that. But I m sure that someone who works as a counselor could provide some useful insight into this matter. Also she didn t even give a mention to the issue of gay/lesbian dating sites. The next issue is that she didn t offer any good advice for who should use online dating sites and what their aims should be. Rejection In dating in real life (IRL) it s expected that the man make the first move, and therefore women end up rejecting lots of guys for various reasons. Anne seems to think that rejection online is somehow worse than rejection IRL, it probably is for some people but that certainly isn t the case for everyone. The way that lots of dating sites seem to work is that women place adverts, men respond to them, and then the women reply to a small subset of the email that they receive. Rejection in this case isn t a matter of telling someone that you aren t interested, but of merely not replying to their mail. From my discussions with a few men who ve used online dating sites the strategy seems to be to send out initial messages to a few dozen women every day and then maybe get a few responses a day. For the messages that get no response you will never know whether the other person found someone else first, wasn t interested in you for some reason, or just didn t bother checking their email. The only comparison to IRL rejection is that which happens after phone numbers have been exchanged, which isn t going to be that common (and has the same issues regardless of how the people met). Guys, relax about the women who don t respond to your first message. They probably get 100+ responses to their advert and don t have time to even read half of them. If you get rejected later in the process then you can look through your email archive at a later date to try and discover what went wrong. The Aim of Online Dating The fact that Anne s client visited a prostitute suggests that maybe he wasn t really after a relationship. In which case using one of the many online services for finding sex partners might have been a better option. Generally it seems that a good strategy is to try and have fun. I don t know any men who have married someone from a dating site, but the general opinion seems to be that they are still worth using. If you meet someone in a bar then you might end up having a drunken conversation that is drowned out by loud music. If you meet someone over the Internet then you can have a quiet conversation over the phone which seems to be a better way to get to know someone (and generally more pleasant for anyone who s not an alcoholic). I think that men who have no immediate aim other than finding someone nice to talk to will do better than those who aim to score quickly. Of the men I know who married women they met over the Internet (but not through online dating sites) I wonder how many of them would have ended up married if they hadn t used the online dating sites first. It seems that men who regularly communicate with women outside formal situations (work etc) will have a better chance of impressing someone that they like than those who lack such experience. Introverts There are a lot of people who really can t function in a bar. With the way our society works it seems that anyone who can t handle the bar scene really should consider online dating. How Counselors can Help It seems to me that someone who is seeing a counselor and who is considering a new way of finding a SO should ask their counselor for advice first. It also seems to me that a good option might be to ask their counselor for advice in online dating. Instead of being unsuccessful and depressed a man who was seeing a female counselor could do well to ask her advice for how to impress women on the Internet. This is probably a business opportunity for female counselors who can advise men on such things, among other things it seems that seeing an online relationship coach would be perceived in a more positive manner than seeing a counselor or psychologist for the more traditional reasons.

Rog rio Brito: Installing Meego on the N900

My last cellphone was a dumb phone. I seem to remember that it was called something like Samsung Voicer. It didn't have those hip things like SIM cards. OK. Fast forward to December of 2010, and after a long hiatus, I decided to get a new phone. It was this shiny Nokia N900. The biggest thing that made me want this one was that some people at DebConf 10 were praising it for having a Debian-like distribution in it, and that it worked very well. I saw that Phil Hands was enthusiastically talking about the bargain of getting one in New York and that it would have cost him many pounds in the UK and, so, he was happy with it. Ot vio Salvador also got one in NY and during one of the nights of that DebConf with him, Tiago Vaz, Daniel Baumann, and Chris Lamb, I asked him to call my parents here in Brazil and he let me use his N900. I had more time with it and played a little bit with the command line, opened the stock media player and played a beautiful trailer of 9 (2009 film), leaving me a very good impression. I bought one, and, indeed, it is a very good machine that can even make phone calls. The ability to run Linux on it (even if it contains some non-free pieces of software) was decisive in me getting it. It runs this distribution called Maemo 5 which is loosely based on Debian. But now, Maemo is not the "cool thing" to run, regarding Linux on these portable devices. Meego is. But with the advent of many Internet forums has brought many people writing some long, convoluted howto documents for things that would be better done as, say, providing a script or, better yet, preparing a package. In the case of getting Meego running on the N900, only three things are required:
  1. Install uboot-pr13 while in Maemo.
  2. Uncompress the MeeGo 1.2 Community Edition for Nokia N900 image to a SD card.
  3. Turn the phone off, plug in the SD card, and PUT THE BACK COVER on the phone.
The last bit of the third step is crucial, as, otherwise, the SD card won't be detected and you will get kernel panics with the device trying to mount the root filesystem from a device that is not there. As an aside, the official documentation tells us one should uncompress the available pre-made images and write them with dd to the device. In my experience, it is completely unnecessary to use it and, in fact, it is so 6 times slower than using a simple shell redirection. That is, instead of:
bzip2 -d < mg-handset-armv7nhl-n900-whateverwhatever-mmcblk0p.raw.bz2   dd bs=4096 of=/dev/mmcblk0
you can get better results with the simpler:
bzip2 -d < mg-handset-armv7nhl-n900-whateverwhatever-mmcblk0p.raw.bz2 > /dev/mmcblk0
I actually used lbzip2 instead of bzip2, but that shouldn't matter. The use of the small block size for the dd command is probably the culprit, but I don't see the need to write the uncompressed data in chunks this small. If there is a problem, I would love to be informed of that. As trying it with uboot and a SD card doesn't mess with your "safe" Maemo installation, this is a good way to play with the successor of Maemo. Perhaps, if we give good feedback to the project, we can influence the direction that it is taking. It will surely be nice to learn about this new "consumer-oriented" distribution.

2 July 2011

Joey Hess: databranches: using git as a database

I've just released git-annex version 3, which stops cluttering the filesystem with .git-annex directories. Instead it stores its data in a git-annex branch, which it manages entirely transparently to the user. It is essentially now using git as a distributed NOSQL database. Let's call it a databranch. This is not an unheard of thing to do with git. The git notes built into recent git does something similar, using a dynamically balanced tree in a hidden branch to store notes. My own pristine-tar injects data into a git branch. (Thanks to Alexander Wirt for showing me how to do that when I was a git newbie.) Some distributed bug trackers store their data in git in various ways. What I think takes git-annex beyond these is that it not only injects data into git, but it does it in a way that's efficient for large quantities of changing data, and it automates merging remote changes into its databranch. This is novel enough to write up how I did it, especially the latter which tends to be a weak spot in things that use git this way. Indeed, it's important to approach your design for using git as a database from the perspective of automated merging. Get the merging right and the rest will follow. I've chosen to use the simplest possible merge, the union merge: When merging parent trees A and B, the result will have all files that are in either A or B, and files present in both will have their lines merged (and possibly reordered or uniqed). The main thing git-annex stores in its databranch is a bunch of presence logs. Each log file corresponds to one item, and has lines with this form:
timestamp [0 1] id
This records whether the item was present at the specified id at a given time. It can be easily union merged, since only the newest timestamp for an id is relevant. Older lines can be compacted away whenever the log is updated. Generalizing this technique for other kinds of data is probably an interesting problem. :) While git can union merge changes into the currently checked out branch, when using git as a database, you want to merge into your internal-use databranch instead, and maintaining a checkout of that branch is inefficient. So git-annex includes a general purpose git-union-merge command that can union merge changes into a git branch, efficiently, without needing the branch to be checked out. Another problem is how to trigger the merge when git pulls changes from remotes. There is no suitible git hook (post-merge won't do because the checked out branch may not change at all). git-annex works around this problem by automatically merging */git-annex into git-annex each time it is run. I hope that git might eventually get such capabilities built into it to better support this type of thing. So that's the data. Now, how to efficiently inject it into your databranch? And how to efficiently retrieve it? The second question is easier to answer, although it took me a while to find the right way ... Which is two orders of magnitude faster than the wrong way, and fairly close in speed to reading data files directly from the filesystem. The right choice is to use git-cat-file --batch; starting it up the first time data is requested, and leaving it running for further queries. This would be straightforward, except git-cat-file --batch is a little difficult when a file is requested that does not exist. To detect that, you'll have to examine its stderr for error messages too. Perhaps git-cat-file --batch could be improved to print something machine parseable to stdout when it cannot find a file. Takes some careful parsing, but straightforward. Efficiently injecting changes into the databranch was another place where my first attempt was an order of magnitude slower than my final code. The key trick is to maintain a separate index file for the branch. (Set GIT_INDEX_FILE to make git use it.) Then changes can be fed into git by using git hash-object, and those hashes recorded into the branch's index file with git update-index --index-info. Finally, just commit the separate index file and update the branch's ref. That works ok, but the sad truth is that git's index files don't scale well as the number of files in the tree grows. Once you have a hundred thousand or so files, updating an index file becomes slow, since for every update, git has to rewrite the entire file. I hope that git will be improved to scale better, perhaps by some git wizard who understands index files (does anyone except Junio and Linus?) arranging for them to be modified in-place. In the meantime, I use a workaround: Each change that will be committed to the databranch is first recorded into a journal file, and when git-annex shuts down, it runs git hash-object just once, passing it all the journal files, and feeds the resulting hashes into a single call to git update-index. Of course, my database code has to make sure to check the journal when retrieving data. And of course, it has to deal with possibly being interrupted in the middle of updating the journal, or before it can commit it, and so forth. If gory details interest you, the complete code for using a git branch as a database, with journaling, is here. After all that, git-annex turned out to be nearly as fast as before when it was simply reading files from the filesystem, and actually faster in some cases. And without the clutter of the .git-annex/ directory, git use is overall faster, commits are uncluttered, and there's no difficulty with branching. Using a git branch as a database is not always the right choice, and git's plumbing could be improved to better support it, but it is an interesting technique.

1 July 2011

Marco Silva: Some C++ stuff

I've been playing with C++ lately, and it's an interesting language. Some random thoughts go here. First, in which situation does "... int x; x = 0 ..." is different from "... int x = 0 ... "? The answer on the end of the post. Second, consider this code:
class A  ;
// void f(const A &a)  
// void f(A a)  
void f(A &a)  
int main()  
  f(A());
  // A a;
  // f(a);
 
It doesn't build under g++ or clang. Some say it builds under MSVC. If the definition of f is swapped by any of the commented ones, it works. If the declaration and call to f on function main is swapped by the commented lines, it also works. Third, dynamic dispatch only works with pointers. Consider this code:
class A  
 public:
  virtual void f()  
    printf("A");
   
 ;
class B : public A  
  void f()  
    printf("B");
   
 ;
int main()  
  A a = B();
  a.f();
  A *p = new B();
  p->f();
  delete p;
  B b;
  A *q = &b
  q->f();
 
It prints ABB. Some things to remember. The answer of the first point is: those codes are different if there is a static before them. This can only happen when they are in the body of a function. In this case, the first would assign x to 0 at each call to the function, and the other only at the first call.

Michael Casadevall: Pandaboard Netboot Images Now Available

As I mentioned in my previous blog post, OMAP4 netboot images were available, but non-functional. I'm pleased to announce that these bugs have now been resolved and it is possible to have a functional install on OMAP4. This also has the added advantage of allowing one special partitioning layouts such as RAID, LVM, or simply having a non-SD based root device. The images are available here: http://ports.ubuntu.com/ubuntu-ports/dists/oneiric/main/installer-armel/current/images/omap4/netboot/

To use, simply dd boot.img-serial or boot.img-fb to an SD card, pop it in, and run, and the installer will pop up.

There is still a known bug that partman will not properly create the necessary boot partition. During the partitioning step, you must select manual partitioning, then create a 72 MiB FAT32 partition, with no mount point, and the Bootable flag must be set to 'on'. This partition must be the first partition on the device. flash-kernel-installer will be able to find the partition on its own.

Ian Wienand: Debugging __thead variables from coredumps

I think the old-fashioned coredump is a little under-appreciated these days. I'm not sure when it changed, but I even had to add myself to /etc/security/limits.conf to raise my ulimit to even create one. Anyway, debugging __thread variables from coredumps is a bit of a pain. For the uninitiated, the __thread identifier specifies a thread-local variable, i.e. every thread gets its own copy of the variable automatically. The implementation of this is highly architecture specific. The reason is that TLS entries need to be accessed via a register kept as part of the thread state, and thus every architecture chooses their own register and builds their own ABI. On x86-32, which is very register-limited, you certainly don't want to dedicate a register to a pointer to TLS variables and take it out of operation. Luckily there is the hang-over from the 70's (60's? 50's?) segmentation. Without going into real detail, segment registers can be used to offset into a region of memory based on a look-up of a region descriptor stored in a table. Simple example of gs and the GDT Above, you see a simplified example of the %gs register loaded with the index value 2, and thus when you access %gs:20 what you are saying is "find entry 2 in the global descriptor table (GDT), follow it and offset 20 into that region. The kernel gives each thread its own GDT (i.e. the GDT register is part of the thread-state). Thus __thread variables are stored based on segment offsets and voila thread-local storage. Now, there's a few tricks here. For various reasons, a process can not setup entries in the GDT; this is a privileged operation that must be done by the kernel. There is actually a special system call for threads to setup their TLS areas in the GDT set_thread_area. When a new thread starts, the thread-library and dynamic linker conspire to allocate and load any static TLS data (i.e. if you have a global __thread variable initialised to some value, then every thread must see that value when it starts) and then calls this to make sure the variables are ready to go. After that, the gs register is filled with the index of that GDT entry, and all TLS access goes via it. That, in a nut-shell, is TLS for x86-32. Now, to the problem. Take, for example, the following short program:
#include <stdio.h>
#include <stdlib.h>
#include <unistd.h>
#include <pthread.h>
int __thread foo;
void* thread(void *in)  
        foo = (int)in;
        printf("foo is %d\n", foo);
        while (1)  
                sleep(10);
         
 
int main(void)  
        pthread_t threads[5];
        int i;
        for (i=0; i<5; i++)  
                pthread_create(&threads[i], NULL,
                               thread, (void*)i);
         
        sleep(5);
        abort();
 
We start a few threads and then abort to make it dump core. But, if you try and examine foo:
$ gdb ./thread core 
GNU gdb (GDB) 7.2-debian
Reading symbols from /home/ianw/tmp/thread/thread...done.
[New Thread 4970]
[New Thread 4975]
[New Thread 4974]
[New Thread 4973]
[New Thread 4972]
[New Thread 4971]
Core was generated by  ./thread'.
Program terminated with signal 6, Aborted.
#0  0xffffe424 in __kernel_vsyscall ()
(gdb) print foo
Cannot find thread-local variables on this target
It seems that gdb doesn't know how to find the value of foo because its not a variable in the usual sense ("this target", in this case, means a coredump). It relies on accessing via the gs register, which relies on the current processes' GDT state, which has since been destroyed. If you care to consult the canonical source of TLS info, you can find out exactly why this is so hard to figure out generically. However, with some work, we can start to figure out the value by hand. A coredump is really a ELF file full of just two things: a bunch of LOAD segments that are just dumps of the process memory regions, and a NOTE section that includes a bunch of notes that the kernel dumps out for us such as the current register state, the process id, the signal that killed us, etc. Here's an example of a core file under readelf
$ readelf --headers ./core 
ELF Header:
  Magic:   7f 45 4c 46 01 01 01 00 00 00 00 00 00 00 00 00 
  Class:                             ELF32
...
  OS/ABI:                            UNIX - System V
...
  Type:                              CORE (Core file)
...
There are no sections in this file.
Program Headers:
  Type           Offset   VirtAddr   PhysAddr   FileSiz MemSiz  Flg Align
  NOTE           0x0003d4 0x00000000 0x00000000 0x006b4 0x00000     0
  LOAD           0x001000 0x08048000 0x00000000 0x00000 0x01000 R E 0x1000
  LOAD           0x001000 0x08049000 0x00000000 0x01000 0x01000 RW  0x1000
  LOAD           0x002000 0x0804a000 0x00000000 0x21000 0x21000 RW  0x1000
  LOAD           0x023000 0x46015000 0x00000000 0x00000 0x1b000 R E 0x1000
  LOAD           0x023000 0x46030000 0x00000000 0x01000 0x01000 R   0x1000
  LOAD           0x024000 0x46031000 0x00000000 0x01000 0x01000 RW  0x1000
...
You can examine the notes; with readelf we see:
$ readelf --notes ./core 
Notes at offset 0x000003d4 with length 0x000006b4:
  Owner                 Data size      Description
  CORE                 0x00000090      NT_PRSTATUS (prstatus structure)
  CORE                 0x0000007c      NT_PRPSINFO (prpsinfo structure)
  CORE                 0x000000a0      NT_AUXV (auxiliary vector)      
  LINUX                0x00000030      Unknown note type: (0x00000200) 
  CORE                 0x00000090      NT_PRSTATUS (prstatus structure)
  LINUX                0x00000030      Unknown note type: (0x00000200) 
  CORE                 0x00000090      NT_PRSTATUS (prstatus structure)
  LINUX                0x00000030      Unknown note type: (0x00000200) 
  CORE                 0x00000090      NT_PRSTATUS (prstatus structure)
  LINUX                0x00000030      Unknown note type: (0x00000200)
  CORE                 0x00000090      NT_PRSTATUS (prstatus structure)
  LINUX                0x00000030      Unknown note type: (0x00000200)
  CORE                 0x00000090      NT_PRSTATUS (prstatus structure)
  LINUX                0x00000030      Unknown note type: (0x00000200)
This shows 5 notes of type NT_PRSTATUS; it should be little surprise that each of these notes describes the process status of one running thread. When gdb pops up [New Thread 4973] that's because it just hit another note that describes the new thread. To actually make sense of the note, however, we need some other tools that look deeper. The elfutils based tools give us a better description of the various notes in the coredump; more akin to what GDB is interpreting them as. Below I've extracted one thread's info:
$ eu-readelf --notes core
...
  CORE                 144  PRSTATUS
    info.si_signo: 6, info.si_code: 0, info.si_errno: 0, cursig: 6
    sigpend: <>
    sighold: <>
    pid: 4970, ppid: 4960, pgrp: 4970, sid: 4960
    utime: 0.000000, stime: 0.000000, cutime: 0.000000, cstime: 0.000000
    orig_eax: 270, fpvalid: 0
    ebx:           4970  ecx:           4970  edx:              6
    esi:              0  edi:     1176018932  ebp:     0xbfa5b710
    eax:              0  eip:     0xffffe424  eflags:  0x00000206
    esp:     0xbfa5b6f8
    ds: 0x007b  es: 0x007b  fs: 0x0000  gs: 0x0033  cs: 0x0073  ss: 0x007b
  LINUX                 48  386_TLS
    index: 6, base: 0xb6043b70, limit: 0x000fffff, flags: 0x00000051
    index: 7, base: 0x00000000, limit: 0x00000000, flags: 0x00000028
    index: 8, base: 0x00000000, limit: 0x00000000, flags: 0x00000028
What's particularly interesting here is that the note type that was previously unknown (Unknown note type: (0x00000200)) has been resolved for us it is in fact of type NT_386_TLS and is a dump of the GDT entries for the thread. So, if we examine how our function is accessing our TLS variable by disassembling the thread function:
(gdb) disassemble thread
Dump of assembler code for function thread:
   0x08048514 <+0>:    push   %ebp
   0x08048515 <+1>:    mov    %esp,%ebp
   0x08048517 <+3>:    sub    $0x18,%esp
   0x0804851a <+6>:    mov    0x8(%ebp),%eax
   0x0804851d <+9>:    mov    %eax,%gs:0xfffffffc
   0x08048523 <+15>:   mov    %gs:0xfffffffc,%edx
   0x0804852a <+22>:   mov    $0x8048670,%eax
   0x0804852f <+27>:   mov    %edx,0x4(%esp)
   0x08048533 <+31>:   mov    %eax,(%esp)
   0x08048536 <+34>:   call   0x80483f4 <printf@plt>
   0x0804853b <+39>:   movl   $0xa,(%esp)
   0x08048542 <+46>:   call   0x8048404 <sleep@plt>
   0x08048547 <+51>:   jmp    0x804853b <thread+39>
Examining the disassembly we can see that foo is accessed via an offset of -4 from %gs (this is OK, as our limit value is maxed out. See the TLS ABI doc for more info). Now, we can examine gs and see which selector it is telling us to use:
(gdb) print $gs >> 3
$31 = 6
Above we shift out the last 3 bits, as these refer to the privilege level (bits 0 and 1) and if this is a GDT or LDT reference (bit 2). Thus, looking at the GDT descriptor for index 6:
  LINUX                 48  386_TLS
    index: 6, base: 0xb6043b70, limit: 0x000fffff, flags: 0x00000051
we can finally do some maths from the base-address to figure out the value:
(gdb) print *(int*)(0xb6043b70 - 4)
$34 = 3
Thus we have found our TLS value; in this case for thread 3 the value is indeed 3. I caution this is the simplest possible case; other "models" (see the TLS doc, again) may not be so simple to work out by hand, but this would certainly be how you would start.

Michal &#268;iha&#345;: Not going to DebConf

Year ago, when DebConf 11 in Banja Luka has been announced, I was really happy for the location and was sure I'm going to visit it. I applied early, requested sponsorship, but then things got slightly more complicated and in the end I had to say no quite shortly before reconfirmation deadline. So I will not meet all the great people behind Debian this year and will wait for another chance (probably in two years, as Nicaragua sounds attractive, but when I would be so far away I'd like to spend at least month in the area and time and money is always problem in such case :-)).

Filed under: Debian English 0 comments Flattr this!

Next.

Previous.