Search Results: "tar"

28 July 2025

Russ Allbery: Review: Cyteen

Review: Cyteen, by C.J. Cherryh
Series: Cyteen #1
Publisher: Warner Aspect
Copyright: 1988
Printing: September 1995
ISBN: 0-446-67127-4
Format: Trade paperback
Pages: 680
The main text below is an edited version of my original review of Cyteen written on 2012-01-03. Additional comments from my re-read are after the original review. I've reviewed several other C.J. Cherryh books somewhat negatively, which might give the impression I'm not a fan. That is an artifact of when I started reviewing. I first discovered Cherryh with Cyteen some 20 years ago, and it remains one of my favorite SF novels of all time. After finishing my reading for 2011, I was casting about for what to start next, saw Cyteen on my parents' shelves, and decided it was past time for my third reading, particularly given the recent release of a sequel, Regenesis. Cyteen is set in Cherryh's Alliance-Union universe following the Company Wars. It references several other books in that universe, most notably Forty Thousand in Gehenna but also Downbelow Station and others. It also has mentions of the Compact Space series (The Pride of Chanur and sequels). More generally, almost all of Cherryh's writing is loosely tied together by an overarching future history. One does not need to read any of those other books before reading Cyteen; this book will fill you in on all of the politics and history you need to know. I read Cyteen first and have never felt the lack. Cyteen was at one time split into three books for publishing reasons: The Betrayal, The Rebirth, and The Vindication. This is an awful way to think of the book. There are no internal pauses or reasonable volume breaks; Cyteen is a single coherent novel, and Cherryh has requested that it never be broken up that way again. If you happen to find all three portions as your reading copy, they contain all the same words and are serviceable if you remember it's a single novel under three covers, but I recommend against reading the portions in isolation. Human colonization of the galaxy started with slower-than-light travel sponsored by the private Sol Corporation. The inhabitants of the far-flung stations and the crews of the merchant ships that supplied them have formed their own separate cultures, but initially remained attached to Earth. That changed with the discovery of FTL travel and a botched attempt by Earth to reassert its authority. At the time of Cyteen, there are three human powers: distant Earth (which plays little role in this book), the merchanter Alliance, and Union. The planet Cyteen is one of only a few Earth-like worlds discovered by human expansion, and is the seat of government and the most powerful force in Union. This is primarily because of Reseune: the Cyteen lab that produces the azi. If Cyteen is about any one thing, it's about azi: genetically engineered human clones who are programmed via intensive psychological conditioning starting before birth. The conditioning uses a combination of drugs to make them receptive and "tape," specific patterns of instruction and sensory stimulation. They are designed for specific jobs or roles, they're conditioned to be obedient to regular humans, and they're not citizens. They are, in short, slaves. In a lot of books, that's as deep as the analysis would go. Azi are slaves, and slavery is certainly bad, so there would probably be a plot around azi overthrowing their conditioning, or around the protagonists trying to free them from servitude. But Cyteen is not any SF novel, and azi are considerably more complex and difficult than that analysis. We learn over the course of the book that the immensely powerful head of Reseune Labs, Ariane Emory, has a specific broader purpose in mind for the azi. One of the reasons why Reseune fought for and gained the role of legal protector of all azi in Union, regardless of where they were birthed, is so that Reseune could act to break any permanent dependence on azi as labor. And yet, they are slaves; one of the protagonists of Cyteen is an experimental azi, which makes him the permanent property of Reseune and puts him in constant jeopardy of being used as a political prisoner and lever of manipulation against those who care about him. Cyteen is a book about manipulation, about programming people, about what it means to have power over someone else's thoughts, and what one can do with that power. But it's also a book about connection and identity, about what makes up a personality, about what constitutes identity and how people construct the moral codes and values that they hold at their core. It's also a book about certainty. Azi are absolutely certain, and are capable of absolute trust, because that's part of their conditioning. Naturally-raised humans are not. This means humans can do things that azi can't, but the reverse is also true. The azi are not mindless slaves, nor are they mindlessly programmed, and several of the characters, both human and azi, find a lot of appeal in the core of certainty and deep self-knowledge of their own psychological rules that azis can have. Cyteen is a book about emotions, and logic, and where they come from and how to balance them. About whether emotional pain and uncertainty is beneficial or damaging, and about how one's experiences make up and alter one's identity. This is also a book about politics, both institutional and personal. It opens with Ariane Emory, Councilor for Science for five decades and the head of the ruling Union Expansionist party. She's powerful, brilliant, dangerously good at reading people, and dangerously willing to manipulate and control people for her own ends. What she wants, at the start of the book, is to completely clone a Special (the legal status given to the most brilliant minds of Union). This was attempted before and failed, but Ariane believes it's now possible, with a combination of tape, genetic engineering, and environmental control, to reproduce the brilliance of the original mind. To give Union another lifespan of work by their most brilliant thinkers. Jordan Warrick, another scientist at Reseune, has had a long-standing professional and personal feud with Ariane Emory. As the book opens, he is fighting to be transferred out from under her to the new research station that would be part of the Special cloning project, and he wants to bring his son Justin and Justin's companion azi Grant with them. Justin is a PR, a parental replicate, meaning he shares Jordan's genetic makeup but was not an attempt to reproduce the conditions of Jordan's rearing. Grant was raised as his brother. And both have, for reasons that are initially unclear, attracted the attention of Ariane, who may be using them as pawns. This is just the initial setup, and along with this should come a warning: the first 150 pages set up a very complex and dangerous political situation and build the tension that will carry the rest of the book, and they do this by, largely, torturing Justin and Grant. The viewpoint jumps around, but Justin and Grant are the primary protagonists for this first section of the book. While one feels sympathy for both of them, I have never, in my multiple readings of the book, particularly liked them. They're hard to like, as opposed to pity, during this setup; they have very little agency, are in way over their heads, are constantly making mistakes, and are essentially having their lives destroyed. Don't let this turn you off on the rest of the book. Cyteen takes a dramatic shift about 150 pages in. A new set of protagonists are introduced who are some of the most interesting, complex, and delightful protagonists in any SF novel I have read, and who are very much worth waiting for. While Justin has his moments later on (his life is so hard that his courage can be profoundly moving), it's not necessary to like him to love this book. That's one of the reasons why I so strongly dislike breaking it into three sections; that first section, which is mostly Justin and Grant, is not representative of the book. I can't talk too much more about the plot without risking spoiling it, but it's a beautiful, taut, and complex story that is full of my favorite things in both settings and protagonists. Cyteen is a book about brilliant people who think on their feet. Cherryh succeeds at showing this through what they do, which is rarely done as well as it is here. It's a book about remembering one's friends and remembering one's enemies, and waiting for the most effective moment to act, but it also achieves some remarkable transformations. About 150 pages in, you are likely to loathe almost everyone in Reseune; by the end of the book, you find yourself liking, or at least understanding, nearly everyone. This is extremely hard, and Cherryh pulls it off in most cases without even giving the people she's redeeming their own viewpoint sections. Other than perhaps George R.R. Martin I've not seen another author do this as well. And, more than anything else, Cyteen is a book with the most wonderful feeling of catharsis. I think this is one of the reasons why I adore this book and have difficulties with some of Cherryh's other works. She's always good at ramping up the tension and putting her characters in awful, untenable positions. Less frequently does she provide the emotional payoff of turning the tables, where you get to watch a protagonist do everything you've been wanting them to do for hundreds of pages, except even better and more delightfully than you would have come up with. Cyteen is one of the most emotionally satisfying books I've ever read. I could go on and on; there is just so much here that I love. Deep questions of ethics and self-control, presented in a way that one can see the consequences of both bad decisions and good ones and contrast them. Some of the best political negotiations in fiction. A wonderful look at friendship and loyalty from several directions. Two of the best semi-human protagonists I've seen, who one can see simultaneously as both wonderful friends and utterly non-human and who put nearly all of the androids in fiction to shame by being something trickier and more complex. A wonderful unfolding sense of power. A computer that can somewhat anticipate problems and somewhat can't, and that encapsulates much of what I love about semi-intelligent bases in science fiction. Cyteen has that rarest of properties of SF novels: Both the characters and the technology meld in a wonderful combination where neither could exist without the other, where the character issues are illuminated by the technology and the technology supports the characters. I have, for this book, two warnings. The first, as previously mentioned, is that the first 150 pages of setup is necessary but painful to read, and I never fully warmed to Justin and Grant throughout. I would not be surprised to hear that someone started this book but gave up on it after 50 or 100 pages. I do think it's worth sticking out the rocky beginning, though. Justin and Grant continue to be a little annoying, but there's so much other good stuff going on that it doesn't matter. The other warning is that part of the setup of the story involves the rape of an underage character. This is mostly off-camera, but the emotional consequences are significant (as they should be) and are frequently discussed throughout the book. There is also rather frank discussion of adolescent sexuality later in the book. I think both of these are relevant to the story and handled in a way that isn't gratuitous, but they made me uncomfortable and I don't have any past history with those topics. Those warnings notwithstanding, this is simply one of the best SF novels ever written. It uses technology to pose deep questions about human emotions, identity, and interactions, and it uses complex and interesting characters to take a close look at the impact of technology on lives. And it does this with a wonderfully taut, complicated plot that sustains its tension through all 680 pages, and with characters whom I absolutely love. I have no doubt that I'll be reading it for a fourth and fifth time some years down the road. Followed by Regenesis, although Cyteen stands well entirely on its own and there's no pressing need to read the sequel. Rating: 10 out of 10

Some additional thoughts after re-reading Cyteen in 2025: I touched on this briefly in my original review, but I was really struck during this re-read how much the azi are a commentary on and a complication of the role of androids in earlier science fiction. Asimov's Three Laws of Robotics were an attempt to control the risks of robots, but can also be read as turning robots into slaves. Azis make the slavery more explicit and disturbing by running the programming on a human biological platform, but they're more explicitly programmed and artificial than a lot of science fiction androids. Artificial beings and their relationship to humans have been a recurring theme of SF since Frankenstein, but I can't remember a novel that makes the comparison to humans this ambiguous and conflicted. The azi not only like being azi, they can describe why they prefer it. It's clear that Union made azi for many of the same reasons that humans enslave other humans, and that Ariane Emory is using them as machinery in a larger (and highly ethically questionable) plan, but Cherryh gets deeper into the emergent social complications and societal impact than most SF novels manage. Azi are apparently closer to humans than the famous SF examples such as Commander Data, but the deep differences are both more subtle and more profound. I've seen some reviewers who are disturbed by the lack of a clear moral stance by the protagonists against the creation of azi. I'm not sure what to think about that. It's clear the characters mostly like the society they've created, and the groups attempting to "free" azi from their "captivity" are portrayed as idiots who have no understanding of azi psychology. Emory says she doesn't want azi to be a permanent aspect of society but clearly has no intention of ending production any time soon. The book does seem oddly unaware that the production of azi is unethical per se and, unlike androids, has an obvious exit ramp: Continue cloning gene lines as needed to maintain a sufficient population for a growing industrial civilization, but raise the children as children rather than using azi programming. If Cherryh included some reason why that was infeasible, I didn't see it, and I don't think the characters directly confronted it. I don't think societies in books need to be ethical, or that Cherryh intended to defend this one. There are a lot of nasty moral traps that civilizations can fall into that make for interesting stories. But the lack of acknowledgment of the problem within the novel did seem odd this time around. The other part of this novel that was harder to read past in this re-read is the sexual ethics. There's a lot of adolescent sexuality in this book, and even apart from the rape scene which was more on-the-page than I had remembered and which is quite (intentionally) disturbing there is a whole lot of somewhat dubious consent. Maybe I've gotten older or just more discriminating, but it felt weirdly voyeuristic to know this much about the sex lives of characters who are, at several critical points in the story, just a bunch of kids. All that being said, and with the repeated warning that the first 150 pages of this novel are just not very good, there is still something magic about the last two-thirds of this book. It has competence porn featuring a precociously brilliant teenager who I really like, it has one of the more interesting non-AI programmed computer systems that I've read in SF, it has satisfying politics that feel like modern politics (media strategy and relationships and negotiated alliances, rather than brute force and ideology), and it has a truly excellent feeling of catharsis. The plot resolution is a bit too abrupt and a bit insufficiently explained (there's more in Regenesis), but even though this was my fourth time through this book, the pacing grabbed me again and I could barely put down the last part of the story. Ethics aside (and I realize that's quite the way to start a sentence), I find the azi stuff fascinating. I know the psychology in this book is not real and is hopelessly simplified compared to real psychology, but there's something in the discussions of value sets and flux and self-knowledge that grabs my interest and makes me want to ponder. I think it's the illusion of simplicity and control, the what-if premise of thought where core motivations and moral rules could be knowable instead of endlessly fluid the way they are in us humans. Cherryh's azi are some of the most intriguing androids in science fiction to me precisely because they don't start with computers and add the humanity in, but instead start with humanity and overlay a computer-like certainty of purpose that's fully self-aware. The result is more subtle and interesting than anything Star Trek managed. I was not quite as enamored with this book this time around, but it's still excellent once the story gets properly started. I still would recommend it, but I might add more warnings about the disturbing parts.

Re-read rating: 9 out of 10

27 July 2025

Kentaro Hayashi: Switching from NVIDIA GPU to AMD GPU

Introduction Recently, I've got a chance to try AMD GPU. I didn't have experience as a user with AMD GPU, but I felt it was very easy to switch.

How to switch from NVIDIA GPU to AMD GPU? Here is the steps to migrate from NVIDIA GPU. (I'm using Debian sid as a daily driver, but the following instructions are also applicable) Not only nvidia-driver, but also need to say good-bye to CUDA related packages. Anyway, it is important to clean it up.
  • Reboot it!
Ensure without nvidia-driver, it correctly boot with GUI desktop. Now you can see driver was changed to nouveau module. You can ensure it with lsmod command.
$ lsmod  grep nou
nouveau              3055616  16
mxm_wmi                12288  1 nouveau
drm_gpuvm              45056  1 nouveau
drm_exec               12288  2 drm_gpuvm,nouveau
gpu_sched              65536  1 nouveau
video                  81920  1 nouveau
i2c_algo_bit           16384  1 nouveau
drm_display_helper    274432  1 nouveau
drm_ttm_helper         16384  2 nouveau
ttm                   106496  2 drm_ttm_helper,nouveau
drm_kms_helper        253952  3 drm_display_helper,drm_ttm_helper,nouveau
drm                   774144  14 gpu_sched,drm_kms_helper,drm_exec,drm_gpuvm,drm_display_helper,drm_ttm_helper,ttm,nouveau
wmi                    28672  4 video,wmi_bmof,mxm_wmi,nouveau
button                 24576  1 nouveau
  • Install amdgpu related stuff
Install the following packages.
libdrm-amdgpu1 2.4.124-2
xserver-xorg-video-amdgpu 23.0.0-1
mesa-vulkan-drivers 25.0.7-2
mesa-utils 9.0.0-2+b2
firmware-amd-graphics 20250410-2
Now ready to switch GPU. I rarely had the opportunity to replace the GPU and in this time need to change power supply as well, it was a bit difficult to do. Then, graphic driver was changed from nouveau to amdgpu as expected.
$ lsmod   grep amd
amd_atl                57344  1
edac_mce_amd           28672  0
kvm_amd               217088  0
kvm                  1396736  1 kvm_amd
ccp                   163840  1 kvm_amd
amdgpu              14450688  33
amdxcp                 12288  1 amdgpu
drm_exec               12288  1 amdgpu
gpu_sched              65536  1 amdgpu
drm_buddy              20480  1 amdgpu
video                  81920  1 amdgpu
i2c_algo_bit           16384  1 amdgpu
drm_suballoc_helper    12288  1 amdgpu
drm_display_helper    274432  1 amdgpu
drm_ttm_helper         16384  2 amdgpu
ttm                   106496  2 amdgpu,drm_ttm_helper
drm_kms_helper        253952  3 drm_display_helper,amdgpu,drm_ttm_helper
drm                   774144  23 gpu_sched,drm_kms_helper,drm_exec,drm_suballoc_helper,drm_display_helper,drm_buddy,amdgpu,drm_ttm_helper,ttm,amdxcp
crc16                  12288  3 bluetooth,amdgpu,ext4
gpio_amdpt             16384  0
gpio_generic           20480  1 gpio_amdpt
That's all. Currently, I'm using it on linux-image-6.12.38+deb13-amd64 kernel. It seems that there is more newer release for firmware-amd-graphics, but no critical issue is found yet.

Conclusion By switching from NVIDIA GPU, there were some disadvantage that some application does not support AMD GPU yet. On the positive side, no need to worry about nvidia-driver issues such as #1089513 I just started using AMD GPU, I hope I could help to improve the AMD GPU experience on Debian. This article was written with Ultimate Hacking Keyboard 60 v2 with Riser 60.

26 July 2025

Bits from Debian: DebConf25 closes in Brest and DebConf26 announced

DebConf25 group photo - click to enlarge On Saturday 19 July 2025, the annual Debian Developers and Contributors Conference came to a close. Over 443 attendees representing 50 countries from around the world came together for a combined 169 events (including some which took place during the DebCamp) including more than 50 Talks, 39 Short Talks, 5 Discussions, 59 Birds of a Feather sessions ("BoF" informal meeting between developers and users), 10 workshops, and activities in support of furthering our distribution and free software, learning from our mentors and peers, building our community, and having a bit of fun. The conference was preceded by the annual DebCamp hacking session held 7 through 13 July where Debian Developers and Contributors convened to focus on their individual Debian-related projects or work in team sprints geared toward in-person collaboration in developing Debian. This year, a session was dedicated to prepare the BoF "Dealing with Dormant Packages: Ensuring Debian's High Standards"; another, at the initiative of our DPL, to prepare suggestions for the BoF Package Acceptance in Debian: Challenges and Opportunities"; and an afternoon around Salsa-CI. As has been the case for several years, a special effort has been made to welcome newcomers and help them become familiar with Debian and DebConf by organizing a sprint "New Contributors Onboarding" every day of Debcamp, followed more informally by mentorship during DebConf. The actual Debian Developers Conference started on Monday 14 July 2025. In addition to the traditional "Bits from the DPL" talk, the continuous key-signing party, lightning talks, and the announcement of next year's DebConf26, there were several update sessions shared by internal projects and teams. Many of the hosted discussion sessions were presented by our technical core teams with the usual and useful "Meet the Technical Committee", the "What's New in the Linux Kernel" session, and a set of BoFs about Debian packaging policy and Debian infrastructure. Thus, more than a quarter of the discussions dealt with this theme, including talks about our tools and Debian's archive processes. Internationalization and Localization have been the subject of several talks. The Python, Perl, Ruby, Go, and Rust programming language teams also shared updates on their work and efforts. Several talks have covered Debian Blends and Debian-derived distributions and other talks addressed the issue of Debian and AI. More than 17 BoFs and talks about community, diversity, and local outreach highlighted the work of various teams involved in not just the technical but also the social aspect of our community; four women who have made contributions to Debian through their artwork in recent years presented their work. The one-day session "DebConf 2025 Academic Track!", organized in collaboration with the IRISA laboratory was the first session welcoming fellow academics at DebConf, bringing together around ten presentations. The schedule was updated each day with planned and ad hoc activities introduced by attendees over the course of the conference. Several traditional activities took place: a job fair, a poetry performance, the traditional Cheese and Wine party (this year with cider as well), the Group Photos, and the Day Trips. For those who were not able to attend, most of the talks and sessions were broadcasted live and recorded; currently the videos are made available through this link. Almost all of the sessions facilitated remote participation via IRC and Matrix messaging apps or online collaborative text documents which allowed remote attendees to "be in the room" to ask questions or share comments with the speaker or assembled audience. DebConf25 saw over 441 T-shirts, 3 day trips, and up to 315 meals planned per day. All of these events, activities, conversations, and streams coupled with our love, interest, and participation in Debian and F/OSS certainly made this conference an overall success both here in Brest, France and online around the world. The DebConf25 website will remain active for archival purposes and will continue to offer links to the presentations and videos of talks and events. Next year, DebConf26 will be held in Santa Fe, Argentina, likely in July. As tradition follows before the next DebConf the local organizers in Argentina will start the conference activities with DebCamp with a particular focus on individual and team work towards improving the distribution. DebConf is committed to a safe and welcome environment for all participants. See the web page about the Code of Conduct on the DebConf25 website for more details on this. Debian thanks the commitment of numerous sponsors to support DebConf25, particularly our Platinum Sponsors: AMD, EDF, Infomaniak, Proxmox, and Viridien. We also wish to thank our Video and Infrastructure teams, the DebConf25 and DebConf committees, our host nation of France, and each and every person who helped contribute to this event and to Debian overall. Thank you all for your work in helping Debian continue to be "The Universal Operating System". See you next year! About Debian The Debian Project was founded in 1993 by Ian Murdock to be a truly free community project. Since then the project has grown to be one of the largest and most influential Open Source projects. Thousands of volunteers from all over the world work together to create and maintain Debian software. Available in 70 languages, and supporting a huge range of computer types, Debian calls itself the universal operating system. About DebConf DebConf is the Debian Project's developer conference. In addition to a full schedule of technical, social and policy talks, DebConf provides an opportunity for developers, contributors and other interested people to meet in person and work together more closely. It has taken place annually since 2000 in locations as varied as Scotland, Bosnia and Herzegovina, India, Korea. More information about DebConf is available from https://debconf.org/. About AMD The AMD ROCm platform includes programming models, tools, compilers, libraries, and runtimes for AI and HPC solution development on AMD GPUs. Debian is an officially supported platform for AMD ROCm and a growing number of components are now included directly in the Debian distribution. For more than 55 years AMD has driven innovation in high-performance computing, graphics and visualization technologies. AMD is deeply committed to supporting and contributing to open-source projects, foundations, and open-standards organizations, taking pride in fostering innovation and collaboration within the open-source community. About EDF EDF is a leading global utility company focused on low-carbon power generation. The group uses advanced engineering and scientific computing tools to drive innovation and efficiency in its operations, especially in nuclear power plant design and safety assessment. Since 2003, the EDF Group has been using Debian as its main scientific computing environment. Debian's focus on stability and reproducibility ensures that EDF's calculations and simulations produce consistent and accurate results. About Infomaniak Infomaniak is Switzerland's leading developer of Web technologies. With operations all over Europe and based exclusively in Switzerland, the company designs and manages its own data centers powered by 100% renewable energy, and develops all its solutions locally, without outsourcing. With millions of users and the trust of public and private organizations across Europe - such as RTBF, the United Nations, central banks, over 3,000 radio and TV stations, as well as numerous cities and security bodies - Infomaniak stands for sovereign, sustainable and independent digital technology. The company offers a complete suite of collaborative tools, cloud hosting, streaming, marketing and events solutions, while being owned by its employees and self-financed exclusively by its customers. About Proxmox Proxmox develops powerful, yet easy-to-use Open Source server software. The product portfolio from Proxmox, including server virtualization, backup, and email security, helps companies of any size, sector, or industry to simplify their IT infrastructures. The Proxmox solutions are built on Debian, we are happy that they give back to the community by sponsoring DebConf25. About Viridien Viridien is an advanced technology, digital and Earth data company that pushes the boundaries of science for a more prosperous and sustainable future. Viridien has been using Debian-based systems to power most of its HPC infrastructure and its cloud platform since 2009 and currently employs two active Debian Project Members. Contact Information For further information, please visit the DebConf25 web page at https://debconf25.debconf.org/ or send mail to press@debian.org.

Birger Schacht: My DebConf 25 review

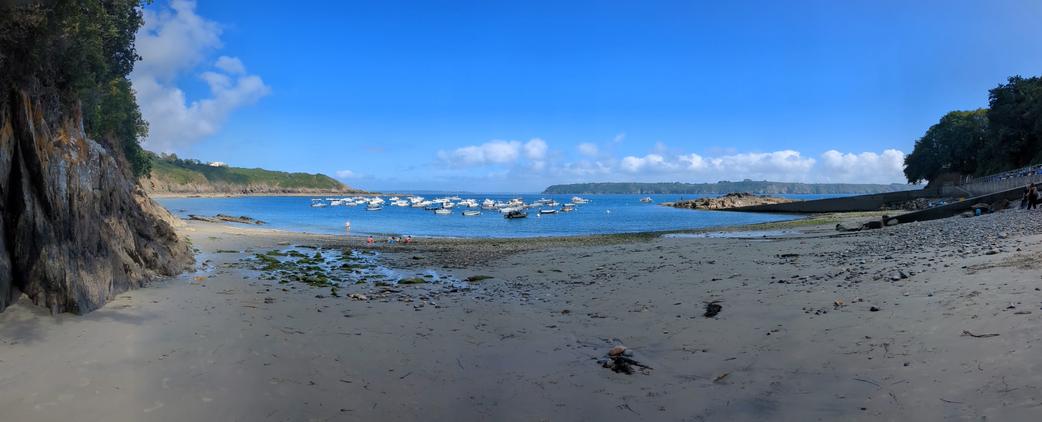
DebConf 25 happened between 14th July and 19th July and I was there. It was my first DebConf (the big one, I was at a Mini DebConf in Hamburg a couple of years ago) and it was interesting. DebConf 25 happened at a Campus University at the outskirts of Brest and I was rather reluctant to go at first (EuroPython 25 was happening at the same time in Prague), but I decided to use the chance of DebConf happening in Europe, reachable by train from Vienna. We took the nighttrain to Paris, then found our way through the maze that is the Paris underground system and then got to Brest with the TGV. On our way to the Conference site we made a detour to a supermarket, which wasn t that easy because is was a national holiday in France and most of the shops were closed. But we weren t sure about the food situation at DebConf and we also wanted to get some beer. At the conference we were greeted by very friendly people at the badge station and the front desk and got our badges, swag and most important the keys to pretty nice rooms on the campus. Our rooms had a small private bathroom with a toilet and a shower and between the two rooms was a shared kitchen with a refrigerator and a microwave. All in all, the accommodation was simple but provided everything we needed and especially a space to have some privacy. During the next days I watched a lot of talks, met new people, caught up with old friends and also had a nice time with my travel buddies. There was a beach near the campus which I used nearly every day. It was mostly sunny except for the last day of the conference, which apparently was not common for the Brest area, so we got lucky regarding the weather. Landscape view of the sea at Dellec beach Given that we only arrived in the evening of the first day of DebConf, I missed the talk When Free Software Communities Unite: Tails, Tor, and the Fight for Privacy (recording), but I watched it on the way home and it was also covered by LWN. On Tuesday I started the day by visiting a talk about tag2upload (recording). The same day there was also an academic track and I watched the talk titled Integrating Knowledge Graphs into the Debian Ecosystem (recording) which presented a property graph showing relationships between various entities like packages, maintainers or bugs (there is a repository with parts of a paper, but not much other information). The speaker also mentioned the graphcast framework and the ontocast framework which sound interesting - we might have use for something liked this at $dayjob. In the afternoon there was a talk about the ArchWiki (recording) which gave a comprehensive insight in how the ArchWiki and the community behind it works. Right after that was a Debian Wiki BoF. There are various technical limitations with the current wiki software and there are not enough helping hands to maintain the service and do content curation. But the BoF had some nice results: there is now a new debian-wiki mailinglist, an IRC channel, a MediaWiki installation has been set up during DebConf, there are efforts to migrate the data and most importantly: and handful of people who want to maintain the service and organize the content of the wiki. I think the input from the ArchWiki folks gave some ideas how that team could operate. Tag at the wall at Dellec beach Wednesday was the day of the daytrip. I did not sign up for any of the trips and used the time to try out tag2upload, uploaded the latest labwc release to experimental and spent the rest of the day at the beach. Other noteworthy session I ve attended were the Don t fear the TPM talk (recording), which showed me a lot of stuff to try out, the session about lintian-ng (no recording), which is an experimental approach to make lintian faster, the review of the first year of wcurls existence (no recording yet) and the summary of Rust packaging in Debian (no recording yet). In between the sessions I started working on packaging wlr-sunclock (#1109230).

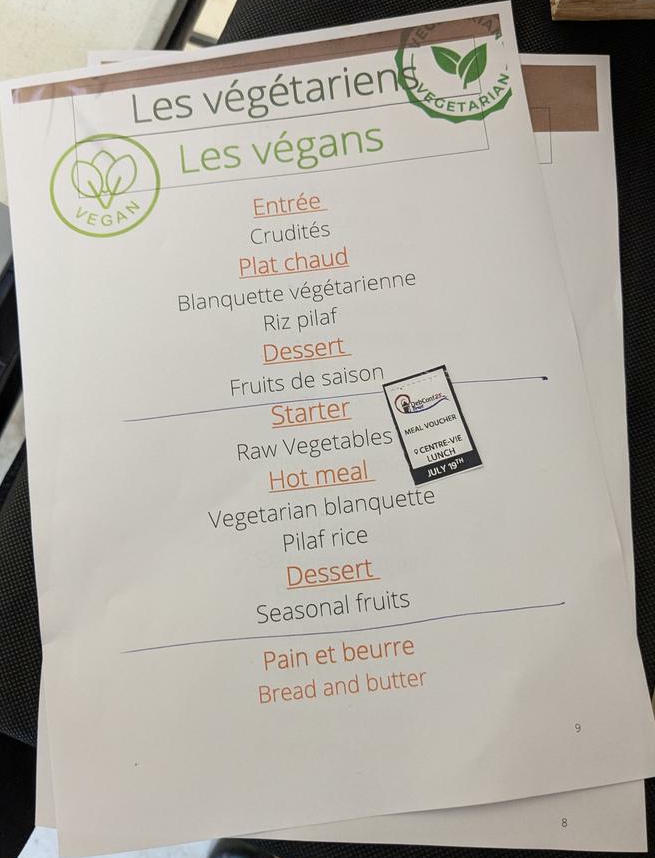
What did not work Vegan food. I might be spoiled by other conferences. Both at EuroPycon last year (definitely bigger, a lot more commercial) and at PyCon CZ 23 (similar in size, a lot more DIY) there was catering with explicitly vegan options. As I ve mentioned in the beginning, we went to a supermarket before we went to the conference and we had to go there one more time during the conference. I think there was a mixture between a total lack of awareness and a LOT of miscommunication. The breakfasts at the conference consisted of pastries and baguettes - I asked at the first day what the vegan options were and the answer was I don t know, maybe the baguette? and we were asked to only take as much baguette as the people who also got pastries. The lunch was prepared by the Restaurant associatif de Kern vent which is a canteen at the university campus. When we asked if there is vegan food, the people there said that there was only a vegetarian option so we only ate salad. Only later we heard via word of mouth that one has to explicitly ask for a vegan meal which was apparently prepared separatly and you had to find the right person that knows about it (I think thats very Debian-like ). But even then a person once got a vegetarian option offered as vegan food. One problem was also the missing / confusing labeling of the food. At the conference dinner there was apparently vegan food, but it was mixed with all the other food. There were some labels but with hundreds of hungry people around and caterers removing empty plates and dropping off plates with other stuff, everything gets mixed up. In the end we ate bread soaked in olive oil, until the olive oil got taken away by the catering people literally while we were dipping the bread in it. And when these issues were raised, some of the reactions can be summarized as You re holding it wrong which was really frustrating. The dinners at the conference hall were similar. At some point I had the impression that vegan and vegetarian was simply seen as the same thing. Dinner menu at the conference If the menus would be written like a debian/copyright file it would probably have looked like this:
Food: *
Diet: Vegan or Vegetarian
But the thing is that Vegan and Vegetarian cannot be mixed. Its similar to non compatible licenses. Once you mix vegan food with vegan food with vegetarian food it s not vegan anymore. Don t get me wrong, I know its hard to organize food for hundreds of people. But if you don t know what it means to provide a vegan option, just communicate the fact so people can look alternatives in advance. During the week some of the vegan people shared food, which was really nice and there were also a lot of non-vegan people who tried to help, organized extra food or simply listened to the hangry rants. Thanks for that!

Paris Saturday was the last day of DebConf and it was a rainy day. On Sunday morning we took the TGV back to Paris and then stayed there for one night because the next night train back to Vienna was on Monday. Luckily the weather was better in Paris. The first thing we did was to look up a vegan burger place. In the evening we strolled along the Seine and had a couple of beers at the Jardins du Trocad ro. Monday the rain also arrived in Paris and we mostly went from one cafe to the next, but also managed to visit Notre Dame.

Conclusio The next DebConf will be in Argentina and I think its likely that DebConf 27 will also not happen anywhere in trainvelling distance. But even if, I think the Mini DebConfs are more my style of happening (there is one planned in Hamburg next spring, and a couple of days ago I learned that there will be a Back to the Future musical show in Hamburg during that time). Nonetheless I had a nice time and I stumbled over some projects I might get more involved in. Thanks also to my travel buddies who put up with me

Matthew Palmer: Object deserialization attacks using Ruby's Oj JSON parser

tl;dr: there is an attack in the wild which is triggering dangerous-but-seemingly-intended behaviour in the Oj JSON parser when used in the default and recommended manner, which can lead to everyone s favourite kind of security problem: object deserialization bugs! If you have the oj gem anywhere in your Gemfile.lock, the quickest mitigation is to make sure you have Oj.default_options = mode: :strict somewhere, and that no library is overwriting that setting to something else.

Prologue As a sensible sysadmin, all the sites I run send me a notification if any unhandled exception gets raised. Mostly, what I get sent is error-handling corner cases I missed, but now and then things get more interesting. In this case, it was a PG::UndefinedColumn exception, which looked something like this:
PG::UndefinedColumn: ERROR:  column "xyzzydeadbeef" does not exist
This is weird on two fronts: firstly, this application has been running for a while, and if there was a schema problem, I d expect it to have made itself apparent long before now. And secondly, while I don t profess to perfection in my programming, I m usually better at naming my database columns than that. Something is definitely hinky here, so let s jump into the mystery mobile!

The column name is coming from outside the building! The exception notifications I get sent include a whole lot of information about the request that caused the exception, including the request body. In this case, the request body was JSON, and looked like this:
 "name":":xyzzydeadbeef", ... 
The leading colon looks an awful lot like the syntax for a Ruby symbol, but it s in a JSON string. Surely there s no way a JSON parser would be turning that into a symbol, right? Right?!? Immediately, I thought that that possibly was what was happening, because I use Sequel for my SQL database access needs, and Sequel treats symbols as database column names. It seemed like too much of a coincidence that a vaguely symbol-shaped string was being sent in, and the exact same name was showing up as a column name. But how the flying fudgepickles was a JSON string being turned into a Ruby symbol, anyway? Enter Oj.

Oj? I barely know aj A long, long time ago, the standard Ruby JSON library had a reputation for being slow. Thus did many competitors flourish, claiming more features and better performance. Strong amongst the contenders was oj (for Optimized JSON ), touted as The fastest JSON parser and object serializer . Given the history, it s not surprising that people who wanted the best possible performance turned to Oj, leading to it being found in a great many projects, often as a sub-dependency of a dependency of a dependency (which is how it ended up in my project). You might have noticed in Oj s description that, in addition to claiming fastest , it also describes itself as an object serializer . Anyone who has kept an eye on the security bug landscape will recall that object deserialization is a rich vein of vulnerabilities to mine. Libraries that do object deserialization, especially ones with a history that goes back to before the vulnerability class was well-understood, are likely to be trouble magnets. And thus, it turns out to be with Oj. By default, Oj will happily turn any string that starts with a colon into a symbol:

>> require "oj"
>> Oj.load(' "name":":xyzzydeadbeef","username":"bob","answer":42 ')
=>  "name"=>:xyzzydeadbeef, "username"=>"bob", "answer"=>42 

How that gets exploited is only limited by the creativity of an attacker. Which I ll talk about more shortly but first, a word from my rant cortex.

Insecure By Default is a Cancer While the object of my ire today is Oj and its fast-and-loose approach to deserialization, it is just one example of a pervasive problem in software: insecurity by default. Whether it s a database listening on 0.0.0.0 with no password as soon as its installed, or a library whose default behaviour is to permit arbitrary code execution, it all contributes to a software ecosystem that is an appalling security nightmare. When a user (in this case, a developer who wants to parse JSON) comes across a new piece of software, they have by definition no idea what they re doing with that software. They re going to use the defaults, and follow the most easily-available documentation, to achieve their goal. It is unrealistic to assume that a new user of a piece of software is going to do things the right way , unless that right way is the only way, or at least the by-far-the-easiest way. Conversely, the developer(s) of the software is/are the domain experts. They have knowledge of the problem domain, through their exploration while building the software, and unrivalled expertise in the codebase. Given this disparity in knowledge, it is tantamount to malpractice for the experts the developer(s) to off-load the responsibility for the safe and secure use of the software to the party that has the least knowledge of how to do that (the new user). To apply this general principle to the specific case, take the Using section of the Oj README. The example code there calls Oj.load, with no indication that this code will, in fact, parse specially-crafted JSON documents into Ruby objects. The brand-user user of the library, no doubt being under pressure to Get Things Done, is almost certainly going to look at this Using example, get the apparent result they were after (a parsed JSON document), and call it a day. It is unlikely that a brand-new user will, for instance, scroll down to the Further Reading section, find the second last (of ten) listed documents, Security.md , and carefully peruse it. If they do, they ll find an oblique suggestion that parsing untrusted input is never a good idea . While that s true, it s also rather unhelpful, because I d wager that by far the majority of JSON parsed in the world is untrusted , in one way or another, given the predominance of JSON as a format for serializing data passing over the Internet. This guidance is roughly akin to putting a label on a car s airbags that driving at speed can be hazardous to your health : true, but unhelpful under the circumstances. The solution is for default behaviours to be secure, and any deviation from that default that has the potential to degrade security must, at the very least, be clearly labelled as such. For example, the Oj.load function should be named Oj.unsafe_load, and the Oj.load function should behave as the Oj.safe_load function does presently. By naming the unsafe function as explicitly unsafe, developers (and reviewers) have at least a fighting chance of recognising they re doing something risky. We put warning labels on just about everything in the real world; the same should be true of dangerous function calls. OK, rant over. Back to the story.

But how is this exploitable? So far, I ve hopefully made it clear that Oj does some Weird Stuff with parsing certain JSON strings. It caused an unhandled exception in a web application I run, which isn t cool, but apart from bombing me with exception notifications, what s the harm? For starters, let s look at our original example: when presented with a symbol, Sequel will interpret that as a column name, rather than a string value. Thus, if our save an update to the user code looked like this:

# request_body has the JSON representation of the form being submitted
body = Oj.load(request_body)
DB[:users].where(id: user_id).update(name: body["name"])

In normal operation, this will issue an SQL query along the lines of UPDATE users SET name='Jaime' WHERE id=42. If the name given is Jaime O Dowd , all is still good, because Sequel quotes string values, etc etc. All s well so far. But, imagine there is a column in the users table that normally users cannot read, perhaps admin_notes. Or perhaps an attacker has gotten temporary access to an account, and wants to dump the user s password hash for offline cracking. So, they send an update claiming that their name is :admin_notes (or :password_hash). In JSON, that ll look like "name":":admin_notes" , and Oj.load will happily turn that into a Ruby object of "name"=>:admin_notes . When run through the above update the user code fragment, it ll produce the SQL UPDATE users SET name=admin_notes WHERE id=42. In other words, it ll copy the contents of the admin_notes column into the name column which the attacker can then read out just by refreshing their profile page.

But Wait, There s More! That an attacker can read other fields in the same table isn t great, but that s barely scratching the surface. Remember before I said that Oj does object serialization ? That means that, in general, you can create arbitrary Ruby objects from JSON. Since objects contain code, it s entirely possible to trigger arbitrary code execution by instantiating an appropriate Ruby object. I m not going to go into details about how to do this, because it s not really my area of expertise, and many others have covered it in detail. But rest assured, if an attacker can feed input of their choosing into a default call to Oj.load, they ve been handed remote code execution on a platter.

Mitigations As Oj s object deserialization is intended and documented behaviour, don t expect a future release to make any of this any safer. Instead, we need to mitigate the risks. Here are my recommended steps:
  1. Look in your Gemfile.lock (or SBOM, if that s your thing) to see if the oj gem is anywhere in your codebase. Remember that even if you don t use it directly, it s popular enough that it is used in a lot of places. If you find it in your transitive dependency tree anywhere, there s a chance you re vulnerable, limited only by the ingenuity of attackers to feed crafted JSON into a deeply-hidden Oj.load call.
  2. If you depend on oj directly and use it in your project, consider not doing that. The json gem is acceptably fast, and JSON.parse won t create arbitrary Ruby objects.
  3. If you really, really need to squeeze the last erg of performance out of your JSON parsing, and decide to use oj to do so, find all calls to Oj.load in your code and switch them to call Oj.safe_load.
  4. It is a really, really bad idea to ever use Oj to deserialize JSON into objects, as it lacks the safety features needed to mitigate the worst of the risks of doing so (for example, restricting which classes can be instantiated, as is provided by the permitted_classes argument to Psych.load). I d make it a priority to move away from using Oj for that, and switch to something somewhat safer (such as the aforementioned Psych). At the very least, audit and comment heavily to minimise the risk of user-provided input sneaking into those calls somehow, and pass mode: :object as the second argument to Oj.load, to make it explicit that you are opting-in to this far more dangerous behaviour only when it s absolutely necessary.
  5. To secure any unsafe uses of Oj.load in your dependencies, consider setting the default Oj parsing mode to :strict, by putting Oj.default_options = mode: :strict somewhere in your initialization code (and make sure no dependencies are setting it to something else later!). There is a small chance that this change of default might break something, if a dependency is using Oj to deliberately create Ruby objects from JSON, but the overwhelming likelihood is that Oj s just being used to parse ordinary JSON, and these calls are just RCE vulnerabilities waiting to give you a bad time.

Is Your Bacon Saved? If I ve helped you identify and fix potential RCE vulnerabilities in your software, or even just opened your eyes to the risks of object deserialization, please help me out by buying me a refreshing beverage. I would really appreciate any support you can give. Alternately, if you d like my help in fixing these (and many other) sorts of problems, I m looking for work, so email me.

25 July 2025

Valhalla's Things: Roll Top Backpack, Handsewn

Posted on July 25, 2025
Tags: madeof:atoms, craft:sewing, FreeSoftWear
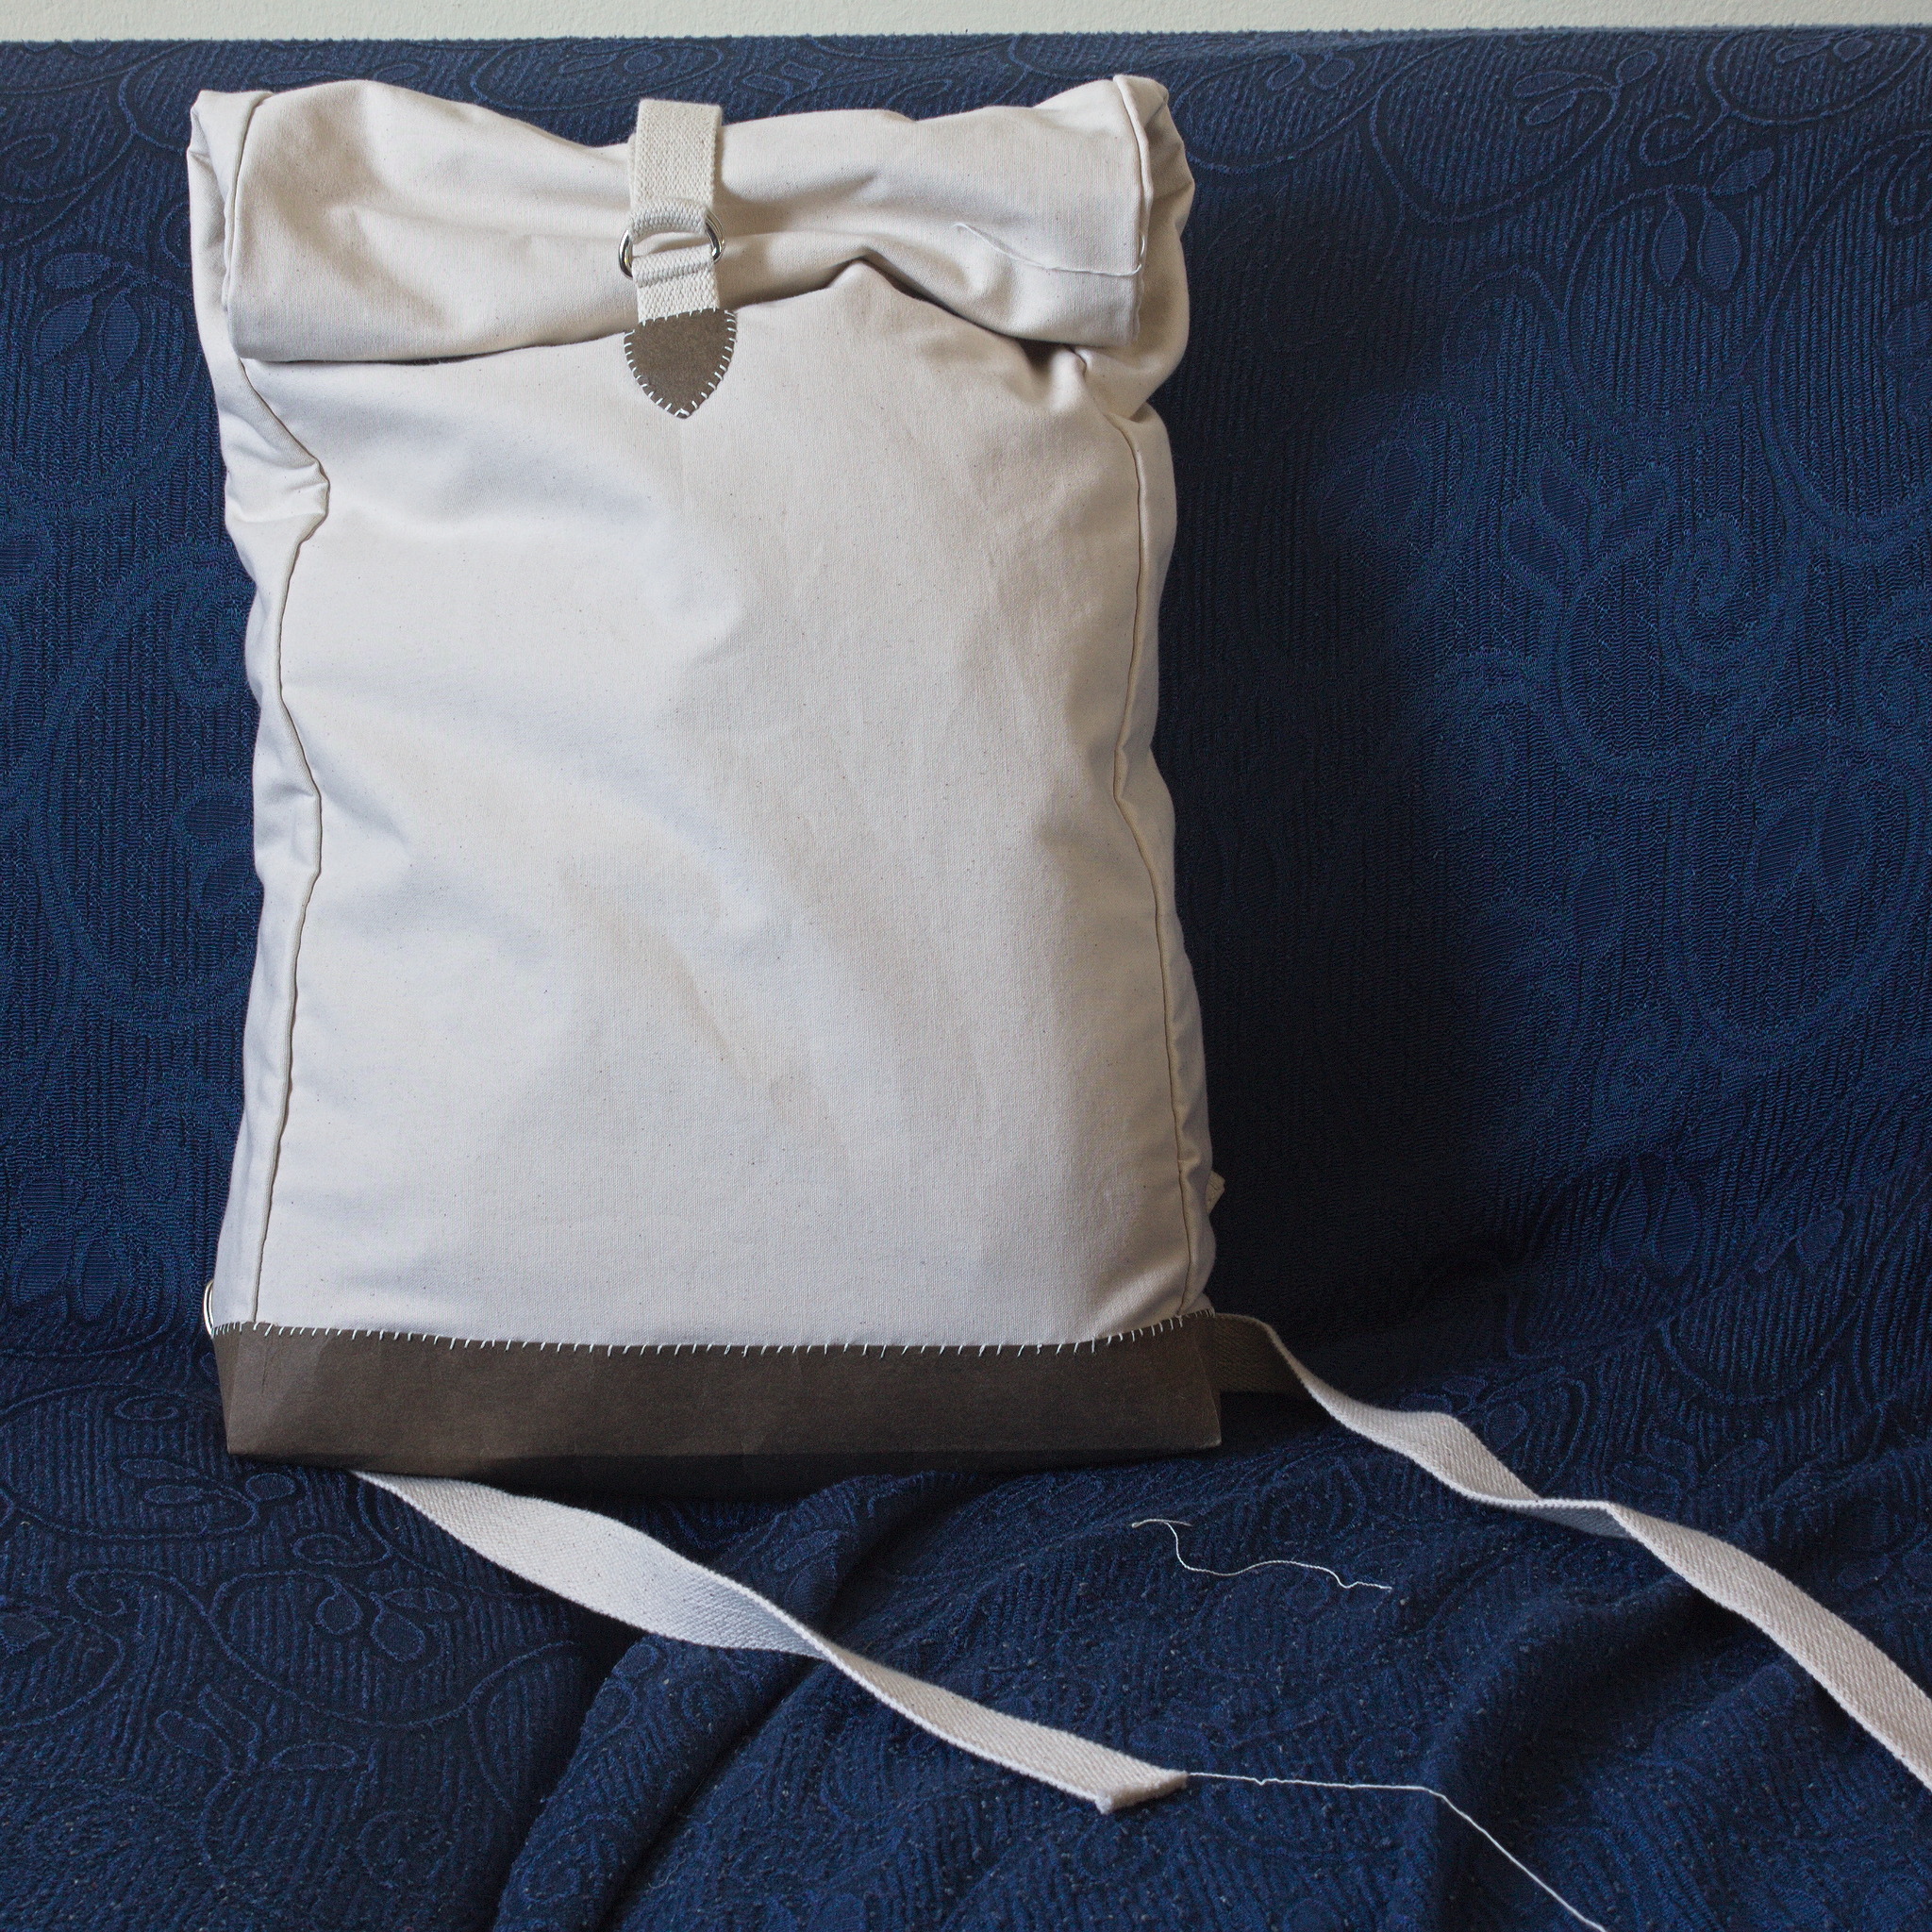
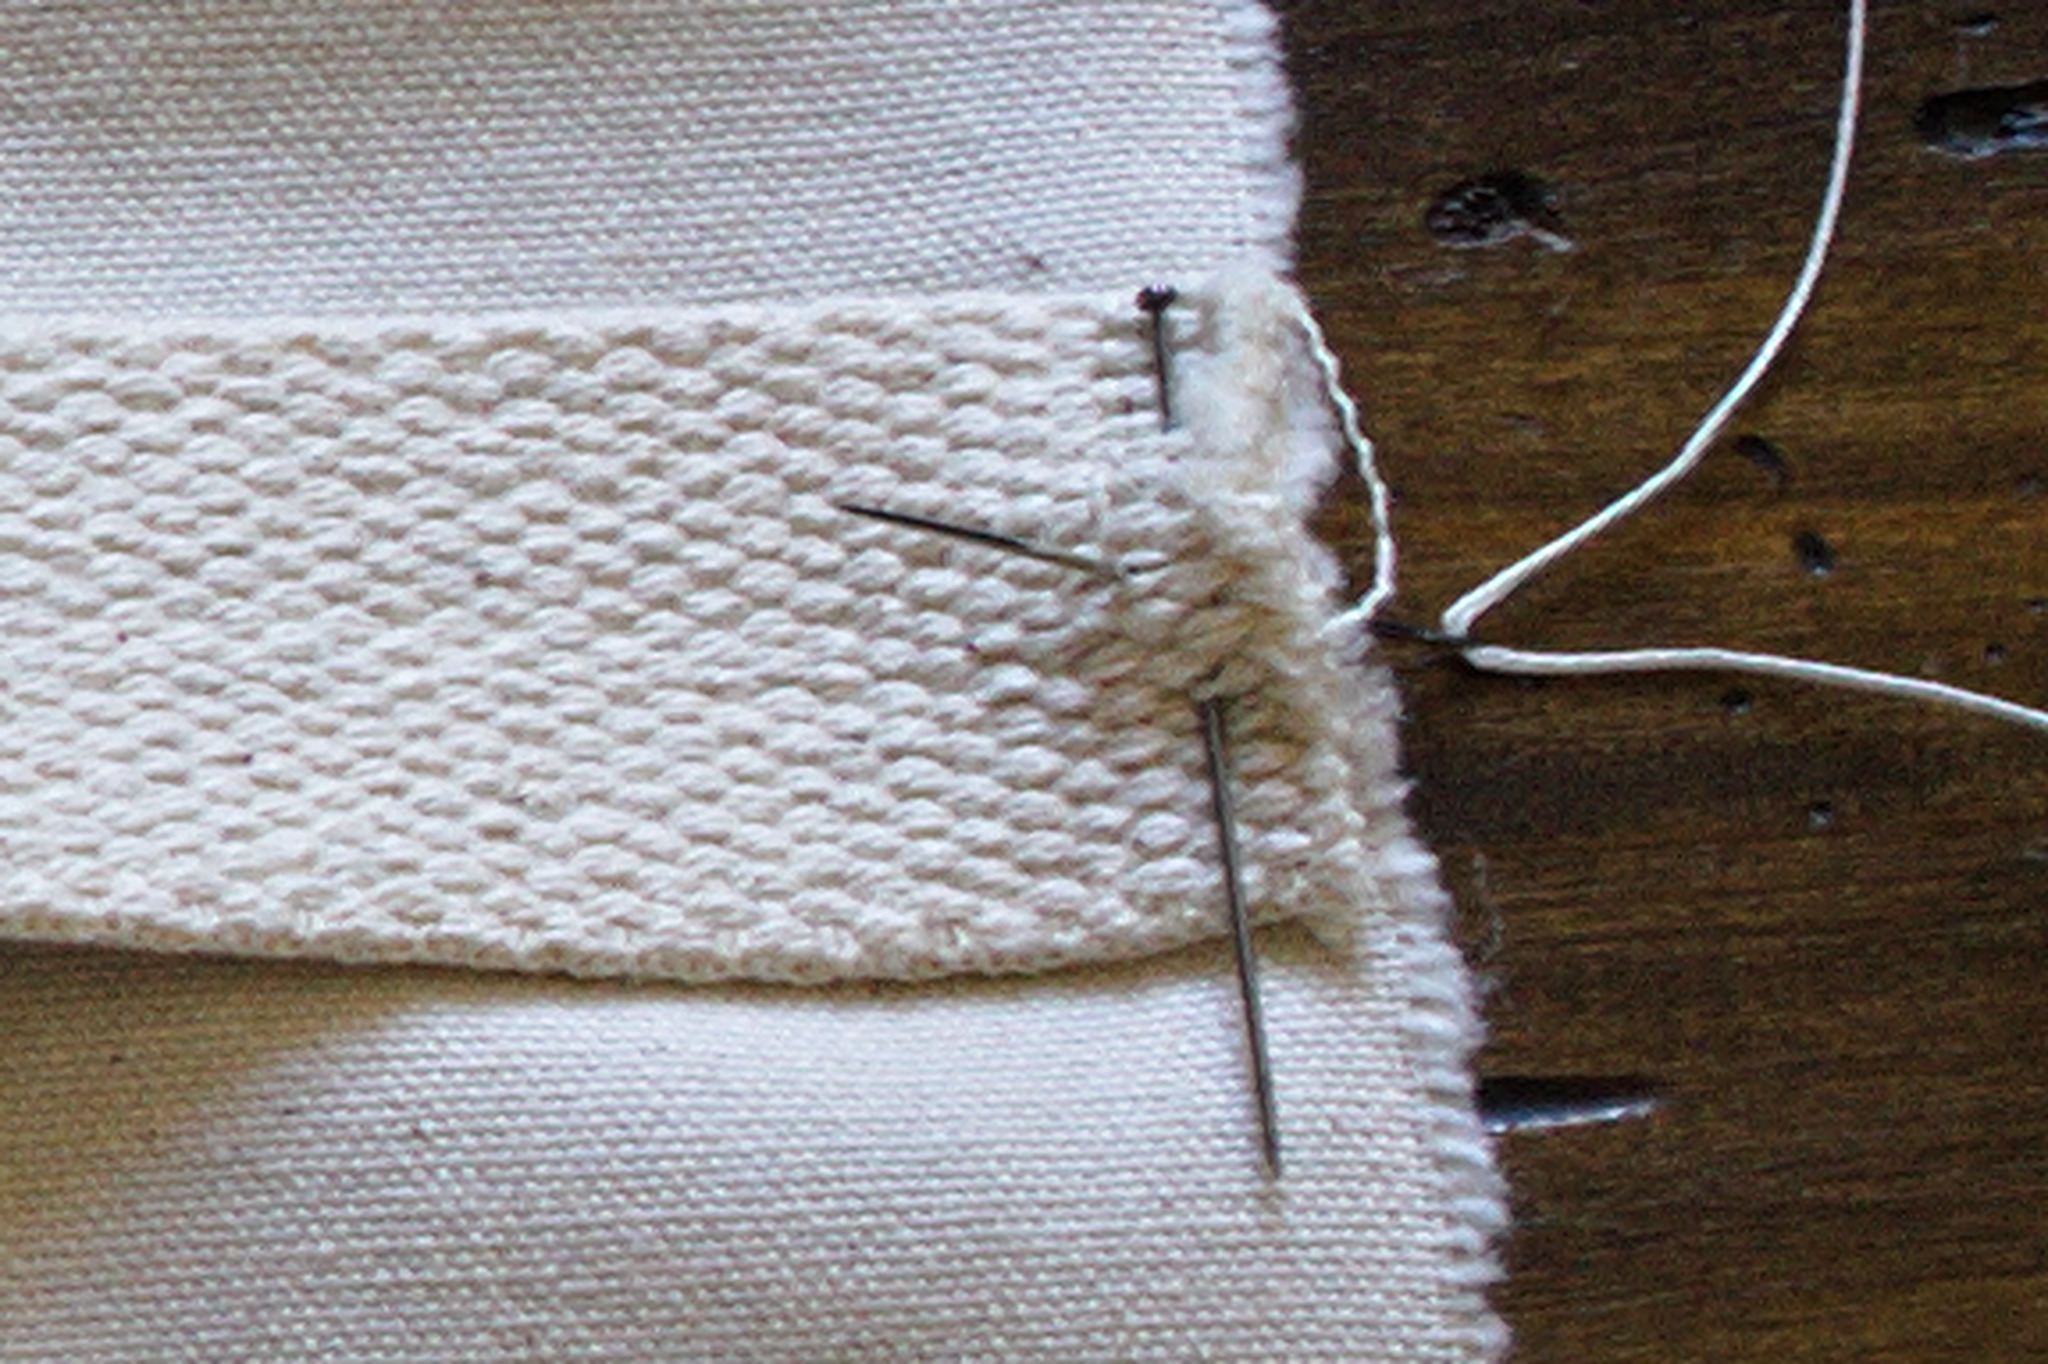
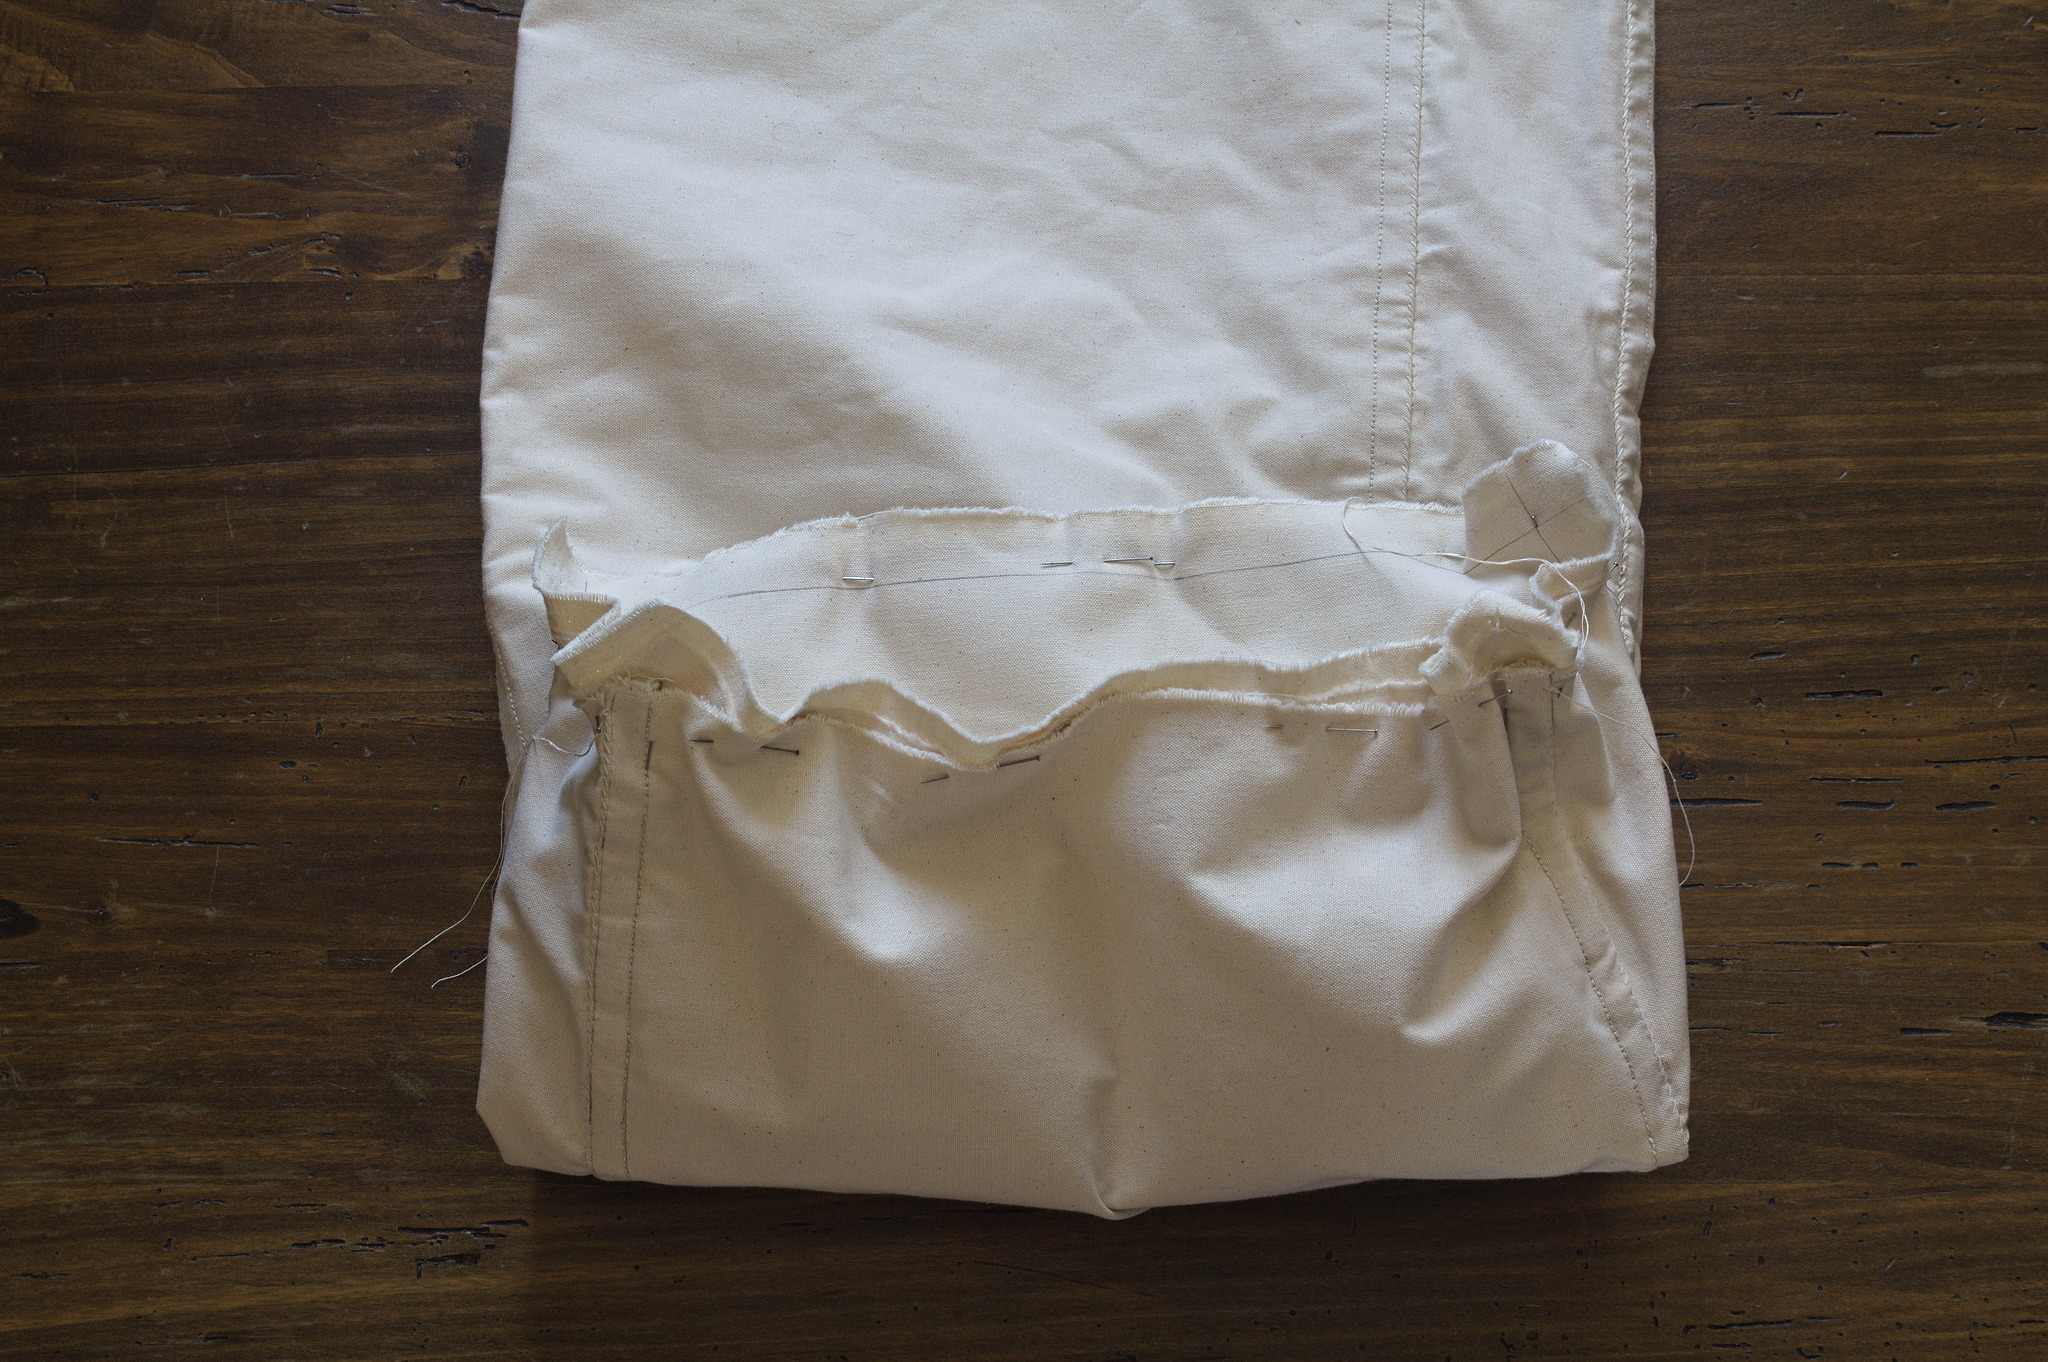
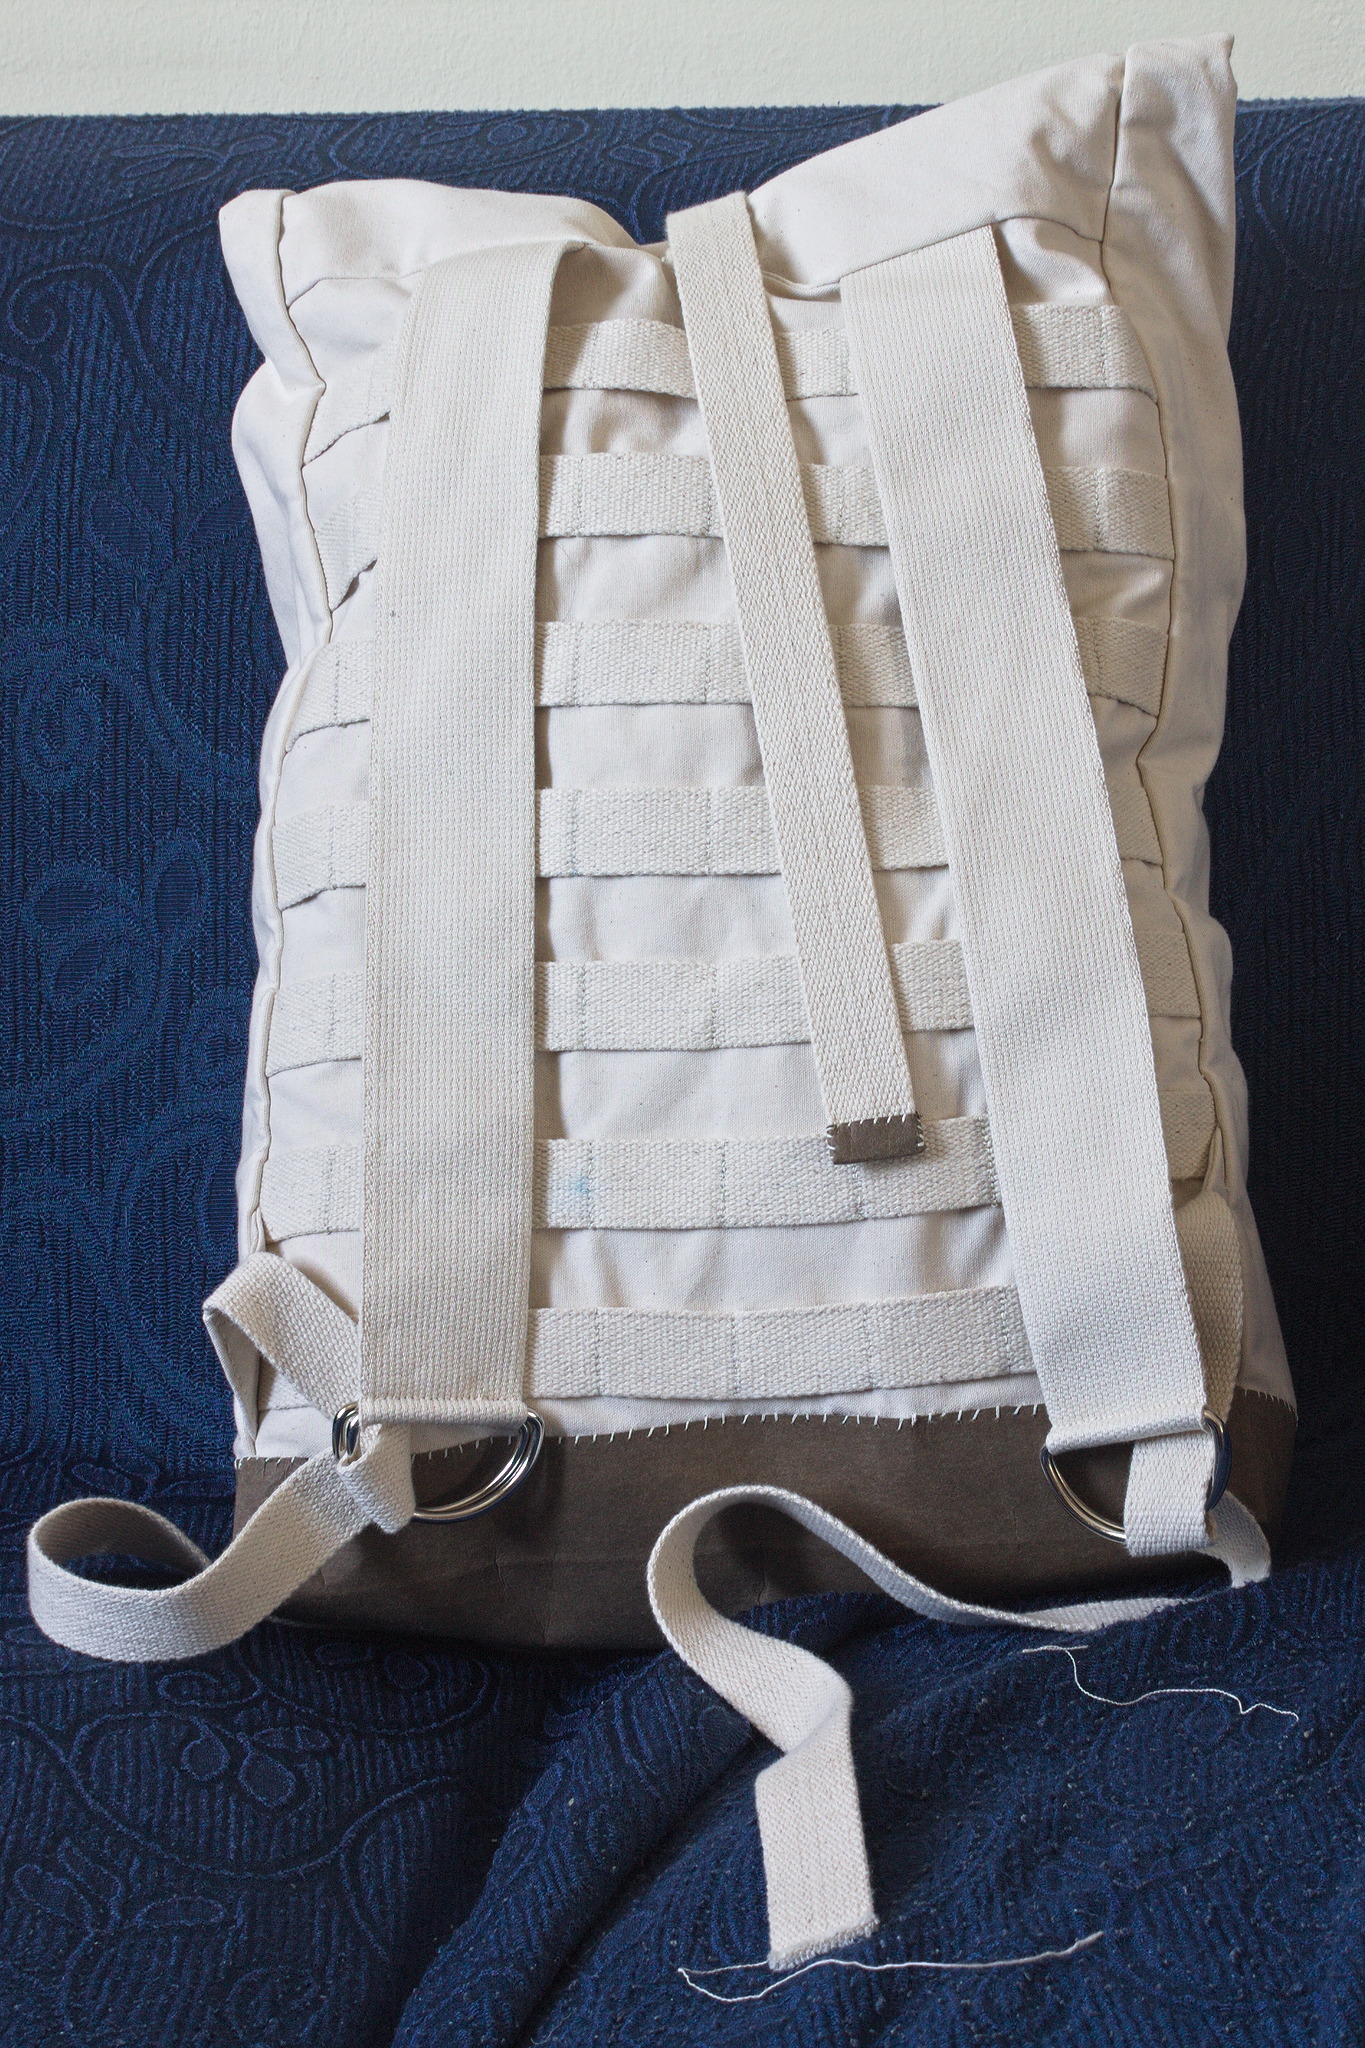
a backpack in a cream fabric with a short dark brown bottom; it closes by rolling down the top and is kept closed by a strap that feeds through two D-rings. I might be slightly insane? Or am I going to prove something about the nature and accessibility of sewing and MYOG1 as a hobby? I love my modular backpack, but it has a very modern look that is maybe not the best thing when otherwise dressed in historybounding dress, and it s also a bit bigger than I planned or needed it to be. So, when one of the shops I buy from had some waterproof cotton canvas on sale I failed my saving throw against temptations and bought a few meters, with the intent to make myself a backpack in a different style. It needs to be a backpack, because my back doesn t like asymmetrical bags2, and as far as I know 19th century backpacks weren t the most comfortable things, so I decided to go for a vaguely timeless roll top model that has the added advantage not to require a lot of hardware for the closure, just a few D-rings. Leather straps would look cool, but also require some tools that I still don t have, so I decided to look for some cotton webbing, and when I finally found some in 25 mm and 50 mm width I could finally start on the project. Except for one thing: thread. As much as I believe that regular n 50 cotton thread got a bad reputation from sellers who decided to cut quality in favour of profit, it is not up to the task of sewing a backpack. Nor that I d use regular sew-all poly thread either. I do have some of the thread I used for my other backpack, which would have been strong enough, but it s also in black, which isn t exactly the look I was aiming for on the natural / ecru colour of both the canvas and the webbing. I also misremembered it as only being available in that colour (it isn t), so I wasn t tempted into doing a full online order of technical materials just for that. On the other hand, I did have in my stash some strong thread I could trust for this job, in natural / ecru. There was only one problem: it was 33 2 Tex linen, and not suitable for the sewing machine. You can t handsew a backpack. Or can you? Of course it s going to be much slower, but I m still in a situation where I have more time and space for handsewing than I have for machine sewing. And as for strength, my perception is that for the same stitch length an handsewn backstitch is stronger than a machine lockstitch, or at least it is more effort to unpick (and thus harder to accidentally unravel if the thread breaks). And so I tried. And it worked. a needle coming straight up through layers of fabric and webbing, in the motion called stabbing. Having to backstitch everything instead of being able to use a running backstitch of course meant that it was slower than other sewing projects, and any time there were more than two layers of fabric I had to use the stabbing motion rather than the sewing one, which is even slower, but other than a few places with many layers of both fabric and webbing it wasn t hard. And to be fair, the seams were fewer and shorter than other sewing projects, and with the usual interruptions and uneven time availability it was done in less than a month, which is somewhat typical for one of my handsewn projects. the layers of the base pinned into the sides, trying to keep everything properly aligned especially on the corners in a way that would be very messy if fed as-is to a sewing machine. It may have been because of the pattern, but I think it s relevant that it was also easier than other backpacks I ve made, with significantly less cursing, even when doing seams that would have been quite fiddly when sewn by machine. I have to admit that now I m tempted to plan another backpack using the same pattern or a slight variation, sewn by machine in a different fabric, to see the difference in the time it takes and to check if the changes I think would make it easier to sew by machine are actually the right thing to do. But maybe I ll wait a bit, other projects are in the queue. The pattern is as usual online, released as #FreeSoftWear. Having used it for a while, I have to say that it is just the right size to fit all the things I usually carry, The fact that it only opens from the top means that finding things that have fallen to the very bottom involves a bit of rummaging, but not having to change a zipper every few years when (not if) it breaks is also very nice, so I m not sure which shape of backpack I prefer. the back of the backpack, showing the shoulder straps made with wide webbing that end in two D-rings, and a pattern of horizontal webbing sewn at 4 cm intervals to attach accessories. The soft back of course is an issue when the backpack is filled with small items, but the molle webbing is there exactly because I have plans to solve it, beside the trivial put something flat towards the back . As an object, I m happy with the result. As a project, it was way more than successful, exceeding all expectations, especially for something somewhat experimental like this one was.

  1. Make Your Own Gear, i.e. sewing or otherwise constructing outdoorish equipment.
  2. at least not if I fill them with stuff as I usually do with my backpack :D

24 July 2025

Valhalla's Things: Things I Have Learnt At DebConf

Posted on July 24, 2025
Tags: madeof:bits
An unsorted list, including some I already knew, but was reminded of.
  • dpkg-mergechangelogs exists.
  • Sewing your own shirt, posting it on planet and wearing it on the first day of DebConf, is more effective than a badge for making people recognise you.
  • I need to look into a number of tools for testings things (and try to start using some of those at $DAYJOB).
  • Masks are good. masks protect you from debbugs. masks protect you from ring cameras in the hotel you re staying on the day after debconf.
  • It s really nice to be chatting of random topics during lunch and discover that you are talking to the maintainer of a package of which you are one of the very few users! (the latter bit needs to be changed :) ).
  • I need to look into sequoia and all of the modern OpenPGP stuff.
  • Even if I don t have a lot of money, apparently I have even less sense (there will be blog posts on the topic in the mid-term future).
  • I can go to a talk about AI and not hate the speaker (yeah, the bar is pretty low there :D ). The automatic subtitles still failed in the same way as automatic subtitles always fail.
  • Debian gets used in really cool places.
  • At times it is a bit or a lot dysfunctional, but Debian still feels like a family.
And I still haven t watched the recordings of those talks that I couldn t (or decided not to, because the hallway track was more interesting) attend.

23 July 2025

Peter Pentchev: Ringlet software updates (2025-03-23)

Ringlet software updates (2025-03-23)Recent initial releases of [Ringlet software][r-site] (a fancy name for my pet projects):

Abhijith PA: Removing spams from your local maildir

I have been using Disroot as my primary email ever since openmailbox.org stopped. I am very grateful for Disroot s service and I occasionally donate to them. Recently, my Disroot inbox has been flooded with spam. On an average day, I used to receive around 90% spams on entire email count. However, the situation has improved since then. I contacted the Disroot team, and they informed me that they are aware of the situation and planning to migrate to Rspamd from Spamassassin. I don t know whether they deployed Rspamd, even if so that only going to process incoming mails, I am looking for a way to identify spams and purge that are already entered my Imap folders. Later I found this script nh2/rspamd-move[1], which seems fit my need. I made couple of trivial changes in the script for my use case. I wasn t sure of directly running this on my Mail/ dir, so I cloned my entire local mail directory to another directory and made available to podman container where I script and rspamd instance exist. I trained rspamd from the /Spam. Later, I manually moved couple of mails to /spam folder/. I requested friends to share their spam folder in the #debian-in channel, but that didn t happen :P
$podman run -it --mount
type=bind,source=/home/abhijith/$MAILS/,target=/container-mail-clone
id:latest
$script.py
(It took some time since I have around 10000+ emails) Wow, it was quite a successful attempt, I was able to catch most of it and move to spam/ and couple of false positive in a different folder. Now I want to do the same in the actual maildir yet very skeptical. While going through the cloned folder with mutt -f I remembered that the mails are already indexed by notmuch. So all I need to do is operate tagging and deletion with notmuch and it will be synced back to the original mail dir. Ta-da. I cleaned by Inbox. [1] - https://github.com/nh2/rspamd-move

Russell Coker: Annoying Wrongness on TV

One thing that annoys me on TV shows and movies is getting the details wrong. Yes it s fiction and yes some things can t be done correctly and in some situations correctly portraying things goes against the plot. But otherwise I think they should try to make it accurate. I was just watching The Americans (a generally good show that I recommend watching) and in Season 4 Episode 9 there s a close up of a glass of wine which clearly shows that the Tears of Wine effect is missing, the liquid in the glass obviously has the surface tension of water not of wine. When they run a show about spies then have to expect that the core audience will be the type of detail oriented people who notice these things. Having actors not actually drink alcohol on set is a standard practice, if they have to do 10 takes of someone drinking a glass of wine then that would be a problem if they actually drank real wine. But they could substitute real wine for the close up shots and of course just getting it right the first time is a good option. Some ridiculous inaccuracy we just need to deal with, like knives making a schwing sound when pulled out of scabbards and silenced guns usually still being quite loud (so many people are used to it being wrong). Organisations like the KGB had guns that were actually silent, but they generally looked obviously different to regular guns and had a much lower effective range. The gold coins shown on TV are another ridiculous thing. The sound of metal hitting something depends on how hard it is and how dense it is. Surely most people have heard the sounds of dropping steel nuts and ball bearings and the sound of dropping lead sinkers and knows that the sounds of items of similar size and shape differ greatly based on density and hardness. A modern coin made of copper, cupro-nickel (the current silver coins), or copper-aluminium (the current gold coins) sounds very different to a gold coin when dropped on a bench. For a show like The Witcher it wouldn t be difficult to make actual gold coins of a similar quality to iron age coin production, any jeweller could make the blanks and making stamps hard enough to press gold isn t an engineering challenge (stamping copper coins would be much more difficult). The coins used for the show could be sold to fans afterwards. Once coins are made they can t be just heaped up. Even if you are a sorcerer you probably couldn t fill a barrel a meter high with gold coins and not have it break from the weight and/or have the coins at the bottom cold welded. Gold coins are supposed to have a precise amount of gold and if you pile them up too high then the cold welding process will transfer gold between coins changing the value. If someone was going to have a significant quantity of gold stored then it would be in gold ingots with separators between layers to prevent cold welding. Movies tend not to show coins close up, I presume that s because they considered it too difficult to make coins and they just use some random coins from their own country. Another annoying thing is shows that don t match up the build dates of objects used. It s nice when they get it right like the movie Titanic featuring a M1911 pistol which is something that a rich person in 1912 would likely have. The series Carnival Row (which I recommend) has weapons that mostly match our WW1 era, everything that doesn t involve magic seems legit. One of the worst examples of this is the movie Anna (by Luc Besson which is mostly a recreation of his film Nikita but in the early 90s and with the KGB). That film features laptops with color screens and USB ports before USB was invented and when color screens weren t common on laptops, as an aside military spec laptops tend to have older designs than consumer spec ones. I ve mostly given up on hoping that movies will get hacking scenes that are any more accurate than knives making a schwing sound. But it shouldn t be that hard for them to find computer gear that was manufactured in the right year to use for the film. Why can t they hire experts on technology to check everything?

22 July 2025

Iustin Pop: Watching website scanning bots

Ever since I put up http://demo.corydalis.io, and setup logcheck, I m inadvertently keeping up with recent exploits in common CMS frameworks, or maybe even normal web frameworks issues, by seeing what 404s I get from the logs. Now, I didn t indent to do this per se, I just wanted to make sure I don t have any 500s, and at one point, I did actually catch a bug by seeing seemingly valid URLs, with referrer my own pages, leading to 404s. But besides that, it s mainly a couple times per week, a bot finds the site, and then it tries in fast succession something like this (real log entries, with the source IP address removed):
[21/Jul/2025:09:27:09 +0200] "GET /pms?module=logging&file_name=../../../../../../~/.aws/credentials&number_of_lines=10000 HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:11 +0200] "GET /admin/config?cmd=cat+/root/.aws/credentials HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:11 +0200] "GET /.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:13 +0200] "GET /.env.local HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:13 +0200] "GET /.env.production HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:16 +0200] "GET /.env.dev HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:17 +0200] "GET /.env.development HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:19 +0200] "GET /.env.prod HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:19 +0200] "GET /.env.stage HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:22 +0200] "GET /.env.test HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:23 +0200] "GET /.env.example HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:25 +0200] "GET /.env.bak HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:26 +0200] "GET /.env.old HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:28 +0200] "GET /.envs/.production/.django HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:28 +0200] "GET /blog.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:31 +0200] "GET /wp-content/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:32 +0200] "GET /application/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:34 +0200] "GET /app/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:35 +0200] "GET /apps/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:37 +0200] "GET /config/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:38 +0200] "GET /config/config.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:40 +0200] "GET /config/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:41 +0200] "GET /api/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:43 +0200] "GET /vendor/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:44 +0200] "GET /backend/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:46 +0200] "GET /server/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:46 +0200] "GET /home/user/.aws/credentials HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:49 +0200] "GET /aws/credentials HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:50 +0200] "GET /.aws/credentials HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:52 +0200] "GET /.aws/config HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:52 +0200] "GET /config/aws.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:55 +0200] "GET /config/aws.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:55 +0200] "GET /.env.production HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:58 +0200] "GET /config.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:59 +0200] "GET /config/config.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:01 +0200] "GET /config/settings.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:02 +0200] "GET /config/secrets.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:04 +0200] "GET /config.yaml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:04 +0200] "GET /config.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:07 +0200] "GET /config.py HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:08 +0200] "GET /secrets.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:10 +0200] "GET /secrets.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:11 +0200] "GET /credentials.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:13 +0200] "GET /.git-credentials HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:14 +0200] "GET /.git/config HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:16 +0200] "GET /.gitignore HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:18 +0200] "GET /.gitlab-ci.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:19 +0200] "GET /.github/workflows HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:22 +0200] "GET /.idea/workspace.xml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:22 +0200] "GET /.vscode/settings.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:25 +0200] "GET /docker-compose.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:25 +0200] "GET /docker-compose.override.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:28 +0200] "GET /docker-compose.prod.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:28 +0200] "GET /docker-compose.dev.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:32 +0200] "GET /phpinfo HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:32 +0200] "GET /_profiler/phpinfo HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:34 +0200] "GET /phpinfo.php HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:34 +0200] "GET /info.php HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:37 +0200] "GET /storage/logs/laravel.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:37 +0200] "GET /storage/logs/error.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:40 +0200] "GET /logs/debug.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:40 +0200] "GET /logs/app.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:49 +0200] "GET /debug.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:51 +0200] "GET /error.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:53 +0200] "GET /.DS_Store HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:55 +0200] "GET /backup.zip HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:58 +0200] "GET /.backup HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:29:00 +0200] "GET /db.sql HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:29:03 +0200] "GET /dump.sql HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:29:06 +0200] "GET /database.sql HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:29:09 +0200] "GET /backup.tar.gz HTTP/1.1" 404 - "" "Mozilla/5.0"
Now, this example is actually trying to catch a bit more things, but many times it s focused on some specific thing, or two things. Here we have docker, MacOS .DS_Store (I m not sure how that s useful - to find more filenames?), VSCode settings, various secrets, GitHub workflows, log output, database dumps, AWS credentials, and still I guess from the wp filename WordPress settings. The first few years were full of WordPress scanners, now it seems it has quieted down, I haven t seen a bot scanning 200 WP potential filenames in ages. And this bot even bothers to put in Mozilla/5.0 as browser identification . Side-note: I don t think the filename path in the first log entry, i.e. ../../../../../../~/, ever properly resolves to the home directory of any user. So I m not that particular scanner ever works, but who knows? Maybe some framework does bad tilde expansion, but at least bash will not expand ~ inside a path, it seems that path is passed as-is to an invoked command (strace confirms it). What s surprising here is that these are usually plain dumb scanners, from the same IP address, no concern on throttling, no attempt to hide, just 2 minutes of brute-forcing a random list of known treasures , then moving on. For this to be worth, it means there are still victims found using this method, sadly. Well, sometimes I get a single, one-off "GET /wp-login.php HTTP/1.1, which is strange enough it might not be a bot even, who knows. But in general, periods of activity of this type are coming and going, probably aligned with new CVEs. And another surprising thing is that for this type of scanning to work (and I ve seen many over the years), the website framework/configuration must allow random file download. Corydalis itself is written in Haskell, using Yesod, and it has a hardcoded (built at compile time) list of static resources it will serve. I haven t made the switch to fully embedding in the binary, but at that point, it won t need to read from the filesystem at all. Right now it will serve a few CSS and JS files, plus fonts, but that s it, no arbitrary filesystem traversal. Strange that some frameworks allow it. This is not productively spent time, but it is fun, especially seeing how this changes over time. And probably the most use anyone gets out of http://demo.corydalis.io .

David Bremner: Hibernate on the pocket reform 9/n

Context Sidequest: Install u-boot-menu Don't be like me and reboot without configuring u-boot-menu. Although the defaults make sense for most people, in my case I lost access to the serial console (because that custom config needed to be re-done), and the default delay was not enough to choose a backup kernel. In consfigurator notation:
  (on-change
      (file:has-content "/etc/u-boot-menu/conf.d/reform.conf"
        '("U_BOOT_TIMEOUT=50"
          "U_BOOT_PARAMETERS=\"ro no_console_suspend cryptomgr.notests \\$ bootargs  console=ttyS2,1500000 keep_bootcon console=tty1\""))
    (cmd:single "u-boot-update"))

The panel, alive.
  • Thanks to a hint from joschc (and a bit of luck) I realized the
    issue I filed was nonsense. Yay?
  • The panel driver is not added by the rk3588 patches (since the build process applies all the patches, this is not a problem for building from reform-debian-packages).
  • After applying the two patches in reform-debian-packages/linux/patches6.15/imx8mp-mnt-pocket-reform/pocket-panel, the patched 6.16 kernel boots, and seems to work, including the panel.
  • The updated source is on branch reform-patches at https://salsa.debian.org/bremner/collabora-rockchip-3588
  • Unsurprisingly hibernate is not working out of the box with 6.16. My next mission is to apply the recommended pci-reset patches on top of 6.16.
previous episode next episode

21 July 2025

Jonathan Dowland: Nine Inch Nails, Paris, 2025-07-07

On July 7th I did a quick one-day trip to Paris to watch Nine Inch Nails, who were performing one of their last shows for the European leg of the tour. I'd missed all the UK dates, which were announced after I was committed to a family holiday. The setup for these shows differs a lot from the norm. First, the support act was German-Iraqi techno DJ Boys Noize, who TR&AR had collaborated with on their soundtrack for the recent movie Challengers. BN did a 75-minute opening set:
Stripped down Set 1 Stripped down Set 1
The main gig was divided into four acts. Act 1 took place on a square "B Stage", situated in the middle of the main floor. Trent and 2-3 band members performed three stripped-down songs, with interpolations to other songs, alternative lyrics, and the like. I enjoyed this section more than I expected to.
Main stage lighting Main stage lighting
They then transition to the main stage for a six-song full-band set. The main stage was draped in layers of transparent curtains. One of the team was on-stage, walking around with a video camera, and the live camera footage was processed and projected onto the curtains in realtime. The visuals were truly fantastic. For the third act, Trent and Atticus returned to the B stage, to be joined by Boys Noize, who then performed four songs in a reworked, remixed, electronic dance format. This ended up being the highlight of the gig for me. I felt the reworkings breathed new life into some old songs.
remix Set 3 remix Set 3
Finally, back to the main stage to close out with a final seven songs. The traditional triad of closers was adjusted, substituting "The Hand That Feeds" for "The Perfect Drug"; a song that wasn't played at all from 1997 to 2018, and has now become a regular fixture. Several tapers recorded the show, and their recordings are up at nin.live. Overall it was great fun: I ended up flying via London and the airport time was a bit of a pain, but I did get a good start on my corrections. I was home the next afternoon. I'm trying not to think of the cost.

20 July 2025

Michael Prokop: What to expect from Debian/trixie #newintrixie

Trixie Banner, Copyright 2024 Elise Couper Update on 2025-07-28: added note about Debian 13/trixie support for OpenVox (thanks, Ben Ford!) Debian v13 with codename trixie is scheduled to be published as new stable release on 9th of August 2025. I was the driving force at several of my customers to be well prepared for the upcoming stable release (my efforts for trixie started in August 2024). On the one hand, to make sure packages we care about are available and actually make it into the release. On the other hand, to ensure there are no severe issues that make it into the release and to get proper and working upgrades. So far everything is looking pretty well and working fine, the efforts seemed to have payed off. :) As usual with major upgrades, there are some things to be aware of, and hereby I m starting my public notes on trixie that might be worth for other folks. My focus is primarily on server systems and looking at things from a sysadmin perspective. Further readings As usual start at the official Debian release notes, make sure to especially go through What s new in Debian 13 + issues to be aware of for trixie (strongly recommended read!). Package versions As a starting point, let s look at some selected packages and their versions in bookworm vs. trixie as of 2025-07-20 (mainly having amd64 in mind):
Package bookworm/v12 trixie/v13
ansible 2.14.3 2.19.0
apache 2.4.62 2.4.64
apt 2.6.1 3.0.3
bash 5.2.15 5.2.37
ceph 16.2.11 18.2.7
docker 20.10.24 26.1.5
dovecot 2.3.19 2.4.1
dpkg 1.21.22 1.22.21
emacs 28.2 30.1
gcc 12.2.0 14.2.0
git 2.39.5 2.47.2
golang 1.19 1.24
libc 2.36 2.41
linux kernel 6.1 6.12
llvm 14.0 19.0
lxc 5.0.2 6.0.4
mariadb 10.11 11.8
nginx 1.22.1 1.26.3
nodejs 18.13 20.19
openjdk 17.0 21.0
openssh 9.2p1 10.0p1
openssl 3.0 3.5
perl 5.36.0 5.40.1
php 8.2+93 8.4+96
podman 4.3.1 5.4.2
postfix 3.7.11 3.10.3
postgres 15 17
puppet 7.23.0 8.10.0
python3 3.11.2 3.13.5
qemu/kvm 7.2 10.0
rsync 3.2.7 3.4.1
ruby 3.1 3.3
rust 1.63.0 1.85.0
samba 4.17.12 4.22.3
systemd 252.36 257.7-1
unattended-upgrades 2.9.1 2.12
util-linux 2.38.1 2.41
vagrant 2.3.4 2.3.7
vim 9.0.1378 9.1.1230
zsh 5.9 5.9
Misc unsorted apt The new apt version 3.0 brings several new features, including: systemd systemd got upgraded from v252.36-1~deb12u1 to 257.7-1 and there are lots of changes. Be aware that systemd v257 has a new net.naming_scheme, v257 being PCI slot number is now read from firmware_node/sun sysfs file. The naming scheme based on devicetree aliases was extended to support aliases for individual interfaces of controllers with multiple ports. This might affect you, see e.g. #1092176 and #1107187, the Debian Wiki provides further useful information. There are new systemd tools available: The tools provided by systemd gained several new options: Debian s systemd ships new binary packages: Linux Kernel The trixie release ships a Linux kernel based on latest longterm version 6.12. As usual there are lots of changes in the kernel area, including better hardware support, and this might warrant a separate blog entry. To highlight some changes with Debian trixie: See Kernelnewbies.org for further changes between kernel versions. Configuration management For puppet users, Debian provides the puppet-agent (v8.10.0), puppetserver (v8.7.0) and puppetdb (v8.4.1) packages. Puppet s upstream does not provide packages for trixie, yet. Given how long it took them for Debian bookworm, and with their recent Plans for Open Source Puppet in 2025, it s unclear when (and whether at all) we might get something. As a result of upstream behavior, also the OpenVox project evolved, and they already provide Debian 13/trixie support (https://apt.voxpupuli.org/openvox8-release-debian13.deb). FYI: the AIO puppet-agent package for bookworm (v7.34.0-1bookworm) so far works fine for me on Debian/trixie. Be aware that due to the apt-key removal you need a recent version of the puppetlabs-apt for usage with trixie. The puppetlabs-ntp module isn t yet ready for trixie (regarding ntp/ntpsec), if you should depend on that. ansible is available and made it with version 2.19 into trixie. Prometheus stack Prometheus server was updated from v2.42.0 to v2.53, and all the exporters that got shipped with bookworm are still around (in more recent versions of course). Trixie gained some new exporters: Virtualization docker (v26.1.5), ganeti (v3.1.0), libvirt (v11.3.0, be aware of significant changes to libvirt packaging), lxc (v6.0.4), podman (v5.4.2), openstack (see openstack-team on Salsa), qemu/kvm (v10.0.2), xen (v4.20.0) are all still around. Proxmox already announced their PVE 9.0 BETA, being based on trixie and providing 6.14.8-1 kernel, QEMU 10.0.2, LXC 6.0.4, OpenZFS 2.3.3. Vagrant is available in version 2.3.7, but Vagrant upstream does not provide packages for trixie yet. Given that HashiCorp adopted the BSL, the future of vagrant in Debian is unclear. If you re relying on VirtualBox, be aware that upstream doesn t provide packages for trixie, yet. VirtualBox is available from Debian/unstable (version 7.1.12-dfsg-1 as of 2025-07-20), but not shipped with stable release since quite some time (due to lack of cooperation from upstream on security support for older releases, see #794466). Be aware that starting with Linux kernel 6.12, KVM initializes virtualization on module loading by default. This prevents VirtualBox VMs from starting. In order to avoid this, either add kvm.enable_virt_at_load=0 parameter into kernel command line or unload the corresponding kvm_intel / kvm_amd module. If you want to use Vagrant with VirtualBox on trixie, be aware that Debian s vagrant package as present in trixie doesn t support the VirtualBox package version 7.1 as present in Debian/unstable (manually patching vagrant s meta.rb and rebuilding the package without Breaks: virtualbox (>= 7.1) is known to be working). util-linux The are plenty of new options available in the tools provided by util-linux: Now no longer present in util-linux as of trixie: The following binaries got moved from util-linux to the util-linux-extra package: And the util-linux-extra package also provides new tools: OpenSSH OpenSSH was updated from v9.2p1 to 10.0p1-5, so if you re interested in all the changes, check out the release notes between those versions (9.3, 9.4, 9.5, 9.6, 9.7, 9.8, 9.9 + 10.0). Let s highlight some notable behavior changes in Debian: There are some notable new features: Thanks to everyone involved in the release, looking forward to trixie + and happy upgrading!
Let s continue with working towards Debian/forky. :)

18 July 2025

Valhalla's Things: FreeSoftWear

Posted on July 18, 2025
Tags: madeof:bits, topic:debian, FreeSoftWear
There may have been a lightning talk. Things similar to the rest of this article may have been said. I think that most people in this room care about running Freely licensed software on their computers. Some probably would also like, when possible, to use Freely licensed hardware, or to enjoy Freely licensed art. And then there are very few people who decided that they d prefer to wear DFSG-Free clothing. If you make your own, it s not that different from software: you get a pattern, the source code, and compilation instructions. The compilation process is a bit manual, but there are a lot of people who enjoy that. It doesn t have to be sewing, it can be knitting, crochet, any craft that can be used to build something that you wear and has patterns or other kinds of source code. I d say that a certain tartan also qualifies. If you re interested in the idea, these are the places I know of that do FreeSoftWear: two are personal websites, included mine, freesewing is a community and an online platform to design patterns. And debian has some useful software, including valentina, for sewing patterns, and kxstitch for cross-stitch and other counted thread embroidery.

17 July 2025

Gunnar Wolf: About our proof-of-concept LLM tool for navigating Debian's manpages

So, for the first year, this year s DebConf had the DebConf Academic Track , that is, content for a one-day-long set of short sessions, for which of them there was a written article presenting the content often with a very academic format, but not necessarily. I hope that for future DebConfs we will continue to hold this track, and that we can help bridge the gap: to get people that are not usually from the academic / universitary prepare content that will be formally expressed and included in a long-lasting, indexed book of proceedings. We did have (informal) proceedings in many of the early DebConfs, and I m very happy to regain that, but with 20 years of better practices. Anyway, of course, I took the opportunity to join this experiment, and together with my Mexican colleague Tzolkin Gardu o who is finishing her PhD here in France (or should I say, second to her, as she is the true leading author of our work). And here you can see the paper we submitted to the DebConf Academic Track, which will be published soon: A retrieval-augmented-generation pipeline to help users query system-provided documentation The corresponding source code is all available at Tzolkin s repository in GitHub. So, what is it about, in shorter words and layman terms? Debian has lots of documentation, but lacks in discoverability. We targetted our venerable manpages: It is well known that manpages are relevant, well-organized documentation describing how to use each of the binaries we ship in Debian. Eric Raymond wrote in his well-known essay The Art of Unix Programming (2003) that the Unix cultural style is telegraphic but complete. It does not hold you by the hand, but it usualy points in the right direction. Our original intent was to digest all of the information in our manpages, but we narrowed it to only the first section of the manual due to the limitations of the hardware a good friend lent us to play with LLMs. We took four different base, redistributable (although, yes, non-DFSG-free) Large Language Models downloaded from HuggingFace (T5-small, MiniLM-L6-v2, BGE-small-en and Multilingual-e5-small), and trained them with the 34579 pages found inside /usr/share/man/man1 of all of the existing Debian packages. We did some interesting fine-tuning (for further details, please refer to the paper itself or to our GitHub repository. The idea is to present an interactive tool that udnerstand natural language queries, and answers with the specific manpage to which they better relate (I d like to say they answer best , but Tzolkin has repeatedly tried to correct my understanding of the resulting vectorial distances). I had prepared some images to present as interaction examples, but I ll wrap up this post with something even better So, this is what you would get with the following queries: We were happy to present like this. During DebCamp, however, I was able to devote some time to translating my client into a Web-accessible system. Do note that it s a bit brittle, and might break now and then. But you are welcome to play with it! Play with the Web interface for our RAG for Debian manuals! I find it worth sharing that, while we used quite a bit of GPU for the training (not too much a couple of nights on an old-although-powerful nVidia 1070 card lent to us by the Felipe Esquivel Fund for Science and Cultural Support), all querying takes place in the CPU, and I usually get between 0.1 and 0.3 seconds per query. My server s architecture is far from rock-solid, and it can break now and then but at least it should respawn upon failure And it should at least be available there for a couple of weeks into August. Anyway, this has been a very interesting journey getting my toes wet in the waters of LLM, and while current results are a bit crude, I think this can be made into an interesting tool for Debian exploration.

Birger Schacht: My first tag2upload upload

Following the DebConf25 talk by Ian Jackson tag2upload - upload simply by pushing a signed git tag I decided to use the quiet time during the day of the DayTrip on DebConf 25 to try out uploading a package using tag2upload. Given the current freeze a couple of the packages I maintainer have new releases waiting. I decided on uploading the new version of labwc to experimental. Labwc is a Wayland compositor based on the wlroots compositor library (the library that sway is using). Labwc is inspired by the Openbox window manager. The upstream team of Labwc released version 0.9.0 last week, the first version that is based on wlroots 0.19.x. Wlroots 0.19.x is also only available in experimental, so that was a good fit for trying an upload with tag2upload. I first used my usual workflow, going into my package repository, doing get fetch origin, checking out the tag of the new release and tagging that with git tag upstream/0.9.0. Then I bumped the version in the debian/experimental branch, adapted the debian/control file for the changed wlroots dependency, committed and built the package using git-buildpackage to check if it builds fine and there are no lintian errors. Then I moved on to look at tag2upload. As a starting point for using tag2upload I read the blogpost by Jonathan Carter My first tag2upload upload. It pointed me to one very important option of git debpush, namely the --baredebian option which I have to use because I use the bare Debian git layout. Given that the last upload of labwc I did was to unstable, I also had to add the --force=changed-suite. I also started right away to use the --tag-only option, because for my first tests I only wanted to have local changes and nothing pushed to anywhere. I also used the --dry-run option. This led to the following command:
> git debpush --baredebian --force=changed-suite --dry-run --tag-only
tags 0.9.0, upstream/0.9.0 all exist in this repository
tell me which one you want to make an orig.tar from: git deborig --just-print '--version=0.9.0-1' TAG
git-debpush: git-deborig failed; maybe try git-debpush --upstream=TAG
This was a bit confusing, because the error message talked about git-deborig, but I was using git-debpush. I also did not want to make an orig.tar! The --upstream option in the git-debpush(1) manual gave an explanation for this:
When pushing a non-native package, git-debpush needs a tag for the upstream part of your package. By default git-debpush asks git-deborig(1), which searches for a suitable tag based on the upstream version in debian/changelog.
So apparently git-debpush can not find out what the correct tag for the upstream version is, because git-deborig can not find out what the correct tag for the upstream version is. git-debpush simply calls git deborig --just-print --version="$version" in line 437. This fails because I initially created a second upstream/0.9.0 to the existing 0.9.0 release tag. I do this for git-buildpackage to find the upstream sources, but with multiple tags git-deborig is not sure which one is the tag it should use (although both point to the same commit). So I removed the upstream/0.9.0 tag and ran git debpush again and now there was no error message (besides the warning regarding the changed suite) but it also did not give an feedback about what is happening. So I tried without the --dry-run option. Again, no output whatsoever, other than the warning about the changed release, BUT my gnupg asked me for permission to sign via my yubikey! And when I looked at the list of tags, I saw that there is now a debian/0.9.0-1 tag that was not there before! Looking at the tag I saw that it was a tag in the format described in the tag2upload(5) manual page, containing the following lines:
labwc release 0.9.0-1 for experimental
[dgit distro=debian split --quilt=baredebian]
[dgit please-upload source=labwc version=0.9.0-1 upstream-tag=0.9.0 upstream=4beee3851f75b53afc2e8699c594c0cc222115bd]
and the tag was signed by me. The 4beee3851f75b53afc2e8699c594c0cc222115bd commit ID is the commit the 0.9.0 tag points to. Now that I had a signed commit tag in the correct format, I went to the labwc packaging repository on salsa and enabled the webhook to trigger the tag2upload service (I just saw that the documentation was updated and there is now a global webhook on salsa, so this step is not needed anymore). Finally I pushed the tags using git push --tags. I could also have used git-debpush for this step, but I d rather use git directly. I then looked at the tag2upload queue and saw how a worker built and uploaded the newest labwc release and I also got an email from the tag2upload service [tag2upload 275] uploaded labwc 0.9.0-1. And a couple of minutes later I got the confirmation that labwc 0.9.0-1 was accepted into experimental. Great! So, to conclude: for tag2upload to work we simply need a git tag in the correct format. The tag2upload service now gets triggered by every pushed tag on salsa but only acts on tags that adhere to the tag2upload(5) format. git-debpush is a simply bash script that creates such a tag and by default also pushes the tag. I think the script could be a bit more verbose, for example telling me that it created a tag and the name of that tag. I think the dependency on git-deborig is also a problem. I use git-buildpackage to build my packages and by default git-buildpacakge assumes upstream tags are of the form upstream/%(version)s (source). I could now change that for all the packages I maintain, but I also think it makes sense to control the tag myself and not use a tag that is controlled by upstream. Upstream could change or delete that tag or I might need to create a tag for a version that is not tagged by upstream. I also think git-debpush is a rather mileading command name, given that the main task of the script is to create a tag in the correct format. Other than that, I m pretty happy about this service. I have a rather crappy uplink at home and it is not so uncommon for my uploads to fail because the connection dropped during dput. Using a simple git based upload approach makes these problems a thing of the past. I might look into other ways to create the needed tag, though.

Otto Kek l inen: Debcraft Easiest way to modify and build Debian packages

Featured image of post Debcraft   Easiest way to modify and build Debian packagesDebian packaging is notoriously hard. Far too many new contributors give up while trying, and many long-time contributors leave due to burnout from having to do too many thankless maintenance tasks. Some just skip testing their changes properly because it feels like too much toil. Debcraft is my attempt to solve this by automating all the boring stuff, and making it easier to learn the correct practices and helping new and old packagers better track changes in both source code and build artifacts.

The challenge of declarative packaging code Unlike how rpm or apk packages are done, the deb package sources by design avoid having one massive procedural packaging recipe. Instead, the packaging is defined in multiple declarative files in the debian/ subdirectory. For example, instead of a script running install -m 755 bin/btop /usr/bin/btop there is a file debian/btop.install containing the line usr/bin/btop. This makes the overall system more robust and reliable, and allows, for example, extensive static analysis to find problems without having to build the package. The notable exception is the debian/rules file, which contains procedural code that can modify any aspect of the package build. Almost all other files are declarative. Benefits include, among others, that the effect of a Debian-wide policy change can be relatively easily predicted by scanning what attributes and configurations all packages have declared. The drawback is that to understand the syntax and meaning of each file, one must understand which build tools read which files and traverse potentially multiple layers of abstraction. In my view, this is the root cause for most of the perceived complexity.

Common complaints about .deb packaging Related to the above, people learning Debian packaging frequently voice the following complaints:
  • Debian has too many tools to learn, often with overlapping or duplicate functionality.
  • Too much outdated and inconsistent documentation that makes learning the numerous tools needlessly hard.
  • Lack of documentation of the generally agreed best practices, mainly due to Debian s reluctance as a project to pick one tool and deprecate the alternatives.
  • Multiple layers of abstraction and lack of clarity on what any single change in the debian/ subdirectory leads to in the final package.
  • Requirement of Debian packages to be developed on a Debian system.

How Debcraft solves (some of) this Debcraft is intentionally opinionated for the sake of simplicity, and makes heavy use of git, git-buildpackage, and most importantly Linux containers, supporting both Docker and Podman. By using containers, Debcraft frees the user from the requirement of having to run Debian. This makes .deb packaging more accessible to developers running some other Linux distro or even Mac or Windows (with WSL). Of course we want developers to run Debian (or a derivative like Ubuntu) but we want them even more to build, test and ship their software as .deb. Even for Debian/Ubuntu users having everything done inside clean hermetic containers of the latest target distribution version will yield more robust, secure and reproducible builds and tests. All containers are built automatically on-the-fly using best practices for layer caching, making everything easy and fast. Debcraft has simple commands to make it easy to build, rebuild, test and update packages. The most fundamental command is debcraft build, which will not only build the package but also fetch the sources if not already present, and with flags such as --distribution or --source-only build for any requested Debian or Ubuntu release, or generate source packages only for Debian or PPA upload purposes. For ease of use, the output is colored and includes helpful explanations on what is being done, and suggests relevant Debian documentation for more information. Most importantly, the build artifacts, along with various logs, are stored in separate directories, making it easy to compare before and after to see what changed as a result of the code or dependency updates (utilizing diffoscope among others). While the above helps to debug successful builds, there is also the debcraft shell command to make debugging failed builds significantly easier by dropping into a shell where one can run various dh commands one-by-one. Once the build works, testing autopkgtests is as easy as running debcraft test. As with all other commands, Debcraft is smart enough to read information like the target distribution from the debian/changelog entry. When the package is ready to be released, there is the debcraft release command that will create the Debian source package in the correct format and facilitate uploading it either to your Personal Package Archive (PPA) or if you are a Debian Developer to the official Debian archive.

Automatically improve and update packages Additionally, the command debcraft improve will try to fix all issues that are possible to address automatically. It utilizes, among others, lintian-brush, codespell and debputy. This makes repetitive Debian maintenance tasks easier, such as updating the package to follow the latest Debian policies. To update the package to the latest upstream version there is also debcraft update. It will read the package configuration files such as debian/gbp.conf and debian/watch and attempts to import the latest upstream version, refresh patches, build and run autopkgtests. If everything passes, the new version is committed. This helps automate the process of updating to new upstream versions.

Try out Debcraft now! On a recent version of Debian and Ubuntu, Debcraft can be installed simply by running apt install debcraft. To use Debcraft on some other distribution or to get the latest features available in the development version install it using:
git clone https://salsa.debian.org/debian/debcraft.git
cd debcraft
make install-local
To see exact usage instructions run debcraft --help.

Contributions welcome Current Debcraft version 0.5 still has some rough edges and missing features, but I have personally been using it for over a year to maintain all my packages in Debian. If you come across some issue, feel free to file a report at https://salsa.debian.org/debian/debcraft/-/issues or submit an improvement at https://salsa.debian.org/debian/debcraft/-/merge_requests. The code is intentionally written entirely in shell script to keep the barrier to code contribution as low as possible.
By the way, if you aspire to become a Debian Developer, and want to follow my examples in using state-of-the-art tooling and collaborate using salsa.debian.org, feel free to reach out for mentorship. I am glad to see more people contribute to Debian!

Arnaud Rebillout: Acquire-By-Hash for APT packages repositories, and the lack of it in Kali Linux

This is a lenghty blog post. It features a long introduction that explains how apt update acquires various files from a package repository, what is Acquire-By-Hash, and how it all works for Kali Linux: a Debian-based distro that doesn't support Acquire-By-Hash, and which is distributed via a network of mirrors and a redirector. In a second part, I explore some "Hash Sum Mismatch" errors that we can hit with Kali Linux, errors that would not happen if only Acquire-By-Hash was supported. If anything, this blog post supports the case for adding Acquire-By-Hash support in reprepro, as requested at https://bugs.debian.org/820660. All of this could have just remained some personal notes for myself, but I got carried away and turned it into a blog post, dunno why... Hopefully others will find it interesting, but you really need to like troubleshooting stories, packed with details, and poorly written at that. You've been warned! Introducing Acquire-By-Hash Acquire-By-Hash is a feature of APT package repositories, that might or might not be supported by your favorite Debian-based distribution. A repository that supports it says so, in the Release file, by setting the field Acquire-By-Hash: yes. It's easy to check. Debian and Ubuntu both support it:
$ wget -qO- http://deb.debian.org/debian/dists/sid/Release   grep -i ^Acquire-By-Hash:
Acquire-By-Hash: yes
$ wget -qO- http://archive.ubuntu.com/ubuntu/dists/devel/Release   grep -i ^Acquire-By-Hash:
Acquire-By-Hash: yes
What about other Debian derivatives?
$ wget -qO- http://http.kali.org/kali/dists/kali-rolling/Release   grep -i ^Acquire-By-Hash:   echo not supported
not supported
$ wget -qO- https://archive.raspberrypi.com/debian/dists/trixie/Release   grep -i ^Acquire-By-Hash:   echo not supported
not supported
$ wget -qO- http://packages.linuxmint.com/dists/faye/Release   grep -i ^Acquire-By-Hash:   echo not supported
not supported
$ wget -qO- https://apt.pop-os.org/release/dists/noble/Release   grep -i ^Acquire-By-Hash:   echo not supported
not supported
Huhu, Acquire-By-Hash is not ubiquitous. But wait, what is Acquire-By-Hash to start with? To answer that, we have to take a step back and cover some basics first. The HTTP requests performed by 'apt update' What happens when one runs apt update? APT first requests the Release file from the repository(ies) configured in the APT sources. This file is a starting point, it contains a list of other files (sometimes called "Index files") that are available in the repository, along with their hashes. After fetching the Release file, APT proceeds to request those Index files. To give you an idea, there are many kinds of Index files, among which: There's an excellent Wiki page that details the structure of a Debian package repository, it's there: https://wiki.debian.org/DebianRepository/Format. Note that APT doesn't necessarily download ALL of those Index files. For simplicity, we'll limit ourselves to the minimal scenario, where apt update downloads only the Packages files. Let's try to make it more visual: here's a representation of a apt update transaction, assuming that all the components of the repository are enabled:
apt update -> Release -> Packages (main/amd64)
                      -> Packages (contrib/amd64)
                      -> Packages (non-free/amd64)
                      -> Packages (non-free-firmware/amd64)
Meaning that, in a first step, APT downloads the Release file, reads its content, and then in a second step it downloads the Index files in parallel. You can actually see that happen with a command such as apt -q -o Debug::Acquire::http=true update 2>&1 grep ^GET. For Kali Linux you'll see something pretty similar to what I described above. Try it!
$ podman run --rm kali-rolling apt -q -o Debug::Acquire::http=true update 2>&1   grep ^GET
GET /kali/dists/kali-rolling/InRelease HTTP/1.1    # <- returns a redirect, that is why the file is requested twice
GET /kali/dists/kali-rolling/InRelease HTTP/1.1
GET /kali/dists/kali-rolling/non-free/binary-amd64/Packages.gz HTTP/1.1
GET /kali/dists/kali-rolling/main/binary-amd64/Packages.gz HTTP/1.1
GET /kali/dists/kali-rolling/non-free-firmware/binary-amd64/Packages.gz HTTP/1.1
GET /kali/dists/kali-rolling/contrib/binary-amd64/Packages.gz HTTP/1.1
However, and it's now becoming interesting, for Debian or Ubuntu you won't see the same kind of URLs:
$ podman run --rm debian:sid apt -q -o Debug::Acquire::http=true update 2>&1   grep ^GET
GET /debian/dists/sid/InRelease HTTP/1.1
GET /debian/dists/sid/main/binary-amd64/by-hash/SHA256/22709f0ce67e5e0a33a6e6e64d96a83805903a3376e042c83d64886bb555a9c3 HTTP/1.1
APT doesn't download a file named Packages, instead it fetches a file named after a hash. Why? This is due to the field Acquire-By-Hash: yes that is present in the Debian's Release file. What does Acquire-By-Hash mean for 'apt update' The idea with Acquire-By-Hash is that the Index files are named after their hash on the repository, so if the MD5 sum of main/binary-amd64/Packages is 77b2c1539f816832e2d762adb20a2bb1, then the file will be stored at main/binary-amd64/by-hash/MD5Sum/77b2c1539f816832e2d762adb20a2bb1. The path main/binary-amd64/Packages still exists (it's the "Canonical Location" of this particular Index file), but APT won't use it, instead it downloads the file located in the by-hash/ directory. Why does it matter? This has to do with repository updates, and allowing the package repository to be updated atomically, without interruption of service, and without risk of failure client-side. It's important to understand that the Release file and the Index files are part of a whole, a set of files that go altogether, given that Index files are validated by their hash (as listed in the Release file) after download by APT. If those files are simply named "Release" and "Packages", it means they are not immutable: when the repository is updated, all of those files are updated "in place". And it causes problems. A typical failure mode for the client, during a repository update, is that: 1) APT requests the Release file, then 2) the repository is updated and finally 3) APT requests the Packages files, but their checksum don't match, causing apt update to fail. There are variations of this error, but you get the idea: updating a set of files "in place" is problematic. The Acquire-By-Hash mechanism was introduced exactly to solve this problem: now the Index files have a unique, immutable name. When the repository is updated, at first new Index files are added in the by-hash/ directory, and only after the Release file is updated. Old Index files in by-hash/ are retained for a while, so there's a grace period during which both the old and the new Release files are valid and working: the Index files that they refer to are available in the repo. As a result: no interruption of service, no failure client-side during repository updates. This is explained in more details at https://www.chiark.greenend.org.uk/~cjwatson/blog/no-more-hash-sum-mismatch-errors.html, which is the blog post from Colin Watson that came out at the time Acquire-By-Hash was introduced in... 2016. This is still an excellent read in 2025. So you might be wondering why I'm rambling about a problem that's been solved 10 years ago, but then as I've shown in the introduction, the problem is not solved for everyone. Support for Acquire-By-Hash server side is not for granted, and unfortunately it never landed in reprepro, as one can see at https://bugs.debian.org/820660. reprepro is a popular tool for creating APT package repositories. In particular, at Kali Linux we use reprepro, and that's why there's no Acquire-By-Hash: yes in the Kali Release file. As one can guess, it leads to subtle issues during those moments when the repository is updated. However... we're not ready to talk about that yet! There's still another topic that we need to cover: this window of time during which a repository is being updated, and during which apt update might fail. The window for Hash Sum Mismatches, and the APT trick that saves the day Pay attention! In this section, we're now talking about packages repositories that do NOT support Acquire-By-Hash, such as the Kali Linux repository. As I've said above, it's only when the repository is being updated that there is a "Hash Sum Mismatch Window", ie. a moment when apt update might fail for some unlucky clients, due to invalid Index files. Surely, it's a very very short window of time, right? I mean, it can't take that long to update files on a server, especially when you know that a repository is usually updated via rsync, and rsync goes to great length to update files the most atomically as it can (with the option --delay=updates). So if apt update fails for me, I've been very unlucky, but I can just retry in a few seconds and it should be fixed, isn't it? The answer is: it's not that simple. So far I pictured the "package repository" as a single server, for simplicity. But it's not always what it is. For Kali Linux, by default users have http.kali.org configured in their APT sources, and it is a redirector, ie. a web server that redirects requests to mirrors that are nearby the client. Some context that matters for what comes next: the Kali repository is synced with ~70 mirrors all around the world, 4 times a day. What happens if your apt update requests are redirected to 2 mirrors close-by, and one was just synced, while the other is still syncing (or even worse, failed to sync entirely)? You'll get a mix of old and new Index files. Hash Sum Mismatch! As you can see, with this setup the "Hash Sum Mismatch Window" becomes much longer than a few seconds: as long as nearby mirrors are syncing the window is opened. You could have a fast and a slow mirror next to you, and they can be out of sync with each other for several minutes every time the repository is updated, for example. For Kali Linux in particular, there's a "detail" in our network of mirrors that, as a side-effect, almost guarantees that this window lasts several minutes at least. This is because the pool of mirrors includes kali.download which is in fact the Cloudflare CDN, and from the redirector point of view, it's seen as a "super mirror" that is present in every country. So when APT fires a bunch of requests against http.kali.org, it's likely that some of them will be redirected to the Kali CDN, and others will be redirected to a mirror nearby you. So far so good, but there's another point of detail to be aware of: the Kali CDN is synced first, before the other mirrors. Another thing: usually the mirrors that are the farthest from the Tier-0 mirror are the longest to sync. Packing all of that together: if you live somewhere in Asia, it's not uncommon for your "Hash Sum Mismatch Window" to be as long as 30 minutes, between the moment the Kali CDN is synced, and the moment your nearby mirrors catch up and are finally in sync as well. Having said all of that, and assuming you're still reading (anyone here?), you might be wondering... Does that mean that apt update is broken 4 times a day, for around 30 minutes, for every Kali user out there? How can they bear with that? Answer is: no, of course not, it's not broken like that. It works despite all of that, and this is thanks to yet another detail that we didn't go into yet. This detail lies in APT itself. APT is in fact "redirector aware", in a sense. When it fetches a Release file, and if ever the request is redirected, it then fires the subsequent requests against the server where it was initially redirected. So you are guaranteed that the Release file and the Index files are retrieved from the same mirror! Which brings back our "Hash Sum Mismatch Window" to the window for a single server, ie. something like a few seconds at worst, hopefully. And that's what makes it work for Kali, literally. Without this trick, everything would fall apart. For reference, this feature was implemented in APT back in... 2016! A busy year it seems! Here's the link to the commit: use the same redirection mirror for all index files. To finish, a dump from the console. You can see this behaviour play out easily, again with APT debugging turned on. Below we can see that only the first request hits the Kali redirector:
$ podman run --rm kali-rolling apt -q -o Debug::Acquire::http=true update 2>&1   grep -e ^Answer -e ^HTTP
Answer for: http://http.kali.org/kali/dists/kali-rolling/InRelease
HTTP/1.1 302 Found
Answer for: http://mirror.freedif.org/kali/dists/kali-rolling/InRelease
HTTP/1.1 200 OK
Answer for: http://mirror.freedif.org/kali/dists/kali-rolling/non-free-firmware/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Answer for: http://mirror.freedif.org/kali/dists/kali-rolling/contrib/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Answer for: http://mirror.freedif.org/kali/dists/kali-rolling/main/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Answer for: http://mirror.freedif.org/kali/dists/kali-rolling/non-free/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Interlude Believe it or not, we're done with the introduction! At this point, we have a good understanding of what apt update does (in terms of HTTP requests), we know that Release files and Index files are part of a whole, and we know that a repository can be updated atomically thanks to the Acquire-By-Hash feature, so that users don't experience interruption of service or failures of any sort, even with a rolling repository that is updated several times a day, like Debian sid. We've also learnt that, despite the fact that Acquire-By-Hash landed almost 10 years ago, some distributions like Kali Linux are still doing without it... and yet it works! But the reason why it works is more complicated to grasp, especially when you add a network of mirrors and a redirector to the picture. Moreover, it doesn't work as flawlessly as with the Acquire-By-Hash feature: we still expect some short (seconds at worst) "Hash Sum Mismatch Windows" for those unlucky users that run apt update at the wrong moment. This was a long intro, but that really sets the stage for what comes next: the edge cases. Some situations in which we can hit some Hash Sum Mismatch errors with Kali. Error cases that I've collected and investigated over the time... If anything, it supports the case that Acquire-By-Hash is really something that should be implemented in reprepro. More on that in the conclusion, but for now, let's look at those edge cases. Edge Case 1: the caching proxy If you put a caching proxy (such as approx, my APT caching proxy of choice) between yourself and the actual packages repository, then obviously it's the caching proxy that performs the HTTP requests, and therefore APT will never know about the redirections returned by the server, if any. So the APT trick of downloading all the Index files from the same server in case of redirect doesn't work anymore. It was rather easy to confirm that by building a Kali package during a mirror sync, and watch if fail at the "Update chroot" step:
$ sudo rm /var/cache/approx/kali/dists/ -fr
$ gbp buildpackage --git-builder=sbuild
+------------------------------------------------------------------------------+
  Update chroot                                Wed, 11 Jun 2025 10:33:32 +0000  
+------------------------------------------------------------------------------+
Get:1 http://http.kali.org/kali kali-dev InRelease [41.4 kB]
Get:2 http://http.kali.org/kali kali-dev/contrib Sources [81.6 kB]
Get:3 http://http.kali.org/kali kali-dev/main Sources [17.3 MB]
Get:4 http://http.kali.org/kali kali-dev/non-free Sources [122 kB]
Get:5 http://http.kali.org/kali kali-dev/non-free-firmware Sources [8297 B]
Get:6 http://http.kali.org/kali kali-dev/non-free amd64 Packages [197 kB]
Get:7 http://http.kali.org/kali kali-dev/non-free-firmware amd64 Packages [10.6 kB]
Get:8 http://http.kali.org/kali kali-dev/contrib amd64 Packages [120 kB]
Get:9 http://http.kali.org/kali kali-dev/main amd64 Packages [21.0 MB]
Err:9 http://http.kali.org/kali kali-dev/main amd64 Packages
  File has unexpected size (20984689 != 20984861). Mirror sync in progress? [IP: ::1 9999]
  Hashes of expected file:
   - Filesize:20984861 [weak]
   - SHA256:6cbbee5838849ffb24a800bdcd1477e2f4adf5838a844f3838b8b66b7493879e
   - SHA1:a5c7e557a506013bd0cf938ab575fc084ed57dba [weak]
   - MD5Sum:1433ce57419414ffb348fca14ca1b00f [weak]
  Release file created at: Wed, 11 Jun 2025 07:15:10 +0000
Fetched 17.9 MB in 9s (1893 kB/s)
Reading package lists...
E: Failed to fetch http://http.kali.org/kali/dists/kali-dev/main/binary-amd64/Packages.gz  File has unexpected size (20984689 != 20984861). Mirror sync in progress? [IP: ::1 9999]
   Hashes of expected file:
    - Filesize:20984861 [weak]
    - SHA256:6cbbee5838849ffb24a800bdcd1477e2f4adf5838a844f3838b8b66b7493879e
    - SHA1:a5c7e557a506013bd0cf938ab575fc084ed57dba [weak]
    - MD5Sum:1433ce57419414ffb348fca14ca1b00f [weak]
   Release file created at: Wed, 11 Jun 2025 07:15:10 +0000
E: Some index files failed to download. They have been ignored, or old ones used instead.
E: apt-get update failed
The obvious workaround is to NOT use the redirector in the approx configuration. Either use a mirror close by, or the Kali CDN:
$ grep kali /etc/approx/approx.conf 
#kali http://http.kali.org/kali <- do not use the redirector!
kali  http://kali.download/kali
Edge Case 2: debootstrap struggles What if one tries to debootstrap Kali while mirrors are being synced? It can give you some ugly logs, but it might not be fatal:
$ sudo debootstrap kali-dev kali-dev http://http.kali.org/kali
[...]
I: Target architecture can be executed
I: Retrieving InRelease 
I: Checking Release signature
I: Valid Release signature (key id 827C8569F2518CC677FECA1AED65462EC8D5E4C5)
I: Retrieving Packages 
I: Validating Packages 
W: Retrying failed download of http://http.kali.org/kali/dists/kali-dev/main/binary-amd64/Packages.gz
I: Retrieving Packages 
I: Validating Packages 
W: Retrying failed download of http://http.kali.org/kali/dists/kali-dev/main/binary-amd64/Packages.gz
I: Retrieving Packages 
I: Validating Packages 
W: Retrying failed download of http://http.kali.org/kali/dists/kali-dev/main/binary-amd64/Packages.gz
I: Retrieving Packages 
I: Validating Packages 
W: Retrying failed download of http://http.kali.org/kali/dists/kali-dev/main/binary-amd64/Packages.gz
I: Retrieving Packages 
I: Validating Packages 
I: Resolving dependencies of required packages...
I: Resolving dependencies of base packages...
I: Checking component main on http://http.kali.org/kali...
I: Retrieving adduser 3.152
[...]
To understand this one, we have to go and look at the debootstrap source code. How does debootstrap fetch the Release file and the Index files? It uses wget, and it retries up to 10 times in case of failure. It's not as sophisticated as APT: it doesn't detect when the Release file is served via a redirect. As a consequence, what happens above can be explained as such:
  1. debootstrap requests the Release file, gets redirected to a mirror, and retrieves it from there
  2. then it requests the Packages file, gets redirected to another mirror that is not in sync with the first one, and retrieves it from there
  3. validation fails, since the checksum is not as expected
  4. try again and again
Since debootstrap retries up to 10 times, at some point it's lucky enough to get redirected to the same mirror as the one from where it got its Release file from, and this time it gets the right Packages file, with the expected checksum. So ultimately it succeeds. Edge Case 3: post-debootstrap failure I like this one, because it gets us to yet another detail that we didn't talk about yet. So, what happens after we successfully debootstraped Kali? We have only the main component enabled, and only the Index file for this component have been retrieved. It looks like that:
$ sudo debootstrap kali-dev kali-dev http://http.kali.org/kali
[...]
I: Base system installed successfully.
$ cat kali-dev/etc/apt/sources.list
deb http://http.kali.org/kali kali-dev main
$ ls -l kali-dev/var/lib/apt/lists/
total 80468
-rw-r--r-- 1 root root    41445 Jun 19 07:02 http.kali.org_kali_dists_kali-dev_InRelease
-rw-r--r-- 1 root root 82299122 Jun 19 07:01 http.kali.org_kali_dists_kali-dev_main_binary-amd64_Packages
-rw-r--r-- 1 root root    40562 Jun 19 11:54 http.kali.org_kali_dists_kali-dev_Release
-rw-r--r-- 1 root root      833 Jun 19 11:54 http.kali.org_kali_dists_kali-dev_Release.gpg
drwxr-xr-x 2 root root     4096 Jun 19 11:54 partial
So far so good. Next step would be to complete the sources.list with other components, then run apt update: APT will download the missing Index files. But if you're unlucky, that might fail:
$ sudo sed -i 's/main$/main contrib non-free non-free-firmware/' kali-dev/etc/apt/sources.list
$ cat kali-dev/etc/apt/sources.list
deb http://http.kali.org/kali kali-dev main contrib non-free non-free-firmware
$ sudo chroot kali-dev apt update
Hit:1 http://http.kali.org/kali kali-dev InRelease
Get:2 http://kali.download/kali kali-dev/contrib amd64 Packages [121 kB]
Get:4 http://mirror.sg.gs/kali kali-dev/non-free-firmware amd64 Packages [10.6 kB]
Get:3 http://mirror.freedif.org/kali kali-dev/non-free amd64 Packages [198 kB]
Err:3 http://mirror.freedif.org/kali kali-dev/non-free amd64 Packages
  File has unexpected size (10442 != 10584). Mirror sync in progress? [IP: 66.96.199.63 80]
  Hashes of expected file:
   - Filesize:10584 [weak]
   - SHA256:71a83d895f3488d8ebf63ccd3216923a7196f06f088461f8770cee3645376abb
   - SHA1:c4ff126b151f5150d6a8464bc6ed3c768627a197 [weak]
   - MD5Sum:a49f46a85febb275346c51ba0aa8c110 [weak]
  Release file created at: Fri, 23 May 2025 06:48:41 +0000
Fetched 336 kB in 4s (77.5 kB/s)  
Reading package lists... Done
E: Failed to fetch http://mirror.freedif.org/kali/dists/kali-dev/non-free/binary-amd64/Packages.gz  File has unexpected size (10442 != 10584). Mirror sync in progress? [IP: 66.96.199.63 80]
   Hashes of expected file:
    - Filesize:10584 [weak]
    - SHA256:71a83d895f3488d8ebf63ccd3216923a7196f06f088461f8770cee3645376abb
    - SHA1:c4ff126b151f5150d6a8464bc6ed3c768627a197 [weak]
    - MD5Sum:a49f46a85febb275346c51ba0aa8c110 [weak]
   Release file created at: Fri, 23 May 2025 06:48:41 +0000
E: Some index files failed to download. They have been ignored, or old ones used instead.
What happened here? Again, we need APT debugging options to have a hint:
$ sudo chroot kali-dev apt -q -o Debug::Acquire::http=true update 2>&1   grep -e ^Answer -e ^HTTP
Answer for: http://http.kali.org/kali/dists/kali-dev/InRelease
HTTP/1.1 304 Not Modified
Answer for: http://http.kali.org/kali/dists/kali-dev/contrib/binary-amd64/Packages.gz
HTTP/1.1 302 Found
Answer for: http://http.kali.org/kali/dists/kali-dev/non-free/binary-amd64/Packages.gz
HTTP/1.1 302 Found
Answer for: http://http.kali.org/kali/dists/kali-dev/non-free-firmware/binary-amd64/Packages.gz
HTTP/1.1 302 Found
Answer for: http://kali.download/kali/dists/kali-dev/contrib/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Answer for: http://mirror.sg.gs/kali/dists/kali-dev/non-free-firmware/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Answer for: http://mirror.freedif.org/kali/dists/kali-dev/non-free/binary-amd64/Packages.gz
HTTP/1.1 200 OK
As we can see above, for the Release file we get a 304 (aka. "Not Modified") from the redirector. Why is that? This is due to If-Modified-Since also known as RFC-7232. APT supports this feature when it retrieves the Release file, it basically says to the server "Give me the Release file, but only if it's newer than what I already have". If the file on the server is not newer than that, it answers with a 304, which basically says to the client "You have the latest version already". So APT doesn't get a new Release file, it uses the Release file that is already present locally in /var/lib/apt/lists/, and then it proceeeds to download the missing Index files. And as we can see above: it then hits the redirector for each requests, and might be redirected to different mirrors for each Index file. So the important bit here is: the APT "trick" of downloading all the Index files from the same mirror only works if the Release file is served via a redirect. If it's not, like in this case, then APT hits the redirector for each files it needs to download, and it's subject to the "Hash Sum Mismatch" error again. In practice, for the casual user running apt update every now and then, it's not an issue. If they have the latest Release file, no extra requests are done, because they also have the latest Index files, from a previous apt update transaction. So APT doesn't re-download those Index files. The only reason why they'd have the latest Release file, and would miss some Index files, would be that they added new components to their APT sources, like we just did above. Not so common, and then they'd need to run apt update at a unlucky moment. I don't think many users are affected in practice. Note that this issue is rather new for Kali Linux. The redirector running on http.kali.org is mirrorbits, and support for If-Modified-Since just landed in the latest release, version 0.6. This feature was added by no one else than me, a great example of the expression "shooting oneself in the foot". An obvious workaround here is to empty /var/lib/apt/lists/ in the chroot after debootstrap completed. Or we could disable support for If-Modified-Since entirely for Kali's instance of mirrorbits. Summary and Conclusion The Hash Sum Mismatch failures above are caused by a combination of things: At the same time: All in all, it seems that all those issues would go away if only Acquire-By-Hash was supported in the Kali packages repository. Now is not a bad moment to try to land this feature in reprepro. After development halted in 2019, there's now a new upstream, and patches are being merged again. But it won't be easy: reprepro is a C codebase of around 50k lines of code, and it will take time and effort for the newcomer to get acquainted with the codebase, to the point of being able to implement a significant feature like this one. As an alternative, aptly is another popular tool to manage APT package repositories. And it seems to support Acquire-By-Hash already. Another alternative: I was told that debusine has (experimental) support for package repositories, and that Acquire-By-Hash is supported as well. Options are on the table, and I hope that Kali will eventually get support for Acquire-By-Hash, one way or another. To finish, due credits: this blog post exists thanks to my employer OffSec. Thanks for reading!

16 July 2025

Sven Hoexter: Windows 10 to Ubuntu Migration

I know that Canonical / Ubuntu people are sometimes not well received due to promotion of Canonical tooling (some might remember upstart and Mir, or more recently snap and netplan). Thus for some positive vibes consider that I could hand out the Ubuntu Desktop image on a USB flash drive to a family member, and the family member could just replace Windows 10 without any assistance. It just worked. This was made possible by the will to keep a slightly dated ThinkPad in use, which it's not supported by Windows 11. I've to admit that I never looked at Ubuntu Desktop before, but the user experience is on par with everything else I know. Thanks to all the folks at Canonical who made that possible! Luckily the times when you had to fiddle with modelines for XFree86, and sleepless nights about configuring lpd to get printing up and running are long gone. I believe now that Microsoft is doing Microsoft things with rolling Windows updates which force users to replace completely fine working hardware is the time to encourage more people to move to open operating systems, and Ubuntu Desktop seems to be a very suitable choice. Things to Improve Albeit I think the out of the box experience is great, there are a few niche topics where things could improve. Default Access to Apt / Ubuntu Universe Well snaps are promoted as the primary application source, but having some graphical interface like synaptic available by default to just install from Ubuntu Universe would be helpful. In this case we wanted to install keepass2 to access the users keepass file kept from the Windows setup. Having to tell someone "open the terminal and type sudo apt install" is something that requires support. Snaps and Isolation Overrides I'm fine with snaps having least privileges, but it would be nice if one could add overrides easily. Here the family member was playing with an Arduino Uno and there is one sample in the workbook that utilizes a Java application called Processing. It's available as a snap, but that one doesn't have access to the required serial port device file. I tried hard to make it work - full details in the snapcraft forum - but failed, and opted to use the --devmode to install it without isolation enforcement. As far as I understood snap that results in no more automatic updates for the application. If someone from the Ubuntu crowd with more snap debug experience has additional hints on how to narrow down which change is required, I would love to improve that and create a PR for the processing developers. Either reply in the forum or reach out via mail sven at stormbind dot net.

Next.

Previous.