Search Results: "cts"

9 December 2024

Freexian Collaborators: Debian Contributions: OpenMPI transitions, cPython 3.12.7+ update uploads, Python 3.13 Transition, and more! (by Anupa Ann Joseph, Stefano Rivera)

Debian Contributions: 2024-11 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Transition management, by Emilio Pozuelo Monfort Emilio has been helping finish the mpi-defaults switch to mpich on 32-bit architectures, and the openmpi transitions. This involves filing bugs for the reverse dependencies, doing NMUs, and requesting removals for outdated (Not Built from Source) binaries on 32-bit architectures where openmpi is no longer available. Those transitions got entangled with a few others, such as the petsc stack, and were blocking many packages from migrating to testing. These transitions were completed in early December.

cPython 3.12.7+ update uploads, by Stefano Rivera Python 3.12 had failed to build on mips64el, due to an obscure dh_strip failure. The mips64el porters never figured it out, but the missing build on mips64el was blocking migration to Debian testing. After waiting a month, enough changes had accumulated in the upstream 3.12 maintenance git branch that we could apply them in the hope of changing the output enough to avoid breaking dh_strip. This worked. Of course there were other things to deal with too. A test started failing due to a Debian-specific patch we carry for python3.x-minimal, and it needed to be reworked. And Stefano forgot to strip the trailing + from PY_VERSION, which confuses some python libraries. This always requires another patch when applying git updates from the maintenance branch. Stefano added a build-time check to catch this mistake in the future. Python 3.12.7 migrated.

Python 3.13 Transition, by Stefano Rivera and Colin Watson During November the Python 3.13-add transition started. This is the first stage of supporting a new version of Python in Debian archive (after preparatory work), adding it as a new supported but non-default version. All packages with compiled Python extensions need to be re-built to add support for the new version. We have covered the lead-up to this transition in the past. Due to preparation, many of the failures we hit were expected and we had patches waiting in the bug tracker. These could be NMUed to get the transition moving. Others had been known about but hadn t been worked on, yet. Some other packages ran into new issues, as we got further into the transition than we d been able to in preparation. The whole Debian Python team has been helping with this work. The rebuild stage of the 3.13-add transition is now over, but many packages need work before britney will let python3-defaults migrate to testing.

Limiting build concurrency based on available RAM, by Helmut Grohne In recent years, the concurrency of CPUs has been increasing as has the demand for RAM by linkers. What has not been increasing as quickly is the RAM supply in typical machines. As a result, we more frequently run into situations where the package builds exhaust memory when building at full concurrency. Helmut initiated a discussion about generalizing an approach to this in Debian packages. Researching existing code that limits concurrency as well as providing possible extensions to debhelper and dpkg to provide concurrency limits based on available system RAM. Thus far there is consensus on the need for a more general solution, but ideas are still being collected for the precise solution.

MiniDebConf Toulouse at Capitole du Libre The whole Freexian Collaborator team attended MiniDebConf Toulouse, part of the Capitole du Libre event. Several members of the team gave talks: Stefano and Anupa worked as part of the video team, streaming and recording the event s talks.

Miscellaneous contributions
  • Stefano looked into packaging the latest upstream python-falcon version in Debian, in support of the Python 3.13 transition. This appeared to break python-hug, which is sadly looking neglected upstream, and the best course of action is probably its removal from Debian.
  • Stefano uploaded videos from various 2024 Debian events to PeerTube and YouTube.
  • Stefano and Santiago visited the site for DebConf 2025 in Brest, after the MiniDebConf in Toulouse, to meet with the local team and scout out the venue. The on-going DebConf 25 organization work of last month also included handling the logo and artwork call for proposals.
  • Stefano helped the press team to edit a post for bits.debian.org on OpenStreetMap s migration to Debian.
  • Carles implemented multiple language support on po-debconf-manager and tested it using Portuguese-Brazilian during MiniDebConf Toulouse. The system was also tested and improved by reviewing more than 20 translations to Catalan, creating merge requests for those packages, and providing user support to new users. Additionally, Carles implemented better status transitions, configuration keys management and other small improvements.
  • Helmut sent 32 patches for cross build failures. The wireplumber one was an interactive collaboration with Dylan A ssi.
  • Helmut continued to monitor the /usr-move, sent a patch for lib64readline8 and continued several older patch conversations. lintian now reports some aliasing issues in unstable.
  • Helmut initiated a discussion on the semantics of *-for-host packages. More feedback is welcome.
  • Helmut improved the crossqa.debian.net infrastructure to fail running lintian less often in larger packages.
  • Helmut continued maintaining rebootstrap mostly dropping applied patches and continuing discussions of submitted patches.
  • Helmut prepared a non-maintainer upload of gzip for several long-standing bugs.
  • Colin came up with a plan for resolving the multipart vs. python-multipart name conflict, and began work on converting reverse-dependencies.
  • Colin upgraded 42 Python packages to new upstream versions. Some were complex: python-catalogue had some upstream version confusion, pydantic and rpds-py involved several Rust package upgrades as prerequisites, and python-urllib3 involved first packaging python-quart-trio and then vendoring an unpackaged test-dependency.
  • Colin contributed Incus support to needrestart upstream.
  • Lucas set up a machine to do a rebuild of all ruby reverse dependencies to check what will be broken by adding ruby 3.3 as an alternative interpreter. The tool used for this is mass-rebuild and the initial rebuilds have already started. The ruby interpreter maintainers are planning to experiment with debusine next time.
  • Lucas is organizing a Debian Ruby sprint towards the end of January in Paris. The plan of the team is to finish any missing bits of Ruby 3.3 transition at the time, try to push Rails 7 transition and fix RC bugs affecting the ruby ecosystem in Debian.
  • Anupa attended a Debian Publicity team meeting in-person during MiniDebCamp Toulouse.
  • Anupa moderated and posted in the Debian Administrator group in LinkedIn.

8 December 2024

Dirk Eddelbuettel: pinp 0.0.11 on CRAN: Maintenance

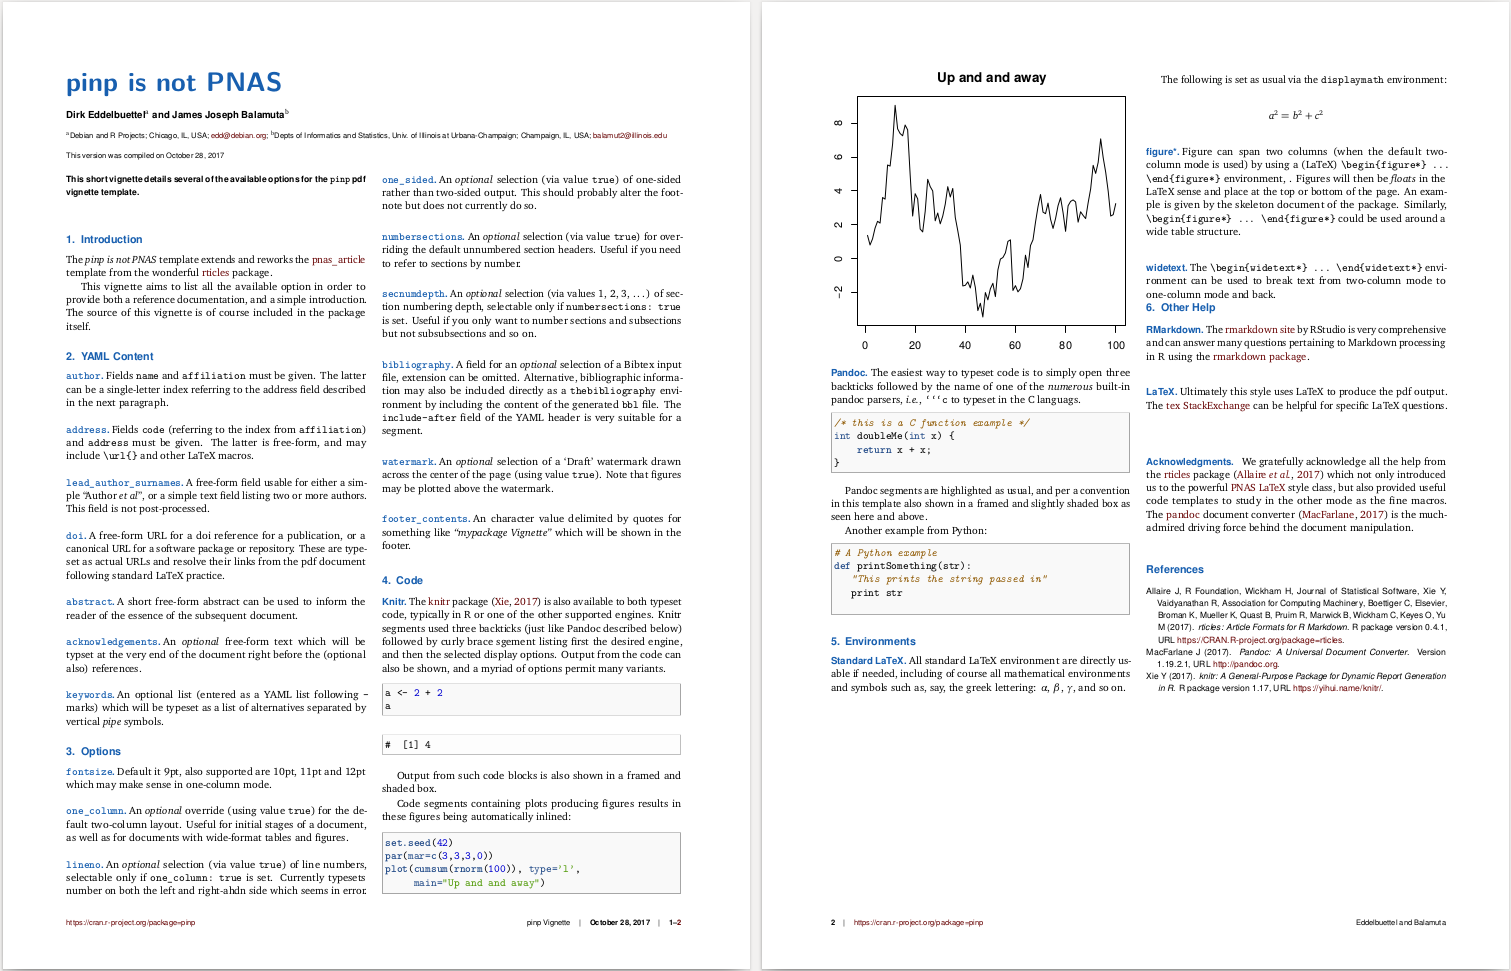
A new version of our pinp package arrived on CRAN today, and is the first release in four years. The pinp package allows for snazzier one or two column Markdown-based pdf vignettes, and is now used by a few packages. A screenshot of the package vignette can be seen below. Additional screenshots are at the pinp page. pinp vignette This release contains no new features or new user-facing changes but reflects the standard package and repository maintenance over the four-year window since the last release: updating of actions, updating of URLs and addressing small packaging changes spotted by ever-more-vigilant R checking code. The NEWS entry for this release follows.
Changes in pinp version 0.0.11 (2024-12-08)
  • Standard package maintenance for continuous integration, URL updates, and packaging conventions
  • Correct two minor nags in the Rd file

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the ping page. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

6 December 2024

B lint R czey: Firebuild 0.8.3 is out with 100+ fixes and experimental macOS support!

The new Firebuild release contains plenty of small fixes and a few notable improvements.

Experimental macOS support The most frequently asked question from people getting to know Firebuild was if it worked on their Mac and the answer sadly used to be that well, it did, but only in a Linux VM. This was far from what they were looking for. Linux and macOS have common UNIX roots, but porting Firebuild to macOS included bigger challenges, like ensuring that dyld(1), macOS s dynamic loader initializes the preloaded interceptor library early enough to catch all interesting calls, and avoid using anything that uses malloc() or thread local variables which are not yet set up then. Preloading libraries on Linux is really easy, running LD_PRELOAD=my_lib.so ls just works if the library exports the symbols to be interposed, while macOS employs multiple lines of defense to prevent applications from using unknown libraries. Firebuild s guide for making DYLD_INSERT_LIBRARIES honored on Macs can be helpful with other projects as well that rely on injecting libraries. Since GitHub s Arm64 macOS runners don t allow intercepting binaries with arm64e ABI yet, Firebuild s Apple Silicon tests are run at Bitrise, who are proud to be first to provide the latest Xcode stacks and were also quick to make the needed changes to their infrastructure to support Firebuild (thanks!  ). Firebuild on macOS can already accelerate simple projects and rebuild itself with Xcode. Since Xcode introduces a lot of nondeterminism to the build, Firebuild can t shine in acceleration with Xcode yet, but can provide nice reports to show which part of the build is the most time consuming and how each sub-command is called. If you would like to try Firebuild on macOS please compile it from the GitHub repository for now. Precompiled binaries will be distributed on the Mac App Store and via CI providers. Contact us to get notified when those channels become available.

Dealing with the Epochalypse Glibc s API provides many functions with time parameters and some of those functions are intercepted by Firebuild. Time parameters used to be passed as 32-bit values on 32-bit systems, preventing them to accurately represent timestamps after year 2038, which is known as the Y2038 problem or the Epochalypse. To deal with the problem glibc 2.34 started providing new function symbol variants with 64-bit time parameters, e.g clock_gettime64() in addition to clock_gettime(). The new 64-bit variants are used when compiling consumers of the API with _TIME_BITS=64 defined. Processes intercepted by Firebuild may have been compiled with or without _TIME_BITS=64, thus libfirebuild now provides both variants on affected systems running glibc >= 34 to work safely with binaries using 64-bit and 32-bit time representation. Many Linux distributions already stopped supporting 32-bit architectures, but Debian and Ubuntu still supports armhf, for example, where the Y2038 problem still applies. Both Debian and Ubuntu performed a transition rebuilding every library (and their reverse dependencies) with -D_FILE_OFFSET_BITS=64 set where the libraries exported symbols that changed when switching to 64-bit time representation (thanks to Steve Langasek for driving this!) . Thanks to the transition most programs are ready for 2038, but interposer libraries are trickier to fix and if you maintain one it might be a good idea to check if it works well both 32-bit and 64-bit libraries. Faketime, for example is not fixed yet, see #1064555.

Select passed through environment variables with regular expressions Firebuild filters out most of the environment variables set when starting a build to make the build more reproducible and achieve higher cache hit rate. Extra environment variables to pass through can be specified on the command line one by one, but with many similarly named variables this may become hard to maintain. With regular expressions this just became easier:
firebuild -o 'env_vars.pass_through += "MY_VARS_.*"' my_build_command
If you are not interested in acceleration just would like to explore what the build does by generating a report you can simply pass all variables:
firebuild -r -o 'env_vars.pass_through += ".*"' my_build_command

Other highlights from the 0.8.3 release
  • Fixed and nicer report in Chrome and other WebKit based browsers
  • Support GLibc 2.39 by intercepting pidfd_spawn() and pidfd_spawnp()
  • Even faster Rust build acceleration
For all the changes please check out the release page on GitHub!  (This post is also published on The Firebuild blog.)

Dirk Eddelbuettel: RcppArmadillo 14.2.2-1 on CRAN: Small Upstream Fixes

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1197 other packages on CRAN, downloaded 37.5 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 605 times according to Google Scholar. Conrad released a minor version 14.2.2 yesterday. This followed a bit of recent work a few of us did in the ensmallen and mlpack repositories following the [14.2.0 release]. Use of (member functions) .min(index) and .max(index) was deprecated in Armadillo in favor of .index_mix() and .index_max(). By now ensmallen and mlpack have been updated at CRAN. To add some spice, CRAN emailed that the (very much unreleased as of now, but coming likely next spring) gcc-15 was unhappy with RcppArmadillo due to some Armadillo code. This likely related to the listed gcc-15 C++ change about Qualified name lookup failure into the current instantiation . Anyway, Conrad fixed it within days and that change too is part of this new version (as is a small behaviour normalization between the two indexing methods that matters in case of ties, this was in 14.2.1). The changes since the last CRAN release are summarised below.

Changes in RcppArmadillo version 14.2.2-1 (2024-12-05)
  • Upgraded to Armadillo release 14.2.2 (Smooth Caffeine)
    • Workarounds for regressions in pre-release versions of GCC 15
    • More selective detection of symmetric/hermitian matrices by various functions

Changes in RcppArmadillo version 14.2.1-1 (2024-11-24) (GitHub Only)
  • Upgraded to Armadillo release 14.2.1 (Smooth Caffeine)
    • Fix for index_min() and index_max() to ensure that the first index of equal extremum values is found

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

5 December 2024

Reproducible Builds: Reproducible Builds in November 2024

Welcome to the November 2024 report from the Reproducible Builds project! Our monthly reports outline what we ve been up to over the past month and highlight items of news from elsewhere in the world of software supply-chain security where relevant. As ever, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. Table of contents:
  1. Reproducible Builds mourns the passing of Lunar
  2. Introducing reproduce.debian.net
  3. New landing page design
  4. SBOMs for Python packages
  5. Debian updates
  6. Reproducible builds by default in Maven 4
  7. PyPI now supports digital attestations
  8. Dependency Challenges in OSS Package Registries
  9. Zig programming language demonstrated reproducible
  10. Website updates
  11. Upstream patches
  12. Misc development news
  13. Reproducibility testing framework

Reproducible Builds mourns the passing of Lunar The Reproducible Builds community sadly announced it has lost its founding member, Lunar. J r my Bobbio aka Lunar passed away on Friday November 8th in palliative care in Rennes, France. Lunar was instrumental in starting the Reproducible Builds project in 2013 as a loose initiative within the Debian project. He was the author of our earliest status reports and many of our key tools in use today are based on his design. Lunar s creativity, insight and kindness were often noted. You can view our full tribute elsewhere on our website. He will be greatly missed.

Introducing reproduce.debian.net In happier news, this month saw the introduction of reproduce.debian.net. Announced at the recent Debian MiniDebConf in Toulouse, reproduce.debian.net is an instance of rebuilderd operated by the Reproducible Builds project. rebuilderd is our server designed monitor the official package repositories of Linux distributions and attempts to reproduce the observed results there. In November, reproduce.debian.net began rebuilding Debian unstable on the amd64 architecture, but throughout the MiniDebConf, it had attempted to rebuild 66% of the official archive. From this, it could be determined that it is currently possible to bit-for-bit reproduce and corroborate approximately 78% of the actual binaries distributed by Debian that is, using the .buildinfo files hosted by Debian itself. reproduce.debian.net also contains instructions how to setup one s own rebuilderd instance, and we very much invite everyone with a machine to spare to setup their own version and to share the results. Whilst rebuilderd is still in development, it has been used to reproduce Arch Linux since 2019. We are especially looking for installations targeting Debian architectures other than i386 and amd64.

New landing page design As part of a very productive partnership with the Sovereign Tech Fund and Neighbourhoodie, we are pleased to unveil our new homepage/landing page. We are very happy with our collaboration with both STF and Neighbourhoodie (including many changes not directly related to the website), and look forward to working with them in the future.

SBOMs for Python packages The Python Software Foundation has announced a new cross-functional project for SBOMs and Python packages . Seth Michael Larson writes that the project is specifically looking to solve these issues :
  • Enable Python users that require SBOM documents (likely due to regulations like CRA or SSDF) to self-serve using existing SBOM generation tools.
  • Solve the phantom dependency problem, where non-Python software is bundled in Python packages but not recorded in any metadata. This makes the job of software composition analysis (SCA) tools difficult or impossible.
  • Make the adoption work by relevant projects such as build backends, auditwheel-esque tools, as minimal as possible. Empower users who are interested in having better SBOM data for the Python projects they are using to be able to contribute engineering time towards that goal.
A GitHub repository for the initiative is available, and there are a number of queries, comments and remarks on Seth s Discourse forum post.

Debian updates There was significant development within Debian this month. Firstly, at the recent MiniDebConf in Toulouse, France, Holger Levsen gave a Debian-specific talk on rebuilding packages distributed from ftp.debian.org that is to say, how to reproduce the results from the official Debian build servers: Holger described the talk as follows:
For more than ten years, the Reproducible Builds project has worked towards reproducible builds of many projects, and for ten years now we have build Debian packages twice with maximal variations applied to see if they can be build reproducible still. Since about a month, we ve also been rebuilding trying to exactly match the builds being distributed via ftp.debian.org. This talk will describe the setup and the lessons learned so far, and why the results currently are what they are (spoiler: they are less than 30% reproducible), and what we can do to fix that.
The Debian Project Leader, Andreas Tille, was present at the talk and remarked later in his Bits from the DPL update that:
It might be unfair to single out a specific talk from Toulouse, but I d like to highlight the one on reproducible builds. Beyond its technical focus, the talk also addressed the recent loss of Lunar, whom we mourn deeply. It served as a tribute to Lunar s contributions and legacy. Personally, I ve encountered packages maintained by Lunar and bugs he had filed. I believe that taking over his packages and addressing the bugs he reported is a meaningful way to honor his memory and acknowledge the value of his work.
Holger s slides and video in .webm format are available.
Next, rebuilderd is the server to monitor package repositories of Linux distributions and attempt to reproduce the observed results. This month, version 0.21.0 released, most notably with improved support for binNMUs by Jochen Sprickerhof and updating the rebuilderd-debian.sh integration to the latest debrebuild version by Holger Levsen. There has also been significant work to get the rebuilderd package into the Debian archive, in particular, both rust-rebuilderd-common version 0.20.0-1 and rust-rust-lzma version 0.6.0-1 were packaged by kpcyrd and uploaded by Holger Levsen. Related to this, Holger Levsen submitted three additional issues against rebuilderd as well:
  • rebuildctl should be more verbose when encountering issues. [ ]
  • Please add an option to used randomised queues. [ ]
  • Scheduling and re-scheduling multiple packages at once. [ ]
and lastly, Jochen Sprickerhof submitted one an issue requested that rebuilderd downloads the source package in addition to the .buildinfo file [ ] and kpcyrd also submitted and fixed an issue surrounding dependencies and clarifying the license [ ]
Separate to this, back in 2018, Chris Lamb filed a bug report against the sphinx-gallery package as it generates unreproducible content in various ways. This month, however, Dmitry Shachnev finally closed the bug, listing the multiple sub-issues that were part of the problem and how they were resolved.
Elsewhere, Roland Clobus posted to our mailing list this month, asking for input on a bug in Debian s ca-certificates-java package. The issue is that the Java key management tools embed timestamps in its output, and this output ends up in the /etc/ssl/certs/java/cacerts file on the generated ISO images. A discussion resulted from Roland s post suggesting some short- and medium-term solutions to the problem.
Holger Levsen uploaded some packages with reproducibility-related changes:
Lastly, 12 reviews of Debian packages were added, 5 were updated and 21 were removed this month adding to our knowledge about identified issues in Debian.

Reproducible builds by default in Maven 4 On our mailing list this month, Herv Boutemy reported the latest release of Maven (4.0.0-beta-5) has reproducible builds enabled by default. In his mailing list post, Herv mentions that this story started during our Reproducible Builds summit in Hamburg , where he created the upstream issue that builds on a multi-year effort to have Maven builds configured for reproducibility.

PyPI now supports digital attestations Elsewhere in the Python ecosystem and as reported on LWN and elsewhere, the Python Package Index (PyPI) has announced that it has finalised support for PEP 740 ( Index support for digital attestations ). Trail of Bits, who performed much of the development work, has an in-depth blog post about the work and its adoption, as well as what is left undone:
One thing is notably missing from all of this work: downstream verification. [ ] This isn t an acceptable end state (cryptographic attestations have defensive properties only insofar as they re actually verified), so we re looking into ways to bring verification to individual installing clients. In particular, we re currently working on a plugin architecture for pip that will enable users to load verification logic directly into their pip install flows.
There was an in-depth discussion on LWN s announcement page, as well as on Hacker News.

Dependency Challenges in OSS Package Registries At BENEVOL, the Belgium-Netherlands Software Evolution workshop in Namur, Belgium, Tom Mens and Alexandre Decan presented their paper, An Overview and Catalogue of Dependency Challenges in Open Source Software Package Registries . The abstract of their paper is as follows:
While open-source software has enabled significant levels of reuse to speed up software development, it has also given rise to the dreadful dependency hell that all software practitioners face on a regular basis. This article provides a catalogue of dependency-related challenges that come with relying on OSS packages or libraries. The catalogue is based on the scientific literature on empirical research that has been conducted to understand, quantify and overcome these challenges. [ ]
A PDF of the paper is available online.

Zig programming language demonstrated reproducible Motiejus Jak ty posted an interesting and practical blog post on his successful attempt to reproduce the Zig programming language without using the pre-compiled binaries checked into the repository, and despite the circular dependency inherent in its bootstrapping process. As a summary, Motiejus concludes that:
I can now confidently say (and you can also check, you don t need to trust me) that there is nothing hiding in zig1.wasm [the checked-in binary] that hasn t been checked-in as a source file.
The full post is full of practical details, and includes a few open questions.

Website updates Notwithstanding the significant change to the landing page (screenshot above), there were an enormous number of changes made to our website this month. This included:
  • Alex Feyerke and Mariano Gim nez:
    • Dramatically overhaul the website s landing page with new benefit cards tailored to the expected visitors to our website and a reworking of the visual hierarchy and design. [ ][ ][ ][ ][ ][ ][ ][ ][ ][ ]
  • Bernhard M. Wiedemann:
    • Update the System images page to document the e2fsprogs approach. [ ]
  • Chris Lamb:
  • FC (Fay) Stegerman:
    • Replace more inline markdown with HTML on the Success stories page. [ ]
    • Add some links, fix some other links and correct some spelling errors on the Tools page. [ ]
  • Holger Levsen:
    • Add a historical presentation ( Reproducible builds everywhere eg. in Debian, OpenWrt and LEDE ) from October 2016. [ ]
    • Add jochensp and Oejet to the list of known contributors. [ ][ ]
  • Julia Kr ger:
  • Ninette Adhikari & hulkoba:
    • Add/rework the list of success stories into a new page that clearly shows milestones in Reproducible Builds. [ ][ ][ ][ ][ ][ ]
  • Philip Rinn:
    • Import 47 historical weekly reports. [ ]
  • hulkoba:
    • Add alt text to almost all images (!). [ ][ ]
    • Fix a number of links on the Talks . [ ][ ]
    • Avoid so-called ghost buttons by not using <button> elements as links, as the affordance of a <button> implies an action with (potentially) a side effect. [ ][ ]
    • Center the sponsor logos on the homepage. [ ]
    • Move publications and generate them instead from a data.yml file with an improved layout. [ ][ ]
    • Make a large number of small but impactful stylisting changes. [ ][ ][ ][ ]
    • Expand the Tools to include a number of missing tools, fix some styling issues and fix a number of stale/broken links. [ ][ ][ ][ ][ ][ ]

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Misc development news

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In November, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related changes:
    • Create and introduce a new reproduce.debian.net service and subdomain [ ]
    • Make a large number of documentation changes relevant to rebuilderd. [ ][ ][ ][ ][ ]
    • Explain a temporary workaround for a specific issue in rebuilderd. [ ]
    • Setup another rebuilderd instance on the o4 node and update installation documentation to match. [ ][ ]
    • Make a number of helpful/cosmetic changes to the interface, such as clarifying terms and adding links. [ ][ ][ ][ ][ ]
    • Deploy configuration to the /opt and /var directories. [ ][ ]
    • Add an infancy (or alpha ) disclaimer. [ ][ ]
    • Add more notes to the temporary rebuilderd documentation. [ ]
    • Commit an nginx configuration file for reproduce.debian.net s Stats page. [ ]
    • Commit a rebuilder-worker.conf configuration for the o5 node. [ ]
  • Debian-related changes:
    • Grant jspricke and jochensp access to the o5 node. [ ][ ]
    • Build the qemu package with the nocheck build flag. [ ]
  • Misc changes:
    • Adapt the update_jdn.sh script for new Debian trixie systems. [ ]
    • Stop installing the PostgreSQL database engine on the o4 and o5 nodes. [ ]
    • Prevent accidental reboots of the o4 node because of a long-running job owned by josch. [ ][ ]
In addition, Mattia Rizzolo addressed a number of issues with reproduce.debian.net [ ][ ][ ][ ]. And lastly, both Holger Levsen [ ][ ][ ][ ] and Vagrant Cascadian [ ][ ][ ][ ] performed node maintenance.
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

2 December 2024

Bits from Debian: Bits from the DPL

This is bits from DPL for November. MiniDebConf Toulouse I had the pleasure of attending the MiniDebConf in Toulouse, which featured a range of engaging talks, complementing those from the recent MiniDebConf in Cambridge. Both events were preceded by a DebCamp, which provided a valuable opportunity for focused work and collaboration. DebCamp During these events, I participated in numerous technical discussions on topics such as maintaining long-neglected packages, team-based maintenance, FTP master policies, Debusine, and strategies for separating maintainer script dependencies from runtime dependencies, among others. I was also fortunate that members of the Publicity Team attended the MiniDebCamp, giving us the opportunity to meet in person and collaborate face-to-face. Independent of the ongoing lengthy discussion on the Debian Devel mailing list, I encountered the perspective that unifying Git workflows might be more critical than ensuring all packages are managed in Git. While I'm uncertain whether these two questions--adopting Git as a universal development tool and agreeing on a common workflow for its use--can be fully separated, I believe it's worth raising this topic for further consideration. Attracting newcomers In my own talk, I regret not leaving enough time for questions--my apologies for this. However, I want to revisit the sole question raised, which essentially asked: Is the documentation for newcomers sufficient to attract new contributors? My immediate response was that this question is best directed to new contributors themselves, as they are in the best position to identify gaps and suggest improvements that could make the documentation more helpful. That said, I'm personally convinced that our challenges extend beyond just documentation. I don't get the impression that newcomers are lining up to join Debian only to be deterred by inadequate documentation. The issue might be more about fostering interest and engagement in the first place. My personal impression is that we sometimes fail to convey that Debian is not just a product to download for free but also a technical challenge that warmly invites participation. Everyone who respects our Code of Conduct will find that Debian is a highly diverse community, where joining the project offers not only opportunities for technical contributions but also meaningful social interactions that can make the effort and time truly rewarding. In several of my previous talks (you can find them on my talks page just search for "team," and don't be deterred if you see "Debian Med" in the title; it's simply an example), I emphasized that the interaction between a mentor and a mentee often plays a far more significant role than the documentation the mentee has to read. The key to success has always been finding a way to spark the mentee's interest in a specific topic that resonates with their own passions. Bug of the Day In my presentation, I provided a brief overview of the Bug of the Day initiative, which was launched with the aim of demonstrating how to fix bugs as an entry point for learning about packaging. While the current level of interest from newcomers seems limited, the initiative has brought several additional benefits. I must admit that I'm learning quite a bit about Debian myself. I often compare it to exploring a house's cellar with a flashlight you uncover everything from hidden marvels to things you might prefer to discard. I've also come across traces of incredibly diligent people who have invested their spare time polishing these hidden treasures (what we call NMUs). The janitor, a service in Salsa that automatically updates packages, fits perfectly into this cellar metaphor, symbolizing the ongoing care and maintenance that keep everything in order. I hadn't realized the immense amount of silent work being done behind the scenes--thank you all so much for your invaluable QA efforts. Reproducible builds It might be unfair to single out a specific talk from Toulouse, but I'd like to highlight the one on reproducible builds. Beyond its technical focus, the talk also addressed the recent loss of Lunar, whom we mourn deeply. It served as a tribute to Lunar's contributions and legacy. Personally, I've encountered packages maintained by Lunar and bugs he had filed. I believe that taking over his packages and addressing the bugs he reported is a meaningful way to honor his memory and acknowledge the value of his work. Advent calendar bug squashing I d like to promote an idea originally introduced by Thorsten Alteholz, who in 2011 proposed a Bug Squashing Advent Calendar for the Debian Med team. (For those unfamiliar with the concept of an Advent Calendar, you can find an explanation on Wikipedia.) While the original version included a fun graphical element which we ve had to set aside due to time constraints (volunteers, anyone?) we ve kept the tradition alive by tackling one bug per day from December 1st to 24th each year. This initiative helps clean up issues that have accumulated over the year. Regardless of whether you celebrate the concept of Advent, I warmly recommend this approach as a form of continuous bug-squashing party for every team. Not only does it contribute to the release readiness of your team s packages, but it s also an enjoyable and bonding activity for team members. Best wishes for a cheerful and productive December
Andreas.

Dirk Eddelbuettel: anytime 0.3.10 on CRAN: Multiple Enhancements

A new release of the anytime package arrived on CRAN today the first is well over four years. The package is fairly feature-complete, and code and functionality remain mature and stable, of course. anytime is a very focused package aiming to do just one thing really well: to convert anything in integer, numeric, character, factor, ordered, input format to either POSIXct (when called as anytime) or Date objects (when called as anydate) and to do so without requiring a format string as well as accomodating different formats in one input vector. See the anytime page, or the GitHub repo for a few examples, and the beautiful documentation site for all documentation. This release slowly matured over four years. It combines a number of strictly internal repository maintenance such as changes to continuous integration with small enhancements (adding for example some new formats, responding better to an error condition, dealing with logical input as an error) with a relaxation of the C++ compilation standard. While we once needed C++11, it is now a constraint as as R itself is quite proactive (the last two releases defaulted already to C++17, suitable compiler permitting) we can now relax this constraint. The documentation site is new, as some other small changes. See the full list of changes which follows.

Changes in anytime version 0.3.10 (2024-12-02)
  • A new documentation site was added.
  • Continuous Integration now uses run.sh from r-ci with bspm
  • Logical input vectors are now recognised as an error (#121)
  • Additional dot-separated format '%Y.%m.%d' is supported
  • Other small updates were made throughout the package
  • No longer set a C++ compilation standard as the default choices by R are sufficient for the package
  • Switch Rcpp include file to Rcpp/Lightest
  • We recommend ~/.R/Makevars compiler flag options -Wno-ignored-attributes -Wno-nonnull -Wno-parentheses
  • The tinytest runner was simplified
  • NA values from conversion now trigger a warning

Courtesy of my CRANberries, there is also a diffstat report of changes relative to the previous release. The issue tracker tracker off the GitHub repo can be use for questions and comments. More information about the package is at the package page, the GitHub repo and the documentation site. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

1 December 2024

Sandro Knau : QML Dependency tracking in Debian

Tracking library dependencies work in Debian to resolve from symbols usage to a library and add this to the list of dependencies. That is working for years now. The KDE community nowadays create more and more QML based applications. Unfortunately QML is a interpreted language, this means missing QML dependencies will only be an issue at runtime. To fix this I created dh_qmldeps, that searches for QML dependencies at build time and will fail if it can't resolve the QML dependency. Me didn't create an own QML interpreter, just using qmlimportscanner behind the scenes and process the output further to resolve the QML modules to Debian packages. The workflow is like follows: The package compiles normally and split to the binary packages. Than dh_qmldeps scans through the package content to find QML content ( .qml files, or qmldirfor QML modules). All founded files will be scanned by qmlimportscanner, the output is a list of depended QML modules. As QML modules have a standardized file path, we can ask the Debian system, which packages ship this file path. We end up with a list of Debian packages in the variable $ qml6:Depends . This variable can be attached to the list of dependencies of the scanned package. A maintainer can also lower some dependencies to Recommends or Suggest, if needed. You can find the source code on salsa and usage documentation you can find on https://qt-kde-team.pages.debian.net/dh_qmldeps.html. The last weeks I now enabled dh_qmldeps for newly every package, that creates a QML6 module package. So the first bugs are solved and it should be usable for more packages. By scanning with qmlimportscanner trough all code, I found several non-existing QML modules: YEAH - the first milestone is reached. We are able to simply handle QML modules. But QML applications there is still room for improvement. In apps the QML files are inside the executable. Additionally applications create internal QML modules, that are shipped directly in the same executable. I still search for a good way to analyse an executable to get a list of internal QML modules and a list of included QML files. Any ideas are welcomed :) As workaround dh_qmldeps scans currently all QML files inside the application source code.
30 November 2024

Enrico Zini: New laptop setup

My new laptop Framework (Framework Laptop 13 DIY Edition (AMD Ryzen 7040 Series)) arrived, all the hardware works out of the box on Debian Stable, and I'm very happy indeed. This post has the notes of all the provisioning steps, so that I can replicate them again if needed. Installing Debian 12 Debian 12's installer just worked, with Secure Boot enabled no less, which was nice. The only glitch is an argument with the guided partitioner, which was uncooperative: I have been hit before by a /boot partition too small, and I wanted 1G of EFI and 1G of boot, while the partitioner decided that 512Mb were good enough. Frustratingly, there was no way of changing that, nor I found how to get more than 1G of swap, as I wanted enough swap to fit RAM for hybernation. I let it install the way it pleased, then I booted into grml for a round of gparted. The tricky part of that was resizing the root btrfs filesystem, which is in an LV, which is in a VG, which is in a PV, which is in LUKS. Here's a cheatsheet. Shrink partitions: note that I used an increasing size because I don't trust that each tool has a way of representing sizes that aligns to the byte. I'd be happy to find out that they do, but didn't want to find out the hard way that they didn't. Resize with gparted: Move and resize partitions at will. Shrinking first means it all takes a reasonable time, and you won't have to wait almost an hour for a terabyte-sized empty partition to be carefully moved around. Don't ask me why I know. Regrow partitions: Setup gnome When I get a new laptop I have a tradition of trying to make it work with Gnome and Wayland, which normally ended up in frustration and a swift move to X11 and Xfce: I have a lot of long-time muscle memory involved in how I use a computer, and it needs to fit like prosthetics. I can learn to do a thing or two in a different way, but any papercut that makes me break flow and I cannot fix will soon become a dealbreaker. This applies to Gnome as present in Debian Stable. General Gnome settings tips I can list all available settings with:
gsettings list-recursively
which is handy for grepping things like hotkeys. I can manually set a value with:
gsettings set <schema> <key> <value>
and I can reset it to its default with:
gsettings reset <schema> <key>
Some applications like Gnome Terminal use "relocatable schemas", and in those cases you also need to specify a path, which can be discovered using dconf-editor:
gsettings set <schema>:<path> <key> <value>
Install appindicators First thing first: app install gnome-shell-extension-appindicator, log out and in again: the Gnome Extension manager won't see the extension as available until you restart the whole session. I have no idea why that is so, and I have no idea why a notification area is not present in Gnome by default, but at least now I can get one. Fix font sizes across monitors My laptop screen and monitor have significantly different DPIs, so:
gsettings set org.gnome.mutter experimental-features "['scale-monitor-framebuffer']"
And in Settings/Displays, set a reasonable scaling factor for each display. Disable Alt/Super as hotkey for the Overlay Seeing all my screen reorganize and reshuffle every time I accidentally press Alt leaves me disoriented and seasick:
gsettings set org.gnome.mutter overlay-key ''
Focus-follows-mouse and Raise-or-lower My desktop is like my desktop: messy and cluttered. I have lots of overlapping window and I switch between them by moving the focus with the mouse, and when the visible part is not enough I have a handy hotkey mapped to raise-or-lower to bring forward what I need and send back what I don't need anymore. Thankfully Gnome can be configured that way, with some work: This almost worked, but sometimes it didn't do what I wanted, like I expected to find a window to the front but another window disappeared instead. I eventually figured that by default Gnome delays focus changes by a perceivable amount, which is evidently too slow for the way I move around windows. The amount cannot be shortened, but it can be removed with:
gsettings set org.gnome.shell.overrides focus-change-on-pointer-rest false
Mouse and keyboard shortcuts Gnome has lots of preconfigured sounds, shortcuts, animations and other distractions that I do not need. They also either interfere with key combinations I want to use in terminals, or cause accidental window moves or resizes that make me break flow, or otherwise provide sensory overstimulation that really does not work for me. It was a lot of work, and these are the steps I used to get rid of most of them. Disable Super+N combinations that accidentally launch a questionable choice of programs:
for i in  seq 1 9 ; do gsettings set org.gnome.shell.keybindings switch-to-application-$i '[]'; done
Gnome-Shell settings: gnome-tweak-tool settings: Gnome Terminal settings: Thankfully 10 years ago I took notes on how to customize Gnome Terminal, and they're still mostly valid: Other hotkeys that got in my way and had to disable the hard way:
for n in  seq 1 12 ; do gsettings set org.gnome.mutter.wayland.keybindings switch-to-session-$n '[]'; done
gsettings set org.gnome.desktop.wm.keybindings move-to-workspace-down '[]'
gsettings set org.gnome.desktop.wm.keybindings move-to-workspace-up '[]'
gsettings set org.gnome.desktop.wm.keybindings panel-main-menu '[]'
gsettings set org.gnome.desktop.interface menubar-accel '[]'
Note that even after removing F10 from being bound to menubar-accel, and after having to gsetting binding to F10 as is:
$ gsettings list-recursively grep F10
org.gnome.Terminal.Legacy.Keybindings switch-to-tab-10 '<Alt>F10'
I still cannot quit Midnight Commander using F10 in a terminal, as that moves the focus in the window title bar. This looks like a Gnome bug, and a very frustrating one for me. Appearance Gnome-Shell settings: gnome-tweak-tool settings: Gnome Terminal settings: Other decluttering and tweaks Gnome Shell Settings: Set a delay between screen blank and lock: when the screen goes blank, it is important for me to be able to say "nope, don't blank yet!", and maybe switch on caffeine mode during a presentation without needing to type my password in front of cameras. No UI for this, but at least gsettings has it:
gsettings set org.gnome.desktop.screensaver lock-delay 30
Extensions I enabled the Applications Menu extension, since it's impossible to find less famous applications in the Overview without knowing in advance how they're named in the desktop. This stole a precious hotkey, which I had to disable in gsettings:
gsettings set org.gnome.shell.extensions.apps-menu apps-menu-toggle-menu '[]'
I also enabled: I didn't go and look for Gnome Shell extentions outside what is packaged in Debian, as I'm very wary about running JavaScript code randomly downloaded from the internet with full access over my data and desktop interaction. I also took care of checking that the Gnome Shell Extensions web page complains about the lacking "GNOME Shell integration" browser extension, because the web browser shouldn't be allowed to download random JavaScript from the internet and run it with full local access. Yuck. Run program dialog The default run program dialog is almost, but not quite, totally useless to me, as it does not provide completion, not even just for executable names in path, and so it ends up being faster to open a new terminal window and type in there. It's possible, in Gnome Shell settings, to bind a custom command to a key. The resulting keybinding will now show up in gsettings, though it can be located in a more circuitous way by grepping first, and then looking up the resulting path in dconf-editor:
gsettings list-recursively grep custom-key
org.gnome.settings-daemon.plugins.media-keys custom-keybindings ['/org/gnome/settings-daemon/plugins/media-keys/custom-keybindings/custom0/']
I tried out several run dialogs present in Debian, with sad results, possibly due to most of them not being tested on wayland: Both gmrun and xfrun4 seem like workable options, with xfrun4 being customizable with convenient shortcut prefixes, so xfrun4 it is. TODO I'll try to update these notes as I investigate. Conclusion so far I now have something that seems to work for me. A few papercuts to figure out still, but they seem manageable. It all feels a lot harder than it should be: for something intended to be minimal, Gnome defaults feel horribly cluttered and noisy to me, continuosly getting in the way of getting things done until tamed into being out of the way unless called for. It felt like a device that boots into flashy demo mode, which needs to be switched off before actual use. Thankfully it can be switched off, and now I have notes to do it again if needed. gsettings oddly feels to me like a better UI than the interactive settings managers: it's more comprehensive, more discoverable, more scriptable, and more stable across releases. Most of the Q&A I found on the internet with guidance given on the UI was obsolete, while when given with gsettings command lines it kept being relevant. I also have the feeling that these notes would be easier to understand and follow if given as gsettings invocations instead of descriptions of UI navigation paths. At some point I'll upgrade to Trixie and reevaluate things, and these notes will be a useful checklist for that. Fingers crossed that this time I'll manage to stay on Wayland. If not, I know that Xfce is still there for me, and I can trust it to be both helpful and good at not getting in the way of my work.

29 November 2024

Dirk Eddelbuettel: RcppAPT 0.0.10: Maintenance

A new version of the RcppAPT package arrived on CRAN earlier today. RcppAPT connects R to the C++ library behind the awesome apt, apt-get, apt-cache, commands (and their cache) which powering Debian, Ubuntu and other derivative distributions. RcppAPT allows you to query the (Debian or Ubuntu) package dependency graph at will, with build-dependencies (if you have deb-src entries), reverse dependencies, and all other goodies. See the vignette and examples for illustrations. This release moves the C++ compilation standard from C++11 to C++17. I had removed the setting for C++11 last year as compilation by compiler default worked well enough. But the version at CRAN still carried, which started to lead to build failures on Debian unstable so it was time for an update. And rather than implicitly relying on C++17 as selected by the last two R releases, we made it explicit. Otherwise a few of the regular package and repository updates have been made, but no new code or features were added The NEWS entries follow.

Changes in version 0.0.10 (2024-11-29)
  • Package maintenance updating continuous integration script versions as well as coverage link from README, and switching to Authors@R
  • C++ compilation standards updated to C++17 to comply with libapt-pkg

Courtesy of my CRANberries, there is also a diffstat report for this release. A bit more information about the package is available here as well as at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Raju Devidas: Finding all sub domains of a main domain

Problem: Need to know all the sub domains of a main domain, e.g. example.com has a sub domain dev.example.com , I also want to know other sub domains. Solution: Install the package called sublist3r, written by Ahmed Aboul-Ela
$ sudo apt install sublist3r
run the command
$ sublist3r -d example.com -o subdomains-example.com.txt
                 ____        _     _ _     _   _____
                / ___  _   _   __   (_)___   _ ___ / _ __
                \___ \        &apos_ \    / __  __   _ \  &apos__ 
                 ___)    _     _)     \__ \  _ ___)    
                 ____/ \__,_ _.__/ _ _ ___/\__ ____/ _ 
                # Coded By Ahmed Aboul-Ela - @aboul3la
[-] Enumerating subdomains now for example.com
[-] Searching now in Baidu..
[-] Searching now in Yahoo..
[-] Searching now in Google..
[-] Searching now in Bing..
[-] Searching now in Ask..
[-] Searching now in Netcraft..
[-] Searching now in DNSdumpster..
[-] Searching now in Virustotal..
[-] Searching now in ThreatCrowd..
[-] Searching now in SSL Certificates..
[-] Searching now in PassiveDNS..
Process DNSdumpster-8:
Traceback (most recent call last):
  File "/usr/lib/python3.12/multiprocessing/process.py", line 314, in _bootstrap
    self.run()
  File "/usr/lib/python3/dist-packages/sublist3r.py", line 269, in run
    domain_list = self.enumerate()
                  ^^^^^^^^^^^^^^^^
  File "/usr/lib/python3/dist-packages/sublist3r.py", line 649, in enumerate
    token = self.get_csrftoken(resp)
            ^^^^^^^^^^^^^^^^^^^^^^^^
  File "/usr/lib/python3/dist-packages/sublist3r.py", line 644, in get_csrftoken
    token = csrf_regex.findall(resp)[0]
            ~~~~~~~~~~~~~~~~~~~~~~~~^^^
IndexError: list index out of range
[!] Error: Google probably now is blocking our requests
[~] Finished now the Google Enumeration ...
[!] Error: Virustotal probably now is blocking our requests
[-] Saving results to file: subdomains-example.com.txt
[-] Total Unique Subdomains Found: 7
AS207960 Test Intermediate - example.com
www.example.com
dev.example.com
m.example.com
products.example.com
support.example.com
m.testexample.com
We can see the subdomains listed at the end of the command output. enjoy, have fun, drink water!

Bits from Debian: Debian welcomes its new Outreachy interns

Outreachy logo Debian continues participating in Outreachy, and we're excited to announce that Debian has selected two interns for the Outreachy December 2024 - March 2025 round. Patrick Noblet Appiah will work on Automatic Indi-3rd-party driver update, mentored by Thorsten Alteholz. Divine Attah-Ohiemi will work on Making the Debian main website more attractive by switching to HuGo as site generator, mentored by Carsten Schoenert, Subin Siby and Thomas Lange.
Congratulations and welcome Patrick Noblet Appiah and Divine Attah-Ohiemi! From the official website: Outreachy provides three-month internships for people from groups traditionally underrepresented in tech. Interns work remotely with mentors from Free and Open Source Software (FOSS) communities on projects ranging from programming, user experience, documentation, illustration and graphical design, to data science. The Outreachy programme is possible in Debian thanks to the efforts of Debian developers and contributors who dedicate their free time to mentor students and outreach tasks, and the Software Freedom Conservancy's administrative support, as well as the continued support of Debian's donors, who provide funding for the internships. Join us and help extend Debian! You can follow the work of the Outreachy interns reading their blogs (they are syndicated in Planet Debian), and chat with us in the #debian-outreach IRC channel and mailing list.

Bits from Debian: Debian welcomes its new Outreachy interns

Outreachy logo Debian continues participating in Outreachy, and we're excited to announce that Debian has selected two interns for the Outreachy December 2024 - March 2025 round. Patrick Noblet Appiah will work on Automatic Indi-3rd-party driver update, mentored by Thorsten Alteholz. Divine Attah-Ohiemi will work on Making the Debian main website more attractive by switching to HuGo as site generator, mentored by Carsten Schoenert, Subin Siby and Thomas Lange.
Congratulations and welcome Patrick Noblet Appiah and Divine Attah-Ohiemi! From the official website: Outreachy provides three-month internships for people from groups traditionally underrepresented in tech. Interns work remotely with mentors from Free and Open Source Software (FOSS) communities on projects ranging from programming, user experience, documentation, illustration and graphical design, to data science. The Outreachy programme is possible in Debian thanks to the efforts of Debian developers and contributors who dedicate their free time to mentor students and outreach tasks, and the Software Freedom Conservancy's administrative support, as well as the continued support of Debian's donors, who provide funding for the internships. Join us and help extend Debian! You can follow the work of the Outreachy interns reading their blogs (they are syndicated in Planet Debian), and chat with us in the #debian-outreach IRC channel and mailing list.

Freexian Collaborators: Tryton 7.0 LTS reaches Debian trixie (by Mathias Behrle, Rapha l Hertzog and Anupa Ann Joseph)

Tryton is a FOSS software suite which is highly modular and scalable. Tryton along with its standard modules can provide a complete ERP solution or it can be used for specific functions of a business like accounting, invoicing etc. Debian packages for Tryton are being maintained by Mathias Behrle. You can follow him on Mastodon or get his help on Tryton related projects through MBSolutions (his own consulting company). Freexian has been sponsoring Mathias s packaging work on Tryton for a while, so that Debian gets all the quarterly bug fix releases as well as the security release in a timely manner.

About Tryton 7.0 LTS Lately Mathias has been busy packaging Tryton 7.0 LTS. As the LTS tag implies, this release is recommended for production deployments since it will be supported until November 2028. This release brings numerous bug fixes, performance improvements and various new features. As part of this work, 41 new Tryton modules and 3 dependency packages have been added to Debian, significantly broadening the options available to Debian users and improving integration with Tryton systems.

Running different versions of Tryton on different Debian releases To provide extended compatibility, a dedicated Tryton mirror is being managed and is available at https://debian.m9s.biz/debian/. This mirror hosts backports for all supported Tryton series, ensuring availability for a variety of Debian releases and deployment scenarios. These initiatives highlight MBSolutions technical contributions to the Tryton community, made possible by Freexian s financial backing. Together, we are advancing the Tryton ecosystem for Debian users.

26 November 2024

Emanuele Rocca: Building Debian packages The Right Way

There is more than one way to do it, but it seems that The Right Way to build Debian packages today is using sbuild with the unshare backend. The most common backend before the rise of unshare was schroot.
The official Debian Build Daemons have recently transitioned to using sbuild with unshare, providing a strong motivation to consider making the switch. Additionally the new approach means: (1) no need to configure schroot, and (2) no need to run the build as root.
Here are my notes about moving to the new setup, for future reference and in case they may be useful to others.
First I installed the required packages:
apt install sbuild mmdebstrap uidmap
Then I created the following script to update my chroots every night:
#!/bin/bash
for arch in arm64 armhf armel; do
    HOME=/tmp mmdebstrap --quiet --arch=$arch --include=ca-certificates --variant=buildd unstable \
        ~/.cache/sbuild/unstable-$arch.tar http://127.0.0.1:3142/debian
done
In the script, I m calling mmdebstrap with --quiet because I don t want to get any output on succesful execution. The script is running in cron with email notifications, and I only want to get a message if something goes south. I m setting HOME=/tmp for a similar reason: the unshare user does not have access to my actual home directory, and by default dpkg tries to use $HOME/.dpkg.cfg as the configuration file. By overriding HOME I avoid the following message to standard error:
dpkg: warning: failed to open configuration file '/home/ema/.dpkg.cfg' for reading: Permission denied
Then I added the following to my sbuild configuration file (~/.sbuildrc):
$chroot_mode = 'unshare';
$unshare_tmpdir_template = '/dev/shm/tmp.sbuild.XXXXXXXXXX';
The first option sets the sbuild backend to unshare, whereas unshare_tmpdir_template is needed on Bookworm to ensure that the build process runs in memory rather than on disk for performance reasons. Starting with Trixie, /tmp is by default a tmpfs so the setting won t be needed anymore.
Packages for different architectures can now be built as follows:
# Tarball used: ~/.cache/sbuild/unstable-arm64.tar
$ sbuild --dist=unstable hello
# Tarball used: ~/.cache/sbuild/unstable-armhf.tar
$ sbuild --dist=unstable --arch=armhf hello
If you have any comments or suggestions about any of this, please let me know.

Sandro Knau : Akademy 2024 in W rzburg

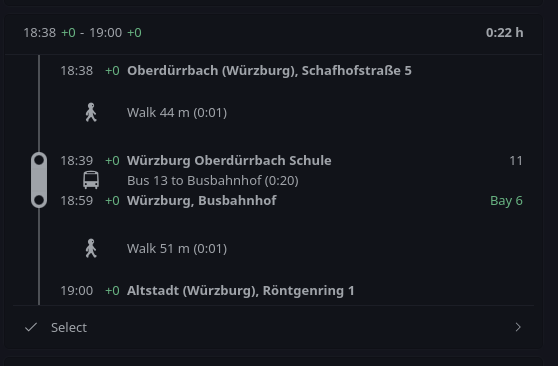
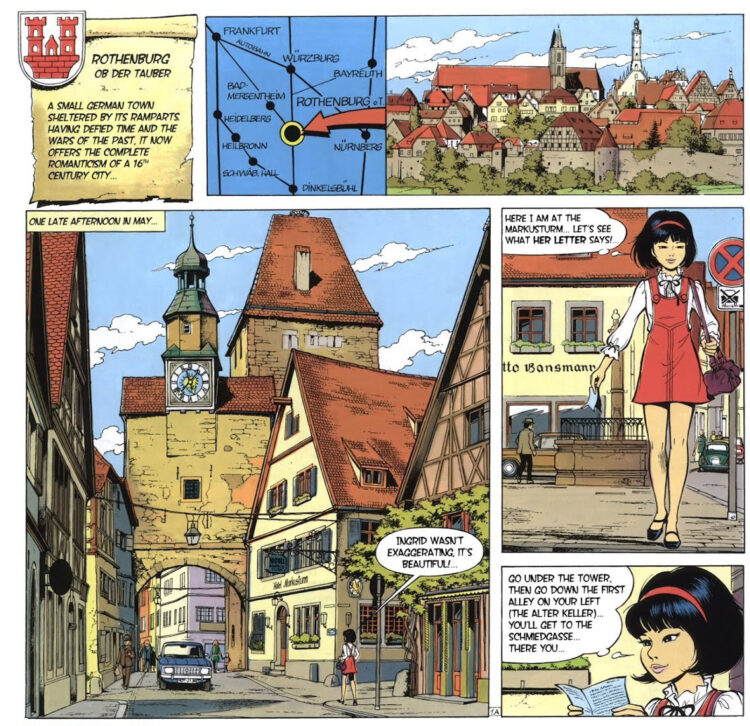
In order to prepare for the Akademy I started some days before to give my Librem 5 ( an Open Hardware Phone) another try and ended up with a non starting Plasma 6. Actually this issue was known already, but hasn't been addressed. In the end I reached the Akademy with my Librem 5 having phosh installed (which is Gnome based), in order to have something working. I met Bushan and Bart who took care and the issue was fixed two days later I could finally install Plasma 6 on it. The last time I tested my Librem 5 with Plasma 5 it felt sluggish and not well working. But this time I was impressed how well the system reacts. Sure there are some things here and there, but in the bigger picture it is quite useable. One annoying issue is that the camera is only working with one app and the other issue is the battery capacity, you have to charge it once a day. Because of missing a QR reader that can use the camera, getting data to the phone was quite challenging. Unfortunately the conference Wifi separated the devices and I couldn't use KDE Connect to transfer data. In the end the only way to import data was taking five photos from the QR Code to import my D-Ticket to Itinerary. With a device with Plasma Mobile, it directly was used for a experiment: How well does Dolphin works on a Plasma Mobile device. Together with Felix Ernst we tried it out and were quite impressed, that Dolphin does work very well on Plasma Mobile, after some simple modifications on the UI. That resulted in a patch to add a mobile UI for Dolphin !826. With more time to play with my Librem 5 I also found an bug in KWeather, that is missing a Refresh option, when used in a Plasma Mobile environment #493656. Akademy is a good place to identify and solve some issues. It is always like that, you chat with someone and they can tell you who to ask to answer the concrete question and in the end you can solve things, that seems unsolvable in the beginning. There was also time to look into the travelling app Itinerary. A lot people are faced with a lot of real world issues, when not in their home town. Itinerary is the best traveling apps I know about. It can import nearly every ticket you have and can get location information from restaurant websites and allow routing to that place. It does add many useful information, while traveling like current delays, platform changes, live updates for elevator, weather information at the destination, a station map and all those features with strong focus on privacy. In detail I found some small things to improve: I additionally learned that it has a lot of details that helps people who have special needs. That is the reason why Daniel Kraut wants to get Itinerary available for iOS. As spoken out, that Daniel wants to reach this goal, others already started to implement the first steps to build apps for iOS. This year I was volunteering in helping out at Akademy. For me it was a lot of fun to meet everyone at the infodesk or help the speakers setup the beamer and microphone. It is also a good opportunity to meet many new faces and get in contact with them. I see also room for improvement. As we were quite busy at the Welcome Event to get out the badges to everyone, I couldn't answer the questions from newcomers, as the queue was too long. I propose that some people volunteer to be available for questions from newcomers. Often it is hard for newcomers to get their first contact(s) in a new community. There is a lot of space for improvement to make it easier for newcomers to join. Some ideas in my head are: Make an event for the newcomers to get them some links into the community and show that everyone is friendly. The tables at the BoFs should make a circle, so everyone can see each other. It was also hard for me to understand everyone as they mostly spoken towards the front. And then BoFs are sometimes full of very specific words and if you are not already deep in the topic you are lost. I can see the problem, on the one side BoFs are also the place where the person that knows the topic already wants to get things done. On the other side new comers join BoFs, are overwhelmed by to many new words get frustrated and think, that they are not welcome. Maybe at least everyone should present itself with name and ask new faces, why they joined the BoF to help them joining. I'm happy, that the food provided for the attendees was very delicious and that I'm not the only one mostly vegetarian with a big amount to be vegan. At the conference the KDE Eco initiation really caught me, as I see a lot of new possibilities in giving more reasons to switch to an Open Source system. The talk from Natalie was great to see how pupils get excited about Open Source and also help their grandparents to move to a Linux system. As I also will start to work as a teacher, I really got ideas what I can do at school. Together with Joseph and Nicole, we finally started to think about how to drive an exploration on what kind of old hardware is still KDE software running. The ones with the oldest hardware will get an old KDE shirt. For more information see #40. The conference was very motivating for me, I also had still energy at the evening to do some Debian packaging and finally pushed kweathercore to Debian and started to work on KWeather. Now I'm even more interested in the KDE apps focusing the mobile world, as I now have some hardware that can actually use those apps. I really enjoyed the workshop how to contribute to Qt by Volker Hilsheimer, especially the way how Volker explained things in a very friendly way, answered every question, sometime postponed some questions but came back to them later. All in all I now have a good overview how Qt is doing development and how I can fix bugs. The daytrip to Rothenburg ob der Tauber was very interesting for me. It was the first time I visited the village. But in my memory it feels like I know the village already. I grew up with reading a lot of comic albums including the good SiFi comic album series "Yoku Tsuno" created by the Belgian writer Roger Leloup. Yoku Tsuno is an electronics engineer, raised in Japan but now living in Belgium. In "On the edge of life" she helps her friend Ingard, who actually lives in Rothenburg. Leloup invested a lot of time to travel to make the make his drawings as accurate as possible. a comic page with Yoko Tsuno in Rothenburg ob der Tauber In order to not have a hard cut from Akademy to normal life, I had a lunch with Carlos, to discuss KDE Neon and how we can improve the interaction with Debian. In the future this should have less friction and make both communities work together more smoothly. Additionally as I used to develop on KDEPIM with the help of Docker images based on Neon I ask for a meta kf6 dev meta package. That should help to get rid of most hand written lists of dev packages in the Docker file in order to make it more simple for new contributors to start hacking on KDEPIM. The rest of the day I finally found time to do the normal tourist stuff: Going to the Wine bridge and having a walk to the castle of W rzburg. Unfortunately you hear a lot of car noises up there, but I could finally relaxe in a Japanese designed garden. Finally at Saturday I started my trip back. The trains towards Eberswalde are broken and I needed to find alternative routing. I got a little bit nervous, as it was the first time I travelled with my Librem 5 and Itinerary only and needed to reach the next train in less than two mins. With the indoor maps provided, I could prepare my run through the train station so I reached successfully my next train. By the way, also if you only only use KDE software, I would recommend everyone to join Akademy ;)

22 November 2024

Matthew Palmer: Your Release Process Sucks

For the past decade-plus, every piece of software I write has had one of two release processes. Software that gets deployed directly onto servers (websites, mostly, but also the infrastructure that runs Pwnedkeys, for example) is deployed with nothing more than git push prod main. I ll talk more about that some other day. Today is about the release process for everything else I maintain Rust / Ruby libraries, standalone programs, and so forth. To release those, I use the following, extremely intricate process:
  1. Create an annotated git tag, where the name of the tag is the software version I m releasing, and the annotation is the release notes for that version.
  2. Run git release in the repository.
  3. There is no step 3.
Yes, it absolutely is that simple. And if your release process is any more complicated than that, then you are suffering unnecessarily. But don t worry. I m from the Internet, and I m here to help.

Sidebar: annotated what-now?!? The annotated tag is one git s best-kept secrets. They ve been available in git for practically forever (I ve been using them since at least 2014, which is practically forever in software development), yet almost everyone I mention them to has never heard of them. A tag , in git parlance, is a repository-unique named label that points to a single commit (as identified by the commit s SHA1 hash). Annotating a tag is simply associating a block of free-form text with that tag. Creating an annotated tag is simple-sauce: git tag -a tagname will open up an editor window where you can enter your annotation, and git tag -a -m "some annotation" tagname will create the tag with the annotation some annotation . Retrieving the annotation for a tag is straightforward, too: git show tagname will display the annotation along with all the other tag-related information. Now that we know all about annotated tags, let s talk about how to use them to make software releases freaking awesome.

Step 1: Create the Annotated Git Tag As I just mentioned, creating an annotated git tag is pretty simple: just add a -a (or --annotate, if you enjoy typing) to your git tag command, and WHAM! annotation achieved. Releases, though, typically have unique and ever-increasing version numbers, which we want to encode in the tag name. Rather than having to look at the existing tags and figure out the next version number ourselves, we can have software do the hard work for us. Enter: git-version-bump. This straightforward program takes one mandatory argument: major, minor, or patch, and bumps the corresponding version number component in line with Semantic Versioning principles. If you pass it -n, it opens an editor for you to enter the release notes, and when you save out, the tag is automagically created with the appropriate name. Because the program is called git-version-bump, you can call it as a git command: git version-bump. Also, because version-bump is long and unwieldy, I have it aliased to vb, with the following entry in my ~/.gitconfig:
[alias]
    vb = version-bump -n
Of course, you don t have to use git-version-bump if you don t want to (although why wouldn t you?). The important thing is that the only step you take to go from here is our current codebase in main to everything as of this commit is version X.Y.Z of this software , is the creation of an annotated tag that records the version number being released, and the metadata that goes along with that release.

Step 2: Run git release As I said earlier, I ve been using this release process for over a decade now. So long, in fact, that when I started, GitHub Actions didn t exist, and so a lot of the things you d delegate to a CI runner these days had to be done locally, or in a more ad-hoc manner on a server somewhere. This is why step 2 in the release process is run git release . It s because historically, you can t do everything in a CI run. Nowadays, most of my repositories have this in the .git/config:
[alias]
    release = push --tags
Older repositories which, for one reason or another, haven t been updated to the new hawtness, have various other aliases defined, which run more specialised scripts (usually just rake release, for Ruby libraries), but they re slowly dying out. The reason why I still have this alias, though, is that it standardises the release process. Whether it s a Ruby gem, a Rust crate, a bunch of protobuf definitions, or whatever else, I run the same command to trigger a release going out. It means I don t have to think about how I do it for this project, because every project does it exactly the same way.

The Wiring Behind the Button
It wasn t the button that was the problem. It was the miles of wiring, the hundreds of miles of cables, the circuits, the relays, the machinery. The engine was a massive, sprawling, complex, mind-bending nightmare of levers and dials and buttons and switches. You couldn t just slap a button on the wall and expect it to work. But there should be a button. A big, fat button that you could press and everything would be fine again. Just press it, and everything would be back to normal.
  • Red Dwarf: Better Than Life
Once you ve accepted that your release process should be as simple as creating an annotated tag and running one command, you do need to consider what happens afterwards. These days, with the near-universal availability of CI runners that can do anything you need in an isolated, reproducible environment, the work required to go from annotated tag to release artifacts can be scripted up and left to do its thing. What that looks like, of course, will probably vary greatly depending on what you re releasing. I can t really give universally-applicable guidance, since I don t know your situation. All I can do is provide some of my open source work as inspirational examples. For starters, let s look at a simple Rust crate I ve written, called strong-box. It s a straightforward crate, that provides ergonomic and secure cryptographic functionality inspired by the likes of NaCl. As it s just a crate, its release script is very straightforward. Most of the complexity is working around Cargo s inelegant mandate that crate version numbers are specified in a TOML file. Apart from that, it s just a matter of building and uploading the crate. Easy! Slightly more complicated is action-validator. This is a Rust CLI tool which validates GitHub Actions and Workflows (how very meta) against a published JSON schema, to make sure you haven t got any syntax or structural errors. As not everyone has a Rust toolchain on their local box, the release process helpfully build binaries for several common OSes and CPU architectures that people can download if they choose. The release process in this case is somewhat larger, but not particularly complicated. Almost half of it is actually scaffolding to build an experimental WASM/NPM build of the code, because someone seemed rather keen on that. Moving away from Rust, and stepping up the meta another notch, we can take a look at the release process for git-version-bump itself, my Ruby library and associated CLI tool which started me down the Just Tag It Already rabbit hole many years ago. In this case, since gemspecs are very amenable to programmatic definition, the release process is practically trivial. Remove the boilerplate and workarounds for GitHub Actions bugs, and you re left with about three lines of actual commands. These approaches can certainly scale to larger, more complicated processes. I ve recently implemented annotated-tag-based releases in a proprietary software product, that produces Debian/Ubuntu, RedHat, and Windows packages, as well as Docker images, and it takes all of the information it needs from the annotated tag. I m confident that this approach will successfully serve them as they expand out to build AMIs, GCP machine images, and whatever else they need in their release processes in the future.

Objection, Your Honour! I can hear the howl of the but, actuallys coming over the horizon even as I type. People have a lot of Big Feelings about why this release process won t work for them. Rather than overload this article with them, I ve created a companion article that enumerates the objections I ve come across, and answers them. I m also available for consulting if you d like a personalised, professional opinion on your specific circumstances.

DVD Bonus Feature: Pre-releases Unless you re addicted to surprises, it s good to get early feedback about new features and bugfixes before they make it into an official, general-purpose release. For this, you can t go past the pre-release. The major blocker to widespread use of pre-releases is that cutting a release is usually a pain in the behind. If you ve got to edit changelogs, and modify version numbers in a dozen places, then you re entirely justified in thinking that cutting a pre-release for a customer to test that bugfix that only occurs in their environment is too much of a hassle. The thing is, once you ve got releases building from annotated tags, making pre-releases on every push to main becomes practically trivial. This is mostly due to another fantastic and underused Git command: git describe. How git describe works is, basically, that it finds the most recent commit that has an associated annotated tag, and then generates a string that contains that tag s name, plus the number of commits between that tag and the current commit, with the current commit s hash included, as a bonus. That is, imagine that three commits ago, you created an annotated release tag named v4.2.0. If you run git describe now, it will print out v4.2.0-3-g04f5a6f (assuming that the current commit s SHA starts with 04f5a6f). You might be starting to see where this is going. With a bit of light massaging (essentially, removing the leading v and replacing the -s with .s), that string can be converted into a version number which, in most sane environments, is considered newer than the official 4.2.0 release, but will be superceded by the next actual release (say, 4.2.1 or 4.3.0). If you re already injecting version numbers into the release build process, injecting a slightly different version number is no work at all. Then, you can easily build release artifacts for every commit to main, and make them available somewhere they won t get in the way of the official releases. For example, in the proprietary product I mentioned previously, this involves uploading the Debian packages to a separate component (prerelease instead of main), so that users that want to opt-in to the prerelease channel simply modify their sources.list to change main to prerelease. Management have been extremely pleased with the easy availability of pre-release packages; they ve been gleefully installing them willy-nilly for testing purposes since I rolled them out. In fact, even while I ve been writing this article, I was asked to add some debug logging to help track down a particularly pernicious bug. I added the few lines of code, committed, pushed, and went back to writing. A few minutes later (next week s job is to cut that in-process time by at least half), the person who asked for the extra logging ran apt update; apt upgrade, which installed the newly-built package, and was able to progress in their debugging adventure. Continuous Delivery: It s Not Just For Hipsters.

+1, Informative Hopefully, this has spurred you to commit your immortal soul to the Church of the Annotated Tag. You may tithe by buying me a refreshing beverage. Alternately, if you re really keen to adopt more streamlined release management processes, I m available for consulting engagements.

Matthew Palmer: Invalid Excuses for Why Your Release Process Sucks

In my companion article, I made the bold claim that your release process should consist of no more than two steps:
  1. Create an annotated Git tag;
  2. Run a single command to trigger the release pipeline.
As I have been on the Internet for more than five minutes, I m aware that a great many people will have a great many objections to this simple and straightforward idea. In the interests of saving them a lot of wear and tear on their keyboards, I present this list of common reasons why these objections are invalid. If you have an objection I don t cover here, the comment box is down the bottom of the article. If you think you ve got a real stumper, I m available for consulting engagements, and if you turn out to have a release process which cannot feasibly be reduced to the above two steps for legitimate technical reasons, I ll waive my fees.

But I automatically generate my release notes from commit messages! This one is really easy to solve: have the release note generation tool feed directly into the annotation. Boom! Headshot.

But all these files need to be edited to make a release! No, they absolutely don t. But I can see why you might think you do, given how inflexible some packaging environments can seem, and since that s how we ve always done it .

Language Packages Most languages require you to encode the version of the library or binary in a file that you want to revision control. This is teh suck, but I m yet to encounter a situation that can t be worked around some way or another. In Ruby, for instance, gemspec files are actually executable Ruby code, so I call code (that s part of git-version-bump, as an aside) to calculate the version number from the git tags. The Rust build tool, Cargo, uses a TOML file, which isn t as easy, but a small amount of release automation is used to take care of that.

Distribution Packages If you re building Linux distribution packages, you can easily apply similar automation faffery. For example, Debian packages take their metadata from the debian/changelog file in the build directory. Don t keep that file in revision control, though: build it at release time. Everything you need to construct a Debian (or RPM) changelog is in the tag version numbers, dates, times, authors, release notes. Use it for much good.

The Dreaded Changelog Finally, there s the CHANGELOG file. If it s maintained during the development process, it typically has an archive of all the release notes, under version numbers, with an Unreleased heading at the top. It s one more place to remember to have to edit when making that preparing release X.Y.Z commit, and it is a gift to the Demon of Spurious Merge Conflicts if you follow the policy of every commit must add a changelog entry . My solution: just burn it to the ground. Add a line to the top with a link to wherever the contents of annotated tags get published (such as GitHub Releases, if that s your bag) and never open it ever again.

But I need to know other things about my release, too! For some reason, you might think you need some other metadata about your releases. You re probably wrong it s amazing how much information you can obtain or derive from the humble tag so think creatively about your situation before you start making unnecessary complexity for yourself. But, on the off chance you re in a situation that legitimately needs some extra release-related information, here s the secret: structured annotation. The annotation on a tag can be literally any sequence of octets you like. How that data is interpreted is up to you. So, require that annotations on release tags use some sort of structured data format (say YAML or TOML or even XML if you hate your release manager), and mandate that it contain whatever information you need. You can make sure that the annotation has a valid structure and contains all the information you need with an update hook, which can reject the tag push if it doesn t meet the requirements, and you re sorted.

But I have multiple packages in my repo, with different release cadences and versions! This one is common enough that I just refer to it as the monorepo drama . Personally, I m not a huge fan of monorepos, but you do you, boo. Annotated tags can still handle it just fine. The trick is to include the package name being released in the tag name. So rather than a release tag being named vX.Y.Z, you use foo/vX.Y.Z, bar/vX.Y.Z, and baz/vX.Y.Z. The release automation for each package just triggers on tags that match the pattern for that particular package, and limits itself to those tags when figuring out what the version number is.

But we don t semver our releases! Oh, that s easy. The tag pattern that marks a release doesn t have to be vX.Y.Z. It can be anything you want. Relatedly, there is a (rare, but existent) need for packages that don t really have a conception of releases in the traditional sense. The example I ve hit most often is automatically generated bindings packages, such as protobuf definitions. The source of truth for these is a bunch of .proto files, but to be useful, they need to be packaged into code for the various language(s) you re using. But those packages need versions, and while someone could manually make releases, the best option is to build new per-language packages automatically every time any of those definitions change. The versions of those packages, then, can be datestamps (I like something like YYYY.MM.DD.N, where N starts at 0 each day and increments if there are multiple releases in a single day). This process allows all the code that needs the definitions to declare the minimum version of the definitions that it relies on, and everything is kept in sync and tracked almost like magic.

Th-th-th-th-that s all, folks! I hope you ve enjoyed this bit of mild debunking. Show your gratitude by buying me a refreshing beverage, or purchase my professional expertise and I ll answer all of your questions and write all your CI jobs.

20 November 2024

Ian Jackson: The Rust Foundation's 2nd bad draft trademark policy

tl;dr: The Rust Foundation s new trademark policy still forbids unapproved modifications: this would forbid both the Rust Community s own development work(!) and normal Free Software distribution practices. Background In April 2023 I wrote about the Rust Foundation s ham-fisted and misguided attempts to update the Rust trademark policy. This turned into drama. The new draft Recently, the Foundation published a new draft. It s considerably less bad, but the most serious problem, which I identified last year, remains. It prevents redistribution of modified versions of Rust, without pre-approval from the Rust Foundation. (Subject to some limited exceptions.) The people who wrote this evidently haven t realised that distributing modified versions is how free software development works. Ie, the draft Rust trademark policy even forbids making a github branch for an MR to contribute to Rust! It s also very likely unacceptable to Debian. Rust is still on track to repeat the Firefox/Iceweasel debacle. Below is a copy of my formal response to the consultation. The consultation closes at 07:59:00 UTC tomorrow (21st November), ie, at the end of today (Wednesday) US Pacific time, so if you want to reply, do so quickly. My consultation response
Hi. My name is Ian Jackson. I write as a Rust contributor and as a Debian Developer with first-hand experience of Debian s approach to trademarks. (But I am not a member of the Debian Rust Packaging Team.) Your form invites me to state any blocking concerns. I m afraid I have one: PROBLEM The policy on distributing modified versions of Rust (page 4, 8th bullet) is far too restrictive. PROBLEM - ASPECT 1 On its face the policy forbids making a clone of the Rust repositories on a git forge, and pushing a modified branch there. That is publicly distributing a modified version of Rust. I.e., the current policy forbids the Rust s community s own development workflow! PROBLEM - ASPECT 2 The policy also does not meet the needs of Software-Freedom-respecting downstreams, including community Linux distributions such as Debian. There are two scenarios (fuzzy, and overlapping) which provide a convenient framing to discuss this: Firstly, in practical terms, Debian may need to backport bugfixes, or sometimes other changes. Sometimes Debian will want to pre-apply bugfixes or changes that have been contributed by users, and are intended eventually to go upstream, but are not included upstream in official Rust yet. This is a routine activity for a distribution. The policy, however, forbids it. Secondly, Debian, as a point of principle, requires the ability to diverge from upstream if and when Debian decides that this is the right choice for Debian s users. The freedom to modify is a key principle of Free Software. This includes making changes that the upstream project disapproves of. Some examples of this, where Debian has made changes, that upstream do not approve of, have included things like: removing user-tracking code, or disabling obsolescence timebombs that stop a particular version working after a certain date. Overall, while alignment in values between Debian and Rust seems to be very good right now, modifiability it is a matter of non-negotiable principle for Debian. The 8th bullet point on page 4 of the PDF does not give Debian (and Debian s users) these freedoms. POSSIBLE SOLUTIONS Other formulations, or an additional permission, seem like they would be able to meet the needs of both Debian and Rust. The first thing to recognise is that forbidding modified versions is probably not necessary to prevent language ecosystem fragmentation. Many other programming languages are distributed under fully Free Software licences without such restrictive trademark policies. (For example, Python; I m sure a thorough survey would find many others.) The scenario that would be most worrying for Rust would be embrace - extend - extinguish . In projects with a copyleft licence, this is not a concern, but Rust is permissively licenced. However, one way to address this would be to add an additional permission for modification that permits distribution of modified versions without permission, but if the modified source code is also provided, under the original Rust licence. I suggest therefore adding the following 2nd sub-bullet point to the 8th bullet on page 4:
  • changes which are shared, in source code form, with all recipients of the modified software, and publicly licenced under the same licence as the official materials.
This means that downstreams who fear copyleft have the option of taking Rust s permissive copyright licence at face value, but are limited in the modifications they may make, unless they rename. Conversely downstreams such as Debian who wish to operate as part of the Free Software ecosystem can freely make modifications. It also, obviously, covers the Rust Community s own development work. NON-SOLUTIONS Some upstreams, faced with this problem, have offered Debian a special permission: ie, said that it would be OK for Debian to make modifications that Debian wants to. But Debian will not accept any Debian-specific permissions. Debian could of course rename their Rust compiler. Debian has chosen to rename in the past: infamously, a similar policy by Mozilla resulted in Debian distributing Firefox under the name Iceweasel for many years. This is a PR problem for everyone involved, and results in a good deal of technical inconvenience and makework. Debian could seek approval for changes, and the Rust Foundation would grant that approval quickly . This is unworkable on a practical level - requests for permission do not fit into Debian s workflow, and the resulting delays would be unacceptable. But, more fundamentally, Debian rightly insists that it must have the freedom to make changes that the Foundation do not approve of. (For example, if a future Rust shipped with telemetry features Debian objected to.) Debian and Rust could compromise . However, Debian is an ideological as well as technological project. The principles I have set out are part of Debian s Foundation Documents - they are core values for Debian. When Debian makes compromises, it does so very slowly and with great deliberation, using its slowest and most heavyweight constitutional governance processes. Debian is not likely to want to engage in such a process for the benefit of one programming language. Users will get Rust from upstream . This is currently often the case. Right now, Rust is moving very quickly, and by Debian standards is very new. As Rust becomes more widely used, more stable, and more part of the infrastructure of the software world, it will need to become part of standard, stable, reliable, software distributions. That means Debian.
(The consultation was a Google Forms page with a single text field, so the formatting isn t great. I have edited the formatting very lightly to avoid rendering bugs here on my blog.)

comment count unavailable comments

Russell Coker: Solving Spam and Phishing for Corporations

Centralisation and Corporations An advantage of a medium to large company is that it permits specialisation. For example I m currently working in the IT department of a medium sized company and because we have standardised hardware (Dell Latitude and Precision laptops, Dell Precision Tower workstations, and Dell PowerEdge servers) and I am involved in fixing all Linux compatibility issues on that I can fix most problems in a small fraction of the time that I would take to fix on a random computer. There is scope for a lot of debate about the extent to which companies should standardise and centralise things. But for computer problems which can escalate quickly from minor to serious if not approached in the correct manner it s clear that a good deal of centralisation is appropriate. For people doing technical computer work such as programming there s a large portion of the employees who are computer hobbyists who like to fiddle with computers. But if the support system is run well even they will appreciate having computers just work most of the time and for a large portion of the failures having someone immediately recognise the problem, like the issues with NVidia drivers that I have documented so that first line support can implement workarounds without the need for a lengthy investigation. A big problem with email in the modern Internet is the prevalence of Phishing scams. The current corporate approach to this is to send out test Phishing email to people and then force computer security training on everyone who clicks on them. One problem with this is that attackers only need to fool one person on one occasion and when you have hundreds of people doing something on rare occasions that s not part of their core work they will periodically get it wrong. When every test Phishing run finds several people who need extra training it seems obvious to me that this isn t a solution that s working well. I will concede that the majority of people who click on the test Phishing email would probably realise their mistake if asked to enter the password for the corporate email system, but I think it s still clear that this isn t a great solution. Let s imagine for the sake of discussion that everyone in a company was 100% accurate at identifying Phishing email and other scam email, if that was the case would the problem be solved? I believe that even in that hypothetical case it would not be a solved problem due to the wasted time and concentration. People can spend minutes determining if a single email is legitimate. On many occasions I have had relatives and clients forward me email because they are unsure if it s valid, it s great that they seek expert advice when they are unsure about things but it would be better if they didn t have to go to that effort. What we ideally want to do is centralise the anti-Phishing and anti-spam work to a small group of people who are actually good at it and who can recognise patterns by seeing larger quantities of spam. When a spam or Phishing message is sent to 600 people in a company you don t want 600 people to individually consider it, you want one person to recognise it and delete/block all 600. If 600 people each spend one minute considering the matter then that s 10 work hours wasted! The Rationale for Human Filtering For personal email human filtering usually isn t viable because people want privacy. But corporate email isn t private, it s expected that the company can read it under certain circumstances (in most jurisdictions) and having email open in public areas of the office where colleagues might see it is expected. You can visit gmail.com on your lunch break to read personal email but every company policy (and common sense) says to not have actually private correspondence on company systems. The amount of time spent by reception staff in sorting out such email would be less than that taken by individuals. When someone sends a spam to everyone in the company instead of 500 people each spending a couple of minutes working out whether it s legit you have one person who s good at recognising spam (because it s their job) who clicks on a remove mail from this sender from all mailboxes button and 500 messages are deleted and the sender is blocked. Delaying email would be a concern. It s standard practice for CEOs (and C*Os at larger companies) to have a PA receive their email and forward the ones that need their attention. So human vetting of email can work without unreasonable delays. If we had someone checking all email for the entire company probably email to the senior people would never get noticeably delayed and while people like me would get their mail delayed on occasion people doing technical work generally don t have notifications turned on for email because it s a distraction and a fast response isn t needed. There are a few senders where fast response is required, which is mostly corporations sending a click this link within 10 minutes to confirm your password change email. Setting up rules for all such senders that are relevant to work wouldn t be difficult to do. How to Solve This Spam and Phishing became serious problems over 20 years ago and we have had 20 years of evolution of email filtering which still hasn t solved the problem. The vast majority of email addresses in use are run by major managed service providers and they haven t managed to filter out spam/phishing mail effectively so I think we should assume that it s not going to be solved by filtering. There is talk about what AI technology might do for filtering spam/phishing but that same technology can product better crafted hostile email to avoid filters. An additional complication for corporate email filtering is that some criteria that are used to filter personal email don t apply to corporate mail. If someone sends email to me personally about millions of dollars then it s obviously not legit. If someone sends email to a company then it could be legit. Companies routinely have people emailing potential clients about how their products can save millions of dollars and make purchases over a million dollars. This is not a problem that s impossible to solve, it s just an extra difficulty that reduces the efficiency of filters. It seems to me that the best solution to the problem involves having all mail filtered by a human. A company could configure their mail server to not accept direct external mail for any employee s address. Then people could email files to colleagues etc without any restriction but spam and phishing wouldn t be a problem. The issue is how to manage inbound mail. One possibility is to have addresses of the form it+russell.coker@example.com (for me as an employee in the IT department) and you would have a team of people who would read those mailboxes and forward mail to the right people if it seemed legit. Having addresses like it+russell.coker means that all mail to the IT department would be received into folders of the same account and they could be filtered by someone with suitable security level and not require any special configuration of the mail server. So the person who read the is mailbox would have a folder named russell.coker receiving mail addressed to me. The system could be configured to automate the processing of mail from known good addresses (and even domains), so they could just put in a rule saying that when Dell sends DMARC authenticated mail to is+$USER it gets immediately directed to $USER. This is the sort of thing that can be automated in the email client (mail filtering is becoming a common feature in MUAs). For a FOSS implementation of such things the server side of it (including extracting account data from a directory to determine which department a user is in) would be about a day s work and then an option would be to modify a webmail program to have extra functionality for approving senders and sending change requests to the server to automatically direct future mail from the same sender. As an aside I have previously worked on a project that had a modified version of the Horde webmail system to do this sort of thing for challenge-response email and adding certain automated messages to the allow-list. The Change One of the first things to do is configuring the system to add every recipient of an outbound message to the allow list for receiving a reply. Having a script go through the sent-mail folders of all accounts and adding the recipients to the allow lists would be easy and catch the common cases. But even with processing the sent mail folders going from a working system without such things to a system like this will take some time for the initial work of adding addresses to the allow lists, particularly for domain wide additions of all the sites that send password confirmation messages. You would need rules to direct inbound mail to the old addresses to the new style and then address a huge amount of mail that needs to be categorised. If you have 600 employees and the average amount of time taken on the first day is 10 minutes per user then that s 100 hours of work, 12 work days. If you had everyone from the IT department, reception, and executive assistants working on it that would be viable. After about a week there wouldn t be much work involved in maintaining it. Then after that it would be a net win for the company. The Benefits If the average employee spends one minute a day dealing with spam and phishing email then with 600 employees that s 10 hours of wasted time per day. Effectively wasting one employee s work! I m sure that s the low end of the range, 5 minutes average per day doesn t seem unreasonable especially when people are unsure about phishing email and send it to Slack so multiple employees spend time analysing it. So you could have 5 employees being wasted by hostile email and avoiding that would take a fraction of the time of a few people adding up to less than an hour of total work per day. Then there s the training time for phishing mail. Instead of having every employee spend half an hour doing email security training every few months (that s 300 hours or 7.5 working weeks every time you do it) you just train the few experts. In addition to saving time there are significant security benefits to having experts deal with possibly hostile email. Someone who deals with a lot of phishing email is much less likely to be tricked. Will They Do It? They probably won t do it any time soon. I don t think it s expensive enough for companies yet. Maybe government agencies already have equivalent measures in place, but for regular corporations it s probably regarded as too difficult to change anything and the costs aren t obvious. I have been unsuccessful in suggesting that managers spend slightly more on computer hardware to save significant amounts of worker time for 30 years.

Next.

Previous.