Search Results: "reg"

16 October 2010

David Paleino: How to: database-less local map rendering with Mapnik and OSM

Here's a quick howto for local map rendering, using python, mapnik and data from OpenStreetMap. This tutorial shows how to create a stylesheet for mapnik from scratch, if you're looking for how to tweak OpenStreetMap's mapnik rendering, I plan to write a tutorial on PostGIS-driven rendering at a later time. This post is not for those who want to make a local slippy map, nor those who want to render different areas of big dumps (think of big national dumps). We'll render some features of a residential area of a city with buildings mapped. We'll get a small dump of the area for this, using the XAPI. First, you need to install mapnik. On Debian-like systems, it should be as easy as:
# apt-get install python-mapnik
Then, you need some python code to use the mapnik library. Let's call it render.py:
#!/usr/bin/python
import mapnik
###
# Configuration
###
style = 'style.xml'
output = 'output.svg'
width = 1280
height = 800
bbox = '12.58664,37.65759,12.5945,37.66325'
###
# Don't touch below!
###
bbox = bbox.split(',')
ll = mapnik.Coord(float(bbox[0]), float(bbox[1]))
tr = mapnik.Coord(float(bbox[2]), float(bbox[3]))
mymap = mapnik.Map(width, height)
mapnik.load_map(mymap, style)
map_bbox = mapnik.Envelope(ll, tr)
mymap.zoom_to_box(map_bbox)
mapnik.render_to_file(mymap, output)
For the purposes of this post, we're going to create a 1280x800 map -- adjust that to suit your needs -- and we specified a bounding box corresponding to that area. That's composed as west,south,east,north coordinates. Be sure to get them right :-). Now we need to write a Mapnik stylesheet, we'll call it style.xml. That's a XML document, you can find the documentation at the official website. The skeleton of a stylesheet is as follows:
<?xml version="1.0" encoding="utf-8"?>
<!DOCTYPE Map>
<Map bgcolor="lightblue" srs="+proj=latlong +datum=WGS84">
<Style name="...">
...
</Style>
<Layer name="...">
 <Datasource>
  ...
 </Datasource>
</Layer>
</Map>
The stylesheet has an arbitrary number of Style elements and an arbitrary number of Layer elements. The former class of elements define the appearance of the features, while the latter defines where to get data from. Each layer has a Datasource child: here's where you say where to get your data from. We're going to use the osm input plugin, which lets you parse the dump directly. This has some drawbacks: But works great for small dumps. In this tutorial, we want to pretty render a residential area, so we first need to render the road network. This will mainly be made of highway=residential roads. Each style can have one or more Rule element. These define what elements that particular style should apply to. Each rule can have different rendering settings. The given dump has different roads: residential, unclassified, tertiary and secondary. Let's add a rule for each. Here's the first of them:
<Rule>
 <Filter>[highway] = 'residential'</Filter>
 <LineSymbolizer>
  <CssParameter name="stroke">#ffffff</CssParameter>
  <CssParameter name="stroke-width">5</CssParameter>
  <CssParameter name="stroke-linejoin">round</CssParameter>
  <CssParameter name="stroke-linecap">round</CssParameter>
 </LineSymbolizer>
 <TextSymbolizer name="name" face_name="DejaVu Sans Book" size="8" fill="#000" halo_radius="1" spacing="300" placement="line" />
</Rule>
It is quite straightforward: you define what elements the rule should apply to, and then add some symbolizer. For a detailed description of each symbolizer, please read the documentation. The example dump also has a railway and some steps. To render them, we use the stroke-dasharray property:
<Rule>
 <Filter>[highway] = 'steps'</Filter>
 <LineSymbolizer>
  <CssParameter name="stroke">#ff0000</CssParameter>
  <CssParameter name="stroke-width">5.0</CssParameter>
  <CssParameter name="stroke-dasharray">2,1</CssParameter>
 </LineSymbolizer>
</Rule>
<Rule>
 <Filter>[railway] = 'rail'</Filter>
 <LineSymbolizer>
  <CssParameter name="stroke">#222222</CssParameter>
  <CssParameter name="stroke-width">3</CssParameter>
  <CssParameter name="stroke-linejoin">round</CssParameter>
 </LineSymbolizer>
 <LineSymbolizer>
  <CssParameter name="stroke">white</CssParameter>
 <CssParameter name="stroke-width">1</CssParameter>
  <CssParameter name="stroke-linejoin">round</CssParameter>
  <CssParameter name="stroke-dasharray">10,20</CssParameter>
 </LineSymbolizer>
</Rule>
Also here, it is quite simple. The values given to stroke-dasharray determine the size of the dashes, and they can be alternated. So, for the steps we have 2px of #ff0000 and 1px of trasparency, while for the rail we have 10px of white and 20px of #222222. What if we want to add some markers to the map? Easy, just use another symbolizer, called PointSymbolizer:
<Rule>
 <Filter>[highway] = 'stop'</Filter>
 <PointSymbolizer width='10' height='22' file='stop.png' type='png' allow_overlap='true' opacity='1.0' />
</Rule>
Here we mark stop signals with a pre-rendered stop.png (only png and tiff are currently supported, and svg support is only in the development version). What to do next? Well, we can make this map really nice. We'll render buildings with a pseudo-3D effect, which, however, does not reflect real heights -- but it's rather nice to see. How to achieve this? BuildingSymbolizer is the answer.
<Rule>
 <Filter>[building] &lt;&gt; ''</Filter>
 <BuildingSymbolizer>
  <CssParameter name="fill">#00ff00</CssParameter>
  <CssParameter name="fill-opacity">0.4</CssParameter>
  <CssParameter name="height">0.00007</CssParameter>
 </BuildingSymbolizer>
</Rule>
Here we just draw building=*. Regarding the height, you need to play a bit -- it took a while before I found a good value of it. One thing missing in this stylesheet, is the rendering of coastlines. Since we don't have a coastline here, I'm skipping it, but the easy way is: use another rule. This is really just a trick; OpenStreetMap renders the coastline in a different way respect to other features, that's why I'm using this trick. I'm not posting the whole stylesheet, but you can download it. You can also get the script, the OSM dump and the stop.png image. Now, you should be able to just do:
$ ./render.py
and you will have your map in output.svg :-) Here's what you would get if you use the files provided above (click to see the original SVG version):

Siegfried Gevatter: Debious A dubious Debian packaging GUI

Just some little (unfinished) concept mockup. Seeing that much of it still ends up as a text box with syntax highlighting it d probably make sense to implement it as a gedit plugin.

Balsamiq source XML Related posts:

  1. One week with Debian
  2. Packaging: Test-building your packages
  3. Arreglant paquets que no compilen: necpp

8 comments
Siegfried-Angel Gevatter Pujals, 2010. Permalink License Post tags: , ,

15 October 2010

Enrico Zini: Award winning code

Award winning code Me and Yuwei had a fun day at hhhmcr (#hhhmcr) and even managed to put together a prototype that won the first prize \o/ We played with the gmp24 dataset kindly extracted from Twitter by Michael Brunton-Spall of the Guardian into a convenient JSON dataset. The idea was to find ways of making it easier to look at the data and making sense of it. This is the story of what we did, including the code we wrote. The original dataset has several JSON files, so the first task was to put them all together:
#!/usr/bin/python
# Merge the JSON data
# (C) 2010 Enrico Zini <enrico@enricozini.org>
# License: WTFPL version 2 (http://sam.zoy.org/wtfpl/)
import simplejson
import os
res = []
for f in os.listdir("."):
    if not f.startswith("gmp24"): continue
    data = open(f).read().strip()
    if data == "[]": continue
    parsed = simplejson.loads(data)
    res.extend(parsed)
print simplejson.dumps(res)
The results however were not ordered by date, as GMP had to use several accounts to twit because Twitter was putting Greather Manchester Police into jail for generating too much traffic. There would be quite a bit to write about that, but let's stick to our work. Here is code to sort the JSON data by time:
#!/usr/bin/python
# Sort the JSON data
# (C) 2010 Enrico Zini <enrico@enricozini.org>
# License: WTFPL version 2 (http://sam.zoy.org/wtfpl/)
import simplejson
import sys
import datetime as dt
all_recs = simplejson.load(sys.stdin)
all_recs.sort(key=lambda x: dt.datetime.strptime(x["created_at"], "%a %b %d %H:%M:%S +0000 %Y"))
simplejson.dump(all_recs, sys.stdout)
I then wanted to play with Tf-idf for extracting the most important words of every tweet:
#!/usr/bin/python
# tfifd - Annotate JSON elements with Tf-idf extracted keywords
#
# Copyright (C) 2010  Enrico Zini <enrico@enricozini.org>
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
import sys, math
import simplejson
import re
# Read all the twits
records = simplejson.load(sys.stdin)
# All the twits by ID
byid = dict(((x["id"], x) for x in records))
# Stopwords we ignore
stopwords = set(["by", "it", "and", "of", "in", "a", "to"])
# Tokenising engine
re_num = re.compile(r"^\d+$")
re_word = re.compile(r"(\w+)")
def tokenise(tweet):
    "Extract tokens from a tweet"
    for tok in tweet["text"].split():
        tok = tok.strip().lower()
        if re_num.match(tok): continue
        mo = re_word.match(tok)
        if not mo: continue
        if mo.group(1) in stopwords: continue
        yield mo.group(1)
# Extract tokens from tweets
tokenised = dict(((x["id"], list(tokenise(x))) for x in records))
# Aggregate token counts
aggregated =  
for d in byid.iterkeys():
    for t in tokenised[d]:
        if t in aggregated:
            aggregated[t] += 1
        else:
            aggregated[t] = 1
def tfidf(doc, tok):
    "Compute TFIDF score of a token in a document"
    return doc.count(tok) * math.log(float(len(byid)) / aggregated[tok])
# Annotate tweets with keywords
res = []
for name, tweet in byid.iteritems():
    doc = tokenised[name]
    keywords = sorted(set(doc), key=lambda tok: tfidf(doc, tok), reverse=True)[:5]
    tweet["keywords"] = keywords
    res.append(tweet)
simplejson.dump(res, sys.stdout)
I thought this was producing a nice summary of every tweet but nobody was particularly interested, so we moved on to adding categories to tweet. Thanks to Yuwei who put together some useful keyword sets, we managed to annotate each tweet with a place name (i.e. "Stockport"), a social place name (i.e. "pub", "bank") and a social category (i.e. "man", "woman", "landlord"...) The code is simple; the biggest work in it was the dictionary of keywords:
#!/usr/bin/python
# categorise - Annotate JSON elements with categories
#
# Copyright (C) 2010  Enrico Zini <enrico@enricozini.org>
# Copyright (C) 2010  Yuwei Lin <yuwei@ylin.org>
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
import sys, math
import simplejson
import re
# Electoral wards from http://en.wikipedia.org/wiki/List_of_electoral_wards_in_Greater_Manchester
placenames = ["Altrincham", "Sale West",
"Altrincham", "Ashton upon Mersey", "Bowdon", "Broadheath", "Hale Barns", "Hale Central", "St Mary", "Timperley", "Village",
"Ashton-under-Lyne",
"Ashton Hurst", "Ashton St Michael", "Ashton Waterloo", "Droylsden East", "Droylsden West", "Failsworth East", "Failsworth West", "St Peter",
"Blackley", "Broughton",
"Broughton", "Charlestown", "Cheetham", "Crumpsall", "Harpurhey", "Higher Blackley", "Kersal",
"Bolton North East",
"Astley Bridge", "Bradshaw", "Breightmet", "Bromley Cross", "Crompton", "Halliwell", "Tonge with the Haulgh",
"Bolton South East",
"Farnworth", "Great Lever", "Harper Green", "Hulton", "Kearsley", "Little Lever", "Darcy Lever", "Rumworth",
"Bolton West",
"Atherton", "Heaton", "Lostock", "Horwich", "Blackrod", "Horwich North East", "Smithills", "Westhoughton North", "Chew Moor", "Westhoughton South",
"Bury North",
"Church", "East", "Elton", "Moorside", "North Manor", "Ramsbottom", "Redvales", "Tottington",
"Bury South",
"Besses", "Holyrood", "Pilkington Park", "Radcliffe East", "Radcliffe North", "Radcliffe West", "St Mary", "Sedgley", "Unsworth",
"Cheadle",
"Bramhall North", "Bramhall South", "Cheadle", "Gatley", "Cheadle Hulme North", "Cheadle Hulme South", "Heald Green", "Stepping Hill",
"Denton", "Reddish",
"Audenshaw", "Denton North East", "Denton South", "Denton West", "Dukinfield", "Reddish North", "Reddish South",
"Hazel Grove",
"Bredbury", "Woodley", "Bredbury Green", "Romiley", "Hazel Grove", "Marple North", "Marple South", "Offerton",
"Heywood", "Middleton",
"Bamford", "Castleton", "East Middleton", "Hopwood Hall", "Norden", "North Heywood", "North Middleton", "South Middleton", "West Heywood", "West Middleton",
"Leigh",
"Astley Mosley Common", "Atherleigh", "Golborne", "Lowton West", "Leigh East", "Leigh South", "Leigh West", "Lowton East", "Tyldesley",
"Makerfield",
"Abram", "Ashton", "Bryn", "Hindley", "Hindley Green", "Orrell", "Winstanley", "Worsley Mesnes",
"Manchester Central",
"Ancoats", "Clayton", "Ardwick", "Bradford", "City Centre", "Hulme", "Miles Platting", "Newton Heath", "Moss Side", "Moston",
"Manchester", "Gorton",
"Fallowfield", "Gorton North", "Gorton South", "Levenshulme", "Longsight", "Rusholme", "Whalley Range",
"Manchester", "Withington",
"Burnage", "Chorlton", "Chorlton Park", "Didsbury East", "Didsbury West", "Old Moat", "Withington",
"Oldham East", "Saddleworth",
"Alexandra", "Crompton", "Saddleworth North", "Saddleworth South", "Saddleworth West", "Lees", "St James", "St Mary", "Shaw", "Waterhead",
"Oldham West", "Royton",
"Chadderton Central", "Chadderton North", "Chadderton South", "Coldhurst", "Hollinwood", "Medlock Vale", "Royton North", "Royton South", "Werneth",
"Rochdale",
"Balderstone", "Kirkholt", "Central Rochdale", "Healey", "Kingsway", "Littleborough Lakeside", "Milkstone", "Deeplish", "Milnrow", "Newhey", "Smallbridge", "Firgrove", "Spotland", "Falinge", "Wardle", "West Littleborough",
"Salford", "Eccles",
"Claremont", "Eccles", "Irwell Riverside", "Langworthy", "Ordsall", "Pendlebury", "Swinton North", "Swinton South", "Weaste", "Seedley",
"Stalybridge", "Hyde",
"Dukinfield Stalybridge", "Hyde Godley", "Hyde Newton", "Hyde Werneth", "Longdendale", "Mossley", "Stalybridge North", "Stalybridge South",
"Stockport",
"Brinnington", "Central", "Davenport", "Cale Green", "Edgeley", "Cheadle Heath", "Heatons North", "Heatons South", "Manor",
"Stretford", "Urmston",
"Bucklow-St Martins", "Clifford", "Davyhulme East", "Davyhulme West", "Flixton", "Gorse Hill", "Longford", "Stretford", "Urmston",
"Wigan",
"Aspull New Springs Whelley", "Douglas", "Ince", "Pemberton", "Shevington with Lower Ground", "Standish with Langtree", "Wigan Central", "Wigan West",
"Worsley", "Eccles South",
"Barton", "Boothstown", "Ellenbrook", "Cadishead", "Irlam", "Little Hulton", "Walkden North", "Walkden South", "Winton", "Worsley",
"Wythenshawe", "Sale East",
"Baguley", "Brooklands", "Northenden", "Priory", "Sale Moor", "Sharston", "Woodhouse Park"]
# Manual coding from Yuwei
placenames.extend(["City centre", "Tameside", "Oldham", "Bury", "Bolton",
"Trafford", "Pendleton", "New Moston", "Denton", "Eccles", "Leigh", "Benchill",
"Prestwich", "Sale", "Kearsley", ])
placenames.extend(["Trafford", "Bolton", "Stockport", "Levenshulme", "Gorton",
"Tameside", "Blackley", "City centre", "Airport", "South Manchester",
"Rochdale", "Chorlton", "Uppermill", "Castleton", "Stalybridge", "Ashton",
"Chadderton", "Bury", "Ancoats", "Whalley Range", "West Yorkshire",
"Fallowfield", "New Moston", "Denton", "Stretford", "Eccles", "Pendleton",
"Leigh", "Altrincham", "Sale", "Prestwich", "Kearsley", "Hulme", "Withington",
"Moss Side", "Milnrow", "outskirt of Manchester City Centre", "Newton Heath",
"Wythenshawe", "Mancunian Way", "M60", "A6", "Droylesden", "M56", "Timperley",
"Higher Ince", "Clayton", "Higher Blackley", "Lowton", "Droylsden",
"Partington", "Cheetham Hill", "Benchill", "Longsight", "Didsbury",
"Westhoughton"])
# Social categories from Yuwei
soccat = ["man", "woman", "men", "women", "youth", "teenager", "elderly",
"patient", "taxi driver", "neighbour", "male", "tenant", "landlord", "child",
"children", "immigrant", "female", "workmen", "boy", "girl", "foster parents",
"next of kin"]
for i in range(100):
    soccat.append("%d-year-old" % i)
    soccat.append("%d-years-old" % i)
# Types of social locations from Yuwei
socloc = ["car park", "park", "pub", "club", "shop", "premises", "bus stop",
"property", "credit card", "supermarket", "garden", "phone box", "theatre",
"toilet", "building site", "Crown court", "hard shoulder", "telephone kiosk",
"hotel", "restaurant", "cafe", "petrol station", "bank", "school",
"university"]
extras =   "placename": placenames, "soccat": soccat, "socloc": socloc  
# Normalise keyword lists
for k, v in extras.iteritems():
    # Remove duplicates
    v = list(set(v))
    # Sort by length
    v.sort(key=lambda x:len(x), reverse=True)
# Add keywords
def add_categories(tweet):
    text = tweet["text"].lower()
    for field, categories in extras.iteritems():
        for cat in categories:
            if cat.lower() in text:
                tweet[field] = cat
                break
    return tweet
# Read all the twits
records = (add_categories(x) for x in simplejson.load(sys.stdin))
simplejson.dump(list(records), sys.stdout)
All these scripts form a nice processing chain: each script takes a list of JSON records, adds some bit and passes it on. In order to see what we have so far, here is a simple script to convert the JSON twits to CSV so they can be viewed in a spreadsheet:
#!/usr/bin/python
# Convert the JSON twits to CSV
# (C) 2010 Enrico Zini <enrico@enricozini.org>
# License: WTFPL version 2 (http://sam.zoy.org/wtfpl/)
import simplejson
import sys
import csv
rows = ["id", "created_at", "text", "keywords", "placename"]
writer = csv.writer(sys.stdout)
for rec in simplejson.load(sys.stdin):
    rec["keywords"] = " ".join(rec["keywords"])
    rec["placename"] = rec.get("placename", "")
    writer.writerow([rec[row] for row in rows])
At this point we were coming up with lots of questions: "were there more reports on women or men?", "which place had most incidents?", "what were the incidents involving animals?"... Time to bring Xapian into play. This script reads all the JSON tweets and builds a Xapian index with them:
#!/usr/bin/python
# toxapian - Index JSON tweets in Xapian
#
# Copyright (C) 2010  Enrico Zini <enrico@enricozini.org>
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
import simplejson
import sys
import os, os.path
import xapian
DBNAME = sys.argv[1]
db = xapian.WritableDatabase(DBNAME, xapian.DB_CREATE_OR_OPEN)
stemmer = xapian.Stem("english")
indexer = xapian.TermGenerator()
indexer.set_stemmer(stemmer)
indexer.set_database(db)
data = simplejson.load(sys.stdin)
for rec in data:
    doc = xapian.Document()
    doc.set_data(str(rec["id"]))
    indexer.set_document(doc)
    indexer.index_text_without_positions(rec["text"])
    # Index categories as categories
    if "placename" in rec:
        doc.add_boolean_term("XP" + rec["placename"].lower())
    if "soccat" in rec:
        doc.add_boolean_term("XS" + rec["soccat"].lower())
    if "socloc" in rec:
        doc.add_boolean_term("XL" + rec["socloc"].lower())
    db.add_document(doc)
db.flush()
# Also save the whole dataset so we know where to find it later if we want to
# show the details of an entry
simplejson.dump(data, open(os.path.join(DBNAME, "all.json"), "w"))
And this is a simple command line tool to query to the database:
#!/usr/bin/python
# xgrep - Command line tool to query the GMP24 tweet Xapian database
#
# Copyright (C) 2010  Enrico Zini <enrico@enricozini.org>
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
import simplejson
import sys
import os, os.path
import xapian
DBNAME = sys.argv[1]
db = xapian.Database(DBNAME)
stem = xapian.Stem("english")
qp = xapian.QueryParser()
qp.set_default_op(xapian.Query.OP_AND)
qp.set_database(db)
qp.set_stemmer(stem)
qp.set_stemming_strategy(xapian.QueryParser.STEM_SOME)
qp.add_boolean_prefix("place", "XP")
qp.add_boolean_prefix("soc", "XS")
qp.add_boolean_prefix("loc", "XL")
query = qp.parse_query(sys.argv[2],
    xapian.QueryParser.FLAG_BOOLEAN  
    xapian.QueryParser.FLAG_LOVEHATE  
    xapian.QueryParser.FLAG_BOOLEAN_ANY_CASE  
    xapian.QueryParser.FLAG_WILDCARD  
    xapian.QueryParser.FLAG_PURE_NOT  
    xapian.QueryParser.FLAG_SPELLING_CORRECTION  
    xapian.QueryParser.FLAG_AUTO_SYNONYMS)
enquire = xapian.Enquire(db)
enquire.set_query(query)
count = 40
matches = enquire.get_mset(0, count)
estimated = matches.get_matches_estimated()
print "%d/%d results" % (matches.size(), estimated)
data = dict((str(x["id"]), x) for x in simplejson.load(open(os.path.join(DBNAME, "all.json"))))
for m in matches:
    rec = data[m.document.get_data()]
    print rec["text"]
print "%d/%d results" % (matches.size(), matches.get_matches_estimated())
total = db.get_doccount()
estimated = matches.get_matches_estimated()
print "%d results over %d documents, %d%%" % (estimated, total, estimated * 100 / total)
Neat! Now that we have a proper index that supports all sort of cool things, like stemming, tag clouds, full text search with complex queries, lookup of similar documents, suggest keywords and so on, it was just fair to put together a web service to share it with other people at the event. It helped that I had already written similar code for apt-xapian-index and dde before. Here is the server, quickly built on bottle. The very last line starts the server and it is where you can configure the listening interface and port.
#!/usr/bin/python
# xserve - Make the GMP24 tweet Xapian database available on the web
#
# Copyright (C) 2010  Enrico Zini <enrico@enricozini.org>
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
import bottle
from bottle import route, post
from cStringIO import StringIO
import cPickle as pickle
import simplejson
import sys
import os, os.path
import xapian
import urllib
import math
bottle.debug(True)
DBNAME = sys.argv[1]
QUERYLOG = os.path.join(DBNAME, "queries.txt")
data = dict((str(x["id"]), x) for x in simplejson.load(open(os.path.join(DBNAME, "all.json"))))
prefixes =   "place": "XP", "soc": "XS", "loc": "XL"  
prefix_desc =   "place": "Place name", "soc": "Social category", "loc": "Social location"  
db = xapian.Database(DBNAME)
stem = xapian.Stem("english")
qp = xapian.QueryParser()
qp.set_default_op(xapian.Query.OP_AND)
qp.set_database(db)
qp.set_stemmer(stem)
qp.set_stemming_strategy(xapian.QueryParser.STEM_SOME)
for k, v in prefixes.iteritems():
    qp.add_boolean_prefix(k, v)
def make_query(qstring):
    return qp.parse_query(qstring,
        xapian.QueryParser.FLAG_BOOLEAN  
        xapian.QueryParser.FLAG_LOVEHATE  
        xapian.QueryParser.FLAG_BOOLEAN_ANY_CASE  
        xapian.QueryParser.FLAG_WILDCARD  
        xapian.QueryParser.FLAG_PURE_NOT  
        xapian.QueryParser.FLAG_SPELLING_CORRECTION  
        xapian.QueryParser.FLAG_AUTO_SYNONYMS)
@route("/")
def index():
    query = urllib.unquote_plus(bottle.request.GET.get("q", ""))
    out = StringIO()
    print >>out, '''
<html>
<head>
<title>Query</title>
<script src="http://ajax.googleapis.com/ajax/libs/jquery/1.4.2/jquery.min.js"></script>
<script type="text/javascript">
$(function() 
    $("#queryfield")[0].focus()
 )
</script>
</head>
<body>
<h1>Search</h1>
<form method="POST" action="/query">
Keywords: <input type="text" name="query" value="%s" id="queryfield">
<input type="submit">
<a href="http://xapian.org/docs/queryparser.html">Help</a>
</form>''' % query
    print >>out, '''
<p>Example: "car place:wigan"</p>

<p>Available prefixes:</p>

<ul>
'''
    for pfx in prefixes.keys():
        print >>out, "<li><a href='/catinfo/%s'>%s - %s</a></li>" % (pfx, pfx, prefix_desc[pfx])
    print >>out, '''
</ul>
'''
    oldqueries = []
    if os.path.exists(QUERYLOG):
        total = db.get_doccount()
        fd = open(QUERYLOG, "r")
        while True:
            try:
                q = pickle.load(fd)
            except EOFError:
                break
            oldqueries.append(q)
        fd.close()
        def print_query(q):
            count = q["count"]
            print >>out, "<li><a href='/query?query=%s'>%s (%d/%d %.2f%%)</a></li>" % (urllib.quote_plus(q["q"]), q["q"], count, total, count * 100.0 / total)
        print >>out, "<p>Last 10 queries:</p><ul>"
        for q in oldqueries[:-10:-1]:
            print_query(q)
        print >>out, "</ul>"
        # Remove duplicates
        oldqueries = dict(((x["q"], x) for x in oldqueries)).values()
        print >>out, "<table>"
        print >>out, "<tr><th>10 queries with most results</th><th>10 queries with least results</th></tr>"
        print >>out, "<tr><td>"
        print >>out, "<ul>"
        oldqueries.sort(key=lambda x:x["count"], reverse=True)
        for q in oldqueries[:10]:
            print_query(q)
        print >>out, "</ul>"
        print >>out, "</td><td>"
        print >>out, "<ul>"
        nonempty = [x for x in oldqueries if x["count"] > 0]
        nonempty.sort(key=lambda x:x["count"])
        for q in nonempty[:10]:
            print_query(q)
        print >>out, "</ul>"
        print >>out, "</td></tr>"
        print >>out, "</table>"
    print >>out, '''
</body>
</html>'''
    return out.getvalue()
@route("/query")
@route("/query/")
@post("/query")
@post("/query/")
def query():
    query = bottle.request.POST.get("query", bottle.request.GET.get("query", ""))
    enquire = xapian.Enquire(db)
    enquire.set_query(make_query(query))
    count = 40
    matches = enquire.get_mset(0, count)
    estimated = matches.get_matches_estimated()
    total = db.get_doccount()
    out = StringIO()
    print >>out, '''
<html>
<head><title>Results</title></head>
<body>
<h1>Results for "<b>%s</b>"</h1>
''' % query
    if estimated == 0:
        print >>out, "No results found."
    else:
        # Give as results the first 30 documents; also use them as the key
        # ones to use to compute relevant terms
        rset = xapian.RSet()
        for m in enquire.get_mset(0, 30):
            rset.add_document(m.document.get_docid())
        # Compute the tag cloud
        class NonTagFilter(xapian.ExpandDecider):
            def __call__(self, term):
                return not term[0].isupper() and not term[0].isdigit()
        cloud = []
        maxscore = None
        for res in enquire.get_eset(40, rset, NonTagFilter()):
            # Normalise the score in the interval [0, 1]
            weight = math.log(res.weight)
            if maxscore == None: maxscore = weight
            tag = res.term
            cloud.append([tag, float(weight) / maxscore])
        max_weight = cloud[0][1]
        min_weight = cloud[-1][1]
        cloud.sort(key=lambda x:x[0])
        def mklink(query, term):
            return "/query?query=%s" % urllib.quote_plus(query + " and " + term)
        print >>out, "<h2>Tag cloud</h2>"
        print >>out, "<blockquote>"
        for term, weight in cloud:
            size = 100 + 100.0 * (weight - min_weight) / (max_weight - min_weight)
            print >>out, "<a href='%s' style='font-size:%d%%; color:brown;'>%s</a>" % (mklink(query, term), size, term)
        print >>out, "</blockquote>"
        print >>out, "<h2>Results</h2>"
        print >>out, "<p><a href='/'>Search again</a></p>"
        print >>out, "<p>%d results over %d documents, %.2f%%</p>" % (estimated, total, estimated * 100.0 / total)
        print >>out, "<p>%d/%d results</p>" % (matches.size(), estimated)
        print >>out, "<ul>"
        for m in matches:
            rec = data[m.document.get_data()]
            print >>out, "<li><a href='/item/%s'>%s</a></li>" % (rec["id"], rec["text"])
        print >>out, "</ul>"
        fd = open(QUERYLOG, "a")
        qinfo = dict(q=query, count=estimated)
        pickle.dump(qinfo, fd)
        fd.close()
    print >>out, '''
<a href="/">Search again</a>

</body>
</html>'''
    return out.getvalue()
@route("/item/:id")
@route("/item/:id/")
def show(id):
    rec = data[id]
    out = StringIO()
    print >>out, '''
<html>
<head><title>Result %s</title></head>
<body>
<h1>Raw JSON record for twit %s</h1>
<pre>''' % (rec["id"], rec["id"])
    print >>out, simplejson.dumps(rec, indent=" ")
    print >>out, '''
</pre>
</body>
</html>'''
    return out.getvalue()
@route("/catinfo/:name")
@route("/catinfo/:name/")
def catinfo(name):
    prefix = prefixes[name]
    out = StringIO()
    print >>out, '''
<html>
<head><title>Values for %s</title></head>
<body>
''' % name
    terms = [(x.term[len(prefix):], db.get_termfreq(x.term)) for x in db.allterms(prefix)]
    terms.sort(key=lambda x:x[1], reverse=True)
    freq_min = terms[0][1]
    freq_max = terms[-1][1]
    def mklink(name, term):
        return "/query?query=%s" % urllib.quote_plus(name + ":" + term)
    # Build tag cloud
    print >>out, "<h1>Tag cloud</h1>"
    print >>out, "<blockquote>"
    for term, freq in sorted(terms[:20], key=lambda x:x[0]):
        size = 100 + 100.0 * (freq - freq_min) / (freq_max - freq_min)
        print >>out, "<a href='%s' style='font-size:%d%%; color:brown;'>%s</a>" % (mklink(name, term), size, term)
    print >>out, "</blockquote>"
    print >>out, "<h1>All terms</h1>"
    print >>out, "<table>"
    print >>out, "<tr><th>Occurrences</th><th>Name</th></tr>"
    for term, freq in terms:
        print >>out, "<tr><td>%d</td><td><a href='/query?query=%s'>%s</a></td></tr>" % (freq, urllib.quote_plus(name + ":" + term), term)
    print >>out, "</table>"
    print >>out, '''
</body>
</html>'''
    return out.getvalue()
# Change here for bind host and port
bottle.run(host="0.0.0.0", port=8024)
...and then we presented our work and ended up winning the contest. This was the story of how we wrote this set of award winning code.

Gerfried Fuchs: Open Source Projectmanagement

I wrote the following as a foreword for the great German book Open Source Projektmanagement that Michael Prokop wrote. Unfortunately the foreword didn't manage it in time into the book because of various circumstances. As I'm not a person to throw away already written material, here is it for your reading pleasure. Maybe it makes you consider obtaining a copy of the German language book for yourself!
The Whole is more than the Sum of the Parts When I first met Mika at a Linux conference some years ago I quickly noticed that he had potential. The way he asked questions and tackled issues did impress me. We did meet again at various events, joined forces in various projects and knew that the result would be good. Back in the year 2004 the only real live CD was Knoppix. It always was too sluggish for me because I never really liked KDE and also OpenOffice.org was too bloated for me. I was working since a year at an Internet provider, felt comfortable in the shell and was missing the tools on Knoppix which I used daily. Often enough the frustration with the status quo starts the best projects. And so I had the idea spinning around to start a sysadmin live CD. There was just one problem here: Exactly at the same time Mika had already started such a project. And I knew one thing: it would had been a lost race to compete with him in creating the better live CD. So I joined his team and helped with the best of my knowledge. The name choice alone showed that he was the right person for the job: Grml an expression of the frustration that even he felt which spoke directly to the heart of so many. But it wasn't just the chosen name that showed that Mika was the right person for the job of the project leader. It's always the sum of the parts, no matter how minor they might look. He quickly managed a first release and in light of that also created an event which was fitting for the release of the first version: the OS04 an Open Source event which managed to get Jon Maddog Hall as keynote speaker. Mika managed through his welcoming way to lure more people into helping out. The team grew over the years, further regular releases increased the fan base, not only through the creative release names which are surely one of the parts that helped create the success. He always was open to suggestions for new tools that helped to extend the project. The lived openness did lead among other things to the case that other live CDs started to use the grml build system. JUXlala 2.0 (the system for preschool kids) is just one example. Why do I write primarily about Grml, one could get subliminal advertising probably cheaper? I do it because Grml is an extremely good example of the experience revealed in this book. And even though every project is different, it is still exactly the sum of the parts that leads to the success of a project. And exactly these parts are covered in this book and can be considered for the project at hand and get implemented accordingly. Good luck whether in large or small.
Rhonda

/debian permanent link Comments: 0 Flattr this

14 October 2010

Axel Beckert: Thoughts on Gitorious and GitHub plus a useful git hook

When I took over the developement of xen-tools, I looked around for an appropriate git hosting. I especially had a look at GitHub and Gitorious. If you just regard the features, GitHub is definitely more targetted on single developers and Gitorious more towards projects: At GitHub, every repository has its URL under the URL of a user page which makes it nearly impossible to have user independent, official repositories for projects which have more than one official developer. At Gitorious, every hosted repository needs to belong to a project, even if it s only a published configuration. But a project can have more than one git repository. You only seem to be able to have personal repositories if you clone some existing Gitorious repository. So from a feature point of view, the xen-tools git repositories fit way better to Gitorious hosting while the git repositories with zshrc, conkerorrc and desktop configuration files defintely have a more fitting addresses on GitHub, in my case http://github.com/xtaran/$repository. On Gitorious, they are now together under a project called Axel s configuration files at http://gitorious.org/abe which contains git repositories of my on grml s .zshrc based .zshrc, my configuration for Conkeror and all the files necessary for my ratpoison/xmobar based netbook/laptop desktop. I though feel a little bad for giving the project the very short slug name abe instead of abe-config (as I did initially) since abe is IMHO not a proper project name for my configuration files and possibly other projects would have a more reasonable claim for that project name on Gitorious. But that way it suites more its purpose: Gather some of my git repositories which don t belong to a proper project. But there s another important point when comparing Gitorious and GitHub: Free Software needs free tools as Benjamin Mako Hill posted recently on Planet Debian. Despite my (probably well known) distrust against Google and therefore also Google Code, and despite knowing the history of SourceForge becoming non-free, I was not that much aware that GitHub s software is only partially open source and therefore also not free software while Gitorious is both as it s licensed under the GNU Affero General Public License (like StatusNet/identi.ca for example) which is basically GPLv3, but its ideas applied to hosted web applications scenario (where the GPL itself doesn t grasp), too. Initially I just had the xen-tools git repositories on Gitorious and all my small one-repository projects as copies of the repositories on my own git server on GitHub to get some more publicity for them and allow social cloning . After reading Mako s article, I decided to at least have repository clones on Gitorious of all repositories I mirror at GitHub, too. That way I force nobody to use the non-free tools on GitHub for social cloning one of my git repositories. And of course I have copies of my code somewhere on the net as backup. Or to say it with Linus Torvalds (slightly updated) words: Only wimps use tape backup: real men just upload their important stuff on git, and let the rest of the world clone it. ;-) But isn t that tedious to always push your code to three repositories? No, it isn t. I just push my code to git.noone.org where I have configured the according remotes and the following post-receive hook:
#!/bin/sh
                                                                     
read oldrev newrev refname
git push gitorious $ refname:t 
git push github $ refname:t 
The only other thing necessary is to use ssh-agent and SSH agent forwarding to at least the host you re pushing to.

Martin-&#201;ric Racine: An old GRSec feature I miss in stock Linux 2.6 kernels

Ages ago, when building my own kernel packages was my main hobby, I used to apply the GRsecurity patch to my kernels. One of the main benefits I found in this patch was that it would make the kernel terminate or, if that failed to have any immediate effect, downright kill any application that suddenly requests an unreasonable amount of system resources. I was wondering if stock Debian and Ubuntu kernels offered any similar feature that could be enabled e.g. via some /sys register?

Russell Coker: Links October 2010

Bruce Schneier wrote an insightful post about why designing products for wiretapping is a bad idea [1]. It seems that large parts of the Internet will be easy to tap (for both governments and criminals) in the near future unless something is done. The bad results of criminal use will outweigh any benefits of government use. Sam Watkins wrote an informative post about Android security [2]. Among other things any application can read all stored data including all photos, that s got to be a problem for anyone who photographs themself naked Rebecca Saxe gave an interesting TED talk about how brains make moral judgements [3]. Somehow she managed to speak about the Theory of Mind without mentioning Autism once. The Guardian has an amusing article by Cory Doctorow about security policies in banks [4]. He advocates promoting statistical literacy (or at least not promoting a lack of it) as a sound government policy. He also suggests allowing regulators to fine banks that get it wrong. Steven Johnson gave an interesting TED talk about Where Good Ideas Come From [5]. It s a bit slow at the start but gets good at the end. Adam Grosser gave an interesting TED talk about a fridge that was designed for use in Africa [6]. The core of the Absorption Refrigerator is designed to be heated in a pot of water in a cooking fire and it can then keep food cool for 12 hours. It s a pity that they couldn t design it to work on solar power to avoid the fuel use for the cooking fire. Josh Silver gave an interesting TED talk about liquid filled spectacles [7]. The glasses are shipped with a syringe filled with liquid at each side that is used to inflate the lenses to the desired refractive index. The wearer can just adjust the syringes until they get to the right magnification, as there are separate syringes the glasses work well with people who s eyes aren t identical (which is most people). Once the syringes are at the right spots the user can tighten some screws to prevent further transfer of liquid and cut the syringes off to give glasses that aren t overly heavy but which can t be adjusted any more, I guess that a natural extension to this would be to allow the syringes to be re-attached so that the user could adjust them every year to match declining vision. One thing that this wouldn t do is counter for Astigmatism (where the lens of the eye doesn t focus light to a point), but I guess they could make lenses to deal with a few common varieties of Astigmatism so that most people who have that problem can get a reasonable approximation. The current best effort is to make the glasses cost $19, which is 19 days salary for some of the poorest people in the world. Glasses in Australia cost up to $650 for a pair (or a more common cost of $200 or about $100 after Medicare) which would be about one day s salary. Eben Bayer gave an inspiring TED talk about one of the ways that mushrooms can save the planet [8]. He has designed molds that can be filled with Pasteurised organic waste (seed husks etc) and then seeded with fungal spores. The fungus then grows mycelium (thin fungal root fibers) through the organic waste making it into a solid structure which fits the shape of the mold. This is currently being used to replace poly-styrene foam for packaging and can apparently be used for making tiles that are fire retardant and sound proof for constructing buildings. The main benefits of the material are that it can be cheaply made without petrochemicals and that it is bio-degradable, I m not sure how the bio-degradable part would work with constructing buildings maybe they would just replace the panels every few years. Annie Lennox gave a TED talk about her Sing foundation to care for women and children who are affected by AIDS [9]. She describes the effect of AIDS in Africa as Genocide. Robert Ballard gave a very informative TED talk about exploring the oceans [10]. This was one of the most informative TED talks I ve seen and Robert is also one of the most enthusiastic speakers I ve seen, it s really worth watching! We really need more money spent on exploring the oceans. Jessa Gamble gave an interesting TED talk which suggests that the best thing to do is to go to bed at about sunset and then have a couple of hours of relaxing time during the middle of the night [11]. Apparently the subjects of body-block experiments who live for a month in a bunker without natural light or access to a clock get better sleep in this manner than they ever had in their life and feel fully awake for the first time. World Changing is a blog that has a lot of interesting articles about climate change and related issues [12]. It s worth a read. Cynthia Schneider gave an interesting TED talk about how reality competition TV is affecting reality [13]. Shows that are derived from the American Idol concept are driving a resurgence in some traditional forms of performance art while also promoting equality among other things it s apparent that winning is more important than misogyny. The Ritual of the Calling of an Engineer is an interesting concept [14]. I think it would be good to have something similar for Computer Science. Benjamin Mako Hill wrote an interesting and insightful essay about Piracy and Free Software [15].

13 October 2010

Kees Cook: mountall umask

The recent CVE-2010-2961 mountall vulnerability got a nice write-up by xorl today. I ve seen a few public exploits for it, but those that I ve seen, including the one in xorl s post, miss a rather important point: udev events can be triggered by regular users without any hardware fiddling. While the bug that kept udev from running inotify correctly on the /dev/.udev/rules.d directory during initial boot kept this vulnerability exposure pretty well minimized, the fact that udev events can be triggered at will made it pretty bad too. If udev had already been restarted, an attacker didn t have to wait at all, nor have physical access to the system. While it is generally understood that udev events are related to hardware, it s important to keep in mind that it also sends events on module loads, and module loads can happen on demand from unprivileged users. For example, say you want to send an X.25 packet, when you call socket(AF_X25, SOCK_STREAM), the kernel will go load net-pf-9, which modules.alias lists as the x25 module. And once loaded, udev sends a module event. (Which, by the way, should serve as a reminder to people to block module loading if you can.) So, as I mentioned, here s yet another exploit for the mountall vulnerability: mountall-CVE-2010-2961.py. It writes to the vulnerable udev rule file and then attempts to trigger udev immediately by walking a list of possible socket() AF_* types.

11 October 2010

Dirk Eddelbuettel: Chicago Marathon 2010

It's the Monday of the Columbus Day weekend here, so I must have been running a Chicago Marathon yesterday. Indeed -- the 34th annual Chicago Marathon took place yesterday but everything was about its 10/10/10 date. The symmetric set of numbers was in all advertisements, posters, street signs, on our bibs, the medals, the (nice, for once) race shirt. Everywhere, and yes, I will admit that it was also part of the reason I finally registered earlier in the year shortly before the race sold out. This was the sixth time I ran this race (and my 14th marathon overall). And I still can't run this course all that well: never got a Boston qualification here. As I had mentioned when I blogged about my third Boston Marathon earlier in the year and the recent Chicago Half-Marathon, I have had some recurrent issue with a sore achilles which limited my running throughout the year. It had gotten better but a quick summary of the miles in my running log showed that I had been running only about 80% of the training miles I had in prior years. And not a single 20-miler. I knew I'd have to pay for that. Plus, as so often, the weather. Not quite as hot as the record-heat of 2007. But close enough: high 60s at the start and high 70s or even low 80s towards the end. But I have to compliment to the race organisers. The race was very well organised (following the experience of 2007) with extra water stops, extra sponges handed out at several spots (!!) and very good communication when during the race the alert level was raised to yellow given the heat and humidity. The searchable results now show a fair number of non-finishers, but at least nobody seems to have died. But it looked ugly on the course. I think I ran by three or four sets of paramedics assisting runners who were 'down and out'.. So how did I do? Fair, I suppose -- I ran pretty well for sixteen miles, then needed a first short walking break and continued to run well towards and past the 18 mile waterstop where a bunch of friends and fellow Oak Park runners were helping. But not long after that, I crumbled and needed to alternate walking and running for most of the remainder. With that I came in at 3:41:41, or a 8:28 min/mile pace. And which is by two seconds slower than the previous 'worst' from 2007. But heck, at least it's still more than three minutes faster than Dubya in Houston in 1993 ... I also got beat by a few local running friends as well as by Chicago's own marathon juggler. So there. Maybe I'll train a bit more next time.

Evgeni Golov: RC bugs 2010/40

Let s join gregora and zack (and others, too lazy to search for links/names) and fix some RC bugs in Debian!So what happened last week?What does that mean? Two bugs are (almost) closed, two need more work. And this leads me to a feature I miss from http://udd.debian.org/bugs.cgi: a comment field as http://bts.turmzimmer.net/ has it. Will ping lucas about this later today.Oh, and on a side-note, I joined http://ask.debian.net let s help our users :)

10 October 2010

Gregor Herrmann: RC bugs 2010/40

a rather active week, although most of my uploads were (again!) either packages prepared by others or packages where I just applied existing patches from the BTS. in case you haven't seen it yet: there will be a BSP at the Mini DebConf Paris at the end of october. .

Joey Hess: first real Haskell program

I've finally started writing my first real program in Haskell. I've been learning Haskell since 2007. That is to say, I've been reading about it, over and over. Progress learning has been annoyingly slow because I have not been able to commit to using it in a real program. Because when I'm writing a real program I want the program now, and I can code in other languages ten to one hundred times faster than I can currently code in Haskell. Nasty viscious cycle. Probably best to avoid getting really good at specific programming languages to avoid it, in hindsight. Writing a real program in Haskell is important because I mostly learn by doing real things. Exercises don't work well for me. Up till now the only real thing I did in Haskell was write a 250 line xmonad config file in it. Which really helped a lot, but mostly only with beating some of its syntax into my head. I have a few hundred lines of git-annex done. I don't need this urgently so I am willing to spend a week writing it instead of dashing off a perl version tonight. I seem to have had bad luck on the parts I tackled first, and run into some swampier parts of the Haskell platform. I hope these problems are behind me, they sure made the first 8 hours fun. time First thing I needed was a data structure with a time stamp. There are multiple modules to handle time, mostly seemingly incompatible, deprecated, and/or possibly broken. Data.DateTime seems to be the current choice, but I don't entirely trust it. Check this weird thing out, it thinks that 0 seconds and 1 second after the Unix epoch are the same second.
Data.DateTime> map (toSeconds . fromSeconds) [-1,0,1,2,100,1000,100000,100000,1000000,100000000,100000000,1000000000,10000000000]
[-2,0,0,1,99,999,99999,99999,999999,99999999,99999999,1000000000,10000000000]
Rounding error? (Now it's not all bad... it does support dates right up until the heat death of the universe, on 32 bit even. No Y2038 bug here.) locking Huh, I read RealWorld_Haskell_ twice and never noticed that it seems to omit POSIX file locking. Which in my Real World is a necessity. Probably because it's so hard in Haskell, with multiple gotchas. First there's the lazy IO problem, which means that if you explicitly close a file, code that read from it may not have really run yet. I ended up needing this scariness from System.IO.Strict, which is sadly not packaged in Debian or part of the Haskell Platform:
hGetContentsStrict h  = hGetContents h >>= \s -> length s  seq  return s
Then there's the Haskell's interface for fcntl locking, which exposes rather more of fcntl locking than I like to think about, being spoiled by perl's 2-parameter interface to it.
waitToSetLock lockfd (ReadLock, AbsoluteSeek, 0, 0)
And then there's that lockfd, which is not a regalar file handle, but a fd number, which has to be obtained by calling handleToFd. And then there's the crazy interface that has handleToFd close the input handle! Which is problimatic if you were going to use the file after you locked it..

9 October 2010

Sylvain Le Gall: ocaml-gettext 0.3.0 is released

After three years, a new version of ocaml-gettext is out. I know that the delay is quite long... Been too busy to do anything regarding this. This new version is mainly a bug fix release: However, the major event of this release is the fact that it is now compatible with OCaml 3.10.0. This is a big news, because string extraction heavily rely on camlp4, which has changed a lot. I have also uploaded a debian package of ocaml-gettext. Plans for next release: Homepage Download
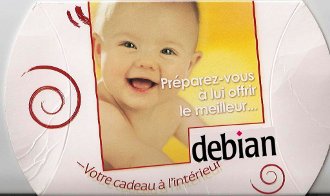
Sylvain Le Gall: Waiting for her in ~1month

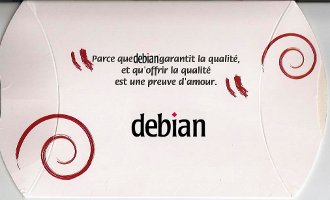
My wife is pregnant and we are expecting our second baby's arrival in about a month. Last time, she came back from her preparation lessons with a adverstisement "baby shower" gift pack. One of them catch my attention: English translation: be prepared to offer him the best... English translation: because Debian guarantee the quality and offering the quality is a proof of love OK, the swirl is the other way and I made a 5 minutes GIMP modification to cut-and-paste the Debian logo. But the message is here! Remember me: For those interested, the real thing is a soap called NUK(R).

8 October 2010

Russell Coker: Web Video, Global Innovation, and Free Software

Web Video and Global Innovation Chris Anderson (the curator of TED) gave an insightful TED talk about Web Video and Global Innovation [1]. Probably most people who have used the Internet seriously have an intuitive knowledge of the basic points of this talk, Chris had the insight to package it together in a clear manner. He describes how the printing press decreased the importance of verbal communication skills and services such as Youtube have caused a resurgence in the popularity and importance of speeches. He has some interesting theories on how this can be leveraged to improve education and society. Lectures for Developers vs Users Now how can we use these principles to advance the development of Free Software? It seems to me that a good lecture about Free Software achieve will achieve some of the following goals:
  1. Promoting projects to new developers.
  2. Teaching developers some new aspects of software development related to the system.
  3. Promoting projects to new users.
  4. Teaching users (and prospective users) how to use the software.
The talks aimed at developers need to be given by technical experts, but talks aimed at users don t need to be given by experts on the technology and someone who has less knowledge of the software but better public speaking skills could probably do a better job when speaking to users. Would it do some good to encourage people to join Free Software projects for the purpose of teaching users? It seems that there are already some people doing such work, but there seems little evidence of people being actively recruited for such work which is a stark contrast to the effort that is sometimes put in to recruiting developers. One problem in regard to separating the user-training and developer-training parts of Free Software advocacy and education is that most conferences seem to appeal to developers and the more Geeky users. Talks for such conferences tend to be given by developers but the audience is a mix of developers and users. Would it be better to have streams in conferences for developers and users with different requirements for getting a talk accepted for each stream? Publishing Videos It has become a standard feature of Free Software related conferences to release videos of all the talks so anyone anywhere in the world can watch them, but it seems that this isn t used as much as we would like. The incidence of Free Software developers citing TED talks in blog posts appears to exceed the incidence of them citing lectures by their peers, while TED talks are world leading in terms of presentation quality the talks by peers are more relevant to the typical Free Software developer who blogs. This seems to be an indication that there is a problem in getting the videos of talks to the audience. Would it help this to make it a standard feature to allow comments (and comments that are rated by other readers) on every video? Would having a central repository (or multiple repositories) of links to Free Software related talks help? Would it help to have a service such as Youtube or Blip.tv used as a separate repository for such talks? Instead of having each conference just use it s own servers if multiple conferences uploaded talks to Youtube (or one of it s competitors) then users could search for relevant talks (including conference content and videos made by individuals not associated with conferences). What about video replies ? What if after each conference there was an RSS feed of links to videos that had one video featured per day in a similar manner to the way TED dribbles the talks out. If you publish 40 videos of 45 minute lectures in one week you can be sure that almost no-one will watch them all and very few people will watch even half of them. But if you had an RSS feed that gave a summary of one talk per day for 6 weeks then maybe many people would watch half of them. Defining Success Chris cites as an example of the success of online video the competition by amateur dancers to create videos of their work and the way that this was used in selecting dancers for The LXD (Legion of eXtraordinary Dancers) [2]. I think that we need a similar culture in our community. Apart from people who give lectures at conferences and some of the larger user group meetings there are very few people giving public video talks related to Free Software. There is also a great lack of instructional videos. This is something that anyone could start doing at home, the basic video mixing that you need can be done with ffmpeg (it s not very good for that purpose, but for short videos it s probably adequate) and Istanbul is good for making videos of X sessions. If we had hundreds of Free Software users making videos of what they were doing then I m sure that the quality would increase rapidly. I expect that some people who made such videos would find themselves invited to speak at major conferences even if they hadn t previously considered themself capable of doing so (the major conferences can be a bit intimidating). How do we Start? Publishing videos requires some significant bandwidth, a cheap VPS has a bandwidth quota of 200GB per month, if short videos are used with an average size of 30MB (which seems about typical for Youtube videos) then that allows more than 6000 video views per month which is OK but as my blog averages about 2000 visits per day (according to Webalizer) it seems that 6000 views per month isn t enough for any serious vlogging. Not to mention the fact that videos in higher resolution or a sudden spike in popularity can drive the usage a lot higher. It seems that a site like Youtube or blip.tv is necessary, which one is best? There are lots of things that can be changed along the way, but a hosting service is difficult to change when people link to it. Conclusion I don t claim to have many answers to these questions. I m planning to start vlogging soon so I will probably learn along the way. I would appreciate any suggestions. Also if anyone has a long suggestion then a blog post will be best (I ll link to any posts that reference this one). If anyone has a long suggestion that is worthy of a blog post but they don t have a blog then I would be happy to post it on my blog.

7 October 2010

Eddy Petri&#537;or: Under the weather...

I've been having a cold for a week now. Horrible. My plans of jogging regularly have been messed with by this inconvenience. I hate caughing.

Julien Danjou: Why notmuch is not much good

I've recently got a mail from one of my faithful reader, asking why not considering notmuch. Actually, I think notmuch already exists in a better way, and that's called IMAP and Sieve. What notmuch does, is tagging your mail with tags (obviously), based on filtering rules you write. The big downside is that you have to tag all your mails on your computer. And if you use several computers, you'll have to tag several times your mails. And you'll have to find a way to maintain your rules to be identical on all your computers. That does not scale. Using Sieve for mail filtering, one can do already that actually, and much more. A notmuch rule like:

notmuch tag +intel from:intel.com and not tag:intel
Can be written as a Sieve rule like:
if address :all :contains "From" "intel.com"  
        addflag "intel";
 
The flags extension for Sieve is explained in RFC5232. The Sieve based solution has the advantage of being treated server side, and therefore not subject to multiple or different MUA usages. It's also fast, if you use a good IMAP server like Dovecot, which has indexing, etc. Furthermore, Sieve can obviously do a lot more than tagging, like splitting into different mailboxes, filtering with regexp usage, vacation, etc. And if you want to fetch your mail locally, you can synchronize the IMAP box entirely with any software able to (like OfflineIMAP). Now, what's probably missing, is a correct support for IMAP flags on various MUA around. But that's not something notmuch helps to solve either. :-) Flattr this

6 October 2010

Lior Kaplan: a very good day for bidi in openoffice.org

As a follow up on my report from last month about bidi status in openoffice.org 3.3, today was a very good day for bidi in openoffice.org. The short story: two important bugs were fixed for 3.3, and we now have the bidi keyword for IssueZilla system. It began with the fix to a cosmetic bug in the openoffice.org main screen which caused the icons to repaint improperly. While this isn t critical at all, it just looks really bad to have it on the main screen. And I don t want people to get the wrong impression. Thanks you Philipp Lohmann for fixing #97556.
Costmetic bug in oo.org RTL UI

Costmetic bug in oo.org RTL UI

The second bug was that AutoFilter isn t working for RTL sheets (regards whether the UI is LTR or RTL). This issue was reported yesterday and got fixed in 24 hours. Thank you Niklas Nebel for fixing #114944. It took us longer to isolate the bug than to get a patch for it. I wish this will happen more (: For closing, and in response to the bidi meta issue, a new keyword was created in the issuezilla: bidi. Till now, there was a bidi sub component in the UI, but this isn t always helpful as sometimes it s better to report against the actual component. The keyword will help us to better tag the issues for easy listing. The thank you list is long, as there were more than a few people behind the scenes today. I ll only mention Netanel, my partner to the Hebrew l10n team.
Filed under: Israeli Community, LibreOffice, Openoffice.org Tagged: bidi, openoffice

Andrew Cater: What you can learn from watching and listening

I'm in hospital, taking an enforced rest from work and normal life.with much too much time to think. Luckily I have relatively slow 'Net access.

I've just spent about three weeks in a specialist orthopaedic hospital which is also a centre of excellence, a research and teaching hospital. Some lessons for FLOSS:

Research methods matter: open communication matters more

The hospital was apparently doing various research projects, some minor, some major: whether cooling a knee joint in surgery improved recovery and aftercare, whether complete pain relief and comprehensive analgesia stimulated recovery, trying to standardise on a pain score to measure subjective pain - " On a scale of 1-10 how does it feel?"

The knee joint research was being written up and would be shared worldwide - if it proved worthwhile, hundreds of patients could benefit. If it wasn't worthwhile, it would still be written up just as comprehensively with testing methodology, evidence from double-blind trials or whatever as appropriate to save someone else from having to re-invent the wheel.

The analgesia study sounded just like the application of a doctor or nurse's intuitive commn sense and experience - but it was being carried out scientifically and measured. also answering supplementary questions like "If pain is sometimes a helpful indicator of problems, how should you guage reactions when all pain is dulled?" Additionally, the ward had dispensations to use different and more flexible drug regimes to include the use of oral morphine derivatives. Again, everything was being noted, measured and shared.

Luca Falavigna: Introducing projectb

Many people know Ultimate Debian Database already, and do use of it to create useful QA tools, or other Debian related activities. There is another database which is widely used by all of us, every day, and runs behind the scenes without being noticed. It is called projectb, the huge database of the Debian archive. projectb is the place where dak stores all the information it needs to run the archive (including but not limited to source packages, related binaries, suite definitions and associations, overrides, and so on), and it tells dak to hit you with a REJECT if you try to upload a package twice, or if you do something The Wrong Way. OK OK, it eventually allows your packages to be accepted too, sometimes it also behaves good :) projectb is hosted on ftp-master.debian.org. Most fellow Debian Developers cannot login over there because access is restricted to FTP and Release people only, but can enjoy its clone on merkel.debian.org [1]. Please note that clone is synced on a regular basis, but it could be a little bit not up-to-date with the very latest changes. Just run the following: psql -d projectb -p 5433 Now that you have access to it, you could want look at its structure to start looking at it. I just provide a couple of trivial examples of what you can do with it, your imagination is the limit [2] ;) This query displays which dpkg version known suites ship:
SELECT s.source, max(s.version) AS version, su.suite_name AS suite
FROM source s
JOIN src_associations sa ON sa.source = s.id
JOIN suite su ON su.id = sa.suite
WHERE s.source = 'dpkg'
GROUP BY s.source, su.suite_name
ORDER BY version;
This query displays changelog entries for debhelper which versions are greater than 8:
SELECT changelog
FROM changelogs
WHERE source = 'debhelper'
AND version > '8';
Working with projectb means working with real Debian archive data, so you are sure to always get solid information. You can also experience a limited (but functional) dak session on merkel. You cannot do much, data is read-only, but this is not a limit for a couple of commands. The most interesting is dak rm, where you can simulate a package removal, and discover reverse dependencies in advance, to save some work to your lovely FTP Team ;) Just run the following:
dak rm -n -R -m "Don't worry, it's a Dry Run" your_behated_package Wait a little bit, and you will be prompted with removal report. Just remember to always use -n and -R flags, though. Want even more? Join FTP Team, and you will given the chance to learn a lot more about Debian! DISCLAIMER: if you plan to write a tool, or perform an activity which relies on current projectb implementation, PLEASE TALK TO FTP TEAM FIRST. Internal structure can change a lot over times, and it is way better let FTP Team to handle exporting/parsing its data for day-by-day tasks. [1] This is probably supposed to change, as merkel is going to be decommissioned soon. [2] If you need a new feature, just talk to FTP Team.

Next.

Previous.
