Jonathan Dowland: Our Study
 This is a fairly self-indulgent post, sorry!
Encouraged by Evgeni,
Michael and
others, given I'm spending a lot more time at my desk in my home office, here's
a picture of it:
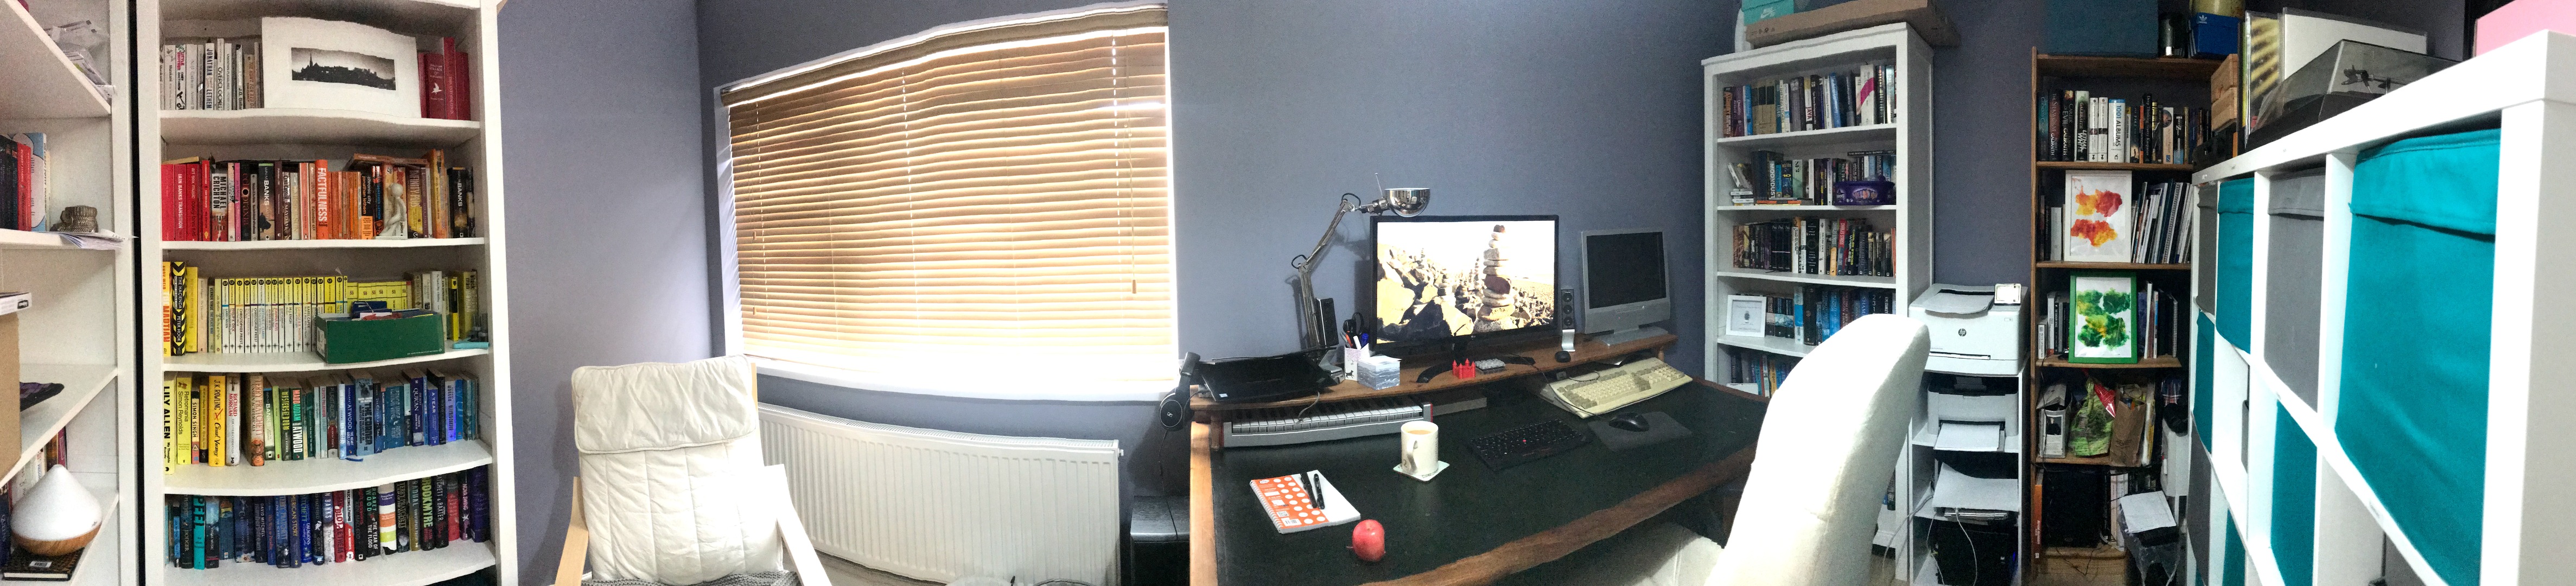 Fisheye shot of my home office
This is a fairly self-indulgent post, sorry!
Encouraged by Evgeni,
Michael and
others, given I'm spending a lot more time at my desk in my home office, here's
a picture of it:
Fisheye shot of my home office
 I released version 2.3 of ledger2beancount,
a ledger to beancount converter.
There are three notable changes with this release:
importmkdocs149. This version includes the following changes:
[ Chris Lamb ]
* Update tests for file 5.39. (Closes: reproducible-builds/diffoscope#179)
* Downgrade the tlsh warning message to an "info" level warning.
  (Closes: #888237, reproducible-builds/diffoscope#29)
* Use the CSS "word-break" property over manually adding U+200B zero-width
  spaces that make copy-pasting cumbersome.
  (Closes: reproducible-builds/diffoscope!53)
* Codebase improvements:
  - Drop some unused imports from the previous commit.
  - Prevent an unnecessary .format() when rendering difference comments.
  - Use a semantic "AbstractMissingType" type instead of remembering to check
    for both "missing" files and missing containers.
[ Jean-Romain Garnier ]
* Allow user to mask/filter reader output via --diff-mask=REGEX.
  (MR: reproducible-builds/diffoscope!51)
* Make --html-dir child pages open in new window to accommodate new web
  browser content security policies.
* Fix the --new-file option when comparing directories by merging
  DirectoryContainer.compare and Container.compare.
  (Closes: reproducible-builds/diffoscope#180)
* Fix zsh completion for --max-page-diff-block-lines.
[ Mattia Rizzolo ]
* Do not warn about missing tlsh during tests.
 A very exciting RcppSimdJson release with the updated upstream simdjson release 0.4.0 as well as a first set of new JSON parsing functions just hit CRAN. RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle use per byte parsed; see the video of the recent talk by Daniel Lemire at QCon (which was also voted best talk). The very recent 0.4.0 release further improves the already impressive speed.
And this release brings a first set of actually user-facing functions thanks to Brendan which put in a series of PRs! The full NEWS entry follows.
Courtesy of CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.Changes in version 0.0.6 (2020-06-25)
- Created C++ integer-handling utilities for safe downcasting and integer return (Brendan in #16 closing #13).
- New JSON functions
.deserialize_jsonand.load_json(Brendan in #16, #17, #20, #21).- Upgrade Travis CI to 'bionic', extract package and version from
DESCRIPTION(Dirk in #23).- Upgraded to simdjson 0.4.0 (Dirk in #25 closing #24).
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.
master for the default git branch. Regardless of the etymology (which is unclear), some people say they have negative associations for this word, Changing this upstream in git is complicated on a technical level and, sadly, contested.
But git is flexible enough that I can make this change in my own repositories. Doing so is not even so difficult.
So:
Announcement
I intend to rename master to trunk in all repositories owned by my personal hat. To avoid making things very complicated for myself I will just delete refs/heads/master when I make this change. So there may be a little disruption to downstreams.
I intend make this change everywhere eventually. But rather than front-loading the effort, I'm going to do this to repositories as I come across them anyway. That will allow me to update all the docs references, any automation, etc., at a point when I have those things in mind anyway. Also, doing it this way will allow me to focus my effort on the most active projects, and avoids me committing to a sudden large pile of fiddly clerical work. But: if you have an interest in any repository in particular that you want updated, please let me know so I can prioritise it.
Bikeshed
Why "trunk"? "Main" has been suggested elswewhere, and it is often a good replacement for "master" (for example, we can talk very sensibly about a disk's Main Boot Record, MBR). But "main" isn't quite right for the VCS case; for example a "main" branch ought to have better quality than is typical for the primary development branch.
Conversely, there is much precedent for "trunk". "Trunk" was used to refer to this concept by at least SVN, CVS, RCS and CSSC (and therefore probably SCCS) - at least in the documentation, although in some of these cases the command line API didn't have a name for it.
So "trunk" it is.
Aside: two other words - passlist, blocklist
People are (finally!) starting to replace "blacklist" and "whitelist". Seriously, why has it taken everyone this long?
I have been using "blocklist" and "passlist" for these concepts for some time. They are drop-in replacements. I have also heard "allowlist" and "denylist" suggested, but they are cumbersome and cacophonous.
Also "allow" and "deny" seem to more strongly imply an access control function than merely "pass" and "block", and the usefulness of passlists and blocklists extends well beyond access control: protocol compatibility and ABI filtering are a couple of other use cases.5 1 * * * mythtv /usr/share/mythtv/mythconverg_backup.pl
/home/mythtv/.mythtv/backuprc:
DBBackupDirectory=/var/backups/mythtv
mkdir /var/backups/mythtv
chown mythtv:mythtv /var/backups/mythtv
/etc/cron.d/mythtv-maintenance runs a contrib script to optimize the database
tables:
10 1 * * * mythtv /usr/bin/chronic /usr/share/doc/mythtv-backend/contrib/maintenance/optimize_mythdb.pl
libmythtv-perl and libxml-simple-perl packages
to be installed on Debian-based systems.
It is quickly followed by a check of the recordings and automatic repair of
the seektable (when possible):
20 1 * * * mythtv /usr/bin/chronic /usr/bin/mythutil --checkrecordings --fixseektable
30 1 * * *  mythtv  /usr/bin/mythutil --quiet --scanvideos
31 1 * * *  mythtv  /usr/bin/mythutil --quiet --scanmusic
45 1 * * 1-4,6-7 root /usr/sbin/xfs_fsr
15 3 * * 2  root  /usr/local/sbin/raid_parity_check md0
15 3 * * 4  root  /usr/local/sbin/raid_parity_check md2
/etc/smartd.conf:
/dev/sda -a -d ata -o on -S on -s (S/../.././04 L/../../6/05)
/dev/sdb -a -d ata -o on -S on -s (S/../.././04 L/../../6/05)

 Like each month, here comes a report about the work of paid contributors to Debian LTS.
Individual reports
In May, 198 work hours have been dispatched among 14 paid contributors. Their reports are available:
No comment Liked this article? Click here. My blog is Flattr-enabled.
 I recently moved house, and the new building has a Doorbird to act as a doorbell and open the entrance gate for people. There's a documented local control API (no cloud dependency!) and a Home Assistant integration, so this seemed pretty straightforward.
#!/usr/bin/perl
print "First Name,Last Name,Display Name,E-mail Address\n";
while(<STDIN>)

  chomp;
  my @fields = split(/\ /, $_);
  printf("%s,%s,%s %s,%s\n", $fields[1], $fields[2], $fields[0], $fields[4], $fields[3]);
Welcome to the 27th post in the rationally regularized R revelations series, or R4 for short. This is a edited / updated version of yesterday s T^4 post #7 as it really fits the R4 series as well as it fits the T4 series.
A new video in both our T^4 series of video lightning talks with tips, tricks, tools, and toys is also a video in the R^4 series as it revisits a topic previously covered in the latter: how to (more easily) get (binary) packages onto your Ubuntu system. In fact, we show it in three different ways.
The slides are here. This repo at GitHub support the series: use it to open issues for comments, criticism, suggestions, or feedback. Thanks to I aki Ucar who followed up on twitter with a Fedora version. We exchanged some more message, and concluded that complete comparison (from an empty Ubuntu or Fedora container) to a full system takes about the same time on either system. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

library (and later module_utils and doc_fragment_plugins) in ansible.cfg and effectively inject our modules, their helpers and documentation fragments into the main Ansible namespace. Not the cleanest solution, but it worked quiet well for us.
When Ansible started introducing Collections, we quickly joined, as the idea of namespaced, easily distributable and usable content units was great and exactly matched what we had in mind.
However, collections are only usable in Ansible 2.8, or actually 2.9 as 2.8 can consume them, but tooling around building and installing them is lacking. Because of that we've been keeping our modules usable outside of a collection.
Until recently, when we decided it's time to move on, drop that compatibility (which costed a few headaches over the time) and release a shiny 1.0.0.
One of the changes we wanted for 1.0.0 is renaming a few modules. Historically we had the module names prefixed with foreman_ and katello_, depending whether they were designed to work with Foreman (and plugins) or Katello (which is technically a Foreman plugin, but has a way more complicated deployment and currently can't be easily added to an existing Foreman setup). This made sense as long as we were injecting into the main Ansible namespace, but with collections the names be became theforemam.foreman.foreman_ <something> and while we all love Foreman, that was a bit too much. So we wanted to drop that prefix. And while at it, also change some other names (like ptable, which became partition_table) to be more readable.
But how? There is no tooling that would rename all files accordingly, adjust examples and tests. Well, bash to the rescue! I'm usually not a big fan of bash scripts, but renaming files, searching and replacing strings? That perfectly fits!
First of all we need a way map the old name to the new name. In most cases it's just "drop the prefix", for the others you can have some if/elif/fi:
prefixless_name=$(echo $ old_name   sed -E 's/^(foreman katello)_//')
if [[ $ old_name  == 'foreman_environment' ]]; then
  new_name='puppet_environment'
elif [[ $ old_name  == 'katello_sync' ]]; then
  new_name='repository_sync'
elif [[ $ old_name  == 'katello_upload' ]]; then
  new_name='content_upload'
elif [[ $ old_name  == 'foreman_ptable' ]]; then
  new_name='partition_table'
elif [[ $ old_name  == 'foreman_search_facts' ]]; then
  new_name='resource_info'
elif [[ $ old_name  == 'katello_manifest' ]]; then
  new_name='subscription_manifest'
elif [[ $ old_name  == 'foreman_model' ]]; then
  new_name='hardware_model'
else
  new_name=$ prefixless_name
fi
That defined, we need to actually have a
$ old_name . Well, that's a for loop over the modules, right?
for module in $ BASE /foreman_*py $ BASE /katello_*py; do
  old_name=$(basename $ module  .py)

done
While we're looping over files, let's rename them and all the files that are associated with the module:
# rename the module
git mv $ BASE /$ old_name .py $ BASE /$ new_name .py
# rename the tests and test fixtures
git mv $ TESTS /$ old_name .yml $ TESTS /$ new_name .yml
git mv tests/fixtures/apidoc/$ old_name .json tests/fixtures/apidoc/$ new_name .json
for testfile in $ TESTS /fixtures/$ old_name -*.yml; do
  git mv $ testfile  $(echo $ testfile   sed "s/$ old_name /$ new_name /")
done
Now comes the really tricky part: search and replace. Let's see where we need to replace first:
module key of the DOCUMENTATION stanza (e.g. module: foreman_example)foreman_example: )foreman_example: )conftest.py and other files related to test executionsed -E -i "/^(\s+$ old_name module):/ s/$ old_name /$ new_name /g" $ BASE /*.py sed -E -i "/^(\s+$ old_name module):/ s/$ old_name /$ new_name /g" tests/test_playbooks/tasks/*.yml tests/test_playbooks/*.yml sed -E -i "/'$ old_name '/ s/$ old_name /$ new_name /" tests/conftest.py tests/test_crud.py sed -E -i "/ $ old_name / s/$ old_name /$ new_name /g' README.md docs/*.mdYou've probably noticed I used
$ BASE and $ TESTS and never defined them Lazy me.
But here is the full script, defining the variables and looping over all the modules.
#!/bin/bash
BASE=plugins/modules
TESTS=tests/test_playbooks
RUNTIME=meta/runtime.yml
echo "plugin_routing:" > $ RUNTIME
echo "  modules:" >> $ RUNTIME
for module in $ BASE /foreman_*py $ BASE /katello_*py; do
  old_name=$(basename $ module  .py)
  prefixless_name=$(echo $ old_name   sed -E 's/^(foreman katello)_//')
  if [[ $ old_name  == 'foreman_environment' ]]; then
    new_name='puppet_environment'
  elif [[ $ old_name  == 'katello_sync' ]]; then
    new_name='repository_sync'
  elif [[ $ old_name  == 'katello_upload' ]]; then
    new_name='content_upload'
  elif [[ $ old_name  == 'foreman_ptable' ]]; then
    new_name='partition_table'
  elif [[ $ old_name  == 'foreman_search_facts' ]]; then
    new_name='resource_info'
  elif [[ $ old_name  == 'katello_manifest' ]]; then
    new_name='subscription_manifest'
  elif [[ $ old_name  == 'foreman_model' ]]; then
    new_name='hardware_model'
  else
    new_name=$ prefixless_name
  fi
  echo "renaming $ old_name  to $ new_name "
  git mv $ BASE /$ old_name .py $ BASE /$ new_name .py
  git mv $ TESTS /$ old_name .yml $ TESTS /$ new_name .yml
  git mv tests/fixtures/apidoc/$ old_name .json tests/fixtures/apidoc/$ new_name .json
  for testfile in $ TESTS /fixtures/$ old_name -*.yml; do
    git mv $ testfile  $(echo $ testfile   sed "s/$ old_name /$ new_name /")
  done
  sed -E -i "/^(\s+$ old_name  module):/ s/$ old_name /$ new_name /g" $ BASE /*.py
  sed -E -i "/^(\s+$ old_name  module):/ s/$ old_name /$ new_name /g" tests/test_playbooks/tasks/*.yml tests/test_playbooks/*.yml
  sed -E -i "/'$ old_name '/ s/$ old_name /$ new_name /" tests/conftest.py tests/test_crud.py
  sed -E -i "/ $ old_name  / s/$ old_name /$ new_name /g' README.md docs/*.md
  echo "    $ old_name :" >> $ RUNTIME
  echo "      redirect: $ new_name " >> $ RUNTIME
  git commit -m "rename $ old_name  to $ new_name " $ BASE  tests/ README.md docs/ $ RUNTIME
done
As a bonus, the script will also generate a
meta/runtime.yml which can be used by Ansible 2.10+ to automatically use the new module names if the playbook contains the old ones.
Oh, and yes, this is probably not the nicest script you'll read this year. Maybe not even today. But it got the job nicely done and I don't intend to need it again anyways.Italianization (Italian: Italianizzazione; Croatian: talijanizacija; Slovene: poitaljan evanje; German: Italianisierung; Greek: ) is the spread of Italian culture and language, either by integration or assimilation.[1][2]
In 1919, at the time of its annexation, the middle part of the County of Tyrol which is today called South Tyrol (in Italian Alto Adige) was inhabited by almost 90% German speakers.[1] Under the 1939 South Tyrol Option Agreement, Adolf Hitler and Benito Mussolini determined the status of the German and Ladin (Rhaeto-Romanic) ethnic groups living in the region. They could emigrate to Germany, or stay in Italy and accept their complete Italianization. As a consequence of this, the society of South Tyrol was deeply riven. Those who wanted to stay, the so-called Dableiber, were condemned as traitors while those who left (Optanten) were defamed as Nazis. Because of the outbreak of World War II, this agreement was never fully implemented. Illegal Katakombenschulen ("Catacomb schools") were set up to teach children the German language.
The Prontuario dei nomi locali dell'Alto Adige (Italian for Reference Work of Place Names of Alto Adige) is a list of Italianized toponyms for mostly German place names in South Tyrol (Alto Adige in Italian) which was published in 1916 by the Royal Italian Geographic Society (Reale Societ Geografica Italiana). The list was called the Prontuario in short and later formed an important part of the Italianization campaign initiated by the fascist regime, as it became the basis for the official place and district names in the Italian-annexed southern part of the County of Tyrol.
Ettore Tolomei (16 August 1865, in Rovereto 25 May 1952, in Rome) was an Italian nationalist and fascist. He was designated a Member of the Italian Senate in 1923, and ennobled as Conte della Vetta in 1937.
The South Tyrol Option Agreement (German: Option in S dtirol; Italian: Opzioni in Alto Adige) was an agreement in effect between 1939 and 1943, when the native German speaking people in South Tyrol and three communes in the province of Belluno were given the option of either emigrating to neighboring Nazi Germany (of which Austria was a part after the 1938 Anschluss) or remaining in Fascist Italy and being forcibly integrated into the mainstream Italian culture, losing their language and cultural heritage. Over 80% opted to move to Germany.
A new video in both our T^4 series of video lightning talks with tips, tricks, tools, and toys is also a video in the R^4 series as it revisits a topic previously covered in the latter: how to (more easily) get (binary) packages onto your Ubuntu system. In fact, we show it in three different ways.
The slides are here. This repo at GitHub support the series: use it to open issues for comments, criticism, suggestions, or feedback. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.
 Limesurvey is an online survey tool. It is very powerful and commonly used in academic environments because it is Free Software (GPLv2+), allows for local installations protecting the data of participants and allowing to comply with data protection regulations. This also means there are typically no load-balanced multi-server szenarios with HA databases. But simple VMs where Limesurvey runs and needs upgrading in place.
There's an LTS branch (currently 3.x) and a stable branch (currently 4.x). There's also a 2.06 LTS branch that is restricted to paying customers. The main developers behind Limesurvey offer many services from template design to custom development to support to hosting ("Cloud", "Limesurvey Pro"). Unfortunately they also charge for easy updates called "ComfortUpdate" (currently 39 for three months) and the manual process is made a bit cumbersome to make the "ComfortUpdate" offer more attractive.
Due to Limesurvey being an old code base and UI elements not being clearly separated, most serious use cases will end up patching files and symlinking logos around template directories. That conflicts a bit with the opaque "ComfortUpdate" process where you push a button and then magic happens. Or you have downtime and a recovery case while surveys are running.
If you do not intend to use the "ComfortUpdate" offering, you can prevent Limesurvey from connecting to
http://comfortupdate.limesurvey.org daily by adding the updatable stanza as in line 14 to limesurvey/application/config/config.php:
config.php, don't let yourself get confused.
Every item in a php array must end with a comma. It can be on the next line.
The basic principle of low risk, near-zero downtime, in-place upgrades is:
Release 0.3.8 of RcppGSL is now getting onto CRAN. The RcppGSL package provides an interface from R to the GNU GSL using the Rcpp package.
Peter Carbonetto let us know in issue #25 that the included example now showed linker errors on (everybody s favourite CRAN platform) Slowlaris. Kidding aside, the added compiler variety really has benefits because we were indeed missing a good handful or two of inline statements in the headers which our good friends g++ and clang++ apparently let us get away with. This has been fixed, and a little bit of the usual package polish and cleanup has been added; see the list of detailed changes below.
Special thanks also to CRAN for a super-smooth and fully automated processing of a package with both compiled code and two handful of reverse dependencies. Courtesy of CRANberries, a summary of changes to the most recent release is also available. More information is on the RcppGSL page. Questions, comments etc should go to the issue tickets at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.Changes in version 0.3.8 (2020-06-21)
- A few missing
inlinestatements were added to the headers fixing a (genuine) error that was seen only on Solaris (Dirk).- The nice
colNormexample is now in a file by itself, the previous versions are off in a new filecolNorm_old.cpp(Dirk).- The README.me now sports two new badges (Dirk).
- Travis CI was updated to 'bionic' and R 4.0 (Dirk).
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.
cvProjectPoints2()
calls. So I decided to just write a small C++ shim to call the new version of
that function, expose that with =extern "C"= to the rest of my world, and I'd be
done. And normally I would be, but this is OpenCV we're talking about. I wrote
the shim, and it didn't work. The code built and ran, but the results were
wrong. After some pointless debugging, I boiled the problem down to this test
program:
#include <opencv2/calib3d.hpp>
#include <stdio.h>
int main(void)

    double fx = 1000.0;
    double fy = 1000.0;
    double cx = 1000.0;
    double cy = 1000.0;
    double _camera_matrix[] =
          fx,  0, cx,
          0,  fy, cy,
          0,   0,  1  ;
    cv::Mat camera_matrix(3,3, CV_64FC1, _camera_matrix);
    double pp[3] =  1., 2., 10. ;
    double qq[2] =  444, 555 ;
    int N=1;
    cv::Mat object_points(N,3, CV_64FC1, pp);
    cv::Mat image_points (N,2, CV_64FC1, qq);
    // rvec,tvec
    double _zero3[3] =  ;
    cv::Mat zero3(1,3,CV_64FC1, _zero3);
    cv::projectPoints( object_points,
                       zero3,zero3,
                       camera_matrix,
                       cv::noArray(),
                       image_points,
                       cv::noArray(), 0.0);
    fprintf(stderr, "manually-projected no-distortion: %f %f\n",
            pp[0]/pp[2] * fx + cx,
            pp[1]/pp[2] * fy + cy);
    fprintf(stderr, "opencv says: %f %f\n", qq[0], qq[1]);
    return 0;
$ g++ -I/usr/include/opencv4 -o tst tst.cc -lopencv_calib3d -lopencv_core && ./tst
manually-projected no-distortion: 1100.000000 1200.000000
opencv says: 444.000000 555.000000
Well that's no good. The answer is wrong, but it looks like it didn't even write anything into the output array. Since this is supposed to be a thin shim to C code, I want this thing to be filling in C arrays, which is what I'm doing here:
double qq[2] =  444, 555 ;
int N=1;
cv::Mat image_points (N,2, CV_64FC1, qq);
cv::Mat, but the API wants cv::InputArray for some arguments and
cv::OutputArray for others. Clearly cv::Mat can be coerced into either of
those types (and that's what you're supposed to do), but the details are not
meant to be understood. You can read the snazzy C++-style documentation.
Clicking on "OutputArray" in the doxygen gets you here. Then I guess you're
supposed to click on "_OutputArray", and you get here. Understand what's going
on now? Me neither.
Stepping through the code revealed the problem. cv::projectPoints() looks like
this:
void cv::projectPoints( InputArray _opoints,
                        InputArray _rvec,
                        InputArray _tvec,
                        InputArray _cameraMatrix,
                        InputArray _distCoeffs,
                        OutputArray _ipoints,
                        OutputArray _jacobian,
                        double aspectRatio )

    ....
    _ipoints.create(npoints, 1, CV_MAKETYPE(depth, 2), -1, true);
    ....
OutputArray object. This object already had a buffer, and that's
where I was expecting the output to go. Instead it went to the brand-new buffer
I didn't want. Issues:
OutputArray object knows it already has a buffer, and they could just
use it instead of allocating a new one
static void cvProjectPoints2Internal( const CvMat* objectPoints,
                  const CvMat* r_vec,
                  const CvMat* t_vec,
                  const CvMat* A,
                  const CvMat* distCoeffs,
                  CvMat* imagePoints, CvMat* dpdr CV_DEFAULT(NULL),
                  CvMat* dpdt CV_DEFAULT(NULL), CvMat* dpdf CV_DEFAULT(NULL),
                  CvMat* dpdc CV_DEFAULT(NULL), CvMat* dpdk CV_DEFAULT(NULL),
                  CvMat* dpdo CV_DEFAULT(NULL),
                  double aspectRatio CV_DEFAULT(0) )

...
CvMat is still there. I
have no words.
Yes, this is a massive library, and maybe other parts of it indeed did make some
sort of non-token transition, but this thing is ridiculous. In the end, here's
the function I ended up with (licensed as OpenCV; see the comment)
// The implementation of project_opencv is based on opencv. The sources have
// been heavily modified, but the opencv logic remains. This function is a
// cut-down cvProjectPoints2Internal() to keep only the functionality I want and
// to use my interfaces. Putting this here allows me to drop the C dependency on
// opencv. Which is a good thing, since opencv dropped their C API
//
// from opencv-4.2.0+dfsg/modules/calib3d/src/calibration.cpp
//
// Copyright (C) 2000-2008, Intel Corporation, all rights reserved.
// Copyright (C) 2009, Willow Garage Inc., all rights reserved.
// Third party copyrights are property of their respective owners.
//
// Redistribution and use in source and binary forms, with or without modification,
// are permitted provided that the following conditions are met:
//
//   * Redistribution's of source code must retain the above copyright notice,
//     this list of conditions and the following disclaimer.
//
//   * Redistribution's in binary form must reproduce the above copyright notice,
//     this list of conditions and the following disclaimer in the documentation
//     and/or other materials provided with the distribution.
//
//   * The name of the copyright holders may not be used to endorse or promote products
//     derived from this software without specific prior written permission.
//
// This software is provided by the copyright holders and contributors "as is" and
// any express or implied warranties, including, but not limited to, the implied
// warranties of merchantability and fitness for a particular purpose are disclaimed.
// In no event shall the Intel Corporation or contributors be liable for any direct,
// indirect, incidental, special, exemplary, or consequential damages
// (including, but not limited to, procurement of substitute goods or services;
// loss of use, data, or profits; or business interruption) however caused
// and on any theory of liability, whether in contract, strict liability,
// or tort (including negligence or otherwise) arising in any way out of
typedef union

    struct

        double x,y;
     ;
    double xy[2];
  point2_t;
typedef union

    struct

        double x,y,z;
     ;
    double xyz[3];
  point3_t;
void project_opencv( // outputs
                     point2_t* q,
                     point3_t* dq_dp,               // may be NULL
                     double* dq_dintrinsics_nocore, // may be NULL
                     // inputs
                     const point3_t* p,
                     int N,
                     const double* intrinsics,
                     int Nintrinsics)

    const double fx = intrinsics[0];
    const double fy = intrinsics[1];
    const double cx = intrinsics[2];
    const double cy = intrinsics[3];
    double k[12] =  ;
    for(int i=0; i<Nintrinsics-4; i++)
        k[i] = intrinsics[i+4];
    for( int i = 0; i < N; i++ )

        double z_recip = 1./p[i].z;
        double x = p[i].x * z_recip;
        double y = p[i].y * z_recip;
        double r2      = x*x + y*y;
        double r4      = r2*r2;
        double r6      = r4*r2;
        double a1      = 2*x*y;
        double a2      = r2 + 2*x*x;
        double a3      = r2 + 2*y*y;
        double cdist   = 1 + k[0]*r2 + k[1]*r4 + k[4]*r6;
        double icdist2 = 1./(1 + k[5]*r2 + k[6]*r4 + k[7]*r6);
        double xd      = x*cdist*icdist2 + k[2]*a1 + k[3]*a2 + k[8]*r2+k[9]*r4;
        double yd      = y*cdist*icdist2 + k[2]*a3 + k[3]*a1 + k[10]*r2+k[11]*r4;
        q[i].x = xd*fx + cx;
        q[i].y = yd*fy + cy;
        if( dq_dp )

            double dx_dp[] =   z_recip, 0,       -x*z_recip  ;
            double dy_dp[] =   0,       z_recip, -y*z_recip  ;
            for( int j = 0; j < 3; j++ )

                double dr2_dp = 2*x*dx_dp[j] + 2*y*dy_dp[j];
                double dcdist_dp = k[0]*dr2_dp + 2*k[1]*r2*dr2_dp + 3*k[4]*r4*dr2_dp;
                double dicdist2_dp = -icdist2*icdist2*(k[5]*dr2_dp + 2*k[6]*r2*dr2_dp + 3*k[7]*r4*dr2_dp);
                double da1_dp = 2*(x*dy_dp[j] + y*dx_dp[j]);
                double dmx_dp = (dx_dp[j]*cdist*icdist2 + x*dcdist_dp*icdist2 + x*cdist*dicdist2_dp +
                                k[2]*da1_dp + k[3]*(dr2_dp + 4*x*dx_dp[j]) + k[8]*dr2_dp + 2*r2*k[9]*dr2_dp);
                double dmy_dp = (dy_dp[j]*cdist*icdist2 + y*dcdist_dp*icdist2 + y*cdist*dicdist2_dp +
                                k[2]*(dr2_dp + 4*y*dy_dp[j]) + k[3]*da1_dp + k[10]*dr2_dp + 2*r2*k[11]*dr2_dp);
                dq_dp[i*2 + 0].xyz[j] = fx*dmx_dp;
                dq_dp[i*2 + 1].xyz[j] = fy*dmy_dp;


        if( dq_dintrinsics_nocore )

            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 0] = fx*x*icdist2*r2;
            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 0] = fy*(y*icdist2*r2);
            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 1] = fx*x*icdist2*r4;
            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 1] = fy*y*icdist2*r4;
            if( Nintrinsics-4 > 2 )

                dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 2] = fx*a1;
                dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 2] = fy*a3;
                dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 3] = fx*a2;
                dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 3] = fy*a1;
                if( Nintrinsics-4 > 4 )

                    dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 4] = fx*x*icdist2*r6;
                    dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 4] = fy*y*icdist2*r6;
                    if( Nintrinsics-4 > 5 )

                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 5] = fx*x*cdist*(-icdist2)*icdist2*r2;
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 5] = fy*y*cdist*(-icdist2)*icdist2*r2;
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 6] = fx*x*cdist*(-icdist2)*icdist2*r4;
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 6] = fy*y*cdist*(-icdist2)*icdist2*r4;
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 7] = fx*x*cdist*(-icdist2)*icdist2*r6;
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 7] = fy*y*cdist*(-icdist2)*icdist2*r6;
                        if( Nintrinsics-4 > 8 )

                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 8] = fx*r2; //s1
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 8] = fy*0; //s1
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 9] = fx*r4; //s2
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 9] = fy*0; //s2
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 10] = fx*0;//s3
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 10] = fy*r2; //s3
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 11] = fx*0;//s4
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 11] = fy*r4; //s4
There are 3 choices for the alternative java (providing /usr/bin/java). Selection Path Priority StatusIt was set to jre-7, but I guess this was from years ago when I ran OpenFire as XMPP server. If something is not working with Jitsi Meet, it helps to not watch the log files only, but also to open the Debug Console in your web browser. That way I catched some XMPP Failures and saw that it tries to connect to some components where the DNS records were missing:
------------------------------------------------------------
* 0 /usr/lib/jvm/java-11-openjdk-amd64/bin/java 1111 auto mode
1 /usr/lib/jvm/java-11-openjdk-amd64/bin/java 1111 manual mode
2 /usr/lib/jvm/java-8-openjdk-amd64/jre/bin/java 1081 manual mode
3 /usr/lib/jvm/jre-7-oracle-x64/bin/java 316 manual mode
meet IN A yourIPOf course you also need to add some config to your ejabberd.yml:
chat.meet IN A yourIP
focus.meet IN A yourIP
pubsub.meet IN A yourIP
host_config:There is more config that needs to be done, but one of the XMPP Failures I spotted from debug console in Firefox was that it tried to connect to conference.domain.net while I prefer to use chat.domain.net for its brevity. If you prefer conference instead of chat, then you shouldn't be affected by this. Just make just that your config is consistent with what Jitsi Meet wants to connect to. Maybe not all of the above lines are necessary, but this works for me. Jitsi config is like this for me with short domains (/etc/jitsi/meet/meet.domain.net-config.js):
domain.net:
auth_password_format: scram
meet.domain.net:
## Disable s2s to prevent spam
s2s_access: none
auth_method: anonymous
allow_multiple_connections: true
anonymous_protocol: both
modules:
mod_bosh:
mod_caps:
mod_carboncopy:
#mod_disco:
mod_stun_disco:
secret: "YOURSECRETTURNCREDENTIALS"
services:
-
host: yourIP # Your coturn's public address.
type: stun
transport: udp
-
host: yourIP # Your coturn's public address.
type: stun
transport: tcp
-
host: yourIP # Your coturn's public address.
type: turn
transport: udp
mod_muc:
access: all
access_create: local
access_persistent: local
access_admin: admin
host: "chat.@HOST@"
mod_muc_admin:
mod_ping:
mod_pubsub:
access_createnode: local
db_type: sql
host: "pubsub.@HOST@"
ignore_pep_from_offline: false
last_item_cache: true
max_items_node: 5000 # For Jappix this must be set to 1000000
plugins:
- "flat"
- "pep" # requires mod_caps
force_node_config:
"eu.siacs.conversations.axolotl.*":
access_model: open
## Avoid buggy clients to make their bookmarks public
"storage:bookmarks":
access_model: whitelist
var config = hosts:In the above config snippet one of the issues solved was to add the port to the bosh setting. Of course you can also take care that your bosh requests get forwarded by your webserver as reverse proxy. Using the port in the config might be a quick way to test whether or not your config is working. It's easier to solve one issue after the other and make one config change at a time instead of needing to make changes in several places. /etc/jitsi/jicofo/sip-communicator.properties:
domain: 'domain.net',
anonymousdomain: 'meet.domain.net',
authdomain: 'meet.domain.net',
focus: 'focus.meet.domain.net',
muc: 'chat.hookipa.net'
, bosh: '//meet.domain.net:5280/http-bind',
//websocket: 'wss://meet.domain.net/ws',
clientNode: 'http://jitsi.org/jitsimeet',
focusUserJid: 'focus@domain.net', useStunTurn: true, p2p:
// Enables peer to peer mode. When enabled the system will try to
// establish a direct connection when there are exactly 2 participants
// in the room. If that succeeds the conference will stop sending data
// through the JVB and use the peer to peer connection instead. When a
// 3rd participant joins the conference will be moved back to the JVB
// connection.
enabled: true, // Use XEP-0215 to fetch STUN and TURN servers.
useStunTurn: true, // The STUN servers that will be used in the peer to peer connections
stunServers: [
// urls: 'stun:meet-jit-si-turnrelay.jitsi.net:443' ,
// urls: 'stun:stun.l.google.com:19302' ,
// urls: 'stun:stun1.l.google.com:19302' ,
// urls: 'stun:stun2.l.google.com:19302' ,
urls: 'stun:turn.domain.net:5349' ,
urls: 'stun:turn.domain.net:3478'
], ....
org.jitsi.jicofo.auth.URL=XMPP:meet.domain.net/etc/jitsi/videobridge/sip-communicator.properties:
org.jitsi.jicofo.BRIDGE_MUC=jvbbrewery@chat.meet.domain.net
org.jitsi.videobridge.ENABLE_STATISTICS=trueSometimes there might be stupid errors like (in my case) wrong hostnames like "chat.meet..domain.net" (a double dot in the domain), but you can spot those easily in the debug console of your browser. There tons of config options where you can easily make mistakes, but watching your logs and your debug console should really help you in sorting out these kind of errors. The other URLs above are helpful as well and more elaborate then my few lines here. Especially Mike Kuketz has some advanced configuration tips like disabling third party requests with "disableThirdPartyRequests: true" or limiting the number of video streams and such. Hope this helps...
org.jitsi.videobridge.STATISTICS_TRANSPORT=muc
org.jitsi.videobridge.STATISTICS_INTERVAL=5000 org.jitsi.videobridge.xmpp.user.shard.HOSTNAME=localhost
org.jitsi.videobridge.xmpp.user.shard.DOMAIN=domain.net
org.jitsi.videobridge.xmpp.user.shard.USERNAME=jvb
org.jitsi.videobridge.xmpp.user.shard.PASSWORD=SECRET
org.jitsi.videobridge.xmpp.user.shard.MUC_JIDS=JvbBrewery@chat.meet.domain.net
org.jitsi.videobridge.xmpp.user.shard.MUC_NICKNAME=videobridge1 org.jitsi.videobridge.DISABLE_TCP_HARVESTER=true
org.jitsi.videobridge.TCP_HARVESTER_PORT=4443
org.ice4j.ice.harvest.NAT_HARVESTER_LOCAL_ADDRESS=yourIP
org.ice4j.ice.harvest.NAT_HARVESTER_PUBLIC_ADDRESS=yourIP
org.ice4j.ice.harvest.DISABLE_AWS_HARVESTER=true
org.ice4j.ice.harvest.STUN_MAPPING_HARVESTER_ADDRESSES=turn.domain.net:3478
org.ice4j.ice.harvest.ALLOWED_INTERFACES=eth0
Next.