Search Results: "will"

2 December 2014

Richard Hartmann: Tabletop games

Wood. I really like wood. Even more, I like working with wood. Touching it, following its grain, and contemplating that it was made mostly from thin air and water. Normally, I just turn trees into handy pieces of firewood. While that's already deeply satisfying in the sense that you actually get to see what you worked for, it's a mostly destructive task. You kill a tree, you chop it up, only to turn it back into (mostly) thin air. As chance would have it, I needed a new table. After dragging myself through way too many furniture stores, I realized that I wouldn't be happy with what's on offer. So I struck a deal with a local carpenter: I would buy from them, but only if I could help building my own table; I would finally create something larger than a carving from wood. After some scouting, the carpenter found five planks of oak which were 4+ meter long, about 40-60 cm wide, and 8+ cm thick: Five raw planks of oak If you think this wood looks old, worn, and broken: You should have seen it up close; it was worse than on the potato-cam picture ;) But that's another great thing about working with wood: by taking off a laughably thin layer of surface material, you can renew the whole thing. We cut off 10 cm from each side as that's what tends to split and tossed that away. Afterwards, we cut off 80 cm from the wider side for the legs. Again, the base tends to have more imperfections and as you don't need to cut long pieces, you have more freedom in deciding how to cut. Cutting is an art in itself; tiny imperfections in the wood's surface can hint at large fissures underneath. The fact that the wood looks worn and spotty does not help in figuring this out. After cutting to minimize waste, you end up with a pile like this: Planks after cutting And a surprising amount of waste, i.e. firewood: Leftovers After a lot of planing, the wood becomes cleaner and smoother: Planed planks Then, everything's fitted so that neighbouring planks have their heartwood running into different directions, and so that the upper surface gets (most of) the interesting features. This is another surprisingly involved process and took about two hours. And no, the potato-cam does not manage to capture the wood's beauty. Set planks After sanding the sides down to perfection to ensure the glue can bond really tightly, the table feet are glued and put into a hydraulic press: Table feet about to be pressed while the tabletop itself shines in all its 287 cm x 107 cm x 6.3 cm glory: Tabletop set and glued Tomorrow, we will sand down the top and bottom of the tabletop and prepare the feet. Grooves will be milled into the wood to glue steel bars into it, as well as another plank that will be glued to the bottom of the tabletop, running along the middle. Along with the alternating heartwood, this helps ensure that this beast of a table will not fold in on itself or otherwise succumb to internal torsion or gravity. The final steps will be to fit the feet, sand down the surface again and then apply two layers of oil. And while most people may not fancy taking a week off just to rise way too early and then do unpaid work, I love it. As I said: I like wood.

Sven Hoexter: Out of the comfort zone: Backporting net-snmp from CentOS 7 to CentOS 5 and 6

Lately I faced the requirement to create a backport of net-snmp 5.7.2, which is part of CentOS 7, to a largely CentOS 5 and 6 based infrastructure. Due to some prior adventures in the rpm world I already knew about Mock (the Fedora equivalent to pbuilder). The easy part was the backporting to CentOS 6. Here the major objectiv is ripping out the newly added systemd support. That boils down to just ripping out a patch, removing a configure flag, some %post, %preun, %postun script snippets and the corresponding %install magic from the spec file. Builds fine but leaves us with the issue that the init script ships in a package net-snmp-sysvinit but the whole chkconfig registration magic is gone. I put that aside for a moment and moved on to CentOS 5. It did not even start to build.
  1. There is no tcp_wrappers-devel in CentOS 5.
  2. The perl libraries are in the main perl package and not in perl-devel.
  3. lm_sensors-devel is not at version 3.
I lowered the versioned build-dep on lm_sensors, disabled via a spec file toggle the tcp-wrapper support and changed the perl build-dep. This time it failed in the configure script due to DTLS support issues with the ancient openssl in CentOS 5. Decided to drop that one as well from the list of configure flags since we do not use it. Tried to build it again, now it failed somewhere down the road post compilation when assembling the package. Not cool. At that time we pushed a few other ideas back and forth. We found an isolated patch for net-snmp 5.6 that could fix our most pressing issue and someone had a look if that could be backported to CentOS 5 easily. Nope, internal structure of net-snmp changed a lot in between. So back to backporting. After staring long enough at the build log I could understand that the variable % RPM_BUILD_ROOT is empty in the CentOS 5 world. And indeed the BuildRoot stanza is also gone from the spec file. So I reintroduced that one and later even found documentation in the Fedora Wiki about this issue. If you know it it's easy to work around it, so I just defined it by hand:
BuildRoot: % _tmppath /% name -% version -% release -root
%global RPM_BUILD_ROOT % buildroot 
About ten minutes later I had a set of rpm files for CentOS 5. Tried to install it, failed due to a depedency on libmysqlclient15 which is part of the mysql package in CentOS 5. Yes, eight years back RedHat did not split off the lib packages and that would mean for us to install a mysql database on every system. So no, we won't do it and we just removed the mysql support. Left with only the init script setup missing I tried to be clever and failed miserable. Be warned, this would've also been a bad idea in the Debian world. Since we have the init script in a seperate binary package I thought I could just use something like
Requires: net-snmp-sysvinit
in the main net-snmp package and re-add the old %post, %preun and %postun magic. Of course that failed at install time for a good reason. In the second (desperate) try to work around it I tried something similar to "PreDepends"
Requires(post): net-snmp-sysvinit 
That works at install time but still breaks on a removal/update. So I think I did the right thing in the end (after reading some more documentation) and just added the scripts to the net-snmp-sysvinit package. It's just about adding the package name to the %post macro invocation. My initial plan included the wish to have one spec file that is usable to build on CentOS 5 and 6 but now I'm left with a number of special cases for CentOS 5. I already knew about the %if %endif conditional macro you can use in rpm spec files, so what was missing was a proper variable to base my decisions on. Every CentOS release ships with a "/etc/rpm/" directory that includes several macro file. Within those one can find the % rhel variable that defines an int we can use.
%if % rhel  <= 5
BuildRequires: perl
%else
BuildRequires: perl-devel
%endif
And finally I could build from one spec file a backport for CentOS 5 and 6. My diff against the CentOS 7 spec is at https://sven.stormbind.net/centos/netsnmp-bp-el56/net-snmp-backport.from_el7.diff Drawbacks of the resulting packages:
  1. No tcp-wrapper support, we don't care but that should be just another package name issue for the conditional Requires, simililar to the perl isssue.
  2. No mysql support. We do not care, one could change that and/or make it conditional or build against newer mysql releases where the -lib package is split.
  3. No DTLS support on CentOS 5. We do not care and that is not easy to fix.
  4. You've to install the net-snmp-sysvinit script to get back the usual setup you'd expect.
  5. We ripped out the systemd support, I did not investigate yet if it's possible to keep that included and just not enable it.
By now CentOS 5 is old. It's painful to backport to it. But it's still possible. Another strategy someone tried was packaging the current net-snmp upstream release based on the CentOS 5 spec file. That would've meant throwing away all 106 patches RedHat includes in that package at the moment and to depend on new upstream releases for your own security support. In case we start using CentOS 7 we would also diverge on the version of snmpd we use. So we decided to stick with the RedHat sources and keep the version consistent on our infrastructure even if we can not keep feature parity. After all the issues one encounters while backporting packages in the rpm world are similar to those in the dpkg world. Still it feels different if you're not familar with the toolchain. For example
  1. If you build a src.rpm with mock you've to copy it out of the result directory before you rebuild it with mock to create the binary package. Mock deletes everything from the result directory when starting a new build. So I guess parallel builds for the same chroot will not work.
  2. Depedencies on files instead of packages are a strange thing.
  3. How on earth do you maintain a patchset of over a hundred patches without something like quilt? I guess you always have to apply them in a for loop on your source directory and then you create a copy of that to implement your modifications and create another patch. I'm pretty sure eight years ago Fedora was far away from using git so I would rule out patch branches in a VCS for the moment. Not sure what they invented inside RedHat to keep track of it.

Rapha&#235;l Hertzog: My Free Software Activities in November 2014

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donators (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Debian LTS This month I have been paid to work 18 hours on Debian LTS (14h allocated by Freexian + 4h I did not spend last month). I did the following tasks: Updating the linux source package took a good half of the allocated time. We opted to update the kernel to the upstream version 2.6.32.64. I integrated the upstream patches and identified about 130 patches that we had to disable (because they were already integrated upstream). Then I updated our openvz flavor patch to apply on top of the new kernel. This required quite a bit of manual conflict resolution and there are even parts where I was not sure that I took the correct decision. I was not able to find an upstream openvz git tree on this kernel version to to double check. Instead I asked Ben Hutchings to review my patch. He told me that he did not volunteer to work on LTS, but that he would be open to contribute to it for money. Following this remark, as the coordinator of Freexian s offer, I offered him to join to the set of paid LTS contributors to take care of the kernel and he accepted. So hopefully we will be able to wrap this linux upload in the first week of december. We had no uploads of the kernel in Squeeze since July so it s good to know that we now have someone who will be able to handle it in priority. Distro Tracker No new developments this month. Instead I spent some time to import old historic news so that when you lookup removed packages you have some actual content instead of a 404 error. For example you can look at python2.1. Another thing that I did is to tag some bugs with the newly-announced tag newcomer . Those are easy bugs that are ideal targets for new contributors who d like to get started: here s the list. It s up to you now! ;-) DEP-14: Recommended layout for Git packaging repositories I have drafted an initial version of a document called Recommended layout for Git packaging repositories and submitted it for discussion on debian-devel. The discussion has been interesting and constructive (yes this is still possible in Debian!). I have a bunch of improvements in my local copy and needs to process a few more feedback before submitting an updated draft. It s not a revolution but it s a good step to try to standardize tags and branches naming conventions. Systemd, the tech-ctte and our mailing lists As an old-timer, I care a lot about the governance of Debian and it s annoying to see how the systemd debate brought back some of our old daemons in terms of hostile atmosphere on our mailing lists. We can disagree on a lot of things, but we must respect each other and we are here to work together on solutions for everybody. As such I wrote to the persons who cross the line to invite them to behave better. And I m glad that our listmasters are backing up our calls with bans when appropriate. I believe we must go further in that direction and I shared an idea (on a debian-private thread that should have never existed, much like most of the traffic on that list) that I shall formalize and share on debian-project@l.d.o at some point. At the same time, we also had another governance-related discussion with the idea to impose some turnover in the technical committee. I m glad to see that we will soon vote on this topic. This is a good thing in general even though we just had 3 tech-ctte members who retired. Misc stuff I sponsored an upload of galette and of 3 of its plugins. I reviewed jitsi-videobridge and jitsi-meet on mentors.debian.net. I filed a few bugs: Thanks See you next month for a new summary of my activities.
No comment Liked this article? Click here. My blog is Flattr-enabled.

Matthias Klumpp: How to build a cross-distro package with Limba

Disclaimer: Limba is stilllimba-small in a very early stage of development. Bugs happen, and I give to guarantees on API stability yet. Limba is a very simple cross-distro package installer, utilizing OverlayFS found in recent Linux kernels (>= 3.18). As example I created a small Limba package for one of the Qt5 demo applications, and I would like to share the process of creating Limba packages it s quite simple, and I could use some feedback on how well the resulting packages work on multiple distributions. I assume that you have compiled Limba and installed it how that is done is described in its README file. So, let s start. 1. Prepare your application The cool thing about Limba is that you don t really have to do many changes on your application. There are a few things to pay attention to, though: This needs to be done so your application will find its data at runtime. Additionally, you need to write an AppStream metadata file, and find out which stuff your application depends on. 2. Create package metadata & install software 1.1 Basics Now you can create the metadata necessary to build a Limba package. Just run
cd /path/to/my/project
lipkgen make-template
This will create a pkginstall directory, containing a control file and a metainfo.xml file, which can be a symlink to the AppStream metadata, or be new metadata. Now, configure your application with /opt/bundle as install prefix (-DCMAKE_INSTALL_PREFIX=/opt/bundle, prefix=/opt/bundle, etc.) and install it to the pkginstall/inst_target directory. 1.2 Handling dependencies If your software has dependencies on other packages, just get the Limba packages for these dependencies, or build new ones. Then place the resulting IPK packages in the pkginstall/repo directory. Ideally, you should be able to fetch Limba packages which contain the software components directly from their upstream developers. Then, open the pkginstall/control file and adjust the Requires line. The names of the components you depend on match their AppStream-IDs (<id/> tag in the AppStream XML document). Any version-relation (>=, >>, <<, <=, <>) is supported, and specified in brackets after the component-id. The resulting control-file might look like this:
Format-Version: 1.0

Requires: Qt5Core (>= 5.3), Qt5DBus (>= 5.3), libpng12
If the specified dependencies are in the repo/ subdirectory, these packages will get installed automatically, if your application package is installed. Otherwise, Limba depends on the user to install these packages manually there is no interaction with the distribution s package-manager (yet?). 3. Building the package In order to build your package, make sure the content in inst_target/ is up to date, then run
lipkgen build pkginstall/
This will build your package and output it in the pkginstall/ directory. 4. Testing the package You can now test your package, Just run
sudo lipa install package.ipk
Your software should install successfully. If you provided a .desktop file in $prefix/share/applications, you should find your application in your desktop s application-menu. Otherwise, you can run a binary from the command-line, just append the version of your package to the binary name (bash-comletion helps). Alternatively, you can use the runapp command, which lets you run any binary in your bundle/package, which is quite helpful for debugging (since the environment a Limba-installed application is run is different from the one of other applications). Example:
runapp $ component_id -$ version :/bin/binary-name
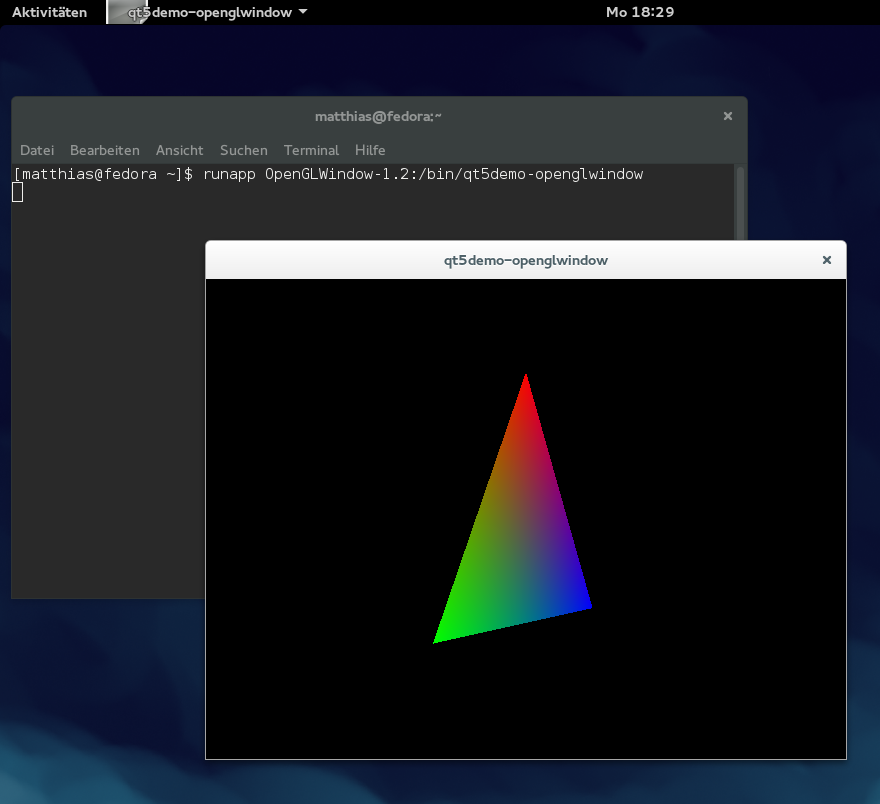
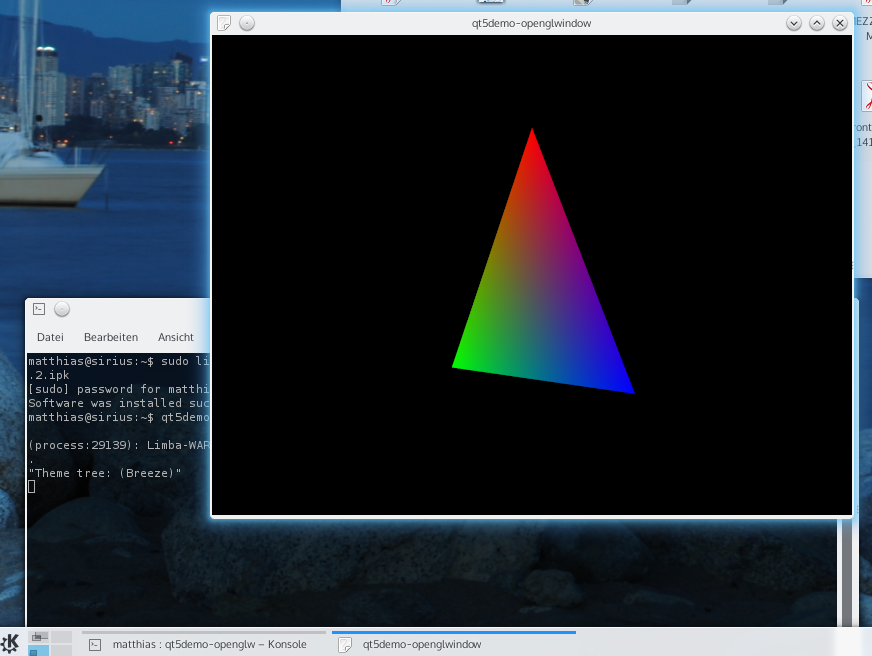
And that s it! :-) I used these steps to create a Limba package for the OpenGL Qt5 demo on Tanglu 2 (Bartholomea), and tested it on Kubuntu 15.04 (Vivid) with KDE, as well as on an up-to-date Fedora 21, with GNOME and without any Qt or KDE stuff installed: qt5demo-limba-kubuntuqt5demo-limba-fedora I encountered a few obstacles when building the packages, e.g. Qt5 initially didn t find the right QPA plugin that has been fixed by adjusting a config file in the Qt5Gui package. Also, on Fedora, a matching libpng was missing, so I included that as well. You can find the packages at Github, currently (but I am planning to move them to a different place soon). The biggest issue with Limba is at time, that it needs Linux 3.18, or an older kernel with OverlayFS support compiled in. Apart from that and a few bugs, the experience is quite smooth. As soon as I am sure there are now hidden fundamental issues, I can think of implementing more features, like signing packages and automatically updating them. Have fun playing around with Limba!
Peter Eisentraut: ccache and clang, part 3

In part 1 and part 2 I investigated how to use ccache with clang. That was more than three years ago. I got an email the other day that ccache bug 8118, which I filed while writing part 1, was closed, as ccache 3.2 was released. The release notes of clang 3.2 contain several items related to clang. So it was time to give this another look. Basically, the conclusions from part 2 still stand: You cannot use ccache with clang without using CCACHE_CPP2. And it is now becoming clear to me that this is an issue that is not going to go away, and it s not really even Clang s fault. Warnings! The problem is that clang s -Wall can cause warnings when compiling the preprocessed version of otherwise harmless C code. This can be illustrated by this piece of C code:
int
foo()
 
        int *p, *q;
        p = q = 0;
        p = p;
        if (p == p)
                return 1;
        if ((p == q))
                return 2;
        return 0;
 
When compiled by gcc-4.9 -Wall, this gives no warnings. When compiled by clang-3.5 -Wall, this results in test.c:7:4: warning: explicitly assigning value of variable of type 'int *' to itself [-Wself-assign] test.c:8:8: warning: self-comparison always evaluates to true [-Wtautological-compare] test.c:10:9: warning: equality comparison with extraneous parentheses [-Wparentheses-equality] test.c:10:9: note: remove extraneous parentheses around the comparison to silence this warning test1.c:10:9: note: use '=' to turn this equality comparison into an assignment You wouldn t normally write code like this, but the C preprocessor could create code with self-assignments, self-comparisons, extra parentheses, and so on. This example represents the issues I saw when trying to compile PostgreSQL 9.4 with ccache and clang; there might be others. You can address this issue in two ways:
  1. Use CCACHE_CPP2, as discussed in part 2. With ccache 3.2, you can now also put this into a configuration file: run_second_cpp = true in ~/.ccache/ccache.conf
  2. Turn off the warnings mentioned above: -Wno-parentheses-equality, -Wno-tautological-compare, -Wno-self-assign (and any others you might find). One might think that these are actually useful warnings that one might want to keep, but GCC doesn t warn about them, and if you develop primarily with GCC, your code might contain these issues anyway. In particular, I have found that -Wno-tautological-compare is necessary for legitimate code.
I think CCACHE_CPP2 is the way to go, for two reasons. Firstly, having to add more and more options to turn off warnings is obviously somewhat stupid. Secondly and more importantly, there is nothing stopping GCC from adding warnings similar to Clang s that would trigger on preprocessed versions of otherwise harmless C code. Unless they come up with a clever way to annotate the preprocessed code to the effect of this code might look wrong to you, but it looked OK before preprocessing, so don t warn about it , in a way that creates no extra warnings and doesn t lose any warnings, I don t think this issue can be solved. Speed! Now the question is, how much would globally setting CCACHE_CPP2 slow things down? To test this, I have built PostgreSQL 9.4rc1 with clang-3.5 and gcc-4.8 (not gcc-4.9 because it creates some unrelated warnings that I don t want to deal with here). I have set export CCACHE_RECACHE=true so that the cache is not read but new cache entries are computed. That way, the overhead of ccache on top of the compiler is measured. Results: (There different percentages between gcc and clang arise because gcc is faster than clang (yes, really, more on that in a future post), but the overhead of ccache doesn t change.) 10% or so is not to be dismissed, but let s remember that this applies only if there is a cache miss. If everything is cached, both methods do the same thing. Also, if you use parallel make, the overhead is divided by the number of parallel jobs. With that in mind, I have decided to put the issue to rest for myself and have made myself a ~/.ccache/ccache.conf containing
run_second_cpp = true
Now Clang or any other compiler should run without problems through ccache. Color! There is one more piece of news in the new ccache release: Another thing I talked about in part 1 was that ccache will disable the colored output of clang, and I suggested workarounds. This was actually fixed in ccache 3.2, so the workarounds are no longer necessary, and the above configuration change is really the only thing to make Clang work smoothly with ccache.

1 December 2014

Iustin Pop: SSD adventures

SSD adventures and fun times! TL;DR: Oh boy. Things work now, but I'm not sure exactly what happened :( When it all worked fine almost In June, I bought a new laptop, and a new SSD for it. I used that model of SSD before (Samsung 840 Evo), although not for a long time, so I wasn't expecting anything unusual. Since the laptop is a slower one, I installed Debian as follows: connect SSD to my workstation, do an install on it (via Virtualbox connected to the raw device), disconnect and install in the laptop. First sign of trouble was that the SSD didn't boot reliably. I said - maybe my Virtualbox method (new method) wasn't right - so I reinstalled on the laptop, and everything was mostly OK. Mostly OK because rarely the laptop had issues with seeing the SSD. Maybe not cold booting, requiring a restart, or giving some ATA errors on boot (bot nothing afterwards). I didn't use the laptop too much - I mostly use it when travelling - so I didn't investigate further. Trouble begins Fast forward to two weeks ago: I was preparing to leave on a trip, so I booted the laptop (everything OK), apt-get dist-upgrade, synced my git trees, etc. Everything was fine. The next day, in the airport between two flights, the laptop doesn't boot - doesn't see the SSD at all. I tried rebooting a gazillion times, nothing. I was quite upset - at the hardware, and at me for not paying attention to the unreliability signs before. Once I arrived at the destination, I opened the laptop, tried re-seating the SSD, nothing. I bought a SATA-to-USB bridge, and surprise! Boots from the first, no issues. Diagnosis A: Laptop SATA connector has issues. I work with this SATA-to-USB bridge for a couple of days, but it was quite slow (~20MB/s), so I buy a SATA-to-USB3 cradle, which should be much faster. But the SSD was not visible in this cradle. Not only that, but it was causing the laptop to hang in the POST screen - reliably. Turn the cradle off, the laptop passes POST, turn it on, the laptop took 2 minutes to pass the POST. OK, the cradle is broken. Connect the SSD back to the USB2 thing not booting For about five minutes, it was like "dead". After that, it booted and behaved normally. I didn't know what to think, I just put it aside. So worked for the rest of the week on the USB2 bridge, with no issues (once it the SSD dropped off, but I think that was just USB being USB). So at the end of the week, diagnosis (A) still was the main contender. On the flight back home, I worked from the plane for a good number of hours, again no issue. Laptop/SSD were fully powered off before the flight, powered with no issues, worked fine. At the end of the flight I completely shut down my laptop. Diagnosis A still on top. Real trouble now After getting home and sleeping a bit, I wanted to power up the laptop just to transfer the code I wrote on the plane. But it didn't power up. No problem, I said, now I actually have access to running Linux machines and I can check what's happening. And to my surprise, the SSD was behaving erratically: The looked like this (when connected over SATA):
20:22:57 kernel: ata2.00: ATA-9: Samsung SSD 840 EVO 500GB, EXT0BB6Q, max UDMA/133
20:22:57 kernel: ata2.00: 976773168 sectors, multi 1: LBA48 NCQ (depth 31/32), AA
20:22:57 kernel: ata2.00: configured for UDMA/133
20:22:57 kernel: scsi 3:0:0:0: Direct-Access     ATA      Samsung SSD 840  EXT0 PQ: 0 ANSI: 5
20:22:57 kernel: sd 3:0:0:0: [sdc] 488397168 512-byte logical blocks: (250 GB/232 GiB)
20:22:57 kernel: sd 3:0:0:0: [sdc] Write Protect is off
20:22:57 kernel: sd 3:0:0:0: [sdc] Mode Sense: 00 3a 00 00
20:22:57 kernel: sd 3:0:0:0: [sdc] Write cache: enabled, read cache: enabled, doesn't support DPO or FUA
20:22:57 kernel: ata2.00: exception Emask 0x0 SAct 0x2 SErr 0x400001 action 0x6 frozen
20:22:57 kernel: ata2: SError:   RecovData Handshk  
20:22:57 kernel: ata2.00: failed command: READ FPDMA QUEUED
20:22:57 kernel: ata2.00: cmd 60/08:08:68:01:00/00:00:00:00:00/40 tag 1 ncq 4096 in
20:22:57 kernel:         res 40/00:00:00:00:00/00:00:00:00:00/00 Emask 0x4 (timeout)
20:22:57 kernel: ata2.00: status:   DRDY  
20:22:57 kernel: ata2: hard resetting link
20:22:57 kernel: ata2: SATA link up 6.0 Gbps (SStatus 133 SControl 300)
20:22:57 kernel: ata2.00: failed to get NCQ Send/Recv Log Emask 0x1
20:22:57 kernel: ata2.00: configured for UDMA/133
20:22:57 kernel: ata2.00: device reported invalid CHS sector 0
20:22:57 kernel: ata2: EH complete
20:22:57 kernel: ata2.00: exception Emask 0x0 SAct 0x400000 SErr 0x400001 action 0x6
20:22:57 kernel: ata2.00: irq_stat 0x44000008
20:22:57 kernel: ata2: SError:   RecovData Handshk  
20:22:57 kernel: ata2.00: failed command: READ FPDMA QUEUED
20:22:57 kernel: ata2.00: cmd 60/08:b0:08:03:00/00:00:00:00:00/40 tag 22 ncq 4096 in
20:22:57 kernel:         res 41/84:00:08:03:00/00:00:00:00:00/00 Emask 0x410 (ATA bus error) <F>
20:22:57 kernel: ata2.00: status:   DRDY ERR  
20:22:57 kernel: ata2.00: error:   ICRC ABRT  
20:22:57 kernel: ata2: hard resetting link
20:22:57 kernel: ata2: SATA link up 6.0 Gbps (SStatus 133 SControl 300)
20:22:57 kernel: ata2.00: failed to get NCQ Send/Recv Log Emask 0x1
20:22:57 kernel: ata2.00: configured for UDMA/133
20:22:57 kernel: ata2: EH complete
Note that all of the messages were in short order (during boot, they show the same timestamp but I don't think it was actually the same second). I tried connecting the SSD over USB2 (partially working), over USB3 (not working!), and directly over SATA (initially not working). I connected another SSD I had around (same model, just smaller capacity) over all three, it worked (so the USB3 bridge was working, at least). Diagnosing (A) was out the door now, and the situation was very clear: SSD dying/dead/almost gone. So I connected both broken SSD and empty SSD to my workstation over SATA, and started copying data (once I managed to boot with the old one being visible and working). During the data copy, I saw that the "broken" SSD behaved erratically indeed: it was copying data off it with either ~40MB/s, ~70MB/s, and ~160MB/s. Not other speed, at least not for long time, just cycling between these three; and this is a very slow speed for this SSD model. And then I remembered that there is, for this model (Samsung 840 Evo), an advisory/firmware fix that old data gets harder to access (slower and slower), due to how TLC cells levels are read/etc. I don't know exactly what "old" means, but since the partition table was written only once, it should be the oldest thing written, which would make it the most susceptible to the slowdown, and could explain the cfdisk slowness. So after the data copy, I tested this: So yes, it is something related to this, probably. Diagnosis B: "just" the Samsung Evo bug. So I proceed to (try to) upgrade the firmware: Uh oh, so it's more than this - the SSD seems to be actually broken. I don't have much experience with SSDs, I used for many years an Intel X25-M and more recently I have a couple of Samsung 840 Pro, but I never had issues until now, so maybe the cheap Evo is just cheap and fast Note that during all this drama, SMART gives good info about SSD, and SMART tests are perfect (short/long). Just a number of UDMA CRC errors so thanks for nothing. I try to the firmware upgrade a few times, I give up. Diagnosis C: SSD is just plain broken. I'll send the SSD for a replacement/fix, so (even though it's encrypted), let's try to erase it first (as I can still read/write to it). And since just dd if=/dev/zero of=/dev/sdX is too common, let's try a builtin (ATA) erase! After fighting with hdparm and the fact that my BIOS does indeed "security freeze" on the drives (so you can't change the security settings nor erase the drives), and finding an article on the net that gives a few workaround, I manage to "unfreeze" it by not only live unplugging the SATA cable, but also the power cable, and plugging them back in. Time to erase. Side-note here: So, especially given the very fast ENHANCED erase, I now believe the SSD is truly broken. Diagnosis C rules. And finally, just confusion After the SSD erase, reading (the zeros) from the SSD is really fast: more than 500MB/s, as expected. I also try once more to upgrade the firmware for the Evo bug, and it works flawlessly this time. Even rebooting the machine many times works without problems, the SSD is seen every single time. I still can't make it work well over the USB3 bridge (but I'm not very convinced that device work well, since Linux does apply quirks when it detects it). But it doesn't give any ATA errors this time, and it works (read and write) consistently fast (as per the Evo specs). I still have to let it go through a long burnin with verification, but a short one works fine, so at this point I'm just very confused as what was (is?) the actual problem with this device, and why it behaves so strange Was the laptop broken? Clearly no. Was the SSD broken, or just impacted by the slowdown issue? Time will tell. I'll put it through the paces, and see. But unless I replace it, I'll keep this just for "fast cache" use cases, and not to hold real data. Yep, computers are fun!

Joey Hess: snowdrift - sustainable crowdfunding for free software development

In a recent blog post, I mentioned how lucky I feel to keep finding ways to work on free software. In the past couple years, I've had a successful Kickstarter, and followed that up with a second crowdfunding campaign, and now a grant is funding my work. A lot to be thankful for. A one-off crowdfunding campaign to fund free software development is wonderful, if you can pull it off. It can start a new project, or kick an existing one into a higher gear. But in many ways, free software development is a poor match for kickstarter-type crowdfunding. Especially when it comes to ongoing development, which it's really hard to do a crowdfunding pitch for. That's why I was excited to find Snowdrift.coop, which has a unique approach. Imagine going to a web page for a free software project that you care about, and seeing this button: 1283 patrons will donate MORE when you pledge That's a lot stronger incentive than some paypal donation button or flattr link! The details of how it works are explained on their intro page, or see the ever-insightful and thoughtful Mike Linksvayer's blog post about it. When I found out about this, I immediately sent them a one-off donation. Later, I got to meet one of the developers face to face in Portland. I've also done a small amount of work on the Snowdrift platform, which is itself free software. (My haskell code will actually render that button above!) Free software is important, and its funding should be based, not on how lucky or good we are at kickstarter pitches, but on its quality and how useful it is to everyone. Snowdrift is the most interesting thing I've seen in this space, and I really hope they succeed. If you agree, they're running their own crowdfunding campaign right now.

Olivier Berger: Offline backup/mirror of a Moodle course, using httrack

I havent found much details online on how to perform a Moodle course mirror that could be browsed offline using httrack. This could be useful both for backup purposes, or for distant learners with connectivity issues. In my case, there s a login/password dialog that grants access to the moodle platform, which can be processed by httrack by capturing the POST form results using the catchurl option. The strategy I ve used is to add filters so that everything is excluded and only explicitely mentioned filters are then allowed to be mirrored. This allows to perform the backup connected with a user that may have high privileges, while avoiding to disappear in loops or complex links following for UI rendering variants of Moodle s interface.
Here s an example command line :
httrack -v -z -%F "Mirrored [from host %s [file %s [at %s]]]" -N "%h%p/%n%[id].%t" "http://mymoodle.example.com/login/index.php?>postfile:/home/myself/websites/mycourse/hts-post0" "http://mymoodle.example.com/course/view.php?id=42" -O "/home/myself/websites/mycourse" "-*/*" "+/login/index.php*" "+*/course/view.php*" "+*/mod/resource/view.php*" "+*/mod/page/view.php*" "+*/mod/forum/view.php*" "+*/mod/forum/discuss.php?d=*[0-9]" "+*/mod/url/view.php*" "+*/pluginfile.php/*" "+*/mod/feedback/view.php*" "+*/mod/feedback/analysis.php*" "+*/theme/*" "-*/course/view.php?id=43"
Let s comment on these different parameters : I hope this will be useful.

30 November 2014

Enrico Zini: cxx11-talk-notes

C++11 talk notes On 2014-11-27 I gave a talk about C++ and new features introduced with C++11: these are the talk notes. See cxx11-talk-examples for the examples. (note: I had to add U+2063 INVISIBLE SEPARATOR to prevent noreturn statements to be misinterpreted by the blog formatter. If you copypaste the code and encounter issues, you may want to delete the noreturn statements and retype them) Overview of programming languages
It has to be as fast as possible, so interpreted languages are out. You don't want to micro manage memory, so C is out. You don't want to require programmers to have a degree, so C++ is out. You want fast startup and not depend on a big runtime, so Java is out. [...] (Bram Moolenaar)
C++ secret cultist protip
Do not call up what you cannot put down.
C++ is a compiled language It is now possible to use the keyword constexpr to mark functions and objects that can be used at compile time:
/*
 * constexpr tells the compiler that a variable or function can be evaluated at
 * compile time.
 *
 * constexpr functions can also be run at run time, if they are called with
 * values not known at compile time.
 *
 * See http://en.cppreference.com/w/cpp/language/constexpr for more nice examples
 *
 * It can be used to avoid using constants in code, and using instead functions
 * for computing hardware bitfields or physical values, without losing in
 * efficiency.
 */
#include <iostream>
using namespace std;
constexpr int factorial(int n)
 
    return n <= 1 ? 1 : (n * factorial(n-1));
 
int main()
 
    cout << "Compile time factorial of 6: " << factorial(6) << endl;
    cout << "Enter a number: ";
    int a;
    cin >> a;
    cout << "Run time factorial of " << a << ": " << factorial(a) << endl;
 
See also this for more nice examples. See this and this for further discussion. Multiline strings
        const char* code = R"--(
          printf("foo\tbar\n");
          return 0;
        )--";
See this. C++ memory management protip RAII: Resource Acquisition Is Instantiation This is not new in C++11, but in my experience I have rarely seen it mentioned in C++ learning material, and it does make a huge difference in my code. See this and this for details. Constructors and member initializer lists Initializers in curly braces now have their own type: std::initializer_list:
#include <string>
#include <iostream>
#include <unordered_set>
using namespace std;
// std::initializer_list< >
//   will have as its value all the elements inside the curly braces
string join(initializer_list<string> strings)
 
    string res;
    for (auto str: strings)
     
        if (!res.empty())
            res += ", ";
        res += str;
     
    return res;
 
int main()
 
    unordered_set<string> blacklist  ".", "..", ".git", ".gitignore"  ;
    cout << join(  "antani", "blinda"  ) << endl;
 
See this for details, including the new uniform initialization trick of omitting parentesis in constructors so that you can call normal constructors and initializer_list constructors with the same syntax, which looks like an interesting thing when writing generic code in templates. Type inference I can now use auto instead of a type to let the compiler automatically compute the value of something I assign to:
        auto i = 3 + 2;
        // See also https://github.com/esseks/monicelli
        vector<string> names  "antani", "blinda", "supercazzola"  ;
        for (auto i = names.cbegin(); i != names.cend(); ++i)
            cout << i;
        template<typename T>
        T frobble(const T& stuff)
         
             // This will work whatever type is returned by stuff.read()
             auto i = stuff.read();
             //  
         
See this for more details. Range-based for loop C++ now has an equivalent of the various foreach constructs found in several interpreted languages!
        for (auto i: list_of_stuff)
                cout << i << endl;
        for (auto n:  0,1,2,3,4,5 )
                cout << n << endl;
        // This construct:
        for (auto i: stuff)
        // If stuff is an array, it becomes:
        for (i = stuff, i < stuff + sizeof(stuff) / sizeof(stuff[0]); ++i)
        // If stuff has .begin() and .end() methods it becomes:
        for (i = stuff.begin(); i != stuff.end(); ++i)
        // Otherwise it becomes:
        for (i = begin(stuff); i != end(stuff); ++i)
        // And you can define begin() and end() functions for any type you
        // want, at any time
See this and this for details. Lambda functions and expressions Lambdas! Closures! Something like this:
// JavaScript
var add = function(a, b)   return a + b;  
# Python
add = lambda a, b: a + b
Becomes this:
auto add = [](int a, int b)   return a + b;  
And something like this:
// JavaScript
var a = 0;
$.each([1, 2, 3, 4], function(idx, el)   a += el  );
Becomes this:
unsigned a = 0;
std::for_each(  1, 2, 3, 4  , [&a](int el)   return a += el;  );
See this, this and this. Tuple types C++ now has a std::tuple type, that like in Python can be used to implement functions that return multiple values:
        tuple<int, string, vector<string>> parse_stuff()
         
                return make_tuple(id, name, values);
         
        string name; vector<string> values;
        // std::ignore can be used to throw away a result
        tie(ignore, name, values) = parse_stuff();
        // std::tie can also be used to do other kind of
        // multi-operations besides assignment:
        return tie(a, b, c) < tie(a1, b1, c1);
        // Is the same as:
        if (a != a1) return a < a1;
        if (b != b1) return b < b1;
        return c < c1;
See here, here and here. Regular expressions We now have regular expressions!
        std::regex re(R"((\w+)\s+(\w+))");
        string s("antani blinda");
        smatch res;
        if (regex_match(s, res, re))
            cout << "OK " << res[1] << " -- " << res[2] << endl;
The syntax is ECMAScript by default and can be optionally changed to basic, extended, awk, grep, or egrep. See here and here. General-purpose smart pointers There is std::unique_ptr to code memory ownership explicitly, and std::shared_ptr as a reference counted pointer, and smart pointers can have custom destructors:
    unique_ptr<dirent, std::function<void(void*)>> dirbuf((dirent*)malloc(len), free);
See here and here. Miscellaneous other cool things Standard attribute specifiers
string errno_str(int error)
 
    char buf[256];
#if (_POSIX_C_SOURCE >= 200112L   _XOPEN_SOURCE >= 600) && ! _GNU_SOURCE
    strerror_r(errno, buf, 256);
    string res(buf);
#else
    string res(strerror_r(errno, buf, 256));
#endif
    return res;
 
[ [noreturn]] void throw_libc_error(int error)
 
    throw runtime_error(errno_str(error));
 
See here. Hash tables See here and look at the new containers unordered_set, unordered_map, unordered_multiset, and unordered_multimap. Multithreading There is a standard threading model, with quite a bit of library support: see here, here, here, and here for atomic data structures. Variadic templates Templates can now take variable number of arguments, and that opens possibilities for interesting code generation, like implementing a generic, type-safe printf statement, or something like this:
db.query(R"(
   INSERT INTO table NAMES (id, name, description)
     VALUES (?, ?, ?)
)", 4, "genio", "fantasia, intuizione, decisione, e velocit  di esecuzione");
See here and here. Essential tools You need at least g++ 4.8 or clang 3.3 to have full C++11 support. They will be both available in jessie, and for wheezy you can use the nightly clang packages repository. I cannot think of a good excuse not to use -Wall on new code. scan-build from clang is another nice resource for catching even more potential problems at compile time. valgrind is a great tool for runtime code analysis: valgrind --tool=memcheck (the default) will check your program for wrong memory accesses and memory leaks. valgrind --tool=callgrind will trace function calls for profiling, to be analyzed with kcachegrind. valgrind --tool=helgrind can check multi-threaded programs for suspicious concurrent memory accesse patterns. And of course gdb: a nice trick with C++ is to issue catch throw to get a breakpoint at the point where an exception is being thrown. help catch provides a list of other interesting catch examples. Coredump tips: ulimit -c to enable core dumps, triggering a core dump with ^\, opening a core with gdb program core, and more details on man 5 core. An extra gdb tip, which is not related to C++ but helped me considerably recently, is that it can be attached to running python programs to get a live Python traceback.

Johannes Schauer: simple email setup

I was unable to find a good place that describes how to create a simple self-hosted email setup. The most surprising discovery was, how much already works after:
apt-get install postfix dovecot-imapd
Right after having finished the installation I was able to receive email (but only in in /var/mail in mbox format) and send email (bot not from any other host). So while I expected a pretty complex setup, it turned out to boil down to just adjusting some configuration parameters.

Postfix The two interesting files to configure postfix are /etc/postfix/main.cf and /etc/postfix/master.cf. A commented version of the former exists in /usr/share/postfix/main.cf.dist. Alternatively, there is the ~600k word strong man page postconf(5). The latter file is documented in master(5).

/etc/postfix/main.cf I changed the following in my main.cf
@@ -37,3 +37,9 @@
mailbox_size_limit = 0
recipient_delimiter = +
inet_interfaces = all
+
+home_mailbox = Mail/
+smtpd_recipient_restrictions = permit_mynetworks reject_unauth_destination permit_sasl_authenticated
+smtpd_sasl_type = dovecot
+smtpd_sasl_path = private/auth
+smtp_helo_name = my.reverse.dns.name.com
At this point, also make sure that the parameters smtpd_tls_cert_file and smtpd_tls_key_file point to the right certificate and private key file. So either change these values or replace the content of /etc/ssl/certs/ssl-cert-snakeoil.pem and /etc/ssl/private/ssl-cert-snakeoil.key. The home_mailbox parameter sets the default path for incoming mail. Since there is no leading slash, this puts mail into $HOME/Mail for each user. The trailing slash is important as it specifies qmail-style delivery'' which means maildir. The default of the smtpd_recipient_restrictions parameter is permit_mynetworks reject_unauth_destination so this just adds the permit_sasl_authenticated option. This is necessary to allow users to send email when they successfully verified their login through dovecot. The dovecot login verification is activated through the smtpd_sasl_type and smtpd_sasl_path parameters. I found it necessary to set the smtp_helo_name parameter to the reverse DNS of my server. This was necessary because many other email servers would only accept email from a server with a valid reverse DNS entry. My hosting provider charges USD 7.50 per month to change the default reverse DNS name, so the easy solution is, to instead just adjust the name announced in the SMTP helo.

/etc/postfix/master.cf The file master.cf is used to enable the submission service. The following diff just removes the comment character from the appropriate section.
@@ -13,12 +13,12 @@
#smtpd pass - - - - - smtpd
#dnsblog unix - - - - 0 dnsblog
#tlsproxy unix - - - - 0 tlsproxy
-#submission inet n - - - - smtpd
-# -o syslog_name=postfix/submission
-# -o smtpd_tls_security_level=encrypt
-# -o smtpd_sasl_auth_enable=yes
-# -o smtpd_client_restrictions=permit_sasl_authenticated,reject
-# -o milter_macro_daemon_name=ORIGINATING
+submission inet n - - - - smtpd
+ -o syslog_name=postfix/submission
+ -o smtpd_tls_security_level=encrypt
+ -o smtpd_sasl_auth_enable=yes
+ -o smtpd_client_restrictions=permit_sasl_authenticated,reject
+ -o milter_macro_daemon_name=ORIGINATING
#smtps inet n - - - - smtpd
# -o syslog_name=postfix/smtps
# -o smtpd_tls_wrappermode=yes

Dovecot Since above configuration changes made postfix store email in a different location and format than the default, dovecot has to be informed about these changes as well. This is done in /etc/dovecot/conf.d/10-mail.conf. The second configuration change enables postfix to authenticate users through dovecot in /etc/dovecot/conf.d/10-master.conf. For SSL one should look into /etc/dovecot/conf.d/10-ssl.conf and either adapt the parameters ssl_cert and ssl_key or store the correct certificate and private key in /etc/dovecot/dovecot.pem and /etc/dovecot/private/dovecot.pem, respectively. The dovecot-core package (which dovecot-imapd depends on) ships tons of documentation. The file /usr/share/doc/dovecot-core/dovecot/documentation.txt.gz gives an overview of what resources are available. The path /usr/share/doc/dovecot-core/dovecot/wiki contains a snapshot of the dovecot wiki at http://wiki2.dovecot.org/. The example configurations seem to be the same files as in /etc/ which are already well commented.

/etc/dovecot/conf.d/10-mail.conf The following diff changes the default email location in /var/mail to a maildir in ~/Mail as configured for postfix above.
@@ -27,7 +27,7 @@
#
# <doc/wiki/MailLocation.txt>
#
-mail_location = mbox:~/mail:INBOX=/var/mail/%u
+mail_location = maildir:~/Mail

# If you need to set multiple mailbox locations or want to change default
# namespace settings, you can do it by defining namespace sections.

/etc/dovecot/conf.d/10-master.conf And this enables the authentication socket for postfix:
@@ -93,9 +93,11 @@


# Postfix smtp-auth
- #unix_listener /var/spool/postfix/private/auth
- # mode = 0666
- #
+ unix_listener /var/spool/postfix/private/auth
+ mode = 0660
+ user = postfix
+ group = postfix
+

# Auth process is run as this user.
#user = $default_internal_user

Aliases Now Email will automatically put into the '~/Mail' directory of the receiver. So a user has to be created for whom one wants to receive mail...
$ adduser josch
...and any aliases for it to be configured in /etc/aliases.
@@ -1,2 +1,4 @@
-# See man 5 aliases for format
-postmaster: root
+root: josch
+postmaster: josch
+hostmaster: josch
+webmaster: josch
After editing /etc/aliases, the command
$ newaliases
has to be run. More can be read in the aliases(5) man page.

Finishing up Everything is done and now postfix and dovecot have to be informed about the changes. There are many ways to do that. Either restart the services, reboot or just do:
$ postfix reload
$ doveadm reload
Have fun!

28 November 2014

Daniel Pocock: XCP / XenServer and Debian Jessie

In 2013, Debian wheezy was released with a number of great virtualization options include the Xen Cloud Platform (XCP / Xen-API) toolstack packaged by Thomas Goirand to run in a native Debian host environment. Unfortunately, XCP is not available as a host (dom0) solution for the upcoming Debian 8 (jessie) release. However, it is possible to continue running a Debian wheezy system as the dom0 host and run virtualized (domU) jessie systems inside it. It may also be possible to use the packages from wheezy on a jessie system, but I haven't looked into that myself so far. Newer kernel boot failures in Xen After successfully upgrading a VM (domU in Xen terminology) from wheezy to jessie, I tried to reboot the VM and found that it wouldn't start. People have reported similar problems booting newer versions of Ubuntu and Fedora in XCP and XenServer environments. PyGrub displayed an error on the dom0 console:
# xe vm-start name-label=server05
Error code: Using  to parse /grub/grub.cfg
Error parameters: Traceback (most recent call last):,
   File "/usr/lib/xcp/lib/pygrub.xcp", line 853, in ,
     raise RuntimeError, "Unable to find partition containing kernel"
There is a quick and easy workaround. Hard-code the kernel and initrd filenames into config values that will be used to boot. A more thorough solution will probably involve using a newer version of PyGrub in wheezy. If the /boot tree is a separate filesystem inside the VM, use commands like the following (substitute the correct UUID for the VM and the exact names/versions of the vmlinuz and initrd.img files):
xe vm-param-set uuid=da654fd0-74db-11e4-82f8-0800200c9a66 \
   PV-bootloader-args="--kernel=/vmlinuz-3.16-3-amd64
   --ramdisk=/initrd.img-3.16-3-amd64"
xe vm-param-set uuid=da654fd0-74db-11e4-82f8-0800200c9a66 \
   PV-args="root=/dev/mapper/vg00-root ro quiet"
and if /boot is on the root filesystem of the VM, this will do the trick:
xe vm-param-set uuid=da654fd0-74db-11e4-82f8-0800200c9a66 \
   PV-bootloader-args="--kernel=/boot/vmlinuz-3.16-3-amd64
   --ramdisk=/boot/initrd.img-3.16-3-amd64"
xe vm-param-set uuid=da654fd0-74db-11e4-82f8-0800200c9a66 \
   PV-args="root=/dev/mapper/vg00-root ro quiet"
Future strategy Once a comprehensive XCP solution appears in Debian again, hopefully it will be possible to migrate running VMs into the new platform without any downtime and retire the wheezy dom0. Other upgrade/migration options exist and the choice will depend on various factors, such as whether or not you have built your own tools around the XCP API and whether you use a solution like OpenStack that depends on it. Debian's pkg-xen-devel mailing list may be a good place to discuss these options further.

Ian Wienand: rstdiary

I find it very useful to spend 5 minutes a day to keep a small log of what was worked on, major bugs or reviews and a general small status report. It makes rolling up into a bigger status report easier when required, or handy as a reference before you go into meetings etc. I was happily using an etherpad page until I couldn't save any more revisions and the page got too long and started giving javascript timeouts. For a replacement I wanted a single file as input with no boilerplate to aid in back-referencing and adding entries quickly. It should be formatted to be future-proof, as well as being emacs, makefile and git friendly. Output should be web-based so I can refer to it easily and point people at it when required, but it just has to be rsynced to public_html with zero setup. rstdiary will take a flat RST based input file and chunk it into some reasonable looking static-HTML that looks something like this. It's split by month with some minimal navigation. Copy the output directory somewhere and it is done. It might also serve as a small example of parsing and converting RST nodes where it does the chunking; unfortunately the official documentation on that is "to be completed" and I couldn't find anything like a canonical example, so I gathered what I could from looking at the source of the transformation stuff. As the license says, the software is provided "as is" without warranty! So if you've been thinking "I should keep a short daily journal in a flat-file and publish it to a web-server but I can't find any software to do just that" you now have one less excuse.

27 November 2014

Niels Thykier: Volume of debian-release mailing list

Page 1 of 5 To be honest, I do not know how many mails it shows per page (though I assume it is a fixed number). So for comparison, I found the month on debian-devel@l.d.o with the highest volume in the past two years: May 2013 with Page 1 of 4 . I hope you will please forgive us, if we are a bit terse in our replies or slow to reply. We simply got a lot to deal with. :)

Stefano Zacchiroli: CTTE nomination

Apparently, enough fellow developers have been foolish enough to nominate me as a prospective member of the Debian Technical Committee (CTTE), that I've been approached to formally accept/decline the nomination. (Accepted nominees would then go through a selection process and possibly proposed to the DPL for nomination.) I'm honored by the nominations and I thank the fellow developers that have thrown my name in the hat. But I've respectfully declined the nomination. Given my current involvement in an ongoing attempt to introduce a maximum term limit for CTTE membership, it would have been highly inappropriate for me to accept the nomination at this time. I have no doubt that the current CTTE and the DPL will fill the empty seats with worthy project members.

Jonathan Dowland: PGP transition statement

-----BEGIN PGP SIGNED MESSAGE-----
Hash: SHA512,SHA1
I'm transitioning from my old, 1024-bit DSA PGP key, FD35 0B0A C6DD 5D91 DB7A 83D1 168B 4E71 7032 F238, to my newer, 4096-bit RSA key, E037 CB2A 1A00 61B9 4336 3C8B 0907 4096 06AA AAAA. If you have signed my old key, I'd be very grateful if you would consider signing my new key. (Thanks in advance!) This is long overdue! I've had 06AAAAAA since 2009, but it took me a while to get enough signatures on it for me to consider a transition. I still have far more signatures on my older key, owing to attending more conferences when I was using it than since I switched. This statement, available in plaintext at http://jmtd.net/log/pgp_transition/statement.txt, has been signed with both keys. I've marked my old key as expiring in around 72 days time, which coincides with my change of job, and will be just short of ten years since I generated it.
-----BEGIN PGP SIGNATURE-----
Version: GnuPG/MacGPG2 v2.0.22 (Darwin)
iQIcBAEBCgAGBQJUdysuAAoJEAkHQJYGqqqquQ0QALVGcn9Wbasg0oh8JeE8rN7h
k7FeZjmGk+ZwfXwo4Eq4pjxKp+TN+r4xBCFSHDRmMaAm9q7aWF/RqkdNiEtioQfJ
SmfzLsoEnSBmS9dr1LvAoxIlUzs/9Lt8EY2tB4NQne3QIu3VyRBjQDvqff6KJgkV
849+GsrJezkg/2VFZkZp1N9y0YwrmezV/1j0N6zR8Y20LlF4YuD3egUJYvbrQ1pA
krJwhiHskXRinqviYMg4CuTZZ3m2wc4fM6uiY5t9taqK90KFgmg73KvW6Rx2L+XP
BUzTlSYHnK+qI23Cng//DthFww2Wf9RofkfRgXk0zAe4+DcoMZzALKtZQA6GrT46
wzsmu459p5nUwwa6BzUvqBzyVtzbtHN5xaFwbjHCPlemsFlH/8LHackJLsBvr2Gp
q292huYu/HNo+Q6OIslFX6rc5AR3HKdbU2DxYMPAfI+CEtW1XwetK8ADSZc1v54C
+sc+Yb2kAleLX2xMIfS9JqvcKOP2Gbo7nTdRPnS2jZRWOv8JxVfFiSzHVODtlLfk
AmRvms5rQ2nPnB21yOd+DP2sACVKY0MS7/UwMh2hoQLR/bSu/jRh24n3WHDfQWtF
Jp4AD80ABFV2t/pSP1L70HlxwPmOzra8AVzCdXMOT/SdT387rSM9fvue4FY5goT+
/pResJSl9pAbBCtjOFJoiEYEARECAAYFAlR3Ky4ACgkQFotOcXAy8jiLawCgofsp
ggze/iSpfkyeL0vhXi6N/WMAoLQogFQY+VaQrVP3lGl1VVh4jw0W
=JBA4
-----END PGP SIGNATURE-----

Keith Packard: Black Friday 2014

Altus Metrum's 2014 Black Friday Event BLACK FOREST, Colorado USA Altus Metrum announces two special offers for "Black Friday" 2014. We are pleased to announce that both TeleMetrum and TeleMega will be back in stock and available for shipment before the end of November. To celebrate this, any purchase of a TeleMetrum, TeleMega, or EasyMega board will include, free of charge, one each of our 160, 400, and 850 mAh Polymer Lithium Ion batteries and a free micro USB cable! To celebrate NAR's addition of our 1.9 gram recording altimeter, MicroPeak, to the list of devices approved for use in contests and records, and help everyone get ready for NARAM 2015's altitude events, purchase 4 MicroPeak boards and we'll throw in a MicroPeak USB adapter for free! These deals will be available from 00:00 Friday, 28 November 2014 through 23:59 Monday, 1 December, 2014. Only direct sales through our web store at http://shop.gag.com are included; no other discounts apply. Find more information on all Altus Metrum products at http://altusmetrum.org. Thank you for your continued support of Altus Metrum in 2014. We continue to work on more cool new products, and look forward to meeting many of you on various flight lines in 2015!

26 November 2014

Gunnar Wolf: Guests in the classroom: @Rolman talks about persistent storage and filesystems

On November 14, as a great way to say goodbye to a semester, a good friend came to my class again to present a topic to the group; a good way to sum up the contents of this talk is "everything you ever wondered about persistent storage". As people who follow my blog know, I like inviting my friends to present selected topics in my Operating Systems class. Many subjects will stick better if presented by more than a single viewpoint, and different experiences will surely enrich the group's learning. So, here is Rolando Cedillo A full gigabyte of him, spawning two hours (including two hiccups where my camera hit a per-file limit...). Rolando is currently a RedHat Engineer, and in his long career, he has worked from so many trenches, it would be a crime not to have him! Of course, one day we should do a low-level hardware session with him, as his passion (and deep knowledge) for 8-bit arcades is beyond any other person I have met. So, here is the full video on my server. Alternatively, you can get it from The Internet Archive.

Francois Marier: Hiding network disconnections using an IRC bouncer

A bouncer can be a useful tool if you rely on IRC for team communication and instant messaging. The most common use of such a server is to be permanently connected to IRC and to buffer messages while your client is disconnected. However, that's not what got me interested in this tool. I'm not looking for another place where messages accumulate and wait to be processed later. I'm much happier if people email me when I'm not around. Instead, I wanted to do to irssi what mosh did to ssh clients: transparently handle and hide temporary disconnections. Here's how I set everything up.

Server setup The first step is to install znc:
apt-get install znc
Make sure you get the 1.0 series (in jessie or trusty, not wheezy or precise) since it has much better multi-network support. Then, as a non-root user, generate a self-signed TLS certificate for it:
openssl req -x509 -sha256 -newkey rsa:2048 -keyout znc.pem -nodes -out znc.crt -days 365
and make sure you use something like irc.example.com as the subject name, that is the URL you will be connecting to from your IRC client. Then install the certificate in the right place:
mkdir ~/.znc
mv znc.pem ~/.znc/
cat znc.crt >> ~/.znc/znc.pem
Once that's done, you're ready to create a config file for znc using the znc --makeconf command, again as the same non-root user:
  • create separate znc users if you have separate nicks on different networks
  • use your nickserv password as the server password for each network
  • enable ssl
  • say no to the chansaver and nickserv plugins
Finally, open the IRC port (tcp port 6697 by default) in your firewall:
iptables -A INPUT -p tcp --dport 6697 -j ACCEPT

Client setup (irssi) On the client side, the official documentation covers a number of IRC clients, but the irssi page was quite sparse. Here's what I used for the two networks I connect to (irc.oftc.net and irc.mozilla.org):
servers = (
   
    address = "irc.example.com";
    chatnet = "OFTC";
    password = "fmarier/oftc:Passw0rd1!";
    port = "6697";
    use_ssl = "yes";
    ssl_verify = "yes";
    ssl_cafile = "~/.irssi/certs/znc.crt";
   ,
   
    address = "irc.example.com";
    chatnet = "Mozilla";
    password = "francois/mozilla:Passw0rd1!";
    port = "6697";
    use_ssl = "yes";
    ssl_verify = "yes";
    ssl_cafile = "~/.irssi/certs/znc.crt";
   
);
Of course, you'll need to copy your znc.crt file from the server into ~/.irssi/certs/znc.crt. Make sure that you're no longer authenticating with the nickserv from within irssi. That's znc's job now.

Wrapper scripts So far, this is a pretty standard znc+irssi setup. What makes it work with my workflow is the wrapper script I wrote to enable znc before starting irssi and then prompt to turn it off after exiting:
#!/bin/bash
ssh irc.example.com "pgrep znc   znc"
irssi
read -p "Terminate the bouncer? [y/N] " -n 1 -r
echo
if [[ $REPLY =~ ^[Yy]$ ]]
then
  ssh irc.example.com killall -sSIGINT znc
fi
Now, instead of typing irssi to start my IRC client, I use irc. If I'm exiting irssi before commuting or because I need to reboot for a kernel update, I keep the bouncer running. At the end of the day, I say yes to killing the bouncer. That way, I don't have a backlog to go through when I wake up the next day.

25 November 2014

Enrico Zini: mock-webserver

A mock webserver to use for unit testing HTTP clients With python -m SimpleHTTPServer it's easy to bring up an HTTP server to use to test HTTP client code, however it only supports GET requests, and I needed to test an HTTP client that needs to perform a file upload. It took way more than I originally expected to put this together, so here it is, hopefully saving other people (including future me) some time:
#!/usr/bin/python3
import http.server
import cgi
import socketserver
import hashlib
import json
PORT = 8081
class Handler(http.server.SimpleHTTPRequestHandler):
    def do_POST(self):
        info =  
            "method": "POST",
            "headers":   k: v for k, v in self.headers.items()  ,
         
        # From https://snipt.net/raw/f8ef141069c3e7ac7e0134c6b58c25bf/?nice
        form = cgi.FieldStorage(
            fp=self.rfile,
            headers=self.headers,
            environ= 'REQUEST_METHOD':'POST',
                     'CONTENT_TYPE':self.headers['Content-Type'],
                      )
        postdata =  
        for k in form.keys():
            if form[k].file:
                buf = form.getvalue(k)
                postdata[k] =  
                    "type": "file",
                    "name": form[k].filename,
                    "size": len(buf),
                    # json.dumps will not serialize a byte() object, so we
                    # return the shasum instead of the file body
                    "sha256": hashlib.sha256(buf).hexdigest(),
                 
            else:
                vals = form.getlist(k)
                if len(vals) == 1:
                    postdata[k] =  
                        "type": "field",
                        "val": vals[0],
                     
                else:
                    postdata[k] =  
                        "type": "multifield",
                        "vals": vals,
                     
        info["postdata"] = postdata
        resbody = json.dumps(info, indent=1)
        print(resbody)
        resbody = resbody.encode("utf-8")
        self.send_response(200)
        self.send_header("Content-type", "application/json")
        self.send_header("Content-Length", str(len(resbody)))
        self.end_headers()
        self.wfile.write(resbody)
class TCPServer(socketserver.TCPServer):
    # Allow to restart the mock server without needing to wait for the socket
    # to end TIME_WAIT: we only listen locally, and we may restart often in
    # some workflows
    allow_reuse_address = True
httpd = TCPServer(("", PORT), Handler)
print("serving at port", PORT)
httpd.serve_forever()

Erich Schubert: Installing Debian with sysvinit

First let me note that I am using systemd, so these things here are untested by me. See e.g. Petter's and Simon's blog entries on the same overall topic.
According to the Debian installer maintainers, the only accepted way to install Debian with sysvinit is to use preseeding. This can either be done at the installer boot prompt by manually typing the magic spell:
preseed/late_command="in-target apt-get install -y sysvinit-core"
or by using a preseeding file (which is a really nice feature I used for installing my Hadoop nodes) to do the same:
d-i preseed/late_command string in-target apt-get install -y sysvinit-core
If you are a sysadmin, using preseeding can save you a lot of typing. Put all your desired configuration into preseeding files, put them on a webserver (best with a short name resolvable by local DNS). Let's assume you have set up the DNS name d-i.example.com, and your DHCP is configured such that example.com is on the DNS search list. You can also add a vendor extension to DHCP to serve a full URL. Manually enabling preseeding then means adding
auto url=d-i
to the installer boot command line (d-i is the hostname I suggested to set up in your DNS before, and the full URL would then be http://d-i.example.com/d-i/jessie/./preseed.cfg. Preseeding is well documented in Appendix B of the installer manual, but nevertheless will require a number of iterations to get everything work as desired for a fully automatic install like I used for my Hadoop nodes.

There might be an easier option.
I have filed a wishlist bug suggesting to use the tasksel mechanism to allow the user to choose sysvinit at installation time. However, it got turned down by the Debian installer maintainers quire rudely in a "No." - essentially this is a "shut the f... up and go away", which is in my opinion an inappropriate to discard a reasonable user wishlist request.
Since I don't intend to use sysvinit anymore, I will not be pursuing this option further. It is, as far as I can tell, still untested. If it works, it might be the least-effort, least-invasive option to allow the installation of sysvinit Jessie (except for above command line magic).
If you have interest in sysvinit, you (because I don't use sysvinit) should now test if this approach works.
  1. Get the patch proposed to add a task-sysvinit package.
  2. Build an installer CD with this tasksel (maybe this documentation is helpful for this step).
  3. Test whether the patch works. Report results to above bug report, so that others interested in sysvinit can find them easily.
  4. Find and fix bugs if it didn't work. Repeat.
  5. Publish the modified ("forked") installer, and get user feedback.
If you are then still up for a fight, you can try to convince the maintainers (or go the nasty way, and ask the CTTE for their opinion, to start another flamewar and make more maintainers give up) that this option should be added to the mainline installer. And hurry up, or you may at best get this into Jessie reloaded, 8.1. - chance are that the release manager will not accept such patches this late anymore. The sysvinit supporters should have investigated this option much, much earlier instead of losing time on the GR.
Again, I won't be doing this job for you. I'm happy with systemd. But patches and proof-of-concept is what makes open source work, not GRs and MikeeUSA's crap videos spammed to the LKML...
(And yes, I am quite annoyed by the way the Debian installer maintainers handled the bug report. This is not how open-source collaboration is supposed to work. I tried to file a proper wishlist bug reporting, suggesting a solution that I could not find discussed anywhere before and got back just this "No. Shut up." answer. I'm not sure if I will be reporting a bug in debian-installer ever again, if this is the way they handle bug reports ...)
I do care about our users, though. If you look at popcon "vote" results, we have 4179 votes for sysvinit-core and 16918 votes for systemd-sysv (graph) indicating that of those already testing jessie and beyond - neglecting 65 upstart votes, and assuming that there is no bias to not-upgrade if you prefer sysvinit - about 20% appear to prefer sysvinit (in fact, they may even have manually switched back to sysvinit after being upgraded to systemd unintentionally?). These are users that we should listen to, and that we should consider adding an installer option for, too.

Next.

Previous.