
Search Results: "xam"

30 August 2008

Frank S. Thomas: Converting git-svn tag branches to real tags

Over the last few days I’ve converted some Subversion repositories used for Debian packaging to Git. None of these Subversion repositories contained upstream sources because of Subversion’s storage inefficiency. With Git I wanted to change that and also track the upstream sources in my repositories. To move a Git repository from a debian-only to debian+upstream layout I found zack’s recipe very helpful. The actual conversion to Git was done with git-svn. I cloned the Subversion repositories with git-svn’s --prefix=svn-import/ and --stdlayout options so that the trunk and all branches and tags were imported as remote branches with svn-import/ prepended. Then I created local branches of the previous Subversion branches and removed the remote remnants, for example:
git checkout -b debian/backports/etch svn-import/branches/etch-backports
git branch -d -r svn-import/branches/etch-backports
The Subversion tags are imported as svn-import/tags/<version> where <version> is the Debian version number. I don’t need branches for every version of my packages but I wanted to convert these tags to real Git tags but without losing the actual commit dates and messages. To achieve this I wrote this small script:
#!/bin/bash
for branch in  git branch -r ; do
    if [  echo $branch   egrep "svn-import/tags/.+$"  ]; then
        version= basename $branch 
        subject= git log -1 --pretty=format:"%s" $branch 
        export GIT_COMMITTER_DATE= git log -1 --pretty=format:"%ci" $branch 
        echo "Tag $version [Y/n]?"
        read yesno
        if [ -z $yesno ]   [ $yesno = "Y" ]; then
            git tag -s -f -m "$subject" "debian/$version" "$branch^"
            git branch -d -r $branch
        fi
    fi
done
For each remote branch that contains svn-import/tags/ it gets the version number, the commit message of the tag and exports GIT_COMMITTER_DATE (man git-tag) with the value of the date the version was tagged in Subversion and then asks you if it should tag the parent of the tag branch with the original commit date and message and remove the then unnecessary tag branch. The “safety measure” is there because people sometimes commit directly to Subversion tags (ugh!) and then "$branch^" would not be the commit you want to tag. To decide which Subversion tags are safe to tag with this script, gitk --all can be of great help. P.S.: This is my first post on Planet Debian, so hello Planet! :-)

Jaldhar Vyas: And That Just About Wraps it up For Obama

The McCain campaign made a great tactical move by choosing Sarah Palin. She appeals to all the constituencies where McCain was weak: women, Christians, Libertarians, small state residents, energy policy wonks, corruption fighters, capitalists, gun enthusiasts, and Tina Fey fetishists. Downsides? She is inexperienced in national affairs but I really don't think the average voter will care. After all many of them were willing to overlook a similar level of inexperience in Obama. And there is one minor possible ethics situation which again will only excite the true believers. When it turns out to be overblown it may actually rebound in Palins favor as an example of MSM manipulation. She can also take the change meme away from the Democrats though that was already on the rocks what with the FISA vote and the choice of Neil Kinnock as his VP nominee. No, the lacklustre convention in Denver clearly showed that far from being the post-ideological, audaciously hopeful candidate of the future, Barack Obama is merely John Kerry with rhythm. So what do the Dems have have left? The traditional Democratic themes of "We're not Bush" (that worked sooo well the last two times didn't it?) and "The Earth is about to explode in a fiery cataclysm." As the situation in Iraq improves, the economy climbs upwards from recession and petrol prices continue to come down its going to be harder to sustain the necessary level of gloom and doom. While Republicans shouldn't exhale just yet (and the title of this post is just a teensy bit hyperbolic,) things are looking pretty good for us at the moment.

29 August 2008

Erich Schubert: Xorg hotplugging

From Roderich Schupp I received the following instructions:
cp /usr/share/doc/hal/examples/10-x11-input.fdi /etc/hal/fdi/policy/
And in order to set a default keymap:
<deviceinfo version="0.2">
  <device>
    <match key="input.xkb.rules" contains="base">
      <merge key="input.xkb.layout" type="string">de</merge>
      <merge key="input.xkb.variant" type="string">nodeadkeys</merge>
    </match>
  </device>
</deviceinfo>
Into yet another custom file in this directory.Thank you, I'm going to try that on my next reboot (which may take a week).

27 August 2008

Dirk Eddelbuettel: littler 0.1.1 released

The new release 0.1.1 of r (pronounced littler) was just rolled up. The only new feature is due to a suggestion by Paul Gilbert: r now reports the value of the optional status variable when calling q() at the end of a script:
$ r -e'q(status=42)'; echo $?
42
This can be very useful to signal exit codes and branching on those in other scripts or Makefile. We also applied a patch to manual page which adds some examples there (thanks, Seb!) and made some small changes to tests and examples. As usual, our code in our svn archive, on my r page, and in the local directory here. A fresh package is in Debian's incoming queue, and Jeff's littler page at Vanderbilt should reflect the new release soon too.

26 August 2008

Russell Coker: Killing Servers with Virtualisation and Swap

The Problem: A problem with virtual machines is the fact that one rogue DomU can destroy the performance of all the others by inappropriate resource use. CPU scheduling is designed to allow reasonable sharing of computational resources, it is unfortunately not well documented, the XenSource wiki currently doesn’t document the “credit” scheduler which is used in Debian/Etch and CentOS 5 [1]. One interesting fact is that CPU scheduling in Xen can have a significant effect on IO performance as demonstrated in the paper by Ludmila Cherkasova, Diwaker Gupta and Amin Vahdat [2]. But they only showed a factor of two performance difference (which while bad is not THAT bad). A more significant problem is managing virtual memory, when there is excessive paging performance can drop by a factor of 100 and even the most basic tasks become impossible. The design of Xen is that every DomU is allocated some physical RAM and has it’s own swap space. I have previously written about my experiments to optimise swap usage on Xen systems by using a tmpfs in the Dom0 [3]. The aim was to have every Xen DomU swap data out to a tmpfs so that if one DomU was paging heavily and the other DomUs were not paging then the paging might take place in the Dom0’s RAM and not hit disk. The experiments were not particularly successful but I would be interested in seeing further research in this area as there might be some potential to do some good. I have previously written about the issues related to swap space sizing on Linux [4]. My conclusion is that following the “twice RAM” myth will lead to systems becoming unusable due to excessive swapping in situations where they might otherwise be usable if the kernel killed some processes instead (naturally there are exceptions to my general rule due to different application memory use patterns - but I think that my general rule is a lot better than the “twice RAM” one). One thing that I didn’t consider at the time is the implications of this problem for Xen servers. If you have 10 physical machines and one starts paging excessively then you have one machine to reboot. If you have 10 Xen DomUs on a single host and one starts paging heavily then you end up with one machine that is unusable due to thrashing and nine machines that deliver very poor disk read performance - which might make them unusable too. Read performance can particularly suffer in a situation when one process or VM is writing heavily to disk due to the way that the disk queuing works, it’s not uncommon for an application to read dozens or hundreds of blocks from disk to satisfy a single trivial request from a user, if each of these block read requests has to wait for a large amount of data to be written out from the write-back cache then performance will suck badly (I have seen this in experiments on single disks and on Linux software RAID - but have not had the opportunity to do good tests on a hardware RAID array). Currently for Xen DomUs I am allocating swap spaces no larger than 512M, as anything larger than that is likely to cause excessive performance loss to the rest of the server if it is actually used. A Solution for Similar Problems: A well known optimisation technique of desktop systems is to use a separate disk for swap, in desktop machines people often use the old disk as swap after buying a new larger disk for main storage. The benefit of this is that swap use will not interfere with other disk use, for example the disk reads needed to run the “ps” and “kill” programs won’t be blocked by the memory hog that you want to kill. I believe that similar techniques can be applied to Xen servers and give even greater benefits. When a desktop machine starts paging excessively the user will eventually take a coffee break and let the machine recover, but when an Internet server such as a web server starts paging excessively the requests keep coming in and the number of active processes increases so it seems likely that using a different device for the swap will allow some processes to satisfy requests by reading data from disk while some other processes are waiting to be paged in. Applying it to Xen Servers: The first thing that needs to be considered for such a design is the importance of reliable swap. When it comes to low-end servers there is ongoing discussion about the relative merits of RAID-0 and RAID-1 for swap. The benefit of RAID-0 is performance (at least in perception - I can imagine some OS swapping algorithms that could potentially give better performance on RAID-1 and I am not aware of any research in this area). The benefit of RAID-1 is reliability. Now there are two issues in regard to reliability, one is continuity of service (EG being able to hot-swap a failed disk while the server is running), and the other is the absence of data loss. For some systems it may be acceptable to have a process SEGV (which I presume is the result if a page-in request fails) due to a dead disk (reserving the data loss protection of RAID for files). One issue related to this is the ability to regain control of a server after a problem. For example if the host OS of a machine had non-RAID swap then a disk failure could prevent a page-in of data related to sshd or some similar process and thus make it impossible to recover the machine without hardware access. But if the swap for a virtual machine was on a non-RAID disk and the host had RAID for it’s swap then the sysadmin could login to the host and reboot the DomU after creating a new swap space on a working disk. Now if you have a server with 8 or 12 disks (both of which seem to be reasonably common capacities of modern 2RU servers) and if you decide that RAID is not required for the swap space of DomUs then it would be possible to assign single disks for swap spaces for groups of virtual machines. So if one client had several virtual machines they could have them share the same single disk for the swap, so a thrashing server would only affect the performance of other VMs from the same client. One possible configuration would be a 12 disk server that has a four disk RAID-5 array for main storage and 8 single disks for swap. 8 CPU cores is common for a modern 2RU server, so it would be possible to lock 8 groups of DomUs so that they share CPUs and swap spaces. Another possibility would be to have four groups of DomUs where each group had a RAID-1 array for swap and two CPU cores. I am not sure of the aggregate performance impact of such a configuration, I suspect that a group of single disks would give better performance for swap than a single RAID array and that RAID-1 would outperform RAID-5. For a single DomU it seems most likely that using part of a large RAID array for swap space would give better performance. But the benefit in partitioning the server seems clear. An architecture where each DomU had it’s own dedicated disk for a swap space is something that I would consider a significant benefit if renting a Xen DomU. I would rather have the risk of down-time (which should be short with hot-swap disks and hardware monitoring) in the rare case of a disk failure than have bad performance regularly in the common situation of someone else’s DomU being overloaded. Failing that, having a separate RAID array for swap would be a significant benefit. If every process that isn’t being paged out could deliver full performance while one DomU was thrashing then it would be a significant benefit over the situation where any DomU can thrash and kill the file access performance of all other DomUs. A single RAID-1 array should handle all the swap space requirements for a small or medium size Xen server One thing that I have not tested is the operation of LVM when one disk goes bad. In the case of a disk with bad sectors it’s possible to move the LVs that are not affected to other disks and to remove the LV that was affected and re-create it after removing the bad disk. The case of a disk that is totally dead (IE the PV header can’t be read or written) might cause some additional complications.

25 August 2008

Russell Coker: Is SE Linux Unixish?

In a comment on my AppArmor is dead post [1] someone complained that SE Linux is not “Unixish“. The security model in Unix is almost exclusively Discretionary Access Control (DAC) [2]. This means that any process that owns a resource can grant access to the resource to other processes without restriction. For example a user can run “chmod 777 ~” and grant every other user on the system the ability to access their files (and take over their account by modifying ~/.login and similar files). I say that it’s almost exclusively DAC because there are some things that a user can not give away, for example they can not permit a program running under a different non-root UID to ptrace their processes. But for file and directory access it’s entirely discretionary. SE Linux is based around the concept of Mandatory Access Control (MAC) [3]. This means that the system security policy (as defined by the people who developed the distribution and the local sysadmin) can not be overridden by the user. When a daemon is prevented from accessing files in a user’s home directory by the SE Linux policy and the user is not running in the unconfined_t domain there is no possibility of them granting access. SE Linux has separate measures for protecting integrity and confidentiality. An option is to use MultiLevel Security (MLS) [4], but a more user-friendly option is MCS (Multi-Category Security). The design of SE Linux is based on the concept of having as much of the security policy as possible being loaded at boot time. The design of the Unix permissions model was based on the concept of using the minimal amount of memory at a time when 1M of RAM was a big machine. An access control policy is comprised of two parts, file labels (which is UID, GID, permissions, and maybe ACLs for Unix access controls and a “security context” for SE Linux) and a policy which determines how those file labels are used. The policy in the Unix system is compiled into the kernel and is essentially impossible to change. The SE Linux policy is loaded at boot time, and the most extreme changes to the policy will at most require a reboot. The policy language used for SE Linux is based on the concept of deny by default (everything that is not specifically permitted is denied) and access controls apply to all operations. The Unix access control is mostly permissive and many operations (such as seeing more privileged processes in the output of “ps”) can not be denied on a standard Unix system. So it seems that in many ways SE Linux is not “Unixish”, and it seems to me that any system which makes a Unix system reasonably secure could also be considered to be “not Unixish”. Unix just wasn’t designed for security, not that it is bad by the standards of modern server and desktop OSs. Of course many of the compromises in the design of Unix (such as having all login sessions recorded in a single /var/run/utmp file and having all user accounts stored in a single /etc/passwd file) impact SE Linux systems. But some of them can be worked around, and others will be fixed eventually.

24 August 2008

Russell Coker: Xen and Linux Memory Assignment Bugs

The Linux kernel has a number of code sections which look at the apparent size of the machine and determine what would be the best size for buffers. For physical hardware this makes sense as the hardware doesn’t change at runtime. There are many situations where performance can be improved by using more memory for buffers, enabling large buffers for those situations when the machine has a lot of memory makes it convenient for the sysadmin. Virtual machines change things as the memory available to the kernel may change at run-time. For Xen the most common case is the Dom0 automatically shrinking when memory is taken by a DomU - but it also supports removing memory from a DomU via the xm mem-set command (the use of xm mem-set seems very rare). Now a server that is purchased for the purpose of running Xen will have a moderate amount of RAM. In recent times the smallest machine I’ve seen purchased for running Xen had 4G of RAM - and it has spare DIMM slots for another 4G if necessary. While a non-virtual server with 8G of RAM would be an unusually powerful machine dedicated for some demanding application, a Xen server with 8G or 16G of RAM is not excessively big, it’s merely got space for more DomU’s. For example one of my Xen servers has 8 CPU cores, 8G of RAM, and 14 DomUs. Each DomU has on average just over half a gig of RAM and half of a CPU core - not particularly big. In a default configuration the Dom0 will start by using all the RAM in the machine, which in this case meant that the buffer sizes were appropriate for a machine with 8G of RAM. Then as DomUs are started memory is removed from the Dom0 and these buffers become a problem. This ended up forcing a reboot of the machine by preventing Xen virtual network access to most of the DomUs. I was seeing many messages in the Dom0 kernel message log such as “xen_net: Memory squeeze in netback driver” and most DomUs were inaccessible from the Internet (I didn’t verify that all DomUs were partially or fully unavailable or test the back-end network as I was in a hurry to shut it down and reboot before too many customers complained). The solution to this is to have the Dom0 start by using a small amount of RAM. To do this I edited the GRUB configuration file and put “dom0_mem=256000” at the end of the Xen kernel line (that is the line starting with “kernel /xen.gz“). This gives the Dom0 kernel just under 256M of RAM from when it is first loaded and prevents allocation of bad buffer sizes, it’s the only solution to this network problem that a quick Google search (the kind you do when trying to fix a serious outage before your client notices (*)) could find. One thing to note is that my belief that it’s kernel buffer sizes that are at the root cause of this problem is based on my knowledge of how some of the buffers are allocated plus an observation of the symptoms. I don’t have a test machine with anything near 8G of RAM so I really can’t do anything more to track this down. There is another benefit to limiting the Dom0 memory, I have found that on smaller machines it’s impossible to reduce the Dom0 memory below a certain limit at run-time. In the past I’ve had problems in reducing the memory of a Dom0 below about 250M, while such a reduction is hardly desirable on a machine with 8G of RAM, when running an old P3 machine with 512M of RAM there are serious benefits to making Dom0 smaller than that. As a general rule I recommend having a limit on the memory of the Dom0 on all Xen servers. If you use the model of having no services running on the Dom0 there is no benefit in having much ram assigned to it. (*) Hiding problems from a client is a bad idea and is not something I recommend. But being able to fix a problem and then tell the client that it’s already fixed is much better than having them call you when you don’t know how long the fix will take.

Jonathan McDowell: DebConf8 writeup

I took a note of the various talks I attended at DebConf, with the aim of writing a few notes about each so that I could try to explain to my work mates exactly what I get out of going. However I think a lot of the benefit is about general face to face contact with fellow DDs and random conversations that happen. Having worked from home for over 3 years I'm finding it quite nice to be back in an office with people working on the same things as me; there are conversations that you will have over a quick cup of coffee or in the corridor that you wouldn't bother typing on IRC or email or picking up the phone for. Debian is a lot like a large organisation full of telecommuters and DebConf provides a vital opportunity for us to have those "minor" conversations that prove quite useful and to remind each other what we're actually like in person. I didn't end up writing a lot of notes during the talks so these are just snippets after the fact. If I'd been more organised I'd have done a write up on a daily basis rather than leaving it all until the week after. A lot of the below is fragmented thoughts, but the longer I leave it the less relevant it gets and the more chance I forget something. It'd have been up faster if I hadn't been fighting Movable Type to try and get some sort of headings. Sunday
Introduction, Marga The "Welcome to DebConf" bit. Marga got up and talked about how at DebConf4 (Brazil) she hadn't been a DD and now she was and how it had been a life changing event. She'd thought she was to blame for DebConf8 in Argentina, but trawling mail archives had shown it was originally Mart n's idea. She hadn't realised at the start quite how much work it would be. Steve's DPL talk, Steve McIntyre The DPL welcomes us to DebConf and talks about Debian's achievements, some of the results of his team survey (the teams largely say they need more manpower. Not really a huge surprise.). NM/User Survey BOF, Paul Wise Paul emailed debian-user, debian-newmaint and various other places (I think) asking about people's experiences as a Debian user or applicant to New Maint. His final results aren't yet published and I got the impression a disappointing number of our users had replied. The NM problems these days seem to be largely down to a lack of AMs, at least according to the stats on nm.debian.org. Meet SPI board - bdale, maulkin, jimmy, michael, others A chance to meet those of the SPI board who were present. The usual "If you're involved with Debian you should seriously consider joining SPI". Some discussion about the fact that although SPI was originally mostly Debian these days other projects are making more and more use of it - OFTC, PostgreSQL and Madwifi for example. Not a huge amount of new information for me. I've been an SPI member for some time and I think they perform a vital role for Debian. They've had issues in the past but it's really good to see them overcome and more projects on board. Monday
http://hp.com/go/debian, bdale Bdale talks about the history of Debian and HP. And makes the point that HP aren't doing any of this to be "nice"; their primary responsibility is to their shareholders. Not surprising, but it's good that even with that criteria at the fore front Debian ends up a good idea for a large multinational. Managing 666 packages, Mart n Ferrari Mostly centered around the pkg-perl experience and the tools/workflow they have to help manage things. Impressive web tool (DEHS) to help track packages with new upstreams, issues or pending uploads. Quality Assurance in Lenny + 1 I can't remember a lot of this, which is a bit bad. I remember a discussion about whether we should release with orphaned packages, or if they should be removed. The argument for not removing them seemed to revolve around a theory that if they weren't buggy then what was the harm, the argument for was that if they were unmaintained and not really used than how did we actually know they weren't buggy, and was it reasonable that they potentially held up library transitions etc? Bugs in large packages Don Armstrong and ways in which the BTS can help people with lots of bugs. This (thankfully) doesn't affect me, but it was interesting to hear Don talk about his work on the BTS and his various ideas. I was sorry I'd missed his talk on SOAP access to it; I shall have to find time to watch the video. Tuesday
Debian and Ubuntu, Mark Shuttleworth The usual interaction with Debian stuff, including how we interact with our upstreams. If a bug is raised with an Ubuntu package then it might well be appropriate to raise it with Debian and upstream as well, but each set of people should be able to use their own bug reporting systems rather than having to go to a foreign system. I don't think it was actually said, but I guess the idea is that launchpad is the thing that will do this gluing together. He also talked about Ubuntu as an "experiment" rather than a fork of Debian; something that has potentially different ideas about how to do things but that these ideas may lead to things that should be fed back into Debian. The point was made that even if you consider Ubuntu a fork they've forked 9 times now; it hasn't been a case of forking once and diverging wildly since thast point. I have a few thoughts on all the whole Debian/Ubuntu stuff which I should really try to form into something coherant and post. I think it's important to take Mark's talk in the context of bdale's "Shareholders come first" point. Derivatives round table Didn't stay for most of this. Ubuntu, Debian-EDU (which I hadn't realised was a derivative rather than a team within Debian, but apparently there are various things it was much easier for them just to patch now and try to work towards a generic solution later), someone from Extramadura and someone from the Munich government Linux stuff. I'm sure I've missed someone off. tdebs/i18n This was a useful BOF. It helped that we said no to the usual video team requirement that if you want to speak you had to wait for the microphone. This works fine for a normal talk, but really impedes the flow of conversation in something like a BOF. tdebs are something that have partly come from a need of Emdebian to reduce installed package size and partly from the desire of the i18n team to be able to update package translations without having to do a full binary NMU of a package. We had some of the FTP team, the release team, the i18n team and Emdebian there and I think some progress has been made. There'd been various conversations had before this meeting which I think helped people think about the issues and objections so that we had answers by the time we all sat down together - an excellent example of the use of DebConf. DebConf9 C ceres Various bits of discussion about next year's DebConf in Extramadura. Temperature is likely to be an issue for me as they reckon it could easily get up to 40C! I'll melt! Venue sounds good; some queries regarding late night hacklabs and net connections to same, but I'm sure the networking team will sort it all out as usual. ;) DebConf10 bids Venezela and New York were both pitching. Lots of people don't want to travel to the US or think they'll have problems doing so (I hadn't realised there was such an issue for people from South America). I suspect various people will have issues with Venezela as well; I heard expressions of doubt over their political stability expressed. However I'd be happy to go to either (and preferably both! DebConf10 + 12 perhaps?) Speaking of which, what ever happened to the Sarajevo bid? If they're reading, have you considered DebConf11? Wednesday
A day trip to an Argentinian ranch and lunch was an asido. Fantastic food and a pleasant afternoon spent sitting in the sun chatting to people. That evening was the formal, but thanks to having stayed up until after 4 on Tuesday I had to wimp out and go to bed fairly early. Not until I'd seen the DPL dance though. :) Thursday
Internationalization in Debian I forget most of this other than pretty graphs from Christian regarding what's translated and what other languages we might have; e.g. you can consider South America to be covered largely by Spanish and Portuguese, or you can consider it to not be covered very much at all by the local indigenous languages. dh-make-webapp: yeah right! Mainly what I took away from this was "It'll never happen thanks to the fact that every web app author uses a different system" and that more work needs to be done on the web apps best practices document. I don't really do web apps, but having them easily installable on my systems is a good thing so I hope some standardisation within Debian comes from this. Best practises in team-maintaining packages Various team members got up to talk about work flow in their teams. Not unsurprisingly different things seem to work for different people. Predictable PRNG in the Vulnerable Debian OpenSSL Package Lucian giving his Black Hat talk about the OpenSSL issues we faced earlier this year. Some queries about automated testing and that it should have found this, which originally I agreed with until I thought about it - you'd have to have run > 65536 tests and compared all the data to find this; something like the FIPS tests against a single run wouldn't have shown any issues. Lucian wanted feedback on ensuring he was presenting the Debian side of things acceptably as well. Keysigning Run by Don Armstrong. Nothing to really remark except I think key signing attendance is dropping off after things like the Helsinki experience. Also I've now managed to get my new RSA key signed by keys other than my own (and I'll try to get sorted out to sign keys myself soon). Friday
LessWatts Intel's drive towards reducing power usage. Odd to hear such things from someone who wasn't Matthew Garrett and I think I'd heard most of it before. Debian technical policy update Sorry Manoj, I should have been paying more attention. Debian Policy is something I think is important, but I'm not enough of a nitpicker to really feel I can contribute a whole lot. Virtualisation in Debian - Present and future This was depressing. What I took away was "We had 2 forms of virtualisation in etch (Xen + vserver) and we're supporting neither for Lenny". As someone running a Xen machine this is problematic. The host does have the hardware support that would allow kvm, but I'm worried about smooth migration (it's a colo box). There was some mention of Xenner, which isn't packaged for Debian. I took a look at doing so but there are some worrying items in the TODO list (like, oh, locking to enable reliable SMP) and I've spectacularly failed to get it compiling so far. I should have another go. Emdebian update Neil Williams about where Emdebian is and waved his Balloon3 about. Some interest from the Openmoko guys and discussion about why it might be better than OpenEmbedded. And equally what it couldn't do that OpenEmbedded can manage (mainly very small installs; a minimal Emdebian install is 24MB+ and with X that goes up to 75MB+ I believe). netconf I'd never actually seen Martin talk about netconf before. Am impressive flow of control diagram. It all sounds quite complex for little benefit at present, but if he pulls it off then I can see it being a much more flexible replacement for the likes of Network Manager. Saturday
Lenny - The Road To Release Neil played with putting the heads of the release team on random images. And tried to tell us all how to behave during the release process in terms of what should and shouldn't be uploaded etc. Most of it is just common sense, but apparently everything he talked about he'd experienced. Also pointed out we were supposed to release in 3 weeks and didn't even have the appropriate kernel in testing yet so it's probably not going to happen. Colour me surprised. Sustainable Computing Low power consumption/affordable computing. Interesting points about the OLPC being used in the middle of nowhere with no chance of an Internet connection being close by compared to neighbours in large cities where people can't necessarily afford top of the line computers or individual connections - in this sort of scenario mesh networking is really viable in terms of getting people connected up. Multi winner voting Manoj needs pretty diagrams, probably drawn by Martin Krafft. ;) Semi-interesting discussion about multi-winner voting (e.g. SPI board elections) and how the current Debian voting system is completely tied to Debian's infrastructure eg the LDAP setup. Manoj would like to make it more generic so it could be used by other groups as well as for different sorts of votes in Debian.

23 August 2008

Daniel Burrows: Package Management Sudoku 2

I got several emails in reply to my previous post on representing Sudoku problems as package dependencies. Several people asked about the algorithm that aptitude uses to solve these problems. A slightly out-of-date discussion package management and the aptitude algorithm can be found at http://people.debian.org/~dburrows/model.pdf. One question was interesting enough to deserve a follow-up blog post: Wolf T. referred to the page http://norvig.com/sudoku.html and asked how long it would take aptitude aptitude to solve the hard Sudoku problems on that page. He suspected that aptitude would do basic constraint propagation and then be forced to exhaustively search all the possible solutions to the problem. In brief: the answer is that it doesn't work by default, but not for the reason he suggested, and you can make it work with a few command-line arguments. In order to try this out you'll need a new version of the Sudoku reducer that can parse the problems on that Web page: debsudoku2.py. If I do a straight conversion of one of those problems and then run it through aptitude, it goes spinning off and never comes back. But aptitude is coded to avoid exhaustive searches; otherwise it couldn't solve dependency problems in reasonable amounts of time. In this particular situation, though, aptitude is clearly performing an exhaustive search; here's one series of status outputs:
open: 5124; closed: 4993; defer: 0; conflict: 374
Resolving dependencies...
open: 10090; closed: 9942; defer: 0; conflict: 398
Resolving dependencies...
open: 14726; closed: 14888; defer: 0; conflict: 440
Resolving dependencies...
Here open is the number of partial solutions that aptitude wants to examine, and closed is the number that it's already examined. aptitude isn't making progress here and it isn't finding solutions; in fact, it's creating, on average, about two new partial solutions for every one it examines. Why is aptitude doing this? Its resolver isn't a brute-force algorithm; in fact, it looks remarkably like the Sudoku solver discussed at http://norvig.com/sudoku.html. On each step, aptitude takes a partial solution, picks one dependency, and resolves it by installing or removing a package. This is pretty much equivalent to filling in one not-filled-in cell; in fact, in the conflicts Sudoku reduction, it's exactly equivalent. There is one difference, though, and it stems from a difference in the problem domains of Sudoku and package management:
Not all dependency resolutions are created equal.
In Sudoku, any solution to the puzzle will do. Not so in package management; solving a dependency problem by removing every package on the system will produce a formally correct answer and a very unhappy user. Even results that are not utterly disastrous could be annoying to the user, so the resolver needs to somehow aim for good answers. The page on Sudoku solvers suggests sticking to whatever value you placed in a cell, unless that doesn't lead to any solutions at all. This is technically known as a depth-first search. The problem with taking this approach when resolving package dependencies is that an apparently safe choice can end up requiring undesirable actions later on (like removing large swathes of the system). For this reason, aptitude tries to strike a balance between sticking to its current line of reasoning, and abandoning it when it seems to be turning out badly (this makes it a form of best-first search). On typical Debian archives, the package relationships are simple enough that it's OK if aptitude does this from time to time; it makes the search a little more thorough (thus costly), but the ability to back out of questionable branches is very valuable. But it looks like when aptitude is applied to Sudoku puzzles, it has trouble settling on a single series of choices. It keeps thinking that the solutions are getting worse, so it backs up and tries another branch, but they don't look any better over there, so it backs up and tries another branch, and so on. The option Aptitude::ProblemResolver::StepScore sets how hard aptitude will try to stick to the same line of reasoning. Its default value is 70, which is reasonable for package archives, but turning it up to a large value such as 10000 will cause aptitude to use a straight depth-first search, just like the Sudoku page recommends:
$ aptitude -s -o 'aptitude::problemresolver::stepscore=10000' -o 'aptitude::auto-install=false' install puzzle
Setting auto-install to false is a workaround for another odd corner case/bug that happens to bite this Sudoku problem: for technical reasons, doing this lets aptitude know that it should avoid solutions that cancel the installation of puzzle. Otherwise you have to sit there telling it no for a bunch of solutions you aren't interested in. Future versions of aptitude will probably provide a way to explicitly give hints to the resolver. With these options, aptitude was able to solve the hard Sudoku puzzles that I gave it in anywhere from fifteen seconds to a minute and 47 seconds. In contrast, the straight Sudoku solver does 30 problems in a second. Why is aptitude so slow? Based on skimming debug traces and looking at the run-time behavior, I conjecture that there are several reasons:
  1. The aptitude search algorithm is very heavyweight. In the case where it takes over a minute, it only actually examines about 5,000 possible solutions. I don't know exactly where all this time is going, but I do know that the resolver does a lot of work on each step, for instance to try and detect dead ends that it hasn't reached yet. This is the conflicts counter that appears while the resolver is running. This pays off tremendously in terms of allowing aptitude to skip huge amounts of work (it may be why aptitude can solve Sudoku puzzles at all!), but it means that the resolver takes a long time for each potential solution it looks at.
  2. The Sudoku page suggests taking the cell with the fewest number of possible entries as the choice. I distinctly remember writing code to do this in aptitude, but it looks like I threw it out at some point or never committed it. I don't see why it should be any worse than the current approach, though (which is to pick an arbitrary dependency); maybe it just got misplaced at some point. Implementing this behavior decreased the time required to solve one puzzle from a minute and 45 seconds to just under a minute; I've committed this change to the post-lenny branch.
  3. The Sudoku resolver has the advantage of being able to very quickly identify illegal moves. aptitude's resolver can learn this information, but it takes time and it can't apply Sudoku-specific optimizations. For instance, the Sudoku solver knows exactly which values can be placed in a given cell at any time. aptitude has to actually consider each of the cells that's available as a possibility and prove to itself that, e.g., 4 and 6 can't be written in the same cell at the same time. And although it can learn this information, it takes time to do so and it takes time to see whether any of the past conflicts that it remembers are present in a given solution.
As I noted above, I've already checked in one change to the resolver's behavior. It might also be worth seeing what happens with a massive increase in StepScore, so I've pegged it at 10000 on my computer to see whether the results I get are noticeably worse. The third item above -- the fact that aptitude needs to do more work to understand which packages can't be installed -- is interesting. The Sudoku solver is very proactive about this: it keeps track at all times of which cell values are legal, and updates these sets every time it transitions. In contrast, aptitude constantly re-checks all the possible moves it could make to see which ones are currently legal. I think that the resolver's speed could be boosted a little by doing the following:
  1. Cache the currently legal solutions of each dependency at the time it's inserted into the queue.
  2. When a new search node is generated by resolving a dependency, drop the formerly legal moves that are knocked out (for instance, by installing a different version of the same package).
  3. Come up with a quick way of re-testing new conflicts (the global list of dead-ends) so that search nodes that are already in the queue can be checked against the conflicts that were added since they were queued.
These changes won't make aptitude able to solve problems that it couldn't solve before, or at least not very many of them, but they should make the resolver faster on every problem it encounters. However, I don't think I want to actually implement them. It would be tricky to confirm that the resolver got faster on real dependency problems (since it's normally almost instantaneous), the changes would make the resolver code more complex and fragile (less readable, less maintainable), and there's a real chance of breaking something. Unless there are cases where the resolver is currently too slow on real package archives that don't involve an exponential blowup, I'm going to shelve the idea for now.

21 August 2008

Russell Coker: Switches and Cables

I’ve just read an amusing series of blog posts about bad wiring [1]. I’ve seen my share of wiring horror in the past. There are some easy ways of minimising wiring problems which seem to never get implemented. The first thing to do is to have switches near computers. Having 48 port switches in a server room and wires going across the building causes mess and is difficult to manage. A desktop machine doesn’t need a dedicated Gig-E (or even 100baseT) connection to the network backbone. Cheap desktop switches installed on desks allow one cable to go to each group of desks (or two cables if you have separate networks for VOIP and data). If you have a large office area then a fast switch in the corner of the room connecting to desktop switches on the desks is a good way to reduce the cabling requirements. The only potential down-side is that some switches are noisy, the switches with big fans can be easily eliminated by a casual examination, but the ones that make whistling sounds from the PSU need to be tested first. The staff at your local electronics store should be very happy to open one item for inspection and plug it in if you are about to purchase a moderate number (they will usually do so even if you are buying a single item). A common objection to this is the perceived lack of reliability of desktop switches. One mitigating factor is that if a spare switch is available the people who work in the area can replace a broken switch. Another is that my observation is that misconfiguration on big expensive switches causes significantly more down-time than hardware failures on cheap switches ever could. A cheap switch that needs to be power-cycled once a month will cause little interruption to work, while a big expensive switch (which can only be configured by the “network experts” - not regular sysadmins such as me) can easily cause an hour of down-time for most of an office during peak hours. Finally the reliability of the cables themselves is also an issue, having two cables running to the local switch in every office can allow an easy replacement to fix a problem - it can be done without involving the IT department (who just make sure that both cables are connected to the switch in the server room). If there is exactly one cable running to each PC from the server room and one of the cables fails then someone’s PC will be offline for a while. In server rooms the typical size of a rack is 42RU (42 Rack Units). If using 1RU servers that means 42 Ethernet cables. A single switch can handle 48 Ethernet ports in a 1RU mount (for the more dense switches), others have 24 ports or less. So a single rack can handle 41 small servers and a switch with 48 ports (two ports to go to the upstream switch and five spare ports). If using 2RU servers a single rack could handle 20 servers and a 24port switch that has two connections to the upstream switch and two spare ports. Also it’s generally desirable to have at least two Ethernet connections to each server (public addresses and private addresses for connecting to databases and management). For 1RU servers you could have two 48 port switches and 40 servers in a rack. For 2RU servers you could have 20 servers and either two 24port switches or one 48port switch that supports VLANs (I prefer two switches - it’s more difficult to mess things up when there are two switches, if one switch fails you can login via the other switch to probe it, and it’s also cheaper). If the majority of Ethernet cables are terminated in the same rack it’s much harder for things to get messed up. Also it’s very important to leave some spare switch ports available as it’s a common occurrence for people to bring laptops into a server room to diagnose problems and you really don’t want them to unplug server A to diagnose a problem with server B… Switches should go in the middle of the rack. While it may look nicer to have the switch at the top or the bottom, that means that the server which is above or below it will have the cables for all the other switches going past it. Ideally the cables would go in neat cable runs at the side of the rack but in my experience they usually end up just dangling in front. If the patch cables are reasonably short and they only dangle across half the servers things won’t get too ugly (this is harm minimisation in server room design). The low end of network requirements is usually the home office. My approach to network design for my home office is quite different, I have no switches! I bought a bunch of dual-port Ethernet cards and now every machine that I own has at least two Ethernet ports (and some have as many as four). My main router and gateway has four ports which allows connections from all parts of my house. Then every desktop machine has at least two ports so that I can connect a laptop in any part of the house. This avoids the energy use of switches (I previously used a 24 port switch that drew 45W [2]), switches of course also make some noise and are an extra point of failure. While switches are more reliable than PCs, as I have to fix any PC that breaks anyway my overall network reliability is increased by not using switches. For connecting the machines in my home I mostly use bridging (only the Internet gateway acts as a router), I have STP enabled on all machines that have any risk of having their ports cross connected but disable it on some desktop machines with two ports (so that I can plug my EeePC in and quickly start work for small tasks).

Ingo Juergensmann: Adding a RAID under a LVM

Just as a personal reminder for the next time I need that:

If there's a machine, for example a Xen host, with just one harddisk and you want to be somewhat safe in case of a disk failure, you can add a second disk and setup a RAID1 (mirroring). It's most simple to shutdown the machine and setup the RAID1 for the dom0. Afterwards you can start the domU VMs again when you're using LVM for their virtual disks. Following these steps will add RAID1 underneath your LVM setup:

0. /dev/sda5 is your current physical volume for your LVM, on the second (equally partitioned) disk /dev/sdb5 will be your starting point for your RAID1 (/dev/md3)
1. create a degraded RAID1 on /dev/sdb5:
# mdadm --create /dev/md3 --level=1 -f --raid-devices=1 /dev/sdb5
mdadm: array /dev/md3 started.
# cat /proc/mdstat
md3 : active raid1 sdb5[0]
135540288 blocks [1/1] [U]

2. prepare it for LVM and add it to your virtual group:
# pvcreate /dev/md3
# vgextend /dev/vg /dev/md3
Volume group "vg" successfully extended

3. move the extends from one disk to the other and be verbose to watch the progress:
# pvmove -v /dev/sda5
Finding volume group "vg"
Archiving volume group "vg" metadata (seqno 22).
Creating logical volume pvmove0
Moving 192 extents of logical volume vg/ts2-swap
Moving 1536 extents of logical volume vg/ts2-disk
[....]
Found volume group "vg"
Removing temporary pvmove LV
Writing out final volume group after pvmove
Creating volume group backup "/etc/lvm/backup/vg" (seqno 31)

4. remove the old partition from the virtual group:
# vgreduce /dev/vg /dev/sda5
Removed "/dev/sda5" from volume group "vg"

5. add the old partition to your raid and set it active:
# mdadm --add /dev/md3 /dev/sda5
mdadm: added /dev/sda5
# cat /proc/mdstat
md3 : active raid1 sda5[1](S) sdb5[0]
135540288 blocks [1/1] [U]
# mdadm --grow /dev/md3 --raid-devices=2
# cat /proc/mdstat
md3 : active raid1 sda5[2] sdb5[0]
135540288 blocks [2/1] [U_]
[>....................] recovery = 0.2% (284480/135540288) finish=39.6min speed=56896K/sec

6. let the RAID1 doing its sync and you're done.

Just as a small side note:
I don't know why the kernel don't want to boot when it get passed root=/dev/md2 as a kernel parameter. It works with root=/dev/sda3, though...

Frank Lichtenheld: Source Views

(This is a more detailled and hopefully better structured explanation of the topic of my Lightning Talk during Debconf) With the ever growing number of packages in our archive we need ever better methods to structure, sort, and search this collection. While projects like debtags try to improve the search in packages, my idea is about improving the way the results are displayed. There is one relation between packages that is currently never strongly featured when presenting package meta-data: the source ↔ binary relation. Usually package managers operate either on binary packages or source packages, but seldomly do they expose the fact that one is generated from the other. In the trivial case of one source package producing one binary package there is probably nothing to gain. But there are a large number of source packages where this isn't true (at the moment about 29% of all the source packages in main build more than one binary package, together producing about 61% of all binary packages). I have the idea (which so far is nothing more) that if we could present packages through their source packages that this could drastically reduce the number of packages to choose from and make some common search actions more effective. This is not by any meaning a trivial task, though, since on the other hand not all source packages necessarily produce binary packages that have much to do with each other, and even for the ones that do, the exact relationship between the binary packages can vary greatly. Also some source packages are really belonging together but are split to make maintenance easier (e.g. KDE and X.org). These splits might not necessarily make any sense to an user. Some ideas what to implement in terms of code to make it easier to let the user benefit from the fact that multiple binaries have the same source:

Add support for a Description field for source packages.
For bonus points implement automatic substvars $ source:Description , $ source:Short-Description , and $ source:Long-Description that make it trivial to reuse (parts of) that description in the descriptions of the binary packages.
Add some way to identify the "main" package built from a common source.
Identify source package usage patterns.
There are a lot of source packages that share common patterns about what they build. Example patterns include:
Application
Main package + -data package + -doc package + ...
Library
-dev package + shlib package + -doc package + ...
Application + Library
Collection of Applications
etc.
I guess many of us already look out for these patterns when searching for packages but identifying them explicetly might make this easier and allow more users to benefit from this information.

Frank Lichtenheld: RC bugs in etch (Starting Stable QA, Part 1)

As everyone can see in the graph of release critical bugs, the number of RC bugs in etch had constantly risen since the release (which was already noted in some other blogs) up until last week. Since I suspected that this number included a lot of false positives, I began to triage this list last week during Debconf. I started with identifying all bugs that were filed against the version in etch, but really only meant the package in testing/unstable (but can't be interpreted correctly with version tracking alone since the version in stable, testing, and unstable is actually identical). There are a lot of reasons why an RC bug might be valid for testing/unstable, but not for stable, even though they share the same package:
Library transitions.
While most cases of library transitions can be handled with targeted binNMUs these days, there remain a few cases where a sourceful upload is needed, e.g. for renamed -dev packages and necessary source changes to adapt to new APIs.
Build-Problems caused by toolchain changes.
Newer gcc versions are often more strict about what constructs they allow. This can cause build problems in a lot of packages once the default version used is increased. Other packages that regulary cause new build problems are linux-libc-dev and dpkg-dev. Since we only require that a package is buildable in the release it is contained in, these are not valid RC bugs for stable.
Changes in the RC policy of the release team.
One example during the lenny release cycle was the use of invoke-rc.d in maintainer scripts to (re-)start daemons. Bugs were filed against a lot of packages not using invoke-rc.d before the etch release but they were only declared to be of RC severity after etch.
etc.
So as the first part of my triaging efforts I tried to identify these cases. I also looked for bugs that were listed as affecting etch due to incomplete version information (i.e. if there is no version given, the bug is assumed to affect all versions). As you can see from the bump in the graph I was able to identify about 200 bugs that met one of these conditions. We should avoid in the future to let the number of false positives grow to such large numbers. Everyone can help with that:
Maintainers
If you get bugs reported without a version number and you can verify that this bug was not present in an older version of the package, add correct "found" information. If you get a bug reported against a version that is both in stable and in testing/unstable, but not valid for stable, tag the bug appropriatly. I would recommend to err on the side of false positives though instead of on the side of false negatives!
Mass-bug filers
Most mass-bug filing that involve RC bugs should use tags to avoid creating false positives.
QA Group
Bugs filed about the proposed orphaning or removal of packages should usually be tagged, since only in very few cases these actually warrant any changes in stable.
At this point you probably ask yourself: What are the appropriate tags? This is much less clear than one might hope, since the involved tags (<suite>) changed/lost their meaning somewhat with the introduction of version tracking. Following my question about the appropriate tags on debian-release the release team and Don Armstrong for the debbugs maintainers seem to have agreed on their new meaning: A bug with suite tags affects the intersection of the set of suites indicated by its version information and the set of suites indicated by its suite tags. Next post: What about the other 600 RC bugs in stable?

Josselin Mouette: Don t worry, your data is safe

Computer security is generally defined as the following:
  1. The data should remain available to those who need it.
  2. The data should not be available to those who don t have the right to.
The critical software component to the first item is your well-known nightmare: the backup software. Backups are easy! In many corporate environments, here is how you ensure you have backups: Isn t that cool? So little work to have all your data completely safe! Wait if you look more closely, there is something wrong here. Nowhere in this process did you specify credentials to the backup guy, nor did you add anything to identify the backup server. Or to say it otherwise, once you have installed the backup agent, the backup server has full access to your data. But you didn t even specify anywhere the IP of the backup server. So this means that anyone on the network has full access to your data. Which, while trying to make your data secure, actually brings a gaping security issue on your system. Security by nullity When you install a well-designed backup agent, like Bacula, you have to specify a password for each client and make this password known to the backup server. A simple authentication protocol ensures that only the backup server is able to backup your data. However, when you install, for example, the HP Data protector agent, it starts listening on a TCP socket and (no kidding!) binds it to a restricted shell which has access to a small list of commands. The backup server only needs to connect to this TCP socket and issue commands. While this has the great advantage of simplifying the development process of the backup server, such a software has a name: a rootkit. Several other proprietary backup software have different implementations, like RPC-based or proprietary protocols, but the basis remains the same: you connect to the TCP port, and you have a way to read absolutely any file on the system. Of course, there are so-called security options, that you can buy besides the disk agent or the nifty web interface. Yes, when you buy software that is critical for your security, the very lowest level of security that you d expect from any software not turning your box into a self-service is a paying option. In the end, what prevents your data from being available to anyone on the intarweb is the ultimate solution to everything(tm): the firewall. As people are not stupid enough to use the same backup system in the DMZ, you can t simply bounce from it after having used a hole in the lousy PHP code that is never updated. (Well, that will still work in many cases since people actually are stupid enough.) No, what makes it very fun is the backup network. The hackup network A tape library is expensive hardware, therefore you only want to buy one. However, when you have several departments or, in outsourced environments, several clients, you can t simply access to the backup agents on all these servers, because of all these evil routers and firewalls that are blocking you. The solution is trivial: use the second network card on all servers to connect to a backup network. The backup network is entirely managed by backup people who have no idea of network security, and is routed all the way down to the backup server. If you are lucky, some ACLs set up by the network guy who plugged the switch will prevent some parts of the network to access some others. In all cases, it s very likely that many people in the company (or from other companies!) have full IP access to all your private servers where sensitive data is stored. That includes access to your databases setup without a password, and of course to your highly secure backup agent. That generally also includes full IP access to the lousy maintained backup server, on which security updates are never installed. But don t worry. Your data is safe. Note: no, this is not a worst-case scenario. Such badly-designed software is widespread. Such practice is widespread in several companies I know.

20 August 2008

Adam Rosi-Kessel: Walter Michalik and the Roslindale Community Center

I’ve had little time in the four years I’ve lived in Roslindale to get involved in community volunteer efforts. My wife Rachele, however, has devoted several years to efforts such as the Roslindale Community Center, Roslindale Village Main Streets, and Roslindale Clean and Green. She has served as chair of both RCC and one of the RVMS committees. Over the past few months, I’ve been disappointed to see the RCC board endure repeated senseless attacks by a perhaps overzealous community member, Walter Michalik, who has effectively paralyzed the organization. I have nothing personal against this guy, but I thought I could do my part here by publishing an example of an email he broadcast to the committee, which I think is embarrassing enough on its own merits to need no editorializing from me, except to say any email that starts with “just so you won’t be surprised when the IRS launches its investigation” can be neither productive nor taken seriously. The context is a response to an announcement sent out pursuant to the Community Centers By-Laws scheduling a special meeting to discuss the recent upheaval on the Council. There’s no reason this should not be in the public record:
Rachele Just so you won’t be surprised when the IRS launches its investigation, be advised that YOU DO NOT HAVE THE AUTHORITY TO CALL FOR A SPECIAL MEETING. The By Laws do not allow the President/Chair to call for a Special meeting - that right is reserved for the MEMBERS to have a power over a hostile or non-performing President/Chair. It was created by a Membership wary of annimosity within its ranks in order to protect itself from falling into a useless dysfunctional body. That’s why our By Laws require the majority of the membership request it through the Chair and not the other way around. So you screwed that up too. Your continuous violation of rules and laws have proven beyond a doubt that this current Roslindale Community Center Council has violated the trust behind its IRS-designated not-for-profit status. The failures are on so many significant levels over 6 months it is readily apparent that the Roslindale Community is better served without a Community Center Council. There is no longer any excuse to allow the residents of Roslindale to be denied the services they deserve that you and the officers have no idea how to deliver. Because that’s what you are supposed to do - serve the residents of Roslindale and not preseide over a self-serving board. You’ve taken us from dysfunctional to non-functional over the past 60 days. You and your officers have already driven away our Archdale partners and now the merger is off. Congratulations. You got what you wanted. You and the officers have withheld information from the Members of the Council imposing gag orders along the way and in more than one instance spreading lies within this community. There are so very many lapses on your part and the rest of the officers that it is very apparent that the Roslindale Community Center exists IN SPITE OF the Roslindale Community Center Council - not because of it. It would be far better indeed, if the Center were run without the Council. What have you done in 6 months? All you do is avoid the work of leadership. Please, just gracefully step aside and let a real leader emerge - or dissolve the Council and let the Center run itself under BCYF before the IRS makes that happen. Of course this is my stated opinion. You can choose not to belive it. You can huddle with a group of self-serving officers and invent excuses or change the agenda away from the message and continue with your ad hominem attacks against the messenger. I’m thick-skinned. Feelings aren’t important to me - services to residents are important to me. While I have, in fact, enjoyed the confidences of others within this community and their true displesure with this Council, I will produce that to the appropriate authorities as I see fit along with the Bill of Particulars I have produced with documentation for all charges. As a founder of the Roslindale Community Center Council I can no longer support you or the officers as any legitimate authority in this community.
Technorati Tags: , ,

John Goerzen: From Dell, a Uniquely Terrible Experience

Ah, Dell. Seeming inventors of the tech support pit of bureaucratic indifferences, inventors of the flamingo pink Inspiron, perpetrators of fraud in New York...

I have, for over a year now, been on a crusade trying to get them to stop sending me their Dell Home and Home Office catalog to my mailbox. It has been a bundle of fun, let me tell you.

They have a nice-sounding privacy policy. It says you can opt out of all their mailings by filling out a form online. Yeah, good luck with that. First of all, there are different forms for different departments at Dell. I've filled out them all, multiple times. They do nothing whatsoever. Perhaps they use them as lists of known-good addresses to send new advertisements to, rather than lists of people to remove. Oh well.

Now, unfortunately I feel compelled to bore you with the saga so far, involving telephone hang-ups, broken privacy policies, and the like. But there is a silver lining at the end, in which I submitted a request to the postal service asking them to block Dell from sending me any more mail, and it appears that they are very likely to violate Federal Law any day now.

I have called them about it. Dealt with the old "let me transfer you to the correct department" then hang up on me ploy. Spoken to people that have promised up and down that I'll be off their list in 30-60 days. It's always 30-60 days, isn't it? Very convenient that I can't tell for 2 months whether or not they've processed my request.

I've tried their online chat. One of my attempts went like this:

Session Started with Agent (Sneha Ranga)

Agent (Sneha Ranga): "Due to circumstances that have affected Dell Communications I am temporarily unable to pull up any information. The down time is temporary. We apologize for the inconvenience, as we value your time as a customer. Please contact us back after an hour."

Session Ended


Ah Dell, only you could reach such a pinnacle of customer service. /kicking someone out of a chat room before they have a chance to say a word.

Finally, last fall, I blogged about the situation (that's the link above). Debbie from Dell red the post and emailed me. Great, I thought. She asked for my address information and catalog information and sent me a removal confirmation:


From: Debbie@Dell.com
Date: Thu, 18 Oct 2007 13:08:18 -0500
To: jgoerzen@complete.org
Subject: RE: Dell mailing list

Thank you, Mr. Goerzen, your request to have the below address
information removed from our marketing lists has been received:

[ my address here ]

We will process your request promptly. However, it may take several
weeks for some changes to take effect. If you are still receiving
catalogs after thirty (30) days feel free to email me. Sorry for any
inconvenience you may have experienced.

Thank you,
Debbie


So that was October. In December, I replied to that message, saying: "I received another mailing today, and it's been nearly 2 months since your initial message. If there's anything further you can do, I'd appreciate it." Debbie said, "I am very sorry Mr. Goerzen, I will resubmit your request." Guess how successful that was.

So in February, I manage to figure out a way to send in a support ticket without having a Dell system serial number. I wrote:

I keep getting your Dell Home and Home Office catalog. I have tried for months to get off your mailing list. I have called in, talked to people in multiple departments, who have promised to remove me from the list. I have contacted you online. NOTHING IS HELPING. This has gone on for MONTHS.

PLEASE NEVER SEND ME MAIL AGAIN, EVER, AND DO NOT RENT OR SHARE MY NAME.

My address is above.

The code on the mailing I received is: [ snipped ]


The form letter I got back said:

If you are currently receiving our catalog or mailings and would like to be removed, please visit the following web page and select the appropriate link under the "Opt-out of direct mail, phone or fax communications" heading: http://www.dell.com/OptOut


I replied, saying that form didn't work. Guess what I got back?

Thank you for signing up for Dell Email Subscriptions. Please save this email for your records.


Yes, that's right. Asking them to take me off their postal mailing lists got them to PUT ME ON their email lists. ARGH.

So they eventually manage to correctly take me off the email list, and of course promise to do the same with the postal list. This back in February.

I contacted them again in March and July, only to have a similar stupidity-laced run-in with clueless form-answer-laden Dell support reps. Each one claimed to have now, finally, and permanently removed me from the list. It never happened, and none of them lifted a finger to find out way, and no amount of begging could make them.

So, here's the good part.

Junkbusters has spent years educating people on how to get rid of unwanted mail, and documents getting a prohibitory order against the sender. It was originally designed for people that didn't want to receive obscene advertising mailings, but thanks to the happy fact that one non-adult-mailer challenged a prohibitory order all the way to the Supreme Court, you can now get prohibitory order against anyone. Yes, even Dell. (The supreme court's ruling even gave an example: you can prohibit a clothing catalog if you want.)

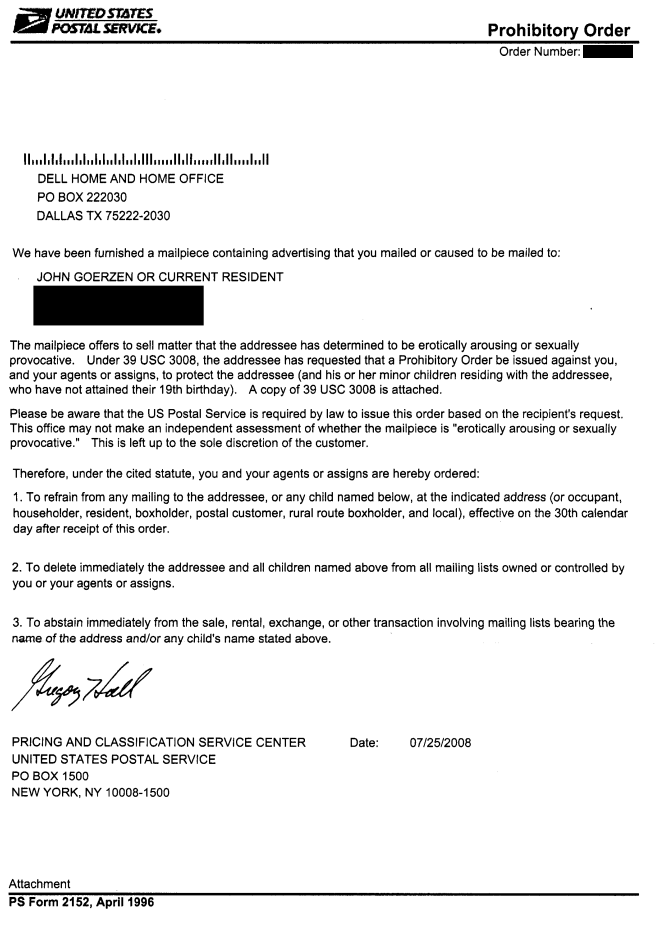
And last month, that's exactly what I did. The USPS sent me back a copy of the letter they sent to Dell, as well as a second page with instructions on reporting violations. Here's the letter they sent to Dell:

dell-usps

Somehow I get a chuckle over some Dell mail clerk trying to figure out how an 11-pound laptop is sexually provocative.

From August 25 on, it is a federal offense for Dell to send me another Home and Home Office catalog. This is a branch of criminal law, not civil law. That is, it's the maybe-go-to-jail branch of law.

How disappointed I was to receive yet another catalog from them today. If only they had waited 5 more days, I could have turned them in now.

Oh well. There's always next month's catalog. Let's just hope the clerk that received the USPS letter removed my name with a better system than everyone else at Dell uses, eh?

19 August 2008

Roland Mas: Netfilter-based port-knocking

When you have a server on the Internet, you get lots of "brute force" attacks on the SSH daemon, trying plausible logins with a variety of passwords. Even with good passwords, these attacks might eventually succeed (and they're annoying even when they don't), so you want to thwart them. One way is to use fail2ban, a script that monitors the failed connections, and sets up firewall rules (for instance) blocking further connections from the attacking IP addresses. It's good, but it fills your logs with messages about IPs getting banned and unbanned after a while. And you're still at risk that the multiple connections crash the SSH daemon, or trigger a bug in it, or whatever. A second layer of protection can be to block all SSH connection attempts except when they come from known IP addresses, but that doesn't work when you're away from home, and you're locked out. Been there, done that. So, some wise people have devised a trick called "port-knocking". It's similar to only opening the door to people who use a special knock (think "That's all, folks"): the firewall stays closed, but it opens a tiny targeted hole to some IP addresses for a limited length of time, based on a secret handshake. The window for attack is therefore very small, and the SSH daemon stays idle most of the time. And you can still log on your hosted server when you're attending conferences. There are a variety of implementations for this concept. Some could be web-based (you need to submit the right password to a web page), some could use other services or a dedicated daemon. But when I started investigating port-knocking, I wanted something simple, preferably with no dependencies on a daemon that would need to be exposed to the net and potentially crash. I found an article on the Debian Administration website, but I wasn't entirely satisfied with it. The principles appealed to me (netfilter-only, secret handshake in the form of opening connections to secret ports), though, so I evolved it into my own implementation, which I proudly present to you today. The goals of this implementation were: The bulk of the work therefore stays in the kernel's netfilter (that's for robustness and no user-land dependency), but the control interface is integrated with the usual firewalling script. Resistance to replay attacks is achieved by choosing hard-to-predict ports. So if someone snoops the wireless while I'm at a conference and catches my secret handshake, it'll only be valid for a short period of time, hopefully short enough to prevent dictionary attacks. The handshake is therefore calculated as a function of the current date and time, with an added secret seed. The following shell function calculates 5 port numbers within a given range (requires dc to be installed, for big-integer arithmetic):
calc_knock_ports ()  
    secret=$1
    bottomport=$2
    topport=$3
    nbports=$(( $topport - $bottomport + 1 ))
    hash=$(TZ=UTC date +%Y-%m-%d-%H-$secret   md5sum   awk ' print $1 '   tr a-z A-Z)
    num=$(echo 16i $hash f   dc)
    pk_port1=$(echo $num $nbports 0 ^ / $nbports % $bottomport + f   dc)
    pk_port2=$(echo $num $nbports 1 ^ / $nbports % $bottomport + f   dc)
    pk_port3=$(echo $num $nbports 2 ^ / $nbports % $bottomport + f   dc)
    pk_port4=$(echo $num $nbports 3 ^ / $nbports % $bottomport + f   dc)
    pk_port5=$(echo $num $nbports 4 ^ / $nbports % $bottomport + f   dc)
 
Okay. So this function calculates ports, now what? Now we're going to define a few chains by which netfilter will store states of IP addresses as they progress through the handshake:
setup_portknocking_tables ()  
    iptables -N portknock_into_phase1
    iptables -A portknock_into_phase1 -m recent --name PK_PHASE1 --set
    # iptables -A portknock_into_phase1 -j LOG --log-level notice --log-prefix "INTO PK_PHASE1: "
    iptables -N portknock_into_phase2
    iptables -A portknock_into_phase2 -m recent --name PK_PHASE1 --remove
    iptables -A portknock_into_phase2 -m recent --name PK_PHASE2 --set
    # iptables -A portknock_into_phase2 -j LOG --log-level notice --log-prefix "INTO PK_PHASE2: "
    iptables -N portknock_into_phase3
    iptables -A portknock_into_phase3 -m recent --name PK_PHASE2 --remove
    iptables -A portknock_into_phase3 -m recent --name PK_PHASE3 --set
    # iptables -A portknock_into_phase3 -j LOG --log-level notice --log-prefix "INTO PK_PHASE3: "                     
    iptables -N portknock_into_phase4
    iptables -A portknock_into_phase4 -m recent --name PK_PHASE3 --remove
    iptables -A portknock_into_phase4 -m recent --name PK_PHASE4 --set
    # iptables -A portknock_into_phase4 -j LOG --log-level notice --log-prefix "INTO PK_PHASE4: "
    iptables -N portknock_into_phase5
    iptables -A portknock_into_phase5 -m recent --name PK_PHASE4 --remove
    iptables -A portknock_into_phase5 -m recent --name PK_PHASE5 --set
    iptables -A portknock_into_phase5 -m recent --name PK_ESTABLISHED --set
    # iptables -A portknock_into_phase5 -j LOG --log-level notice --log-prefix "INTO PK_PHASE5: "
    iptables -N portknock_accept
    iptables -A portknock_accept -m limit -j LOG --log-level notice --log-prefix "ACCEPTED AFTER PORTKNOCKING: "
    # iptables -A portknock_accept -m recent --name PK_PHASE5 --remove
    iptables -A portknock_accept -j ACCEPT
    iptables -N portknocking
 
These chains use the recent module, which seems to be commonly available in standard kernels. You'll notice how, as one packet goes through these rules, its originating IP address moves from one set of "recent" addresses to the next. But no logic exists yet to make the packet actually go through these rules, so here comes the glue:
refresh_portknocking ()  
    calc_knock_ports f00b4r 10000 10999
    iptables -F portknocking
    iptables -A portknocking -p tcp --dport $pk_port1 -m state --state NEW                                                 -j portknock_into_phase1
    iptables -A portknocking -p tcp --dport $pk_port2 -m state --state NEW -m recent --rcheck --name PK_PHASE1 --seconds 5 -j portknock_into_phase2
    iptables -A portknocking -p tcp --dport $pk_port3 -m state --state NEW -m recent --rcheck --name PK_PHASE2 --seconds 5 -j portknock_into_phase3
    iptables -A portknocking -p tcp --dport $pk_port4 -m state --state NEW -m recent --rcheck --name PK_PHASE3 --seconds 5 -j portknock_into_phase4
    iptables -A portknocking -p tcp --dport $pk_port5 -m state --state NEW -m recent --rcheck --name PK_PHASE4 --seconds 5 -j portknock_into_phase5
    # echo clear > /proc/net/ipt_recent/PK_DONE
    echo clear > /proc/net/ipt_recent/PK_PHASE1
    echo clear > /proc/net/ipt_recent/PK_PHASE2
    echo clear > /proc/net/ipt_recent/PK_PHASE3
    echo clear > /proc/net/ipt_recent/PK_PHASE4
    echo clear > /proc/net/ipt_recent/PK_PHASE5
 
Right. This function adds rules to the portknocking chain. A packet injected into this ruleset will, depending on its destination port and whether its source IP address has already been seen, end up in one of the PK_PHASE* sets. All we have to do now is therefore to send some packets to this portknocking chain, and use the port-knocking sets to decide whether to accept incoming connections or not:
iptables -A INPUT -j portknocking
iptables -A INPUT -m recent --rcheck --seconds 5 --name PK_PHASE5 -m state --state NEW -p tcp --dport ssh -j portknock_accept
This example only mentions accepting incoming SSH connections, but it's in no way a limitation: a server of mine uses similar rules to DNAT certain ports to internal IP addresses. And there we have it for the server part: incoming SSH connections are usually ignored (well, handled by the rest of the firewall script, but let's assume that it drops these packets by default), but if one IP address knows the appropriate ports and sends a connection attempt to them in order, then it'll be able to open SSH connections for a little while after that. Of course, it's going to be boring if one has to send these packets by hand, but it can be easily automated by a script. Here's a ~/bin/portknock.sh I have:
#! /bin/sh
host=$1
port=$2
calc_knock_ports ()  
[...]
 
calc_knock_ports f00b4r 10000 10999
for i in $pk_port1 $pk_port2 $pk_port3 $pk_port4 $pk_port5 ; do
    nc -w 1 $host $i < /dev/null > /dev/null 2>&1
done
nc $host $port
It's designed to be called with two parameters, a host and a port, and it needs netcat in addition to dc. Why the last line, I hear you cry? Because then I can just add the following lines to my ~/.ssh/config:
Host blahblah
  IdentityFile foobar
  ProxyCommand /home/roland/bin/portknock.sh %h %p
...and SSH will automagically tunnel its network socket through the script, which will in turn happily tunnel that through netcat after completing the secret handshake. And when I type ssh myserver on my laptop, interesting stuff happens behind the scenes, and a special, just-for-me hole is opened in the server firewall, just for the few seconds I need to establish the SSH session (packets belonging to established TCP sockets are allowed by the firewall's connection tracking). Note: This article is deliberately short on details and ready-to-run scripts. Firstly because firewall scripts vary wildly so any script would have to be adapted anyway, but mostly because security is best handled with one's brain switched on. Fiddling with a firewall can easily open gaping holes or lock everyone out. So please make sure you understand what goes on before blindly pasting stuff into your own setup. Some of the lines that are commented out may also be of interest, and were left as an exercise for the reader. Other lines were not included, and are also left as a rather important exercise to the reader; note in particular how the netfilter rules as currently established do not mitigate the replay attacks...

MJ Ray: Using at to Record DebConf Streams

While I enjoyed watching some of the DebConf 8 Video Team’s Excellent Service, not all of it was at convenient times for me, being several timezones away, so I used the following script to record some of the streams:-
#!/bin/sh
# Example: recordstream 09:00 09:55 -Otalk.ogv http://server:8000/stream
start=$1
end=$2
shift 2
( echo wget -q "$@" '&'
echo 'echo $! > $HOME/wget.pid' )   at $start
echo 'kill $(<$HOME/wget.pid)'   at $end
I think that’s right, but I might have fluffed a $@ for a $* or similar (I usually use the simpler rc shell but it’s not on that server yet). It uses the oft-forgotten at command for one-off timed scripts, so you’ll need the at package installed. I think it might exploit the fact that players like mplayer, VLC and ffplay don’t mind truncated streams, but it seems to work fairly reliably apart from the timing. In other Debian-related news: Debian GNU/Linux: 15 Years Old and at the Crossroads by Bruce Byfield seems an interesting summary (warning: its feedback form contains an eyetest), but doesn’t mention DebConf apart from getting its name wrong. I had the impression that there were a few “at the crossroads” type of talks at DebConf. I guess we’ll see what concrete results come out of DebConf over the next few weeks.

Dirk Eddelbuettel: UseR! 2008 talk

Besides the slides from the tutorial at UseR! 2008 that were mentioned here previously, I also gave a short talk on scripting with R in high-performance computing using our littler frontend to R. The talk introduces and extends an example related to some of the material from the tutorial itself. The slides from the talk are a little rough as the talk was somewhat ad-hoc: As session chair, I was confronted with a fairly last-minute cancellation and a 15 minute hole, and thought this would make a good little talk. It does show a nice trick for using littler with Open MPI (via snow) under the powerful slurm resource manager and batch/queue engine.

Sandro Tosi: Debugging Python scripts

I was trying to squash a bug (for the reference, #494545) of reportbug and I felt I needed a tool to help me debugging that Python script.

So googling up a bit, I came across pdb: it's a really powerful tool, and this guide helped me getting used to it (another one, with extended examples, is here).

Whilst for sure the power of import pdb;pdb.set_trace() is huge and keep adding it in the right places let me fix the bug, but what I was really searching for was something like set -x for a shell script, something that without touching the code, would allow me to debug it. Any suggestions?

Next.

Previous.
