Search Results: "cas"

5 October 2011

Niels Thykier: Numbers and lintian

Lintian uses some small scripts to collect data from packages. In daily talk, they are usually referred to as collection scripts. Lintian uses files to track the status of collection scripts between runs. Consider the following directory listing on lintian.d.o:
$ ls -al laboratory/binary/eclipse/.*-*
-rw-r--r-- 1 user group  45 Jul 18 01:21 laboratory/binary/eclipse/.ar-info-1
-rw-r--r-- 1 user group  45 Jul 18 01:21 laboratory/binary/eclipse/.bin-pkg-control-1
-rw-r--r-- 1 user group  45 Jul 18 01:21 laboratory/binary/eclipse/.changelog-file-1
-rw-r--r-- 1 user group  45 Jul 18 01:21 laboratory/binary/eclipse/.copyright-file-1
-rw-r--r-- 1 user group  45 Jul 18 01:21 laboratory/binary/eclipse/.debian-readme-1
-rw-r--r-- 1 user group  45 Jul 18 01:21 laboratory/binary/eclipse/.doc-base-files-1
-rw-r--r-- 1 user group  45 Jul 18 01:21 laboratory/binary/eclipse/.fields-1
[...]
This example shows that a bunch of collections scripts have been run for the eclipse binary package. Each of these files contain the version of Lintian that created them (or last wrote them) and a timestamp. Why the interest in these files? Let us go a bit back in time to the 15th of June 2011. That was the day where Lintian 2.5.1 was uploaded to unstable. That version of Lintian had 17 collection scripts[1] for binary packages. So every binary package would have 17 files and there are over 35 000 binary packages in the Debian archive. Ouch, so that makes about 595 000 files if we use this on all binary packages on the archive. The size of each of those files are about 45 bytes, so that is a total of 25.5 MB for all of these files[2]. So other than the inode abuse , this is not too bad. A little du -h should confirm this
$ du -h laboratory/binary/eclipse/.*-*
4.0K    laboratory/binary/eclipse/.ar-info-1
4.0K    laboratory/binary/eclipse/.bin-pkg-control-1
4.0K    laboratory/binary/eclipse/.changelog-file-1
4.0K    laboratory/binary/eclipse/.copyright-file-1
4.0K    laboratory/binary/eclipse/.debian-readme-1
4.0K    laboratory/binary/eclipse/.doc-base-files-1
4.0K    laboratory/binary/eclipse/.fields-1
[...]
Whaaa oh the file system uses a block-size of 4K bytes, so I guess we have to pay a full block for these files. Let s see what that gives, 595 000 times 4 kB is 2.27 GB Oops! That was in the (not too distant) past. About a month later (12th of July), the code creating these files are refactored into:
sub _mark_coll_finished  
    my ($self, $collname, $collver) = @_;
    # In the "old days" we would also write the Lintian version and the time
    # stamp in these files, but since we never read them it seems like overkill.
    #  - for the timestamp we could use the mtime of the file anyway
    return touch_file "$self-> base_dir /.$collname-$collver";
 
This turns out to be a very space-saving change if we ask du -h:
$ du -h laboratory/binary/lintian/.*-*
0       laboratory/binary/lintian/.ar-info-1
0       laboratory/binary/lintian/.bin-pkg-control-1
0       laboratory/binary/lintian/.changelog-file-1
0       laboratory/binary/lintian/.copyright-file-1
0       laboratory/binary/lintian/.debian-readme-1
0       laboratory/binary/lintian/.doc-base-files-1
[...]
Existing files are not emptied, so we still have some old non-empty files left on lintian.d.o. Nevertheless that was the "nice story" about "the side effect of being lazy sometimes reduces space waste"[3]. But we have another "number" problem. If you grep for "Too many links" in the lintian.log from lintian.d.o you should see:
$ grep -i "too many links" logs/lintian.log
mkdir: cannot create directory  /srv/lintian.debian.org/laboratory/binary/aces3': Too many links
mkdir: cannot create directory  /srv/lintian.debian.org/laboratory/binary/boinc-cgi-stripchart': Too many links
mkdir: cannot create directory  /srv/lintian.debian.org/laboratory/binary/libbrailleutils-java': Too many links
mkdir: cannot create directory  /srv/lintian.debian.org/laboratory/binary/libbrailleutils-java-doc': Too many links
mkdir: cannot create directory  /srv/lintian.debian.org/laboratory/binary/libclippoly0': Too many links
mkdir: cannot create directory  /srv/lintian.debian.org/laboratory/binary/libclippoly-dev': Too many links
mkdir: cannot create directory  /srv/lintian.debian.org/laboratory/binary/xul-ext-cookie-monster': Too many links
mkdir: cannot create directory  /srv/lintian.debian.org/laboratory/binary/cucumber': Too many links
[...]
$ grep -i "too many links" logs/lintian.log   wc -l
3274
In the Lintian Laboratory every package is unpacked in a directory based on its type and name (as hinted in the output above). The problem is that ext3 has a limit of the amount sub-directories a directory can have[4]. This limit is just shy of 32 000 and (as a reminder) Debian has over 35 000 binary packages. So a lot of packages are currently not checked on lintian.d.o (#641468). The current feature branch for #641468 already solves the directory limit issue (by using a "mirror-like" pool layout). It also removes the need for "1 file per completed collection" by writing this information in the existing "per entry" status file.
I hope we can get the branch merged into master within 2-3 weeks, though there are still a few issues that needs to be worked out before then. Footnotes: [1] Actually it had 18 collections, but one of them are "auto-removed" so it is better not to include it in this case. [2] Content alone - metadata like permissions and such is ignored. [3] I admit it was more luck than intention! [4] The limit comes from the "32 000 hardlink per inode" limitation.

Tollef Fog Heen: The SugarCRM rest interface

We use SugarCRM at work and I've complained about its not-very-RESTy REST interface. John Mertic a (the?) SugarCRM Community Manager asked me about what problems I'd had (apart from its lack of RESTfulness) and I said I'd write a blog post about it. In our case, the REST interface is used to integrate Sugar and RT so we get a link in both interfaces to jump from opportunities to the corresponding RT ticket (and back again). This should be a fairly trivial exercise or so you would think. The problems, as I see it are: My first gripe is the complete lack of REST in the URLs. Everything is just sent to https://sugar/service/v2/rest.php. Usually a POST, but sometimes a GET. It's not documented what to use where. The POST parameters we send when logging in are:

method=>"login"
input_type=>"JSON"
response_type=>"JSON"
rest_data=>json($params)
$params is a hash as follows:
user_auth =>  
            user_name => $USERNAME,
            password => $PW,
            version => "1.2",
 ,
application => "foo",
Nothing seems to actually care about the value of application, nor about the user_auth.version value. The password is the md5 of the actual password, hex encoded. I'm not sure why it is, as this adds absolutely no security, but it is. This is also not properly documented. This gives us a JSON object back with a somewhat haphazard selection of attributes (reformatted here for readability):
 
     "id":"<hex session id>,
     "module_name":"Users",
     "name_value_list":  
             "user_id":  
                     "name":"user_id",
                     "value":"1"
              ,
             "user_name":  
                     "name":"user_name",
                     "value":"<username>"
              ,
             "user_language":  
                     "name":"user_language",
                     "value":"en_us"
              ,
             "user_currency_id":  
                     "name":"user_currency_id",
                 "value":"-99"
              ,
             "user_currency_name":  
                     "name":"user_currency_name",
                     "value":"Euro"


What is the module_name? No real idea. In general, when you get back an id and a module_name field, it tells you that the id exists is an object that exists in the context of the given module. Not here, since the session id is not a user. The worst here is the name_value_list concept which is used all over the REST interface. First, it's not a list, it's a hash. Secondly, I have no idea what would be wrong by just using keys directly in the top level object, so the object would have looked somewhat like:
 
     "id":"<hex session id>,
     "user_id": 1,
     "user_name": "<username>,
     "user_language":"en_us",
     "user_currency_id": "-99",
     "user_currency_name": "Euro"
 
Some people might argue that since you can have custom field names this can cause clashes. Except, it can't, since they're all suffixed with _c. So we're now logged in and can fetch all opportunities. This we do by posting:
method=>"get_entry_list",
input_type=>"JSON",
response_type=>"JSON",
rest_data=>to_json([
            $sid,
            $module,
            $where,
            "",
            $next,
            $fields,
            $links,
            1000
])
Why this is a list rather than a hash? Again, I don't know. A hash would make more sense to me. The resulting JSON looks like:
 
    "result_count" : 16,
    "relationship_list" : [],
    "entry_list" : [
        
          "name_value_list" :  
             "rt_status_c" :  
                "value" : "resolved",
                "name" : "rt_status_c"
              ,
             [ ]
           ,
          "module_name" : "Opportunities",
          "id" : "<entry_uuid>"
        ,
       [ ]
    ],
    "next_offset" : 16
 
Now, entry_list actually is a list here, which is good and all, but there's still the annoying name_value_list concept. Last, we want to update the record in Sugar, to do this we do:
method=>"set_entry",
input_type=>"JSON",
response_type=>"JSON",
rest_data=>to_json([
    $sid,
    "Opportunities",
    $fields
])
$fields is not a name_value_list, but instead is:
 
    "rt_status_c" : "resolved",
    "id" : "<status text>"
 
Why this works and my attempts at using a proper name_value_list didn't work? I have no idea. I think that pretty much sums it up. I'm sure there are other problems in there (such as the over 100 lines of support code for the about 20 lines of actual code that does useful work), though.

Jonathan McDowell: Thanks for the offer, but...

I was due for another Google interview mail it seems. I have to say I wasn't expecting it, but this week I had a follow up to my polite mail from 6 months ago that said "No thanks, I'm not looking" asking if it was still the case. Normally I welcome this little bit of ego stroking; it's always nice to be wanted. Except that's not really the case, is it? It's an invitation to interview for something, not any indication that you've done more than tick some initial boxes. Google mails inevitably ask me if I'd like to work in SRE. It's always SRE. No one ever emails and asks if I want to work on self-replicating nanobots that will roam Mars searching for the perfect spot to build a beach house. And that's where things fall down. If someone currently has a job, then emailing them out of the blue to ask if they want to come and interview for something vague is hoping that they're either looking, and just haven't come to you yet, or not looking but unhappy enough with their current role that all they needed to start was an email asking them to submit a recent CV. For the former, if you're Google, do you really think that person doesn't know where to find you? For the latter, you're being quite presumptuous, aren't you? The act of updating my CV my be some effort (actually it's usually not, because the stuff that's not on it is the stuff I can't talk about because it's not released yet, or stuff that's specific and thus wouldn't go on a CV for a vague job spec). Even if it's not the act of interviewing is potentially a waste of time for both of us, if the role isn't clear. One argument used is that people will be placed according to the skills they show during the interview process. That's fine from the employers point of view, but if you're actively trying to get some interest from people who are gainfully employed you really need to grab their attention somehow. I can't remember the last time I had an unsolicited email interview offer that actually wowed me, or indeed even showed more than a passing sign of tailoring a spec to my profile. When I was running Black Cat I made a point of always replying to unsolicited CVs. How polite I was depended on how the covering emails were worded (a Word document with nothing else was likely to get short shrift, something well targeted in a Linux friendly format would normally get some comment about how we weren't hiring and were unlikely to be, but if that changed it would be mentioned on the website), but I felt people deserved a reply - I have been disappointed by not receiving responses myself to what I considered well targeted job inquiries. So far I've so far taken the same approach with mails from corporate recruiters (less so with recruiters that are associated with recruitment firms, rather than directly with the companies they are hiring for), but I'm starting to feel like changing that stance. Candidates are told to tailor CVs to the role being applied for, provide a decent cover letter, and in general make companies want to talk to them. Companies who are sending out recruitment emails should be held to the same standard. Even assuming you do a basic phone screen first, I can probably expect to need to take a day off work assuming that goes well. You need to convince me I can justify that before I'm going to feel like engaging at all. (And if I'm honest, based on what I've seen so far, it's unlikely to happen. All of the things I've considered have come from conversations with people I know directly about companies they own or work for, never some random contact via email. I try hard not to think of recruitment mail as spam, but I can how that line of thought follows through.) I should apologize to Google here. They got mentioned as an example, but I don't think they're particularly bad. I did interview with them at one point, and made the decision not to continue that process after deciding a different, more certain, path was better for me. So I've displayed interest. And in response to my reply today of "I know where to find you, so please assume I'll do so if I change my mind." they've said they'll make a note on their records.

4 October 2011

Michael Banck: 4 Oct 2011

Woodchuck and FrOSCon

At the end of August, I attended FrOSCon in Bonn again, after skipping it last year. The evening before FrOSCon however, I visited Neal Walfield, his wife Isabel and their little son Noam in D sseldorf. Besides having a great time and a lovely dinner, I was most impressed by their collection of Maemo devices (they had at least two N770s, an N900 and, to my jealousy, an N950) which Neal is doing research on these days. He works on woodchuck, which is a project investigating how to improve data availability on mobile devices and our conversation prompted him to implement ATP Woodchuck, which makes smarter decisions when to run APT upgrade on your Maemo device then the standard updater. As part of the research, they also run a user behaviour study which I joined, where one installs a client which records various data off your N900 and sends them anonymized (he seems to be doing a good job at that) to figure out how people use their mobile devices and hopefully enhance the experience. So if you have a N900, you should consider joining the study so they get better data.
The next day, I picked up Martin Michlmayr nearby and we headed for FrOSCon. I was quite impressed by the Makerbot at the Tarent booth, but I still don't know what they are really doing and why they had it on display... In the afternoon, I attended a couple of talks in the PostgreSQL developer room and a talk about a big OpenVPN deployment, before ending the day with the excellent as always social event barbeque. On Sunday, I went to quite a few talks, but I thought that two of them were particularly interesting:
Michael "Monty" Widenius of MySQL gave a talk titled "Why going open source will improve your product" about starting businesses on an open source project, or how business can/should open-source their product. Besides a detailed discussion about the various forms of Open Source licenses and the Open-Core model, he proposed the idea of "Business Source" (see slide 20 of his presentation), where a startup would distribute the source code under a non-commercial (but otherwise open-source) license with the explicit guarantee that the license would be changed to a true FLOSS license at some defined point in the future, giving the company a head start to develop and nurture their project. I asked whether this has been already implemented in practise and how the community could be sure that e.g. lawyers after a hostile takeover would not just remove that part of the copyright notice, as long as a true distribution under a FLOSS license has not happened yet. Monty wasn't aware of any real-word cases, and he did not seem to be concerned about this and said the original intent would be clear in a possible court case. This was the first time I heard about this approach, I wonder how other people think about it, whether it would work in practise and be a useful thing to have?
Second, I attended a talk by Gregor Geiermann, a Ph.D. student in linguistics on "Perceptions of rudeness in Free Software communities". He conducted an online survey about the perceived rudeness of several forum thread posts on Ubuntu Forums. Survey participants were first asked a couple of generic questions about their gender, nationality etc. and were then presented with a series of posts. For each post, they were asked to rate how rude they thought it was on a scale of 1 to 5 and they also had the possibility to highlight the parts of the post they considered rude as well as add comments. He presented a neat web application for analyzing the results, which makes it possible to select different groups (he did male vs. female and Americans vs. Germans in the talk) and have their overall rudeness ratings as well as the highlighted texts visualized as different shades of blue. Comments can be easily accessed. There were quite a few interesting differences e.g. in how Germans perceived rudeness compared to Americans (RTFM comments were considered less rude by Germans for example, IIRC). In response to my question, he said he intended to release the web application as open source and this might be an interesting tool for FLOSS projects to analyze how their public communication channels are perceived by various groups. Unfortunately, I cannot find any other resources about this on the web as of today, so I should try to contact him about it at some point.

Andreas Barth: Building a mipsel porter box and buildd

As grub is now working on the loongson 2e boxes as well (thanks to phcoder and Colin Watson), it is time to move the buildds running at my home to a data center (previously we couldn't remote manage the kernels / boot flags without VGA console, which means no data center usage). Also one of the boxes could be converted to a porter machine, so that we could get an mipsel porter box again. The machines are delivered only with 256M of ram, which is a bit too less for usage. Thanks to Zugschlus (Marc Haber) I got 1g ram for both machines going to Vienna (one buildd, one porter box), and thanks to Robert Grimm a 160g harddisk to replace the build-in 40g in the porter box (the buildd can cope with 40g fine). The additional ram modules and hard disk are visible on the following picture.
eysler.debian.org is now DSAed, online and building packages (including autosigning). I will shutdown monteverdi.ayous.org which is still at my place in the next days, reinstall the system and send it to Darmstadt as another buildd for data center hosting there. After that happens all mipsel buildds are DSAed as it should be, and are running in a data center and not via some DSL line. (In case you're looking for hardware at your place, there are a couple of loongson 2f-systems available to buy. 2f is the successor cpu of 2e. Some 2f systems get delivered with Debian installed on it, see e.g. http://www.aliexpress.com/product-gs/290632002-Yeeloong-8101-Laptop-10-inch-Debian-EU-Adaptor-version--wholesalers.html. However, for buildd usage, the 2e are fine as well, and we got them sponsored some time ago.)

3 October 2011

Timo Jyrinki: From MeeGo to Tizen, Debian, ...?

The MeeGo community is frustrated with the news of the MeeGo brand being abandoned. Some are understandably angry or otherwise not happy about how Linux Foundation, Intel handled the Tizen announcement and community in general - or more like how they didn't handle it at all.Last week Openmind 2011 happened to be arranged in Tampere on the very same day as Tizen announcement came alive. It was good in the way that it lead to the fact that Nomovok's CEO Pasi Nieminen was able to initiate the "Reigniting MeeGo" session not just by talking vague things about future, but actually about the process which led to Tizen and the unfortunately brief initial PR about it. Pasi is intense on emphasizing the quality and role of Qt in Tizen as well, even though officially Tizen is all about HTML5 and apparently from Samsung's part at least EFL is provided as a native toolkit. However, the promise of Tizen compared to MeeGo is reportedly that the toolkit is not specified in compliancy documents, so HTML5 with WAC is the main/only "3rd party apps" layer whereas others can be offered case-by-case. This means that unlike before, the underlying system can be built on top of practically any distribution (theoretically) and using whatever toolkits and other techniques wanted. Obviously the "Nordic System Integrators" are probably all very keen of using Qt to produce more of Nokia N9 quality user experiences in various products.

Taking the corporate hat off, I as a community member am also puzzled. The only reason I was not completely blown by the news was that I didn't yet manage to get involved in MeeGo community on a daily basis, since I'm involved with a dozen communities already. Instead I've been more like scratching the surface with MeeGo Network Finland meetings, IRC activity, OBS usage for building a few apps for MeeGo Harmattan and MeeGo proper etc. But I can somewhat understand how people like Jarkko Moilanen from meego-fi feel. They have given a _lot_ to the MeeGo community and brand, all taken away without hearing or pre-notice.

So where to now for MeeGo community? Tizen is one obvious choice. However, for all the talks that even I started this post with, Tizen is still vaporware today, and the dislike of how community is being treated might make it easy to consider other options. Also, if Tizen's reference implementation has lesser meaning, it might also mean less to actually be "in" the Tizen community than in MeeGo. I met Jos Poortvliet at Openmind, and he invited people to openSUSE. There is a lot of common ground with MeeGo and openSUSE - strong OBS usage, RPM packaging, community side focused on KDE and therefore Qt.

I would like to now point similarly to Debian! If one is tired about corporate interests and not listening to community, there is no match for Debian's 15+ years history, purely volunteer based, trust based organization, and first of all scope. While openSUSE has traditionally focused on desktop (even though like Jos pointed out they are open to all new contributions and projects), Debian has always had the "universal" scope, ie. no boundaries besides producing free software operating system for various purposes. There are over 10 architectures maintained at the moment, including the ARM (different ports for ARMv4 and hard-float ARMv7) and x86 from MeeGo world. There are even alternative kernels to Linux, mainly the GNU/kFreeBSD port. There are multiple relevant plans and projects like the Smartphones wiki area, most noticeably Debian on Neo FreeRunner. I have run Debian on my primary mobile phone for over 2.5 years, although now in the recent months I've had dual-SIM in my Nokia N950 as well (Debian not yet running on Nokia N950 or Nokia N9 - but it can and will be done!).

What Debian may lack in both good and bad is corporate funding, if you don't count the still quite respectful contributions from Ubuntu to Debian (it's in Ubuntu's interests to contribute as much possible back to Debian, so that the delta remains small). For each and every aspect, it needs a volunteer - there are a thousand volunteer Debian Developers, and at least a double of that of people without the official DD status but who still maintain a package or two among the 25000+ packages in Debian. That means also that one my find it more lucrative to join a project that has paid people to do some of the "boring parts", more of fancy web tools, including for bug handling and build systems like the OBS (which I do love by the way). On the other hand, there is no other project in my opinion where what you do really matters as much.

To find out more about Debian from MeeGo perspective, please see the recent mailing list post Mobile UXes - From the DebConf11 BoF to the stars where I wrote most of the MeeGo (CE) part when I was asked to and known of my MeeGo involvement.

Last but not certainly least, there is the Mer project - originally "maemo reconstructed", ie. making Nokia's "not really distro" into a real distro by filling in the void places. Now it's obviously MeeGo reconstructed, and they aim to be the MeeGo they always wanted MeeGo to be! Read the post for details from Carsten Munk and other key Mer people. They share the love for Qt, and want the core to be as lean as possible. They also aim to incorporate the most community like aspect from MeeGo - MeeGo CE - as the reference vendor in Mer. They also aim to be Tizen compliant - and when Tizen comes alive, I wouldn't see why the Tizen reference implementation couldn't be used for saving resources. Maybe Nomovok and/or others could offer the Qt maintaining part.

So, it might be that Tizen itself is enough for most people's needs. The key point however in this post is not to fall in agony if one corporate based project takes big turns - it has happened before, it will happen in the future. There are always enough political and business reasons from some points of view to do Big Changes. But the wider community is out there, always, and it's bigger than you think. You should consider where you want to contribute by asking yourself why you are/were part of for example the MeeGo community. Aaron Seigo from KDE asked us all this question in the Openmind MeeGo Reignited session, and I think it's good to repeat.

2 October 2011

Jose Luis Rivas Contreras: Moving from Screen to Tmux

I ve been a long-time user of GNU Screen, as almost every person I know that spend a lot of time in a terminal. I must admit I was happy, I really was. I was used to my workflow with 4 terminals 8 25 and a bunch of screens, with several nested-screens. I used awesome-wm before, so definitely I felt I wasn t using all the space in my laptop screen (my laptop is a ThinkPad X61, so 1024 768 in a 12 inches-screen) but that was OK, after all my workflow was, well, good. Until 2 days ago, I was told to try tmux, in fact, I was told and why are you using screen? use tmux . As a daily-user of Screen my first reaction was I m used to , I can use it as I want , and a lot of excuses for just not trying something new. But then I made a little research (on Google, of course). In about 30 minutes I ended up with a multiplexer working as I wanted and as I never got Screen to work. Finally I was using just a terminal and using all the space available in my tiny-laptop-screen and plus: saving a lot of bandwidth with my permanent SSH connection (a really big plus now that I m living with a capped link to the net with a GSM-modem). I changed the Ctrl-b shortcut to Ctrl-a (b is too far for using it with only one hand), configured so I could use nested tmux es like screen when I push Ctrl-a a, activated visual monitoring and even got to use the tmux s buffer along with my X11 buffer when I press Ctrl-a >!! It s all in my ~/.tmux.conf, use it at will. Later I will make a screencast about using tmux, so more people can get a working tmux easily. ATM, I m even more happy than I was with GNU Screen, so, any other recommendation, people?

Neil Williams: Uses of Emdebian - special purpose computers

A continuation of my intermittent series on Emdebian and prompted by a query from Paul Wise, I thought I'd cover some of the uses to which a device running Emdebian can be put. It is a bit long this one...

So, yes, there are general purpose computers which could run Emdebian but there are common features amongst general purpose computers:
  1. Lots of different tasks must be supported - lots of different packages installed, each user could quite easily use a distinct set of packages from another user.

  2. Multi-user support - even if any one machine is only used by one person, a general purpose computer must have support for adding another user - not just a system user, a real user with a login, shell, possibly bookmarks and browser history etc.

  3. Connectivity - general purpose computers (and that includes mobile phones) must connect to a variety of other computers to be at all useful.

  4. Multi-modal data input - there needs to be support for a mouse and a keyboard or touchscreen and just as likely, software support for accessibility interfaces like an on screen keyboard and switch inputs.

  5. Storage for user data - the system admin can't know how much data users are going to add and if it is general purpose, it's probably going to support media players, image viewers, even office software. The data files managed and written by such software tend to be large and tend to accumulate into large collections. This means that a general purpose machine cannot anticipate the full storage requirements, so has to allow plenty of room for user data storage. If there's so much storage space available, why use an OS which is primarily designed to take up less space? Just use the full version, Debian.


Now compare with the common features of special purpose or single-purpose computers:
  1. Single task only - a splash screen (without support for removal) covers all the boot information, the single task starts as a daemon and if the user quits the task, the task initiates a shutdown, not quit. Every effort is made to prevent the task from exposing the underlying OS, including auto-restarts if it does crash.

  2. Single-user support - indeed, user is not the typical user. user in this case is a non-login user without a shell, created by the postinst of the task package purely to support running the task without root privileges (because if the task doesn't need privileges, it shouldn't retain privileges).

  3. Single mode input - don't expect these machines to support 105 key keyboards. You'll be lucky to have 5 keys which are really just buttons. The button won't just enter 'J' into the machine, it will fire off a command to charge your bank or start a drill or shutdown a malfunctioning service. (Each button will often be multi-functional as well, depending on context). Some devices will replace the mouse with a touchscreen but many are fitted in places where touchscreens simply won't survive, where keys have to be able to withstand being submerged in water (or oil) for hours. Many machines simply won't have mouse support at all. Many will not have any typical external connectors. Indeed, units which go into dirty or wet environments certainly won't have standard external connectors of any kind. Think boats and factories. Internal battery packs with custom hot-fit replacements, buttons encased in 4mm of clear plastic, screens viewable only through protective mesh / filters.

  4. Restricted connectivity - if the task doesn't need networking, no networking hardware is fitted. If the task doesn't need USB, no USB hardware is fitted. If the task doesn't need serial connections, there will probably be an internal serial connector but also a Warranty void if removed sticker. Don't expect an RS232 inside the case either, this will be a flat cable connector which you'll need to attach to a breakout board which correctly connects the cable wires to the RS232 port pins. That mapping is not standardised (why would it? only service engineers are approved to use it.)

  5. Constrained user data - the task is in complete control and determines what the user can view, store and access. Storage can be expensive and a power drain, so if the task doesn't need Gb of storage, don't fit the machine with Gb of storage. Profit.


So what are these mysterious single-use computers running Emdebian? It's hard to tell because the task has no particular reason to tell the user anything about the OS. Perhaps a different way to phrase the same question would be: Why use a general purpose OS for a special purpose computer?.


This is why Emdebian Grip is popular for these machines - because Emdebian Grip is binary compatible with the equivalent Debian suite and when a bug appears in the high level user interface, it is much easier to debug that on the desktop than on device. Debian stable is a fantastic OS for commercial development - the stability of the OS makes detection of interface bugs much easier. It is rare that developers have to investigate whether bugs in their UI come down to a bug in the underlying OS. That saves time.

The machines themselves? I'm sure others can come up with other examples but these are some which come to my mind (no particular order):


Anywhere where the device simply needs to DoTheRightThing in a variety of unpredictable circumstances, you're going to need a general purpose OS to gather the data and produce the right result. Anywhere where the device has only a single task, you're going to want to not provide access to the rest of the system. There's no point providing "general purpose access" when the device doesn't have "general purpose hardware". There's no point fitting general purpose hardware if the device does not use it. That is a waste of money, a waste of resources and causes unnecessary delays if one component or other becomes unobtainable or changes behaviour. Limit your exposure to hardware bugs and get the product out to the user more quickly and more reliably, everyone is happy. Fit non-standard hardware and you can fit custom hardware which better matches the profile of the device usage - why use standard speakers capable of CD quality across a vast frequency range when the device only makes very very loud alert noises which can be done at lower sample rates and with narrow range, high amplitude, speakers.

There are all sorts of estimates for the number of computers now in the average Western home. It's worth noting that the vast majority of those computers are not PCs or laptops or even game consoles and routers - all instances of general purpose machines with general purpose access / connectivity. A lot of the computers in your home are embedded in machines like white goods, media controllers (set top boxes and the like). Some of these will still use low level firmware written entirely in assembly or COBOL. More complex ones already have a general purpose OS inside yet constrain that OS with a simple, user-friendly interface which is tailored to the hardware actually fitted. It might be cool to connect to your set top box over Bluetooth but really, is that actually going to sell more units? Only if there are other high-end services written for the device which the average customer won't want to see pushing up the price of the base unit. Some machines (particularly in automotive uses) will need to be using Real Time operating systems and Safety Critical operating systems but even some of those are based on general purpose systems - just old versions which have been thoroughly tested.

Finally, consider that for a lot of these devices, the customer is not you. The customer is another business who then put the device into something else which is installed into a factory production line which produces something which goes into creating a consumer product you find in Tesco or on Amazon or bundled in with another service like your TV/broadband contract. There is absolutely no reason for these devices to provide general purpose computing to you, even if the device itself is part of something else which can provide such services.

Wouter Verhelst: Test suites considered good

Yesterday, I uploaded NBD 2.9.24-1 to Debian. The big new feature in that release is that it now has an 'includedir' global configuration variable, with which it supports a conf.d-style directory. This feature was implemented by request of Vagrant Cascadian, of LTSP fame. Only it didn't build on kFreeBSD. The reason? The particular test that I added for that new feature failed. It turned out to be a simple bug in the code, which just didn't trigger on Linux but which was a bug none the less. I hadn't noticed, since my main development machine runs Linux; this is why I added a test suite to the code. Bug fixed, new package is in incoming. Whee.

1 October 2011

Sergio Talens-Oliag: Static website generators

The last month I was supposed to work on a OpenStack related project, but for administrative reasons it has been delayed and I've tried to do small tasks to be able to finish them quickly and start the work on the main project when the issues get solved. As the delay has been longer than expected last Wednesday I've realized than on the last weeks I did a lot of small system administration tasks: With all the changes I did I noticed that I had to do something with our Intranet server; it is just a reverse proxy for a lot of different web services and its main page was one static HTML page with links to them, nothing else. In the long term maybe we will replace it with something based on Drupal or Lifeay, but for now I just wanted something to be able to organize the links and provide some information about the services for the new users without having to write HTML (I really like Agile Documentation Tools that let me focus on the content and forget about the markup), and started to look at some of them. My first idea was to use ikiwiki, as it has all the features I was looking for: I can use Markdown or reStructuredText to write the contents, the source pages are easily handled on a Version Control System, it supports the use of templates for the HTML, etc., but it seemed to me that using ikiwiki was like killing flies with a cannon (that's a Spanish say, I guess it's easy to understand it in English, no?) and I decided to review other tools to build static web sites. To make a long story short, I selected some tools that met my requirements and looked nice on their demo sites; after my first review I thought that Hyde was going to be my bet, as it uses technologies I'm already familiar with, but after trying it I saw that I was going to have a problem with documentation (the current Hyde version lacks it) and it was going to be more complicated that using ikiwiki. Before giving up I decided to review simpler tools, just in case, and after looking some of them I ended up using poole, a simple python script (the source is just one file and it only requires python-markdown to work). Before moving to the content I tried to adapt a couple of free themes to be used by the tool, but I didn't liked the result, so I went back to the plain style provided by the tool and added a logo and a background. With that simple look and feel I started to work with the content, splitting it into eight markdown files and a python macro to include a file that has all the links used on the site. While trying to make the main page look good I noticed how little I know about CSS, but using search engines I was able to build a two column block into the main page and publish the contents and with the help of some CSS enabled co-workers I changed the look and feel of the site in about 30 minutes. In summary, if you want a really simple website, you know a little bit of python and don't want to spend much time learning how to use a website generator then Poole is a good option. If you want something more complex I still think that ikiwiki is a good option, but YMMV.
30 September 2011

Craig Small: ncurses library split

The new ncurses library that is currently sitting in the NEW queue will have a significant change that, if we ve done it right, should be an invisible change. If we ve got it wrong, then the BTS (and us) may be a little busy. What has happened is that the low-level terminfo library has been split out from the general ncurses library making a new package called libtinfo5. This also means that there only needs to be one libtinfo5 package because at this low level it doesn t care about wide characters, so there is no libtinfo5w (and that gets important later). libncurses is linked to libtinfo so from the point of view of using libncurses there should be no major change in how things are done. So, why bother? The way ncurses was built before causes a nice long conga line of trouble . There really are (was) two main ncurses library packages, libncurses5 and libncursesw5. The w meant it was for wide characters. So anything that uses ncurses needs to decide which one to link to or perhaps both. A problem came up with the readline library that needs to link to ncurses because programs that link to IT (such as python) want a wide library but other programs do not. One solution is to have two readline libraries, but then any other library would need to be compiled and built twice as well and so on and so on. readline didn t really want the full ncurses library, it only wants the terminfo part but there was (until now) no way of picking up that bit only. Once this new version of ncurses gets released then readline can link to libterminfo which is agnostic to wide and non-wide characters which means it is as well which them means everything else should, in theory work. If you are using ncurses for some low-level terminfo work only, you may want to have a look to see if you can link to libtinfo5 only which will mean depending on libtinfo5 and not libncurses5 or libncursesw5. I m just writing this up mainly and uploading the packages, the bulk of the work was done by Sven and Matthias as well as some help from our ever-helpful upstream Thomas.

28 September 2011

Alejandro Rios P.: 2011 Colombian Mini-DebConf

This weekend we'll be having the 4th version of the Colombian Mini-Debconf. It will be held in the Otraparte Museum, in the city of Medellin. The cool thing this year is that we'll be having mostly Debian contributors than just users, with the kind participation of Anibal Monsalve, who is currently in the country.

There will be several 10-min lightening talks, followed by a key signing party and some actual work in packaging, and of course we'll be having some beers with Debian friends.

More info (in Spanish): http://wiki.debian.org/DebianColombia/MiniDebconf2011

27 September 2011

Vincent Bernat: Speeding up SSL: enabling session reuse

Session reuse is one of the most important mechanism to improve SSL performance: by submitting an appropriate blob to the server, a client is able to trigger an abbreviated handshake, improving latency and computation time. There exists two distinct ways to achieve session reuse: session identifiers as described in RFC 5246 and session tickets as depicted in RFC 5077. A quick note: when I say SSL, unless I mention a version number, you should read TLS instead. Look at the article for TLS on Wikipedia for some background on this.

Theory of operation To establish a SSL connection, four messages need to be exchanged between client and server. With a latency of 50 ms, we have a 200 ms overhead to establish the connection (plus TCP handshake). Moreover, to share a common secret, both the client and the server needs to achieve some public-key cryptographic operations which are costly, computation-wise. SSL full handshake To avoid a full SSL handshake each time a client request a resource, it is possible for the client to request an abbreviated handshake, saving a complete round-trip (100 ms) and avoiding the costliest part of the full SSL handshake. SSL abbreviated handshake Two mechanisms can be used to accomplish an abbreviated handshake:
  1. When the server sends the Server Hello message, it can include a session identifier. The client should store it and present it in the Client Hello message of the next session. If the server finds the corresponding session in its cache and accepts to resume the session, it will send back the same session identifier and will continue with the abbreviated SSL handshake. Otherwise, it will issue a new session identifier and switch to a full handshake. This mechanism is detailed in RFC 5246. It is the most common mechanism because it exists since earlier versions of SSL.
  2. In the last exchange of a full SSL handshake, the server can include a New Session Ticket message (not represented in the handshake described in the picture) which will contain the complete session state (including the master secret negotiated between the client and the server and the cipher suite used). Therefore, this state is encrypted and integrity-protected by a key known only by the server. This opaque datum is known as a session ticket. The details lie in RFC 5077 which supersedes RFC 4507.
The ticket mechanism is a TLS extension. The client can advertise its support by sending an empty Session Ticket extension in the Client Hello message. The server will answer with an empty Session Ticket extension in its Server Hello message if it supports it. If one of them does not support this extension, they can fallback to the session identifier mechanism built into SSL. RFC 5077 identifies situations where tickets are desirable over session identifiers. The main improvement is to avoid to maintain a server-side session cache since the whole session state is remembered by the client, not the server. A session cache can be costly in term of memory and difficult to share between multiple hosts when requests are load-balanced across servers.

Browser support Session identifiers are part of SSL and are therefore supported since a long time by clients and servers. However, session tickets are an optional TLS extension and therefore, the support is not as widespread as for session identifiers. Support for tickets was added in OpenSSL 0.9.8f (October 2007). In GnuTLS, this is version 2.9.3 (August 2009). For NSS, the set of libraries behind most browsers, support of RFC 5077 is in version 3.12 (June 2008). Schannel, Microsoft implementation of TLS, does not currently supports tickets. To check if a browser supports session resume without and with tickets, I have written a web server listening to several ports with different configurations (session cache disabled or enabled, ticket support disabled or enabled). With the help of some Javascript, it is possible to interact with this server to determine what kind of session resume a browser support. Checking for browser support for session resume It is difficult to get extensive results this way since you need to install a lot of browsers to get something valuable. Surprisingly, Android 2.3.4 browser (as shipped by Cyanogen Mod) does not support any session resume. Another way to check if a browser supports session resume is to use a sniffer and to spot Client Hello messages. If a client tries to resume a session, it will use an appropriate session identifier or send a ticket. A simple program parsing PCAP files allows to automate this task and get some interesting statistics. Here are random facts from more than 300 000 requests (38 000 clients) to a customer care service of an important French telco:
  • 35% of requests exhibit support of tickets;
  • 53.3% of requests ask to resume without tickets; 25.6% with tickets;
  • 67.2% of requests exhibit support of SNI;
  • 86.7% of requests use TLS 1.0; the remaining uses SSL 3.0; almost no TLS 1.1/1.2;
  • in average, a client execute 8 SSL handshakes;
  • ciphers supported by all clients are 3DES-SHA, RC4-MD5 and RC4-SHA.
With some log analysis to match each requests with the appropriate user agent, we can split the world in two parts: browsers supporting RFC 5077 (Chrome and Firefox) and browsers not supporting RFC 5077 (Internet Explorer, Opera 9.80, Safari for MacOS and iOS and Android browser).

Web server support There is no unique recipe to configure a web server to handle appropriately and efficiently session resume. Here are some generic directions :
  • if the web server uses multiple processes, you need to configure a shared memory session cache; usually, tickets will work just fine in this setup;
  • if you use local load-balancing, one easy way to avoid any problem is to use ensure that one IP is mapped to one server (either statically with hashing or dynamically with a stick table); if your load-balancer understands SSL, you can also use session identifier (and disable tickets1) to build a stick table;
  • if you don t want to apply the previous advice, you need to share the session cache between the servers with something like memcached and disable tickets;
  • if you use global load-balancing (DNS based), there is no need to ensure that session resumption works across geographic pools since a user will usually stick to one pool.
Remember that only one client out of three supports TLS tickets. Therefore, you cannot rely on them to ensure proper session resume. You need a session cache.

Setting a session cache with Apache & nginx Apache features two different SSL engines. The first one is mod_ssl and uses OpenSSL as backend. It is possible to setup a shared session cache with SSLSessionCache but the memcached-enabled session cache is available only in the development branch. You can also get one by switching to mod_gnutls backend. The cache is enabled with GnuTLSCache. In this case, do not enable tickets because they cannot be shared. With nginx, you need to enable the shared session cache with ssl_session_cache. Currently, it lacks a memcached-enabled session cache but Matt Palmer has some patches to add it to the 0.8 branch. However, those patches can have a serious impact on nginx performance since retrieving a session from memcached is done synchronously (mostly because a limitation in OpenSSL design who does not allow to register asynchronous callbacks with SSL_CTX_sess_set_get_cb()). As a proof of concept, I have also added a similar feature to stud, the scalable TLS unwrapping daemon, a very efficient network proxy terminating SSL connections. The same limitation as for nginx applies: performances will suffer. Look at the pull request for more details.

Sharing tickets RFC 5077 tells tickets allow to load-balance requests across servers. However, to the best of my knowledge, there is currently no web server able to share tickets across a pool. Actually, when a server initializes its SSL stack, it will randomly generate some keys that will be used to protect and encrypt tickets. In OpenSSL, from ssl/ssl_lib.c:
    /* Setup RFC4507 ticket keys */
    if ((RAND_pseudo_bytes(ret->tlsext_tick_key_name, 16) <= 0)
              (RAND_bytes(ret->tlsext_tick_hmac_key, 16) <= 0)
              (RAND_bytes(ret->tlsext_tick_aes_key, 16) <= 0))
            ret->options  = SSL_OP_NO_TICKET;
Therefore, with a round-robin load-balanced pool of servers, tickets have to be disabled because servers would not accept tickets from neighbors. One way to solve this is to generate keys deterministically by hashing some common secret with the private key. I have implemented this approach for stud. Here is a simplified version (no error handling, no allocation) of the pull request for this feature:
    unsigned char keys[48];
    EVP_PKEY *pkey = grab_private_key();
    /* To get our key, we sign the seed with the private key */
    unsigned int siglen;
    unsigned char sign[LARGE_ENOUGH];
    EVP_MD_CTX mdctx;
    EVP_MD_CTX_init(&mdctx);
    EVP_SignInit(&mdctx, EVP_sha256());
    EVP_SignUpdate(&mdctx, some_secret, strlen(some_secret));
    EVP_SignFinal(&mdctx, sign, &siglen, pkey);
    /* And we keep only the first bytes. */
    memcpy(keys, sign, sizeof(keys));
    /* Tell OpenSSL to use those keys */
    SSL_CTX_set_tlsext_ticket_keys(ctx, keys, sizeof(keys));

Testing While tests can be done with just openssl s_client and openssl sess_id, testing all aspects can take a lot of time. For this purpose, I have written a client testing session resume with and without tickets. Here is a typical result: twitter.com RFC session resume The program will try to establish five consecutive SSL connections for each IP without and with tickets. For each IP, the last four SSL connections should always reuse the first SSL session. Here, Twitter web servers seem properly configured: for each IP, session resume is successful. Their web servers do not support tickets or they may have disabled it because they share the session cache between servers inside the same pool.

  1. RFC 5077 describes interactions between session identifiers and session tickets. When using tickets, the server should send back an empty session identifier. The client may present an empty session identifier or generate one. However, for all practical purposes, it seems that servers send back a non-empty session identifier and clients just stick to this identifier. Please, investigate if you want to use SSL session identifiers for load-balancing while keeping tickets enabled.

Christian Perrier: Stop making sense...

Hope a few of my readers got it from the title of this blog post. And maybe many others didn't. So let's talk about "Stop Making Sense". You're warned: nothing to do with free software...or running, this time. This is all about music. Music from the 80's. "Stop Making Sense" is indeed, in my opinion, one of the best achieved musical movie. It is simple: it features a gig by the Talking Heads, back in 1983, when this band was among the most innovative ones that ever appeared in the late 70's. And I finally managed to take time to actually buy the DVD and see it again as I didn't see it since 1985. For many people, Talking Heads is the incredible person that's David Byrne. That's certainly true for some parts (and this is what lead to their split in 1991), but the movie really gives credit to all members of the band, either the "regular" ones (Tina Weymouth, Chris Frantz, Jerry Harrison) or the tour musicians (Bernie Worrell, Alex Weir, Steven Scales, Lynn Mabry, Edna Holt). The construction of the movie is simple: it just starts with Byrne bringing a music box on an empty stage, with his acoustic guitar and playing an incredible tense "Psycho Killer" (there are so many different version of that mythical piece but this one is among the best). Then Tina joins for a not-so-often played "Heaven" and brings her so inimitable bass line (I count Tina among my very favourite bass player, immediately after Tony Levin). At the end of the piece, the crew quietly brings a full drum set, then Chris Frantz joins, smiling as ever, and the rhythm increases with "Thank you for sending me an angel". Then Jerry Harrison joins, to make the original Heads line-up for a really funky "Found a Job", where Jerry shows that he was THE Heads lead guitar (and Tina is still keeping the foundations so strong). Continuing the increasing tension, the rest of the musicians join for Slippery People, then Burning Down the House ("Who's got a match?"). All this culmminates in a crazy joggin on stage during "Life During Wartime" and Byrne performing incredible and stellar movements on stage. THis one surely makes the band entirely exhausted. How can they survive this? The few next songs are a little bit less stunning (oh, well, "Making Flippy Floppy" still features a dream bass line)...until a really special "Once in a Lifetime" that...has just to be seen (SAME AS IT EVER WAS), then a break where....the Tom Tom Club (namely Chris, Tina and the rest of the band) perform a giant "Genius of Love", so funky. All this is indeed meant for Byrne to prepare for his top appearance, in "Girlfriend is Better", in a giant suit, that makes his head over his long neck yet more...strange. This leads to a crazy "Take me to the River" which has always been the top of the Heads shows during the 80's and a tireless encore on "Crosseyed and Painless". The movie ends up and you nearly never had a breath. So, yes, if you think you enjoy the Heads music and have never seen that movie, just try doing it once. That's how music was in the 80's..and, doh, these folks were so good! By the way, all parts of the movie can be seen on YouTube in case you just want to see what *I* enjoy. Ah, and yes I share the love of the Heads with Danese "we never meet often enough" Cooper, by the way. We once made a promise ourselves to sing Psycho Killer in karaoke if we're happy (and drunk) enough to meet again before we're too old for this..:-).

26 September 2011

Gunnar Wolf: e-voting: Something is brewing in Jalisco...

There's something brewing, moving in Jalisco (a state in Mexico's West, where our second largest city, Guadalajara, is located). And it seems we have an opportunity to participate, hopefully to be taken into account for the future. Ten days ago, I was contacted by phone by the staff of UDG Noticias, for an interview on the Universidad de Guadalajara radio station. The topic? Electronic voting. If you are interested in what I said there, you can get the interview from my webpage. I held some e-mail contact with the interviewer, and during the past few days, he sent me some links to notes in the La Jornada de Jalisco newspaper, and asked for my opinion on them: On September 23, a fellow UNAM researcher, C sar Astudillo, claims the experience in three municipalities in Jalisco prove that e-voting is viable in the state, and today (September 26), third generation of an electronic booth is appearingly invulnerable. Of course, I don't agree with the arguments presented (and I'll reproduce the mails I sent to UDG Noticias about it before my second interview just below They are in Spanish, though). However, what I liked here is that it does feel like a dialogue. Their successive texts seem to answer to my questioning. So, even though I cannot yet claim this is a real dialogue (it would be much better to be able to sit down face to face and have a fluid conversation), it feels very nice to actually be listened to from the other side! My answer to the first note:
El tema de las urnas electr nicas sigue dando de qu hablar por ac en Jalisco... nosotros en Medios UDG hemos presentado distintas voces como la del Dr. Gabriel Corona Armenta, que est a favor del voto electr nico, del Dr. Luis Antonio Sobrado, magistrado presidente del tribunal supremo de elecciones de Costa Rica, quien nos habl sobre los 20 MDD que les cuesta implementar el sistema por lo que no lo han logrado hasta el momento, pudimos hablar hasta argentina con Federico Heinz y su rotunda oposici n al voto electr nico y por supuesto la entrevista que le realizamos a usted. Sin embargo este d a La Jornada Jalisco publica la siguiente nota http://www.lajornadajalisco.com.mx/2011/09/23/index.php?section=politica... nos gustar a saber cu l es su punto de vista al respecto, quedo a la espera de su respuesta
Hola, Pues... Bueno, s que el IFE hizo un desarrollo muy interesante y bien hecho hace un par de a os, dise ando desde cero las urnas que propon an emplear, pero no se instrumentaron fuera de pilotos (por cuesti n de costos, hasta donde entiendo). Se me hace triste y peligroso que el IEPC de Jalisco est proponiendo, teniendo ese antecedente, la compra de tecnolog a prefabricada, y confiando en lo que les ofrece un proveedor. Se me hace bastante iluso, directamente, lo que propone el t tulo: comicios en tres municipios prueban la viabilidad del voto electr nico en todo el estado . Pong moslo en estos t rminos: El que no se caiga una choza de l mina con estructura de madera demuestra que podemos construir rascacielos de l mina con estructura de madera? Ahora, un par de p rrafos que me llaman la atenci n de lo que publica esta nota de La Jornada:
la propuesta de realizar la elecci n en todo el estado con urnas electr nicas que desea llevar a cabo el Instituto Electoral y de Participaci n Ciudadana (IEPC) es viable, pues los comicios realizados en tres municipios son pruebas suficientes para demostrar que la urna es fiable
y algunos p rrafos m s adelante,
Cu ntas experiencias m s se necesitan para saber si es confiable, 20, 30, no lo s (...) Pero cuando se tiene un diagn stico real, efectivo y serio de cu ndo t cnicamente procede, se puede tomar la decisi n
Como lo menciono en mi art culo... No podemos confundir a la ausencia de evidencia con la evidencia de ausencia. Esto es, que en un despliegue menor no haya habido irregulares no significa que no pueda haberlas. Que haya pa ses que operan 100% con urnas electr nicas no significa que sea el camino a seguir. Hay algunas -y no pocas- experiencias de fallas en diversos sentidos de urnas electr nicas, y eso demuestra que no puede haber confianza en las implementaciones. Aunque el equipo nos saliera gratis (que no es el caso), hay que invertir recursos en su resguardo y mantenimiento. Aunque se generara un rastro impreso verificado por el votante (que s lo ha sido el caso en una peque a fracci n de las estacione de votaci n), nada asegura que los resultados reportados por el equipo sean siempre consistentes con la realidad. El potencial para mal uso que ofrecen es demasiado. Saludos,
And to September 26th:
Disculpe que lo molestemos otra vez, pero este d a fue publicada otra nota m s sobre el tema de las Urnas electr nicas en Jalisco donde se asegura que la urna es invulnerable. http://www.lajornadajalisco.com.mx/2011/09/26/index.php?section=politica... nos podr a conceder unos minutos para hablar con usted, como la vez pasada, v a telef nica sobre el caso espec fico de Jalisco, en referencia a estas notas publicadas recientemente? si es posible podr a llamarle este d a a las 2 pm? Quedo a la espera de su respuesta agradeci ndole su ayuda, apreciamos mucho esta colaboraci n que est haciendo con nosotros
Hola, ( ) Respecto a esta nota: Nuevamente, ausencia de evidencia no es evidencia de ausencia. Se le permite a un peque o segmento de personas jugar con una m quina. Significa eso que fue una prueba completa, exhaustiva? No, s lo que ante un jugueteo casual no pudieron encontrar fallos obvios y graves. Un verdadero proceso que brindara confianza consistir a en (como lo hicieron en Brasil - Y resultaron vulnerables) convocar a la comunidad de expertos en seguridad en c mputo a hacer las pruebas que juzguen necesarias teniendo un nivel razonable de acceso al equipo. Adem s, la seguridad va m s all de modificar los resultados guardados. Un par de ejemplos que se me ocurren sin darle muchas vueltas:
  • Qu pasa si meto un chicle a la ranura lectora de tarjeta magn tica?
  • Qu pasa si golpeo alguna de las teclas lo suficiente para hacerla un poquito menos sensible sin destruirla por completo? (o, ya entrados en gastos, si la destruyo)
La negaci n de servicio es otro tipo de ataque con el cual tenemos que estar familiarizados. No s lo es posible modificar el sentido de la votaci n, sino que es muy f cil impedir que la poblaci n ejerza su derecho. Qu har an en este caso? Bueno, podr an caer de vuelta a votaci n sobre papel - Sobre hojas de un block, probablemente firmadas por cada uno de los funcionarios, por ejemplo. Pero si un atacante bloque la lectura de la tarjeta magn tica, que es necesaria para que el presidente de casilla la marque como cerrada, despoj de su voto a los usuarios. S , se tienen los votos impresos (que, francamente, me da mucho gusto ver que esta urna los maneja de esta manera). El conteo es posible, aunque un poco m s inc modo que en una votaci n tradicional (porque hay que revisar cu les son los que est n marcados como invalidados - no me queda muy claro c mo es el escenario del elector que vot por una opci n, se imprimi otra, y el resultado fue corregido y marcado como tal)... Pero es posible. Sin embargo, y para cerrar con esta respuesta: Si hacemos una corrida de prueba, en circunstancias controladas, obviamente no se notar n los much simos fallos que una urna electr nica puede introducir cuando los "chicos malos" son sus programadores. Podemos estar seguro que este marcador Atlas-Chivas-Cruz Azul tenga el mismo ndice de fiabilidad como una elecci n de candidatos reales, uno de los cuales puede haberle pagado a la empresa desarrolladora para manipular la elecci n? Y a n si el proceso fuera perfecto, indican aqu que est n _intentando_ licitar estas urnas (y nuevamente, si lo que menciona esta nota es cierto, son de las mejores urnas disponibles, y han atendido a muchos de los se alamientos - Qu bueno!)... Para qu ? Qu nos van a dar estas urnas, qu va a ganar la sociedad? Mayor rapidez? Despreciable - Media hora de ganancia. A cambio de cu nto dinero? Mayor confiabilidad? Me queda claro que no, siendo que no s lo somos cuatro trasnochados los que ponemos su sistema en duda, sino que sus mismos proponentes apuntan a la duda generalizada. La frase con la que cierra la nota se me hace digna para colgar un ep logo: "en ese futuro quiz no tan distante la corrupci n tambi n ocurre y sta se debe siempre al factor humano". Y el factor humano sigue ah . Las urnas electr nicas son programadas por personas, por personas falibles. Sin importar del lado que est n, recordar n la pol mica cuando se hizo p blico que la agregaci n de votos en el 2006 fue supervisada por la empresa Hildebrando, propiedad del cu ado del entonces candidato a la presidencia Felipe Calder n. Qu evita que caigamos en un escenario similar, pero ampliamente distribu do? Y aqu hay que referirnos a la sentencia de la Suprema Corte de Alemania: En dicho pa s, las votaciones electr nicas fueron declaradas anticonstitucionales porque s lo un grupo de especialistas podr an auditarlas. Una caja llena de papeles con la evidencia clara del sentido del voto de cada participante puede ser comprendida por cualquier ciudadano. El c digo que controla a las urnas electr nicas, s lo por un peque o porcentaje de la poblaci n.

John Goerzen: Five

Dad, will you and mom stay up all night decorating the house for me?
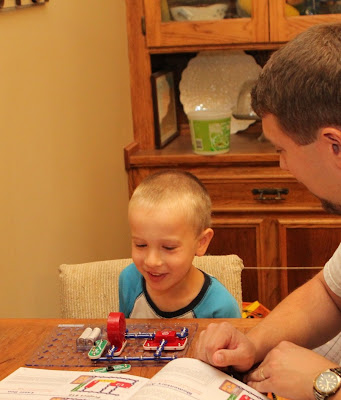
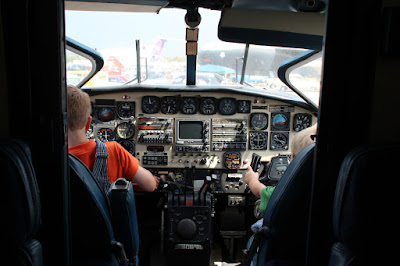
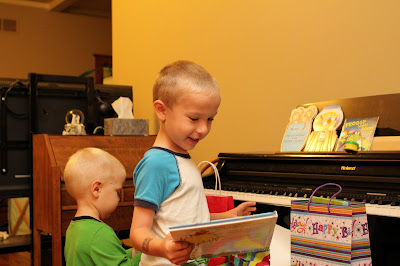
That was Jacob s question to me at bedtime the evening before his fifth birthday. Jacob had already had his birthday party a few weeks ago. When scheduling means that parties happen that far away from the boys real birthdays, they get a smaller celebration with just Terah and me where we open their presents from us. A low-key thing, so we weren t planning to decorate the house. I said, Well, I don t think we ll be doing all that since you already had your birthday party. And the look of eager anticipation on his face turned to a very sad and disappointed look, and made me feel really bad. Uhoh. So while Jacob was sleeping, I mentioned it to Terah. We decided we should improvise something simple, so she found some old streamers and we taped them up, running them through several rooms in the house and across his door. It took a few minutes using supplies we already had, but the joy the next morning was priceless. Oh dad, you said you wouldn t stay up all night, BUT YOU DID! Oh I am SO HAPPY! YAY YAY YAY! And he ran through the house to discover what else was set up. Then he ran to find Oliver and gave him a tour of everything. Then we sat down to open his presents. Here he is, holding a present from Terah and me: That s a copy of The Lorax. My friend Jonathan had brought a copy along during our road trip in Mexico, and Jacob was really excited about it. And didn t really want to give it up, because You can only get The Lorax in Mexico. He (and Oliver) really enjoyed all his presents he also got a train book from us (which he said, Oh, yay, it s the book they have at preschool! ), and a game and some other presents from the distant relatives. But the highlight was something of an impulse buy. I was at the RadioShack in Derby a place I ve written about before, It is what a RadioShack should (and used to) be. It has a large amateur radio section, sells all sorts of coax by the foot, and provides astonishingly good post-sale service. Well, I was there with a radio question, and Mark (the owner) who is an excellent salesman in a positive way pointed me to a display of snap kits. I noticed their Electronics 101 Snap-Kit (a rebranded Snap Circuits Jr. SC-100). A ham in Pennsylvania had suggested them to me once, and as Jacob s birthday was coming up, I gave it some thought. The kit said ages 8 and up. I asked Mark what he thought about a boy just turning 5. He said, Well, probably not normally. But knowing you, if you re there to work on them with him, I think he d enjoy it. But I wouldn t have him work on it by himself. I agreed and we bought it. I pondered how to explain the concept of this thing to Jacob. Eventually I decided I would call it a toy-building kit. He understood that. Jacob and I spent hours together working with it. He would flip through the book, either picking circuits that looked interesting or telling me what kind of circuit he wanted to build. Then I would tell him what to put where, and he d snap them together and play with them. He only played with each finished product a few minutes before he was ready to try another. Once I got him very excited with my offer to show him how to hook up two switches in parallel for the fan he built (and later introduced the parallel vs. series concept by hooking them up in series instead.) Here we are working on it together. Jacob repeatedly called Terah over to look at the things he built. He was very excited that he assembled it himself. Eventually, Oliver (age 2) came over wanting to help. So he sat on my lap, and handed parts to Jacob, then Jacob put them on the grid. Oliver really enjoyed being involved in this way, even though I had to keep him from doing things like ripping the capacitor off its mount. We tend to be modest in terms of the number of things we give the boys and their cost, reasoning that we, like many, already have too many toys in our house, and that greater cost doesn t necessarily equate with a better experience for the boys. I particularly look for things with lasting value and unique experiences for them, and I think we succeeded this year. But I realized quickly that the greatest value of this kit wasn t electronics. It was having a great way for me to spend a lot of time doing things with the boys which all of us enjoyed. Those hours building things together were as much a present for me as for Jacob, I m quite sure. Jacob s real party was a few weeks ago at the Great Plains Transportation Museum in Wichita. They let people rent a historic caboose to use for a birthday party for children. So we did that for Jacob this year. That was a huge hit for the boys. Jacob got to help his grandpa make some pie (instead of cake) for the party. He enjoyed eating it, of course. He enjoyed opening his presents high up on the observation chair in the caboose. And the boys got to play on all the other equipment in the museum. Jacob enjoyed playing tour guide for family since most of them hadn t been there. He also enjoyed watching freight trains pass on the other side of the fence from the museum preferably while sitting in one of the museum s engines. Oliver certainly didn t get left out. Train-watching is serious business, after all. Jacob has long talked about going to the train museum and the airplane museum (Kansas Aviation Museum) on the same day, so one of his birthday surprises was that we went to the airplane museum after his party. His favorite item there is a retired FedEx 727. Here he is walking down the rear of the plane. And, of course, they played captain and co-pilot in several different planes.

Benjamin Mako Hill: Science as Dance

The following selected bibliography showcases only a small portion of the academics who have demonstrated that while it may take two to tango, it only takes one to give a scholarly paper a silly cliche title:

Briganti, G. 2006. It Takes Two to Tango-The CH-53K is arguably the first serious US attempt to open the defense cooperation NATO has been seeking. Rotor and Wing 40(7):60 63.
Coehran, J. 2006. It Takes Two to Tango: Problems with Community Property Ownership of Copyrights and Patents in Texas. Baylor L. Rev. 58:407.
Diamond, M.J. 1984. It takes two to tango: Some thoughts on the neglected importance of the hypnotist in an interactive hypnotherapeutic relationship. American Journal of Clinical Hypnosis 27(1):3 13.
Kraack, A. 1999. It takes two to tango: The place of women in the construction of hegemonic masculinity in a student pub. Masculinities in Aotearoa/New Zealand 153 165.
Lackey, J. 2006. It takes two to tango: beyond reductionism and non-reductionism in the epistemology of testimony. The Epistemology of testimony 160 89.
Miller, C.A. 1998. It takes two to tango: understanding and acquiring symmetrical verbs. Journal of psycholinguistic research 27(3):385 411.
Modiano, N. 1984. It Takes Two to Tango, or Transmission is a Two-Way Street. Anthropology & Education Quarterly 15(4):326 330.
Ott, M.A. 2008. It Takes Two to Tango: Ethical Issues Raised by the Study of Topical Microbicides with Adolescent Dyads. The Journal of adolescent health: official publication of the Society for Adolescent Medicine 42(6):541.
Rubenstein, J.H. 2009. It takes two to tango: dance steps for diagnosing Barrett s esophagus. Respiratory Care Clinics of North America 69(6):1011 1013.
Settersten Jr, R.A. 2009. It takes two to tango: the (un) easy dance between life-course sociology and life-span psychology. Advances in Life Course Research 14(1-2):74 81.
Skaerbaek, E. 2004. It takes two to tango on knowledge production and intersubjectivity. NORA: Nordic Journal of Women's Studies 12(2):93 101.
Spencer, M. 2005. It takes two to tango. Journal of Business Strategy 26(5):62 68.
Vanaerschot, G. 2004. It Takes Two to Tango: On Empathy With Fragile Processes. Psychotherapy: Theory, Research, Practice, Training 41(2):112.
Viskochil, D.H. 2003. It takes two to tango: mast cell and Schwann cell interactions in neurofibromas. Journal of Clinical Investigation 112(12):1791 1792.
Weiner, A. 2001. It Takes Two to Tango:: Information, Metabolism, and the Origins of Life. Cell 105(3):307 308.
Wittman, M.L. 1990. It Takes Two to Tango: Your Simplistic System for Self-survival. Witmark Pub. Co.
There are also a few hundred groups who have demonstrated that larger groups can so as well.

25 September 2011

Christian Perrier: [life] [running] Berlin marathon: I ran in the world record race...

...but I didn't break it myself. Still, Patrick Makau broke today Haile Gebresselassie's world record by 21 seconds, lowering it down to 2h03'38". This is an impressive performance, considering the quite "high" temporature today in Berlain (about 23 C). My own race was quite good, though not perfect. My goal was targeting 3h36', to break my own record (3h40'24"). However, my preparation was complicated by an hurted ankle in early August, then a very shaky September month at work with a lot of stress and work days up to 12 hours. Not the best way to prepare a marathon. Last two weeks were fairly good wrt running, with an half-marathon run in 1h43' two weeks ago. Still, we complicated this by speding a few days to do sightseeing in Berlin (you can't really be in such a nice city and not try to see it!). So, that means a lot of walking here or there, with museum visits and quite long days. Again, not the best way to prepare a marathon..:-) Still, my watch was set on a 5'07"/km pace. My goal was starting like this, work to avoid going faster over the first 20K ad see what happens. At the beginning, it worked fairly well. Contrary to Paris marathon, Berlin's start in Strasse des 17. Juni is very cool for the first 3 kilometers with an incredibly wide avenue, whilst Paris marathon shrinks in Rue de Rivoli after km 1.5, making it fairly complicated to pass. Also, runners in Germany are much more respectful of running principles and very few register for starting blocks that are nont their real performance (like registering for 3h30 while your best time if 4h). So less passing and a much more costant pace. Up to km15 in Kreuzbeg, everything went well, though the heat was growing, which already made me suspect that I would not make it (0-5K in 25'31", 5-10K in 25'54", 10-15K in 25'55") . From this point, I had to "fight" a bit more to keep the pace...and a few streets without shade had their effect. Moreover, I already had to refill my belt bottle after drinking 0,8l for the first 17KM. The pace thus went down to about 5'10-5'15" and I reached half-marathon in 1h50'28", already not really on time for less than 3h40). 15-20K in 26'41", including a bottle refill. Then 20-25 in 25'44", so small drop after all. However, the wall hit me on km28. For the first time in my marathon life, I think I considered abandoning because I was feeling without any energy and still 1/3 of a marathon to run. Well, that was only the 30K wall which they apparently moved 2K earlier..:-) After calming myself down, I decided to do what has to be done in such case: refill with energy. So long for the gels I had and particularly the hyper-glucidic "Coup de Fouet". Finally, around KM30, I found more motivation to complete the race. Anyway, we were then very very far away, at the end of Hohenzollendamm, so the only option was to come back anyway! Despite all this, I kept a very decent pace, after all: 26'45" for 25-30K. Each kilometer, my watch was beeping to remind me that I was not crawling on the street but more keeping about 5'20". Still, the last kilometers on these giants avenues (oh, endless Leipziger Strasse after Postdamer Platz!) needed a lot of motivation to be completed. It's indeed only at Gendarmenmarkt that I finally could be reliefed and know that I would not only finish, but also do it in a very decent time. 30-35K in 27'43", 35-40K in 27'38". Then we turned in Unter den Linden and, even better, at KM41, my beloved Elizabeth was there yelling. This, plus Brandenburder Tor not so far away....I could then "sprint" at 5'08" for the last kilometer. Finally, this marathon (my 6th official) was completed in 3h44'50", which is my second best. I'm really happy with this result, finally. OK, I didn't break my record as I was intending to (I think I can go down to 3h35 with a normal preparation and good conditions), but the way I managed the difficulty was finally good. So, now, let's prepare the next goal, a 67km night race in November, the longest distance I have ever run. Yet another different thing to prepare. And what about Berlin in all this? Well, in short, that city is *great*. What could I tell more?

23 September 2011

Matthew Garrett: Supporting UEFI secure boot on Linux: the details

An obvious question is why Linux doesn't support UEFI secure booting. Let's ignore the issues of key distribution and the GPL and all of those things, and instead just focus on what would be required. There's two components - the signed binary and the authenticated variables.

The UEFI 2.3.1 spec describes the modification to the binary format required to produce a signed binary. It's not especially difficult - you add an extra entry to the image directory, generate a hash of the entire binary other than the checksum, the certificate directory entry and the signatures themselves, encrypt that hash with your key and embed the encrypted hash in the binary. The problem has been that there was a disagreement between Microsoft and Intel over whether this signature was supposed to include the PKCS header or not, and until earlier this week the only widely available developer firmware (Intel's) was incompatible with the only widely available signed OS (Microsoft's). There's further hilarity in that the specification lists six supported hash algorithms, but the implementations will only accept two. So pretty normal, really. Developing towards a poorly defined target is a pain. Now that there's more clarity we'll probably have a signing tool before too long.

Authenticated variables are the other part of the puzzle. If a variable requires authentication, the operating system's attempt to write it will fail unless the new data is appropriately signed. The key databases (white and blacklists) are examples of authenticated variables. The signing actually takes place in userspace, and the handoff between the kernel and firmware is identical for both this case and the unauthenticated case. The only problem in Linux's support here is that our EFI variable support was written to a pre-1.0 version of the EFI specification which stated that variables had a maximum size of 1024 bytes, and this limitation ended up exposed to userspace. So all we really need to do there is add a new interface to let arbitrary sized variables be written.

Summary: We don't really support secure boot right now, but that's ok because you can't buy any hardware that supports it yet. Adding support is probably about a week's worth of effort at most.

comment count unavailable comments

22 September 2011

Lucas Nussbaum: Windows dynamic disks and debian installer ?

Windows has a feature called Dynamic Disks, which makes it ignore the DOS partition table and manage partitions its own ways. gparted is supposed to detect that, and warn the user that it can t deal with that. The solution is to reboot in Windows, switch the partition back to Basic disks , and then proceed with installing Debian (or Ubuntu). However, a student of mine had an interesting experience because gparted did not detect the dynamic disk stuff and did not warn about it, so the student went ahead with installing Debian squeeze. After reboot in Windows, Windows sees the partition as invalid . The same happens with Ubuntu 11.04 (not really surprising). I m surprised I did not find much information about that issue. Does someone has more info ? The student was using two disks in his laptop, and only the second one (not the one used to boot windows) was using dynamic disks .

Next.

Previous.