Search Results: "xam"

11 September 2008

Russell Coker: Noise in Computer Rooms

Some people think that you can recognise a good restaurant by the presence of obscure dishes on the menu or having high prices. The reality is that there are two ways of quickly identifying a good restaurant, one is the Michelin Guide [1] (or a comparable guide - if such a thing exists), the other is how quiet the restaurant is. By a quiet restaurant I certainly don’t mean a restaurant with no customers (which may become very noisy once customers arrive). I mean a restaurant which when full will still be reasonably quiet. Making a restaurant quiet is not in itself a sufficient criteria to be a good restaurant - but it’s something that is usually done after the other criteria (such as hiring good staff and preparing a good menu) are met. The first thing to do to make a room quiet is to have good carpet. Floor boards are easy to clean and the ratio of investment to lifetime is very good (particularly for hard wood), but they reflect sound and the movement of chairs and feet makes noise. A thick carpet with a good underlay is necessary to absorb sound. Booths are also good for containing sound if the walls extend above head height. Decorations on the walls such as curtains and thick wallpaper also absorb sound. A quiet environment allows people to talk at a normal volume which improves the dining experience. It seems to me that the same benefits apply to server rooms and offices, with the benefit being more efficient work. I found it exciting when I first had my desk in a server room (surrounded by tens of millions of pounds worth of computer gear). But as I got older I found it less interesting to work in that type of environment just as I found it less interesting to have dinner in a noisy bar - and for the same reasons. For a server room there is no escaping the fact that it will be noisy. But if the noise can be minimised then it will allow better communication between the people who are there and less distraction which should result in higher quality of work - which matters if you want good uptime! One thing I have observed is that physically larger servers tend to make less noise per volume and per compute power. For example a 2RU server with four CPUs seems to always make less noise than two 1RU servers that each have two CPUs. I believe that this is because a fan with a larger diameter can operate at a lower rotational speed which results in less bearing noise and the larger fans also give less turbulence. While it’s obvious that using fewer servers via virtualisation has the potential to avoid noise (both directly through fans and disks and indirectly through the cooling system for the server room [2]). A less obvious way of reducing noise is to swap two 1RU servers for one 2RU server - although my experience is that for machines in a similar price band, a 2RU server often has comparable compute power (in terms of RAM and disk capacity) to three or four 1RU servers. To reduce noise both directly and indirectly it is a requirement to increase disk IO capacity (in terms of the number of random IOs per second) without increasing the number of spindles (disks). I just read an interesting Sun blog covering some concepts related to using Solid State Disks (SSDs) on ZFS for best performance [3]. It seems that using such techniques is one way of significantly increasing the IO capacity per server (and thus allowing more virtual servers on one physical machine) - it’s a pity that we currently don’t have access to ZFS or a similar filesystem for Linux servers (ZFS has license issues and the GPL alternatives are all in a beta state AFAIK). Another possibility that seems to have some potential is the use of NetApp Filers [4] for the main storage of virtual machines. A NetApp Filer gives a better ratio of IO requests per second to the number of spindles used than most storage array products due to the way they use NVRAM caching and their advanced filesystem features (which also incidentally gives some good options for backups and for detecting and correcting errors). So a set of 2RU servers that have the maximum amount of RAM installed and which use a NetApp Filer (or two if you want redundancy) for the storage with the greatest performance requirements should give the greatest density of virtual machines. Blade servers also have potential to reduce noise in the server room. The most significant way that they do this is by reducing the number of power supplies, instead of having one PSU per server (or two if you want redundancy) you might have three or five PSUs for a blade enclosure that has 8 or more blades. HP blade enclosures support shutting down some PSUs when the blades are idling and don’t need much power (I don’t know whether blade enclosures from other vendors do this - I expect that some do). A bigger problem however is the noise in offices where people work. It seems that the major responsible for this is the cheap cubicles that are used in most offices (and almost all computer companies). More expensive cubicles that are at almost head-height (for someone who is standing) and which have a cloth surface absorb sound better significantly improve the office environment, and separate offices are better still. One thing I would like to see is more use of shared desktop computers, it’s not difficult to set up a desktop machine with multiple video cards, so with appropriate software support (which is really difficult) you could have one desktop machine for two, or even four users which would save electricity and reduce noise. Better quality carpet on the floors would also be a good thing. While office carpet wears out fast adding some underlay would not increase the long-term cost (it can remain as the top layer gets replaced). Better windows in offices are necessary to provide a quiet working environment. The use of double-glazed windows with reflective plastic film significantly decreases the amount of heating and cooling that is required in the office. This would permit a lower speed of air flow for heating and cooling which means less noise. Also an office in a central city area will have a noise problem outside the building, again double (or even triple) glazed windows help a lot. Some people seem to believe that an operations room should have no obstacles (one ops room where I once worked had all desks facing a set of large screens that displayed network statistics and the desks were like school desks with no dividers), I think that even for an ops room there should be some effort made to reduce the ambient noise. If the room is generally reasonably quiet then it should be easy to shout the news of an outage so that everyone can hear it. Let’s assume for the sake of discussion that a quieter working environment can increase productivity by 5% (I think this is a conservative assumption). For an office full of skilled people who are doing computer work the average salary may be about $70,000, and it’s widely regarded that to factor in the management costs etc you should double the salary - so the average cost of an employee would be about $140,000. If there are 50 people in the office then the work of those employees has a cost of $7,000,000 per annum. A 5% increase in that would be worth $350,000 per annum - you could buy a lot of windows for that!

Russell Coker: Islamophobia

I recently wasted a bit of time reading some right-wing blogs. One thing I noted was the repeated references to news reports about young women from an Islamic background being beaten (and in some cases killed) by their fathers (and other male relatives) for not conforming to some weird cultural ideas that some people associate with Islam. These are spun as examples of Islam being bad and therefore opposing immigration policies that allow Muslims into countries identified as “Christendom” or “The West” (never mind the fact that the vast majority of the population in “Christendom” don’t even attend church twice a year and the fact that Australia is directly south of China, Russia, and North Korea). It seems to me that when young people follow the cultural standards of the country where they live rather than the standards of the country that their parents came from then it’s evidence of “multiculturalism” working. When young Muslim women are beaten by their fathers whether it’s considered an example of Muslims being bad (and who therefore should be excluded) or an example of Muslims as victims who should be protected is a matter of interpretation. It’s not as if there is any shortage of domestic violence cases from any religious or cultural group. It’s often claimed that fundamentalist Muslims hate our culture, strangely the same people seem to claim that our culture will be destroyed by radical Islam. These two ideas seem to conflict, if our culture (the pro-science, free-speech, few inhibitions on clothing standards, do what you want but don’t hurt others culture that most readers of my blog enjoy) can be destroyed by radical Islam then they wouldn’t hate it. I think that the reason why fundamentalist religious people (Christians and Muslims) dislike our culture is because it is so strong. Our culture offers a way of life that is simply better than that which fundamentalist religious groups offer. Any religious person can choose to take a liberal approach to their religion (emphasising the positive aspects of giving to charity, being nice to others, etc) and enjoy our culture. Our culture is based around wide-spread communication, mass media, mobile phones, the Internet, custom clothing design, etc. It can do to religions what the sea does to rocks. It seems that the strongest efforts at attacking our culture come from Christian groups. For example the Exclusive Bretheren [1] runs a high school in my area, according to a local paper it distinguishes itself by having no students enter a university course! The Exclusive Bretheren (and some other radical Christian groups) have a deliberate policy of keeping children stupid with the idea that people who think may decide to change their religion. Some time ago I had a taxi driver start an unsolicited discussion of religion by telling me how much he hated Muslims. I pointed out the fact that there are Muslims of all races and asked why he thought that I was not a Muslim. After that the rest of the journey was very quiet. The mainstream media would have us believe that Muslims have some sort of monopoly on terrorism. Noam Chomsky’s paper “Terror and Just Response” [2] is one of many that he has written on this issue. I realise that many people don’t want to acknowledge the involvement of the US government (and it’s allies such as Australia) in international terrorism. But please read Noam’s position (which is compelling) or read his wikipedia page which lists his extensive accomplishments [3] (if it’s the background of an author that impresses you).

10 September 2008

Russell Coker: Execmod and SE Linux - i386 Must Die

I have previously written about the execmod permission check in SE Linux [1] and in a post about SE Linux on the desktop I linked to some bug reports about it [2] (which probably won’t be fixed in Debian). One thing I didn’t mention is the proof of the implication of this. When running a program in the unconfined_t domain on a SE Linux system (the domain for login sessions on a default configuration), if you set the boolean allow_execmod then the following four tests from paxtest will be listed as vulnerable: Executable bss (mprotect)
Executable data (mprotect)
Executable shared library bss (mprotect)
Executable shared library data (mprotect) This means that if you have a single shared object which uses text relocations and therefore needs the execmod permission then the range of possible vectors for attack against bugs in the application has just increased by four. This doesn’t necessarily require that the library in question is actually being used either! If a program is linked against many shared objects that it might use, then even if it is not going to ever use the library in question it will still need execmod access to start and thus give extra possibilities to the attacker. For reference when comparing a Debian system that doesn’t run SE Linux (or has SE Linux in permissive mode) to a SE Linux system with execmod enabled the following tests fail (are reported as vulnerable): Executable anonymous mapping (mprotect)
Executable heap (mprotect)
Executable stack (mprotect)
Writable text segments If you set the booleans allow_execstack and allow_execheap then you lose those protections. But if you use the default settings of all three booleans then a program running in the unconfined_t domain will be protected against 8 different memory based attacks. Based on discussions with other programmers I get the impression that fixing all the execmod issues on i386 is not going to be possible. The desire for a 15% performance boost (the expected result of using an extra register) is greater than the desire for secure systems among the people who matter most (the developers). Of course we could solve some of these issues by using statically linked programs and have statically linked versions of the libraries in question which can use the extra register without any issues. This does of course mean that updates to the libraries (including security updates) will require rebuilding the statically linked applications in question - if a rebuild was missed then this could be reduce the security of the system. To totally resolve that issue we need to have i386 machines (the cause of the problem due to their lack of registers) go away. Fortunately in the mainstream server, desktop, and laptop markets that is already pretty much done. I’m still running a bunch of P3 servers (and I know many other people who have similar servers), but they are not used for tasks that involve running programs that are partially written in assembly code (mplayer etc). One problem is that there are still new machines being released with the i386 ISA as the only instruction set. For example the AMD Geode CPU [2] is used by the One Laptop Per Child (OLPC) project [3] and the new Intel Atom line of CPUs [4] apparently only supports the AMD64 ISA on the “desktop” models and the versions used in ultra-mobile PCs are i386 only. I think that these issues are particularly difficult in regard to the OLPC. It’s usually not difficult to run “yum upgrade” or “apt-get dist-upgrade” on an EeePC or similar ultra-mobile PC. But getting an OLPC machine upgraded in some of the remote places where they may be deployed might be more difficult. Past experience has shown that viruses and trojans can get to machines that are supposed to be on isolated networks, so it seems that malware can get access to machines that can not communicate with servers that contain security patches… One mitigating factor however is that the OLPC OS is based on Fedora, and Fedora seems to be taking the strongest efforts to improve security of any mainstream distribution, a choice between 15% performance and security seems to be a no-brainer for the Fedora developers.

Russell Coker: Efficiency of Cooling Servers

One thing I had wondered was why home air-conditioning systems are more efficient than air-conditioning systems for server rooms. I received some advice on this matter from the manager of a small server room (which houses about 30 racks of very powerful and power hungry servers). The first issue is terminology, the efficiency of a “chiller” is regarded as the number of Watts of heat energy removed divided by the number of Watts of electricity consumed by the chiller. For example when using a 200% efficient air cooling plant, a 100W light bulb is rated as being a 150W heat source. 100W to Heat it, 50W from the cooling plant to cool it. For domestic cooling I believe that 300% is fairly common for modern “split systems” (it’s the specifications for the air-conditioning on my house and the other air-conditioners on display had similar ratings). For high-density server rooms with free air cooling I have been told that a typical efficiency range is between 80% and 110%! So it’s possible to use MORE electricity on cooling than on running the servers! One difficulty in cooling a server room is that the air often can’t flow freely (unlike a big open space such as the lounge room of your house). Another is the range of temperatures and the density of heat production in some parts (a 2RU server can dissipate 1000W of heat in a small space). These factors can be minimised by extracting hot air at the top and/or rear of racks and forcing cold air in the bottom and/or the front and by being very careful when planning where to place equipment. HP offers some services related to designing a server room to increase cooling efficiency, one of the services is using computational fluid dynamics to simulate the air-flow in the server-room [1]! CFD is difficult and expensive (the complete package from HP for a small server room costs more than some new cars), I believe that the fact that it is necessary for correct operation of some server rooms is an indication of the difficulty of the problem. The most effective ways of cooling servers involve tight coupling of chillers and servers. This often means using chilled water or another liquid to extract the heat. Chilled water refrigeration systems largely remove the problem of being unable to extract the heat from the right places, but instead you have some inefficiency in pumping the water and the servers are fixed in place. I have not seen or heard of chilled water being used for 2RU servers (I’m not saying that it doesn’t get used or that it wouldn’t make sense - merely that I haven’t seen it). When installing smaller servers (2RU and below) there is often a desire to move them and attaching a chilled-water cooling system would make such a move more difficult and expensive. When a server weighs a ton or more then you aren’t going to move it in a hurry (big servers have to be mostly disassembled before the shell can be moved, and the shell might require the efforts of four men to move it). Another issue related to water cooling is the weight. Managing a moderate amount of water involves a lot of heavy pipes (a leak would be really bad) and the water itself can weigh a lot. A server room that is based around 20Kg servers might have some issues with the extra weight of water cooling (particularly the older rooms), but a server room designed for a single rack that weighs a ton can probably cope. I have been told that the cooling systems for low density server rooms are typically as efficient as those used for houses, and may even be more efficient. I expect that when designing an air-conditioner the engineering trade-offs when designing for home use favor low purchase price. But someone who approves the purchase of an industrial cooling system will be more concerned about the overall cost of operations and will be prepared to spend some extra money up-front and recover it over the course of a few years. The fact that server rooms run 24*7 also gives more opportunity to recover the money spent on the purchase (my home A-C system runs for about 3 months a year for considerably less than 24 hours a day). So it seems that the way to cool servers efficiently is to have low density server rooms (to the largest extent possible). One step towards this goal would be to have servers nearer the end users. For example having workgroup servers near the workgroup (instead of in the server room). Of course physical security of those servers would be more challenging - but if all the users have regular desktop PCs that can be easily 0wned then having the server for them in the same room probably doesn’t make things any worse. Modern tower servers are more powerful than rack mounted servers that were available a few years ago while also being very quiet. A typical rack-mounted server is not something you would want near your desk, but one of the quiet tower servers works quite well.

Erich Schubert: A few words on my job and research

As some might know, I've been working at the university for a few weeks now. I'm very happy how it all worked out, because of the people there and the subjects to work on. It's just great to think through some mind-bending index structure to improve reverse-k-nearest-neighbor queries. And the professor (who is very well known for his work on R*-Trees, the X-Tree, and the DBSCAN and OPTICS algorithms) really manages to aggregate excellent people.(rkNN is the problem of finding those points for which a Nearest Neighbor Search [Wikipedia] would return the given point. There are many use cases for example in location based services.)A lot of my work involves a framework which has been published recently on the SSDBM 2008 conference: ELKI - Environment for DeveLoping KDD-Applications Supported by Index-StructuresThe goal of ELKI is to become what WEKA is for machine learning. And it's well on it's way for that.ELKI aims at the data mining researcher, it's not designed to squeeze out the last bit of performance. Instead it allows you to compare different algorithms, try different index structures (including various spatial and metrical trees) and offers all kinds of functionality you can reuse. If you are planning to do some real world applications, it likely is still useful for prototyping.In the last weeks I've already put quite some effort in ELKI, so expect the next version to be released with significant changes and new functionality. In fact some working functionality was just left out of the release because we hadn't cleaned up the code yet.Currently, getting started with ELKI can be a bit tricky. It's not hard to use, but you just need to find out where to start. The next release will therefore include a "dummy algorithm" that mostly serves as being a template for implementing custom algorithms (it can also be used for benchmarking an index structure, though).

9 September 2008

Christian Perrier: Good day for D-I l10n

Three days after I posted my last blog entry about it, a great progress was made about translation completeness for D-I. We jumped from 34 languages meeting the release criteria up to 41. Shaking out translators seems to be efficient even though t requires a big investment in time. So, welcome back to Spanish, Indonesian, Georgian, Hebrew, Khmer, Nepali, Simplified Chinese. There are still uncertainties for: Amharic, Bengali, Bosnian, Catalan, Danish, Greek, Esperanto, Estonian, Hungarian, Kurdish, Latvian, Macedonian, Norwegian Nynorsk, Northern Sami, Slovenian, Albanian, Tagalog, Ukrainian, Wolof Several of these have *very few missing strings* (as a matter of example, Catalan is only missing the strings....that warn users that the translation might be incomplete...interesting chicken-and-egg situation which could be easily solved by completing 5 miserable strings). 12 days left (the end of the translation update round is on Saturday 20th midnight UTC)....hurry!

Biella Coleman: STDIN, My Hacker Class Blog

So, I am pleased to announce that my course on hackers, which has already started, will be hosting a class blog, STDIN. Starting next class when we address phone phreaking, we will have one entry summarizing in some details each class readings and discussions. There is one student in charge for every class and then anyone else can post as they wish. I am also making an effort to post various definitions and examples of hackers, hacking, hacks and compile a master list at the end. I am not sure it will produce anything interesting except a list of definitions, but sometimes you see new associations and meanings when with such a comparative potpourri.

Biella Coleman: STDIN, My Hacker Class Blog

So, I am pleased to announce that my course on hackers, which has already started, will be hosting a class blog, STDIN. Starting next class when we address phone phreaking, we will have one entry summarizing in some details each class readings and discussions. There is one student in charge for every class and then anyone else can post as they wish. I am also making an effort to post various definitions and examples of hackers, hacking, hacks and compile a master list at the end. I am not sure it will produce anything interesting except a list of definitions, but sometimes you see new associations and meanings when with such a comparative potpourri.

Erich Schubert: Increasing your privacy

Many people are already aware of the amount of data Google can (and does) collect on them. Some people therefore refuse to use certain google applications altogether. Others just like them too much.There are some services that won't work with heavy ad blocking and anonymizing services - others will work just fine. A prime example everybody uses is Google search.Google search will work just fine if you use anonymizers. Google Mail won't.Privoxy and TOR is a great combination for anonymizing, however you won't want to use them for bandwidth-heavy web surfing, and there is little benefit of using them for web sites where you authenticate anyway.Here's a way to do a compromise:
  1. Install and configure Privoxy and TOR. Make sure they work.
  2. Setup a proxy.pac file (proxy autoconfiguration) for your browser like this:
    function FindProxyForURL(url, host)  
        var google = /https?:\/\/([^/]*\.)?google\.[a-z]*($ \/)/;
        var tor = /https?:\/\/([^/]*)\.(exit onion)($ \/)/;
        if (google.test(url))  
            if (shExpMatch(url, "*.google.com/mail*"))  
                return "DIRECT";
             
            return "PROXY 127.0.0.1:8118";
         
        if (tor.test(url))  
            return "PROXY 127.0.0.1:8118";
         
        if (shExpMatch(host, "config.privoxy.org"))  
            return "PROXY 127.0.0.1:8118";
         
        return "DIRECT";
     
    
    and point your browser to it.
  3. Add the following to your privoxy/user.action file:
      +client-header-filter hide-tor-exit-notation   
    .exit
      +filter js-events  +crunch-all-cookies  
    .google./(search blogsearch scholar images)
    
    And don't forget to reload privoxy.
You should now be able to access Google search with enhanced privacy (I can't guarantee you they won't be able to track you though!) while at the same time you can access your Gmail account at full speed.When using Google Search (including image, blog and scholar search, feel free to add additional services) you should be seeing a login button, while you could be accessing Google Mail at the same time in another tab.This list is of course not exhaustive. You might want to actually use privoxy and TOR by default, and only disable it for certain sites (or configure privoxy accordingly). You get the idea: this is just a very minimal approach to disable tracking exactly by the Google search site. It all depends on how serious you are about privacy and how important data throughput is for you.Also it will allow you to access certain TOR functionality (such as hidden services) without running TOR all the time (after all, it is and will always be slower than direct access).[Update: apparently some TOR exit nodes trigger a spam protection on Google, and without cookies you can't solve the captcha. So the use of TOR doesn't work well with Google. All the privoxy cookie blocking however is still recommended.]

7 September 2008

Michal Čihař: More fun with phpMyAdmin package in Debian

When finishing series of articles about Debian packaging and writing about dbconfig-common, I just had to ask myself, why it is not used in phpMyAdmin package. I did not find any reason and as Thijs did not have any objections, I hacked it together this evening. So what you will get? All fancy features where phpMyAdmin requires it's database to manage some additional features. For example you can create PDF pages with structure of your database, add additional comments to databases, notice relations between MyISAM tables, etc. Simply see wiki for more details. Besides this, phpMyAdmin is now automatically configured to use database you choose using dbconfig-common, so you can also connect to remote MySQL server without manually configuring anything. The only thing which scares me a bit is that we now increased a lot number of debconf questions user has to reply by this...

6 September 2008

Benjamin Mako Hill: Happy Birthday GNU

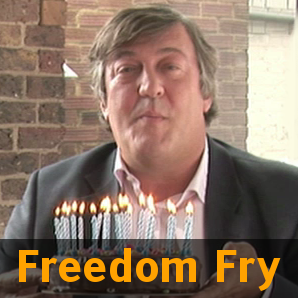
Nearly a week after its release, I suspect most of my audience has seen the FSF's Freedom Fry video of Stephen Fry wishing the GNU project and the free software movement a happy birthday. While I'm not usually one for birthdays, I thought I'd at least reflect on it briefly. Certainly, it's a wonderful video -- for which Matt Lee at others at the FSF should be proud. But it's fact that the GNU project is now twenty-five years old that is truly noteworthy. /copyrighteous/images/freedom_fry.png Wikipedia says that a generation (i.e., the average interval between the birth of parents and of their offspring) is somewhere between 25-30 years in most of the Western world. Twenty-five years isn't just a big number divisible by five, it marks a generational shift. Certainly, GNU has matured and accomplished wonderful things in last quarter-century. More importantly perhaps, it's produced wonderful progeny. It has spawned hundreds of thousands of free software projects, thousands of free or nearly-free operating systems, and an unbelievably vibrant global free and open source software community. Beyond the software realm, the free culture movement, most free licensing projects, and much of the access to knowledge movement can trace a connection back to GNU. We are living, and building, a new generation of the free software movement. It's not been an entirely smooth ride, feelings have been hurt, and it's hard for GNU's proponents -- myself included -- to not wince at some of what has been done in GNU's name and because of its example. But even cynics must admit: the world is an undeniably better place because of GNU and the efforts and ideas that it has motivated. I turn 28 in December and have spent my entire computing life in world where free software was a viable option and an active form of resistance. Here's to another generation! May we be half as productive and positive as the last!
5 September 2008

Gunnar Wolf: Awesome!

For about eight years, I was a very happy WindowMaker user. It was very lightweight, aesthetically pleasing, and I had interiorized its behaviour and keybindings so much, I didn't feel I'd ever switch away. I periodically tried (forced myself even!) to use any of the other, more en vogue environments... Experimented using Gnome for a week, KDE for a week, XFCE for a week (so I would have enough time to learn their ways)... And always came back to my good, well-known wmaker.
In 2006, when we held DebConf6 in Mexico, I saw how other people worked with ion3. I fell immediately in love with it. Not because it is prettier, snappier or has nicer widgets than other window managers - but because it is enormously more usable. Quoting Tuomo Valkonen, the ion3 author,
Ion is not perfect and certainly not for everyone, but neither is any user interface. Usability is subjective.
Using a keyboard-oriented, tiling window manager represented -for the first time in 20 years (I had my first contact with a Macintosh in 1986)- a radical user interface change. For my way of working, I just don't need a desktop, I don't need having a background space or overlapping windows. What I need is a way to functionally organize the windows I have open at any given time, quickly switch between them (and not depending on the mouse, please!), maximizing screen space and all that. ion3 was godsent.
Now, in 2007 there was (yet another) huge flamefest. Valkonen basically does not want distributors distributing any version of ion3 that's not the latest, and introducing changes not approved by him - He basically demands ion to be non-free. So, it was moved to the non-free section of Debian where only Womble decided to keep giving it support. And, of course, by September 2007 Julien Danjou announced he had written another window manager: Awesome.
My main motivation for switching away from ion3 is that... I don't want to use non-free software. But I was very comfortable with ion3. It was only after I saw many other people using Awesome at DebConf8 I decided to bite the bullet and switch. It looked at least as comfortable as ion3.
But... Well, I cannot come up with better phrasing than what Joey said when he switched to Awesome, almost exactly a month ago. When changing between the mainstream window managers, the differences are mostly cosmetic. But with these really different window managers... I cannot but reproduce Joey's words:
I wish I had a good analogy to explain to my nontechnical readers what changing to a new window manager is about.
One way to think about it is that it's like driving a car down the road, and suddenly swapping the steering wheel and brakes out for a tiller and gear shifter. And having to downshift for braking until you learn that the brakes moved to the turn indicator lever. By trial and error.
But that's really only part of it. Another way to look at it is adopting a new philosophy. Or, in some cases a cult. (In some cases, with crazy cult leaders.) Whether they use Windows or a Mac, or Linux, most computer users are members of a big established religion, with some implicit assumptions, like "thy windows shall be overlapping, like papers on the desktop, and thou shalt move them with thy mouse".
So, changing to a new window manager is a process of being dumped into a different environment, where nothing works like you've come to expect, and trying to construct a mental model that you can use to make sense of it. But it's also a process of modifying that environment to behave the way you like.
And when done whole-heartedly, this doesn't just mean trying to make it like the environment you were used to before. It means trying to absorb the underlying philosopy of the window manager, and think up new ways of doing things, inspired by that philosopy, and modify the environment to allow doing those things.
So ideally, "I switched to a new window manager" doesn't mean "my screen has some different widgets on it now". It means "I'm looking at the screen with new eyes."
So, what's so different?
Besides learning some new keybindings (expected, of course), Awesome has several suggested layouts to help you organize your workflow, usually (although not always) consisting of a main area and a side area, tiled side by side (or one above the other, or several stranger ways). This sounds rigid, but it is incredibly comfortable - and I've only been an Awesome user for three days!
But what sets Awesome apart from basically anything else is the concept of tags. Whey you see an Awesome session, you recognize something similar to the very well known workspaces concept we have had in any Unix-like environment for many years, right? Well, but they are not workspaces. They are tags. What is the difference?
When I work with workspace, each of my windows can be in a different workspace. So in one, I'll have my mail-related stuff. In another one, I might be browsing. In another one, I have my development things, and I might be following some logfiles in yet another one.
Awesome allows you to use tags for categorization in much a more flexible way.
For example: I am mostly a web-oriented developer. I usually need four things when developing a system: A browser, Emacs, the log for my development server, and a console where I can peek and poke at my objects and interactions. Of course, cramming them all into the same screen makes no sense - It would be better to follow the good ol' desktop metaphore, and just switch the focus and raise the window, right?
In Awesome, I can have them all set to the maximum screen size - _and_ use the most common combinations as well. Each of the windows can be tagged to more than one workspace (and yes, this is immensely more flexible than the always visible hint on traditional WMs).
To begin with, I'll give each major process a tag to itself, to work full-screen. Emacs is on tag 1, my browser on tag 2. The log and the console share a terminal (i.e. via screen or terminator).
This console by itself is not too useful, so I'll set it to tag 4, and we will go back to it later.
So if I'm building a view or following online documentation, I will add tag 3 to both Emacs and the browser.
I'm also setting tag 4 to the browser - That allows me to use it next to my terminal, following the results of my website-clicking.
And, of course, tag 5 will be set to Emacs and to the console, so I can quickly check any quick API-related question that does not need the documentation or look at a newly written method.
By the way, have you noticed CapsLock is the most stupid key invented, ever? Ok, I gave a good use to it: It's called Mod4. Imagine it is just an extra Ctrl, Alt or Meta key.
So, Mod4-1 gives me Emacs. Mod4-2 gives me the browser. Mod4-3 gives Emacs+browser, Mod4-4 gives browser+console, and Mod4-5 gives Emacs+console. And, of course, the handy Mod4-0 gives me all of my open windows tiled side by side.
Even this is a pattern of being a newbie, I know - I could keep 4 and 5 free, and just tag several simultaneous tags to be active. How? Switch to tag 1 exclusively (Mod4-1), and activate tag2 as well (Ctrl-Mod4-2). There, I have Emacs and browser side by side. Want to get the console instead of the browser? Simple. Ctrl-Mod4-2 (toggle off tag 2), Ctrl-Mod4-3 (toggle on tag 3).
Anyway - As you can see, I am excited at finding a very new and nice tool to help me work better. Today I was playing a bit with the Awesome widgets, but that's something to be talked about later.
In Debian, we are at a crossing point: Awesome is just reaching ion3's popularity. And I'm adding my two main machines' votes to Awesome.
This is Awesome. Quoting (yes, one last quote) the official Awesome site, This gonna be LEGEN... wait for it... DARY!.

Nico Golde: Google chrome code reuse nightmare

While some people think that Googles new open source webbrowser Chrome is a great example of code reuse I think the opposite is true. He found at least 25 open source libraries used by the browser. So far this is not a problem but what is a problem is that it embeds all of them in the upstream source tarball instead of depending on the system-wide copies. I know that it might be problematic if people have to install 25 libraries on their own (they could provide static builds though) but for distributors this is just a nightmare if security issues pop-up in one of the used libraries (famous libraries who had issues in the past: webkit, libpng, libjpeg, libxml, ...).

In this case the distributors can't just fix the security issue in the shared library and all applications using it are fixed, no they also have to fix all the copies in software like Chrome. Same if you installed Chrome from source, if a security issue pops out in one of the embedded libs you have to go and install a new Chrome version. Google also needs to additionally maintain upstream and security fixes in their embedded code copies but I guess they have enough manpower to do so.

I didn't yet look at the Chrome source code but I hope it has at least a way to link against the system-wide copies without patching the makefiles.

4 September 2008

John Goerzen: Political Thoughts

It may come as no surprise to some of you that I actually enjoy -- yes, enjoy -- watching political conventions. I've spent some time watching them over the past two weeks.

McCain has yet to speak tonight as I write this, but I've got to get out a few comments.

First of all, both parties of course were attacking the presidential candidate of the other. But did you notice a key difference? The Democrats attacked McCain on policy, while the McCain people attacked Obama on biography. VP nominee Palin even went so far as to mock Obama's work 20 years ago as a community organizer. I think that is incredibly telling. It seems to me to indicate that the Republicans know that their policies aren't working, and are grasping at straws to find something else. There is plenty in McCain's biography that the Democrats could go after -- his involvement in one of the worst scandals in the Senate, for instance -- but they aren't.

What about the other difference? Hope vs. fear. Obama's speech last week was truly inspiring. I don't think I've ever been inspired by a politician before. Make no mistake about it, he set the bar for himself incredibly high. I don't think anybody since Kennedy has done that. Obama realizes that there are things we must do as a country, and he also emphasized that the "ask not what your country can do for you" theme. Watching Giulianni and Palin was an exercise in fear-mongering. It's a constant stream of "9/11 MUSLIM OIL SHORTAGE TERRORISM NUCLEAR BIN LADEN IRAN GAS PRICES RED ALERT PANIC PANIC PANIC MEXICANS 9/11 9/11 9/11 SCARY WAR WAR WAR." It's as if they have discovered M-x spook RET in Emacs.

The Democrats, on the other hand, are talking about reducing health care costs, making sure everyone is covered, ending war, making the economy better for working-class people. It's an interesting disconnect that Obama highlighted well: McCain has said that the American economy has done well over the past 8 years. And indeed, by some "traditional" measures, such as productivity or GDP, it has. But the vast majority of Americans are not better off today than they were 8 years ago. Obama argues that the way McCain measures economic success is way off; our economy is not doing well if the vast majority of regular Americans are not doing well.

Also telling was how both candidates promised to reach across party lines (Bush promised that too). One actually is working to do it. Take abortion, for example. Obama said that he doesn't agree with the pro-lifers, but surely everyone can agree that providing better funding and support for alternatives to abortion such that it becomes incredibly rare is a good thing. Where's McCain looking for common ground? And then, of course, we have Palin wanting her family to be off limits -- but only when it's convenient to her.

I've voted in the past, but usually as a vote against someone rather than a vote for someone. This year, I'll make a single vote and do both.

Kapil Paranjape: Happy Birthday to GNU

The FSF is celebrating the birth of the idea that is GNU. There is a video which I have mirrored here for local users. So I plan to sing "Happy Birthday to GNU" on 27th September 2008 as well. It seems like some people are not quite so happy. One correspondent wrote that it was not the 25th birthday of the "GNU Operating System" since that would mean the GNU+HURD which he feels is still not ready. In my opinion the term "GNU Operating System" represents in loose terms "a free alternative to Unix" (free as in mukta). And that idea was born 25 years ago.2 I think that the HURD was just the "concept of a notion of an idea" 25 years ago. (The first article about the HURD was on the net about 1990 or so). Moreover, in comparison with Unix of 25 years ago, the GNU+HURD combination could be considered "ready". Thus, there is indeed much to celebrate. For example,
  1. There is not one --- there are many free alternatives to Unix. In fact, there are perhaps no non-free Unixes visible anymore! Does this owe a lot to the resolution made by RMS 25 years ago? Absolutely. Of course, it also owes a lot to the resolve of the hackers who followed up on this and took it well beyond what he had in mind.
  2. One can run the GNU tools + HURD combination to get an environment as good or better than what was available as Unix 25 years ago. Does a general member of the public really need to do this? No. There are currently a number of far superior solutions. Does the software community need this? Yes. (See below.)
I think that there are a lot of people who disagree with RMS and FSF today on a number of issues --- and these detractors may even be right. Perhaps this makes some people begrudge FSF celebrating the 25th anniversary/birthday of GNU. I offer the following points for their consideration:
  1. The vision and resolve RMS and the FSF put behind the vision --- starting 25 years ago --- have got us here.
  2. The FSF's astuteness in getting a rather well-known person like Stephen Fry 1 to celebrate GNU. If any of the distros had managed it, it would have been considered a coup!
  3. While Linux may be the dominant player in Unix today, the alternatives like *BSD, Solaris and even the HURD have an important role to play in the development of free software.
  4. That chocolate cake looks really delicious. :-)
So here's to (at least) another 25 years for GNU!

  1. Perhaps most famous in his roles as Jeeves and as the voice of the Hitchhiker's guide to the Galaxy).
  2. Of course, the practical-minded people may disagree and say we should celebrate "things" and not "ideas". Like it or not, the FSF has always valued the latter over the former.

Martin Michlmayr: The European Open Source Observatory and Repository (OSOR)

I attended the Open Nordic Conference in Norway in June, a conference that brought together people from Norway, Sweden, Finland and Denmark. Attending the conference allowed me to find out what's going on with FOSS in Northern Europe. What I found interesting is that there was a lot of talk about using FOSS in the public sector. A number of countries are working on repositories to exchange software, in particular for public administration. One example is the Software Exchange (softwareborsen.dk), a project by the Danish National Software Knowledge Centre to promote the use of FOSS in Danish public administration. The Norwegian software exchange (delingsbazaren.no) plays a similar role in Norway. It seems as if every country is working on their own software repository to share FOSS. As such, it's great to see that the European Commission is taking a step towards bringing everyone together by introducing the Open Source Observatory and Repository (OSOR) for European public administrations. The goal of OSOR is to provide a platform for the exchange of information, experiences and FOSS code for the use in public administrations. OSOR will officially launch at the Open Source World Conference in Malaga in October. I've always thought that there is not enough cooperation and communication between European countries, so I have high hopes for OSOR. (Originally published on FOSSBazaar)

31 August 2008

Biella Coleman: The making of

One of my favorite things to watch are the “making of [movie, documentary etc] segments that are now routinely included in any DVD. It is nice to look behind the curtain and see exactly what choices are made, what is excluded, and why they are made. I wish that more books, especially academic ones, had a “making of” section, giving a window into these choices. We are not exactly encouraged to include this commentary in the book itself but one can find this type of insight in author interview. I recently read one such interview with the author of Two Bits: The Cultural Significance of Free Software. The interview is on his site and the original is here. There are a couple of things that I found particularly interesting, such as how to treat iconic figures such as RMS and ESR [not as researchers, for example :-) ] and the importance of letting your research and thinking brew over a fairly long period of time, despite the pressure of publishing fast, quick and dirty, which is especially strong with anything “digital.” The book is hefty and long, but as is emphasized in the interview, it is also pragmatic and readable. If folks on Planet have not yet checked it out and are not ready to commit to a long book, I would checkout Chapter 6 on the creation of the copyleft. It is sure to please academics and geeks alike.

Steve Kemp: There can be only one

When volume becomes high enough you start to observe patterns in SPAM pretty easily. I think that this is primarily because people like to see patterns, whether they are present or not. The trick is determining whether they are real patterns or not, and then to a lesser extent whether they are useful patterns. For example I host mail for a business domain. That means that incoming messages come primarily from existing customers, and very rarely from potential new ones. In practise that means that email is expected to arrive from 9am til 6pm (+/-2hours) Email received at 2AM? Either it is somebody working remotely, a foreign contact, or much more likely it is SPAM. Now clearly you cannot dump all messages received at unusual times of the day, but it is a surprisingly robust SPAM indicator for that particular domain. All heuristics are fallable, but some are useful regardless.. I'd love to know what people can learn from their SPAM. This week I'm handling approximately 80,000 messages a day, per MX, which isn't huge (ie. 2-3 million a month). ObQuote: Highlander

30 August 2008

Mark Brown: Apple Mail and format=flowed

There’s one thing that the Apple Mail client gets right which I’ve never seen anything else try to do - the way it formats messages. Most mail clients seem to offer plain text and HTML as user selectable options and do exactly what they’re told regardless of the content of the message. If HTML is enabled they always send a mail with both text/plain and text/html renditions of the message. Normally the plain text version is a fixed, 80 column version. This is wasteful of bandwidth, especially since very few users actually use any formatting at all, and means that mail programs that don’t do HTML have to treat the mails as though the fixed layout the sending system chooses is important even when it results in poor layout (for example, on mobile devices with small screens). What Apple Mail does here is to only enable the more complex formatting options if they add information that can’t be represented in the less complex formats. By default mails are sent in text/plain with the format=flowed option to let the reader know it can safely reflow the text and no HTML alternative is generated. If something that can’t be represented using format=flowed is included in the message then a HTML alternative is generated - transparently and without user intervention. This is good partly because it’s nice to see format=flowed used, it’s a nice technical solution to the problem, but mostly because it’s great user interface design. Most Apple Mail users will never notice if it is or isn’t generating HTML e-mail, they’ll just see that it’s doing what they expect and won’t have to deal with an option that they probably don’t understand or have much of a view on. Other users won’t be troubled with HTML generated by Apple Mail users unless there is some content in the formatting. It’d be good to see more MUAs implementing similar behavior, at least optionally.

Russell Coker: Improving Blog Latency to Benefit Readers

I just read an interesting post about latency and how it affects web sites [1]. The post has some good ideas but unfortunately mixed information on some esoteric technologies such as infiniband that are not generally applicable with material that is of wide use (such as ping times). The post starts by describing the latency requirements of Amazon and stock broking companies. It’s obvious that stock brokers have a great desire to reduce latency, it’s also not surprising that Google and Amazon analyse the statistics of their operations and make changes to increase their results by a few percent. But it seems to be a widely held belief that personal web sites are exempt from such requirements. The purpose of creating content on a web site is to have people read it, if you can get an increase in traffic of a few percent by having a faster site and if those readers refer others then it seems likely to have the potential to significantly improve the result. Note that an increase in readership through a better experience is likely to be exponential, and an exponential increase of a few percent a year will eventually add up (an increase of 4% a year will double the traffic in 18 years). I have been considering hosting my blog somewhere else for a while. My blog is currently doing about 3G of traffic a month which averages out to just over 1KB/s, peaks will of course be a lot greater than that and the 512Kb/s of the Internet connection would probably be a limit even if it wasn’t for the other sites onn the same link. The link in question is being used for serving about 8G of web data per month and there is some mail server use which also takes bandwidth. So performance is often unpleasantly slow. For a small site such as mine the most relevant issues seem to be based around available bandwidth, swap space use (or the lack therof), disk IO (for when things don’t fit in cache) and available CPU power exceeding the requirements. For hosting in Australia (as I do right now) bandwidth is a problem. Internet connectivity is not cheap in any way and bandwidth is always limited. Also the latency of connections from Australia to other parts of the world often is not as good as desired (especially if using cheap hosting as I currently do). According to Webalizer only 3.14% of the people who access my blog are from Australia, they will get better access to my site if hosted in Australia, and maybe the 0.15% of people who access my blog from New Zealand will also benefit from the locality of sites hosted in Australia. But the 37% of readers who are described as “US Commercial” (presumably .com) and the 6% described as “United States” (presumably .us) will benefit from US hosting, as will most of the 30% who are described as “Network” (.net I guess). For getting good network bandwidth it seems that the best option is to choose what seems to be the best ISP in the US that I can afford, where determining what is “best” is largely based on rumour. One of the comments on my post about virtual servers and swap space [2] suggested just not using swap and referenced the Amazon EC2 (Elastic Computing) cloud service and the Gandi.net hosting (which is in limited beta and not generally available). The Amazon EC2 clound service [3] has a minimum offering of 1.7G of RAM, 1EC2 Compute Unit (equivalent to a 1.0-1.2GHz 2007 Opteron or 2007 Xeon processor), 160G of “instance storage” (local disk for an instance) running 32bit software. Currently my server is using 12% of a Celeron 2.4GHz CPU on average (which includes a mail server with lots of anti-spam measures, Venus, and other things). Running just the web sites on 1EC2 Compute Unit should use significantly less than 25% of a 1.0GHz Opteron. I’m currently using 400M of RAM for my DomU (although the MySQL server is in a different DomU). 1.7G of RAM for my web sites is heaps even when including a MySQL server. Currently a MySQL dump of my blog is just under 10M of data, with 1.7G of RAM the database should stay entirely in RAM which will avoid the disk IO issues. I could probably use about 1/3 of that much RAM and still not swap. The cost of EC2 is $US0.10 per hour of uptime (for a small server), so that’s $US74.40 per month. The cost for data transfer is 17 cents a GIG for sending and 10 cents a gig for receiving (bulk discounts are available for multiple terabytes per month). I am not going to pay $74 per month to host my blog. But sharing that cost with other people might be a viable option. An EC2 instance provides up to 5 “Elastic IP addresses” (public addresses that can be mapped to instances) which are free when they are being used (there is a cost of one cent per hour for unused addresses - not a problem for me as I want 24*7 uptime). So it should be relatively easy to divide the costs of an EC2 instance among five people by accounting for data transfer per IP address. Hosting five web sites that use the same software (MySQL and Apache for example) should reduce memory use and allow more effective caching. A small server on EC2 costs about five times more than one of the cheap DomU systems that I have previously investigated [4] but provides ten times the RAM. While the RAM is impressive, I have to wonder about CPU scheduling and disk IO performance. I guess I can avoid disk IO on the critical paths by relying on caching and not doing synchronous writes to log files. That just leaves CPU scheduling as a potential area where it could fall down. Here is an interesting post describing how to use EC2 [5]. Another thing to consider is changing blog software. I currently use Wordpress which is more CPU intensive than some other options (due to being written in PHP), is slightly memory hungry (PHP and MySQL), and doesn’t have the best security history. It seems that an ideal blog design would use a language such as Java or PHP for comments and use static pages for the main article (with the comments in a frame or loaded by JavaScript). Then the main article would load quickly and comments (which probably aren’t read by most users) would get loaded later.

Next.

Previous.