Search Results: "reg"

25 January 2011

John Goerzen: rdiff-backup, ZFS, and rsync scripts

rdiff-backup vs. ZFS As I ve been writing about backups, I ve gone ahead and run some tests with rdiff-backup. I have been using rdiff-backup personally for many years now probably since 2002, when I packaged it up for Debian. It s a nice, stable system, but I always like to look at other options for things every so often. rdiff-backup stores an uncompressed current mirror of the filesystem, similar to rsync. History is achieved by the use of compressed backwards binary deltas generated by rdiff (using the rsync algorithm). So, you can restore the current copy very easily a simple cp will do if you don t need to preserve permissions. rdiff-backup restores previous copies by applying all necessary binary deltas to generate the previous version. Things I like about rdiff-backup:
  1. Bandwidth-efficient
  2. Reasonably space-efficient, especially where history is concerned
  3. Easily scriptable and nice CLI
  4. Unlike tools such as duplicity, there is no need to periodically run full backups old backups can be deleted without impacting the ability to restore more current backups
Things I don t like about it:
  1. Speed. It can be really slow. Deleting 3 months worth of old history takes hours. It has to unlink vast numbers of files and that s pretty much it, but it does it really slowly. Restores, backups, etc. are all slow as well. Even just getting a list of your increment sizes so you d know how much space would be saved can take a very long time.
  2. The current backup copy is stored without any kind of compression, which is not at all space-efficient
  3. It creates vast numbers of little files that take forever to delete or summarize
So I thought I would examine how efficient ZFS would be. I wrote a script that would replay the rdiff-backup history first it would rsync the current copy onto the ZFS filesystem and make a ZFS snapshot. Then each previous version was processed by my script (rdiff-backup s files are sufficiently standard that a shell script can process them), and a ZFS snapshot created after each. This lets me directly compare the space used by rdiff-backup to that used by ZFS using actual history. I enabled gzip-3 compression and block dedup in ZFS. My backups were nearly 1TB in size and the amount of space I had available for ZFS was roughly 600GB, so I couldn t test all of them. As it happened, I tested the ones that were the worst-case scenario for ZFS: my photos, music collection, etc. These files had very little duplication and very little compressibility. Plus a backup of my regular server that was reasonably compressible. The total size of the data backed up with rdiff-backup was 583 GB. With ZFS, this came to 498GB. My dedup ratio on this was only 1.05 (meaning 5% or 25GB saved). The compression ratio was 1.12 (60GB saved). The combined ratio was 1.17 (85GB saved). Interestingly 498 + 85 = 583. Remember that the data under test here was mostly a worst-case scenario for ZFS. It would probably have done better had I had the time to throw the rest of my dataset at it (such as the 60GB backup of my iPod, which would have mostly deduplicated with the backup of my music server). One problem with ZFS is that dedup is very memory-hungry. This is common knowledge and it is advertised that you need to use roughly 2GB of RAM per TB of disk when using dedup. I don t have quite that much to dedicate to it, so ZFS got VERY slow and thrashed the disk a lot after the ARC grew to about 300MB. I found some tweakables in zfsrc and the zfs command that let me tweak the ARC cache to grow bigger. But the machine in question only has 2GB RAM, and is doing lots of other things as well, so this barely improved anything. Note that this dedup RAM requirement is not out of line with what is expected from these sorts of solutions. Even if I got absolutely stellar dedup ratio of 2:1, that would get me at most 1TB. The cost of buying a 1TB disk is less than the cost of upgrading my system to 4GB RAM, so dedup isn t worth it here. I think the lesson is: think carefully about where dedup makes sense. If you re storing a bunch of nearly-identical virtual machine images the sort of canonical use case for this go for it. A general fileserver well, maybe you should just add more disk instead of more RAM. Then that raises the question: if I don t need dedup from ZFS, do I bother with it at all, or just use ext4 and LVM snapshots? I think ZFS still makes sense, given its built-in support for compression and very fast snapshots LVM snapshots are known to cause serious degradation to write performance once enabled, which ZFS doesn t. So I plan to switch my backups to use ZFS. A few observations on this:
  1. Some testing suggests that the time to delete a few months of old snapshots will be a minute or two with ZFS compared to hours with rdiff-backup.
  2. ZFS has shown itself to be more space-efficient than rdiff-backup, even without dedup enabled.
  3. There are clear performance and convenience wins with ZFS.
  4. Backup Scripts So now comes the question of backup scripts. rsync is obviously a pretty nice choice here and if used with inplace perhaps even will play friendly with ZFS snapshots even if dedup is off. But let s say I m backing up a few machines at home, or perhaps dozens at work. There is a need to automate all of this. Specifically, there s a need to:
    1. Provide scheduling, making sure that we don t hammer the server with 30 clients all at once
    2. Provide for run before jobs to do things like snapshot databases
    3. Be silent on success and scream loudly via emails to administrators on any kind of error and keep backing up other systems when there is an error
    4. Create snapshots and provide an automated way to remove old snapshots (or mount them for reading, as ZFS-fuse doesn t support the .zfs snapshot directory yet)
    To date I haven t found anything that looks suitable. I found a shell script system called rsbackup that does a large part of this, but something about using a script whose homepage is a forum makes me less than 100% confident. On the securing the backups front, rsync comes with a good-looking rrsync script (inexplicably installed under /usr/share/doc/rsync/scripts instead of /usr/bin on Debian) that can help secure the SSH authorization. GNU rush also looks like a useful restricted shell.

23 January 2011

Dirk Eddelbuettel: CRANberries is now tweeting

The CRANberries service (which reports on new and updated CRAN packages for the R language and environment) is now tweeting about new packages. Simply follow @CRANberriesFeed to receive theses messages. For the technically minded, adding this to the existing 200-line program which runs all of CRANberries was very easy. CRANberries relies only on R itself and a few Unix tools like diffstat as well as the simple blosxom txt-to-html/rss 'blog compiler'. The tweeting itself is now done by this new function
tweetNewBlogEntry <- function(curPkg, curVer, reposurl)  
    ## tests reveal that pipe(), cat(), close() is easiest
    ## to send multiple messages, may need --background option
    con <- pipe("bti --config bti.conf", "w")
    cat("New CRAN package", curPkg, "with initial version", curVer, " http://goo.gl/pgljT\n", file=con)
    close(con)
 
which simply pipes the message in Greg KH's bti program (which is now a new dependency). Special thanks to its Debian maintainer Gregor Herrmann for some helpful emails; I am using the newest release 0.29 which itself needs liboauth0. Once OAuth tokens are set-up (and see here for how to do that) all we need is the three-liner above. At this point I am not too sure what to do about updated packages. One message per updated package seems too noisy. To be seen---comments or suggestions welcome.

Joachim Breitner: A Mistake in Church s Paper

For a course at the IIT Bombay on functional programing, I was preparing a presentation on Alonzo Church s theorem, based on his original 1936 paper An Unsolvable Problem of Elementary Number Theory where he first showed that the Entscheidungsproblem is not solvable. In that paper, he states a theorem (Theorem II) If a formula has a normal form [ ] any sequence of reductions of the formula must (if continued) terminate in the normal form . This seems to be wrong. Consider the lambda expression KI , where K=( xy.x), I=( x.x) and =( x.xx)( x.xx). This has a normal form I. But because reduces to , there is a non-terminating sequence KI KI , in contradiction to Church s claim. The same example contradicts his Theorem III: If a formula has a normal form, every well-formed part of it has a normal form. , which is used in the very proof of his main result, Theorem XVIII. There is no proof for Theorem II in this paper. He cites it from the then forthcoming paper Some properties of Conversion by him and J. B. Rosser. There, proofs are given (see Theorem 2 and its Corollary) but they are quite impenetrable to me. So I was searching for some correction paper, or any other discussion of this issue, but could not find any. Does any reader of this blog know more? What happened in that times when a paper had an error in some proof? What would happen now? Or is this not an error after all, but just a subtle difference between the definitions of -calculus as we know and as they introduced it? Unrelated to this question: The professor asked me to write down a summary of (my interpretation of) the importance and impact of Church s paper with regard to G del and Hilbert s program, and how that relates to B hm s theorem. In the spirit of sharing, I have uploaded my thoughts on Church and B hm, comments are welcome. Update: Christian von Essen solved the riddle in a comment to this post: Church only considers lambda abstractions as well-formed when the bound variable actually occurs (freely) in the abstracted term. This does not allow for the K combinator and thus there is no problem.

Russell Coker: Autism, Food, etc

James Purser wrote Stop Using Autism to Push Your Own Brand of Lunacy about the organisations that use Autism for their own political agenda [1]. He references the ongoing vaccine issue (which didn t even stop when Andrew Wakefield was proven to have engaged in fraudulent research) and a campaign of PETA.PETA s ClaimsPETA claims that many autistic kids improve dramatically when put on a diet free of dairy foods [2]. They also speculate about the possibility of Autism being caused by dairy.One thing that confuses the issue is the impact of stress on people with Autism Spectrum Disorders (ASDs). Whatever you are trying to do you will probably do it less effectively if under an excessive amount of stress, and the background stress levels of people on the Autism Spectrum tend to be quite high at the best of times. So add in some extra stress from a food allergy and the ability to emulate an NT can decrease a lot.There are people who make credible claims about significant behavior improvements in Autistic children after changing their diet. Eliminate foods that trigger a minor allergic response and the behavior of NT kids will improve too.I m sure that there are some Autistic kids who have a minor intolerance to lactose or casein who s behavior would improve if they had no dairy products. There are probably just as many Autistic kids who have a minor allergy to peanuts who would get the same benefit from avoiding peanut butter. It s not inconceivable that some Autistic people may be allergic to soy or wheat and find that they can cope better if their consume more milk, cheese, and steak and less vegetables!Also some people on the Autism Spectrum have a better sense of smell than NTs, and it s fairly common to be more fussy about the appearance of food. Force children to eat food that smells bad and their behavior might deteriorate.The issues of diet and Autism are more difficult than those of vaccines because while people just imagine the vaccines to have a bad affect, there are people who are proven to get a bad affect from certain foods.Some Ideas for ResearchI think that the biggest problem with PETA s research in this regard is citing a study of only 20 individuals and only testing the removal of milk. A proper study would involve more subjects (maybe 100) and separate tests of removing milk, eggs, wheat, rice, seeds, nuts, soy, fish, spices, and food colorings and additives.It would also test various methods of reducing stress, having a more quiet environment etc.PETA do deserve some credit for leaving this URL in the comments [3], it s a study that disproves the link between milk and Autism. But it s still a small sample size of 14.Why They Target AutismIn spite of psychologists moving to define Asperger Syndrome and Autism as the same thing, the people who make such claims aren t talking about people like me. They want to make claims about people who can t refute them, such as people who fit the Rain Man stereotype. The Low Functioning Autistic (LFA) people have less ability to communicate and are easier to ignore, so if you want to make some stuff up about a group of people then they are an easy target.Parents of LFA kids are often desperate and will latch on to any idea that seems to help. They can imagine that things have improved in spite of a lack of evidence and also fail to realise that children can improve rapidly just due to their natural development, 1 month is not much time for an adult but for a 4yo it s 2% of their life!Also any supposed research that includes testimony of parents should be regarded as rubbish. If you talk to any child psychologist they will tell you about how difficult it is to convince parents that their child is on the Autism Spectrum, a Google search for autism + denial also brings up plenty of hits. Parental denial doesn t stop at refusing to accept a diagnosis, it includes wanting to reject it at any later time based on any shred of evidence that may be available. So when there is a diet change or some other supposed cause followed by some apparently better behavior they want to claim that Autism is cured.I ve written a document titled Some Suggestions for Parents of Aspies [4] which is largely based on the childhood memories and adult experiences of various Aspies. My document covers many issues and few kids on the Spectrum will benefit from all of them, but I think that there is something there that can benefit every child on the Spectrum and probably a lot of geeky NT kids too. It seems to me that when dealing with Autistic kids it s a lot better to seek advice from adults on the Autism Spectrum than from random Neuro-Typical people (NTs), particularly if those NTs happen to have an agenda to push. The sensible parents are the ones who seek advice from psychologists and people like me rather than from random unqualified NTs.

22 January 2011

Mark Brown: Tracing ASoC with trace events

Kernel 2.6.38 will add support for tracing ASoC using trace points. Previously all logging for ASoC had been done using printk(), meaning that changing the active logging required a kernel rebuild and that when trace was enabled the volume of trace could easily become very disruptive to other logging within the system. Trace points solve these problems by providing a framework for enabling and disabling individual traces dynamically and separate logging infrastructure designed for easy filtering and post-processing. When using trace points it s reasonable to leave them enabled all the time, making life much easier especially when debugging intermittent problems. There s a bunch of existing documentation out there for the trace subsystem, including some in the kernel under Documentation/trace, which I won t repeat here. The ASoC events are grouped together under asoc . The raw log can be viewed by looking at the file tracing/trace in debugfs. Here s a sample output from starting playback of an MP3 on a Samsung SMDK6410 reference system using WM8580, a high performance six channel CODEC with a very simple software interface:
mplayer-1673  [000]   183.920000: snd_soc_dapm_start: card=SMDK-I2S
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=Rear val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=Center+Sub val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=Front val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=VOUT3R val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=VOUT3L val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=VOUT2R val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=VOUT2L val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=VOUT1R val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=VOUT1L val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=DAC3 val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=DAC2 val=1
mplayer-1673  [000]   183.920000: snd_soc_dapm_widget_power: widget=DAC1 val=1
mplayer-1673  [000]   183.920000: snd_soc_bias_level_start: card=SMDK-I2S val=2
mplayer-1673  [000]   183.920000: snd_soc_bias_level_done: card=SMDK-I2S val=2
mplayer-1673  [000]   183.920000: snd_soc_reg_read: codec=wm8580-codec.0-001b.27 reg=32 val=1e
mplayer-1673  [000]   183.920000: snd_soc_reg_write: codec=wm8580-codec.0-001b.27 reg=32 val=2
mplayer-1673  [000]   183.920000: snd_soc_bias_level_start: card=SMDK-I2S val=3
mplayer-1673  [000]   183.920000: snd_soc_bias_level_done: card=SMDK-I2S val=3
mplayer-1673  [000]   183.920000: snd_soc_dapm_done: card=SMDK-I2S
mplayer-1673  [000]   183.920000: snd_soc_reg_read: codec=wm8580-codec.0-001b.27 reg=13 val=10
mplayer-1673  [000]   183.920000: snd_soc_reg_write: codec=wm8580-codec.0-001b.27 reg=13 val=0
Each line represents a trace event, showing the process that initiated the event, the CPU it ran on and the time it was recorded at together with event-specific details. On this system the time is reported with 10ms accuracy and the CODEC is very simple so the timing information is not terribly informative, but more accurate timers can be really helpful in analysing what s going on with more complex CODECs. The set of events available will change over time, the key ones currently present in the kernel are: The set of events traced will change as the subsystem develops and as people gain more experience with using the trace API.

Enrico Zini: Cross-distro Meeting on Application Installer

Cross-distro Meeting on Application Installer I have been to a Cross-distro Meeting on Application Installer which to the best of our knowledge is also the first one of its kind. Credit goes to Vincent Untz for organising it, to OpenSUSE for hosting it and to the various sponsors for getting us there. It went surprisingly well. We got along, got stuff done, did as much work as possible to agree on as many formats, protocols and technologies as we possibly could. The timing of it is very important, as most major distros would like to adopt some of the features that just became popular in the various new app markets and stores, such as screenshots, user comments and ratings. It looks like a lot of new code is about to be written, or a lot of existing code is about to gain quite a bit of popularity. For my part, I presented the work on Debtags and apt-xapian-index. With regards to Debtags, other distros seem to be missing a compehensive classification system, and Debtags is, well, it. With regards to apt-xapian-index, we just noticed that it's the perfect back-end for what everyone would like to do, and the index structure is rather distribution-agnostic, and it's been road-tested with considerable success by at least software-center, so it attracted quite a bit of interest, and will likely attract some more. Just to prove a point I put together a prototype webby markety appy thing in just a few hours of work. The meeting was also the ideal place to create a joint effort to match package names across distributions, which means that a lot of things that were hard to share before, such as screenshots, tags and patches, are suddenly not hard to share anymore.

21 January 2011

Cyril Brulebois: Debian XSF News #2

Time for a second Debian XSF News issue! I ll skip stuff related to the new katamari since I wrote about that already.

20 January 2011

John Goerzen: Research on deduplicating disk-based and cloud backups

Yesterday, I wrote about backing up to the cloud. I specifically was looking at cloud backup services. I ve been looking into various options there, but also various options for disk-based backups. I d like to have both onsite and offsite backups, so both types of backup are needed. Also, it is useful to think about how the two types of backups can be combined with minimal overhead. For the onsite backups, I d want to see:
  1. Preservation of ownership, permissions, etc.
  2. Preservation of symlinks and hardlinks
  3. Space-efficient representation of changes ideally binary deltas or block-level deduplication
  4. Ease of restoring
  5. Support for backing up Linux and Windows machines
Deduplicating Filesystems for Local Storage Although I initially thought of block-level deduplicating file systems as something to use for offsite backups, they could also make an excellent choice for onsite disk-based backups. rsync-based dedup backups One way to use them would be to simply rsync data to them each night. Since copies are essentially free, we could do (or use some optimized version of) cp -r current snapshot/2011-01-20 or some such to save off historic backups. Moreover, we d get dedup both across and within machines. And, many of these can use filesystem-level compression. The real upshot of this is that the entire history of the backups can be browsed as a mounted filesystem. It would be fast and easy to find files, especially when users call about that file that they deleted at some point in the past but they don t remember when, exactly what it was called, or exactly where it was stored. We can do a lot more with find and grep to locate these things than we could do with tools in Bacula (or any other backup program) restore console. Since it is a real mounted filesystem, we could also do fun things like make tarballs of it at will, zip parts up, scp them back to the file server, whatever. We could potentially even give users direct access to their files to restore things they need for themselves. The downside of this approach is that rsync can t store all the permissions unless it s running as root on the system. Wrappers such as rdup around rsync could help with that. Another downside is that there isn t a central scheduling/statistics service. We wouldn t want the backup system to be hammered by 20 servers trying to send it data at once. So there d be an element of rolling our own scripts, though not too bad. I d have preferred not to authorize a backup server with root-level access to dozens of machines, but may be inescapable in this instance. Bacula and dedup The other alternative I thought of system such as Bacula with disk-based volumes . A Bacula volume is normally a tape, but Bacula can just write them to disk files. This lets us use the powerful Bacula scheduling engine, logging service, pre-backup and post-backup jobs, etc. Normally this would be an egregious waste of disk space. Bacula, like most tape-heritage programs, will write out an entire new copy of a file if even one byte changes. I had thought that I could let block-level dedupe reduce the storage size of Bacula volumes, but after looking at the Bacula block format spec, this won t be possible as each block will have timestamps and such in it. The good things about this setup revolve around using the central Bacula director. We need only install bacula-fd on each server to be backed up, and it has a fairly limited set of things it can do. Bacula already has built-in support for defining simple or complicated retention policies. Its director will email us if there is a problem with anything. And its logs and catalog are already extensive and enable us to easily find out things such as how long backups take, how much space they consume, etc. And it backs up Windows machines intelligently and comprehensively in addition to POSIX ones. The downsides are, of course, that we don t have all the features we d get from having the entire history on the filesystem all at once, and far less efficient use of space. Not only that, but recovering from a disaster would require a more extensive bootstrapping process. A hybrid option may be possible: automatically unpacking bacula backups after they ve run onto the local filesystem. Dedupe should ensure this doesn t take additional space if the Bacula blocksize aligns with the filesystem blocksize. This is certainly not a given however. It may also make sense to use Bacula for Windows and rsync/rdup for Linux systems. This seems, however, rather wasteful and useless. Evaluation of deduplicating filesystems I set up and tested three deduplicating filesystems available for Linux: S3QL, SDFS, and zfs-fuse. I did not examine lessfs. I ran a similar set of tests for each:
  1. Copy /usr/bin into the fs with tar -cpf - /usr/bin tar -xvpf - -C /mnt/testfs
  2. Run commands to sync/flush the disk cache. Evaluate time and disk used at this point.
  3. Rerun the tar command, putting the contents into a slightly different path in the test filesystem. This should consume very little additional space since the files will have already been there. This will validate that dedupe works as expected, and provide a hint about its efficiency.
  4. Make a tarball of both directories from the dedup filesystem, writing it to /dev/zero (to test read performance)
I did not attempt to flush read caches during this, but I did flush write caches. The test system has 8GB RAM, 5GB of which was free or in use by a cache. The CPU is a Core2 6420 at 2.13GHz. The filesystems which created files atop an existing filesystem had ext4 mounted noatime beneath them. ZFS was mounted on an LVM LV. I also benchmarked native performance on ext4 as a baseline. The data set consists of 3232 files and 516MB. It contains hardlinks and symlinks. Here are my results. Please note the comments below as SDFS could not accurately complete the test.
Test ext4 S3QL SDFS zfs-fuse
First copy 1.59s 6m20s 2m2s 0m25s
Sync/Flush 8.0s 1m1s 0s 0s
Second copy+sync N/A 0m48s 1m48s 0m24s
Disk usage after 1st copy 516MB 156MB 791MB 201MB
Disk usage after 2nd copy N/A 157MB 823MB 208MB
Make tarball 0.2s 1m1s 2m22s 0m54s
Max RAM usage N/A 150MB 350MB 153MB
Compression none lzma none gzip-2
It should be mentioned that these tests pretty much ruled out SDFS. SDFS doesn t appear to support local compression, and it severely bloated the data store, which was much larger than the original data. Moreover, it permitted any user to create and modify files, even if the permissions bits said that the user couldn t. tar gave many errors unpacking symlinks onto the SDFS filesystem, and du -s on the result threw up errors as well. Besides that, I noted that find found 10 fewer files than in my source data. Between the huge memory consumption, the data integrity concerns, and inefficient disk storage, SDFS is out of the running for this project. S3QL is optimized for storage to S3, though it can also store its files locally or on an sftp server a nice touch. I suspect part of its performance problem stems from being designed for network backends, and using slow compression algorithms. S3QL worked fine, however, and produced no problems. Creating a checkpoint using s3qlcp (faster than cp since it doesn t have to read the data from the store) took 16s. zfs-fuse appears to be the most-used ZFS implementation on Linux at the moment. I set up a 2GB ZFS pool for this test, and set dedupe=on and compress=gzip-2. When I evaluated compression in the past, I hadn t looked at lzjb. I found a blog post comparing lzjb to the gzip options supported by zfs and wound up using gzip-2 for this test. ZFS really shone here. Compared to S3QL, it took 25s instead of over 6 minutes to copy the data over and took only 28% more space. I suspect that if I selected gzip -9 compression it would have been closer both in time and space to S3QL. But creating a ZFS snapshot was nearly instantaneous. Although ZFS-fuse probably doesn t have as many users as ZFS on Solaris, still it is available in Debian, and has a good backing behind it. I feel safer using it than I do using S3QL. So I think ZFS wins this comparison. I spent quite some time testing ZFS snapshots, which are instantaneous. (Incidentally, ZFS-fuse can t mount them directly as documented, so you create a clone of the snapshot and mount that.) They worked out as well as could be hoped. Due to dedupe, even deleting and recreating the entire content of the original filesystem resulted in less than 1MB additional storage used. I also tested creating multiple filesystems in the zpool, and confirmed that dedupe even works between filesystems. Incidentally wow, ZFS has a ton of awesome features. I see why you OpenSolaris people kept looking at us Linux folks with a sneer now. Only our project hasn t been killed by a new corporate overlord, so guess that maybe didn t work out so well for you <grin>. The Cloud Tie-In This discussion leaves another discussion: what to do about offsite backups? Assuming for the moment that I want to back them up over the Internet to some sort of cloud storage facility, there are about 3 options:
  1. Get an Amazon EC2 instance with EBS storage and rsync files to it. Perhaps run ZFS on that thing.
  2. Use a filesystem that can efficiently store data in S3 or Cloud Files (S3QL is the only contender here)
  3. Use a third-party backup product (JungleDisk appears to be the leading option)
There is something to be said for using a different tool for offsite backups if there is some tool-level issue, that could be helpful. One of the nice things about JungleDisk is that bandwidth is free, and disk is the same $0.15/GB-mo that RackSpace normally charges. JungleDisk also does block-level dedup, and has a central management interface. This all spells nice for us. The only remaining question would be whether to just use JungleDisk to back up the backup server, or to put it on each individual machine as well. If it just backs up the backup server, then administrative burdens are lower; we can back everything there up by default and just not worry about it. On the other hand, if there is a problem with our main backups, we could be really stuck. So I d say I m leaning towards ZFS plus some sort of rsync solution and JungleDisk for offsite. I had two people suggest CrashPlan Pro on my blog. It looks interesting, but is a very closed product which makes me nervous. I like using standard tools and formats gives me more peace of mind, control, and recovery options. CrashPlan Pro supports multiple destinations and says that they do cloud hosting, but don t list pricing anywhere. So I ll probably not mess with it. I m still very interested in what comments people may have on all this. Let me know!

19 January 2011

Gunnar Wolf: Mandate for what?

I lived in Israel between 1994 and 1996 This was just after the signature of the Oslo agreements, the Rabin-Arafat signature. 1994-95 was a beautiful time to be in Israel; there was the excitement of a prospect of real peace with the Palestinians, something that had been just seen as unattainable for the past 50 years. But we also saw the buildup of a huge tension, of real hatred. And the dream of the end of the conflict, of two people living in peace side by side was heavily shattered on November 4 1995, when prime minister Rabin was assassinated. But for the sake of where I'm trying to get to (this post is meant to be about current Mexico, not of Israel 15 years ago), lets go a couple of months back. The Israeli society is a deeply democratic one (although I understand many people feel it is losing that trait). Lots of political propaganda of all sorts, many of it very creative, are posted on the streets And not by the government or by political parties, but by citizen movements. I tried to follow it... I remember a particular sticker that I started seeing very often: Rabin has no mandate over the Golan . At first, I understod that the Golan residents rejected Rabin's authority (but, why was it posted all over the country? And what specifically was it about?), until a friend explained to me that it meant that it rather meant that the right wing all over the country felt that Rabin had no right to push for negotiations involving in any way the Golan heights return to Syria because that was not his electoral platform. So, fast-forward in time, and 12500Km to the west. If you have followed my ramblings for the past ~five years, you are aware of what I think about Mexico's government It is an illegitimate government, which got the power thanks to a dirty and illegal (as per Mexico's legal system) campaign and to voting fraud. And, according to what I have read, around 30% of the population still believe firmly the elections were stolen. But even if they were legal, valid and legitimate What has happened since 2006 should not be seen as valid. In Mexico, we don't have such a democratic culture. The society is not used to demanding anything from the politicians. We often see, as an example, that when talking about political organs, there is a divide everybody understands although makes no sense: We talk about citizens as people unaffiliated to political parties (v.gr. the 1996 Federal Electoral Institute was very well regarded as it was "el IFE ciudadano", and has since then been overtaken by the parties). Why are the parties' members not seen as citizens? Well, maybe because of the same distortion field that makes us believe our de-facto president when he stated that, from the (then) over 28000 people killed in the war campaign against crime (he oficially declared he never used the term war... Of course, he was proved wrong), only ~10% were civilians. In my book, that would mean that ~25000 soldiers have been killed But no, he means mostly drug trafficants. So, as they are not innocent bystanders, they somehow stopped being civilians? But again, I'm straying off the topic. Let us assume for a minute that the 2006 elections were clean legal, and that the campaigns were not diffamatory, and all that. And tha we had a modern government, with the stated separation between the three powers and all that. By today, the Legislative power would have surely called for the government's disolution. Why? Again, we Mexicans are not used to what a democratic system means. We can see over and over examples of people who have been voted to power and forgot/betrayed everything they campaigned for. And we are used to that being... Normal. But, who did we vote for? Given the suposition of this last paragraphs (clean elections led to our current government), did the majority of the population vote for Felipe Calder n, the person? Or did it vote for Partido Acci n Nacional, the abstract entity organized as a party? No. The vote was (should have been) for the political campaign, for the things he promised he would work for, the priorities in the direction he would give the nation. Not too long ago, we took pride of living in a peaceful country. Yes, everybody feared the crime rate in the streets, everybody knew big cities such as the one I live in (and love living in) have deep problems. But the country had good relations and good respect from the international players, and it was mostly safe. And, I don't think any of the few readers that have read this far (regardless of where they live or how much they know me) has that opinion of Mexico anymore. What is now heard inside and outside is that we have a huge organized crime (mostly due to drug traffic), and that it's taking over the country. Why did this happen? The fact is, Calder n lacked legitimacy when he reached the presidency in December 2006. And although his campaign was centered on pushing work generation (his slogan was El presidente del empleo, The president of the jobs), lifting restrictions to entreprises, opening borders, getting more money in our economy... He knew he had to please the people that would protect him from any (then, probable) insurrection: Military and police. Our army has always been more a joke than an army... But they still have their guns. So, contrary to everything he promised, the first things he signed was a salary increase to all order-keeping forces in the country, and an all-out attack against drug traffic cartels. He had to make the order-keeping forces protagonist, useful and loyal. Now, fast-forward again to 2011. The country is living the worst violence since the end of the 1910-1920 revolution. Over 30,000 people have been killed. Economy has fallen as it had not for many years (this was the worst-performing country in America in 2009). Work generation was said to be high, but then corrected to indicate it was mediocre (just about the baseline of population growth). So, the balance so far of four years of... Government? Economic disaster. Social disaster. Promises unachieved. Starting actions he had no mandate to do. Felipe Calder n has no mandate to get us in this war. Even if he had been democratically elected, he would have to step down.

Robert Millan: Finally, amd32 is taking shape

When AMD launched its now widely used 64-bit architecture in year 2000, it started marketing it as a significant step forward because of it having longer word and pointer size. One just has to check the advertising material and notice those big 64 being touted as the main improvement. But it is commonly accepted that most applications don t need a 64-bit address space for anything. Building them in LP64 model is just a waste of memory due to increase of pointer size. Even though this made most applications lag behind, the new architecture still was an improvement in terms of speed because of the AMD revised ISA, featuring changes like: To summarize, most of the merit from AMD64 architecture was in fixing some of the insanity of Intel 386 ISA (instruction set architecture), rather than the increased pointer size which was a source of inefficiency most of the time. Perhaps AMD didn t evaluate this correctly, or perhaps its marketing side won over technical merit. However, although the new hardware is biased towards LP64 data model, it s not actually enforced. It was a matter of time until an independent project took over and attempted to fix this, combining the AMD64 ISA with ILP32 data model. I ve been reading with much interest in the binutils and gcc mailing lists that such project is beginning to take shape. A port of binutils, GCC, GDB and Linux is already available. Future plans include porting Glibc which will make it possible to build a standard GNU derivative out of this. Sadly, I don t have the time to devote to this project myself, but I ll continue following its progress. I m looking forward to bringing this speed boost to my machines.

Rapha&#235;l Hertzog: What I publish on Planet Debian and Planet Ubuntu

Up to now, Planet Debian and Planet Ubuntu were syndicating the main feed of my blog. I changed this recently (remember, I explained how I created my custom WordPress feed). Read on to learn why and subscribe to the main feed now if you want to get all my Debian/Ubuntu articles in the future. Planet Debian/Ubuntu are supposed to be windows into the lives of the contributors. Whatever they are doing. Obviously you get a lot of infos about Debian and Ubuntu since most contributors spend a lot of time working on those distributions. Due to this, those planets have also become dedicated medias to exchange between contributors. The problem I had is that my blog is more than just a place where I speak of what I do within Debian. As part of my evil plan, I set out my blog to become a great documentation resource for Debian/Ubuntu users. So when I wrote articles for users and/or beginners (like 5 reasons why a Debian package is more than a simple file archive or How to rebuild Debian packages), I got some remarks that it was odd to have those articles on Planet Debian because most contributors knew those things already. The bottom line is that from now on I ll decide on a case by case whether the article is suitable for Planet Debian&Ubuntu based on my feelings (and the feedback I get by email). But if you enjoyed my articles for users, I invite you to directly subscribe to my blog to make sure you ll get them all in the future: By the way I would like to thank you all. This blog has been created last July and I m glad to have already more than 1400 regular followers (spread over RSS/email/Twitter/Identi.ca/Facebook, not counting the thousands that read me via Planet Debian/Ubuntu). I hope you ll enjoy 2011 with me, and continue sharing the articles you like.

6 comments Liked this article? Click here. My blog is Flattr-enabled.

Russell Coker: Free Amazon EC2 Servers

Amazon is providing free EC2 access for new customers (who have never been customers before) for one year [1]. It is 750 hours per month (enough to run non-stop for an entire month) of access to a Linux micro instance which has 613M of RAM and the ability to burst to two ECUs of compute power. The main EC2 web page [2] describes an ECU as the equivalent CPU capacity of a 1.0-1.2 GHz 2007 Opteron or 2007 Xeon processor and they also describe a single core of a modern CPU as having 3.5 ECUs. So a micro instance could burst to half the CPU power of a single core. The DomU that runs my blog (as well as some web sites for friends) has been averaging less than 1% use of a CPU core over the last few months, so the CPU capacity of a micro instance should be more than adequate for most things that run on the net.The free offering only provides 15G of free data transmission and 15G of free data reception per month. For my blog server that would be more than adequate as it has sent 24.5G and received 14G over the last 75 days.The Cost of Disk IOThe offer requires that you sign up with a credit card so if you use more than the free capacity then you have to start paying. It seems that the main issue in this regard is disk IO.The only storage that is available for a micro instance is the Elastic Block Store (EBS) [3]. The main way that EC2 operates is that when you create a new virtual machine it copies the data from an existing image so you can easily create dozens or hundreds of virtual machines with local disk performance and the data is removed when the instance is shut down. EBS is essentially SAN based storage, it s persistent and operates like a regular disk.The pricing for EBS is $0.10 per allocated GB per month plus $0.10 per million IOs. Unfortunately they don t define what an IO is apart from mentioning that you can use IOSTAT to measure them. According to iostat the server running my blog is doing 0.99 tps, so that means in a 30 day month I would expect 30*24*3600*0.99 = 2.56M transactions. Iostat also tells me that my blog server has read 62075330 blocks and written 91683344 blocks over the last 75 days 16 hours of uptime, that means it would do about (62075330+91683344)/75.66*30 = 61M block transfers in a 30 day month. So if I was to run my blog server on EC2 I could be spending either $0.15 or $6.00 per month on disk IO depending on how they count it (or maybe something in between, something larger than a 512 byte block but smaller than a transaction as reported by iostat could be used). Given that the last time I checked the prices one could rent a DomU for less than $6 per month [4] the difference in possible ways of measuring IOs is very significant!The MySQL server that is the backend to my blog (as well as a few other things) seems to be averaging about 3 writes per second (and no reads during operation because the databases are small). So it might be another 5 million IOs per month for the database.It s unfortunate that Amazon haven t clearly specified what they mean when measuring IO for billing purposes. Some aspects of measurement such as whether the bills for bandwidth include Ethernet headers can be ignored as a 26 byte Ethernet header won t make much difference to the bill when the average packet size is around 400 bytes or more (from ifconfig output it seems that my blog server sends packets of an average size of 459 bytes and receives packets of an average size of 1250 bytes). But the methods of measuring disk IO could give a factor of 20 difference in the bill.Optimising for EC2If I was going to put my blog on EC2 then I would start by configuring Apache to log to a fifo and then write a daemon that stores the log data and allows my home server to poll it and get the log data. As the filesystem is already mounted with noatime it seems that writing logs is the cause of all the disk writes so if they were stored in RAM (which shouldn t be a problem with 4M of logs per day) then all those writes could be avoided. Another possible solution to this would be to make /var/log be a tmpfs and then rsync the files periodically to my home server. I don t really need to have all the logs remain on the server I just need them to remain somewhere.Amazon also offers 100,000 messages on their Simple Queue Service (SQS) for free [5]. The messages can be up to 8K in size and are stored for up to 4 days. So it seems possible to put Apache logs into SQS messages in bundles of less than 8K and then get them out later for transfer to a server outside EC2.If I was able to get my disk writes to almost zero then there s a good chance that I could get into the free zone for one year.ConclusionWould I use this service? If I was looking for new hosting for my blog then I would seriously consider it. EC2 is quite fast and well connected and depending on how they work out the billing for disk IO I could probably keep the cost close to zero.EC2 is a different way of running things so you can t just have a virtual server running and expect it to automatically restart if it goes down for any reason (a standard feature of virtual hosting companies). Amazon does have a range of tools for managing EC2 instances and they all seem to be available in the free trial. So after spending the time to learn those tools the result should be good.I think that there are two groups of people who could benefit from using this. One is hobbyists, this is a great way to learn some skills related to high-end server stuff and EC2 experience should look good on a CV. The other is companies who want to use EC2 anyway and who will just save some money that they would otherwise pay. I ve seen someone recommend the free offering from EC2 for a company that needed a small server, I think that isn t a good option as a company that only wants a single small server will be better off paying something between $5 and $20 per month for a DomU from one of the virtual hosting providers.After a year you have to pay regular prices. A micro instance costs $0.02 per hour which is $14.40 per month, SQS costs $0.10 per month for sending up to 1G of data in and at $0.01 per 10,000 SQS requests would costs $0.03 (the 4M of log data I generate per day would be 1000 requests to write and read it which would be 30,000 requests per month), the EBS for MySQL would cost $0.10 for 1G of storage and maybe $0.50 for IOs. That means $15.13 before counting bandwidth.My blog server averages just under 10G of transmitted data per month, the first Gig is free so that would cost $0.15 for each subsequent Gig which is $1.35 per month. It receives just under 6G per month which at $0.10 per gig would be $0.60. So including data transfer it would be about $17.08 per month.This is a lot more expensive than some of the cheaper virtual server offerings but admittedly the cheaper virtual offerings don t have as much RAM. Also with a blog instance running on EC2 I could easily configure it so that I could create some big instances that use the same MySQL database if a lot of extra traffic suddenly started arriving. A micro instance running MySQL on it s own could cope with a heap of load a lot more easily than the PHP code for my blog. So using bigger servers to run the PHP code while running MySQL on the same server would be a good option particularly if the bigger servers use caching.Finally if you want to run an EC2 instance for a year then you can get a reserved instance, you pay $54 per annum and the cost drops to $0.007 per hour instead of $0.02 per hour. Using a reserved instance for my blog would give a cost of $54+365*24*0.007+12*(0.10+0.03+0.10+0.50) or about $124.08 per annum. $10 per month isn t too bad. So if I migrated my blog to EC2 then I would probably keep it there after the free period expired. The ability to expand rapidly when necessary is worth paying extra. Of course I am making some assumptions such as that the performance of a micro instance doesn t totally suck as Amazon don t specify what bursting to 2ECU really means it could have some performance problems.Note that all prices in this post are in US Dollars.

Dirk Eddelbuettel: RcppBDT 0.1.0

The family of Rcpp packages just grew by one: the first 0.1.0 release of RcppBDT is now on CRAN. RcppBDT stands for Rcpp Boost Date_Time. It employs what we call Rcpp modules: a mechanism which provides easier ways to expose C++ functions and classes to R (and which bears some resemblance to Boost.Python---see this vignette about Rcpp modules for more details). And thus RcppBDT provides R users with access to (some) Boost Date.Time functionality. I used Boost Date.Time because it is widely known, useful and well tested. It can also be used in pure template mode not requiring linking (if one foregoes string parsing and formatting which is fine here as we get this from R already; it can be added via a #define in the header file). With that, the package is rather portable as it only needs to find the Boost headers. (And no, I have not yet added a configure option for that.) Basic usage follows Rcpp modules and provides the C++ class via a Reference Class in R. That means using a new constructor and assessing functions via the $ operator. Here is an example:
R> library(RcppBDT)
Creating a new generic function for "print" in "RcppBDT"
Creating a new generic function for "format" in "RcppBDT"
R> d <- new(bdtMod$date, 2011, 1, 18)
R> format(d)
[1] "2011-01-18"
R>
Not very exiting yet: we create a date, using explicit year, months and date arguments and then format it. Something more useful follows:
R> d$getDayOfWeek()
[1] 2
R> d$getModJulian()
[1] 55579
R> d$getFirstOfNextMonth()
[1] "2011-02-01"
R>
We can use accessors to extracts parts of the date, or use functions to convert the date to different representations such as a modified Julian date. Moreover, given a date, we can apply helper functions such as get me the date of the beginning of the next month. More interesting still are helper functions such as the ones below. Note that this also shows the alternate access method using wrapper functions I added for the package, this may be more familiar to most R users:
R> getNthDayOfWeek(third, Wed, Dec, 2010)
[1] "2010-12-15"
R> getLastDayOfWeekInMonth(Sat, Dec, 2010)
[1] "2010-12-25"
R> getFirstDayOfWeekInMonth(Sat, Dec, 2010)
[1] "2010-12-04"
R> getFirstDayOfWeekAfter(Wed, as.Date("2010-12-31"))
[1] "2011-01-05"
R>
This uses some of the constants Jan, Feb, ... , Dec; Sun, Mon, ..., Sat and first ... fifth defined in the package; normal integers can also be used. The third Wednesday in a month is also known as the IMM Date to Finance-heads; the example was borrowed from Whit's earlier rboostdatetime code on github. More examples are in the demo available with the package and accessible via demo(RcppBDT) once you install the package. As always, feedback would be welcome, both on the usefulness (or lack thereof) of the Boost Date.Time functionality as well as on the Rcpp modules wrapping. Additional Boost Date.Time functionality (durations, times, ...) may be added; contributions would be welcome. The rcpp-devel mailing list off the R-Forge page for Rcpp is the best place to start a discussion.

18 January 2011

Russell Coker: Conferences and People on the Autism Spectrum

There have been some recent discussions about issues related to the treatment of women at Free Software conferences, I ve written posts about Aspie Social Skills and Free Software [1] and Empathy, Autism, and Geeks [2] about this. But of course discussion continued on how Aspies supposedly cause problems that no-one seems to be noticing.Lisa of Chaotic Idealism wrote an interesting post about the NT social bias [3]. In summary NTs seem to think that Autism Spectrum Disorders are only about socialisation, not realising that for many people on the Spectrum it s sensory issues that are their main problem. Social problems are exacerbated by sensory issues and other causes of stress, so I think it s worth considering ways in which conferences can be planned to be less stressful for people on the Autism Spectrum, people who have SPD [4] that isn t associated with an ASD, and NTs who just get annoyed by loud noises etc.What Autism Conferences DoAutscape is one of only two conferences for people on the Autism Spectrum and the only one which clearly documents how they plan their conference [5]. The first noteworthy thing that they do is have badge colors to indicate what level of social interaction is desired by each delegate, I don t think that this is relevant to Free Software conferences as people who don t have sufficient social skills to suit at least a green badge probably won t be attending. But I think that when attending a conference about Free Software or any other equally geeky topic (if there is an equally geeky topic) it s worth keeping in mind the fact that there are probably a lot of people who would like to talk to you but lack the social skills to start a conversation.
No initiationRedPlease do not initiate any interaction with me.
Prior PermissionYellowPlease do not initiate unless I have already given you permission to approach me on a yellow badge.
Please initiateGreenI would like to socialise, but I have difficulty initiating. Please initiate with me.
NeutralWhite (or no badge)I am able to regulate my own interaction.
The next thing that they document is a black circle badge which indicates that the wearer shouldn t be photographed. Prior to reading that web site I wasn t aware of this being an Autistic issue, I was only aware of it being an issue for women who don t want zoomed-in pictures of themselves appearing on guys web sites (even pictures that aren t up-skirt or down-blouse can be unwelcome). A conference policy that prohibited photographs that zoom in on one person without that person s consent (or parental consent in the case of minors) would probably be a good idea.Another thing about badges is that it s a really good idea to have the delegate s name on both sides of the badge if the badge is attached in a way that permits it to turn. People on the Autism Spectrum tend to have some difficulty in recognising people and in remembering names. I find it inconvenient when someone expects me to recognise them but has their badge turned around so I can t see their name. Some people get really unhappy if they think that someone doesn t recognise them.Autscape has long breaks between activities and a leisure session each afternoon to allow delegates to recover from the stress of dealing with people. It seems to me that computer conferences in some cases could do with longer breaks between sessions. I find that a lot of the benefit of a conference is in what happens outside sessions and the standard practice of publishing videos of presentations makes personal meetings a more important part of the conference.Autscape has designated quiet spaces. I think that for computer conferences which have hack-labs (which seems to be most Free Software conferences nowadays even if they aren t labelled as such) it would be good to have some lab areas designated as quiet zones. I think that it is a really good thing to meet people you ve only known by email and then play some LAN based games against them and that this should be encouraged as part of a conference, but having that sort of thing separated from people who want to do some quiet coding is a really good idea. Whether people want to do quiet coding, read email, or just escape from the stress of a conference a quiet hack-lab would be a good place for it.An issue that s related to quiet spaces is the ability to escape from social situations. One of my pet hates is corporate meetings on boats, when the boat is in motion there is no escape. Corporate meetings that are only accessible by coach are also bad. Fortunately most conferences aren t like that.The Autscape web site states that they prohibit people from wearing perfume or aftershave to help people who are sensitive to smell. My observation of Free Software conferences is that encouraging everyone to have a shower every morning would be a good idea as there are stronger smells from unwashed people than from perfume.One thing that s interesting about the Autscape web site is that they have different color schemes available and have tested it in multiple web browsers including Safari and Konqueror (which apparently don t work so well). It s interesting to note that they test with such a variety of browsers including free software ones most corporations don t do that.Sensory Processing IssuesThe main SPD issues related to conferences seem to be noise and light related.For social events one difficulty that most people on the Spectrum seem to face is in listening to one person in a noisy crowded room. As well as that sudden noises and loud background noises can be very stressful. While it s sometimes impossible to avoid crowds (which can be another problem) it is often possible to select venues that have less noise problems. A venue with carpet on the floor and soft walls (anything other than brick or concrete) will be a lot quieter than one with hard surfaces that reflect noise. It seems that a quiet venue will benefit NTs as well, there seems to be a strong correlation between the price of food at restaurants and the amount of sound absorbing material on the floor and walls people who can afford a good dining experience seem to want it quiet.In terms of visual issues the relevant problems seem to be related to sudden transitions and lecture halls that are extremely dark. The only thing that can be done by conference organisers is to seek to have the lights in the lecture halls as bright as possible without preventing the viewing of the projector screen, this is usually done anyway.For social events the whole binge drinking at crowded bars thing doesn t work too well due to noise, poor lighting, crowds, and the smell of vomit. But there s no shortage of reasons to discourage binge drinking at conferences.FoodPsychology Today has a good article about preferences for food and picky eaters [6]. Lots of people on the Autism Spectrum have similar issues. The thing to do when arranging a conference meal is to have things neat and without needless combinations. Think about making food look more like what you would expect to see in a Japanese restaurant and less like Paella. Also having some very plain food on offer is a good thing, I think that bread-rolls for dinner and ice-cream for desert makes a viable meal. But any dish with a word like hash or mixed in it s name isn t a good option. Finally some combinations are really bad, I always find rare steak and potatoes on the same plate to be rather disgusting potato that s blood-stained doesn t appeal. The majority of conference meals satisfy these criteria.Autscape provides options of eating outside the main dining hall for people who can t tolerate the noise. For a Free Software conference it might be a better idea to provide seating outside the main area for people who are going to make noise. I don t mind people who want to get really drunk at the conference dinner, but I would prefer them to be in a separate room. Also when assisting a drunk friend to leave the venue before they cause more problems it would be convenient if there was a good place to take them to. The one occasion when I had to strongly encourage a friend to leave a conference dinner to reduce his embarrassment the next day (and reduce the annoyance for everyone else) there was no good place to take him so he just came back!ConclusionI don t expect that anyone will make any significant changes to conference plans after reading this post. I have tried to focus on things that would benefit NTs as well, but there are practical issues that get in the way such as the cost and availability of venues that are large enough. But there are some smaller ideas that can be implemented with relative ease.I hope that the people who are making claims about Autism and conference behavior will refer to this in future. If you think that there is a problem with the way people on the Spectrum act at conferences then the solution will more likely involve the suggestions I make here than anything else.

17 January 2011

Joey Hess: the conversion

It's summer in Spain, and outside there's a dry heat, but in the hack lab, it's frigid. I'm sitting across the table from Otavio, and each of our laptops is showing the same identical screen of text, editing the same file. Slowly. The file is located in Colorado, and we're fighting serious conference lag, plus transatlantic lag. Type a few lines, wait a minute, hope it shows up, and restart the converter to see if it worked. We're struggling with figuring out how to make it work, and pair programming across the table like this helps -- although we also struggle with each others accents sometimes, so we're eventually mostly communicating via text on the computers. Eventually Otavio rolls off to bed. Later, everyone else in the conference goes to bed or whatever -- I don't really notice. At some point a cleaning woman comes in, and seems suprised to see me. I muster up enough Spanish to ask if this muy fio air conditioning can be turned off. A bit later, I make this commit and then go out, look at storks in early morning light, and go to bed.
r59731   joeyh   2009-07-24 12:30:52 -0400 (Fri, 24 Jul 2009)   1 line
up to r15000; also skip the packages/po accient revs
That would have been 6 am local time. The log shows us back at it by 11 am local. There's so much detail in these logs, and it's hard to tell how any individual bit will turn out useful, but the value in aggregate is undeniable and that's why we struggle to retain it as technology marches on.
A few days later and the conversion is caught up to the commits documenting it. Everyone goes home. Later still, and work is done to verify the conversion. Problems are found, fixed. The worst of them involves the Danish language, and absolute evil. Tempers flare, and I have the last argument I'll ever have the pleasure of having with Frans. At some point in there, I do rather more coding in C++ than I ever have before, or ever wanted to. Frans's objections are addressed by that, more or less. We're using a weird tool that was developed as a kind of one-off for another project, but happens to meet our needs pretty well -- but we're stuck dealing with its bugs. And its need for copious handholding and historical research. The file we started out editing grows to two thousand lines, and now covers ten years of odd bits of history.
Suddenly it's a year and a half later. I'm in a cabin in winter, Otavio is down in summer, and I'm once again dealing with lag (dialup lag this time). We run the converter again -- one last time. And a time more.. and four or five more "last times". Finally, after a longish day, it's done.
This was not a major project, just some little bits of time here and there, maybe a week's worth in total, spread out over a few years and four or five people. It hardly seems worth writing about, just another codebase converted from Subversion to Git, a bit behind most of the other ones. Just thought I'd give you a glimpse behind the curtain.

Phil Hands: Cloud Expo Europe

Debian will be exhibiting at next month's Cloud Expo Europe on the 2nd & 3rd of Feb.
(well I will be if you fancy keeping me company please add yourself to this page)If you fancy visiting the show, you can register for free before midnight on the 1st of February (after that it costs 15.00 GBP)oh, and later the same week,I'm going to FOSDEM, the Free and Open Source Software Developers' European Meeting

Rapha&#235;l Hertzog: Review of my Debian related goals for 2010

Last year I shared my Debian related goals for 2010 . I announced that I would not be able to complete them all and indeed I have not, but I have still done more than what I expected. Let s have a look. Translate my Debian book into English and get it published: NOT DONE Or rather not yet done. It s still an important project of mine and I will do it this year. When I wrote this last year, I expected to find a publisher that would take care of everything but we failed to find a suitable one so we re going to do it ourselves. Cleanup the dpkg perl API and create libdpkg-perl: DONE libdpkg-perl has been introduced with dpkg 1.15.6. Create dpkg-buildflags: DONE dpkg-buildflags has been introduced with dpkg 1.15.7. It s not widely used yet and it won t really be until debhelper 7 supports it (see #544844). It would be nice to see progress on this front this year. Ensure the new source formats continue to gain acceptance: DONE The adoption rate has been steady, it clearly slowed down since the freeze though. I have implemented quite a few features to satisfy the needs of users, like the possibility to unapply the patches after the build, or the possibility to fail in case of unwanted upstream changes. Design a generic vcs-buildpackage infrastructure to be integrated in dpkg-dev: NOT DONE I believe it s something important on the long term but it never made it to my short-term TODO list and it s unlikely to change any time soon. Continue fixing dpkg bugs faster than they are reported: PARTLY DONE We have dealt with many bugs over the year, but we still have 20 more bugs than at the start of last year (370 vs 350). We re not doing bad compared to many other Debian teams but we can still benefit from some help. Start here if you re interested. Enhance our infrastructure to ease interaction between contributors and to have a better view of how each package is maintained: NOT DONE I am convinced that we need something to have a clearer idea of the commitments made by each contributor. I don t put the same amount of care in maintaining smarty-gettext that I do on dpkg. If we had a database of the stuff that we know we don t do well enough, it s easier to point new contributors towards those. Anyway, this project is still unlikely to come to the top of my priorities any time soon. Work on the developers-reference: NOT DONE We have switched the Maintainer field to debian-policy@lists.debian.org to have more review of the changes suggested through the bug tracking system but that has not changed much on the global situation. I still hope to become more active on it sometimes this year. Maybe by trying to make it more fun and creating the text for some of the wishlist bugs as blog articles first. Rewrite in C the last Perl scripts provided by the dpkg binary package: DONE Dpkg 1.15.8 was the first version working without Perl, I announced it in July. Integrate the 3-way merge tool for Debian changelogs in dpkg-dev: DONE dpkg-mergechangelogs is part of dpkg-dev since 1.15.7. I enjoy it regularly. Unfortunately it doesn t work well for cherry-picks. Would be nice to see this fixed, anyone up to the task? :-)
Click here to subscribe to my free newsletter and get my monthly analysis on what s going on in Debian and Ubuntu. Or just follow along via the RSS feed, Identi.ca, Twitter or Facebook.

One comment Liked this article? Click here. My blog is Flattr-enabled.

Michal &#268;iha&#345;: Useful parameters for Lintian

Every time I review some package for sponsoring, I usually end up suggesting to fix some of more picky things which lintian finds. It looks like everybody is using default set of checks and does not look at others. Indeed the defaults tell about things which are really errors or need override, but --pedantic and --display-info show also useful hints. However you need to take them more as a suggestions than as a errors. What I usually find interesting is --pedantic, because it tells about several things, which might be good idea to have in your package. Missing Homepage in debian/control is one of them and I believe this should exist for every package which has a homepage. The --display-info (or just -I) is also useful, for example it does spell checking of texts in binaries and man pages. Registration into doc-base is also useful integration into the system and you should definitely do it if the package provides documentation in HTML. To run these checks every time, you can create alias in your ~/.bashrc:
alias lintian='lintian -I --pedantic'

Filed under: Debian English 7 comments Flattr this!

16 January 2011

Gregor Herrmann: RC bugs 2011/01 - 2011/02

new year, new RC bugs most of the fixes below are for newly reported bugs in versions that don't affect squeeze. the rest are mainly uploads of packages or patches prepared by others.
Dirk Eddelbuettel: Plotting overbought / oversold regions in R

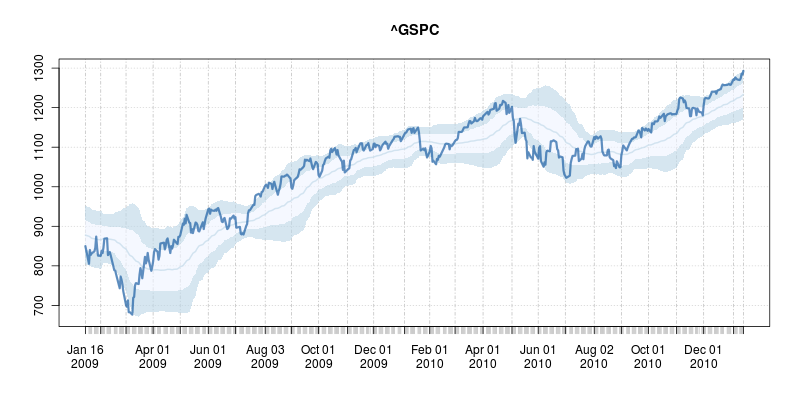
The good folks at Bespoke Investment Group frequently show charts of so-called overbought or oversold levels; see e.g. here for the most recent global markets snapshot. Classifying markets as overbought or oversold is a popular heuristic. It starts from computing a rolling smoothed estimate of the prices, usually via a (exponential or standard) moving average over a suitable number of days (where Bespoke uses 50 days, see here). This is typically coupled with a (simple) rolling standard deviation. Overbought and oversold regions are then constructed by taking the smoothed mean plus/minus one and two standard deviations. Doing this is in R is pretty easy thanks to the combination of R's rich base functions and its add-on packages from CRAN. Below is a simply function I wrote a couple of months ago---and I figured I might as well release. It relies on the powerful packages quantmod and TTR by my pals Jeff Ryan and Josh Ulrich, respectively.
## plotOBOS -- displaying overbough/oversold as eg in Bespoke's plots
##
## Copyright (C) 2010 - 2011  Dirk Eddelbuettel
##
## This is free software: you can redistribute it and/or modify it
## under the terms of the GNU General Public License as published by
## the Free Software Foundation, either version 2 of the License, or
## (at your option) any later version.
suppressMessages(library(quantmod))     # for getSymbols(), brings in xts too
suppressMessages(library(TTR))          # for various moving averages
plotOBOS <- function(symbol, n=50, type=c("sma", "ema", "zlema"), years=1, blue=TRUE)  
    today <- Sys.Date()
    X <- getSymbols(symbol, src="yahoo", from=format(today-365*years-2*n), auto.assign=FALSE)
    x <- X[,6]                          # use Adjusted
    type <- match.arg(type)
    xd <- switch(type,                  # compute xd as the central location via selected MA smoother
                 sma = SMA(x,n),
                 ema = EMA(x,n),
                 zlema = ZLEMA(x,n))
    xv <- runSD(x, n)                   # compute xv as the rolling volatility
    strt <- paste(format(today-365*years), "::", sep="")
    x  <- x[strt]                       # subset plotting range using xts' nice functionality
    xd <- xd[strt]
    xv <- xv[strt]
    xyd <- xy.coords(.index(xd),xd[,1]) # xy coordinates for direct plot commands
    xyv <- xy.coords(.index(xv),xv[,1])
    n <- length(xyd$x)
    xx <- xyd$x[c(1,1:n,n:1)]           # for polygon(): from first point to last and back
    if (blue)  
        blues5 <- c("#EFF3FF", "#BDD7E7", "#6BAED6", "#3182BD", "#08519C") # cf brewer.pal(5, "Blues")
        fairlylight <- rgb(189/255, 215/255, 231/255, alpha=0.625) # aka blues5[2]
        verylight <- rgb(239/255, 243/255, 255/255, alpha=0.625) # aka blues5[1]
        dark <- rgb(8/255, 81/255, 156/255, alpha=0.625) # aka blues5[5]
      else  
        fairlylight <- rgb(204/255, 204/255, 204/255, alpha=0.5)         # grays with alpha-blending at 50%
        verylight <- rgb(242/255, 242/255, 242/255, alpha=0.5)
        dark <- 'black'
     
    plot(x, ylim=range(range(xd+2*xv, xd-2*xv, na.rm=TRUE)), main=symbol, col=fairlylight) 		# basic xts plot
    polygon(x=xx, y=c(xyd$y[1]+xyv$y[1], xyd$y+2*xyv$y, rev(xyd$y+xyv$y)), border=NA, col=fairlylight) 	# upper
    polygon(x=xx, y=c(xyd$y[1]-1*xyv$y[1], xyd$y+1*xyv$y, rev(xyd$y-1*xyv$y)), border=NA, col=verylight)# center
    polygon(x=xx, y=c(xyd$y[1]-xyv$y[1], xyd$y-2*xyv$y, rev(xyd$y-xyv$y)), border=NA, col=fairlylight) 	# lower
    lines(xd, lwd=2, col=fairlylight)   # central smooted location
    lines(x, lwd=3, col=dark)           # actual price, thicker
    invisible(NULL)
 
After downloading data and computing the rolling smoothed mean and standard deviation, it really is just a matter of plotting (appropriate) filled polygons. Here I used colors from the neat RColorBrewer package with some alpha blending. Colors can be turned off via an option to the function; ranges, data length and type of smoother can also be picked. To call this in R, simply source the file and the call, say, plotOBOS("^GSPC", years=2) which creates a two-year plot of the SP500 as shown here: Example chart of overbought/oversold levels from plotOBOS() function This shows the market did indeed bounce off the oversold lows nicely on a few occassions in 2009 and 2010 --- but also continued to slide after hitting the condition. Nothing is foolproof, and certainly nothing as simple as this is, so buyer beware. But it may prove useful in conjunction with other tools. The code for the script is here and of course available under GPL 2 or later. I'd be happy to help incorporate it into some other finance package. Lastly, if you read this post this far, also consider our R / Finance conference coming at the end of April.

Edit: Corrected several typos with thanks to Josh.

Next.

Previous.