Search Results: "beh"

20 May 2022

Louis-Philippe V ronneau: Introducing metalfinder

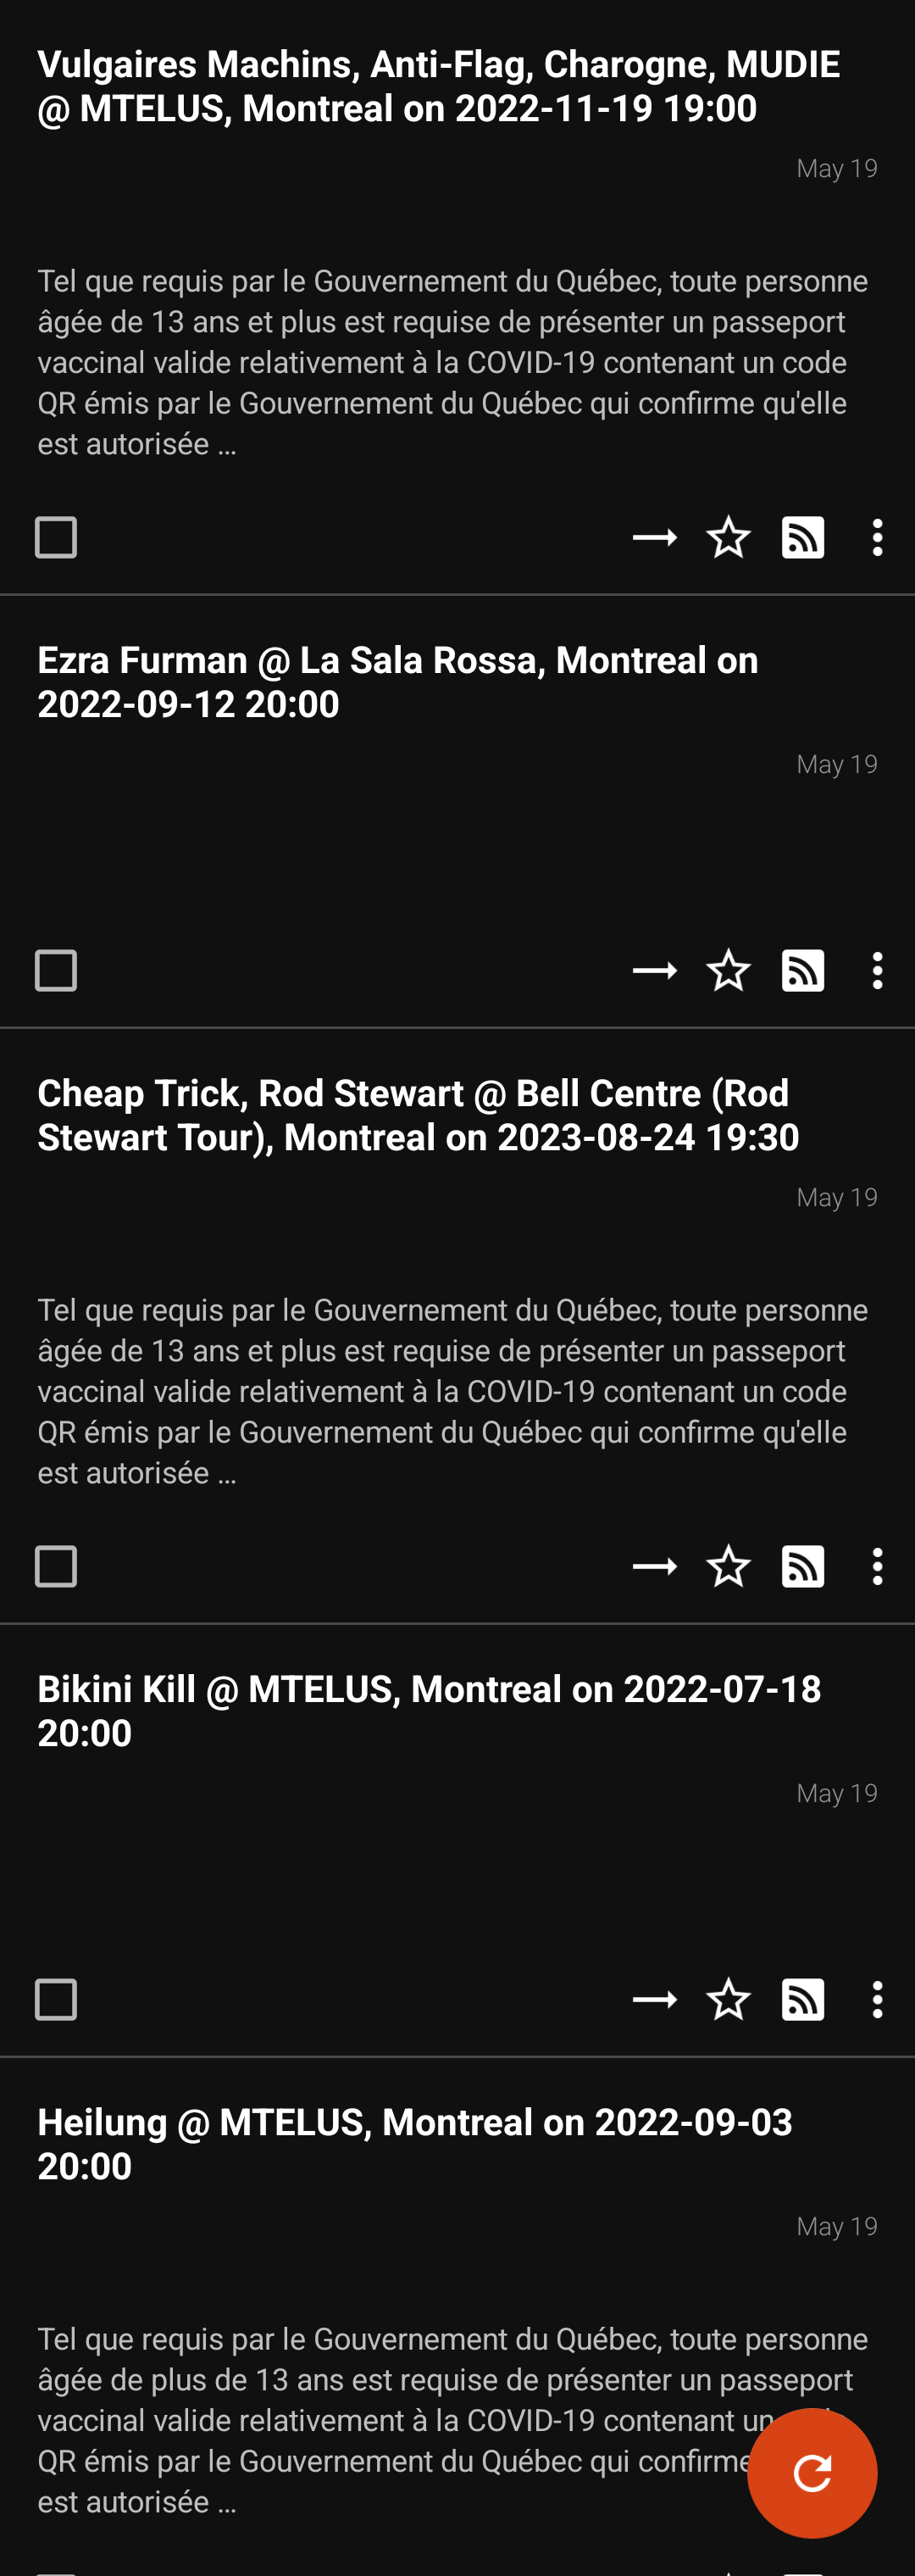
After going to an incredible Arch Enemy / Behemoth / Napalm Death / Unto Others concert a few weeks ago, I decided I wanted to go to more concerts. I like music, and I really enjoy concerts. Sadly, I often miss great performances because no one told me about it, or my local newspaper didn't cover the event enough in advance for me to get tickets. Some online services lets you sync your Spotify account to notify you when a new concert is announced, but I don't use Spotify. As a music geek, I have a local music collection and if I need to stream it, I have a supysonic server. Introducing metalfinder, a cli tool to find concerts using your local music collection! At the moment, it scans your music collection, creates a list of artists and queries Bandsintown for concerts in your town. Multiple output formats are supported, but I mainly use the ATOM one, as I'm a heavy feed reader user. Screenshot of the ATOM output in my feed reader The current metalfinder version (1.1.1) is a MVP: it works well enough, but I still have a lot of work to do... If you want to give it a try, the easiest way is to download it from PyPi. metalfinder is also currently in NEW and I'm planning to have something feature complete in time for the Bookworm freeze.

13 May 2022

Antoine Beaupr : BTRFS notes

I'm not a fan of BTRFS. This page serves as a reminder of why, but also a cheat sheet to figure out basic tasks in a BTRFS environment because those are not obvious to me, even after repeatedly having to deal with them. Content warning: there might be mentions of ZFS.

Stability concerns I'm worried about BTRFS stability, which has been historically ... changing. RAID-5 and RAID-6 are still marked unstable, for example. It's kind of a lucky guess whether your current kernel will behave properly with your planned workload. For example, in Linux 4.9, RAID-1 and RAID-10 were marked as "mostly OK" with a note that says:
Needs to be able to create two copies always. Can get stuck in irreversible read-only mode if only one copy can be made.
Even as of now, RAID-1 and RAID-10 has this note:
The simple redundancy RAID levels utilize different mirrors in a way that does not achieve the maximum performance. The logic can be improved so the reads will spread over the mirrors evenly or based on device congestion.
Granted, that's not a stability concern anymore, just performance. A reviewer of a draft of this article actually claimed that BTRFS only reads from one of the drives, which hopefully is inaccurate, but goes to show how confusing all this is. There are other warnings in the Debian wiki that are quite scary. Even the legendary Arch wiki has a warning on top of their BTRFS page, still. Even if those issues are now fixed, it can be hard to tell when they were fixed. There is a changelog by feature but it explicitly warns that it doesn't know "which kernel version it is considered mature enough for production use", so it's also useless for this. It would have been much better if BTRFS was released into the world only when those bugs were being completely fixed. Or that, at least, features were announced when they were stable, not just "we merged to mainline, good luck". Even now, we get mixed messages even in the official BTRFS documentation which says "The Btrfs code base is stable" (main page) while at the same time clearly stating unstable parts in the status page (currently RAID56). There are much harsher BTRFS critics than me out there so I will stop here, but let's just say that I feel a little uncomfortable trusting server data with full RAID arrays to BTRFS. But surely, for a workstation, things should just work smoothly... Right? Well, let's see the snags I hit.

My BTRFS test setup Before I go any further, I should probably clarify how I am testing BTRFS in the first place. The reason I tried BTRFS is that I was ... let's just say "strongly encouraged" by the LWN editors to install Fedora for the terminal emulators series. That, in turn, meant the setup was done with BTRFS, because that was somewhat the default in Fedora 27 (or did I want to experiment? I don't remember, it's been too long already). So Fedora was setup on my 1TB HDD and, with encryption, the partition table looks like this:
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  /boot/efi
 sda2                   8:2    0     1G  0 part  /boot
 sda3                   8:3    0   7,8G  0 part  
   fedora_swap        253:5    0   7.8G  0 crypt [SWAP]
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /
(This might not entirely be accurate: I rebuilt this from the Debian side of things.) This is pretty straightforward, except for the swap partition: normally, I just treat swap like any other logical volume and create it in a logical volume. This is now just speculation, but I bet it was setup this way because "swap" support was only added in BTRFS 5.0. I fully expect BTRFS experts to yell at me now because this is an old setup and BTRFS is so much better now, but that's exactly the point here. That setup is not that old (2018? old? really?), and migrating to a new partition scheme isn't exactly practical right now. But let's move on to more practical considerations.

No builtin encryption BTRFS aims at replacing the entire mdadm, LVM, and ext4 stack with a single entity, and adding new features like deduplication, checksums and so on. Yet there is one feature it is critically missing: encryption. See, my typical stack is actually mdadm, LUKS, and then LVM and ext4. This is convenient because I have only a single volume to decrypt. If I were to use BTRFS on servers, I'd need to have one LUKS volume per-disk. For a simple RAID-1 array, that's not too bad: one extra key. But for large RAID-10 arrays, this gets really unwieldy. The obvious BTRFS alternative, ZFS, supports encryption out of the box and mixes it above the disks so you only have one passphrase to enter. The main downside of ZFS encryption is that it happens above the "pool" level so you can typically see filesystem names (and possibly snapshots, depending on how it is built), which is not the case with a more traditional stack.

Subvolumes, filesystems, and devices I find BTRFS's architecture to be utterly confusing. In the traditional LVM stack (which is itself kind of confusing if you're new to that stuff), you have those layers:
  • disks: let's say /dev/nvme0n1 and nvme1n1
  • RAID arrays with mdadm: let's say the above disks are joined in a RAID-1 array in /dev/md1
  • volume groups or VG with LVM: the above RAID device (technically a "physical volume" or PV) is assigned into a VG, let's call it vg_tbbuild05 (multiple PVs can be added to a single VG which is why there is that abstraction)
  • LVM logical volumes: out of that volume group actually "virtual partitions" or "logical volumes" are created, that is where your filesystem lives
  • filesystem, typically with ext4: that's your normal filesystem, which treats the logical volume as just another block device
A typical server setup would look like this:
NAME                      MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
nvme0n1                   259:0    0   1.7T  0 disk  
 nvme0n1p1               259:1    0     8M  0 part  
 nvme0n1p2               259:2    0   512M  0 part  
   md0                     9:0    0   511M  0 raid1 /boot
 nvme0n1p3               259:3    0   1.7T  0 part  
   md1                     9:1    0   1.7T  0 raid1 
     crypt_dev_md1       253:0    0   1.7T  0 crypt 
       vg_tbbuild05-root 253:1    0    30G  0 lvm   /
       vg_tbbuild05-swap 253:2    0 125.7G  0 lvm   [SWAP]
       vg_tbbuild05-srv  253:3    0   1.5T  0 lvm   /srv
 nvme0n1p4               259:4    0     1M  0 part
I stripped the other nvme1n1 disk because it's basically the same. Now, if we look at my BTRFS-enabled workstation, which doesn't even have RAID, we have the following:
  • disk: /dev/sda with, again, /dev/sda4 being where BTRFS lives
  • filesystem: fedora_crypt, which is, confusingly, kind of like a volume group. it's where everything lives. i think.
  • subvolumes: home, root, /, etc. those are actually the things that get mounted. you'd think you'd mount a filesystem, but no, you mount a subvolume. that is backwards.
It looks something like this to lsblk:
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  /boot/efi
 sda2                   8:2    0     1G  0 part  /boot
 sda3                   8:3    0   7,8G  0 part  [SWAP]
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /srv
Notice how we don't see all the BTRFS volumes here? Maybe it's because I'm mounting this from the Debian side, but lsblk definitely gets confused here. I frankly don't quite understand what's going on, even after repeatedly looking around the rather dismal documentation. But that's what I gather from the following commands:
root@curie:/home/anarcat# btrfs filesystem show
Label: 'fedora'  uuid: 5abb9def-c725-44ef-a45e-d72657803f37
    Total devices 1 FS bytes used 883.29GiB
    devid    1 size 922.47GiB used 916.47GiB path /dev/mapper/fedora_crypt
root@curie:/home/anarcat# btrfs subvolume list /srv
ID 257 gen 108092 top level 5 path home
ID 258 gen 108094 top level 5 path root
ID 263 gen 108020 top level 258 path root/var/lib/machines
I only got to that point through trial and error. Notice how I use an existing mountpoint to list the related subvolumes. If I try to use the filesystem path, the one that's listed in filesystem show, I fail:
root@curie:/home/anarcat# btrfs subvolume list /dev/mapper/fedora_crypt 
ERROR: not a btrfs filesystem: /dev/mapper/fedora_crypt
ERROR: can't access '/dev/mapper/fedora_crypt'
Maybe I just need to use the label? Nope:
root@curie:/home/anarcat# btrfs subvolume list fedora
ERROR: cannot access 'fedora': No such file or directory
ERROR: can't access 'fedora'
This is really confusing. I don't even know if I understand this right, and I've been staring at this all afternoon. Hopefully, the lazyweb will correct me eventually. (As an aside, why are they called "subvolumes"? If something is a "sub" of "something else", that "something else" must exist right? But no, BTRFS doesn't have "volumes", it only has "subvolumes". Go figure. Presumably the filesystem still holds "files" though, at least empirically it doesn't seem like it lost anything so far. In any case, at least I can refer to this section in the future, the next time I fumble around the btrfs commandline, as I surely will. I will possibly even update this section as I get better at it, or based on my reader's judicious feedback.

Mounting BTRFS subvolumes So how did I even get to that point? I have this in my /etc/fstab, on the Debian side of things:
UUID=5abb9def-c725-44ef-a45e-d72657803f37   /srv    btrfs  defaults 0   2
This thankfully ignores all the subvolume nonsense because it relies on the UUID. mount tells me that's actually the "root" (? /?) subvolume:
root@curie:/home/anarcat# mount   grep /srv
/dev/mapper/fedora_crypt on /srv type btrfs (rw,relatime,space_cache,subvolid=5,subvol=/)
Let's see if I can mount the other volumes I have on there. Remember that subvolume list showed I had home, root, and var/lib/machines. Let's try root:
mount -o subvol=root /dev/mapper/fedora_crypt /mnt
Interestingly, root is not the same as /, it's a different subvolume! It seems to be the Fedora root (/, really) filesystem. No idea what is happening here. I also have a home subvolume, let's mount it too, for good measure:
mount -o subvol=home /dev/mapper/fedora_crypt /mnt/home
Note that lsblk doesn't notice those two new mountpoints, and that's normal: it only lists block devices and subvolumes (rather inconveniently, I'd say) do not show up as devices:
root@curie:/home/anarcat# lsblk 
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  
 sda2                   8:2    0     1G  0 part  
 sda3                   8:3    0   7,8G  0 part  
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /srv
This is really, really confusing. Maybe I did something wrong in the setup. Maybe it's because I'm mounting it from outside Fedora. Either way, it just doesn't feel right.

No disk usage per volume If you want to see what's taking up space in one of those subvolumes, tough luck:
root@curie:/home/anarcat# df -h  /srv /mnt /mnt/home
Filesystem                Size  Used Avail Use% Mounted on
/dev/mapper/fedora_crypt  923G  886G   31G  97% /srv
/dev/mapper/fedora_crypt  923G  886G   31G  97% /mnt
/dev/mapper/fedora_crypt  923G  886G   31G  97% /mnt/home
(Notice, in passing, that it looks like the same filesystem is mounted in different places. In that sense, you'd expect /srv and /mnt (and /mnt/home?!) to be exactly the same, but no: they are entirely different directory structures, which I will not call "filesystems" here because everyone's head will explode in sparks of confusion.) Yes, disk space is shared (that's the Size and Avail columns, makes sense). But nope, no cookie for you: they all have the same Used columns, so you need to actually walk the entire filesystem to figure out what each disk takes. (For future reference, that's basically:
root@curie:/home/anarcat# time du -schx /mnt/home /mnt /srv
124M    /mnt/home
7.5G    /mnt
875G    /srv
883G    total
real    2m49.080s
user    0m3.664s
sys 0m19.013s
And yes, that was painfully slow.) ZFS actually has some oddities in that regard, but at least it tells me how much disk each volume (and snapshot) takes:
root@tubman:~# time df -t zfs -h
Filesystem         Size  Used Avail Use% Mounted on
rpool/ROOT/debian  3.5T  1.4G  3.5T   1% /
rpool/var/tmp      3.5T  384K  3.5T   1% /var/tmp
rpool/var/spool    3.5T  256K  3.5T   1% /var/spool
rpool/var/log      3.5T  2.0G  3.5T   1% /var/log
rpool/home/root    3.5T  2.2G  3.5T   1% /root
rpool/home         3.5T  256K  3.5T   1% /home
rpool/srv          3.5T   80G  3.5T   3% /srv
rpool/var/cache    3.5T  114M  3.5T   1% /var/cache
bpool/BOOT/debian  571M   90M  481M  16% /boot
real    0m0.003s
user    0m0.002s
sys 0m0.000s
That's 56360 times faster, by the way. But yes, that's not fair: those in the know will know there's a different command to do what df does with BTRFS filesystems, the btrfs filesystem usage command:
root@curie:/home/anarcat# time btrfs filesystem usage /srv
Overall:
    Device size:         922.47GiB
    Device allocated:        916.47GiB
    Device unallocated:        6.00GiB
    Device missing:          0.00B
    Used:            884.97GiB
    Free (estimated):         30.84GiB  (min: 27.84GiB)
    Free (statfs, df):        30.84GiB
    Data ratio:               1.00
    Metadata ratio:           2.00
    Global reserve:      512.00MiB  (used: 0.00B)
    Multiple profiles:              no
Data,single: Size:906.45GiB, Used:881.61GiB (97.26%)
   /dev/mapper/fedora_crypt  906.45GiB
Metadata,DUP: Size:5.00GiB, Used:1.68GiB (33.58%)
   /dev/mapper/fedora_crypt   10.00GiB
System,DUP: Size:8.00MiB, Used:128.00KiB (1.56%)
   /dev/mapper/fedora_crypt   16.00MiB
Unallocated:
   /dev/mapper/fedora_crypt    6.00GiB
real    0m0,004s
user    0m0,000s
sys 0m0,004s
Almost as fast as ZFS's df! Good job. But wait. That doesn't actually tell me usage per subvolume. Notice it's filesystem usage, not subvolume usage, which unhelpfully refuses to exist. That command only shows that one "filesystem" internal statistics that are pretty opaque.. You can also appreciate that it's wasting 6GB of "unallocated" disk space there: I probably did something Very Wrong and should be punished by Hacker News. I also wonder why it has 1.68GB of "metadata" used... At this point, I just really want to throw that thing out of the window and restart from scratch. I don't really feel like learning the BTRFS internals, as they seem oblique and completely bizarre to me. It feels a little like the state of PHP now: it's actually pretty solid, but built upon so many layers of cruft that I still feel it corrupts my brain every time I have to deal with it (needle or haystack first? anyone?)...

Conclusion I find BTRFS utterly confusing and I'm worried about its reliability. I think a lot of work is needed on usability and coherence before I even consider running this anywhere else than a lab, and that's really too bad, because there are really nice features in BTRFS that would greatly help my workflow. (I want to use filesystem snapshots as high-performance, high frequency backups.) So now I'm experimenting with OpenZFS. It's so much simpler, just works, and it's rock solid. After this 8 minute read, I had a good understanding of how ZFS worked. Here's the 30 seconds overview:
  • vdev: a RAID array
  • vpool: a volume group of vdevs
  • datasets: normal filesystems (or block device, if you want to use another filesystem on top of ZFS)
There's also other special volumes like caches and logs that you can (really easily, compared to LVM caching) use to tweak your setup. You might also want to look at recordsize or ashift to tweak the filesystem to fit better your workload (or deal with drives lying about their sector size, I'm looking at you Samsung), but that's it. Running ZFS on Linux currently involves building kernel modules from scratch on every host, which I think is pretty bad. But I was able to setup a ZFS-only server using this excellent documentation without too much problem. I'm hoping some day the copyright issues are resolved and we can at least ship binary packages, but the politics (e.g. convincing Debian that is the right thing to do) and the logistics (e.g. DKMS auto-builders? is that even a thing? how about signed DKMS packages? fun-fun-fun!) seem really impractical. Who knows, maybe hell will freeze over (again) and Oracle will fix the CDDL. I personally think that we should just completely ignore this problem (which wasn't even supposed to be a problem) and ship binary packages directly, but I'm a pragmatic and do not always fit well with the free software fundamentalists. All of this to say that, short term, we don't have a reliable, advanced filesystem/logical disk manager in Linux. And that's really too bad.

10 May 2022

Russell Coker: Elon and Free Speech

Elon Musk has made the news for spending billions to buy a share of Twitter for the alleged purpose of providing free speech. The problem with this claim is that having any company controlling a large portion of the world s communication is inherently bad for free speech. The same applies for Facebook, but that s not a hot news item at the moment. If Elon wanted to provide free speech he would want to have decentralised messaging systems so that someone who breaks rules on one platform could find another with different rules. Among other things free speech ideally permits people to debate issues with residents of another country on issues related to different laws. If advocates for the Russian government get kicked off Twitter as part of the American sanctions against Russia then American citizens can t debate the issue with Russian citizens via Twitter. Mastodon is one example of a federated competitor to Twitter [1]. With a federated messaging system each host could make independent decisions about interpretation of sanctions. Someone who used a Mastodon instance based in the US could get a second account in another country if they wanted to communicate with people in countries that are sanctioned by the US. The problem with Mastodon at the moment is lack of use. It s got a good set of features and support for different platforms, there are apps for Android and iPhone as well as lots of other software using the API. But if the people you want to communicate with aren t on it then it s less useful. Elon could solve that problem by creating a Tesla Mastodon server and give a free account to everyone who buys a new Tesla, which is the sort of thing that a lot of Tesla buyers would like. It s quite likely that other companies selling prestige products would follow that example. Everyone has seen evidence of people sharing photos on social media with someone else s expensive car, a Mastodon account on ferrari.com or mercedes.com would be proof of buying the cars in question. The number of people who buy expensive cars new is a very small portion of the world population, but it s a group of people who are more influential than average and others would join Mastodon servers to follow them. The next thing that Elon could do to kill Twitter would be to have all his companies (which have something more than a dozen verified Twitter accounts) use Mastodon accounts for their primary PR releases and then send the same content to Twitter with a 48 hour delay. That would force journalists and people who want to discuss those companies on social media to follow the Mastodon accounts. Again this wouldn t be a significant number of people, but they would be influential people. Getting journalists to use a communications system increases it s importance. The question is whether Elon is lacking the vision necessary to plan a Mastodon deployment or whether he just wants to allow horrible people to run wild on Twitter. The Verge has an interesting article from 2019 about Gab using Mastodon [2]. The fact that over the last 2.5 years I didn t even hear of Gab using Mastodon suggests that the fears of some people significantly exceeded the problem. I m sure that some Gab users managed to harass some Mastodon users, but generally they were apparently banned quickly. As an aside the Mastodon server I use doesn t appear to ban Gab, a search for Gab on it gave me a user posting about being pureblood at the top of the list. Gab claims to have 4 million accounts and has an estimated 100,000 active users. If 5.5% of Tesla owners became active users on a hypothetical Tesla server that would be the largest Mastodon server. Elon could demonstrate his commitment to free speech by refusing to ban Gab in any way. The Wikipedia page about Gab [3] has a long list of horrible people and activities associated with it. Is that the free speech to associate with Tesla? Polestar makes some nice electric cars that appear quite luxurious [4] and doesn t get negative PR from the behaviour of it s owner, that s something Elon might want to consider. Is this really about bragging rights? Buying a controlling interest in a company that has a partial monopoly on Internet communication is something to boast about. Could users of commercial social media be considered serfs who serve their billionaire overlord?

6 May 2022

Antoine Beaupr : Wallabako 1.4.0 released

I don't particularly like it when people announce their personal projects on their blog, but I'm making an exception for this one, because it's a little special for me. You see, I have just released Wallabako 1.4.0 (and a quick, mostly irrelevant 1.4.1 hotfix) today. It's the first release of that project in almost 3 years (the previous was 1.3.1, before the pandemic). The other reason I figured I would mention it is that I have almost never talked about Wallabako on this blog at all, so many of my readers probably don't even know I sometimes meddle with in Golang which surprises even me sometimes.

What's Wallabako Wallabako is a weird little program I designed to read articles on my E-book reader. I use it to spend less time on the computer: I save articles in a read-it-later app named Wallabag (hosted by a generous friend), and then Wallabako connects to that app, downloads an EPUB version of the book, and then I can read it on the device directly. When I'm done reading the book, Wallabako notices and sets the article as read in Wallabag. I also set it to delete the book locally, but you can actually configure to keep those books around forever if you feel like it. Wallabako supports syncing read status with the built-in Kobo interface (called "Nickel"), Koreader and Plato. I happen to use Koreader for everything nowadays, but it should work equally well on the others. Wallabako is actually setup to be started by udev when there's a connection change detected by the kernel, which is kind of a gross hack. It's clunky, but actually works and I thought for a while about switching to something else, but it's really the easiest way to go, and that requires the less interaction by the user.

Why I'm (still) using it I wrote Wallabako because I read a lot of articles on the internet. It's actually most of my readings. I read about 10 books a year (which I don't think is much), but I probably read more in terms of time and pages in Wallabag. I haven't actually made the math, but I estimate I spend at least double the time reading articles than I spend reading books. If I wouldn't have Wallabag, I would have hundreds of tabs open in my web browser all the time. So at least that problem is easily solved: throw everything in Wallabag, sort and read later. If I wouldn't have Wallabako however, I would be either spend that time reading on the computer -- which I prefer to spend working on free software or work -- or on my phone -- which is kind of better, but really cramped. I had stopped (and developing) Wallabako for a while, actually, Around 2019, I got tired of always read those technical articles (basically work stuff!) at home. I realized I was just not "reading" (as in books! fiction! fun stuff!) anymore, at least not as much as I wanted. So I tried to make this separation: the ebook reader is for cool book stuff. The rest is work. But because I had the Wallabag Android app on my phone and tablet, I could still read those articles there, which I thought was pretty neat. But that meant that I was constantly looking at my phone, which is something I'm generally trying to avoid, as it sets a bad example for the kids (small and big) around me. Then I realized there was one stray ebook reader lying around at home. I had recently bought a Kobo Aura HD to read books, and I like that device. And it's going to stay locked down to reading books. But there's still that old battered Kobo Glo HD reader lying around, and I figured I could just borrow it to read Wallabag articles.

What is this new release But oh boy that was a lot of work. Wallabako was kind of a mess: it was using the deprecated go dep tool, which lost the battle with go mod. Cross-compilation was broken for older devices, and I had to implement support for Koreader.

go mod So I had to learn go mod. I'm still not sure I got that part right: LSP is yelling at me because it can't find the imports, and I'm generally just "YOLO everythihng" every time I get anywhere close to it. That's not the way to do Go, in general, and not how I like to do it either. But I guess that, given time, I'll figure it out and make it work for me. It certainly works now. I think.

Cross compilation The hard part was different. You see, Nickel uses SQLite to store metadata about books, so Wallabako actually needs to tap into that SQLite database to propagate read status. Originally, I just linked against some sqlite3 library I found lying around. It's basically a wrapper around the C-based SQLite and generally works fine. But that means you actually link your Golang program against a C library. And that's when things get a little nutty. If you would just build Wallabag naively, it would fail when deployed on the Kobo Glo HD. That's because the device runs a really old kernel: the prehistoric Linux kobo 2.6.35.3-850-gbc67621+ #2049 PREEMPT Mon Jan 9 13:33:11 CST 2017 armv7l GNU/Linux. That was built in 2017, but the kernel was actually released in 2010, a whole 5 years before the Glo HD was released, in 2015 which is kind of outrageous. and yes, that is with the latest firmware release. My bet is they just don't upgrade the kernel on those things, as the Glo was probably bought around 2017... In any case, the problem is we are cross-compiling here. And Golang is pretty good about cross-compiling, but because we have C in there, we're actually cross-compiling with "CGO" which is really just Golang with a GCC backend. And that's much, much harder to figure out because you need to pass down flags into GCC and so on. It was a nightmare. That's until I found this outrageous "little" project called modernc.org/sqlite. What that thing does (with a hefty does of dependencies that would make any Debian developer recoil in horror) is to transpile the SQLite C source code to Golang. You read that right: it rewrites SQLite in Go. On the fly. It's nuts. But it works. And you end up with a "pure go" program, and that thing compiles much faster and runs fine on older kernel. I still wasn't sure I wanted to just stick with that forever, so I kept the old sqlite3 code around, behind a compile-time tag. At the top of the nickel_modernc.go file, there's this magic string:
//+build !sqlite3
And at the top of nickel_sqlite3.go file, there's this magic string:
//+build sqlite3
So now, by default, the modernc file gets included, but if I pass --tags sqlite3 to the Go compiler (to go install or whatever), it will actually switch to the other implementation. Pretty neat stuff.

Koreader port The last part was something I was hesitant in doing for a long time, but that turned out to be pretty easy. I have basically switch to using Koreader to read everything. Books, PDF, everything goes through it. I really like that it stores its metadata in sidecar files: I synchronize all my books with Syncthing which means I can carry my read status, annotations and all that stuff without having to think about it. (And yes, I installed Syncthing on my Kobo.) The koreader.go port was less than 80 lines, and I could even make a nice little test suite so that I don't have to redeploy that thing to the ebook reader at every code iteration. I had originally thought I should add some sort of graphical interface in Koreader for Wallabako as well, and had requested that feature upstream. Unfortunately (or fortunately?), they took my idea and just ran with it. Some courageous soul actually wrote a full Wallabag plugin for koreader, in Lua of course. Compared to the Wallabako implementation however, the koreader plugin is much slower, probably because it downloads articles serially instead of concurrently. It is, however, much more usable as the user is given a visible feedback of the various steps. I still had to enable full debugging to diagnose a problem (which was that I shouldn't have a trailing slash, and that some special characters don't work in passwords). It's also better to write the config file with a normal text editor, over SSH or with the Kobo mounted to your computer instead of typing those really long strings over the kobo. There's no sample config file which makes that harder but a workaround is to save the configuration with dummy values and fix them up after. Finally I also found the default setting ("Remotely delete finished articles") really dangerous as it can basically lead to data loss (Wallabag article being deleted!) for an unsuspecting user... So basically, I started working on Wallabag again because the koreader implementation of their Wallabag client was not up to spec for me. It might be good enough for you, but I guess if you like Wallabako, you should thank the koreader folks for their sloppy implementation, as I'm now working again on Wallabako.

Actual release notes Those are the actual release notes for 1.4.0.
Ship a lot of fixes that have accumulated in the 3 years since the last release. Features:
  • add timestamp and git version to build artifacts
  • cleanup and improve debugging output
  • switch to pure go sqlite implementation, which helps
  • update all module dependencies
  • port to wallabago v6
  • support Plato library changes from 0.8.5+
  • support reading koreader progress/read status
  • Allow containerized builds, use gomod and avoid GOPATH hell
  • overhaul Dockerfile
  • switch to go mod
Documentation changes:
  • remove instability warning: this works well enough
  • README: replace branch name master by main in links
  • tweak mention of libreoffice to clarify concern
  • replace "kobo" references by "nickel" where appropriate
  • make a section about related projects
  • mention NickelMenu
  • quick review of the koreader implementation
Bugfixes:
  • handle errors in http request creation
  • Use OutputDir configuration instead of hardcoded wallabako paths
  • do not noisily fail if there's no entry for book in plato
  • regression: properly detect read status again after koreader (or plato?) support was added

How do I use this?
This is amazing. I can't believe someone did something that awesome. I want to cover you with gold and Tesla cars and fresh water.
You're weird please stop. But if you want to use Wallabako, head over to the README file which has installation instructions. It basically uses a hack in Kobo e-readers that will happily overwrite their root filesystem as soon as you drop this file named KoboRoot.tgz in the .kobo directory of your e-reader. Note that there is no uninstall procedure and it messes with the reader's udev configuration (to trigger runs on wifi connect). You'll also need to create a JSON configuration file and configure a client in Wallabag. And if you're looking for Wallabag hosting, Wallabag.it offers a 14-day free trial. You can also, obviously, host it yourself. Which is not the case for Pocket, even years after Mozilla bought the company. All this wouldn't actually be necessary if Pocket was open-source because Nickel actually ships with a Pocket client. Shame on you, Mozilla. But you still make an awesome browser, so keep doing that.

5 May 2022

Reproducible Builds: Reproducible Builds in April 2022

Welcome to the April 2022 report from the Reproducible Builds project! In these reports, we try to summarise the most important things that we have been up to over the past month. If you are interested in contributing to the project, please take a few moments to visit our Contribute page on our website.

News Cory Doctorow published an interesting article this month about the possibility of Undetectable backdoors for machine learning models. Given that machine learning models can provide unpredictably incorrect results, Doctorow recounts that there exists another category of adversarial examples that comprise a gimmicked machine-learning input that, to the human eye, seems totally normal but which causes the ML system to misfire dramatically that permit the possibility of planting undetectable back doors into any machine learning system at training time .
Chris Lamb published two supporter spotlights on our blog: the first about Amateur Radio Digital Communications (ARDC) and the second about the Google Open Source Security Team (GOSST).
Piergiorgio Ladisa, Henrik Plate, Matias Martinez and Olivier Barais published a new academic paper titled A Taxonomy of Attacks on Open-Source Software Supply Chains (PDF):
This work proposes a general taxonomy for attacks on open-source supply chains, independent of specific programming languages or ecosystems, and covering all supply chain stages from code contributions to package distribution. Taking the form of an attack tree, it covers 107 unique vectors, linked to 94 real-world incidents, and mapped to 33 mitigating safeguards.

Elsewhere in academia, Ly Vu Duc published his PhD thesis. Titled Towards Understanding and Securing the OSS Supply Chain (PDF), Duc s abstract reads as follows:
This dissertation starts from the first link in the software supply chain, developers . Since many developers do not update their vulnerable software libraries, thus exposing the user of their code to security risks. To understand how they choose, manage and update the libraries, packages, and other Open-Source Software (OSS) that become the building blocks of companies completed products consumed by end-users, twenty-five semi-structured interviews were conducted with developers of both large and small-medium enterprises in nine countries. All interviews were transcribed, coded, and analyzed according to applied thematic analysis

Upstream news Filippo Valsorda published an informative blog post recently called How Go Mitigates Supply Chain Attacks outlining the high-level features of the Go ecosystem that helps prevent various supply-chain attacks.
There was new/further activity on a pull request filed against openssl by Sebastian Andrzej Siewior in order to prevent saved CFLAGS (which may contain the -fdebug-prefix-map=<PATH> flag that is used to strip an arbitrary the build path from the debug info if this information remains recorded then the binary is no longer reproducible if the build directory changes.

Events The Linux Foundation s SupplyChainSecurityCon, will take place June 21st 24th 2022, both virtually and in Austin, Texas. Long-time Reproducible Builds and openSUSE contributor Bernhard M. Wiedemann learned that he had his talk accepted, and will speak on Reproducible Builds: Unexpected Benefits and Problems on June 21st.
There will be an in-person Debian Reunion in Hamburg, Germany later this year, taking place from 23 30 May. Although this is a Debian event, there will be some folks from the broader Reproducible Builds community and, of course, everyone is welcome. Please see the event page on the Debian wiki for more information. 41 people have registered so far, and there s approx 10 on-site beds still left.
The minutes and logs from our April 2022 IRC meeting have been published. In case you missed this one, our next IRC meeting will take place on May 31st at 15:00 UTC on #reproducible-builds on the OFTC network.

Debian Roland Clobus wrote another in-depth status update about the status of live Debian images, summarising the current situation that all major desktops build reproducibly with bullseye, bookworm and sid, including the Cinnamon desktop on bookworm and sid, but at a small functionality cost: 14 words will be incorrectly abbreviated . This work incorporated:
  • Reporting an issue about unnecessarily modified timestamps in the daily Debian installer images. [ ]
  • Reporting a bug against the debian-installer: in order to use a suitable kernel version. (#1006800)
  • Reporting a bug in: texlive-binaries regarding the unreproducible content of .fmt files. (#1009196)
  • Adding hacks to make the Cinnamon desktop image reproducible in bookworm and sid. [ ]
  • Added a script to rebuild a live-build ISO image from a given timestamp. [
  • etc.
On our mailing list, Venkata Pyla started a thread on the Debian debconf cache is non-reproducible issue while creating system images and Vagrant Cascadian posted an excellent summary of the reproducibility status of core package sets in Debian and solicited for similar information from other distributions.
Lastly, 122 reviews of Debian packages were added, 44 were updated and 193 were removed this month adding to our extensive knowledge about identified issues. A number of issue types have been updated as well, including timestamps_generated_by_hevea, randomness_in_ocaml_preprocessed_files, build_path_captured_in_emacs_el_file, golang_compiler_captures_build_path_in_binary and build_path_captured_in_assembly_objects,

Other distributions Happy birthday to GNU Guix, which recently turned 10 years old! People have been sharing their stories, in which reproducible builds and bootstrappable builds are a recurring theme as a feature important to its users and developers. The experiences are available on the GNU Guix blog as well as a post on fossandcrafts.org
In openSUSE, Bernhard M. Wiedemann posted his usual monthly reproducible builds status report.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 210 and 211 to Debian unstable, as well as noticed that some Python .pyc files are reported as data, so we should support .pyc as a fallback filename extension [ ]. In addition, Mattia Rizzolo disabled the Gnumeric tests in Debian as the package is not currently available [ ] and dropped mplayer from Build-Depends too [ ]. In addition, Mattia fixed an issue to ensure that the PATH environment variable is properly modified for all actions, not just when running the comparator. [ ]

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Daniel Golle:
    • Prefer a different solution to avoid building all OpenWrt packages; skip packages from optional community feeds. [ ]
  • Holger Levsen:
    • Detect Python deprecation warnings in the node health check. [ ]
    • Detect failure to build the Debian Installer. [ ]
  • Mattia Rizzolo:
    • Install disorderfs for building OpenWrt packages. [ ]
  • Paul Spooren (OpenWrt-related changes):
    • Don t build all packages whilst the core packages are not yet reproducible. [ ]
    • Add a missing RUN directive to node_cleanup. [ ]
    • Be less verbose during a toolchain build. [ ]
    • Use disorderfs for rebuilds and update the documentation to match. [ ][ ][ ]
  • Roland Clobus:
    • Publish the last reproducible Debian ISO image. [ ]
    • Use the rebuild.sh script from the live-build package. [ ]
Lastly, node maintenance was also performed by Holger Levsen [ ][ ].
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

28 April 2022

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, March 2022

A Debian LTS logo
Every month we review the work funded by Freexian s Debian LTS offering. Please find the report for March below. Debian project funding Learn more about the rationale behind this initiative in this article. Debian LTS contributors In March, 11 contributors were paid to work on Debian LTS, their reports are available below. If you re interested in participating in the LTS or ELTS teams, we welcome participation from the Debian community. Simply get in touch with Jeremiah or Rapha l if you are if you are interested in participating. Evolution of the situation In March we released 42 DLAs. The security tracker currently lists 81 packages with a known CVE and the dla-needed.txt file has 52 packages needing an update. We re glad to welcome a few new sponsors such as lectricit de France (Gold sponsor), Telecats BV and Soliton Systems. Thanks to our sponsors Sponsors that joined recently are in bold.

27 April 2022

Antoine Beaupr : building Debian packages under qemu with sbuild

I've been using sbuild for a while to build my Debian packages, mainly because it's what is used by the Debian autobuilders, but also because it's pretty powerful and efficient. Configuring it just right, however, can be a challenge. In my quick Debian development guide, I had a few pointers on how to configure sbuild with the normal schroot setup, but today I finished a qemu based configuration.

Why I want to use qemu mainly because it provides better isolation than a chroot. I sponsor packages sometimes and while I typically audit the source code before building, it still feels like the extra protection shouldn't hurt. I also like the idea of unifying my existing virtual machine setup with my build setup. My current VM is kind of all over the place: libvirt, vagrant, GNOME Boxes, etc?). I've been slowly converging over libvirt however, and most solutions I use right now rely on qemu under the hood, certainly not chroots... I could also have decided to go with containers like LXC, LXD, Docker (with conbuilder, whalebuilder, docker-buildpackage), systemd-nspawn (with debspawn), unshare (with schroot --chroot-mode=unshare), or whatever: I didn't feel those offer the level of isolation that is provided by qemu. The main downside of this approach is that it is (obviously) slower than native builds. But on modern hardware, that cost should be minimal.

How Basically, you need this:
sudo mkdir -p /srv/sbuild/qemu/
sudo apt install sbuild-qemu
sudo sbuild-qemu-create -o /srv/sbuild/qemu/unstable.img unstable https://deb.debian.org/debian
Then to make this used by default, add this to ~/.sbuildrc:
# run autopkgtest inside the schroot
$run_autopkgtest = 1;
# tell sbuild to use autopkgtest as a chroot
$chroot_mode = 'autopkgtest';
# tell autopkgtest to use qemu
$autopkgtest_virt_server = 'qemu';
# tell autopkgtest-virt-qemu the path to the image
# use --debug there to show what autopkgtest is doing
$autopkgtest_virt_server_options = [ '--', '/srv/sbuild/qemu/%r-%a.img' ];
# tell plain autopkgtest to use qemu, and the right image
$autopkgtest_opts = [ '--', 'qemu', '/srv/sbuild/qemu/%r-%a.img' ];
# no need to cleanup the chroot after build, we run in a completely clean VM
$purge_build_deps = 'never';
# no need for sudo
$autopkgtest_root_args = '';
Note that the above will use the default autopkgtest (1GB, one core) and qemu (128MB, one core) configuration, which might be a little low on resources. You probably want to be explicit about this, with something like this:
# extra parameters to pass to qemu
# --enable-kvm is not necessary, detected on the fly by autopkgtest
my @_qemu_options = ['--ram-size=4096', '--cpus=2'];
# tell autopkgtest-virt-qemu the path to the image
# use --debug there to show what autopkgtest is doing
$autopkgtest_virt_server_options = [ @_qemu_options, '--', '/srv/sbuild/qemu/%r-%a.img' ];
$autopkgtest_opts = [ '--', 'qemu', @qemu_options, '/srv/sbuild/qemu/%r-%a.img'];
This configuration will:
  1. create a virtual machine image in /srv/sbuild/qemu for unstable
  2. tell sbuild to use that image to create a temporary VM to build the packages
  3. tell sbuild to run autopkgtest (which should really be default)
  4. tell autopkgtest to use qemu for builds and for tests
Note that the VM created by sbuild-qemu-create have an unlocked root account with an empty password.

Other useful tasks
  • enter the VM to make test, changes will be discarded (thanks Nick Brown for the sbuild-qemu-boot tip!):
     sbuild-qemu-boot /srv/sbuild/qemu/unstable-amd64.img
    
    That program is shipped only with bookworm and later, an equivalent command is:
     qemu-system-x86_64 -snapshot -enable-kvm -object rng-random,filename=/dev/urandom,id=rng0 -device virtio-rng-pci,rng=rng0,id=rng-device0 -m 2048 -nographic /srv/sbuild/qemu/unstable-amd64.img
    
    The key argument here is -snapshot.
  • enter the VM to make permanent changes, which will not be discarded:
     sudo sbuild-qemu-boot --readwrite /srv/sbuild/qemu/unstable-amd64.img
    
    Equivalent command:
     sudo qemu-system-x86_64 -enable-kvm -object rng-random,filename=/dev/urandom,id=rng0 -device virtio-rng-pci,rng=rng0,id=rng-device0 -m 2048 -nographic /srv/sbuild/qemu/unstable-amd64.img
    
  • update the VM (thanks lavamind):
     sudo sbuild-qemu-update /srv/sbuild/qemu/unstable-amd64.img
    
  • build in a specific VM regardless of the suite specified in the changelog (e.g. UNRELEASED, bookworm-backports, bookworm-security, etc):
     sbuild --autopkgtest-virt-server-opts="-- qemu /var/lib/sbuild/qemu/bookworm-amd64.img"
    
    Note that you'd also need to pass --autopkgtest-opts if you want autopkgtest to run in the correct VM as well:
     sbuild --autopkgtest-opts="-- qemu /var/lib/sbuild/qemu/unstable.img" --autopkgtest-virt-server-opts="-- qemu /var/lib/sbuild/qemu/bookworm-amd64.img"
    
    You might also need parameters like --ram-size if you customized it above.
And yes, this is all quite complicated and could be streamlined a little, but that's what you get when you have years of legacy and just want to get stuff done. It seems to me autopkgtest-virt-qemu should have a magic flag starts a shell for you, but it doesn't look like that's a thing. When that program starts, it just says ok and sits there. Maybe because the authors consider the above to be simple enough (see also bug #911977 for a discussion of this problem).

Live access to a running test When autopkgtest starts a VM, it uses this funky qemu commandline:
qemu-system-x86_64 -m 4096 -smp 2 -nographic -net nic,model=virtio -net user,hostfwd=tcp:127.0.0.1:10022-:22 -object rng-random,filename=/dev/urandom,id=rng0 -device virtio-rng-pci,rng=rng0,id=rng-device0 -monitor unix:/tmp/autopkgtest-qemu.w1mlh54b/monitor,server,nowait -serial unix:/tmp/autopkgtest-qemu.w1mlh54b/ttyS0,server,nowait -serial unix:/tmp/autopkgtest-qemu.w1mlh54b/ttyS1,server,nowait -virtfs local,id=autopkgtest,path=/tmp/autopkgtest-qemu.w1mlh54b/shared,security_model=none,mount_tag=autopkgtest -drive index=0,file=/tmp/autopkgtest-qemu.w1mlh54b/overlay.img,cache=unsafe,if=virtio,discard=unmap,format=qcow2 -enable-kvm -cpu kvm64,+vmx,+lahf_lm
... which is a typical qemu commandline, I'm sorry to say. That gives us a VM with those settings (paths are relative to a temporary directory, /tmp/autopkgtest-qemu.w1mlh54b/ in the above example):
  • the shared/ directory is, well, shared with the VM
  • port 10022 is forward to the VM's port 22, presumably for SSH, but not SSH server is started by default
  • the ttyS1 and ttyS2 UNIX sockets are mapped to the first two serial ports (use nc -U to talk with those)
  • the monitor UNIX socket is a qemu control socket (see the QEMU monitor documentation, also nc -U)
In other words, it's possible to access the VM with:
nc -U /tmp/autopkgtest-qemu.w1mlh54b/ttyS2
The nc socket interface is ... not great, but it works well enough. And you can probably fire up an SSHd to get a better shell if you feel like it.

Nitty-gritty details no one cares about

Fixing hang in sbuild cleanup I'm having a hard time making heads or tails of this, but please bear with me. In sbuild + schroot, there's this notion that we don't really need to cleanup after ourselves inside the schroot, as the schroot will just be delted anyways. This behavior seems to be handled by the internal "Session Purged" parameter. At least in lib/Sbuild/Build.pm, we can see this:
my $is_cloned_session = (defined ($session->get('Session Purged')) &&
             $session->get('Session Purged') == 1) ? 1 : 0;
[...]
if ($is_cloned_session)  
$self->log("Not cleaning session: cloned chroot in use\n");
  else  
if ($purge_build_deps)  
    # Removing dependencies
    $resolver->uninstall_deps();
  else  
    $self->log("Not removing build depends: as requested\n");
 
 
The schroot builder defines that parameter as:
    $self->set('Session Purged', $info-> 'Session Purged' );
... which is ... a little confusing to me. $info is:
my $info = $self->get('Chroots')->get_info($schroot_session);
... so I presume that depends on whether the schroot was correctly cleaned up? I stopped digging there... ChrootUnshare.pm is way more explicit:
$self->set('Session Purged', 1);
I wonder if we should do something like this with the autopkgtest backend. I guess people might technically use it with something else than qemu, but qemu is the typical use case of the autopkgtest backend, in my experience. Or at least certainly with things that cleanup after themselves. Right? For some reason, before I added this line to my configuration:
$purge_build_deps = 'never';
... the "Cleanup" step would just completely hang. It was quite bizarre.

Disgression on the diversity of VM-like things There are a lot of different virtualization solutions one can use (e.g. Xen, KVM, Docker or Virtualbox). I have also found libguestfs to be useful to operate on virtual images in various ways. Libvirt and Vagrant are also useful wrappers on top of the above systems. There are particularly a lot of different tools which use Docker, Virtual machines or some sort of isolation stronger than chroot to build packages. Here are some of the alternatives I am aware of: Take, for example, Whalebuilder, which uses Docker to build packages instead of pbuilder or sbuild. Docker provides more isolation than a simple chroot: in whalebuilder, packages are built without network access and inside a virtualized environment. Keep in mind there are limitations to Docker's security and that pbuilder and sbuild do build under a different user which will limit the security issues with building untrusted packages. On the upside, some of things are being fixed: whalebuilder is now an official Debian package (whalebuilder) and has added the feature of passing custom arguments to dpkg-buildpackage. None of those solutions (except the autopkgtest/qemu backend) are implemented as a sbuild plugin, which would greatly reduce their complexity. I was previously using Qemu directly to run virtual machines, and had to create VMs by hand with various tools. This didn't work so well so I switched to using Vagrant as a de-facto standard to build development environment machines, but I'm returning to Qemu because it uses a similar backend as KVM and can be used to host longer-running virtual machines through libvirt. The great thing now is that autopkgtest has good support for qemu and sbuild has bridged the gap and can use it as a build backend. I originally had found those bugs in that setup, but all of them are now fixed:
  • #911977: sbuild: how do we correctly guess the VM name in autopkgtest?
  • #911979: sbuild: fails on chown in autopkgtest-qemu backend
  • #911963: autopkgtest qemu build fails with proxy_cmd: parameter not set
  • #911981: autopkgtest: qemu server warns about missing CPU features
So we have unification! It's possible to run your virtual machines and Debian builds using a single VM image backend storage, which is no small feat, in my humble opinion. See the sbuild-qemu blog post for the annoucement Now I just need to figure out how to merge Vagrant, GNOME Boxes, and libvirt together, which should be a matter of placing images in the right place... right? See also hosting.

pbuilder vs sbuild I was previously using pbuilder and switched in 2017 to sbuild. AskUbuntu.com has a good comparative between pbuilder and sbuild that shows they are pretty similar. The big advantage of sbuild is that it is the tool in use on the buildds and it's written in Perl instead of shell. My concerns about switching were POLA (I'm used to pbuilder), the fact that pbuilder runs as a separate user (works with sbuild as well now, if the _apt user is present), and setting up COW semantics in sbuild (can't just plug cowbuilder there, need to configure overlayfs or aufs, which was non-trivial in Debian jessie). Ubuntu folks, again, have more documentation there. Debian also has extensive documentation, especially about how to configure overlays. I was ultimately convinced by stapelberg's post on the topic which shows how much simpler sbuild really is...

Who Thanks lavamind for the introduction to the sbuild-qemu package.

26 April 2022

Tim Retout: Exploring StackRox

At the end of March, the source code to StackRox was released, following the 2021 acquisition by Red Hat. StackRox is a Kubernetes security tool which is now badged as Red Hat Advanced Cluster Security (RHACS), offering features such as vulnerability management, validating cluster configurations against CIS benchmarks, and some runtime behaviour analysis. In fact, it s such a diverse range of features that I have trouble getting my head round it from the product page or even the documentation. Source code is available via the StackRox organisation on GitHub, and the most obviously interesting repositories seem to be: My initial curiosity has been around the collector , to better understand what runtime behaviour the tool can actually pick up. I was intrigued to find that the actual kernel component is a patched version of Falco s kernel module/eBPF probes; a few features are disabled compared to Falco, e.g. page faults and signal events. There s a list of supported syscalls in driver/syscall_table.c, which seems to have drifted slightly or be slightly behind the upstream Falco version? In particular I note the absence of io_uring, but given RHACS is mainly deployed on Linux 4.18 at the moment (RHEL 8) this is probably a non-issue. (But relevant if anyone were to run it on newer kernels.) That s as far as I ve got for now. Red Hat are making great efforts to reach out to the community; there s a Slack channel, and office hours recordings, and a community hub to explore further. It s great to see new free software projects created through acquisition in this way - I m not sure I remember seeing a comparable example.

22 April 2022

Ritesh Raj Sarraf: Systemd Service Hang

Finally, TIL, what can all be the reason for systemd services to hang indefinitely. The internet is flooded with numerous reports on this topic but no clear answers. So no more uselessly marked workarounds like: systemctl daemon-reload and systemctl-daemon-reexec for this scenario. The scene would be something along the lines of:
rrs         6467  0.0  0.0  23088 15852 pts/1    Ss   12:53   0:00          \_ /bin/bash
rrs        11512  0.0  0.0  14876  4608 pts/1    S+   13:18   0:00              \_ systemctl restart snapper-timeline.timer
rrs        11513  0.0  0.0  14984  3076 pts/1    S+   13:18   0:00                  \_ /bin/systemd-tty-ask-password-agent --watch
rrs        11514  0.0  0.0 234756  6752 pts/1    Sl+  13:18   0:00                  \_ /usr/bin/pkttyagent --notify-fd 5 --fallback
The snapper-timeline service is important to me and it not running for months is a complete failure. Disappointingly, commands like systemctl --failed do not report of this oddity. The overall system status is reported to be fine, which is completely incorrect. Thankfully, a kind soul s comment gave the hint. The problem is that you could be having certain services in Activating status, which thus blocks all other services; quietly. So much for the unnecessary fun. Looking further, in my case, it was:
rrs@priyasi:~$ systemctl list-jobs 
JOB  UNIT                           TYPE  STATE  
81   timers.target                  start waiting
85   man-db.timer                   start waiting
88   fstrim.timer                   start waiting
3832 snapper-timeline.service       start waiting
83   snapper-timeline.timer         start waiting
39   systemd-time-wait-sync.service start running
87   logrotate.timer                start waiting
84   debspawn-clear-caches.timer    start waiting
89   plocate-updatedb.timer         start waiting
91   dpkg-db-backup.timer           start waiting
93   e2scrub_all.timer              start waiting
40   time-sync.target               start waiting
86   apt-listbugs.timer             start waiting

13 jobs listed.
13:12                      
That was it. I knew the systemd-timesyncd service, in the past, had given me enough headaches. And so was it this time, just quietly doing it all again.
rrs@priyasi:~$ systemctl status systemd-time-wait-sync.service
  systemd-time-wait-sync.service - Wait Until Kernel Time Synchronized
     Loaded: loaded (/lib/systemd/system/systemd-time-wait-sync.service; enabled; vendor preset>
     Active: activating (start) since Fri 2022-04-22 13:14:25 IST; 1min 38s ago
       Docs: man:systemd-time-wait-sync.service(8)
   Main PID: 11090 (systemd-time-wa)
      Tasks: 1 (limit: 37051)
     Memory: 836.0K
        CPU: 7ms
     CGroup: /system.slice/systemd-time-wait-sync.service
              11090 /lib/systemd/systemd-time-wait-sync

Apr 22 13:14:25 priyasi systemd[1]: Starting Wait Until Kernel Time Synchronized...
Apr 22 13:14:25 priyasi systemd-time-wait-sync[11090]: adjtime state 5 status 40 time Fri 2022->
13:16                   => 3  
Dear LazyWeb, anybody knows of why the systemd-time-wait-sync service would hang indefinitely? I ve had identical setups on many machines, in the same network, where others don t exhibit this problem.
rrs@priyasi:~$ systemctl cat systemd-time-wait-sync.service

...snipped...

[Service]
Type=oneshot
ExecStart=/lib/systemd/systemd-time-wait-sync
TimeoutStartSec=infinity
RemainAfterExit=yes

[Install]
WantedBy=sysinit.target
The TimeoutStartSec=infinity is definitely an attribute that shouldn t be shipped in any system services. There are use cases for it but that should be left for local admins to explicitly decide. Hanging for infinity is not a desired behavior for a system service. In figuring all this out, today I learnt the handy systemctl list-jobs command, which will give the list of active running/blocked/waiting jobs.

19 April 2022

Steve McIntyre: Firmware - what are we going to do about it?

TL;DR: firmware support in Debian sucks, and we need to change this. See the "My preference, and rationale" Section below. In my opinion, the way we deal with (non-free) firmware in Debian is a mess, and this is hurting many of our users daily. For a long time we've been pretending that supporting and including (non-free) firmware on Debian systems is not necessary. We don't want to have to provide (non-free) firmware to our users, and in an ideal world we wouldn't need to. However, it's very clearly no longer a sensible path when trying to support lots of common current hardware. Background - why has (non-free) firmware become an issue? Firmware is the low-level software that's designed to make hardware devices work. Firmware is tightly coupled to the hardware, exposing its features, providing higher-level functionality and interfaces for other software to use. For a variety of reasons, it's typically not Free Software. For Debian's purposes, we typically separate firmware from software by considering where the code executes (does it run on a separate processor? Is it visible to the host OS?) but it can be difficult to define a single reliable dividing line here. Consider the Intel/AMD CPU microcode packages, or the U-Boot firmware packages as examples. In times past, all necessary firmware would normally be included directly in devices / expansion cards by their vendors. Over time, however, it has become more and more attractive (and therefore more common) for device manufacturers to not include complete firmware on all devices. Instead, some devices just embed a very simple set of firmware that allows for upload of a more complete firmware "blob" into memory. Device drivers are then expected to provide that blob during device initialisation. There are a couple of key drivers for this change: Due to these reasons, more and more devices in a typical computer now need firmware to be uploaded at runtime for them to function correctly. This has grown: At the beginning of this timeline, a typical Debian user would be able to use almost all of their computer's hardware without needing any firmware blobs. It might have been inconvenient to not be able to use the WiFi, but most laptops had wired ethernet anyway. The WiFi could always be enabled and configured after installation. Today, a user with a new laptop from most vendors will struggle to use it at all with our firmware-free Debian installation media. Modern laptops normally don't come with wired ethernet now. There won't be any usable graphics on the laptop's screen. A visually-impaired user won't get any audio prompts. These experiences are not acceptable, by any measure. There are new computers still available for purchase today which don't need firmware to be uploaded, but they are growing less and less common. Current state of firmware in Debian For clarity: obviously not all devices need extra firmware uploading like this. There are many devices that depend on firmware for operation, but we never have to think about them in normal circumstances. The code is not likely to be Free Software, but it's not something that we in Debian must spend our time on as we're not distributing that code ourselves. Our problems come when our user needs extra firmware to make their computer work, and they need/expect us to provide it. We have a small set of Free firmware binaries included in Debian main, and these are included on our installation and live media. This is great - we all love Free Software and this works. However, there are many more firmware binaries that are not Free. If we are legally able to redistribute those binaries, we package them up and include them in the non-free section of the archive. As Free Software developers, we don't like providing or supporting non-free software for our users, but we acknowledge that it's sometimes a necessary thing for them. This tension is acknowledged in the Debian Free Software Guidelines. This tension extends to our installation and live media. As non-free is officially not considered part of Debian, our official media cannot include anything from non-free. This has been a deliberate policy for many years. Instead, we have for some time been building a limited parallel set of "unofficial non-free" images which include non-free firmware. These non-free images are produced by the same software that we use for the official images, and by the same team. There are a number of issues here that make developers and users unhappy:
  1. Building, testing and publishing two sets of images takes more effort.
  2. We don't really want to be providing non-free images at all, from a philosophy point of view. So we mainly promote and advertise the preferred official free images. That can be a cause of confusion for users. We do link to the non-free images in various places, but they're not so easy to find.
  3. Using non-free installation media will cause more installations to use non-free software by default. That's not a great story for us, and we may end up with more of our users using non-free software and believing that it's all part of Debian.
  4. A number of users and developers complain that we're wasting their time by publishing official images that are just not useful for a lot (a majority?) of users.
We should do better than this. Options The status quo is a mess, and I believe we can and should do things differently. I see several possible options that the images team can choose from here. However, several of these options could undermine the principles of Debian. We don't want to make fundamental changes like that without the clear backing of the wider project. That's why I'm writing this...
  1. Keep the existing setup. It's horrible, but maybe it's the best we can do? (I hope not!)
  2. We could just stop providing the non-free unofficial images altogether. That's not really a promising route to follow - we'd be making it even harder for users to install our software. While ideologically pure, it's not going to advance the cause of Free Software.
  3. We could stop pretending that the non-free images are unofficial, and maybe move them alongside the normal free images so they're published together. This would make them easier to find for people that need them, but is likely to cause users to question why we still make any images without firmware if they're otherwise identical.
  4. The images team technically could simply include non-free into the official images, and add firmware packages to the input lists for those images. However, that would still leave us with problem 3 from above (non-free generally enabled on most installations).
  5. We could split out the non-free firmware packages into a new non-free-firmware component in the archive, and allow a specific exception only to allow inclusion of those packages on our official media. We would then generate only one set of official media, including those non-free firmware packages. (We've already seen various suggestions in recent years to split up the non-free component of the archive like this, for example into non-free-firmware, non-free-doc, non-free-drivers, etc. Disagreement (bike-shedding?) about the split caused us to not make any progress on this. I believe this project should be picked up and completed. We don't have to make a perfect solution here immediately, just something that works well enough for our needs today. We can always tweak and improve the setup incrementally if that's needed.)
These are the most likely possible options, in my opinion. If you have a better suggestion, please let us know! I'd like to take this set of options to a GR, and do it soon. I want to get a clear decision from the wider Debian project as to how to organise firmware and installation images. If we do end up changing how we do things, I want a clear mandate from the project to do that. My preference, and rationale Mainly, I want to see how the project as a whole feels here - this is a big issue that we're overdue solving. What would I choose to do? My personal preference would be to go with option 5: split the non-free firmware into a special new component and include that on official media. Does that make me a sellout? I don't think so. I've been passionately supporting and developing Free Software for more than half my life. My philosophy here has not changed. However, this is a complex and nuanced situation. I firmly believe that sharing software freedom with our users comes with a responsibility to also make our software useful. If users can't easily install and use Debian, that helps nobody. By splitting things out here, we would enable users to install and use Debian on their hardware, without promoting/pushing higher-level non-free software in general. I think that's a reasonable compromise. This is simply a change to recognise that hardware requirements have moved on over the years. Further work If we do go with the changes in option 5, there are other things we could do here for better control of and information about non-free firmware:
  1. Along with adding non-free firmware onto media, when the installer (or live image) runs, we should make it clear exactly which firmware packages have been used/installed to support detected hardware. We could link to docs about each, and maybe also to projects working on Free re-implementations.
  2. Add an option at boot to explicitly disable the use of the non-free firmware packages, so that users can choose to avoid them.
Acknowledgements Thanks to people who reviewed earlier versions of this document and/or made suggestions for improvement, in particular:

8 April 2022

Jacob Adams: The Unexpected Importance of the Trailing Slash

For many using Unix-derived systems today, we take for granted that /some/path and /some/path/ are the same. Most shells will even add a trailing slash for you when you press the Tab key after the name of a directory or a symbolic link to one. However, many programs treat these two paths as subtly different in certain cases, which I outline below, as all three have tripped me up in various ways1.

POSIX and Coreutils Perhaps the trickiest use of the trailing slash in a distinguishing way is in POSIX2 which states:
When the final component of a pathname is a symbolic link, the standard requires that a trailing <slash> causes the link to be followed. This is the behavior of historical implementations3. For example, for /a/b and /a/b/, if /a/b is a symbolic link to a directory, then /a/b refers to the symbolic link, and /a/b/ refers to the directory to which the symbolic link points.
This leads to some unexpected behavior. For example, if you have the following structure of a directory dir containing a file dirfile with a symbolic link link pointing to dir. (which will be used in all shell examples throughout this article):
$ ls -lR
.:
total 4
drwxr-xr-x 2 jacob jacob 4096 Apr  3 00:00 dir
lrwxrwxrwx 1 jacob jacob    3 Apr  3 00:00 link -> dir
./dir:
total 0
-rw-r--r-- 1 jacob jacob 0 Apr  3 00:12 dirfile
On Unixes such as MacOS, FreeBSD or Illumos4, you can move a directory through a symbolic link by using a trailing slash:
$ mv link/ otherdir
$ ls
link	otherdir
On Linux5, mv will not rename the indirectly referenced directory and not the symbolic link, when given a symbolic link with a trailing slash as the source to be renamed. despite the coreutils documentation s claims to the contrary6, instead failing with Not a directory:
$ mv link/ other
mv: cannot move 'link/' to 'other': Not a directory
$ mkdir otherdir
$ mv link/ otherdir
mv: cannot move 'link/' to 'otherdir/link': Not a directory
$ mv link/ otherdir/
mv: cannot move 'link/' to 'otherdir/link': Not a directory
$ mv link otherdirlink
$ ls -l otherdirlink
lrwxrwxrwx 1 jacob jacob 3 Apr  3 00:13 otherdirlink -> dir
This is probably for the best, as it is very confusing behavior. There is still one advantage the trailing slash has when using mv, even on Linux, in that is it does not allow you to move a file to a non-existent directory, or move a file that you expect to be a directory that isn t.
$ mv dir/dirfile nonedir/
mv: cannot move 'dir/dirfile' to 'nonedir/': Not a directory
$ touch otherfile
$ mv otherfile/ dir
mv: cannot stat 'otherfile/': Not a directory
$ mv otherfile dir
$ ls dir
dirfile  otherfile
However, Linux still exhibits some confusing behavior of its own, like when you attempt to remove link recursively with a trailing slash:
rm -rvf link/
Neither link nor dir are removed, but the contents of dir are removed:
removed 'link/dirfile'
Whereas if you remove the trailing slash, you just remove the symbolic link:
$ rm -rvf link
removed 'link'
While on MacOS, FreeBSD or Illumos4, rm will also remove the source directory:
$ rm -rvf link
link/dirfile
link/
$ ls
link
The find and ls commands, in contrast, behave the same on all three operating systems. The find command only searches the contents of the directory a symbolic link points to if the trailing slash is added:
$ find link -name dirfile
$ find link/ -name dirfile
link/dirfile
The ls command acts similarly, showing information on just a symbolic link by itself unless a trailing slash is added, at which point it shows the contents of the directory that it links to:
$ ls -l link
lrwxrwxrwx 1 jacob jacob 3 Apr  3 00:13 link -> dir
$ ls -l link/
total 0
-rw-r--r-- 1 jacob jacob 0 Apr  3 00:13 dirfile

rsync The command rsync handles a trailing slash in an unusual way that trips up many new users. The rsync man page notes:
You can think of a trailing / on a source as meaning copy the contents of this directory as opposed to copy the directory by name , but in both cases the attributes of the containing directory are transferred to the containing directory on the destination.
That is to say, if we had two folders a and b each of which contained some files:
$ ls -R .
.:
a  b
./a:
a1  a2
./b:
b1  b2
Running rsync -av a b moves the entire directory a to directory b:
$ rsync -av a b
sending incremental file list
a/
a/a1
a/a2
sent 181 bytes  received 58 bytes  478.00 bytes/sec
total size is 0  speedup is 0.00
$ ls -R b
b:
a  b1  b2
b/a:
a1  a2
While running rsync -av a/ b moves the contents of directory a to b:
$ rsync -av a/ b
sending incremental file list
./
a1
a2
sent 170 bytes  received 57 bytes  454.00 bytes/sec
total size is 0  speedup is 0.00
$ ls b
a1  a2	b1  b2

Dockerfile COPY The Dockerfile COPY command also cares about the presence of the trailing slash, using it to determine whether the destination should be considered a file or directory. The Docker documentation explains the rules of the command thusly:
COPY [--chown=<user>:<group>] <src>... <dest>
If <src> is a directory, the entire contents of the directory are copied, including filesystem metadata. Note: The directory itself is not copied, just its contents. If <src> is any other kind of file, it is copied individually along with its metadata. In this case, if <dest> ends with a trailing slash /, it will be considered a directory and the contents of <src> will be written at <dest>/base(<src>). If multiple <src> resources are specified, either directly or due to the use of a wildcard, then <dest> must be a directory, and it must end with a slash /. If <dest> does not end with a trailing slash, it will be considered a regular file and the contents of <src> will be written at <dest>. If <dest> doesn t exist, it is created along with all missing directories in its path.
This means if you had a COPY command that moved file to a nonexistent containerfile without the slash, it would create containerfile as a file with the contents of file.
COPY file /containerfile
container$ stat -c %F containerfile
regular empty file
Whereas if you add a trailing slash, then file will be added as a file under the new directory containerdir:
COPY file /containerdir/
container$ stat -c %F containerdir
directory
Interestingly, at no point can you copy a directory completely, only its contents. Thus if you wanted to make a directory in the new container, you need to specify its name in both the source and the destination:
COPY dir /dirincontainer
container$ stat -c %F /dirincontainer
directory
Dockerfiles do also make good use of the trailing slash to ensure they re doing what you mean by requiring a trailing slash on the destination of multiple files:
COPY file otherfile /othercontainerdir
results in the following error:
When using COPY with more than one source file, the destination must be a directory and end with a /
  1. I m sure there are probably more than just these three cases, but these are the three I m familiar with. If you know of more, please tell me about them!.
  2. Some additional relevant sections are the Path Resolution Appendix and the section on Symbolic Links.
  3. The sentence This is the behavior of historical implementations implies that this probably originated in some ancient Unix derivative, possibly BSD or even the original Unix. I don t really have a source on that though, so please reach out if you happen to have any more knowledge on what this refers to.
  4. I tested on MacOS 11.6.5, FreeBSD 12.0 and OmniOS 5.11 2
  5. unless the source is a directory trailing slashes give -ENOTDIR
  6. In fairness to the coreutils maintainers, it seems to be true on all other Unix platforms, but it probably deserves a mention in the documentation when Linux is the most common platform on which coreutils is used. I should submit a patch.

5 April 2022

Matthew Garrett: Bearer tokens are just awful

As I mentioned last time, bearer tokens are not super compatible with a model in which every access is verified to ensure it's coming from a trusted device. Let's talk about that in a bit more detail.

First off, what is a bearer token? In its simplest form, it's simply an opaque blob that you give to a user after an authentication or authorisation challenge, and then they show it to you to prove that they should be allowed access to a resource. In theory you could just hand someone a randomly generated blob, but then you'd need to keep track of which blobs you've issued and when they should be expired and who they correspond to, so frequently this is actually done using JWTs which contain some base64 encoded JSON that describes the user and group membership and so on and then have a signature associated with them so whenever the user presents one you can just validate the signature and then assume that the contents of the JSON are trustworthy.

One thing to note here is that the crypto is purely between whoever issued the token and whoever validates the token - as far as the server is concerned, any client who can just show it the token is just fine as long as the signature is verified. There's no way to verify the client's state, so one of the core ideas of Zero Trust (that we verify that the client is in a trustworthy state on every access) is already violated.

Can we make things not terrible? Sure! We may not be able to validate the client state on every access, but we can validate the client state when we issue the token in the first place. When the user hits a login page, we do state validation according to whatever policy we want to enforce, and if the client violates that policy we refuse to issue a token to it. If the token has a sufficiently short lifetime then an attacker is only going to have a short period of time to use that token before it expires and then (with luck) they won't be able to get a new one because the state validation will fail.

Except! This is fine for cases where we control the issuance flow. What if we have a scenario where a third party authenticates the client (by verifying that they have a valid token issued by their ID provider) and then uses that to issue their own token that's much longer lived? Well, now the client has a long-lived token sitting on it. And if anyone copies that token to another device, they can now pretend to be that client.

This is, sadly, depressingly common. A lot of services will verify the user, and then issue an oauth token that'll expire some time around the heat death of the universe. If a client system is compromised and an attacker just copies that token to another system, they can continue to pretend to be the legitimate user until someone notices (which, depending on whether or not the service in question has any sort of audit logs, and whether you're paying any attention to them, may be once screenshots of your data show up on Twitter).

This is a problem! There's no way to fit a hosted service that behaves this way into a Zero Trust model - the best you can say is that a token was issued to a device that was, around that time, apparently trustworthy, and now it's some time later and you have literally no idea whether the device is still trustworthy or if the token is still even on that device.

But wait, there's more! Even if you're nowhere near doing any sort of Zero Trust stuff, imagine the case of a user having a bunch of tokens from multiple services on their laptop, and then they leave their laptop unlocked in a cafe while they head to the toilet and whoops it's not there any more, better assume that someone has access to all the data on there. How many services has our opportunistic new laptop owner gained access to as a result? How do we revoke all of the tokens that are sitting there on the local disk? Do you even have a policy for dealing with that?

There isn't a simple answer to all of these problems. Replacing bearer tokens with some sort of asymmetric cryptographic challenge to the client would at least let us tie the tokens to a TPM or other secure enclave, and then we wouldn't have to worry about them being copied elsewhere. But that wouldn't help us if the client is compromised and the attacker simply keeps using the compromised client. The entire model of simply proving knowledge of a secret being sufficient to gain access to a resource is inherently incompatible with a desire for fine-grained trust verification on every access, but I don't see anything changing until we have a standard for third party services to be able to perform that trust verification against a customer's policy.

Still, at least this means I can just run weird Android IoT apps through mitmproxy, pull the bearer token out of the request headers and then start poking the remote API with curl. It may all be broken, but it's also got me a bunch of bug bounty credit, so, it;s impossible to say if its bad or not,

(Addendum: this suggestion that we solve the hardware binding problem by simply passing all the network traffic through some sort of local enclave that could see tokens being set and would then sequester them and reinject them into later requests is OBVIOUSLY HORRIFYING and is also probably going to be at least three startup pitches by the end of next week)

comment count unavailable comments

Dirk Eddelbuettel: RcppArmadillo 0.11.0.0.0 on CRAN: Upstream Updates

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 972 other packages on CRAN, downloaded over 24 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 465 times according to Google Scholar. This release brings a new upstream release 11.0.0. We tested this very rigorously via three different RC release each of which got a full reverse-dependencies run (for which results are always logged here). The full set of changes (since the last CRAN release 0.10.8.1.0) follows.

Changes in RcppArmadillo version 0.11.0.0 (2022-04-04)
  • Upgraded to Armadillo release 11.0.0 (Creme Brulee)
    • added variants of inv() and inv_sympd() that provide rcond (reciprocal condition number)
    • expanded inv() and inv_sympd() with options inv_opts::tiny and inv_opts::allow_approx
    • stricter handling of singular matrices by inv() and inv_sympd()
    • stricter handling of non-sympd matrices by inv() and inv_sympd()
    • stricter handling of non-finitie matrices by pinv()
    • more robust handling of rank deficient matrices by solve()
    • faster handling of diagonal matrices by rcond()
    • changed eigs_sym() and eigs_gen() to use higher quality RNG
    • quantile() and median() will now throw an exception if given matrices/vectors have NaN elements
    • workaround for yet another bug in Intel MKL
  • Until May 2022, protect correction to Field behavior via define of RCPP_ARMADILLO_FIX_Field
  • If a LAPACK installation with missing complex routines is found (as e.g. Ubuntu using 3.9.0) then the LAPACK unit test is skipped.

Changes in RcppArmadillo version 0.10.8.2.0 (2022-02-01)
  • Upgraded to Armadillo release 10.8.2 (Realm Raider)
    • fix potential speed regression in pinv() and rank()

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

4 April 2022

Arturo Borrero Gonz lez: Wikimedia Toolforge and Grid Engine

Logos This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. One of the most important and successful products provided by the Wikimedia Cloud Services team at the Wikimedia Foundation is Toolforge, a hosting service commonly known in the industry as Platform as a Service (PaaS). In particular, it is a platform that allows users and developers to run and use a variety of applications with the ultimate goal of helping the Wikimedia mission from the technical side. Toolforge is powered by two different backend engines, Kubernetes and Grid Engine. The two backends have traditionally offered different features for tool developers. But as time moves forward we ve learnt that Kubernetes is the future. Explaining why is the purpose of this blog post: we want to share more information and reasoning behind this mindset. There are a number of reasons that make Grid Engine poorly suitable to remain as execution backend in Toolforge: As mentioned above, our desire is to cover all our grid-like needs with Kubernetes, a technology which has several benefits: The relationship between Toolforge and Grid Engine has been interesting over the years. The grid has been used for quite a lot of time, we have plenty of documentation and established good practices. On the other hand, the grid is hard to maintain, imposes a heavy burden on the WMCS team and is a technology we must eventually discontinue. How to accommodate the two realities is a refreshing challenge, one that we hope to tackle together in the near future. A tradeoff exists here, but it is clear to us which option is best. So we will work on deprecating and removing Grid Engine and migrating use cases into Kubernetes. This deprecation, however, will be done with care, as we know our technical community relies on the grid for some import Toolforge tools. And some of these workflows will need some adaptation in order to be fully supported on Kubernetes. Stay tuned for more information on present and next works surrounding the Wikimedia Toolforge service. The next blog post will share more concrete details. This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.

1 April 2022

Paul Wise: FLOSS Activities March 2022

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review
  • Spam: reported 3 Debian bug reports and 53 Debian mailing list posts
  • Debian wiki: RecentChanges for the month
  • Debian BTS usertags: changes for the month
  • Debian screenshots:

Administration
  • Debian servers: investigate wiki mail delivery issue, restart backup director
  • Debian wiki: unblock IP addresses, approve accounts

Communication
  • Forward python-plac test failure issue upstream
  • Participate in Debian Project Leader election discussions
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors The oci-python-sdk and plac work was sponsored. All other work was done on a volunteer basis.

31 March 2022

Matthew Garrett: ZTA doesn't solve all problems, but partial implementations solve fewer

Traditional network access controls work by assuming that something is trustworthy based on some other factor - for example, if a computer is on your office network, it's trustworthy because only trustworthy people should be able to gain physical access to plug something in. If you restrict access to your services to requests coming from trusted networks, then you can assert that it's coming from a trusted device.

Of course, this isn't necessarily true. A machine on your office network may be compromised. An attacker may obtain valid VPN credentials. Someone could leave a hostile device plugged in under a desk in a meeting room. Trust is being placed in devices that may not be trustworthy.

A Zero Trust Architecture (ZTA) is one where a device is granted no inherent trust. Instead, each access to a service is validated against some policy - if the policy is satisfied, the access is permitted. A typical implementation involves granting each device some sort of cryptographic identity (typically a TLS client certificate) and placing the protected services behind a proxy. The proxy verifies the device identity, queries another service to obtain the current device state (we'll come back to that in a moment), compares the state against a policy and either pass the request through to the service or reject it. Different services can have different policies (eg, you probably want a lax policy around whatever's hosting the documentation for how to fix your system if it's being refused access to something for being in the wrong state), and if you want you can also tie it to proof of user identity in some way.

From a user perspective, this is entirely transparent. The proxy is made available on the public internet, DNS for the services points to the proxy, and every time your users try to access the service they hit the proxy instead and (if everything's ok) gain access to it no matter which network they're on. There's no need to connect to a VPN first, and there's no worries about accidentally leaking information over the public internet instead of over a secure link.

It's also notable that traditional solutions tend to be all-or-nothing. If I have some services that are more sensitive than others, the only way I can really enforce this is by having multiple different VPNs and only granting access to sensitive services from specific VPNs. This obviously risks combinatorial explosion once I have more than a couple of policies, and it's a terrible user experience.

Overall, ZTA approaches provide more security and an improved user experience. So why are we still using VPNs? Primarily because this is all extremely difficult. Let's take a look at an extremely recent scenario. A device used by customer support technicians was compromised. The vendor in question has a solution that can tie authentication decisions to whether or not a device has a cryptographic identity. If this was in use, and if the cryptographic identity was tied to the device hardware (eg, by being generated in a TPM), the attacker would not simply be able to obtain the user credentials and log in from their own device. This is good - if the attacker wanted to maintain access to the service, they needed to stay on the device in question. This increases the probability of the monitoring tooling on the compromised device noticing them.

Unfortunately, the attacker simply disabled the monitoring tooling on the compromised device. If device state was being verified on each access then this would be noticed before too long - the last data received from the device would be flagged as too old, and the requests would no longer satisfy any reasonable access control policy. Instead, the device was assumed to be trustworthy simply because it could demonstrate its identity. There's an important point here: just because a device belongs to you doesn't mean it's a trustworthy device.

So, if ZTA approaches are so powerful and user-friendly, why aren't we all using one? There's a few problems, but the single biggest is that there's no standardised way to verify device state in any meaningful way. Remote Attestation can both prove device identity and the device boot state, but the only product on the market that does much with this is Microsoft's Device Health Attestation. DHA doesn't solve the broader problem of also reporting runtime state - it may be able to verify that endpoint monitoring was launched, but it doesn't make assertions about whether it's still running. Right now, people are left trying to scrape this information from whatever tooling they're running. The absence of any standardised approach to this problem means anyone who wants to deploy a strong ZTA has to integrate with whatever tooling they're already running, and that then increases the cost of migrating to any other tooling later.

But even device identity is hard! Knowing whether a machine should be given a certificate or not depends on knowing whether or not you own it, and inventory control is a surprisingly difficult problem in a lot of environments. It's not even just a matter of whether a machine should be given a certificate in the first place - if a machine is reported as lost or stolen, its trust should be revoked. Your inventory system needs to tie into your device state store in order to ensure that your proxies drop access.

And, worse, all of this depends on you being able to put stuff behind a proxy in the first place! If you're using third-party hosted services, that's a problem. In the absence of a proxy, trust decisions are probably made at login time. It's possible to tie user auth decisions to device identity and state (eg, a self-hosted SAML endpoint could do that before passing through to the actual ID provider), but that's still going to end up providing a bearer token of some sort that can potentially be exfiltrated, and will continue to be trusted even if the device state becomes invalid.

ZTA doesn't solve all problems, and there isn't a clear path to it doing so without significantly greater industry support. But a complete ZTA solution is significantly more powerful than a partial one. Verifying device identity is a step on the path to ZTA, but in the absence of device state verification it's only a step.

comment count unavailable comments

30 March 2022

Ulrike Uhlig: How do kids conceive the internet?

I wanted to understand how kids between 10 and 18 conceive the internet. Surely, we have seen a generation that we call digital natives grow up with the internet. Now, there is a younger generation who grows up with pervasive technology, such as smartphones, smart watches, virtual assistants and so on. And only a few of them have parents who work in IT or engineering
Pervasive technology contributes to the idea that the internet is immaterial With their search engine website design, Google has put in place an extremely simple and straightforward user interface. Since then, designers and psychologists have worked on making user interfaces more and more intuitive to use. The buzzwords are usability and user experience design . Besides this optimization of visual interfaces, haptic interfaces have evolved as well, specifically on smartphones and tablets where hand gestures have replaced more clumsy external haptic interfaces such as a mouse. And beyond interfaces, the devices themselves have become smaller and slicker. While in our generation many people have experienced opening a computer tower or a laptop to replace parts, with the side effect of seeing the parts the device is physically composed of, the new generation of end user devices makes this close to impossible, essentially transforming these devices into black boxes, and further contributing to the idea that the internet they are being used to access with would be something entirely intangible.

What do kids in 2022 really know about the internet? So, what do kids of that generation really know about the internet, beyond purely using services they do not control? In order to find out, I decided to interview children between 10 and 18. I conducted 5 interviews with kids aged 9, 10, 12, 15 and 17, two boys and three girls. Two live in rural Germany, one in a German urban area, and two live in the French capital. I wrote the questions in a way to stimulate the interviewees to tell me a story each time. I also told them that the interview is not a test and that there are no wrong answers. Except for the 9 year old, all interviewees possessed both, their own smartphone and their own laptop. All of them used the internet mostly for chatting, entertainment (video and music streaming, online games), social media (TikTok, Instagram, Youtube), and instant messaging. Let me introduce you to their concepts of the internet. That was my first story telling question to them:

If aliens had landed on Earth and would ask you what the internet is, what would you explain to them? The majority of respondents agreed in their replies that the internet is intangible while still being a place where one can do anything and everything . Before I tell you more about their detailed answers to the above question, let me show you how they visualize their internet.

If you had to make a drawing to explain to a person what the internet is, how would this drawing look like? Each interviewee had some minutes to come up with a drawing. As you will see, that drawing corresponds to what the kids would want an alien to know about the internet and how they are using the internet themselves.

Movies, series, videos A child's drawing. In the middle, there is a screen, on the screen a movie is running. Around the screen there are many people, at least two dozens. The words 'film', 'series', 'network', 'video' are written and arrows point from these words to the screen. There's also a play icon. The youngest respondent, a 9 year old girl, drew a screen with lots of people around it and the words film, series, network, video , as well as a play icon. She said that she mostly uses the internet to watch movies. She was the only one who used a shared tablet and smartphone that belonged to her family, not to herself. And she would explain the net like this to an alien:
"Internet is a er one cannot touch it it s an, er [I propose the word idea ], yes it s an idea. Many people use it not necessarily to watch things, but also to read things or do other stuff."

User interface elements There is a magnifying glass icon, a play icon and speech bubbles drawn with a pencil. A 10 year old boy represented the internet by recalling user interface elements he sees every day in his drawing: a magnifying glass (search engine), a play icon (video streaming), speech bubbles (instant messaging). He would explain the internet like this to an alien:
"You can use the internet to learn things or get information, listen to music, watch movies, and chat with friends. You can do nearly anything with it."

Another planet Pencil drawing that shows a planet with continents. The continents are named: H&M, Ebay, Google, Wikipedia, Facebook. A 12 year old girl imagines the internet like a second, intangible, planet where Google, Wikipedia, Facebook, Ebay, or H&M are continents that one enters into.
"And on [the] Ebay [continent] there s a country for clothes, and ,trousers , for example, would be a federal state in that country."
Something that was unique about this interview was that she told me she had an email address but she never writes emails. She only has an email account to receive confirmation emails, for example when doing online shopping, or when registering to a service and needing to confirm one s address. This is interesting because it s an anti-spam measure that might become outdated with a generation that uses email less or not at all.

Home network Kid's drawing: there are three computer towers and next to each there are two people. The first couple is sad, the seconf couple is smiling, the last one is suprised. Each computer is connected to a router, two of them by cable, one by wifi. A 15 year old boy knew that his family s devices are connected to a home router (Freebox is a router from the French ISP Free) but lacked an imagination of the rest of the internet s functioning. When I asked him about what would be behind the router, on the other side, he said what s behind is like a black hole to him. However, he was the only interviewee who did actually draw cables, wifi waves, a router, and the local network. His drawing is even extremely precise, it just lacks the cable connecting the router to the rest of the internet.
Satellite internet This is another very simple drawing: On top left, there's planet Earth an there are lines indicating that earth is a sphere. Around Earth there are two big satellites reaching most of Earth. on the left, below, there are three icons representing social media services on the internet: Snapchat, Instagram, TikTok. On the right, there are simplified drawings of possibilities which the internet offers: person to person connection, email (represented by envelopes), calls (represented by an old-style telephone set). A 17 year old girl would explain the internet to an alien as follows:
"The internet goes around the entire globe. One is networked with everyone else on Earth. One can find everything. But one cannot touch the internet. It s like a parallel world. With a device one can look into the internet. With search engines, one can find anything in the world, one can phone around the world, and write messages. [The internet] is a gigantic thing."
This interviewee stated as the only one that the internet is huge. And while she also is the only one who drew the internet as actually having some kind of physical extension beyond her own home, she seems to believe that internet connectivity is based on satellite technology and wireless communication.

Imagine that a wise and friendly dragon could teach you one thing about the internet that you ve always wanted to know. What would you ask the dragon to teach you about? A 10 year old boy said he d like to know how big are the servers behind all of this . That s the only interview in which the word server came up. A 12 year old girl said I would ask how to earn money with the internet. I always wanted to know how this works, and where the money comes from. I love the last part of her question! The 15 year old boy for whom everything behind the home router is out of his event horizon would ask How is it possible to be connected like we are? How does the internet work scientifically? A 17 year old girl said she d like to learn how the darknet works, what hidden things are there? Is it possible to get spied on via the internet? Would it be technically possible to influence devices in a way that one can listen to secret or telecommanded devices? Lastly, I wanted to learn about what they find annoying, or problematic about the internet.

Imagine you could make the internet better for everyone. What would you do first? Asked what she would change if she could, the 9 year old girl advocated for a global usage limit of the internet in order to protect the human brain. Also, she said, her parents spend way too much time on their phones and people should rather spend more time with their children. Three of the interviewees agreed that they see way too many advertisements and two of them would like ads to disappear entirely from the web. The other one said that she doesn t want to see ads, but that ads are fine if she can at least click them away. The 15 year old boy had different ambitions. He told me he would change:
"the age of access to the internet. More and more younger people access the internet ; especially with TikTok there is a recommendation algorithm that can influcence young people a lot. And influencing young people should be avoided but the internet does it too much. And that can be negative. If you don t yet have a critical spirit, and you watch certain videos you cannot yet moderate your stance. It can influence you a lot. There are so many things that have become indispensable and that happen on the internet and we have become dependent. What happens if one day it doesn t work anymore? If we connect more and more things to the net, that s not a good thing."

The internet - Oh, that s what you mean! On a sidenote, my first interview tentative was with an 8 year old girl from my family. I asked her if she uses the internet and she denied, so I abandoned interviewing her. Some days later, while talking to her, she proposed to look something up on Google, using her smartphone. I said: Oh, so you are using the internet! She replied: Oh, that s what you re talking about? I think she knows the word Google and she knows that she can search for information with this Google thing. But it appeared that she doesn t know that the Google search engine is located somewhere else on internet and not on her smartphone. I concluded that for her, using the services on the smartphone is as natural as switching on a light in the house: we also don t think about where the electricity comes from when we do that.

What can we learn from these few interviews? Unsurprisingly, social media, streaming, entertainment, and instant messaging are the main activities kids undertake on the internet. They are completely at the mercy of advertisements in apps and on websites, not knowing how to get rid of them. They interact on a daily basis with algorithms that are unregulated and known to perpetuate discrimination and to create filter bubbles, without necessarily being aware of it. The kids I interviewed act as mere service users and seem to be mostly confined to specific apps or websites. All of them perceived the internet as being something intangible. Only the older interviewees perceived that there must be some kind of physical expansion to it: the 17 year old girl by drawing a network of satellites around the globe, the 15 year old boy by drawing the local network in his home. To be continued

28 March 2022

Antoine Beaupr : What is going on with web servers

I stumbled upon this graph recently, which is w3techs.com graph of "Historical yearly trends in the usage statistics of web servers". It seems I hadn't looked at it in a long while because I was surprised at many levels:
  1. Apache is now second, behind Nginx, since ~2022 (so that's really new at least)
  2. Cloudflare "server" is third ahead of the traditional third (Microsoft IIS) - I somewhat knew that Cloudflare was hosting a lot of stuff, but I somehow didn't expect to see it there at all for some reason
  3. I had to lookup what LiteSpeed was (and it's not a bike company): it's a drop-in replacement (!?) of the Apache web server (not a fork, a bizarre idea but which seems to be gaining a lot of speed recently, possibly because of its support for QUIC and HTTP/3
So there. I'm surprised. I guess the stats should be taken with a grain of salt because they only partially correlate with Netcraft's numbers which barely mention LiteSpeed at all. (But they do point at a rising share as well.) Netcraft also puts Nginx's first place earlier in time, around April 2019, which is about when Microsoft's IIS took a massive plunge down. That is another thing that doesn't map with w3techs' graphs at all either. So it's all lies and statistics, basically. Moving on. Oh and of course, the two first most popular web servers, regardless of the source, are package in Debian. So while we're working on statistics and just making stuff up, I'm going to go ahead and claim all of this stuff runs on Linux and that BSD is dead. Or something like that.

27 March 2022

Andrew Cater: Imminent release for the media images for Debian 10.12 and 11.3 20220327 0010

OK - so it wasn't quite all done in one day - and since today is TZ change day in the UK, it might actually run into the TZ bump but I suspect that it will all be done very soon now. Very few glitches - everybody cheerful with what's been done.I did spot someone in IRC who had been reading the release notes - which is always much appreciated. Lots of security fixes overall in the last couple of months but just a fairly normal time, I think.Thanks to the team behind all of this: the ftpmasters, the press team and everyone else involved in making Debian more secure. This is the last blog for this one - there will be another point release along in about three months or so.

26 March 2022

Andrew Cater: Debian media team - testing and releasing Debian 11.3 - 20220326 1243UTC

And back to relative normality : the usual suspects are in Cambridge. It's a glorious day across the UK and we're spending it indoors with laptops :)We'll also be releasing a point release of Buster as a wrap up of recent changes.Debian 10 should move from full support to LTS on July August 14th - one year after the release of Debian 11 - and there will be a final point release of Buster somewhere around that point.
All seems to be behaving itself well.Thanks to all for the hard work that goes into preparing each release and especially the security fixes of which there seem to be loads lately.


Next.

Previous.