Search Results: "nate"

15 September 2008

Adam Rosi-Kessel: The man hears what he wants to hear

(and disregards the rest) Jonah Lehrer reports the result of a depressing but unsurprising experiment: The Facts Don’t Matter.
Political scientists Brendan Nyhan and Jason Reifler provided two groups of volunteers with the Bush administration’s prewar claims that Iraq had weapons of mass destruction. One group was given a refutation — the comprehensive 2004 Duelfer report that concluded that Iraq did not have weapons of mass destruction before the United States invaded in 2003. Thirty-four percent of conservatives told only about the Bush administration’s claims thought Iraq had hidden or destroyed its weapons before the U.S. invasion, but 64 percent of conservatives who heard both claim and refutation thought that Iraq really did have the weapons. The refutation, in other words, made the misinformation worse. A similar “backfire effect” also influenced conservatives told about Bush administration assertions that tax cuts increase federal revenue. One group was offered a refutation by prominent economists that included current and former Bush administration officials. About 35 percent of conservatives told about the Bush claim believed it; 67 percent of those provided with both assertion and refutation believed that tax cuts increase revenue. In a paper approaching publication, Nyhan, a PhD student at Duke University, and Reifler, at Georgia State University, suggest that Republicans might be especially prone to the backfire effect because conservatives may have more rigid views than liberals: Upon hearing a refutation, conservatives might “argue back” against the refutation in their minds, thereby strengthening their belief in the misinformation. Nyhan and Reifler did not see the same “backfire effect” when liberals were given misinformation and a refutation about the Bush administration’s stance on stem cell research.
It’s particularly interesting that the backfire effect is more pronounced with Republicans; this certainly resonates with my admittedly biased view. Better information doesn’t seem to fix the problem, either:
During the first term of Bill Clinton’s presidency, the budget deficit declined by more than 90 percent. However, when Republican voters were asked in 1996 what happened to the deficit under Clinton, more than 55 percent said that it had increased. What’s interesting about this data is that so-called “high-information” voters - these are the Republicans who read the newspaper, watch cable news and can identify their representatives in Congress - weren’t better informed than “low-information” voters.
Anyone have a better solution? Or should we just throw in the towel on democracy?

Sylvain Le Gall: Distributing OCaml libraries: common problems for packager and how upstream author can help solving it

Having already done some Debian packages of OCaml libraries, I wish to share my experience on what are the most common problems. The intent is to help people releasing OCaml libraries to have a good interaction with (Debian) packager. I think most of the tips should also apply to other distributions as well. I consider the use of findlib mandatory for this task as described in the Debian OCaml packaging policy. Problems listed here are common, and I have encountered them for my libraries... In fact, most of the time when I finished building a personnal OCaml library I package it for my own and to test that everything is fine. Being a packager and an upstream author is really a different job. "Upstream author" is used for people developing and releasing OCaml libraries and "packager" for people doing packages for a distribution. Here is the list of the most common problems and their solutions:


Libraries are linked statically in OCaml. It is an advantage and a problem. But upstream author should remember that the LGPL license doesn't support static link directly. If you link an executable with the library statically, the executable is contaminated by the license. This error is probably the most problematic, because it requires to go through the whole project fixing license header for explaining that there is an exception to the LGPL.
There is no way for a packager to fix this problem. Packager are not allowed to change the license. Library having this problem can be still packaged but complicate the legal aspect of building application using this library.
Good example of this can be found in OCaml LICENSE itself :
As a special exception to the GNU Library General Public License, you
may link, statically or dynamically, a "work that uses the Library"
with a publicly distributed version of the Library to produce an
executable file containing portions of the Library, and distribute
that executable file under terms of your choice, without any of the
additional requirements listed in clause 6 of the GNU Library General
Public License.  By "a publicly distributed version of the Library",
we mean either the unmodified Library as distributed by INRIA, or a
modified version of the Library that is distributed under the
conditions defined in clause 2 of the GNU Library General Public
License.  This exception does not however invalidate any other reasons
why the executable file might be covered by the GNU Library General
Public License.
Followed by the text of the LGPL. Each file header looks like:
This file is distributed under the terms of the GNU Library General
Public License, with the special exception on linking described in 
file ../LICENSE.
By far this is the most common error I have seen. Upstream author consider that you are able to build a native and byte version of their library. Unfortunately this is not the case for most architectures. This error is pretty simple to fix by separating byte and opt targets in Makefile. The ultimate test is to rename /usr/bin/ocamlopt and /usr/bin/ocamlopt.opt to something different and try to rebuild the library from scratch. META file is the base of everything in findlib. This is very important to provide good META file because it helps other people to easily build thing over OCaml library. Each library should provide its own META file. Until now, Debian packager was used to write this missing META file and contribute it to upstream author. I think that now findlib has become a standard in OCaml developement, so upstream should take into consideration this file. A good test for META file is to install it and:
~$ ocaml
        Objective Caml version 3.10.1
# #use "topfind";;
- : unit = ()
Findlib has been successfully loaded. Additional directives:
  #require "package";;      to load a package
  #list;;                   to list the available packages
  #camlp4o;;                to load camlp4 (standard syntax)
  #camlp4r;;                to load camlp4 (revised syntax)
  #predicates "p,q,...";;   to set these predicates
  Topfind.reset();;         to force that packages will be reloaded
  #thread;;                 to enable threads
- : unit = ()
# #require "ZZZ";;
If you are able to load your library in ocaml toplevel, this is a good point. ocamlfind allow to install library. Using it is the best way to install your ocaml library. Moreovoer, you should use the most simple way to install. For pure OCaml library this is straightforward and allow Debian packager to override destination directory by using environment variable OCAMLFIND_DESTDIR.
install:
      ocamlfind install toto META toto.mli toto.cmi toto.cmxa toto.cma toto.cmx
For non-pure library, you could add a OCAMLFINDFLAGS variable to allow Debian packager add "-ldconf ignore":
install:
      ocamlfind install $(OCAMLFINDFLAGS) toto META toto.mli toto.cmi toto.cmxa toto.cma toto.cmx
".mli" files is the human-readable interface to the library. Even if most OCaml programmers use the ocamldoc HTML API of the library, it is best to distribute these files. In particular, Debian packager use it to automatically generate up-to-date HTML API documentation directly. ".cmx" files contain more informations than ".cmxa". Distributing these files allow application based on the library to be more optimized. This one comes from my "Windows experiment". Most of the time upstream author doesn't forget about "*.a" but doesn't add "*.lib" (yes is this windows counterpart of ".a" file). This one is not very OCaml specific. In Makefile and sh you have the same wildcard "*.mli". But if the wildcard is not expanded into sh, it just stay as is. It will make the executable called looked for a file "*.mli" literally. Mixing Makefile wildcard and sh is the best option here:
install:
     ocamlfind install $(OCAMLFINDFLAGS) toto META $(wildcard *.mli *.cmi toto.cmxa toto.cma *.cmx)
This way you test and expand to only existing files. This is more or less a problem. In fact, if everything is fine, there is no problem and you should just forget about this point. If the custom build system is complex and if there is an error in it: it becomes a big problem. I must confess that I have myself done this kind of mistake a lot of time. But looking back, I think that most of the time I should have used directly OCamlMakefile. I think relying on ocamlfind for library installation, simple Makefile, OCamlMakefile, OMake or ocamlbuild, is just enough. This point is a problem for upstream author and communication with packagers (from Debian and other distributions). A bug tracking system is a way to publish, comment, work on and find solution of bugs. If you have a single problem in a library having the bug public helps people to show you what is wrong. Of course, Debian (and Fedora, FreeBSD...) has its own bug tracking system and upstream author can use it directly. This is less work for upstream but tends to make the bug "distribution specific". Having an upstream author BTS helps to track the bug across distributions. If upstream author doesn't like maintaining their own BTS, he/she should consider hosting part of the project on a forge like OCamlCore.org. Even if they don't host the source code, this is still a good idea. That's all. If you have other common problems, feel free to comment, i will add it to the list.

14 September 2008

Neil Williams: oh dear - aspire one mail

Linpus Lite (or maybe just aspire one mail) is only going to last a few more days on this aspire1, it's beginning to annoy me:
Update
sylpheed has now replaced aspire mail. OK, I still use aspire mail for calendar and addressbook stuff (for now), but sylpheed is a much better email client.

  1. aspire one mail has no GnuPG support

  2. aspire one mail has no non-HTML composition support. No, really, it doesn't even send plain text alongside the HTML. email sent from the aspire to myself comes in as an attachment in other email clients! (i.e. spam)


So, I would have to investigate a different email client but then there are niggles with Linpus itself:
  1. the aspire default kernel build lacks the pl2303 kernel module so that I can't use the aspire to control my balloon3 board over usb serial

  2. intermittent problem with network manager forgetting WPA passphrases


Testing continues - probably resulting in installing Lenny at the end of this week. Some of these things might be fixable using pages like taoofmac and Reg Hardware.
Unfortunately, the problem with usbserial means that I'll have to take two laptops if I want to demonstrate the balloon3 board in places.
I also don't seem to be able to locate any copyright files which makes me nervous. Maybe it's just a lack of knowledge of Fedora (at least not since FC5).

13 September 2008

Martin F. Krafft: 9 years ago

Today, nine years ago, 13 September 1999 was a dark day for the human age: only a few days after more than a hundred of people were killed in bombings all over Russia, another bomb took the lives of 118 in an apartment complex in Moscow. Several other bombs were fortunately defused on the same day. NP: Pulp: This is Hardcore

Martin F. Krafft: Gazpacho are (finally) coming to Switzerland!

Gazpacho, one of my all-time favourite bands, are (finally) coming to Switzerland!!! On 17 October 2008, they ll play a gig at the Z7 in Pratteln/Basel. Guess who ll be there!?! It makes me very happy that they have recently signed WiV Entertainment as event/tour managers, because it means I ll probably get to see them more often in the future. To help a bit, I have agreed to be their Swiss street team (together with Tibor from Basel), which means I ll be distributing flyers and posters when I return from Ireland, in exchange for free tickets for Penny and myself. You should join us! Tickets are 22 and can be ordered from the Z7 concert page (scroll down, I can t link directly, unfortunately). According to their news page (scroll down a bit), they are also playing in Oslo on 26 September, in Verviers, Belgium on 18 October, and in Den Bosch, The Netherlands on 19 October. Don t miss them! NP: Pulp: Freaks

Gintautas Miliauskas: Russian to English dictionaries on Linux

Update (2008-09-13): the dictionaries in http://dictd.xdsl.by/dicts are probably more complete than the ones provided here, see this post for more information. It is very convenient for me to have a local dictd server set up, not only to look up obscure English words and jargon, but also for translation from foreign languages. Dictd is quite fast and powerful, with a multitude of dict clients to choose from. There are some pretty good free dictionaries too. For German, the dictionary in the Debian (Ubuntu) package dict-de-en (German-English + English-German) is fairly good. For Russian, the Mueller English-Russian dictionary (mueller7accent-dict) is great. Unfortunately, the Mueller dictionary does not contain translations from Russian to English. I have been using ksocrat for that purpose, but KSocrat is a little buggy and its usability does not shine. I looked around on the web for a downloadable Russian-English dictionary in dict format, but surprisingly could not find anything useful. There are quite a few online translation sites, heaps of small DOS-era utilities and some home-made Windows stuff, but nothing that would be easy to feed to dictd. What I did find was Sdictionary. Sdictionary is a dictionary application that has a fairly large community. Its Russian-English dictionary with 300 000 words was more than adequate for my purposes, but the database format was incompatible with dictd, and I couldn't find a converter on the web, so I wrote one. The converter from Sdictionary to Dictd formats is a bash script that dumps an Sdictionary file to a plain text file and massages it a bit so that it can be fed to dictfmt. To use the script you will need to install PTkSdict from swaj.net (Debian package) and the Ubuntu packages dictfmt and dictzip. Then just drop the script in the same directory as some dictionary foo.dct and run ./sdict2dictd.sh foo (where foo is the name of the dct file). The script should produce foo.dict.gz and foo.index which you can install into /usr/share/dictd. The script is far from perfect and discards some formatting but it's better than nothing. The best solution would probably be to extend dictfmt so that it could read the Sdict dump files directly. If you just want a dictd Russian-English dictionary, I have uploaded the files converted from Sdict here: rus_eng_full.dict.dz (8MB), rus_eng_full.index (15MB). By the way, when running in daemon mode, dictd eats an unreasonable amount of RAM (it's taking 40MB resident memory on my machine). If the dict server is only for personal use, it makes sense to run it through inetd as described in /usr/share/doc/dictd/README.inetd.gz. It appears that the speed difference is not noticeable on modern computers.

12 September 2008

Russell Coker: Not All Opinions Are Equal

It seems to be a common idea by non-bloggers that the comment they enter on a blog is somehow special and should be taken seriously by the author of the blog (everyone is a legend in their own mind). In a recent discussion one anonymous commentator seemed offended that I didn’t take his comments seriously and didn’t understand why I would take little notice of an anonymous comment while taking note of a later comment on the same issue by the author of the project in question. In most forums (and I use the term in the broadest way) an anonymous comment is taken with a weight that is close to zero. That doesn’t mean that it will be ignored, it just means that the requirement for providing supporting evidence or of having a special insight and explaining it is much greater. One example of this is the comment weighting system used by Slashdot.org (AKA “/.”). The /. FAQ has a question “Why should I log in?” with the answer including “Posting in Discussions at Score:1 instead of Score:0 means twice as many people will see your comments” [1]. /. uses the term “Anonymous Coward” as the identification of users who are not logged in, this gives an idea of how they are regarded. Advogato uses a rating method for blog posts which shows you only posts from blogs that you directly rank well or which match the trust metric (based on rankings of people you rank) [2]. I believe that the automated systems developed by /. and other online forums emulate to a some extent the practices that occur off-line. For any discussion in a public place a comment from someone who does not introduce themself (or gives an introduction that gives no reason to expect quality) will be treated with much less weight than one from someone who is known. When someone makes a comment their background will be considered by people who hear it. If a comment is entirely a matter of opinion and can not be substantiated by facts and logical analysis then the acceptance of the comment is solely based on the background of the author (and little things like spelling errors can count against the author). Therefore if you want your blog comments to be considered by blog authors and readers you need to make sure that you are known. Using your full name is one way of not being as anonymous but most names are not unique on the Internet (I’ve previously described some ways of ensuring that you beat other people with the same name in Google rankings [3]). The person who owns the blog can use the email address that is associated with the comment to identify the author (if it’s a real email address and it’s known by Google). But for other readers the only option is the “Website” field. The most common practice is to use the “Website” field in the comment to store the URL of your blog (most blog comments are written by bloggers). But there is nothing stopping you from using any other URL, if you are not a blogger and want to write comments on blogs you could create a personal web page to use for the comments. If the web page you use for such purposes gives links to references as to your relevant experience then that would help. Someone who has skills in several areas could create a web page for each one and reference the appropriate page in their comment. One problem we face is that it is very easy to lie on the net. There is no technical obstacle to impersonation on the net, while I haven’t seen any evidence of people impersonating others in an attempt to add credibility to blog comments I expect it’s only a matter of time before that happens (I expect that people do it already but the evidence of them getting caught has not been published anywhere that I’ve read). People often claim university education to add weight to their comments (usually in email but sometimes in blog comments too). One problem with this is that anyone could falsely claim to have a university degree and no-one could disprove their claim without unreasonable effort, another is that a university degree actually doesn’t mean much (lots of people remain stupid after graduating). One way in which adding a URL to a comment adds weight is that for a small web site the author will check a reasonable portion of the sites that link to them, so if someone impersonates me and has a link to my web site in the comment then there’s a good chance that I will notice this. OpenID [4] has the potential to alleviate this by making it more difficult to forge an association with a web site. One thing that I am working on is enabling OpenID on all the web sites that are directly associated with me. I plan to use a hardware device to authenticate myself with the OpenID server (so I can securely enter blog comments from any location). I expect that it will become the standard practice that comments will not be accepted by most blogs if they are associated with a URL that is OpenID enabled unless the author of the comment authenticates themself via OpenID. Even when we get OpenID enabled everywhere there is still the issue of domain specific expertise. While I am well enough known for my work on SE Linux that most people will accept comments about it simply because I wrote them, the same can not be said for most topics that I write about. When writing about topics where I am not likely to be accepted as an expert I try and substantiate my main points with external web pages. Comments are likely to be regarded as spam if they have too many links so it seems best to only use one link per comment - which therefore has to be on an issue that is important to the conclusion and which might be doubted if evidence was not provided. The other thing that is needed is a reasonable chain of deduction. Simply stating your opinion means little, listing a series of logical steps that led you to the opinion and are based on provable facts will hold more weight. These issues are not only restricted to blog comments, I believe that they apply (to differing degrees) to all areas of online discussion.

Riku Voipio: Marvell 78x00 board


What we are having here is a quite non-typical ARM based motherboard. It features a pre-production version of Marvell 78x00 series ARM SoC, clocked at 1GHz. It features multiple on-board sata and gigE connectors, as well as pci-e slots and DDR2 ram slots. Fairly "meh" in x86 world, but on the ARM world most systems are designed mainly for low power consumption, tiny size and low cost. Which, while creating allows creating many exciting devices, makes finding meaty buildd's tricky. When we intruduced armel port, the security people rose the concern that arm buildd's are too slow. Especially from the security Point of view, where getting security fixes out fast is important - every second of waiting for security builds to finish someone could be exploited!

Luckily, some people from Marvell had heard about our need and arranged to donate a developer board for us!

So far, the build speed improvement, compared to our current (Thecus N2100) buildd's is very promising. When looking at build times of some slow-building packages which likely will see security uploads:


Package Thecus MV78100 HPPA MIPS
linux-2.6 39h 11h 6h 17h
webkit 17h 5h 3h 4h
qt4-x11 59h 17h 7h 13h
xulrunner 14h 4h 1.5h 3h


We see that with a Marvell board we are more in the line with other architectures. And the production hardware is going to be even faster! There is a dual-core version as well, but it's not SMP. Both cores are independent, and would basically both run their own Linux image. If manage to find a easy way to implement and manage that, we could run two theoretically run two independent buildd instances on the same board.

See the Linux Devices article for more details about the MV78x00 in general.

Adrian von Bidder: 25 pair telco cable color scheme

I had to rewire a DSL concentrator (thunderstorm blew one of the ports...) today. The concentrator has two fan-out cables (input, output) with 25 RJ-11 connectors, color coded, so I had to find the colors of the remaining non-defective ports (there are 12 ports on this concentrator, the other 13 pairs are not connected. Presumably there isn't a 12 pair cable.) Google shows tons of references to the apparently standard 25 pair color code (first pair is white/blue), but unfortunately “my” cable had a light blue/light yellow first pair with most other pairs made up of cables with a base color and a colored stripe. I couldn't find the color chart on the Internet. Finally, the strange thought of RTFM entered my mind (and I even found the manual of the concentrator), and found that the importer has added a color chart leaflet to it; the cable is referred to as a “Telco50” cable. So here we go:
PairFirst WireSecond Wire
1redred — white
2yellowyellow — black
3greengreen — white
4blueblue — white
5brownbrown — white
6blackblack — white
7purplepurple — white
8orangeorange — white
9light greengreen — black
10blue — blackpurple — black
11light blue — blacklight blue — red
12light green — greenlight green — blue
13light green — blacklight green — red
14light blue — bluelight blue — green
15light yellow — redlight yellow — black
16light yellow — greenlight yellow — blue
17graygray — black
18gray — greengray — red
19red — blacklight red
20light red — bluelight red — green
21light red — blacklight red — red
12whiteorange — black
13white — bluewhite — green
24white — redwhite — black
25light bluelight yellow
(Actually, on the DSL concentrator here this order is listed as “pin” numbers while the 12 ports are assigned in reverse order, starting at 25. The concentrator is a Zyxel VES-1012 and is not in production anymore.)

11 September 2008

Martin F. Krafft: Host naming theme

Init Seven, my favourite Swiss ISP, has offered to collocate one of my machines in their racks with native IPv6-connectivity. I am now searching for a name for this new host. A recent discussion has made me curious about how many people can deduce my host naming theme from the set of names of currently operational machines under the madduck.net domain:
albatross, bell, brick, cigar, cirrus, clegg, diamond, echo, embryo, eugene, fishbowl, gerald, gnome, lapse, lust, mother, pict, pig, piper, pulse, seamus, sheep, time, vera, wall.
If you know what ties this list together, please help me christen the new machine! Update: the responses have been overwhelming, 183 people have written in so far, and 149 of them knew what s going on (though some admitted to cheating with a search engine). Thanks to everyone! In addition to the common theme, which most guessed correctly, I have a few other restrictions, mainly that the words have to be singular names or nouns, and that they have to feel right . Here are the suggestions I ve received which passed my filters, in decreasing order of frequency:
emily, lucifer, fletcher, lunatic, arnold, flesh, gig, bike, moon, brain, hand, balloon, hope, alan, marmelade, wing, heart, summer, thunder, sam, tropez, sky, stethoscope, khyber, lotus, jugband, cymbaline, remergence, dawn, hell, desert, worm, eclipse, dog, sysyphus, julia, scarecrow, sun, overdrive, vizier, matilda, eiderdown, babe, pillow, funkydung, atom, fore, shout, breast, domine, swan, charade, grantchester, money.
Curiously, I forgot about worm and wing, which are in use, so those are out. Some of them are not candidates because I d mistype them all the time ( stethoscope , cymbaline , sysyphus , remergence , scarecrow , eiderdown , marmelade , grantchester ). Some just don t seem right ( tropez , shout , overdrive , flesh , breast , sky , jugband , eclipse , lucifer , money ) Some are not appropriate as hostname for computers ( brain , heart , damage , hell , lunatic , babe ). Those who suggested machine were referred to my SMTP servers greeting banner. I have to scratch fletcher and desert because of their source. I have to do the same to thunder , unfortunately. And I ought to retire pulse , although not really. Noone suggested grimble and crumble . As there are so many, and so many more, I am changing my rule to significant, enigmatic, and memorable singular nouns and names , which brings us down to:
arnold, gig, bike, moon, alan, khyber, lotus, julia, sun, vizier, matilda, atom, domine, swan, charade, grimble, crumble.
Given that list, I think I will be launching gig, khyber, lotus, charade, vizier, domine, and/or swan in the near future. Or if it s a pair, it ll be grimble and crumble. Thanks all, this was fun. PS: you may use the same naming scheme for your hosts, but you take full responsibility in case you and I ever have to fuse networks in any way. NP: Riverside: Out of Myself

10 September 2008

Russell Coker: Execmod and SE Linux - i386 Must Die

I have previously written about the execmod permission check in SE Linux [1] and in a post about SE Linux on the desktop I linked to some bug reports about it [2] (which probably won’t be fixed in Debian). One thing I didn’t mention is the proof of the implication of this. When running a program in the unconfined_t domain on a SE Linux system (the domain for login sessions on a default configuration), if you set the boolean allow_execmod then the following four tests from paxtest will be listed as vulnerable: Executable bss (mprotect)
Executable data (mprotect)
Executable shared library bss (mprotect)
Executable shared library data (mprotect) This means that if you have a single shared object which uses text relocations and therefore needs the execmod permission then the range of possible vectors for attack against bugs in the application has just increased by four. This doesn’t necessarily require that the library in question is actually being used either! If a program is linked against many shared objects that it might use, then even if it is not going to ever use the library in question it will still need execmod access to start and thus give extra possibilities to the attacker. For reference when comparing a Debian system that doesn’t run SE Linux (or has SE Linux in permissive mode) to a SE Linux system with execmod enabled the following tests fail (are reported as vulnerable): Executable anonymous mapping (mprotect)
Executable heap (mprotect)
Executable stack (mprotect)
Writable text segments If you set the booleans allow_execstack and allow_execheap then you lose those protections. But if you use the default settings of all three booleans then a program running in the unconfined_t domain will be protected against 8 different memory based attacks. Based on discussions with other programmers I get the impression that fixing all the execmod issues on i386 is not going to be possible. The desire for a 15% performance boost (the expected result of using an extra register) is greater than the desire for secure systems among the people who matter most (the developers). Of course we could solve some of these issues by using statically linked programs and have statically linked versions of the libraries in question which can use the extra register without any issues. This does of course mean that updates to the libraries (including security updates) will require rebuilding the statically linked applications in question - if a rebuild was missed then this could be reduce the security of the system. To totally resolve that issue we need to have i386 machines (the cause of the problem due to their lack of registers) go away. Fortunately in the mainstream server, desktop, and laptop markets that is already pretty much done. I’m still running a bunch of P3 servers (and I know many other people who have similar servers), but they are not used for tasks that involve running programs that are partially written in assembly code (mplayer etc). One problem is that there are still new machines being released with the i386 ISA as the only instruction set. For example the AMD Geode CPU [2] is used by the One Laptop Per Child (OLPC) project [3] and the new Intel Atom line of CPUs [4] apparently only supports the AMD64 ISA on the “desktop” models and the versions used in ultra-mobile PCs are i386 only. I think that these issues are particularly difficult in regard to the OLPC. It’s usually not difficult to run “yum upgrade” or “apt-get dist-upgrade” on an EeePC or similar ultra-mobile PC. But getting an OLPC machine upgraded in some of the remote places where they may be deployed might be more difficult. Past experience has shown that viruses and trojans can get to machines that are supposed to be on isolated networks, so it seems that malware can get access to machines that can not communicate with servers that contain security patches… One mitigating factor however is that the OLPC OS is based on Fedora, and Fedora seems to be taking the strongest efforts to improve security of any mainstream distribution, a choice between 15% performance and security seems to be a no-brainer for the Fedora developers.

Steve McIntyre: Still ill... :-(

I posted a couple of weeks back to say that I'd got the Debconf plague again this year. Unfortunately, it looks like I picked up something worse than just the normal cold/'flu. I've been on penicillin for a week to try and clear up a throat infection, but it's not gone yet. Time for blood tests to see if I've got anything worse. I've been too ill to go to work several times in the last couple of weeks, feeling totally exhausted and feverish. Here's hoping that things start clearing up soon... Again, if I've not responded to you about Debian stuff lately then please pester/remind me as necessary and I'll try to get back to you.

Axel Beckert: deuxchevaux.org is back

My primary e-mail domain deuxchevaux.org was offline for one and a half week due to my (former) domain provider Korypet went bankrupt and probably hadn’t paid the registrar’s invoice for deuxchevaux.org although I had paid Korypet’s invoice. (The domain wasn’t expired. Its expiration date was somewhen in 2009.) Korypet itself just told its customers (and told it only on request) that they a) will shut down their business because it doesn’t pay off and that b) their service won’t be as good as usual since their head is currently in hospital. I should have noticed that there is something fishy and some details were missing at lastest when they told customers (also only on request) that they have to shut down some services earlier than announced because one of their providers has terminated their agreement with Korypet at short notice. I also should have expected that they couldn’t keep their promise to continue domains and DNS until May 2009 as they couldn’t keep other promised grace periods. I’m quite sad about how Korypet went down and how bad blood they caused — not only for me — since they offered not only good services for money but also had really good (and personal) support. But I guess that this quality at very low prices was also one of the reasons why they couldn’t keep up their business for longer. I had one of their UML based, low-end virtual “VD” servers for about six years, and used it as secondary DNS server and IRC client host. I also often thought about getting a second one at some other geographical location (they offered virtual servers in three German cities). That was the reason why I started to move my domains to them a while ago. They even could fully answer me domain registration questions for which the eDNS and the Hetzner staff only had partial and therefore confusing answers. Since it was the easiest way, I tried to transfer the domains I had registered with Korypet to the B2C division of their registrar Key Systems, to DomainDiscount24. The web interface isn’t as bad as the name “DomainDiscount24” suggests, but they seem to have communication problems if – as in this case – more than one of their business divisions are involved. It took at least two phone calls until they did the all the necessary things to get the domains transferred from Korypet’s business customer account to my newly created end customer account although they have a special form for former Korypet customers. Domains I registered after Korypet stopped accepting new domains (well, they just didn’t answer on my domain registration requests anymore) I have registered via eDNS which was a recommendation form someone on the DaLUG mailing list. My conclusion after these hassles: No more domain registration resellers, only directly interacting with registrars. Never register all domains at the same company. Have more than two DNS servers at different hosters. Don’t have domain registrations and DNS servers at the same company. So I now register my domains either at DomainDiscount24 or at eDNS. And .ch domains of course directly at SWITCH. (If only all domain registrations would be so simple and uncomplicated as with SWITCH!) And my DNS servers are currently hosted at x encon in Hannover (Yes, it’s a Xen DomU :-) and Hetzner in Erlangen. And a third one in Switzerland is already planned.

9 September 2008

Steve Kemp: Yo lunchbox, hurry it up.

Today I received two kittens. They rock. Somebody else who rocks? Martin F. Krafft. Martin rocks because of this gem I came across today managing ~/.ssh/known_hosts via git. The idea is that instead of having a single file known_hosts you have a known_hosts.d/ directory containing multiple entries that are concatenated together. So neat. So obvious. So nice. Rock award. ObFilm: Jay and Silent Bob Strike Back

Michal Čihař: White Russian and Aiccu problems

Today, I wanted to finish something what looked like easy task from beginning. To bing IPv6 connectivity to my home using tunnel from Sixxs. As I have an OpenWRT, I expected it should not be harder than setting up same thing on my Debian notebook. There exists several howtos on the net, we can take the one on Sixxs wiki as a good starting point. Just follow the instructions and you should get it working right? Unfortunately not. Aiccu connects, IPv6 addresses are assigned, subnet is correctly distributed over network using radvd, but IPv6 connectivity does not work. Going deeper into this issue, I found out that some packets go out, but nothing comes back. When comparing results with Aiccu set up on my Debian notebook, I noticed that packets from OpenWRT router are few bytes larger, but I didn't though it could be a reason. Unfortunately it was -- OpenWRT contains wrongly compiled Aiccu, which does not strip ethernet headers from outgoing packets and gateway then throws them out. This is a well known bug, but unfortunately nobody fixed it for White Russian. Anyway I'm not going to reinstall whole system to Kamikaze just to make the thing work, so I compiled the Aiccu package on my own and now the tunnel works fine. If you are interested, you can get the package here.

8 September 2008

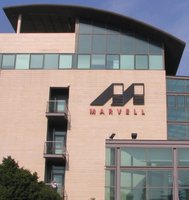
Martin Michlmayr: Visiting Marvell in Yoqne'am

Marvell in Yoqne'am Since I'm spending the summer in Israel, I used the opportunity yesterday to visit the Marvell site in Yoqne'am where the majority of the NAS software engineering team is located. They first gave me a tour through the hardware labs which I found incredibly interesting. It's amazing what equipment those folks use to perform QA tests of new chips, how they can reverse engineer chips and even make some modifications to test their theories about hardware bugs. I found it really amazing and at the same time felt glad that changing things in software is so easy. Later they showed me the software lab where they had an exhibition of various devices based on the Orion chip, including NAS devices, but also printers, wifi APs and game machines. They also told me some details of their product roadmap but unfortunately I cannot share that information. The only thing I can say is that we'll see a lot of new devices to which it would be cool to port Debian.

Holger Levsen: We had joy we had fun we had changelogs in the sun

In an hour the online part of this combined embedded+fai meeting in Badajoz in Extremadura, Spain, will sadly be over, but the sadness will hopefully be compensated by good food (yes, the food at the last dinner was great) and more fun! To me it were three intensive days (plus some two half days of intense travelling) which were really productive. This post is a summary of what I did here, to document how useful these meetings are. I'm only one person out of 18, who did some Debian work here, much more stuff was done, most of it I probably didnt even notice, as 14 people where working on embedded stuff, which I mostly ignored... ;-) That said, I think it was still very nice to have this meeting together, a.) because I'm quite interested in embedded stuff and b.) because the embedded crowd is a fun one to hang around with!

Right now I'm quite tired so that I dont fully remember what I have done on the first day :) It included uploading the DebConf7 mpeg videos which will now be used by Miguel Gea to create DVDs from those, so that he gets familar with the toolchain, so that he then can do the DebConf8 DVDs once those videos are (fully) ready. That will still take some time though, but hopefully not too long.

Unlike DebConf8 I also brought my fancy new fonera2 with me, in the hope to give it to someone to work on emdebian support for it. This is quite a longer road, as currently uclibc is not part of Debian, but thats only one step in this puzzle. Much to my joy Per Andersson took the opportunity to play with it and now took it home with him to document how to run Debian on it. I'm looking forward to see progress on this in the future ;-) Update: uclibc support is only needed for running Debian from the 4mb flash it has. But since it also has an usbport one can attach some storage there and run a full Debian system, just like on the nslug, which also has 32mb of RAM.

Unfortunatly I basically forgot about the FSG-3 I also took with me (which was for good reasons, one the second and third day I mostly did FAI work), but then I remembered 90min before the end, which was really too late. Narf. But Riku had a short look at it and told me one thing I didn't knew before: (at least) arm(el) kernels need to have the cpu id set in the kernel and the debian kernels don't have that, as they are build for more than one cpu type, so one has to prepend an arm assembler code instruction before running the kernel... I'm curious to do this soon :-)

But I have more hardware news to tell: C sar G mez Mart n (thanks for organizing this meeting, too!!!1) gave me back my OLPC laptop which I borrowed to him quite some time ago, so he could use it for a talk he gave at a university in Extremadura, so now I finally could give Andres Salomon new debian image for the XO a try. It was really nice to finally see a nice Debian gnome desktop on the device :-)

Today the FAI group, that was Sebastian, Michael, Thomas and me, also took a break to visit the Alcazaba de Badajoz (built around 1100, so roughly 900 years ago) which is an amazing building (thats why I linked to the spanish wikipedia entry as it has nicer pictures), from where you can see most of the city. I've been to Badajoz at least three times now and I'm really glad I finally did that, it's only 5min away from the office where the meeting was held and I highly recommend it to anyone going here.

Oh, and last and definitly not least I did a lot of work on FAI too. Besides discussing stuff which will hit planet after I posted this (hah! Michael already posted it, though without proper credit, so I will do a repost) I mostly reviewed changes and patches and discussed bugs, I didn't develop many patches myself (well, except one for the changelog..) but I've read every change at least twice, once as a commit msg and once in a full review. Plus many patches I read more often... all in all I think FAI is now in an great shape for lenny (which was the only thing we worked on during the weekend, we discussed some future plans, but work was only done for lenny), except that we want to another upload (with only documentation changes) after the upcoming one (which has quite some documentation changes already, but also some RC+important and some trivial bugfixes).

As you might have guessed, I started this entry on saturday and am finishing it now. According to the topic of the #extremadura2008 channel, which we created to coordinate between the groups, we also fixed 7 RC bugs (or 8? one should really document the bug numbers and not the number of bugs..) affecting lenny and 3 more which are only relevant to sid. Which is not as many as I would have liked to be fixed, but then, it wasn't a ("traditional") bug squashing party either. Which makes me wonder, are there any planned in the coming weeks?

So all in all I think this meeting was really very productive. Plus, I also enjoyed a special half an hour of real holidays: on saturday we had to leave lunch without having a chance to have a coffee afterwards, so I stumbled into a random cafe on the way to the venue. Turned out it was a very nice one, where due to its nice interiour I managed to reflect on life, 42 and all the rest almost immediatly. A totally unexpected but needed break. I wont say more here, because the thoughts and memories are really mostly relevant for me, but I'm really happy I found that space. DebConf8 and this meeting both were really fun, but I really didnt have a minute to reflect things. 30 minutes to do that is definitly not enough, but it was a good start. Now I just need to find another opportunity to continue with it. I hope this will happen before the next Extremadura meeting ;-)

Christoph Haas: mentors.debian.net s flakiness

A lot of users of mentors.debian.net have already mailed, irced and jabbered me. (Fortunately nobody rang at my door.) The service was pretty unreliable in the past weeks. If I’m not mistaken it was due to not enough RAM. Unfortunately it’s a VPS server (sponsored for that purpose by vpslink.com) that has 1 GB RAM but doesn’t allow to set up swap for the rare cases where a 100 MB more RAM would save the world. Took me a while to figure out where the infrequent “MySQL server has gone away” came from. That lead to packages either left in the incoming directory or being thrown away randomly during the import into the repository because not all database error conditions have been properly caught. The better news is that the debexpo project done during this year’s Google Summer of Code is now done. The Pylons-based software was written to suit the need for easy-to-use web-based Debian package repositories like PPAs or debpool. I am currently working on a few subleties of debexpo before it will be used for mentors.debian.net. I intend to announce the beta version of mentors.debian.net in about a week. And I hope for lots of feedback then. And let’s hope I get the RAM situation improved on the server. The mentors backend was the only software using the MySQL database. With debexpo (which uses SQLAlchemy for database interaction) I’m free to use PostgreSQL or even SQLite.

5 September 2008

Joachim Breitner: vm.overcommit_memory = 2, vm.overcommit_ratio = 0

Do you know this experience: A program, in my case subversion, has a bug and starts to eat memory. You can not interact with your system any more, only watch the memory and swap run full (if you have a display for that). Then it takes a while, while the kernel kills the (hopefully right) program. Things start to move again, until they are fully recovered from the swap and you can continue your work. Or the kernel does somehow not kill the right program, and you are screwed.During regular work, though, your swap is hardy ever needed. Only after a while, a few megabytes of never-used RAM is swapped out, to make space for using the RAM as a file cache.I d like to see the kernel not give out more memory to processes than there is physical memory, because that s plenty for normal work, and if there is more requested, then that s most likely wrong. But I still want the kernel to use the rest of the memory for caching files, and also move some unused RAM pages to the swap file.Unfortunately, there does not seem to be a settings that achieves this directly. But if you happen to have the swap about the same size as your RAM, then these settings, when written to /etc/sysctl.d/vm.conf, will do the job:
vm.overcommit_memory = 2
vm.overcommit_ratio = 0
The first one is to make sure the kernel does not hand out more memory than you tell it to, and the second is to make sure that it only hands out (swap size + 0 * RAM size) to processes.Beware that things go wrong if you happen to have no swap any more for some reason, beause then the kernel will hand out zero memory! Therefore, you need to make sure that these settings are applied after swap was enabled. On a Debian machine, rename /etc/rcS.d/S30procps to /etc/rcS.d/S37procps. This would not be possible if you could also specify the ration of swap memory to be used. Then I could set that to zero and the RAM ratio to 100.If anyone knows better ways to achieve this, I m interested to hear them.Update: For my qemu based armel package builder, this is not enough it seems. I m now running it with overcommit_ratio = 50.

Martin F. Krafft: Swamp airports with trash

I am surely not the only one to complain about the ridiculous liquids restrictions for airplane travel. Since these new regulation are in place, I ve challenged them, found holes, and compiled tips for those trying to blow up planes. I wouldn t write another story if it weren t for an idea I ve had at Zurich airport on my last trip to London: let s swamp the airports with trash so that they ll be forced to deal with Brussels and IATA to return to normal. After checking in for my flight, I stopped by the supermarket to buy two containers of yoghurt that would make someone happy. The containers each said 150g (that s weight, not volume) on them, and I put them into a clear, resealable one-litre bag, placed them into a tray to be x-ray-scanned separately, only to have them confiscated. After discovering (not much to my surprise) that the security staff didn t know the difference between weight and volume, nor understood the concept of density, I got a chance to speak to the head security officer (surrounded by five police whose attention I d gotten), and learnt that Zurich airport has one ton of trash to discard every day, Frankfurt supposedly has to deal with four. As I was walking onto my plane, I tried to think of non-recyclable containers that we could fill with liquids to bring along to increase that amount. My theory was that once the trash problem became too massive, the airports would have to deal with the authorities to resolve this liquid restriction, because it seems quite clear that normal people have no way to influence choices made that affect our safety . Unfortunately, I see two problems: First, we d be dealing with trash and hence face all the environmental concerns. The airports do not recycle the millions of PET bottles they confiscate every day, so we shouldn t make that worse. Unfortunately, I cannot think of another liquid container that wouldn t come with similar concerns. Second, the airports might have the burden, but they won t carry the cost of all the trash. In fact, thanks to the security theatre related to liquids, we already pay higher airport taxes and charges. Surely it can t be in our interest to push that further up the scale. So in the end, swamping airports with trash doesn t seem like a viable way forward, unfortunately. I wish I knew what to do. I wish that the decision makers at IATA would finally admit that they overreacted and revert to normal, with sensible security measures, which focus on fending off the real threats, not fake ones. Unfortunately, nobody likes to admit that they were wrong, especially not when the decision is heavily backed up by the lobby of vending machine companies and restaurant owners, who benefit greatly from these ridiculous liquid safety measures. NP: Pulp: We Love Life

Next.

Previous.