Search Results: "ana"

20 February 2012

Ben Hutchings: Feed reading

I switched from Google Reader to Liferea a while back. I was mostly happy with the functionality of Reader but I don't really want my reading history to be recorded or my feed list to be vulnerable to the whim of Google's inscrutable abuse department. I'm still using Liferea but unfortunately it has a lot of problems. Yes I do have bug numbers: So, I'm looking for an alternative again. My requirements are:
  1. MAY be a desktop or web application.
  2. If it's a web application, it MUST be reasonably secure, e.g. it must not be written in PHP.
  3. If it's a web application, it MUST allow for multiple independent users on the same server.
  4. If it's a desktop application, it MUST embed a browser engine (presumably Gecko or WebKit) so I can follow links without having to switch windows.
  5. MUST support organisation of feeds by folders or tags, including combined item lists.
  6. MUST keep track of which items have been read.
  7. MUST support a global 'unread items' list. SHOULD only remove items from this list when I refresh it, not as soon as I move away from an item.
  8. SHOULD support a three-pane (folder/list/item) view or something similar. Google Reader's list view with expanding items is perhaps even better, though it means links must be opened in a separate tab.
  9. SHOULD support folder and item navigation by keyboard.
  10. SHOULD have some way to flag/bookmark items for later attention.
  11. If it's a desktop application, it SHOULD have some sort of download manager to support podcasts.

19 February 2012

Richard Hartmann: RAID sucks

Intro RAID sucks, and so do all other Free alternatives in the Linux world. Having been in exactly the same situation several times in the past, I have been following Russell Coker's posts regarding data integrity with interest. FWIW, the correct answer to "BTRFS (sic) and Xen" is: subvolumes. Now that Fedora has, once again, decided to postpone their switch to Btrfs as default file system, I decided to write up my own take on this topic. Any and all my considerations are made under the assumption that important data is backed up while semi-important data is at least living on two different machines. Beware, this is a long post, but I do like to think it's well worth reading. RAID Disk failures Let's recap the current situation for "traditional" file systems like xfs, ext 2..4 , etc. In case you need to freshen up on the technical details go here. Silent corruption All the RAID levels with redundancy are fine and dandy if you lose a whole disk and put in a new one. Of course, that does not help you the tiniest bit once you get read errors. Controllers which manage RAID 1 or 10 may or may not compare the data while it's being read and may or may not tell you about discrepancies. They can then toss a coin and give you either result. There is no way to determine which is correct. RAID 2, 3, 4, 5, and 6 could, in theory, verify the data as it's being read, but that would limit your read rate to that of a single disk so no one does that. We actually had a massive web presence fail over night, once. No one knew what the cause was as there hadn't been any kind of access logged. As that particular deployment is done directly from a VCS, we simply ran a diff and found one change. We traced the failure down to a syntax error; a one character change made everything fail. Looking at the ASCII table, it was clear that one single bit had flipped. This sucked. A lot. Mitigation So you end up scrubbing your RAID sets on a weekly basis, recovering from silent corruption with the help of your RAID 6's two parity stripes. And even though you schedule the scrubbings with the least priority, you still take a performance hit when randomly seeking a lot. ZFS Some smart people at Sun set out to fix these problems and more, and fix it they did. The "Z" in ZFS is meant to imply that this is the last file system you will ever need and if not for its license, this might have worked. Of course, "last" and "forever" mean "not now" and "10 years" respectively, in computer terms. The limits within ZFS have been chosen so that the entropy needed to create a disk able to max out a ZFS volume would, literally, require our oceans to boil. Let's just say that you won't encounter these limits any time soon. While that is a nice thing to know, it does not say anything about data integrity. There are several mechanisms ensuring data integrity built in ZFS, the most fundamental being extensive checksumming. Checksums are vastly superior to live comparisions which RAID would have to perform as it does not need to sacrifice any significant i/o reading checksum data. With HDD access, you are i/o-bound, and not CPU-bound, anyway, so performing the checksum calculations is laughably cheap when factoring in the added safety. Everything, be data, metadata, inodes, you name it, is checksummed. Every read operation must go through the checksumming functions, ensuring that all data which reaches your user space is correct. If ZFS can't verify the checksum, it will not deliver any data at all, ensuring noticeable, as opposed to silent, corruption. So how does ZFS recover when the checksum does not match the data? copies= 1..3 The easy way is to store several copies of your data within your volume. Mount a ZFS volume or subvolume with copies=2 or 3 and all data that is being written from then on will be copied twice or three times. Trivial in principle, but powerful when built into a file system. RAIDz 1..3 This is where things start to get interesting. RAIDz1, 2, and 3 will allow you to lose 1, 2, or 3 disks respectively while still retaining your data; at the obvious expense of the storage capacity of as many disks. Basically, RAIDz2 is ZFS' variant of RAID 6, but it's so much better than mere RAID 6. Moo! RAIDz will not assign fixed slices and fill them up like RAID does. It will look at the current write speeds and use appropriate slice sizes dynamically. As a direct result, data which has been written at roughly the same time will always be near other data written at the same time. This is very nice for functionality like snapshots, writeable subvolumes and other things and is called COW, ZFS' variant of super cow powers. This also enables ZFS to write data, read it back and verify the checksum and only then point to the new data. Atomic commits done right. Keep rollin' As ZFS has to keep track of what data is still in use in which volumes and subvolumes anyway, it knows which regions are free to be reclaimed. Instead of filling up random places, ZFS will roll over your disks, overwriting unused data on the fly. This bears repeating: Contrary to RAID 5 and 6, ZFS will never need to read old data in order to write new data. Write performance galore and anyone still stuck on RAID 10 can finally enjoy the increased data security. Btrfs To be completely honest, I do not know Btrfs as well as I know ZFS. If I get anything wrong, correct me. If I offend anyone with my outsider's interpretation, that is not my intention. Btrfs has been initiated by Oracle way before it ever even thought about buying Sun or history might have run a different course, for worse or a lot worse. The closing of Java, Solaris, ZFS, Hudson, OpenOffice (since then "gifted" aka thrown away), and others makes me think the latter. As there are few technological developments which caused me as much stress, overtime and pain as OCFS2, I am naturally wary of file systems sponsored by Oracle and their data focus integrity/availability. The fact that there's still no way to fsck a Btrfs volume could be birthing pain or yet another facet of Oracle's stance on this topic, I honestly don't know. Either way, it's a good idea to be wary for now. I can't say too much on Btrfs' technical underpinnings, but I know it uses COW and that it has its own variant of RAID. Toss in snapshots (writeable?), subvolumes and integrated block device management, and you have the building blocks of a decent file system. Still, Btrfs is not ready for prime time. Btrfs has been "one or two years in the future" for a few years now so I will not be holding my breath. And once the first distributions are starting to use Btrfs by default, people will lose data. A year or three after that, I will feel comfortable to use it myself and in production. Commercial solutions You can either hand a lot of money to proprietary vendors who will not tell you a thing about how things work internally (and no way to fix things directly) or you can buy solutions that employ ZFS in the back-end. I prefer my storage hardware to be relatively dumb while keeping the intelligent bits where I can see and poke them so this is not really part of these considerations. So what can you do? Test your disks before deploying them Easy, but vitally important:
disk=/dev/foo
smartctl -a $disk
smartctl -t long $disk
badblocks -swo $vendor_$model_$serial_$timestamp.badblocks.swo $disk
smartctl -a $disk

If you are lazy, get a copy of disktest, a tool I wrote to do exactly this. It should wait for the long self-test to finish, can not read out all vendor names, and does not have a way to document who ran the test, but it's a start. Patches and feedback are, obviously, welcome. And yes, I will package this soonish. Using your disks This list is surprisingly short. You can use And that's it. At work, I prefer small RAID 6 volume sets. It sucks, but there is nothing better. For personal use, I have a machine with a FUSE-based RAIDz2 mounted with copies=2. Three disks can fail and my data is still secure. While this setup is slow as molasses due to FUSE, speed is not a consideration for me here; data safety is. A migration to Debian/kFreeBSD in the medium term is still likely. If you have things to add or disagree with me, I would love to hear from you. Update: Jan Christian Kaessens pointed out that, contrary to my experience, zfsonlinux did not bring down his sytem in flames. As zfsonlinux is a kernel module, potential performance is a lot better. Also, it supports ZFS Pool Version 28 as opposed to FUSE-ZFS' 23. While the really nice features are in v 29 and 30 (which are closed thanks to Oracle) v 28 still has some nice changes.

Petter Reinholdtsen: First release candidate of Debian Edu / Skolelinux based on Squeeze

One week delayed due to DVD build problems, we managed today to wrap up and publish the first release candidate for Debian Edu / Skolelinux based on Squeeze. The full announcement is available on the project announcement list. Check it out if you need a software solution for your school.

Russ Allbery: Debian, licenses, and license-count

A few people have been using the license-count tool that I wrote to analyze the breakdown of licenses in Debian and draw some conclusions. Unfortunately, some of those conclusions can't be drawn from the output of this specific tool (which doesn't make them wrong, just unproven). So here are a few cautions. license-count was written for a specific purpose: to see how many references there are to a particular license in Debian so that we had some facts behind our discussion of whether to include it in common-licenses. It was not written to classify packages into particular categories, only to find out how many copies of a license we could save by adding it to common-licenses. This means that using it to determine how much software in Debian is covered by a particular license fails in the following ways:
  1. license-count numbers cannot be added. Since the goal is to find every reference to a given license, each package is not classified as under one and only one license. If a package has material under the GPL, the LGPL, and the GFDL, it will add one to each of those counts. This means that you cannot determine, from its output, questions like "how many packages are covered under one of the GPL family of licenses?" You will double- or treble-count packages when you add the numbers together.
  2. license-count counts any reference, not just "important" ones. If the license is referenced in debian/copyright, that counts, since the goal is to see how many packages might benefit from being able to reference it in common-licenses. This may not be the license that the package is under, just some small portion of the package. For example, all of my packages that use Autotools add to the GPL count because I include all the source code licensing statements, including the statements for libtool and the Automake helper scripts, which say that the files can be released under either the GPL or the license of the including package. These packages are generally under a BSD-style license (or in some cases the Apache 2.0 license), not under the GPL, but since the reproduced license text has a reference to the GPL, license-count adds one to the GPL column for each of those binary packages. For most purposes for counting GPL-covered software, these are false positives. I don't know how many people are as complete in documenting license statements as I am, but just the binary packages that I maintain probably count for at least 50 false positives because of this alone.
  3. license-count numbers include dual-licensing. Whether this matters for your analysis or not depends on what question you're asking, of course. If you're asking whether the package is covered under a copyleft license, including the thousands of packages that are dual-licensed under the Artistic license and the GPL may be okay, since the Artistic license is a sort of copyleft (although it allows you to avoid the copyleft requirement by renaming executables, providing the originals, and documenting your changes). But, for example, one of my packages is dual-licensed under a BSD-style license and the GPL (for reasons that aren't worth getting into). This package is not covered by copyleft under any reasonable definition of the term, but license-count will count it as a package using the GPL.
In order to draw interesting conclusions like "how much software in Debian is protected by copyleft," I'm afraid that you'd have to write a much more sophisticated tool than license-count.

18 February 2012

Biella Coleman: Montreal, first impressions

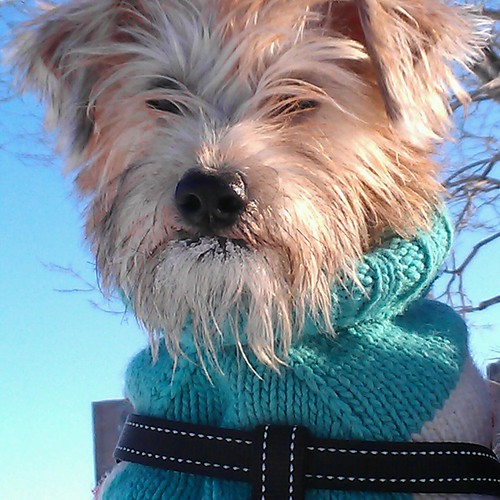
frozenlights When I told people of my plans to move to Montreal, it usually prompted one of two reactions: one was some version of joyful envy, many people exclaiming breathlessly Montreal is one of my favorite cities, one person once even clutching my arm and told me as he looked me straight in the eye: you are so lucky, there is no city quite like Montreal in North America. The second reaction came off as a thinly veiled mixture of disdain and disbelief usually peppered with many reallys: oh wow, really, really you would really leave NYC? I am pretty certain they really were thinking something along the lines of what a fool, how dare she leave a great job, a great university, a world class city (the only city to live) for some Canadian mid-sized city, which is like tundra for a good chunk of the year? The decision to move weighed heavily on me, if for no other reason I had a choice to stay or to go and I honestly have not had a choice, a decision to make about where to go since I got accepted to graduate school (and even then the choice was more obvious than this one). So over a month into my move what is my verdict? In a word, win. I don t miss NYC at all though I get why some people cannot leave the place and know that despite some oddities and difficulties of living in Montreal, it fits my tastes and needs much better than NYC which dwarfed me in so many ways. I never felt I could enjoy it, I grew tired of the cramped living quarters, the noise ate at my soul, and I simply felt more overwhelmed by the fact that I could not even get a handle on the neighborhoods in my vicinity, much less all the other hoods in the area. Instead of dogging NYC anymore, I think I will spend a little time on first impressions, as they will soon be lost to the familiarity borne with time and experience. In essence Montreal is chock full of life but rather intimate, a quirky city with lots of charm but some grit and lacking the way over designed and done feel of cities like Portland. Here are some of quirks: 1. The Hawt Metro: I fell in love with the Metro when I first rode it a few years ago. I just love the powder blue color of the cars and the super sweet 1960s aesthetic of many stations. Even better and unlike NYC, they are just clean and quiet. The downside? The temperatures approximates a sauna during the winter and while you would think this is a good thing, when you are layered with the clothing necessary to survive outside (re: long underwear along with Canada-coat, gloves, hat, and scarf), it is hooooooot down there and you feel like you need to pass out. 2. Spend money, get free stuff: In many establishments you get free stuff (like blueberries or some like sports bar) when you spend over a certain amount of money, like 70 bucks. Quirky local tradition. 3. The culture of negotiation and the kick ass standard lease: Housing is amazing here. There is plenty of it, there are many different styles, and it is rather fun exploring all the different hoods that make up the city. Problem is too that lots of apartments have weird problems and issues and I had to steer clear of anything that could even possibly have mold. I spent weeks day in day out looking for a place, desperate to move out of my corporate apartment very nicely provided by the university but still not my ideal living situation. Finally found a place that fit all my needs in the perfect location and I took it to only find out that places are priced to negotiate and I was faced with the decision to negotiate or not. Sort of did, was not thrilled about it (thinking that I might lose the place) but it sort of worked and I scored the place. If price is up to haggling, the lease on the other hand, is standard (you can buy one at your local bodega ). It is the law to use it and it is like a no nonsense, straightforward lease, which is very protective of renters. 4. Montreal is known for its exceptional food but you know Poutine is just plain gross: Food here is good and I can tell that I will get a handle of restaurants in a way that felt impossible in NYC. The gluten free religion seems to be spreading, thankfully. There are many little Fruiterias! to get your fruits veggies which I am still exploring and right around my house is a crazy supermarket that is so cheap, which is weird because consumer goods generally ain t cheap in Montreal like they are in the states but this place is a gem and everyone agrees (and almost impossible to notice from the street!). Now Poutine is disgusting. Ok it did not help that the first night I went out to eat it, I was still under the clutches of Noro virus, and I think it re-activated the nausea that had been zapped by some strong medicine and the hospital, the day before, which brings me to the next point, the health care system. 5. Healthcare, I had to use it way too early: So last week I came down with the Noro virus and you usually wait it out as it runs through you quickly but I was dehydrated before I even started to vomit to for 8 hours straight, at which point severely tired and so nauseous (I was yelling to make it stop), I went to the hospital. Now I had talked to lot of people about the healthcare system in Montreal as it seems good, really great but a bit over taxed, especially compared to where I had lived in Edmonton where it was like a magic fairy tale dream. I had heard of two things: the care is excellent but the facilities are shocking and the wait times unless dire can be atrociously long. So facilities, yea they are kinda shocking, somewhat shabby but who cares, so long as the care is good, no? Packaging is irrelevant so long as the goods are derived. Before going I was scared of the long wait times (and also the taxi took me by mistake to Montreal General Hospital was looked too much like a HUGE version of the creepy buildings in The Shining for me, and I was supposed to go to Jewish General so left for there). The wait time: nearly none, somewhat as shocking as the facilities first looked to me. I think it was a combination of the time I arrived, with the fact that my lounge was parched and yellowish-gross (sorry, it was gross), indicating I was dehydrated, oh and I was crying bit hysterically, for despite my high threshold for pain, nausea terrorizes me. I was covered by insurance and since I did not yet have my McGill health cards (it takes three months to qualify for the local stuff), I did pay and the price was laughably cheap compared to what I would pay in NYC for the same treatment. 6. Now for my favorite, snow so nice, ice oh Christ: Well this winter has been, by all accounts, weak and warm, the spirit of winter barely making its way from the underworld to the outerworld. But even though it is has been more idle than full throttle, I still got a pretty accurate taste of what winter is like, with a few days of 20- c temps, and having to walk a number of times on a layer of frozen ice that makes it feel like a very dangerous mini-ice age in the making. IMAG0028-1 I do rather love the quiet snow falling and just love love sprinting through the snow with my dog, Roscoe, who has taken a liking for prancing in the white stuff and looks awful cute with his winter man s ice beard. After a sizable snowfall, it is clear they city does not toy with the snow removal although the sidewalk snow plows do look somewhat like very large and dangerous but kinda cute toys. But let s be frank, winters are hard, so hard that I think I would go mad if I had to stay through the entire thing, being born and raised in the tropics So the fact that I am writing this from the southern hemisphere in the height of summer gives me the assurance I can handle the rest of the snow, ice, ice and snow upon my return.

Stefano Zacchiroli: GPL-d Debian software skew (?)

At FOSDEM, John Sullivan delivered an interesting talk titled Is copyleft being framed? to verify alleged claims on the decline of GPL-d software. (Slides are available.) The crux of the talk is the analysis he performed on the Debian archive to discover the amount of software we distribute that is covered by GPL, LGPL, or AGPL ("GPL-d" for short in the remainder). John's talk steps in an interesting and long running debate (a recent summary of which is available in this ITWire article). The most interesting part is the discrepancy among John's results and Blackduck's, which are often used to argue how the popularity of the GPL license is declining. That might be the case. Or not. The more analyses we do to find it out, the better. The underlying assumption on John's work is that Debian is a representative sample of the Free Software out there, which I think is a reasonable assumption. I find the analysis presented in the talk completely satisfactorily from a purely scientific point of view. The same cannot be said about Blackduck's result: both their methods and data are secret, making it impossible to reproduce their experiments. Highly unscientific. Still, John's results are surprising: as much as 87 percent of Lenny's packages and 93 percent of Squeeze's are GPL-d. That seems a lot. Puzzled about that, John discussed with me the issue before his talk, in search for pitfalls in his methods or data. Finding none, I pointed him to the almighty DktrKranz for some extra review; who found nothing either. To stay on the safe side, even during his talk John called for independent reviews of his results. What could be wrong? The tool used to gather the data is license-count from the debian-policy package. Input data are the debian/copyright files of all Debian source packages. If license-count is not bugged, our debian/copyright files might be. One thing that occurred to me only a few days ago is the habit of declaring a different license for Debian packaging (the files under debian/) than the software being packaged itself. That's a bad habit because it might cause unwanted license mixtures via patches that live under debian/ but I've seen several occurrences of it in the Debian archive. For name and (self-)shame: I've also been guilty of it in the past, when I was young . Is that reason enough to skew results and overestimate GPL-d software? I don't think so, I hope not, but ultimately I don't know. It'd be nice to rule out the possibility entirely. So if anyone is willing to do some sampling of affected debian/copyright files and propose patches for license-count to exclude those "false positives", please shout. (As a bonus point: that would also help to take more sound decision for the typical use case of license-count, i.e. deciding when a license should be added to /usr/share/common-licenses.) Other independent reviews of the results are equally welcome. Note: the above, as well as John's analysis, would be a trivial exercise if DEP-5 were already widely deployed in the Debian archive.
Update: add link to John's slides
Update 19/02/2012: Russ Allbery, author of license-count, posted a way more likely cause of data skew in John's analysis: double counting among the different types of copyleft licenses

Neil Williams: Introducing ladder

We needed a new package at work and once I'd written it, I realised that it could well be useful for others, so I did the ITP and the package is now in Debian unstable.

Ladder - Stepwise repository upgrade tool

Ladder creates a local repository of packages required
to upgrade a tarball of a chroot to a new milestone or
software release.
.
The repository can be signed and includes all specified
target packages and dependencies. The repository can then
be distributed and used to upgrade multiple devices in
sequence without needing network access.


The only dependencies are some simple perl modules, reprepro for the repository, apt and gnupg for the signing. None of those need to be particularly recent versions, so once ladder has had a little time in testing, I will be doing a backport to Squeeze. Lenny is a little less likely but eminently possible if someone specifically asks for it. Not that it particularly needs a backport mind, if you want to run ladder on some other Debian-based system, it's simply a case of installing the version in unstable. reprepro was in Lenny at a suitable version for what ladder requires, so any system remotely recent should be able to run ladder without changes.

Normally, whenever you need to upgrade a device, you need to get that device onto a network, get access over the serial port or some form of pre-configured network connection, run the commands and clean up afterwards. OK, now do that again... oh and here are another 40 or 100 devices which all need precisely the same thing done and they all have to be shipped to paying customers today. What does any geek do? Script it.

Ladder is part of that process. There would need to be some scripting / programming support on the devices concerned but ladder makes it easier to put that support in place at the design stage and then automate the actual update without the device needing to get onto a network and, potentially, allowing you to decide how to offer the upgrade (automatic, user involvement, engineers only etc.) Once that is implemented, the device is simply pointed at a locally mounted filesystem which contains the ladder step for the migration. Each step is a SecureApt signed repository which is available at a deterministic location which can be easily scripted and which contains only the packages necessary (with dependencies) to upgrade any device installed at Milestone A to Milestone B. Nice and small, only the stuff you need, whatever architecture you like and if you need to migrate from Milestone A to Milestone D, then you create a few steps on the ladder and automate the migration from A to B to C to D. All you need is enough space on whatever local media you need to use to plug into the devices. Then copy the media enough times, start the interface on each device and do something useful whilst the upgrade happens. Then, when the next lot need to be upgraded, you already have the media... Oh and ladder does not need to run on the same architecture as the devices - all package handling is entirely architecture-neutral. So create the ladder steps and media on your fast x86 machines and then let the slower SSD devices take their own sweet time via automation. Simple - maybe, hopefully.

I'm expressly talking about devices here because this is where the original requirement arose - embedded devices which don't have direct / automatic / accessible network ports or even a working network configuration preset. These aren't new images to flash onto the device either, these are apt repositories, so only the stuff which needs to be changed is changed which saves a lot of time writing to slow SSD storage.

If the mechanism sounds familiar, yes, it's using the same principles as xapt, multistrap and emdebian-grip but I thought it could be useful, so I generalised the interface (a bit) and uploaded.

Let me know via the BTS if you need tweaks to the support. Ladder isn't particularly about getting desktop machines from Debian Potato to Debian Wheezy because you need to identify a target package to be the top point of the dependency chain which gets into the step repository and all devices should start with the same packages at the same versions. Normally, the kind of devices I use at work have a single top level application which is the sole user interface and which directly or indirectly depends on all the other software required for that device. Whilst the target package value could take a few carefully selected packages instead of just one and there is support for an extra packages field, it's not intended / expected to be useful for desktops. This is for use with multiple devices which all have the same package selection, are at the same milestone at the start and which all need to migrate smoothly to whatever milestone is intended - one step at a time. Ladder could be used to migrate between Debian releases and I've included example config files to support that, but the principle usage is with internal / proprietary repositories based on a common Debian stable platform where the user interface software is managed via identifiable milestones and where users have no direct control over installing packages. It's a production / manufacturing support tool more than a user / admin support tool. If you want to manage servers and desktops which allow users to install (or request to be installed) arbitrary packages, there are plenty of tools which already support this and are used by DSA in Debian for exactly these tasks. Ladder is not puppet but Linp didn't sound like a good name...

Ladder step repositories only include the binary packages, not sources - so if the migration is not going to be done in-house and you're expecting to distribute these steps to users somehow, ensure that the original source repository is available online for the Debian / free software packages concerned. If you can't do that (because the source is proprietary), you possibly shouldn't be distributing the binaries as a user update mechanism in the first place because each step will include packages from the core Debian system which need to have the sources available when distributed.

Inevitably, the ladder source package already contains two POT files for translations of the runtime messages and the POD based manpage. I expect to need to expand / clarify the manpage in due course, so don't rush to translate it yet as it's likely to change.

Benjamin Mako Hill: Advice for Prospective Doctoral Students

There is tons of advice on the Internet (e.g., on the academic blogs I read) for prospective doctoral students. I am very happy with my own graduate school choices but I feel that I basically got lucky. Few people are saying the two things I really wish someone had told me before I made the decision to get a PhD: Most People Getting Doctorates Probably Shouldn't In most fields, the only thing you need a PhD for is to become a professor -- and even this requirement can be flexible. You can have almost any job in any company or non-profit without a PhD. You can teach without a PhD. You can write books without a PhD. You can do research and work in thinktanks without a PhD. You don't even always need a PhD to grant PhDs to other people: two of my advisors at the Media Lab supervised PhD work but did not have doctorates themselves! Becoming a tenured professor is more difficult without a doctorate, but it is not impossible. There are grants and jobs outside of universities that require doctorates, but not nearly as many as most people applying for PhDs programs think. Getting a doctorate can even hurt: If you want to work in a company or non-profit, you are usually better off with 4-6 years of experience doing the kind of work you want to do than with the doctorate and the less relevant experience of getting one. Starting salaries for people with doctorates are often higher than for people with masters degrees. But salaries for people with masters degrees and 5 years of experience are even higher -- and that's before you take into account the opportunity costs of working for relatively low graduate student wages for half a decade. PhD take an enormous amount of time and, in most programs, you spend a huge amount of this time doing academic busy work, teaching, applying for grants or fellowships, and writing academic papers that very few people read. These are skills you'll need to be a successful professor. They are useful skills for other jobs too, but not as useful as the experience of actually doing those other jobs for the time it takes to get the degree. Evaluating Graduate Programs If you are still convinced you need a doctorate, or any graduate degree for that matter, you will need to pick a program. Plenty of people will offer advice on how to pick the right program and trying to balance all the complicated and contradictory advice can be difficult. Although I love my program and advisors, I've known many less happy students. Toward that end, there are two pieces of meta-advice that I wish everybody was told before they applied:
  1. Find recent graduates of the program you are considering, and the faculty advisor(s) you are planning on working with, and look at where they are now. Are these ex-students doing the kind of work that you want to do? Are they at great programs at great universities? Chances are good that a PhD program and its faculty will prepare future students to be like, and do work like, the students they have trained in the past. Programs that consistently make good placements are preparing their students well, supporting them, making sure they have the resources necessary to do good work, and helping their students when they are on the job market. A program whose students do poorly, or just end doing work that isn't like the kind you want to do, will probably fail you too.

  2. If recent graduates seem to be generally successful and doing the kind of work you want to do, find one who looks most like the kind of academic you want to become and talk to them about their experience. Chances are, your faculty advisors will overlap with theirs and your experience will be similar. Ex-students can tell you the strengths of weaknesses of the program you are considering and what to watch out for. If they had a horrible experience, there's a decent chance you will too, and they will tell you so.

Doing these two things means you don't have to worry about trying to think of all the axes on which you want to evaluate a program or pour through admissions material which is only tangentially connected to the reality you'll live for a long time. What matters most is the outcomes, of course, because you're be living the rest of your life for a lot longer than you'll be in the PhD program.

17 February 2012

Joey Hess: addicted to $

One of the weird historical accidents of programming languages is that so many of them use $ for important things. The reason is just that out of the available punctuation, nearly all of it has a mathmatical or other predefined use that makes sense to retain in a programming language context, while $ (and also @ and #) do not. Still, $ annoys me, it's so asymetric that we use it all over our code, and never a or to be seen. The one language that manages to use $ nicely, IMHO, is Haskell. Recently I noticed that it has an actual visual mnemonic in its use of $. And it's used for something I've not seen in other languages. The visual mnemonic of $ is that it looks like an opening parenthesis, with the related closing parenthesis on a line below it.
(something (that
    (lisp folks
        (are (very (familiar with)))
    )
))
And this is also the problem that $ solves:
something $ that $
    haskell folks $
        are $ very $ familiar with
This is a trivial feature.. but oh so useful. The implementation in Haskell of $ is simply:
f $ x = f x
infixr 0 $
Just function application, but at a different precedence than usual. I am now very addicted to my $. Out of 15 thousand lines of code, only 87 contain )), while 10% use $.

16 February 2012

Eddy Petrișor: HOWTO: Git - reauthor/fix author and committer email and author name after a git cvsimport

You might find yourself at some moment when your git repository imported from CVS does not contain all the correct names and email addresses of the commits which were once in CVS but are now part of your project history in your git repo. Or you might do a cvsimport which missed a few authors.

Let's suppose you first import the cvs repo into git, but then you realise you missed some authors.

Before being able to do a git cvsimport, you need a checkout of the module or cvs subdir that you want to turn into its own git repo.

For ease of use I defined CVSCMD as
cvs -z9 -d :pserver:my_cvs_id@cvs.server.com:/root_dir
You will need to replace the items written in italics according to you situation, more exactly, you need to define 'my_cvs_id', 'cvs.server.com' and 'root_dir'. If your acces method to the server is not pserver, you should change that accordingly. This information should be available from your project admin or pages.


Check out the desired module or even subdir of a module

$CVSCMD checkout -d localdirname MODULE/path/to/subdir

git cvsimport -A ../authors -m -z 600 -C ../new-git-repo -R

How to find out the commits which do need rewriting

The way to limit yourself only to the commits that had no cvs-git author and commit information on git-cvsimport time is to use a filter like this:
git log -E --author='^[^@]*$' --pretty=format:%h
This tells git log to print only the abbreviated hashes (%h) for the commits that have NO '@' sign in the 'Author:', which happens if no cvs user id to git author and email was provided in the authors file and git cvsimport time.

We will use this command's output to tell later git filter-branch which commits need rewriting. *

But before that...

How do we find if our authors file is complete?

For this task we'll use a slighly modified form of the previous command and some shell script magic.
git log -E --author='^[^@]*$' --pretty=format:%an sort -u > all-leftout-cvs-authors
And now in all-leftout-cvs-authors we'll have a sorted list of all cvs id's which were not handled in the original git-cvsimport. In my case there are only 19 such ids:
$ wc -l all-leftout-cvs-authors
19 all-leftout-cvs-authors

Nice, that will be easy to fix. Now edit your all-leftout-cvs-authors file to add the relevant information in a format similar to this:
john = John van Code <john@code.temple.tld>
jimmy = Jimmy O'Document <jimmy@documenting.com>
In case you can't make a complete cvs-user-to-name-and-email map, you might want to use stubs of the following form in order to be able to easily identify later such commits, if you prefer (or you could let them unaltered at al ;-):
cvsid=cvsid <cvsid@cvs.server.com>

How to actually do the filtering to fix history (using git-filter-branch and a script)

After this is done, we'll need just one more piece, the command to do the altering itself which reads as follow (note that my final authors file is called new-authors and that I placed this in a script in order to be able to easily run it without trying to escape all spaces and such madness):

[ "$authors_file" ]   export authors_file=$HOME/new-authors

#git filter-branch -f --remap-cvs --env-filter '
git filter-branch -f --env-filter '

get_name ()
grep "^$1=" "$authors_file" sed "s/^.*=\(.*\)\ .*$/\1/"


get_email ()
grep "^$1=" "$authors_file" sed "s/^.*\ <\(.*\)>$/\1/"


if grep -q "^$GIT_COMMITTER_NAME" "$authors_file" ; then
GIT_AUTHOR_NAME=$(get_name "$GIT_COMMITTER_NAME") &&
GIT_AUTHOR_EMAIL=$(get_email "$GIT_COMMITTER_NAME") &&
GIT_COMMITTER_NAME="$GIT_AUTHOR_NAME" &&
GIT_COMMITTER_EMAIL="$GIT_AUTHOR_EMAIL" &&
export GIT_AUTHOR_NAME GIT_AUTHOR_EMAIL &&
export GIT_COMMITTER_NAME GIT_COMMITTER_EMAIL
fi
' -- --all
You might wonder what's up with the commented git filter-branch line with the --remap-cvs option. This script will NOT work for you as long as you have the stock git-filter-branch script and keep the option --remap-cvs while not patching your git-filter-branch script (/usr/lib/git-core/git-filter-branch), but that option will provide a file with the mappings from the old to the new commit ids. If you want that function, too, you'll want to apply this patch to git-filter-branch:

diff --git a/git-filter-branch b/git-filter-branch
old mode 100644
new mode 100755
index ae602e3..d1f7ef6
--- a/git-filter-branch
+++ b/git-filter-branch
@@ -149,6 +149,11 @@ do
prune_empty=t
continue
;;
+ --remap-cvs)
+ shift
+ remap_cvs=t
+ continue
+ ;;
-*)
;;
*)
@@ -368,6 +373,33 @@ while read commit parents; do
die "could not write rewritten commit"
done <../revs

+# Rewrite the cvs-revisions file, if requested and the file exists
+
+ORIG_CVS_REVS_FILE="$ GIT_DIR /cvs-revisions"
+if [ -f "$ORIG_CVS_REVS_FILE" ]; then
+ if [ "$remap_cvs" ]; then
+ printf "CVS remapping requested\n"
+
+ CVS_REVS_FILE="$tempdir/cvs-revisions"
+ cp "$ORIG_CVS_REVS_FILE" "$CVS_REVS_FILE"
+ printf "\nFound $ORIG_CVS_REVS_FILE; will copy and alter it as $CVS_REVS_FILE\n"
+ cvs_remap__commit_count=0
+ newcommits="$(ls ../map/ wc -l)"
+ for commit in ../map/* ; do
+ cvs_remap__commit_count=$(($cvs_remap__commit_count+1))
+ printf "\rRemap CVS commit $commit ($cvs_remap__commit_count/$newcommits)"
+
+ oldsha1="$(basename $commit)"
+ read newsha1 < $commit
+ sed -i "s@$oldsha1\$@$newsha1@" "$CVS_REVS_FILE"
+ done
+ else
+ warn "\nNo CVS remapping requested, but cvs-revisions file found. All CVS mappings will be lost.\n"
+ fi
+elif [ "$remap_cvs" ]; then
+ warn "\nWARNING: CVS remap was ignored, since no original cvs-revisions file was found\n"
+fi
+
# If we are filtering for paths, as in the case of a subdirectory
# filter, it is possible that a specified head is not in the set of
# rewritten commits, because it was pruned by the revision walker.
@@ -491,6 +523,11 @@ if [ "$filter_tag_name" ]; then
done
fi

+if [ "$remap_cvs" -a -f "$CVS_REVS_FILE" ]; then
+ mv "$ORIG_CVS_REVS_FILE" "$ORIG_CVS_REVS_FILE.original"
+ cp "$CVS_REVS_FILE" "$ORIG_CVS_REVS_FILE"
+fi
+
cd ../..
rm -rf "$tempdir"


Then, after running this script, let's call it filter, you should have a brand new git repo with the appropriate authors and their emails set.


P.S.: I have started writing this post some time ago but stopped just before the last part, the one with the filter script. I realise I might be missing something in the explanation, but if you have problems, please comment so I can help you fixing them.

P.P.S.: * I realised in the filter script at some point I wanted to do something like:
for R in $(git log -E --author='^[^@]*$' --pretty=format:%H   head -n 2) ; do
[the same git filter branch command above but ending in ...]
' $R
done
But I think I remember that $R didn't work on the whole history, but only on that revision, or some other weird of that sort. I know I ended up not filtering explicitly those revisions, but the entire history. I hope this helps.

15 February 2012

Mike (stew) O'Connor: Udev and multiple keyboards

I've started using my kinesis keyboard with my laptop a lot during the workday, but not the rest of the time, which means my USB keyboard is being plugged and unplugged often. I prefer to have a lot of keys remapped on the kinesys, So I was having an annoying time having to run xmodmap (possibly without the benefit of having Mod4 to get the window manager to give me a shell) to set these keys. I survived about two weeks before this bugged me enough to figure out what could be done to solve this. I had solved it once before by dropping a magically crafted file into /etc/hal/fdi/policy, but that system is long gone. Luckily it looks like thanks (at least in part) to Martin Pitt, udev has a keymap facility for handling this type of scenario. /usr/share/doc/udev/README.keymap.txt.gz has a bunch of good hints that got me started.
$ /lib/udev/findkeyboards
USB keyboard: input/event2
AT keyboard: input/event0
Finds my keyboard devices. I'm interested in the USB connected keyboard. So I run:
/lib/udev/keymap -i input/event2
To discover scan codes my keyboard generates for the keys I want to remap. here #654928 got me, the trick is to issue the above command from the laptop keyboard, so that the terminal you launched keymap in doesn't get wonky because it never got the key-release event from the enter key. When I hit keys on my external keyboard now, I get stuff like:
scan code: 0x7004A   key code: home
scan code: 0x700E7   key code: rightctrl
They key codes coming out match what is printed on the keycaps. From here I generate a file matching files in /lib/udev/keymaps, but change the keycodes to the keycodes I want to remap to, ending up with:
0x7004A leftmeta 
0x700E7 rightalt
This file goes into /lib/udev/keymaps/kinesis-stew. It appears the things like leftmeta/rightalt which are valid come from /usr/include/linux/input.h. It also seems to be valid to put hex there, but I didn't find a good way to figure out what hex codes go with which key codes. Then I look for the VendorID/DeviceID by looking in the output of "udevadm info --export-db" for input/event2 and find:
ID_VENDOR_ID=05f3
ID_MODEL_ID=0007
So now I'm ready to create my udev rule (which I put into /etc/udev/rules.d/99-stew-keymap.rules
ATTRS idVendor =="05f3", ATTRS idProduct =="0007", RUN+="keymap $name kinesis-stew"
And now everything seems to be good. I can plug and unplug my external keyboard without having to run xmodmap to get the keybindings I want, and the keybindings for the built-in laptop keyboard are not disturbed.

C.J. Adams-Collier: software bridge loops suck, too

I didn t realize that I had two of my machines attached to openvpn from the same l2 segment. It caused a network outage for about 24 hours. Sorry for the downtime folks. I believe that if I turn on stp for all nodes which have two legs in to the same l2, I can avoid this type of problem in the future. But I don t think the broadcast network overhead for managing the spanning tree is worth it. Especially for vlans which span counties.
Wait, I think LD1 is in the same county as the vlan hub. How about vlans which span legislative districts. http://wa-demchairs.org/kcdems/districts.php Hello from LD40, Orcas3! Reporting from F5 HQ/LD36 in Seattle.
I use the following tools to manage my vlans and bridges: vlan, bridge-utils and openvpn I verify my tls certs with perl.
#!/usr/bin/perl -wT
use strict;
use Log::Log4perl;
Log::Log4perl->init('/etc/openvpn/log4perl.conf') or die "couldn't init logger: $!";
my $logger = Log::Log4perl->get_logger('tls-verify');
$logger->debug("verifying tls cert for config [$ENV config ]");
my($network) = ($ENV config  =~ m:^/etc/openvpn/(.*?).conf$:);
my($certificate_depth) = ($ARGV[0] =~ /^(\d+)$/);
my($locality,$organization,$org_unit,$common_name) =
  ($ARGV[1] =~ m /C=US/ST=Washington/L=(.*?)/O=(.*?)/(?:OU=(.*?)/)?CN=(.*)$ );
$logger->debug("X509_NAME_oneline: [$ARGV[1]");
my %network_cn =
  (
   vl3  =>  [ 'vl3.colliertech.org',
              'Collier_Technologies_Server_CA',
              'Collier_Technologies_Root_CA',
   ],
   vl12 =>  [ 'vl12.colliertech.org',
              'Collier_Technologies_Server_CA',
              'Collier_Technologies_Root_CA',
   ],
   vl245 => [ 'vl245.colliertech.org',
              'Collier_Technologies_Server_CA',
              'Collier_Technologies_Root_CA',
   ],
  );
if( exists $network_cn $network  ) 
  exit 0 if $network_cn $network ->[$certificate_depth] eq $common_name;
  $logger->error("common name: [$common_name], network: [$network], depth: [$certificate_depth]");
 else 
  $logger->error("network: [$network]");
 
exit 1;

Dirk Eddelbuettel: Kurt Elling, Regina Carter and Anat Cohen at the CSO

Yesterday was Valentine's Day, and Kurt Elling came back to Chicago for a show at Symphony Center. He brought along guest stars Regina Carter (violin) and Anat Cohen (clarinet), as well as a small band led by Elling's long-time collaborator Laurence Hobgood on piano. The program was titled Passion World and featured songs from around the world. Quite impressively, Elling actually sang in French, Spanish, Portuguese, German and of cause English. The program lacked a little bit of cohesion at times, but it was still a most enjoyable and solid two-hour set. A similar concert will take place in Minneapolis on Saturday, so for those near the Twin Cities I would recommended looking for tickets.

Iustin Pop: Running in the snow

I've been wanting to write a blog post about running for a while now; things like that I finally registered for a few upcoming races in and around Z rich (which I hope I planned correctly, not like last year), or that I finally managed to find a schedule that allows me to run both in good and bad weather, or other boring things like this. However what I want to write now about is the morning run I had today. I woke up, planning to run at work during lunch or something like that, then I looked outside: snow! For the first time in about a month or so, real, serious snow falling, and white all around. I didn't want to miss this opportunity, so I first checked the temperature: 0 C ( 2 ), which is fine (I don't have gear to run at -10 C, for example), maybe a bit wet but acceptable. Got dressed, and went outside. Even the alley to the apartment building was not yet cleared . So I went on my usual 10K run to work and it was, by far, the best run ever or at least the best for the past 6 months, my memory is short . It was wonderful, snow falling down, the woods black and white, and a bit of wind. I managed to run about one thirds with both eyes open, about two thirds with just one eye open (heavy wind from one side), and some short streches with both eyes closed, due to heavy wind from ahead. I also had a better pace than expected; about 20 seconds slower per km, which is good, given that running in snow is harder than on clear ground. One surprising fact: usually I cross on average about one other runner each two-three hundres meters. However today, in the entire 10K, only one other runner. On top of that, a few people seemed surprised at work that I chose to run on such terrible weather. Why were people so scared of snow? To me it was wonderful, I felt completely like a child again, being able to plough through ankle-deep, pristine snow, ignoring (or rather enjoying) the cold wind, forgetting everything else. Too bad the snow half-melted by evening. I miss winters with lots of snow

Niels Thykier: Python optimization and profiling

For the past 5 days, I have worked on replacing a part of Britney (our beloved testing migration tool). The part I am trying replacing is her installability tester , which is probably one of the most used parts of Britney. I know premature optimization is the root of all evil, but I felt compelled to be a bit evil this time. The reason is that a na ve algorithm could easily spend decades on computing the result of our most complete tests (each consists of roughly 2 * 35 000 packages). Within a couple of days, I felt I had a reasonable candidate to use on the large tests. On the large tests, it ran with a noticeable speed regression and it produced one different result. The result difference was about 20-40 source packages and their binaries. You may have noticed I used difference and not regression . In the given test, our current implementation at some point gives up with an AIEEE error. So I decided to turn my attention to the speed regression first. As any good programmer, I decided to use a profiler (cProfile) to determine my bottle-necks. This turned out to be a good idea, as the bottleneck was not quite where I thought it was. I wish I could say I just patched it out the issue, but unfortunately not. I played around with various changes such as using implied for loops rather than explicit ones etc. Some times I would manage to cut the runtime in half only to be unable to reproduce it later. Yesterday I finally realized what caused this. I was working in 3 different chroots, two 64-bit sid chroots[1] and a 32-bit stable chroot. Turns out that my replacement is only slow in the stable chroot. As soon as I moved to a sid chroot, the runtime was more or less cut in half. I have not bothered to check if it is the 32 vs 64 bit, the stable vs sid part or maybe the python profile in stable is just slow[2]. I simply moved to my sid chroots for now and continued working. With that taken care of, I figured I would remind myself of what I was up against. On the largest test I have available, I profiled my implementation to around 4:30 5:00 minutes. Regardless of my changes, I always got times in that range. I did manage to patch a bug in my code that reduced by only diff to 10 source packages (plus their binaries) at the price of 30 seconds. So I was back to 5 minutes according to the profiler, but I noticed that my test runner disagreed. According to my test runner my implementation had a runtime of approx. 3 minutes and 40 seconds. For comparison my test runner puts the original implementation at 3 minutes and 20 seconds for that test. In short, I have spent most of my day trying to optimize my code to compensate for the +20% overhead the profiler introduced. Admittedly, my replacement still needs some speed improvement on some other tests where it still has a factor 2 runtime regression. I also need to fix the last diff, which now I suspect is in my replacement. [1] In case you were wondering, yes those chroots are on two different machines. [2] Of course, it could be a combination of that as well Anyhow, I am too lazy to research it at the moment.

13 February 2012

Michal &#268;iha&#345;: phpMyAdmin translations status

As phpMyAdmin is approaching to 3.5 release, it has come time to share about translations status. Here comes third round of translation status update. Since last update we have one new translation at 100%, but one has dropped from the list: There are few which are really close to 100% and I hope they will get there soon: As you can see, traveling around FOSDEM was really useful for Czech translation, which I've managed to complete during that weekend (+ Monday when I traveled to Nuremberg). There was great amount of work done on Polish translation, so hopefully it will be on 100% in next report. Also Rouslan is progressing quite well on Italian, but there is still fair amount of work to be done. Was your language not mentioned? It's now perfect time to contribute to it.

Filed under: English Phpmyadmin 0 comments Flattr this!

James Bromberger: Debian Wheezy: US$19 Billion. Your price FREE!

As many would know, Debian GNU/Linux is one of the oldest, and the largest Linux distributions that is available for free. Since it was first released in 1993, several people have analysed the size and produced cost estimates for the project. In 2001, Jes s M. Gonz lez-Barahona et al produced an article entitled Counting Potatoes , an analysis of Debian 2.2 (code named Potato). When Potato was released in June 2003, it contained 2,800 source packages of software, totalling around 55 million lines of source code. When using David A. Wheeler s sloccount tool to apply the COCOMO model of development, and an average developer salary of US$56,000, the projected development cost that Gonz lez-Barahona calculated to start-from-scratch and build Debian 2.2 in 2003 was US$1.9 billion. In 2007 an analysis entitled Macro-level software evolution: a case study of a large software compilation by Jes s M. Gonz lez-Barahona, Gregorio Robles, Martin Michlmayr, Juan Jos Amor and Daniel M. German was released. It found that Debian 4.0 (codename Etch released April 2007) had just over 10,000 source packages of software and 288 million lines of source code. This analysis also delved into the dependencies of software packages, and the update flow between Debian release (not all packages are updated with each release). Today (February 2012) the current development version of Debian, codenamed Wheezy, contains some 17,141 source packages of software, but as it s still in development this number may change over the coming months. I analysied the source code in Wheezy, looking at the content from the original software that Debian distributes from its upstream authors without including the additional patches that Debian Developers apply to this software, or the package management scripts (used to install, configure and de-install packages). One might argue that these patches and configuration scripts are the added value of Debian, however the in my analysis I only examined the pristine upstream source code. By using David A Wheeler s sloccount tool and average wage of a developer of US$72,533 (using median estimates from Salary.com and PayScale.com for 2011) I summed the individual results to find a total of 419,776,604 source lines of code for the pristine upstream sources, in 31 programming languages including 429 lines of Cobol and 1933 lines of Modula3! In my analysis the projected cost of producing Debian Wheezy in February 2012 is US$19,070,177,727 (AU$17.7B, EUR 14.4B, GBP 12.11B), making each package s upstream source code wrth an average of US$1,112,547.56 (AU$837K) to produce. Impressively, this is all free (of cost). Zooming in on the Linux Kernel In 2004 David A. Wheeler did a cost analysis of the Linux Kernel project by itself. He found 4,000,000 source lines of code (SLOC), and a projected cost between US$175M and US$611M depending on the complexity rating of the software. Within my analysis above, I used the standard (default) complexity with the adjusted salary for 2011 (US$72K), and deducted that Kernel version 3.1.8 with almost 10,000,000 lines of source code would be worth US$540M at standard complexity, or US$1,877M when rated as complex . Another Kernel Costing in 2011 put this figure at US$3 billion, so perhaps there s some more variance in here to play with. Individual Projects Other highlights by project included:
Project Version Thousands
of SLOC
Projected cost
at US$72,533/developer/year
Samba 3.6.1 2,000 US$101 (AU$93M)
Apache 2.2.9 693 US$33.5M (AU$31M)
MySQL 5.5.17 1,200 US$64.2M (AU$59.7M)
Perl 5.14.2 669 US$32.3M (AU$30M)
PHP 5.3.9 693 US$33.5M (AU$31.1M)
Bind 9.7.3 319 US$14.8M (AU$13.8M)
Moodle 1.9.9 396 US$18.6M (AU$17.3M)
Dasher 4.11 109 US$4.8M (AU$4.4M)
DVSwitch 0.8.3.6 6 US$250K (AU$232K)
Debian Wheezy by Programming Language The upstream code that Debian distributes is written in many different languages. ANSI C with 168,536,758 is the dominant language (40% of all lines), followed by C++ at 83,187,329 (20%) and Java with 34,698,990 (8%).
Line chart

Break down of Wheezy by Language

If you are intersted in finding the line count and cost projections for any of the 17,000+ projects, you will find them in the raw data CSV. Other Tools and Comparisons Ohcount is another source code cost analysis tool. In March 2011 Ohcount was run across Debian Sid: its results are here. In comparison, its results appear much lower than the sloccount tool. There s also the Ohloh.net Debian Estimate which only finds 55 Million source lines of code and a projected cost of US$1B. However Ohloh uses Ohcount for its estimates, and seems to be to be around 370 million SLOC missing compared to my recent analysis. Summary Over the last 10 years the cost to develop Debian has increased ten-fold. It s intersting to know that US$19 billion of software is available to use, review, extend, and share, for the bargain price of $0. If we were to add in Debian patches and install scripts then this projected figure would increase. If only more organisations would realise the potential they have before them. Need help with Linux (including Debian), Perl, or AWS? See www.jamesbromberger.com.

12 February 2012

Sylvain Beucler: Branching FreeGLUT SVN with Git

I'm working on porting FreeGLUT to Android! Since I don't have access so the repository (I'm not a regular contributor), and since it will be a BIG patch, I thought I'd try a git-svn branch. So this won't be a post on OpenGL for once ;) I'm not an expert at managing Git branch but here's how I set it up. In this case, let's forget about importing tags: they don't have the same directory branch point in the hierarchy (sometimes the freeglut/ module, sometimes the parent directory), and git-svn only correctly supports set of sane tags that track the same initial directory. SVN is SLOW, especially remotely. I suggest you make a rsync copy of the repository first, it will greatly speed up the import :
rsync -avHSP freeglut.svn.sourceforge.net::svn/freeglut/ freeglut.svn/
Then start the import with git-svn :
git svn clone --trunk=trunk/freeglut/freeglut file://$(pwd)/freeglut.svn/ freeglut-git/
And edit .git/config to point to https://freeglut.svn.sourceforge.net/svnroot/freeglut :
[svn-remote "svn"]
    url = https://freeglut.svn.sourceforge.net/svnroot/freeglut
    fetch = trunk/freeglut/freeglut:refs/remotes/trunk
I work with 2 branches: Here's how I synchronize the upstream repository and merge it regularly with my feature branch:
git svn fetch
git checkout master
git merge remotes/trunk
git checkout android  # my feature branch
git merge master
# if conflict
git add .../sthing.c
git commit -m "Merge master"
git push
Any better way? The ongoing work is available at https://gitorious.org/freeglut/android :)

Matthew Garrett: Some things you may have heard about Secure Boot which aren't entirely true

Talking about Secure Boot again, I'm afraid. One of the things that's made discussion of this difficult is that, while the specification isn't overly complicated, some of the outcomes aren't obvious at all until you spend a long time thinking about it. So here's some clarification on a few points.
Secure Boot provides no additional securityUntrue. Attacks against the pre-boot environment are real and increasingly common - this is a recent proof of concept, and this has been seen in the wild. Once something has got into the MBR, all bets are off. It can modify your bootloader or kernel, inserting its own code to return valid results whenever any kind of malware checker scans for it. The only way to reliably identify it is to either move the disk to another system or to cold boot off verified media. By restricting pre-OS code to something that's been signed, Secure Boot does provide enhanced security.
Secure Boot is just another name for Trusted BootUntrue. Trusted Boot requires the ability to measure the entire boot process, which gives the OS the ability to figure out everything that's been run before OS startup. The root of trust is in the hardware and a TPM is required. Secure Boot is simply a way to limit the applications that are run before the OS. Once booted, there is no way for the OS to identify what was previously booted, or even if the system was booted securely.
Microsoft are just requiring that vendors implement the specificationUntrue. Quoting from the Windows 8 Hardware Certification Requirements:

MANDATORY: No in-line mechanism is provided whereby a user can bypass Secure Boot failures and boot anyway Signature verification override during boot when Secure Boot is enabled is not allowed. A physically present user override is not permitted for UEFI images that fail signature verification during boot. If a user wants to boot an image that does not pass signature verification, they must explicitly disable Secure Boot on the target system.

Section 27.7.3.3 of version 2.3.1A of the UEFI spec explicitly permits implementations to provide a physically present user override. Whether this is a good thing or not is obviously open to argument, but the fact remains that Microsoft forbid behaviour that the specification permits.
Secure Boot can be used to implement DRMUntrue. The argument here is that Secure Boot can be used to restrict the software that a machine can run, and so can limit a system to running code that implements effective copy protection mechanisms. This isn't the case. For that to be true, there would need to be a mechanism for the OS to identify which code had been run in the pre-OS environment. There isn't. The only communication channel between the firmware and the OS is via a single UEFI variable called "SecureBoot", which may be either "1" or "0". Additionally, the firmware may provide a table to the OS containing a list of UEFI executables that failed to authenticate. It is not required to provide any information about the executables that authenticated correctly.

In both these cases, the OS is required to trust the firmware. If the firmware has been compromised in any way (such as the user turning off Secure Boot), the data provided by the firmware can be trivially modified and the OS told that everything is fine. As long as machines exist where users are permitted to disable Secure Boot, Secure Boot is not any kind of DRM scheme.
Secure Boot provides physical securityUntrue. Secure Boot does not in any way claim to improve security against attackers who have physical access, for the same reasons as the DRM case. The OS has no way to determine that the firmware's behaviour has been modified. A physically-present attacker can simply disable Secure Boot and install a piece of malware that lies to the OS about platform security. The "Evil Maid" attack still exists.
Secure Boot only defines the interaction between the firmware and the bootloader. It doesn't specify any higher policyMisleading. It's true that Secure Boot only specifies the authentication of pre-OS code. However, if you implement Secure Boot it's because you want to ensure that only authenticated code has run before your OS. If there is any way for unauthenticated code to touch the hardware before your OS starts, you can't ensure that. If an authenticated Linux kernel is booted and then loads an unsigned driver, that unsigned driver can fabricate a fake UEFI environment and then launch Windows from it. Windows would falsely believe that it has booted securely. If that authenticated Linux kernel were widely distributed, attackers could use it as an attack vector for Windows. The logical response from Microsoft would be to blacklist that kernel.

The inevitable outcome of implementing Secure Boot is that every component that can touch hardware must be signed. Anyone who implements Secure Boot without requiring that is adding no additional security whatsoever.
Only machines that want to boot Windows need to carry Microsoft's keysAgain, misleading. Microsoft only require one signing key to be installed, and the Windows bootloader will be signed with a key that chains back to this one. However, the bootloader is not the only component that must be signed. Any drivers that are carried on ROMs on plug-in cards must also be signed. One approach here would have been for all hardware vendors to have their own keys. This would have been unscalable - any shipped machine would have to carry keys for every vendor who produces PCI cards. If a machine carried an nvidia key but not an AMD one, swapping a geforce for a radeon would have resulted in the firmware graphics driver failing to load. Instead, Microsoft are providing a signing service. Vendors will be able to sign up for WHQL membership and have their UEFI drivers signed by Microsoft.

This leads to the problem. The Authenticode format used for signing UEFI objects only allows for a single signature. If a driver is signed by Microsoft, it can't be signed by anybody else. Therefore, if a system vendor wants to support off-the-shelf PCI devices with Microsoft-signed drivers, the system must carry Microsoft's key. If the same key is used as the root of trust for the driver signing and for the bootloader signing, that also means that the system will boot Windows.
This is only a problem for clients, not serversNot strictly true. While Microsoft's current requirements don't mandate the presence of Secure Boot on server hardware, if present it must be enabled and locked down as it is for clients. It's not valid for servers to ship with disabled Secure Boot support, or for it to be shipped in a mode allowing users to make automated policy modifications at OS install time.
Secure Boot is required by NISTThis is one that I've heard from multiple people working on Secure Boot. It's amazingly untrue. The document they're referring to is NIST SP800-147, which is a document that describes guidelines for firmware security - that is, what has to be done to ensure that the firmware itself is secure. This includes making sure that the OS can't overwrite the firmware and that firmware updates must be signed. It says absolutely nothing about the firmware only running signed software. Secure Boot depends upon the firmware being trusted, so these guidelines are effectively a required part of Secure Boot. But Secure Boot is not within the scope of SP800-147 at all.
It's easy for Linux to implement Secure BootMisleading. From a technical perspective, sure. From a practical perspective, not at all. I wrote about the details here.
It's only a problem for hobbyist Linux, not the real Linux marketUntrue. It's unclear whether even the significant Linux vendors can implement Secure Boot in a way that meets the needs of their customers and still allows them to boot on commodity hardware. A naive implementation removes many of the benefits of Linux for enterprise customers, such as the ability to use local modifications to micro-optimise systems for specific workloads. One of the key selling points of Linux is the ability to make use of local expertise when adapting the product for your needs. Secure Boot makes that more difficult.

ConclusionMuch reporting on the issues surrounding Secure Boot so far has been inaccurate, leading to misunderstandings about the (genuine) benefits and the (genuine) drawbacks. Any useful discussion must be based around an accurate understanding of the specification rather than statements from analysts with no real understanding of the Linux market or security.

comment count unavailable comments

Iustin Pop: perf stats for doing nothing

Perf stats for "doing nothing" I've recently discovered the perf Linux tool. I heard that oprofile was deprecated and that there is a new tool, and I noted down to try it sometime. Updated: more languages, fixed typos, more details, some graphs. Apologies if this shows twice in your feed. The problem with perf stats is that I hate bloat, or even perceived bloat. Even when it doesn't affect me in any way, the concept of wasted cycles makes me really sad. You probably can guess where this is going I said, well, let's see what perf says about a simple "null" program. Surely doing nothing should be just a small number of instructions, right? Note: I think that perf also records kernel-side code, because the lowest I could get was about ~50K instructions for starting a null program in assembler that doesn't use libc and just executes the syscall asm instruction. However, these ~50K instructions are noise the moment you start to use more high-level languages. Yes, this is expected, but the I was still shocked. And there's lots of delta between languages I'd expected to behave somewhat identical. Again, this is not important in the real world. At all. They are just numbers, and probably the noise (due to short runtime) has lots of influence on the resulting numbers. And I might have screwed up the measurements somehow. Test setup Each program was the equivalent of 'exit 0' in the appropriate form for the language. During the measurements, the machine was as much as possible idle (single-user mode, measurements run at real-time priority, etc.). For compiled languages, -O2 was used. For scripts, a simple #!/path/to/interpreter (without options, except in the case of Python, see below) was used. Each program/script was run 500 times (perf's -r 500) and I've checked that the variations were small ( 0.80% on the metrics I used). You can find all the programs I've used at http://git.k1024.org/perf-null.git/, the current tests are for the tag version perf-null-0.1. The raw data for the below tables/graphs is at log-4. Results Compiled languages
Language Cycles Instructions
asm 63K 51K
c-dietlibc 74K 57K
c-libc-static 177K 107K
c-libc-shared 506K 300K
c++-static 178K 107K
c++-dynamic 1,750K 1,675K
haskell-single 2,229K 1,338K
haskell-threaded 2,629K 1,522K
ocaml-bytecode 3,271K 2,741K
ocaml-native 1,042K 666K
Going from dietlibc to glibc doubles the number of instructions, and for libc going from static to dynamic linking again roughly doubles it. I didn't manage to compile a program dynamically-linked against dietlibc. C++ is interesting. Linked statically, it is in the same ballpark as C, but when linked dynamically, it executes an order of magnitude (!) more instructions. I would guess that the initialisation of the standard C++ library is complex? Haskell, which has a GC and quite a complex runtime, executes slightly less instructions than C++, but uses more cycles. Not bad, given the capabilities of the runtime. The two versions of the Haskell program are with the single-threaded runtime and with the multi-threaded one; not much difference. A fully statically-linked Haskell binary (not recommended usually) goes below 1M instructions, but not by much. OCaml is a very nice surprise. The bytecode runtime is a bit slow to startup, but the (native) compiled version is quite fast to start: only 2 number of instructions and cycles compared to C, for an advanced language. And twice as fast as Haskell . Nice! Shells
Language Cycles Instructions
dash 766K 469K
bash 1,680K 1,044K
mksh 1,258K 942K
mksh-static 504K 322K
So, dash takes ~470K instructions to start, which is way below the C++ count and a bit higher than the C one. Hence, I'd guess that dash is implemented in C . Next, bash is indeed slower on startup than dash, and by slightly more than 2 (both instructions and cycles). So yes, switching /bin/sh from bash to dash makes sense. I wasn't aware of mksh, so thanks for the comments. It is, in the static variant, more efficient that dash, by about 1.5 . However, the dynamically linked version doesn't look too great (dash is also dynamically linked; I would guess a statically-linked dash "beats" mksh-static). Text processing I've added perl here (even though it's a 'full' language) just for comparison; it's also in the next section.
Language Cycles Instructions
mawk 849K 514K
gawk 1,363K 980K
perl 2,946K 2,213K
A normal spread. I knew the reason why mawk is Priority: required is that it's faster than gawk, but I wouldn't have guessed it's almost twice as fast. Interpreted languages Here is where the fun starts
Language Cycles Instructions
lua 5.1 1,947K 1,485K
lua 5.2 1,724K 1,335K
lua jit 1,209K 803K
perl 2,946K 2,213K
tcl 8.4 5,011K 4,552K
tcl 8.5 6,888K 6,022K
tcl 8.6 8,196K 7,236K
ruby 1.8 7,013K 6,128K
ruby 1.9.3 35,870K 35,022K
python 2.6 -S 11,752K 10,247K
python 2.7 -S 11,438K 10,198K
python 3.2 -S 29,003K 27,409K
pypy -S 21,106K 10,036K
python 2.6 25,143K 21,989K
python 2.7 47,325K 50,217K
python 2.7 -O 47,341K 50,185K
python 3.2 113,567K 124,133K
python 3.2 -O 113,424K 124,133K
pypy 90,779K 68,455K
The numbers here are not quite what I expected. There's a huge delta between the fastest (hi Lua!) and the slowest (bye Python!). I wasn't familiar with Lua, so I tested it thanks to the comments. It is, I think, the only language which actually improves from one version to the next (bonus points), and where the JIT version also make is faster. In context, lua jit starts faster than C++. Perl is the one that goes above C++'s instructions count, but not by much. From the point of view of the system, a Perl 'hello world' is only about 1.3 -1.6x slower than a C++ one. Not bad, not bad. Next category is composed of TCL and Ruby, both of which had older versions 2-3 slower than Perl, but whose most recent versions are even more slower. TCL has an almost constant slowdown across versions (5M, 6.9M, 8.2M cycles), but Ruby seems to have taken a significant step backwards: 1.9.3 is 5 slower than 1.8. I wonder why? As for TCL, I didn't expect it to be slower to startup than Perl; good to know. Last category is Python. Oh my. If you run perf stat python -c 'pass' you get some unbelievable numbers, like 50M instructions to do, well, nothing. Yes, it has a GC, yes, it does import modules at runtime, but still On closer investigation, the site module and the imports it does do eat a lot of time. Running a simpler python -S brings it back to a more reasonable 10M instructions, which is in-line with the other interpreted languages. However, even with the -S taken into account, Python also slows down across versions: a tiny improvement from 2.6 to 2.7, but (like Ruby) a 3 slowdown from 2.7 to 3.2. Trying the optimised version (-O) doesn't help at all. Trying pypy, which was based on Python 2.7, makes it around 2 slower to startup (both with and without -S). So in the interpreted languages, it seems only Lua is trying to improve, the rest of the languages are piling up bloat with every version. Note: I should have tried multiple perl versions too. Java Java is in its own category; you guess why , right? GCJ was version 4.6, whereas by java below I mean OpenJDK Runtime Environment (IcedTea6 1.11) (6b24-1.11-4).
Language Cycles Instructions
null-gcj 97,156K 74,576K
java -jamvm 85,535K 80,102K
java -server 147,174K 136,803K
java -zero 132,967K 124,977K
java -cacao 229,799K 205,312K
Using gcj to compile to native code (not sure whether that's native-native or something else) results in a binary that uses less than 100M cycles to start, but the jamvm VM is faster than that (85M cycles). Not bad for java! Python 3.2 is slower to startup yes, I think the world has gone crazy. However, the other VMs are a few times slower: server (the default one) is ~150M cycles, and cacao is ~230M cycles. Wow. The other thing about java is that it was the only one that couldn't be put nicely in a file that you just exec (there is binfmt_misc indeed, but that doesn't allow different Java classes to use different Java VMs, so I don't count this), as opposed to every single other thing I tested here. Someone didn't grow on Unix? Comparative analysis Since there are almost 4 orders of magnitude difference between all the things tested here, a graph of cycles or instructions is not really useful. However, cycles/instruction, branches percentage and branches miss-predicted percentage can be. Hence first the cycles/instructions: Cycles/instruction Pypy is jumping out of the graph here, with the top value of over 2 cycles/instruction. Lua JIT is also bigger than Lua non-JIT, so maybe there's something to this (mostly joking, two data points don't make a series). On the other hand, Python wins as best cycles/instruction (0.91). Lots of ILP, to get below 1? Java gets, irrespective of VM, consistently near 1.0-1.1. C++ gets very different numbers between static linking (1.666) and dynamic linking (1.045), whereas C has basically identical numbers. mksh also has a difference between dynamic and static linking. Hmm Ruby, TCL and Python have consistent values across versions. And that's about what I can see from that graph. Next up, percentage of branches out of total instructions and percentage of branches missed: Branch statistics Note that the two lines shouldn't really be on the same graph; for the branch %, the 100% is the total instructions count, but for the branch miss %, the 100% is the total branch count. Anyway. There are two low-value outliers: So it seems the gcj libraries are well optimised? I'm not familiar enough with this topic, but on the graph it does indeed stand out. On the other end, mksh-static has a high branch miss percentage: 11.60%, which jumps clearly ahead of all the others; this might be why it has a high cycles/instruction count, due to all the stalls in misprediction; one has to wonder why it confuses the branch predictor? I find it interesting that the overall branch count is very similar across languages, both when most of the cost is in the kernel (e.g. asm) and when the user-space cost heavily over-weighs the kernel (e.g. Java). The average is 20.85%, minimum is 17.46%, max 22.93%, standard deviation (if I used gnumeric correctly) is just 0.01. This seems a bit suspicious to me . On the other hand, the mispredicted branches percentage varies much more: from a measly 2.82% to 11.60% (5x difference). Summary So to recap, counting just instructions: Overall, you get roughly three orders of magnitude slower startup between a plain C program using dietlibc and Python. And all, to do basically nothing. On the other hand, I learned some interesting things while doing it, so it wasn't quite for nothing .

Next.

Previous.