Search Results: "ag"

9 June 2020

Dirk Eddelbuettel: Rcpp Webinar Recording Available

As announced in a few tweets leading up to it, I took the date of what would have been the annual R/Finance conference as an opportunity to hold the one-hour tutorial / workshop with introductory Rcpp material which I often present on the first morning preceding the conference as a self-organized webinar. The live-streaming worked actually reasonably well via obs to youtube (even though the comprehensive software by the latter complained at times about insufficient bitstream rates the joys of living with a (near) monopolistic broadband provider whom I should leave for fiber ). Apparently around seventy people connected to the stream which is more than we usually have in the seminar room at UIC for the R/Finance morning. The recording is now available here, and has already been seen over 200 times:

If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Bits from Debian: Great fonts in Debian 10 (or later)

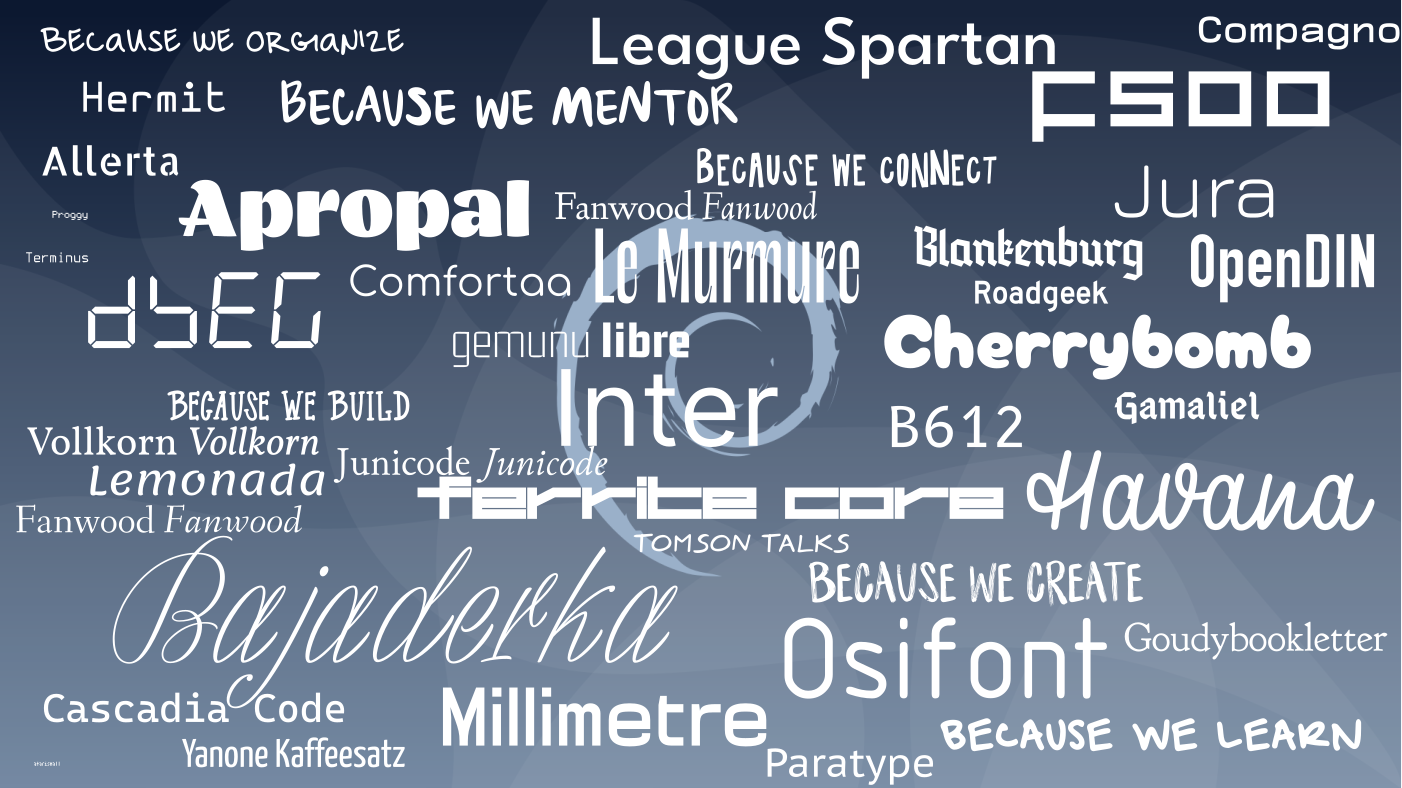
An example of several fonts in Debian 10 Debian comes with tons of fonts for all kinds of purposes, you can easily list them all (almost) with: apt-cache search ^fonts- Above you can see a nice composition with examples of several fonts. The composition is published under the MIT (Expat) license and the source SVG (created with Inkscape) can be downloaded here. You will need the fonts to be installed in your system so the SVG is correctly rendered. If you want to learn more you can have a look at the wiki page about fonts (https://wiki.debian.org/Fonts), and if you want to contribute or maintain fonts in Debian, don't hesitate to join the Fonts Team!

7 June 2020

Enrico Zini: Cooperation links

This comic was based on this essay from Augusten Burroughs: How to live unhappily ever after. In addition to the essay, I highly recommend reading his books. It's also been described in psychology as flow.
With full English subtitles
Confict where it comes from and how to deal with it
Communication skills
Other languages
Distributed teams are where people you work with aren t physically co-located, ie. they re at another office building, home or an outsourced company abroad. They re becoming increasingly popular, for DevOps and other teams, due to recruitment, diversity, flexibility and cost savings. Challenges arise due to timezones, language barriers, cultures and ways of working. People actively participating in Open Source communities tend to be effective in distributed teams. This session looks at how to apply core Open Source principles to distributed teams in Enterprise organisations, and the importance of shared purposes/goals, (mis)communication, leading vs managing teams, sharing and learning. We'll also look at practical aspects of what's worked well for others, such as alternatives to daily standups, promoting video conferencing, time management and virtual coffee breaks. This session is relevant for those leading or working in distributed teams, wanting to know how to cultivate an inclusive culture of increased trust and collaboration that leads to increased productivity and performance.

Dirk Eddelbuettel: T^4 #5: More About Byobu

Another video in our T^4 series of video lightning talks with tips, tricks, tools, and toys (where we had seen the announcement, shells sessions one, two, and three, as well as one byobu session) is now up at YouTube. It goes a little deeper in the wonderful byobu and persistent sessions with multiple concurrent accesses illustrating why it is called both a text-based window manager and a terminal multiplexer :

The slides are here. This repo at GitHub support the series: use it to open issues for comments, criticism, suggestions, or feedback. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Joachim Breitner: Managed by an eleven year old

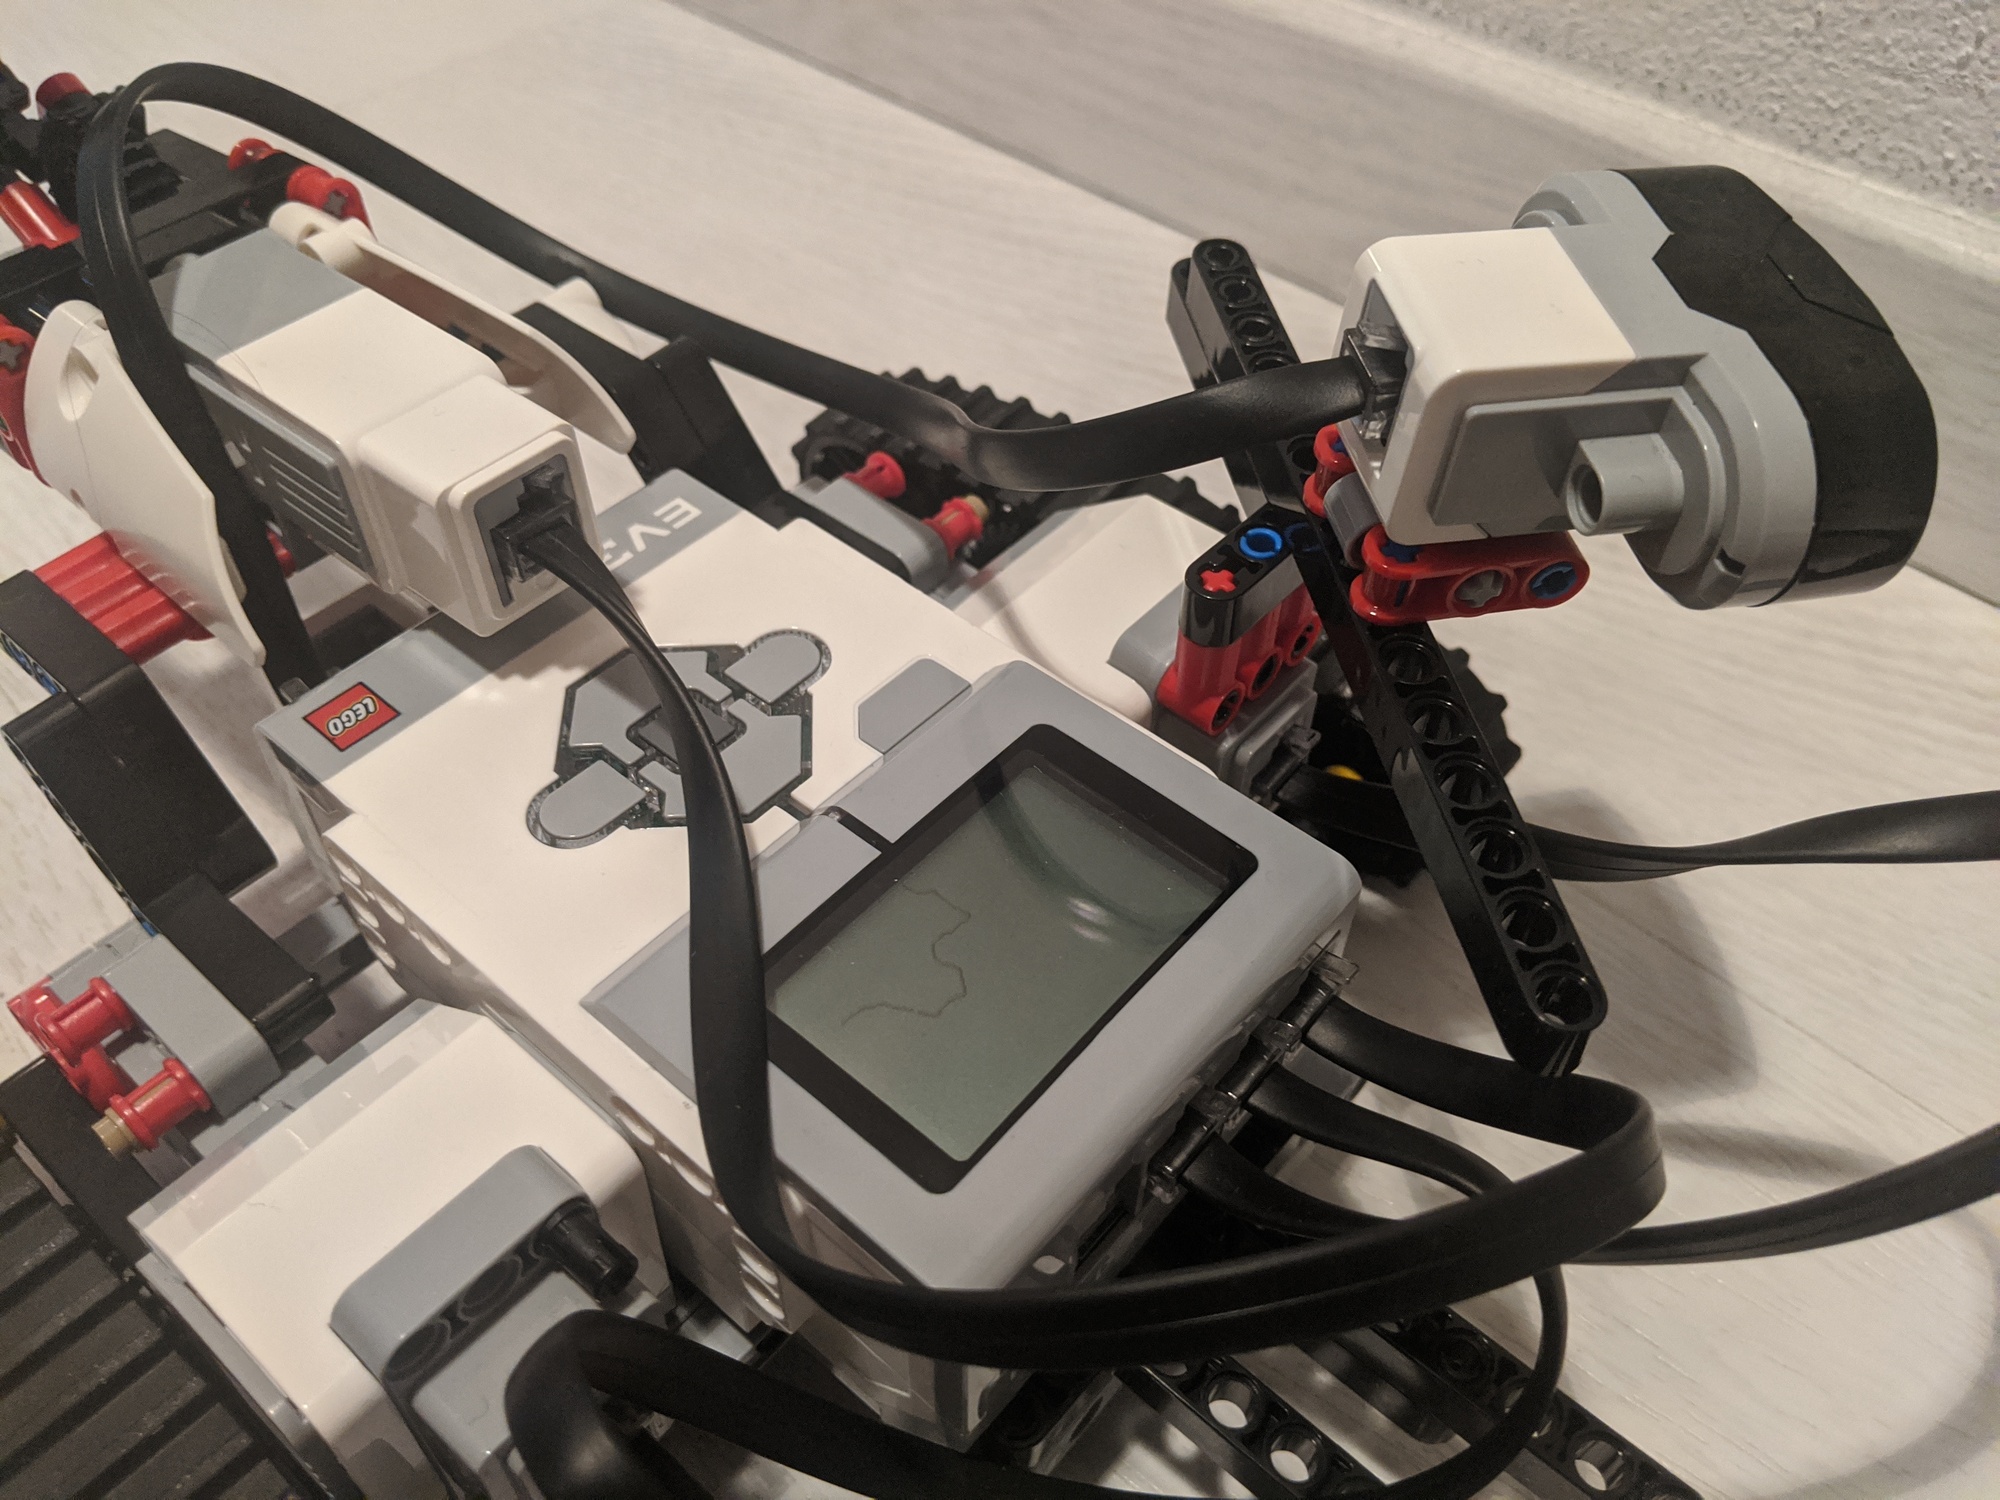
This weekend I had some pretty good uncle time. My eleven year old nephew (after beating me in a fair match of tennis) wanted to play with his Lego Mindstorms set. He never even touches it unless I am around to help him, but then he quiet enjoys. As expected, when I ask him what we should try to build, he tends to come up with completely unrealistic or impossible ideas, and we have to somehow reduce the scope to something doable. This time round, inspired by their autonomous vacuum cleaner, he wanted to build something like that. That was convenient, because now I could sell him what I wanted to try to do, namely make the robot follow a wall at more or less constant distance, as a useful first step. We mounted the infra red distance sensor at an 45 angle to the front-left, and then I built a very simple control loop measure the distance, subtract 40, apply a factor, and feed that into the steering input of the drive action, and repeat. I must admit that I was pretty proud to see just how well that very simple circuit worked: The little robot turned sharp corners in both directions, and otherwise drove nicely parallel and with constant distance to the wall. I was satisfied with that achievement and would have happily ended it here before we might be disappointed by more ambitious and then failing goals. But my nephew had not forgotten about the vacuum cleaner, and casually asked if I could make the robot draw an outline of its path, and thus of the room, on the display. Ok, where do I begin to explain just how unfeasible that is yes, it seemed one can draw to the display. But how should the robot know where it is? How far it turns? How far it went? This is programming by connecting boxes, and I would not expect such an interface to allow for complex logic (right?). And I would need trigonometry and stuff. But he didn t quite believe it, and thus got me thinking indeed, the arithmetic block can evaluate more complex formulas, involving sin and cos so maybe if I can somehow keep track of where the robot is heading well, let s give it a try. So by dragging boxes and connecting wires, I implemented a simple logic (three variables, x and y for current position, alpha for current heading; in each loop add the steering input onto alpha, and add (sin(alpha),cos(alpha)) onto the current position; throw in some linear factors to calibrate; draw pixel at (x, y)). And, to my nephew s joy and my astonishment, the robot was drawing a curvy line that clearly correlates with the taken path! It wasn t respecting the angles perfectly, a square might not properly close, but half an hour earlier I would have actively bet against that we would pull this off!
After a few turns

After a few turns

I was, I must admit, a bit proud. But not only about the technical nerding, but also about my uncleing: That night, according to his parents, my nephew said that he can t remember ever being so happy!

6 June 2020

Petter Reinholdtsen: Secure Socket API - a simple and powerful approach for TLS support in software

As a member of the Norwegian Unix User Group, I have the pleasure of receiving the USENIX magazine ;login: several times a year. I rarely have time to read all the articles, but try to at least skim through them all as there is a lot of nice knowledge passed on there. I even carry the latest issue with me most of the time to try to get through all the articles when I have a few spare minutes. The other day I came across a nice article titled "The Secure Socket API: TLS as an Operating System Service" with a marvellous idea I hope can make it all the way into the POSIX standard. The idea is as simple as it is powerful. By introducing a new socket() option IPPROTO_TLS to use TLS, and a system wide service to handle setting up TLS connections, one both make it trivial to add TLS support to any program currently using the POSIX socket API, and gain system wide control over certificates, TLS versions and encryption systems used. Instead of doing this:
int socket = socket(PF_INET, SOCK_STREAM, IPPROTO_TCP);
the program code would be doing this:
int socket = socket(PF_INET, SOCK_STREAM, IPPROTO_TLS);
According to the ;login: article, converting a C program to use TLS would normally modify only 5-10 lines in the code, which is amazing when compared to using for example the OpenSSL API. The project has set up the https://securesocketapi.org/ web site to spread the idea, and the code for a kernel module and the associated system daemon is available from two github repositories: ssa and ssa-daemon. Unfortunately there is no explicit license information with the code, so its copyright status is unclear. A request to solve this about it has been unsolved since 2018-08-17. I love the idea of extending socket() to gain TLS support, and understand why it is an advantage to implement this as a kernel module and system wide service daemon, but can not help to think that it would be a lot easier to get projects to move to this way of setting up TLS if it was done with a user space approach where programs wanting to use this API approach could just link with a wrapper library. I recommend you check out this simple and powerful approach to more secure network connections. :) As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Russell Coker: Comparing Compression

I just did a quick test of different compression options in Debian. The source file is a 1.1G MySQL dump file. The time is user CPU time on a i7-930 running under KVM, the compression programs may have different levels of optimisation for other CPU families. Facebook people designed the zstd compression system (here s a page giving an overview of it [1]). It has some interesting new features that can provide real differences at scale (like unusually large windows and pre-defined dictionaries), but I just tested the default mode and the -9 option for more compression. For the SQL file zstd -9 provides significantly better compression than gzip while taking only slightly less CPU time than gzip -9 while zstd with the default option (equivalent to zstd -3 ) gives much faster compression than gzip -9 while also being slightly smaller. For this use case bzip2 is too slow for inline compression of a MySQL dump as the dump process locks tables and can hang clients. The lzma and xz compression algorithms provide significant benefits in size but the time taken is grossly disproportionate. In a quick check of my collection of files compressed with gzip I was only able to fine 1 fild that got less compression with zstd with default options, and that file got better compression with zstd -9 . So zstd seems to beat gzip everywhere by every measure. The bzip2 compression seems to be obsolete, zstd -9 is much faster and has slightly smaller output. Both xz and lzma seem to offer a combination of compression and time taken that zstd can t beat (for this file type at least). The ultra compression mode 22 gives 2% smaller output files but almost 28 minutes of CPU time for compression is a bit ridiculous. There is a threaded mode for zstd that could potentially allow a shorter wall clock time for zstd --ultra -22 than lzma/xz while also giving better compression.
Compression Time Size
zstd 5.2s 130m
zstd -9 28.4s 114m
gzip -9 33.4s 141m
bzip2 -9 3m51 119m
lzma 6m20 97m
xz 6m36 97m
zstd -19 9m57 99m
zstd --ultra -22 27m46 95m
Conclusion For distributions like Debian which have large archives of files that are compressed once and transferred a lot the zstd --ultra -22 compression might be useful with multi-threaded compression. But given that Debian already has xz in use it might not be worth changing until faster CPUs with lots of cores become more commonly available. One could argue that for Debian it doesn t make sense to change from xz as hard drives seem to be getting larger capacity (and also smaller physical size) faster than the Debian archive is growing. One possible reason for adopting zstd in a distribution like Debian is that there are more tuning options for things like memory use. It would be possible to have packages for an architecture like ARM that tends to have less RAM compressed in a way that decreases memory use on decompression. For general compression such as compressing log files and making backups it seems that zstd is the clear winner. Even bzip2 is far too slow and in my tests zstd clearly beats gzip for every combination of compression and time taken. There may be some corner cases where gzip can compete on compression time due to CPU features, optimisation for CPUs, etc but I expect that in almost all cases zstd will win for compression size and time. As an aside I once noticed the 32bit of gzip compressing faster than the 64bit version on an Opteron system, the 32bit version had assembly optimisation and the 64bit version didn t at that time. To create a tar archive you can run tar czf or tar cJf to create an archive with gzip or xz compression. To create an archive with zstd compression you have to use tar --zstd -cf , that s 7 extra characters to type. It s likely that for most casual archive creation (EG for copying files around on a LAN or USB stick) saving 7 characters of typing is more of a benefit than saving a small amount of CPU time and storage space. It would be really good if tar got a single character option for zstd compression. The external dictionary support in zstd would work really well with rsync for backups. Currently rsync only supports zlib, adding zstd support would be a good project for someone (unfortunately I don t have enough spare time). Now I will change my database backup scripts to use zstd. Update: The command tar acvf a.zst filenames will create a zstd compressed tar archive, the a option to GNU tar makes it autodetect the compression type from the file name. Thanks Enrico!

Thorsten Alteholz: My Debian Activities in May 2020

FTP master This month I accepted 211 packages and rejected only 9. The overall number of packages that got accepted was 228. Debian LTS This was my seventy-first month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 17.25h. During that time I did LTS uploads of: I started to work on php5 as well but did not upload a fixed version yet. Last but not least I did some days of frontdesk duties. Debian ELTS This month was the twenty third ELTS month. During my small allocated time I uploaded: I also did some days of frontdesk duties. Other stuff I improved packaging of I sponsored uploads of On my Go challenge I uploaded:
golang-github-apparentlymart-go-versions, golang-github-hashicorp-go-slug, golang-github-mozillazg-go-httpheader, golang-github-hashicorp-terraform-json, golang-github-hashicorp-terraform-plugin-test, golang-github-sean pager, golang-github-sean seed, golang-github-timberio-go-datemath,

5 June 2020

Dirk Eddelbuettel: corels 0.0.2 on CRAN: Initial upload!

Corels is now on CRAN! The package was introduced with an initial tweet which pointed to the GitHub repo. The source code repo has since been relocated from my account to the (upstream) corels org in GitHub. And renamed: as the upstream (C++) repo as well as the existing Python package simply call is corels we now do too. The repo, to be distinguishable as a directory, will remain named rcppcorels. We also describe the package a little on the corels package page. Some more work should go into along with work in the upstream repos, so please follow whichever GitHub repo you are interested in. The work on corels is also what is described in the recent arXiv paper on Rcpp and libraries: If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Sean Whitton: spacecadetrebindings

I ve been less good at taking adequate typing breaks during the lockdown and I ve become concerned about how much chording my left hand does on its own during typical Emacs usage, with caps lock rebound to control, as I ve had it for years. I thought that now was as good a time as any to do something drastic about this. Here are my rebindings: Optional extras: This has the following advantages: The main disadvantage, aside from an adjustment period when I feel that someone has inserted a massive marshmellow between me and my computer, is that Ctrl-Alt combinations are a bit difficult; in Emacs, C-M-SPC is hard to do without. However I think I ve found a decent way to do it (thumb on control, curled ring finger on alt, possibly little finger on shift for Emacs infamous C-M-S-v standard binding).

4 June 2020

Steve McIntyre: Interesting times, and a new job!

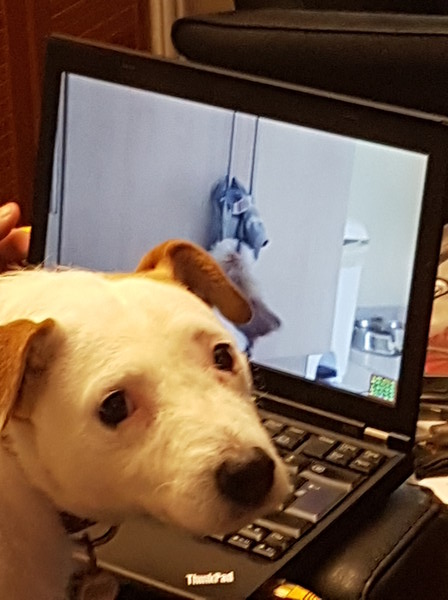
It's (yet again!) been a while since I blogged last, sorry... It's been over ten years since I started in Arm, and nine since I joined Linaro as an assignee. It was wonderful working with some excellent people in both companies, but around the end of last year I started to think that it might be time to look for something new and different. As is the usual way in Cambridge, I ended up mentioning this to friends and things happened! After discussions with a few companies, I decided to accept an interesting-looking offer from a Norwegian company called Pexip. My good friend Vince had been raving for a while about how much he enjoyed his job there, which was a very good sign! He works from his home near Cambridge, and they were very happy to take me on in a similar way. There will be occasional trips to the UK office near Reading, or to the Norway HQ in Oslo. But most of the time I'll be working in my home office with all the home comforts and occasionally even an office dog! Pepper and a laptop! As is common in the UK for senior staff, I had to give 3 months notice with my resignation. When I told my boss in Arm way way back in February that I had decided to leave, I planned for a couple of weeks of down-time in between jobs. Perfect timing! The third week of May in Cambridge is the summer Beer Festival, and my birthday is the week after. All was looking good! Then the world broke... :-( As the "novel coronavirus" swept the world, countries closed down and normal life all-but disappeared for many. I acknowledge I'm very lucky here - I'm employed as a software engineer. I can effectively work from home, and indeed I was already in the habit of doing that anyway. Many people are not so fortunate. :-/ In this period, I've heard of some people in the middle of job moves where their new company have struggled and the new job has gone away. Thankfully, Pexip have continued to grow during this time and were still very keen to have me. I finally started this week! So, what does Pexip do? The company develops and supplies a video conferencing platform, mainly targeting large enterprise customers. We have some really awesome technology, garnering great reviews from customers all over the world. See the website for more information! Pexip logo Where do I fit in? Pexip is a relatively small company with a very flat setup in engineering, so that's a difficult question to answer! I'll be starting working in the team developing and maintaining PexOS, the small Linux-based platform on which other things depend. (No prizes for guessing which distro it's based on!) But there's lots of scope to get involved in all kinds of other areas as needs and interests arise. I can't wait to get stuck in! Although I'm no longer going to be working on Debian arm port issues on work time, I'm still planning to help where I can. Let's see how that works...

Steve McIntyre: What can you preseed when installing Debian?

Preseeding is a very useful way of installing and pre-configuring a Debian system in one go. You simply supply lots of the settings that your new system will need up front, in a preseed file. The installer will use those settings instead of asking questions, and it will also pass on any extra settings via the debconf database so that any further package setup will use them. There is documentation about how to do this in the Debian wiki at https://wiki.debian.org/DebianInstaller/Preseed, and an example preseed file for our current stable release (Debian 10, "buster") in the release notes. One complaint I've heard is that it can be difficult to work out exactly the right data to use in a preseed file, as the format is not the easiest to work with by hand. It's also difficult to find exactly what settings can be changed in a preseed. So, I've written a script to parse all the debconf templates in each release in the Debian archive and dump all the possible settings in each. I've put the results up online at my debian-preseed site in case it's useful. The data will be updated daily as needed to make sure it's current. Updated June 2020 - changed the URL for the preseed site now I have a domain set up at https://preseed.debian.net/.

Antoine Beaupr : Replacing Smokeping with Prometheus

I've been struggling with replacing parts of my old sysadmin monitoring toolkit (previously built with Nagios, Munin and Smokeping) with more modern tools (specifically Prometheus, its "exporters" and Grafana) for a while now. Replacing Munin with Prometheus and Grafana is fairly straightforward: the network architecture ("server pulls metrics from all nodes") is similar and there are lots of exporters. They are a little harder to write than Munin modules, but that makes them more flexible and efficient, which was a huge problem in Munin. I wrote a Migrating from Munin guide that summarizes those differences. Replacing Nagios is much harder, and I still haven't quite figured out if it's worth it.

How does Smokeping work Leaving those two aside for now, I'm left with Smokeping, which I used in my previous job to diagnose routing issues, using Smokeping as a decentralized looking glass, which was handy to debug long term issues. Smokeping is a strange animal: it's fundamentally similar to Munin, except it's harder to write plugins for it, so most people just use it for Ping, something for which it excels at. Its trick is this: instead of doing a single ping and returning this metrics, it does multiple ones and returns multiple metrics. Specifically, smokeping will send multiple ICMP packets (20 by default), with a low interval (500ms by default) and a single retry. It also pings multiple hosts at once which means it can quickly scan multiple hosts simultaneously. You therefore see network conditions affecting one host reflected in further hosts down (or up) the chain. The multiple metrics also mean you can draw graphs with "error bars" which Smokeping shows as "smoke" (hence the name). You also get per-metric packet loss. Basically, smokeping runs this command and collects the output in a RRD database:
fping -c $count -q -b $backoff -r $retry -4 -b $packetsize -t $timeout -i $mininterval -p $hostinterval $host [ $host ...]
... where those parameters are, by default:
  • $count is 20 (packets)
  • $backoff is 1 (avoid exponential backoff)
  • $timeout is 1.5s
  • $mininterval is 0.01s (minimum wait interval between any target)
  • $hostinterval is 1.5s (minimum wait between probes on a single target)
It can also override stuff like the source address and TOS fields. This probe will complete between 30 and 60 seconds, if my math is right (0% and 100% packet loss).

How do draw Smokeping graphs in Grafana A naive implementation of Smokeping in Prometheus/Grafana would be to use the blackbox exporter and create a dashboard displaying those metrics. I've done this at home, and then I realized that I was missing something. Here's what I did.
  1. install the blackbox exporter:
    apt install prometheus-blackbox-exporter
    
  2. make sure to allow capabilities so it can ping:
    dpkg-reconfigure prometheus-blackbox-exporter
    
  3. hook monitoring targets into prometheus.yml (the default blackbox exporter configuration is fine):
    scrape_configs:
      - job_name: blackbox
          metrics_path: /probe
          params:
            module: [icmp]
          scrape_interval: 5s
          static_configs:
            - targets:
              - octavia.anarc.at
              # hardcoded in DNS
              - nexthop.anarc.at
              - koumbit.net
              - dns.google
          relabel_configs:
            - source_labels: [__address__]
              target_label: __param_target
            - source_labels: [__param_target]
              target_label: instance
            - target_label: __address__
              replacement: 127.0.0.1:9115  # The blackbox exporter's real hostname:port.
    
    Notice how we lower the scrape_interval to 5 seconds to get more samples. nexthop.anarc.at was added into DNS to avoid hardcoding my upstream ISP's IP in my configuration.
  4. use this Grafana panel to graph the results. It was created with this query:
    sum(probe_icmp_duration_seconds phase="rtt" ) by (instance)
    
    • Set the Legend field to instance RTT
    • Set Draw modes to lines and Mode options to staircase
    • Set the Left Y axis Unit to duration(s)
    • Show the Legend As table, with Min, Avg, Max and Current enabled
    Then this query, for packet loss:
    1-avg_over_time(probe_success[$__interval])!=0 or null
    
    • Set the Legend field to instance packet loss
    • Set a Add series override to Lines: false, Null point mode: null, Points: true, Points Radius: 1, Color: deep red, and, most importantly, Y-axis: 2
    • Set the Right Y axis Unit to percent (0.0-1.0) and set Y-max to 1
    Then set the entire thing to Repeat, on target, vertically. And you need to add a target variable like label_values(probe_success, instance).
The result looks something like this:
A plot of RTT and packet loss over time of three nodes Not bad, but not Smokeping
This actually looks pretty good! The resulting dashboard is available in the Grafana dashboard repository.

What is missing? Now, that doesn't exactly look like Smokeping, does it. It's pretty good, but it's not quite what we want. What is missing is variance, the "smoke" in Smokeping. There's a good article about replacing Smokeping with Grafana. They wrote a custom script to write samples into InfluxDB so unfortunately we can't use it in this case, since we don't have InfluxDB's query language. I couldn't quite figure out how to do the same in PromQL. I tried:
stddev(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" )
stddev_over_time(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" [$__interval])
stddev_over_time(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" [1m])
The first two give zero for all samples. The latter works, but doesn't look as good as Smokeping. So there might be something I'm missing. SuperQ wrote a special exporter for this called smokeping_prober that came out of this discussion in the blackbox exporter. Instead of delegating scheduling and target definition to Prometheus, the targets are set in the exporter. They also take a different approach than Smokeping: instead of recording the individual variations, they delegate that to Prometheus, through the use of "buckets". Then they use a query like this:
histogram_quantile(0.9 rate(smokeping_response_duration_seconds_bucket[$__interval]))
This is the rationale to SuperQ's implementation:
Yes, I know about smokeping's bursts of pings. IMO, smokeping's data model is flawed that way. This is where I intentionally deviated from the smokeping exact way of doing things. This prober sends a smooth, regular series of packets in order to be measuring at regular controlled intervals. Instead of 20 packets, over 10 seconds, every minute. You send one packet per second and scrape every 15. This has the same overall effect, but the measurement is, IMO, more accurate, as it's a continuous stream. There's no 50 second gap of no metrics about the ICMP stream. Also, you don't get back one metric for those 20 packets, you get several. Min, Max, Avg, StdDev. With the histogram data, you can calculate much more than just that using the raw data. For example, IMO, avg and max are not all that useful for continuous stream monitoring. What I really want to know is the 90th percentile or 99th percentile. This smokeping prober is not intended to be a one-to-one replacement for exactly smokeping's real implementation. But simply provide similar functionality, using the power of Prometheus and PromQL to make it better. [...] one of the reason I prefer the histogram datatype, is you can use the heatmap panel type in Grafana, which is superior to the individual min/max/avg/stddev metrics that come from smokeping. Say you had two routes, one slow and one fast. And some pings are sent over one and not the other. Rather than see a wide min/max equaling a wide stddev, the heatmap would show a "line" for both routes.
That's an interesting point. I have also ended up adding a heatmap graph to my dashboard, independently. And it is true it shows those "lines" much better... So maybe that, if we ignore legacy, we're actually happy with what we get, even with the plain blackbox exporter. So yes, we're missing pretty "fuzz" lines around the main lines, but maybe that's alright. It would be possible to do the equivalent to the InfluxDB hack, with queries like:
min_over_time(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" [30s])
avg_over_time(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" [5m])
max_over_time(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" [30s])
The output looks something like this:
A plot of RTT and packet loss over time of three nodes, with minimax Looks more like Smokeping!
But there's a problem there: see how the middle graph "dips" sometimes below 20ms? That's the min_over_time function (incorrectly, IMHO) returning zero. I haven't quite figured out how to fix that, and I'm not sure it is better. But it does look more like Smokeping than the previous graph. Update: I forgot to mention one big thing that this setup is missing. Smokeping has this nice feature that you can order and group probe targets in a "folder"-like hierarchy. It is often used to group probes by location, which makes it easier to scan a lot of targets. This is harder to do in this setup. It might be possible to setup location-specific "jobs" and select based on that, but it's not exactly the same.

Credits Credits to Chris Siebenmann for his article about Prometheus and pings which gave me the avg_over_time query idea.

Reproducible Builds: Reproducible Builds in May 2020

Welcome to the May 2020 report from the Reproducible Builds project. One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. Nonetheless, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into seemingly secure software during the various compilation and distribution processes. In these reports we outline the most important things that we and the rest of the community have been up to over the past month.

News The Corona-Warn app that helps trace infection chains of SARS-CoV-2/COVID-19 in Germany had a feature request filed against it that it build reproducibly. A number of academics from Cornell University have published a paper titled Backstabber s Knife Collection which reviews various open source software supply chain attacks:
Recent years saw a number of supply chain attacks that leverage the increasing use of open source during software development, which is facilitated by dependency managers that automatically resolve, download and install hundreds of open source packages throughout the software life cycle.
In related news, the LineageOS Android distribution announced that a hacker had access to the infrastructure of their servers after exploiting an unpatched vulnerability. Marcin Jachymiak of the Sia decentralised cloud storage platform posted on their blog that their siac and siad utilities can now be built reproducibly:
This means that anyone can recreate the same binaries produced from our official release process. Now anyone can verify that the release binaries were created using the source code we say they were created from. No single person or computer needs to be trusted when producing the binaries now, which greatly reduces the attack surface for Sia users.
Synchronicity is a distributed build system for Rust build artifacts which have been published to crates.io. The goal of Synchronicity is to provide a distributed binary transparency system which is independent of any central operator. The Comparison of Linux distributions article on Wikipedia now features a Reproducible Builds column indicating whether distributions approach and progress towards achieving reproducible builds.

Distribution work In Debian this month: In Alpine Linux, an issue was filed and closed regarding the reproducibility of .apk packages. Allan McRae of the ArchLinux project posted their third Reproducible builds progress report to the arch-dev-public mailing list which includes the following call for help:
We also need help to investigate and fix the packages that fail to reproduce that we have not investigated as of yet.
In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update.

Software development

diffoscope Chris Lamb made the changes listed below to diffoscope, our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. He also prepared and uploaded versions 142, 143, 144, 145 and 146 to Debian, PyPI, etc.
  • Comparison improvements:
    • Improve fuzzy matching of JSON files as file now supports recognising JSON data. (#106)
    • Refactor .changes and .buildinfo handling to show all details (including the GnuPG header and footer components) even when referenced files are not present. (#122)
    • Use our BuildinfoFile comparator (etc.) regardless of whether the associated files (such as the orig.tar.gz and the .deb) are present. [ ]
    • Include GnuPG signature data when comparing .buildinfo, .changes, etc. [ ]
    • Add support for printing Android APK signatures via apksigner(1). (#121)
    • Identify iOS App Zip archive data as .zip files. (#116)
    • Add support for Apple Xcode .mobilepovision files. (#113)
  • Bug fixes:
    • Don t print a traceback if we pass a single, missing argument to diffoscope (eg. a JSON diff to re-load). [ ]
    • Correct differences typo in the ApkFile handler. (#127)
  • Output improvements:
    • Never emit the same id="foo" anchor reference twice in the HTML output, otherwise identically-named parts will not be able to linked to via a #foo anchor. (#120)
    • Never emit an empty id anchor either; it is not possible to link to #. [ ]
    • Don t pretty-print the output when using the --json presenter; it will usually be too complicated to be readable by the human anyway. [ ]
    • Use the SHA256 over MD5 hash when generating page names for the HTML directory-style presenter. (#124)
  • Reporting improvements:
    • Clarify the message when we truncate the number of lines to standard error [ ] and reduce the number of maximum lines printed to 25 as usually the error is obvious by then [ ].
    • Print the amount of free space that we have available in our temporary directory as a debugging message. [ ]
    • Clarify Command [ ] failed with exit code messages to remove duplicate exited with exit but also to note that diffoscope is interpreting this as an error. [ ]
    • Don t leak the full path of the temporary directory in Command [ ] exited with 1 messages. (#126)
    • Clarify the warning message when we cannot import the debian Python module. [ ]
    • Don t repeat stderr from if both commands emit the same output. [ ]
    • Clarify that an external command emits for both files, otherwise it can look like we are repeating itself when, in reality, it is being run twice. [ ]
  • Testsuite improvements:
    • Prevent apksigner test failures due to lack of binfmt_misc, eg. on Salsa CI and elsewhere. [ ]
    • Drop .travis.yml as we use Salsa instead. [ ]
  • Dockerfile improvements:
    • Add a .dockerignore file to whitelist files we actually need in our container. (#105)
    • Use ARG instead of ENV when setting up the DEBIAN_FRONTEND environment variable at runtime. (#103)
    • Run as a non-root user in container. (#102)
    • Install/remove the build-essential during build so we can install the recommended packages from Git. [ ]
  • Codebase improvements:
    • Bump the officially required version of Python from 3.5 to 3.6. (#117)
    • Drop the (default) shell=False keyword argument to subprocess.Popen so that the potentially-unsafe shell=True is more obvious. [ ]
    • Perform string normalisation in Black [ ] and include the Black output in the assertion failure too [ ].
    • Inline MissingFile s special handling of deb822 to prevent leaking through abstract layers. [ ][ ]
    • Allow a bare try/except block when cleaning up temporary files with respect to the flake8 quality assurance tool. [ ]
    • Rename in_dsc_path to dsc_in_same_dir to clarify the use of this variable. [ ]
    • Abstract out the duplicated parts of the debian_fallback class [ ] and add descriptions for the file types. [ ]
    • Various commenting and internal documentation improvements. [ ][ ]
    • Rename the Openssl command class to OpenSSLPKCS7 to accommodate other command names with this prefix. [ ]
  • Misc:
    • Rename the --debugger command-line argument to --pdb. [ ]
    • Normalise filesystem stat(2) birth times (ie. st_birthtime) in the same way we do with the stat(1) command s Access: and Change: times to fix a nondeterministic build failure in GNU Guix. (#74)
    • Ignore case when ordering our file format descriptions. [ ]
    • Drop, add and tidy various module imports. [ ][ ][ ][ ]
In addition:
  • Jean-Romain Garnier fixed a general issue where, for example, LibarchiveMember s has_same_content method was called regardless of the underlying type of file. [ ]
  • Daniel Fullmer fixed an issue where some filesystems could only be mounted read-only. (!49)
  • Emanuel Bronshtein provided a patch to prevent a build of the Docker image containing parts of the build s. (#123)
  • Mattia Rizzolo added an entry to debian/py3dist-overrides to ensure the rpm-python module is used in package dependencies (#89) and moved to using the new execute_after_* and execute_before_* Debhelper rules [ ].

Chris Lamb also performed a huge overhaul of diffoscope s website:
  • Add a completely new design. [ ][ ]
  • Dynamically generate our contributor list [ ] and supported file formats [ ] from the main Git repository.
  • Add a separate, canonical page for every new release. [ ][ ][ ]
  • Generate a latest release section and display that with the corresponding date on the homepage. [ ]
  • Add an RSS feed of our releases [ ][ ][ ][ ][ ] and add to Planet Debian [ ].
  • Use Jekyll s absolute_url and relative_url where possible [ ][ ] and move a number of configuration variables to _config.yml [ ][ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Other tools Elsewhere in our tooling: strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build. In May, Chris Lamb uploaded version 1.8.1-1 to Debian unstable and Bernhard M. Wiedemann fixed an off-by-one error when parsing PNG image modification times. (#16) In disorderfs, our FUSE-based filesystem that deliberately introduces non-determinism into directory system calls in order to flush out reproducibility issues, Chris Lamb replaced the term dirents in place of directory entries in human-readable output/log messages [ ] and used the astyle source code formatter with the default settings to the main disorderfs.cpp source file [ ]. Holger Levsen bumped the debhelper-compat level to 13 in disorderfs [ ] and reprotest [ ], and for the GNU Guix distribution Vagrant Cascadian updated the versions of disorderfs to version 0.5.10 [ ] and diffoscope to version 145 [ ].

Project documentation & website
  • Carl Dong:
  • Chris Lamb:
    • Rename the Who page to Projects . [ ]
    • Ensure that Jekyll enters the _docs subdirectory to find the _docs/index.md file after an internal move. (#27)
    • Wrap ltmain.sh etc. in preformatted quotes. [ ]
    • Wrap the SOURCE_DATE_EPOCH Python examples onto more lines to prevent visual overflow on the page. [ ]
    • Correct a preferred spelling error. [ ]
  • Holger Levsen:
    • Sort our Academic publications page by publication year [ ] and add Trusting Trust and Fully Countering Trusting Trust through Diverse Double-Compiling [ ].
  • Juri Dispan:

Testing framework We operate a large and many-featured Jenkins-based testing framework that powers tests.reproducible-builds.org that, amongst many other tasks, tracks the status of our reproducibility efforts as well as identifies any regressions that have been introduced. Holger Levsen made the following changes:
  • System health status:
    • Improve page description. [ ]
    • Add more weight to proxy failures. [ ]
    • More verbose debug/failure messages. [ ][ ][ ]
    • Work around strangeness in the Bash shell let VARIABLE=0 exits with an error. [ ]
  • Debian:
    • Fail loudly if there are more than three .buildinfo files with the same name. [ ]
    • Fix a typo which prevented /usr merge variation on Debian unstable. [ ]
    • Temporarily ignore PHP s horde](https://www.horde.org/) packages in Debian bullseye. [ ]
    • Document how to reboot all nodes in parallel, working around molly-guard. [ ]
  • Further work on a Debian package rebuilder:
    • Workaround and document various issues in the debrebuild script. [ ][ ][ ][ ]
    • Improve output in the case of errors. [ ][ ][ ][ ]
    • Improve documentation and future goals [ ][ ][ ][ ], in particular documentiing two real world tests case for an impossible to recreate build environment [ ].
    • Find the right source package to rebuild. [ ]
    • Increase the frequency we run the script. [ ][ ][ ][ ]
    • Improve downloading and selection of the sources to build. [ ][ ][ ]
    • Improve version string handling.. [ ]
    • Handle build failures better. [ ]. [ ]. [ ]
    • Also consider architecture all .buildinfo files. [ ][ ]
In addition:
  • kpcyrd, for Alpine Linux, updated the alpine_schroot.sh script now that a patch for abuild had been released upstream. [ ]
  • Alexander Couzens of the OpenWrt project renamed the brcm47xx target to bcm47xx. [ ]
  • Mattia Rizzolo fixed the printing of the build environment during the second build [ ][ ][ ] and made a number of improvements to the script that deploys Jenkins across our infrastructure [ ][ ][ ].
Lastly, Vagrant Cascadian clarified in the documentation that you need to be user jenkins to run the blacklist command [ ] and the usual build node maintenance was performed was performed by Holger Levsen [ ][ ][ ], Mattia Rizzolo [ ][ ] and Vagrant Cascadian [ ][ ][ ].

Mailing list: There were a number of discussions on our mailing list this month: Paul Spooren started a thread titled Reproducible Builds Verification Format which reopens the discussion around a schema for sharing the results from distributed rebuilders:
To make the results accessible, storable and create tools around them, they should all follow the same schema, a reproducible builds verification format. The format tries to be as generic as possible to cover all open source projects offering precompiled source code. It stores the rebuilder results of what is reproducible and what not.
Hans-Christoph Steiner of the Guardian Project also continued his previous discussion regarding making our website translatable. Lastly, Leo Wandersleb posted a detailed request for feedback on a question of supply chain security and other issues of software review; Leo is the founder of the Wallet Scrutiny project which aims to prove the security of Android Bitcoin Wallets:
Do you own your Bitcoins or do you trust that your app allows you to use your coins while they are actually controlled by them ? Do you have a backup? Do they have a copy they didn t tell you about? Did anybody check the wallet for deliberate backdoors or vulnerabilities? Could anybody check the wallet for those?
Elsewhere, Leo had posted instructions on his attempts to reproduce the binaries for the BlueWallet Bitcoin wallet for iOS and Android platforms.


If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

This month s report was written by Bernhard M. Wiedemann, Chris Lamb, Holger Levsen, Jelle van der Waa and Vagrant Cascadian. It was subsequently reviewed by a bunch of Reproducible Builds folks on IRC and the mailing list.

Gunnar Wolf: Tor from Telmex. When I say achievement unlocked , I mean it!

### The blockade has ended! For some introduction.. Back in 2016, Telmex Mexico's foremost communications provider and, through the brands grouped under the *Am rica M vil* brand, one of Latin America's most important ISPs set up rules to block connecitons to (at least) seven of Tor's *directory authorities* (*DirAuths*). We believe they might have blocked all of them, in an attempt to block connections from Tor from anywhere in their networks, but Tor is much more resourceful than that so, the measure was not too effective. Only... _Some_ blocking did hurt Telmex's users: The ability to play an active role in Tor. The ability to host Tor relays at home. Why? Because the *consensus protocol* requires relays to be reachable in order to be measured from the network's *DirAuths*. ### Technical work to prove the blocking We dug into the issue as part of the work we carried out in the project I was happy to lead between 2018 and 2019, *UNAM/DGAPA/PAPIME PE102718*. In March 2019, I presented a paper titled [Distributed Detection of Tor Directory Authorities Censorship in Mexico](https://www.thinkmind.org/index.php?view=article&articleid=icn_2019_6_20_38010) ([alternative download](http://ru.iiec.unam.mx/4538/) in the [Topic on Internet Censorship and Surveillance (TICS) track](https://tics.site/) of the XVIII International Conference on Networks. Then... We had many talks inside our group, but nothing seemed to move for several months. We did successfully push for increasing the number of Tor relays in Mexico (we managed to go from two to eleven stable relays not much in absolute terms, but quite good relatively, even more considering most users were not technically able to run one!) Jacobo N jera, journalist participant of our project, didn't leave things there just lying around waiting magically for justice to happen. Together with Vasilis Ververis, from the [Magma Project](https://magma.lavafeld.org/), they presented some weeks ago a [Case study: Tor Directory Authorities Censorship in Mexico](https://magma.lavafeld.org/guide/data-analysis.html#case-study-tor-directory-authorities-censorship-in-mexico). ### Pushing to action But a good part of being a journalist is knowing _how_ and _when_ to spread the word. Having already two technical studies showing the blocking in place, Jacobo presented his findings with [an article in GlobalVoices: *The largest telecommunications operator in Mexico blocks the secure network*](https://es.globalvoices.org/2020/05/28/en-mexico-el-mas-grande-operador-de-telecomunicaciones-bloquea-la-internet-segura/). Surprisingly (to me, at least), this story was picked up by a major Mexican newspaper: The same evening the story hit GlobalVoices, [Rodrigo Riquelme](https://www.eleconomista.com.mx/autor/rriquelme) posted an article, in the Technology section of *El Economista*, titled [Telmex blocks seven out of ten accesses to the Tor network in Mexico](https://www.eleconomista.com.mx/tecnologia/Telmex-bloquea-siete-de-10-accesos-a-la-red-Tor-en-Mexico-20200528-0078.html). And that very same day, Telmex sent a reply I am translating in full (that is now included at the end of Riquelme's article): > Mexico City, May 28, 2020 > > In relation to Tor navigation from TELMEX's network, the company > informs: > > In TELMEX, we are committed to the full respect to navigation > freedom for all of our users. > > TELMEX practices no application-level blocking policies; the Tor > application, as well as the rest of Internet applications, can be > freely accessed from our network. > > In order to protect the Internauts' information, the seven refered > nodes were in their time reported because they were associated with > the distribution of the WannaCry ransomware, which is the reason > they were filtered, but this does not hamper the use of the Tor > application. ### So we got an answer...? Jacobo knew we had to take advantage of this answer, and act fast! He entered rush-writing mode and, with the help of our good friend and lawyer Salvador Alc ntar, we wrote [a short letter to Renato Flores Cartas, Corporative Communication of Am rica M vil](https://internetanonima.net/respuesta-a-telmex-sobre-la-red-tor-en-mexico/), and sent it on June 1st. Next thing I know, this evening Jacobo was asking me if I could confirm the blocking was lifted. What I could not believe it! But, yes Today Jacobo published the confirmation that [the seven blocked IP routes were finally reachable again from ASN 8151 (UNINET / Telmex / Am rica M vil)!](https://internetanonima.net/confirmamos-desbloqueo-de-las-7-direcciones-de-la-red-tor-por-telmex/) Of course, this story was picked up again by El Economista [Telmex unblocks IP addresses for the Tor network's directory authority server IPs in Mexico](https://www.eleconomista.com.mx/tecnologia/Telmex-desbloquea-direcciones-IP-de-servidores-de-autoridad-de-la-red-Tor-en-Mexico-20200604-0094.html). ### Wrapping up How can I put this in words? I am very, very, very, *very, very, very*, **very, very, very** happy we managed to see this through! Although we have been pushing for increasing the usage of Tor among users at risk in Mexico Being a journalist, defending human rights, are still a high-risk profession in my country. We strongly believe in this, and will continue trying to raise awareness of the usage. But, just as with free software, *using* network anonymization tools is not all. We need more people to become active, to become engaged, to *become active participants* in anonymization. As the adage says, *anonymity loves company* In order to build strong, sufficient anonymization capability for everybody that needs it, we need more people to *provide relay services*. And this is a *huge* step to improve Mexico's participation in the Tor network! --- Image credits: [*Seeing My World Through a Keyhole*, by Kate Ter Haar](https://www.flickr.com/photos/katerha/4592429363) (CC-BY); [Tor logo (Wikimedia Commons)](https://commons.wikimedia.org/wiki/File:Tor-logo-2011-flat.svg)

3 June 2020

Debian Project Leader: DPL Activity logs for April/May 2020

First month as DPL I survived my first month as DPL! I agree with previous DPLs who have described it as starting a whole new job. Fortunately it wasn't very stressful, but it certainly was very time consuming. On the very first day my inbox exploded with requests. I dealt with this by deferring anything that wasn't important right away and just started working through it. Fortunately the initial swell subsided as the month progressed. The bulk of my remaining e-mail backlog are a few media outlets who wants to do interviews. I'll catch up with those during this month. Towards the end of the month, most of my focus was on helping to prepare for an online MiniDebConf that we hosted over the last weekend in May. We had lots of fun and we had some great speakers sharing their knowledge and expertise during the weekend. Activity log As I do on my own blog for free software activities, I'll attempt to keep a log of DPL activities on this blog. Here's the log for the period 2020-04-21 to 2020-05-21: 2020-04-19: Handover session with Sam, our outgoing DPL. We covered a lot of questions I had and main areas that the DPL works in. Thanks to Sam for having taken the time to do this. 2020-04-21: First day of term! Thank you to everybody who showed support and have offered to help! 2020-04-21: Request feedback from the trademark team on an ongoing trademark dispute. 2020-04-21: Join the GNOME Advisory Board as a representative from Debian. 2020-04-21: Reply on an ongoing community conflict issue. 2020-04-21: Update Debian project summary for SPI annual report. 2020-04-21: Received a great e-mail introduction from Debian France and followed up on that. 2020-04-21: Posted "Bits from the new DPL" to debian-devel-announce. 2020-04-22: Became Debian's OSI Affilliate representative. 2020-04-22: Reply to a bunch of media inquiries for interviews, will do them later when initial priorities are on track. 2020-04-23: Resign as Debian FTP team trainee and mailing list moderator. In both these areas there are enough people taking care of it and I intend to maximise available time for DPL and technical areas in the project. 2020-04-25: Review outgoing mail for trademark team. 2020-04-25: Answer some questions in preparation for DAM/Front Desk delegation updates. 2020-04-26: Initiated wiki documentation for delegation updates process. 2020-04-27: Update delegation for the Debian Front Desk team. 2020-04-29: Schedule video call with Debian treasurer team. 2020-04-29: OSI affiliate call. Learned about some Open Source projects including OpenDev, OpenSourceMatters, FOSS Responders and Democracy Labs. 2020-05-04: Delivered my first talk session as DPL titled "Mixed Bag of Debian" at "Fique Em Casa Use Debian" (Stay at home and use Debian!), organised by Debian Brazil, where they had a different talk every evening during the month of May. Great initiative I hope other local groups consider copying their ideas! 2020-05-05: Had a 2 hour long call with the treasurer team. Feeling optimistic for the future of Debian's financing although it will take some time and a lot of work to get where we want to be. 2020-05-17: Respond to cloud delegation update.

Jonathan Dowland: using Template Haskell to generate boilerplate

Here's a practical example of applying Template Haskell to reduce the amount of boilerplate code that is otherwise required. I wrote the below after following this excellent blog post by Matt Parsons. This post will be much higher-level, read Matt's blog for the gorier details. Liquorice Liquorice is a toy project of mine from a few years ago that lets you draw 2D geometric structures similar to LOGO. Liquorice offers two interfaces: pure functions that operate on an explicit Context (the pen location: existing lines, etc.), and a second "stateful" interface where the input and output are handled in the background. I prefix the pure ones P. and the stateful ones S. in this blog post for clarity. The stateful interface can be much nicer to use for larger drawings. Compare example8b.hs, written in terms of the pure functions, and the stateful equivalent example8.hs. The majority of the stateful functions are "wrapped" versions of the pure functions. For example, the pure function P.step takes two numbers and moves the pen forward and sideways. Its type signature is
P.step :: Int -> Int -> Context -> Context
Here's the signature and implementation of the stateful equivalent:
S.step :: Int -> Int -> State Context ()
S.step x y = modify (P.step x y)
Writing these wrapped functions for the 29 pure functions is boilerplate that can be generated automatically with Template Haskell. Generating the wrapper functions Given the Name of a function to wrap, we construct an instance of FunD, the TH data-type representing a function definition. We use the base name of the incoming function as the name for the new one.
mkWrap fn = do
     
    let name = mkName (nameBase fn)
    return $ FunD name [ Clause (map VarP args) (NormalB rhs) [] ]
To determine how many arguments the wrapper function needs to accept, we need to determine the input function's arity. We use Template Haskell's reify function to get type information about the function, and derive the arity from that. Matt Parson's covers this exactly in his blog.
info    <- reify fn
let ty   = (\(VarI _ t _ ) -> t) info
let n    = arity ty - 1
args    <- replicateM n (newName "arg")
We can use the list "args" directly in the clause part of the function definition, as the data-type expects a list. For the right-hand side, we need to convert from a list of arguments to function application. That's a simple left-fold:
-- mkFnApp f [a,b,c] => ((f a) b) c => f a b c
mkFnApp = foldl (\e -> appE e . varE)
rhs     <- [  modify $(mkFnApp (varE fn) args) :: State Context ()  ]
We use TH's oxford brackets for the definition of rhs. This permits us to write real Haskell inside the brackets, and get an expression data-type outside them. Within we have a splice (the $( )), which does the opposite: the code is evaluated at compile time and generates an Exp that is then converted into the equivalent Haskell code and spliced into place. Finally, we need to apply the above to a list of Names. Sadly, we can't get at the list of exported names from a Module automatically. There is an open request for a TH extension for this. In the meantime, we export a list of the functions to wrap from the Pure module and operate on that
import Liquorice.Pure
wrapPureFunctions = mapM mkWrap pureFns
Finally, we 'call' wrapPureFunctions at the top level in our state module and Template Haskell splices all the function definitions into place. The final code ended up only around 30 lines of code, and saved about the same number of lines of boilerplate. But in doing this I noticed some missing functions, and it will pay dividends if more pure functions are added. Limitations The current implementation has one significant limitation: it cannot handle higher-order functions. An example of a pure higher-order function is place, which moves the pen, performs an operation, and then moves it back:
P.place :: Int -> Int -> (Context -> Context) -> Context -> Context
Wrapping this is not sufficient because the higher-order parameter has the pure function signature Context -> Context. If we wrapped it, the stateful version of the function would accept a pure function as the parameter, but you would expect it to accept another stateful function. To handle these, at a minimum we would need to detect the function arguments that have type Context -> Context and replace them with State Context (). The right-hand side of the wrapped function would also need to do more work to handle wrapping and unwrapping the parameter. I haven't spent much time thinking about it but I'm not sure that a general purpose wrapper would work for all higher-order functions. For the time being I've just re-implemented the half-dozen of them.

Ben Hutchings: Introducing debplate, a template system for Debian packages

For about two months I've been working on a new project, debplate, which currently lives at benh/debplate on Salsa. This is a template system for Debian packages, primarily intended to ease building multiple similar binary packages from a single source. With some changes, it could also be useful for making multiple source packages consistent (issue #9). I want debplate to be capable of replacing the kernel team's existing template system and a lot of its custom scripting, but it is also meant to a general tool. I believe it's already capable of supporting source packages with relatively simple needs, and there are some examples of these in the debplate source. My long-term goal is that debplate will replace most team-specific and package-specific template systems, making those source packages using it less unusual and easier to contribute to. I gave a short talk about debplate at MiniDebConf Online on Sunday.
Ben Hutchings: Debian LTS work, May 2020

I was assigned 17.25 hours of work by Freexian's Debian LTS initiative, and carried over 2.5 hours from April. I worked all 19.75 hours this month. I sent a request for testing an update of the linux package to 3.16.83. I then prepared and, after review, released Linux 3.16.84. I rebased the linux package onto that and sent out a further request for testing. I then backported some additional security fixes, but have still not made an upload. I attended the LTS contributor meeting on IRC.

Andy Simpkins: Getting Co-ap tools working on Debian

At work we have a wonderful pyhon tool that we are able to send CoAP messages to and from our products. Perfect for development work. However recently I needed to install a copy of the tools onto my personal laptop because the only work laptops I have access to have completely dead batteries and so are not suitable for taking out into a field to perform RF range tests .

As a company we have chosen not to package internal development tools I think that this is a mistake, but this is not my decision. So I simply copied across the coap tools directory and tried to run them. Obviously nothing worked! However, the error messages were enough to work out what dependencies I needed to resolve. Error #1 Missing libasan.so.2 shared library
By a process of deduction we found that gcc5 contains libasan2, quite old.
Debian s snapshots was our saviour here:
wget http://snapshot.debian.org/archive/debian/20180412T100152Z/pool/main/g/gcc-5/libasan2_5.5.0-12_amd64.deb

wget http://snapshot.debian.org/archive/debian/20180412T100152Z/pool/main/g/gcc-5/gcc-5-base_5.5.0-12_amd64.deb

dpkg -i ./gcc-5-base_5.5.0-12_amd64.deb ./libasan2_5.5.0-12_amd64.deb

great that was enough to get the port bindings to work
Error #2 google.protobuf When I tried to issue coap requests I ran into missing python3 imports google.protobuf fortunately this is found packaged in Debian buster as party of python3-protobuf
apt-get install python3-protobuf
Done! everything works :-)

Next.

Previous.