Search Results: "xam"

10 January 2009

Julian Andres Klode: python-apt documentation - 2nd time


News: http://bzr.debian.org/loggerhead/users/jak/python-apt/jak/revision/219 introduced again some new documentation. doc/source/apt/debfile.rst 6
doc/source/apt_pkg/cache.rst 540 +++++++++++++++++++++++++++++++++-
doc/source/apt_pkg/index.rst 24 +
doc/source/conf.py 5
doc/source/examples/cache-packages.py 22 +
doc/source/examples/cache-pkgfile.py 29 +
doc/source/examples/missing-deps.py 51 +++ 7 files changed, 659 insertions(+), 18 deletions(-) You can see them at http://people.debian.org/~jak/python-apt-doc/ Missing seem to be:
- AcquireFile
- AcquireItem
- ActionGroup
- Configuration
- MetaIndex
- PackageIndexFile
- PkgManager
- PkgRecords
- PkgSourceList
- PkgSrcRecords
- ProblemResolver
- TagFile
- TagSection But the weekend is not over yet. I will blog tomorrow again, and once I m finished with everything (which may be tomorrow, too). Have fun, read the documentation, find the mistakes. Some things are currently written as ??? , if you know what fits there, please tell me. Posted in Debian, Python

Lucas Nussbaum: On Debian membership

The more I think about it, The more I m convinced that the both approaches that have been proposed to change the way we deal with Debian membership (Joerg s new statuses for non-developing contributors, and Lars counting of advocates) are both steps in the wrong direction. I really would like something simpler, and less technical, to become a Debian Developer. After all, what matters is that we trust new developers to make the right decisions (for example, not touch something that they are not confortable with). We currently verify that they know each and every technical bit about things that they may never encounter during their DD life, but that doesn t say anything about their ability to work with others inside a community, or their judgement when touching packages that they don t maintain. For example, we could have something inspired by the current process to become a Debian Maintainer: instead of going through 50+ questions, we could rely on advocations from existing Debian Developers to judge new applicants. The advocation wouldn t simply be +1 emails (as in Lars proposal), but would instead contain a detailed description of what the applicant did. A group of DDs (DAMs, basically) would then read the advocation emails, and decide whether there s sufficient proof that the applicant can be granted DD status. That would allow a much faster process, removing the load from the Application Managers and NM Frontdesk Members. And it probably wouldn t reduce the quality of new DDs, because of the need to collect advocation emails from several DDs. Probably the best way to move forward with that would be to work on a document (DEP?) that would list all the changes and explain them, and then ask all the developers to vote on it, like it was done for the Debian Maintainers GR. Are there some people interested on working on a first draft of such a document?

9 January 2009

Raphael Geissert: PHPIDS bypass of the day


What to do when bored and reading the latest blog posts from The Spanner?
Once again I read about a PHPIDS bypass so I tried to find a way to bypass it too, so here it is:


you=this
,the=('a\
ler\
t'),you=you[the]
you('hello world \
by Raphael Geissert \
based on example by\
Gareth Heyes\
')
,/abc abc\
abc abc abc\
abc\
/,/abc abc\
abc abc abc\
abc\
/

Michal Čihař: Gammu test version 1.22.90

After lot of development, I finally decided to release new testing release of Gammu. The biggest changes are in SMS daemon, which got lot of improvements and is now in separate binary gammu-smsd. It can log better (support for syslog and Windows Event Log has been added), it can work as a proper daemon or Windows Service, it can be debugged easier (Gammu logs go to same log as other messages, SQL queries can be logged), can reload configuration on the fly. In libGammu, debugging has also improved (you can now use callback to process messages), some memory leaks were fixed and some minor bugs has been fixed. Command line interface now supports text for text messages to be entered through parameter and not only using standard input, it has a new command chekfirmware which obsoletes UsePhoneDB configuration option and other bug fixes has happened, for example messages sending is now again working on Windows. And last but not least, SMS daemon, all related things and gammu configuration files now have man pages, which boosts documentation level from none to almost perfect ;-). As a special bonus for Czech users, Gammu translation is now more complete and all new man pages are translated to Czech. Full list of changes: You can download from usual place: http://cihar.com/gammu/, Debian users will find packages in experimental as soon as they will go through NEW queue.

8 January 2009

Simon McVittie: Converting Debian packaging from bzr to git

I recently converted most of the Debian packaging for Telepathy and related projects from bzr to git, while changing the repository contents from just the debian/ directory to the whole source tree. Here's the recipe, using the latest one to be converted (pymsn) as an example.

Create a repository
mkdir pymsn
cd pymsn
git init

Mass tarball import
  • download all the tarballs into ../tarballs
  • rename all the tarballs to *.orig.tar.gz:
    rename 's/^pymsn-/pymsn_/' *.tar.gz
    rename 's/\.tar\.gz$/.orig.tar.gz/' *.tar.gz
    
  • use git-import-orig to import them:
    cd ../pymsn
    ls ../tarballs/pymsn_*.orig.tar.gz
    for v in 0.2 0.2.1 0.2.2 0.3.0 0.3.1 0.3.2 0.3.3; do \
    git-import-orig --no-merge --no-dch --pristine-tar \
        -u $v ../tarballs/pymsn_$v.orig.tar.gz; done
    
  • throw away the resulting master branch in favour of using one we convert from bzr later:
    git checkout upstream
    git branch -D master
    

Converting the Debian packaging This has the slight complication that in some (but not all) of the bzr commits, the repository contained only the contents of the debian directory, in the root of the repository. So, I needed to rewrite history, with this script:
#!/bin/sh
# index-filter.sh
if git ls-files -s   grep debian; then
    :
else
    git ls-files -s  
        sed -e "s-\t-&debian/-"  
        GIT_INDEX_FILE=$GIT_INDEX_FILE.new git update-index --index-info &&
    mv $GIT_INDEX_FILE.new $GIT_INDEX_FILE
fi
  • Download unstable and experimental packaging into ../pymsn-experimental and ../pymsn-unstable
  • Use bzr-fast-export and git-fast-import to import the two branches:
    ~/.bazaar/plugins/fastimport/exporters/bzr-fast-export.py \
        ../pymsn-unstable   git fast-import
    git branch -m master debian-lenny
    ~/.bazaar/plugins/fastimport/exporters/bzr-fast-export.py \
        ../pymsn-experimental   git fast-import
    git branch -m master debian
    git branch -D tmp
    
  • Rewrite history so changelog, control etc. are consistently inside a debian directory, with the script shown above:
    git filter-branch --index-filter $(pwd)/../index-filter.sh debian-lenny
    rm -r .git/refs/original
    git filter-branch --index-filter $(pwd)/../index-filter.sh debian
    rm -r .git/refs/original
    
  • Merge the appropriate upstream versions into each branch:
    git checkout debian
    git merge upstream/0.3.3
    vim debian/control        # and change Vcs-Bzr to Vcs-Git
    dch "Move packaging to git"
    debcommit -a
    git checkout debian-lenny
    git merge upstream/0.3.1
    vim debian/control        # and change Vcs-Bzr to Vcs-Git
    dch "Move packaging to git"
    debcommit -a
    
  • Rescue Debian patches and put them on a debian-patches branch, which is rebased with each upstream release. For pymsn, there aren't any patches in the debian branch at the moment:
    git branch debian-patches upstream/0.3.3
    
    but there is one in the debian-lenny branch:
    git branch debian-lenny-patches upstream/0.3.1
    git checkout debian-lenny
    cp debian/patches/00-fix-dns-resolution.diff ..
    git checkout debian-lenny-patches
    patch -p1 < ../00-fix-dns-resolution.diff
    git commit -a
    
  • Make a repository on alioth:
    cd /git/pkg-telepathy
    GIT_DIR=pymsn.git git init --bare --shared
    GIT_DIR=pymsn.git git config hooks.mailinglist ...
    vim pymsn.git/description
    
  • Push to the repository:
    git gc --aggressive
    git remote add origin git+ssh://git.debian.org/git/pkg-telepathy/pymsn.git
    git push --all
    
  • On alioth, do some more setup after the initial push:
    cat > pymsn.git/hooks/post-receive <<EOF
    #!/bin/sh
    exec /usr/local/bin/git-commit-notice
    EOF
    chmod +x pymsn.git/hooks/post-receive
    GIT_DIR=pymsn.git git symbolic-ref HEAD refs/heads/debian
    
  • Mark the old repositories as no longer used:
    cd ../pymsn-unstable
    dch $'This repository is no longer used, instead please use git:\n'\
    "git://git.debian.org/git/pkg-telepathy/pymsn.git" -c changelog
    debcommit -c changelog
    bzr push
    cd ../pymsn-experimental
    dch $'This repository is no longer used, instead please use git:\n'\
    "git://git.debian.org/git/pkg-telepathy/pymsn.git" -c changelog
    debcommit -c changelog
    bzr push
    cd ../pymsn
    

Sven Mueller: About Usability

Sami Haahtinen wrote a nice post about usability. I do mostly agree with him, except for one little thing: A few years back, I noticed that I often started as a kind of Joe User with new applications, and often even stayed that way, often wishing that the UI of that application was simpler or at least made it more obvious which options are important and which I could most likely keep at their defaults.
Yet I am a system administrator and programmer/developer, so most people would probably consider me as an advanced user by default (wether that is correct in any given context or not, for example I still don t really grok GIMP).
Also I did have quite a lot of contact with users that have very little experience, knowledge and interest in computers and software and only use them to achive certain goals. Anyway, I m quite sure most readers of this blog are aware that Linus Torvalds once complained about the Gnome printing dialog being simplified way too much. And at that time, I had to agree (note that I didn t check out Gnome again since those days, at least 2 years ago). What I really wonder (especially since I realized this in some of my own applications) is why it is so hard for developers to add some additional checkbox or button that enables/disables advanced options. For example, let s take an applications printing dialog. By default, it would only allow the selection of a printer, orientation (if sensible) and (if the selected printer supports more than one) the paper size. Now advanced options might include duplex printing (automatic or manual), printing mutliple pages on a single sheet of paper, printing in grey on color printers, These options might be of use to anyone, but would most likely confuse beginners. So what I did in most of my little application was to just show the basic options and add an advanced options button which provided access to additional functionality which was not normally needed. As for the issue with firefox updates mentioned by Sami: I don t think it is a problem that firefox asks what to do with extensions. For one, it only lists extensions which are installed but claim not to support the new version of firefox. Second, practically everyone I know of who uses any extension can be considered to be an advanced user. And third: The dialog is pretty straightforward about what it is asking and when I once hit it while a ( dumb user ) friend was sitting with me, he understood what it was about quite easily (I didn t explain the dialog, just what extensions were). So my idea of a good UI is:
As simple as possible for beginning users, but allow advanced users to get to the details ( Details or Advanced options buttons/checkboxes/dialogs).

Bdale Garbee: Grand Works

In June of 2005, I finished reading "The Professor and the Madman" by Simon Winchester, which is an intriguing story of two significant contributors to the Oxford English Dictionary, or OED. I first heard this book mentioned in an interview on the Charlie Rose show, and it sounded interesting, so I bought a paperback copy, and it was indeed an interesting read. I wrote these thoughts down then, but neglected to post them until now. That was likely in part because others beat me to the punch. In particular, I think I remember listening to a presentation by Nat Friedman on the topic at around that time. In any case, I stumbled today over the text I wrote back then, and thought the words were still worth sharing. The most interesting thing I learned in reading this book wasn't actually about the principal characters, but instead involves a speech given by Richard Chenevix Trench to the Philological Society, entitled "On Some Deficiencies in Our English Dictionaries." This is the talk that eventually led to the creation of the OED, and the intriguing bit to me is an idea Trench proposed that was new at the time, but absolutely fundamental to the Open Source & Linux world today. Trench well understood that an undertaking of such magnitude as compilation of an exhaustive dictionary of the English language, detailing the history and lifetime of each word illustrated with many example of usage from existing literature, could never be accomplished by one individual. Instead, he proposed explicitly involving a large group of unpaid volunteer contributors. Winchester claims that while this may sound obvious today, that this idea had never been put forward before for such an undertaking. Absolutely brilliant. As an up-close observer of the evolution of the community approach to software development and maintenance, I couldn't help but draw connections. We are today engaged in an equally grand effort that may well have an enduring impact, that fundamentally would not be possible to accomplish without the contributions of an astoundingly diverse array of unpaid volunteer contributors...

6 January 2009

Joey Hess: proposing rel-vcs

I'm working on designing a microformat that can be used to indicate the location of VCS (git, svn, etc) repositories related to a web page. I'd appreciate some web standards-savvy eyes on my rel-vcs microformat rfc. If it looks good, next steps will be making things like gitweb, viewvc, ikiwiki, etc, support it. I've already written a preliminary webcheckout tool that will download an url, parse the microformat, and run the appropriate VCS program(s). (Followed by, with any luck, github, ohloh, etc using the microformat in both the pages they publish, and perhaps, in their data importers.) Why? Well,
  1. A similar approach worked great for Debian source packages with the XS-VCS-* fields.
  2. Pasting git urls from download pages of software projects gets old.
  3. I'm tired of having to do serious digging to find where to clone the source to websites like Keith Packard's blog, or cariographics.org, or St Hugh of Lincoln Primary School. Sites that I know live in a git repo, somewhere.
  4. With the downturn, hosting sites are going down left and right, and users who trusted their data to these sites are losing it. Examples include AOL Hometown and Ficlets, Google lively, Journalspace, podango, etc etc. Even livejournal's future is looking shakey. Various people are trying to archive some of this data before it vanishes for good. I'm more interested in establishing best practices that make it easy and attractive to let all the data on your website be cloned/forked/preserved. Things that people bitten by these closures just might demand in the future. This will be one small step in that direction.

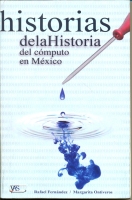
Gunnar Wolf: Historias de la Historia del c mputo en m xico


Some months ago, I got a phone call from Rafael Fern ndez Flores. He wanted to interview me for a book he was working on regarding the history of computers in Mexico. The first computer in Latin America was installed in 1958 at my University (UNAM), and last year there were several activities conmemorating it. One of said activities is the publication of the book Historias de la Historia del c mputo en m xico, by Rafael Fern ndez and Margarita Ontiveros.
The book was printed in November, and Rafael gave me my copy in early December. It is quite an entertaining read - I mostly enjoyed the archaeological parts of it, referring to the 1950s and 1960s, and with many people that I know first hand (as my father is one of the founding researchers of the Centro de Investigaci n en Matem ticas Aplicadas, Sistemas y Servicios, CIMASS, now IIMAS).
I do believe, anyway, the book is focused too heavily on what happened in the large-scale computer world during a fundamental point in time for me (late 1970s, early 1980s) - It shows that the authors were very involved in the important projects the University set foot on, but they overlook fundamental pieces of the history. Very important developments were made in smaller venues (it was shocking for me to find only one mention, and just as a reference, to Fundaci n Arturo Rosenblueth and its great Centros Galileo, where many hundreds of kids (me included) learned to love computers, to program, and had a thriving socialization place. I also missed mentions of the BBS scene in Mexico, for which there are various exponents. And, just to single out one person, I found it absurd to have me interviewed and not to include La Mancha de la Calabaza que Ladra.
One of the last chapters -there are over 40 chapters, stemming from over 30 individual interviews- publishes the talk I had with Rafael. I must say there are small errata in its transcription (the first example that comes to my mind: I told him that one of the fruits of the OLPC project was the appearance of the now-popular netbooks, partly due to the appearance of lower cost parts, but I must reiterate I didn't say the Asus EEE is a part of said project). You can I am attaching my interview (as scanned, low-res images) to this post, in case you are interested.
Anyway - If the topic interests you, you will find many interesting passages, many passages you will surely laugh with and probably remember. The book is very well laid out. And it is a great joy to be part of it!

Benjamin Mako Hill: Change of Plans

One change and one addition to my current European tour. First, it looks like we'll be skipping Amsterdam this time and heading straight to London from Zagreb on the evening of January 10th. We'll still plan to arrive in Cambridge before the 13th. Second, I'll be giving a redux of my Revealing Errors talk at Mama in Zagreb on January 10th at 14:00 as part of the normal skill sharing meeting. It's the longer version of my OSCON keynote with many more examples. Folks who have seen earlier versions of the talk seem to think it's a lot of fun. If you are in or near Zagreb, you should come!

5 January 2009

Ben Hutchings: Searching for invalid object code

J r my Bobbio suggested that I should explain how I looked for packages affected by a compiler bug (Debian bug 506713; gcc bug 38287). I don't claim that this is a particularly good way to do it, but here it is: First, I identified a pattern to search for. Unfortunately I don't really understand the cause or fix for the bug, but I did have the example which led to this bug report: Debian bug 490999. The bad code was a stack-pointer-relative load immediately after a stack allocation (SPARC save instruction) where the offset was not adjusted for the stack allocation:
save  %sp, -112, %sp
ld  [ %sp + 0x40 ], %i5
I generalised this to:
save  %sp, offset1, sp
...
ld  [ %sp + offset2 ], register
where offset1 + offset2 < 0. Of course, this may be valid if the intervening instructions include a restore, branch or store to the effective stack location that the last instruction loads from. I ended up allowing up to 10 intervening instructions and examining a disassembly to work out which cases were valid. I looked up the instruction encoding for these two instructions. Thankfully SPARC is RISC so they are simple and regular: I took the dumb but effective approach of scanning entire files for this pattern rather than only scanning their code sections. This seemed to work - I got no false hits for non-code - but might not work for other patterns that could match ASCII text. I wrote the scanning program in Python, which is my default choice of language unless I know it's going to be too slow. I was hoping to be able to read the code files into arrays, but unfortunately the Python array type only supports the native byte-order (SPARC is big-endian and I was intending to use an x86 which is little-endian). I tried reading into a tuple using struct.unpack, which does support explicit byte-ordering, but this used so much memory for larger files that the program swapped to a crawl. So finally I resorted to reading the file into a string, doing a string search for '\x9d\xe3', rejecting matches that weren't appropriately aligned, then unpacking and comparing the code words from the point of the string match. (In Python 3.0 I would have to use the bytes type for this, as str is a Unicode string type.) So that's how I scanned single files. The next step was to find, unpack and scan all the SPARC shared libraries in the archive. (This particular code generation bug is understood to affect only PIC code, and that is normally only used in shared libraries.) I wrote functions to search Contents-sparc for shared library files - assumed to match the pattern ([^\s]*/lib[^/\s]+\.so(?:\.[^/\s]*)?) - and to parse Packages to find the filenames for the packages containing those files. The latter uses the debian_bundle.deb822 module from python-debian. The last key function downloads and unpacks a package using wget and dpkg-deb. I could have used the httplib module for downloading but I correctly anticipated that I'd need to restart the script several times so I wanted to cache the packages which was easier to do using wget. So, that's the explanation. If you really want to see it, here's the code.

4 January 2009

Sami Haahtinen: About Usability

Some people consider the gnome usability guidelines a nuisance and some consider certain applications way too simplistic. While it is really hard to get the usability right, it's well worth it. We need to keep in mind that as computer oriented people we tend to see things differently. Things that are simple to us aren't really that simple to the "normal people". But one of the simple things we can do the insure that the software we write serve the people it's designed for is to remove all not needed pop-ups and questions. A good way to detect these would be to ask yourself why would a user choose anything else but the most logical option. It's kind of hard to explain, so lets pick an example: Firefox is updated, the first question it usually asks after upgrade is about incompatible extensions. The user is presented with choices, check for updates or cancel. Now, we are dealing with internet browser so the user should be connected to the internet so there is no problem with checking for the updates, we can rule out that scenario. The other scenario that I can come up with is that a developer doesn't want to update some certain extension. So at least I can't come up with any reasonable scenario why someone would want to select anything else but to upgrade the main option of upgrading the extensions. Why not just leave out the option and instead do the upgrade automatically. If you wish to be transparent, you can show the user that you are doing the upgrade. Or you can do like some applications do and just do it without bothering the user with the options. I know I sound like a Google fanboy, but Google generally gets this right. Their applications skip out all upgrade related notices and just do the upgrade. Regular user doesn't want to upgrade because the user has been scared with incompatibility notices and upgrade checklists for so long. Just going ahead with the upgrade in complete silence keeps their software up to date as well. Another example would be from few years back: The Ubuntu installation. Back in the day Debian was working on Debian Installer, which is also used as the main installer in Ubuntu alternative installation media. Debian Installer is capable of doing most things silently, but with Debian it by default asks a lot of questions. It doesn't matter, since most people who install Debian can be categorized as developers. But in my opinion, the thing that made Ubuntu a success was that it doesn't ask the questions that can be answered without asking the user. So, back to usability. There are basically 2 camps, the "normal" users and the developers. Developers want and need to see a lot of the backend behaviour, just to debug problems. Currently a lot of the open source software is focused towards developers while they are gaining grounds on the "normal" population as well. We should start focusing on the users for a change.

Evan Prodromou: 15 Niv se CCXVII

I really like the This American Life podcast. It's probably one of my favorite pieces of public radio, and having a full high-quality public feed is fantastic. However, I've been a little grumpy about the long forewords that have been put into the show lately, asking for donations from podcast listeners. Here's the scoop: apparently WBEZ (Chicago Public Radio) is spending US$150K just on the bandwidth to keep the podcast on the air (not counting servers, staff, or whatever). This is not just small potatoes for WBEZ; they just laid off a dozen workers. So, podcast listeners should pay their fair share and help out Chicago Public Radio. Now, I'm a big fan of public radio, and I think everyone should become a member. However, I find the premise of this solicitation kind of faulty. First, there are a lot of technical ways they could cut down on their bandwidth requirements. Providing an alternative BitTorrent RSS feed, for example, would reduce their bandwidth requirements a lot. They'd need to put a bit of documentation on their site, but is that really harder than getting people to pony up $$? I think not. Second, they could change the redistribution requirements and let other people or organizations mirror the episodes. A Creative Commons license would let other people distribute the files, saving WBEZ a lot (possibly all) of the distribution costs. But that second option is probably not that interesting to WBEZ. Why not? Because they make money selling "This American Life" to other public radio stations. If they put it under a free-redistribution license, they wouldn't be able to get that income. So, in reality, the service announcements at the beginning of the podcasts aren't really asking listeners to keep the podcasts running. There are lots of ways to do that. What the announcements ask is for listeners to support a particular "business" model. There are even ways (like BitTorrent) to have their cake and eat it too. I'm still going to contribute to WBEZ, since I like the show and I'm glad it's produced the way it is. But I regret the disingenuous guilt-tripping that's going on. It's not a fair way to treat listeners and supporters. tags:

3 January 2009

David Moreno: Ruby goodies: Modules and methods for my everyday Ruby

I make a lot of Web script processing, whether scraping, webservices, systems administration, etc. Because I sometimes happen to repeat small and useful chunks of code for different projects, I thought that, given making new modules and methods is usually hassleless in Ruby, I should make my own set of methods and goodies I constantly use. Example 1, I sometimes miss Perl s LWP::Simple simplicity where I just pass a URL to a subroutine and get the content on a variable, quick, one-liner. Example 2, extract all links on a given URL on an array that I can then iterate and maybe fetch given the first example. Getting all A links is very easy to do, say with regex or with Hpricot (which should the best way to parse HTML), but most of the time I (and people, I d bet) need absolute URLs which is fairly more complex (relative, absolute URLs, BASE href declarations, etc, the same case as in Feedbag). Well, for different cases like that one, I ve started my own set of Ruby goodies. If you don t find them useful, I understand, they are mostly for my needs, I just want to make it public, because maybe, some other people might indeed find them useful. Simple installation:
sudo gem install damog-goodies -s http://gems.github.com/
As time and needs pass, I will be adding stuff into it. For the time being, here s both above examples in action:

>> require "goodies"
requiring /var/lib/gems/1.8/gems/damog-goodies-0.1/lib/goodies/array.rb
requiring /var/lib/gems/1.8/gems/damog-goodies-0.1/lib/goodies/lwr.rb
requiring /var/lib/gems/1.8/gems/damog-goodies-0.1/lib/goodies/html.rb
=> true
>> pp HTML::Links.find "damog.net"
["mailto:david-YOUKNOWTHEDEAL-axiombox.com",
 "http://log.damog.net/",
 "http://historiasdenuevayork.com",
 "http://axiombox.com/",
 "http://flickr.com/photos/raquelydavid",
 "http://last.fm/user/damog",
 "http://maggit.com.mx",
 "http://twitter.com/damog",
 "http://www.facebook.com/profile.php?id=670490388",
 "http://www.chess.com?ref_id=1380378",
 "http://www.chess.com",
 "http://www.chess.com/members/view/damog?ref_id=1380378",
 "http://www.chess.com/echess/create_game.html?uid=1380378&ref_id=1380378",
 "http://www.chess.com/home/game_archive.html?member=damog&ref_id=1380378"]
=> nil
>> pp HTML::Links.find("http://google.com").first(10)
["http://images.google.com/imghp?hl=en&tab=wi",
 "http://maps.google.com/maps?hl=en&tab=wl",
 "http://news.google.com/nwshp?hl=en&tab=wn",
 "http://www.google.com/prdhp?hl=en&tab=wf",
 "http://mail.google.com/mail/?hl=en&tab=wm",
 "http://www.google.com/intl/en/options/",
 "http://video.google.com/?hl=en&tab=wv",
 "http://groups.google.com/grphp?hl=en&tab=wg",
 "http://books.google.com/bkshp?hl=en&tab=wp",
 "http://scholar.google.com/schhp?hl=en&tab=ws"]
=> nil
>> get "debian.org"
[snip]
>> get("planeta.debian.net")[0, 100]
=> "<!DOCTYPE HTML PUBLIC "-//W3C//DTD HTML 4.01 Transitional//EN" "http://www.w3.org/TR/html4/loose.dtd"
>>
Repository is, as usual, kindly hosted at GitHub on damog/goodies.

Julian Andres Klode: python-apt: Deprecation of mixedCase names, re-organisation of apt.progress, and more


[as sent to deity@lists.debian.org] Hello, while hacking a bit on python-apt in the last days, I formulated some
proposals which I want to present to you. I have already implemented proposals I and VII, started with the implementation
of proposal II, and have partially implemented proposal III, all in
my local branch. I could implement the rest next week, and this could
result in python-apt 0.7.9~exp2 (at least this is my wish, I do not
have commit access to the python-apt repository, and this mail is not
discussed yet :) ). My local branch is not online yet, but I m working on it. It is based
off debian-sid revision 202 (which is 0.7.9~exp1). I would have also suggest to (at least partially) follow PEP 7 (C code),
but re-indenting the whole extension code is not a good idea. Before I go on, I would like to know your opinions about these proposals,
what you like and what not, your suggestions, etc, etc List of Proposals
 I   Deprecation of mixedCase naming conventions in apt module
 II  Re-organisation of the apt.progress module
 III Language updates
 IV  Unification of testing code
 V   Cleanup of the code
 VI  Using unique variable names throughout the modules
 VII Some other changes
 
I. Deprecation of mixedCase naming conventions in apt module In order to comply with PEP 8, we should start to change our names
from mixedCase to lowercasewithunderscores style. This style is
more common in the Python world, and used eg. in the Python library. I hereby propose that:
  1. a new module apt.deprecate is introduced, which provides functions
    for compatibility and a class named DeprecateMixedCase
  2. Most classes are changed to subclass DeprecateMixedCase instead of
    object.
  3. All methods, attributes and variable names are changed from the
    mixedCase style to the lowercasewithunderscores style.
  4. apt_pkg will be changed to call the new methods on progress objects,
    and fall back to the old names if methods with new names are not
    available.
How backward compatibility is implemented: The DeprecatedMixedName class provides the methods getattr()
and setattr(). These classes will forward all access to attributes
with mixedNames to the ones with lowercasewithunderscores names. In case of methods, the getattr() method returns a helper function
which fixes all keyword arguments with mixedCase names and than calls
the right function. As this only works for methods with mixedCase names, methods which have
mixedCase-named args, get the argument **kwds, and its content will be
checked for mixedCase-named arguments. [On the other side, given that
the API is marked as not stable, we could also drop that level of
compatibility.] Schedule:
  1. Implement all the changes in an experimental version of python-apt
    as soon as possible.
  2. (A) Once all packages have been adjusted to use the new names, remove
    the old ones (about 50 binary packages, and I would write the needed
    patches). This would Breaks: about 50 packages.
    or
    (B) After the release of Debian Squeeze, remove the compatibility
    functions (and the deprecate module from apt). This is the same
    as (A), but does not require Breaks on 50 packages.
Known Issues:
  1. The methods will not be available using their oldName at class
    level, only at object level. This means that some code subclassing
    apt.* classes may fail. Most code will not break, however.
II. Re-organisation of the apt.progress module The apt.progress module is not very consistent in the way classes
are named. For example, there is OpTextProgress but TextFetchProgress. Therefore, I hereby propose that:
  1. For each of the for types of progress ( Cdrom , Fetch , Install , Op ),
    a new class is introduced with the name: Abstract%sProgress % progress
  2. For each type of progress a class Text%sprogress % progress is introduced,
    which subclasses Abstract%sProgress and provides textual output
  3. For further classes, a general naming scheme is introduced, which is
    %(outputtype)s%(progresstype)sProgress [whereas (1) and (2) implement
    this naming scheme]
Schedule: Same as in proposal I. III. Language updates The apt package has been written some time ago, and has not been updated
to make use of the latest language features. Therefore, I propose that:
  1. all code using old language features is adjusted to use language
    features as of Python 2.5.
    1.1 Examples include the use of decorators, and the use
    of str methods instead of functions of the string module.
  2. The with statement will be used where appropriate, and that
    apt_pkg.*Lock() gain support for being used as context managers.
Schedule: Implement as soon as possible. IV. Unification of testing code Most modules ship test code which will be called when the module is
run as a script. Therefore, I propose that:
  1. All testing code in the apt module is removed
  2. All the tests in the tests directory of python-apt
    are converted to a unified testing suite.
  3. Testing code which has been removed as part of (1) is
    reintroduced in the relevant test module, if appropriate.
Schedule: Implement as soon as possible. V. Cleanup of the code In accordance to PEP 8, which is also named as a rule in apt/README.apt,
code will be reformatted where needed. This includes 2 lines between module-level definitions, spaces after
, , comparing to None using is instead of = , and more. Schedule: Implement as soon as possible. VI. Using unique variable names throughout the modules I hereby propose the following names:
 cache    - An apt.cache.Cache() object
 pkg      - An object returned by cache[str()] (in special cases)
 pkg      - An apt.package.Package() object
 cand     - An object returned by depcache.GetCandidateVer()
This would remove some confusion for developers, especially
if you see that apt.Package() objects are named cand in debfile,
but pkg everywhere else. Schedule: Implement as soon as possible. VII. Some other changes Here is a list of other changes I have already made in my branch:
  • Remove apt.package.Record(), it behaves exactly like the
    object it is wrapping (apt_pkg.ParseTagFile() result)
  • Move the Origin class out of the Package() class and at
    the module level.
  • If a package should be marked for upgrade, but is not upgradable
    raise an exception (which will be apt.package.NotUpgradableError)
Schedule: Implement as soon as possible. Posted in Debian

1 January 2009

Sandro Tosi: Compress MySQL Tables

I got this long running task that (fsck!) died almost at the end of the job, and it logs its operation in a MySQL table.

Since I want to keep those "partial" results for further inspection (even after I'll fix and let the tool run again until the end) I don't want to waste disk space (it's ~650mb), so why don't compress that table?

With MySQL (and MyISAM tables like mine), it's pretty easy: go into the directory of the db schema:
# cd /var/lib/mysql/tabs_compare/
# ls -l
total 659500
-rw-rw---- 1 mysql mysql 65 2008-09-21 00:35 db.opt
-rw-rw---- 1 mysql mysql 12840 2008-12-25 00:44 log_1230162297.frm
-rw-rw---- 1 mysql mysql 675299244 2009-01-01 20:34 log_1230162297.MYD
-rw-rw---- 1 mysql mysql 1024 2009-01-01 20:37 log_1230162297.MYI
Pretty big :) Now, check the table:
# myisamchk log_1230162297.MYI
Checking MyISAM file: log_1230162297.MYI
Data records: 4293747 Deleted blocks: 0
- check file-size
- check record delete-chain
- check key delete-chain
- check index reference
- check record links
Hopefully there is no error, so we can compress that table:
# myisampack log_1230162297.MYI
Compressing log_1230162297.MYD: (4293747 records)
- Calculating statistics
- Compressing file
43.05%
And the result it's really nice:
# ls -l
total 375572
-rw-rw---- 1 mysql mysql 65 2008-09-21 00:35 db.opt
-rw-rw---- 1 mysql mysql 12840 2008-12-25 00:44 log_1230162297.frm
-rw-rw---- 1 mysql mysql 384558282 2009-01-01 20:34 log_1230162297.MYD
-rw-rw---- 1 mysql mysql 1024 2009-01-01 20:49 log_1230162297.MYI
The compress command didn't even take a full core on my machine and almost took 20secs to complete.

Now rebuild indexes (if any) and recheck the table to be error free:
# myisamchk -r log_1230162297.MYI
...
# myisamchk log_1230162297.MYI
...
now tell MySQL to reload those table with:
mysql> flush tables <schema>;
Keep always in mind that compressed tables are read-only, so no DML commands, while DDL are allowed (so you can DROP it, for example).

31 December 2008

Joachim Breitner: Handling explicit and implicit recusion in Haskell data

For a while I have been pondering over a problem that arises when your functionally written program has some state with cross references for example a list of users, each of which uses a number of computers, and a list of computers, each having an owner. Implicit referencing For doing queries on such data, it would be convenient if every reference is just the referenced object itself. Although we would visualize this as a graph, semantically, it is more like an infinite tree. This is possible in Haskell, due to laziness, and if you create the data structure cleverly, it even uses constant memory, no matter how deep you enter this infinite tree (a recent post of mine talks about this). A possible data definition would be:
data User = User  
userName :: String,
uses :: [Computer]

data Computer = Computer
computerName :: String,
owner :: User -- references the Users

data State = State [User] [Computer]

testState = let user = User "Conrad" [computer]
computer = Computer "Z3" user
in State [user] [computer]
Explicit referencing But such a representation is very unsuitable for updates (at least I can t think if a nice way of updating such a graph without breaking the internal cross-references) and serialization, which is a must for a HAppS based application. So what one would probably start with is this data structure:
data User = User  
userId :: Int,
userName :: String,
uses :: [Int] -- references the Computers

data Computer = Computer
computerId :: Int,
computerName :: String,
owner :: Int -- references the Users

data State = State [User] [Computer]

testState = State
[User 0 "Conrad" [1]]
[Computer 1 "Z3" 0]
I think the semantics of this are clear. Note that the referencing is currently not type-safe, but this can be provided by phantom types. Maybe I ll write more about that later. Now imaging you want to display the information about the first computer with your web application. You extract the information with let State _ cs = testState in head cs and pass that to your templating engine. But what if your template wants to display the name of the owner? It only has access to his userId. You would either need to know what information the template will ever need, extract that from the state beforehand and pass it along, or give the template access to the whole state. In that case, though, there has to be lookup-logic in your output code, which is also not nice. Woudln t it be nice if you could, in your application logic, work with the explicit references, which are easy to modify and store, but somehow turn that into the implicit referencing? Duplicated representation One way would be to have two unrelated sets of data structures, ExplicitState, ExplicitUser, ExplicitComputer, which use explicit identifiers to reference each other, and ImplicitState,... which are defined as the first representation of our state. It is then mostly trivial to write a function that converts ExplicitState to ImplicitState. The big disadvantage of this is that you have to maintain these two different hierarchies. It also means that every function on the state has to be defined twice, which often almost identical code. Clearly, this is not desirable. Annotated representation It would be more elegant if the state is stored in one data type that, controlled by a type parameter, comes in the one or the other representation. To do that, we need two types: One that contains a value, and one that contains just a reference:
newtype Id v = Id v deriving (Show, Typeable, Data)
newtype Ref v = Ref Int deriving (Show, Typeable, Data)
Then we need to adjust our data definitions, to make use of these. (I ll leave out the names, to keep the code smaller)
data User ref = User  
userId :: Int,
uses :: [ref (Computer ref)]

data Computer ref = Computer
computerId :: Int,
owner :: ref (User ref)

data State ref = State [User ref] [Computer ref]
Here we introduce a type parameter ref , which will later be either Id or Ref. Note that now a reference also states the object it is a reference for, which greatly increases type safety. Functions on these data types that don t work with the references will be polymorphic in the ref type parameter, so only need to be written once. A User Id is a complete user with all related data, while User Ref is a user with only references. And a Ref (User Ref) is reference to a user, which contains references... Not so kind kinds Did you notice the lack of a deriving clause? Our data structures have the relatively peculiar kind ((* -> *) -> *), which makes it hard for the compiler to derive instances for things like Show. But we already know that we will only use Id or Ref for the type variable, so we can use ghc s StandaloneDeriving language extension and have these instances created:
deriving instance Show (User Id)
deriving instance Show (User Ref)
deriving instance Show (Computer Id)
deriving instance Show (Computer Ref)
deriving instance Show (State Id)
deriving instance Show (State Ref)
Toggling a type parameter The next step is to write the conversion function. It will have type
unrefState :: State Ref -> State Id
For that, and for later, we need lookup functions:
unrefUserRef :: State Id -> Ref (User Ref) -> Id (User Id)
unrefUserRef (State l _) (Ref i) = Id $ fromJust $
find (\u@(User i' _) -> i == i') l
unrefComputerRef :: State Id -> Ref (Computer Ref) -> Id (Computer Id)
unrefComputerRef (State _ l) (Ref i) = Id $ fromJust $
find (\u@(Computer i' _) -> i == i') l
These expect a State (with implicit referencing) and a reference, and look up this reference. The function unrefState then looks like this:
unrefState :: State Ref -> State Id
unrefState (State us cs) =
let unrefState = State (map (unrefUser unrefState) us)
(map (unrefComp unrefState) cs)
in unrefState
where unrefUser :: State Id -> User Ref -> User Id
unrefUser s (User i refs) = User i (map (unrefComputerRef s) refs)

unrefComp :: State Id -> Computer Ref -> Computer Id
unrefComp s (Computer i ref) = Computer i (unrefUserRef s ref)
Note how we tie the knot in the let expression. This is the trick that ensures constant memory consumption, because every reference points back to the same place in memory. Satisfied already? So what do we have? We have no duplication of data types, we can write general functions, and we can resolve the explicit referencing. We can also easily write functions like unrefUser :: State Ref -> User Ref -> User Id, which transform just a part of the state. But writing unrefState is very tedious when the State becomes more complex. Each of the other unrefSomething functions are very similar, but need to be written anyways. This is unsatisfactory. What we want, is a generic function, something like
gunref :: State Ref -> a Ref -> a Id
which, given a state with explicit references, replaces all explicit references in the first argument (which could be State Ref or User Ref or anything like that) with implicit ones. This function can not exist, because we would not know anything about a and b. But maybe we can do this:
gunref :: (Data (a Id), Data (a Ref)) =>  State Ref -> a Ref -> a Id
Typeable and Data Before being able to do so, we need to derive Data for our types. We can start with
deriving instance Data (User Id)
deriving instance Data (User Ref)
deriving instance Data (Computer Id)
deriving instance Data (Computer Ref)
deriving instance Data (State Id)
deriving instance Data (State Ref
but that will complain about missing Typeable instances. Unfortunately, ghc s deriver for Typeable (even the stand-alone-one), does not handle our peculiar kind, so we need to do it by hand. With some help from quicksilver on #haskell, I got it to work:
instance Typeable1 ref => Typeable (User ref) where
typeOf _ = mkTyConApp (mkTyCon "User") [typeOf1 (undefined :: ref ())]
instance Typeable1 ref => Typeable (Computer ref) where
typeOf _ = mkTyConApp (mkTyCon "Computer") [typeOf1 (undefined :: ref ())]
instance Typeable1 ref => Typeable (State ref) where
typeOf _ = mkTyConApp (mkTyCon "State") [typeOf1 (undefined :: ref ())]
everywhere is not enough Turning to the documentation of Data.Generics, I notice with some disappointment that there is no function that is able to change a type they all seem to replace a value by another value of the same type. But the functions gfoldl and gunfold sounded like they could be used for this. Warning: What comes now is a very non-haskellish hack that subverts the type system, just to get the job done. Please read it with a healthy portion of distrust. If you know of a cleaner way of doing that, please tell me! Wrapped Data I want to do some heavy type hackery, so I need to disable haskell s type system. There is Data.Dynamic, but not even that is enough, as we need to carry a type s Data instance around as well. So let s wrap that up:
data AData where AData :: Data a => a -> AData
instance Show AData where show (AData a) = "<" ++ show (typeOf a) ++ ">"

fromADataE :: forall b. Data b => AData -> b
fromADataE (AData d) = case cast d of
Just v -> v
Nothing -> error $ "Type error, trying to convert " ++
show (typeOf d) ++ " to " ++
show (typeOf (undefined :: b)) ++ "."
There is also a function that converts an AData back to a normal type, if possible. If it s not possible, then there is a bug in our code, so we give an informative error message. AData transformers Similar to everywhere, we want to have transformers that combinable. They need to have the change to convert an arbitrary value, but also signal that they could not convert something (and this something has to be recursed into). I came up with this:
type ADataT = AData -> Maybe AData

extADT :: forall a b. (Data a, Data b) => ADataT -> (a -> b) -> ADataT
extADT at t a@(AData v) = case cast v of
Just x -> Just (AData (t x))
Nothing -> at a

doNothing :: ADataT
doNothing = const Nothing
ADataT is the type for such a transformer. doNothing will not transform anything, and extADT can be used to add any function to the list of tried transformers, in the spirit of extT. The ugly part To apply such a transformer, I want to use this function, which I ll describe in the code comments:
everywhereADT :: forall a b. (Data a, Data b) => ADataT -> a -> b

-- first check if we can transform this value already
everywhereADT f v = case f (AData v) of
-- if so, coerce it to the users requested type, which hopefully goes well
Just r -> fromADataE r
-- if not, we need to recurse into the data structure
Nothing -> recursed

-- for that, we first need to figure out the arguments to the
-- constructor. We store them in the untyped list
where args :: [AData]
(Const args) = gfoldl k z v
-- gfoldl lets us have a look at each argument. We wrap it in AData
-- and append it to the list
k (Const args) arg = Const (AData arg : args)
z start = Const []

-- We need the data constructor of the input data type. If the user did not want
-- it to be transformed, it will be the same
c = toConstr v

-- To give better error messages, we make sure that the outmost type constructor
-- of the requested type actually has the data constructor we were given. Otherwise
-- gunfold will complain in a non-helpful way
input_type = dataTypeRep (constrType c)
output_type = dataTypeRep (dataTypeOf (undefined :: b))

recursed = if input_type /= output_type
then error $ "Can not convert <" ++ show input_type ++ ">"++
" to <" ++ show output_type ++ ">."
-- the types match, so we assemble the output type, using gunfold
else snd (gunfold k' z' c)
k' :: forall b r . Data b => ([AData], b -> r) -> ([AData],r)

-- we start by reversing the input list
z' start = (reverse args,start)

-- then we call us recursively on the argument and feed the result
-- to the output constructor
k' ((AData a) : args, append) = (args, append (everywhereADT f a))

-- Used for folding (we don t need to retain the original constructor)
data Const a b = Const a
What a beast! But surprisingly, it works. Here are some examples. Note that I always have to specify the requested output type:
bool2Int :: Bool -> Int
bool2Int False = 0
bool2Int True = 1

*Main> everywhereADT (doNothing extADT bool2Int) True :: Int
1
*Main> everywhereADT (doNothing extADT bool2Int) True :: ()
*** Exception: Type error, trying to convert Int to ().
*Main> everywhereADT (doNothing extADT bool2Int) (True,False) :: (Int,Int)
(1,0)
*Main> everywhereADT (doNothing extADT bool2Int) ([True,False],True,()) :: ([Int],Int,())
([1,0],1,())
*Main> everywhereADT (doNothing extADT bool2Int) ([True,False],True,()) :: [()]
*** Exception: Can not convert to .
*Main> everywhereADT (doNothing extADT bool2Int) [True] :: [Bool]
[*** Exception: Type error, trying to convert Int to Bool.
I hope this code does not inflict too much pain on any Haskell-loving reader. I know I violated the language, but I didn t know how to do it better (at least not without using Template Haskell). I also know that this is not very good performance wide: Every single value in the input will be deconstructed, type-compared several times and re-assembled. If that is an issue, then this function should only be used for prototyping. Almost done To apply this to our state, we only need to glue it to our lookup functions from above:
gunref :: (Data (a Id), Data (a Ref)) =>  State Ref -> a Ref -> a Id
gunref s w = let unrefState = gunref' unrefState s
in gunref' unrefState w

gunref' :: (Data (a Id), Data (a Ref)) => State Id -> a Ref -> a Id
gunref' unrefState = everywhereADT unref'
where unref' = doNothing extADT
unrefUserRef unrefState extADT
unrefComputerRef unrefState
Now we have a generic unreferencer. I set the type a bit more specific than necessary, to make it safe to use (under the assumption that the list of lookup functions is complete and will not leave any Ref in the output).
*Main> testState 
State [User userId = 0, uses = [Ref 1] ] [Computer computerId = 1, owner = Ref 0 ]
*Main> gunref testState testState
State [User userId = 0, uses = [Id (Computer computerId = 1, owner = Id (User userId = 0,
uses = [Id (Computer computerId = 1, owner = Id (User userId = 0, uses = ..
Oh, and by the way, if you want to test this code, you ll need at least:
 -# LANGUAGE DeriveDataTypeable, FlexibleInstances, GADTs,
FlexibleContexts, StandaloneDeriving, ScopedTypeVariables #-

Romain Beauxis: Fun with liquidsoap and video..

The other day, I wanted to prepare some videos of my favorite reggae and soul tunes for uploading them to YouTube.. My goal was very simple: prepare a video with a static image and the music I wanted to upload.. After briefly digging for a simple software to do that, which I could not found, I said "hey, why not doing it with liquidsoap !". Well, that is fairly easy ! Video support in liquidsoap is very young, but the amount of things that can be done is already quite important, so I though this would be an interesting example.. All you have to do is to prepare a PPN version of the picture, using convert /path/to/image.jpeg /path/to/image.ppn and have the mp3 or ogg file in an other place... From the scripting point of view, the only difficult thing is to have liquidsoap stop at the end of the song.. As liquidsoap is mainly a streaming language, it is not designed to be able to stop easily. It should be made better soon, but for now I had to use a special trick: compose sequentially the song with a blank source. On the blank source, I add special metadata such that the output file is reopened with a new title when the song has ended. Eventually, the shutdown is triggered when adding the new metadata on the blank source. Here is the code:
# Log to stdout
set("log.file",false)
set("log.stdout",true)
# Disable real-time processing, to process with the maximun speed
set("root.sync",false)
# Enable video
set("frame.video.channels",1)

# The video source using a static image
s = video.image(width=240,height=240,x=40,"/tmp/bla.ppm")
# The audio song.
audio = single("/tmp/bla.mp3")
# The special metadata function, that
# also triggers the shutdown..
def end_meta(_) =
shutdown ()
[("title","prout")]
end
# This is the blank source
bl = map_metadata(insert_missing=true,update=false,end_meta,blank())
# And the final source: the sequence song and blank added
# with the video of the static image..
final = add([sequence([audio,bl]),s])
# Output to a theora file, reopen on new metadata..
output.file.theora(reopen_on_metadata=true,"/tmp/$(title).ogv",
final)
The result is just what I wanted (surprisingly !): The other videos can be found here.

30 December 2008

David Moreno: Introducing Feedbag: Feed auto-discovery Ruby library/tool

Last week, I spent some time building a good (that I liked) feed auto-discovery tool to use in Ruby for other project I m building, rFeed. I liked CPAN s Feed::Find, and at some point I made a wrapper class to run a Perl script using such module, however, I wasn t happy by mixing it all. So, Feedbag was born:
>> require "rubygems"
=> true
>> require "feedbag"
=> true
>> Feedbag.find "log.damog.net"
=> ["http://feeds.feedburner.com/TeoremaDelCerdoInfinito",
 "http://log.damog.net/comments/feed/"]
>> planet_feeds = Feedbag.find("planet.debian.org")
[ ... ]
>> planet_feeds.first(3)
=> ["http://planet.debian.org/rss10.xml",
 "http://planet.debian.org/rss20.xml",
 "http://planet.debian.org/atom.xml"]
>> planet_feeds.size
=> 104
>>
It makes smart use of relative and absolute bases, hrefs, links, content types, etc. It is also a single Ruby file, so you can grab it and use it on your application. Plus, it only requires Hpricot as dependency. It can find all feeds linked on a web page, but it will return the most important at the beginning of the resulting array, so you will have the important one on the first results (see example above with Planet Debian). Synopsis, README and a brief tutorial have been placed at axiombox.com/feedbag. You can also take a look at the git repo, hosted in GitHub.

Neil Williams: Comparing Packages files

Something that's bothered me and Emdebian in general for months is that it should be simple to compare two repositories and work out which packages need to migrate, which are behind etc. using perl. apt-cross has had rough support for this for some time but it isn't general - it relies on the apt perl bindings.

Recently, the shell scripts for Emdebian Grip became too complex to maintain long term - and far too slow. The main reason was the difficulty in getting all the relevant repository data into memory within a shell scripts. So, I turned to perl and the result is the tenth package to be derived from emdebian-tools source: libdebian-packages-compare-perl - Debian::Packages::Compare - emdebian repository comparison support. So far, it is meant to run on the server because various elements of meta-data need to be read from the repository configuration and that means relying on reprepro. In time, I hope to extend it so that this meta-data can be set arbitrarily so that the module only requires a pair of Packages files - at which point it can be extended to handle a Packages.gz file too (it already looks for and handles the Sources.gz file). The module includes bespoke handling for Emdebian TDebs and the locale root layout.

It reads the Packages file, create a hash of Package and version - once per arch, one per suite, one pair per repo. The underlying libparse-debian-packages-perl is a very simple module, there probably isn't any point putting extra data into the comparison hashes, get the data necessary and load the full Packages data separately using get_single_package.

This module is currently tied to the repository layout used by reprepro in order to identify the architecture list and various other pieces of meta-data. In time, functions can be added to provide such lists.

The module expects to find all repositories beneath a single base directory:

$base/$repo_name/conf/distributions

If $base is undefined or if the repository directories cannot be found, subsequent functions each return undef.

etc.

Example code:

use Debian::Packages::Compare;

my $base = '/path/to/repositories/'
&set_base($base);

my $debu = &read_packages ('unstable', 'filter');
my $gripu = &read_packages ('unstable', 'grip');
my %debianunstable = %$debu if (defined $debu);
my %gripunstable = %$gripu if (defined $gripu);
foreach my $pkg (sort keys %debianunstable)

if ($debianunstable $pkg 'source' ne $gripunstable $pkg 'source' )

# $pkg is either not in grip repository or is a different version


The main features for subsequent versions will involve more verbose error handling.

Currently just in Emdebian SVN, I'll be releasing to Emdebian fairly soon. If there's interest, I could put it into experimental but I think it needs that meta-data handling code first.

Debian::Packages::Compare.pm.

Next.

Previous.