Search Results: "will"

31 July 2025

Matthew Garrett: Secure boot certificate rollover is real but probably won't hurt you

LWN wrote an article which opens with the assertion "Linux users who have Secure Boot enabled on their systems knowingly or unknowingly rely on a key from Microsoft that is set to expire in September". This is, depending on interpretation, either misleading or just plain wrong, but also there's not a good source of truth here, so.

First, how does secure boot signing work? Every system that supports UEFI secure boot ships with a set of trusted certificates in a database called "db". Any binary signed with a chain of certificates that chains to a root in db is trusted, unless either the binary (via hash) or an intermediate certificate is added to "dbx", a separate database of things whose trust has been revoked[1]. But, in general, the firmware doesn't care about the intermediate or the number of intermediates or whatever - as long as there's a valid chain back to a certificate that's in db, it's going to be happy.

That's the conceptual version. What about the real world one? Most x86 systems that implement UEFI secure boot have at least two root certificates in db - one called "Microsoft Windows Production PCA 2011", and one called "Microsoft Corporation UEFI CA 2011". The former is the root of a chain used to sign the Windows bootloader, and the latter is the root used to sign, well, everything else.

What is "everything else"? For people in the Linux ecosystem, the most obvious thing is the Shim bootloader that's used to bridge between the Microsoft root of trust and a given Linux distribution's root of trust[2]. But that's not the only third party code executed in the UEFI environment. Graphics cards, network cards, RAID and iSCSI cards and so on all tend to have their own unique initialisation process, and need board-specific drivers. Even if you added support for everything on the market to your system firmware, a system built last year wouldn't know how to drive a graphics card released this year. Cards need to provide their own drivers, and these drivers are stored in flash on the card so they can be updated. But since UEFI doesn't have any sandboxing environment, those drivers could do pretty much anything they wanted to. Someone could compromise the UEFI secure boot chain by just plugging in a card with a malicious driver on it, and have that hotpatch the bootloader and introduce a backdoor into your kernel.

This is avoided by enforcing secure boot for these drivers as well. Every plug-in card that carries its own driver has it signed by Microsoft, and up until now that's been a certificate chain going back to the same "Microsoft Corporation UEFI CA 2011" certificate used in signing Shim. This is important for reasons we'll get to.

The "Microsoft Windows Production PCA 2011" certificate expires in October 2026, and the "Microsoft Corporation UEFI CA 2011" one in June 2026. These dates are not that far in the future! Most of you have probably at some point tried to visit a website and got an error message telling you that the site's certificate had expired and that it's no longer trusted, and so it's natural to assume that the outcome of time's arrow marching past those expiry dates would be that systems will stop booting. Thankfully, that's not what's going to happen.

First up: if you grab a copy of the Shim currently shipped in Fedora and extract the certificates from it, you'll learn it's not directly signed with the "Microsoft Corporation UEFI CA 2011" certificate. Instead, it's signed with a "Microsoft Windows UEFI Driver Publisher" certificate that chains to the "Microsoft Corporation UEFI CA 2011" certificate. That's not unusual, intermediates are commonly used and rotated. But if we look more closely at that certificate, we learn that it was issued in 2023 and expired in 2024. Older versions of Shim were signed with older intermediates. A very large number of Linux systems are already booting certificates that have expired, and yet things keep working. Why?

Let's talk about time. In the ways we care about in this discussion, time is a social construct rather than a meaningful reality. There's no way for a computer to observe the state of the universe and know what time it is - it needs to be told. It has no idea whether that time is accurate or an elaborate fiction, and so it can't with any degree of certainty declare that a certificate is valid from an external frame of reference. The failure modes of getting this wrong are also extremely bad! If a system has a GPU that relies on an option ROM, and if you stop trusting the option ROM because either its certificate has genuinely expired or because your clock is wrong, you can't display any graphical output[3] and the user can't fix the clock and, well, crap.

The upshot is that nobody actually enforces these expiry dates - here's the reference code that disables it. In a year's time we'll have gone past the expiration date for "Microsoft Windows UEFI Driver Publisher" and everything will still be working, and a few months later "Microsoft Windows Production PCA 2011" will also expire and systems will keep booting Windows despite being signed with a now-expired certificate. This isn't a Y2K scenario where everything keeps working because people have done a huge amount of work - it's a situation where everything keeps working even if nobody does any work.

So, uh, what's the story here? Why is there any engineering effort going on at all? What's all this talk of new certificates? Why are there sensationalist pieces about how Linux is going to stop working on old computers or new computers or maybe all computers?

Microsoft will shortly start signing things with a new certificate that chains to a new root, and most systems don't trust that new root. System vendors are supplying updates[4] to their systems to add the new root to the set of trusted keys, and Microsoft has supplied a fallback that can be applied to all systems even without vendor support[5]. If something is signed purely with the new certificate then it won't boot on something that only trusts the old certificate (which shouldn't be a realistic scenario due to the above), but if something is signed purely with the old certificate then it won't boot on something that only trusts the new certificate.

How meaningful a risk is this? We don't have an explicit statement from Microsoft as yet as to what's going to happen here, but we expect that there'll be at least a period of time where Microsoft signs binaries with both the old and the new certificate, and in that case those objects should work just fine on both old and new computers. The problem arises if Microsoft stops signing things with the old certificate, at which point new releases will stop booting on systems that don't trust the new key (which, again, shouldn't happen). But even if that does turn out to be a problem, nothing is going to force Linux distributions to stop using existing Shims signed with the old certificate, and having a Shim signed with an old certificate does nothing to stop distributions signing new versions of grub and kernels. In an ideal world we have no reason to ever update Shim[6] and so we just keep on shipping one signed with two certs.

If there's a point in the future where Microsoft only signs with the new key, and if we were to somehow end up in a world where systems only trust the old key and not the new key[7], then those systems wouldn't boot with new graphics cards, wouldn't be able to run new versions of Windows, wouldn't be able to run any Linux distros that ship with a Shim signed only with the new certificate. That would be bad, but we have a mechanism to avoid it. On the other hand, systems that only trust the new certificate and not the old one would refuse to boot older Linux, wouldn't support old graphics cards, and also wouldn't boot old versions of Windows. Nobody wants that, and for the foreseeable future we're going to see new systems continue trusting the old certificate and old systems have updates that add the new certificate, and everything will just continue working exactly as it does now.

Conclusion: Outside some corner cases, the worst case is you might need to boot an old Linux to update your trusted keys to be able to install a new Linux, and no computer currently running Linux will break in any way whatsoever.

[1] (there's also a separate revocation mechanism called SBAT which I wrote about here, but it's not relevant in this scenario)

[2] Microsoft won't sign GPLed code for reasons I think are unreasonable, so having them sign grub was a non-starter, but also the point of Shim was to allow distributions to have something that doesn't change often and be able to sign their own bootloaders and kernels and so on without having to have Microsoft involved, which means grub and the kernel can be updated without having to ask Microsoft to sign anything and updates can be pushed without any additional delays

[3] It's been a long time since graphics cards booted directly into a state that provided any well-defined programming interface. Even back in 90s, cards didn't present VGA-compatible registers until card-specific code had been executed (hence DEC Alphas having an x86 emulator in their firmware to run the driver on the card). No driver? No video output.

[4] There's a UEFI-defined mechanism for updating the keys that doesn't require a full firmware update, and it'll work on all devices that use the same keys rather than being per-device

[5] Using the generic update without a vendor-specific update means it wouldn't be possible to issue further updates for the next key rollover, or any additional revocation updates, but I'm hoping to be retired by then and I hope all these computers will also be retired by then

[6] I said this in 2012 and it turned out to be wrong then so it's probably wrong now sorry, but at least SBAT means we can revoke vulnerable grubs without having to revoke Shim

[7] Which shouldn't happen! There's an update to add the new key that should work on all PCs, but there's always the chance of firmware bugs


comment count unavailable comments

Simon Josefsson: Independently Reproducible Git Bundles

The gnulib project publish a git bundle as a stable archival copy of the gnulib git repository once in a while. Why? We don t know exactly what this may be useful for, but I m promoting for this to see if we can establish some good use-case. A git bundle may help to establish provinence in case of an attack on the Savannah hosting platform that compromise the gnulib git repository. Another use is in the Debian gnulib package: that gnulib bundle is git cloned when building some Debian packages, to get to exactly the gnulib commit used by each upstream project see my talk on gnulib at Debconf24 and this approach reduces the amount of vendored code that is part of Debian s source code, which is relevant to mitigate XZ-style attacks. The first time we published the bundle, I wanted it to be possible to re-create it bit-by-bit identically by others. At the time I discovered a well-written blog post by Paul Beacher on reproducible git bundles and thought he had solved the problem for me. Essentially it boils down to disable threading during compression when producing the bundle, and his final example show this results in a predictable bit-by-bit identical output:
$ for i in $(seq 1 100); do \
> git -c 'pack.threads=1' bundle create -q /tmp/bundle-$i --all; \
> done
$ md5sum /tmp/bundle-*   cut -f 1 -d ' '   uniq -c
    100 4898971d4d3b8ddd59022d28c467ffca
So what remains to be said about this? It seems reproducability goes deeper than that. One desirable property is that someone else should be able to reproduce the same git bundle, and not only that a single individual is able to reproduce things on one machine. It surprised me to see that when I ran the same set of commands on a different machine (started from a fresh git clone), I got a different checksum. The different checksums occured even when nothing had been committed on the server side between the two runs. I thought the reason had to do with other sources of unpredictable data, and I explored several ways to work around this but eventually gave up. I settled for the following sequence of commands:
REV=ac9dd0041307b1d3a68d26bf73567aa61222df54 # master branch commit to package
git clone https://git.savannah.gnu.org/git/gnulib.git
cd gnulib
git fsck # attempt to validate input
# inspect that the new tree matches a trusted copy
git checkout -B master $REV # put $REV at master
for b in $(git branch -r   grep origin/stable-   sort --version-sort); do git checkout $ b#origin/ ; done
git remote remove origin # drop some unrelated branches
git gc --prune=now # drop any commits after $REV
git -c 'pack.threads=1' bundle create gnulib.bundle --all
V=$(env TZ=UTC0 git show -s --date=format:%Y%m%d --pretty=%cd master)
mv gnulib.bundle gnulib-$V.bundle
build-aux/gnupload --to ftp.gnu.org:gnulib gnulib-$V.bundle
At the time it felt more important to publish something than to reach for perfection, so we did so using the above snippet. Afterwards I reached out to the git community on this and there were good discussion about my challenge. At the end of that thread you see that I was finally able to reproduce a bit-by-bit identical bundles from two different clones, by using an intermediate git -c pack.threads=1 repack -adF step. I now assume that the unpredictable data I got earlier was introduced during the git clone steps, compressing the pack differently each time due to threaded compression. The outcome could also depend on what content the server provided, so if someone ran git gc, git repack on the server side things would change for the user, even if the user forced threading to 1 during cloning more experiments on what kind of server-side alterations results in client-side differences would be good research. A couple of months passed and it is now time to publish another gnulib bundle somewhat paired to the bi-yearly stable gnulib branches so let s walk through the commands and explain what they do. First clone the repository:
REV=225973a89f50c2b494ad947399425182dd42618c   # master branch commit to package
S1REV=475dd38289d33270d0080085084bf687ad77c74d # stable-202501 branch commit
S2REV=e8cc0791e6bb0814cf4e88395c06d5e06655d8b5 # stable-202507 branch commit
git clone https://git.savannah.gnu.org/git/gnulib.git
cd gnulib
git fsck # attempt to validate input
I believe the git fsck will validate that the chain of SHA1 commits are linked together, preventing someone from smuggling in unrelated commits earlier in the history without having to do SHA1 collision. SHA1 collisions are economically feasible today, so this isn t much of a guarantee of anything though.
git checkout -B master $REV # put $REV at master
# Add all stable-* branches locally:
for b in $(git branch -r   grep origin/stable-   sort --version-sort); do git checkout $ b#origin/ ; done
git checkout -B stable-202501 $S1REV
git checkout -B stable-202507 $S2REV
git remote remove origin # drop some unrelated branches
git gc --prune=now # drop any unrelated commits, not clear this helps
This establish a set of branches pinned to particular commits. The older stable-* branches are no longer updated, so they shouldn t be moving targets. In case they are modified in the future, the particular commit we used will be found in the official git bundle.
time git -c pack.threads=1 repack -adF
That s the new magic command to repack and recompress things in a hopefully more predictable way. This leads to a 72MB git pack under .git/objects/pack/ and a 62MB git bundle. The runtime on my laptop is around 5 minutes. I experimented with -c pack.compression=1 and -c pack.compression=9 but the size was roughly the same; 76MB and 66MB for level 1 and 72MB and 62MB for level 9. Runtime still around 5 minutes. Git uses zlib by default, which isn t the most optimal compression around. I tried -c pack.compression=0 and got a 163MB git pack and a 153MB git bundle. The runtime is still around 5 minutes, indicating that compression is not the bottleneck for the git repack command. That 153MB uncompressed git bundle compresses to 48MB with gzip default settings and 46MB with gzip -9; to 39MB with zst defaults and 34MB with zst -9; and to 28MB using xz defaults with a small 26MB using xz -9. Still the inconvenience of having to uncompress a 30-40MB archive into
the much larger 153MB is probably not worth the savings compared to
shipping and using the (still relatively modest) 62MB git bundle. Now finally prepare the bundle and ship it:
git -c 'pack.threads=1' bundle create gnulib.bundle --all
V=$(env TZ=UTC0 git show -s --date=format:%Y%m%d --pretty=%cd master)
mv gnulib.bundle gnulib-$V.bundle
build-aux/gnupload --to ftp.gnu.org:gnulib gnulib-$V.bundle
Yay! Another gnulib git bundle snapshot is available from
https://ftp.gnu.org/gnu/gnulib/. The essential part of the git repack command is the -F parameter. In the thread -f was suggested, which translates into the git pack-objects --no-reuse-delta parameter:
--no-reuse-delta
When creating a packed archive in a repository that has existing packs, the command reuses existing deltas. This sometimes results in a slightly suboptimal pack. This flag tells the command not to reuse existing deltas but compute them from scratch.
When reading the man page, I though that using -F which translates into --no-reuse-object would be slightly stronger:
--no-reuse-object
This flag tells the command not to reuse existing object data at all, including non deltified object, forcing recompression of everything. This implies --no-reuse-delta. Useful only in the obscure case where wholesale enforcement of a different compression level on the packed data is desired.
On the surface, without --no-reuse-objects, some amount of earlier compression could taint the final result. Still, I was able to get bit-by-bit identical bundles by using -f so possibly reaching for -F is not necessary. All the commands were done using git 2.51.0 as packaged by Guix. I fear the result may be different with other git versions and/or zlib libraries. I was able to reproduce the same bundle on a Trisquel 12 aramo (derived from Ubuntu 22.04) machine, which uses git 2.34.1. This suggests there is some chances of this being possible to reproduce in 20 years time. Time will tell. I also fear these commands may be insufficient if something is moving on the server-side of the git repository of gnulib (even just something simple as a new commit), I tried to make some experiments with this but let s aim for incremental progress here. At least I have now been able to reproduce the same bundle on different machines, which wasn t the case last time. Happy Reproducible Git Bundle Hacking!

Michael Ablassmeier: libvirt - incremental backups for raw devices

Skimming through the latest libvirt releases, to my surprise, i found that latest versions (>= v10.10.0) have added support for the QCOW data-file setting. Usually the incremental backup feature using bitmaps was limited to qcow2 based images, as there was no way to store the bitmaps persistently within raw devices. This basically ruled out proper incremental backups for direct attached luns, etc. In the past, there were some discussions how to implement this, mostly by using a separate metadata qcow image, holding the bitmap information persistently. These approaches have been discussed again lately and required features were implemented In order to be able to use the feature, you need to configure the virtual machines and its disks in a special way: Lets assume you have a virtual machine that uses a raw device /tmp/datafile.raw 1) Create an qcow image (same size as the raw image):
 # point the data-file to a temporary file, as create will overwrite whatever it finds here
 qemu-img create -f qcow2 /tmp/metadata.qcow2 -o data_file=/tmp/TEMPFILE,data_file_raw=true ..
 rm -f /tmp/TEMPFILE
2) Now use the amend option to point the qcow image to the right raw device using the data-file option:
 qemu-img amend /tmp/metadata.qcow2 -o data_file=/tmp/datafile.raw,data_file_raw=true
3) Reconfigure the virtual machine configuration to look like this:
    <disk type='file' device='disk'>
      <driver name='qemu' type='qcow2' cache='none' io='native' discard='unmap'/>
      <source file='/tmp/metadata.qcow2'>
        <dataStore type='file'>
          <format type='raw'/>
          <source file='/tmp/datafile.raw'/>
        </dataStore>
      </source>
      <target dev='vda' bus='virtio'/>
    </disk>
Now its possible to create persistent checkpoints:
 virsh checkpoint-create-as vm6 --name test --diskspec vda,bitmap=test
 Domain checkpoint test created
and the persistent bitmap will be stored within the metadata image:
 qemu-img info  /tmp/tmp.16TRBzeeQn/vm6-sda.qcow2
 [..]
    bitmaps:
        [0]:
            flags:
                [0]: auto
            name: test
            granularity: 65536
Hoooray. Added support for this in virtnbdbackup v2.33

30 July 2025

Utkarsh Gupta: FOSS Activites in July 2025

Here s my 70th monthly but brief update about the activities I ve done in the F/L/OSS world.

Debian
This was my 79th month of actively contributing to Debian. I became a DM in late March 2019 and a DD on Christmas 19! \o/ Debian was in freeze throughout so whilst I didn t do many uploads, there s a bunch of other things I did:
  • Attended DebConf25 in Brest, France.
    • Lead the bursary BOF and discussions.
    • Participated in other sessions, especially around the FTP masters.
    • I ve started to look at things with my trainee hat on.
    • Participated in the Debian Security Tracker sprints during DebCamp. More on that below.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
This was my 54th month of actively contributing to Ubuntu. I joined Canonical to work on Ubuntu full-time back in February 2021. Whilst I can t give a full, detailed list of things I did (there s so much and some of it might not be public yet!), here s a quick TL;DR of what I did:
  • Released Questing snapshot 3! \o/
  • EOL d Oracular. o/
  • Participated in the mid-cycle sprints.
  • Got a recognition award for leading 24.04.2 LTS release and leading the Release Management team.
  • Preparing for the 24.04.3 LTS release early next month.

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the stretch and jessie release (+2 years after LTS support). This was my 70th month as a Debian LTS and 57th month as a Debian ELTS paid contributor.
I only worked for 15.00 hours for LTS and 5.00 hours for ELTS and did the following things:
  • [LTS] Released DLA 4263-1 for ruby-graphql.
    • Coordinated with upstream due to lack of clarity on 1.11.4 being affected & not having a clear reproducer.
    • As 1.11.4 was still partially vulnerable and the backport was non-trivial, it was probably conveinent to bump the upstream version to 1.11.12 instead, fixing:
    • CVE-2025-27407): a remote code execution.
    • Salsa repository: https://salsa.debian.org/lts-team/packages/ruby-graphql.
    • Coordinated with the Security team for a p-u fix or a DSA.
  • [E/LTS] Frontdesk duty from 28th July to 04th August.
  • [LTS] Attended the monthly LTS meeting on IRC. Summary here.

Debian Security Tracker sprint 2025 Thanks to the LTS team for also organizing a security tracker sprint during DebCamp25. I attended the sprint and spent 10 hours working on the following tasks: That s all. A quicky shoutout to Roberto for organizing the sprints remotely and being awake at odd hours. <3
Until next time.
:wq for today.

29 July 2025

Ravi Dwivedi: How to paste your password on your bank's website

If your bank is like mine, its website doesn t allow you to copy your password and paste it by performing a simple Ctrl+V. I tried the Don t Fuck With Paste extension in Firefox, which could paste my bank account s profile password but not the login password. Therefore, I asked on Mastodon a couple of days ago and got some responses. The solution that worked for me was to use Shift+Insert to paste the password. It worked for me in LibreWolf and Firefox, and that s all I needed. Furthermore, this behavior by bank websites leads to users choosing insecure and memorable passwords. Using this trick will help you choose strong passwords for your bank account. I prefer to use random and strong passwords generated using the password manager pass. It is a freedom-respecting software, unlike popular proprietary password managers promoted by YouTubers. Feel free to check out their webpage here. The reason I use pass is that it stores all the passwords locally (and optionally in a remote Git repository) in encrypted form, which can only be decrypted using your private GPG keys.

Christoph Berg: The Debian Conference 2025 in Brest

It's Sunday and I'm now sitting in the train from Brest to Paris where I will be changing to Germany, on the way back from the annual Debian conference. A full week of presentations, discussions, talks and socializing is laying behind me and my head is still spinning from the intensity.
Pollito and the gang of DebConf mascots wearing their conference badgesPollito and the gang of DebConf mascots wearing their conference badges (photo: Christoph Berg)
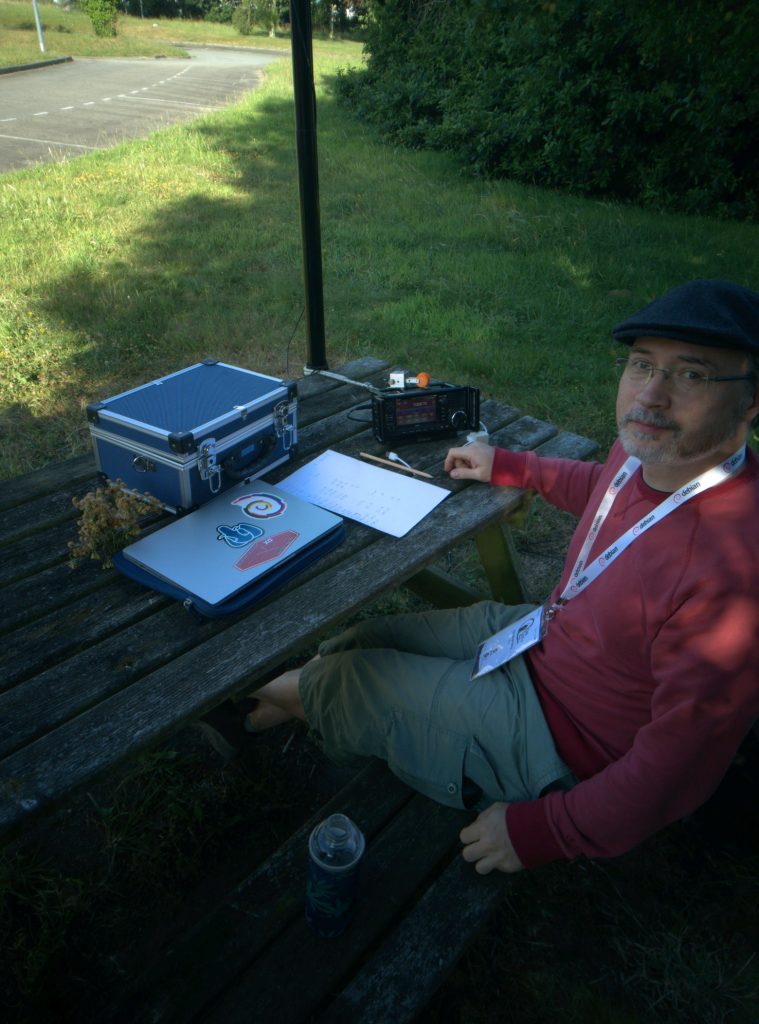
Sunday, July 13th It started last Sunday with traveling to the conference. I got on the Eurostar in Duisburg and we left on time, but even before reaching Cologne, the train was already one hour delayed for external reasons, collecting yet another hour between Aachen and Liege for its own technical problems. "The train driver is working on trying to fix the problem." My original schedule had well over two hours for changing train stations in Paris, but being that late, I missed the connection to Brest in Montparnasse. At least in the end, the total delay was only one hour when finally arriving at the destination. Due to the French julliet quatorze fireworks approaching, buses in Brest were rerouted, but I managed to catch the right bus to the conference venue, already meeting a few Debian people on the way. The conference was hosted at the IMT Atlantique Brest campus, giving the event a nice university touch. I arrived shortly after 10 in the evening and after settling down a bit, got on one of the "magic" buses for transportation to the camping site where half of the attendees where stationed. I shared a mobile home with three other Debianites, where I got a small room for myself. Monday, July 14th Next morning, we took the bus back to the venue with a small breakfast and the opening session where Enrico Zini invited me to come to his and Nicolas Dandrimont's session about Debian community governance and curation, which I gladly did. Many ideas about conflict moderation and community steering were floated around. I hope some of that can be put into effect to make flamewars on the mailing lists less heated and more directed. After that, I attended Olly Betts' "Stemming with Snowball" session, which is the stemmer used also in PostgreSQL. Text search is one of the areas in PostgreSQL that I never really looked closely at, including the integration into the postgresql-common package, so it was nice to get more information about that. In preparation for the conference, a few of us Ham radio operators in Debian had decided to bring some radio gear to DebConf this year in order to perhaps spark more interest for our hobby among the fellow geeks. In the afternoon after the talks, I found a quieter spot just outside of the main hall and set up a shortwave antenna by attaching a 10m mast to one of the park benches there. The 40m band was still pretty much closed, but I could work a few stations from England, just across the channel from Bretagne, answering questions from interested passing-by Debian people between the contacts. Over time, the band opened and more European stations got into the log.
F/DF7CB in Brest (photo: Evangelos Ribeiro Tzaras)
Tuesday, July 15th Tuesday started with Helmut Grohne's session about "Reviving (un)schroot". The schroot program has been Debian's standard way of managing build chroots for a long time, but it is more and more being regarded as obsolete with all kinds of newer containerization and virtualization technologies taking over. Since many bits of Debian infrastructure depend on schroot, and its user interface is still very useful, Helmut reimplemented it using Linux namespaces and the "unshare" systemcall. I had already worked with him at the Hamburg Minidebconf to replace the apt.postgresql.org buildd machinery with the new system, but we were not quite there yet (network isolation is nice, but we still sometimes need proper networking), so it was nice to see the effort is still progressing and I will give his new scripts a try when I'm back home. Next, Stefano Rivera and Colin Watson presented Debusine, a new package repository and workflow management system. It looks very promising for anyone running their own repository, so perhaps yet another bit of apt.postgresql.org infrastructure to replace in the future. After that, I went to the Debian LTS BoF session by Santiago Ruano Rinc n and Bastien Roucari s - Debian releases plus LTS is what we are covering with apt.postgresql.org. Then there were bits from the DPL (Debian Project Leader), and a session moderated by Stefano Rivera interesting to me as a member of the Debian Technical Committee on the future structure of the packages required for cross-building in Debian, a topic which had been brought to TC a while ago. I am happy that we could resolve the issue without having to issue a formal TC ruling as the involved parties (kernel, glibc, gcc and the cross-build people) found a promising way forward themselves. DebConf is really a good way to get such issues unstuck. Ten years ago at the 2015 Heidelberg DebConf, Enrico had given a seminal "Semi-serious stand-up comedy" talk, drawing parallels between the Debian Open Source community and the BDSM community - "People doing things consensually together". (Back then, the talk was announced as "probably unsuitable for people of all ages".) With his unique presentation style and witty insights, the session made a lasting impression on everyone attending. Now, ten years later (and he and many in the audience being ten years older), he gave an updated version of it. We are now looking forward to the sequel in 2035. The evening closed with the famous DebConf tradition of the Cheese & Wine party in a old fort next to the coast, just below the conference venue. Even when he's a fellow Debian Developer, Ham and also TC member, I had never met Paul Tagliamonte in person before, but we spent most of the evening together geeking out on all things Debian and Ham radio.
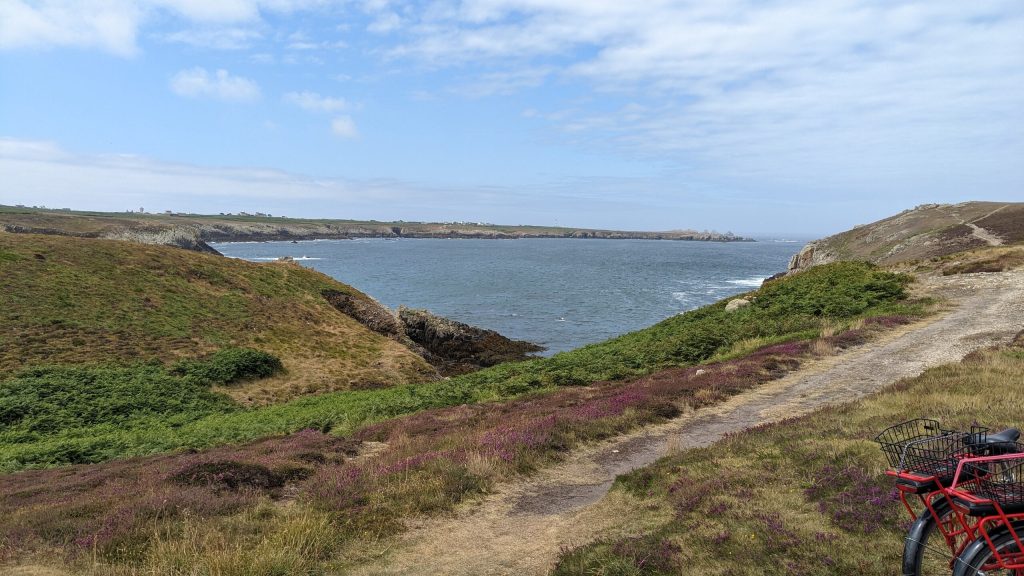
The northern coast of Ushant (photo: Christoph Berg)
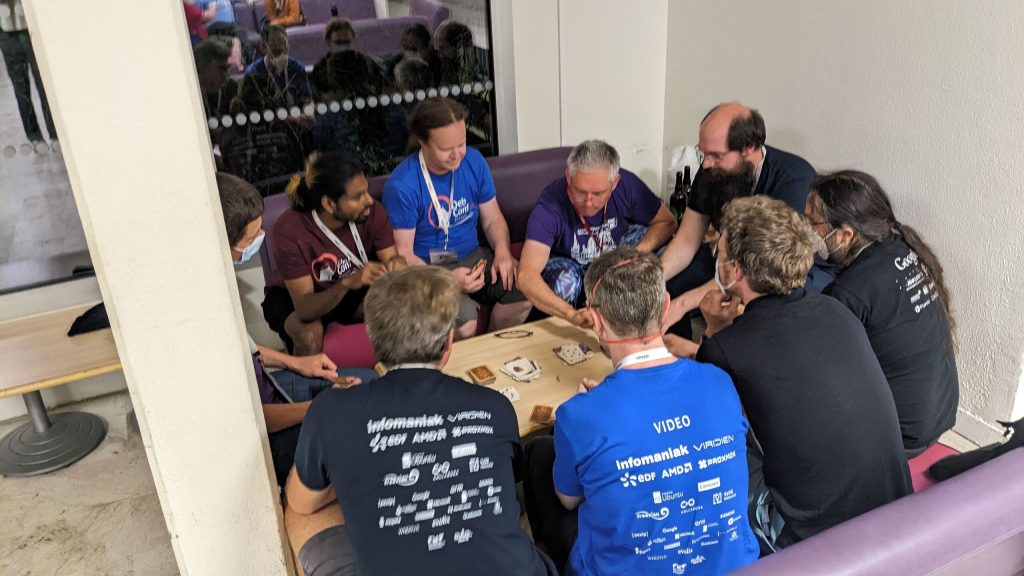
Wednesday, July 16th Wednesday already marked the end of the first half of the week, the day of the day trips. I had chosen to go to Ouessant island (Ushant in English) which marks the Western end of French mainland and hosts one of the lighthouses yielding the way into the English channel. The ferry trip included surprisingly big waves which left some participants seasick, but everyone recovered fast. After around one and a half hours we arrived, picked up the bicycles, and spent the rest of the day roaming the island. The weather forecast was originally very cloudy and 18 C, but over noon this turned into sunny and warm, so many got an unplanned sunburn. I enjoyed the trip very much - it made up for not having time visiting the city during the week. After returning, we spent the rest of the evening playing DebConf's standard game, Mao (spoiler alert: don't follow the link if you ever intend to play).
Having a nice day (photo: Christoph Berg)
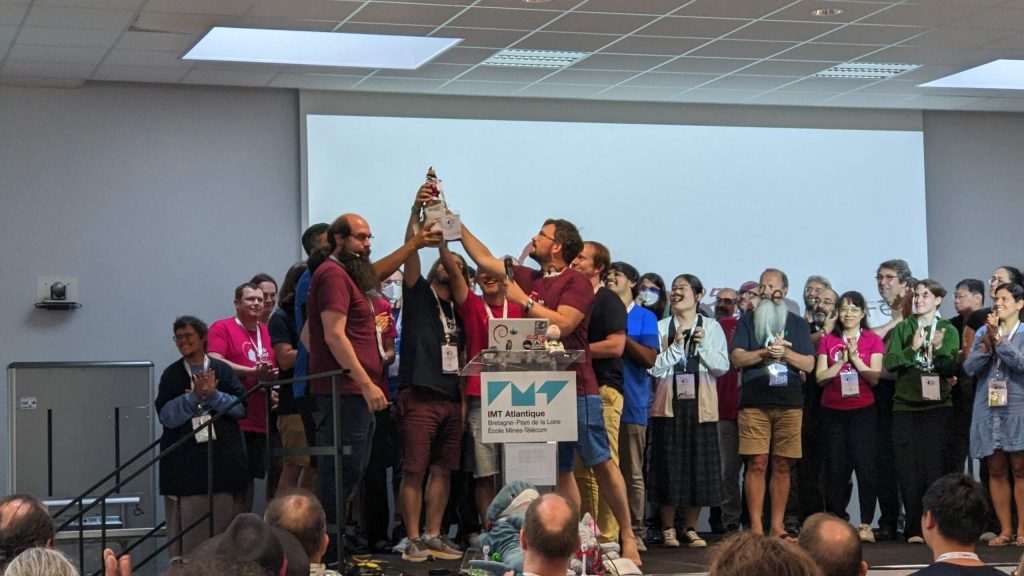
Thursday, July 17th The next day started with the traditional "Meet the Technical Committee" session. This year, we trimmed the usual slide deck down to remove the boring boilerplate parts, so after a very short introduction to the work of the committee by our chairman Matthew Vernon, we opened up the discussion with the audience, with seven (out of 8) TC members on stage. I think the format worked very well, with good input from attendees. Next up was "Don't fear the TPM" by Jonathan McDowell. A common misconception in the Free Software community is that the TPM is evil DRM hardware working against the user, but while it could be used in theory that way, the necessary TPM attestations seem to impossible to attain in practice, so that wouldn't happen anyway. Instead, it is a crypto coprocessor present in almost all modern computers that can be used to hold keys, for example to be used for SSH. It will also be interesting to research if we can make use of it for holding the Transparent Data Encryption keys for CYBERTEC's PostgreSQL Enterprise Edition. Aigars Mahinovs then directed everyone in place for the DebConf group picture, and Lucas Nussbaum started a discussion about archive-wide QA tasks in Debian, an area where I did a lot of work in the past and that still interests me. Antonio Terceiro and Paul Gevers followed up with techniques to track archive-wide rebuilding and testing of packages and in turn filing a lot of bugs to track the problems. The evening ended with the conference dinner, again in the fort close by the coast. DebConf is good for meeting new people, and I incidentally ran into another Chris, who happened to be one of the original maintainers of pgaccess, the pre-predecessor of today's pgadmin. I admit still missing this PostgreSQL frontend for its simplicity and ability to easily edit table data, but it disappeared around 2004. Friday, July 18th On Friday, I participated in discussion sessions around contributors.debian.org (PostgreSQL is planning to set up something similar) and the New Member process which I had helped to run and reform a decade or two ago. Agathe Porte (also a Ham radio operator, like so many others at the conference I had no idea of) then shared her work on rust-rewriting the slower parts of Lintian, the Debian package linter. Craig Small talked about "Free as in Bytes", the evolution of the Linux procps free command. Over the time and many kernel versions, the summary numbers printed became better and better, but there will probably never be a version that suits all use cases alike. Later over dinner, Craig (who is also a TC member) and I shared our experiences with these numbers and customers (not) understanding them. He pointed out that for PostgreSQL and looking at used memory in the presence of large shared memory buffers, USS (unique set size) and PSS (proportional set size) should be more realistic numbers than the standard RSS (resident set size) that the top utility is showing by default. Antonio Terceiro and Paul Gevers again joined to lead a session, now on ci.debian.net and autopkgtest, the test driver used for running tests on packages after then have been installed on a system. The PostgreSQL packages are heavily using this to make sure no regressions creep in even after builds have successfully completed and test re-runs are rescheduled periodically. The day ended with Bdale Garbee's electronics team BoF and Paul Tagliamonte and me setting up the radio station in the courtyard, again answering countless questions about ionospheric conditions and operating practice. Saturday, July 19th Saturday was the last conference day. In the first session, Nikos Tsipinakis and Federico Vaga from CERN announced that the LHC will be moving to Debian for the accelerator's frontend computers in their next "long shutdown" maintenance period in the next year. CentOS broke compatibility too often, and Debian trixie together with the extended LTS support will cover the time until the next long shutdown window in 2035, until when the computers should have all been replaced with newer processors covering higher x86_64 baseline versions. The audience was very delighted to hear that Debian is now also being used in this prestige project. Ben Hutchings then presented new Linux kernel features. Particularly interesting for me was the support for atomic writes spanning more than one filesystem block. When configured correctly, this would mean PostgreSQL didn't have to record full-page images in the WAL anymore, increasing throughput and performance. After that, the Debian ftp team discussed ways to improve review of new packages in the archive, and which of their processes could be relaxed with new US laws around Open Source and cryptography algorithms export. Emmanuel Arias led a session on Salsa CI, Debian's Gitlab instance and standard CI pipeline. (I think it's too slow, but the runners are not under their control.) Julian Klode then presented new features in APT, Debian's package manager. I like the new display format (and a tiny bit of that is also from me sending in wishlist bugs). In the last round of sessions this week, I then led the Ham radio BoF with an introduction into the hobby and how Debian can be used. Bdale mentioned that the sBitx family of SDR radios is natively running Debian, so stock packages can be used from the radio's touch display. We also briefly discussed his involvement in ARDC and the possibility to get grants from them for Ham radio projects. Finally, DebConf wrapped up with everyone gathering in the main auditorium and cheering the organizers for making the conference possible and passing Pollito, the DebConf mascot, to the next organizer team.
Pollito on stage (photo: Christoph Berg)
Sunday, July 20th Zoom back to the train: I made it through the Paris metro and I'm now on the Eurostar back to Germany. It has been an intense week with all the conference sessions and meeting all the people I had not seen so long. There are a lot of new ideas to follow up on both for my Debian and PostgreSQL work. Next year's DebConf will take place in Santa Fe, Argentina. I haven't yet decided if I will be going, but I can recommend the experience to everyone! The post The Debian Conference 2025 in Brest appeared first on CYBERTEC PostgreSQL Services & Support.

28 July 2025

Dimitri John Ledkov: Achieving actually full disk encryption of UEFI ESP at rest with TCG OPAL, FIPS, LUKS

Achieving full disk encryption using FIPS, TCG OPAL and LUKS to encrypt UEFI ESP on bare-metal and in VMs
Many security standards such as CIS and STIG require to protect information at rest. For example, NIST SP 800-53r5 SC-28 advocate to use cryptographic protection, offline storage and TPMs to enhance protection of information confidentiality and/or integrity.Traditionally to satisfy such controls on portable devices such as laptops one would utilize software based Full Disk Encryption - Mac OS X FileVault, Windows Bitlocker, Linux cryptsetup LUKS2. In cases when FIPS cryptography is required, additional burden would be placed onto these systems to operate their kernels in FIPS mode.Trusted Computing Group works on establishing many industry standards and specifications, which are widely adopted to improve safety and security of computing whilst keeping it easy to use. One of their most famous specifications them is TCG TPM 2.0 (Trusted Platform Module). TPMs are now widely available on most devices and help to protect secret keys and attest systems. For example, most software full disk encryption solutions can utilise TCG TPM to store full disk encryption keys providing passwordless, biometric or pin-base ways to unlock the drives as well as attesting that system have not been modified or compromised whilst offline.TCG Storage Security Subsystem Class: Opal Specification is a set of specifications for features of data storage devices. The authors and contributors to OPAL are leading and well trusted storage manufacturers such as Samsung, Western Digital, Seagate Technologies, Dell, Google, Lenovo, IBM, Kioxia, among others. One of the features that Opal Specification enables is self-encrypting drives which becomes very powerful when combined with pre-boot authentication. Out of the box, such drives always and transparently encrypt all disk data using hardware acceleration. To protect data one can enter UEFI firmware setup (BIOS) to set NVMe single user password (or user + administrator/recovery passwords) to encrypt the disk encryption key. If one's firmware didn't come with such features, one can also use SEDutil to inspect and configure all of this. Latest release of major Linux distributions have SEDutil already packaged.Once password is set, on startup, pre-boot authentication will request one to enter password - prior to booting any operating systems. It means that full disk is actually encrypted, including the UEFI ESP and all operating systems that are installed in case of dual or multi-boot installations. This also prevents tampering with ESP, UEFI bootloaders and kernels which with traditional software-based encryption often remain unencrypted and accessible. It also means one doesn't have to do special OS level repartitioning, or installation steps to ensure all data is encrypted at rest.What about FIPS compliance? Well, the good news is that majority of the OPAL compliant hard drives and/or security sub-chips do have FIPS 140-3 certification. Meaning they have been tested by independent laboratories to ensure they do in-fact encrypt data. On the CMVP website one can search for module name terms "OPAL" or "NVMe" or name of hardware vendor to locate FIPS certificates.Are such drives widely available? Yes. For example, a common Thinkpad X1 gen 11 has OPAL NVMe drives as standard, and they have FIPS certification too. Thus, it is likely in your hardware fleet these are already widely available. Use sedutil to check if MediaEncrypt and LockingSupported features are available.Well, this is great for laptops and physical servers, but you may ask - what about public or private cloud? Actually, more or less the same is already in-place in both. On CVMP website all major clouds have their disk encryption hardware certified, and all of them always encrypt all Virtual Machines with FIPS certified cryptography without an ability to opt-out. One is however in full control of how the encryption keys are managed: cloud-provider or self-managed (either with a cloud HSM or KMS or bring your own / external). See these relevant encryption options and key management docs for GCP, Azure, AWS. But the key takeaway without doing anything, at rest, VMs in public cloud are always encrypted and satisfy NIST SP 800-53 controls.What about private cloud? Most Linux based private clouds ultimately use qemu typically with qcow2 virtual disk images. Qemu supports user-space encryption of qcow2 disk, see this manpage. Such encryption encrypts the full virtual machine disk, including the bootloader and ESP. And it is handled entirely outside of the VM on the host - meaning the VM never has access to the disk encryption keys. Qemu implements this encryption entirely in userspace using gnutls, nettle, libgcrypt depending on how it was compiled. This also means one can satisfy FIPS requirements entirely in userspace without a Linux kernel in FIPS mode. Higher level APIs built on top of qemu also support qcow2 disk encryption, as in projects such as libvirt and OpenStack Cinder.If you carefully read the docs, you may notice that agent support is explicitly sometimes called out as not supported or not mentioned. Quite often agents running inside the OS may not have enough observability to them to assess if there is external encryption. It does mean that monitoring above encryption options require different approaches - for example monitor your cloud configuration using tools such as Wiz and Orca, rather than using agents inside individual VMs. For laptop / endpoint security agents, I do wish they would start gaining capability to report OPAL SED availability and status if it is active or not.What about using software encryption none-the-less on top of the above solutions? It is commonly referred to double or multiple encryption. There will be an additional performance impact, but it can be worthwhile. It really depends on what you define as data at rest for yourself and which controls you need. If one has a dual-boot laptop, and wants to keep one OS encrypted whilst booted into the other, it can perfectly reasonable to encrypted the two using separate software encryption keys. In addition to the OPAL encryption of the ESP. For more targeted per-file / per-folder encryption, one can look into using gocryptfs which is the best successor to the once popular, but now deprecated eCryptfs (amazing tool, but has fallen behind in development and can lead to data loss).All of the above mostly talks about cryptographic encryption, which only provides confidentially but not data integrity. To protect integrity, one needs to choose how to maintain that. dm-verity is a good choice for read-only and rigid installations. For read-write workloads, it may be easier to deploy ZFS or Btrfs instead. If one is using filesystems without a built-in integrity support such as XFS or Ext4, one can retrofit integrity layer to them by using dm-integrity (either standalone, or via dm-luks/cryptsetup --integrity option).

If one has a lot of estate and a lot of encryption keys to keep track off a key management solution is likely needed. The most popular solution is likely the one from Thales Group marketed under ChiperTrust Data Security Platform (previously Vormetric), but there are many others including OEM / Vendor / Hardware / Cloud specific or agnostic solutions.

I hope this crash course guide piques your interest to learn and discover modern confidentially and integrity solutions, and to re-affirm or change your existing controls w.r.t. to data protection at rest.

Full disk encryption, including UEFI ESP /boot/efi is now widely achievable by default on both baremetal machines and in VMs including with FIPS certification. To discuss more let's connect on Linkedin.

Russ Allbery: Review: Cyteen

Review: Cyteen, by C.J. Cherryh
Series: Cyteen #1
Publisher: Warner Aspect
Copyright: 1988
Printing: September 1995
ISBN: 0-446-67127-4
Format: Trade paperback
Pages: 680
The main text below is an edited version of my original review of Cyteen written on 2012-01-03. Additional comments from my re-read are after the original review. I've reviewed several other C.J. Cherryh books somewhat negatively, which might give the impression I'm not a fan. That is an artifact of when I started reviewing. I first discovered Cherryh with Cyteen some 20 years ago, and it remains one of my favorite SF novels of all time. After finishing my reading for 2011, I was casting about for what to start next, saw Cyteen on my parents' shelves, and decided it was past time for my third reading, particularly given the recent release of a sequel, Regenesis. Cyteen is set in Cherryh's Alliance-Union universe following the Company Wars. It references several other books in that universe, most notably Forty Thousand in Gehenna but also Downbelow Station and others. It also has mentions of the Compact Space series (The Pride of Chanur and sequels). More generally, almost all of Cherryh's writing is loosely tied together by an overarching future history. One does not need to read any of those other books before reading Cyteen; this book will fill you in on all of the politics and history you need to know. I read Cyteen first and have never felt the lack. Cyteen was at one time split into three books for publishing reasons: The Betrayal, The Rebirth, and The Vindication. This is an awful way to think of the book. There are no internal pauses or reasonable volume breaks; Cyteen is a single coherent novel, and Cherryh has requested that it never be broken up that way again. If you happen to find all three portions as your reading copy, they contain all the same words and are serviceable if you remember it's a single novel under three covers, but I recommend against reading the portions in isolation. Human colonization of the galaxy started with slower-than-light travel sponsored by the private Sol Corporation. The inhabitants of the far-flung stations and the crews of the merchant ships that supplied them have formed their own separate cultures, but initially remained attached to Earth. That changed with the discovery of FTL travel and a botched attempt by Earth to reassert its authority. At the time of Cyteen, there are three human powers: distant Earth (which plays little role in this book), the merchanter Alliance, and Union. The planet Cyteen is one of only a few Earth-like worlds discovered by human expansion, and is the seat of government and the most powerful force in Union. This is primarily because of Reseune: the Cyteen lab that produces the azi. If Cyteen is about any one thing, it's about azi: genetically engineered human clones who are programmed via intensive psychological conditioning starting before birth. The conditioning uses a combination of drugs to make them receptive and "tape," specific patterns of instruction and sensory stimulation. They are designed for specific jobs or roles, they're conditioned to be obedient to regular humans, and they're not citizens. They are, in short, slaves. In a lot of books, that's as deep as the analysis would go. Azi are slaves, and slavery is certainly bad, so there would probably be a plot around azi overthrowing their conditioning, or around the protagonists trying to free them from servitude. But Cyteen is not any SF novel, and azi are considerably more complex and difficult than that analysis. We learn over the course of the book that the immensely powerful head of Reseune Labs, Ariane Emory, has a specific broader purpose in mind for the azi. One of the reasons why Reseune fought for and gained the role of legal protector of all azi in Union, regardless of where they were birthed, is so that Reseune could act to break any permanent dependence on azi as labor. And yet, they are slaves; one of the protagonists of Cyteen is an experimental azi, which makes him the permanent property of Reseune and puts him in constant jeopardy of being used as a political prisoner and lever of manipulation against those who care about him. Cyteen is a book about manipulation, about programming people, about what it means to have power over someone else's thoughts, and what one can do with that power. But it's also a book about connection and identity, about what makes up a personality, about what constitutes identity and how people construct the moral codes and values that they hold at their core. It's also a book about certainty. Azi are absolutely certain, and are capable of absolute trust, because that's part of their conditioning. Naturally-raised humans are not. This means humans can do things that azi can't, but the reverse is also true. The azi are not mindless slaves, nor are they mindlessly programmed, and several of the characters, both human and azi, find a lot of appeal in the core of certainty and deep self-knowledge of their own psychological rules that azis can have. Cyteen is a book about emotions, and logic, and where they come from and how to balance them. About whether emotional pain and uncertainty is beneficial or damaging, and about how one's experiences make up and alter one's identity. This is also a book about politics, both institutional and personal. It opens with Ariane Emory, Councilor for Science for five decades and the head of the ruling Union Expansionist party. She's powerful, brilliant, dangerously good at reading people, and dangerously willing to manipulate and control people for her own ends. What she wants, at the start of the book, is to completely clone a Special (the legal status given to the most brilliant minds of Union). This was attempted before and failed, but Ariane believes it's now possible, with a combination of tape, genetic engineering, and environmental control, to reproduce the brilliance of the original mind. To give Union another lifespan of work by their most brilliant thinkers. Jordan Warrick, another scientist at Reseune, has had a long-standing professional and personal feud with Ariane Emory. As the book opens, he is fighting to be transferred out from under her to the new research station that would be part of the Special cloning project, and he wants to bring his son Justin and Justin's companion azi Grant with them. Justin is a PR, a parental replicate, meaning he shares Jordan's genetic makeup but was not an attempt to reproduce the conditions of Jordan's rearing. Grant was raised as his brother. And both have, for reasons that are initially unclear, attracted the attention of Ariane, who may be using them as pawns. This is just the initial setup, and along with this should come a warning: the first 150 pages set up a very complex and dangerous political situation and build the tension that will carry the rest of the book, and they do this by, largely, torturing Justin and Grant. The viewpoint jumps around, but Justin and Grant are the primary protagonists for this first section of the book. While one feels sympathy for both of them, I have never, in my multiple readings of the book, particularly liked them. They're hard to like, as opposed to pity, during this setup; they have very little agency, are in way over their heads, are constantly making mistakes, and are essentially having their lives destroyed. Don't let this turn you off on the rest of the book. Cyteen takes a dramatic shift about 150 pages in. A new set of protagonists are introduced who are some of the most interesting, complex, and delightful protagonists in any SF novel I have read, and who are very much worth waiting for. While Justin has his moments later on (his life is so hard that his courage can be profoundly moving), it's not necessary to like him to love this book. That's one of the reasons why I so strongly dislike breaking it into three sections; that first section, which is mostly Justin and Grant, is not representative of the book. I can't talk too much more about the plot without risking spoiling it, but it's a beautiful, taut, and complex story that is full of my favorite things in both settings and protagonists. Cyteen is a book about brilliant people who think on their feet. Cherryh succeeds at showing this through what they do, which is rarely done as well as it is here. It's a book about remembering one's friends and remembering one's enemies, and waiting for the most effective moment to act, but it also achieves some remarkable transformations. About 150 pages in, you are likely to loathe almost everyone in Reseune; by the end of the book, you find yourself liking, or at least understanding, nearly everyone. This is extremely hard, and Cherryh pulls it off in most cases without even giving the people she's redeeming their own viewpoint sections. Other than perhaps George R.R. Martin I've not seen another author do this as well. And, more than anything else, Cyteen is a book with the most wonderful feeling of catharsis. I think this is one of the reasons why I adore this book and have difficulties with some of Cherryh's other works. She's always good at ramping up the tension and putting her characters in awful, untenable positions. Less frequently does she provide the emotional payoff of turning the tables, where you get to watch a protagonist do everything you've been wanting them to do for hundreds of pages, except even better and more delightfully than you would have come up with. Cyteen is one of the most emotionally satisfying books I've ever read. I could go on and on; there is just so much here that I love. Deep questions of ethics and self-control, presented in a way that one can see the consequences of both bad decisions and good ones and contrast them. Some of the best political negotiations in fiction. A wonderful look at friendship and loyalty from several directions. Two of the best semi-human protagonists I've seen, who one can see simultaneously as both wonderful friends and utterly non-human and who put nearly all of the androids in fiction to shame by being something trickier and more complex. A wonderful unfolding sense of power. A computer that can somewhat anticipate problems and somewhat can't, and that encapsulates much of what I love about semi-intelligent bases in science fiction. Cyteen has that rarest of properties of SF novels: Both the characters and the technology meld in a wonderful combination where neither could exist without the other, where the character issues are illuminated by the technology and the technology supports the characters. I have, for this book, two warnings. The first, as previously mentioned, is that the first 150 pages of setup is necessary but painful to read, and I never fully warmed to Justin and Grant throughout. I would not be surprised to hear that someone started this book but gave up on it after 50 or 100 pages. I do think it's worth sticking out the rocky beginning, though. Justin and Grant continue to be a little annoying, but there's so much other good stuff going on that it doesn't matter. The other warning is that part of the setup of the story involves the rape of an underage character. This is mostly off-camera, but the emotional consequences are significant (as they should be) and are frequently discussed throughout the book. There is also rather frank discussion of adolescent sexuality later in the book. I think both of these are relevant to the story and handled in a way that isn't gratuitous, but they made me uncomfortable and I don't have any past history with those topics. Those warnings notwithstanding, this is simply one of the best SF novels ever written. It uses technology to pose deep questions about human emotions, identity, and interactions, and it uses complex and interesting characters to take a close look at the impact of technology on lives. And it does this with a wonderfully taut, complicated plot that sustains its tension through all 680 pages, and with characters whom I absolutely love. I have no doubt that I'll be reading it for a fourth and fifth time some years down the road. Followed by Regenesis, although Cyteen stands well entirely on its own and there's no pressing need to read the sequel. Rating: 10 out of 10

Some additional thoughts after re-reading Cyteen in 2025: I touched on this briefly in my original review, but I was really struck during this re-read how much the azi are a commentary on and a complication of the role of androids in earlier science fiction. Asimov's Three Laws of Robotics were an attempt to control the risks of robots, but can also be read as turning robots into slaves. Azis make the slavery more explicit and disturbing by running the programming on a human biological platform, but they're more explicitly programmed and artificial than a lot of science fiction androids. Artificial beings and their relationship to humans have been a recurring theme of SF since Frankenstein, but I can't remember a novel that makes the comparison to humans this ambiguous and conflicted. The azi not only like being azi, they can describe why they prefer it. It's clear that Union made azi for many of the same reasons that humans enslave other humans, and that Ariane Emory is using them as machinery in a larger (and highly ethically questionable) plan, but Cherryh gets deeper into the emergent social complications and societal impact than most SF novels manage. Azi are apparently closer to humans than the famous SF examples such as Commander Data, but the deep differences are both more subtle and more profound. I've seen some reviewers who are disturbed by the lack of a clear moral stance by the protagonists against the creation of azi. I'm not sure what to think about that. It's clear the characters mostly like the society they've created, and the groups attempting to "free" azi from their "captivity" are portrayed as idiots who have no understanding of azi psychology. Emory says she doesn't want azi to be a permanent aspect of society but clearly has no intention of ending production any time soon. The book does seem oddly unaware that the production of azi is unethical per se and, unlike androids, has an obvious exit ramp: Continue cloning gene lines as needed to maintain a sufficient population for a growing industrial civilization, but raise the children as children rather than using azi programming. If Cherryh included some reason why that was infeasible, I didn't see it, and I don't think the characters directly confronted it. I don't think societies in books need to be ethical, or that Cherryh intended to defend this one. There are a lot of nasty moral traps that civilizations can fall into that make for interesting stories. But the lack of acknowledgment of the problem within the novel did seem odd this time around. The other part of this novel that was harder to read past in this re-read is the sexual ethics. There's a lot of adolescent sexuality in this book, and even apart from the rape scene which was more on-the-page than I had remembered and which is quite (intentionally) disturbing there is a whole lot of somewhat dubious consent. Maybe I've gotten older or just more discriminating, but it felt weirdly voyeuristic to know this much about the sex lives of characters who are, at several critical points in the story, just a bunch of kids. All that being said, and with the repeated warning that the first 150 pages of this novel are just not very good, there is still something magic about the last two-thirds of this book. It has competence porn featuring a precociously brilliant teenager who I really like, it has one of the more interesting non-AI programmed computer systems that I've read in SF, it has satisfying politics that feel like modern politics (media strategy and relationships and negotiated alliances, rather than brute force and ideology), and it has a truly excellent feeling of catharsis. The plot resolution is a bit too abrupt and a bit insufficiently explained (there's more in Regenesis), but even though this was my fourth time through this book, the pacing grabbed me again and I could barely put down the last part of the story. Ethics aside (and I realize that's quite the way to start a sentence), I find the azi stuff fascinating. I know the psychology in this book is not real and is hopelessly simplified compared to real psychology, but there's something in the discussions of value sets and flux and self-knowledge that grabs my interest and makes me want to ponder. I think it's the illusion of simplicity and control, the what-if premise of thought where core motivations and moral rules could be knowable instead of endlessly fluid the way they are in us humans. Cherryh's azi are some of the most intriguing androids in science fiction to me precisely because they don't start with computers and add the humanity in, but instead start with humanity and overlay a computer-like certainty of purpose that's fully self-aware. The result is more subtle and interesting than anything Star Trek managed. I was not quite as enamored with this book this time around, but it's still excellent once the story gets properly started. I still would recommend it, but I might add more warnings about the disturbing parts.

Re-read rating: 9 out of 10

26 July 2025

Bits from Debian: DebConf25 closes in Brest and DebConf26 announced

DebConf25 group photo - click to enlarge On Saturday 19 July 2025, the annual Debian Developers and Contributors Conference came to a close. Over 443 attendees representing 50 countries from around the world came together for a combined 169 events (including some which took place during the DebCamp) including more than 50 Talks, 39 Short Talks, 5 Discussions, 59 Birds of a Feather sessions ("BoF" informal meeting between developers and users), 10 workshops, and activities in support of furthering our distribution and free software, learning from our mentors and peers, building our community, and having a bit of fun. The conference was preceded by the annual DebCamp hacking session held 7 through 13 July where Debian Developers and Contributors convened to focus on their individual Debian-related projects or work in team sprints geared toward in-person collaboration in developing Debian. This year, a session was dedicated to prepare the BoF "Dealing with Dormant Packages: Ensuring Debian's High Standards"; another, at the initiative of our DPL, to prepare suggestions for the BoF Package Acceptance in Debian: Challenges and Opportunities"; and an afternoon around Salsa-CI. As has been the case for several years, a special effort has been made to welcome newcomers and help them become familiar with Debian and DebConf by organizing a sprint "New Contributors Onboarding" every day of Debcamp, followed more informally by mentorship during DebConf. The actual Debian Developers Conference started on Monday 14 July 2025. In addition to the traditional "Bits from the DPL" talk, the continuous key-signing party, lightning talks, and the announcement of next year's DebConf26, there were several update sessions shared by internal projects and teams. Many of the hosted discussion sessions were presented by our technical core teams with the usual and useful "Meet the Technical Committee", the "What's New in the Linux Kernel" session, and a set of BoFs about Debian packaging policy and Debian infrastructure. Thus, more than a quarter of the discussions dealt with this theme, including talks about our tools and Debian's archive processes. Internationalization and Localization have been the subject of several talks. The Python, Perl, Ruby, Go, and Rust programming language teams also shared updates on their work and efforts. Several talks have covered Debian Blends and Debian-derived distributions and other talks addressed the issue of Debian and AI. More than 17 BoFs and talks about community, diversity, and local outreach highlighted the work of various teams involved in not just the technical but also the social aspect of our community; four women who have made contributions to Debian through their artwork in recent years presented their work. The one-day session "DebConf 2025 Academic Track!", organized in collaboration with the IRISA laboratory was the first session welcoming fellow academics at DebConf, bringing together around ten presentations. The schedule was updated each day with planned and ad hoc activities introduced by attendees over the course of the conference. Several traditional activities took place: a job fair, a poetry performance, the traditional Cheese and Wine party (this year with cider as well), the Group Photos, and the Day Trips. For those who were not able to attend, most of the talks and sessions were broadcasted live and recorded; currently the videos are made available through this link. Almost all of the sessions facilitated remote participation via IRC and Matrix messaging apps or online collaborative text documents which allowed remote attendees to "be in the room" to ask questions or share comments with the speaker or assembled audience. DebConf25 saw over 441 T-shirts, 3 day trips, and up to 315 meals planned per day. All of these events, activities, conversations, and streams coupled with our love, interest, and participation in Debian and F/OSS certainly made this conference an overall success both here in Brest, France and online around the world. The DebConf25 website will remain active for archival purposes and will continue to offer links to the presentations and videos of talks and events. Next year, DebConf26 will be held in Santa Fe, Argentina, likely in July. As tradition follows before the next DebConf the local organizers in Argentina will start the conference activities with DebCamp with a particular focus on individual and team work towards improving the distribution. DebConf is committed to a safe and welcome environment for all participants. See the web page about the Code of Conduct on the DebConf25 website for more details on this. Debian thanks the commitment of numerous sponsors to support DebConf25, particularly our Platinum Sponsors: AMD, EDF, Infomaniak, Proxmox, and Viridien. We also wish to thank our Video and Infrastructure teams, the DebConf25 and DebConf committees, our host nation of France, and each and every person who helped contribute to this event and to Debian overall. Thank you all for your work in helping Debian continue to be "The Universal Operating System". See you next year! About Debian The Debian Project was founded in 1993 by Ian Murdock to be a truly free community project. Since then the project has grown to be one of the largest and most influential Open Source projects. Thousands of volunteers from all over the world work together to create and maintain Debian software. Available in 70 languages, and supporting a huge range of computer types, Debian calls itself the universal operating system. About DebConf DebConf is the Debian Project's developer conference. In addition to a full schedule of technical, social and policy talks, DebConf provides an opportunity for developers, contributors and other interested people to meet in person and work together more closely. It has taken place annually since 2000 in locations as varied as Scotland, Bosnia and Herzegovina, India, Korea. More information about DebConf is available from https://debconf.org/. About AMD The AMD ROCm platform includes programming models, tools, compilers, libraries, and runtimes for AI and HPC solution development on AMD GPUs. Debian is an officially supported platform for AMD ROCm and a growing number of components are now included directly in the Debian distribution. For more than 55 years AMD has driven innovation in high-performance computing, graphics and visualization technologies. AMD is deeply committed to supporting and contributing to open-source projects, foundations, and open-standards organizations, taking pride in fostering innovation and collaboration within the open-source community. About EDF EDF is a leading global utility company focused on low-carbon power generation. The group uses advanced engineering and scientific computing tools to drive innovation and efficiency in its operations, especially in nuclear power plant design and safety assessment. Since 2003, the EDF Group has been using Debian as its main scientific computing environment. Debian's focus on stability and reproducibility ensures that EDF's calculations and simulations produce consistent and accurate results. About Infomaniak Infomaniak is Switzerland's leading developer of Web technologies. With operations all over Europe and based exclusively in Switzerland, the company designs and manages its own data centers powered by 100% renewable energy, and develops all its solutions locally, without outsourcing. With millions of users and the trust of public and private organizations across Europe - such as RTBF, the United Nations, central banks, over 3,000 radio and TV stations, as well as numerous cities and security bodies - Infomaniak stands for sovereign, sustainable and independent digital technology. The company offers a complete suite of collaborative tools, cloud hosting, streaming, marketing and events solutions, while being owned by its employees and self-financed exclusively by its customers. About Proxmox Proxmox develops powerful, yet easy-to-use Open Source server software. The product portfolio from Proxmox, including server virtualization, backup, and email security, helps companies of any size, sector, or industry to simplify their IT infrastructures. The Proxmox solutions are built on Debian, we are happy that they give back to the community by sponsoring DebConf25. About Viridien Viridien is an advanced technology, digital and Earth data company that pushes the boundaries of science for a more prosperous and sustainable future. Viridien has been using Debian-based systems to power most of its HPC infrastructure and its cloud platform since 2009 and currently employs two active Debian Project Members. Contact Information For further information, please visit the DebConf25 web page at https://debconf25.debconf.org/ or send mail to press@debian.org.

Birger Schacht: My DebConf 25 review

DebConf 25 happened between 14th July and 19th July and I was there. It was my first DebConf (the big one, I was at a Mini DebConf in Hamburg a couple of years ago) and it was interesting. DebConf 25 happened at a Campus University at the outskirts of Brest and I was rather reluctant to go at first (EuroPython 25 was happening at the same time in Prague), but I decided to use the chance of DebConf happening in Europe, reachable by train from Vienna. We took the nighttrain to Paris, then found our way through the maze that is the Paris underground system and then got to Brest with the TGV. On our way to the Conference site we made a detour to a supermarket, which wasn t that easy because is was a national holiday in France and most of the shops were closed. But we weren t sure about the food situation at DebConf and we also wanted to get some beer. At the conference we were greeted by very friendly people at the badge station and the front desk and got our badges, swag and most important the keys to pretty nice rooms on the campus. Our rooms had a small private bathroom with a toilet and a shower and between the two rooms was a shared kitchen with a refrigerator and a microwave. All in all, the accommodation was simple but provided everything we needed and especially a space to have some privacy. During the next days I watched a lot of talks, met new people, caught up with old friends and also had a nice time with my travel buddies. There was a beach near the campus which I used nearly every day. It was mostly sunny except for the last day of the conference, which apparently was not common for the Brest area, so we got lucky regarding the weather. Landscape view of the sea at Dellec beach Given that we only arrived in the evening of the first day of DebConf, I missed the talk When Free Software Communities Unite: Tails, Tor, and the Fight for Privacy (recording), but I watched it on the way home and it was also covered by LWN. On Tuesday I started the day by visiting a talk about tag2upload (recording). The same day there was also an academic track and I watched the talk titled Integrating Knowledge Graphs into the Debian Ecosystem (recording) which presented a property graph showing relationships between various entities like packages, maintainers or bugs (there is a repository with parts of a paper, but not much other information). The speaker also mentioned the graphcast framework and the ontocast framework which sound interesting - we might have use for something liked this at $dayjob. In the afternoon there was a talk about the ArchWiki (recording) which gave a comprehensive insight in how the ArchWiki and the community behind it works. Right after that was a Debian Wiki BoF. There are various technical limitations with the current wiki software and there are not enough helping hands to maintain the service and do content curation. But the BoF had some nice results: there is now a new debian-wiki mailinglist, an IRC channel, a MediaWiki installation has been set up during DebConf, there are efforts to migrate the data and most importantly: and handful of people who want to maintain the service and organize the content of the wiki. I think the input from the ArchWiki folks gave some ideas how that team could operate. Tag at the wall at Dellec beach Wednesday was the day of the daytrip. I did not sign up for any of the trips and used the time to try out tag2upload, uploaded the latest labwc release to experimental and spent the rest of the day at the beach. Other noteworthy session I ve attended were the Don t fear the TPM talk (recording), which showed me a lot of stuff to try out, the session about lintian-ng (no recording), which is an experimental approach to make lintian faster, the review of the first year of wcurls existence (no recording yet) and the summary of Rust packaging in Debian (no recording yet). In between the sessions I started working on packaging wlr-sunclock (#1109230).
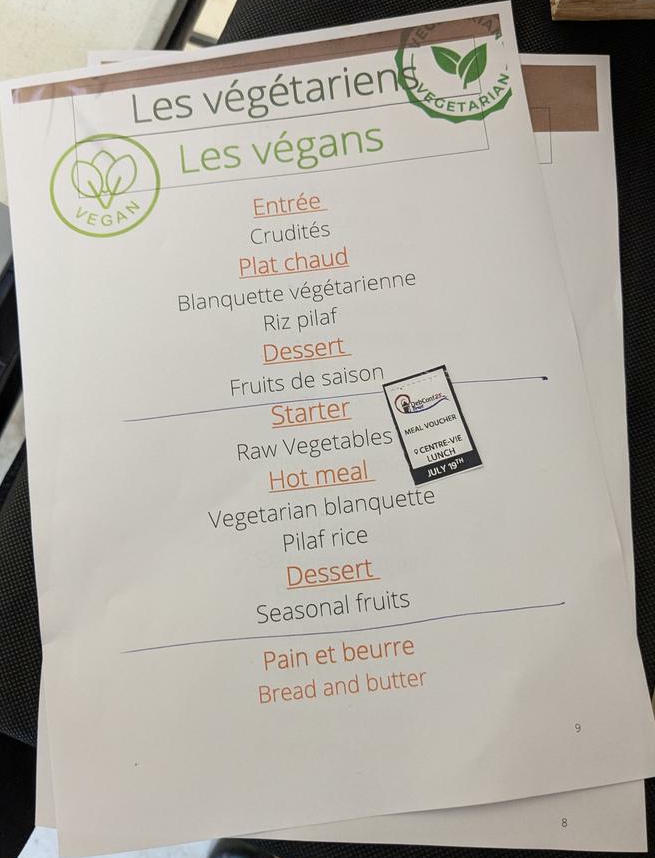
What did not work Vegan food. I might be spoiled by other conferences. Both at EuroPycon last year (definitely bigger, a lot more commercial) and at PyCon CZ 23 (similar in size, a lot more DIY) there was catering with explicitly vegan options. As I ve mentioned in the beginning, we went to a supermarket before we went to the conference and we had to go there one more time during the conference. I think there was a mixture between a total lack of awareness and a LOT of miscommunication. The breakfasts at the conference consisted of pastries and baguettes - I asked at the first day what the vegan options were and the answer was I don t know, maybe the baguette? and we were asked to only take as much baguette as the people who also got pastries. The lunch was prepared by the Restaurant associatif de Kern vent which is a canteen at the university campus. When we asked if there is vegan food, the people there said that there was only a vegetarian option so we only ate salad. Only later we heard via word of mouth that one has to explicitly ask for a vegan meal which was apparently prepared separatly and you had to find the right person that knows about it (I think thats very Debian-like ). But even then a person once got a vegetarian option offered as vegan food. One problem was also the missing / confusing labeling of the food. At the conference dinner there was apparently vegan food, but it was mixed with all the other food. There were some labels but with hundreds of hungry people around and caterers removing empty plates and dropping off plates with other stuff, everything gets mixed up. In the end we ate bread soaked in olive oil, until the olive oil got taken away by the catering people literally while we were dipping the bread in it. And when these issues were raised, some of the reactions can be summarized as You re holding it wrong which was really frustrating. The dinners at the conference hall were similar. At some point I had the impression that vegan and vegetarian was simply seen as the same thing. Dinner menu at the conference If the menus would be written like a debian/copyright file it would probably have looked like this:
Food: *
Diet: Vegan or Vegetarian
But the thing is that Vegan and Vegetarian cannot be mixed. Its similar to non compatible licenses. Once you mix vegan food with vegan food with vegetarian food it s not vegan anymore. Don t get me wrong, I know its hard to organize food for hundreds of people. But if you don t know what it means to provide a vegan option, just communicate the fact so people can look alternatives in advance. During the week some of the vegan people shared food, which was really nice and there were also a lot of non-vegan people who tried to help, organized extra food or simply listened to the hangry rants. Thanks for that!

Paris Saturday was the last day of DebConf and it was a rainy day. On Sunday morning we took the TGV back to Paris and then stayed there for one night because the next night train back to Vienna was on Monday. Luckily the weather was better in Paris. The first thing we did was to look up a vegan burger place. In the evening we strolled along the Seine and had a couple of beers at the Jardins du Trocad ro. Monday the rain also arrived in Paris and we mostly went from one cafe to the next, but also managed to visit Notre Dame.

Conclusio The next DebConf will be in Argentina and I think its likely that DebConf 27 will also not happen anywhere in trainvelling distance. But even if, I think the Mini DebConfs are more my style of happening (there is one planned in Hamburg next spring, and a couple of days ago I learned that there will be a Back to the Future musical show in Hamburg during that time). Nonetheless I had a nice time and I stumbled over some projects I might get more involved in. Thanks also to my travel buddies who put up with me

Matthew Palmer: Object deserialization attacks using Ruby's Oj JSON parser

tl;dr: there is an attack in the wild which is triggering dangerous-but-seemingly-intended behaviour in the Oj JSON parser when used in the default and recommended manner, which can lead to everyone s favourite kind of security problem: object deserialization bugs! If you have the oj gem anywhere in your Gemfile.lock, the quickest mitigation is to make sure you have Oj.default_options = mode: :strict somewhere, and that no library is overwriting that setting to something else.

Prologue As a sensible sysadmin, all the sites I run send me a notification if any unhandled exception gets raised. Mostly, what I get sent is error-handling corner cases I missed, but now and then things get more interesting. In this case, it was a PG::UndefinedColumn exception, which looked something like this:
PG::UndefinedColumn: ERROR:  column "xyzzydeadbeef" does not exist
This is weird on two fronts: firstly, this application has been running for a while, and if there was a schema problem, I d expect it to have made itself apparent long before now. And secondly, while I don t profess to perfection in my programming, I m usually better at naming my database columns than that. Something is definitely hinky here, so let s jump into the mystery mobile!

The column name is coming from outside the building! The exception notifications I get sent include a whole lot of information about the request that caused the exception, including the request body. In this case, the request body was JSON, and looked like this:
 "name":":xyzzydeadbeef", ... 
The leading colon looks an awful lot like the syntax for a Ruby symbol, but it s in a JSON string. Surely there s no way a JSON parser would be turning that into a symbol, right? Right?!? Immediately, I thought that that possibly was what was happening, because I use Sequel for my SQL database access needs, and Sequel treats symbols as database column names. It seemed like too much of a coincidence that a vaguely symbol-shaped string was being sent in, and the exact same name was showing up as a column name. But how the flying fudgepickles was a JSON string being turned into a Ruby symbol, anyway? Enter Oj.

Oj? I barely know aj A long, long time ago, the standard Ruby JSON library had a reputation for being slow. Thus did many competitors flourish, claiming more features and better performance. Strong amongst the contenders was oj (for Optimized JSON ), touted as The fastest JSON parser and object serializer . Given the history, it s not surprising that people who wanted the best possible performance turned to Oj, leading to it being found in a great many projects, often as a sub-dependency of a dependency of a dependency (which is how it ended up in my project). You might have noticed in Oj s description that, in addition to claiming fastest , it also describes itself as an object serializer . Anyone who has kept an eye on the security bug landscape will recall that object deserialization is a rich vein of vulnerabilities to mine. Libraries that do object deserialization, especially ones with a history that goes back to before the vulnerability class was well-understood, are likely to be trouble magnets. And thus, it turns out to be with Oj. By default, Oj will happily turn any string that starts with a colon into a symbol:

>> require "oj"
>> Oj.load(' "name":":xyzzydeadbeef","username":"bob","answer":42 ')
=>  "name"=>:xyzzydeadbeef, "username"=>"bob", "answer"=>42 

How that gets exploited is only limited by the creativity of an attacker. Which I ll talk about more shortly but first, a word from my rant cortex.

Insecure By Default is a Cancer While the object of my ire today is Oj and its fast-and-loose approach to deserialization, it is just one example of a pervasive problem in software: insecurity by default. Whether it s a database listening on 0.0.0.0 with no password as soon as its installed, or a library whose default behaviour is to permit arbitrary code execution, it all contributes to a software ecosystem that is an appalling security nightmare. When a user (in this case, a developer who wants to parse JSON) comes across a new piece of software, they have by definition no idea what they re doing with that software. They re going to use the defaults, and follow the most easily-available documentation, to achieve their goal. It is unrealistic to assume that a new user of a piece of software is going to do things the right way , unless that right way is the only way, or at least the by-far-the-easiest way. Conversely, the developer(s) of the software is/are the domain experts. They have knowledge of the problem domain, through their exploration while building the software, and unrivalled expertise in the codebase. Given this disparity in knowledge, it is tantamount to malpractice for the experts the developer(s) to off-load the responsibility for the safe and secure use of the software to the party that has the least knowledge of how to do that (the new user). To apply this general principle to the specific case, take the Using section of the Oj README. The example code there calls Oj.load, with no indication that this code will, in fact, parse specially-crafted JSON documents into Ruby objects. The brand-user user of the library, no doubt being under pressure to Get Things Done, is almost certainly going to look at this Using example, get the apparent result they were after (a parsed JSON document), and call it a day. It is unlikely that a brand-new user will, for instance, scroll down to the Further Reading section, find the second last (of ten) listed documents, Security.md , and carefully peruse it. If they do, they ll find an oblique suggestion that parsing untrusted input is never a good idea . While that s true, it s also rather unhelpful, because I d wager that by far the majority of JSON parsed in the world is untrusted , in one way or another, given the predominance of JSON as a format for serializing data passing over the Internet. This guidance is roughly akin to putting a label on a car s airbags that driving at speed can be hazardous to your health : true, but unhelpful under the circumstances. The solution is for default behaviours to be secure, and any deviation from that default that has the potential to degrade security must, at the very least, be clearly labelled as such. For example, the Oj.load function should be named Oj.unsafe_load, and the Oj.load function should behave as the Oj.safe_load function does presently. By naming the unsafe function as explicitly unsafe, developers (and reviewers) have at least a fighting chance of recognising they re doing something risky. We put warning labels on just about everything in the real world; the same should be true of dangerous function calls. OK, rant over. Back to the story.

But how is this exploitable? So far, I ve hopefully made it clear that Oj does some Weird Stuff with parsing certain JSON strings. It caused an unhandled exception in a web application I run, which isn t cool, but apart from bombing me with exception notifications, what s the harm? For starters, let s look at our original example: when presented with a symbol, Sequel will interpret that as a column name, rather than a string value. Thus, if our save an update to the user code looked like this:

# request_body has the JSON representation of the form being submitted
body = Oj.load(request_body)
DB[:users].where(id: user_id).update(name: body["name"])

In normal operation, this will issue an SQL query along the lines of UPDATE users SET name='Jaime' WHERE id=42. If the name given is Jaime O Dowd , all is still good, because Sequel quotes string values, etc etc. All s well so far. But, imagine there is a column in the users table that normally users cannot read, perhaps admin_notes. Or perhaps an attacker has gotten temporary access to an account, and wants to dump the user s password hash for offline cracking. So, they send an update claiming that their name is :admin_notes (or :password_hash). In JSON, that ll look like "name":":admin_notes" , and Oj.load will happily turn that into a Ruby object of "name"=>:admin_notes . When run through the above update the user code fragment, it ll produce the SQL UPDATE users SET name=admin_notes WHERE id=42. In other words, it ll copy the contents of the admin_notes column into the name column which the attacker can then read out just by refreshing their profile page.

But Wait, There s More! That an attacker can read other fields in the same table isn t great, but that s barely scratching the surface. Remember before I said that Oj does object serialization ? That means that, in general, you can create arbitrary Ruby objects from JSON. Since objects contain code, it s entirely possible to trigger arbitrary code execution by instantiating an appropriate Ruby object. I m not going to go into details about how to do this, because it s not really my area of expertise, and many others have covered it in detail. But rest assured, if an attacker can feed input of their choosing into a default call to Oj.load, they ve been handed remote code execution on a platter.

Mitigations As Oj s object deserialization is intended and documented behaviour, don t expect a future release to make any of this any safer. Instead, we need to mitigate the risks. Here are my recommended steps:
  1. Look in your Gemfile.lock (or SBOM, if that s your thing) to see if the oj gem is anywhere in your codebase. Remember that even if you don t use it directly, it s popular enough that it is used in a lot of places. If you find it in your transitive dependency tree anywhere, there s a chance you re vulnerable, limited only by the ingenuity of attackers to feed crafted JSON into a deeply-hidden Oj.load call.
  2. If you depend on oj directly and use it in your project, consider not doing that. The json gem is acceptably fast, and JSON.parse won t create arbitrary Ruby objects.
  3. If you really, really need to squeeze the last erg of performance out of your JSON parsing, and decide to use oj to do so, find all calls to Oj.load in your code and switch them to call Oj.safe_load.
  4. It is a really, really bad idea to ever use Oj to deserialize JSON into objects, as it lacks the safety features needed to mitigate the worst of the risks of doing so (for example, restricting which classes can be instantiated, as is provided by the permitted_classes argument to Psych.load). I d make it a priority to move away from using Oj for that, and switch to something somewhat safer (such as the aforementioned Psych). At the very least, audit and comment heavily to minimise the risk of user-provided input sneaking into those calls somehow, and pass mode: :object as the second argument to Oj.load, to make it explicit that you are opting-in to this far more dangerous behaviour only when it s absolutely necessary.
  5. To secure any unsafe uses of Oj.load in your dependencies, consider setting the default Oj parsing mode to :strict, by putting Oj.default_options = mode: :strict somewhere in your initialization code (and make sure no dependencies are setting it to something else later!). There is a small chance that this change of default might break something, if a dependency is using Oj to deliberately create Ruby objects from JSON, but the overwhelming likelihood is that Oj s just being used to parse ordinary JSON, and these calls are just RCE vulnerabilities waiting to give you a bad time.

Is Your Bacon Saved? If I ve helped you identify and fix potential RCE vulnerabilities in your software, or even just opened your eyes to the risks of object deserialization, please help me out by buying me a refreshing beverage. I would really appreciate any support you can give. Alternately, if you d like my help in fixing these (and many other) sorts of problems, I m looking for work, so email me.

24 July 2025

Valhalla's Things: Things I Have Learnt At DebConf

Posted on July 24, 2025
Tags: madeof:bits
An unsorted list, including some I already knew, but was reminded of.
  • dpkg-mergechangelogs exists.
  • Sewing your own shirt, posting it on planet and wearing it on the first day of DebConf, is more effective than a badge for making people recognise you.
  • I need to look into a number of tools for testings things (and try to start using some of those at $DAYJOB).
  • Masks are good. masks protect you from debbugs. masks protect you from ring cameras in the hotel you re staying on the day after debconf.
  • It s really nice to be chatting of random topics during lunch and discover that you are talking to the maintainer of a package of which you are one of the very few users! (the latter bit needs to be changed :) ).
  • I need to look into sequoia and all of the modern OpenPGP stuff.
  • Even if I don t have a lot of money, apparently I have even less sense (there will be blog posts on the topic in the mid-term future).
  • I can go to a talk about AI and not hate the speaker (yeah, the bar is pretty low there :D ). The automatic subtitles still failed in the same way as automatic subtitles always fail.
  • Debian gets used in really cool places.
  • At times it is a bit or a lot dysfunctional, but Debian still feels like a family.
And I still haven t watched the recordings of those talks that I couldn t (or decided not to, because the hallway track was more interesting) attend.

23 July 2025

Peter Pentchev: Ringlet software updates (2025-03-23)

Ringlet software updates (2025-03-23)Recent initial releases of [Ringlet software][r-site] (a fancy name for my pet projects):

Abhijith PA: Removing spams from your local maildir

I have been using Disroot as my primary email ever since openmailbox.org stopped. I am very grateful for Disroot s service and I occasionally donate to them. Recently, my Disroot inbox has been flooded with spam. On an average day, I used to receive around 90% spams on entire email count. However, the situation has improved since then. I contacted the Disroot team, and they informed me that they are aware of the situation and planning to migrate to Rspamd from Spamassassin. I don t know whether they deployed Rspamd, even if so that only going to process incoming mails, I am looking for a way to identify spams and purge that are already entered my Imap folders. Later I found this script nh2/rspamd-move[1], which seems fit my need. I made couple of trivial changes in the script for my use case. I wasn t sure of directly running this on my Mail/ dir, so I cloned my entire local mail directory to another directory and made available to podman container where I script and rspamd instance exist. I trained rspamd from the /Spam. Later, I manually moved couple of mails to /spam folder/. I requested friends to share their spam folder in the #debian-in channel, but that didn t happen :P
$podman run -it --mount
type=bind,source=/home/abhijith/$MAILS/,target=/container-mail-clone
id:latest
$script.py
(It took some time since I have around 10000+ emails) Wow, it was quite a successful attempt, I was able to catch most of it and move to spam/ and couple of false positive in a different folder. Now I want to do the same in the actual maildir yet very skeptical. While going through the cloned folder with mutt -f I remembered that the mails are already indexed by notmuch. So all I need to do is operate tagging and deletion with notmuch and it will be synced back to the original mail dir. Ta-da. I cleaned by Inbox. [1] - https://github.com/nh2/rspamd-move

Russell Coker: Annoying Wrongness on TV

One thing that annoys me on TV shows and movies is getting the details wrong. Yes it s fiction and yes some things can t be done correctly and in some situations correctly portraying things goes against the plot. But otherwise I think they should try to make it accurate. I was just watching The Americans (a generally good show that I recommend watching) and in Season 4 Episode 9 there s a close up of a glass of wine which clearly shows that the Tears of Wine effect is missing, the liquid in the glass obviously has the surface tension of water not of wine. When they run a show about spies then have to expect that the core audience will be the type of detail oriented people who notice these things. Having actors not actually drink alcohol on set is a standard practice, if they have to do 10 takes of someone drinking a glass of wine then that would be a problem if they actually drank real wine. But they could substitute real wine for the close up shots and of course just getting it right the first time is a good option. Some ridiculous inaccuracy we just need to deal with, like knives making a schwing sound when pulled out of scabbards and silenced guns usually still being quite loud (so many people are used to it being wrong). Organisations like the KGB had guns that were actually silent, but they generally looked obviously different to regular guns and had a much lower effective range. The gold coins shown on TV are another ridiculous thing. The sound of metal hitting something depends on how hard it is and how dense it is. Surely most people have heard the sounds of dropping steel nuts and ball bearings and the sound of dropping lead sinkers and knows that the sounds of items of similar size and shape differ greatly based on density and hardness. A modern coin made of copper, cupro-nickel (the current silver coins), or copper-aluminium (the current gold coins) sounds very different to a gold coin when dropped on a bench. For a show like The Witcher it wouldn t be difficult to make actual gold coins of a similar quality to iron age coin production, any jeweller could make the blanks and making stamps hard enough to press gold isn t an engineering challenge (stamping copper coins would be much more difficult). The coins used for the show could be sold to fans afterwards. Once coins are made they can t be just heaped up. Even if you are a sorcerer you probably couldn t fill a barrel a meter high with gold coins and not have it break from the weight and/or have the coins at the bottom cold welded. Gold coins are supposed to have a precise amount of gold and if you pile them up too high then the cold welding process will transfer gold between coins changing the value. If someone was going to have a significant quantity of gold stored then it would be in gold ingots with separators between layers to prevent cold welding. Movies tend not to show coins close up, I presume that s because they considered it too difficult to make coins and they just use some random coins from their own country. Another annoying thing is shows that don t match up the build dates of objects used. It s nice when they get it right like the movie Titanic featuring a M1911 pistol which is something that a rich person in 1912 would likely have. The series Carnival Row (which I recommend) has weapons that mostly match our WW1 era, everything that doesn t involve magic seems legit. One of the worst examples of this is the movie Anna (by Luc Besson which is mostly a recreation of his film Nikita but in the early 90s and with the KGB). That film features laptops with color screens and USB ports before USB was invented and when color screens weren t common on laptops, as an aside military spec laptops tend to have older designs than consumer spec ones. I ve mostly given up on hoping that movies will get hacking scenes that are any more accurate than knives making a schwing sound. But it shouldn t be that hard for them to find computer gear that was manufactured in the right year to use for the film. Why can t they hire experts on technology to check everything?

22 July 2025

Iustin Pop: Watching website scanning bots

Ever since I put up http://demo.corydalis.io, and setup logcheck, I m inadvertently keeping up with recent exploits in common CMS frameworks, or maybe even normal web frameworks issues, by seeing what 404s I get from the logs. Now, I didn t indent to do this per se, I just wanted to make sure I don t have any 500s, and at one point, I did actually catch a bug by seeing seemingly valid URLs, with referrer my own pages, leading to 404s. But besides that, it s mainly a couple times per week, a bot finds the site, and then it tries in fast succession something like this (real log entries, with the source IP address removed):
[21/Jul/2025:09:27:09 +0200] "GET /pms?module=logging&file_name=../../../../../../~/.aws/credentials&number_of_lines=10000 HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:11 +0200] "GET /admin/config?cmd=cat+/root/.aws/credentials HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:11 +0200] "GET /.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:13 +0200] "GET /.env.local HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:13 +0200] "GET /.env.production HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:16 +0200] "GET /.env.dev HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:17 +0200] "GET /.env.development HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:19 +0200] "GET /.env.prod HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:19 +0200] "GET /.env.stage HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:22 +0200] "GET /.env.test HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:23 +0200] "GET /.env.example HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:25 +0200] "GET /.env.bak HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:26 +0200] "GET /.env.old HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:28 +0200] "GET /.envs/.production/.django HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:28 +0200] "GET /blog.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:31 +0200] "GET /wp-content/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:32 +0200] "GET /application/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:34 +0200] "GET /app/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:35 +0200] "GET /apps/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:37 +0200] "GET /config/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:38 +0200] "GET /config/config.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:40 +0200] "GET /config/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:41 +0200] "GET /api/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:43 +0200] "GET /vendor/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:44 +0200] "GET /backend/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:46 +0200] "GET /server/.env HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:46 +0200] "GET /home/user/.aws/credentials HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:49 +0200] "GET /aws/credentials HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:50 +0200] "GET /.aws/credentials HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:52 +0200] "GET /.aws/config HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:52 +0200] "GET /config/aws.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:55 +0200] "GET /config/aws.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:55 +0200] "GET /.env.production HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:58 +0200] "GET /config.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:27:59 +0200] "GET /config/config.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:01 +0200] "GET /config/settings.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:02 +0200] "GET /config/secrets.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:04 +0200] "GET /config.yaml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:04 +0200] "GET /config.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:07 +0200] "GET /config.py HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:08 +0200] "GET /secrets.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:10 +0200] "GET /secrets.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:11 +0200] "GET /credentials.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:13 +0200] "GET /.git-credentials HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:14 +0200] "GET /.git/config HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:16 +0200] "GET /.gitignore HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:18 +0200] "GET /.gitlab-ci.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:19 +0200] "GET /.github/workflows HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:22 +0200] "GET /.idea/workspace.xml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:22 +0200] "GET /.vscode/settings.json HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:25 +0200] "GET /docker-compose.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:25 +0200] "GET /docker-compose.override.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:28 +0200] "GET /docker-compose.prod.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:28 +0200] "GET /docker-compose.dev.yml HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:32 +0200] "GET /phpinfo HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:32 +0200] "GET /_profiler/phpinfo HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:34 +0200] "GET /phpinfo.php HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:34 +0200] "GET /info.php HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:37 +0200] "GET /storage/logs/laravel.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:37 +0200] "GET /storage/logs/error.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:40 +0200] "GET /logs/debug.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:40 +0200] "GET /logs/app.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:49 +0200] "GET /debug.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:51 +0200] "GET /error.log HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:53 +0200] "GET /.DS_Store HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:55 +0200] "GET /backup.zip HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:28:58 +0200] "GET /.backup HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:29:00 +0200] "GET /db.sql HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:29:03 +0200] "GET /dump.sql HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:29:06 +0200] "GET /database.sql HTTP/1.1" 404 - "" "Mozilla/5.0"
[21/Jul/2025:09:29:09 +0200] "GET /backup.tar.gz HTTP/1.1" 404 - "" "Mozilla/5.0"
Now, this example is actually trying to catch a bit more things, but many times it s focused on some specific thing, or two things. Here we have docker, MacOS .DS_Store (I m not sure how that s useful - to find more filenames?), VSCode settings, various secrets, GitHub workflows, log output, database dumps, AWS credentials, and still I guess from the wp filename WordPress settings. The first few years were full of WordPress scanners, now it seems it has quieted down, I haven t seen a bot scanning 200 WP potential filenames in ages. And this bot even bothers to put in Mozilla/5.0 as browser identification . Side-note: I don t think the filename path in the first log entry, i.e. ../../../../../../~/, ever properly resolves to the home directory of any user. So I m not that particular scanner ever works, but who knows? Maybe some framework does bad tilde expansion, but at least bash will not expand ~ inside a path, it seems that path is passed as-is to an invoked command (strace confirms it). What s surprising here is that these are usually plain dumb scanners, from the same IP address, no concern on throttling, no attempt to hide, just 2 minutes of brute-forcing a random list of known treasures , then moving on. For this to be worth, it means there are still victims found using this method, sadly. Well, sometimes I get a single, one-off "GET /wp-login.php HTTP/1.1, which is strange enough it might not be a bot even, who knows. But in general, periods of activity of this type are coming and going, probably aligned with new CVEs. And another surprising thing is that for this type of scanning to work (and I ve seen many over the years), the website framework/configuration must allow random file download. Corydalis itself is written in Haskell, using Yesod, and it has a hardcoded (built at compile time) list of static resources it will serve. I haven t made the switch to fully embedding in the binary, but at that point, it won t need to read from the filesystem at all. Right now it will serve a few CSS and JS files, plus fonts, but that s it, no arbitrary filesystem traversal. Strange that some frameworks allow it. This is not productively spent time, but it is fun, especially seeing how this changes over time. And probably the most use anyone gets out of http://demo.corydalis.io .

David Bremner: Hibernate on the pocket reform 10/n

Context

Finally applying the pci reset series.
$ b4 am 20250715-pci-port-reset-v6-0-6f9cce94e7bb@oss.qualcomm.com
$ git am -3 v6_20250715_manivannan_sadhasivam_pci_add_support_for_resetting_the_root_ports_in_a_platform_specifi.mbx
There is quite a scary looking conflict between the last patch in the series and https://lore.kernel.org/r/1744940759-23823-1-git-send-email-shawn.lin@rock-chips.com which is now upstream (collabora) in rockchip-devel. I resolved the second basically by taking both, as it seemed like two independent sets of additions to the same parts of the file. The first it looks like Shawn's commit referenced above should prevail.
  • If anyone is curious about the (possibly incorrectly) rebased patches, they are at https://salsa.debian.org/bremner/collabora-rockchip-3588 (reform-patches is the default, and relevant branch).

testing
  • The new (6.16~rc7+) kernel boots
  • It successfully reboots
  • devices test passes, although the UBSAN warning / error is still there
 174.559032] UBSAN: array-index-out-of-bounds in net/mac80211/rc80211_minstrel_ht.c:409:33
[  174.559830] index 15 is out of range for type 'minstrel_rate_stats [10]'
[  174.560462] CPU: 7 UID: 0 PID: 213 Comm: kworker/u32:10 Tainted: G        WC OE       6.16.0-rc7+ #6 NONE
[  174.560470] Tainted: [W]=WARN, [C]=CRAP, [O]=OOT_MODULE, [E]=UNSIGNED_MODULE
[  174.560472] Hardware name: MNT Pocket Reform with RCORE RK3588 Module (DT)
[  174.560474] Workqueue: mt76 mt76u_tx_status_data [mt76_usb]
[  174.560489] Call trace:
[  174.560491]  show_stack+0x34/0x98 (C)
[  174.560501]  dump_stack_lvl+0x60/0x80
[  174.560508]  dump_stack+0x18/0x24
[  174.560514]  ubsan_epilogue+0x10/0x48
[  174.560520]  __ubsan_handle_out_of_bounds+0xa0/0xd0
[  174.560526]  minstrel_ht_tx_status+0x890/0xc68 [mac80211]
[  174.560633]  rate_control_tx_status+0xbc/0x180 [mac80211]
[  174.560730]  ieee80211_tx_status_ext+0x1d8/0x9a0 [mac80211]
[  174.560822]  mt76_tx_status_unlock+0x188/0x2a0 [mt76]
[  174.560844]  mt76x02_send_tx_status+0x130/0x4a0 [mt76x02_lib]
[  174.560860]  mt76x02_tx_status_data+0x64/0xa8 [mt76x02_lib]
[  174.560872]  mt76u_tx_status_data+0x84/0x120 [mt76_usb]
[  174.560879]  process_one_work+0x178/0x3c8
[  174.560885]  worker_thread+0x208/0x400
[  174.560890]  kthread+0x120/0x220
[  174.560894]  ret_from_fork+0x10/0x20
[  174.560898] ---[ end trace ]---
  • "platform" test still fails with
[   88.484072] rk_gmac-dwmac fe1b0000.ethernet end0: Link is Down
[   88.597026] rockchip-dw-pcie a40c00000.pcie: Failed to receive PME_TO_Ack
[   88.598523] PM: hibernation: hibernation debug: Waiting for 5 second(s).
[   94.667723] rockchip-dw-pcie a40c00000.pcie: Phy link never came up
[   94.668281] rockchip-dw-pcie a40c00000.pcie: fail to resume
[   94.668783] rockchip-dw-pcie a40c00000.pcie: PM: dpm_run_callback(): genpd_restore_noirq returns -110
[   94.669594] rockchip-dw-pcie a40c00000.pcie: PM: failed to restore noirq: error -110
[  120.035426] watchdog: CPU4: Watchdog detected hard LOCKUP on cpu 5
[  120.035978] Modules linked in: xt_CHECKSUM xt_tcpudp nft_chain_nat xt_MASQUERADE nf_nat nf_conntrack nf_defrag_ipv6 nf_defrag_ipv4 nft_compat bridge stp llc nf_tables aes_neon_bs aes_neon_blk ccm snd_seq_dummy snd_hrtimer snd_seq snd_seq_device dwmac_rk binfmt_misc mt76x2_common mt76x02_usb mt76_usb mt76x02_lib mt76 mac80211 libarc4 snd_soc_simple_card rockchip_saradc industrialio_triggered_buffer cfg80211 snd_soc_tlv320aic31xx rk805_pwrkey kfifo_buf reform2_lpc(OE) industrialio rockchip_thermal rfkill rockchip_rng hantro_vpu cdc_acm rockchip_rga v4l2_vp9 snd_soc_rockchip_i2s_tdm rockchip_vdec2 panthor videobuf2_dma_sg v4l2_jpeg drm_gpuvm v4l2_h264 drm_exec snd_soc_audio_graph_card snd_soc_simple_card_utils joydev evdev dm_mod nvme_fabrics efi_pstore configfs nfnetlink ip_tables x_tables autofs4 ext4 crc16 mbcache jbd2 btrfs blake2b_generic xor xor_neon raid6_pq mali_dp snd_soc_meson_axg_toddr snd_soc_meson_axg_fifo snd_soc_meson_codec_glue panfrost drm_shmem_helper gpu_sched ao_cec_g12a meson_vdec(C)
[  120.036066]  videobuf2_dma_contig hid_generic videobuf2_memops v4l2_mem2mem videobuf2_v4l2 videodev videobuf2_common mc dw_hdmi_i2s_audio meson_drm meson_canvas meson_dw_mipi_dsi meson_dw_hdmi usbhid hid mxsfb mux_mmio panel_edp imx_dcss ti_sn65dsi86 nwl_dsi mux_core pwm_imx27 xhci_plat_hcd xhci_hcd onboard_usb_dev snd_soc_hdmi_codec snd_soc_core micrel snd_pcm_dmaengine nvme snd_pcm nvme_core snd_timer snd nvme_keyring nvme_auth soundcore stmmac_platform stmmac pcs_xpcs phylink mdio_devres of_mdio sdhci_of_dwcmshc fixed_phy sdhci_pltfm phy_rockchip_usbdp dw_mmc_rockchip fwnode_mdio ehci_platform typec phy_rockchip_samsung_hdptx phy_rockchip_naneng_combphy rk808_regulator pwm_rockchip dwc3 dw_wdt libphy fan53555 ohci_platform sdhci ehci_hcd ulpi rtc_pcf8523 dw_mmc_pltfm udc_core ohci_hcd dw_mmc cqhci mdio_bus rockchip_dfi rockchipdrm dw_hdmi_qp analogix_dp i2c_rk3x usbcore phy_rockchip_inno_usb2 dw_mipi_dsi dw_mipi_dsi2 usb_common cpufreq_dt drm_dp_aux_bus [last unloaded: mt76x2u]
[  120.036150] Sending NMI from CPU 4 to CPUs 5:
  • The results are similar if I uncomment the unloading of the dwc3 module
set -x
echo platform >  /sys/power/pm_test
echo reboot > /sys/power/disk
sleep 2
rmmod mt76x2u
sleep 2
#rmmod dwc3
#sleep 2
echo disk >  /sys/power/state
sleep 2
#modprobe dwc3
#sleep 2
modprobe mt76x2u
  • Unsurprisingly, if I try an actual resume (instead of a "platform" test), I get the same messages about "Phy link never came up" and the system needs a hard reboot after trying to resume.
  • Barring inspiration, my next move will be to report my lack of success to the appropriate kernel mailing list(s).
previous episode

20 July 2025

Michael Prokop: What to expect from Debian/trixie #newintrixie

Trixie Banner, Copyright 2024 Elise Couper Update on 2025-07-28: added note about Debian 13/trixie support for OpenVox (thanks, Ben Ford!) Debian v13 with codename trixie is scheduled to be published as new stable release on 9th of August 2025. I was the driving force at several of my customers to be well prepared for the upcoming stable release (my efforts for trixie started in August 2024). On the one hand, to make sure packages we care about are available and actually make it into the release. On the other hand, to ensure there are no severe issues that make it into the release and to get proper and working upgrades. So far everything is looking pretty well and working fine, the efforts seemed to have payed off. :) As usual with major upgrades, there are some things to be aware of, and hereby I m starting my public notes on trixie that might be worth for other folks. My focus is primarily on server systems and looking at things from a sysadmin perspective. Further readings As usual start at the official Debian release notes, make sure to especially go through What s new in Debian 13 + issues to be aware of for trixie (strongly recommended read!). Package versions As a starting point, let s look at some selected packages and their versions in bookworm vs. trixie as of 2025-07-20 (mainly having amd64 in mind):
Package bookworm/v12 trixie/v13
ansible 2.14.3 2.19.0
apache 2.4.62 2.4.64
apt 2.6.1 3.0.3
bash 5.2.15 5.2.37
ceph 16.2.11 18.2.7
docker 20.10.24 26.1.5
dovecot 2.3.19 2.4.1
dpkg 1.21.22 1.22.21
emacs 28.2 30.1
gcc 12.2.0 14.2.0
git 2.39.5 2.47.2
golang 1.19 1.24
libc 2.36 2.41
linux kernel 6.1 6.12
llvm 14.0 19.0
lxc 5.0.2 6.0.4
mariadb 10.11 11.8
nginx 1.22.1 1.26.3
nodejs 18.13 20.19
openjdk 17.0 21.0
openssh 9.2p1 10.0p1
openssl 3.0 3.5
perl 5.36.0 5.40.1
php 8.2+93 8.4+96
podman 4.3.1 5.4.2
postfix 3.7.11 3.10.3
postgres 15 17
puppet 7.23.0 8.10.0
python3 3.11.2 3.13.5
qemu/kvm 7.2 10.0
rsync 3.2.7 3.4.1
ruby 3.1 3.3
rust 1.63.0 1.85.0
samba 4.17.12 4.22.3
systemd 252.36 257.7-1
unattended-upgrades 2.9.1 2.12
util-linux 2.38.1 2.41
vagrant 2.3.4 2.3.7
vim 9.0.1378 9.1.1230
zsh 5.9 5.9
Misc unsorted apt The new apt version 3.0 brings several new features, including: systemd systemd got upgraded from v252.36-1~deb12u1 to 257.7-1 and there are lots of changes. Be aware that systemd v257 has a new net.naming_scheme, v257 being PCI slot number is now read from firmware_node/sun sysfs file. The naming scheme based on devicetree aliases was extended to support aliases for individual interfaces of controllers with multiple ports. This might affect you, see e.g. #1092176 and #1107187, the Debian Wiki provides further useful information. There are new systemd tools available: The tools provided by systemd gained several new options: Debian s systemd ships new binary packages: Linux Kernel The trixie release ships a Linux kernel based on latest longterm version 6.12. As usual there are lots of changes in the kernel area, including better hardware support, and this might warrant a separate blog entry. To highlight some changes with Debian trixie: See Kernelnewbies.org for further changes between kernel versions. Configuration management For puppet users, Debian provides the puppet-agent (v8.10.0), puppetserver (v8.7.0) and puppetdb (v8.4.1) packages. Puppet s upstream does not provide packages for trixie, yet. Given how long it took them for Debian bookworm, and with their recent Plans for Open Source Puppet in 2025, it s unclear when (and whether at all) we might get something. As a result of upstream behavior, also the OpenVox project evolved, and they already provide Debian 13/trixie support (https://apt.voxpupuli.org/openvox8-release-debian13.deb). FYI: the AIO puppet-agent package for bookworm (v7.34.0-1bookworm) so far works fine for me on Debian/trixie. Be aware that due to the apt-key removal you need a recent version of the puppetlabs-apt for usage with trixie. The puppetlabs-ntp module isn t yet ready for trixie (regarding ntp/ntpsec), if you should depend on that. ansible is available and made it with version 2.19 into trixie. Prometheus stack Prometheus server was updated from v2.42.0 to v2.53, and all the exporters that got shipped with bookworm are still around (in more recent versions of course). Trixie gained some new exporters: Virtualization docker (v26.1.5), ganeti (v3.1.0), libvirt (v11.3.0, be aware of significant changes to libvirt packaging), lxc (v6.0.4), podman (v5.4.2), openstack (see openstack-team on Salsa), qemu/kvm (v10.0.2), xen (v4.20.0) are all still around. Proxmox already announced their PVE 9.0 BETA, being based on trixie and providing 6.14.8-1 kernel, QEMU 10.0.2, LXC 6.0.4, OpenZFS 2.3.3. Vagrant is available in version 2.3.7, but Vagrant upstream does not provide packages for trixie yet. Given that HashiCorp adopted the BSL, the future of vagrant in Debian is unclear. If you re relying on VirtualBox, be aware that upstream doesn t provide packages for trixie, yet. VirtualBox is available from Debian/unstable (version 7.1.12-dfsg-1 as of 2025-07-20), but not shipped with stable release since quite some time (due to lack of cooperation from upstream on security support for older releases, see #794466). Be aware that starting with Linux kernel 6.12, KVM initializes virtualization on module loading by default. This prevents VirtualBox VMs from starting. In order to avoid this, either add kvm.enable_virt_at_load=0 parameter into kernel command line or unload the corresponding kvm_intel / kvm_amd module. If you want to use Vagrant with VirtualBox on trixie, be aware that Debian s vagrant package as present in trixie doesn t support the VirtualBox package version 7.1 as present in Debian/unstable (manually patching vagrant s meta.rb and rebuilding the package without Breaks: virtualbox (>= 7.1) is known to be working). util-linux The are plenty of new options available in the tools provided by util-linux: Now no longer present in util-linux as of trixie: The following binaries got moved from util-linux to the util-linux-extra package: And the util-linux-extra package also provides new tools: OpenSSH OpenSSH was updated from v9.2p1 to 10.0p1-5, so if you re interested in all the changes, check out the release notes between those versions (9.3, 9.4, 9.5, 9.6, 9.7, 9.8, 9.9 + 10.0). Let s highlight some notable behavior changes in Debian: There are some notable new features: Thanks to everyone involved in the release, looking forward to trixie + and happy upgrading!
Let s continue with working towards Debian/forky. :)

17 July 2025

Gunnar Wolf: About our proof-of-concept LLM tool for navigating Debian's manpages

So, for the first year, this year s DebConf had the DebConf Academic Track , that is, content for a one-day-long set of short sessions, for which of them there was a written article presenting the content often with a very academic format, but not necessarily. I hope that for future DebConfs we will continue to hold this track, and that we can help bridge the gap: to get people that are not usually from the academic / universitary prepare content that will be formally expressed and included in a long-lasting, indexed book of proceedings. We did have (informal) proceedings in many of the early DebConfs, and I m very happy to regain that, but with 20 years of better practices. Anyway, of course, I took the opportunity to join this experiment, and together with my Mexican colleague Tzolkin Gardu o who is finishing her PhD here in France (or should I say, second to her, as she is the true leading author of our work). And here you can see the paper we submitted to the DebConf Academic Track, which will be published soon: A retrieval-augmented-generation pipeline to help users query system-provided documentation The corresponding source code is all available at Tzolkin s repository in GitHub. So, what is it about, in shorter words and layman terms? Debian has lots of documentation, but lacks in discoverability. We targetted our venerable manpages: It is well known that manpages are relevant, well-organized documentation describing how to use each of the binaries we ship in Debian. Eric Raymond wrote in his well-known essay The Art of Unix Programming (2003) that the Unix cultural style is telegraphic but complete. It does not hold you by the hand, but it usualy points in the right direction. Our original intent was to digest all of the information in our manpages, but we narrowed it to only the first section of the manual due to the limitations of the hardware a good friend lent us to play with LLMs. We took four different base, redistributable (although, yes, non-DFSG-free) Large Language Models downloaded from HuggingFace (T5-small, MiniLM-L6-v2, BGE-small-en and Multilingual-e5-small), and trained them with the 34579 pages found inside /usr/share/man/man1 of all of the existing Debian packages. We did some interesting fine-tuning (for further details, please refer to the paper itself or to our GitHub repository. The idea is to present an interactive tool that udnerstand natural language queries, and answers with the specific manpage to which they better relate (I d like to say they answer best , but Tzolkin has repeatedly tried to correct my understanding of the resulting vectorial distances). I had prepared some images to present as interaction examples, but I ll wrap up this post with something even better So, this is what you would get with the following queries: We were happy to present like this. During DebCamp, however, I was able to devote some time to translating my client into a Web-accessible system. Do note that it s a bit brittle, and might break now and then. But you are welcome to play with it! Play with the Web interface for our RAG for Debian manuals! I find it worth sharing that, while we used quite a bit of GPU for the training (not too much a couple of nights on an old-although-powerful nVidia 1070 card lent to us by the Felipe Esquivel Fund for Science and Cultural Support), all querying takes place in the CPU, and I usually get between 0.1 and 0.3 seconds per query. My server s architecture is far from rock-solid, and it can break now and then but at least it should respawn upon failure And it should at least be available there for a couple of weeks into August. Anyway, this has been a very interesting journey getting my toes wet in the waters of LLM, and while current results are a bit crude, I think this can be made into an interesting tool for Debian exploration.

Otto Kek l inen: Debcraft Easiest way to modify and build Debian packages

Featured image of post Debcraft   Easiest way to modify and build Debian packagesDebian packaging is notoriously hard. Far too many new contributors give up while trying, and many long-time contributors leave due to burnout from having to do too many thankless maintenance tasks. Some just skip testing their changes properly because it feels like too much toil. Debcraft is my attempt to solve this by automating all the boring stuff, and making it easier to learn the correct practices and helping new and old packagers better track changes in both source code and build artifacts.
The challenge of declarative packaging code Unlike how rpm or apk packages are done, the deb package sources by design avoid having one massive procedural packaging recipe. Instead, the packaging is defined in multiple declarative files in the debian/ subdirectory. For example, instead of a script running install -m 755 bin/btop /usr/bin/btop there is a file debian/btop.install containing the line usr/bin/btop. This makes the overall system more robust and reliable, and allows, for example, extensive static analysis to find problems without having to build the package. The notable exception is the debian/rules file, which contains procedural code that can modify any aspect of the package build. Almost all other files are declarative. Benefits include, among others, that the effect of a Debian-wide policy change can be relatively easily predicted by scanning what attributes and configurations all packages have declared. The drawback is that to understand the syntax and meaning of each file, one must understand which build tools read which files and traverse potentially multiple layers of abstraction. In my view, this is the root cause for most of the perceived complexity.

Common complaints about .deb packaging Related to the above, people learning Debian packaging frequently voice the following complaints:
  • Debian has too many tools to learn, often with overlapping or duplicate functionality.
  • Too much outdated and inconsistent documentation that makes learning the numerous tools needlessly hard.
  • Lack of documentation of the generally agreed best practices, mainly due to Debian s reluctance as a project to pick one tool and deprecate the alternatives.
  • Multiple layers of abstraction and lack of clarity on what any single change in the debian/ subdirectory leads to in the final package.
  • Requirement of Debian packages to be developed on a Debian system.

How Debcraft solves (some of) this Debcraft is intentionally opinionated for the sake of simplicity, and makes heavy use of git, git-buildpackage, and most importantly Linux containers, supporting both Docker and Podman. By using containers, Debcraft frees the user from the requirement of having to run Debian. This makes .deb packaging more accessible to developers running some other Linux distro or even Mac or Windows (with WSL). Of course we want developers to run Debian (or a derivative like Ubuntu) but we want them even more to build, test and ship their software as .deb. Even for Debian/Ubuntu users having everything done inside clean hermetic containers of the latest target distribution version will yield more robust, secure and reproducible builds and tests. All containers are built automatically on-the-fly using best practices for layer caching, making everything easy and fast. Debcraft has simple commands to make it easy to build, rebuild, test and update packages. The most fundamental command is debcraft build, which will not only build the package but also fetch the sources if not already present, and with flags such as --distribution or --source-only build for any requested Debian or Ubuntu release, or generate source packages only for Debian or PPA upload purposes. For ease of use, the output is colored and includes helpful explanations on what is being done, and suggests relevant Debian documentation for more information. Most importantly, the build artifacts, along with various logs, are stored in separate directories, making it easy to compare before and after to see what changed as a result of the code or dependency updates (utilizing diffoscope among others). While the above helps to debug successful builds, there is also the debcraft shell command to make debugging failed builds significantly easier by dropping into a shell where one can run various dh commands one-by-one. Once the build works, testing autopkgtests is as easy as running debcraft test. As with all other commands, Debcraft is smart enough to read information like the target distribution from the debian/changelog entry. When the package is ready to be released, there is the debcraft release command that will create the Debian source package in the correct format and facilitate uploading it either to your Personal Package Archive (PPA) or if you are a Debian Developer to the official Debian archive.

Automatically improve and update packages Additionally, the command debcraft improve will try to fix all issues that are possible to address automatically. It utilizes, among others, lintian-brush, codespell and debputy. This makes repetitive Debian maintenance tasks easier, such as updating the package to follow the latest Debian policies. To update the package to the latest upstream version there is also debcraft update. It will read the package configuration files such as debian/gbp.conf and debian/watch and attempts to import the latest upstream version, refresh patches, build and run autopkgtests. If everything passes, the new version is committed. This helps automate the process of updating to new upstream versions.

Try out Debcraft now! On a recent version of Debian and Ubuntu, Debcraft can be installed simply by running apt install debcraft. To use Debcraft on some other distribution or to get the latest features available in the development version install it using:
git clone https://salsa.debian.org/debian/debcraft.git
cd debcraft
make install-local
To see exact usage instructions run debcraft --help.

Contributions welcome Current Debcraft version 0.5 still has some rough edges and missing features, but I have personally been using it for over a year to maintain all my packages in Debian. If you come across some issue, feel free to file a report at https://salsa.debian.org/debian/debcraft/-/issues or submit an improvement at https://salsa.debian.org/debian/debcraft/-/merge_requests. The code is intentionally written entirely in shell script to keep the barrier to code contribution as low as possible.
By the way, if you aspire to become a Debian Developer, and want to follow my examples in using state-of-the-art tooling and collaborate using salsa.debian.org, feel free to reach out for mentorship. I am glad to see more people contribute to Debian!

Next.

Previous.