Search Results: "tar"

12 July 2015

Lars Wirzenius: /u/liw no more

I've used Reddit for many years. I used it for many years without an account, but eventually I made one. The site has always had its share of unpleasantness, people who're more interested in tearing down than in building. In recent years, it's gotten worse, and getting out of hand. During the fairly short reign of Ellen Pao as CEO, I found things to be getting better. The site was starting to make it clear that harrassment, for example, was unacceptable. Unsurprisingly, this made some of the nastier people quite upset. Pao has now resigned, and a new CEO has started. He had an "Ask Me Anything" session yesterday, and made it clear that he's changing things. From my point of view, it's changing to the worse. He made it clear that as long as Reddit itself does not get into legal trouble, and harrassment isn't too overt or particularly public, it's OK now. I've closed my Reddit account.

11 July 2015

Joey Hess: sweet summer

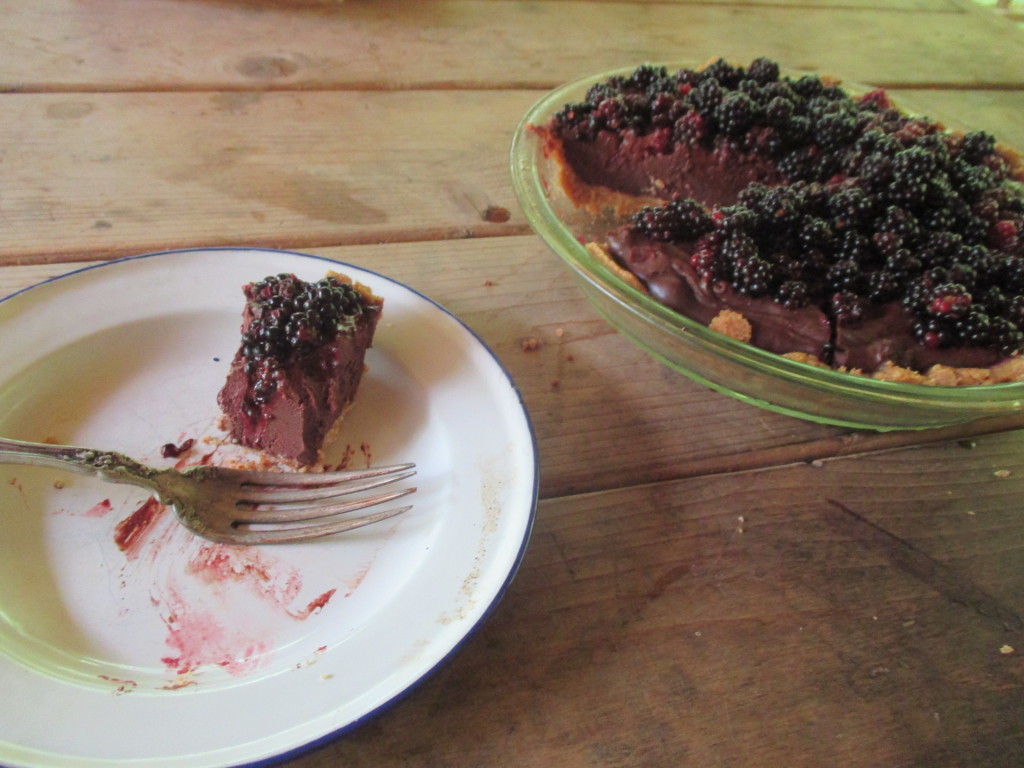
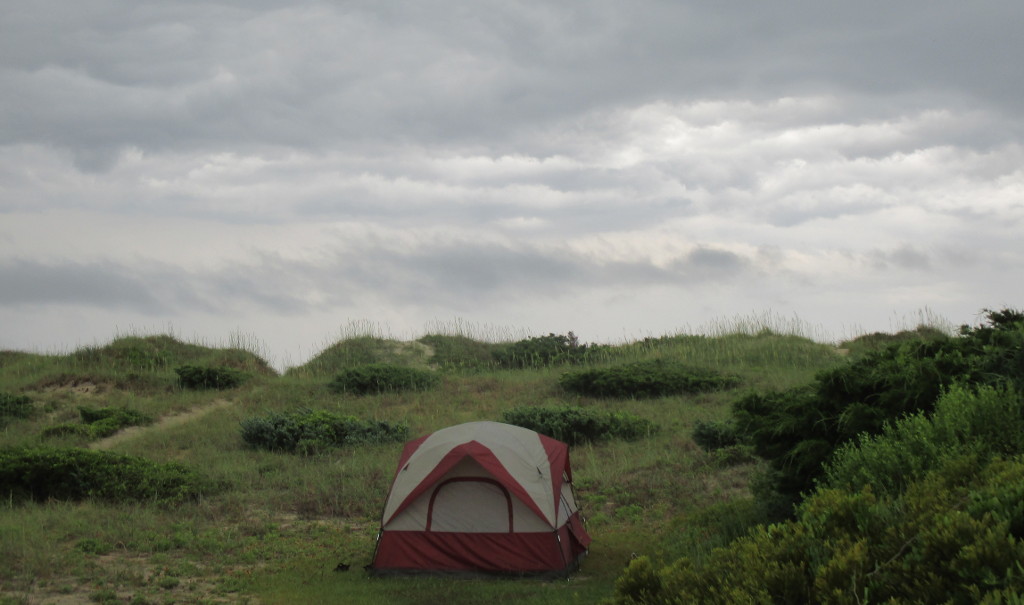
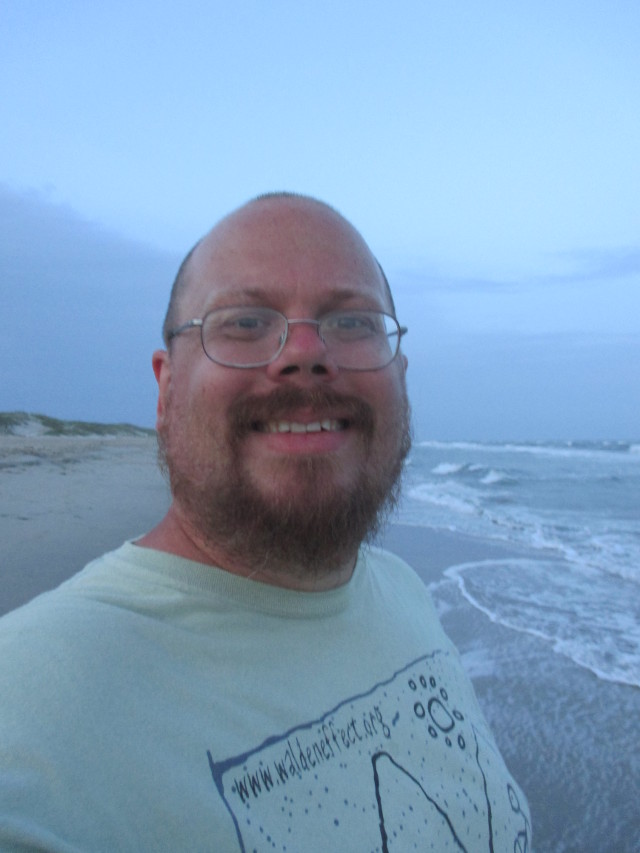
blackberrytart.jpg Having a wonderful summer, full of simple sweet pleasures. Mom visited today, and I made her this blackberry chocolate tart. Picking berries, swimming in the river, perfect summer day. dunetent.jpg Earlier this summer, camped at in the dunes on Ocracoke island with many family and friends. Thunderstorms away across the sound flashed and grumbled long in the night, but mostly missed us. Jupiter and Venus in conjunction overhead, and the arch of the milky way completed the show. beachselfie.jpg

10 July 2015

Chris Lamb: Where's the principled opposition to the "WhatsApp ban"?

The Independent reports that David Cameron wishes to ban the instant messaging application WhatsApp due its use of end-to-end encryption. That we might merely be pawns in manoeuvring for some future political compromise (or merely susceptible to cheap clickbait) should be cause for some concern, but what should worry us more is that if it takes scare stories about WhatsApp for our culture to awaken on the issues of privacy and civil liberties, then the central argument against surveillance was lost a long time ago. However, the situation worsens once you analyse the disapproval in more detail. One is immediately struck by a predominant narrative of technical considerations; a ban would be "unworkable" or "impractical". A robust defence of personal liberty or a warning about the insidious nature of chilling effects? Perhaps a prescient John Locke quote to underscore the case? No. An encryption ban would "cause security problems." The argument proceeds in a tediously predictable fashion: it was already difficult to keep track whether one should ipso facto be in favour of measures that benefit the economy, but we are suddenly co-opted as technocrats to consider the "damage" it could to do the recovery or the impact on a now-victimised financial sector. The coup-de-gr ce finally appeals to our already inflated self-regard and narcissism: someone could "steal your identity." Perhaps even more disappointing is the reaction from more technically-minded circles who, frankly, should know better. Here, they give the outward impression of metaphorically stockpiling copies of the GnuPG source code in their bunkers, perhaps believing the shallow techno-utopianist worldview that all social and cultural problems can probably be solved with Twitter and a JavaScript intepreter. The tragedy here is that I suspect that this isn't what the vast majority of people really believe. Given a hypothetical ban that could, somehow, bypass all of the stated concerns, I'm pretty upbeat and confident that most people would remain uncomfortable with it on some level. So what, exactly, does it take for us to oppose this kind of intervention on enduring principled grounds instead of transient and circumventable practical ones? Is the problem just a lack of vocabulary to discuss these issues on a social scale? A lack of courage? Whilst it's certainly easier to dissect illiberal measures on technical merit than to make an impassioned case for abstract freedoms, every time we gleefully cackle "it won't work" we are, in essence, conceding the central argument to the authoritarian and the censorious. If one is right but for the wrong reasons, were we even right to begin with?

Joey Hess: our beautiful fake histories

Here's an odd thing about the git bisect command: It has only 1 option (--no-checkout). Compare with eg git commit, which has 36 options by my count. The difference is largely down to git having a pervasive culture of carefully edited history. We need lots of git commit options to carefully produce commits that look Just Right. Staging only some of the files we've edited, perhaps even staging only some of the changes within a file. Amend that commit if we notice we made a mistake. Create a whole series of beautiful commits, and use rebase later to remix them into a more beautiful whole. Beautiful fake histories. Because coding is actually messy; our actual edit history contains blind alleys and doublings back on itself; contains periods of many days the code isn't building properly. We want to sweep that complexity away, hide it under the rug. This works well except when it doesn't, when some detail airbrushed out of the only remaining history turns out to be important. Once we have these beautiful fake histories of changes, we can easily bisect them and find the commit that introduced a bug. So bisect doesn't need a lot of options to control how it works. I'd like to suggest a new option though. At least as a thought experiment. --merges-only would make bisect only check the merge commits in the range of commits being bisected. The bisection would result in not a single commit, but in the set of commits between two merges. I suspect this would be useful for faster bisecting some histories of the beautiful fake kind. But I know it would be useful when the history is messy and organic and full of false starts and points where the code doesn't build. Merges, in such histories, are often the points where things reach a certian level of beauty, where that messy feature branch got to the point it all built again (please let this happen today) and was merged into master. Bisecting such points in a messy organic history should work about as well as bisecting carefully gardened histories. I think I'll save the full rant about beautiful fake history vs messy real history for some other day. Or maybe I've already ranted that rant here before, I can't remember. Let's just say that I personally come down on the side of liking my git history to reflect the actual code I was working on, even if it was broken and even if I threw it away later. I've indeed taken this to extreme lengths with propellor; in its git history you can see every time I've ever run it, and the version of my config file and code at that point. Apologies to anyone who's been put off by that... But oddly, propellor gets by far more contributions from others than any of my other haskell programs. All in the form of beaufiully constructed commits, naturally.

Gunnar Wolf: Finishing the course on "Free Software and Open Standards"

A couple of months ago, I was invited to give the starting course for the Masters degree in Free Software in the Universidad Andina Sim n Bol var university. UASB is a multinational university, with campuses in (at least) Ecuador, Chile, Bolivia and Colombia; I was doubtful at first regarding the seriousness of this proposal and the viability of the program, but time made my doubts disappear. Bolivia is going through an interesting process, as they have one of the strongest worded government mandates for migration to free software for the public administration in the next couple of years; this migration has prompted the interest of many professionals in the country. In particular, we have over 40 registered people for this Masters degree. Studying a Masters degree is a long-term commitment which signifies a big time investment, and although many of the student are quite new to the idea of free software, they are willing to spend this time (and money, as the university is privately owned and charges for its enrollment). I gave this class together with Alejandro Miranda (a.k.a. @pooka), as we have a very good pair-teaching dynamics; we had already given many conferences together, but this is the first time we had the opportunity to share a whole course and the experience was very good. We have read the students' logs, and many of them clearly agree with this. I had to skip two of the (ten) lessons, as I travelled from Mexico to Argentina halfway through it (of course, we brought the babies to meet my wife's family and friends!), so we had also the honor of having Esteban Lima fill in for those sessions. I am very happy and grateful that the University took care to record our presentations and intend to record and put online all of the classes; as we were the first in the program, there were some understandable hiccups and some sessions were lost, but most are available. Here they are, in case you are interested in refering to them:
Topic Video (my server) Video (Youtube)
Introduction to free software Watch Watch
History Watch Watch
Free culture N/A N/A
The effects of free software Watch Watch
Free software and open standards related to technologic soverignity Watch Watch
The free software ecosystem Watch Watch
Free software implementation in Bolivia Watch Watch
Introduction to intelectual property: Copyright, patents, trademarks, etc. Watch Watch
Who is "the community" and why do we speak about it? Watch Watch
Current status and challenges for the movement N/A N/A
We have yet another video file (which I have not fully followed through) titled ADSIB - Migration plan. It can also be downloaded from my server or watched online at Youtube. All in all: This was a great opportunity and a joy to do. I think the material we used and developed fit well what was expected from us, and we had fun giving somewhat heterodox readings on our movement.

9 July 2015

Sven Hoexter: Ubuntu 14.04 upstart and bonding

As usual when you add something new to your technology stack you'll find a "new" issue. A bit late in the game I made my first contact today with Ubuntu in the 14.04 incarnation when a colleague tried to stop and start a bond with:
ifdown bond0 && ifup bond0
About an hour later I had a virtual machine running and found the same bug in the pre-up ifenslave script which I later found to be already described in LP1269921. Apparantly Ubuntu integrated parts of the networking stuff with upstart and udev but did not care about how to cater people with bonding setups. At least the official documentation is very sparse on that topic. While someone from sysEleven rewrote the ifenslave script, I found that way too invasive and not well to handle. You can either push it via a configuration management system and overwrite a package owned script, or you roll you own package. So after some tinkering I decided to go with a different dirty workaround and setup the bond itself via pre-up snippets. In my test case it looks like this:
auto eth1 eth2 bond0
iface eth1 inet manual
  bond-master bond0
iface eth2 inet manual
  bond-master bond0
iface bond0 inet static
  address 192.168.1.1
  netmask 255.255.255.0
  bond-primary eth1
  bond-slaves eth1 eth2
  pre-up echo +bond0 > /sys/class/net/bonding_masters   true
  pre-up ifenslave bond0 eth1 eth2
I'm not yet sure if that breaks some other features of the ifenslave integration in ifupdown, but it seems to work so far. Let's see how far I can get with it.

8 July 2015

Sven Hoexter: for the reproducible builds gang

I gave up maintaining the LyX package about five years ago, but I still care. So I filled #9414 some time ago and it should be fixed for the next major release 2.2.0. So in case someone from the reproducible builds gang starts to look at LyX please hold the line and wait for the next major release instead.

Sven Hoexter: F5 BigIP and 1K DH parameter vs SSL Labs

So as a consequence of the weakdh issue(s) Qualys SSL Labs started to cap the rating at a B level if you provide DH cipher suites with 1K DH parameter. Now if you're terminating your TLS connections on F5s BigIP you're currently not able to change the DH parameter (they're random but of a fixed size). Finally there is a public comment from F5 written by Brian McHenry which is worth reading if you're running those boxes. As a side note, what most people running on TMOS 11.6.x should've already done is preferring ECDHE over DHE, which would look like this:
ciphers "!LOW:!SSLv3:!MD5:!RC4-SHA:!EXPORT:ECDHE+AES-GCM:ECDHE+AES:DHE+AES-GCM:DHE+AES:DHE+3DES:AES-GCM+RSA:RSA+AES:RSA+3DES"
That of course does not bring back the somewhat overrated A grade on the SSL Labs site. That boils down to choosing to provide DHE with 1K DH parameter or let everyone else, who does not yet support ECDHE, use RSA with your 2K public key. Honestly, for a public portal with a very wide range of users, I'm far from sure which one is the better choice. Looking at the weakest link "RSA+3DES" with TLSv1.0 is nothing that can convince the paranoid, but this cipher setting would bring you back the A grade:
ciphers "!LOW:!SSLv3:!MD5:!RC4-SHA:!EXPORT:ECDHE+AES-GCM:ECDHE+AES:AES-GCM+RSA:RSA+AES:RSA+3DES"

7 July 2015

Lunar: Reproducible builds: week 10 in Stretch cycle

What happened about the reproducible builds effort this week: Media coverage Daniel Stender published an English translation of the article which originally appeared in Linux Magazin in Admin Magazine. Toolchain fixes Fixes landed in the Debian archive: Lunar submitted to Debian the patch already sent upstream adding a --clamp-mtime option to tar. Patches have been submitted to add support for SOURCE_DATE_EPOCH to txt2man (Reiner Herrmann), epydoc (Reiner Herrmann), GCC (Dhole), and Doxygen (akira). Dhole uploaded a new experimental debhelper to the reproducible repository which exports SOURCE_DATE_EPOCH. As part of the experiment, the patch also sets TZ to UTC which should help with most timezone issues. It might still be problematic for some packages which would change their settings based on this. Mattia Rizzolo sent upstream a patch originally written by Lunar to make the generate-id() function be deterministic in libxslt. While that patch was quickly rejected by upstream, Andrew Ayer came up with a much better one which sadly could have some performance impact. Daniel Veillard replied with another patch that should be deterministic in most cases without needing extra data structures. It's impact is currently being investigated by retesting packages on reproducible.debian.net. akira added a new option to sbuild for configuring the path in which packages are built. This will be needed for the srebuild script. Niko Tyni asked Perl upstream about it using the __DATE__ and __TIME__ C processor macros. Packages fixed The following 143 packages became reproducible due to changes in their build dependencies: alot, argvalidate, astroquery, blender, bpython, brian, calibre, cfourcc, chaussette, checkbox-ng, cloc, configshell, daisy-player, dipy, dnsruby, dput-ng, dsc-statistics, eliom, emacspeak, freeipmi, geant321, gpick, grapefruit, heat-cfntools, imagetooth, jansson, jmapviewer, lava-tool, libhtml-lint-perl, libtime-y2038-perl, lift, lua-ldoc, luarocks, mailman-api, matroxset, maven-hpi-plugin, mknbi, mpi4py, mpmath, msnlib, munkres, musicbrainzngs, nova, pecomato, pgrouting, pngcheck, powerline, profitbricks-client, pyepr, pylibssh2, pylogsparser, pystemmer, pytest, python-amqp, python-apt, python-carrot, python-crypto, python-darts.lib.utils.lru, python-demgengeo, python-graph, python-mock, python-musicbrainz2, python-pathtools, python-pskc, python-psutil, python-pypump, python-repoze.sphinx.autointerface, python-repoze.tm2, python-repoze.what-plugins, python-repoze.what, python-repoze.who-plugins, python-xstatic-term.js, reclass, resource-agents, rgain, rttool, ruby-aggregate, ruby-archive-tar-minitar, ruby-bcat, ruby-blankslate, ruby-coffee-script, ruby-colored, ruby-dbd-mysql, ruby-dbd-odbc, ruby-dbd-pg, ruby-dbd-sqlite3, ruby-dbi, ruby-dirty-memoize, ruby-encryptor, ruby-erubis, ruby-fast-xs, ruby-fusefs, ruby-gd, ruby-git, ruby-globalhotkeys, ruby-god, ruby-hike, ruby-hmac, ruby-integration, ruby-ipaddress, ruby-jnunemaker-matchy, ruby-memoize, ruby-merb-core, ruby-merb-haml, ruby-merb-helpers, ruby-metaid, ruby-mina, ruby-net-irc, ruby-net-netrc, ruby-odbc, ruby-packet, ruby-parseconfig, ruby-platform, ruby-plist, ruby-popen4, ruby-rchardet, ruby-romkan, ruby-rubyforge, ruby-rubytorrent, ruby-samuel, ruby-shoulda-matchers, ruby-sourcify, ruby-test-spec, ruby-validatable, ruby-wirble, ruby-xml-simple, ruby-zoom, ryu, simplejson, spamassassin-heatu, speaklater, stompserver, syncevolution, syncmaildir, thin, ticgit, tox, transmissionrpc, vdr-plugin-xine, waitress, whereami, xlsx2csv, zathura. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which have not made their way to the archive yet: reproducible.debian.net A new package set for the X Strike Force has been added. (h01ger) Bugs tagged with locale are now visible in the statistics. (h01ger) Some work has been done add tests for NetBSD. (h01ger) Many changes by Mattia Rizzolo have been merged on the whole infrastructure: debbindiff development Version 26 has been released on June 28th fixing the comparison of files of unknown format. (Lunar) A missing dependency identified in python-rpm affecting debbindiff installation without recommended packages was promptly fixed by Michal iha . Lunar also started a massive code rearchitecture to enhance code reuse and enable new features. Nothing visible yet, though. Documentation update josch and Mattia Rizzolo documented how to reschedule packages from Alioth. Package reviews 142 obsolete reviews have been removed, 344 added and 107 updated this week. Chris West (Faux) filled 13 new bugs for packages failing to build from sources. The following new issues have been added: snapshot_placeholder_replaced_with_timestamp_in_pom_properties, different_encoding, timestamps_in_documentation_generated_by_org_mode and timestamps_in_pdf_generated_by_matplotlib.

Petter Reinholdtsen: MPEG LA on "Internet Broadcast AVC Video" licensing and non-private use

After asking the Norwegian Broadcasting Company (NRK) why they can broadcast and stream H.264 video without an agreement with the MPEG LA, I was wiser, but still confused. So I asked MPEG LA if their understanding matched that of NRK. As far as I can tell, it does not. I started by asking for more information about the various licensing classes and what exactly is covered by the "Internet Broadcast AVC Video" class that NRK pointed me at to explain why NRK did not need a license for streaming H.264 video:
According to a MPEG LA press release dated 2010-02-02, there is no charge when using MPEG AVC/H.264 according to the terms of "Internet Broadcast AVC Video". I am trying to understand exactly what the terms of "Internet Broadcast AVC Video" is, and wondered if you could help me. What exactly is covered by these terms, and what is not? The only source of more information I have been able to find is a PDF named AVC Patent Portfolio License Briefing, which states this about the fees:
  • Where End User pays for AVC Video
    • Subscription (not limited by title) 100,000 or fewer subscribers/yr = no royalty; > 100,000 to 250,000 subscribers/yr = $25,000; >250,000 to 500,000 subscribers/yr = $50,000; >500,000 to 1M subscribers/yr = $75,000; >1M subscribers/yr = $100,000
    • Title-by-Title - 12 minutes or less = no royalty; >12 minutes in length = lower of (a) 2% or (b) $0.02 per title
  • Where remuneration is from other sources
    • Free Television - (a) one-time $2,500 per transmission encoder or (b) annual fee starting at $2,500 for > 100,000 HH rising to maximum $10,000 for >1,000,000 HH
    • Internet Broadcast AVC Video (not title-by-title, not subscription) no royalty for life of the AVC Patent Portfolio License
Am I correct in assuming that the four categories listed is the categories used when selecting licensing terms, and that "Internet Broadcast AVC Video" is the category for things that do not fall into one of the other three categories? Can you point me to a good source explaining what is ment by "title-by-title" and "Free Television" in the license terms for AVC/H.264? Will a web service providing H.264 encoded video content in a "video on demand" fashing similar to Youtube and Vimeo, where no subscription is required and no payment is required from end users to get access to the videos, fall under the terms of the "Internet Broadcast AVC Video", ie no royalty for life of the AVC Patent Portfolio license? Does it matter if some users are subscribed to get access to personalized services? Note, this request and all answers will be published on the Internet.
The answer came quickly from Benjamin J. Myers, Licensing Associate with the MPEG LA:
Thank you for your message and for your interest in MPEG LA. We appreciate hearing from you and I will be happy to assist you. As you are aware, MPEG LA offers our AVC Patent Portfolio License which provides coverage under patents that are essential for use of the AVC/H.264 Standard (MPEG-4 Part 10). Specifically, coverage is provided for end products and video content that make use of AVC/H.264 technology. Accordingly, the party offering such end products and video to End Users concludes the AVC License and is responsible for paying the applicable royalties. Regarding Internet Broadcast AVC Video, the AVC License generally defines such content to be video that is distributed to End Users over the Internet free-of-charge. Therefore, if a party offers a service which allows users to upload AVC/H.264 video to its website, and such AVC Video is delivered to End Users for free, then such video would receive coverage under the sublicense for Internet Broadcast AVC Video, which is not subject to any royalties for the life of the AVC License. This would also apply in the scenario where a user creates a free online account in order to receive a customized offering of free AVC Video content. In other words, as long as the End User is given access to or views AVC Video content at no cost to the End User, then no royalties would be payable under our AVC License. On the other hand, if End Users pay for access to AVC Video for a specific period of time (e.g., one month, one year, etc.), then such video would constitute Subscription AVC Video. In cases where AVC Video is delivered to End Users on a pay-per-view basis, then such content would constitute Title-by-Title AVC Video. If a party offers Subscription or Title-by-Title AVC Video to End Users, then they would be responsible for paying the applicable royalties you noted below. Finally, in the case where AVC Video is distributed for free through an "over-the-air, satellite and/or cable transmission", then such content would constitute Free Television AVC Video and would be subject to the applicable royalties. For your reference, I have attached a .pdf copy of the AVC License. You will find the relevant sublicense information regarding AVC Video in Sections 2.2 through 2.5, and the corresponding royalties in Section 3.1.2 through 3.1.4. You will also find the definitions of Title-by-Title AVC Video, Subscription AVC Video, Free Television AVC Video, and Internet Broadcast AVC Video in Section 1 of the License. Please note that the electronic copy is provided for informational purposes only and cannot be used for execution. I hope the above information is helpful. If you have additional questions or need further assistance with the AVC License, please feel free to contact me directly.
Having a fresh copy of the license text was useful, and knowing that the definition of Title-by-Title required payment per title made me aware that my earlier understanding of that phrase had been wrong. But I still had a few questions:
I have a small followup question. Would it be possible for me to get a license with MPEG LA even if there are no royalties to be paid? The reason I ask, is that some video related products have a copyright clause limiting their use without a license with MPEG LA. The clauses typically look similar to this:
This product is licensed under the AVC patent portfolio license for the personal and non-commercial use of a consumer to (a) encode video in compliance with the AVC standard ("AVC video") and/or (b) decode AVC video that was encoded by a consumer engaged in a personal and non-commercial activity and/or AVC video that was obtained from a video provider licensed to provide AVC video. No license is granted or shall be implied for any other use. additional information may be obtained from MPEG LA L.L.C.
It is unclear to me if this clause mean that I need to enter into an agreement with MPEG LA to use the product in question, even if there are no royalties to be paid to MPEG LA. I suspect it will differ depending on the jurisdiction, and mine is Norway. What is MPEG LAs view on this?
According to the answer, MPEG LA believe those using such tools for non-personal or commercial use need a license with them:
With regard to the Notice to Customers, I would like to begin by clarifying that the Notice from Section 7.1 of the AVC License reads: THIS PRODUCT IS LICENSED UNDER THE AVC PATENT PORTFOLIO LICENSE FOR THE PERSONAL USE OF A CONSUMER OR OTHER USES IN WHICH IT DOES NOT RECEIVE REMUNERATION TO (i) ENCODE VIDEO IN COMPLIANCE WITH THE AVC STANDARD ("AVC VIDEO") AND/OR (ii) DECODE AVC VIDEO THAT WAS ENCODED BY A CONSUMER ENGAGED IN A PERSONAL ACTIVITY AND/OR WAS OBTAINED FROM A VIDEO PROVIDER LICENSED TO PROVIDE AVC VIDEO. NO LICENSE IS GRANTED OR SHALL BE IMPLIED FOR ANY OTHER USE. ADDITIONAL INFORMATION MAY BE OBTAINED FROM MPEG LA, L.L.C. SEE HTTP://WWW.MPEGLA.COM The Notice to Customers is intended to inform End Users of the personal usage rights (for example, to watch video content) included with the product they purchased, and to encourage any party using the product for commercial purposes to contact MPEG LA in order to become licensed for such use (for example, when they use an AVC Product to deliver Title-by-Title, Subscription, Free Television or Internet Broadcast AVC Video to End Users, or to re-Sell a third party's AVC Product as their own branded AVC Product). Therefore, if a party is to be licensed for its use of an AVC Product to Sell AVC Video on a Title-by-Title, Subscription, Free Television or Internet Broadcast basis, that party would need to conclude the AVC License, even in the case where no royalties were payable under the License. On the other hand, if that party (either a Consumer or business customer) simply uses an AVC Product for their own internal purposes and not for the commercial purposes referenced above, then such use would be included in the royalty paid for the AVC Products by the licensed supplier. Finally, I note that our AVC License provides worldwide coverage in countries that have AVC Patent Portfolio Patents, including Norway. I hope this clarification is helpful. If I may be of any further assistance, just let me know.
The mentioning of Norwegian patents made me a bit confused, so I asked for more information:
But one minor question at the end. If I understand you correctly, you state in the quote above that there are patents in the AVC Patent Portfolio that are valid in Norway. This make me believe I read the list available from <URL: http://www.mpegla.com/main/programs/AVC/Pages/PatentList.aspx > incorrectly, as I believed the "NO" prefix in front of patents were Norwegian patents, and the only one I could find under Mitsubishi Electric Corporation expired in 2012. Which patents are you referring to that are relevant for Norway?
Again, the quick answer explained how to read the list of patents in that list:
Your understanding is correct that the last AVC Patent Portfolio Patent in Norway expired on 21 October 2012. Therefore, where AVC Video is both made and Sold in Norway after that date, then no royalties would be payable for such AVC Video under the AVC License. With that said, our AVC License provides historic coverage for AVC Products and AVC Video that may have been manufactured or Sold before the last Norwegian AVC patent expired. I would also like to clarify that coverage is provided for the country of manufacture and the country of Sale that has active AVC Patent Portfolio Patents. Therefore, if a party offers AVC Products or AVC Video for Sale in a country with active AVC Patent Portfolio Patents (for example, Sweden, Denmark, Finland, etc.), then that party would still need coverage under the AVC License even if such products or video are initially made in a country without active AVC Patent Portfolio Patents (for example, Norway). Similarly, a party would need to conclude the AVC License if they make AVC Products or AVC Video in a country with active AVC Patent Portfolio Patents, but eventually Sell such AVC Products or AVC Video in a country without active AVC Patent Portfolio Patents.
As far as I understand it, MPEG LA believe anyone using Adobe Premiere and other video related software with a H.264 distribution license need a license agreement with MPEG LA to use such tools for anything non-private or commercial, while it is OK to set up a Youtube-like service as long as no-one pays to get access to the content. I still have no clear idea how this applies to Norway, where none of the patents MPEG LA is licensing are valid. Will the copyright terms take precedence or can those terms be ignored because the patents are not valid in Norway?

Russ Allbery: INN 2.6.0 release candidate

In more INN-related news (and catching up on my substantial backlog), a second release candidate for the INN 2.6.0 release is now available. (The first one was only circulated on the inn-workers mailing list.) INN 2.6.0 is the next major release of INN, with lots of improvements to the build system, protocol support, and the test suite, among many other things. Changes have been accumulating slowly for quite some time. There are a lot of changes, so I won't go into all the details here. If you're curious, take a look at the NEWS file. You can get the release candidate from ftp.isc.org. (Note that this link will be removed once INN 2.6.0 is released.) As always, thanks to Julien LIE for preparing this release and doing most of the maintenance work on INN! For more information about INN, see the official ISC download page or from my personal INN pages. The latter also has links to the full changelog and the other INN documentation.

Matthew Palmer: It's 10pm, do you know where your SSL certificates are?

The Internet is going encrypted. Revelations of mass-surveillance of Internet traffic has given the Internet community the motivation to roll out encrypted services the biggest of which is undoubtedly HTTP. The weak point, though, is SSL Certification Authorities. These are trusted third parties who are supposed to validate that a person requesting a certificate for a domain is authorised to have a certificate for that domain. It is no secret that these companies have failed to do the job entrusted to them, again, and again, and again. Oh, and another one. However, at this point, doing away with CAs and finding some other mechanism isn t feasible. There is no clear alternative, and the inertia in the current system is overwhelming, to the point where it would take a decade or more to migrate away from the CA-backed SSL certificate ecosystem, even if there was something that was widely acknowledged to be superior in every possible way. This is where Certificate Transparency comes in. This protocol, which works as part of the existing CA ecosystem, requires CAs to publish every certificate they issue, in order for the certificate to be considered valid by browsers and other user agents. While it doesn t guarantee to prevent misissuance, it does mean that a CA can t cover up or try to minimise the impact of a breach or other screwup their actions are fully public, for everyone to see. Much of Certificate Transparency s power, however, is diminished if nobody is looking at the certificates which are being published. That is why I have launched sslaware.com, a site for searching the database of logged certificates. At present, it is rather minimalist, however I intend on adding more features, such as real-time notifications (if a new cert for your domain or organisation is logged, you ll get an e-mail about it), and more advanced searching capabilities. If you care about the security of your website, you should check out SSL Aware and see what certificates have been issued for your site. You may be unpleasantly surprised.

6 July 2015

Ben Hutchings: Debian LTS work, June 2015

This was my seventh month working on Debian LTS. I was assigned 14.75 hours of work by Freexian's Debian LTS initiative. p7zip I did not receive any feedback from upstream for my proposed fix for CVE-2015-1038 mentioned last month, so I went ahead and uploaded it based on my own testing. (I also uploaded the fix to wheezy-security, jessie-security and sid.) Afterwards, I received a request from upstream for a patch against their latest release (even the version in sid is quite a long way behind that), so I ported the fix forward to that. linux-2.6 I backported further security fixes, but had to give up on one (CVE-2014-8172, AIO soft lockup) as the fix depends on wide-ranging changes. For CVE-2015-1805 (pipe iovec overrun leading to memory corruption), the upstream fix was also not applicable, but this looked so serious that we needed to fix it anyway. Red Hat had already fixed this in their 2.6.32-based kernel and they didn't have overlapping changes to the pipe implementation, so I was able to extract this fix from their source tarball. I uploaded and issued DLA-246-1. Unfortunately, I failed to notice that Linux 2.6.32.66 had introduced two regressions that were fixed in 2.6.32.67. While these didn't appear in my testing, one of them did affect several users that were quick to upgrade. I applied the upstream fixes, made a second upload and issued DLA-246-2. I also triaged the issues that are still unfixed, and I spent some time working on a fix for CVE-2015-1350 (unprivileged chown removes setcap attribute), but I haven't yet completed the backport to 2.6.32 or tested it. openssl I looked at OpenSSL, which is still marked as affected by CVE-2015-4000 (encryption downgrade aka Logjam). After discussion with the LTS team I made a note of the current situation, which is that a full fix (rejecting Diffie-Hellman keys shorter than 1024 bits) must wait until more servers have been upgraded.

Mike Gabriel: My FLOSS activities in June 2015

June 2015 has been mainly dedicated to these five fields of endeavour: Received Sponsorship Last month's contributions of mine (8h) to the Debian LTS project had been contracted by Freexian [1] again. Thanks to Raphael Hertzog for having me on the team. Thanks to all the people and companies sponsoring the Debian LTS Team's work. Also a big thanks to people from Hetzner GmbH for sponsoring my stay at X2Go: The Gathering 2015 @ Linuxhotel (in Essen, Germany). MATE 1.10 entering Debian experimental Together with Martin Wimpress from Ubuntu MATE and other people in the Debian MATE Packaging Team I managed to upload a great portion of the MATE 1.10 packages to Debian experimental. Please note that this is still work in progress. Not all MATE 1.10 packages have been uploaded yet and several packages from the MATE 1.10 series in Debian have grave bugs still (mostly packaging and installation issues). The plan is to make the complete MATE 1.10 stack available in Debian experimental by the end of July and also get all the open kinks fixed by then. Development nx-libs 3.6.x In June 2015, I have looked at various aspects of nx-libs development: read more

Ritesh Raj Sarraf: Apport Integration with Debian - GSoC Update

For this year's Google Summer of Code, I have been mentoring Yuru Roy Shao, on Integrating Apport with Debian. Yuru is a CS student studying at University of Michigan, USA completing his PhD. For around 2+ years, Apport was packaged for Debian, but remained in Experimental. While we did have a separate (Debian BTS aware) crashdb, the general concerns (bug spam, too many duplicates etc) were the reason we held its inclusion. With this GSoC, Yuru has been bringing some of the missing integration pieces of Debian. For example, we are now using debianbts to to talk to the Debian BTS Server, and fetch bug reports for the user. While apport's Bug Report data collection itself is very comprehensive, still for Debian, it will have the option to use native as well as reportbug. This will allow us to use the many hooks people have integrated so far with reportbug. Both Bug Report data collectors will be available. Yuru has blogged about his GSoC progress so far, here. Please do have a read, and let us know your views. If the travel formalities work out well, I intend to attend Debconf this year, and can talk in more detail.

Categories:

Keywords:

Like:

Russ Allbery: INN 2.5.5

(This release has actually been ready for a while, but there were a few technical difficulties with getting it copied up to the right places, and then I got very distracted by various life stuff.) This is the first new release of INN in about a year, and hopefully the last in the 2.5.x series. A beta release of INN 2.6.0 will be announced shortly (probably tomorrow). As is typical for bug-fix releases, this release rolls up a bunch of small bug fixes that have been made over the past year. The most notable changes include new inn.conf parameters to fine-tune the SSL/TLS configuration for nnrpd (generally to tighten it over the OpenSSL defaults), a few new flags to various utilities, multiple improvements to pullnews, and support for properly stopping cnfsstat and innwatch if INN is started and then quickly stopped. As always, thanks to Julien LIE for preparing this release and doing most of the maintenance work on INN! You can get the latest version from the official ISC download page or from my personal INN pages. The latter also has links to the full changelog and the other INN documentation.

5 July 2015

Ben Armstrong: BLT Bike Trail Early Summer 2015

This is one of my regular walking routes, from home to Five Island Lake and back. It s about 15 km. I usually walk too briskly to capture the many visual delights of this route. Today on the trip out, I stopped and took several photos to share with you. [slb_group]
An early morning walk up the BLT bike trail. Click to start the slideshow.An early morning walk up the BLT bike trail to Five Island Lake (pictured here) and back. Click to start the slideshow.
The walk starts from our subdivision. It s cool and clear when I leave. Saskatoon berries Saskatoon berries Saskatoon berries Dew on leaves Dew on leaves Pitcher plants Something s attacking this alder. Maybe woolly aphids? Wild strawberries Wild strawberry Wild strawberry Wild strawberry Wild strawberries Daisy Daisy Vetch Vetch Water lily Water lily Sensitive fern Squirrel! Cranberry Lake Cranberry Lake
[/slb_group]

Thorsten Alteholz: My Debian Activities in June 2015

FTP assistant This month I marked 539 packages for accept, rejected 61 of them and had to send 24 emails to maintainers. This is a new personal record. Even in the month before the Jessie freeze I accepted only 407 packages. So, very well done (self-laudation has to happen from time to time :-) ). Another record was broken as well. After 19 month of doing this kind of work, I got my first insulting email. I would prefer to wait another 19 month before I get the next one Squeeze LTS This was my twelfth month that I did some work for the Squeeze LTS initiative, started by Raphael Hertzog at Freexian. This month I got assigned a workload of only 14.5h and I spent most of it to work on a new upload of php5. Unfortunately there have been so many CVEs comming in, that I didn t do an upload yet. Other stuff I uploaded was This month I also had my first one and a half weeks of doing frontdesk work. As introduced in this email, every member of the LTS team should do some LTS CVE triage. Up to now it was mainly done by Raphael and he wants to share this task with everybody else. So I answered questions on the IRC channel, on the LTS list and looked for CVEs that are important for Squeeze LTS or could be ignored. Other stuff This month I also uploaded a new version of harminv and wondered why the package didn t move to testing. Of course there is a document how to do a transition of a library properly. But hey, it is me, I know everything better and of course I can use a shortcut. Oh boy, I was wrong. So I also uploaded new versions of meep, meep-lam4, meep-openmpi, meep-mpi-default and meep-mpich2. And the moral of the story: If you don t understand why something should be done in a specific way, you shouldn t try to do it different. Donations Again, thanks alot to all donors. I really appreciate this and hope that everybody is pleased with my commitment. Don t hesitate to make suggestions for improvements.

Petter Reinholdtsen: New laptop - some more clues and ideas based on feedback

Several people contacted me after my previous blog post about my need for a new laptop, and provided very useful feedback. I wish to thank every one of these. Several pointed me to the possibility of fixing my X230, and I am already in the process of getting Lenovo to do so thanks to the on site, next day support contract covering the machine. But the battery is almost useless (I expect to replace it with a non-official battery) and I do not expect the machine to live for many more years, so it is time to plan its replacement. If I did not have a support contract, it was suggested to find replacement parts using FrancEcrans, but it might present a language barrier as I do not understand French. One tip I got was to use the Skinflint web service to compare laptop models. It seem to have more models available than prisjakt.no. Another tip I got from someone I know have similar keyboard preferences was that the HP EliteBook 840 keyboard is not very good, and this matches my experience with earlier EliteBook keyboards I tested. Because of this, I will not consider it any further. When I wrote my blog post, I was not aware of Thinkpad X250, the newest Thinkpad X model. The keyboard reintroduces mouse buttons (which is missing from the X240), and is working fairly well with Debian Sid/Unstable according to Corsac.net. The reports I got on the keyboard quality are not consistent. Some say the keyboard is good, others say it is ok, while others say it is not very good. Those with experience from X41 and and X60 agree that the X250 keyboard is not as good as those trusty old laptops, and suggest I keep and fix my X230 instead of upgrading, or get a used X230 to replace it. I'm also told that the X250 lack leds for caps lock, disk activity and battery status, which is very convenient on my X230. I'm also told that the CPU fan is running very often, making it a bit noisy. In any case, the X250 do not work out of the box with Debian Stable/Jessie, one of my requirements. I have also gotten a few vendor proposals, one was Pro-Star, another was Libreboot. The latter look very attractive to me. Again, thank you all for the very useful feedback. It help a lot as I keep looking for a replacement. Update 2015-07-06: I was recommended to check out the lapstore.de web shop for used laptops. They got several different old thinkpad X models, and provide one year warranty.

Robert Edmonds: Git packaging workflow for py-lmdb

Recently, I packaged the py-lmdb Python binding for the LMDB database library. This package is going to be team maintained by the pkg-db group, which is responsible for maintaining BerkeleyDB and LMDB packages. Below are my notes on (re-)Debianizing this package and how the Git repository for the source package is laid out. The upstream py-lmdb developer has a Git-centric workflow. Development is done on the master branch, with regular releases done as fast-forward merges to the release branch. Release tags of the form py-lmdb_X.YZ are provided. The only tarballs provided are the ones that GitHub automatically generates from tags. Since these tarballs are synthetic and the content of these tarballs matches the content on the corresponding tag, we will ignore them in favor of using the release tags directly. (The --git-pristine-tar-commit option to gbp-buildpackage will be used so that .orig.tar.gz files can be replicated so that the Debian archive will accept subsequent uploads, but tarballs are otherwise irrelevant to our workflow.) To make it clear that the release tags come from upstream's repository, they should be prefixed with upstream/, which would preferably result in a DEP-14 compliant scheme. (Unfortunately, since upstream's release tags begin with py-lmdb_, this doesn't quite match the pattern that DEP-14 recommends.) Here is how the local packaging repository is initialized. Note that git clone isn't used, so that we can customize how the tags are fetched. Instead, we create an empty Git repository and add the upstream repository as the upstream remote. The --no-tags option is used, so that git fetch does not import the remote's tags. However, we also add a custom fetch refspec refs/tags/*:refs/tags/upstream/* so that the remote's tags are explicitly fetched, but with the upstream/ prefix.
$ mkdir py-lmdb
$ cd py-lmdb
$ git init
Initialized empty Git repository in /home/edmonds/debian/py-lmdb/.git/
$ git remote add --no-tags upstream https://github.com/dw/py-lmdb
$ git config --add remote.upstream.fetch 'refs/tags/*:refs/tags/upstream/*'
$ git fetch upstream
remote: Counting objects: 3336, done.
remote: Total 3336 (delta 0), reused 0 (delta 0), pack-reused 3336
Receiving objects: 100% (3336/3336), 2.15 MiB   0 bytes/s, done.
Resolving deltas: 100% (1958/1958), done.
From https://github.com/dw/py-lmdb
 * [new branch]      master     -> upstream/master
 * [new branch]      release    -> upstream/release
 * [new branch]      win32-sparse-patch -> upstream/win32-sparse-patch
 * [new tag]         last-cython-version -> upstream/last-cython-version
 * [new tag]         py-lmdb_0.1 -> upstream/py-lmdb_0.1
 * [new tag]         py-lmdb_0.2 -> upstream/py-lmdb_0.2
 * [new tag]         py-lmdb_0.3 -> upstream/py-lmdb_0.3
 * [new tag]         py-lmdb_0.4 -> upstream/py-lmdb_0.4
 * [new tag]         py-lmdb_0.5 -> upstream/py-lmdb_0.5
 * [new tag]         py-lmdb_0.51 -> upstream/py-lmdb_0.51
 * [new tag]         py-lmdb_0.52 -> upstream/py-lmdb_0.52
 * [new tag]         py-lmdb_0.53 -> upstream/py-lmdb_0.53
 * [new tag]         py-lmdb_0.54 -> upstream/py-lmdb_0.54
 * [new tag]         py-lmdb_0.56 -> upstream/py-lmdb_0.56
 * [new tag]         py-lmdb_0.57 -> upstream/py-lmdb_0.57
 * [new tag]         py-lmdb_0.58 -> upstream/py-lmdb_0.58
 * [new tag]         py-lmdb_0.59 -> upstream/py-lmdb_0.59
 * [new tag]         py-lmdb_0.60 -> upstream/py-lmdb_0.60
 * [new tag]         py-lmdb_0.61 -> upstream/py-lmdb_0.61
 * [new tag]         py-lmdb_0.62 -> upstream/py-lmdb_0.62
 * [new tag]         py-lmdb_0.63 -> upstream/py-lmdb_0.63
 * [new tag]         py-lmdb_0.64 -> upstream/py-lmdb_0.64
 * [new tag]         py-lmdb_0.65 -> upstream/py-lmdb_0.65
 * [new tag]         py-lmdb_0.66 -> upstream/py-lmdb_0.66
 * [new tag]         py-lmdb_0.67 -> upstream/py-lmdb_0.67
 * [new tag]         py-lmdb_0.68 -> upstream/py-lmdb_0.68
 * [new tag]         py-lmdb_0.69 -> upstream/py-lmdb_0.69
 * [new tag]         py-lmdb_0.70 -> upstream/py-lmdb_0.70
 * [new tag]         py-lmdb_0.71 -> upstream/py-lmdb_0.71
 * [new tag]         py-lmdb_0.72 -> upstream/py-lmdb_0.72
 * [new tag]         py-lmdb_0.73 -> upstream/py-lmdb_0.73
 * [new tag]         py-lmdb_0.74 -> upstream/py-lmdb_0.74
 * [new tag]         py-lmdb_0.75 -> upstream/py-lmdb_0.75
 * [new tag]         py-lmdb_0.76 -> upstream/py-lmdb_0.76
 * [new tag]         py-lmdb_0.77 -> upstream/py-lmdb_0.77
 * [new tag]         py-lmdb_0.78 -> upstream/py-lmdb_0.78
 * [new tag]         py-lmdb_0.79 -> upstream/py-lmdb_0.79
 * [new tag]         py-lmdb_0.80 -> upstream/py-lmdb_0.80
 * [new tag]         py-lmdb_0.81 -> upstream/py-lmdb_0.81
 * [new tag]         py-lmdb_0.82 -> upstream/py-lmdb_0.82
 * [new tag]         py-lmdb_0.83 -> upstream/py-lmdb_0.83
 * [new tag]         py-lmdb_0.84 -> upstream/py-lmdb_0.84
 * [new tag]         py-lmdb_0.85 -> upstream/py-lmdb_0.85
 * [new tag]         py-lmdb_0.86 -> upstream/py-lmdb_0.86
$
Note that at this point we have content from the upstream remote in our local repository, but we don't have any local branches:
$ git status
On branch master
Initial commit
nothing to commit (create/copy files and use "git add" to track)
$ git branch -a
  remotes/upstream/master
  remotes/upstream/release
  remotes/upstream/win32-sparse-patch
$
We will use the DEP-14 naming scheme for the packaging branches, so the branch for packages targeted at unstable will be called debian/sid. Since I already made an initial 0.84-1 upload, we need to start the debian/sid branch from the upstream 0.84 tag and import the original packaging content from that upload. The --no-track flag is passed to git checkout initially so that Git doesn't consider the upstream release tag upstream/py-lmdb_0.84 to be the upstream branch for our packaging branch.
$ git checkout --no-track -b debian/sid upstream/py-lmdb_0.84
Switched to a new branch 'debian/sid'
$
At this point I imported the original packaging content for 0.84-1 with git am. Then, I signed the debian/0.84-1 tag:
$ git tag -s -m 'Debian release 0.84-1' debian/0.84-1
$ git verify-tag debian/0.84-1
gpg: Signature made Sat 04 Jul 2015 02:49:42 PM EDT using RSA key ID AAF6CDAE
gpg: Good signature from "Robert Edmonds <edmonds@mycre.ws>" [ultimate]
gpg:                 aka "Robert Edmonds <edmonds@fsi.io>" [ultimate]
gpg:                 aka "Robert Edmonds <edmonds@debian.org>" [ultimate]
$
New upstream releases are integrated by fetching new upstream tags and non-fast-forward merging into the packaging branch. The latest release is 0.86, so we merge from the upstream/py-lmdb_0.86 tag.
$ git fetch upstream --dry-run
[...]
$ git fetch upstream
[...]
$ git checkout debian/sid
Already on 'debian/sid'
$ git merge --no-ff --no-edit upstream/py-lmdb_0.86
Merge made by the 'recursive' strategy.
 ChangeLog                        46 ++++++++++++++
 docs/index.rst                   46 +++++++++++++-
 docs/themes/acid/layout.html      4 +-
 examples/dirtybench-gdbm.py       6 ++
 examples/dirtybench.py           19 ++++++
 examples/nastybench.py           18 ++++--
 examples/parabench.py             6 ++
 lib/lmdb.h                       37 ++++++-----
 lib/mdb.c                       281 ++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++---------------------
 lib/midl.c                        2 +-
 lib/midl.h                        2 +-
 lib/py-lmdb/preload.h            48 ++++++++++++++
 lmdb/__init__.py                  2 +-
 lmdb/cffi.py                    120 ++++++++++++++++++++++++-----------
 lmdb/cpython.c                   86 +++++++++++++++++++------
 lmdb/tool.py                      5 +-
 misc/gdb.commands                21 ++++++
 misc/runtests-travisci.sh         3 +-
 misc/runtests-ubuntu-12-04.sh    28 ++++----
 setup.py                          2 +
 tests/crash_test.py              22 +++++++
 tests/cursor_test.py             37 +++++++++++
 tests/env_test.py                73 +++++++++++++++++++++
 tests/testlib.py                 14 +++-
 tests/txn_test.py                20 ++++++
 25 files changed, 773 insertions(+), 175 deletions(-)
 create mode 100644 lib/py-lmdb/preload.h
 create mode 100644 misc/gdb.commands
$
Here I did some additional development work like editing the debian/gbp.conf file and applying a fix for #790738 to make the package build reproducibly. The package is now ready for an 0.86-1 upload, so I ran the following gbp dch command:
$ gbp dch --release --auto --new-version=0.86-1 --commit
gbp:info: Found tag for topmost changelog version '6bdbb56c04571fe2d5d22aa0287ab0dc83959de5'
gbp:info: Continuing from commit '6bdbb56c04571fe2d5d22aa0287ab0dc83959de5'
gbp:info: Changelog has been committed for version 0.86-1
$
This automatically generates a changelog entry for 0.86-1, but it includes commit summaries for all of the upstream commits since the last release, which I had to edit out. Then, I used gbp buildpackage with BUILDER=pbuilder to build the package in a clean, up-to-date sid chroot. After checking the result, I signed the debian/0.86-1 tag:
$ git tag -s -m 'Debian release 0.86-1' debian/0.86-1
$
The package is now ready to be pushed to git.debian.org. First, a bare repository is initialized:
$ ssh git.debian.org
edmonds@moszumanska:~$ cd /srv/git.debian.org/git/pkg-db/
edmonds@moszumanska:/srv/git.debian.org/git/pkg-db$ umask 002
edmonds@moszumanska:/srv/git.debian.org/git/pkg-db$ mkdir py-lmdb.git
edmonds@moszumanska:/srv/git.debian.org/git/pkg-db$ cd py-lmdb.git/
edmonds@moszumanska:/srv/git.debian.org/git/pkg-db/py-lmdb.git$ git --bare init --shared
Initialized empty shared Git repository in /srv/git.debian.org/git/pkg-db/py-lmdb.git/
edmonds@moszumanska:/srv/git.debian.org/git/pkg-db/py-lmdb.git$ echo 'py-lmdb Debian packaging' > description
edmonds@moszumanska:/srv/git.debian.org/git/pkg-db/py-lmdb.git$ mv hooks/post-update.sample hooks/post-update
edmonds@moszumanska:/srv/git.debian.org/git/pkg-db/py-lmdb.git$ chmod a+x hooks/post-update
edmonds@moszumanska:/srv/git.debian.org/git/pkg-db/py-lmdb.git$ logout
Shared connection to git.debian.org closed.
Then, we add a new debian remote to our local packaging repository. Per our repository conventions, we need to ensure that only branch names matching debian/* and pristine-tar and tag names matching debian/* and upstream/* are pushed to the debian remote when we run git push debian, so we add a a set of remote.debian.push refspecs that correspond to these conventions. We also add an explicit remote.debian.fetch refspec to fetch tags.
$ git remote add debian ssh://git.debian.org/git/pkg-db/py-lmdb.git
$ git config --add remote.debian.push 'refs/tags/debian/*'
$ git config --add remote.debian.push 'refs/tags/upstream/*'
$ git config --add remote.debian.push 'refs/heads/debian/*'
$ git config --add remote.debian.push 'refs/heads/pristine-tar'
$ git config --add remote.debian.fetch 'refs/tags/*:refs/tags/*'
We now run the initial push to the remote Git repository. The --set-upstream option is used so that our local branches will be configured to track the corresponding remote branches. Also note that the debian/* and upstream/* tags are pushed as well.
$ git push debian --set-upstream
Counting objects: 3333, done.
Delta compression using up to 8 threads.
Compressing objects: 100% (1083/1083), done.
Writing objects: 100% (3333/3333), 1.37 MiB   0 bytes/s, done.
Total 3333 (delta 2231), reused 3314 (delta 2218)
To ssh://git.debian.org/git/pkg-db/py-lmdb.git
 * [new branch]      pristine-tar -> pristine-tar
 * [new branch]      debian/sid -> debian/sid
 * [new tag]         debian/0.84-1 -> debian/0.84-1
 * [new tag]         debian/0.86-1 -> debian/0.86-1
 * [new tag]         upstream/last-cython-version -> upstream/last-cython-version
 * [new tag]         upstream/py-lmdb_0.1 -> upstream/py-lmdb_0.1
 * [new tag]         upstream/py-lmdb_0.2 -> upstream/py-lmdb_0.2
 * [new tag]         upstream/py-lmdb_0.3 -> upstream/py-lmdb_0.3
 * [new tag]         upstream/py-lmdb_0.4 -> upstream/py-lmdb_0.4
 * [new tag]         upstream/py-lmdb_0.5 -> upstream/py-lmdb_0.5
 * [new tag]         upstream/py-lmdb_0.51 -> upstream/py-lmdb_0.51
 * [new tag]         upstream/py-lmdb_0.52 -> upstream/py-lmdb_0.52
 * [new tag]         upstream/py-lmdb_0.53 -> upstream/py-lmdb_0.53
 * [new tag]         upstream/py-lmdb_0.54 -> upstream/py-lmdb_0.54
 * [new tag]         upstream/py-lmdb_0.56 -> upstream/py-lmdb_0.56
 * [new tag]         upstream/py-lmdb_0.57 -> upstream/py-lmdb_0.57
 * [new tag]         upstream/py-lmdb_0.58 -> upstream/py-lmdb_0.58
 * [new tag]         upstream/py-lmdb_0.59 -> upstream/py-lmdb_0.59
 * [new tag]         upstream/py-lmdb_0.60 -> upstream/py-lmdb_0.60
 * [new tag]         upstream/py-lmdb_0.61 -> upstream/py-lmdb_0.61
 * [new tag]         upstream/py-lmdb_0.62 -> upstream/py-lmdb_0.62
 * [new tag]         upstream/py-lmdb_0.63 -> upstream/py-lmdb_0.63
 * [new tag]         upstream/py-lmdb_0.64 -> upstream/py-lmdb_0.64
 * [new tag]         upstream/py-lmdb_0.65 -> upstream/py-lmdb_0.65
 * [new tag]         upstream/py-lmdb_0.66 -> upstream/py-lmdb_0.66
 * [new tag]         upstream/py-lmdb_0.67 -> upstream/py-lmdb_0.67
 * [new tag]         upstream/py-lmdb_0.68 -> upstream/py-lmdb_0.68
 * [new tag]         upstream/py-lmdb_0.69 -> upstream/py-lmdb_0.69
 * [new tag]         upstream/py-lmdb_0.70 -> upstream/py-lmdb_0.70
 * [new tag]         upstream/py-lmdb_0.71 -> upstream/py-lmdb_0.71
 * [new tag]         upstream/py-lmdb_0.72 -> upstream/py-lmdb_0.72
 * [new tag]         upstream/py-lmdb_0.73 -> upstream/py-lmdb_0.73
 * [new tag]         upstream/py-lmdb_0.74 -> upstream/py-lmdb_0.74
 * [new tag]         upstream/py-lmdb_0.75 -> upstream/py-lmdb_0.75
 * [new tag]         upstream/py-lmdb_0.76 -> upstream/py-lmdb_0.76
 * [new tag]         upstream/py-lmdb_0.77 -> upstream/py-lmdb_0.77
 * [new tag]         upstream/py-lmdb_0.78 -> upstream/py-lmdb_0.78
 * [new tag]         upstream/py-lmdb_0.79 -> upstream/py-lmdb_0.79
 * [new tag]         upstream/py-lmdb_0.80 -> upstream/py-lmdb_0.80
 * [new tag]         upstream/py-lmdb_0.81 -> upstream/py-lmdb_0.81
 * [new tag]         upstream/py-lmdb_0.82 -> upstream/py-lmdb_0.82
 * [new tag]         upstream/py-lmdb_0.83 -> upstream/py-lmdb_0.83
 * [new tag]         upstream/py-lmdb_0.84 -> upstream/py-lmdb_0.84
 * [new tag]         upstream/py-lmdb_0.85 -> upstream/py-lmdb_0.85
 * [new tag]         upstream/py-lmdb_0.86 -> upstream/py-lmdb_0.86
Branch pristine-tar set up to track remote branch pristine-tar from debian.
Branch debian/sid set up to track remote branch debian/sid from debian.
$
After the initial push, we need to configure the remote repository so that clones will checkout the debian/sid branch by default:
$ ssh git.debian.org
edmonds@moszumanska:~$ cd /srv/git.debian.org/git/pkg-db/py-lmdb.git/
edmonds@moszumanska:/srv/git.debian.org/git/pkg-db/py-lmdb.git$ git symbolic-ref HEAD refs/heads/debian/sid
edmonds@moszumanska:/srv/git.debian.org/git/pkg-db/py-lmdb.git$ logout
Shared connection to git.debian.org closed.
We can check if there are any updates in upstream's Git repository with the following command:
$ git fetch upstream --dry-run -v
From https://github.com/dw/py-lmdb
 = [up to date]      master     -> upstream/master
 = [up to date]      release    -> upstream/release
 = [up to date]      win32-sparse-patch -> upstream/win32-sparse-patch
 = [up to date]      last-cython-version -> upstream/last-cython-version
 = [up to date]      py-lmdb_0.1 -> upstream/py-lmdb_0.1
 = [up to date]      py-lmdb_0.2 -> upstream/py-lmdb_0.2
 = [up to date]      py-lmdb_0.3 -> upstream/py-lmdb_0.3
 = [up to date]      py-lmdb_0.4 -> upstream/py-lmdb_0.4
 = [up to date]      py-lmdb_0.5 -> upstream/py-lmdb_0.5
 = [up to date]      py-lmdb_0.51 -> upstream/py-lmdb_0.51
 = [up to date]      py-lmdb_0.52 -> upstream/py-lmdb_0.52
 = [up to date]      py-lmdb_0.53 -> upstream/py-lmdb_0.53
 = [up to date]      py-lmdb_0.54 -> upstream/py-lmdb_0.54
 = [up to date]      py-lmdb_0.56 -> upstream/py-lmdb_0.56
 = [up to date]      py-lmdb_0.57 -> upstream/py-lmdb_0.57
 = [up to date]      py-lmdb_0.58 -> upstream/py-lmdb_0.58
 = [up to date]      py-lmdb_0.59 -> upstream/py-lmdb_0.59
 = [up to date]      py-lmdb_0.60 -> upstream/py-lmdb_0.60
 = [up to date]      py-lmdb_0.61 -> upstream/py-lmdb_0.61
 = [up to date]      py-lmdb_0.62 -> upstream/py-lmdb_0.62
 = [up to date]      py-lmdb_0.63 -> upstream/py-lmdb_0.63
 = [up to date]      py-lmdb_0.64 -> upstream/py-lmdb_0.64
 = [up to date]      py-lmdb_0.65 -> upstream/py-lmdb_0.65
 = [up to date]      py-lmdb_0.66 -> upstream/py-lmdb_0.66
 = [up to date]      py-lmdb_0.67 -> upstream/py-lmdb_0.67
 = [up to date]      py-lmdb_0.68 -> upstream/py-lmdb_0.68
 = [up to date]      py-lmdb_0.69 -> upstream/py-lmdb_0.69
 = [up to date]      py-lmdb_0.70 -> upstream/py-lmdb_0.70
 = [up to date]      py-lmdb_0.71 -> upstream/py-lmdb_0.71
 = [up to date]      py-lmdb_0.72 -> upstream/py-lmdb_0.72
 = [up to date]      py-lmdb_0.73 -> upstream/py-lmdb_0.73
 = [up to date]      py-lmdb_0.74 -> upstream/py-lmdb_0.74
 = [up to date]      py-lmdb_0.75 -> upstream/py-lmdb_0.75
 = [up to date]      py-lmdb_0.76 -> upstream/py-lmdb_0.76
 = [up to date]      py-lmdb_0.77 -> upstream/py-lmdb_0.77
 = [up to date]      py-lmdb_0.78 -> upstream/py-lmdb_0.78
 = [up to date]      py-lmdb_0.79 -> upstream/py-lmdb_0.79
 = [up to date]      py-lmdb_0.80 -> upstream/py-lmdb_0.80
 = [up to date]      py-lmdb_0.81 -> upstream/py-lmdb_0.81
 = [up to date]      py-lmdb_0.82 -> upstream/py-lmdb_0.82
 = [up to date]      py-lmdb_0.83 -> upstream/py-lmdb_0.83
 = [up to date]      py-lmdb_0.84 -> upstream/py-lmdb_0.84
 = [up to date]      py-lmdb_0.85 -> upstream/py-lmdb_0.85
 = [up to date]      py-lmdb_0.86 -> upstream/py-lmdb_0.86
We can check if any co-maintainers have pushed updates to the git.debian.org repository with the following command:
$ git fetch debian --dry-run -v
From ssh://git.debian.org/git/pkg-db/py-lmdb
 = [up to date]      debian/sid -> debian/debian/sid
 = [up to date]      pristine-tar -> debian/pristine-tar
 = [up to date]      debian/0.84-1 -> debian/0.84-1
 = [up to date]      debian/0.86-1 -> debian/0.86-1
 = [up to date]      upstream/last-cython-version -> upstream/last-cython-version
 = [up to date]      upstream/py-lmdb_0.1 -> upstream/py-lmdb_0.1
 = [up to date]      upstream/py-lmdb_0.2 -> upstream/py-lmdb_0.2
 = [up to date]      upstream/py-lmdb_0.3 -> upstream/py-lmdb_0.3
 = [up to date]      upstream/py-lmdb_0.4 -> upstream/py-lmdb_0.4
 = [up to date]      upstream/py-lmdb_0.5 -> upstream/py-lmdb_0.5
 = [up to date]      upstream/py-lmdb_0.51 -> upstream/py-lmdb_0.51
 = [up to date]      upstream/py-lmdb_0.52 -> upstream/py-lmdb_0.52
 = [up to date]      upstream/py-lmdb_0.53 -> upstream/py-lmdb_0.53
 = [up to date]      upstream/py-lmdb_0.54 -> upstream/py-lmdb_0.54
 = [up to date]      upstream/py-lmdb_0.56 -> upstream/py-lmdb_0.56
 = [up to date]      upstream/py-lmdb_0.57 -> upstream/py-lmdb_0.57
 = [up to date]      upstream/py-lmdb_0.58 -> upstream/py-lmdb_0.58
 = [up to date]      upstream/py-lmdb_0.59 -> upstream/py-lmdb_0.59
 = [up to date]      upstream/py-lmdb_0.60 -> upstream/py-lmdb_0.60
 = [up to date]      upstream/py-lmdb_0.61 -> upstream/py-lmdb_0.61
 = [up to date]      upstream/py-lmdb_0.62 -> upstream/py-lmdb_0.62
 = [up to date]      upstream/py-lmdb_0.63 -> upstream/py-lmdb_0.63
 = [up to date]      upstream/py-lmdb_0.64 -> upstream/py-lmdb_0.64
 = [up to date]      upstream/py-lmdb_0.65 -> upstream/py-lmdb_0.65
 = [up to date]      upstream/py-lmdb_0.66 -> upstream/py-lmdb_0.66
 = [up to date]      upstream/py-lmdb_0.67 -> upstream/py-lmdb_0.67
 = [up to date]      upstream/py-lmdb_0.68 -> upstream/py-lmdb_0.68
 = [up to date]      upstream/py-lmdb_0.69 -> upstream/py-lmdb_0.69
 = [up to date]      upstream/py-lmdb_0.70 -> upstream/py-lmdb_0.70
 = [up to date]      upstream/py-lmdb_0.71 -> upstream/py-lmdb_0.71
 = [up to date]      upstream/py-lmdb_0.72 -> upstream/py-lmdb_0.72
 = [up to date]      upstream/py-lmdb_0.73 -> upstream/py-lmdb_0.73
 = [up to date]      upstream/py-lmdb_0.74 -> upstream/py-lmdb_0.74
 = [up to date]      upstream/py-lmdb_0.75 -> upstream/py-lmdb_0.75
 = [up to date]      upstream/py-lmdb_0.76 -> upstream/py-lmdb_0.76
 = [up to date]      upstream/py-lmdb_0.77 -> upstream/py-lmdb_0.77
 = [up to date]      upstream/py-lmdb_0.78 -> upstream/py-lmdb_0.78
 = [up to date]      upstream/py-lmdb_0.79 -> upstream/py-lmdb_0.79
 = [up to date]      upstream/py-lmdb_0.80 -> upstream/py-lmdb_0.80
 = [up to date]      upstream/py-lmdb_0.81 -> upstream/py-lmdb_0.81
 = [up to date]      upstream/py-lmdb_0.82 -> upstream/py-lmdb_0.82
 = [up to date]      upstream/py-lmdb_0.83 -> upstream/py-lmdb_0.83
 = [up to date]      upstream/py-lmdb_0.84 -> upstream/py-lmdb_0.84
 = [up to date]      upstream/py-lmdb_0.85 -> upstream/py-lmdb_0.85
 = [up to date]      upstream/py-lmdb_0.86 -> upstream/py-lmdb_0.86
$
We can check if anything needs to be pushed from our local repository to the git.debian.org repository with the following command:
$ git push debian --dry-run -v
Pushing to ssh://git.debian.org/git/pkg-db/py-lmdb.git
To ssh://git.debian.org/git/pkg-db/py-lmdb.git
 = [up to date]      debian/sid -> debian/sid
 = [up to date]      pristine-tar -> pristine-tar
 = [up to date]      debian/0.84-1 -> debian/0.84-1
 = [up to date]      debian/0.86-1 -> debian/0.86-1
 = [up to date]      upstream/last-cython-version -> upstream/last-cython-version
 = [up to date]      upstream/py-lmdb_0.1 -> upstream/py-lmdb_0.1
 = [up to date]      upstream/py-lmdb_0.2 -> upstream/py-lmdb_0.2
 = [up to date]      upstream/py-lmdb_0.3 -> upstream/py-lmdb_0.3
 = [up to date]      upstream/py-lmdb_0.4 -> upstream/py-lmdb_0.4
 = [up to date]      upstream/py-lmdb_0.5 -> upstream/py-lmdb_0.5
 = [up to date]      upstream/py-lmdb_0.51 -> upstream/py-lmdb_0.51
 = [up to date]      upstream/py-lmdb_0.52 -> upstream/py-lmdb_0.52
 = [up to date]      upstream/py-lmdb_0.53 -> upstream/py-lmdb_0.53
 = [up to date]      upstream/py-lmdb_0.54 -> upstream/py-lmdb_0.54
 = [up to date]      upstream/py-lmdb_0.56 -> upstream/py-lmdb_0.56
 = [up to date]      upstream/py-lmdb_0.57 -> upstream/py-lmdb_0.57
 = [up to date]      upstream/py-lmdb_0.58 -> upstream/py-lmdb_0.58
 = [up to date]      upstream/py-lmdb_0.59 -> upstream/py-lmdb_0.59
 = [up to date]      upstream/py-lmdb_0.60 -> upstream/py-lmdb_0.60
 = [up to date]      upstream/py-lmdb_0.61 -> upstream/py-lmdb_0.61
 = [up to date]      upstream/py-lmdb_0.62 -> upstream/py-lmdb_0.62
 = [up to date]      upstream/py-lmdb_0.63 -> upstream/py-lmdb_0.63
 = [up to date]      upstream/py-lmdb_0.64 -> upstream/py-lmdb_0.64
 = [up to date]      upstream/py-lmdb_0.65 -> upstream/py-lmdb_0.65
 = [up to date]      upstream/py-lmdb_0.66 -> upstream/py-lmdb_0.66
 = [up to date]      upstream/py-lmdb_0.67 -> upstream/py-lmdb_0.67
 = [up to date]      upstream/py-lmdb_0.68 -> upstream/py-lmdb_0.68
 = [up to date]      upstream/py-lmdb_0.69 -> upstream/py-lmdb_0.69
 = [up to date]      upstream/py-lmdb_0.70 -> upstream/py-lmdb_0.70
 = [up to date]      upstream/py-lmdb_0.71 -> upstream/py-lmdb_0.71
 = [up to date]      upstream/py-lmdb_0.72 -> upstream/py-lmdb_0.72
 = [up to date]      upstream/py-lmdb_0.73 -> upstream/py-lmdb_0.73
 = [up to date]      upstream/py-lmdb_0.74 -> upstream/py-lmdb_0.74
 = [up to date]      upstream/py-lmdb_0.75 -> upstream/py-lmdb_0.75
 = [up to date]      upstream/py-lmdb_0.76 -> upstream/py-lmdb_0.76
 = [up to date]      upstream/py-lmdb_0.77 -> upstream/py-lmdb_0.77
 = [up to date]      upstream/py-lmdb_0.78 -> upstream/py-lmdb_0.78
 = [up to date]      upstream/py-lmdb_0.79 -> upstream/py-lmdb_0.79
 = [up to date]      upstream/py-lmdb_0.80 -> upstream/py-lmdb_0.80
 = [up to date]      upstream/py-lmdb_0.81 -> upstream/py-lmdb_0.81
 = [up to date]      upstream/py-lmdb_0.82 -> upstream/py-lmdb_0.82
 = [up to date]      upstream/py-lmdb_0.83 -> upstream/py-lmdb_0.83
 = [up to date]      upstream/py-lmdb_0.84 -> upstream/py-lmdb_0.84
 = [up to date]      upstream/py-lmdb_0.85 -> upstream/py-lmdb_0.85
 = [up to date]      upstream/py-lmdb_0.86 -> upstream/py-lmdb_0.86
Everything up-to-date
Finally, in order to set up a fresh local clone of the git.debian.org repository that's configured like the local repository created above, we have to do the following:
$ git clone --origin debian ssh://git.debian.org/git/pkg-db/py-lmdb.git
Cloning into 'py-lmdb'...
remote: Counting objects: 3333, done.
remote: Compressing objects: 100% (1070/1070), done.
remote: Total 3333 (delta 2231), reused 3333 (delta 2231)
Receiving objects: 100% (3333/3333), 1.37 MiB   1.11 MiB/s, done.
Resolving deltas: 100% (2231/2231), done.
Checking connectivity... done.
$ cd py-lmdb
$ git remote add --no-tags upstream https://github.com/dw/py-lmdb
$ git config --add remote.upstream.fetch 'refs/tags/*:refs/tags/upstream/*'
$ git fetch upstream
remote: Counting objects: 56, done.
remote: Total 56 (delta 25), reused 25 (delta 25), pack-reused 31
Unpacking objects: 100% (56/56), done.
From https://github.com/dw/py-lmdb
 * [new branch]      master     -> upstream/master
 * [new branch]      release    -> upstream/release
 * [new branch]      win32-sparse-patch -> upstream/win32-sparse-patch
$ git branch --track pristine-tar debian/pristine-tar 
Branch pristine-tar set up to track remote branch pristine-tar from debian.
$ git config --add remote.debian.push 'refs/tags/debian/*'
$ git config --add remote.debian.push 'refs/tags/upstream/*'
$ git config --add remote.debian.push 'refs/heads/debian/*'
$ git config --add remote.debian.push 'refs/heads/pristine-tar'
$ git config --add remote.debian.fetch 'refs/tags/*:refs/tags/*'
$
This is a fair amount of effort beyond a simple git clone, though, so I wonder if anything can be done to optimize this.

Next.

Previous.