Search Results: "pm"

25 October 2007

Enrico Zini: axi-query-similar

apt-xapian-index: searching for similar packages I've recently posted: Today I'll show how to abuse Xapian to show a list of packages similar to a given one. This time I'll try just linking to the code in wsvn and showing in the blog only show the most important bits. So, we have a package name, and we want to show what are the packages similar to that one. To do it, we simply build a big OR query with all the terms indexed for that package: Xapian will show us the packages whose terms are most similar, and that does the trick. This works because Xapian gives us the best results first, therefore even if no package except the given one will give an exact match, we still get the nearest matches first. In order to get the list of indexed terms given a package name we need to do two things:
  1. Get the Xapian document for the package.
  2. Get the termlist of the document.
To get the Xapian document we search for a term that only that document can have. In the index, the package name is indexed with the special prefix "XP", so we can search for that:
def docForPackage(pkgname):
    "Get the document corresponding to the package with the given name"
    # Query the term with the package name
    query = xapian.Query("XP"+pkgname)
    enquire = xapian.Enquire(db)
    enquire.set_query(query)
    # Get the top result only
    matches = enquire.get_mset(0, 1)
    if matches.size() == 0:
        return None
    else:
        m = matches[0]
        return m[xapian.MSET_DOCUMENT]
Then we build the big term list, by iterating the termlist of the document:
# Build a term list with all the terms in the given packages
terms = []
# Get the document corresponding to the package name
doc = docForPackage(pkgname)
if not doc: continue
# Retrieve all the terms in the document
for t in doc.termlist():
    if len(t.term) < 2 or t.term[:2] != 'XP':
        terms.append(t.term)
Note that it's trivial to fetch terms from more than one document, if you want to query "all packages a bit like this one and a bit like that one", although that's less of a useful feature. Lastly, we build the final query:
# Build the big OR query
query = xapian.Query(xapian.Query.OP_AND_NOT,
            # Terms we want
            xapian.Query(xapian.Query.OP_OR, terms),
            # AND NOT the input packages
            xapian.Query("XP"+pkgname))
I add an AND_NOT part with the input package name so that we don't get in the output the package that we asked for. This is it:
$ ./axi-query-similar.py debtags
20309 results found.
Results 1-20:
33% debtags-edit - GUI browser and editor for Debian Package Tags
27% tagcolledit - GUI editor for tagged collections
25% libtagcoll2-dev - Functions used to manipulate tagged collections (development version)
24% tagcoll - Commandline tool to perform operations on tagged collections
19% packagesearch - GUI for searching packages and viewing package information
18% doodle - Desktop Search Engine (client)
18% doodled - Desktop Search Engine (daemon)
18% libept0 - High-level library for managing Debian package information
18% upgrade-system - system upgrader from Konflux
18% libept-dev - High-level library for managing Debian package information
17% ept-cache - Commandline tool to search the package archive
16% tracker-utils - metadata database, indexer and search tool - commandline tools
[...]

You can use the wsvn interface to get to the full source code and the module it uses. Next in the series: adaptive quality cutoff.

Matthew Garrett

Linux-hero wrote about how Ubuntu kills your hard drive. The situation is somewhat less clear than you might think from the article, but the basic takeaway message is that Ubuntu doesn't touch your hard drive power management settings by default. In almost all cases, it's more likely to be your BIOS or the firmware on your hard drive.

The script that's executed when you plug or unplug your laptop is /etc/acpi/power.sh. The relevant sections are:
function laptop_mode_enable  
...
    $HDPARM -S $SPINDOWN_TIME /dev/$drive 2>/dev/null
    $HDPARM -B 1 /dev/$drive 2>/dev/null
 
That is, when the laptop_mode_enable function is called, we set the drive power parameters. Now, by default laptop_mode_enable isn't called:
if [ x$ENABLE_LAPTOP_MODE = xtrue ]; then
    (sleep 5 && laptop_mode_enable)&
fi
because ENABLE_LAPTOP_MODE is false in the default install (check /etc/default/acpi-support). This means that, by default, we do not alter the hard drive power settings. In other words, the APM settings that your drive is using in Ubuntu are the ones that your BIOS programmed into it when the computer started. This is supported by the fact that people see this issue after resuming from suspend. We don't touch the hard drive settings at that point, so the only way it can occur is if your BIOS or drive default to this behaviour.

If you enable laptop mode, then we will enable aggressive power management on the drive and that may lead to some reduction in hard drive lifespan. That's a fairly inevitable consequence of laptop mode, since it only makes sense if the laptop enages in aggressive power management. But, as I said, that's not the default behaviour of Ubuntu.

There's certainly an argument that we should work around BIOSes, but in general our assumption has been that your hardware manufacturer has a better idea what your computer is capable of than we do. If a laptop manufacturer configures your drive to save power at the cost of life expectancy, then that's probably something you should ask your laptop manufacturer about.

24 October 2007

David Welton: Open Source Licenses, Network Effects, and Competitive Strategy

I was recently talking with some people who develop a BSD licensed product who are a bit worried about competition. I had this to say, and I thought I would share it. I think the concern is the "Sun Microsystems situation", where there is a second project (B) based on open source project (A), and code only moves in one direction, towards B, a, commercial project. That can be kind of scary, especially when the commercial project has some sort of advantage. There is a real risk that as users and developers move towards project B, network effects take over, and B comes to dominate. The GPL is one answer to this problem, that the Apache Software Foundation, and others in the "BSD camp" have chosen to eschew, in favor of another solution: 1) making the development community broad enough and strong enough to make it hard to vacuum up all the talent over to project B, and 2) moving fast enough with the project that development outstrips that of project B. Of course, that strategy is not always possible, but that's the direction to take, I think - make it so that it's a big effort to 'keep up' with project A for the commercial guys, to the point where they don't want to diverge very far from the main development line for fear of not being able to keep up with all the good stuff coming out of it. One of the ways this can happen with a BSD style license is to get lots of companies contributing to the common code base, something that is at times easier if they have no worries about restraints the license may place on their future directions. Incidentally, I also think people may like the GPL because it makes things "fair", without worrying so much about putting in the effort to "outrun" the competition in terms of code or community. These are some of the reasons why I don't get too worked up about there being a "best" license. It really depends on the situation, and the goals of the people involved, too much to get fixated with one license being "superior".

23 October 2007

Isaac Clerencia: Open aLANtejo 2007

Last weekend I had the chance to attend the Open aLANtejo conference, in beautiful vora, Portugal. I went there to give a presentation about Open Source Game Development and had the chance to meet interesting people that I knew through somebody else or just from the community lore :P To be honest I had a really better time than I expected :) Some of the speakers were the Bitrock people, Jono Bacon (Ubuntu Community Manager) and Juanjo from Igalia. I’m really looking forward to meet up again. The organisation team was also really helpful and passionate about the event, so if you get invited, don’t think twice about going :)

22 October 2007

Bernd Zeimetz: short package update

short package update Didn't find the time to blog lately, so here's the very short summary of (hopefully) all news regarding the more important packages I take care of: gimp-plugin-registry / gimp-refocus gimp-plugin-registry is at version 0.4.2-1 now, including several updates and new plugins since my last blog entry. Also I've moved the refocus plugin into gimp-plugin-registry - now gimp-refocus is only a transitional package, which will install gimp-plugin-registry. gimp-refocus will be removed from Debian before Lenny will be frozen. As it was not shipped with Etch there's no need keep the transitional package in the release. gpsd Successfully hijacked gpsd, the new upload fixed a lot of bugs, including one old RC bug which was the reason why gpsd was removed form testing. If you're using gpsd please check the packages in unstable - comments appreciated. If you've used libgps form the gpsd package before, you'll have to look into the libgps-dev and libgps16 packages now. Bugs against packages using the library were filed in time. Also I plan to get a beta version of 2.35 into experimental during the next weeks, which will come with a more or less completely rewritten NMEA layer and a lot of fixes and improvements. radiance Finally integrated in Debian! Development of radiance started in 1985 and is still actively developed, but nobody every thought about including it in Debian. I'll blog about radiance later, in the meantime please read this wikipedia article. viking Today the latest version 0.9.3 was uploaded to unstable. Most important addition: Realtime GPS tracking, using gpsd. If you're interested in OpenStreetMap, geocaching or any other fun with GPS devices, take a look into viking.

21 October 2007

Russell Coker: Open Hardware - What Would Change

I have just read an interesting post speculating about the possibility of open source hardware [1]. To some extent things have been following a trend in that direction. Back in the bad old days every computer manufacturer wanted to totally control their market segment and prevent anyone else from “stealing their business”. Anti-competitive practices were standard in the computer industry, when you bought a mainframe you were effectively making a commitment to buy all peripherals and parts from the same company. The problems were alleviated by government action, but the real change came from the popularity of PC clones. White-box clones where every part came from a different company truly opened up the hardware development, and it wasn’t all good. When running a simple single-tasking OS such as MS-DOS the problems were largely hidden. But when running a reliable multi-tasking OS such as Linux hardware problems became apparent. The PCI bus (which autoconfigured most things) reduced the scope of the problem but there are still ways that white-box machines can fail you. Now when I get a white-box machine I give it away to members of my local LUG. My time is too valuable to waste on debugging white-box hardware, I would rather stick to machines from IBM and HP which tend to just work. Nowadays I buy only name-brand machines, all the parts were designed and tested to work together - this doesn’t guarantee that the machine will be reliable but it does significantly improve the probability. Fortunately modern hardware is much faster than I require for the work I do, so buying second-hand name-brand machines (for less money than a new white-box machine) is a viable option. The PCI bus [2] standard from Intel can be compared to some of the “Open Source” licenses from companies where anyone can use the software but only one company can really be involved in developing it. One significant impediment to open hardware development is the proprietary nature of CPU manufacture. Currently there are only a few companies that have the ability to fabricate high-end CPUs so projects such as OpenRISC [3] which develop free CPU designs will be limited to having their CPUs implemented with older technology (which means lower clock speeds). However this doesn’t mean that they aren’t useful, tailoring factors such as the number of registers, the bus width of the CPU, and the cache size to match the target application has the potential to offset the performance loss from a lower clock speed. But this doesn’t mean that an OpenRISC or similar open core would be ideal for your typical desktop machine. If companies such as Intel and AMD were compelled to fabricate any competing CPU design at a reasonable cost (legislation in this regard is a possibility as the two companies collectively dominate the world computer industry and it would be easy for them to form a cartel) then designs such as OpenRISC could be used to implement new CPUs for general purpose servers. Another issue is the quality of support for some optional extra features which are essential for some operations. For example Linux software RAID is quite good for what it does (basic mirroring, striping, RAID-5 and RAID-6), but it doesn’t compare well with some hardware RAID implementations (which actually are implemented in software with a CPU on the RAID controller). For example with a HP hardware RAID device you can start with two disks in a RAID-1 and then add a third disk to make it a RAID-5 (I’ve done it). Adding further disks to make it a larger RAID-5 is possible too. Linux software RAID does not support such things (and I’m not aware of any free software RAID implementation which does). It would certainly be possible to write such code but no-one has done so - and HP seem happy to make heaps of money selling their servers with the RAID features as a selling point. Finally there’s the issue of demand. When hardware without free software support (such as some video cards which need binary-only drivers for best performance) is discussed there is always a significant group of people who want it. The binary-only drivers in question are of low quality, often don’t support the latest kernels, and have such a history of causing crashes that kernel developers won’t accept bug reports from people who use them, but still people use them. In the short-term at least I expect that an open hardware design would deliver less performance and in spite of the fact that it would have the potential to offer better reliability the majority of the market would not accept it. The production volume of electronics gear is the major factor determining the price so it would cost more. I think that both IBM and HP provide hardware that is open enough for my requirements, they both have engineers working on their Linux support and the interfaces are well enough documented that we generally don’t have any problems with them. Both Intel and AMD and the major system vendors are all working on making things more open, so I expect some small bug significant improvements in the near future.

19 October 2007

Anthony Towns: Multiple Repositories -- Sumultaneously!

If, like me, you’ve been following development of Joey’s nifty new multi-repository tool and busily registering all your git and bzr and cvs and whatnot repos, you might have noticed a tantalising TODO item that’s recently appeared in the git repo:

* Ability to run commands in paralell? (-j n)
  If done right, this could make an update of a lot of repos faster. If
  done wrong, it could suck mightily. ;-)
Well, sucking mightily just means you need to prototype it first, so here’s a little add-on to mr(1) that runs multiple invocations of mr(1) simultaneously, naturally enough called mrs(1). Consideration of what that implies about superior multitasking is left as an exercise to the interested reader. The implementation is slightly interesting: it’s a fairly simple perl script that first uses “mr list” to get a list of repositories to work with, then simply uses perl’s “open” function to run mr on each of those directories with the output piped to a filehandle. At that point, things get slightly complicated, since we want to keep them all running no matter what’s going on, so we have a select() loop that collects all the output into one buffer per command, which we put together later, and print out. And just for kicks, if the output ’s longer than 20 lines, we pipe it through less after trimming out any ugly ^M nonsense we might have had thanks to progress updates or similar. I like it, anyway. And happily, while “mr update” takes about fifty seconds for me, “mrs update” takes about ten. Fun! (Joey: btw, it’s “parallel” :)

Russell Coker: Banking with an Infected Computer

Bruce Schneier summarised a series of articles about banking security [1]. He mentioned the fact that banks don’t seem to care about small losses and would rather just deal with the problem (presumably by increasing their fees to account for losses). There are some other interesting bits in the article, for example banks are planning a strategy of securing transactions with an infected computer [2]! Now there are some possible solutions to this, for example if the bank issued a hardware device that allowed the customer to enter the account number, amount to transfer, destination account, and PIN number and then produced a cryptographically secure hash (based in part on a rolling code) that the user could type in. The only way that you are going to do anything securely with an infected host is if everything is offloaded into an external device. In which case why not just do the Internet banking on the external device? It’s not difficult to make a hardware device that is small enough to carry everywhere, has a display, an input device, net access, and which is reasonably difficult to crack externally. Consider for example a typical mobile phone which has more RAM, CPU power, and storage than a low-end machine that was used for web browsing in 1996. Mobile phones have a good history of not being hacked remotely and are difficult for the owner to “unlock”. A locked-down mobile phone would be a good platform for Internet banking, it has wireless net access in most places (and with a Java application on the phone it could do banking by encrypted SMS). Being locked down to prevent the user from reconfiguring the software (or installing new software) will solve most of the security problems that plague Windows. If when signing up for a new phone contract I was offered the possibility of getting a phone with secure banking software installed for a small extra fee then I would be very interested. Of course we would want some external auditing of the software development to make sure that it’s not like some of the stupid ideas that banks have implemented. Here is a classic example of banking stupidity [3]. They display a selected word and picture for the user when they login to try and prevent phishing (of course a proxy or a key-logger on the local machine will defeat that). They also ask for an extra password (of the simple challenge phrase variety) if you use a different IP address, of course as the typical broadband user doesn’t know when their IP address changes they wouldn’t know if their data was being proxied and dial-up users will enter it every time. A google search for “internet banking” picture password turns up a bunch of banks that implement such ideas.

Raphael Geissert: DeBaBaReTools: The de-what?

It's been a while since I wanted to post about a project I started.
But today when I read Russell Coker's post about his SE Linux repository I decided it was time to blog about DeBaBaReTools.


So, what is/are DeBaBaReTools?
is: a project which tries to unify different packages-building systems (pbuilder, buildd, etc) and different repository tools (debarchiver, reprepro, etc) in a single system by providing an incoming/ system.

are: Debian Bash-Based Repository Tools.

Or in other words:
DeBaBaReTools handles new packages by:


DeBaBaReTools is NOT a rewrite of a repository tool (like reprepro, debpool or debarchiver), neither yet an other building tool (like buildd or pbuilder). It is rather a glue between those two kind of tools.

So, how does DeBaBaReTools work?
As already said, they are a set of scripts which do all the work.
These are some of the scripts (more might be written later, they are under development):


Note that at the moment these are the only supported backends: gpgv, du, md5sums (all built in checkSums), pbuilder and reprepro.

Sounds interesting, doesn't it? :)

So, here's the magic:

The backends system
DeBaBaReTools doesn't try to re-invent the wheel, but it makes use of all the available tools so it works as less as possible.

This is where the backends take action. They are even more shell (even tough DeBaBaReTools clearly specifies they are Bash scripts they should work on any other POSIX-compatible shell) scripts which are loaded on demand and according to the user settings.

This opens a wide range of possible combinations of backends; making DeBaBaReTools work with almost anything.

The probe.sh script searches different directories for the specified backend (and will soon support user-hinted backends).

I think an example says more than a thousand words:
When needsBuild finds a package that needs to be built in a given architecture, the toBuild shell function is called. In order to provide the already said flexibility, needsBuild will at startup time call probeFile "buildQueue" which will then check several directories for the required backend (buildQueue in this case). Once it finds the given backend (backends/buildQueue/) it will check for any user hint (which will specify the real backend to be used) and then for a default one (default.sh which is a symlink to a real backend, plaintext.sh by default).

So, if somebody at some point wants to use a sqlite database to store all that information, that person would have to write a file called backends/buildQueue/sqlite.sh (or make it available in any of the include paths which can be extended via the EXTRA_PROBE_DIRS env variable) and either set a user hint or make default.sh point to it.
The sqlite.sh script can then call any external tools (or even more scripts) to insert the information in the database, read it and more.

I know this is a lot of blahblahblah but no single line of code is shown.
I've already requested an alioth project but it was denied because the package isn't already in the Debian archive.
If you are a DD and you think this sounds like a good project please contact the Alioth admins and convince them to create a project account for DeBaBaReTools.
Once created, many other people will be able to work on it and make it work with virtually any tool.

Any kind of feedback is very welcomed but I hope they are constructive ideas.

Why did I start this crazy project?
Because AFAIR only dak is able to do such job but I think dak is just too complex for a simple system to manage an a repository with an incoming system. And AFAIK there's no script which is able to do this job besides dak.

I hope this post makes sense because I don't want to review it again (I'm tired) :)

:bye: all

17 October 2007

Steve Kemp: Prepare yourself you know it's a must

After years of on-again-off-again infatuation I now own my very own steam engine. This makes me far far happier than I was expecting. In other news a new release of xen-tools was made to fix some stupid bugs, a release of xen-shell is pending for the same reason, and after declaring I'd not make another release of GNUMP3d again I'm just about to do that too. I am finding myself rather bored working on the same projects for so long. Though thankfully each of those three is essentially complete. If I died tomorrow there would be no real need for future development. I guess I need a new project to work upon. The mail-scanning was going to be that project, but that has been sidetracked as I've been stripping out all the pretty and functional user-interface code with the aim of selling the code to $company as a one-off deal. (Not confirmed. Nice idea though.) So I need a new project. People like Joey Hess who can almost instantly start fun projects (such as moreutils, ikiwiki, pristine-tar, mr) which just seem so obvious, necessary and useful on a whim make me jealous! All in all life is good and steamy. I just need inspiration. And more hours in the day too.

Michal &#268;iha&#345;: I should review better what I upload

Well I somehow expected it will happen to me when I started to use Debian experimental distribution, but now it really happened. I noticed that last Gammu upload went to unstable instead of experimental just when today updating my other development machine and I was surprised that Gammu is going to be updated. Well the version is not that bad, but it is far from being stable. Anyway it is good for something - unstable users will do much more testing than experimental ones ;-).

16 October 2007

Russell Coker: War is Bad for the Environment

I just read a nutty post claiming that Neo-Conservatism is good for the environment [1]. The first bogus claim is that Saddam had WMD and war was required because he was a despot. The fact is that the Iraqi government was always repressive, there are many factions in Iraq that don’t like each other and a repressive government is the only way to keep such groups in a united country. The current civil war in Iraq and the effective secession of Kurdistan (which currently seems to be involved in an undeclared border war with Turkey) demonstrates this. Saddam was always a despot, but he did improve the living conditions of most Iraqis - the best way to avoid a revolution is to convince the majority of the population that things will get worse if there is change. I suggest reading the Wikipedia page about Saddam Hussein [2]. The best information on Fourth Generation Warfare (4GW) seems to be on the conservative military analysis site Defense and the National Interest [7]. It covers all the issues related to invading other countries from a conservative point of view. Note that Neo-Conservatives are not Conservatives, the real Conservatives hate the Neo-Cons more than anyone else does. The amusing statement is made that “apologists claim it was one of the most advanced Arab nations” and then a link is provided to information on Saudi Arabian censorship. It’s worth reading the wikipedia page about the history of Saudi Arabia [3], among other interesting facts “the U.S. Army Corps of Engineers built the country’s television and broadcast facilities and oversaw the development of its defense industry” (does the US army share responsibility for the censorship?). It’s widely regarded that if the US military support was removed then the Saudi government would be overthrown. Referring to Saudi Arabia hardly seems like something you want to do if trying to justify occupying other middle-eastern states. An unsubstantiated claim is made that under-developed countries produce excess pollution due to inefficient technology. Unlike some people I try to get some facts before posting so I looked up the wikipedia page on CO2 emissions per capita [4]. It seems that the highest ranking first-world country is Luxembourg at #4, the next is the US at #10. The countries on the list that rank higher than the US have a combined population of about 11,000,000 while the US population is 302,000,000 - some quite mental arithmetic suggests that the US produces about 20 times more CO2 than the top 9 countries on the list combined! It doesn’t seem that having the highest technology is helping the US protect the environment, I guess that they just use it to build bigger cars. The next thing I noticed is the countries that are at the bottom of the list - they are the world’s poorest countries. It seems that countries without much money just can’t afford to burn lots of oil, while countries with lots of money can. No real surprises there. The lowest ranking on the list for a country that is unlikely to be regarded as being in abject poverty is India at position #133. The next lowest is Turkey at position #98 followed by China at #91. As a final point of reference Switzerland is at position #69 a produces just under 27% the CO2 that the US does (on a per-capita basis). According to the CIA World Fact Book Switzerland has an infant mortality rate of 4.28/1000 and a life expectancy of 80.62 [5], while the US has an infant mortality rate of 6.37/1000 and a life expectancy of 78 [6]. I believe that the infant mortality rate and the life expectancy are the two factors that are most representative of quality of life as they are the easiest factors for measuring the overall health of the population. Being healthy is one of the most important factors in quality of life. It seems to me that by all objective measures the Swiss are doing better than the people of the US, yet they produce less pollution and never invade other countries. Probably the most ridiculous statement in the post is “see rapidly dwindling resources wasted on jihad and revolution“. A revolution (locals using force to create a new government) takes little resources and most actions that a more simple-minded analysis might call “jihad” takes almost none. Sending an invasion force to the other side of the world and supporting an occupying army for years does however use significant resources, consider that the Hummvee is the least fuel-efficient vehicle on American roads in terms of work done (trucks and buses use more fuel but carry large amounts of cargo or many people), but it’s also the most fuel-efficient vehicle used by the US army in Iraq. There is the possibility that Jaldhar was attempting satire. If so then I suggest that satire be kept separate from serious web content to avoid confusion about where the satire ends. But if you want some satire about oil then I suggest consulting theonion.com. Before someone accuses me of being impolite, over a year ago the best estimate for the death toll from the occupation of Iraq was 655,000 [8]. Current extrapolations from the previous medical research suggest that the death toll has now exceeded 1,000,000. Regardless of whether the original post was intended as satire or not, I’m not laughing and I don’t feel the need to be polite to someone who makes excuses for such loss of life. Finally as a positive suggestion towards the environment (and any other issue that you may want to discuss), I suggest analysing the issues before writing about them and not blindly trusting other people. When you write a post make objective claims with references to back them up. When you read a post consider the points that are made and the references that are cited. Do the references support the claims? Are there other interpretations of the evidence? Are the reference sites reputable?

Biella Coleman: Topics in Digital Media

Next semester I am teaching one (yay one) course and it is a graduate course on digital media. This is the description I have so far and I will post the tentative syllabus in the next few week.
Computers, especially in their networked dimension, have sparked a series of ethical, political, and social debates that often revolve around a series of stark and connected dualities: control and freedom; pleasure and exploitation; creativity and constraint. In this course we will approach topics in digital media via an historical angle that squarely addresses these dualities. To this end, we will often cross-cut readings on similar topics and material whose conclusion about the nature of computing will often vary considerably. The goal, however, is not to determine the correct or right side of these dualities but have students come away with a firm understanding of the following: 1) the history of computing and networking in light of the ways the authors as well as technologists/inventors construct or understand these dualities; 2) the various sources technological, social, and political that may shape or drive any of these elements; 3) unpack the political and social relationships, if any, between them and the stakes involved in how these authors represent the nature of computing and networking. The course primarily concentrates on computers and networks and is roughly chronological, starting with the first digital computers and ending with our digital present. Particular topics we address are: cybernetics and liberalism; networks and the cold war; personal computers and online communities; hackers, the free software movement and intellectual property; labor, development, and computers; peer-to-peer knowledge production; computer gaming; and counter-globalization and computer networking.

MJ Ray: the Cooperative Group Half-Yearly Meeting

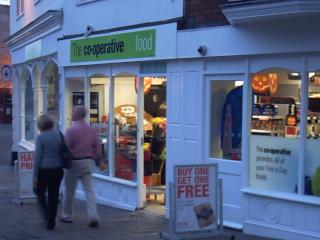
I attended my first half-yearly meeting as a member of the co-operative group yesterday evening at 7pm. The event for the strangely-named Kennet and Avon area was held at Jury's Hotel near Queen Square, which is a part of Bristol I've not visited for a while, so I got there a bit early to find it. the co-operative food, The Centre, Bristol I found it easily, which gave me a few minutes spare to visit the co-operative food store on the Centre (pictured), which is the first rebranded one I've seen. It looks light and airy and the staff were friendly. I didn't find everything I was looking for, but after exiting, I noticed I'd not seen around the corner of the L-shaped store! Anyway, the meeting itself was chaired by Peter Begley and was attended by six elected reps, three regional officers, four trading managers (all food?) and about 50 members by my reckoning. There was a comment later in the meeting about the low turnout from Bath - it seems that a meeting for each city had been requested and refused. There was also a comment about lack of transport from Weston-super-Mare, about which I'm not sure: trains between WsM and Bristol are at least hourly. Maybe there should be a shuttle between station and meeting for people who can't walk, but it seems nuts to run a bus from here when trains are faster and have space. Officer Chris Griffiths gave a presentation (with loud music!) about our community support, including windfarms on the co-operative farms, Farm to Fork, the Woodcraft Folk, the Queens Award for Sustainable Development, community chef visits to Ilfracombe and Bath, community challenge, Mukti Mitchell's Low Carbon Lifestyle Tour, Fairtrade fashion shows, Holyland Handicrafts Co-operative at Bath Christmas Market, BAND (D is for Daycare, but I missed the rest), Toy Box Library Bath, Avonmouth Community Centre Association and Oldfield Park Juniors. Frank Jones presented the business interim report, noting that the group has a 2.2% increase of revenue before reinsurance premiums, but the bad weather has hit the insurance arm, reducing the overall profit. Nevertheless, we still paid a total of 38 million pounds to and on behalf of members. The closure of WsM Dolphin Square and the gain of the co-operative pharmacy in Milton were mentioned in passing. There was a short presentation about the constitutional review. The first members' consultation ends on 26 October, so send in your comments soon. There was particular concern about some multi-thousand-pound payments to elected representatives who stand down. Then came member questions, which I'll describe in another post, approval of past minutes, reports of the local co-operative party (success in Bath+NES, 8 councillors in Bristol, loss of 2 councillors in N.Somerset) and presentations to Frank Jones and Simon Crew of 10-year elected service awards. The meeting closed at 9pm.
15 October 2007

Romain Francoise: In Rainbows

Once again, PopMatters is right on. I'm amazed that after all these years, international fame and millions of records sold, Radiohead can still get together and make an album such as In Rainbows, true to their sound, intricate and emotional, powerful. Wow.

13 October 2007

Julien Valroff: Switched to Dovecot LDA and Sieve

I have worked almost all the day to update my mail server configuration to use Dovecot LDA and the Sieve mail filtering language instead of maildrop. This was very easy thanks to Christoph’s ISP-style Email Server with Debian-Etch and Postfix 2.3 how-to.
(more…)

Biella Coleman: Decoding Liberation: The Promise of FOSS (and Web 2.0)

Last week I helped Samir Chopra and Scott Dexter kick off their book release party in New York City. The book Decoding Liberation: The Promise of Free and Open Source Software is the first academic book length piece on free software proper that among other things examines the repercussions of such elements as language use (free software vs open source) and licensing (such as non-copyleft licensing). Here are my opening remarks, which don’t give justice to the book but give a small taste of what is in there. Samir and Scott are computer scientists, philosophers, and political thinkers and bring these positions and perspectives to bear in their work. While I tend to avoid the discussion on the differences and divergences between free and open source software and licensing (just because I ask a set of questions that tend not to go into that territory), they spend a hefty about of time on this sort of engagement And what is so useful about their approach is that it is technically detailed and carefully analyzed, clarifying the stakes involved in choosing a certain set of licensing over others, or the political implications of language use. Along with this focus, there are many other threads they unpack and one of my favorites is on the aesthetics of code, which I discuss with some detail in my opening remarks with the help of one of my favorite literary writers, Susan Sontag. The conversation that followed was lively, in part because there were a number of people in the audience who are also very familiar with FOSS (Somewhat unbelievably, there were 3 anthropologists there who study free software, myself, Jelena Karanovic, and Anita Chan). And I think one of the most interesting questions was launched by Anita who asked the authors what they meant more precisely by the promise of FOSS as well as liberation. The conversation that followed was too rich to recount here, but something that I raised and I do think is important is the relationship between the buzz word of the last few years, Web 2.0 and FOSS. Web 2.0 is related to FOSS in so far as Web 2.0 refers to a suite of technologies that allow for the creation of user-generated content and collaboration. FOSS refers to a development methodology that is based on promiscuous sharing of code and collaboration. The similarities, however, end there because much of the Web 2.0 infrastructure is proprietary. FOSS by definition is non-proprietary. But I think that soon we are going to see more Web 2.0-like companies open up their infrastructure entirely or at least important components. One example of a new technology that is Web 2.0-like and is entirely free software is a activist networking tool crabgrass that is pretty impressive (I have used it to coordinate my move and am using it now to coordinate a collaborative grant). It is still under development but once released, it will be a great boon to any group that needs to collaborate and organize and coordinate:
Crabgrass also provides a public advocacy centric view of content so that people can learn more about issues and organizations through social relationships. Blog tools, voter guides, petitions, event organizing tools, and action alerts are being added to the functionality of the platform. Crabgrass integrates wikis, asset repositories, task lists, calendars, polls, and meeting schedulers into one tool which allows groups to manage their internal organizing.
The other technology that I am excited about and that I have already written about is Kaltura. As I mentioned, Kaltura is important because it lowers the bar for collaboration, providing tools to facilitate video editing. But what I find as interesting and as significant is that they are perhaps the first large-scale Web 2.0 company that is actively seeking to enter the territory of FOSS and in this respect, once they do so, they will lead the field, not simply for technical reasons, but because they choose to make and engage with open source technologies. Bringing Web 2.0 within the orbit of FOSS and brining FOSS within the orbit of Web 2.0 can only work to bolster each other, and this is where I think, at least part of the promise of FOSS lies.

11 October 2007

Steve Kemp: I put a spell on you

Felipe Sateler kindly made a Debian package for the chronicle blog compiler, so you can now get it from my apt-get repository. He suggested it be uploaded to Debian sid, I'm happy to do so if there is any interest. Otherwise I'll keep placing release there when they occur. (To be honest I don't anticipate any major development unless there are bugs, or people would like to contribute themes ..)

Russell Coker: Getting People into IT

Pia writes about the difficulty in getting young women and young people in general into the computer industry [1]. While I agree that having more women in the computer industry would be a good thing, I have difficulty believing some of the claims that Pia makes. For example the claim that “[girls] are more career focused earlier in their school life“. I chose my career when I was about 11 years old [2] and several of my friends made similar decisions at similar ages. I would be interested to read anecdotal evidence from women in the computer industry about how old they were when they decided on their career and if their friends did the same, a reference to any research on this topic would also be useful. I tend to believe that boys are more career focussed at all stages of their life but have little evidence to support this idea. One fact that seems obvious is that the idea that “if you don’t succeed in your career then you can always marry someone who does” is almost non-existent among boys. It seems likely that such ideas have a statistically relevant affect on the focus on career of boys vs girls. Also the Australian Bureau of Statistics reports that the MEDIAN income for women is significantly lower than for men [4], I find it difficult to imagine that girls could be more career focussed from a younger age and yet get significantly lower pay (note the fact that it’s median not mean income is very significant as it removes the “glass ceiling” effect). Phillip Greenspun writes about why there are so few women doing scientific research [6] and makes some good points about why scientific research is generally not well paid and therefore a university student would choose a career in some other area and suggests that it’s a macho thing that guys enter such competitive fields for relatively low wages. Maybe some women correctly assess the costs and benefits of a career in scientific research and then make the mistake of equating Computer Science to other branches of science. But the median income suggests that although there may be some valid reasons for avoiding science that would only cover a small portion of the problem (the difference in median income can not be explained by misplaced attempts to maximise income). One problem that is significant is the quality of school education for girls. Not only is there the issue that boys may crowd-out girls for some subjects that are supposedly traditionally for boys (such as all science) but even girls schools aren’t as good as they should be. Some time ago I was talking to a teacher at an all-girls school, the school was moderately expensive and parents were paying the extra money presumably to give their daughters educational opportunities that they might miss in a co-ed school. However the school did not teach hard maths (”Maths B” was the official name at the time) and only taught the easy maths (official name “Maths A” and unofficial name “Vegie Maths“) because they didn’t have many girls demanding it (which is probably difficult to measure if you don’t offer it as a reasonable option) and the girls who wanted to study it could always move to a different school. So the choice facing girls at the exclusive school in question was “skip the subject that is most useful for further studies in most science subjects” or “go to a different school and miss most of your friends“, this sort of decision would surely discourage some potential female computer programemers. Also I think that the difference between boys and girls in regard to studying computer science has a lot to do with the fact that given a choice between missing most of their friends and missing out on something related to computers would be a no-brainer for most boys. Paul Graham’s article about Nerds has some interesting points to make in this regard - maybe the problem is that girls aren’t Nerdish enough [5]. Pia also writes about parents and teachers advising children not do study IT because of a perceived lack of jobs. I think that the problem here is not just bad advice, but also a bad tendency to take advice. Someone who wants to study in an established field which changes little over time (law and accounting spring to mind) probably should take careful note of the advice that they are given - things haven’t changed much in the last few decades. But someone who wants to study in a field that changes rapidly and where every year has new and significant developments (of which the best example is the computer industry) should probably be quite skeptical of all advice - most advice about the computer industry concerns how things used to be not how things are. Finally when considering whether to accept advice you should consider who is offering it. For example advice from a hiring manager should be carefully noted (as the manager will tell you precisely what factors influence their own decisions on hiring). Advice from people who are successful in the industry should also be noted. Advice from a school career advisor who gets paid about 1/3 what any 25yo can earn in the computer industry should be entirely ignored. I wonder whether being hesitant to ignore advice is a problem for girls in this regard. When I was in year 11 I had to take a subject related to career planning. It covered some things that were of minor use (such as writing CVs) and had an assignment of writing a fictional CV for yourself a few years after leaving university. I received bad marks for preparing a CV that involved changing jobs as companies went bankrupt or projects failed due to bad management, I was told that if your employer fails in the market it makes you look bad! However my fictional CV did bear some resemblance to what really happened… In terms of what industries have jobs available, the best advice I can give students is to actively do some research of their own. It’s not difficult to get the jobs sections of some newspapers and do a quick scan to see how many positions are open in a field, and it’s even easier to do some searches on online jobs sites (which usually tell you how many positions posted in the last X days match your criteria). For example I just visited jobserve.com.au and found 1724 Engineering jobs and 5622 IT jobs advertised. If you compare this to the university intake (I visited the Swinburne university courses list [3] and found 25 IT courses vs 29 Engineering course) it seems that the ratio of Engineering graduates to jobs is not likely to be as good as that for CS graduates. Of course it may be that all the other universities have hardly any Engineering courses and balance the ratio out (but I doubt it). In any case this would be a good way of injecting some facts into a discussion of the relative merits of different career choices and avoiding it being an issue of parents/teachers not liking computers vs children liking them. Determining the relative pay rates of different industries is a lot more difficult (and requires a significant amount of work), some recruiting agencies publish statistics - but those stats only apply to the positions that they fill (which is a sub-set of the actual positions). Finally as a piece of advice for children, try and find a job that you enjoy. If you earn $30K doing something you enjoy then you’ll probably be happier than if you earn $100K doing something you hate. Also if you enjoy your work then you will probably be able to take the extra steps needed to become successful - often it’s not a choice between having fun or making good money but a choice between fun and good money or the absence of both. If someone tells you to avoid doing what you love and instead do something boring for some unsubstantiated belief that there would be more money in it then be a nerd and tell them that their opinion is not relevant (it does tend to make teachers angry though).

10 October 2007

Russell Coker: Who Can Contribute to Free Software

A common misconception is that only programmers can contribute to free software. The first significant reference I recall to this was in a presentation by Pia Waugh [1] where she mentioned that she felt that the way words such as “coder” and “hacker” are used in the community as synonyms for “contributor” are denigrating to people such as herself who aren’t coders! I’m certain that no-one in the Australian Linux community would have any doubt about Pia’s contributions, not even when they mis-use terms such as “coder“. Non-coding ways of contributing include writing documentation, arranging meetings and conferences, and serving on the committee of LUGs and other organisations. I’m sure that there are many other ways of contributing that I can’t think of at the moment. The development of the free software community depends on a wide range of skills, and many of the best coders don’t have great skills in other areas. The meme that you have to be a great coder to contribute causes two problems, one is that there is a lack of contributers to non-coding tasks, and another is that coders end up doing non-coding work that they are often not particularly good at and which takes them away from things that they do well. I recently refused a nomination for the committee of my local LUG because I believe that most members can do the committee work as well as I can and many of them can do it better than me - so it’s best if I spend my time coding and preparing presentations about code that I write instead of joining the LUG committee. I was reminded of Pia’s presentation (from some years ago) by a comment on my blog post about Ideas for a Home University [2] where the commenter seems to believe that they can’t adopt the university degree equivalent via free software contributions that I suggest because of not being a programmer or sys-admin. I really doubt that anyone would care if Pia has a university degree (I don’t know whether she has one), I’m sure that the companies that hire Waugh Partners [3] do so because of the reputation that Pia and Jeff have for getting things done and for their positions in the community and not because of whatever certificates that the partners may have. I suggest to the commenter in question (and anyone else in a similar position) that they become involved in running their local LUG (or starting one if there isn’t one already). You would really be surprised by the number of job opportunities that arise from running such a community organisation.

Next.

Previous.
