Search Results: "cas"

23 April 2012

Clint Adams: Work in advertising!

The marketing industry divides itself up into a number of businesses. Some are boutique agencies, but most are owned by one of the world's four major holding companies. These conglomerates pursue an aggressive M&A strategy, snapping up smaller companies all the time. There are other sets of services, as well as variations on the above, particularly in terms of targeting certain age groups or ethnic groups, but also particular industries or sectors (movies, politics). There is direct marketing (spamming) through all the imaginable media. There is also paying people to blog about certain things without disclosing their sponsorship.

Russell Coker: Links April 2012

Karen Tse gave an interesting TED talk about how to stop police torture as an investigative tool [1]. Mostly it s about training and empowering public defenders. Phil Plait gave an interesting TED talk about how to defend the Earth from asteroids [2]. Julian Baggini wrote an interesting article for the Financial Times about the persecution of Atheists in the US [3]. Charlie Todd of Improv Everywhere gave an amusing TED talk about Improv events that he has run [4]. He is most famous for organising people to wear blue shirts and khaki pants in Best Buy, but he s done lots of other funny things. Paul Zak gave an interesting TED talk about trust, morality, and oxytocin [5]. One of the many interesting fact that he shared is that oxytocin levels can significantly increase when using social networking sites. So people who use Facebook etc are likely to be more trustworthy as well as more trusting. The Occupy the Judge Rotenberg Center movement aims to stop the torture of Autistic children in the US [6], Anonymous is involved in that too. Paul Lewis gave an insightful TED talk about the use of crowdsourced data in news reporting [7]. A lot of the analysis of citizen journalism is based on comparing bloggers with full-time paid journalists, but Paul describes how professional full-time journalistic work can be greatly assisted by random people filming and photographing things that seem noteworthy. Make sure your next phone has the best possible camera phone cameras will never be great but the quality of the camera you have with you is what matters. Sam Harris published an interesting interview with Tim Prowse who is a Baptist minister who faked belief for two years after becoming an atheist [8A]. He also references The Clergy Project a support group for atheists who are current or former members of the clergy [8B]. Cracked has an insightful article about 6 things that rich people need to stop saying [9]. How do the 1% not understand these things? Barack Obama and Nichelle Nichols (who played Lt Uhura in the original Star Treck) give the Vulcan Salute in the White-House [10]. Gabriel Arana wrote an insightful article about his experiences with the ex-gay movement [11]. The therapist who hurt him so much is still doing the same to other victims. S#!T Ignorant People Say To Autistics is an interesting youtube video about ignorant and annoying people [12]. Strangely I ve received little of that myself, I wonder whether women on the Autism Spectrum get a lot more of that than men. At GManCaseFile an ex-FBI agent has written an informative post about how the TSA is failing [13]. The Nieder Family has an interesting article about how patents are being used to prevent the creation of assisted communication (AAC) devices for children [14]. Apparently the company that has the patents wants all AAC devices to be really expensive and profitable for them. This is yet another example of patents doing harm not good. Renew Economy has an informative article by Giles Parkinson about the affect that solar power generation will have on power prices [15]. In short as solar systems produce power when it s most needed (during the day and at the hottest time of the day for warm climates) it will dramatically reduce the auction price for wholesale power. That will hurt the business of the power companies and also allow lower prices on the retail market. Related posts:
  1. Links March 2012 Washington s Blog has an informative summary of recent articles about...
  2. Links February 2012 Sociological Images has an interesting article about the attempts to...
  3. Links April 2010 Sam Harris gave an interesting TED talk about whether there...

Julien Danjou: OpenStack Swift eventual consistency analysis & bottlenecks

Swift is the software behind the OpenStack Object Storage service. This service provides a simple storage service for applications using RESTful interfaces, providing maximum data availability and storage capacity. I explain here how some parts of the storage and replication in Swift works, and show some of its current limitations. If you don't know Swift and want to read a more "shallow" overview first, you can read John Dickinson's Swift Tech Overview. How Swift storage works If we refer to the CAP theorem, Swift chose availability and partition tolerance and dropped consistency. That means that you'll always get your data, they will be dispersed on many places, but you could get an old version of them (or no data at all) in some odd cases (like some server overload or failure). This compromise is made to allow maximum availability and scalability of the storage platform. But there are mechanisms built into Swift to minimize the potential data inconsistency window: they are responsible for data replication and consistency. The official Swift documentation explains the internal storage in a certain way, but I'm going to write my own explanation here about this. Consistent hashing Swift uses the principle of consistent hashing. It builds what it calls a ring. A ring represents the space of all possible computed hash values divided in equivalent parts. Each part of this space is called a partition. The following schema (stolen from the Riak project) shows the principle nicely: Consistent hashing ring In a simple world, if you wanted to store some objects and distribute them on 4 nodes, you would split your hash space in 4. You would have 4 partitions, and computing hash(object) modulo 4 would tell you where to store your object: on node 0, 1, 2 or 3. But since you want to be able to extend your storage cluster to more nodes without breaking the whole hash mapping and moving everything around, you need to build a lot more partitions. Let's say we're going to build 210 partitions. Since we have 4 nodes, each node will have 210 4 = 256 partitions. If we ever want to add a 5th node, it's easy: we just have to re-balance the partitions and move 1 4 of the partitions from each node to this 5th node. That means all our nodes will end up with 210 5 204 partitions. We can also define a weight for each node, in order for some nodes to get more partitions than others. With 210 partitions, we can have up to 210 nodes in our cluster. Yeepee. For reference, Gregory Holt, one of the Swift authors, also wrote an explanation post about the ring. Concretely, when building one Swift ring, you'll have to say how much partitions you want, and this is what this value is really about. Data duplication Now, to assure availability and partitioning (as seen in the CAP theorem) we also want to store replicas of our objects. By default, Swift stores 3 copies of every objects, but that's configurable. In that case, we need to store each partition defined above not only on 1 node, but on 2 others. So Swift adds another concept: zones. A zone is an isolated space that does not depends on other zone, so in case of an outage on a zone, the other zones are still available. Concretely, a zone is likely to be a disk, a server, or a whole cabinet, depending on the size of your cluster. It's up to you to chose anyway. Consequently, each partitions has not to be mapped to 1 host only anymore, but to N hosts. Each node will therefore store this number of partitions:
number of partition stored on one node = number of replicas   total number of partitions   number of node
Examples:
We split the ring in 210 = 1024 partitions. We have 3 nodes. We want 3 replicas of data.
Each node will store a copy of the full partition space: 3 210 3 = 210 = 1024 partitions.
We split the ring in 211 = 2048 partitions. We have 5 nodes. We want 3 replicas of data.
Each node will store 211 3 5 1129 partitions.
We split the ring in 211 = 2048 partitions. We have 6 nodes. We want 3 replicas of data.
Each node will store 211 3 6 = 1024 partitions.
Three rings to rule them all In Swift, there is 3 categories of thing to store: account, container and objects. An account is what you'd expect it to be, a user account. An account contains containers (the equivalent of Amazon S3's buckets). Each container can contains user-defined key and values (just like a hash table or a dictionary): values are what Swift call objects. Swift wants you to build 3 different and independent rings to store its 3 kind of things (accounts, containers and objects). Internally, the two first categories are stored as SQLite databases, whereas the last one is stored using regular files. Note that this 3 rings can be stored and managed on 3 completely different set of servers. Swift storage schema Data replication Now that we have our storage theory in place (accounts, containers and objects distributed into partitions, themselves stored into multiple zones), let's go the replication practice. When you put something in one of the 3 rings (being an account, a container or an object) it is uploaded into all the zones responsible for the ring partition the object belongs to. This upload into the different zones is the responsibility of the swift-proxy daemon. Swift proxy schema But if one of the zone is failing, you can't upload all your copies in all zones at the upload time. So you need a mechanism to be sure the failing zone will catch up to a correct state at some point. That's the role of the swift- container,account,object -replicator processes. This processes are running on each node part of a zone and replicates their contents to nodes of the other zones. When they run, they walk through all the contents from all the partitions on the whole file system and for each partition, issue a special REPLICATE HTTP request to all the other zones responsible for that same partition. The other zone responds with information about the local state of the partition. That allows the replicator process to decide if the remote zone has an up-to-date version of the partition. In case of account and containers, it doesn't check at the partition level, but check each account/container contained inside each partition. If something is not up-to-date, it will be pushed using rsync by the replicator process. This is why you'll read that the replication updates are "push based" in Swift documentation.
# Pseudo code describing replication process for accounts
# The principle is exactly the same for containers
for account in accounts:
    # Determine the partition used to store this account
    partition = hash(account) % number_of_partitions
    # The number of zone is the number of replicas configured
    for zone in partition.get_zones_storing_this_partition():
        # Send a HTTP REPLICATE command to the remote swift-account-server process
        version_of_account = zone.send_HTTP_REPLICATE_for(account):
        if version_of_account < account.version()
            account.sync_to(zone)
This replication process is O(number of account number of replicas). The more your number of account will increase and the more you will want replicas for your data, the more the replication time for your accounts will grow. The same rule applies for containers.
# Pseudo code describing replication process for objects
for partition in partitions_storing_objects:
    # The number of zone is the number of replicas configured
    for zone in partition.get_zones_storing_this_partition():
        # Send a HTTP REPLICATE command to the remote swift-object-server process
        verion_of_partition = zone.send_HTTP_REPLICATE_for(partition):
        if version_of_partition < partition.version()
            # Use rsync to synchronize the whole partition
            # and all its objects
            partition.rsync_to(zone)
This replication process is O(number of objects partitions number of replicas). The more your number of objects partitions will increase, and the more you will want replicas for your data, the more the replication time for your objects will grow. I think this is something important to know when deciding how to build your Swift architecture. Choose the right number the number of replicas, partitions and nodes. Replication process bottlenecks Copycat File accesses The problem, as you might have guessed, is that to replicate, it walks through every damn things, things being accounts, containers, or object's partition hash files. This means it need to open and read (part of) a every file your node stores to check that data need or not to be replicated! For accounts & containers replication, this is done every 30 seconds by default, but it will likely take more than 30 seconds as soon as you hit around 12 000 containers on a node (see measurements below). Therefore you'll end up checking consistency of accounts & containers on each all node all the time, using obviously a lot of CPU time. For reference, Alex Yang also did an analysis of that same problem. TCP connections Worst, the HTTP connections used to send the REPLICATE commands are not pooled: a new TCP connection is established each time something has to be checked against the same thing stored on a remote zone. This is why you'll see in the Swift's Deployment Guide this lines listed under "general system tuning":
# disable TIME_WAIT.. wait..
net.ipv4.tcp_tw_recycle=1
net.ipv4.tcp_tw_reuse=1
# double amount of allowed conntrack
net.ipv4.netfilter.ip_conntrack_max = 262144
In my humble opinion, this is more an ugly hack than a tuning. If you don't activate this and if you have a lot of containers on your node, you'll end up soon with thousands of connections in TIME_WAIT state, and you indeed risk to overload the IP conntrack module. Container deletion We also should talk about container deletion. When a user deletes a container from its account, the container is marked as deleted. And that's it. It's not deleted. Therefore the SQLite database file representing the container will continue to be checked for synchronization, over and over. The only way to have a container permanently deleted is to mark an account as deleted. This way the swift-account-reaper will delete all its containers and, finally, the account. Measurement On a pretty big server, I measured the replications to be done at a speed of around 350 account,container,object-partitions /second, which can be a real problem if you chose to build a lots of partition and you have a low number_of_node number_of_replicas ratio. For example, the default parameters runs the container replication every 30 seconds. To check replication status of 12 000 containers stored on one node at the speed of 350 containers/seconds, you'll need around 34 seconds to do so. In the end, you'll never stop checking replication of your containers, and the more you'll have containers, the more your inconsistency window will increase. Conclusion Until some of the code is fixed (the HTTP connection pooling probably being the "easiest" one), I warmly recommend to chose correctly the different Swift parameters for your setup. The replication process optimization consists in having the minimum amount of partitions per node, which can be done by: For very large setups, some code to speed up accounts and containers synchronization, and remove deleted containers will be required, but this does not exist yet, as far as I know.

22 April 2012

Joey Hess: moving my email archives and packages to git-annex

I've recently been moving some important data into git-annex, and finding it simplifies things while also increasing my flexability. email archives I've kept my email archives in git for years. This works ok, just choose the right file format (compressed mbox) and number of files (one archive per mailbox per month or so) and git can handle this well enough, as email is not really large. But, email is not really small either. Keeping my email repository checked out on my netbook consumes 2 gigabytes of its 30 gigabyte SSD, half of which is duplication in .git. Also, I have only kept it at 2 gigabytes through careful selection of what classes of mail I archive. That made sense when archival disk was more expensive, but what makes sense these days is to archive everything. For a while I've wanted to have a "raw" archive, that includes all email I receive. (Even spam.) This protects against various disasters in mail filtering or reading. Setting that up was my impetus for switching my mail archives to git-annex today. The new system I've settled on is to first copy all incoming mail into a "raw" maildir folder. Then mailfilter sorts it into the folders I sync (with offlineimap) and read. Each day, the "raw" folder is moved into a mbox archive, and that's added to the git annex. Each month, the mail I've read is moved into a monthly archives, and added to the git annex. A simple script does the work. I counted the number of copies that existed of my mail when it was stored in git, and found 7 copies spread amoung just 3 drives. I decided to slim that back, and configured git-annex to require only 5 copies. But those 5 copies will spread amoung more drives, including several offline archival drives, so it will be more robust overall. My netbook will have an incomplete checkout of my mail, omitting the "raw" archive. If I need to peek inside a spam folder for a lost mail, I can quickly pull it down; if I need to free up space I can quickly drop older archives. This is the flexability that git-annex fans love. :) By the way, this also makes it easier to permanantly delete mail, when you really need to (ie, for contractual reasons). Before, I'd have to do a painful git-filter-branch if I needed to get rid of eg, mail for old jobs. Now I can git annex drop --force. Pro Tip: If you're doing this kind of migration to git-annex, you can save bandwidth by not re-transferring files to machines that already have a copy. I ran this command on my netbook to inject the archives it had in the old repository into the new repository, verifying checksums as it goes:
cd ~/mail/archive; find -type l -exec git annex reinject ~/mail.old/archive/    \;
Note on mairix compatability: I use mairix to index and search my mail. But it refuses to follow git-annex's symlinks to the content. So I have to point it at .git/annex/objects/. I also configured annex.backend to SHA256E, which keeps the extensions on my compressed mailbox files, which is necessary for mairix to realize they're compressed. debian packages I'd evolved a complex and fragile chain of personal apt repositories to hold Debian packages I've released. I recently got rid of the mess, which looked like this: dput local mini-dinstall repo dput&rarr;mini-dinstallrepo on my server &rarr;dput Debian The point of all that was that I could "upload" a package locally while offline and batch transfer it later. And I had a local and a public apt repository of just the packages I've uploaded. But these days, packages uploaded to Debian are available nearly immediately, so there's not much reason to do that. My old system also had a problem: It only kept the most recent single copy of each package. Again, disk is cheap, so I'd rather have archives of everything I have uploaded. Again I switched to git-annex. My new system is simplicity itself. I release a package by checking it into a "toupload" directory in my git annex repository on my netbook. Items in that directory are dput to Debian and moved to "released". I have various other clones of that repository, which I git annex move packages to periodically to free up SSD space. In the rare cases when I build a package on a server, I check it into the clone on the server, and again rely on git-annex to copy it around. Now, does anyone know a good way to download a copy of every package you're ever released from archive.debian.org? (Ideally as a list of urls I can feed to git annex addurl.) conclusion My email and Debian packages were the last large files I was not storing in git-annex. Even backups of my backups end up checked into git-annex and archived away. Now that I'm using git-annex in every place I can, my goal with it is to make it as easy as possible for as many of you to use it as possible, too. I have some inotify tricks up my sleeve that seem promising. Kickstarter may be involved. Watch this space!

Gregor Herrmann: RC bugs 2012/16

this week I've started to look at the (not yet release critical) gcc 4.7 bugs. luckily there are still enough patches for them in the BTS but at the time of writing, at least 138 are not fixed & don't have a patch yet. so still some work ahead.

& for those who prefer to fix debian/rules files, lucas' last archive rebuild (where build-arch was used) still leaves enough work, & many bugs are not difficult to fix with a basic understanding of makefiles & debian build sytems.

Julian Andres Klode: Reference Counting and Tail Calls

One thing I thought about today is reference counting in combination with tail calls. Imagine a function like this:
function f(x)   return g(x+1);  
Now consider that x is a reference counted object and that x + 1 creates a new object. The call to g(x + 1) shall be in tail call position. In most reference counted languages, the reference to an argument is owned by the caller. That is, f() owns the reference to x + 1. In that case, the call to g() would no longer be in a tail call position, as we still have to decrease the reference count after g() exits. An alternative would be that the callee owns the reference. This however, will most likely create far more reference count changes than a caller-owns language (increase reference count in caller, decrease reference count in callee). For example, the following function requires an increment before the call to g().
function f1(x)   return g(x);  
Does anyone have any ideas on how to solve the problem of tail calls while avoiding the callee-owns scenario? Something that does not require a (non-reference-counting) garbage collector would be preferably.
Filed under: General

Christian Perrier: Bug #670000

Julien Cristau reported Debian bug #670000 on Sunday April 22th, against libgtkada. This bug is indeed part of a MBF for packages that are "marked as Multi-Arch: same, but contain files in arch-independent paths with arch-specific contents" (doh, these multi-arch things are sometimes giving me headaches!) Bug #660000 was reported as of February 15th: 2 months and 7 days for 10,000 bugs. As expected, QA work and release preparation do trigger an increase in bug report rate and we're now again quite close from the "10,000 bugs in two months mark". I forgot to report that bug #666666 has been reported in the meantime. This time by one of the top bug reporters in Debian, namely Lucas Nussbaum, during one of his archive-wide package rebuilds, against psimedia. Next step will be bug #680000, targeted in June 2012. With this rate, bug #700000 should be reported around mid-November 2012 and Kartik Mistry would win the Bug #700000 prediction contest". In the meantime, Launchpad will have reached bug #1000000 (the highest bug number is currently #986849....which will be no longer true by the time you read this). The rate in LP is currently about 20,000 bugs per month. I wonder how many of these are closed as I feel like this is humanly impossible to process that many bug reports.

Iustin Pop: Running: Z rich city run rain, rain, rain

This year was the 10th anniversary of the Z rich marathon, so they had a new category: 10km city run (at least, I think it was a new category). So I went along, thinking 10k would be a nice Sunday run. But oh, even the famed Swiss organisational skills fail some time. And when they fail, they fail hard. First, if you have 3 events all going on at the same time (marathon, team run, city run), please, please mark the road appropriately. The finish line was marked only marathon and team run, so I didn't even knew when I finished, I only realised well, that must have been it when I reached the place where I gave back the transponder chip. This marking issue was on-going for the last ~500-600 metres, as I thought I was lost when running along a road marked (again) only with marathon and team run and almost exited the road to look for my actual trail. Of course, if I had remembered that the finish is common to all three categories, all would have been good, but don't ask me to remember such stuff at the end of a race. Second, clothes storage. They had clothes storage organised nicely, in railroad freight cars, 500 people per car. This went well, except that they underestimated the number of people registering, so the last car had well over 700 bags, which created a huge bottleneck for this single car, which of course was where I also had the clothes (as I registered late). So I run for ~1 hour and then spend 30 minutes getting my clothes back. This wouldn't have been an issue, if the weather would have been fine. But it started raining seriously 500 meters into the race, and by the time I finished I was already fully drenched, just in a t-shirt (thanks fully with long pants) and waiting in the rain for 30 minutes was painful. I think also unhealthy, due to the abrupt switch from running to just standing in the rain. I haven't been so cold in a long while. By the time I got home my hands were shaking so hard I couldn't unzip my jacket (and I couldn't stop shaking, which is not a good sign). So yeah, I learned a few things. Try not to use the clothes storage if you can (it was the first time I used it), especially if you can pick up the stuff they give you a day early (and I could have gone to the race directly dressed) and I hope the organisers learned to provide better conditions just in case it rains. Which in Z rich happens, well, quite often. People were joking in the line: "1 hour running, 1 hour picking the clothes, 1 week sick". I hope I won't get sick (a hot tea after a hot bath can do wonders), but still, at least my voice will sound like after whole-night partying. OK, rant over. What about the race? It's nice (except the very dark overcast & rain, as said), through the centre of the city; as a friend says: Running on Bahnhofstrasse is cool . Otherwise, 10k seem to go quite quick nowadays . Having ~1,600 people all in red t-shirts was funny, especially if you're trying to look for friends. It was a very diverse crowd, you could see more varied people than in the other races (where more running-focused people seem to come); here there were all kind of people, children, teenagers, adults and so on, no per-category start or such. As to myself, I still am bothered by some small injuries, so I can't enjoy the nice result I got: 47m26.4s, for a 4m.44s/km! Yay! Of course, the reason I run so fast was because I was cold and needed to run to heat up. Also, again a flat race. I should start getting friends with hills. And due to the fact that it was a more diverse crowd, for the first time I didn't class (in my age category) around the ~66% down the list, but around ~44% only (~13 minutes slower than the winner). Yay!

Robert Collins: Reading list

I ve recently caught up on a bunch of reading some of which are worth commending. Read them all, or none. I enjoyed them all.

20 April 2012

Sven Mueller: Ex-TSA lead on air traffic security woes

I came across this article today and really found it noteworthy: http://online.wsj.com/article/SB10001424052702303815404577335783535660546.html Original title: Why Airport Security Is Broken And How To Fix It Kip Hawley, TSA head from July 2005 to January 2009, writes about how the current TSA procedures came into being, how he failed at some of his goals (to make the checks less annoying) during his involvement and what could be done to fix procedures. I especially liked these points:
By the time of my arrival, the agency was focused almost entirely on finding prohibited items. Constant positive reinforcement on finding items like lighters had turned our checkpoint operations into an Easter-egg hunt. When we ran a test, putting dummy bomb components near lighters in bags at checkpoints, officers caught the lighters, not the bomb parts.
(also quoted on LWN.net) And this one:
The public wants the airport experience to be predictable, hassle-free and airtight and for it to keep us 100% safe. But 100% safety is unattainable.
I think the most important thing he mentioned is the fifth and last of his action items to improve both experience by passengers and security:
5. Randomize security: Predictability is deadly. Banned-item lists, rigid protocols if terrorists know what to expect at the airport, they have a greater chance of evading our system.
He got it nailed there, in my opinion: If security measures are predictable, the loopholes in it are also predictable, so you basically give attackers a handbook of what to avoid when planning the attack. This, by the way isn t limited to physical security and air travel, but also applies to IT security (though it is much easier to hide your IT security measures and make them somewhat unpredictable that way, then it is to do so with physical security and passenger screening on airports.

Dirk Eddelbuettel: RcppArmadillo 0.3.0.2 released and on CRAN

Earlier today, Conrad Sanderson released another bug-fix version 3.0.2 for the still fairly recent 3.0.0 version of his excellent Armadillo C++ template library for linear algebra. The new RcppArmadillo release 0.3.0.2 also appeared on CRAN this morning. Beside Conrad's bugfix in Armadillo itself, he also convinced us to unroll a change imposed by R: NDEBUG is now being defined unconditionally when compiling R packages. In Armadillo's case, this suppresses a number of useful things including bounds-checking. So we now undefine this symbol in the initial RcppArmadillo headers. Users can still set it manually, and/or define ARMA_NO_DEBUG. The short NEWS entry follows below.
0.3.0.2 2012-04-19
    o   Upgraded to Armadillo release 3.0.2
          * fixes for handling diagonal matrices
    o   Undefine NDEBUG if it has been set (as R does) as this prevents a
        number of useful debugging checks. Users can still define it or
        define ARMA_NO_DEBUG if they want a 'non-development' build
Courtesy of CRANberries, there is also a diffstat report for 0.3.0.2 relative to 0.3.0.1 As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

Keith Packard: fireworks

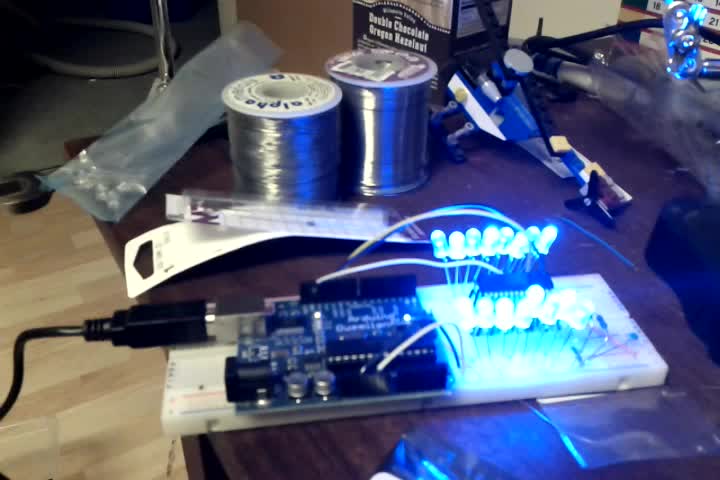
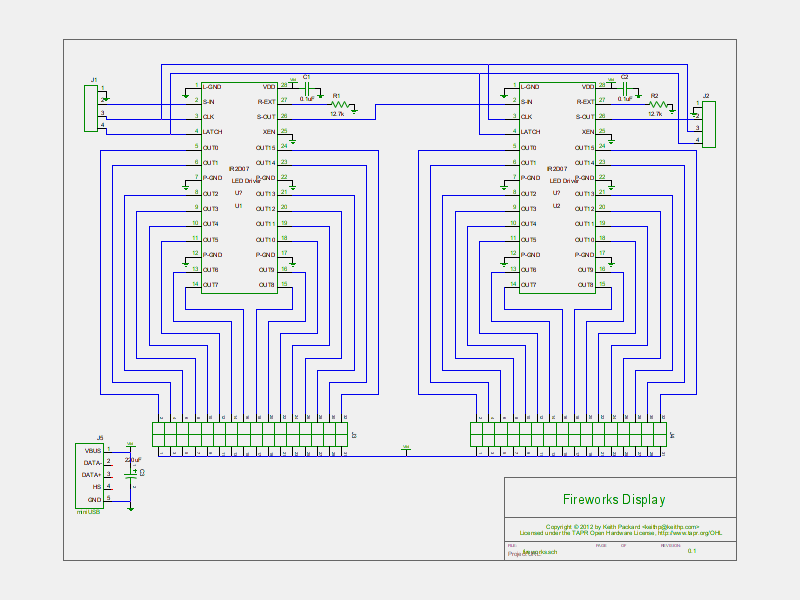
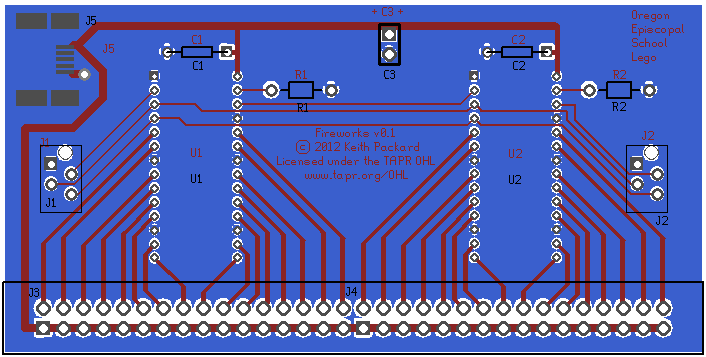
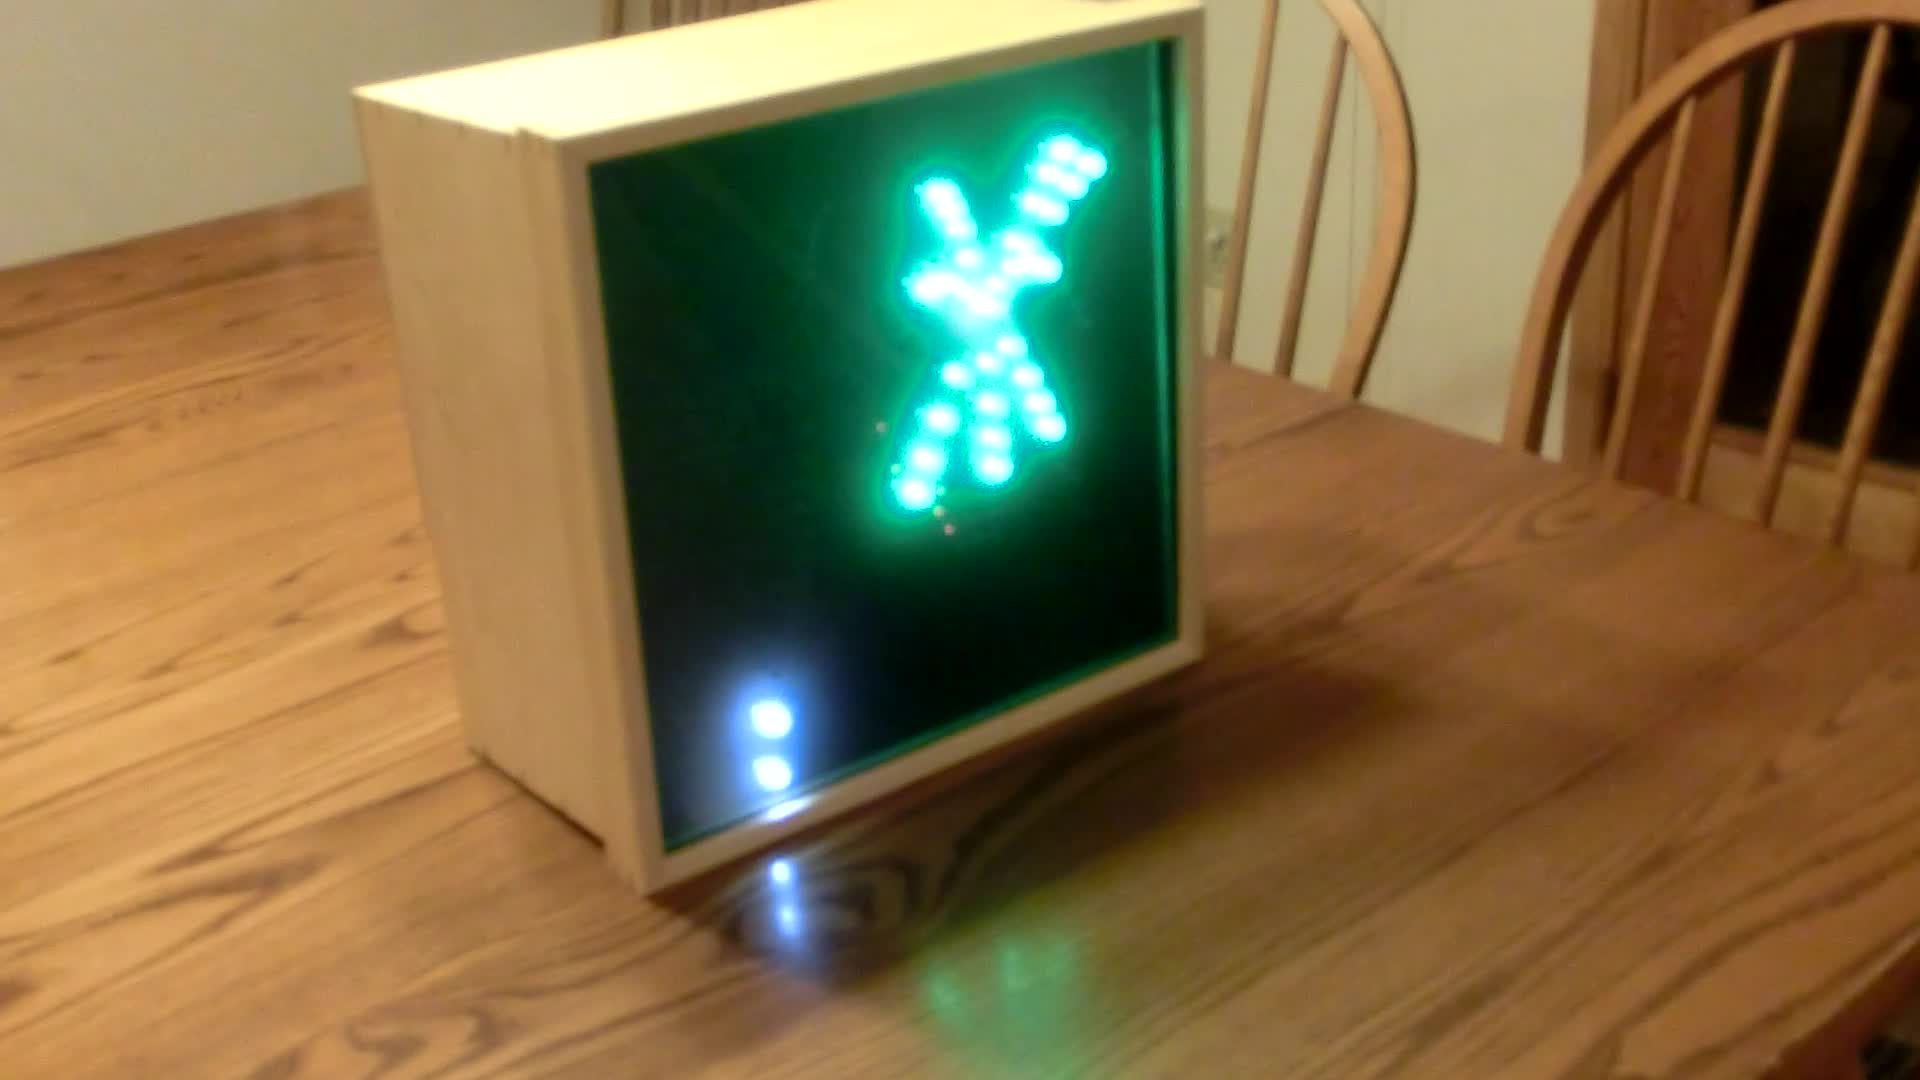
LED Fireworks. Or, parent helpers go overboard My friend, Mike Ward, and I help out at our kids school by teaching 5th and 6th graders programming in conjunction with a Lego class. For several years, I was teaching Logo on ancient Apple II machines. The teacher had a great curriculum and the kids learned a lot, but this year we decided to switch things around and try them out on Arduinos. This spring, the kids are building a Lego display centered around a birthday party theme for the star elephant at the Oregon Zoo (Packy), who turned 50 last weekend. In a moment of fun, I suggested that perhaps we should have some fireworks, along with the presents and birthday cake. How hard could it be to wire up a couple of LEDs to an Arduino to make something that looked like fireworks? Selecting parts. Mike and I sat down to order some parts from Digikey. We found these nice, cheap, LED drivers from Sharp. Then we found a selection of LEDs from Cree along with current-programming resistors (12.7k ) to drive the LEDs at 20mA, and some bypass caps (0.1 F) to keep the parts happy. The LED drivers are simple shift registers, with separate clock and data. They have both input and output pins, so you can daisy chain them and drive as many as you like from a single pair of CPU pins. We figured 160 LEDs would be plenty, so we ordered 10 chips. The LED drivers came in a through-hole, DIP package; it seemed like we d be able to just stuff them into a breadboard and quickly wire things up. Prototyping the design The LED driver chips turn out to use a much finer pitch package than the usual 0.1 spacing. There s no way we could stuff them into a breadboard and quickly wire things up. Obviously, a bit more care while ordering would have uncovered this, but my experience with through-hole parts is limited to parts from the mid 1970s I soldered extension wires onto one chip to test the circuit, and managed to get one chip talking to an Arduino. Here s a short movie of that in action: You can see the LED driver chip sitting on a set of extension leads plugged into the breadboard. It s hooked to the SPI port on the Arduino board, with the clock set as fast as it will go. If you watch the video, you can see that the LEDs actually vary in brightness. They re actually being pulse-width modulated. Clocked at 2MHz, there s enough bandwidth in the SPI bus to drive 160 LEDs with 127 discrete pulse widths at nearly 100Hz (100 * 127 * 160 = 2032000). Is bread boarding practical? With the chip propped up on its extension wires, and the LEDs plugged in, the whole setup was not surprisingly fragile. Getting five of these chips wired up and running for the length of the Lego show (one day at school and two days at the zoo) seemed unlikely. So, we decided to build some custom circuit boards. Using the GEDA tools to make circuit boards My business partner, Bdale Garbee, and I build rocketry electronics through Altus Metrum. He s the hardware guy and I spend my weekends writing firmware for various micro-controllers. Of course, I use free software tools for the firmware, and Bdale uses the free gEDA tools for the hardware. I ve gotten vaguely familiar with those by helping Bdale review circuit diagrams and PC board layout over the years. So I figured I d be able to learn a bit more about them and come up with some designs. I decided to stick two LED drivers on each board. As the chips can drive each LED with up to 50mA of current, each board could potentially consume 1.6A at 5V. Sticking a linear regulator on each board capable of supplying that much current would have required a hefty heat sink. Instead, I decided to stick a mini USB connector on the board and use some cheap USB power supplies. Of course, there wasn t a pre-packaged schematic symbol or footprint for the LED driver, so I first had to construct those. But, with symbols for all of the parts I used available, I drew this circuit: Wiring up 32 LEDs It s really easy to draw wires showing 32 LEDs hooked up to each board. Actually selecting connectors that can be easily hooked up took a bit more time. The idea of crimping individual two-pin connectors for 160 LEDs didn t seem like fun, plus individual connectors were going to cost a small fortune (the best option I found would have cost about $0.40 per LED). Bdale suggested using ribbon cable with a crimp-on connector crimp a connector across the whole cable and then split out two-wire sets for each LED. I d still have to individually solder each LED to the wire, but on the board end, all I d have to do is crimp the connector on to the cable. Designing the circuit boards The gEDA tools separate schematic design and PCB layout into two separate tools; the schematic program, gschem, exports a netlist and set of components which the schematic program, PCB, can import. This sounded a bit clunky to me, as you have to re-export and re-import the schematic data into the PCB each time you make changes, but it seems to work reasonably well in practice. The first time the schematic data is imported to the PCB tool, all of the component footprints are simply stacked on top of one another. With those moved to sensible locations, the tool will show rats for each netlist. Having drawn the schematic with symbols that strongly resembled the actual components, it was pretty easy to work through the rats one at a time by painting copper on the board. I d noticed that all of the signals could easily be routed on one side of the board, so I flooded the back side with a ground plane to keep things quiet. The final circuit board design looks like this: Circuit boards. All Altus Metrum products are manufactured by Advanced Circuits, and we ve been quite happy with them. They offer a cheap and fast prototyping service through their barebonespcb.com site. These boards are two layers with no silk screen or solder mask. I uploaded my design and in a couple of days I got back some shiny circuit boards: The footprint I designed for the LED drivers turned out to have a very small gap between the pads for each pin and the ground plane. This lead to a couple of shorted pins in the five boards, which were pretty easy to diagnose as the LED driven by that pin would be stuck on. Here s another picture with the ribbon cable connected and an LED lit up: Mounting the LEDs I started by writing a small nickle program to simulate the trajectory of a ballistic fireworks shell followed by an explosion at apogee and subsequent ballistic tracks for the resulting pieces. I made the initial conditions of the launch somewhat random, and Mike and I sat and watched that draw things until we saw a couple that looked good . The output from that was a series of X/Y locations spaced uniformly in time. Mike used those to drill holes in a piece of acrylic from TAP plastics. He glued the LEDs into that with some white glue (so that we have a chance of getting them back out): A custom maple box? I spent last weekend visiting my father for his birthday. Meanwhile, Mike was busy back home building a case for the project. I got home and found that he had fabricated a solid maple case. It s beautiful, and holds all of the LEDs, boards, wires and a couple of 4-outlet USB power supplies. Here s a picture of the joint he made in the box corners: The finished product Here s the inside of the box: And here s a movie of the whole thing in action. It s missing 8 white LEDs; I hadn t ordered enough from Digikey. Downloading schematics and PCB artwork The hardware design is licensed under the TAPR Open Hardware License. It s all stored in git (of course):
git://keithp.com/git/hw/fireworks
All of the symbols I created are also available through git:
git://keithp.com/git/hw/keithp
Things I d do differently One of the frustrating things about moving atoms around instead of just bits is that once you ve got a physical artifact, it s really expensive to change it. There are a couple of minor things I would change if I were going to build more of these: Things that worked well There were a couple of things that went better than I had expected:

19 April 2012

James Morrison: Issues with Appengine

I like App Engine, my wedding website runs on App Engine as well as a couple recent commercial projects. However, there are some annoyances that make a lot of the useful things I learned at Google not applicable.

  1. Chunked responses
    App Engine doesn't have a way of doing chunked responses.
    1.5. Processing after sending the responseMy annoyance here is that I can't send an early response and wait for some resource. Say I want to do 5 url fetches that I cache for a short period of time. If I want to reply in 250ms, I want to use any of the results I've gotten and reply to the user. Then once the rest of the fetches come in, I want to put them in the cache, so they will come back quickly the next time.
  2. Counters
    App Engine has crappy support for counters. You can shard your counters into the datastore: https://developers.google.com/appengine/articles/sharding_counters#counter_python or you can use taskqueues: http://blog.appenginefan.com/2009/10/non-sharded-counters-part-2-using-task.html . Now, how do you graph these counters over time, well, that is left as an exercise for the reader. Google has special datastores for stores and retrieving counters.
  3. Backends
    Backends in appengine are versioned separately from frontends. This sounds like a good idea, but to run the devserver with backends, the backends need to be in the same source tree. Thus backends share the same url space. Backends also share the same app.yaml, so again the url space is shared. Thus, if you make a change that you want to coordinate between the frontend and the backend, you need to change the application version in app.yaml, then rename all the backends in backends.yaml. If backends are supposed to be in the same source tree as frontends, then they should be prefixed with the application version. If backends should be versioned separately from frontends, then they shouldn't share url handlers from app.yaml.
    3.5 Uploading backends is slow
    Each backend is uploaded through appcfg.py separately. So if you are crazy and have one backend per backend level, then you need to upload 4 copies of the source code each time the backends get updated.
  4. Logging
    I want structured logs. Instead what you have to do is use the python logging module to write out human readable logs, then parse them out into the structure you want.
    http://code.google.com/p/google-app-engine-samples/source/browse/trunk/logparser/logparser.py

As a preemptive counter, 1.5 could be dealt with using backends and a background thread, except backends don't scale to the number of queries, so my use case above isn't fixed.

Rapha&#235;l Hertzog: People behind Debian: Samuel Thibault, working on accessibility and the Hurd

Samuel Thibault is a French guy like me, but it took years until we met. He tends to keep a low profile, even though he s doing lots of good work that deserves to be mentioned. He focuses on improving Debian s accessibility and contributes to the Hurd. Who said he s a dreamer? :-) Checkout his interview to have some news of Wheezy s status on those topics. Raphael: Who are you? Samuel: I am 30 years old, and live in Bordeaux, France. During the workday, I teach Computer Science (Architecture, Networking, Operating Systems, and Parallel Programming, roughly) at the University of Bordeaux, and conduct researches in heterogeneous parallel computing. During the evening, I play the drums and the trombone in various orchestra (harmonic/symphonic/banda/brass). During the night, I hack on whatever fun things I can find, mainly accessibility and the Hurd at the moment, but also miscellaneous bits such as the Linux console support. I am also involved in the development of Aquilenet, an associative ISP around Bordeaux, and getting involved in the development of the network infrastructure in Bordeaux. I am not practicing Judo any more, but I roller-skate to work, and I like hiking in the mountains. I also read quite a few mangas. Saturday mornings do not exist in my schedule (Sunday mornings do, it s Brass Band rehearsal :) ). Raphael: How did you start contributing to Debian? Samuel: Bit by bit. I have been hacking around GNU/Linux since around 1998. I installed my first Debian system around 2000, as a replacement for my old Mandrake installation (which after all my tinkering was actually no longer looking like a Mandrake system any more!). That was Potato at the time, which somebody offered me through a set of CDs (downloading packages over the Internet was unthinkable at the time with the old modems). I have been happily reading and hacking around documentation, source code, etc. provided on them. Contribution things really started to take off when I went to the ENS Lyon high school in 2001: broadband Internet access in one s own student room! Since sending a mail was then really free, I started submitting bugs against various packages I was using. Right after that I started submitting patches along them, and then patches to other bugs. I did that for a long time actually. I had very little knowledge of all packaging details at the time, I was just a happy hacker submitting reports and patches against the upstream source code. At ENS Lyon, I met a blind colleague with very similar hacking tastes (of course we got friends) and he proposed me, for our student project, to work on a brlnet project (now called brlapi), a client/server protocol that lets applications render text on braille devices themselves. Along the way, I got to learn in details how a blind person can use a Unix system and the principles that should be followed when developing Accessibility. That is how I got involved in it. We presented our project at JDLL, and the Hurd booth happened to be next to our table, so I discussed with the Hurd people there about how the Hurd console could be used through braille. That is how I got into the Hurd too. From then on, I progressively contributed more and more to the upstream parts of both accessibility software and the Hurd. And then to the packaging part of them. Through patches in bug reports first, as usual, as well as through discussions on the mailing lists. But quickly enough people gave me commit access so I could just throw the code in. I was also given control over the Hurd buildds to keep them running. It was all good at that stage: I could contribute in all the parts I was caring about. People however started telling me that I should just apply for being a Debian Developer; both from accessibility and Hurd sides. I had also seen a bunch of my friends going through the process. I was however a bit scared (or probably it was just an excuse) by having to manage a gpg key, it seemed like a quite dangerous tool to me (even if I already had commit access to glibc at the time anyway ). I eventually applied for DM in 2008 so as to at least be able to upload some packages to help the little manpower of the Accessibility and Hurd teams. Henceforth I had already a gpg key, thus no excuse any more. And having it in the DM keyring was not enough for e.g. signing the hurd-i386 buildd packages. So I ended up going through NM in 2009, which went very fast, since I had already been contributing to Debian and learning all the needed stuff for almost 10 years! I now have around 50 packages in my QA page, and being a DD is actually useful for my work, to easily push our software to the masses :) So to sum it up, the Debian project is very easy to contribute to and open to new people. It was used during discussions at the GNU Hackers Meeting 2011 as an example of a very open community with public mailing lists and discussions. The mere fact that anybody can take the initiative of manipulating the BTS (if not scared by the commands) without having to ask anybody is an excellent thing to welcome contributions; it is notable tha the GNU project migrated to the Debbugs BTS. More generally, I don t really see the DD status as a must, especially now that we have the DM status (which is still a very good way to drag people into becoming DDs). For instance, I gave a talk at FOSDEM 2008 about the state of accessibility in Debian. People did not care whom I was, they cared that there was important stuff going on and somebody talking about it. More generally, decisions that are made through a vote are actually very rare. Most of the time, things just happen on the mailing lists or IRC channels where anybody can join the discussion. So I would recommend beginners to first use the software, then start reporting bugs, then start digging in the software to try fix the bugs by oneself, eventually propose patches, get them reviewed. At some point the submitted patches will be correct already most of the time. That s when the maintainers will start getting bored of just applying the patches, and simply provide with commit access, and voil , one has become a main contributor. Raphael: You re one of the main contributors to the Debian GNU/Hurd port. What motivates you in this project? Samuel: As I mentioned above, I first got real contact with the Hurd from the accessibility point of view. That initially brought me into the Hurd console, which uses a flexible design and nice interfaces to interact with it. The Hurd driver for console accessibility is actually very straightforward, way simpler than the Windows or Linux drivers. That is what caught me initially. I have continued working on it for several reasons. First, the design is really interesting for users. There are many things that are natural in the Hurd while Linux is still struggling to achieve them, such as UID isolation, recently mentioned in LWN. What I really like in the Hurd is that it excels at providing users with the same features as the administrator s. For instance, I find it annoying that I still can not mount an ISO image that I build on e.g. ries.debian.org. Linux now has FUSE which is supposed to permit that, but I have never seen it enabled on an ssh-accessible machine, only on desktop machines, and usually just because the administrator happens to be the user of the machine (who could as well just have used sudo ) For me, it is actually Freedom #0 of Free Software: let the user run programs for any purpose, that is, combining things together all the possible ways, and not being prevented from doing some things just because the design does not permit to achieve them securely. I had the chance to give a Hurd talk to explain that at GHM 2011, whose main topic was extensibility , I called it GNU/Hurd AKA Extensibility from the Ground, because the design of the Hurd is basically meant for extensibility, and does not care whether it is done by root or a mere user. All the tools that root uses to build a GNU/Hurd system can be used by the user to build its own GNU/Hurd environment. That is guaranteed by the design itself: the libc asks for things not to the kernel, but to servers (called translators), which can be provided by root, or by the user. It is interesting to see that it is actually also tried with varying success in GNU/Linux, through gvfs or Plash. An example of things I love being able to do is: $ zgrep foo ~/ftp://cdn.debian.net/debian/dists/sid/main/Contents-*.gz On my Hurd box, the ~/ftp: directory is indeed actually served by an ftpfs translator, run under my user uid, which is thus completely harmless to the system. Secondly and not the least, the Hurd provides me with interesting yet not too hard challenges. LWN confirmed several times that the Linux kernel has become very difficult to significantly contribute to, so it is no real hacking fun any more. I have notably implemented TLS support in the Hurd and the Xen and 64bit support in the GNU Mach kernel used by the Hurd. All three were very interesting to do, but were already done for Linux (at least for all the architectures which I actually know a bit and own). It happens that both TLS and Xen hacking experience became actually useful later on: I implemented TLS in the threading library of our research team, and the Xen port was a quite interesting line on my CV for getting a postdoc position at XenSource :) Lastly, I would say that I am used to lost causes :) My work on accessibility is sometimes a real struggle, so the Hurd is almost a kind of relief. It is famous for his vapourware reputation anyway, and so it is fun to just try to contribute to it nevertheless. An interesting thing is that the opinion of people on the Hurd is often quite extreme, and only rarely neutral. Some will say it is pure vapourware, while others will say that it is the hope of humanity (yes we do see those coming to #hurd, and they are not always just trolls!). When I published a 0.401 version on 2011 April 1st, the comments of people were very diverse, and some even went as far as saying that it was horrible of us to make a joke about the promised software :) Raphael: The FTPmasters want to demote the Hurd port to the debian-ports.org archive if it doesn t manage a stable release with wheezy. We re now at 2 months of the freeze. How far are you from being releasable ? Samuel: Of course, I can not speak for the Debian Release team. The current progress is however encouraging. During Debconf11, Michael Banck and I discussed with a few Debian Release team members about the kind of goals that should be achieved, and we are near completion of that part. The Debian GNU/Hurd port can almost completely be installed from the official mirrors, using the standard Debian Installer. Some patches need some polishing, but others are just waiting for being uploaded Debian GNU/Hurd can start a graphical desktop and run office tools such as gnumeric, as well as the iceweasel graphical web browser, KDE applications thanks to Pino Toscano s care, and GNOME application thanks to Emilio Pozuelo Monfort s care. Of course, general textmode hacking with gcc/make/gdb/etc. just works smoothly. Thanks to recent work on ghc and ada by Svante Signell, the archive coverage has passed 76%. There was a concern about network board driver support: until recently, the GNU Mach kernel was indeed still using a glue layer to embed the Linux 2.2 or even 2.0 drivers (!). Finding a network board supported by such drivers had of course become a real challenge. Thanks to the GSoC work of Zheng Da, the DDE layer can now be used to embed Linux 2.6.32 drivers in userland translators, which was recently ACCEPTed into the archive, and thus brings way larger support for network boards. It also pushes yet more toward the Hurd design: network drivers as userland process rather than kernel modules. That said, the freeze itself is not the final deadline. Actually, freeze periods are rests for porters, because maintainers stop bringing newer upstream versions which of course break on peculiar architectures. That will probably be helpful to continue improving the archive coverage. Raphael: The kfreebsd port brought into light all the packages which were not portable between different kernels. Did that help the Hurd port or are the problems too different to expect any mutual benefit? Samuel: The two ports have clearly helped each other in many aspects. The hurd-i386 port is the only non-Linux one that has been kept working (at least basically) for the past decade. That helped to make sure that all tools (dpkg, apt, toolchain, etc.) were able to cope with non-Linux ports, and keep that odd-but-why-not goal around, and evidently-enough achievable. In return, the kFreeBSD port managed to show that it was actually releasable, at least as a technological preview, thus making an example. In the daily work, we have sometimes worked hand in hand. The recent porting efforts of the Debian Installer happened roughly at the same time. When fixing some piece of code for one, the switch-case would be left for the other. When some code could be reused by the other, a mail would be sent to advise doing so, etc. In the packaging effort, it also made a lot of difference that a non-Linux port is exposed as released architecture: people attempted by themselves to fix code that is Linuxish for no real reason. The presence of the kFreeBSD is however also sometimes a difficulty for the Hurd: in the discussions, it sometimes tends to become a target to be reached, even if the systems are not really comparable. I do not need to detail the long history of the FreeBSD kernel and the amount of people hacking on it, some of them full-time, while the Hurd has only a small handful of free-time hackers. The FreeBSD kernel stability has already seen long-term polishing, and a fair amount of the Debian software was actually already ported to the FreeBSD kernel, thanks to the big existing pure-FreeBSD hackerbase. These do not hold for the GNU/Hurd port, so the expectations should go along. Raphael: You re also very much involved in the Debian Accessibility team. What are the responsibilities of this team and what are you doing there? Samuel: As you would expect it, the Debian Accessibility team works on packaging accessibility-related packages, and helping users with them; I thus do both. But the goal is way beyond just that. Actual accessibility requires integration. Ideally enough, a blind user should be able to just come to a Debian desktop system, plug his braille device, or press a shortcut to enable speech synthesis, and just use the damn computer, without having to ask the administrator to install some oddly-named package and whatnot. Just like any sighted user would do. He should be able to diagnose why his system does not boot, and at worse be able to reinstall his computer all by himself (typically at 2am ). And that is hard to achieve, because it means discussing about integration by default of accessibility features. For instance, the Debian CD images now beep during at the boot menu. That is a precious feature that has been discussed between debian-boot and debian-accessibility for a few weeks before agreeing on how to do it without too much disturbance. Similarly, my proposition of installing the desktop accessibility engines has been discussed for some time before being commited. What was however surprisingly great is that when somebody brought the topic back for discussion, non-debian-accessibility people answered themselves. This is reassuring, because it means things can be done durably in Debian. On the installation side, our current status is that the stable Debian installer has a high contrast color theme, and several years ago, I have pushed toward making standard CD images automatically detect braille devices, which permits standalone installation. I have added to the Wheezy installer some software speech synthesis (which again brought discussion about size increase vs versatility etc.) for blind people who do not have a braille device. I find it interesting to work on such topic in Debian rather than another distribution, because Debian is an upstream for a lot of distributions. Hopefully they just inherit our accessibility work. It at least worked for the text installer of Ubuntu. Of course, the Accessibility team is looking for help, to maintain our current packages, but also introduce new packages from the TODO list or create some backports. One does not need to be an expert in accessibility: tools can usually be tested, at least basically, by anybody, without particular hardware (I do not own any, I contributed virtual ones to qemu). For new developments and ideas, it is strongly recommended to come and discuss on debian-accessibility, because it is easy to get on a wrong track that does not bring actual accessibility. We still have several goals to achieve: the closest one is to just fix the transition to gnome3, which has been quite bad for accessibility so far :/ On the longer run, we should ideally reach the scenario I have detailed above: desktop accessibility available and ready to be enabled easily by default. Raphael: What s the biggest problem of Debian? Samuel: Debian is famous for its heated debian-devel discussions. And some people eventually say this no fun any more . That is exemplified in a less extreme way in the debian-boot/accessibility discussions that I have mentioned above. Sometimes, one needs to have a real stubborn thick head to continue the discussion until finding a compromise that will be accepted for commit. That is a problem because people do not necessarily have so much patience, and will thus prefer to contribute to a project with easier acceptance. But it is also a quality: as I explained above, once it is there, it is apparently for good. The Ubuntu support of accessibility in its installer has been very diverse, in part due to quite changing codebase. The Debian Installer codebase is more in a convergence process. Its base will have almost not changed between squeeze and wheezy. That allowed the Debian Accessibility team to continue improving its accessibility support, and not have to re-do it. A wiki page explains how to test its accessibility features, and some non-debian-accessibility people do go through it. A problem I am much more frightened by is the manpower in some core teams. The Debian Installer, grub, glibc, Xorg, gcc, mozilla derivatives, When reading the changelogs of these, we essentially keep seeing the same very few names over and over. And when one core developer leaves, it is very often still the same names which appear again to do the work. It is hard to believe that there are a thousand DDs working on Debian. I fear that Debian does not manage to get people to work on core things. I often hear people saying that they do not even dare thinking about putting their hands inside Xorg, for instance. Xorg is complex, but it seems to me that it tends to be overrated, and a lot of people could actually help there, as well as all the teams mentioned above. And if nobody does it, who will? Raphael: Do you have wishes for Debian Wheezy? Samuel: That is an easy one :) Of course I wish that we manage to release the hurd-i386 port. I also wish that accessibility of gnome3 gets fixed enough to become usable again. The current state is worrying: so much has changed that the transition will be difficult for users already, the current bugs will clearly not help. I also hope to find the time to fix the qt-at-spi bridge, which should (at last!) bring complete KDE accessibility. Raphael: Is there someone in Debian that you admire for their contributions? Samuel: Given the concerns I expressed above, I admire all the people who do spend time on core packages, even when that is really not fun everyday. Just to alphabetically name a few people I have seen so often here and there in the areas I have touched in the last few years: Aur lien Jarno, Bastian Blank, Christian Perrier, Colin Watson, Cyril Brulebois, Frans Pop, J rg Jaspert, Joey Hess, Josselin Mouette, Julien Cristau, Matthias Klose, Mike Hommey, Otavio Salvador, Petr Salinger, Robert Millan, Steve Langasek. Man, so many things that each of them works on! Of course this list is biased towards the parts that I touched, but people working in others core areas also deserve the same admiration.
Thank you to Samuel for the time spent answering my questions. I hope you enjoyed reading his answers as I did. Note that older interviews are indexed on wiki.debian.org/PeopleBehindDebian.

Subscribe to my newsletter to get my monthly summary of the Debian/Ubuntu news and to not miss further interviews. You can also follow along on Identi.ca, Google+, Twitter and Facebook.

3 comments Liked this article? Click here. My blog is Flattr-enabled.

Michal &#268;iha&#345;: Weblate appliance

Thanks to great SUSE Studio I've made available appliance with ready to run Weblate. It's based on openSUSE 12.1, with few packages coming from Python devel repository (where I had to push some package updates) and Weblate package, which is currently available in my home. After booting the appliance, you will get Weblate running as web service (it takes some time on first boot as database setup is done in that time). In case you will use it for more than playing, please remember to change default passwords as described in our documentation. Anyway let's stop talking, you can get the appliance at SUSE Studio Gallery.

Filed under: English Suse Weblate 2 comments Flattr this!

18 April 2012

Wouter Verhelst: Screen scraping sucks

At a customer, I've migrated a number of manually-maintained servers to having them be maintained through puppet not so long ago. Since then, some more machines have been added, and getting them up and running properly was a breeze: do a base install, install puppet, sign the certificate, restart puppet, and then wait and twiddle thumbs while puppet did its magic. Easy as pie. Now, a few months later, we needed to install a number of windows machines for a lab (not my choice), and the person involved asked me to figure out some diskspace so we could start creating images for those. Not a chance. Instead, I suggested looking for a configuration management system, similar to puppet. Since we're using Samba 3 to run the Windows network here, dropping everything in Active Directory was not an option. But a short while later, he came back with the note that puppet, in its 2.7 version, actually does support Windows as a platform for the managed machines. Interesting. The unfortunate bit was that puppet supports creating files and installing software when it is distributed as an MSI file, but not when it's distributed as a .exe file. This is not unexpected; MSI files can be installed noninteractively; but when something is distributed as a .exe file, it means it needs to be installed interactively; and puppet does not have the ability to interact with GUI software. The workaround: use something that does have that ability (in my case, autoit), and use an exec block in puppet to make it call those scripts. In effect, that's a bit like screenscraping. Add a creates stanza to the block, so that the installer isn't started again if the software at hand has already been installed. This 'autoit' thing also comes with a recording utility, allowing one to create an initial script by just doing the installation, and having the tool just record stuff. With that, the machines are installed 99% automated. I say 99%, because there are still some issues: I'll have to think about this some more, I guess. First, it's clear that while puppet does have some Windows functionality, it's not entirely ready yet. And somehow, using autoit to add to Puppet functionality feels like an ugly hack. We'll see what the future brings.

Michal &#268;iha&#345;: Weblate 0.9

Pretty much on schedule, Weblate 0.9 has been released today. Besides dozen of bug fixes, the project has been changed to recommended file layout for Django 1.4. In case you are upgrading you will need to adjust few bits, please check documentation. Full list of changes for 0.9: You can find more information about Weblate on it's website, the code is hosted on Github. If you are curious how it looks, you can try it out on demo server. You can login there with demo account using demo password or register your own user. Weblate is also being used https://l10n.cihar.com/ as official translating service for phpMyAdmin, Gammu, Weblate itself and others.

Filed under: English Weblate 0 comments Flattr this!

Richard Hartmann: Potpourri I

Google rant Seems venting can be a worthwhile once in a while; the content of this post made its way into Google. No promises of any kind were made, but it's good to know that this is getting some exposure within Google :) That was quick. moreutils et al Steve Kemp is right; moreutils is very useful in some situations. And yes, it's a pity that we all have our own scripts without a central repository to host them all. The problem is one of diminishing returns and information overload; if any given collection becomes too large, it becomes tedious to look through it. You may have the Most Awesome Ever solution to any given problem, but unless whoever needs it can find it quickly, it's useless to them. Thorsten Glaser suggested this collection, but it suffers from the same basic problem: Not enough content? You won't find what you need. Too much content? You won't find what you need. Finding the right balance is highly non-trivial. Linux storage Russell Coker shared yet another chapter of his continuing quest for modern, reliable, software-based storage on Linux. The short version is "ZFS is not that good on Linux while btrfs is not ready for prime time, yet." That's, unfortunately, not much of a surprise. fsck.btrfs is still too new and the lack of RAID 5/6 is an absolute show-stopper as far as I am concerned. COW solves the writing speed issues so, hopefully, that old argument can finally be laid to rest. And on top of the "wastng" of more disks for RAID 10, the minimum number of failed disks that can lead to data loss on RAID 10 is two whereas it's three for RAID 6. No-brainer, imo. Anyone who does not agree with Dell's pricing structure should seriously consider looking at SuperMicro, by the way. Cheap(ish), reliable, high disk densities. Password hashes Saku Ytti talks about password hashing and the relative merits of different algorithms. While I agree that bcrypt incorporates a good approach inasmuch it's designed to be slow to compute and can be made slower as needed, I think he focuses on one aspect while disregarding all others. Still, the premise that deterring brute force attacks on known hashes is the only concern is wrong. Avoiding collisions, reasonable certainty that there are no computational shortcuts, irreversibility, pseudo-random output, full use of the output's possible values, and thorough analysis by experts in the field are important concerns, as well. Brute forcing known hashes is hardly the only attack. When brute forcing a service, i.e. against an unknown hash, no matter if the system is remote or local, the computational cost of hashing is mostly irrelevant. Rainbow tables help mitigate computational cost when trying to extract clear text in case the hash is known. And if there are a lot of collisions or an easy way to find them, knowing the clear text password is not needed. Simply use whatever generates the correct output and you're done. Again, I am not saying that bcrypt is a bad idea; it's just that there are more concerns than computational cost alone. Travel If you know your way around Novosibirsk, please contact me. We have almost no idea what to do while there other than visiting the railroad museum; part of the reason why we are stopping there is to have a break after ~50 hours on the train and because Novosibirsk is just an awesome name. Our focus while there will be on seeing interesting industrial or research sites. Given that there are large industrial complexes and formerly secret cold war secret research cities situated around Novosibirsk it would be a pity not to see any of them. We may end up hiring a taxi via the hotel and having that drive us around a bit. Somewhat boring and potentially costly, but a feasible backup. Blogging frequency I have to admit being am a bit worried about spamming the various aggregators which are fed from this blog. Writing this catchall post is an attempt to mitigate this. While I am getting a surprising amount of positive feedback, I would be interested to hear anything negative, if applicable, as well. You know how to reach me.

Richard Hartmann: Woegle is me

Google seems to become more and more annoying. Package download http://dl.google.com/linux/chrome/deb/ is slow. Not just slow, but slow. Any random apt-get update will take ages; just sitting there waiting for Google's servers to send any data. Downloading actual packages is slow, as well. Ironically, Google's PageRank will punish sites for loading slowly; it's a pity they don't use their considerable server & bandwidth capacities to fix slowness they are causing, themselves. Chrome Copy and paste is a central part of what I use a mouse for. X has had two copy buffers for as long as I can remember, one for mouse selection, pasting with middle mouse button and one for CTRL-c/CTRL-v. Chrome merges the two. That's bad enough in and as of itself, but every time Chrome gets focus, it will clobber anything you may have in your copy buffers at that time with anything that's selected. No matter if you selected it via mouse, via keyboard, a context switch autoselected something. Selection goes into buffer. Every time. Every. Single. Time. To add insult to injury, this is dependent on which tab is active. And if you happen to search on the site (CTRL-f), it will always use what's in the search bar to clobber buffers, no matter if anything on the actual website has been selected. I can't find the bug report about this at the moment, but Google's stance is that this is a feature and introducing an option for traditional copy & paste handling is not desirable. Google+ I get that they feel a need to combat Facebook, but still, pushing Google+ on you is just annoying. At least the Android application has had a permission change on ICS so it can not auto-update. It's the little things ;) WWW Unified branding, the need to support touch-based devices in their UI, etc. Still, GMail's new interface sucks and the old one will be going away for good. And while making some UI elements larger or displaying them unconditionally makes sense for hand-held portrait displays, this is highly annoying on wide-screen landscape displays. 1366x768 may have overtaken 1024x768, but 768 is a constant here and still not a lot. As an aside, hopefully the Apple Effect and the iPad 3 will break the age-long stalemate with regards to screen resolution. More is better, here. Android Bloatware Using stock Android means you won't get Facebook and other useless apps pre-installed. Yet, uninstalling stock applications, like Google+, is impossible. Rights management It's nice that I get to see what kind of access an application would like to have. It's not nice that I can not choose what access I am willing to grant any given application. I can make a binary decision, install or not install, but I can't refuse random access rights to applications. There are custom versions of Android out there which allow you to do this and many applications seem to cope with being unable to do some things. This should be a standard feature. Access management The concept of "access to USB storage" meaning "whatver your SD card or, in the Galaxy Nexus' case, just a specific directory" is also broken. There is a middle ground between "this application needs access to a large chunk of storage" and "this application needs complete access to said large chunk". Just assign the application a specific directory to write into and read from and done's done. Multi-user I can not hand anyone my phone to play a game or surf the Internet without giving them the ability to look through all my email, contacts, calendar, you name it. While I only give my phone to people I trust completely, this still sucks. How hard can it be to create a minimal guest mode which allows people to access a few pre-selected applications with a custom setting of if they are allowed to use cellular data and/or WiFi? Data access Authorized Access Ah, the big one.... Keep in mind that I am using Google's latest and greatest, the Samsung Galaxy Nexus GSM. It's as cutting-edge as you can get. Yes, having one continuous storage device is nice. But MTP support on Linux is abysmal and you are forced to access your data by means of MTP or PTP. gphoto2, gwenview, and gthumb are all unable to import any photos via PTP; no program I tried can transfer anything via MTP. gphoto2 will transfer the background images which APOD (highly recommended, by the way; there's also a donation application for this) stores on my phone. That's it. So, unless I send email to myself, use WiFi-based hacks, or root my phone, I can not access my data. On the strongest mobile platform in the world. Using the most powerful and versatile OS with up-to-date packages. In 2012. Yay. Unauthorized Access Not being able to access my data is a Bad Thing. Even worse is when others can access my data. Contrary to older Android versions, someone decided that it would be a good idea to allow MTP or PTP, only. As in "you can not disable MTP and PTP. One of them has the be activated." This is awesome when you want to charge your phone at an airport or at an acquaintance's possibly malware-ridden Windows machine. Everyone and their bot-herder can potentially access my data while I can not. Usability And while MTP/PTP is an either/or decision, they are using check-boxes, not radio buttons. There's a decade or more of UI experience about check-box versus radio button, so why not use it? I know of at least one owner of a Galaxy Nexus who was not even aware that he couldn't turn off MTP (the default) as the UI pretends otherwise. Opaqueness And good luck trying to contact anybody about this. Having filed a few bugs against Google stuff in the past, I simply gave up on it. Back when Gmail's mailing list filtering and labelling system was somewhat broken, I spent months hunting down people who knew people who knew someone who was able to actually do something about it.

17 April 2012

Andrew Cater: Raspberry Pi ARM credit card computer - update

Still waiting for mine - though I did buy a case for when it comes. News from www.raspberrypi.org - the prototype submitted for EMC testing has apparently passed, though the paperwork has to be validated (blog posting).
It has passed CE marking, FCC part 15 marking, Canadian certification and the Australian C-Tick scheme. There is also an updated trademark policy at new trademark rules ( http://www.raspberrypi.org/trademark-rules ) and a video over at the Farnell/Element14 website from Eben Upton detailing how to set up the Raspberry Pi, shots of booting, explanations of how to use an editor, compile a first Python program and how to build the graphics demos provided. ( http://www.element14.com/community/docs/DOC-44459 )

Next.

Previous.