Search Results: "xam"

13 April 2009

Simon McVittie: DSpam and how not to do it

At some point I might document my current e-mail setup, but for now, here's the bit that caused plenty of frustration on Friday. Many howtos for postfix and dspam will tell you that if you embed user IDs in the signature with PgSQLUIDInSignature on (or the MySQL equivalent, you can do something like this for retraining, and set it up to receive spam@example.com:
# master.cf
dspamretrain unix -     n       n       -       10      pipe
  flags=R user=dspam argv=/usr/bin/dspam --user dspam
      --class=$ nexthop  --source=error
# mailbox_transport map
spam    dspamretrain:spam
notspam dspamretrain:innocent
in which --user dspam names an arbitrary user (dspam will extract the uid from the signature and switch from "dspam" to the correct user, but the command line argument is still required, for no particular reason). I said it named an arbitrary user, but actually that's a lie. The things to be careful of are: Having failed at both of those, my retrain address wasn't working, and sadness ensued.

Wouter Verhelst: Ugly fonts

This week seems like ugly fonts week. First, KDE4 was uploaded to unstable. Now I'm not a KDE user, but I do cherry-pick a few KDE applications which I find useful or interesting, and use them in my IceWM environment; these are mainly korganizer (with konsolekalendar in my .bashrc), kdebluetooth, and digikam. First thing I noticed is that something went horribly bad with the fonts -- see this screenshot for an example of what the problem is; the korganizer window in the background has ugly artifacts, while the kbluetooth menu in the foreground is still a KDE3 window which does what I was expecting. Second, someone thought it good to add console-setup as a dependency of Xorg 7.4. Now by itself, there's nothing wrong with that, except for the fact that console-setup by default changes the console font to something else. I had, in fact, tried out this setup a while back, but eventually (after a few weeks), decided that I did not like this font, because it's a) ugly and b) unreadable on a high-resolution 12" display. So I changed /etc/default/console-setup to get the VGA font back, ran the console-setup initscript, and all was well. Until my laptop was resumed from suspend-to-RAM. Apparently the console font is changed at that point in time, too, with some other configuration, and I'm not sure how to fix it. Oh well.

Ingo Juergensmann: Debian/m68k's future

Stephen Marenka wrote to the debian-68k list lately:

So you may have noticed the following in your buildd logs for python-
depending packages.

dpkg: regarding .../python-docutils_0.5-3_all.deb containing python-docutils:
package uses Breaks; not supported in this dpkg
dpkg: error processing /srv/chroot/sid/var/cache/apt/archives/python-docutils_0.
+5-3_all.deb (--unpack):
unsupported dependency problem - not installing python-docutils

That's right, our old etch-m68k dpkg doesn't support Breaks.

The options I can think of are.

Option 1: backport dpkg to etch-m68k
Yuck. etch-m68k is old and likely insecure. Who knows what
back-porting dpkg would look like.

Option 2: lenny-lite
Build lenny with base, build-essential, and buildd-required
packages. I can probably do this one myself if there's
interest. I'll probably include anything required for d-i
too.

Option 3: lenny
Go ahead and try to do a lenny release. I think we have
nearly all the binary packages, but how to shove them into
an archive intelligently? I'm willing to help if anyone
knows how and can direct or is otherwise willing to lead.

Option 4: throw in the towel
Say it's time to retire m68k on debian. We have an ancient
glibc with borked threads. gcc-4.3 is fairly broken. A
number of packages need some bugs fixed, others need some
porting. Not so many helpers these days. Funny thing is with
aranym we have plenty of horsepower (although we need to fix
the fpu emulation) and with d-ports our buildds won't get
locked out of wanna-build. Kernel's probably in the best
shape it's been in a long time.

peace,

stephen

--
Stephen R. Marenka If life's not fun, you're not doing it right!


Yes, it's true... the Vancouver proposal seems to be a true success in killing the m68k port. Stephens mail is just a written example of what I've been thinking about for several weeks as well: does it still make sense to run my Amigas after being kicked out by Debian?

Luckily there were some new users appearing on the list asking for how to install Debian on their m68k machines, which shows that there's still interest in the port and need for a Debian on m68k. This makes me more confident in still supporting the m68k port for me by running several buildds 24/7. But as Stephens mail shows the m68k port is in trouble. It would be nice if there were more porters helping in actually porting software or fixing bugs. There are some open issues like NPTL support and such. See the list archive or the Debian wiki for more information.

Despite all the bad luck with being kicked off by Debian, the port did made some progress in the past: we're not bound by real m68k hardware anymore. Thanks to Aranym every interested developer can now contribute by running the emulator on his/her fast i386 machine. There are crosscompilers available as well.

But there's still work to do. For example to Coldfire inclusion seems to got stuck somehow. And I don't think that it makes much sense to try to build all of Debian >>6000 packages for m68k, but to concentrate on maybe below 2000 packages. So if you want to help to m68k port staying alive, please join us at debian-68k mailing list! :-)

12 April 2009

Biella Coleman: Memefactory, the video

I have found myself, at least on a few occasions, talking to a person whose relationship to the Internets is much thinner than my own, trying to explain the nature of certain Internet memes. I find this a pretty tough task to pull off as I tend to make memes sound really infantile (and perhaps that is just what they are). To explain this world to the uninitiated, I either: 1) very quickly give up and move onto some other less obscure 2) go into semi-professorial lecture mode and give a mini-low down on memes, some of the early examples, a small theory of self-referential irony, 4chan, rickrolls, encyclopedia dramatic etc etc and then show a bunch of memes as really you can t do it justice without the audio visul component. Now, I can just point people to the Meme Factory to three youngish guys from Brooklyn who put together a **fantastic show**** a few weeks ago on, yes, Internet Memes. It was a dazzling ride into the (sometimes very obnoxious) territory that is memeology, addressing and displaying both the happy-cheery-cute side of memes as well as its darker side. The video they have on their site documents their presentation and the word is out that they will soon craft something more like a stand-alone video-essay about Internet memes. As we wait for this next step in their project, this video is an amusing watch (though the interesting stuff starts about 3 minutes in).

Biella Coleman: Memefactory, the video

I have found myself, at least on a few occasions, talking to a person whose relationship to the Internets is much thinner than my own, trying to explain the nature of certain Internet memes. I find this a pretty tough task to pull off as I tend to make memes sound really infantile (and perhaps that is just what they are). To explain this world to the uninitiated, I either: 1) very quickly give up and move onto some other less obscure 2) go into semi-professorial lecture mode and give a mini-low down on memes, some of the early examples, a small theory of self-referential irony, 4chan, rickrolls, encyclopedia dramatic etc etc and then show a bunch of memes as really you can t do it justice without the audio visul component. Now, I can just point people to the Meme Factory to three youngish guys from Brooklyn who put together a **fantastic show**** a few weeks ago on, yes, Internet Memes. It was a dazzling ride into the (sometimes very obnoxious) territory that is memeology, addressing and displaying both the happy-cheery-cute side of memes as well as its darker side. The video they have on their site documents their presentation and the word is out that they will soon craft something more like a stand-alone video-essay about Internet memes. As we wait for this next step in their project, this video is an amusing watch (though the interesting stuff starts about 3 minutes in).

Sean Finney: a productive weekend for debian stuff

(note that i've just tried enabling the comments feature of ikiwiki, so feel free to use it :) ) (update: okay so i apparently failed to enable comments earlier... but it should be working now :) ) compiz(-fusion) 0.8.2 uploaded to unstable for all you lovers of desktop bling, the latest stable release of compiz-fusion has been uploaded to unstable. new features of note: new one-off script for building compiz packages the biggest problem with trying to maintain compiz packages is that they're for some reason distributed as almost a dozen different source projects upstream, but extremely interdependant wrt their API. therefore updating the packages to a new upstream version is a Big Pain. i've numbed that pain a bit with a new helper script, which should amongst other things make it easier to manage backports to lenny, which i've already seen people requesting. compiz 0.8.2 lenny packages available for testing ..which brings us to our next topic. before i upload them to somewhere a little more official, i figure i could put a call out to teh lazywebs to do some QA work and make sure that it doesn't totally explode on your system (unless you're using the explode animation plugin, in which case it's functioning properly) sources.list entry to try it out on an amd64 lenny system:
deb http://people.debian.org/~seanius/compiz/lenny-backports/amd64 ./

sources.list entry to try it out on an i386 lenny system:
deb http://people.debian.org/~seanius/compiz/lenny-backports/i386 ./

and then apt-get install compiz compiz-fusion-plugins-main (etc) so give it a try and let me know how it goes! pkg-php moving to git with some initial legwork from Mark Hershberger we've migrated to a git repository for the php packaging vcs. due to the long and convoluted history of our svn repository, we decided it wasn't worth the effort of trying to get every single svn commit mapped into the new repo. as a compromise to having to start from scratch, we used the existing branches/tags on top of a series of upstream tarball imports to get an accurate representation of the release history. new git<->bts integration hook for debian packaging i've been dabbling with a new hook to make for more useful integration from a git-buildpackage oriented workflow. in this workflow the changelog is often the last thing prepared, possibly days or even weeks after a fix has been committed for a bug. therefore the standard tagpending and typical changelog-scanning hooks aren't incredibly useful. instead, this hook scans for "Closes:" meta-info in the commits, similar to how "git dch" does, and then sends a notification and/or control commands to the bts. here's an example. note that it also mentions the branch that recieved the fix in the notification, so it's easier to see which branches have a fix at a quick glance. how to use this for your own git repo:
REPO_PATH=/path/to/your/repo.git
HOOK_REPO_PATH=/somewhere/you/want/to/put/it
git clone git://git.debian.org/users/seanius/vcs-hooks/git-hooks.git $HOOK_REPO_PATH
ln -sf $HOOK_REPO_PATH/git-post-receive-url-notifications.py $REPO_PATH/hooks/post-receive

there's a number of configurable options (take a look at the top of the file for some fairly verbose comments), but it should work with some fairly reasonable defaults out of the box. it can also be configured to do the more traditional changelog-scanning, but i'm finding it to be a better workflow to avoid combining changelog entries with the actual fixes (makes them harder to cherry-pick later), and a notification with a link to the changelog entry really isn't that useful beyond what "bts tag nnn pending" can already do. plus i don't like the typical duplication involved in manually managing the changelog. i find it better to generate the changelog via git-dch and automatically get all the "closes:" tags, and then just do a bit of editorial touchups before preparing/releasing the upload. so give it a try if you like, feel free to send feedback/fixes/etc. for example i think the utf-8 support might still be a bit dodgy, as well as possibly the automatic gitweb url detection and changelog scanning.

Manoj Srivastava: Manoj: Sample kernel symlink postinst hook script

With the new kernel-package hitting Sid today, and the fact that it no longer does symlink handling by default, I thought it was time that we had an example script that shows how to do that. This is a fairly full featured script, feel free to cull down to use just what you want. I ll post a couple of ther scripts, if there is interest in this. BTW, this script does far more than the old kernel-package postisnt script ever did. Have fun.
    1  #!/bin/sh -
    2  #                               -*- Mode: Sh -*- 
    3  # 
    4  # This is an example of a script that can be run as a postinst hook,
    5  # and manages the symbolic links in a manner similar to the kernel
    6  # image default behaviour, except that the latest two versions (as
    7  # determined by ls -lct) are kept. You can modify this script 
    8  # 
    9  # Copyright 2003, 2004, 2005, 2006, 2007, 2008, 2009 Manoj Srivastava
   10  # Copyright 2009 Darren Salt
   11  
   12  set -e
   13  
   14  # The dir where symlinks are managed
   15  SYMLINKDIR=/
   16  
   17  if [ $# -ne 2 ]; then
   18      echo Usage: $0 version location
   19      exit 2
   20  fi
   21  
   22  version="$1"
   23  vmlinuz_location="$2"
   24  vmlinuz_dir="$(dirname "$2")"
   25  
   26  cd $SYMLINKDIR   exit 1
   27  
   28  if [ -n "$DEB_MAINT_PARAMS" ]; then
   29      eval set -- "$DEB_MAINT_PARAMS"
   30  fi
   31  
   32  if [ -z "$1" ]   [ "$1" != "configure" ]; then
   33      exit 0;
   34  fi
   35  
   36  rm -f vmlinuz vmlinuz.old vmlinuz-rd vmlinuz-rd.old initrd.img initrd.img.old 
   37  
   38  # Create a temporary file safely
   39  if [ -x /bin/tempfile ]; then
   40      outfile=$(tempfile -p outp -m 0600);
   41  else
   42      set -e
   43      mkdir /tmp/kernel-image-$version-$$
   44      outfile=/tmp/kernel-image-$version-$$/output
   45  fi
   46  
   47  (cd "$vmlinuz_dir" && ls -ct vmlinuz-*) > $outfile
   48  
   49  STD="$(head -n 1 $outfile               sed 's/vmlinuz-//')" 
   50  OLD="$(head -n 2 $outfile   tail -n 1   sed 's/vmlinuz-//')" 
   51  
   52  if [ "X$STD" = "X" ]; then
   53      exit 0;
   54  fi
   55  
   56  # If you want version-specific links, here's how to start
   57  STD24="$(grep vmlinuz-2.4 $outfile   head -n 1   sed 's/vmlinuz-//')"   true
   58  OLD24="$(grep vmlinuz-2.4 $outfile   head -n 1   tail -n 1   sed 's/vmlinuz-//')"   true
   59  
   60  STD25="$(grep vmlinuz-2.5 $outfile   head -n 1   sed 's/vmlinuz-//')"   true
   61  OLD25="$(grep vmlinuz-2.5 $outfile   head -n 1   tail -n 1   sed 's/vmlinuz-//')"   true
   62  
   63  echo Booting $STD, old is $OLD
   64  
   65  if [ -f "$vmlinuz_dir/"initrd.img-$STD ] ; then 
   66     ln -s "$vmlinuz_dir/"initrd.img-$STD initrd.img
   67     ln -s "$vmlinuz_dir/"vmlinuz-$STD vmlinuz-rd
   68  else
   69     ln -s "$vmlinuz_dir/"vmlinuz-$STD vmlinuz
   70  fi
   71  
   72  if [ "X$OLD" != "X" ]; then
   73      if [ -f "$vmlinuz_dir/"initrd.img-$OLD ] ; then
   74      ln -s "$vmlinuz_dir/"initrd.img-$OLD initrd.img.old
   75      ln -s "$vmlinuz_dir/"vmlinuz-$OLD vmlinuz-rd.old
   76      else
   77      ln -s "$vmlinuz_dir/"vmlinuz-$OLD vmlinuz.old
   78      fi
   79  fi
   80  
   81  # if [ "X$STD24" != "X" ]; then
   82  #     if [ -f "$vmlinuz_dir/"initrd.img-$STD24 ] ; then 
   83  #     ln -s "$vmlinuz_dir/"initrd.img-$STD24 initrd24.img
   84  #     ln -s "$vmlinuz_dir/"vmlinuz-$STD24 vmlinuz24-rd
   85  #     else
   86  #     ln -s "$vmlinuz_dir/"vmlinuz-$STD24 vmlinuz24
   87  #     fi
   88  # fi
   89  # if [ "X$OLD24" != "X" ]; then
   90  #     if [ -f "$vmlinuz_dir/"initrd.img-$OLD24 ] ; then
   91  #     ln -s "$vmlinuz_dir/"initrd.img-$OLD24 initrd24.img.old
   92  #     ln -s "$vmlinuz_dir/"vmlinuz-$OLD vmlinuz24-rd.old
   93  #     else
   94  #     ln -s "$vmlinuz_dir/"vmlinuz-$OLD vmlinuz24.old
   95  #     fi
   96  # fi
   97  
   98  # Run boot loaders here.
   99  #lilo
  100  
  101  rm -f $outfile 
  102  if [ -d /tmp/kernel-image-$version-$$ ]; then
  103      rmdir /tmp/kernel-image-$version-$$
  104  fi
  105  
  106  exit 0

11 April 2009

Benjamin Mako Hill: American Gothic and the Free Culture Imperative

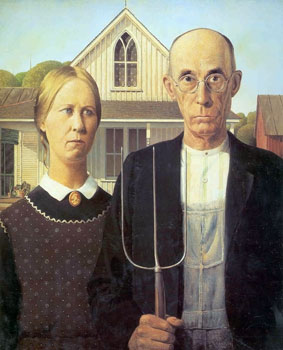
About a year ago, I read American Gothic by Steven Biel and the book has left a surprising lasting impression on me. The book describes the background, history, and life of "American Gothic: America's most famous painting" by Grant Wood. Even if you don't recognize the name "American Gothic", you are likely to recognize the picture or the scene. The book is a serious and -- as far as I can tell -- reasonably comprehensive treatment of the subject that is interesting, insightful at points, and a breeze to read. Thumbnail of the American Gothic Painting Of course, the book is not actually about the painting that hangs in the Art Institute of Chicago -- although it will certainly teach you more than you probably ever wanted to know about that painting, its subjects, its settings, etc. The book is really the story of how that paining has been received, understood, and used. Nearly half of the book focuses on examples of people who have remixed, reworked, reimagined, and reproduced the painting in myriad forms, formats, settings, and ways. The book contains scores of photographs of celebrities posing in American Gothic style settings, dozens of political cartoons based on the paintings, images of talk shows, magazine covers, Broadway plays, product advertisements, toys, gifts, kitch, and more, done up in recognizeable representations of the basic American Gothic form. There is a very incomplete of references to American Gothic in popular culture at Wikipedia that can give a tiny taste of what is out there. The last chapter of the book is devoted to these "parodies" and there's some brief talk of issues around copyright and control of the image. Wood's sister Nan was the owner of the copyright for much of the second half of the twentieth century and is also the woman in the painting. She famously charged several makers of more lurid take-offs with defamation and successfully blocked a number of remixes. In 1988, Nan transferred ownership to the Visual Artists and Galleries Association (VAGA) which will hold the copyright until 2025. VAGA also claims "rights of publicity" in Nan's image which will last until 2060. VAGA takes a very expansive view of its copyright claims and argues that it has both veto power and royalty rights to any recognizably similar work. For example, VAGA does not want the American Gothic image used in alcohol advertisements and has successfully had such ads pulled. Biel's book contains no reference to the amount of money made from licensing the work but one can only conclude that it must be massive. VAGA blocked a plan by Iowa to use the picture on the back of the Iowa state quarter due to licensing disagreements; instead Iowa used a different Wood painting that was clearly in the public domain. What struck me most about Biel's book is related to just how deeply ingrained in American culture the American Gothic image has become. The book cites simple surveys that show that almost every American recognizes the painting (although only a small fraction know the painting's name or who painted it). The thousands of parodies that the book documents are testament to the fact that the painting has become a way of representing something essential about American culture and its values. But in a strange way, the painting's popularity and incessant reuse has also made it part of the culture that it so effectively captured. We can think of culture as a set of shared values and references that help us related to each other and to communicate. Just like idioms in language, culture helps us communicate more effectively, certainly, but also lets us communicate messages that would not be communicable otherwise. When Out Magazine, Coors, or any of several dozen others replace the figures in American Gothic with a gay or lesbian couple, they are succinctly sending a message about homosexual relationships and American traditional values that could not be made any other way. In this way, American Gothic -- both the painting and Biel's book -- represent a strong argument for free culture. If American Society has infused American Gothic with so much value, how can it be fair to let one person or organization own it? Are they not owning an essential mode through which a society can relate, experience, and communicate? I can't help but conclude that it shouldn't matter if VAGA does not like alcohol, advertisements, homosexuality, or wants to make a some money every time someone makes a cartoon parody. These are trivial concerns next to the importance of our society's need to communicate about these issues. If doing so requires the use of a shared cultural reference in VAGA's painting, I find it hard to justify VAGA's position of control. We need to be able to reproduce and reimagine American Gothic because it has become part of us. It's a striking example of the way that art becomes culture and the reason that truly free culture is the only appropriate response. We can't afford to let our experience of the world and each other -- to let ourselves at a very fundamental level -- be owned and controlled.
Julian Andres Klode: Python 3.1 and python-apt


So, I have started to port python-apt to Python 3. Most things work already, but there is one single problem. I can not access the attributes of the objects, only their methods. In Python 2.5, everything works perfectly. In Python 3.1, the same code produces an error. An example is apt_pkg.GetCache().Packages. I defined the slots tp_getattro and tp_methods. In Python 3.1, tp_getattro seems to be ignored. If you want to help,
http://bzr.debian.org/loggerhead/users/jak/python-apt/py3k/changes for browsing the branch and http://bzr.debian.org/users/jak/python-apt/py3k/ for branching it. This branch contains the current state and allows you to build a python-apt package shipping with Python 3.1 modules and extensions. But as I wrote above, not everything works yet. But its far enough for about 5 hours of work. Update 2009-04-12 00:17 CEST: I just fixed a bunch of problems, including the one listed above. Most of python-apt should work now, including the apt package. Posted in Debian, Python

Mike Hommey: Following up on SSH through jump hosts

I got interesting comments on my previous post about SSH through jump hosts, that made me think a bit. The first one of them suggested to use a syntax that unfortunately doesn t work on anything other than zsh, but had the nice idea to add a login for each jump server. Sadly, this only works when there is only one hop, for reasons similar to those we will explore below. The second one suggested / would not be so good a separator, because it would fail in svn+ssh urls and such, which is a good point that I didn t think of only by lack of such use case. The simplicity of the resulting configuration was nice enough. This decided me to take a shot at implementing something that would allow adding both login and port number for each jump server. The first implementation detail to set was which characters to use for login, port number and hop separators. I chose respectively % (@ is unfortunately impossible to use because ssh would take it, leaving out any hop before the character), : (pretty standard) and + (not allowed in DNS, and not too illogical as such a separator, I thought). The result can look like dark magic when you are not savvy with sed and regular expressions:
Host *+*
ProxyCommand ssh $(echo %h sed 's/+[^+]*$//;/+/! s/%%/@/;s/:/ -p / ;s/\([^+%%]*\)%%\([^+]*\)$/\2 -l \1/ ) PATH=.:\$PATH nc -w1 $(echo %h sed s/^.*+//;/:/!s/$/ %p/;s/:/ / )
The syntax you can use to connect through jump hosts is the following:
ssh login1%host1:port1+login2%host2:port2+host3:port3 -l login3
We ll see further down why we can t put a login for the final destination host. Or if you want to skip the boring implementation details, you can also skip to the end, where a slightly more compact version lies: while writing this post, I got some optimization ideas. Let me try to split the sed syntax to make it a little more understandable:
s/+[^+]*$//; # Remove all characters starting from the last + in the string (i.e. keep the n - 1 first hops)
/+/! # If the string doesn t contain a + after the previous command (i.e. there is only one hop remaining), do the following, otherwise, skip until the closing curly brace
s/%%/@/; # Replace % with @ (% is doubled because of the ProxyCommand)
s/:/ -p / # Replace : with -p . Combined with the previous command, we rewrite login%host:port as login@host -p port
;
s/\([^+%%]*\)%%\([^+]*\)$/\2 -l \1/ # Rewrite hop1+hop2+login%lasthop as hop1+hop2+lasthop -l login
The second sed goes like this:
s/^.*+//; # Remove everything up to the last occurrence of + in the string (i.e. only keep the last hop)
/:/! # If there is no : in the string, do the following, otherwise, skip the next statement
s/$/ %p/;
# Add %p at the end of the line
s/:/ / # Replace : with . These last three instructions prepare a host port combination for use with nc.
Let s see what the ProxyCommand looks like for some examples, skipping PATH setting and nc option for better readability:
host1+host2
ssh host1 nc host2 %p
login1%host1+host2:port2
ssh login1@host1 nc host2 port2
login1%host1:port1+host2:port2
ssh login1@host1 -p port1 nc host2 port2
Now, maybe you start to see why we can t put a login on the last hop: not only does it make no sense for nc, but also the main ssh process that runs the ProxyCommand and will actually talk to the remote host won t have any knowledge of it. From the above examples, it also appears obvious why we replace login%host:port with login@host -p port : so that the ssh command in the ProxyCommand gets the proper arguments for login and port. Note we could also replace with host -p port -l login for the same effect. With even more hops, this is what happens:
host1+host2+host3
ssh host1+host2 nc host3 %p
login1%host1:port1+host2:port2+host3
ssh login1%host1:port1+host2:port2 nc host3 %p
Each of these ProxyCommands will trigger another ProxyCommand quite looking like our first few examples. In the first hops, if we d just replace all % with @ , in cases where logins are given everywhere, we d end up with a ProxyCommand like the following:
ssh login%host1+login%host2 nc host3 %p
As we saw above, we can t use a login on the last hop, which means this ProxyCommand wouldn t work as expected and is why we have to rewrite login1%host1+login2%hop2 as login%host1+host2 -l login2 with the last instruction in the first sed. In the end, this is what happens:
login1%host1+login2%host2+host3
ssh login1%host1+host2 -l login2 nc host3 %p
login1%host1:port1+login2%host2:port2+host3:port3
ssh login1%host1:port1+host2:port2 -l login2 nc host3 %p
In this last example, you see the :port2 part is not changed into -p port2 . Actually, it would still work with the latter form : the ProxyCommand ssh login1%host1:port1+host2 -p port2 -l login2 would itself have ssh login1@host1 -p port1 nc host2 %p as ProxyCommand, in which %p would be replaced by port2, given as argument to -p. Based on this and with further small optimizations, we can slightly shorten our ProxyCommand to the following :
Host *+*
ProxyCommand ssh $(echo %h sed 's/+[^+]*$//;s/\([^+%%]*\)%%\([^+]*\)$/\2 -l \1/;s/:/ -p / ) PATH=.:\$PATH nc -w1 $(echo %h sed s/^.*+//;/:/!s/$/ %p/;s/:/ / )
sed instructions decryption is left as an exercise to the reader ;). Update : modified the shortened version to fix the issue spotted in the comments.

Chris Lamb: Installing FogBugz the Debian way

Yeah, proprietary software is bad, but let's at least install it the Debian way. The following walkthrough assumes Debian lenny.
#!/bin/sh
set -e
for PEAR_PKG in Auth_SASL HTTP_Client Mail_Mime XML_Tree
do
        PKG_TEMP=$(mktemp -d)
        cd $ PKG_TEMP 
        pear download $ PEAR_PKG 
        dh-make-pear $ PEAR_PKG *.tgz
        cd $(find -mindepth 1 -type d   head -n1)
        dpkg-buildpackage -uc -us -rfakeroot
        sudo dpkg -i ../*.deb
        rm -rf $ PKG_TEMP 
done
$ sudo ./install.sh
/***************************************\
*            FogBugz 6 Setup
\***************************************/
--    Checking for required tools
 +      found mono 1.9.1
[..]

10 April 2009

Jurij Smakov: Series of unfortunate events

While I did not think I would continue hacking on VoiDroid after achieving a semi-broken proof-of-concept implementation, it seems that I can t get out of it easily :-). I spent today trying to implement a solution which would allow the native C++ code to call into Java - for example, if we have a call in progress, and want to update the call status displayed to the user when it changes. The JNI library has some native callbacks which are getting called on call state changes, but getting the information to Java turned out to be a quite an experience, which, I thought, would be amusing to document, and, hopefully, save someone some quality bang-head-on-desk time. 1. Some of the threads calling native callbacks were initiated in Java (and thus known to JVM), and some where not, they were started in the native code. As JVM did not know anything about them, JNI calls would fail without too much explanation. Eventually I figured that out, and started attaching them as appropriate (JNI provides facilities for that). 2. Even after attaching, I could not resolve references to my classes from the native code, until I found a mysterious line in JNI docs: When a thread is attached to the VM, the context class loader is the bootstrap loader.. Basically, it means that when you attach a native thread, it is only capable of resolving built-in Java classes. 3. I later found a reference to a technique, suggesting to cache a good classloader from a Java-initiated thread, and later set the classloader for the attached thread to it. I implemented that, only to find out that Android s JVM is not your regular JVM, so things are slightly different here, and this technique does not work. 4. Luckily, there is an incredibly useful post describing the problem, and suggesting a workaround: caching an instance of needed class globally in native code, after calling NewGlobalRef on it, to avoid garbage collection on exit from a native function. I did that, however I only had access to the class, and Android JNI only supports calling NewGlobalRef on an object, so I had to create a dummy object in the native code (JNI_OnLoad() function, actually) and cache that. 5. That finally enabled me to call into Java from native, attached threads (w00t!). Unfortunately, you are not allowed to modify the UI (exactly what I wanted to do from my Java callback!) from a non-UI thread, which brought me right back to the drawing board. 6. As callbacks initiated from native code would not work for this reason, it was suggested to me to use a classic producer-consumer mechanism, getting Java call into the native library block until new information gets delivered by a native thread. Easily done with some pthread mutexes, and the goal is close, right? 7. Wrong! Now the problem was that if I started a UI Java thread, which would call the native function in a loop to retrieve the data (it would not actually spin, as the native function blocks until new data is available), then it would be declared not responding by the UI framework in a few seconds. I could start a non-UI thread for that, but you guessed it a non-UI thread is not allowed to update UI! Instead of resolving the problem we just shifted it into the Java land. 8. While I was simply thinking about stuffing the result into a class variable and passing it to the UI thread this way, this tutorial, showing how to display a progress indicator while doing some heavy calculations in the background, provided a more elegant idea. One can use Android s android.os.Handler class to pass messages (with arbitrary payload) between threads. That was the last piece of the puzzle, which allowed me to finally achieve a working implementation (some 10 hours or so later :-).

Joey Hess: Racing the Beam

I devoured Racing the Beam last night. It does a great job at getting inside the Atari 3600 platform and explaining how it affected the early games that ran on it. Full of great examples, like Yars Revenge displaying its own code onscreen as a visual effect, to avoid needing a random number generator. Teaches how to analyse screenshots of 3600 games and see how the crazily limited hardware was coaxed into drawing them. Highly recommended, just wish it were twice as long. (I also enjoyed that the book itself is a nice recursive hack. Its (fairly cheap) printing process didn't allow reproducing the detailed color photos of the games needed for reference. So they printed them on the inside of the dust jacket instead.)
While I just missed out on the heyday of the Atari 3600, I was writing similar games on my 130XE a bit later, mostly limited by having to use slow BASIC. This was probably the first video game I ever wrote, judging by its filename ("VIDIO").
You're the green dot, zipping across the screen. Each time it reaches the right side, it wraps back to the left, leaving a wall behind. Crash into the wall and you lose a life.
As I've mentioned before, I still enjoy VIDIO, both its simplicity and gameplay. And the key to its gameplay is that the dot moves fast and the controls are not very precise, making it hard to go thru a given hole in the wall. And the controls are not very precise because of a limitation of the platform. The BASIC program can only sample the joystick position occasionally, and so there's little fine control. So, Racing the Beam has helped me realize that the platform made this game what it is.
BTW, here's the code to VIDIO. (more)

9 April 2009

Manoj Srivastava: Manoj: kernel-package: Add support for kernel image debug package

A new version of kernel-package in Incoming at the time of writing adds support for creating a package which contains the Linux kernel debug image. This means the debugging information for the modules in the kernel image package, and the uncompressed vmlinux image. This builds on suggestions and code from Troy Heber, Theodore Y. Ts o, and Dann Frazier. As support for kexec/kdump support becomes more real, it will be very useful to be able to build kernels that have debugging information available, but not necessarily to install the debugging information on every single client system. The .ko object files are stripped of the debugging information before they are placed in the standard linux-image installation package. However, before that, a copy of the vmlinux and unstripped .ko files are saved in a debuginfo package, and everything except for the debugging information is removed from them using objcopy --keep-only-debug. This means that if someone ends up with a crash dump, they can send it to a support engineer and only the support engineer needs to install the debuginfo package and use the crash utility to debug the crash dump. It s also useful for developers, since the debuginfo information can be stored somewhere outside of /lib for storing its debug information, for example. This is useful for keeping the size of the root partition small, for those who keep / separate from /usr. The locations used are compatible also with SystemTap, which provides free software infrastructure to simplify the gathering of information about the running Linux system. This assists diagnosis of a performance or functional problem. SystemTap eliminates the need for the developer to go through the tedious and disruptive instrument, recompile, install, and reboot sequence that may be otherwise required to collect data. Also, I had to clear out some FUD about kernel-package from the ircbot dpkg on the OFTC Debian IRC channel, since someone had implied that kernel-package was some how obsolete. As can be seen, it is being actively developed, and features are being added apace.

Mike Hommey: SSH through jump hosts

I often need to connect to a server with ssh from another server because I don t have direct access. I even gave a small configuration example to use such jump hosts using ProxyCommands. A while ago, I got fed up to have to add new entries for each host I wanted to join with a jump server, especially when I only need these entries sporadicly, and decided to write a generic configuration. I ended up with this setup:
Host *%*
ProxyCommand ssh $(echo %h cut -d%% -f1) nc -w1 $(echo %h cut -d%% -f2) %p
The trick here is that you can use subshell expansions in a ProxyCommand. So, when I ssh to host1%host2 , the first subshell expansion returns host1 and the second host2 , this setup ends up being the equivalent of :
Host host1%host2
ProxyCommand ssh host1 nc -w1 host2 %p
which is quite similar to the setup from my previous post. Later on, I came up with an even more powerful implementation:
Host *%*
ProxyCommand ssh $(echo %h awk -F%% ' OFS="%%"; NF--; print $0 ') nc $(echo %h awk -F%% ' print $NF ') %p
Here, the first awk splits at the % characters and returns all fields except the last one, and the second awk returns only the last field. As a consequence, sshing to host1%host2%host3%host4 will have the first subshell expansion return host1%host2%host3 and the second host4 . The setup will then be equivalent to:
Host host1%host2%host3%host4
ProxyCommand ssh host1%host2%host3 nc -w1 host4 %p
The ssh in the ProxyCommand will, in turn, trigger the rule again so that the result is that host4 will be contacted from host3, which is contacted from host2 that we contacted from host1. In the meanwhile, I decided % was not that nice a separator, and switched to using /, which also allows for a nicer setup with the same recursive effect:
Host */*
ProxyCommand ssh $(dirname %h) nc -w1 $(basename %h) %p
Finally, since some remote hosts don t have nc installed, I usually copy it in my $HOME on these servers and changed my setup to:
Host */*
ProxyCommand ssh $(dirname %h) PATH=.:\$PATH nc -w1 $(basename %h) %p
The main drawback of this method is that the more jump hosts you use, the more your ssh traffic is encapsulated (recursively) in other ssh traffic. The advantage, though, is that you don t need to forward an agent onto untrusted servers to use ssh key authentication on any of the jump or final servers, nor to forward X11 or tunnel multiple times.

7 April 2009

Steve Kemp: I think you should let this one go

I work with log files a lot. Most of the logfiles I work with are in a standard format of some kind, and most often they are rotated upon a daily basis. (Examples include syslog, qpsmtpd, and Apache logfiles.) I wish there were a general purpose way to say "grep time-range pattern logfile". Right now, for example, I've just deployed some changes upon a cluster of hosts. Now I want to see only messages that refer to a particular area of the codebase only those that occurred after 23:00 - which is when I did the commit/push/pull dance. I've written a quick hack - tgrep (time-grep) - which allows simple before/equal/after/range grepping :
# show matching lines after 23:00PM
tgrep \>23:00:00 -i subject /var/log/qpsmtpd/qpsmtpd.log
# show matching lines in the interval 23:00PM 23:15PM
tgrep 23:00:00-23:15:00 -i -r subject /var/log/qpsmtpd/
If there is a common way of doing this "properly" then I'd love to be educated, failing that take it if it is useful (moreutils?) ObFilm: Chasing Amy

Jon Dowland: zte mf622

I'm currently waiting for my ADSL to be setup and so I've borrowed my mum's "three" 3G mobile broadband USB dongle. The device is a "ZTE MF622" and getting this working in Linux apparently used to be a bit of a nightmare. However, with Debian Lenny and 2.6.26-1-amd64 it is trivial: you plug it in, it appears as a USB mass storage device; wait a little bit and it disappears and comes back as some USB serial devices. You can then chat to /dev/ttyUSB0 (or whatever the first ttyUSB device belonging to the dongle is). There's a working wvdial configuration at http://ubuntuforums.org/archive/index.php/t-665332.html, reproduced here for convenience:
[Dialer Defaults]
Init2 = ATZ
Init3 = ATQ0 V1 E1 S0=0 &C1 &D2 +FCLASS=0
Stupid Mode = 1
Modem Type = Analog Modem
ISDN = 0
Phone = *99#
Modem = /dev/ttyUSB0
Username = user
Dial Command = ATDT
Password = pass
Baud = 460800
IF you don't want to use wvdial there are bare ppp scripts at http://hillj.co.uk/2008/01/31/how-to-get-online-with-three-mobile-uk-and-linux-ubuntu/, although I haven't tested these. Whilst researching this I stumbled across several examples of more extreme ways of getting the initial switchover to work, including http://blog.ufsoft.org/zte-mf622-usb-modem-under-linux#extended which includes a udev snippet that forcefully calls rmmod and modprobe. This will totally fail if you are using usb-storage or usb-serial for anything else, which is probably not the case for the majority of people trying to get this to work at the time they are trying, but there are several examples out there of people complaining that their USB has failed since trying these instructions. We are often accused of having a problem of missing documentation in the free software world. I'm wondering if this is one example of where we have bad, damaging documentation. How can we deal with that? Incidentally, for those whose devices won't automatically switch over to the serial device, there's a program usb-modeswitch (currently in sid) that can do the job for you. There are apparently hacks in the usb-storage Linux kernel module that special-case the switchover for some Huawei devices. I couldn't find anything in there for the ZTE device.

Mike Hommey: How not to provide robust clustered storage with Linux and GFS

(The title is a bit strong, on purpose) LWN links to an article describing how to provide robust clustered storage with Linux and GFS. While explaining how to setup GFS can be nice, the incentive made me jump. The author writes:
Load balancing is difficult; often we need to share file systems via NFS or other mechanisms to provide a central location for the data. While you may be protected against a Web server node failure, you are still sharing fate with the central storage node. Using GFS, the free clustered file system in Linux, you can create a truly robust cluster that does not depend on other servers. In this article, we show you how to properly configure GFS.
In case you don t know, GFS is not exactly a clustered storage . It is more a shared storage . You have one storage, and several clients accessing it. You have one storage array, compared to the NFS case, where you have one central server for the data. But what is a storage array except a special (and expensive) kind of server ? You don t depend on other servers, but you depend on other servers ? How is that supposed to be different ?
Conceptually, a clustered file system allows multiple operating systems to mount the same file system, and write to it at the same time. There are many clustered file systems available including Sun s Lustre, OCFS from Oracle, and GFS for Linux.
OCFS and GFS are the same class of file systems, but Lustre is definitely out of league and would, actually, provide a truly robust cluster that does not depend on other servers. Lustre is a truly clustered filesystem, that distributes data on several nodes such that losing some nodes don t make you lose access to the data. With the incentive given by the author, and considering he lists Lustre as an example, I would actually have preferred an article about setting up Lustre.

Manoj Srivastava: Manoj: Not your father's kernel-package

A few hours ago, a new version of kernel-package was uploaded to experimental. This is a major change,and I would appreciate it if folks took it out for a spin, kicked the tires, and provide feedback about where this version is lacking. This is only part of the way along in this development cycle. I would like to add a debug-info separation, either in a different directory than / in the image packages, or a separate package by itself. I would also like to create an overlay directory for /usr/share/kernel-package/, so people can inject code or override the defaults for kernel-package easily. I am also willing to make any changes to standardize the handling of hook scripts for kernel packages in Debian.
Table of Contents

./debian/ is ephemeral
make-kpkg removes and re-creates ./debian on every invocation. This started as an exercise to protect ourselves from the upstream builddep functionality, that randomly cleaned out ./debian whether or not it had created it, effectively making it impossible to run dpkg-buildpackage easily (which is ok, if all you care about is the image package) This does make the kernel-package far more nimble; we now offer less surprise to users who did not expect stampts that the kernel-packagge used to not do duplicate work. Now, if you edit a couple of files in the kernel source, and run make-kpkg, the kernel will build as expected. There are no more version mismatch errors, and the kernel version can be modified using localconfig as one desires. With this, kernel-package can routinely be used to build kernels out of the git tree. The con is that we no longer cater to official kernels, or to anyone who expected content in ./debian to persist. At some point, there are plans to implement an overlay directory that will shadow /usr/share/kernel-package/ruleset, but that is not yet implemented. In any case, the kernel team in Debian regards kernel-package to be broken, and have been bad mouthing it and deprecating it for a few years now, so this will not be a loss for them.

Get rid of the facility to patch kernel sources
The patch the kernel facility was adding complexity, and failing to provide the flexibility required for a generic patching facility. It used to be useful at one point, but in the modern parlance, witht he widespread use of distribute version control systems, and various facilities to manage source and patch them, the built in version was clunky. This means the --added-patches option of make-kpkg is gone, the work-around is to prepare the kernel sources before calling make-kpkg.

Remove special case code for official kernels
For the longest tine (well, ever since Herbert Xu too over building kernel images from me), kernel-package has carried specal case code for official images. This has caused some problems, recently, since the need to preserve ./debian has caused no end of problems when the version changed out from under ./debian, or when people wanted to edit a file and expected kernel-package to do a minimal recompile. However, sometime in the Etch release cycle, the kernel team deprecated kernel-package as the means of building official kernels. They have recently started saying they think kernel-package is broken, and have their own recommendation for how to build kernel packages. Therefore, a full release cycle later, we can get rid of the special case rules used for official packages. Also, this allows us to drop ./debian at the drop of a hat, and recreate it with an version that reflects the current state of the kernel sources.

Header package no longer create symbolic links in /usr/src
Instead, ship an example shell script that replicates the old behaviour. This script can then be deployed on the target machines, and could be a part of a locally created kernel configuration package, if one needs to deploy the same behavior across a cluster of machines.

The postinst no longer manipulates symlinks
This is a shift from previous behaviour. Any symbolic link manipulation must now be done with hook scripts in /etc/kernel/*.d directories. Firstly, modern boot loaders scan the boot directory for kernel images, and the user no longer has to code in the path to the symbolic links that the kernel image package used to manipulate. Secondly, hardcoding the behaviour into the postinst made for a very rigid policy; and user wanted more flexibility than that. There is an example shipped with the package that shows a more flexible scheme that kept two symbolic links for version 2.4 kernels, and two symbolic links for 2.6 kernels; it can be easily modified to keep two links for 2.9 kernels and two links for 2.8 kernels, or one of each, or whatever the user wants.

Image postinst no longer runs a boot loader
Please note that this was already the case for grub, one of the more popular boot loaders. Now that we have a mechanism for running arbitrary scripts when the image packages are manipulated, we can stop embedding the boot loader actions in the package itself. This means that lilo, elilo, etc will no longer be run directly by the post install script, and all the code related to detecting the boot loader, managing the configuration, and adding bits about bootloader documentation is all removed from the postinst. This allows the image package to be more flexible, since the end user is no longer restricted to the actions encoded in the image package. This is a fairly large change. It also opens the door for the user to easily use non-standard bootloaders, if they so desire.

The image postinst no longer creates an initramfs
Instead, there are example scripts provided that will perform the task. These scripts will work for official kernel images as well. The initramfs scripts provided work with the make-kpkg images as well as the official images, and are thus better than the script shipped with initramfs-tools themselves, as they offer a super set of functionality. This also demonstrates how the posts install script communicates with the initramfs creation scripts so that no initramfs is generated in case you do not want it.

6 April 2009

David Moreno: Rubx: Twitter's Ruby shell

rubxRubx, also known as Ruby Boobie, is a nice spoiled girlie bot that runs on Twitter. She listens when you talk to her and when you do, it'll better be with Ruby: She will interpret your tweet in Ruby and reply to you with what your code returns. How does it work? You send a message to her:
@rubx "The day I was born it was a " << Time.local(1984, "aug", 8).strftime("%A")
And @rubx will reply:
@damog "The day I was born it was a Wednesday"
Go see more about her (examples, FAQ, etc) on axiombox.com/rubx or on her Twitter profile. As we tested the hack, a bunch of people started interacting with Rubx too, some people calling her Twitter Line Interface Ruby Interpreter! :). See what other people has tried with her here.

Next.

Previous.
