Search Results: "xam"

14 May 2009

Julian Andres Klode: PHP, MySQL, PostgreSQL, etc.


Well, I m currently writing a PHP and SQL application at school, so here are some of my thoughts on the problems I encounter. PHP is crap Many PHP applications are low quality applications. The problem is that PHP makes it hard for developers to write good applications. PHP developers tend to use many global variables, global code, and not many classes or functions. And when writing applications for the web, PHP makes it easy to mix PHP and HTML, in my opinion even too easy. Well-written applications follow some basic rules. First, separate your code into functions and classes, and (2) split your code over multiple files. And there is one rule which is especially important for non-commandline applications: (3) seperate logic and presentation. This means if you write a web application, use a template engine. PHP error and exception handling is also an interesting topic. The problem here lies in the distinction between the both. In my opinion, there should only be one way to handle such stuff: Using exceptions. Exceptions are a very widespread way to program today, and are used in languages like Java and Python for cases where PHP uses errors. The concept of PHP s errors results in code like @do_something or die("blah"); being written in libraries which is a problem as it clearly violates rule (3) I wrote above, because there is no way to catch this die() error. Furthemore, PHP has no clear concept of namespaces in the current stable versions (< 5.3). PHP 5.3 finally gets namespaces, but using a backslash character, which looks really bad and makes everyone think of eithers Windows systems or escape characters. There are even more problems with PHP. From time to time, PHP just crashes with a segmentation fault. MySQL vs. PostgreSQL MySQL seems to have many problems with checking data, which can confuse me. It got better in MySQL 5 with the introduction of the new sql_modes like STRICT_ALL_TABLES and TRADITIONAL. And using storage engines like InnoDB also allows you to take advantage of stuff like foreign keys and transactions. But MySQL is still problematic. For example, in an application I wrote I had multiple entries identified by a numeric id (an INTEGER). One day, I wanted to check whether my error handling was OK and requested an entry with the invalid ID 1X , which resulted in SELECT * from A where id='1X';. Now I expected to get an error or at least no result, but MySQL happily proceeded with the query and returned the entry with the ID 1. I tried the same thing on PostgreSQL and got an error message that 1X is not integer, as I expected it. As another example, when I run the same PHP application using PDO on a MySQL database and a PostgreSQL database, I always get strings from the MySQL database whereas I get integers from PostgreSQL if the columns are integers. Another thing which PostgreSQL does better than MySQL is password encryption. MySQL only provides access to the standard crypt() function and by default only generates DES passwords. It allows other methods to be used (although not all are available everywhere and therefore not documented), but it provides no way to create a salt for them, which makes them not very useful. PostgreSQL in contrast provides less encryption methods but it provides the gen_salt() function which can be used to generate salts for blowfish encryption (gen_salt('bf')). Another problem is that MySQL simply ignores references when they are added to the column definition instead of a separate FOREIGN KEY . Because MySQL gives no errors when a feature like REFERENCES is not supported, developers may think that the feature is supported and write code using this feature just to realize later that what they wrote does not what they want. And you can t write AGPL applications using MySQL client libraries, because MySQL is GPL-2 which is incompatible with the AGPL. You might think that the FOSS License Exception helps here, but this only lists (among others) the GPL-3. Or am I wrong? But PostgreSQL has other problems, at least when it comes to the performance of the information_schema.columns view. This may be related to the fact that PostgreSQL has > 1000 rows whereas MySQL only has 250. And PostgreSQL may be a bit harder to configure. Final words All in all, PHP and MySQL are not the best choices for writing applications. They are to tolerant, and do not treat errors in an acceptable way by aborting the current action. I can get around some problems in PHP by using error handlers which raise exceptions and setting error_reporting to E_ALL, but in fact this should be the default. MySQL problems can be solved to a large extend by setting sql_mode to TRADTIONAL and using InnoDB databases, which should in my opinion be the default and not an option. My recommendation is to use PostgreSQL servers and for the applications: use frameworks (if you are allowed to, which may not be always the case [e.g. when you are learning SQL, using a ORM is clearly the wrong way]), document your code, separate your code into classes and functions, and make sure you are not using to many global variables. And use a SCM to track your changes. Posted in General

11 May 2009

Brice Goglin: Debian/X.org notes - Why some X drivers like firmware-linux

We got many bug reports about X being slow. Many of them are caused by some MTRR/PAT problems in kernel 2.6.29. But some are not. It appears to be caused by Debian 2.6.29 kernels not containing ugly binary graphics firmware anymore. Indeed, radeon, r128 and mga driver need a firmware for 3D, but also for some 2D and Xv features (basically everything that's hardware accelerated). So if you use one of these X drivers and you have some problems, a quick look in the kernel logs might tell you that a firmware is missing. Installing the firmware-linux package may help then. We are adding the corresponding Suggests line to X drivers. Moreover, some people are upgrading to 2.6.30 pre-release because it contains DRM support for R600 boards. A ugly binary firmware is needed as well and it has obviously been removed from Debian 2.6.30 experimental packages. But firmware-linux does not seem to contain this firmware yet. So if you want 2.6.30 for R600 DRM, you want to either build your own 2.6.30 kernel, or wait for an updated firmware-linux package to be available with R600 firmware. See bug#523467 for an example.
(Permanent link)

10 May 2009

Ond&#345;ej &#268;ert&iacute;k: My experience with running an opensource project

Nir Aides, the author of the excellent winpdb debugger, sent me the following email on September 21, 2008, so I asked him if I can copy his email and reply in form of a blog post (so that other people can comment and join the discussion) and he agreed. It took me almost a year to reply, but I made it. :)

Hi Ondrej,

How are you?

I am about to publish a new free software project, a new simple PHP framework, and I am interested in your advice.

You started SymPy and were able to make other people join you and develop it with you.
How did you do it?
How did it happen?
Did you actively call for other people or they spontaneously showed interest and joined you?
Are the other major contributor people who were your friends before you started the project?
Did you need to create or manage the project in a particular way to make it attractive to other people?
Are there things you are aware of that promote collaboration or demote it?

I was never successful in doing the same with Winpdb, which while it became reasonably popular, no one has ever joined me to develop it, except for a notable tutorial contribution by Chris Lasher which was developed independently.

Now with the new project, I am wondering what are my chances of making other people try it and take it on. On the one hand it is a new and fresh code base in an interesting field, on the other hand, why would anyone bother to spend their energy on this new project when they have Symfony or Drupal?

What do you think?

BTW, Ohloh believes you have a median of 19,000 lines of changed code per month since the start of their log. Can this be true? Is this humanly possible? According to it SymPy has over 1,000,000 lines of code? I can't understand these numbers. Winpdb has about 25,000 lines after 3 years of development. And from my experience 1,000,000 lines of code projects need about 20-50 full time developers to work on for 2-5 years which is about 40-250 man years. And as if this is not enough you are listed as owner in a dozen other projects in Google code and have enough time to become an awarded scientist. How is this possible?

http://www.ohloh.net/p/sympy/contributors/

BTW2, do you still use Winpdb? If you find yourself using it less, can you say what are the reasons, or what it would take to make it more useful?

BTW3, How is SymPy doing?

Cheers,
Nir


So my most honest answer how to run a successful opensource project is: I don't know.

But nevertheless I tried to summarize some of my ideas and experience and some guidelines that I try to follow, maybe it will be useful to you Nir, or anyone else.

First of all, there has to be a public mailinglist (easily accessible), public bug tracker, nice webpage, easy to find downloads, frequent releases (once a month is good, but in the worst case at least 4 times a year) and a set of guidelines to follow in order to contribute. So that's a must, if the project doesn't have the above, it's almost impossible to become successful. However, that is just a start, just a playground. There are still many projects that have the above and yet they totally fail to attract developers.

So I think the most important principle is that I always think how to employ other people in what I do. If I have some plan in my head how to do something, e.g. how to move some things forward, I always create exact steps and put it to issues, or our mailinglist, so that each step can be done by someone who is completely new to sympy. So I try to look at things from other people's perspective and think -- ok, I quite like this SymPy project and I'd like to get this done (for example a new release, or something fixed, or implemented), but I have no idea how to start and what exactly needs to be done.

So what I try to do if someone comes to our list and asks for something, is that I create a new issue for it and think how I would fix it if I had time. Then write the necessary steps in the issue and invite the submitter to fix it and I offer help with explaining anything and guiding. Now there are two things that can happen. Either the submitter has time and a will to go forward and in this case he starts wrestling with it and whenever he has some code or a question, I need to find time, review it and offer some way out. Or the submitter is too busy, in which case the instructions simply rest in the issues and the next time someone asks for the feature, the instructions are already there. I don't have estimates how frequent either case is.

When I am working on something myself, I try not to code privately, but also put up issues first and put the steps needed in the issues, so that it's easy for other people to join in.

In general, the most precious value for me is the fact that someone else had to sit down at his computer and wrote the patch. So I do everything possible to get new (or more) people interested in the development. Some people think that only super programmers can do a decent job and it's useless to invest time in people that may just have started with Python. They are wrong. Among the SymPy developers (around 65 people total have contributed patches so far at the time of writing this post), we have all kinds of people. We have people from high school, we have a retired US army engineer, we have physicists, mathematicians, biologists, engineers, teachers, or just hobbyists, who do it for fun. Unfortunately, we do not have many women (I think no patch that made it into sympy was contributed by a woman, but I may be wrong), so if anyone has any ideas how to get more women involved, let me know (I know we have several women fans, so that's a good start:). We have people whose first open source project they ever contributed to was sympy and people who are new to Python.

Many times the first patch that a new potential developer submits is not perfect, usually it's faster for me to write it myself, than to help with the first patch, however my rule is to always help the submitter do that. Sometimes he sends a second patch, or a third, and usually it needs less and less work on my side and it already pays off, because he is then able to fix things himself, if he discovers a bug and sympy has just won a one more contributor.

So I came to the conclusion that all that is needed is an enthusiasm. You don't even have to know Python (as you can learn all these things on the way) and you can still do useful things for us and really spare our time.

To answer another question from Nir's email, SymPy has about 130000 lines of code and another about 20000 lines of tests, so I think those stats are wrong. Also the changed lines of code is in my opinion wrong, we usually have about 250 new patches per release (this depends how often we release and other things).

Yes, I am involved in couple other projects, e.g. Debian, Sage, ipython, scipy, hpfem.org (and couple more), basically everything that has to do with numeric simulation and Python, but my activity there varies. The most time consuming thing in the last couple years was definitely school, I was finishing my master in Theoretical Physics in Prague and then moved to the Nevada/Reno and I just finished my first semester here at PhD in Chemical Physics, and sometimes it was just crazy, e.g. I finished teaching at 7pm and instead of going home and sleep, I stayed in my office, fixed 10 sympy issues that were holding off a release, finished at 1am, went home (by bike, since I don't have a car yet), slept couple hours and then did just school again for a week, other people reviewed the issues in the meantime, and then I made the release (instead of sleeping again). In the last semester it was not unusual that I got home at 1am every week day, then slept most of Saturday to catch up, on Sunday I did some laundry and shopping, and the rest of time I did grading and homeworks for all my classes and teaching, no time for anything else (e.g. no friends, no girls, no rest, no hobby, no opensource stuff, nothing). So sometimes one has to work pretty hard to get through it, but fortunately it's behind me finally, if all goes well, I should be just doing research from now on and have a real life too. Also I am sorry I didn't manage to reply sooner. :)

To answer the other questions:
Are the other major contributor people who were your friends before you started the project?
No, not a single major contributor was my friend before I started the project. Every single one of them become a developer using the procedure I described above, e.g. first showed on the list or in the issues, and maybe even the very first patch was not a high quality one (and if I was stupid and arrogant, or didn't see the big potential, I would just ignore them). But when given a chance, they became extremely good developers and sympy would simply just not be here without them.

Did you actively call for other people or they spontaneously showed interest and joined you?
I very much encourage everyone to contribute, but the initial interest must be in them, e.g. they at least have to show around the mailinglist/issues, so that I know about them. But once I know they are interested in some issue, yes, I try to invite them to fix it, with my help.

One observation I made is that I have to always think in the spirit "how to earn new money, not how to spare the money I already have", e.g. when applied to sympy, how to get new developers, how to develop the new great things etc. Even if I am super busy as I was, I still have to think this way. Once I start thinking how to conserve and preserve what we already have, I am done, finished and that's the road to hell.

If I am open, positive, full of energy, I can see people joining me and we can do great things together. It probably sounds obvious, but it was not for me, when for example some people I worked with, started their own projects, when I got busy, and started to compete, instead of helping sympy out. And I felt betrayed, after so much work that I invested into it and started to become protective. And then I realised that's wrong. I can never stop other people do what they want to do. If they want to have their own project, they will have it. If they don't want to help sympy out, they won't (and what is more important, there is nothing wrong with either of that). It's that simple and being protective only makes things worse.

There is also a question of the license that you use for the project, e.g. one should basically only choose between BSD (maybe also MIT or Apache), LGPL and GPL (there are also several versions of the GPL licenses). Unfortunately the fact is, that there are people who will never contribute a code under a permissive BSD license (because it's not protecting their work enough) and there are also other people who really want to code to be BSD (or other permissive license) so they can sell it and they don't need to consult with lawyers what they are or aren't allowed to do and also so that they can combine it with any other code (opensource or not). It also depends if one wants to combine (and distribute) other codes together. So choosing a license is also important. I believe that for sympy BSD is the best and for other projects (like Sage) GPL is the best and one has to decide on a case by case basis. For Winpdb, I would make it BSD too, since you can get more people using it.

To conclude, SymPy is a little more than 2 years old, and it has been a great ride so far and more things are coming, e.g. this summer we have 5 Google Summer of Code students and people are starting it to use in their research and we plan to use it in our codes at our group here in Reno too, so things look promising. I am really glad, we managed to build such a community, so that when I am busy, as I was the last semester, other people help out with patches, reviews and other things, so that the project doesn't stall and when I got rid of my school duties now, we can move things forward a lot.

So maybe you can get inspired by some of the ideas above. I am also interested in any discussion about this (feel free to post a comment below, or send me an email, or just write to a sympy list about what you think).

Martin Meredith: This whole GPG/PGP thing

So, SHA-1 has potential exploits, but you know what? I only use it for signing plain text things. Email, change files I ve no reason to use it for encryption, as I don t encrypt things Surely, if anyone is going to make something that collides with a valid signature of mine, it s going to either a) be noticable to the person reading it (random characters in an email?) or b) not be processable by whatever automated sytem is using it. I ve yet to hear of any exploit that could affect the way I use SHA-1 in a meaningful way. Ok, yes, I m not going to be using it to hash passwords in future (well, GPG uses it to hash passwords, but generally, to be able to crack that, someone would have to have my secret key anyway, which I would count as being compromised!) If someone can give me a real world example of how this can be used against me, I might go out of my way to replace my key, but for now, I don t see the need. Ok, I might take the next time I meet up with a fellow Debian Developer as a chance to replace my key, but I m not going to go out of my way to do so (as I had to for getting my key signed by my first Debian/Ubuntu Developer in the first place)
8 May 2009

Alastair McKinstry: Funding Public Health care : the bigger picture

Adrian von Bidder raises an interesting discussion on why public health care is difficult. Basically, it comes back to the challenge:
How much money should be spent on this person's illness? which is a very, very bad question. We try to sidestep it by only taking about statistics etc., but no matter how you look at it, you either do 20'000  per week medications for 80 year old patients who will die soon anyway and get a system society can't pay, or you don't and you get a system where the rich are better off than the poor.
The problem is, the majority of health costs are in the last few years of a persons life: when the body is breaking down. If viewed from the problem of health-care funding vs. eg. education, you have an ethical dilemma: is it worth it ? Here there are no easy answers. Nick Bostrom wrote a very interesting and persuasive essay a while back, The fable of the Dragon Tyrant. In short, we are getting somewhere with regenerative medicine While cures are hard to come by at this stage, there is a growing realization in medicine that senesence, what we used to call "old age", is curable. But we have a lot of psychological defensive mechanisms to help us cope with the carnage of old age that make us deny the problem: if we look afresh at "old age" knowing it to be curable, any delay in doing so is abhorrent. From a public, societal perspective, we spend a fortune every year on health. But we do so in a very disjointed way: we pay colossal amounts for health care, but also for basic health science: in the US, for example, the budget for the National Institutes of Health is about 30 billion dollars. Nearly twice that of NASA. Similar figures are spent in Europe, but there is this strange gap in the middle: the drug companies and medical industry. We start the development of new drugs with public money, and we buy the drugs with public money, but the choice of what drugs and treatments are developed are left to private industry, that is, a profit motive. This results in many cases in expensive treatments to treat symptoms rather than necessarily cure the problem. Faced with the huge costs of geriatric medicine and senesence, the response should be co-ordinated: funding a cure will be expensive, but save a fortune (Think, instead of a pensioner slowly dying and 'being a drain on resources', of 'experienced citizen in the prime of their productive, tax-paying years'). Instead of funding the basic science alone, we should be funding the complete drug and treatment development publically, only farming out the actual manufacture to private industry. It is silly to spend a fortune to keep merely keep someone alive at the age of eighty or so, when we know for a larger investment (bigger than a private company can do), we can cure them properly. The solution to the dilemma, then, is to stop thinking of the elderly being a drain, but actually applying our public efforts in a co-ordinated manner to solving the carnage of old age. Tags ,

7 May 2009

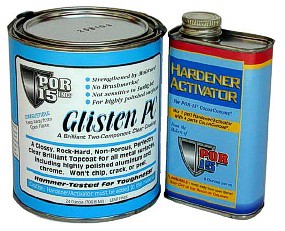
Biella Coleman: Make our words glisten


glisten vs hardened words, originally uploaded by the biella.
Now that I am (thankfully) done teaching until September, I have time to devour two small mountains of readings that I need to finish before I return to my manuscript, which I will be working on, I hope uber-productively, all summer long. One pile of readings deals with coding, open source, and the commons, such as Scott Rosenberg s Dreaming in Code and David Bollier s Viral Spiral. Another pile of reading edges toward the theoretical side of things, having to do with craft, pleasure, and humor, since it is pleasure in its many many many guises from from the calm feeling of self-satisfaction that underlies pride in one s craft, to the more sublime feeling of ecstatic bliss that powers many creative sprints. If one entertains pleasure, one must also entertain its darker side, for all of this feel good stuff is nonetheless often springs forth from a deep sea of passionate frustration. This seems to be the driving theme of Dreaming in Code and it is also what animates Ellen Ullman s fictional account of pure frustration, The Bug. I am quite fond of native expressions of geek frustration and recently was provided with an exquisite example a rant against the Adobe PSD format. The author of Xee, A light-weight, fast and convenient image viewer for Mac OS X explained his utter contempt for the Adobe PSD in the following way:
At this point, I d like to take a moment to speak to you about the Adobe PSD format. PSD is not a good format. PSD is not even a bad format. Calling it such would be an insult to other bad formats, such as PCX or JPEG. No, PSD is an abysmal format. Having worked on this code for several weeks now, my hate for PSD has grown to a raging fire that burns with the fierce passion of a million suns. If there are two different ways of doing something, PSD will do both, in different places. It will then make up three more ways no sane human would think of, and do those too. PSD makes inconsistency an art form. Why, for instance, did it suddenly decide that *these* particular chunks should be aligned to four bytes, and that this alignement should *not* be included in the size? Other chunks in other places are either unaligned, or aligned with the alignment included in the size. Here, though, it is not included. Were it within my power, I would gather every single copy of those specs, and launch them on a spaceship directly into the sun.
Even if this account represents unadulterated irritation, he leaves us, the reader, with nothing of the irritation, only pleasure. This aftermath of frustration is delivered through the vehicle of humor, which within the hacker context, is the cultural container that best captures the spirit of hacker pleasure or so I will be arguing. Like many humorous rants from the world of hacking (and please send me any others you know of), this text dances with liveliness; it exudes its own rhythm; it glistens to use Ronald Barthes apt phrasing from his short book The Pleasure of Text, which I just finished as part of my theoretical escape into the pleasure-dome. Although there are parts of his book which are to be frank, *really* *not* *pleasurable*, partly due to obscure references to High French Theory, which elide even an academic pair of eyes, the book generally pleases. And one of the most pleasing chunks is his definition of a stereotype:
The stereotype is the word repeated without any magic, any enthusiasm, as though it were natural, as though by some miracle this recurring words were adequate on each occasion for different reasons, as though to imitate could no longer be sensed as an imitation: an unconstrained word that claims consistency and is unaware of its own insistence
In contrast to the stereotype, a string of words that enchants does so by slipping off the page to hit you squarely in the heart or the gut. Unfortunately, while academic writing steers clear of stereotypes, often trying to present the detailed singularity of a phenomena (even when conditioned by social forces), it does not exactly glisten, though there are a handful of exceptions. I think we need more texts that glisten, even if only during sections or parts of our books and articles (much like the rant helped enliven the more staid technical document). In recent years, in large part due to the influence of free software, there has been an explosion, a move toward going open access. All of this is laudable and I fully embrace it (and have gotten into some small battles over it). But without an aesthetic politics that values pleasure in reading and writing we are doomed to obscurity anyway. A move toward making our knowledge public also required a move toward thinking about the literary aesthetics of pleasure.

Biella Coleman: Make our words glisten


glisten vs hardened words, originally uploaded by the biella.
Now that I am (thankfully) done teaching until September, I have time to devour two small mountains of readings that I need to finish before I return to my manuscript, which I will be working on, I hope uber-productively, all summer long. One pile of readings deals with coding, open source, and the commons, such as Scott Rosenberg s Dreaming in Code and David Bollier s Viral Spiral. Another pile of reading edges toward the theoretical side of things, having to do with craft, pleasure, and humor, since it is pleasure in its many many many guises from from the calm feeling of self-satisfaction that underlies pride in one s craft, to the more sublime feeling of ecstatic bliss that powers many creative sprints. If one entertains pleasure, one must also entertain its darker side, for all of this feel good stuff is nonetheless often springs forth from a deep sea of passionate frustration. This seems to be the driving theme of Dreaming in Code and it is also what animates Ellen Ullman s fictional account of pure frustration, The Bug. I am quite fond of native expressions of geek frustration and recently was provided with an exquisite example a rant against the Adobe PSD format. The author of Xee, A light-weight, fast and convenient image viewer for Mac OS X explained his utter contempt for the Adobe PSD in the following way:
At this point, I d like to take a moment to speak to you about the Adobe PSD format. PSD is not a good format. PSD is not even a bad format. Calling it such would be an insult to other bad formats, such as PCX or JPEG. No, PSD is an abysmal format. Having worked on this code for several weeks now, my hate for PSD has grown to a raging fire that burns with the fierce passion of a million suns. If there are two different ways of doing something, PSD will do both, in different places. It will then make up three more ways no sane human would think of, and do those too. PSD makes inconsistency an art form. Why, for instance, did it suddenly decide that *these* particular chunks should be aligned to four bytes, and that this alignement should *not* be included in the size? Other chunks in other places are either unaligned, or aligned with the alignment included in the size. Here, though, it is not included. Were it within my power, I would gather every single copy of those specs, and launch them on a spaceship directly into the sun.
Even if this account represents unadulterated irritation, he leaves us, the reader, with nothing of the irritation, only pleasure. This aftermath of frustration is delivered through the vehicle of humor, which within the hacker context, is the cultural container that best captures the spirit of hacker pleasure or so I will be arguing. Like many humorous rants from the world of hacking (and please send me any others you know of), this text dances with liveliness; it exudes its own rhythm; it glistens to use Ronald Barthes apt phrasing from his short book The Pleasure of Text, which I just finished as part of my theoretical escape into the pleasure-dome. Although there are parts of his book which are to be frank, *really* *not* *pleasurable*, partly due to obscure references to High French Theory, which elide even an academic pair of eyes, the book generally pleases. And one of the most pleasing chunks is his definition of a stereotype:
The stereotype is the word repeated without any magic, any enthusiasm, as though it were natural, as though by some miracle this recurring words were adequate on each occasion for different reasons, as though to imitate could no longer be sensed as an imitation: an unconstrained word that claims consistency and is unaware of its own insistence
In contrast to the stereotype, a string of words that enchants does so by slipping off the page to hit you squarely in the heart or the gut. Unfortunately, while academic writing steers clear of stereotypes, often trying to present the detailed singularity of a phenomena (even when conditioned by social forces), it does not exactly glisten, though there are a handful of exceptions. I think we need more texts that glisten, even if only during sections or parts of our books and articles (much like the rant helped enliven the more staid technical document). In recent years, in large part due to the influence of free software, there has been an explosion, a move toward going open access. All of this is laudable and I fully embrace it (and have gotten into some small battles over it). But without an aesthetic politics that values pleasure in reading and writing we are doomed to obscurity anyway. A move toward making our knowledge public also required a move toward thinking about the literary aesthetics of pleasure.

Adrian von Bidder: Why Public Health-Care is Difficult

A reply to Tore, who is probably partly wrong. I don't claim the U.S. system is good or bad, I don't know it. But I don't think public (which he seems to imply means free) health care is as easy as he suggests. I'm starting at his assertion that
Very few people break their legs intentionally to stay at a nice hospital. [Health care] is not a resource likely to be wasted once people are given free access to it.
The case of a broken leg is easy. What about chronic illnesses, especially those difficult to diagnose (some kinds of back pain, psychological problems, ...)? What about bored old people who spend their days talking to doctors about how bad getting older is? Easily available (cheap or free) health care has lead to hospitals being swamped with people with minor issues to the point where people with serious problems died because hospital staff didn't get to them in time. And, because the state's budget is not infinite, hospitals become badly run institutions with always-overworked staff leading to even fewer people wanting to work there etc. This has happened in the UK, for example (I think the system I have been reading about ages ago has since been replaced by a different one.) Switzerland doesn't have this problem (to this extent) because we really care about (this means, here: throw money at) our health system, but the result is that the mandatory health insurance becomes insanely expensive. There is talk about half the population needing state subsidies to pay for their health insurance within the next few years. Which, of course, will just move the cost from the whole population (via mandatory health insurance) to the whole population (via taxes) so I don't quite see the point... You'll note I don't propose solutions either. But I think it's important to acknowledge that health care is a difficult topic because, in the end, it always comes down to the question How much money should be spent on this person's illness? which is a very, very bad question. We try to sidestep it by only taking about statistics etc., but no matter how you look at it, you either do 20'000 per week medications for 80 year old patients who will die soon anyway and get a system society can't pay, or you don't and you get a system where the rich are better off than the poor. Or you delegate the decision to the doctor or the insurance or ... and try to minimize the number of people who deserve (can you see it, the hard question didn't get away!) treatment but don't get it. Update 20090508 - Response to comments I'd like to thank you for commenting. I didn't know (and sorry about that didn't care to research) that the U.S. system is even more expensive than ours, since my main message is just that health care is about hard decisions. Some people always will be left out. Elaborating a bit on the 20'000 a week medication: partly, I agree with Adrian and Tore: patent-supported monopolies on medication plays a part. Partly, because I stipulate there will always be rare illnesses where a few cases per year worldwide will have to pay for all the research and production of the medication. Of course, the cost can be distributed so that the patient (or his insurance) doesn't have to pay it, but society as a whole will still pay. So the hard question won't go away easily, now it's just become Do we fund research for this rare illness with fewer than five cases per year worldwide? Of course, now we're not speaking of people anymore, but already just of cases, and we're not cutting treatment for an actual person but we're just cutting budget on research, so it may be easier on the conscience, but it's still fundamentally the same question. Conclusion? Health-care will always be a difficult topic, and it will never be free. The cost can just be distributed in different ways.

Ian Wienand: Quickly describing hash utilisation

I think the most correct way to describe utilisation of a hash-table is using chi-squared distributions and hypothesis and degrees of freedom and a bunch of other things nobody but an actuary remembers. So I was looking for a quick method that was close-enough but didn't require digging out a statistics text-book. I'm sure I've re-invented some well-known measurement, but I'm not sure what it is. The idea is to add up the total steps required to look-up all elements in the hash-table, and compare that to the theoretical ideal of a uniformly balanced hash-table. You can then get a ratio that tells you if you're in the ball-park, or if you should try something else. A diagram should suffice. Scheme for acquiring a hash-utilisation ratio This seems to give quite useful results with a bare minimum of effort, and most importantly no tricky floating point math. For example, on the standard Unix words with a 2048 entry hash-table, the standard DJB hash came out very well (as expected)
Ideal 2408448
Actual 2473833
----
Ratio 0.973569
To contrast, a simple "add each character" type hash:
Ideal 2408448
Actual 6367489
----
Ratio 0.378241
Example code is hash-ratio.py. I expect this measurement is most useful when you have a largely static bunch of data for which you are attempting to choose an appropriate hash-function. I guess if you are really trying to hash more or less random incoming data and hence only have a random sample to work with, you can't avoid doing the "real" statistics.

Joey Hess: sha-1

So, sha-1 is looking increasingly insecure in applications where birthday attacks are possible. ("Birthday attacks" ... what a phrase ... I hope my non-technical readers stopped at "sha-1".) Two things about that:
First, I wanted to mention that I've today released jetring 0.15, which adds support for arbitrary hashes in the index file, and deprecates use of sha-1, going to sha-256 by default. There is a jetring-checksum -u utility that can be used to upgrade sha-1 hashes in existing jetring index files. If you're using jetring in an application where changesets are provided by third paries, then a birthday attack could be possible (though not easy?), and you should upgrade your index. debian-maintainer is a good example of such a jetring user.
Secondly, our beloved git uses sha-1, and this seems unlikely to change soon or without significant pain. So, what kinds of collision attacks would you need to watch out for when using git? Here is a real-world example I've been pondering. Is it accurate? Here's a different scenario.. This seems more plausible. This sort of attack is easy to accomplish with a subversion repository, and was one of the reasons I was glad to switch to git, since its checksums and signed tags seemed to prevent this kind of mischief. So, worrying, especially if your project uses such a build server. Update: Thanks to the commenters for helping me correct my example. (I hope!)

5 May 2009

Michal &#268;iha&#345;: Going native IPv6

I finally managed to ask my hosting provider for a IPv6 addresses and it went surprisingly smoothly. So since today, all what is running on my server (for example Wammu website or phpMyAdmin wiki and demo) should be accessible natively over IPv6. And thanks to Sixxs guys for providing tunnel which I've been using up to now.

Manoj Srivastava: Manoj: Debian list spam reporting the Gnus way

So, recently our email overlords graciously provided means for us minions to help them in their toils and help clean up the spammish clutter in the mailing lists by helping report the spam. And the provided us with a dead simple means of reporting such spam to them. Now, us folks who knoweth that there is but one editor, the true editor, and its, err, proponent is RMS, use Gnus to follow the emacs mailing lists, either directly, or through gmane. There are plenty of examples out there showing how to automate reporting spam to gmane, so I won t bore y all with the details. Here I only show how one serves our list overlords, and smite the spam at the same time. Some background, from the Gnus info page. I ll try to keep it brief. There is far more functionality present if you read the documentation, but you can see that for yourself.
The Spam package provides Gnus with a centralized mechanism for detecting and filtering spam. It filters new mail, and processes messages according to whether they are spam or ham. There are two contact points between the Spam package and the rest of Gnus: checking new mail for spam, and leaving a group. Checking new mail for spam is done in one of two ways: while splitting incoming mail, or when you enter a group. Identifying spam messages is only half of the Spam package s job. The second half comes into play whenever you exit a group buffer. At this point, the Spam package does several things: it can add the contents of the ham or spam message to the dictionary of the filtering software, and it can report mail to various places using different protocols.
All this is very plugin and modular. The advantage is, that you can use various plugin front ends to identify spam and ham, or mark messages as you go through a group, and when you exit the group, spam is reported, ham and spam messages are copied to special destinations for future training of your filter. Since you inspect the marks put into the group buffer as you read the messages, there is a human involved in the processing, but as much as possible can be automated away. Do read the info page on the Spam package in Gnus, it is edifying. Anyway, here is a snippet from my etc/emacs/news/gnusrc.el file, which can help automate the tedium of reporting spam. This is perhaps more like how Gnus does things than having to press a special key for every spam, and which does nothing to help train your filter.
    1  (add-to-list
    2   'gnus-parameters
    3   '("^nnml:\\(debian-.*\\)$"
    4           (to-address . "\\1@lists.debian.org")
    5           (to-list . "\\1@lists.debian.org")
    6           (admin-address . "\\1-request@lists.debian.org")
    7           (spam-autodetect . t)
    8           (spam-autodetect-methods spam-use-gmane-xref spam-use-hashcash spam-use-BBDB)
    9           (spam-process '(spam spam-use-resend))
   10           (spam-report-resend-to . "report-listspam@lists.debian.org")
   11           (subscribed . t)
   12           (total-expire . t)
   13           ))

4 May 2009

Biella Coleman: Mad developments

There is a lot of madness when it comes to psychiatry. One recent example of madness perhaps insanity is this faux peer review journal. At least there seems to be a growing counter-current in medicine that wants to sever the umbilical cord between doctors and drug companies as well as a vibrant grass roots move to embrace a different politics in and of madness.

2 May 2009

Russell Coker: Too Stupid to be a Judge

Bruce Schneier has written about the foolish actions of Justice Antonin Scalia [1]. Antonin made some comments opposing the need for greater privacy protection, most people could get away with doing that, but when a Supreme Court Justice does so it gets some attention. In response to this Fordham University law professor Joel Reidenberg assigned his class a project to discover private information on Antonin using public sources. The class produced a dossier of such information which was then offered to Antonin [2], but which was not published. Now anyone who knows anything about how the world works would just accept this. Among other things Antonin now knows what is publicly available and can take steps to remove some public data according to his own desires. But being apparently unaware of the Streisand effect [3] Antonin went on to say the following: It is not a rare phenomenon that what is legal may also be quite irresponsible. That appears in the First Amendment context all the time. What can be said often should not be said. Prof. Reidenberg s exercise is an example of perfectly legal, abominably poor judgment. Since he was not teaching a course in judgment, I presume he felt no responsibility to display any. This is of course essentially issuing a challenge to the entire Internet to discover the information that the Fordham students discovered. Of course doing so would not be fun unless it was published. The meme of 2009 has yet to be defined, it might be discovering and widely publishing personal information about Antonin. Already one of the comments in Bruce Schneier s blog suggests that activists should do such research on all senior figures in the US government to encourage them to take privacy more seriously. I expect that the first reaction of the legislative branch to such practices would be to enact special laws to protect their own privacy while still allowing large corporations (the organisations that pay for the election campaigns) to do whatever they want to ordinary people. It s an interesting situation, I predict that Antonin will regard this as one of the biggest mistakes he s ever made. I m sure that there are many more LULZ to come from this.

30 April 2009

Biella Coleman: On Chasing Plastic

Anyone who knew me prior to 2000, knew me as a fanatic Ultimate Frisbee player. I was (mostly) all about chasing a plastic disc on lush green fields. Ultimate Frisbee, which took my attention and soul my first year of college, commanded my attention, time, and body for years. The New York Times just ran a nice short piece piece about Ultimate Frisbee, which apparently has skyrocketed in popularity since 2003. One section of the article caught my attention:
It may be a non-contact sport according to its rules, but Ultimate is hardly free of injuries. The quick cutting and sprinting have made anterior cruciate ligament tears among women players especially common. JOY CHEN, a 33-year-old software developer in Alameda, Calif., considers herself lucky that herniated disks, a rotator cuff tear and ankle sprains have been the extent of her Ultimate injuries. We hit each other and the ground pretty hard, said Ms. Chen, who discovered Ultimate in college after years as a soccer and tennis player. She played with Stanford University s Superfly, which went on a three-year run as undefeated women s national collegiate champions.
Injury goes with the sport as hand and glove and young players tend to wear these injuries as a badge of pride. As much as I adore the sport and there are days I get pretty bummed that I no longer play I think that the UPA and older players should seriously skool the younger generation on the danger of injuries. It is an extreme sport that requires extreme care. Tournaments are usually composed of 4-7 games over the course of 2 days. If that is not demanding enough, the body gets pretty intimate with the the ground while laying out and then there are there all those sprained ankles and broken bones and ligaments from collisions. Today I suffer from bouts of knarly neck pain, for example, which is due in part from playing without taking proper precautions. One of my best friends, who was a stellar player in college, also suffers from pretty devastating back pain. It is an extreme sport that requires extreme care. I say toss out the pride in pain/injuries and in place, instill a healthy sense of fear of the injuries so that people get proper long term and sustained care for their injuries so that they can keep on playing the world s best sport. PS For those that don t know, UF also revolves around an ethical philosophy Spirit of the Game, which unfortunately the article makes no mention of, despite its centrality to the sport.

29 April 2009

Antti-Juhani Kaijanaho: Initramfs problems with the new kernel-package, and a solution

I ve been using Manoj s new kernel-package for some weeks now, and used it to compile two kernels (a reconfigured 2.6.29.1 and the new 2.6.29.2). Both times I ve had trouble with initrd. As the documentation says, kernel-package kernel packages no longer do their own initramfs generation. One must copy the example scripts at /usr/share/doc/kernel-package/examples/etc.kernel/postinst.d/initramfs and /usr/share/doc/kernel-package/examples/etc.kernel/postrm.d/initramfs to the appropriate subdirectories of /etc/kernel/. However, this is not enough. My /etc/kernel-img.conf file had the usual posthook and prehook lines calling update-grub. Unfortunately, those hooks are called before the postinst.d hooks, and so update-grub never saw my initramfs images. Fix? I removed those lines from /etc/kernel-img.conf and created a very simple postinst.d and postrm.d script:
#!/bin/sh
update-grub
I call the script zzz-grub-local, to ensure that it runs last.

28 April 2009

Florian Ragwitz: Implementing Typed Lexical Variables

For quite some time perl provided a form of my declarations that includes a type name, like this:
my Str $x = 'foo';
However, that didn't do anything useful, until Vincent Pit came along and wrote the excellent Lexical::Types module, which allows you to extend the semantics of typed lexicals and actually make them do something useful. For that, it simply invokes a callback for every my declaration with a type in the scopes it is loaded. Within that callback you get the variable that is being declared as well as the name of the type used in the declaration. We also have Moose type constraints and the great MooseX::Types module, that allows us to define our own type libraries and import the type constraints into other modules. Let's glue those modules together. Consider this code:
use MooseX::Types::Moose qw/Int/;
use Lexical::Types;
my Int $x = 42;
The first problem is that the perl compiler expects a package with the name of the type used in my to exist. If there's no such package compilation will fail. Creating top-level namespaces for all the types we want to use would obviously suck. Luckily the compiler will also try to look for a function with the name of the type in the current scope. If that exists and is inlineable, it will call that function and use the return value as a package name. In the above code snippet an Int function already exists. We imported that from MooseX::Types::Moose. Unfortunately it isn't inlineable. Even if it were, compilation would still fail, because it would return a Moose::Meta::TypeConstraint instead of a valid package name. To fix that, let's rewrite the code to this:
use MooseX::Types::Moose qw/Int/;
use MooseX::Lexical::Types qw/Int/;
my Int $x = 42;
Let's also write a MooseX::Lexical::Types module that replaces existing imported type exports with something that can be inlined and returns an existing package name based on the type constraint's name.
package MooseX::Lexical::Types;
use Class::MOP;
use MooseX::Types::Util qw/has_available_type_export/;
use namespace::autoclean;
sub import  
    my ($class, @args) = @_;
    my $caller = caller();
    my $meta = Class::MOP::class_of($caller)   Class::MOP::Class->initialize($caller);
    for my $type_name (@args)  
        # get the type constraint by introspecting the caller
        my $type_constraint = has_available_type_export($caller, $type_name);
        my $package = 'MooseX::Lexical::Types::TYPE::' . $type_constraint->name;
        Class::MOP::Class->create($package);
        $meta->add_package_symbol('&'.$type_name => sub ()   $package  );
     
    Lexical::Types->import; # enable Lexical::Types for the caller
 
1;
With that the example code now compiles. Unfortunately it breaks every other usecase of MooseX::Types. The export will still need to return a Moose::Meta::TypeConstraint at run time so this will continue to work:
has some_attribute => (is => 'ro', isa => Int);
So instead of returning a plain package name from our exported function we will return an object that delegates all method calls to the actual type constraint, but evaluates to our special package name when used as a string:
my $decorator = MooseX::Lexical::Types::TypeDecorator->new($type_constraint);
$meta->add_package_symbol('&'.$type_name => sub ()   $decorator  );
and:
package MooseX::Lexical::Types::TypeDecorator;
use Moose;
use namespace::autoclean;
# MooseX::Types happens to already have a class that doesn't do much
# more than delegating to a real type constraint!
extends 'MooseX::Types::TypeDecorator';
use overload '""' => sub  
    'MooseX::Lexical::Types::TYPE::' . $_[0]->__type_constraint->name
 ;
1;
Now we're able to use Int as usual and have Lexical::Types invoke its callback on MooseX::Lexical::Types::TYPE::Int. Within that callback we will need the real type constraint again, but as it is invoked as a class method with no good way to pass in additional arguments, we will need to store the type constraint somewhere. I choose to simply add a method to the type class we create when constructing our export. After that, all we need is to implement our Lexical::Types callback. We will put that in a class all our type classes will inherit from:
Class::MOP::Class->create(
    $package => (
        superclasses => ['MooseX::Lexical::Types::TypedScalar'],
        methods      =>  
            get_type_constraint => sub   $type_constraint  ,
         ,
    ),
);
The Lexical::Types callback will now need to tie things together by modifying the declared variable so it will automatically validate values against the type constraint when being assigned to. There are several ways of doing this. Using tie on the declared variable would probable be the easiest thing to do. However, I decided to use Variable::Magic (also written by Vincent Pit - did I mention he's awesome?), because it's mostly invisible at the perl level and also performs rather well (not that it'd matter, given that validation itself is relatively slow):
package MooseX::Lexical::Types::TypedScalar;
use Carp qw/confess/;
use Variable::Magic qw/wizard cast/;
use namespace::autoclean;
my $wiz = wizard
    # store the type constraint in the data attached to the magic
    data => sub   $_[1]->get_type_constraint  ,
    # when assigning to the variable, fail if we can't validate the
    # new value ($_[0]) against the type constraint ($_[1])
    set  => sub  
        if (defined (my $msg = $_[1]->validate($  $_[0]  )))  
            confess $msg;
         
        ();
     ;
sub TYPEDSCALAR  
    # cast $wiz on the variable in $_[1]. pass the type package name
    # in $_[0] to the wizard's data construction callback.
    cast $_[1], $wiz, $_[0];
    ();
 
1;
With this, our example code now works. If someone wants to assign, say, 'foo' to the variable declared as my Int $x our magic callback will be invoked, try to validate the value against the type constraint and fail loudly. WIN! The code for all this is available github and should also be on CPAN shortly. You might notice warnings about mismatching prototypes. Those are caused by Class::MOP and fixed in the git version of it, so they'll go away with the next release. There's still a couple of caveats, but please see the documentation for that.

27 April 2009

Russell Coker: Email Passwords

I was doing some routing sysadmin work for a client when I had to read mail in the system administration mailbox. This mailbox is used for cron job email, communication with ISPs that run servers for the company, and other important things. I noticed that the account was subscribed to some mailing lists related to system administration, the following is from one of the monthly messages from a list server: Passwords for sysadmin@example.com: List Password // URL
-
whatever-users@example.org victoria3 That doesn t seem terribly exciting, unless you know that the password used for the list server happens to be the same as the one used for POP and IMAP access to the account in question, and that it is available as webmail Of course I didn t put the real password in my blog post, I replaced it with something conceptually similar and equally difficult to guess (naturally I ve changed the password). The fact that the password wasn t a string of 8 semi-random letters and digits is not a good thing, but not really bad on it s own. It s only when the password gets used for 3rd party servers that you have a real problem. I wonder how many list servers are run by unethical people who use the passwords to gain access to email accounts, and how many hostile parties use such lists of email addresses and passwords when they compromise servers that run mailing lists. Now there would be an obvious security benefit to not having the list server store the password in clear-text or at least not send it out every month. Of course the down-side to doing that is that it doesn t give someone like me the opportunity to discover the problem and change the password.

Clint Adams: ZOMG vs. libre.fm

This is about two things that are not robust. zomg, as of version 0.5.7, can play libre.fm radio streams without modification. It does not do this particularly well. As of today a second type of libre.fm radio stream is available, so I will give two illustrative examples: These stations lack the intelligence to avoid annoying duplication or much of anything but randomization. However, both zomg and libre.fm are free software, and anyone can chip in and improve this if desired. In other news, the state of client support has moved a bit, though not as much as one might have hoped. You can get a picture of that here.

26 April 2009

Sean Finney: new git hook for debian packaging: pre-recieve fileset fascism

previously i threw together a small hook to make it a bit easier to avoid duplicate work while maintaining packages, as well as easily keep the BTS up to date with relevant information. now i've commonized the code just a bit and have a second hook which can be used to maintain certian (what i believe to be) good practices for keeping packages in git. admittedly, it's a bit more "stick" than "carrot" with respect to streamlining workflows, but i feel the justifications and the resulting benefits are worth it. so the hook does basically two things, either of which can be customized and/or disabled. prevent "non-debian" changes on a "debian" branch assuming that there are seperate branches for "debian" packaging and for "upstream" development, this hook prevents upstream-style changes on the debian branches. that is to say changes to files outside ./debian are not permitted on a "debian" branch, unless of course you're merging from an upstream branch. instead, changes to the source in a debian branch should be managed by quilt-style "feature patches", or a more advanced branch topology using some kind of feature branches (topgit or similar). prevent changelog modifications from being mixed in with other commits this one might be a bit more controversial for some. basically, the idea is that: therefore, this hook "declines" commits which modify debian/changelog, unless it is the only file being changed. using this new hook note this is the same repo as the other hook, so if you already have that set up you can skip the clone and instead just pull in the changes. to set it up:
REPO_PATH=/path/to/your/repo.git
HOOK_REPO_PATH=/somewhere/you/want/to/put/it
git clone git://git.debian.org/users/seanius/vcs-hooks/git-hooks.git $HOOK_REPO_PATH
ln -sf $HOOK_REPO_PATH/debian/git-hooks/pre-receive-fileset-fascism.py $REPO_PATH/hooks/pre-receive

the config options for controlling this hook (these are git config options just like the other hook):
# hooks.debianbranches (default: 'debian-.*')
#    a regular expression which indicates which branches are "debian" branches.
#    in the context of this hook such branches are not allowed to have changes
#    in files outside of the ./debian directory.
# hooks.sacredchangelog (default: True)
#    if set to True, debian/changelog can not be changed in a commit that
#    also modifies other files.  this helps ensure changes that are easily
#    merged/cherry-picked/reverted.

examples of the hook in action rejecting a commit that has an entangled changelog:
rangda[~/debian/php] git push                                  :)
Counting objects: 9, done.
Delta compression using 2 threads.
Compressing objects: 100% (5/5), done.
Writing objects: 100% (5/5), 442 bytes, done.
Total 5 (delta 4), reused 0 (delta 0)
fileset-fascism rejecting commit 2fab3269b3d9daedd7013a576483a11ccb4cb86a
    debian/changelog must be changed seperately from other files.
    changed files in this commit:
        debian/changelog
        debian/control
error: hooks/pre-receive exited with error code 1
To ssh://git.debian.org/git/pkg-php/php.git
 ! [remote rejected] debian-sid -> debian-sid (pre-receive hook declined)
error: failed to push some refs to 'ssh://git.debian.org/git/pkg-php/php.git'

rejecting a commit that has non ./debian changes:
rangda[~/debian/php] git push                                  :)
Counting objects: 5, done.
Delta compression using 2 threads.
Compressing objects: 100% (3/3), done.
Writing objects: 100% (3/3), 309 bytes, done.
Total 3 (delta 2), reused 0 (delta 0)
fileset-fascism rejecting commit d96669c0780e33b250af81404e263fc181fe0547
    non ./debian changes on a debian branch in this commit.
error: hooks/pre-receive exited with error code 1
To ssh://git.debian.org/git/pkg-php/php.git
 ! [remote rejected] debian-sid -> debian-sid (pre-receive hook declined)
error: failed to push some refs to 'ssh://git.debian.org/git/pkg-php/php.git'

as always, comments/feedback/suggestions/etc welcome :)

Next.

Previous.

