Search Results: "ed"

25 December 2020

Russ Allbery: DocKnot 4.00

This release of my static site generator and software release management tool is finally at a point where I'm happy with some of the interface and think that piece may be stable for a while. This release converts the package metadata format from JSON to YAML and cleans up a bunch of organizational errors I made when I designed it originally. That also means that the entire metadata is now in a single file, docs/docknot.yaml by convention, instead of needing a whole directory of files. (This comes with the minor drawback that one edits Markdown in text blocks in YAML, which has somewhat less editor support, but it works fine for me.) There's a whole other blog post in how I've now tried many different markup formats, including TOML, and have decided YAML is the best one around if you want humans to be able to write it. (JSON or Protobuf is probably best if you only care about information exchange between software.) The short version is that YAML is way too large of a language and very painful to fully implement, but everything else fails to deal with one or more hard problems: nested structure, multi-line text, comments, or not requiring tedious quoting of everything. I'll be converting other software I maintain over to YAML with time. This release also drops support for pointing the bug reporting address at the CPAN RT instance, since that's going away early in 2021. I will need to do new releases of all my Perl modules to point them at a different bug tracker. Also in this release are some fixes for word wrapping and verbatim paragraph detection, some improved markup in generated README.md files, and other minor fixes. As of this release, I'm now uploading the Debian packages to Debian proper as well. I'm not sure if anyone else will ever use this software, but since I'm going to be doing more automatic generation of files in source releases using it, it's properly part of the build toolchain for the software I maintain. You can get the latest version from the DocKnot distribution page.

Sandro Tosi: Devils: Massimo Ruggiero's apartment building

If you enjoyed watching Devils, like me, and if you tend to obsess over tiny details that have absolutely nothing to do with the story being told, like me, and you lived in that general area, like me, then you may be curious of the location of Massimo's apartment.In several shots we can see views of both The Gherkin and the north side of Canary Wharf, so that means the building is in and around E1/E2/E3 zip codes. But London is huge, and while yes i tried to just browse Google Maps for clues, that didn't produce any result.The final clue is revealed in the 9th episode, at minute 20:10, and precisely with this shot:
at the bottom left we can see the entrance sign for Tobacco Dock, located at:So right there, just off to the right from the entrance, it's the apartment building: Park Vista Tower.The exact apartment number, i don't know, it's probably somewhere on the door or on the door frame, which can probably be seen one of the times when Sofia or others come to visit Massimo, but since that happened mid 9th episode, i'm not gonna go back to find that clue

John Goerzen: So Many Caring People In This World

When I was a boy and I would see scary things in the news, my mother would say to me, Look for the helpers. You will always find people who are helping. To this day, especially in times of disaster, I remember my mother s words and I am always comforted by realizing that there are still so many helpers so many caring people in this world. Fred Rogers
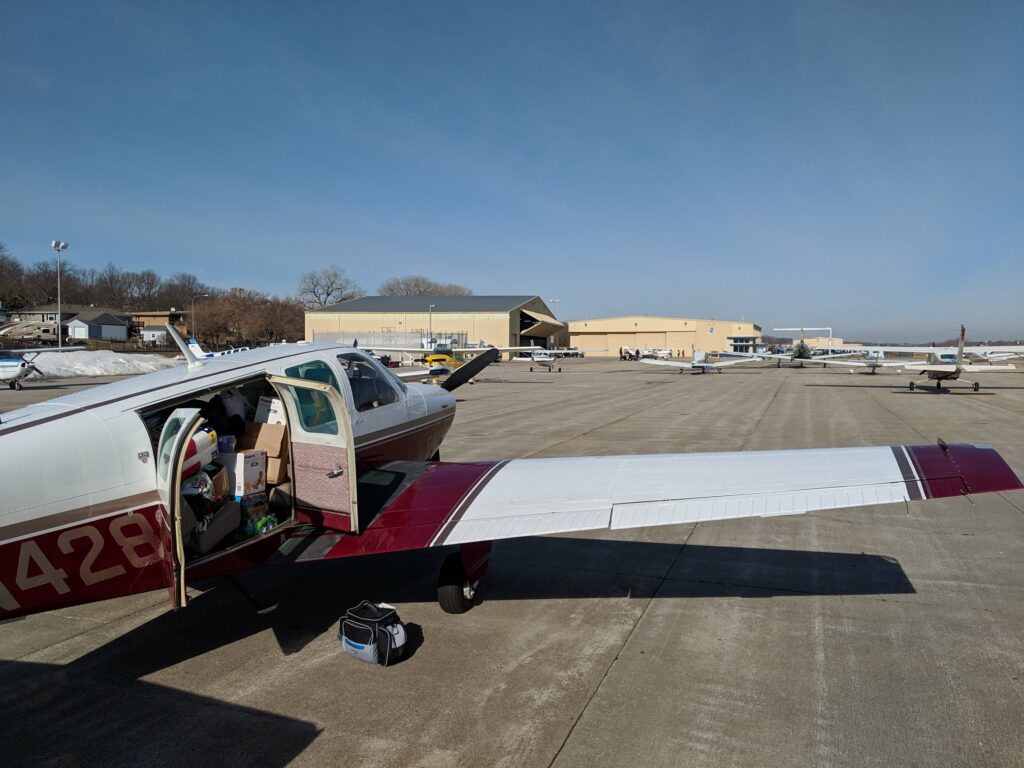
This photo doesn t have amazing lighting or fantastic composition. In fact, it looks ordinary. It s only when you know its story that the beauty shines through. In 2019, Fremont, NE had been cut off by flooding. People were trying to get in and out of the town, and couldn t. The only way in or out was from the small airport. About 50 pilots from Nebraska and Iowa (and me from Kansas) came over to help. Every plane you see here and more that I couldn t fit in the frame was at Millard Airport, Omaha, flying people and supplies into and out of Fremont. Estimates are that we flew over 1000 people and tons of supplies that weekend. All safely. I remember flying the family with a 1-week-old baby that had gone to Omaha for a doctor appointment and then couldn t get home for three days. I remember the elderly couple and their dog that I flew out of Fremont, the former Marine riding in the co-pilot seat next to me, cracking jokes with me as we went. I remember the group of ladies that were laughing as I gave them the required seat belt briefing, the mom with her kids, the man that had to get to work, and packed a few day s supplies in his backpack, unsure when he d be able to get back home. It was the first some had ever been in a plane. There were so many helpers. People all over Omaha brought supplies to Millard airport. Others had just shown up at both airports to help organize and make lists of passengers and match them up with different size planes. Someone at Millard had a trailer and golf cart for supplies. When I d land at Fremont, before I was even out of the plane, highschoolers had already swarmed it and were helping to unload supplies or help passengers out. One time when I got back to Millard, I found lunch: a pizza place had donated pizza for the pilots, and then a restaurant in Fremont did too. With so many extra planes in the sky, Omaha ATC was slammed and still did a fantastic job. I of course took no photos of the people I carried, but I have thought of them often in the last year. This photo is of Millard airport, Omaha, loading up supplies. Look at all these helpers. I think it s one of the most beautiful sights I ve ever seen. Today there are billions of helpers in this world. The obvious ones: the truck drivers, the health care workers, the grocery store workers. And also the non-obvious ones: all the people that are wearing masks, practicing social distancing, forgoing Christmas gatherings, for the good of others, despite the hardship and heartbreak it may cause. If you didn t know the story of this photo, you wouldn t know these planes were all helpers in time of disaster. We don t know the story of all the people we see in our world today, but chances are good that many of them are helpers also. When you know their story, the beauty shines through. May we all be able to see the beauty that still surrounds us this Christmas.

Niels Thykier: Improvements to IntelliJ/PyCharm support for Debian packaging files

I have updated my debpkg plugin for IDEA (e.g. IntelliJ, PyCharm, Android Studios) to v0.0.8. Here are some of the changes since last time I wrote about the plugin. New file types supported Links for URLs and bug closes There are often links in deb822 files or the debian/changelog and as of v0.0.8, the plugin will now highlight them and able you to easily open them via your browser. In the deb822 case, they generally appear in the Homepage field, the Vcs-* fields or the Format field of the debian/copyright field. For the changelog file, they often appear in the form of bug Closes statements such as the #123456 in Closes: #123456 , which is a reference to https://bugs.debian.org/123456. Improvements to debian/control The dependency validator now has per-field knowledge. This enables it to flag dependency relations in the Provides field that uses operators other than = (which is the only operator that is supported in that field). It also knows which fields support build-profile restrictions. It in theory also do Architecture restrictions, but I have not added it among other because it gets a bit spicy around binary packages. (Fun fact, you can have Depends: foo [amd64] but only for arch:any packages.) The plugin now suggests adding a Rules-Requires-Root field to the Source stanza along with a quick fix for adding the field. Admittedly, it was mostly done as exercise for me to learn how to do that kind of feature. Support for machine-readable debian/copyright The plugin now has a dedicated file type for debian/copyright that follows the machine-readable format. It should auto-detect it automatically based on the presence of the Format field being set to https://www.debian.org/doc/packaging-manuals/copyright-format/1.0. Sadly, I have not found the detection reliable in all cases, so you may have to apply it manually. With the copyright format, the plugin now scans the Files fields for common issues like pointing on non-existing paths and invalid escape sequences. When the plugin discovers a path that does not match anything, it highlights the part of the path that cannot be found. As an example, consider the pattern src/foo/data.c and that src/foo exist but data.c does not exist, then the plugin will only flag the data.c part of src/foo/data.c as invalid. The plugin will also suggest a quick fix if you a directory into the Files field to replace it with a directory wildcard (e.g. src/foo -> src/foo/* ), which is how the spec wants you to reference every file beneath a given directory. Finally, when the plugin can identify part of the path, then it will turn it into a link (reference in IDEA lingo). This means that you can CTRL + click on it to jump to the file. As a side-effect, it also provides refactoring assistance for renaming files, where renaming a file will often be automatically reflected in debian/copyright. This use case is admittedly mostly relevant people, who are both upstream and downstream maintainer. Folding support improvement for .dsc/.changes/.buildinfo files The new field types appeared with two cases, where I decided to improve the folding support logic. The first was the GPG signature (if present), which consists of two parts. The top part with is mostly a single line marker but often followed by a GPG armor header (e.g. Hash: SHA512 ) and then the signature blob with related marker lines around it. Both cases are folded into a single marker line by default to reduce their impact on content in the editor view. The second case was the following special-case pattern:
Files:
 <md5> <size> filename
Checksums-Sha256:
 <sha256> <size> filename
In the above example, where there is exactly on file name, those fields will by default now be folded into:
Files: <md5> <size> filename
Checksums-Sha256: <sha256> <size> filename
For all other multi-line fields, the plugin still falls back to a list of known fields to fold by default as in previous versions. Spellchecking improvements The plugin already supported selective spell checking in v0.0.3, where it often omitted spell checking for fields (in deb822 files) where it did not make sense. The spell check feature has been improved by providing a list of known packaging terms/jargo used by many contributors (so autopkgtests is no longer considered a typo). This applies to all file types (probably also those not handled by the plugin as it is just a dictionary). Furthermore, the plugin also attempts discover common patterns (e.g. file names or command arguments) and exempt these from spell checking in the debian/changelog. This also includes manpage references such as foo.1 or foo(1) . It is far from perfect and relies on common patterns to exclude spell checking. Nonetheless, it should reduce the number of false positive considerably. Feedback welcome Please let me know if you run into bugs or would like a particular feature implemented. You can submit bug reports and feature requests in the issue tracker on github.

24 December 2020

Russ Allbery: control-archive 1.9.0

This is the software used to manage the archive of control messages and the Netnews active and newsgroups files at ftp.isc.org. This release switches to gpg1 in order to support older keys and produces better diagnostics when the X-PGP-Sig header is invalid because it's missing the useless version field. It also includes various hierarchy metadata updates, including adding rocksolid.*, removing dictator.* at its maintainer's request, and updating the fr.* key. You can get the latest release from the control-archive distribution page.

John Goerzen: Joyful is the Dark

Joyful is the dark
coolness of the tomb,
waiting for the wonder
of the morning. Never was that midnight
touched by dread and gloom;
darkness was the cradle
of the dawning. Brian Wren
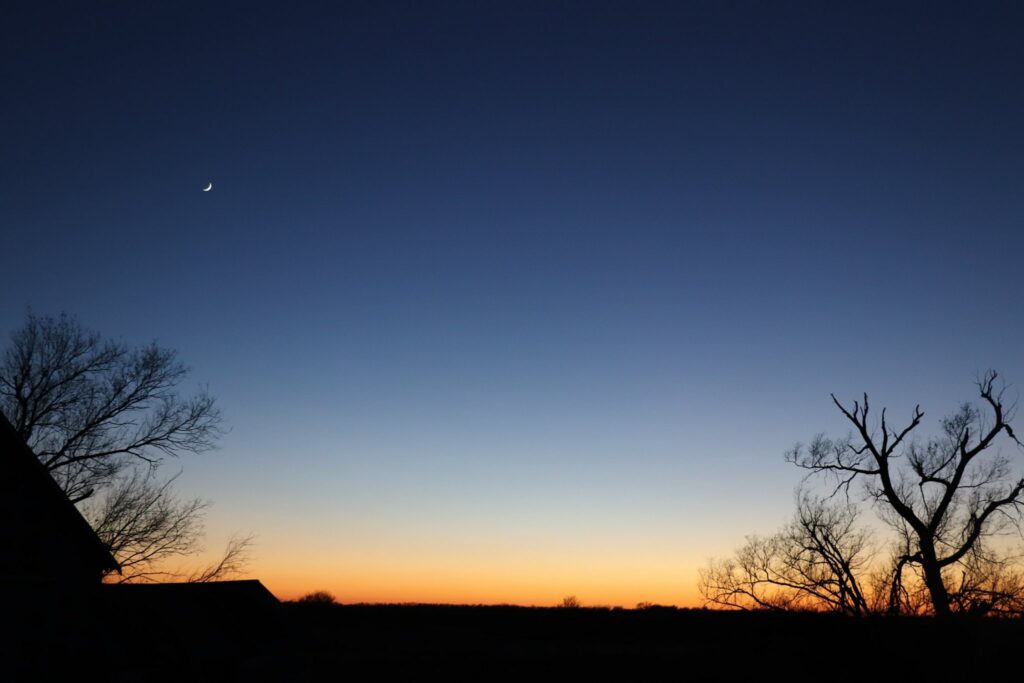
Most of us are not personally experiencing symptoms of a pandemic virus, but with all the changes around us, with all the worries within us, many of us have been touched by dread and gloom. I can find many layers of meaning in this poem. Today I think this poem excerpt reminds us to find the joy where we are, in the moment we are. Are we just waiting for the morning? Or do we take advantage of this pause to gaze up at the beautiful colors of the night? Are we defined by this moment, or do we define it? We are OK right now, so let this time be the cradle of something beautiful. If you haven t noticed the moon in this photo, zoom in. I don t see dread and gloom in this photo. I see color, and hope, and beauty. Rural Kansas, 2017

23 December 2020

Sven Hoexter: Jenkins dynamically parameterized pipelins for terraform execution

Jenkins in the Ops space is in general already painful. Lately the deprecation of the multiple-scms plugin caused some headache, becaue we relied heavily on it to generate pipelines in a Seedjob based on structure inside secondary repositories. We kind of started from scratch now and ship parameterized pipelines defined in Jenkinsfiles in those secondary repositories. Basically that is the way it should be, you store the pipeline definition along with code you'd like to execute. In our case that is mostly terraform and ansible. Problem Directory structure is roughly "stage" -> "project" -> "service". We'd like to have one job pipeline per project, which dynamically reads all service folder names and offers those as available parameters. A service folder is the smallest entity we manage with terraform in a separate state file. Now Jenkins pipelines are by intention limited, but you can add some groovy at will if you whitelist the usage in Jenkins. You have to click through some security though to make it work. Jenkinsfile This is basically a commented version of the Jenkinsfile we copy now around as a template, to be manually adjusted per project.
// Syntax: https://jenkins.io/doc/book/pipeline/syntax/
// project name as we use it in the folder structure and job name
def TfProject = "myproject-I-dev"
// directory relative to the repo checkout inside the jenkins workspace
def jobDirectory = "terraform/dev/$ TfProject "
// informational string to describe the stage or project
def stageEnvDescription = "DEV"
/* Attention please if you rebuild the Jenkins instance consider the following:
- You've to run this job at least *thrice*. It first has to checkout the
repository, then you've to add permisions for the groovy part, and on
the third run you can gather the list of available terraform folder.
- As a safeguard the first first folder name is always the invalid string
"choose-one". That prevents accidential execution of a random project.
- If you add new terraform folder you've to run the "choose-one" dummy rollout so
the dynamic parameters pick up the new folder. */
/* Here we hardcode the path to the correct job workspace on the jenkins host, and
   discover the service folder list. We have to filter it slightly to avoid temporary folders created by Jenkins (like @tmp folders). */
List tffolder = new File("/var/lib/jenkins/jobs/terraform $ TfProject /workspace/$ jobDirectory ").listFiles().findAll   it.isDirectory() && it.name ==~ /(?i)[a-z0-9_-]+/  .sort()
/* ensure the "choose-one" dummy entry is always the first in the list, otherwise
   initial executions might execute something. By default the first parameter is
   used if none is selected */
tffolder.add(0,"choose-one")
pipeline  
    agent any
    /* Show a choice parameter with the service directory list we stored
       above in the variable tffolder */
    parameters  
        choice(name: "TFFOLDER", choices: tffolder)
     
    // Configure logrotation and coloring.
    options  
        buildDiscarder(logRotator(daysToKeepStr: "30", numToKeepStr: "100"))
        ansiColor("xterm")
     
    // Set some variables for terraform to pick up the right service account.
    environment  
        GOOGLE_CLOUD_KEYFILE_JSON = '/var/lib/jenkins/cicd.json'
        GOOGLE_APPLICATION_CREDENTIALS = '/var/lib/jenkins/cicd.json'
     
stages  
    stage('TF Plan')  
    /* Make sure on every stage that we only execute if the
       choice parameter is not the dummy one. Ensures we
       can run the pipeline smoothly for re-reading the
       service directories. */
    when   expression   params.TFFOLDER != "choose-one"    
    steps  
        /* Initialize terraform and generate a plan in the selected
           service folder. */
        dir("$ params.TFFOLDER ")  
        sh 'terraform init -no-color -upgrade=true'
        sh 'terraform plan -no-color -out myplan'
         
        // Read in the repo name we act on for informational output.
        script  
            remoteRepo = sh(returnStdout: true, script: 'git remote get-url origin').trim()
         
        echo "INFO: job *$ JOB_NAME * in *$ params.TFFOLDER * on branch *$ GIT_BRANCH * of repo *$ remoteRepo *"
     
     
    stage('TF Apply')  
    /* Run terraform apply only after manual acknowledgement, we have to
       make sure that the when     condition is actually evaluated before
       the input. Default is input before when. */
    when  
        beforeInput true
        expression   params.TFFOLDER != "choose-one"  
     
    input  
        message "Cowboy would you really like to run **$ JOB_NAME ** in **$ params.TFFOLDER **"
        ok "Apply $ JOB_NAME  to $ stageEnvDescription "
     
    steps  
        dir("$ params.TFFOLDER ")  
        sh 'terraform apply -no-color -input=false myplan'


    post  
            failure  
                // You can also alert to noisy chat platforms on failures if you like.
                echo "job failed"
             
         
job-dsl side of the story Having all those when conditions in the pipeline stages above allows us to create a dependency between successful Seedjob executions and just let that trigger the execution of the pipeline jobs. This is important because the Seedjob execution itself will reset all pipeline jobs, so your dynamic parameters are gone. By making sure we can re-execute the job, and doing that automatically, we still have up to date parameterized pipelines, whenever the Seedjob ran successfully. The job-dsl script looks like this:
import javaposse.jobdsl.dsl.DslScriptLoader;
import javaposse.jobdsl.plugin.JenkinsJobManagement;
import javaposse.jobdsl.plugin.ExecuteDslScripts;
def params = [
    // Defaults are repo: mycorp/admin, branch: master, jenkinsFilename: Jenkinsfile
    pipelineJobs: [
        [name: 'terraform myproject-I-dev', jenkinsFilename: 'terraform/dev/myproject-I-dev/Jenkinsfile', upstream: 'Seedjob'],
        [name: 'terraform myproject-I-prod', jenkinsFilename: 'terraform/prod/myproject-I-prod/Jenkinsfile', upstream: 'Seedjob'],
    ],
]
params.pipelineJobs.each   job ->
    pipelineJob(job.name)  
        definition  
            cpsScm  
                // assume admin and branch master as a default, look for Jenkinsfile
                def repo = job.repo ?: 'mycorp/admin'
                def branch = job.branch ?: 'master'
                def jenkinsFilename = job.jenkinsFilename ?: 'Jenkinsfile'
                scm  
                    git("ssh://git@github.com/$ repo .git", branch)
                 
                scriptPath(jenkinsFilename)
             
         
        properties  
            pipelineTriggers  
                triggers  
                    if(job.upstream)  
                        upstream  
                            upstreamProjects("$ job.upstream ")
                            threshold('SUCCESS')


Disadvantages There are still a bunch of disadvantages you've to consider Jenkins Rebuilds are Painful In general we rebuild our Jenkins instances quite frequently. With the approach outlined here in place, you've to allow the groovy script execution after the first Seedjob execution, and then go through at least another round of run the job, allow permissions, run the job, until it's finally all up and running. Copy around Jenkinsfile Whenever you create a new project you've to copy around Jenkinsfiles for each and every stage and modify the variables at the top accordingly. Keep the Seedjob definitions and Jenkinsfile in Sync You not only have to copy the Jenkinsfile around, but you also have to keep the variables and names in sync with what you define for the Seedjob. Sadly the pipeline env-vars are not available outside of the pipeline when we execute the groovy parts. Kudos This setup was crafted with a lot of help by Michael and Eric.

John Goerzen: O, Sunlight!

O, Sunlight! The most precious gold to be found on Earth. Roman Payne
There is much beauty in this world, much hope, much life. All we need to do is pause, breathe, and take a moment to see it. It might be as simple as the gift of sunlight. I hope you all have moments of sunlight and delight each day. Marion County, KS, April 2013

Jonathan McDowell: Rooting the Tesco Hudl

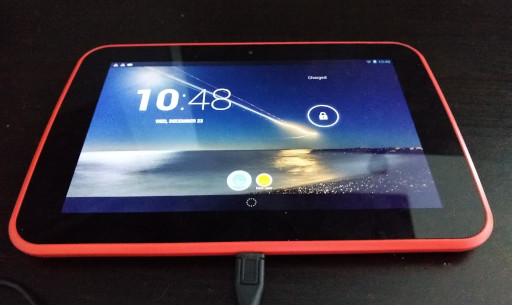
Tesco Hudl I have an original Tesco Hudl - a Rockchip RK3188 based Android tablet. It s somewhat long in the tooth and mine is running Android 4.2.2 (Jelly Bean). As a first step in trying to get it updated a bit I decided to root it and have a poke about. There are plenty of guides for this, but they mostly involve downloading Android apps that look dodgy or don t exist any more. Thankfully the bootloader is unlocked, so I did it the hard (manual) way from a Debian 10 (Buster) box. I doubt this is useful to many folk, but I thought I d write it up. As you d expect follow this at your own risk; there is the potential to brick the Hudl. First, enable developer mode on the Hudl (so we can adb in). Open the Settings app, scroll down to the bottom and click About Tablet , scroll down to the bottom and tap Build number 7 times, at which point it will tell you You are now a developer! . Go back to the main settings menu and just above About Tablet there will now be a Developer options entry. Click it, then make sure the box beside USB debugging is ticked. Now you need to install the appropriate tools on your Debian box. That should be:
$ sudo apt install adb rkflashtool
We also need to download a suitable su tool. I lazily went for the prebuilt SuperSU Root:
$ mkdir hudl-root
$ cd hudl-root
$ wget https://supersuroot.org/downloads/SuperSU-v2.79-201612051815.zip
$ unzip SuperSU-v2.79-201612051815.zip
2.82 is the latest version but has problems on Jelly Bean; the device will end up not properly booting. Hook the Hudl up to your machine with a suitable USB cable and you ll now be able to get a shell on it:
$ adb shell
* daemon not running; starting now at tcp:5037
* daemon started successfully
shell@android:/ $
Ctrl-D will quit the shell and return you back to the local prompt. Next step is to reboot into the Rockchip bootloader, and use that to download the system partition (just over 1G in size)
$ adb reboot bootloader
$ sudo rkflashtool r system > system.img
rkflashtool: info: rkflashtool v5.2
rkflashtool: info: Detected RK3188...
rkflashtool: info: interface claimed
rkflashtool: info: working with partition: system
rkflashtool: info: found offset: 0x00142000
rkflashtool: info: found size: 0x00200000
rkflashtool: info: reading flash memory at offset 0x00341fe0... Done!
We now have a system.img file which represents the system partition of the device. We can mount that and copy over the su binary and SuperSU apk.
$ sudo mount -o loop system.img /mnt
$ sudo cp common/Superuser.apk /mnt/app/
$ sudo cp armv7/su /mnt/xbin/
$ sudo chmod +sx /mnt/xbin/su
$ sudo umount /mnt
Finally we can write this image back to the device, reboot and once the reboot has completed use adb to connect and su to root. SuperSU might pop up a dialog on the tablet asking you to ok the action (and possibly indicate it needs to do a fixup of the installation):
$ sudo rkflashtool w system < system.img
$ sudo rkflashtool b
$ adb shell
shell@android:/ $ su -
root@android:/ #

John Goerzen: How & Why To Use Airgapped Backups

A good backup strategy needs to consider various threats to the integrity of data. For instance: It s that last one that is of particular interest today. A lot of backup strategies are such that if a user (or administrator) has their local account or network compromised, their backups could very well be destroyed as well. For instance, do you ssh from the account being backed up to the system holding the backups? Or rsync using a keypair stored on it? Or access S3 buckets, etc? It is trivially easy in many of these schemes to totally ruin cloud-based backups, or even some other schemes. rsync can be run with delete (and often is, to prune remotes), S3 buckets can be deleted, etc. And even if you try to lock down an over-network backup to be append-only, still there are vectors for attack (ssh credentials, OpenSSL bugs, etc). In this post, I try to explore how we can protect against them and still retain some modern conveniences. A backup scheme also needs to make a balance between: My story so far About 20 years ago, I had an Exabyte tape drive, with the amazing capacity of 7GB per tape! Eventually as disk prices fell, I had external disks plugged in to a server, and would periodically rotate them offsite. I ve also had various combinations of partial or complete offsite copies over the Internet as well. I have around 6TB of data to back up (after compression), a figure that is growing somewhat rapidly as I digitize some old family recordings and videos. Since I last wrote about backups 5 years ago, my scheme has been largely unchanged; at present I use ZFS for local and to-disk backups and borg for the copies over the Internet. Let s take a look at some options that could make this better. Tape The original airgapped backup. You back up to a tape, then you take the (fairly cheap) tape out of the drive and put in another one. In cost per GB, tape is probably the cheapest medium out there. But of course it has its drawbacks. Let s start with cost. To get a drive that can handle capacities of what I d be needing, at least LTO-6 (2.5TB per tape) would be needed, if not LTO-7 (6TB). New, these drives cost several thousand dollars, plus they need LVD SCSI or Fibre Channel cards. You re not going to be hanging one off a Raspberry Pi; these things need a real server with enterprise-style connectivity. If you re particularly lucky, you might find an LTO-6 drive for as low as $500 on eBay. Then there are tapes. A 10-pack of LTO-6 tapes runs more than $200, and provides a total capacity of 25TB sufficient for these needs (note that, of course, you need to have at least double the actual space of the data, to account for multiple full backups in a set). A 5-pack of LTO-7 tapes is a little more expensive, while providing more storage. So all-in, this is going to be in the best possible scenario nearly $1000, and possibly a lot more. For a large company with many TB of storage, the initial costs can be defrayed due to the cheaper media, but for a home user, not so much. Consider that 8TB hard drives can be found for $150 $200. A pair of them (for redundancy) would run $300-400, and then you have all the other benefits of disk (quicker access, etc.) Plus they can be driven by something as cheap as a Raspberry Pi. Fancier tape setups involve auto-changers, but then you re not really airgapped, are you? (If you leave all your tapes in the changer, they can generally be selected and overwritten, barring things like hardware WORM). As useful as tape is, for this project, it would simply be way more expensive than disk-based options. Fundamentals of disk-based airgapping The fundamental thing we need to address with disk-based airgapping is that the machines being backed up have no real-time contact with the backup storage system. This rules out most solutions out there, that want to sync by comparing local state with remote state. If one is willing to throw storage efficiency out the window maybe practical for very small data sets one could just send a full backup daily. But in reality, what is more likely needed is a way to store a local proxy for the remote state. Then a runner device (a USB stick, disk, etc) could be plugged into the network, filled with queued data, then plugged into the backup system to have the data dequeued and processed. Some may be tempted to short-circuit this and just plug external disks into a backup system. I ve done that for a long time. This is, however, a risk, because it makes those disks vulnerable to whatever may be attacking the local system (anything from lightning to ransomware). ZFS ZFS is, it should be no surprise, particularly well suited for this. zfs send/receive can send an incremental stream that represents a delta between two checkpoints (snapshots or bookmarks) on a filesystem. It can do this very efficiently, much more so than walking an entire filesystem tree. Additionally, with the recent addition of ZFS crypto to ZFS on Linux, the replication stream can optionally reflect the encrypted data. Yes, as long as you don t need to mount them, you can mostly work with ZFS datasets on an encrypted basis, and can directly tell zfs send to just send the encrypted data instead of the decrypted data. The downside of ZFS is the resource requirements at the destination, which in terms of RAM are higher than most of the older Raspberry Pi-style devices. Still, one could perhaps just save off zfs send streams and restore them later if need be, but that implies a periodic resend of a full stream, an inefficient operation. dedpulicating software such as borg could be used on those streams (though with less effectiveness if they re encrypted). Tar Perhaps surprisingly, tar in listed incremental mode can solve this problem for non-ZFS users. It will keep a local cache of the state of the filesystem as of the time of the last run of tar, and can generate new tarballs that reflect the changes since the previous run (even deletions). This can achieve a similar result to the ZFS send/receive, though in a much less elegant way. Bacula / Bareos Bacula (and its fork Bareos) both have support for a FIFO destination. Theoretically this could be used to queue of data for transfer to the airgapped machine. This support is very poorly documented in both and is rumored to have bitrotted, however. rdiff and xdelta rdiff and xdelta can be used as sort of a non-real-time rsync, at least on a per-file basis. Theoretically, one could generate a full backup (with tar, ZFS send, or whatever), take an rdiff signature, and send over the file while keeping the signature. On the next run, another full backup is piped into rdiff, and on the basis of the signature file of the old and the new data, it produces a binary patch that can be queued for the backup target to update its stored copy of the file. This leaves history preservation as an exercise to be undertaken on the backup target. It may not necessarily be easy and may not be efficient. rsync batches rsync can be used to compute a delta between two directory trees and express this as a single-file batch that can be processed by a remote rsync. Unfortunately this implies the sender must always keep an old tree around (barring a solution such as ZFS snapshots) in order to compute the delta, and of course it still implies the need for history processing on the remote. Getting the Data There OK, so you ve got an airgapped system, some sort of runner device for your sneakernet (USB stick, hard drive, etc). Now what? Obviously you could just copy data on the runner and move it back off at the backup target. But a tool like NNCP (sort of a modernized UUCP) offer a lot of help in automating the process, returning error reports, etc. NNCP can be used online over TCP, over reliable serial links, over ssh, with offline onion routing via intermediaries or directly, etc. Imagine having an airgapped machine at a different location you go to frequently (workplace, friend, etc). Before leaving, you put a USB stick in your pocket. When you get there, you pop it in. It s despooled and processed while you want, and return emails or whatever are queued up to be sent when you get back home. Not bad, eh? Future installment I m going to try some of these approaches and report back on my experiences in the next few weeks.

Russ Allbery: Review: Anti-Social

Review: Anti-Social, by Nick Pettigrew
Publisher: Century
Copyright: 2020
ISBN: 1-4735-7639-3
Format: Kindle
Pages: 375
Nick Pettigrew was an anti-social behavior officer for council housing for over a decade. This book is a diary of one year in the life of that job. According to the author, the dates, names, and some of the identifying details have been changed but not exaggerated. While it's hard to verify that, and I'm sure a few of the stories have been tweaked to make better narratives, it has a messiness and chaos of half-resolved drama mixed with mundane office tedium that makes it ring true. The subject matter requires some explanation for US readers. Council housing is the UK's version of what the US would call public housing or "the projects," although it's a far larger percentage of the housing stock in the UK than it is in the US. These are buildings built by the government and run by local governments or non-profits to provide housing to working class and poor people at reduced cost compared to the private market. As in the US, new council housing construction has dropped off dramatically; as in the US, a bunch of it has been privatized, although in the UK the Right to Buy law at least sells the housing to the people living in it, as opposed to slumlords. The 1998 UK Crime and Disorder Act collects under anti-social behavior a bunch of low-grade irritations that in the US would fall under public nuisance laws, noise ordinances, and other vague misdemeanors like "creating a public disturbance": essentially, all the irritating and obnoxious things that people subject their neighbors to, but which fall short of obvious criminal behavior like theft or assault. As Pettigrew puts it:
"I just don't want to hear the word 'cunt' shouted repeatedly at 3am every night any more. I don't think that's unreasonable."
That law required the organizations managing council estates to have a procedure to deal with anti-social behavior, and thus the job of an anti-social behavior officer was created. In the US, these sorts of problems are dealt with by the local police, which is a little like trying to get rid of a raccoon by running it over with a balky, thirty-year-old car. The best outcome is that the raccoon gets freaked out by your efforts to get the car to start and leaves. The worst outcome is that you accidentally run over your neighbor's kid while aiming for the raccoon. Either way, neither you nor the car nor your neighbors are going to be happy about the process. An anti-social behavior officer is someone with some authority to do things like install cameras, tell people who don't live somewhere that they need to stop coming there, and start eviction proceedings, but who doesn't carry guns, can't arrest people, and enforces those rules when necessary via court proceedings or calling the police. In other words, it's one of the types of alternative responders whose job is to solve problems rather than stop crimes that we've been talking about in the United States. And although Pettigrew is quite grumpy and cynical about his job (for very understandable reasons explained in this book), my takeaway from another country with even worse problems is that the system sort of works. It's underfunded and poorly managed and nebulous and sometimes very sad, but it also achieves some of what it sets out to do, and you can see the outlines of a better system beneath it. My favorite thing about this book is that it forces the reader to grapple with the actual job in all its messiness, rather than our ideals of what we want the job to be. For example, if you're going to hire a bunch of people to do this job, you need some way to figure out whether they're any good at it, but it's not obvious how to measure success.
One infuriating KPI we're measured on is the final question a resident is asked once their case is closed: "Are you happy with the outcome of your case?" Because unless you evict the problem neighbor within a fortnight, erect a security wall around the complainant's house manned by armed guards, and bake them a cake, the answer will almost certainly be no.
Pettigrew has a background in comedy so he's sarcastically funny rather than strident or didactic, which for me was just the tone I needed to enjoy reading this enough to think deeply about it. The thing that most surprised me, even though it probably shouldn't, was just how many of the problems Pettigrew had to deal with stemmed from drugs. My guess is that a good 75% of the issues he described were a direct result of someone dealing drugs, growing drugs, stealing things to buy drugs, throwing parties with druggie friends, doing bizarre and dangerous things because they were on drugs, not taking care of their property because they were too busy doing drugs, or letting their property be taken over by other people doing or selling drugs. It's just never-ending. The case load is clearly made worse by chronic understaffing and underfunding, and spending more money on giving people more assistance is part of any reasonable solution, but so is reducing the demand. If the pattern of complaints in the US is at all similar (and I bet it is), it's no wonder that the police perceive drugs as central to their job. Pettigrew talks about this at some length in the epilogue, and I think one of his conclusions is worth quoting here:
Years of interacting with class A drug users has shown me that they really don't want to be out hustling to make enough money for their next score of diluted heroin. They want to sit at home, take drugs and when those drugs wear off, take some more. You may view this as a wasted life, and you may well be right, but here's the thing: they are going to do this anyway, whether we decide to criminalize them or not. If, after a lengthy period of honest, mature drug education across the country via schools, further education, government advertising and so on, class A drugs were made legally available on prescription to adults via pharmacies, the vast majority of users would pick up their prescriptions, go home, take their drugs and leave everyone else alone. They couldn't be arsed to break into your car if they didn't have to.
The decriminalization argument is a lot larger than the space of this book review, so I won't get into it further, except to say that if you think that conclusion sounds unreasonable or dangerous or destructive to society, consider reading this book. One of the things that becomes obvious from Pettigrew's diary of incidents is that most people just want to feel safe, and a truly stunning amount of crime and anti-social behavior that makes them feel not safe is a direct or indirect result of people trying to get drugs or to get money to get drugs. The other pattern that's obvious from this book (and obvious from most writing by anyone involved in the justice system) is that the system doesn't really work.
The best way to describe going to court is that it's like paying a visit to a run-down hospital where nobody gets better.
Some of that is because it's not set up to solve problems, and a lot of that is because solving problems is a lot more expensive than we want to admit and we don't want to pony up the resources. I'm probably making this book sound hopelessly depressing, but it's not. It's angry and cynical, but it's also very funny (particularly if you like sarcasm), extremely quotable, insightful, and deeply empathetic. There are people trying their best to help other people despite a system that doesn't reward them for doing so, and surprisingly often they manage to do so. The path to helping more people isn't even that difficult to find. The epilogue of this book is full of solid and straightforward ideas that don't require some novel insight into humanity, just a bunch of hard work. And, while reading about the work of helping people and being exasperated by people, you'll also get to laugh at the bits of office nonsense that are universal.
The old form for monthly one-to-ones used to have two questions "What did you do over the last month?" and "What do you plan to do in the next month?" and my line manager at the time seemed unimpressed when I answered "my job" to both.
I loved this book. It was one of my favorite random finds of the year, and, at least judging from how difficult it is to find in Amazon search results, it's not gotten enough attention in the United States. Highly recommended. Rating: 9 out of 10

John Goerzen: Every Storm Runs Out Of Rain

Every storm runs out of rain. Maya Angelou
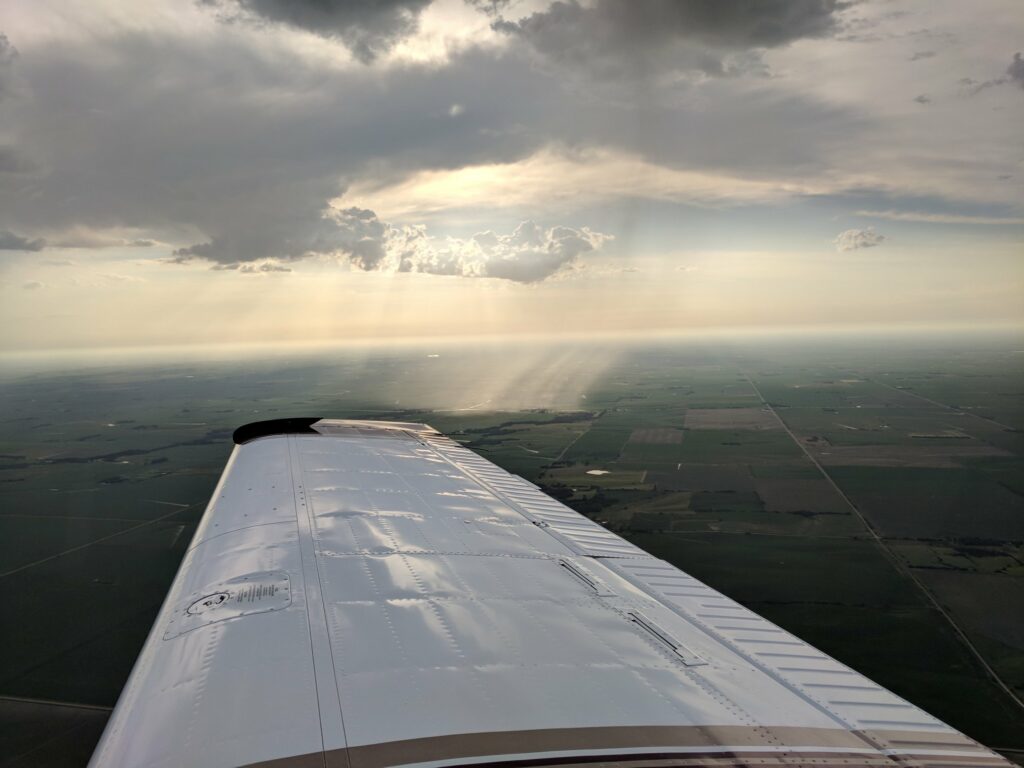
There are a lot of rain clouds in life these days. May we all remember that days like this one are behind us and also ahead of us. Every storm runs out of rain.
That was the start of a series of photos from my collection & quotes I shared with friends during the initial lockdown in spring. I ll be sharing some here. And here we all are, still dealing with this and it s more severe in a lot of ways. One of my colleagues won t be able to see his parents this Christmas for the first time in over 40 years. But this storm will run out rain. And look how the scene changed, in just a few minutes. This is coming!

22 December 2020

Andrej Shadura: Vendoring Rust dependencies for a Debian derivative

Recently, I needed to package a Rust crate libslirp for a Apertis, a Debian derivative. libslirp is used by the newly release UML backend of debos, our Debian image build tool. Unfortunately, this crate hasn t yet been properly packaged for Debian proper, so I could not simply pull the packaging from Debian. Even worse, its build dependencies haven t all been packaged yet. Most importantly, I have only uploaded zbus to Debian today, and at that time none of its dependencies were in Debian either. Another issue with this were that each crate is packaged for Debian as a separate package, making the process a bit more tricky since I d need to import all of the crates into Apertis separately. Doing that takes time and is further complicated by the CI loop we re using which requires the full build process to complete for a package before a pipeline a dependent package can run. Having all that considered, I took a shortcut: I vendored all the build dependencies with the package itself, and here s how. I started with debcargo-conf, where the not-yet-complete packaging lives. With debcargo, I generated the source package as if I were to upload to Debian. Since I ll be vendoring the dependencies, I have removed most of the Rust dependencies and replaced them with those extra dependencies needed by those crates. So, I replaced this:
Build-Depends: debhelper (>= 12),
 dh-cargo (>= 24),
 cargo:native,
 rustc:native,
 libstd-rust-dev,
 librust-enumflags2-0.6+default-dev (>= 0.6.4-~~),
 librust-ipnetwork-0.17+default-dev,
 librust-lazy-static-1+default-dev (>= 1.4-~~),
 librust-libc-0.2+default-dev,
 librust-libslirp-sys-4+default-dev (>= 4.2.0-~~),
 librust-libsystemd-0.2+default-dev,
 librust-mio-0.6+default-dev,
 librust-mio-extras-2+default-dev (>= 2.0.5-~~),
 librust-nix-0.17+default-dev,
 librust-slab-0.4+default-dev,
 librust-structopt-0.3+default-dev,
 librust-url-2+default-dev (>= 2.1-~~),
 librust-zbus-1+default-dev,
 librust-zvariant-2+default-dev
By this:
Build-Depends: debhelper (>= 12),
 dh-cargo (>= 17),
 cargo:native,
 rustc:native,
 libstd-rust-dev,
 pkg-config,
 libglib2.0-dev,
 libslirp-dev
I wanted to keep the delta to the future Debian package at a bare minimum, so I kept the original dh-cargo build process, only making sure the vendored dependencies are found in the right place. The cleanest approach in my view was to use the fact that the 3.0 (quilt) source format allows multiple original tarballs: the main tarball would be the same orig tarball as in Debian, and an extra tarball would contain the vendored code. When we sync with Debian, the extra tarball would be dropped, just as the adjustments to the debian/rules. To generate the vendor tarball, I added this to the rules file:
include /usr/share/dpkg/pkg-info.mk
vendor:
        -[ -d vendor ] && rm -rf vendor
        rm -rf Cargo.lock
        cargo vendor
        tar Jcf ../$(DEB_SOURCE)_$(DEB_VERSION_UPSTREAM).orig-vendor.tar.xz vendor/
.PHONY: vendor
This target, being run manually and not as part of the build process, download the latest dependencies satisfying the requirements in Cargo.toml and rolls them into a vendor tarball. Now, to make dh-cargo use the vendored code, we need to link it into the right place. dh-cargo creates a Cargo registry tree in a subdirectly under debian/ where it symlinks crates from the Rust development packages. This extra code makes sure the vendored dependencies are available there too:
override_dh_auto_configure:
        dh_auto_configure $@
        for d in vendor/* ; \
        do \
                [ -L debian/cargo_registry/$$(basename $$d) ] && rm debian/cargo_registry/$$(basename $$d) ; \
                ln -rs $$d debian/cargo_registry ; \
        done
An important thing here is that if the build happens on a non-clean system, dh-cargo may have symlinked a system crate already installed so we need to remove that symlink and replace it by ours. We build packages in clean chroots, so this is not that important, otherwise for reproducibility reasons it would be better to create the registry directory from scratch. The final package can be found at the Apertis GitLab.

Jan Wagner: Call for testing: monitoring-plugins 2.3 in experimental

As announced recently I prepared a monitoring-plugins 2.3 package for experimental. If there is enough positive feedback until 12th January 2021, I intend to upload this into unstable targeted for Debian Bullseye.

Happy testing.

Julien Danjou: I am a Software Engineer and I am in Charge

I am a Software Engineer and I am in ChargeFifteen years have passed since I started my career in IT which is quite some time. I've been playing with computers for 25 years now, which makes me quite knowledgeable about the field, for sure.However, while I was fully prepared to bargain with computers, I was not prepared to do so with humans. The whole career management thing was unknown to me. I had no useful skills to navigate within the enterprise organization. I had to learn the ropes the hard way, failing along the way. It hurt.Almost ten years ago, I had the chance to meet a new colleague Alexis Monville. Alexis was a team facilitator, and I started to work with him on many non-technical levels. He taught me a lot about agility and team organization. Working on this set of new skills changed how I envisioned my work and how I fit into the company.
I am a Software Engineer and I am in ChargeAlexis Monville
I worked on those aspects of my job because I decided to be in charge of my career rather than keeping things boring. That was one of the best decisions I ever made. Growing the social aspect of my profession allowed me to develop and find aspiring jobs and missions.Getting to that point takes a lot of time and effort, and it's pretty hard to do it alone. My friend Alexis wrote an excellent book titled I am a Software Engineer and I am in Charge. I'm proud to have been the first reviewer the book before it was released a few weeks ago.Many developers out there are stuck in a place where they are not excited by their colleagues' work and whose managers do not appropriately recognize their achievement. It would be best for them if they did something about that.
I am a Software Engineer and I am in ChargeThe book!
This book is an excellent piece for engineers who wants to break the cycle of frustration. It covers many situations I encountered across my professional life those last years, giving good insights into how to solve them.To paraphrase Alexis, the answers to your career management problems are not on StackOverflow they're not technical issues. However, you can still solve them with the right tools. That's where I am a Software Engineer and I am in Charge shines. It gives you leads, solutions, and exercise to get out of this kind of situation. It helps increase your impact and satisfaction at work.I love this book, and I wish I had access to it years ago. Developing technical leadership is not easy and requires a mindset shift. Having a way to bootstrap yourself with this is a luxury.If you're a software engineer at the beginning of your career or struggling with your current professional situation, I profoundly recommend reading this book! You'll get a fast track on your career, for sure.
I am a Software Engineer and I am in Charge

Joachim Breitner: Don t think, just defunctionalize

TL;DR: CPS-conversion and defunctionalization can help you to come up with a constant-stack algorithm. Update: Turns out I inadvertedly plagiarized the talk The Best Refactoring You ve Never Heard Of by James Koppel. Please consider this a form of sincere flattery.

The starting point Today, I ll take you on a another little walk through the land of program transformations. Let s begin with a simple binary tree, with value of unknown type in the leaves, as well as the canonical map function:
data T a = L a   B (T a) (T a)
map1 :: (a -> b) -> T a -> T b
map1 f (L x) = L (f x)
map1 f (B t1 t2) = B (map1 f t1) (map1 f t2)
As you can see, this map function is using the program stack as it traverses the tree. Our goal is now to come up with a map function that does not use the stack! Why? Good question! In Haskell, there wouldn t be a strong need for this, as the Haskell stack is allocated on the heap, just like your normal data, so there is plenty of stack space. But in other languages or environments, the stack space may have a hard limit, and it may be advised to not use unbounded stack space. That aside, it s a fun exercise, and that s sufficient reason for me. (In the following, I assume that tail-calls, i.e. those where a function end with another function call, but without modifying its result, do not actually use stack space. Once all recursive function calls are tail calls, the code is equivalent to an imperative loop, as we will see.)

Think? We could now just stare at the problem (rather the code), and try to come up with a solution directly. We d probably think ok, as I go through the tree, I have to remember all the nodes above me so I need a list of those nodes and for each of these nodes, I also need to remember whether I am currently processing the left child, and yet have to look at the right one, or whether I am done with the left child so what do I have to remember about the current node ? ah, my brain spins already. Maybe eventually I figure it out, but why think when we can derive the solution? So let s start with above map1, and rewrite it, in several, mechanical, steps into a stack-less, tail-recursive solution.

Go! Before we set out, let me rewrite the map function using a local go helper, as follows:
map2 :: forall a b. (a -> b) -> T a -> T b
map2 f t = go t
  where
    go :: T a -> T b
    go (L x) = L (f x)
    go (B t1 t2) = B (go t1) (go t2)
This transformation (effectively the static argument transformation ) has the nice advantage that we do not have to pass f around all the time, and that when we copy the function, I only have to change the top-level name, but not the names of the inner functions. Also, I find it more aesthetically pleasing.

CPS A blunt, effective tool to turn code that is not yet using tail-calls into code that only uses tail-calls is use continuation-passing style. If we have a function of type -> t, we turn it into a function of type -> (t -> r) -> r, where r is the type of the result we want at the very end. This means the function now receives an extra argument, often named k for continuation, and instead of returning some x, the function calls k x. We can apply this to our go function. Here, both t and r happen to be T b; the type of finished trees:
map3 :: forall a b. (a -> b) -> T a -> T b
map3 f t = go t (\r -> r)
  where
    go :: T a -> (T b -> T b) -> T b
    go (L x) k  = k (L (f x))
    go (B t1 t2) k  = go t1 (\r1 -> go t2 (\r2 -> k (B r1 r2)))
Note that when initially call go, we pass the identity function (\r -> r) as the initial continuation. Alas, suddenly all function calls are in tail position, and this codes does not use stack space! Technically, we are done, although it is not quite satisfying; all these lambdas floating around obscure the meaning of the code, are maybe a bit slow to execute, and also, we didn t really learn much yet. This is certainly not the code we would have writing after thinking hard .

Defunctionalization So let s continue rewriting the code to something prettier, simpler. Something that does not use lambdas like this. Again, there is a mechanical technique that can help it. It likely won't make the code prettier, but it will get rid of the lambdas, so let s do that an clean up later. The technique is called defunctionalization (because it replaces functional values by plain data values), and can be seen as a form of refinement. Note that we pass around vales of type (T b -> T b), but we certainly don t mean the full type (T b -> T b). Instead, only very specific values of that type occur in our program, So let us replace (T b -> T b) with a data type that contains representatives of just the values we actually use.
  1. We find at all values of type (T b -> T b). These are:
    • (\r -> r)
    • (\r1 -> go t2 (\r2 -> k (B r1 r2)))
    • (\r2 -> k (B r1 r2))
  2. We create a datatype with one constructor for each of these:
     data K = I   K1   K2
    (This is not complete yet.)
  3. We introduce an interpretation function that turns a K back into a (T b -> T b):
    eval :: K -> (T b -> T b)
    eval = (* TBD *)
  4. In the function go, instead of taking a parameter of type (T b -> T b), we take a K. And when we actually use the continuation, we have to turn the K back to the function using eval:
    go :: T a -> K a b -> T b
    go (L x) k  = eval k (L (f x))
    go (B t1 t2) k = go t1 K1
    We also do this to the code fragments identified in the first step; these become:
    • (\r -> r)
    • (\r1 -> go t2 K2)
    • (\r2 -> eval k (B r1 r2))
  5. Now we complete the eval function: For each constructor, we simply map it to the corresponding lambda from step 1:
    eval :: K -> (T b -> T b)
    eval I = (\r -> r)
    eval K1 = (\r1 -> go t2 K2)
    eval K2 = (\r2 -> eval k (B r1 r2))
  6. This doesn t quite work yet: We have variables on the right hand side that are not bound (t2, r1, k). So let s add them to the constructors K1 and K2 as needed. This also changes the type K itself; it now needs to take type parameters.
This leads us to the following code:
data K a b
  = I
    K1 (T a) (K a b)
    K2 (T b) (K a b)
map4 :: forall a b. (a -> b) -> T a -> T b
map4 f t = go t I
  where
    go :: T a -> K a b -> T b
    go (L x) k  = eval k (L (f x))
    go (B t1 t2) k  = go t1 (K1 t2 k)
    eval :: K a b -> (T b -> T b)
    eval I = (\r -> r)
    eval (K1 t2 k) = (\r1 -> go t2 (K2 r1 k))
    eval (K2 r1 k) = (\r2 -> eval k (B r1 r2))
Not really cleaner or prettier, but everything is still tail-recursive, and we are now working with plain data.

We like lists To clean it up a little bit, we can notice that the K data type really is just a list of values, where the values are either T a or T b. We do not need a custom data type for this! Instead of our K, we can just use the following, built from standard data types:
type K' a b = [Either (T a) (T b)]
Now I replace I with [], K1 t2 k with Left t2 : k and K2 r1 k with Right r1 : k. I also, very suggestively, rename go to down and eval to up:
map5 :: forall a b. (a -> b) -> T a -> T b
map5 f t = down t []
  where
    down :: T a -> K' a b -> T b
    down (L x) k  = up k (L (f x))
    down (B t1 t2) k  = down t1 (Left t2 : k)
    up :: K' a b -> T b -> T b
    up [] r = r
    up (Left  t2 : k) r1 = down t2 (Right r1 : k)
    up (Right r1 : k) r2 = up k (B r1 r2)
At this point, the code suddenly makes more sense again. In fact, I can try to verbalize it:
As we traverse the tree, we have to remember for all parent nodes, whether there is still something Left to do when we come back to it (so we remember a T a), or if we are done with that (so we have a T b). This is the list K' a b. We begin to go down the left of the tree (noting that the right siblings are still left to do), until we hit a leaf. We transform the leaf, and then go up. If we go up and hit the root, we are done. Else, if we go up and there is something Left to do, we remember the subtree that we just processed (as that is already in the Right form), and go down the other subtree. But if we go up and there is nothing Left to do, we put the two subtrees together and continue going up.
Quite neat!

The imperative loop At this point we could stop: the code is pretty, makes sense, and has the properties we want. But let s turn the dial a bit further and try to make it an imperative loop. We know that if we have a single tail-recursive function, then that s equivalent to a loop, with the function s parameter turning into mutable variables. But we have two functions! It turns out that if you have two functions a -> r and b -> r that have the same return type (which they necessarily have here, since we CPS-converted them further up), then those two functions are equivalent to a single function taking a or b , i.e. Either a b -> r. This really nothing else than the high-school level algebra rule of ra rb = ra + b. So (after reordering the arguments of down to put T b first) we can rewrite the code as
map6 :: forall a b. (a -> b) -> T a -> T b
map6 f t = go (Left t) []
  where
    go :: Either (T a) (T b) -> K' a b -> T b
    go (Left (L x))     k        = go (Right (L (f x))) k
    go (Left (B t1 t2)) k        = go (Left t1) (Left t2 : k)
    go (Right r)  []             = r
    go (Right r1) (Left  t2 : k) = go (Left t2) (Right r1 : k)
    go (Right r2) (Right r1 : k) = go (Right (B r1 r2)) k
Do you see the loop yet? If not, maybe it helps to compare it with the following equivalent imperative looking pseudo-code:
mapLoop :: forall a b. (a -> b) -> T a -> T b
mapLoop f t  
  var node = Left t;
  var parents = [];
  while (true)  
    switch (node)  
      Left (L x) -> node := Right (L (f x))
      Left (B t1 t2) -> node := Left t1; parents.push(Left t2)
      Right r1 ->  
        if (parents.len() == 0)  
          return r1;
          else  
          switch (parents.pop())  
            Left t2  -> node := Left t2; parents.push(Right r1);
            Right r2 -> node := Right (B r1 r2)


Conclusion I find it enlightening to see how apparently very different approaches to a problem (recursive, lazy functions and imperative loops) are connected by a series of rather mechanical transformations. When refactoring code, it is helpful to see if one can conceptualize the refactoring as one of those mechanical steps (refinement, type equivalences, defunctionalization, cps conversion etc.) If you liked this post, you might enjoy my talk The many faces of isOrderedTree, which I have presented at MuniHac 2019 and Haskell Love 2020.

Norbert Preining: Debian KDE Status for Bullseye

A long journey has come to nice finish. 9 month ago I switched to KDE/Plasma, and started to package newer versions of it than available in Debian. Since then I have packaged every single version of Plasma, the KDE frameworks, and KDE Apps and made them available for Debian/unstable and Debian/testing via the OBS build server. Today, finally, I have uploaded Frameworks 5.77 and Plasma 5.20.4 to unstable, the end of a long story. Despite some initial disagreements with the Debian Qt/KDE Team, we found a modus vivendi, and since some months now I am member of the team and working together with the rest to get an uptodate KDE/Plasma system into Debian/bullseye. Thanks to everyone involved! The last weeks we have also worked on updating many of the KDE/Apps packages to the latest release 20.12.0, which means that as of now, Debian/unstable contains the most recent versions of KDE Frameworks, KDE Plasma, and of most KDE Apps. Thanks goes to all the team members, in particular to (in alphabetic order) Aur lien, Patrick, Pino, Sandro, and Scarlett for their work, and to all the testers and bug reporters. The current status is also more or less what we plan to get into Debian/Bullseye. An update to Frameworks 5.78 and Plasma 5.20.5 is still possible, but not decided by now. Concerning my OBS packages: they are mostly superseeded by now, and all but the KDE Apps package can be removed from the apt sources. The only remaining archive of interest is
deb https://download.opensuse.org/repositories/home:/npreining:/debian-kde:/apps2012/Debian_Unstable/ ./
and the same with Testing instead of Unstable for Debian/testing. For those adventurous, there is also the digikam-beta repository That s it. Have a nice Christmas, if you celebrate it, and a good start into a hopefully better 2021! Enjoy.

21 December 2020

Chris Lamb: Interview: Reproducibility and the future of free software

I recently took part in an interview with Vladimir Bejdo, an intern at the Software Freedom Conservancy, in order to talk about the Reproducible Builds project, my own participation in software freedom, the importance of reproducibility in software development and to have a brief discussion on the issues facing free software as a whole:
VB: To start off with, it might be useful to first ask you this how would you relate the importance of reproducibility to a user who is non-technical? CL: I sometimes use the analogy of the food supply chain to quickly relate our work to non-technical audiences. The multiple stages of how our food reaches our plates today (such as seeding, harvesting, picking, transportation, packaging, etc.) can loosely translate to how software actually ends up on our computers, particularly in the way that if any of the steps in the multi-stage food supply chain has an issue then it quickly becomes a serious problem. For example, even if we could guarantee that only the most wholesome apples were picked in our orchards, if they became tainted on the way to the supermarket it will be a real problem for us at the end of the day. We may not even be able to even tell by simply inspecting our Pink Ladies or Honeycrisps, and washing them thoroughly under the tap may not be enough either. In an ideal world, we would be able to personally inspect the provenance of our food at all of the stages of manufacturing and transportation. But at some point, we must place our trust in the process and in brands, as well as various regulatory bodies to ensure that potential problems in our food are minimized, possibly even paying a time/effort premium by growing our own or buying direct from local markets in order to minimize the number of steps, etc. However, when we use free software we can do better: Reproducible builds are a set of software development practices, ideas and tools that create an independently-verifiable path all the way from the original source code to what actually runs on our machines. Reproducible builds can reveal the injection of back-doors introduced by the hacking of developers own computers, build servers and package repositories, and also expose where volunteers or companies have been coerced into making changes via blackmail, court order, and so on. With reproducible builds, there is no longer any need to trust any particular source of authority. In the same way that, say, a Mr Smith might check that his calculator is giving him the right answer to 2+2=4 by asking enough of his friends to check theirs too, users and developers of a reproducible build can verify the software they are using by creating a collective consensus instead.
The full interview can be found on the Conservancy webpages.

Russ Allbery: Review: Behind the Throne

Review: Behind the Throne, by K.B. Wagers
Series: Indranan War #1
Publisher: Orbit
Copyright: August 2016
ISBN: 0-316-30859-5
Format: Kindle
Pages: 416
Hail is a gunrunner, an outlaw and criminal, someone who knows how to survive violence and navigate by personal loyalty. That world knows her as Cressen Stone. What her colleagues don't know is that she's also an Imperial Princess. Hailimi Mercedes Jaya Bristol left that world twenty years earlier in secret pursuit of her father's killer and had no intention of returning. But her sisters are dead, her mother's health is failing, and two Imperial Trackers have been sent to bring her back to her rightful position as heir. I'm going to warn up-front that the first half of this novel was rough to the point of being unreadable. Wagers tries much too hard to establish Hail as a reluctant heroine torn between her dislike of royal protocols and her grief and anger at the death of her sisters. The result is excessively melodramatic and, to be frank, badly written. There are a lot of passages like this:
His words slammed into me, burning like the ten thousand volts of a Solarian Conglomerate police Taser.
(no, there's no significance to the Solarian Conglomerate here), or, just three paragraphs later:
The air rushed out of my lungs. Added grief for a niece I'd never known. One more log on the pyre set to burn my freedom to ashes. The hope I'd had of getting out of this mess was lost in that instant, and I couldn't do anything but stare at Emmory in abject shock.
Given how much air rushes out of Hail's lungs and how often she's struck down with guilt or grief, it's hard to believe she doesn't have brain damage. Worse, Hail spends a great deal of the first third of the book whining, which given that the book is written in first person gets old very quickly. Every emotion is overwritten and overstressed as Hail rails against obvious narrative inescapability. It's blatantly telegraphed from the first few pages that Hail is going to drop into the imperial palace like a profane invasion force and shake everything up, but the reader has to endure far too long of Hail being dramatically self-pitying about the plot. I almost gave up on this book in irritation (and probably should have). And then it sort of grew on me, because the other thing Wagers is doing (also not subtly) is a story trope for which I have a particular weakness: The fish out of water who nonetheless turns out to be the person everyone needs because she's systematically and deliberately kind and thoughtful while not taking any shit. Hail left Pashati young and inexperienced, with a strained relationship with her mother and a habit of letting her temper interfere with her ability to negotiate palace politics. She still has the temper, but age, experience, and confidence mean that she's decisive and confident in a way she never was before. The second half of this book is about Hail building her power base and winning loyalty by being loyal and decent. It's still not great writing, but there's something there I enjoyed reading. Wagers's setting is intriguing, although it makes me a bit nervous. The Indranan Empire was settled by colonists of primarily Indian background. The court trappings, mythology, and gods referenced in Behind the Throne are Hindu-derived, and I suspect (although didn't confirm) that the funeral arrangements are as well. Formal wear (and casual wear) for women is a sari. There's a direct reference to the goddess Lakshimi (not Lakshmi, which Wikipedia seems to indicate is the correct spelling, although transliteration is always an adventure). I was happy to see this, since there are more than enough SF novels out there that seem to assume only western countries go into space. But I'm never sure whether the author did enough research or has enough personal knowledge to pull off the references correctly, and I personally wouldn't know the difference. The Indranan Empire is also matriarchal, and here Wagers goes for an inversion of sexism that puts men in roughly the position women were in the 1970s. They can, in theory, do most jobs, but there are many things they're expected not to do, there are some explicit gender lines in power structures, and the role of men in society is a point of political conflict. It's skillfully injected as social background, with a believable pattern of societal prejudice that doesn't necessarily apply to specific men in specific situations. I liked that Wagers did this without giving the Empire itself any feminine-coded characteristics. All admirals are women because the characters believe women are obviously better military leaders, not because of some claptrap about nurturing or caring or some other female-coded reason from our society. That said, this gender role inversion didn't feel that significant to the story. The obvious "sexism is bad, see what it would be like if men were subject to it" message ran parallel to the main plot and never felt that insightful to me. I'm therefore not sure it was successful or worth the injection of sexism into the reading experience, although it certainly is different from the normal fare of space empires. I can't recommend Behind the Throne because a lot of it just isn't very good. But I still kind of want to because I sincerely enjoyed the last third of the book, despite some lingering melodrama. Watching Hail succeed by being a decent, trustworthy, loyal, and intelligent person is satisfying, once she finally stops whining. The destination is probably not worth the journey, but now that I've finished the first book, I'm tempted to grab the second. Followed by After the Crown. Rating: 6 out of 10

Russell Coker: MPV vs Mplayer

After writing my post about VDPAU in Debian [1] I received two great comments from anonymous people. One pointed out that I should be using VA-API (also known as VAAPI) on my Intel based Thinkpad and gave a reference to an Arch Linux Wiki page, as usual Arch Linux Wiki is awesome and I learnt a lot of great stuff there. I also found the Debian Wiki page on Hardware Video Acceleration [2] which has some good information (unfortunately I had already found all that out through more difficult methods first, I should read the Debian Wiki more often. It seems that mplayer doesn t suppoer VAAPI. The other comment suggested that I try the mpv fork of Mplayer which does support VAAPI but that feature is disabled by default in Debian. I did a number of tests on playing different videos on my laptop running Debian/Buster with Intel video and my workstation running Debian/Unstable with ATI video. The first thing I noticed is that mpv was unable to use VAAPI on my laptop and that VDPAU won t decode VP9 videos on my workstation and most 4K videos from YouTube seem to be VP9. So in most cases hardware decoding isn t going to help me. The Wikipedia page about Unified Video Decoder [3] shows that only VCN (Video Core Next) supports VP9 decoding while my R7-260x video card [4] has version 4.2 of the Unified Video Decoder which doesn t support VP9, H.265, or JPEG. Basically I need a new high-end video card to get VP9 decoding and that s not something I m interested in buying now (I only recently bought this video card to do 4K at 60Hz). The next thing I noticed is that for my combination of hardware and software at least mpv tends to take about 2/3 the CPU time to play videos that mplayer does on every video I tested. So it seems that using mpv will save me 1/3 of the power and heat from playing videos on my laptop and save me 1/3 of the CPU power on my workstation in the worst case while sometimes saving me significantly more than that. Conclusion> To summarise quite a bit of time experimenting with video playing and testing things: I shouldn t think too much about hardware decoding until VP9 hardware is available (years for me). But mpv provides some real benefits right now on the same hardware, I m not sure why.

Next.

Previous.