Search Results: "ema"

12 July 2011

Gustavo Franco: Google+ and your data

Let's make it clear: Your data is yours and in Google+ official announcement there's the following "You and over a billion others trust Google, and we don t take this lightly. In fact we ve focused on the user for over a decade: liberating data, ...". John Goerzen is wrong.

I can understand people having problems to use a product during its field trial and demanding features. I won't sit and watch people spreading FUD in bold before asking though.

Last, but not least, the following link is easily visible in the Settings and is also listed in the Help pages:
https://plus.google.com/settings/exportdata


John Goerzen: First Look at Google Plus

Seems like everybody s writing Google+ reviews these days, but most of the ones I ve found seem to be fluff pieces. I haven t used it long, but have some initial impressions to share. First, an analogy. Facebook reminds me of the sleazy guy selling stuff from his car down the street. They do things like change privacy defaults when they think it s good for Facebook, rather than good for you. Google+ reminds me of an Apple product. It s beautiful, easy to learn, but locks everything down and is lacking some critical features. So here goes with the details. The good I think that this can be best summed up by: it s not Facebook. Facebook has, perhaps, set an incredibly low bar but still, this holds. Facebook is the only website I can ever remember using that changes things so much, so often, and so completely that I keep having this feeling of not knowing how to do things. Try maintaining a Facebook page or two and you ll especially feel my pain then. But even the basics: how many times have I accidentally posted a partial comment because I pressed Enter to start a new paragraph (that has only been the button used for that for, hmm, let s see now, decades), and instead it posted the comment. Principle of least surprise, anyone? Google+ has a simple and, on the surface anyway, intuitive interface. However, it does get muddy; more on that below. I m going to spend a lot more space on the bad below, but don t let that diminish my excitement about having a viable alternative to Facebook. I am keen to get rid of that monster. The Bad I ll start of this section with the fact that Google+ is a tightly-controlled walled garden. There is no way to take a copy of your status updates, comments, etc. and back them up with your own devices. If your Google account goes away, so do all your updates about your kids first words. Facebook does have this feature these days. It has broken half the time, but it exists, works, and I use it. Twitter doesn t have the feature built in, but its API makes it pretty easy; you could easily use my twidge program to do this, for instance. But whatever you put in G+ stays in G+. There is no autoposting it to twitter or Facebook, no backups, nothing. I m disappointed in that, given Google s prior attitude about openness to individual data ownership. (Update 7/12/2011: There is a way to get a backup, which I hadn t noticed; see comments below.) Almost as bad, there s also no way to get data in. So I now have identi.ca, twitter, Facebook, and now also G+ accounts. When I post an item in identi.ca, it autoposts to twitter, and then it autoposts from twitter to Facebook. Handy one place to notify people of my public activities. My uploads to Flickr and blog posts also auto-post to Facebook, so people I m friends with there get a picture of what I m doing outside of Facebook without me manually having to link it in. Not so with G+. There is no way to even add an RSS feed for my blog to auto-post to G+ as there is with Facebook. If you use G+, the only way to get stuff into it is with a keyboard. Poor integration with other Google apps is also an issue. G+ is nowhere near Google s first social app. They also have Blogger, Google Reader, Buzz, Gmail, etc. So here s the rub. These aren t integrated well, and when they have tried to integrate them, they ve done an exceedingly poor job of it. As an example: Buzz is a twitter-like service for posting updates. Very similar to what G+ does, right? Well, the best you can do is link your Buzz account to a separate tab on your profile. You can t even have your Buzz updates flow straight into G+, from what I can see. You have a separate list of followers in Buzz from G+. Reader is even worse; it has a sharing feature, but it s not G+ aware, so it goes to a reader inbox. But what takes the cake is the integration with Gmail Contacts. Sounds easy? Not entirely. When you add someone to G+, apparently it sometimes links the record with their entry in Contacts. And the help gives you the handy warning that when you remove them from G+, you have the option of removing them from Contacts, which could impact what you see on a mobile device. It is unclear what happens when it doesn t link the record, or how it decides which record to link (some people have more than one person in a family sharing phone numbers and email addresses, for instance.) One very nice feature of G+ is you can add email addresses, even if they aren t G+ members. Then when you post updates to the circle you ve added them to, G+ offers to send them an email with an update. Very handy. Except the undocumented part is that if you select Your circles (meaning all your circles), rather than individually ticking the box by each circle, they don t get the email. And they also don t get it if you set it Public. You have to select their specific circle, which is a significant difference from how people with G+ accounts are treated. And that s just an example. There are a ton of things that work one way 95% of the time, but have non-obvious exceptions. Some of these exceptions are documented in the help, and some aren t. I m still confused about the integration with Picasa. G+ help says that you can upload unlimited numbers of photos for free (though they will be downscaled at a certain point). Picasa has definite storage limits. But G+ uploads are showing up in Picasa. Do I really get free storage by uploading to the same place via a different tool? Very odd. And finally, a gripe about web standards. I ve been using Firefox/Iceweasel 3.5, which came out in Debian squeeze and is still supported there. It is also pretty darn new by corporate IT standards. And Google Plus refuses to let me log in with it, saying it s incompatible. Perhaps it can t do some fancy animation, but then again I don t really care. Seems Google has forgotten the old RFC adage: be liberal in what you accept and conservative in what you generate. If you can detect that my browser won t animate something right, then you could give me a stripped-down version of the page rather than an error message.

Gunnar Wolf: Free Software must migrate to become Free Culture

Cineast and Free Culture activist Nina Paley wrote some days ago a rantifesto on why the FSF has a double standard: Why are the Freedoms guaranteed for Free Software not guaranteed for Free Culture?, by not following its own very strict rules on software when it comes to culture as a whole. Her post was widely circulated, and got (at least) one reply by fellow Debian Developer Wouter Verhelst, largely agreeing with her, and an anti-rantifesto by Joe Brockmeier Which was promptly answered again by Wouter with a very fun and inspired post, written from the right angle: From the viewpoint of a person who is both a programmer and a musician, and understands the concepts at hand. I'd love to write a longer, better thought post But I'm tired and frankly stressed by many things, so I am just echoing their very interesting discussion to other people who might want to read it. I have been thinking and writing bits on that subject over the last couple of months. An example of that was the talk I gave at the Senate ~6 weeks ago. Following that talk, I wrote a short article for Revista Z calo (a widely circulated magazine mainly dealing with Mexican politics and social issues) called simply Software libre, cultura libre (full text available, but in Spanish only You can try reading an automated translation if it suits you). I wrote the article, mind you, with very limited time, and I'll be the first to recognize the prose was quite poor this time :( Anyway My point is that our nature is to share culture, to build it in a collaborative fashion, and having the Internet as a practically zero-cost, zero loss medium with which we can interchange our creativity with other like-minded people will naturally boost creativity. Free Software emerged before other Free Culture groups just because programmers had privileged access to Internet in the 80s and early 90s; as network access and digital creation tools have got to more people, it's just natural for all kinds of free culture to grow. Software is just a form of knowledge. Code is just a notation for a certain kind of ideas, just as the mathematical or musical notations. I believe (and hope) it's just unavoidable for us all to eventually switch to a mainly free cultural creation system.

11 July 2011

Thorsten Glaser: [Update] Hilfe gesucht: Mitarbeiter berwachung

Deutsche Version dieses Postings read the English Version instead Der Leiter der Abteilung Systemadministration einer Firma, welche in diesem Artikel ungenannt bleiben soll, wo der Zufall es will, da ich f r sie arbeite, m chte uns Mitarbeiter dazu zwingen, das Feature der persistenten Historie (also einen niedergeschriebenen Verlauf der abgesetzten Befehle) der Shell (Kommandozeile) auf allen Systemen zu benutzen. Nun hat die mksh dies vern nftigerweise, w hrend immer noch verf gbar, standardm ig aus Gr nden der Privatsph re deaktiviert, und ich finde, dies sollte sich nicht ndern. Es kann ja nicht sein, da man mir beim Arbeiten ber die Schulter guckt; was kommt als n chstes, Video berwachung der B ros? (Seine Argumentation l uft darauf hinaus, da er nachvollziehen/verstehen kann, wie ich (ha! ich! nicht die anderen, nein, ich!) ein Problem das letzte Mal gel st habe; es ist aber nichts anderes als rekonstru eren zu k nnen, wer wann was eingetippt/gemacht hat. Naja, Argumentationen sind eh relativ, andere jagen Flugzeuge in ihre eigenen Verteidigungsministerien, welche gerade zuf llig umgebaut werden ) Ich habe dies nat rlich in die F hrungsetage eskaliert, und unser Gesch ftsf hrer versteht meine Bedenken und m chte nun ein Gespr ch anraunen, um eine L sung zu finden. Die meisten meiner Kollegen im Bereich Systemadministration denken leider nichtmals dr ber nach, obschon ich in anderen Bereichen Gleichgesinnte gefunden habe. Einen Betriebsrat haben wir auch gro er Fehler, ich wei nicht (aber ich s e eh nicht drin, ich hasse Politik jeder Art). Dies l t mich in dringender Not, Argumente wider diese Total berwachung aller (insbesondere auf der Kommandozeile arbeitenden also besonders mich) Kollegen zu finden, idealerweise solche, die durch deutsches Recht gest tzt sind. Wenn ihr solche habt, bitte mailt die schnell an meine eMail-Adresse, welche da nicht junk@mirbsd.org lautet, sondern mit einem tg vor dem Klammeraffen (dies dient der Abwehr unerw nschter Werbemails). Vielen Dank bereits im Voraus! Update 12.07.2011: Wir haben geredet, und wie viele kommentierten keine L sung auf rechtlicher Ebene gefunden, sondern stattdessen, nachdem wir festgestellt hatten, da mir dieses Problem sehr am Herzen liegt, nach anderen L sungen f r das eigentliche Ziel des Chefadmins gesucht; dies z hlt als ein Entgegenkommen auf Seiten der Firma. Ich habe zugestimmt, meine L sungen in kleine Skripte zu verpacken und ins VCS zu committen f r das Herausfinden, wann was auf einem Server ge ndert wurde, im Fehlerfall, denken wir uns gerade ohnehin was aus. Danke an alle, die kommentiert haben!

Raphaël Hertzog: 7 tips to file useful Debian bug reports and get your problem solved

Filing bug reports is the most common way for users to contribute. Even if it s not too difficult, I ll give you some advice to improve the quality of your reports. After all, when you go out of your way to report a bug, it is in the hope to see it fixed so let s see how we can make this more likely. 1. Try to reproduce the bug If you can t reproduce the bug, it s next to impossible to find the root cause and thus to fix it. In that case, I would suggest you to wait until you experienced the bug multiple times. Maybe you ll be able to find something that triggers it (or that makes it more likely to encounter it). If the application has a debug/verbose mode, it might be a good idea to enable it until you experience the bug a second time. The generated log might be helpful for the developer to understand what happens exactly. So don t file bug reports straight away unless you can reproduce it. The exception to the rule is when the application gives some useful information like a core-dump, a back-trace or an error message. Obviously if the bug happens during an upgrade, it s difficult to reproduce it (unless you have multiple computers) but you should still report it. Be sure to include all the relevant information (versions of packages before and after the upgrade, logs of the upgrade, etc.). 2. Do your best to identify the faulty package When you report a bug to Debian, you must assign it to a package. While there are pseudo-packages useful for problems which are not directly attributable to a real package, in most of the cases you should report a bug against the specific package that seems to be the cause of the problem you encountered. In turn this often requires you to attribute the problem to a file (for example the executable of the application that triggers the bug). Once you have a filename you can use dpkg -S to identify the corresponding package.
$ dpkg -S /usr/bin/hamster-time-tracker
hamster-applet: /usr/bin/hamster-time-tracker
Note that reportbug accepts a filename as parameter and will do the above conversion for you. If you only know the name of the application (but not the filename of the associated executable), you can use dpkg -S with a pattern to let it return all possible matches:
$ dpkg -S hamster
hamster-applet: /usr/share/applications/hamster-applet.desktop
hamster-applet: /usr/share/gnome/help/hamster-applet/es/statistics.page
[ ]
hamster-applet: /usr/bin/hamster-time-tracker
[ ]
Or you can also verify in the list of installed packages:
$ dpkg -l "*hamster*"
Desired=Unknown/Install/Remove/Purge/Hold
  Status=Not/Inst/Conf-files/Unpacked/halF-conf/Half-inst/trig-aWait/Trig-pend
 / Err?=(none)/Reinst-required (Status,Err: uppercase=bad)
 / Name            Version         Description
+++-===============-===============-==============================================
ii  hamster-applet  2.32.1-1        time tracking applet for GNOME
3. Verify that the bug is not already reported and/or fixed If there s a newer version of the software available, it s a good idea to try to reproduce the problem with this version too. Because the developers tend to care only about the latest version, they will want to reproduce it with this version, and they will be annoyed if the problem that you reported is already fixed. That s why bug reports of users of testing/unstable tend to be more useful than bug reports of stable users. In any case, you want to verify that the bug has not yet been reported: filing a duplicate bug is useless and only generates more work for the developers to merge both bugs together. On the opposite, it s highly appreciated to add supplementary information to an existing bug report, even a simple confirmation that the bug still exists on a newer version is useful. Note that reportbug will automatically show you the list of open bugs before allowing you to submit a new one. 4. Use reportbug While the Debian bug tracking system allows anyone to submit a new bug with a simple mail, you should really use a dedicated program like reportbug (or reportbug-ng) because it will automatically include lots of useful information in the generated report (version of dependencies, current architecture, etc.) and will assist you in all the steps. 5. Describe the problem so that the developer can reproduce it Ideally your report should include everything required so that the developer can reproduce the problem on his system. If a given document triggers the bug, attach it. Describe the steps required to reproduce the bug in great details just like you would explain it to your grand-ma. Explain how you expected the program to react and what happened instead. You can learn much more on how to draft a good bug report in this article: How to report bugs effectively. It s a bit long but well worth it if you intend to report bugs and thus interact with developers. 6. Be kind and willing to help When you draft a bug report, keep in mind that you re writing to a volunteer free software developer and not to a customer service. You should be respectful and follow the usual rules of courtesy. Developers attention is scarce and should not be wasted. Be willing to help, if the developer starts investigating your problem, he might need your help to get supplementary information (in particular if he can t reproduce it) and you should be ready to provide it. Thus it s important to keep whatever you need to reproduce the problem. In some cases, the Debian maintainer might be overworked and you can offer your help to forward the bug to the upstream bug tracker, it s always appreciated. If you re reasonably confident that the problem is not Debian-specific, you can do it straight away and set the forwarded field to the URL of the upstream bug report (for example with bts forwarded <bug> <url>). 7. Use the correct severity The Debian bug tracking system lets you set the initial severity of the bug report (in decreasing severity: critical, grave, serious, important, normal, minor, wishlist). Pick the correct severity according to the official definitions but don t misread them. In particular, don t over-inflate the severity: for instance if you lost some data due to a misuse of the software, it s not critical (i.e. rm -rf * doesn t warrant a critical bug against rm). If you use only a tiny part of a software, and that part doesn t work, the package might be unusable for you but it s not unusable for everybody, so it doesn t warrant the grave severity. The important severity is often a good choice in those cases. Do not under-estimate the severity either, if a problem is important enough that it must be fixed before the next stable release (for example a regression compared to the previous release), pick a release-critical severity (i.e. at least serious ). The maintainer and the release manager can always lower the severity if they do not agree with your initial judgment. And now, happy bug-reporting!
Follow me on Identi.ca, Twitter and Facebook. Or subscribe to this blog by RSS or by email.

6 comments Liked this article? Click here. My blog is Flattr-enabled.

Vincent Bernat: Rewriting my .zshrc

Ten years ago, I started to use ZSH, a shell designed for interactive use but which is also powerful for scripting usage. I had a fairly comprehensive .zshrc file splitted in several parts. I have decided to rewrite it for several reasons:
  1. I did not take advantage of several features of ZSH, like some advanced parameter expansion, arrays, arithmetic expressions and other built-in features. There were a lot of head, awk, sed that could be replaced by some ZSH machinery (something easier to read like $ $ (f)~~"$(</etc/hosts)" %%\#* ).
  2. It contained a lot of hacks to make things work on some odd/old setups. I was not really sure that those hacks are useful anymore. It also contained a lot of conditionals where some parts of the code were executed depending on the hostname.
I have discovered oh-my-zsh, a nice project trying to provide a generic and flexible ZSH configuration:
A community-driven framework for managing your zsh configuration. Includes 40+ optional plugins (rails, git, OSX, hub, capistrano, brew, ant, macports, etc), over 80 terminal themes to spice up your morning, and an auto-update tool so that makes it easy to keep up with the latest updates from the community.
The idea of such a project is to fork it and make the changes that you need. I was previously hacking around Phil! s ZSH Prompt for my prompt. oh-my-zsh contains a close theme (jonathan). Neat. However, I decided to write my .zshrc from scratch (but with some snippets stolen from oh-my-zsh). Why? Mostly because I want to precisely configure ZSH. Even with its plugin architecture and its override mechanism, oh-my-zsh provides some features (options, aliases, functions) that I do not want. Of course, thanks to git, you can fork and make any local changes you want but since I would have modified most of the files, it seemed easier to just start from scratch. I have published the result on GitHub. You can use it as is, fork it or (better) steal and adapt some snippets for your own usage. Here is the mandatory screenshot for the prompt (no much space left for the commands): My ZSH prompt Here is a short snippet used to select a sensible EDITOR depending on what is available. It uses anonymous functions (to restrict the scope of local variables), arrays and flags in parameter expansion. For another example, take a look on how I select a valid locale.
()  
    local -a editors
    local editor
    editors=(
        "emacs23 -Q -D -nw" # Fast emacs
        "jove" "mg" "jed"   # Emacs clone
        "vim" "vi"          # vi
        "editor")           # fallback
    for editor in $editors; do
        (( $+commands[$editor[(w)1]] )) &&  
            export EDITOR=$editor
            break
         
    done
 
Enjoy! UPDATED: Anonymous functions were introduced in ZSH 4.3.7. Older versions do not support them. A workaround is to use a classic function instead:
__()  
    local -a editors
    local editor
    ...
  && __

10 July 2011

NeuroDebian: NeuroDebian@HBM2011.ca

NeuroDebian@HBM2011.ca On June 26-30 the annual meeting of the Organization for Human Brain Mapping (HBM2011) took place in Quebec City, Canada. Encouraged by our positive experience at last year s SfN in San Diego and enthusiasm of our scientific adviser, James V. Haxby, we hosted another NeuroDebian booth. The setup was pretty much the same as last year: Some chairs and tables, lots of people, our tri-fold flyers, a Debian mirror and some virtual machine images to show Debian in action. This time we also had an LCD display attracting visitors with the package swarm, some demos, and our recent paper. We had many curious people have their first exposure to Debian, long-time users expressing their gratitude to Debian, and our upstream developers getting together to discuss various topics. Having registered the booth as NeuroDebian , we had the additional pleasure of explaining visitors the concept of a project inside Debian, in contrast to a derived distribution. But that is nothing new really, so let s talk about the differences from last year s booth. First of all, we had more people at the booth. Dominique Belhachemi volunteered to help us out and that was very much appreciated. Although HBM has only about a tenth of the attendees that SfN has, we had significantly more traffic. While last year people were primarily interested in knowing about the project, this time many of them wanted to give it a try immediately. People came with their laptops, got the VM images and started playing with Debian. After a day or so, some came back and asked for recommendations on particular software after having been exposed to the wealth of the Debian archive. What also had increased was the number of developers, or rather research labs developing neuroimaging software that came to the booth to discuss how to get their software into Debian and how to arrange ongoing maintenance of these future Debian packages. As we have our plates already quite full, we have been spending some time on mentoring interested developers to learn the art of Debian packaging and making them familiar with Debian s procedures and standards (e.g. working on #609820 with Yannick Schwartz, upstream, at the booth). ../../_images/BusyBooth216.jpg Two promising new developments need to be mentioned. First, we were approached by companies that develop hardware for brain-imaging and psychophysics research. They were curious to learn about Debian as an integrated platform that offers free software solutions that an increasing amount of their customers demands (e.g. PsychoPy). Apparently, the movement towards open research software has finally made it into the business plans of companies, as they seem to start perceiving compatibility with free software systems as a competitive advantage. We explained how software gets into Debian, and how its release cycle is managed. To foster their motivation we also pointed them to the existing open-source software that is already available or even present in Debian. Let s see whether we see more Debian-certified research products in the future. Lastly, we started talking with folks from the INCF to explore possibilities of collaborating on INCF projects using Debian as the integration and development platform. The INCF is an OECD-funded organization that develops collaborative neuroinformatics infrastructure and promotes the sharing of data and computing resources to the international research community. At least one INCF project is already relying on the efforts of the NeuroDebian project. We are going to continue this discussion during a workshop in September. A report will follow...
../../_images/DDs13.jpg

Debian people at the booth (f.l.t.r): Michael Hanke, Yaroslav Halchenko, Stephan Gerhard, Dominique Belhachemi. Not shown: Swaroop Guntupalli.

Acknowledgments This booth has been made possible by the generous support of Prof. James V. Haxby (Dartmouth College, New Hampshire, USA).

9 July 2011

Wouter Verhelst: Freedom, continued

Okay, so the story continues: Joe Brockmeier has posted a rebuttal to Nina Paley's post that I commented on earlier today. Basically, Joe says that Culture is not the same things as Software, and gives a lot of arguments as to why this would be true. But I can't agree with him. Let's see why. His first argument is "One of these things is not like the other". As in,
But it's far more reasonable and sensible to discuss Perl scripts and software written in assembler embedded on a chip together, and the rights that they come with, than to try to talk about rights to modify sculpture and essays.
I don't see how one could combine a perl script with an embedded assembler program, except perhaps over a network, or by using exec() two cases in which the FSF would consider that they are not even derivatives anymore, they are "at arm's length", and it would be legal to do something like this if one bit was released under the GPL while the other was not. At the same time, it's possible to engrave (part of) an essay into a statue, for example. Or make a technical apparatus which looks like a statue but which will play music if you come near it. Both would be valid cases of some artist combining two separate and (at first sight) distinct things into one work.
Sure, you could crowdsource sculpture, but I doubt it will have much practical application. (And certainly difficult over the Internet, but I digress...)
It's called RepRap, and it's very much possible over the Internet. Joe moves on, with 'Unintended consequences of forkable prose'.
Take the GNU Manifesto, for example. If you could "fork" the manifesto, I could easily see variant versions modified to justify open source instead of free software.
This argument had been brought forward during the discussions which Debian had on the GFDL vote, and has been seriously debunked there. In short: the ability and right to fork someone's prose does not, in any way, give you the right to misrepresent them. While I believe it should be okay for someone to base a theoretical Open Source Manifesto on the GNU Manifesto, I do not believe it should be okay for them to still keep calling it the GNU Manifesto. It's not the same thing anymore, so that should be clear. This is true within Free Software as well: if you fork, you give it a new name, so it becomes clear that you're not the original anymore. Moreover, I doubt the kind of prose found in the GNU Manifesto is the same kind of prose that Nina would like to see in a free culture movement. Not because the GNU Manifesto is a bad piece of writing it isn't but because Free Culture likely focuses on other things than manifestos. Next, we get "Solving a problem that doesn't exist"
The spark that fired off the GNU revolution was a legitimate problem because of non-free code, a user was unable to make use of hardware they (or their university) legitimately owned.
(...)
While Paley and others may want the same freedoms to go with cultural works, it is not a real problem in the same sense.
Pardon ye me? I am a musician. Not a very brilliant one, mind you, but I play the flute with much enthusiasm, and have done so in a number of places. If you've been to any debconf since 2007, surely you must've heard me play. Also, I've been singing in choirs since I was sixteen which, I just realized, means I've now been singing for more than half my lifetime. Time flies, it must be said. One of the orchestra that I've been playing in was an extended flute choir with a rather unusual instrumentarium: apart from 30-something flautists, the orchestra also had a piano and drummer, a number of guitar players, and a bass guitar. Such an unusual set of music means you have three options: you play original music, written specifically for your group; you play something written for a different set of instruments, without changing anything, and hope nobody notices that it doesn't actually sound very well; or you make modifications. You make a derivative work of the music, so you can actually play it. There, I've said the word. This isn't just true for music; I've yet to see the first theatre performance that is true, word-for-word, to the original script. Also, movies use music all the time. When they do, there are usually two options: either they have original pieces of music written specifically for their movie (as is the case for most Hollywood blockbusters), or they take a piece of existing music, and adapt it so it fits the events in the movie better. By, say, shortening it, so it doesn't run into the next scene. Or by repeating the refrain an extra time, so the words line up nicely with the action. Or by having a group of musicians record a version of that piece specifically for your movie, which is the same thing in everything except the speed so that the feet of the actor walking on the big screen hit the ground in sync with the music. Or... well. You get the idea. By claiming that artists have no need to modify and derive from others, the only thing Joe accomplishes is to show that he really, really, really doesn't know what the fuck he's talking about. Artists have a need to modify other artists' works all the time. The only difference with free software is that they either need to invoke the fair use clause, or need to pay big bucks to the original rightsholder. Sound familiar? Joe finishes up with stating that despite all of that, Free Culture is still possible. And:
That doesn't mean that free culture is impossible. It simply means that different standards apply.
Exactly: different standards apply. And why? There is no good reason for that. Because people make money from cultural works? Well, money is made from software, too, that has never been a good enough reason. Because Culture is not functional? How many in the Free Software movement would even be willing to only be doing software all the time, and not ever do anything remotely related to Culture? None, I would say. Culture is just as functional as Software, it just serves different functions. In the comments, Joe clarifies that he isn't against people preferring not to use the ND clause in the CC licenses they select, he's just against demanding that others do the same. That argument would make sense if not for the fact that the FSF demands, mostly, that Software Should Be Free!!1!. By not complaining about the GNU Manifesto, but complaining about Paley's "Rantifesto", which basically complains about the lack of such an environment in the free culture movement, Joe just makes a fool of himself. Anyway, 'nuff said.

8 July 2011

Russell Coker: Multiple Filesystems for Security

There is always been an ongoing debate about how to assign disk space into multiple partitions. I think that nowadays the best thing to do is to assign about 10G for the root filesystem for every desktop and server system because 10G is a small fraction of the disk space available (even the smallest laptops seem to all have disks larger than 100G nowadays). Even if 10G turns out not to be enough using separate filesystems for /var or /usr provides little benefit now that it s easy to resize the root filesystem with LVM and a separate /usr is known to be broken [1]. In a discussion on a private mailing list there was a suggestion that multiple filesystems should be used for security. DoS Attacks There are some minor security benefits in having multiple filesystems. If a critical program will fail when there is no free disk space then allowing an unprivileged process to use up all the space on that filesystem is a minor security issue, so having unprivileged processes not being permitted to write to important filesystems is a benefit. But most failures of this type are merely DoS attacks which usually aren t a big deal if you can control a local process there are usually lots of other ways of DoSing a system. Links Links have been the cause of many security issues in Unix over the years. Using different filesystems for different tasks can prevent the use of hard links in attacks aimed at exploiting race conditions. But even if you prevent hard links there are similar issues with symbolic links. SE Linux is one of many security improvements for Linux which allow restrictions on the creation of hard links. SE Linux also allows restricting the ability of processes to follow symbolic links, so a privileged process can be denied access to follow a sym-link that was created by an unprivileged process. NFS The subtree_check option in /etc/exports causes the NFS server to verify that file access is in the correct subtree. So if you export only one subdirectory of a filesystem to a given server then hostile code on that server (or on a network device which impersonates that server) can t access other subdirectories. This option is documented as having performance implications and working best for filesystems that are mostly read-only, for this reason it s turned off by default in recent versions of the NFS utilities. So if you want to NFS export /home then it s probably a good idea to have /home be on a separate filesystem to prevent attacks on the root filesystem. But of the systems with significant use of /home (IE anything other than accounts used solely for su - ) most of them have a separate filesystem for /home anyway so this shouldn t be an issue. SE Linux When mounting filesystems with SE Linux there is a context= mount option that allows specifying the context for all files on the filesystem. This can save a small amount of storage space for XATTRs and theoretically improve performance (although the difference is unlikely to show up on benchmarks for anything other than fsck). Generally the context mount option is only used for a filesystem that has a huge number of files with the same context, such as a mail spool that uses Maildir, Cyrus, or any of the other formats that involve one file per message. But again such data is generally stored on a separate filesystem for other reasons anyway. I found one interesting corner case in regard to SE Linux systems mounting files from an NFS server. When an NFS server exports multiple subdirectories of a filesystem mounted on /foo then if one NFS client running SE Linux is to mount two subdirectories of /foo with different contexts then the second mount attempt will give the error an incorrect mount option was specified . This is because as of kernel 2.6.18 by default it s not permitted to mount parts of the same filesystem with different mount options. The option nosharecache allows you to use different mount options, but does apparently permit some undesirable behavior in the case of hard links that cross between the subtrees. Thanks to Eric Paris for the tip about nosharecache. The best example I can think of for which you might want context mount options that differ among files that are used for the same purpose on an NFS mount is a web server which has data files and CGI-BIN scripts. So it seems that a SE Linux web server that mounts it s data over NFS and is at risk of having hard links between the CGI-BIN directory and the data directory is a corner case in which multiple filesystems is required for security. This seems to be a very unlikely case. Conclusion Servers that are deployed in the real world are complex enough that there are always systems with some unusual corner cases demanding configuration choices that aren t expected. There are some real corner cases for SE Linux where multiple filesystems are compelled for security or for a combination of security and best performance. But I wouldn t make a generic recommendation of using lots of filesystems for security. I think that the people who encounter the strange corner cases can usually work out that they need to do something different. So a small number of filesystems seems like a good general aim that doesn t conflict with security.

5 July 2011

John Goerzen: The Lives of Others

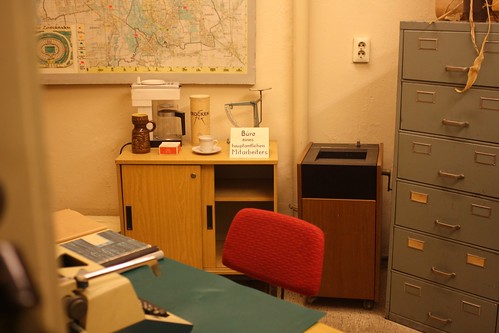
It s not very often that I watch a movie anymore. It s been a few years since I ve actually purchased one (normally I see them from Netflix). But yesterday I saw one that may change that. The Lives of Others is an incredible film set in the former East Germany (GDR/DDR) mostly in 1984. The authenticity of it is incredible and so is the story. It s subtitled, but if you re an American wary of subtitled European films, don t be wary of this one. It is easy to watch and worth every minute. The story revolves around the Stasi, the GDR Ministry for State Security ( secret police ). It is an incredible picture of what living in a police state was like, and how many of the informants were victims of the regime too. My breath caught near the beginning of the film, showing the inside of a Stasi building. A prisoner was being interrogated for helping someone attempt to escape to the west. But the reason my breath caught was this incredible feeling of I was there . Last year, Terah and I were in Leipzig and visited the Stasi museum there, Museum in der Runden Ecke . I always have an incredible sense of history when being in a preserved place, and this building was literally the Stasi headquarters for Leipzig. Much of it was preserved intact, and seeing it in the film brought home even more vividly the terrible things that happened in that building, and others like it, not so very long ago. IMG_2717 We watched the special features on the Blu-Ray disc, and one of them was an interview with director Florian Henckel von Donnersmarck. He described how he spent a lot of time interviewing both victims of the Stasi, as well as ex-Stasi officers. One of the most disturbing things to me was his almost offhand comment that most of the former Stasi officers still had some pride in performing their jobs well. Even now, freed of the state s ideology, they were proud of the work they did which could be put most charitably as ruining people s lives. What leads a person to view life that way? How can we try to make sure it doesn t happen again elsewhere? I am happy to say that most of us have never experienced anything like the Stasi. And yet, small reflections of that mindset can be seen almost everywhere. Societies at wartime or feeling under threat, even Western democracies, can drum up those feelings. In the USA, for instance, the McCarthyism era saw people s careers ruined for alleged anti-state behavior. Contemporary examples include the indefinite detention (I hate that word; shouldn t we say imprisonment ?) of terrorism suspects at Guantanamo Bay, and the terrible treatment of Bradley Manning, who revealed some true but embarrassing things about the US military which really needed to be revealed. Even tobacco farmers and companies are selling a product they know ruins lives, but somehow keep doing it. And there are still members of the public that try to make life difficult for people that don t think like they do. From organizing campaigns of telephone harassment of colleges that don t perform the American national anthem before sporting events, to tossing about the term un-American (a loaded McCarthyist one, which many may not even be aware) at an inflated rate, we are not immune from attempts at forcing conformity or silence in others, and blind loyalty to state. I am never in a particularly celebratory mood on July 4, the biggest day for American boasting, faux patriotism, militarism, and general flag-waving. We do have a lot to be proud of and thankful for, but it seems that we celebrate all the wrong things on July 4, and see it as an occasion to proclaim American exceptionalism rather than as one to see how far we ve come and bolster hope for how far we can, and should, yet go. No, I don t think that the land of the free ought to have operated secret prisons in Europe (nor the Europeans to have been complicit in it), or that the American military was defending our freedom 100% of the time they were deployed, or that it is right for governments to mandate daily recitation of an untrue document (the pledge of allegiance) in schools. And yet, I am mindful that I have a lot to be thankful for stability, lack of much internal violent conflict, etc. And this particular day I am happy that a post like this is not something that gets the attention of some government agency and mostly that I will have a handful of angry emails to delete.

4 July 2011

Nathan Handler: Google Summer of Code Report #3

Since my last report, a lot of visible changes have been made. First, if you edit the value of any of the text inputs on the dashboard table, your changes will be saved when you hit the submit button. This feature still needs a bit of work though. For example, I noticed during testing that if you submit the form multiple times, you will sometimes end up with approximately duplicate entries in the changes file (the file that stores user-submitted changes to the table). I also need to implement some checks to ensure that the values submitted are actually valid (i.e. we probably only want to allow a few possible values for the status column). Another big improvement is the addition of a graph at the bottom of each project s page. This graph tracks the number of open tasks versus time. The graph is re-generated once each day based on a progress file. This file simply lists a date and the number of open tasks on each line. While the graph does correctly show a line tracking the progress, it still has some issues to sort out. For example, the x-axis does not properly display a time increment. Work on the graph was blocked for a while due to not having a fully-functioning dashboard. Now that the dashboard is functioning, I should be able to start working on fixing these graph issues. Several people approached me to request the ability to link directly to a particular project. That way, users do not need to mess around with the select boxes. Above each table is a title. If you click on the title, the URL should update to link directly to the project. This is done with the distro and project query parameters. For example, a link to dex.html?distro=ubuntu&project=ancient-patches will take you directly to Ubuntu s ancient-patches project. Attempting to specify an invalid distro or project will cause the query parameters to be ignored. While looking at the table title, you will also notice a new (Graph) link. This link will take you directly to the bottom of the page so you can view the graph. Currently, it is not possible to link directly to the graph anchor tag of a specific project. Attempting to do so will cause the #graph portion of the URL to be ignored. However, if you click on the actual graph, it will load a full-size graph.png that you can link to. One rather significant issue that has shown up is that the table is very wide. On most monitors, you will have to scroll horizontally to view all of the columns. This is due to the fact that most of the cells are made up of text inputs (they don t have a background or border, but if you click on some text in the table, you should see the box) rather than plain text. The size parameter for a text input was meant to specify how many characters should be visible. However, while I have the size parameter set correctly for each input, it is showing up much wider than the text. I will continue to play around with this, since excluding the size parameter results in some values getting cut-off. As mentioned in my last report, I have continued to work with Allison Randal to make the dashboard more useful. I have received feedback directly from her and indirectly from other people working on the python2.7 project. During my last phone call with my mentor, Stefano Zacchiroli, we agreed that it would be very helpful to spend some time documenting how to go about adding a new project to the dashboard and how to utilize all of the dashboard s features. The goal of this is to not require people to go through me or any other individual to be able to use the dashboard. So while the Summer of Code is meant to focus on programming, I will probably spend some time adding some documentation, as a program is rather useless if nobody knows how to use it. Another bug that I will be working on has to do with sorting the table. I had this feature working early on in the project. However, the sorting broke when I starting using text inputs instead of plain text. I have done some research, and I hope to get the sorting re-implemented in the near future. One other feature that has been requested by several people is the ability to hide completed tasks. This has been on my todo list for a while. Matt Zimmerman wanted to take this a step farther. He felt that the status of the task should be separate from the bug. This means that you can have an open task with a closed bug or a closed task with an open bug. The user could then have some more control over what data they are seeing. I will probably attempt to add some check boxes to control whether certain information is displayed. The user will also be able to specify this directly in the URL. This means that a team could link directly to all open tasks in a project. It is also worth noting that thanks to some help from the fantastic Alioth admins, I now have a live instance of the dashboard running on Alioth. While the URL might change in the future, I hope to keep it running on Alioth. If you are interested in helping out with DEX or dextools, my code is available in a git repository on alioth. You can also join the debian-derivatives mailing list, join #debian-derivatives on OFTC, or contact me directly via email or on IRC (nhandler).

Ross Burton: System Defaults in GSettings

Note: Florian in the comments points me at the documentation (albeit rather concise) for this in the API documentation under Vendor Overrides. GSettings, like GConf before it, allows the administrator of a system to override the default settings or lock down keys to particular settings. This is well documented in the GNOME wiki. However GConf didn't really have the concept of vendor patches. Traditionally if a Vendor wanted to change a default (say, the wallpaper) they'd have to patch the GConf schemas directly. Luckily for people who maintain distributions, GSettings provides a way of installing vendor overrides directly. It's not documented as far as I can tell so consider this a first draft at the manual... First, find the setting you want to override, dconf-editor is useful for this. Say you're making a work-orientated custom distribution so you want the shell's popup calendar to show the week number by default. Some digging in dconf-editor leads us to the org.gnome.shell.calendar folder (the "schema") with a boolean key show-weekdate that defaults to false. By changing the default of this to true, all users will have work week shown unless they explicitly set it to false. Now we've found the information we need we can write the override file. Create a new file with the extension .gschema.override, such as mydistro-tweaks.gschema.override. This file is a .ini-style keyfile, logically mapping schemas to groups and key/value pairs to (predicable) key/value pairs. The value needs to be in the GVariant serialisation format, but for things like booleans, numbers and strings these are fairly obvious. So we'd have a file that looks a little something like this:
[org.gnome.shell.calendar]
  show-weekdate=true
Note that you can set multiple keys in multiple schemas in the same override file, so if we also wanted to show the date in the panel we'd have this:
[org.gnome.shell.calendar]
show-weekdate=true
[org.gnome.shell.clock]
show-date=true
Now the file is ready to be installed. Put it in a package, install to $prefix/share/glib-2.0/schemas and finally run glib-compile-schemas $prefix/share/glib-2.0/schemas in the post-install/post-remove hooks. Done! (many thanks to Ryan Lortie for telling me how vendor patches work)

Rapha&#235;l Hertzog: How to prepare patches for Debian packages

You want to start contributing to Debian and/or Ubuntu, you decided to help a package maintainer and you re now looking for how to change a source package and how to submit your changes. 1. Retrieve the source package and install build-dependencies The first step is to retrieve the latest version of the source package and to install the required build-dependencies. I already covered how to do this with apt-get in the article explaining how to rebuild a source package. If you prefer, you can use dget (from the devscripts package) to directly grab the source package. You can find the URL of the .dsc files in the Package Tracking System for example. Sometimes apt-get will warn you that the source package is maintained in a VCS repository, like this:
$ apt-get source wordpress
[...]
NOTICE: 'wordpress' packaging is maintained in the 'Git' version control system at:
git://git.debian.org/git/collab-maint/wordpress.git
[...]
In that case, you can use debcheckout to retrieve the VCS repository instead (provided that you have the corresponding VCS installed):
$ debcheckout wordpress
declared git repository at git://git.debian.org/git/collab-maint/wordpress.git
git clone git://git.debian.org/git/collab-maint/wordpress.git wordpress ...
Cloning into wordpress...
Note however that some maintainers use their VCS in a way that s not really compatible with the explanations that I will give below. It s also a good idea to install the package packaging-dev . It s a meta-package depending on the most common tools that are used for Debian packaging work. 2. Do the changes Execute dch --nmu to record the fact that you re working on an update prepared by someone who is not the maintainer (NMU means Non Maintainer Upload). This also ensures that if we build the package, we won t overwrite the original source package that we downloaded, thus making it possible to generate a diff between both versions. 2.1. Modify Debian packaging files Now fire your text editor and do the required changes in the debian sub-directory. You will probably run dch -a multiple times to document each subsequent change. 2.2. Modify upstream files If you have to modify upstream files, the proper way to do it depends on the source package format ( 1.0 vs 3.0 (quilt) vs 3.0 (native) , see the debian/source/format file) and on the presence or not of a patch system (the what-patch can help you identify it). In this explanation, I ll assume that the package is using the recommended format: 3.0 (quilt) . (It also works for 1.0 if quilt is used and if you configured ~/.quiltrc as recommended by /usr/share/doc/quilt/README.source). First you should ensure that all patches have been applied with quilt push -a. If there s no patch yet, you want to create the debian/patches directory (with mkdir debian/patches). 2.2.1. Import a patch If the upstream changes are already in a patch file (say /tmp/patch that you downloaded from the upstream VCS repository) you can import that patch like this:
$ quilt import -P fix-foobar.patch /tmp/patch
Importing patch /tmp/patch (stored as fix-foobar.patch)
$ quilt push
Applying patch fix-foobar.patch
[...]
Now at patch fix-foobar.patch
The -P option allows to select the name of the patch file created in debian/patches/. As you see, the new patch file is recorded in debian/patches/series but not applied by default, we re thus doing it with quilt push. 2.2.1. Create a new patch If the upstream changes that you want to make are not in a patch yet, you should tell quilt that you re going to create one:
$ quilt new fix-foobar.patch
Patch fix-foobar.patch is now on top
Then you must record every file that you re going to modify with a quilt add invocation. quilt then makes a backup of those files so that it can generate the patch later on. If you re going to modify the files with your text editor you can just do quilt edit file-to-modify, it s the same than quilt add file-to-modify followed by sensible-editor file-to-modify.
$ quilt edit foobar.c
File foobar.c added to patch fix-foobar.patch
The last step is tell quilt to generate the patch:
$ quilt refresh
Refreshed patch fix-foobar.patch
3. Test your changes You should build your modified package with debuild -us -uc . You can easily install the resulting package with debi . Verify that everything works as expected. If not, continue your modifications until you re satisfied with the result. 4. Generate a patch and mail it If you followed the instructions, you should have two .dsc files in the parent directory, like this:
$ cd ..
$ ls wordpress_*.dsc
../wordpress_3.0.5+dfsg-1.1.dsc
../wordpress_3.0.5+dfsg-1.dsc
Generating the patch to send to the maintainer is then just a matter of running debdiff:
$ debdiff wordpress_3.0.5+dfsg-1.dsc wordpress_3.0.5+dfsg-1.1.dsc >/tmp/wp-debdiff
You can send the /tmp/wp-debdiff file to the wordpress maintainer. Usually you send it via the bugreport that your update is fixing and you add the patch tag to the report. This can be automated with the nmudiff utility. By default it assumes that you re using mutt but it can also directly feed the resulting mail to sendmail. The default text that nmudiff proposes assumes that you re actually performing an NMU and that the result has been uploaded. If that s not the case, you should edit the text and make it clear that you re just sending a patch. If you have been working in a VCS repository, instead of using debdiff you can simply use the diff feature integrated in your VCS (git diff, svn diff, etc.). But note that with a distributed VCS (like git/bzr/mercurial, unlike svn) you should probably have committed all individual changes in separate changesets. And instead of sending a single patch, you re probably going to send a series of patches (though it might be easier to just upload your branch in a public repository and give the corresponding URL to the maintainer).
Found it useful? Be sure to not miss other packaging tips (or lessons), click here to subscribe to my free newsletter and get new articles by email.

No comment Liked this article? Click here. My blog is Flattr-enabled.

3 July 2011

Clint Adams: A very little bit about how herb works

This information is pieced together from no fewer than five informants. As such it is likely to contain inaccuracies. Every year, through the conference registration system, a fork of an old version of Pentabarf, attendees declare that they need sponsorship. They state their cost of travel as well as how much of this amount they can afford to pay themselves. In addition, there is a text field in which one is to answer what you do for Debian and why you request sponsorship. Next a committee is assembled. The head of the committee hand-picks its members. In 2011, twenty-four people were asked if they would like to participate, thirteen people were named to the committee, and twelve of those ended up voting. This committee is named herb , after Herbert Powell. The members of herb each individually rate the applicants on two factors: contribution to Debian and amount requested. Each factor is rated on a five-point scale (-2 to +2). Raters may leave, at their option, a comment regarding the applicant. The raters are able to see previous ratings and comments. In the interest of avoiding the appearance of conflict of interest, each rater will refrain voluntarily from self-rating. Individual raters use exercise judgment during this process.
Contribution to Debian is very subjective, and some raters will vote either on total travel cost, requested amount, the ratio of the two, or something else. At a certain point in time, a weighted average of all the ratings is used to order all the applicants into a list. At the top will be the people ranked most highly. The herb team will then conduct an IRC meeting in which ranking may be arbitrarily changed and two thresholds will be established. The result of this process is three lists of people: queue A, for people who should definitely get sponsorship; queue B, for people that might get sponsorship if people from queue A cancel or other circumstances arise; and queue C, which is not really a queue, but a rejection pile. In some cases, the structure of these queues are decided before definite budget numbers are known. Applicants are emailed to let them know which queues they are in, and their rankings within those queues.

Dominique Dumont: Generate a configuration editor from a config template file with Perl: lcdproc example

Hello Creating a configuration model for Config::Model can be a boring task: When a configuration system has a lot of parameters, a lot of details need to be specified to have a complete configuration validation tool. So, all tricks are permitted to make this task more bearable. Let s see how this can be applied to lcdproc. This project requires a configuration file that supports more than 40 drivers. Each driver has it own set of parameters for a total of about 250 parameters. That s a lot to specify.. Fortunately, LCDd.conf template file is written in a way which makes it relatively easy to parse and get all required information to build a model. All drivers are listed in this template file, most parameters have default values and legal values are written in comments in a uniform way. Hence this file (and comments) can be parsed to retrieve information required for the model. This blog will describe how this task can be implemented in Perl using Config::Model modules. The code will be slightly trimmed down to keep this blog (relatively) short. All initialisation code and error checks are removed. You can get the whole script on sourceforge. The main steps are:
  1. prepare a parser for LCDd.conf template
  2. parse LCDd.conf template
  3. prepare a LCDd model skeleton
  4. translate LCDd.conf template information in a format suitable to create a model.
  5. Write the resulting LCDd model
First, here s the necessary incantation to start properly a Perl program:
use strict;
use warnings;
Then load all required libraries. Their use will be described later:
use Config::Model;
use Config::Model::Itself 1.225;
use Config::Model::Backend::IniFile;
use 5.10.0;
use IO::File;
use IO::String;
Perform some initialisation to avoid upsetting the logging system:
use Log::Log4perl qw(:easy);
Log::Log4perl->easy_init($WARN);
Let s also initialize a model object that will be very useful later:
my $model = Config::Model->new();
Now we can really start the fun part. Step 1: Create a parser for LCDd.conf (INI file)
Problem: LCDd.conf comments must also be analysed to get more semantic information. The comments must be retrieved and associated with the INI classes and parameters found in this file. Fortunately, Config::Model::Backend::IniFile is able to associate comments with the relevant parameters. But Config::Model::Backend::IniFile must store its values in a configuration tree. So let s create a model suitable for LCDd.conf template that accepts any INI class and any INI parameter Dummy::Class is used to store any parameter found in an INI class. The accept keyword with .* regular expression means that any INI parameter will be accepted in each INI class.
$model->create_config_class(
  name   => 'Dummy::Class',
  accept => [
    '.*' =>  
       type => 'leaf',
       value_type => 'uniline'
        ,
    ],
);
Now the Dummy model must provide a configuration class to hold all INI classes:
$model->create_config_class(
    name   => 'Dummy',
    accept => [
       '.*' =>  
           type => 'node',
           config_class_name => 'Dummy::Class'
        ,
    ],
);
Note that an INI backend could be specified directly here. But, some useful parameters are commented out in LCD.conf. Some some processing is required to be able to create a model with these commented parameters. See below for this processing. Step 2: Parse LCDd.conf Now the dummy configuration class is created. Let s create a configuration tree from this dummy class to store the data from LCDd.conf
my $dummy = $model->instance(
    instance_name   => 'dummy',
    root_class_name => 'Dummy',
)-> config_root;
Now, read LCDd.conf:
my $lcd_file
  = IO::File->new('examples/lcdproc/LCDd.conf');
my @lines    = $lcd_file->getlines;
And perform the pre-processing on LCDd.conf mentioned above. Just un-commenting commented parameters is required:
foreach (@lines)   s/^#(\w+=)/$1/  
Store the pre-processed LCDd.conf in a IO::Handle usable by INI backend
my $ioh = IO::String->new( join( '', @lines ) );
Create an INI backend to read the data from pre-processed LCDd.conf and store it in the configuration tree:
my $ini_backend = Config::Model::Backend::IniFile
  ->new( node => $dummy );
$ini_backend->read( io_handle => $ioh );
Step 3: Prepare LCDd configuration model Your attention please. You may remember that we invoked instance on object to create the dummy configuration tree to hold LCDd.conf data. The instance method used the Dummy configuration class. Now, we must invoke instance again on object. But this time, instance will use Config::Model::Itself. This model is Config::Model s way of eating its own dog food. The configuration tree created there will be able to hold LCDd model. Hence the root of this special configuration tree will be called meta_root to avoid confusion with the other configuration root defined above (for the Dummy model). Still with me? Good, let s create this meta tree that will contain LCDd model:
my $meta_root = $model->instance(
    root_class_name => 'Itself::Model',
    instance_name   => 'meta_model',
) -> config_root;
Create the main LCDd configuration class and store the first comment from LCDd.conf as class description:
my $first_comment = $dummy->annotation ;
$meta_root
  ->grab("class:LCDd class_description")
  ->store( $first_comment );
Append my own text in this description:
my $extra_description =
    "Model information extracted from template /etc/LCDd.conf"
  . "\n\n=head1 BUGS\n\nThis model does not support to load "
  . "several drivers. Loading several drivers is probably a "
  . "marginal case. Please complain to the author if this "
  . "assumption is false";
$meta_root->load(
     qq!class:LCDd
        class_description.="\n\n$extra_description"!
);
Add legal stuff in the model:
$meta_root->load( qq!
  class:LCDd
    copyright:0="2011, Dominique Dumont"
    copyright:1="1999-2011, William Ferrell and others"
    license="GPL-2"
!
);
Add INI backend so configuration object created from LCDd model will be able to read user s INI files:
$meta_root->load( qq!
  class:LCDd
    read_config:0
      backend=ini_file
      config_dir="/etc"
      file="LCDd.conf"
!
);
Note that all the load calls above could be done as one call. They were split for better clarity. Step 4:Extracting LCDd.conf information Now that all information from LCDd.conf template file is stored in $dummy configuration tree, it s time to use this information to enhance the skeleton of LCDd model created above. Let s first find all the INI classes defined in LCDd.conf:
my @ini_classes = $dummy->get_element_name;
Now before actually mining LCDd.conf information, we must prepare several subs to handle them. This is done using a dispatch table:
my %dispatch;
First create the default entry which will be used for most parameters. This subs is passed: the INI class name, the INI parameter name, the comment attached to the parameter, the INI value, and an optional value type. It will return a string describing a model for simple elements. For instance: class:"LCDd::MD8800" element:Device type=leaf value_type=uniline default="/dev/ttyS1" description="device to use [default: /dev/ttyS1]" Here s the subroutine invoked by default. Let s create a an anonymous subroutine and store it in the dispatch table:
$dispatch _default_  = sub  
    my ( $ini_class, $ini_param, $ini_note,
         $ini_v, $value_type ) = @_;
    $value_type  = 'uniline';
Now, prepare a string that will be used later to create the ini_class model. This string uses Config::Model s serialisation format described in Config::Model::Loader:
    my $load = qq!class:"$ini_class"
                  element:$ini_param type=leaf !;
Get semantic information from LCDd.conf template comments (written between square brackets):
    my $info = $ini_note =~ /\[(.*)\]/ ? $1 : '';
    $info =~ s/\s+//g;
Use this semantic information to better specify the parameter:
    $load .=
        $info =~ /legal:(\d+)-(\d+)/
           ? " value_type=integer min=$1 max=$2"
      : $info =~ /legal:([\w\,]+)/
           ? " value_type=enum choice=$1"
      :    " value_type=$value_type";
    if ( $info =~ /default:(\w+)/ )  
        # specify upstream default value
        # if it was found in the comment
        $load .= qq! upstream_default="$1"!
           if length($1);
     
    else  
        # or use the value found in INI
        # file as default
        $ini_v =~ s/^"//g;
        $ini_v =~ s/"$//g;
        $load .= qq! default="$ini_v"!
           if length($ini_v);
     
The model (in serialised format) is ready, let s return it and exit the subroutine:
    return $load;
 ;
Now let s take care of the special cases. This one deals with Driver parameter found in INI [server] class. This sub will create a string for an enum element. The possible values of the enum are extracted from the comment found in the LCDd.conf file:
$dispatch "LCDd::server" Driver  = sub  
    my ( $class, $elt, $info, $ini_v ) = @_;
    my $load = qq!class:"$class"
                    element:$elt
                      type=leaf
                      value_type=enum
    !;
    my @drivers = split /\W+/, $info;
    while ( @drivers
            and ( shift @drivers ) !~ /supported/ )  
      # nothing, the work is done by shift operator
      # in loop test to skip all words in $info until
      # 'The following drivers are supported:'.
      # ok, that's a hack
     
    $load .= 'choice='
          . join( ',', @drivers ) . ' ';
    return $load;
 ;
This sub invokes the default sub and add a small feature to the model to ensure that DriverPath ends with / . This is ensured by the match="/$" snippet:
$dispatch "LCDd::server" DriverPath  = sub  
    my ( $class, $elt, $info, $ini_v ) = @_;
    return   $dispatch _default_ ->(@_)
           . q! match="/$" !;
 ;
Likewise, this sub invokes the default sub with the optional 4th parameter that forces the value_type of the element. In this case, we enforce an integer element:
 $dispatch "LCDd::server" WaitTime 
 = $dispatch "LCDd::server" ReportLevel 
 = $dispatch "LCDd::server" Port 
 = sub  
    my ( $class, $elt, $info, $ini_v ) = @_;
    return $dispatch _default_ ->( @_, 'integer' );
   ;
This sub returns a string for a list element with default values:
  $dispatch "LCDd::server" GoodBye 
= $dispatch "LCDd::server" Hello 
= sub  
    my ( $class, $elt, $info, $ini_v ) = @_;
    my $ret = qq( class:"$class"
                    element:$elt
                      type=list
                ) ;
    $ret .= 'cargo type=leaf
             value_type=uniline - ' ;
    $ret .= 'default_with_init:0="\" '.$elt.'\"" ' ;
    $ret .= 'default_with_init:1="\" LCDproc!\""';
    return $ret ;
 ;
Now that the dispatch table is ready, let s really mine LCDd.conf information. First handle all INI classes in the foreach loop:
foreach my $ini_class (@ini_classes)  
Let s retrieve parameters for this INI class from the LCDd.conf template:
  my $ini_obj = $dummy->grab($ini_class);
This will be the name of the lcdproc driver configuration class (e.g. LCDd::imonlcd):
  my $config_class   = "LCDd::$ini_class";
The configuration class will also be created in a serialised format. Let s create config class in case there s no parameter in INI file:
  $meta_root->load(qq!class:"LCDd::$ini_class"!);
Now, loop over all INI parameters and create LCDd::$ini_class elements:
  my @all_ini_params = $ini_obj->get_element_name ;
  foreach my $ini_param ( @all_ini_params )  
Retrieve the value provided in template LCDd.conf:
    my $ini_v = $ini_obj->grab_value($ini_param);
Retrieve the comment attached to the value provided in template LCDd.conf:
    my $ini_comment
      = $ini_obj->grab($ini_param)->annotation;
    # escape embedded quotes
    $ini_comment =~ s/"/\\"/g;
Retrieve the correct sub from dispatch table:
    my $sub = $dispatch $config_class $ini_param 
              $dispatch _default_ ;
Run the sub to get the model string:
    my $model_spec
      = $sub->( $config_class, $ini_param,
                   $ini_comment, $ini_v );
Attach the comment from LCDd.conf as class description:
    $model_spec .= qq! description="$ini_comment"!
      if length($ini_comment);
Then, last but not least, load class specification in the model, and end the loop aroung INI parameters:
    $meta_root->load($model_spec);
   
Now create a an $ini_class element in LCDd class (to link LCDd class and LCDd::$ini_class):
  my $driver_class_spec = qq!
    class:LCDd
      element:$ini_class
  ! ;
Since server and menu are not drivers, they have a special treatment:
  if (   $ini_class eq 'server'
      or $ini_class eq 'menu' )  
    $driver_class_spec .= qq!
      type=node
      config_class_name="LCDd::$ini_class"
    ! ;
   
Here s the treatment for LCDd drivers. Setup the model with a warped node so that a driver configuration class is shown only if the driver was selected in the [server] class:
  else  
    $driver_class_spec .= qq!
      type=warped_node
      config_class_name="LCDd::$ini_class"
      level=hidden
      follow:selected="- server Driver"
      rules:"\$selected eq '$ini_class'"
        level=normal
    !;
   
Now we can load the LCDd driver model in meta root:
  $meta_root->load($driver_class_spec);
 
Step 5: save LCDd model Still with me ? Good. Here s the last part, now that the model was created in memory, let s save it in files. Config::Model::Itself constructor returns an object to read or write the data:
my $rw_obj = Config::Model::Itself
     ->new( model_object => $meta_root );
say "Writing all models in file (please wait)";
$rw_obj->write_all(
    model_dir => 'lib/Config/Model/models/'
);
That s it. Once this script is run, the directory lib/Config/Model/models/ contains a bunch of files: You can see the resulting editor in my first blog on lcdproc. Conclusion and future steps (with you?) As mentioned at the end of this blog, the result of this model generation process is far from perfect, because the information retrieved from LCDd.conf template are not complete for this task (which is normal since these comments were targeted for users). Now, I d really like to discuss with project developers to improve configuration template to generate better models. For project owner, such an improvement would give them: Please leave a comment on this blog (or send a message to config-model-users at lists.sourceforge.net) if you are interested in configuration tool generation for a project you contribute to. All the best

Rapha&#235;l Hertzog: My Debian activities in June 2011

This is my monthly summary of my Debian related activities. If you re among the people who made a donation to support my work (195 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. Dropbox for Debian This is not free software but Dropbox is very popular and they did only provide an Ubuntu package that did not work on Debian. So I created an official package. I have been in touch with Dropbox developers and they have been very helpful. They ll shortly release a signature mechanism (with GPG) so that we can further improve the package by verifying the origin of the downloaded binaries. SAT Britney At the start of the month, I continued my work on the britney reimplementation (the software that creates testing out of unstable) but I quickly stalled it because the release managers asked the feedback of Stefano Zacchiroli and Ralf Treinen (who have extensive knowledge on the topic with their research work on Mancoosi) and I did not want to invest further work in case they would identify a major flow the feedback came only very late this month and while it was somewhat negative, I still think it s worth pursuing the effort for a bit longer. Converted ftplib to multiarch While dpkg still doesn t support multiarch (no news from Guillem and no visible sign of progress :-( ), unstable got all the remaining bits allowing us to convert libraries to multiarch (see the announce). As soon as the required libc6 landed in unstable, I looked into converting the only library package that I maintain. I had no major problem but I still identified 2 issues in Lintian (filed as #630164 and quickly fixed by Niels Thykier). build-arch / build-indep support For the 42th time in the last 10 years, the idea of using build-arch/build-indep targets in the rules file has surfaced again. I had already decided some time ago that I would accept a patch implementing a new field Build-Features to enable dpkg-buildpackage to use those targets and this time Bill Allombert completed such a patch so I merged it. The technical committee also decided that it would take a final decision on this topic (see #629385). Roger Leigh provided useful input by doing an archive-wide rebuild with the various solutions suggested. Given that the majority would like to make the target mandatory at some point in the future, I provided the dpkg patch for my preferred solution. We would use auto-detection as a temporary measure until all packages have been converted to have the targets. The technical committee has not yet taken any decision even though the discussion stalled since the 12th of June. But that s usual with that body. I m sure it will be solved during Debconf. ;-) Misc dpkg work Hamster applet update Hamster-applet is a GNOME application which did not have a 3.0 release, but it had a development release (2.91.x). I checked out whether it was possible to package this version for experimental and have the applet work with the GNOME fallback mode. Apparently not, the code was not yet updated to be compatible with the newer panel. Instead I uploaded the latest stable version (2.32.1) to unstable. It has some nice improvements in the standalone version (and the name of the executable changed). For usage with GNOME 3, I have created a custom shortcut to start it quickly (with gconf-editor set /apps/metacity/global_keybindings/run_command_1 to <Mod4>t and /apps/metacity/keybinding_commands/command_1 to hamster-time-tracker because the GNOME 3 control panel does not seem to work to set custom keybindings currently). Translated my professional website into English While I m grateful for all the people who are supporting my work, I m still far from my goal to have one third of my time funded through donations and sales of products on this blog. So I decided to also bring more visibility to my company and in particular to its Debian-related service offering. It was only available in French up to now so I translated it and expanded it a bit. My support page on this blog now also links to my company s website. If your company needs help to create Debian packages, or needs Debian technical support by email, you just found the right partner. :-) BTW, I have discounted prices for individuals and non-profits who would like to benefit from my help to create Debian packages. The Debian Administrator s Handbook This is the title of the upcoming translation of my book. The project now has a dedicated website: debian-handbook.info. You can subscribe to its RSS feed to keep up with the latest news. The full table of contents is online along with a FAQ. I m actively looking for partners to help me promote the fundraising once it goes live. If you can reach a large set of readers interested by a good Debian book, get in touch with me to join the affiliate program. Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Russell Coker: Can Online Dating make You Depressed?

Anne Rettenberg wrote an article for Psychology Today that is critical of the idea of online dating [1], she cites one example of a man who visited a prostitute due to being depressed at his lack of success in online dating to support her claim. The first big problem with her article is that she doesn t mention the different experiences that male and female customers presumably have on online dating sites. I don t know what it s like for women on the dating sites so I can t comment on that. But I m sure that someone who works as a counselor could provide some useful insight into this matter. Also she didn t even give a mention to the issue of gay/lesbian dating sites. The next issue is that she didn t offer any good advice for who should use online dating sites and what their aims should be. Rejection In dating in real life (IRL) it s expected that the man make the first move, and therefore women end up rejecting lots of guys for various reasons. Anne seems to think that rejection online is somehow worse than rejection IRL, it probably is for some people but that certainly isn t the case for everyone. The way that lots of dating sites seem to work is that women place adverts, men respond to them, and then the women reply to a small subset of the email that they receive. Rejection in this case isn t a matter of telling someone that you aren t interested, but of merely not replying to their mail. From my discussions with a few men who ve used online dating sites the strategy seems to be to send out initial messages to a few dozen women every day and then maybe get a few responses a day. For the messages that get no response you will never know whether the other person found someone else first, wasn t interested in you for some reason, or just didn t bother checking their email. The only comparison to IRL rejection is that which happens after phone numbers have been exchanged, which isn t going to be that common (and has the same issues regardless of how the people met). Guys, relax about the women who don t respond to your first message. They probably get 100+ responses to their advert and don t have time to even read half of them. If you get rejected later in the process then you can look through your email archive at a later date to try and discover what went wrong. The Aim of Online Dating The fact that Anne s client visited a prostitute suggests that maybe he wasn t really after a relationship. In which case using one of the many online services for finding sex partners might have been a better option. Generally it seems that a good strategy is to try and have fun. I don t know any men who have married someone from a dating site, but the general opinion seems to be that they are still worth using. If you meet someone in a bar then you might end up having a drunken conversation that is drowned out by loud music. If you meet someone over the Internet then you can have a quiet conversation over the phone which seems to be a better way to get to know someone (and generally more pleasant for anyone who s not an alcoholic). I think that men who have no immediate aim other than finding someone nice to talk to will do better than those who aim to score quickly. Of the men I know who married women they met over the Internet (but not through online dating sites) I wonder how many of them would have ended up married if they hadn t used the online dating sites first. It seems that men who regularly communicate with women outside formal situations (work etc) will have a better chance of impressing someone that they like than those who lack such experience. Introverts There are a lot of people who really can t function in a bar. With the way our society works it seems that anyone who can t handle the bar scene really should consider online dating. How Counselors can Help It seems to me that someone who is seeing a counselor and who is considering a new way of finding a SO should ask their counselor for advice first. It also seems to me that a good option might be to ask their counselor for advice in online dating. Instead of being unsuccessful and depressed a man who was seeing a female counselor could do well to ask her advice for how to impress women on the Internet. This is probably a business opportunity for female counselors who can advise men on such things, among other things it seems that seeing an online relationship coach would be perceived in a more positive manner than seeing a counselor or psychologist for the more traditional reasons.

Erich Schubert: Google vs. Facebook

Let the games begin. It looks like Google and Facebook are going to fight it out.
Given the spectacular failures of Wave and Buzz, people are of course skeptic about the success of Google Plus. However, I'm rather confident it is going to stay. Here are some things I like about it:
Some people think that Google will not stand a chance against social giant Facebook. But after all, Google has more users - and they have tons of services people like to use. So when Google Maps has Plus integration, will the users use it to chat about where to meet, or will they go the long way and post the map URL on Facebook, without the option of updating it collaboratively?
Googles position is much stronger than many people believe, once you think about integration possibilities. The current Plus is just a fragment, the missing puzzle piece connecting the other apps. But imagine that Google now Plus-connects its various services: YouTube, Maps, Mail, Talk, ... - for them, this is just a matter of some engineering. I guess probably half of these are already in internal testing. And Facebook just can't keep up there. Sure, they do have Facebook Video. But actually, most people prefer YouTube. And while Google can integrate plus all the way there, Facebook cannot. And while Google is the master of search, Facebook is particularly weak there - they can't even properly search their own data. Google however will at some point offer an "find things that interest me" button; Sparks is just the beginning where you have to manually define your interests (which will probably remain an option due to privacy concerns!); it is way too static right now.
So essentially, Google doesn't need to copy Facebook. They just need to do what is obvious on their own products, and Facebook will have a hard time keeping up.
Plus, in my opinion, Google got the timing just right. Users aren't too happy with Facebook these days, there is just no big alternative around anymore; their friends are on Facebook and not on some other social network. Facebook doesn't seem to evolve much anymore. The mail functionality opened more security holes (apparently you can post to a group with a fake user name when you spoof the senders email address) than it contributed to functionality and usefulness. Privacy is still not in line with all countries such as Germany; but Facebook keeps telling those users essentially that they don't care. Spam and fraud still reappears every month following the same pattern again and again (Clickjacking). The search function of Facebook is still usually described as "useless" ... People waste time in games and annoy their friends with random game invitations and posts. Facebook should better make a major move now, too. More than a demo of Skype integration. But whenever Facebook changed, their users complained ...

Of course, Google+ still has a long way to go, too. There are still many things missing here, too. For example groups and events. I figure Google is already testing them in "dogfood", and they'll actually come out within the month. With groups I do not refer to the existing Google product, but to what would be "public circles" that you need to join and that are accessible to all the circle members instead of just the creator. And events are also a key function; probably one of the most used on Facebook. These may require much more careful design to integrate well with Calendar. But given the visual update of Calender these days, this may just be around the corner, too.

2 July 2011

Guillaume Mazoyer: Status report Jigsaw num. 3 for GSoC 2011

code.pngAt beginning of the last two weeks, I was working on the final package of JTReg. I was working on generating man pages and I finally found a solution. I decided to use help2man to generate the man pages but I had to patch the two scripts jtreg.sh and jtdiff.sh . Basically, these two scripts launch main classes of the jtreg.jar JAR file. The problem with them is that they don t know where they can find the JAR file on Debian. So I patched the two scripts shell so they can locate JAR files in /usr/share/java .
To be able to generate man pages with help2man, I needed to be able to use the scripts. But with jtdiff.sh and jtreg.sh using jtreg.jar which is not in /usr/share/java during the build, I had to find a way to make the scripts work. I decided to patch the scripts (again) and make them depend of some environment variables. So in each script, there are 4 used variables: So during the packaging only JTREG_HOME needed to be changed to be able to use the script. Once the scripts patch done, I finally wrote the rules file of the package. Once again, I used javahelper so the rules file contains the following code:

#!/usr/bin/make -f
JAVA_HOME = /usr/lib/jvm/default-java

override_dh_auto_build:
ant -f make/build.xml
dh_auto_build
JTREG_HOME=./dist/jtreg/lib/ help2man \
--name="Regression Test Harness" \
--help-option="-help" \
./dist/jtreg/linux/bin/jtdiff > jtdiff.1
JTREG_HOME=./dist/jtreg/lib/ help2man \
--name="Regression Test Harness" \
--help-option="-help" \
./dist/jtreg/linux/bin/jtreg > jtreg.1

override_dh_auto_clean:
rm -r dist :
rm -r build :
rm jtdiff.1 :
rm jtreg.1 :
dh_auto_clean

%:
dh $@ --with javahelper


As you can see it is not really complicated. The most interesting part is the one when the man pages are generated. The JTREG_HOME variable is set to ./dist/jtreg/lib/ because it is the path where jtreg.jar is once it is built. I also used the help-option option of help2man because the help option of jtreg and jtdiff is -help and not help .
The jtreg package is now on the Debian Java team SVN so anyone can get it using:

svn checkout svn+ssh://$ SVN_USER @svn.debian.org/svn/pkg-java/trunk/jtreg

Thanks to Sylestre Ledru, jtreg is now available in Sid and the ITP is now closed.

The second part of my work consisted in testing Jigsaw and fixed tests if necessary. All the packaging work is now useful since the tests need JTReg to be run. The problem with the current build system of Jigsaw is that it is enough generic to be used on any system. So I had to patch several makefiles. To find them:

cd jigsaw-tests
find . -name 'Makefile' grep '/test/Makefile'

Then, the path to find jtreg has to be modified to match /usr/bin/jtreg . After that it is possible to run the tests with the following command:

make test

Passing all the tests is something which takes a lot of time. After that, I identified 42 (that s a cool number right?) failing tests. Some of them came from the lack of X11 server and other from unreachable network hosts. Some hackers of IcedTea gave me some ideas to fix several tests. They told me to look here and here because I just had the same problems that they had before.
With this, I was able to fix the tests related to unreachable hosts and to the lack of X server. I used Xvfb to fix the X server depending tests.
After running the tests again, only 13 tests were still failing. That is a good result. Tom Marble and me decided to apply the patch of Alan Bateman and re-run the tests to see if it will break something:

cd jigsaw-tests
mkdir patches && cd patches
wget http://cr.openjdk.java.net/~alanb/jigsaw-mp-prototype1/webrev/jdk.patch
cd jdk
patch -p1 < ../patches/jdk.patch
make clean
make sanity
make all
make modules
xvfb-run -e xvfb-errors -a -s -ac make test -k


15 tests failed against 13 before. The 2 new failing tests are: I didn t go further but I ll try to understand why we have 15 failing tests in few days. All the modifications that I have made on the source code of Jigsaw can be found in a patch format here:

This 2 weeks were also dedicated to the understanding of Jigsaw and its modules. Reading the jigsaw-dev mailing list, I have found some interesting conversation about jigsaw and how to write modules. So I decided to write a module to see how it works. I followed the instruction of the quick start guide but when compiling the module didn t work. So I tried to understand why and then to fix it. I eventually compiled and installed my module and here is how I did it:

mkdir -p src/com.greetings/com/greetings/
mkdir -p src/org.astro/org/astro/
mkdir modules
vim src/com.greetings/module-info.java
vim src/com.greetings/com/greetings/Hello.java
vim src/org.astro/module-info.java
vim src/org.astro/org/astro/World.java
./jigsaw/build/linux-amd64/bin/javac -d modules \
-modulepath ./jigsaw/build/linux-amd64/modules/modules \
-sourcepath src find src -name '*.java'
./jigsaw/build/linux-amd64/bin/jmod create -L mlib
./jigsaw/build/linux-amd64/bin/jmod install \
modules org.astro com.greetings -L mlib
./jigsaw/build/linux-amd64/bin/java -L mlib -m com.greetings


And here it is, we have a nice hello world module. The documentation says to put the module-info.java of org.astro in src/org.astro/org/astro/ but it didn t work for me so I tried to put it in src/org.astro/ and it worked. Also the quick start guide says that we have to use the -modulepath option to specify where the modules are. I first tried to use ./jigsaw/build/linux-amd64/modules/ but javac told me he could not find java.lang so I noticed that there is a subdirectory called modules in ./jigsaw/build/linux-amd64/modules/ so I used it as module path and it worked.

Writing a module and seeing how Jigsaw modules are made started to make me think about the packaging of Jigsaw. Dependencies being available, knowing how to build and test Jigsaw and seeing how modules are made, I think that I will soon try to start the packaging of Jigsaw and getting started with the packaging will be my goal for the next two weeks.

30 June 2011

Jordi Mallach: Cinema d'Estiu de Benimaclet 2011

Yeah! It's this time of the year: Friday evenings after work with your friends having some cool beer on the streets, Saturdays around the nearby mountains for a good hike and swimming in a lake or river, and good beach Sunday in a Valencian beach. And for a great ending of a Summer weekend, a good indie movie in your neighbourhood, reclaiming the streets and going back to our roots, when people perceived the public spaces as theirs, and would bring foldable chairs out, would gather with their neighbours and had a good after-dinner chat a la fresca. The always active Associaci de Ve ns i Ve nes de Benimaclet has organized, for the fifth year four cinema projections in Benimaclet's square, which are open for anyone who wants to share good moments with us. The program this year includes Soul Kitchen (3rd of July), When the Wind Blows (10th), Concursante (17th) and Moon (24th). Before every movie, we'll enjoy live music by local bands, and projections of good short films. We'll be happy to see you there, and remember you only need a chair and some dinner... but be sure to be there a bit before 22:00: last year this got so popular some people started having issues to find good spots for their chairs!

Next.

Previous.