Search Results: "tar"

31 October 2015

Andrew Cater

Ken Starks (Helios) of Reglue could use your help

I'm not normally one to respond to online appeals for money: there are often far too many of them. Ken Starks is a well known Linux personality who set up a charity to provide needy local people with Linux and recycled machines. He's also a good guy who works hard for this as something he believes in: this is no scam. The Helios Project (from before his own charity merged with another known as Reglue) is also still an SPI project as far as I know

Ken is currently holding a fund raising drive to replace his vehicle used for the Reglue project on Indiegogo. This is probably most of interest to US readers who may be able to treat this as charitable donation - the things he's offering in return for donations are most readily shipped within the US and Canada.

Any and all help would be greatly appreciated.


Jonathan McDowell: Thoughts on the LG G Watch R Android smartwatch

Back in March I was given an LG G Watch R, the first Android Wear smartwatch to have a full round display (the Moto 360 was earlier, but has a bit cut off the bottom of the actual display). I d promised I d get round to making some comments about it once I d had it for a while and have failed to do so until now. Note that this is very much comments on the watch from a user point of view; I haven t got to the point of trying to do any development or other hacking of it. Firstly, it s important to note I already was wearing a watch and have been doing so for all of my adult life. Just a basic, unobtrusive analogue watch (I ve had a couple since I was 18, before that it was pretty much every type of calculator watch available at some point), but I can t remember a period where I didn t. The G Watch R is bulkier than what I was previously wearing, but I haven t found it obtrusive. And I love the way it looks; if you don t look closely it doesn t look like a smart watch (and really it s only the screen that gives it away). Secondly, I already would have taken my watch off at night and when I was showering. So while the fact that the battery on the G Watch R will really only last a day and a half is by far and away its most annoying problem, it s not as bad as it could be for me. The supplied charging dock is magnetic, so it lives on my beside table and I just drop the watch in it when I go to bed. With those details out of the way, what have I thought of it? It s certainly a neat gadget. Being able to see my notifications without having to take my phone out of my pocket is more convenient than I expected - especially when it s something like an unimportant email that I can then easily dismiss by swiping the watch face. My agenda being just a flick away, very convenient, particularly when I m still at the stage of trying to remember where my next lecture is. Having walking directions from Google Maps show up on the watch (and be accompanied by a gentle vibration when I need to change direction) is pretty handy too. The ability to take pictures via the phone camera, not so much. Perhaps if it showed me roughly what I was about to photograph, but without that it s no easier than using the phone interface. It s mostly an interface for consuming information - I ve tried the text to SMS interface a few times, but it s just not reliable enough that I d choose to use it. I ve also been pleased to see it get several updates from LG in the time I ve had it. First the upgrade from Wear 4.4 to Wear 5.1 (probably via 5.0 but I forget), but also the enabling of wifi support. The hardware could always support this, but initially Android Wear didn t and then there was some uncertainty about the FCC certification for the G Watch R. I can t say I use it much (mostly the phone is within range) but it s nice to see the improvements in support when they re available. What about the downsides? Battery life, as mentioned above, is definitely the major one. Mostly a day is fine, but the problem comes if I m ever away. There s no way to charge without the charging dock, so that becomes another things I have to pack. And it s really annoying to have your watch go dead on you midday when you forget to do so. I also had a period where I d frequently (at least once a week) find an Android Wear isn t responding. Wait/Restart? error on the watch screen. Not cool, but thankfully seems to have stopped happening. Finally there s the additional resource requirements it puts on the phone. I have a fairly basic Moto G 4G that already struggles with Ingress and Chrome at the same time, so adding yet another thing running all the time doesn t help. I m sure I could make use of a few more apps if I was more comfortable with loading the phone. The notable point for me with the watch was DebConf. I d decided not to bring it, not wanting the hassle of dealing with the daily charging. I switched back to my old analogue watch (a Timex, if you care). And proceeded to spend 3 days looking at it every time my phone vibrated before realising that I couldn t do that. That marked the point where I accepted that I was definitely seeing benefits from having a smart watch. So when I was away for a week at the start of September, I brought the charger with me (at some point I ll get round to a second base for travel). I was glad I d done so. I m not sure I m yet at the point I d replace it in the event it died, but on the whole I m more of a convert that I was expecting to be.

30 October 2015

Dirk Eddelbuettel: littler 0.3.0 -- on CRAN !!

max-heap image A new major release of littler is now available. And for the first time in the nine years since 2006 when Jeff started the effort (which I joined not long after) we are now a CRAN package. This required a rewrite of the build system, foregoing the calls to aclocal, autoheader, automake and leaving just a simpler autoconf layer creating a configure script and a simple src/Makevars.in. Not only does R provide such a robust and well-understood build system (which I got to understand reasonably well given all my R packages, but being on CRAN and leveraging its mechanism for installation and upgrades is clearly worth the change. There may be a moment or two of transition. While we can create a binary in an R package, we cannot (generally) copy to /usr/bin or /usr/local/bin as part of the build process (for lack of write-rights to those directories). So if you do not have r in the $PATH and load the package, it makes a suggestion (which needs a linebreak which I added here):
R> library(littler)
The littler package provides 'r' as a binary.
You could link to the 'r' binary installed in
'/usr/local/lib/R/site-library/littler/bin/r' from
'/usr/local/bin' in order to use 'r' for scripting.
R> 
Similarly, you could copy (or softlink) r to ~/bin if that is in your $PATH. The Debian (and Ubuntu) packages will continue to provide /usr/bin/r as before. Note thah these packages will now be called r-cran-littler to match all other CRAN packages. The NEWS file entry is below.
Changes in littler version 0.3.0 (2015-10-29)
  • Changes in build system
    • First CRAN Release as R package following nine years of source releases
    • Script configure, src/Makevars.in and remainder of build system rewritten to take advantage of the R package build infrastructure
    • Reproducible builds are better supported as the (changing) compilation timestamps etc are only inserted for 'verbose builds' directly off the git repo, but not for Debian (or CRAN) builds off the release tarballs
  • Changes in littler functionality
    • Also source $R_HOME/etc/Rprofile.site and ~/.Rprofile if present
  • Changes in littler documentation
    • Added new vignette with examples
Full details for the littler release are provided as usual at the ChangeLog page. The code is available via the GitHub repo, from tarballs off my littler page and the local directory here -- and now of course all from its CRAN page and via install.packages("littler"). A fresh package has gone to the incoming queue at Debian where it will a few days as the binary packages was renamed from littler to r-cran-littler matching all other CRAN packages. Michael Rutter will probably have new Ubuntu binaries at CRAN once the source package gets into Debian proper. Comments and suggestions are welcome at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Laura Arjona: Look at that nice looking FreedomBox!

This is a guest post by Alberto Fuentes, Debian contributor. Thanks!! I m rebuilding one my home server and decided to take a look at the FreedomBox project as the base for it. The 0.6 version was recently released and I wasn t aware of how advanced the project is already! They have a virtualbox image ready for some quick test. It took me longer to download it than to start using it. Here s is a pic of what it looks like to entice you to try it :) Selection_175
All this is already on debian right now and you can turn any debian sid installation into a FreedomBox just by installing a package. The setup generates everything private on the first run, so even the virtualbox image can be used as the final thing They use Plinth (Django) to integrate the applications into the web interface. More info on how to help integrate more Debian packages here. A live demo is going to be streamed this Friday 30 Oct 2015 and a hackaton is scheduled for this saturday 31 Oct 2015. Cheers!
Filed under: My experiences and opinion Tagged: Debian, English, Freedom, FreedomBox, selfhosting

29 October 2015

B lint R czey: FFmpeg and Kodi arrived to jessie-backports!

FFmpeg Kodi Debian JessieDebian has switched to FFmpeg in testing in July but the work on the package did not stop at that point. After careful testing we can now provide official packages for Jessie users through jessie-backports. See installation instructions here. FFmpeg becoming available in jessie-backports also enabled us to provide Kodi from Debian in the same official repository. Thanks to everyone in the Debian Multimedia Maintainers team, especially Andreas Cadhalpun who is also upstream developer at the FFmpeg project, Reinhard Tartler who maintained FFmpeg then Libav then FFmpeg again in Debian for long years and everyone else I could not name here but helped making this possible!

Daniel Pocock: Lumicall rapid provisioning, Opus support and other enhancements

Thanks to feedback from many people at DebConf15, Lumicall has had a range of improvements over the last couple of months and it is now easier to use and more reliable than ever. Rapid provisioning for Debian.org, FedRTC.org and other SIP accounts 1. Setup your SIP password in the Debian LDAP or the FedRTC account setup (using Fedora OpenID) or any other SIP service that supports rapid provisioning (see the FAQ). 2. Install the Lumicall app from F-Droid, Google Play or by direct download. 3. When the app starts the first time, you can verify your phone number (so other users can call you using the number they know) or just click the "Manual account setup" link underneath the verification button. If you do verify your number, the "Add account" link is also available in the menu from the main screen. Test calls If a friend installs Lumicall too and you dial their number, the Lumicall popup should appear and give you the option to make the call over SIP. You can also make test calls using this link for a recorded announcement. Many other improvements
  • Support for the OPUS codec, which brings us one step closer to direct WebRTC interoperability
  • Fixing a bug in ice4j that caused NAT traversal to fail intermittently
  • Tweaks to make it more tolerant of IPv6 networks
  • The rapid account setup form (described above) for existing SIP accounts
  • Conversion to the Gradle build system (for Android Studio)
  • Breaking out embedded library code from the Lumicall repository into standalone projects so they can be maintained independently
  • Use of the compatibility library to display the ActionBar, consistent with the current design guidelines, while still maintaining compatibility with older devices
  • Use of Spongy Castle instead of Bouncy Castle crypto library for more consistent behavior across different Android devices
Share your experiences with Lumicall All feedback is welcome. If you can come in person to the workshop in Manchester (2 November) or the mini-DebConf in Cambridge (I'll be there Saturday, 7 November) then we can look at any problems in person and access logs with the Android tools if necessary. Discussion is also welcome on the Lumicall users mailing list or the Free RTC mailing list.

Daniel Pocock: reSIProcate 1.10 release

reSIProcate 1.10.0 was released a few weeks ago and after going through the various QA cycles has become available in packages for Debian jessie-backports, EPEL6 and EPEL7 and the latest releases of Fedora and Ubuntu. Key features of the 1.10.x branch: A 1.10.1 release was tagged yesterday and is not yet widely available in packages. This release is only significant for people using RADIUS authentication and keen to change from the FreeRADIUS-client library to radcli.

Joey Hess: concurrent output library

concurrent-output is a Haskell library I've developed this week, to make it easier to write console programs that do a lot of different things concurrently, and want to serialize concurrent outputs sanely. It's increasingly easy to write concurrent programs, but all their status reporting has to feed back through the good old console, which is still obstinately serial. Haskell illustrates problem this well with this "Linus's first kernel" equivilant interleaving the output of 2 threads:
> import System.IO
> import Control.Concurrent.Async
> putStrLn (repeat 'A')  concurrently  putStrLn (repeat 'B')
BABABABABABABABABABABABABABABABABABABABABABABABABABABABABABABABABABABABABABABA
...
That's fun, but also horrible if you wanted to display some messages to the user:
> putStrLn "washed the car"  concurrently  putStrLn "walked the dog"
walwkaesdh etdh et hdeo gc
ar
To add to the problem, we often want to run separate programs concurrently, which have output of their own to display. And, just to keep things interesting, sometimes a unix program will behave differently when stdout is not connected to a terminal (eg, ls cat). To tame simple concurrent programs like these so they generate readable output involves a lot of plumbing. Something like, run the actions concurrently, taking care to capture the output of any commands, and then feed the output that the user should see though some sort of serializing channel to the display. Dealing with that when you just wanted a simple concurrent program risks ending up with a not-so-simple program. So, I wanted an library with basically 2 functions:
outputConcurrent :: String -> IO ()
    
createProcessConcurrent :: CreateProcess -> IO whatever
The idea is, you make your program use outputConcurrent to display all its output, and each String you pass to that will be displayed serially, without getting mixed up with any other concurrent output. And, you make your program use createProcessConcurrent everywhere it starts a process that might output to stdout or stderr, and it'll likewise make sure its output is displayed serially. Oh, and createProcessConcurrent should avoid redirecting stdout and stderr away from the console, when no other concurrent output is happening. So, if programs are mostly run sequentially, they behave as they normally would at the console; any behavior changes should only occur when there is concurrency. (It might also be nice for it to allocate ttys and run programs there to avoid any behavior changes at all, although I have not tried to do that.) And that should be pretty much the whole API, although it's ok if it needs some function called by main to set it up:
import Control.Concurrent.Async
import System.Console.Concurrent
import System.Process
main = withConcurrentOutput $
    outputConcurrent "washed the car\n"
         concurrently 
    createProcessConcurrent (proc "ls" [])
         concurrently 
    outputConcurrent "walked the dog\n"
$ ./demo
washed the car
walked the dog
Maildir/  bin/  doc/  html/  lib/  mail/  mnt/  src/  tmp/
I think that's a pretty good API to deal with this concurrent output problem. Anyone know of any other attempts at this I could learn from? I implemented this over the past 3 days and 320 lines of code. It got rather hairy: It seems to work pretty great though. I got Propellor using it, and Propellor can now run actions concurrently!

28 October 2015

Simon Richter: CEC remote control with Onkyo Receivers

For future reference: if you have an Onkyo AV receiver, these are picky about the CEC logical address of the player. If you have a default installation of Kodi, the default type is "recording device", and the logical address is 14 -- this is rejected. If you change the CEC device configuration, which can be found in .kodi/userdata/peripheral_data/ to use a device_type of 4 (which maps to a logical address of 4), then the receiver will start sending key events to Kodi. You may also need to set your remote control mode to 32910, by pressing the Display button in combination with the input source selector your Pi is connected to for three seconds, and then entering the code. This setting is not available from the GUI, so you really have to change the XML file. Next step: finding out why Kodi ignores these key presses. :(

Daniel Pocock: Free Real-Time Communications workshop in Manchester, 2 November

Manchester Free Software and MadLab are hosting a workshop on Free and Federated Real-Time Communications with Free Software next Monday night, 2 November from 7pm. Add this to your calendar (iCalendar link) Users and developers are invited to come and discover the opportunities for truly free and secure chat, voice and video with WebRTC, mobile VoIP and the free desktop. This is an interactive workshop with practical, hands-on opportunities to explore this topic, see what works and what doesn't and learn about troubleshooting techniques to help developers like myself improve the software. This is also a great opportunity for any Java developers who would like to get some exposure to the Android platform. People wishing to fully participate in all the activities are encouraged to bring a laptop with the Wireshark software and Android tools (especially adb, the command line utility) or if you prefer to focus on WebRTC, have the latest version of Firefox and Chrome installed. If you are keen to run the DruCall module for WebRTC or your own SIP or XMPP server, you can try setting it up as described in the RTC Quick Start Guide and come along to the workshop with any questions you have. A workshop near you? Manchester has a history of great technological innovation, including the first stored program computer and it is a real thrill for me to offer this workshop there. FSFE Manchester ran a workshop evaluating the performance of free software softphones back in 2012. Over the coming months, I would like to be able to hold further workshops in other locations to get feedback from people who are trying this technology, including the Lumicall app, JSCommunicator and DruCall. If you are interested in helping organize such an event or you have any other feedback about this topic, please come and discuss it on the Free RTC mailing list.

Martin-Éric Racine: xf86-video-geode: Last call, dernier s vice

I guess that the time has finally come to admit that, as far as upstream development is concerned, the Geode X.Org driver is reaching retirement age:
While there have indeed been recent contributions by a number of developers to keep it compilable against recent X releases, the Geode driver has accumulated too much cruft from the Cyrix and NSC days, and it hasn't seen any active contribution from AMD in a long time. Besides, nowadays, Xserver pretty much assumes that its runs on an X driver that leverages its matching kernel driver and thus won't require root priviledges to launch. This isn't the case with the Geode driver, since it directly probes FBDEV and MSR, both of which reside in /dev and require root priviledges to access.
On Debian, as a stopgap measure, the package now Recommends a legacy wrapper that enforces operation as root. Meanwhile, other distributions are mercilessly droping all X drivers that don't leverage KMS. Basically, unless a miracle happens really quick, Geode will soon become unusable on X.
Back when AMD was still involved, a concensus had been reached that, since the Geode series doesn't offer any sort of advanced graphic capabilities, the most sensible option would indeed be to make a KMS driver and let Xserver use its generic modeline driver on top of that, then drop the Geode X driver entirely. Amazingly enough, someone did start working on a KMS driver for Geode LX, but it never made it as far as the Linux kernel tree (additionally, Gitorious seems to be down, but I have a copy of the driver's Git tree on hand, if anyone is interested). While I'll still be accepting and merging patches to the Geode X driver, our best long-term option would be to finalize the KMS driver and have it merged into Linux ASAP.

John Goerzen: The Train to Galesburg

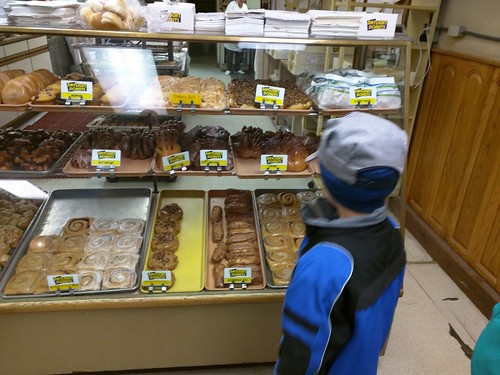
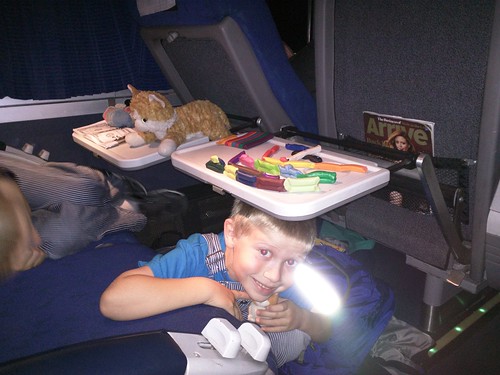
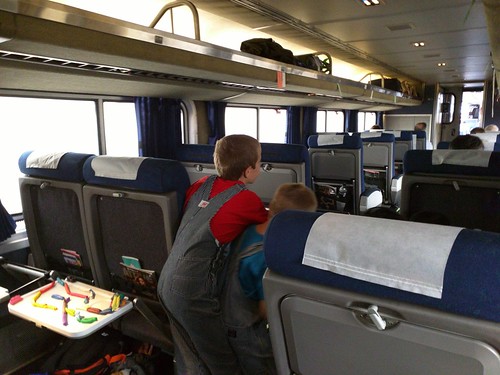
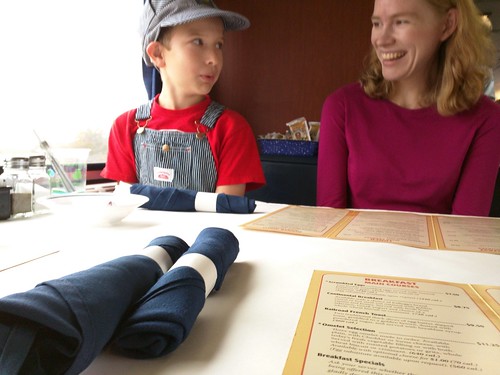
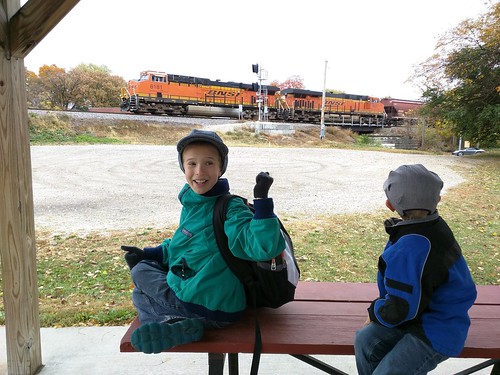
Sometimes, children are so excited you just can t resist. Jacob and Oliver have been begging for a train trip for awhile now, so Laura and I took advantage of a day off school to take them to the little town of Galesburg, IL for a couple days. Galesburg is a special memory for me; nearly 5 years ago, it was the first time Jacob and I took an Amtrak trip somewhere, just the two of us. And, separately, Laura s first-ever train trip had been to Galesburg to visit friends. There was excitement in the air. I was asked to supply a bedtime story about trains I did. On the way to the train station in the middle of the night there was excited jabbering about trains. Even when I woke them up, they lept out of bed and raced downstairs, saying, Dad, why aren t you ready yet? As the train was passing through here at around 4:45AM, and we left home with some time to spare, we did our usual train trip thing of stopping at the one place open at such a time: Druber s Donuts. IMG_20151023_040731 Much as Laura and I might have enjoyed some sleep once we got on the train, Jacob and Oliver weren t having it. Way too much excitement was in the air. Jacob had his face pressed against the window much of the time, while Oliver was busy making snake trains from colored clay complete with eyes. IMG_20151023_062304 The boys were dressed up in their train hats and engineer overalls, and Jacob kept musing about what would happen if somebody got confused and thought that he was the real engineer. When an Amtrak employee played along with that later, he was quite thrilled! We were late enough into Galesburg that we ate lunch in the dining car. A second meal there what fun! Here they are anxiously awaiting the announcement that the noon reservations could make their way to the dining car. Oh, and jockeying for position to see who would be first and get to do the all-important job of pushing the button to open the doors between train cars. IMG_20151023_120143 Even waiting for your food can be fun. IMG_20151023_120728 Upon arriving, we certainly couldn t leave the train station until our train did, even though it was raining. IMG_20151023_145755 Right next to the train station is the Discovery Depot Children s Museum. It was a perfect way to spend a few hours. Jacob really enjoyed the building wall, where you can assemble systems that use gravity (really a kinetic/potential energy experiment wall) to funnel rubber balls all over the place. He sticks out his tongue when he s really thinking. Fun to watch. IMG_20151023_153113 Meanwhile, Oliver had a great time with the air-powered tube system, complete with several valves that can launch things through a complicated maze of transparent tubes. IMG_20151024_150309 VID_20151024_150159 They both enjoyed pretending I was injured and giving me rides in the ambulance. I was diagnosed with all sorts of maladies a broken leg, broken nose. One time Jacob held up the pretend stethoscope to me, and I said ribbit. He said, Dad, you ve got a bad case of frog! You will be in the hospital 190 days! Later I would make up things like I think my gezotnix is all froibled and I was ordered to never leave the ambulance again. He told the story of this several times. After the museum closed, we ate supper. Keep in mind the boys had been up since the middle of the night without sleeping and were still doing quite well! They did start to look a bit drowsy I thought Oliver was about to fall asleep, but then their food came. And at the hotel, they were perfectly happy to invent games involving jumping off the bed. Saturday, we rode over to Peck Park. We had heard about this park from members of our church in Kansas, but oddly even the taxi drivers hadn t ever heard of it. It s well known as a good place to watch trains, as it has two active lines that cross each other at a rail bridge. And sure enough, in only a little while, we took in several trains. IMG_20151024_110035 VID_20151024_110229 The rest of that morning, we explored Galesburg. We visited an antique mall and museum, saw the square downtown, and checked out a few of the shops my favorite was the Stray Cat, featuring sort of a storefront version of Etsy with people selling art from recycled objects. But that wasn t really the boys thing, so we drifted out of there on our way to lunch at Baked, where we had some delicious deep-dish pizza. After that, we still had some time to kill before getting back on the train. We discussed our options. And what do you know we ended up back at the children s museum. We stopped at a bakery to get the fixins for a light supper on the train, and ate a nice meal in the dining car once we got on. Then, this time, they actually slept. Before long, it was 3AM again and time to get back off the train. Oliver was zonked out sleepy. Somehow I managed to get his coat and backpack on him despite him being totally limp, and carried him downstairs to get off the train. Pretty soon we walked to our car and drove home. We tucked them in, and then finally tucked ourselves in. Sometimes being really tired is well worth it.

27 October 2015

Mart n Ferrari: Tales from the SRE trenches: Dev vs Ops

This is the second part in a series of articles about SRE, based on the talk I gave in the Romanian Association for Better Software. On the first part, I introduced briefly what is SRE. Today, I present some concrete ways in which SRE tried to make things better, by stopping the war between developers and SysAdmins.

Dev vs Ops: the eternal battle So, it starts at looking at the problem: how to increase the reliability of the service? It turns out that some of the biggest sources of outages are new launches: a new feature that seemed innocuous somehow managed to bring the whole site down. Devs want to launch, and Ops want to have a quiet weekend, and this is were the struggle begins. When launches are problematic, bureaucracy is put in place to minimise the risks: launch reviews, checklists, long-lived canaries. This is followed by development teams finding ways of side-stepping those hurdles. Nobody is happy. One of the key aspects of SRE is to avoid this conflict completely, by changing the incentives, so these pressures between development and operations disappear. At Google, they achieve this with a few different strategies:

Have an SLA for your service Before any service can be supported by SRE, it has to be determined what is the level of availability that it must achieve to make the users and the company happy: this is called the Service Level Agreement (SLA). The SLA will define how availability is measured (for example, percentage of queries handled successfully in less than 50ms during the last quarter), and what is the minimum acceptable value for it (the Service Level Objective, or SLO). Note that this is a product decision, not a technical one. This number is very important for an SRE team and its relationship with the developers. It is not taken lightly, and it should be measured and enforced rigorously (more on that later). Only a few things on earth really require 100% availability (pacemakers, for example), and achieving really high availability is very costly. Most of us are dealing with more mundane affairs, and in the case of websites, there are many other things that fail pretty often: network glitches, OS freezes, browsers being slow, etc. So an SLO of 100% is almost never a good idea, and in most cases it is impossible to reach. In places like Google an SLO of "five nines" (99.999%) is not uncommon, and this means that the service can't fail completely for more than 5 minutes across a whole year!

Measure and report performance against SLA/SLO Once you have a defined SLA and SLO, it is very important that these are monitored accurately and reported constantly. If you wait for the end of the quarter to produce a hand-made report, the SLA is useless, as you only know you broke it when it is too late. You need automated and accurate monitoring of your service level, and this means that the SLA has to be concrete and actionable. Fuzzy requirements that can't be measured are just a waste of time. This is a very important tool for SRE, as it allows to see the progression of the service over time, detect capacity issues before they become outages, and at the same time show how much downtime can be taken without breaking the SLA. Which brings us to one core aspect of SRE:

Use error budgets and gate launches on them If SLO is the minimum rate of availability, then the result of calculating 1 - SLO is what fraction of the time a service can fail without failing out of the SLA. This is called an error budget, and you get to use it the way you want it. If the service is flaky (e.g. it fails consistently 1 of every 10000 requests), most of that budget is just wasted and you won't have any margin for launching riskier changes. On the other hand, a stable service that does not eat the budget away gives you the chance to bet part of it on releasing more often, and getting your new features quicker to the user. The moment the error budget is spent, no more launches are allowed until the average goes back out of the red. Once everyone can see how the service is performing against this agreed contract, many of the traditional sources of conflict between development and operations just disappear. If the service is working as intended, then SRE does not need to interfere on new feature launches: SRE trusts the developers' judgement. Instead of stopping a launch because it seems risky or under-tested, there are hard numbers that take the decisions for you. Traditionally, Devs get frustrated when they want to release, but Ops won't accept it. Ops thinks there will be problems, but it is difficult to back this feeling with hard data. This fuels resentment and distrust, and management is never pleased. Using error budgets based on already established SLAs means there is nobody to get upset at: SRE does not need to play bad cop, and SWE is free to innovate as much as they want, as long as things don't break. At the same time, this provides a strong incentive for developers to avoid risking their budget in poorly-prepared launches, to perform staged deployments, and to make sure the error budget is not wasted by recurrent issues.
That's all for today. The next article will continue delving into how traditional tensions between Devs and Ops are played in the SRE world. Comment

Wouter Verhelst: Adventures with modern electronics

I got me a new television last wednesday. The previous one was still functional, but with its 20 inch display it was (by today's standards) a very small one. In itself that wasn't an issue, but combined with my rather large movie collection and the 5.1 surround set that I bought a few years ago, my living room was starting to look slightly ridiculous. The new TV is a Panasonic 40" UHD ("4K") 3D-capable so-called smart thing. Unfortunately, all did not go well. When I initially hooked it up, I found it confusingly difficult to figure out how to make it display something useful from the HDMI input rather than from the (not yet connected) broadcast cable. This eventually turned out to be due to the fact that the HDMI input was not selectable by a button marked "AUX" or similar, but by a button marked with some pictogram on a location near the teletext controls, which was pretty much the last place I'd look for such a thing. After crossing that bridge, I popped in the correct film for that particular day and started watching it. The first thing I noticed, however, was that something was odd with the audio. It turned out that the TV as well as the 5.1 amplifier support the CEC protocol, which allows the TV to control some functionality of the A/V receiver. Unfortunately, the defaults were set in the TV to route audio to the TV's speakers, rather than to the 5.1 amp. This was obviously wrong, and it took me well over an hour to figure out why that was happening, and how I could fix it. My first solution at that time was to disable CEC on the amplifier, so that I could override where the audio would go there. Unfortunately, that caused the audio and video to go out of sync; not very pleasant. In addition, the audio would drop out every twenty seconds or so, which if you're trying to watch a movie is horribly annoying, and eventually I popped the DVD into a machine with analog 5.1 audio and component HD video outputs; not the best quality, but at least I could stop getting annoyed about it. Over the next few days, I managed to get the setup working better and better: There's just on thing remaining: when I go into the channel list and try to move some channels around, the TV has the audacity to tell me that it's "not allowed". I mean, I paid for it, so I get to say what's allowed, not you, thankyouverymuch. Anyway, I'm sure I'll figure that out eventually. The TV also has some 3D capability, but unfortunately it's one of those that require active 3D glasses, so the set that I bought at the movie theatre a while ago won't work. So after spending several tens of euros on extra cabling, I'll have to spend even more on a set of 3D glasses. They'll probably be brand-specific, too. Ah well. It's a bit odd, in my opinion, that it takes me almost a week to get all that stuff to properly work. Ten years ago, the old TV had some connections, a remote, and that was it; you hook it up and you're done. Not anymore.

Marco d'Itri: Per-process netfilter rules

This article documents how the traffic of specific Linux processes can be subjected to a custom firewall or routing configuration, thanks to the magic of cgroups. We will use the Network classifier cgroup, which allows tagging the packets sent by specific processes. To create the cgroup which will be used to identify the processes I added something like this to /etc/rc.local:
mkdir /sys/fs/cgroup/net_cls/unlocator
/bin/echo 42 > /sys/fs/cgroup/net_cls/unlocator/net_cls.classid
chown md: /sys/fs/cgroup/net_cls/unlocator/tasks
The tasks file, which controls the membership of processes in a cgroup, is made writeable by my user: this way I can add new processes without becoming root. 42 is the arbitrary class identifier that the kernel will associate with the packets generated by the member processes. A command like systemd-cgls /sys/fs/cgroup/net_cls/ can be used to explore which processes are in which cgroup. I use a simple shell wrapper to start a shell or a new program as members of this cgroup:
#!/bin/sh -e
CGROUP_NAME=unlocator
if [ ! -d /sys/fs/cgroup/net_cls/$CGROUP_NAME/ ]; then
  echo "The $CGROUP_NAME net_cls cgroup does not exist!" >&2
  exit 1
fi
/bin/echo $$ > /sys/fs/cgroup/net_cls/$CGROUP_NAME/tasks
if [ $# = 0 ]; then
  exec $ SHELL:-/bin/sh 
fi
exec "$@"
My first goal is to use a special name server for the DNS queries of some processes, thanks to a second dnsmasq process which acts as a caching forwarder. /etc/dnsmasq2.conf:
port=5354
listen-address=127.0.0.1
bind-interfaces
no-dhcp-interface=*
no-hosts
no-resolv
server=185.37.37.37
server=185.37.37.185
/etc/systemd/system/dnsmasq2.service:
[Unit]
Description=dnsmasq - Second instance
Requires=network.target
[Service]
ExecStartPre=/usr/sbin/dnsmasq --test
ExecStart=/usr/sbin/dnsmasq --keep-in-foreground --conf-file=/etc/dnsmasq2.conf
ExecReload=/bin/kill -HUP $MAINPID
PIDFile=/run/dnsmasq/dnsmasq.pid
[Install]
WantedBy=multi-user.target
Do not forget to enable the new service:
systemctl enable dnsmasq2
systemctl start dnsmasq2
Since the cgroup match extension is not yet available in a released version of iptables, you will first need to build and install it manually:
git clone git://git.netfilter.org/iptables.git
cd iptables
./autogen.sh
./configure
make -k
sudo cp extensions/libxt_cgroup.so /lib/xtables/
sudo chmod -x /lib/xtables/libxt_cgroup.so
The netfilter configuration required is very simple: all DNS traffic from the marked processes is redirected to the port of the local dnsmasq2:
iptables -t nat -A OUTPUT -m cgroup --cgroup 42 -p udp --dport 53 -j REDIRECT --to-ports 5354
iptables -t nat -A OUTPUT -m cgroup --cgroup 42 -p tcp --dport 53 -j REDIRECT --to-ports 5354
For related reasons, I also need to disable IPv6 for these processes:
ip6tables -A OUTPUT -m cgroup --cgroup 42 -j REJECT
I use a different cgroup to force some programs to use my office VPN by first setting a netfilter packet mark on their traffic:
iptables -t mangle -A OUTPUT -m cgroup --cgroup 43 -j MARK --set-mark 43
The packet mark is then used to policy-route this traffic using a dedicate VRF, i.e. routing table 43:
ip rule add fwmark 43 table 43
This VPN VRF just contains a default route for the VPN interface:
ip route add default dev tun0 table 43
Depending on your local configuration it may be a good idea to also add to the VPN VRF the routes of your local interfaces:
ip route show scope link proto kernel \
    xargs -I ROUTE ip route add ROUTE table 43
Since the source address selection happens before the traffic is diverted to the VPN, we also need to source-NAT to the VPN address the marked packets:
iptables -t nat -A POSTROUTING -m mark --mark 43 --out-interface tun0 -j MASQUERADE

26 October 2015

Carl Chenet: db2twitter: get data in database, build and send tweets

db2twitter automatically extracts fields from your database, use them to feed a template of tweet and send the tweet. db2twitter is developed by and run for LinuxJobs.fr, the job board of th french-speaking Free Software and Opensource community. banner-linuxjobs-small Imagine you want to send tweets like this sentence : MyTux hires a #Django developer https://www.mytux.fr/jobs/36 Let s say you have a MySQL database with a database mytuxjobs , a table jobs and fields title and url db2twitter will need the following informations:
dbhost=localhost
database=mytuxjobs
dbuser=mytuxjobs
dbpass=V3rYs3cr3t!
dbtables=jobs,
jobs_rows=title,id
Lets define a template for our tweet:
tweet=MyTux hires a   https://www.mytux.fr/jobs/ "
db2twitter will get data from the database, builds a tweet filling the wildcard of the tweet template with the data from the database, and send the tweet. By default the last row in the given table is used. Cool isn t it? db2twitter is coded in Python 3.4, uses SQlAlchemy (see supported database types) and Tweepy. The official documentation is available on readthedocs.

Steve Kemp: It begins - a new mail client, with lua scripting

Once upon a time I wrote a mail-client, which worked in the console directly via Maildir manipulation. My mail client was written in C++, and used Lua for scripting unlike clients such as mutt, alpine, and similar alternatives which don't have complete scripting support. I've pondered several times whether to restart this project, but I think it is the right thing to do. The original lumail client has a rich API, but it is very ad-hoc and random. Functions were added where they seemed like a good idea, but with no real planning, and although there are grouped functions that operate similarly there isn't a lot of consistency. The implementation is clean in places, elegant in others, and horrid in yet more parts. This time round everything is an object, accessible to Lua, with Lua, and for Lua. This time round all the drawing-magic is will be written in Lua. So to display a list of Maildirs I create a bunch of objects, one for each Maildir, and then the Lua function Maildir.to_string is called. That function looks like this:
--
-- This method returns the text which is displayed when a maildir is
-- to be show in maildir-mode.
--
function Maildir.to_string(self)
   local total  = self:total_messages()
   local unread = self:unread_messages()
   local path   = self:path()
   local output = string.format( "[%05d / %05d] - %s", unread, total, path );
   if ( unread > 0 ) then
      output = "$[RED]" .. output
   end
   if ( string.find( output, "Automated." ) ) then
      output = strip_colour( output )
      output = "$[YELLOW]" .. output
   end
   return output
end
The end result is something that looks like this:
[00001 / 00010 ] - Amazon.de
[00000 / 00023 ] - Automated.root
The formatting can thus be adjusted clearly, easily, and without hacking the core of the client. Providing I implement the apporpriate methods to the Maildir object. It's still work in progress. You can view maildirs, view indexes, and view messages. You cannot reply, forward, or scroll properly. That said the hard part is done now, and I'm reasonably happy with it. The sample configuration file is a bit verbose, but a good demonstration regardless. See the code, if you wish, online here:

Simon Josefsson: Combining Dnsmasq and Unbound

For my home office network I have been using Dnsmasq for some time. Dnsmasq provides me with DNS, DHCP, DHCPv6, and IPv6 Router Advertisement. I run dnsmasq on a Debian Jessie server, but it works similar with OpenWRT if you want to use a smaller device. My entire /etc/dnsmasq.d/local configuration used to look like this:
dhcp-authoritative
interface=eth1
read-ethers
dhcp-range=192.168.1.100,192.168.1.150,12h
dhcp-range=2001:9b0:104:42::100,2001:9b0:104:42::1500
dhcp-option=option6:dns-server,[::]
enable-ra
Here dhcp-authoritative enable DHCP. interface=eth1 says to listen on eth1 only, which is my internal (IPv4 NAT) network. I try to keep track of the MAC address of all my devices in a /etc/ethers file, so I use read-ethers to have dnsmasq give stable IP addresses for them. The dhcp-range is used to enable DHCP and DHCPv6 on my internal network. The dhcp-option=option6:dns-server,[::] statement is needed to inform the DHCP clients of the DNS resolver s IPv6 address, otherwise they would only get the IPv4 DNS server address. The enable-ra parameter enables IPv6 router advertisement on the internal network, thereby removing the need to run radvd too useful since I prefer to use copyleft software. Recently I had a desire to use DNSSEC, and enabled it in Dnsmasq using the following statements:
dnssec
trust-anchor=.,19036,8,2,49AAC11D7B6F6446702E54A1607371607A1A41855200FD2CE1CDDE32F24E8FB5
dnssec-check-unsigned
The dnssec keyword enable DNSSEC validation in dnsmasq, using the indicated trust-anchor (get the root-anchors from IANA). The dnssec-check-unsigned deserves some more discussion. The dnsmasq manpage describes it as follows:
As a default, dnsmasq does not check that unsigned DNS replies are legitimate: they are assumed to be valid and passed on (without the authentic data bit set, of course). This does not protect against an attacker forging unsigned replies for signed DNS zones, but it is fast. If this flag is set, dnsmasq will check the zones of unsigned replies, to ensure that unsigned replies are allowed in those zones. The cost of this is more upstream queries and slower performance.
For example, this means that dnsmasq s DNSSEC functionality is not secure against active man-in-the-middle attacks between dnsmasq and the DNS server it is using. Even if example.org used DNSSEC properly, an attacker could fake that it was unsigned to dnsmasq, and I would get potentially incorrect values in return. We all know that the Internet is not a secure place, and your threat model should include active attackers. I believe this mode should be the default in dnsmasq, and users should have to configure dnsmasq to not be in that mode if they really want to (with the obvious security warning). Running with this enabled for a couple of days resulted in frustration about not being able to reach a couple of domains. The behaviour was that my clients would hang indefinitely or get a SERVFAIL, both resulting in lack of service. You can enable query logging in dnsmasq with log-queries and enabling this I noticed three distinct form of error patterns:
jow13gw dnsmasq 460 - -  forwarded www.fritidsresor.se to 213.80.101.3
jow13gw dnsmasq 460 - -  validation result is BOGUS
jow13gw dnsmasq 547 - -  reply cloudflare-dnssec.net is BOGUS DNSKEY
jow13gw dnsmasq 547 - -  validation result is BOGUS
jow13gw dnsmasq 547 - -  reply linux.conf.au is BOGUS DS
jow13gw dnsmasq 547 - -  validation result is BOGUS
The first only happened intermittently, the second did not cause any noticeable problem, and the final one was reproducible. To be fair, I only found the last example after starting to search for problem reports (see post confirming bug). At this point, I had a confirmed bug in dnsmasq that affect my use-case. I want to use official packages from Debian on this machine, so installing newer versions manually is not an option. So I started to look into alternatives for DNS resolving, and quickly found Unbound. Installing it was easy:
apt-get install unbound
unbound-control-setup 
I created a local configuration file in /etc/unbound/unbound.conf.d/local.conf as follows:
server:
	interface: 127.0.0.1
	interface: ::1
	interface: 192.168.1.2
	interface: 2001:9b0:104:42::2
	access-control: 127.0.0.1 allow
	access-control: ::1 allow
	access-control: 192.168.1.2/24 allow
	access-control: 2001:9b0:104:42::2/64 allow
	outgoing-interface: 155.4.17.2
	outgoing-interface: 2001:9b0:1:1a04::2
#	log-queries: yes
#	verbosity: 2
The interface keyword determine which IP addresses to listen on, here I used the loopback interface and the local address of the physical network interface for my internal network. The access-control allows recursive DNS resolving from those networks. And outgoing-interface specify my external Internet-connected interface. log-queries and/or verbosity are useful for debugging. To make things work, dnsmasq has to stop providing DNS services. This can be achieved with the port=0 keyword, however that will also disable informing DHCP clients about the DNS server to use. So this has to be added in manually. I ended up adding the two following lines to /etc/dnsmasq.d/local:
port=0
dhcp-option=option:dns-server,192.168.1.2
Restarting unbound and dnsmasq now leads to working (and secure) internal DNSSEC-aware name resolution over both IPv4 and IPv6. I can verify that resolution works, and that Unbound verify signatures and reject bad domains properly with dig as below, or use online DNSSEC resolver test page although I m not sure how confident you can be in the result from that page.
$ host linux.conf.au
linux.conf.au has address 192.55.98.190
linux.conf.au mail is handled by 1 linux.org.au.
$ host sigfail.verteiltesysteme.net
;; connection timed out; no servers could be reached
$ 
I use Munin to monitor my services, and I was happy to find a nice Unbound Munin plugin. I installed the file in /usr/share/munin/plugins/ and created a Munin plugin configuration file /etc/munin/plugin-conf.d/unbound as follows:
[unbound*]
user root
env.statefile /var/lib/munin-node/plugin-state/root/unbound.state
env.unbound_conf /etc/unbound/unbound.conf
env.unbound_control /usr/sbin/unbound-control
env.spoof_warn 1000
env.spoof_crit 100000
I run munin-node-configure --shell sh to enable it. To work unbound has to be configured as well, so I create a /etc/unbound/unbound.conf.d/munin.conf as follows.
server:
	extended-statistics: yes
	statistics-cumulative: no
	statistics-interval: 0
remote-control:
	control-enable: yes
The graphs may be viewed at my munin instance.

Russ Allbery: Review: Hawk

Review: Hawk, by Steven Brust
Series: Vlad Taltos #14
Publisher: Tor
Copyright: October 2014
ISBN: 0-7653-2444-X
Format: Hardcover
Pages: 320
This is the fourteenth book in the Vlad Taltos series (not counting the various associated books and other series), builds directly on the long-term plot arc of the series (finally!), and is deeply entangled with Vlad's friends and former life as a Jhereg boss. As you might imagine from that introduction, this is absolutely not the place to start with this series. For the past few books, Brust has been following a pattern of advancing the series plot in one book and then taking the next book to fill in past history or tell some side story. That means, following Tiassa, we were due some series advancement, and that's exactly what we get. We also, finally, get some more details about Lady Teldra. Nothing all that revelatory, but certainly intriguing, and more than just additional questions (at last). When Brust finally takes this gun off the wall and fires it, the resulting bits of world-building might be even better than Issola. At its heart, though, Hawk is a caper novel. If you're like me, you're thinking "it's about time." I think this is the sort of story Brust excels at, particularly with Vlad as his protagonist. Even better, unlike some of the other multi-part novels, this is a book-length caper focused on a very important goal, and with the potential to get rid of some annoyances in Vlad's life that have lingered for rather too long. We see many of Vlad's Dragaeran friends, but (apart from Daymar) mostly in glimpses. This is Vlad's book, with heavy helpings of Loiosh. The caper is also a nicely twisty one, involving everything from different types of magic to the inner workings of the Jhereg organization. As is typical for Vlad's schemes, there are several false fronts and fake goals, numerous unexpected twists, and a rather fun guest appearance. Oh, and lots and lots of snark, of course. I think my favorite part of the book was the interaction between Vlad and Kragar, which added a lot of emotional depth both to this story and to some of the previous stories of Vlad's life as a Jhereg. And I'm hoping that where Brust leaves things at the end of this book implies a Vlad who is more free to act, to see his friends, and to get entangled in Imperial politics, since I think that leads to the best stories. Of course, if Brust holds to pattern, the next book will be backfill or side stories and we'll have to wait longer for a continuation of the main story. As much as I like those side stories, I'm hoping Brust will break pattern. I'm increasingly eager to see where this story will go. The all-too-brief interaction with Sethra in this book promises so much for the future. If you like the Vlad Taltos books overall, you'll probably like this one. It's a return to the old scheming Vlad, but tempered by more experience and different stakes. There's a bit of lore, a bit of world-building, and a lot of Vlad being tricky. This series is still going strong fourteen books in. Rating: 8 out of 10

Craig Small: ps standards and locales

I looked at two interesting issues today around the ps program in the procps project. One had a solution and the other I m puzzled about. ps User-defined Format Issue #9 was quite the puzzle. The output of ps changed depending if a different option had a hyphen before it or not. First, the expected output
$ ps p $$ -o pid=pid,comm=comm
 pid comm
31612 bash
Next, the unusual output.
$ ps -p $$ -o pid=pid,comm=comm
pid,comm=comm
 31612
The difference being the second we have -p not p. The second unexpected thing about this is, it was designed that way. Unix98 standard apparently permits this sort of craziness. To me it is a useless feature that will more likely than not confuse people. Within ps, depending on what sort of flags you start with, you use a sysv parser or a bsd parser. One of them triggered the Unix98 compatibility option while the other did not, hence the change in behavior. The next version of procps will ship with a ps that has the user-defined output format of the first example. I had a look at the latest standard, IEEE 1003.1-2013, doesn t seem to have anything like that in it. Short Month Length This one has got me stuck. A user has reported in issue #5 that when they use their locale columns such as start time get mis-aligned because their short month is longer than 3 characters. They also mention some other columns for memory etc are not long enough but that s a generic problem that is impossible to fix sensibly. OK, for the month problem the fix would be to know what the month length is and set the column width for those columns to that plus a bit more for the other fixed components, simple really. Except; how do you know for a specific locale what their short month length is? I always assumed it was three! I haven t found anything that has this information. Note, I m not looking for strlen() but some function that has the maximum length for short month names (e.g. Jan, Feb, Mar etc). This also got me thinking how safe some of those date to string functions are if you have a static buffer as the destination. It s not safe to assume they will be DD MMM YYYY because there might be more Ms. So if you know how to work out the short month name length, let me know!

Next.

Previous.