Search Results: "cas"

9 August 2012

C.J. Adams-Collier: Linus on Instantiation and Armadaification

I feel a sense of pride when I think that I was involved in the development and maintenance of what was probably the first piece of software accepted into Debian which then had and still has direct up-stream support from Microsoft. The world is a better place for having Microsoft in it. The first operating system I ever ran on an 08086-based CPU was MS-DOS 2.x. I remember how thrilled I was when we got to see how my friend s 80286 system ran BBS software that would cause a modem to dial a local system and display the application as if it were running on a local machine. Totally sweet. When we were living at 6162 NE Middle in the nine-eight 292, we got an 80386 which ran Doom. Yeah, the original one, not the fancy new one with the double barrel shotgun, but it would probably run that one, too. It was also totally sweet and all thanks to our armadillo friends down south and partially thanks to their publishers, Apogee. I suckered my brothers into giving me their allowance from Dad one time so that we could all go in on a Sound Blaster Pro 16 sound card for the family s 386. I played a lot of Team Fortress and Q2CTF on that rig. I even attended the Quake 3 Arena launch party that happened at Zoid s place. I recall that he ported the original quake to Linux. I also recall there being naughty remarks included in the README.txt. When my older brother, Aaron turned 16, he was gifted a fancy car. When asked what type of car I would like when I turned 16, I said that I d prefer a computer instead. So I got a high-end 80486 with math co-processor. It could compile the kernel in 15 minutes flat. With all the bits turned on on in /usr/src/linux/.config. But this was later. I hadn t even heard of linux when I got my system. I wanted to be entertained by the thing. I made sure to get a CD-Rom and a sound card. I got on the beta for Ultima Online and spent a summer as a virtual collier. Digging stuff out of mines north of Britannia and hauling them to town to make weapons and armor out of them. And then setting out in said armor only to be PK d because I forgot healing potions and I was no good at fighting. While I was in the middle of all this gaming, my friend Lucas told me that I should try out this lynx thing that they run at the University of Washington. He heard that it was reported to run doom faster than it ran on MS-DOS. It turns out that it did, but that it was not, in fact, called lynx. Or pine. The Doom engine ran so fast that the video couldn t keep up. This was probably because they didn t use double buffering for frame display, since they didn t want to waste the time maintaining and switching context. I think I downloaded the boot/root 3.5 disk pair and was able to get the system to a shell with an on-phone assist from the Rev. I then promptly got lost in bash and the virtual terminals (OMG! I GET SIX CONSOLES!?) and bought a book on the subject. It shipped with slackware. Which I ran. Until Debian came along. Lucas also recommended that I try out this IRC thing, so I did. And I m still doing it on #linpeople just like I did back then. I learned to write Pascal on dos. Then I learned c while they were trying to teach me c++. I learned emacs and vi when I was attending North Kitsap High School. I learned sed and only a little awk when I took Running Start classes in Lynnwood at Edmonds Community College and perl & x.509 while attending Olympic Community College and simultaneously jr-administering Sinclair Communications. I studied TCP/IP, UNP, APUE, C and algorithms & data structures while preparing for an interview with a company whose CEO claimed to have invented SCSI. I learned PGP and PHP while writing web-based adware for this company. I didn t want to write ads and instead wanted to work in security, so took a job with Security Portal. While there, I wrote what one might call a blogging platform. It worked and made it possible for authors to write prose and poetry. Editors didn t have to manage a database in order to review and publish the posts that were ready. Everyone but me was able to avoid html and cgi. Then I sold pizza. Then I helped bring the bombay company onto the interwebs using the Amazon ECS (now AWS) platform. Then I helped support MaxDB. Then I helped develop and maintain the Amazon blogging platform. And then attempted to reduce the load on the Amazon pager system by doing and enforcing code reviews. It turns out that they prefer to run their support team at full bore and a load average of 16.
<iframe allowfullscreen="" frameborder="0" height="288" scrolling="no" src="http://www.youtube.com/embed/MShbP3OpASA" width="448"></iframe>
I am now, still, fully employed in an effort to make hard things possible. The hard thing we re working on now is the implementation and ongoing operations of distributed x.500 infrastructure. This includes request handling, processing and delivery of response ( la HTTP, SMTP, IMAP, SIP, RTP, RTSP, OCSP) including authentication, authorization and auditing (AAA) of all transactions. It s a hard thing to get right, but our product development team gets it right. Consistently and reliably. We make mistakes sometimes (sorry Bago), but we correct them and make the product better. I m the newest member of an R and d team (note: big R, little d) called NTR, which sits behind the firewall that is Product Development, out of production space. In a manner that reminds me of Debian Testing. We try new things. Our current project is to allow users to compare their current (cloud-based or iron-based) IT system with what their system would be like with a BIG-IP in front of it. I can probably come up with a demo if anyone s interested in checking it out. I ll go work on that now.

8 August 2012

Rapha&#235;l Hertzog: How to use quilt to manage patches in Debian packages

Most Debian source packages are using the 3.0 (quilt) format. This means that Debian changes to upstream files are managed in a quilt patch series. Knowledge of quilt is thus a must if you want to get involved in some serious packaging work. Don t worry, this tutorial will teach you how to use quilt in the context of Debian packaging. Pre-requisites Install the packaging-dev package to get a decent set of packages to do Debian packaging. It includes the quilt package.
$ sudo apt-get install packaging-dev
What s quilt? Read the description of the Debian package:
Quilt manages a series of patches by keeping track of the changes each of them makes. They are logically organized as a stack, and you can apply, un-apply, update them easily by traveling into the stack (push/pop). Quilt is good for managing additional patches applied to a package received as a tarball or maintained in another version control system. The stacked organization is proven to be efficient for the management of very large patch sets (more than hundred patches). As matter of fact, it was designed by and for Linux kernel hackers (Andrew Morton, from the -mm branch, is the original author), and its main use by the current upstream maintainer is to manage the (hundreds of) patches against the kernel made for the SUSE distribution.
The various files involved Stack of files PictureTo better understand the various quilt commands, you should have a basic idea of how the tool works. The stack of patches is maintained in a dedicated directory ( patches by default, but in Debian packages we override this value to debian/patches ). This directory contains the patch files and a series file that gives an ordered list of patches to apply. Example:

$ ls debian/patches/
01_use_stdlib_htmlparser_when_possible.diff
02_disable-sources-in-sphinxdoc.diff
03_manpage.diff
06_use_debian_geoip_database_as_default.diff
series
$ cat debian/patches/series
01_use_stdlib_htmlparser_when_possible.diff
02_disable-sources-in-sphinxdoc.diff
03_manpage.diff
06_use_debian_geoip_database_as_default.diff
When quilt is used, it also maintains some internal files in a directory of its own (it s named .pc ). This directory is used to know what patches are currently applied (.pc/applied-patches) and to keep backup copies of files modified by the various patches. Configuring quilt Before going further, you should put this in your ~/.quiltrc file:
for where in ./ ../ ../../ ../../../ ../../../../ ../../../../../; do
    if [ -e $ where debian/rules -a -d $ where debian/patches ]; then
        export QUILT_PATCHES=debian/patches
        break
    fi
done
This ensures that quilt will always use debian/patches instead of patches when your current directory is within a Debian source package where debian/patches exists. If you only use quilt for debian packaging, then you can be more expedient and put a simple export QUILT_PATCHES=debian/patches in that file. As a matter of personal preferences, I also have those lines in my ~/.quiltrc:
QUILT_PUSH_ARGS="--color=auto"
QUILT_DIFF_ARGS="--no-timestamps --no-index -p ab --color=auto"
QUILT_REFRESH_ARGS="--no-timestamps --no-index -p ab"
QUILT_DIFF_OPTS='-p'
It enables syntax coloring for the output of several commands and customizes the generated patches to get rid of useless information. I recommend you to use those settings too. Applying and unapplying patches, navigating in the stack of patches When you already have a patch series, you can navigate in the stack of patches so that any subset of consecutive patches (starting from the bottom) can be applied. quilt series will list all patches known by quilt. You can apply all patches with quilt push -a or unapply them all with quilt pop -a. You can also verify what patches are applied (quilt applied) or unapplied (quilt unapplied). quilt push applies the next unapplied patch (i.e. the patch returned by quilt next) and quilt pop unapplies the last applied patch (i.e. the patch returned by quilt top). You can give a patch name as parameter to quilt push/pop and it will apply/unapply all the patches required until the given patch is on the top. Here are some examples of navigation in a quilt patch series
$ quilt series
02_disable-sources-in-sphinxdoc.diff
03_manpage.diff
06_use_debian_geoip_database_as_default.diff
$ quilt applied
No patches applied
$ quilt next
02_disable-sources-in-sphinxdoc.diff
$ quilt push
Applying patch 02_disable-sources-in-sphinxdoc.diff
patching file docs/conf.py
Now at patch 02_disable-sources-in-sphinxdoc.diff
$ quilt push
Applying patch 03_manpage.diff
patching file docs/man/django-admin.1
Now at patch 03_manpage.diff
$ quilt applied
02_disable-sources-in-sphinxdoc.diff
03_manpage.diff
$ quilt unapplied
06_use_debian_geoip_database_as_default.diff
$ quilt pop -a
Removing patch 03_manpage.diff
Restoring docs/man/django-admin.1
Removing patch 02_disable-sources-in-sphinxdoc.diff
Restoring docs/conf.py
No patches applied
$ quilt push 03_manpage.diff
Applying patch 02_disable-sources-in-sphinxdoc.diff
patching file docs/conf.py
Applying patch 03_manpage.diff
patching file docs/man/django-admin.1
Now at patch 03_manpage.diff
$ quilt top
03_manpage.diff
Creating a new patch If there s no quilt series yet, you want to create the debian/patches directory first. If you already have one, you need to decide where to insert the new patch. Quilt will always add the new patch just after the patch which is currently on top. So if you want to add the patch at the end of the series, you need to run quilt push -a first. Then you can use quilt new name-of-my-patch.diff to tell quilt to insert a new empty patch after the current topmost patch. In this operation quilt does almost nothing except updating the series file and recording the fact that the new patch is applied (even if still empty at this point!). Now to add changes in this patch, you re supposed to modify files but only after having informed quilt of your intent to modify those files. You do this with quilt add file-to-modify. At this point quilt will make a backup copy of that file so that it can generate the final patch when you re done with your changes. It s quite common to forget this step and to be unable to generate the patch afterward. That s why I recommend you to use quilt edit file-to-modify which is a shorthand for doing quilt add and then opening the file in your favorite text editor. If you want, you can review your work in progress with quilt diff. When you re done with the changes, you should call quilt refresh to generate the patch (or to update it if it was already existing). And since you re a good packager, you call quilt header --dep3 -e to add DEP-3 meta-information to your patch header. Importing an external patch If someone else already prepared a patch, you can just import it right away with quilt import /tmp/the-patch. If you want to import it under a better name you can use the option -P better-patch-name . Like quilt new, it inserts the patch after the topmost patch. Updating patches for a new upstream version With some luck, your patches will still apply with some offsets in line numbers (quilt displays those offsets) and sometimes with some fuzz:
$ quilt push
[...]
Hunk #1 succeeded at 1362 (offset 11 lines).
Hunk #2 succeeded at 1533 with fuzz 1 (offset 4 lines).
[...]
While offsets are nothing to worry about (it means some lines were added and/or removed before the patched part), fuzz means that patch had to ignore some context lines to find the place where to apply the changes. In that case, you need to double check that patch did the right thing because it might have made changes somewhere where it shouldn t. Also, you ll have to update those patches because dpkg-source doesn t accept any fuzz. If you re confident that all patches are correctly applied by quilt, you can refresh them to get rid of those warnings:
$ quilt pop -a
[...]
$ while quilt push; do quilt refresh; done
That was for the easy case. Now let s deal with the case where some of the patches no longer apply. There s one case that is usually nice to have:
$ quilt push
Applying patch 04_hyphen-manpage.diff
patching file docs/man/django-admin.1
Hunk #1 FAILED at 194.
1 out of 1 hunk FAILED -- rejects in file docs/man/django-admin.1
Patch 04_hyphen-manpage.diff can be reverse-applied
When the patch can be reverse-applied, it means that the upstream authors included the Debian patch (or that they made the same change even though you forgot to forward the patch). You can thus get rid of it:
$ quilt delete -r 04_hyphen-manpage.diff
Removed patch 04_hyphen-manpage.diff
Note that without the -r the patch is only dropped from the series file. With -r the patch file is also removed. But there s a less desirable case where the patch is still relevant but it doesn t apply any longer:
$ quilt push
Applying patch 01_disable_broken_test.diff
patching file tests/regressiontests/test_utils/tests.py
Hunk #1 FAILED at 422.
1 out of 1 hunk FAILED -- rejects in file tests/regressiontests/test_utils/tests.py
Patch 01_disable_broken_test.diff does not apply (enforce with -f)
In that case, you should follow quilt s advice to force the patch application, manually apply the parts of the patch that were rejected, and then refresh the patch.
$ quilt push -f
Applying patch 01_disable_broken_test.diff
patching file tests/regressiontests/test_utils/tests.py
Hunk #1 FAILED at 422.
1 out of 1 hunk FAILED -- saving rejects to file tests/regressiontests/test_utils/tests.py.rej
Applied patch 01_disable_broken_test.diff (forced; needs refresh)
$ vim tests/regressiontests/test_utils/tests.py    
$ quilt refresh
Refreshed patch 01_disable_broken_test.diff
Other quilt commands You should probably read quilt s manual page too to learn about the various other commands and options that exist. There s at least quilt rename new-name that you can also find useful to rename the topmost patch (you can use -P patch-to-rename to rename a patch which is not currently at the top). Feedback Please leave comments if you have suggestions of improvements, or if there are some tips that are good to know. I might incorporate them in this article. Feel free to share this article with newbie packagers which are struggling with quilt. For your convenience, you can also refer to this article with this URL: http://raphaelhertzog.com/go/quilt
Found it useful? Be sure to not miss other packaging tips (or lessons), click here to subscribe to my free newsletter and get new articles by email.

2 comments Liked this article? Click here. My blog is Flattr-enabled.

Aigars Mahinovs: Fun with the new camera

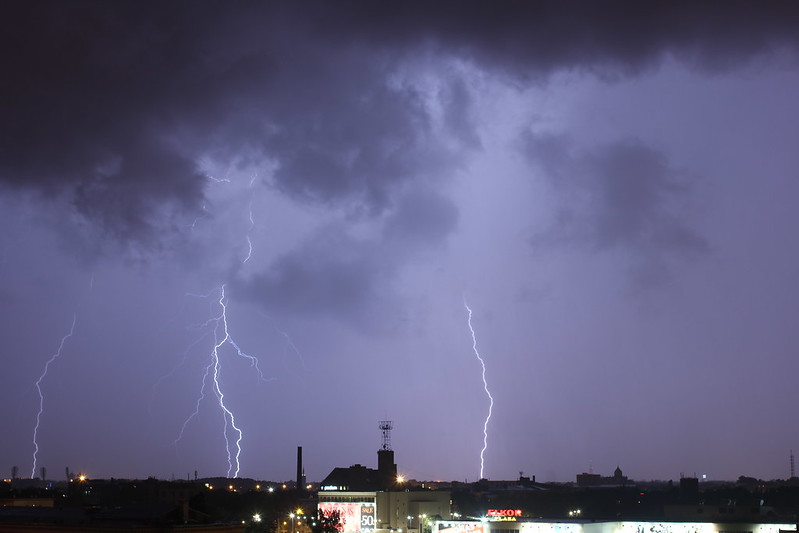
Triple hit! So, I finally received my Canon 650D and Canon EF 40mm STM lens. I am very happy with the purchase. The STM lens is very, very compact, it is barely bigger than the lens cap that comes with the camera. The focusing is fast enough and it is very smooth and silent enough not to be audible in video mode. The largest bonus of the 650D compared to my old 550D is the articulated display. It has come in handy many times already. It is especially useful with the STM lens, live view and touch to focus function. Very useful to focus on something even when the camera is at an weird angle. And a couple days ago I got to really use the new camera capturing the shot above (an others in that set). It turns out capturing cool lightning shots is quite easy: It is basically the same as shooting photos of a fireworks display, with the exception that lightning is not so bright sometimes and that there is a high chance of rain in a thunderstorm ;) P.S. Got over 5k photos in Flickr now with this set, and closing in for 500k views. That feels cool :)

Russell Coker: Hard Drives for Backup

The general trend seems to be that cheap hard drives are increasing in capacity faster than much of the data that is commonly stored. Back in 1998 I had a 3G disk in my laptop and about 800M was used for my home directory. Now I have 6.2G used for my home directory (and another 2G in ~/src) out of the 100G capacity in my laptop. So my space usage for my home directory has increased by a factor of about 8 while my space available has increased by a factor of about 30. When I had 800M for my home directory I saved space by cropping pictures for my web site and deleting the originals (thus losing some data I would rather have today) but now I just keep everything and it s still doesn t take up much of my hard drive. Similar trends apply to most systems that I use and that I run for my clients. Due to the availability of storage people are gratuitously using a lot of disk space. A relative recently took 10G of pictures on a holiday, her phone has 12G of internal storage so there was nothing stopping her. She might decide that half the pictures aren t that great if she had to save space, but that space is essentially free (she couldn t buy a cheaper phone with less storage) so there s no reason to delete any pictures. When considering backup methods one important factor is the ability to store all of one type of data on one backup device. Having a single backup span multiple disks, tapes, etc has a dramatic impact on the ease of recovery and the potential for data loss. Currently 3TB SATA disks are really cheap and 4TB disks are available but rather expensive. Currently only one of my clients has more than 4TB of data used for one purpose (IE a single filesystem) so apart from that client a single SATA disk can backup anything that I run. Benefits of Hard Drive Backup When using a hard drive there is an option to make it a bootable disk in the same format as the live disk. I haven t done this, but if you want the option of a quick recovery from a hardware failure then having a bootable disk with all the data on it is a good option. For example a server with software RAID-1 could have a backup disk that is configured as a degraded RAID-1 array. The biggest benefit is the ability to read a disk anywhere. I ve read many reports of tape drives being discovered to be defective at the least convenient time. With a SATA disk you can install it in any PC or put it in a USB bay if you have USB 3.0 or the performance penalty of USB 2.0 is bearable a USB 2.0 bay is great if you want to recover a single file, but if you want terabytes in a hurry then it won t do. A backup on a hard drive will typically use a common filesystem. For backing up Linux servers I generally use Ext3, at some future time I will move to BTRFS as having checksums on all data is a good feature for a backup. Using a regular filesystem means that I can access the data anywhere without needing any special software, I can run programs like diff on the backup, and I can export the backup via NFS or Samba if necessary. You never know how you will need to access your backup so it s best to keep your options open. Hard drive backups are the best solution for files that are accidentally deleted. You can have the first line of backups on a local server (or through a filesystem like BTRFS or ZFS that supports snapshots) and files can be recovered quickly. Even a SATA disk in a USB bay is very fast for recovering a single file. LTO tapes have a maximum capacity of 1.5TB at the moment and tape size has been increasing more slowly than disk size. Also LTO tapes have an expected lifetime of only 200 reads/writes of the entire tape. It seems to me that tapes don t provide a great benefit unless you are backing up enough data to need a tape robot. Problems with a Hard Drive Backup Hard drives tend not to survive being dropped so posting a hard drive for remote storage probably isn t a good option. This can be solved by transferring data over the Internet if the data isn t particularly big or doesn t change too much (I have a 400G data set backed up via rsync to another country because most of the data doesn t change over the course of a year). Also if the data is particularly small then solid state storage (which costs about $1 per GB) is a viable option, I run more than a few servers which could be entirely backed up to a 200G SSD. $200 for a single backup of 200G of data is a bit expensive, but the potential for saving time and money on the restore means that it can be financially viable. Some people claim that tape storage will better survive a Carrington Event than hard drives. I m fairly dubious about the benefits of this, if a hard drive in a Faraday Cage (such as a regular safe that is earthed) is going to be destroyed then you will probably worry about security of the food supply instead of your data. Maybe I should just add a disclaimer this backup system won t survive a zombie apocalypse . ;) It s widely regarded that tape storage lasts longer than hard drives. I doubt that this provides a real benefit as some of my personal servers are running on 20G hard drives from back when 20G was big. The fact that drives tend to last for more than 10 years combined with the fact that newer bigger drives are always being released means that important backups can be moved to bigger drives. As a general rule you should assume that anything which isn t regularly tested doesn t work. So whatever your backup method you should test it regularly and have multiple copies of the data to deal with the case when one copy becomes corrupt. The process of testing a backup can involve moving it to newer media. I ve seen it claimed that a benefit of tape storage is that part of the data can be recovered from a damaged tape. One problem with this is that part of a database often isn t particularly useful. Another issue is that in my experience hard drives usually don t fail entirely unless you drop them, drives usually fail a few sectors at a time. How to Implement Hard Drive Backup The most common need for backups is when someone deletes the wrong file. It s usually a small restore and you want it to be an easy process. The best solution to this is to have a filesystem with snapshots such as BTRFS or ZFS. In theory it shouldn t be too difficult to have a cron job manage snapshots, but as I ve only just started putting BTRFS and ZFS on servers I haven t got around to changing my backups. Snapshots won t cover more serious problems such as hardware, software, or user errors that wipe all the disks in a server. For example the only time I lost a significant amount of data from a hosted server was when the data center staff wiped it, so obviously good off-site backups are needed. The easiest way to deal with problems that wipe a server is to have data copied to another system. For remote backups you can rsync to a local system and then use cp -rl or your favorite snapshot system to make a hard linked copy of the tree. A really neat feature is the ZFS ability to send a filesystem snapshot (or the diff between two snapshots) to a remote system [1]. Once you have regular backups on local storage you can then copy them to removable disks as often as you wish, I think I ll have to install ZFS on some of my servers for the sole purpose of getting the send feature! There are NAS devices that provide similar functionality to the ZFS send/receive (maybe implemented with ZFS), but I m not a fan of cheap NAS devices [2]. It seems that the best way to address the first two needs of backup (fast local restore and resilience in the face of site failure) is to use ZFS snapshots on the server and ZFS send/receive to copy the data to another site. The next issue is that the backup server probably won t be big enough for all the archives and you want to be able to recover from a failure on the backup server. This requires some removable storage. The simplest removable backup is to use a SATA drive bay with eSATA and USB connectors. You use a regular filesystem like Ext3 and just copy the files on. It s easy, cheap, and requires no special skill or software. Requiring no special skill is important, you never know who will be called on to recover from backups. When a server is backing up another server by rsync (whether it s in the same rack or another country) you want the backup server to be reliable. However there is no requirement for a single reliable server and sometimes having multiple backup servers will be cheaper. At current purchase prices you can buy two cheap tower systems with 4*3TB disks for less money than a single server that has redundant PSUs and other high end server features. Having two cheap servers die at once seems quite unlikely so getting two backup servers would be the better choice. For filesystems that are bigger than 4TB a disk based backup would require backup software that handles multi part archives. One would hope that any software that is designed for tape backup would work well for this (consider a hard drive as a tape with a very fast seek), but often things don t work as desired. If anyone knows of a good Linux backup program that supports multiple 4TB SATA disks in eSATA or USB bays then please let me know. Conclusion BTRFS or ZFS snapshots are the best way of recovering from simple mistakes. ZFS send/receive seems to be the best way of synchronising updates to filesystems to other systems or sites. ZFS should be used for all servers. Even if you don t currently need send/receive you never know what the future requirements may be. Apart from needing huge amounts of RAM (one of my servers had OOM failures when it had a mere 4G of RAM) there doesn t seem to be any down-side to ZFS. I m unsure of whether to use BTRFS for removable backup disks. The immediate up-sides are checksums on all data and meta-data and the possibility of using built-in RAID-1 so that a random bad sector is unlikely to lose data. There is also the possibility of using snapshots on a removable backup disk (if the disk contains separate files instead of an archive). The down-sides are lack of support on older systems and the fact that BTRFS is fairly new. Have I missed anything? Related posts:
  1. New Storage Developments Eweek has an article on a new 1TB Seagate drive....
  2. IDE hard drives I just lent two 80G IDE drives to a friend,...
  3. Hot-swap Storage I recently had to decommission an old Linux server and...

Johannes Schauer: Bootstrappable Debian - How to help

TLDR: multiarch, multiarch, multiarch, cross buildability, staged build dependencies, wiki page, corrections/hints/requests to debian-bootstrap at lists.mister-muffin.de This summer (and this year's GSoC) is nearing its end and to make it easier for people to make use of the information my tools produced so far, I created a page in the Debian wiki. It lists not only the open issues I see but also statistics that I gathered using the output of my GSoC project. I want to use this blog post to make people aware of that page as well as to get some feedback on it and anything related to it. The biggest blocker my tools face, is that many packages are still missing multiarch information. As long as at least the basic packages do not have their cross build dependencies satisfied via multiarch for an existing foreign architecture, automated tools can not properly analyze the dependency situation in the bootstrapping case, when many packages of the new foreign architecture do not even exist yet. If Debian is supposed to be bootstrappable, then the first stage is to make a set of basic packages cross compile for an existing foreign architecture. Once this is possible, a tool of mine can analyze the cyclic build dependency situation that might occur when cross compiling for an architecture that does not exist yet. Then, staged cross builds can be used to cross compile a minimal foreign system. Due to missing multiarch classification, it is not known yet how big the cyclic build dependency situation is for the base packages. It is not only the conversion of packages to multiarch that is needed but also the adding of the :any (and rare cases :native) qualifier to build dependencies on M-A: allowed packages. Prominent build dependencies that should (but are not yet) be M-A: allowed are python and gettext. Both are needed as a build dependency by many packages of the base system. Unfortunately wanna-build does not understand qualifiers like :any and :native yet. Until it does, no package can be marked :any or :native and cross compilation of many base packages can not succeed. Once the point is reached, where a base system can be cross compiled from nothing, native compilation can start. Since native compilation doesnt depend on multiarch, the dependency situation when trying to natively compiling all of Debian from nothing is understood much better. Unfortunately, the cyclic build dependency situation is also much worse in the native case and there exists a big 1000 node strongly connected component of binary and source packages that all interdepend on each other. This dependency mess can be solved using three approaches: The wiki page gives many hints on how to find packages that each method can be applied to. Stage building is a tool that might be useful for cross building (we dont know for sure yet) but is definitely needed for native compilation. It is needed for native compilation because after all possible dependencies are moved to Build-Depends-Indep, the only other alternative to stage building for breaking dependency cycles is to cross build source packages. Since building a package without one of its build dependencies "staged" is often much easier than making the package in question cross compile, it is a preferred alternative. Once more packages have been made multiarch, it might be possible to prove that there is no alternative to introducing a notion of staged builds. Some people (wookey, Patrick McDermott, Guillem Jover, myself) decided that the following format to mark staged build dependencies would be preferred over others:
Build-Depends: huge (>= 1.0) [i386 arm] <!embedded !bootstrap>, tiny
The <> format was proposed by Guillem Jover in bug#661538. Patches for dpkg and dose3 are done. More people need to discuss about this format for a final decision on how to indicate staged build dependencies. For more information on the topic, have a look at the corresponding wiki page. Feel free to direct any comments/critique/hints to debian-bootstrap at lists.mister-muffin.de or directly to me.

6 August 2012

Vincent Sanders: Education is when you read the fine print. Experience is what you get if you don't.

Given my title I guess I just got a load of "experience" from Gandi. Previously I have written about building the NetSurf Continuous Integration (CI) server and my misjudgement of the resources it would require to be useful.

I contacted Gandi and they confirmed my suspicion that my only options to extend the VPS were to spend a great deal more money. The total spend would have been in excess of 300 per year to get a minimally satisfactory configuration.

So I contacted Mythic Beasts and they offered the NetSurf project a selection of deals they could not refuse. Once we decided on the right deal for us the system was in place, ready to use, within a morning.

Thanks to the generous open source project discount the offering from Mythic is almost double what Gandi were offering for less than half the price. I was, as previously concluded, dumb to go with Gandi in the first place when Mythic were an option.

Once the system was transferred to the shiny new server I went back to Gandi and asked how much my mistake of buying a years service for a single month worth of VPS service was going to cost. The reply was somewhat disappointing I was simply referred to section 8.1.2 of the contract (tl;dr We have your money now, tough luck, your problem). It would appear my mistake was going to cost me the full 114 I had paid.

I was somewhat disheartened at this turn of events but then Daniel Silverstone offered to take on the VPS if I could transfer it to his Gandi handle so he could administer it. this seemed like a good solution, at least the resource would be used and not wasted. Gandi response to this was initially promising but this is the final reply:

I'm really sorry to inform you that my supervisor refused the share transfer request to the other account. He told me that we do not transfer products either in those cases. I deeply apologize since I thought it was possible. I thank you for your confidence in Gandi, and hope that this occurrence does not deter you from continuing with us.
Now I must stress that Gandi are completely within their contractual rights to do this and are not obligated to provide any assistance to help make my blunder less costly to me, but they have firmly shown they have no willingness to be flexible in any way which means I know where I will not be spending my money in future.

Oh and then Pete from Mythic mentioned that they have a full refund and flexible policy on their services and we can always switch to the monthly billing rate and get a refund on the outstanding balance or move it or...

Basically my recommendation for an open source project looking for hosting, VPS or any network services has to be to go talk to the nice people at Mythic and steer clear of Gandi. Maybe in future all providers will realise that they are in a competitive market and certainly a little customer service flexibility might have made this posting much more about my mistake and not the attitude of the suppliers involved.

Mike Hommey: Building a Linux kernel module without the exact kernel headers

Imagine you have a Linux kernel image for an Android phone, but you don t have the corresponding source, nor do you have the corresponding kernel headers. Imagine that kernel has module support (fortunately), and that you d like to build a module for it to load. There are several good reasons why you can t just build a new kernel from source and be done with it (e.g. the resulting kernel lacks support for important hardware, like the LCD or touchscreen). With the ever-changing Linux kernel ABI, and the lack of source and headers, you d think you re pretty much in a dead-end. As a matter of fact, if you build a kernel module against different kernel headers, the module will fail to load with errors depending on how different they are. It can complain about bad signatures, bad version or other different things. But more on that later. Configuring a kernel The first thing is to find a kernel source for something close enough to the kernel image you have. That s probably the trickiest part with getting a proper configuration. Start from the version number you can read from /proc/version. If, like me, you re targeting an Android device, try Android kernels from Code Aurora, Linaro, Cyanogen or Android, whichever is closest to what is in your phone. In my case, it was msm-3.0 kernel. Note you don t necessarily need the exact same version. A minor version difference is still likely to work. I ve been using a 3.0.21 source, which the kernel image was 3.0.8. Don t however try e.g. using a 3.1 kernel source when the kernel you have is 3.0.x. If the kernel image you have is kind enough to provide a /proc/config.gz file, you can start from there, otherwise, you can try starting from the default configuration, but you need to be extra careful, then (although I won t detail using the default configuration because I was fortunate enough that I didn t have to, there will be some details further below as to why a proper configuration is important). Assuming arm-eabi-gcc is in your PATH, and that you have a shell opened in the kernel source directory, you need to start by configuring the kernel and install headers and scripts:
$ mkdir build
$ gunzip -c config.gz > build/.config # Or whatever you need to prepare a .config
$ make silentoldconfig prepare headers_install scripts ARCH=arm CROSS_COMPILE=arm-eabi- O=build KERNELRELEASE= adb shell uname -r 
The silentoldconfig target is likely to ask you some questions about whether you want to enable some things. You may want to opt for the default, but that may also not work properly. You may use something different for KERNELRELEASE, but it needs to match the exact kernel version you ll be loading the module from. A simple module To create a dummy module, you need to create two files: a source file, and a Makefile. Place the following content in a hello.c file, in some dedicated directory:
#include <linux/module.h>       /* Needed by all modules */
#include <linux/kernel.h>       /* Needed for KERN_INFO */
#include <linux/init.h>         /* Needed for the macros */
static int __init hello_start(void)
 
  printk(KERN_INFO "Hello world\n");
  return 0;
 
static void __exit hello_end(void)
 
  printk(KERN_INFO "Goodbye world\n");
 
module_init(hello_start);
module_exit(hello_end);
Place the following content in a Makefile under the same directory:
obj-m = hello.o
Building such a module is pretty straightforward, but at this point, it won t work yet. Let me enter some details first. The building of a module When you normally build the above module, the kernel build system creates a hello.mod.c file, which content can create several kind of problems:
MODULE_INFO(vermagic, VERMAGIC_STRING);
VERMAGIC_STRING is derived from the UTS_RELEASE macro defined in include/generated/utsrelease.h, generated by the kernel build system. By default, its value is derived from the actual kernel version, and git repository status. This is what setting KERNELRELEASE when configuring the kernel above modified. If VERMAGIC_STRING doesn t match the kernel version, loading the module will lead to the following kind of message in dmesg:
hello: version magic '3.0.21-perf-ge728813-00399-gd5fa0c9' should be '3.0.8-perf'
Then, there s the module definition.
struct module __this_module
__attribute__((section(".gnu.linkonce.this_module"))) =  
 .name = KBUILD_MODNAME,
 .init = init_module,
#ifdef CONFIG_MODULE_UNLOAD
 .exit = cleanup_module,
#endif
 .arch = MODULE_ARCH_INIT,
 ;
In itself, this looks benign, but the struct module, defined in include/linux/module.h comes with an unpleasant surprise:
struct module
 
        (...)
#ifdef CONFIG_UNUSED_SYMBOLS
        (...)
#endif
        (...)
        /* Startup function. */
        int (*init)(void);
        (...)
#ifdef CONFIG_GENERIC_BUG
        (...)
#endif
#ifdef CONFIG_KALLSYMS
        (...)
#endif
        (...)
(... plenty more ifdefs ...)
#ifdef CONFIG_MODULE_UNLOAD
        (...)
        /* Destruction function. */
        void (*exit)(void);
        (...)
#endif
        (...)
 
This means for the init pointer to be at the right place, CONFIG_UNUSED_SYMBOLS needs to be defined according to what the kernel image uses. And for the exit pointer, it s CONFIG_GENERIC_BUG, CONFIG_KALLSYMS, CONFIG_SMP, CONFIG_TRACEPOINTS, CONFIG_JUMP_LABEL, CONFIG_TRACING, CONFIG_EVENT_TRACING, CONFIG_FTRACE_MCOUNT_RECORD and CONFIG_MODULE_UNLOAD. Start to understand why you re supposed to use the exact kernel headers matching your kernel? Then, the symbol version definitions:
static const struct modversion_info ____versions[]
__used
__attribute__((section("__versions"))) =  
	  0xsomehex, "module_layout"  ,
	  0xsomehex, "__aeabi_unwind_cpp_pr0"  ,
	  0xsomehex, "printk"  ,
 ;
These come from the Module.symvers file you get with your kernel headers. Each entry represents a symbol the module requires, and what signature it is expected to have. The first symbol, module_layout, varies depending on what struct module looks like, i.e. depending on which of the config options mentioned above are enabled. The second, __aeabi_unwind_cpp_pr0, is an ARM ABI specific function, and the last, is for our printk function calls. The signature for each function symbol may vary depending on the kernel code for that function, and the compiler used to compile the kernel. This means that if you have a kernel you built from source, modules built for that kernel, and rebuild the kernel after modifying e.g. the printk function, even in a compatible way, the modules you built initially won t load with the new kernel. So, if we were to build a kernel from the hopefully close enough source code, with the hopefully close enough configuration, chances are we wouldn t get the same signatures as the binary kernel we have, and it would complain as follows, when loading our module:
hello: disagrees about version of symbol symbol_name
Which means we need a proper Module.symvers corresponding to the binary kernel, which, at the moment, we don t have. Inspecting the kernel Conveniently, since the kernel has to do these verifications when loading modules, it actually contains a list of the symbols it exports, and the corresponding signatures. When the kernel loads a module, it goes through all the symbols the module requires, in order to find them in its own symbol table (or other modules symbol table when the module uses symbols from other modules), and check the corresponding signature. The kernel uses the following function to search in its symbol table (in kernel/module.c):
bool each_symbol_section(bool (*fn)(const struct symsearch *arr,
                                    struct module *owner,
                                    void *data),
                         void *data)
 
        struct module *mod;
        static const struct symsearch arr[] =  
                  __start___ksymtab, __stop___ksymtab, __start___kcrctab,
                  NOT_GPL_ONLY, false  ,
                  __start___ksymtab_gpl, __stop___ksymtab_gpl,
                  __start___kcrctab_gpl,
                  GPL_ONLY, false  ,
                  __start___ksymtab_gpl_future, __stop___ksymtab_gpl_future,
                  __start___kcrctab_gpl_future,
                  WILL_BE_GPL_ONLY, false  ,
#ifdef CONFIG_UNUSED_SYMBOLS
                  __start___ksymtab_unused, __stop___ksymtab_unused,
                  __start___kcrctab_unused,
                  NOT_GPL_ONLY, true  ,
                  __start___ksymtab_unused_gpl, __stop___ksymtab_unused_gpl,
                  __start___kcrctab_unused_gpl,
                  GPL_ONLY, true  ,
#endif
         ;
        if (each_symbol_in_section(arr, ARRAY_SIZE(arr), NULL, fn, data))
                return true;
        (...)
The struct used in this function is defined in include/linux/module.h as follows:
struct symsearch  
        const struct kernel_symbol *start, *stop;
        const unsigned long *crcs;
        enum  
                NOT_GPL_ONLY,
                GPL_ONLY,
                WILL_BE_GPL_ONLY,
          licence;
        bool unused;
 ;
Note: this kernel code hasn t changed significantly in the past four years. What we have above is three (or five, when CONFIG_UNUSED_SYMBOLS is defined) entries, each of which contains the start of a symbol table, the end of that symbol table, the start of the corresponding signature table, and two flags. The data is static and constant, which means it will appear as is in the kernel binary. By scanning the kernel for three consecutive sequences of three pointers within the kernel address space followed by two integers with the values from the definitions in each_symbol_section, we can deduce the location of the symbol and signature tables, and regenerate a Module.symvers from the kernel binary. Unfortunately, most kernels these days are compressed (zImage), so a simple search is not possible. A compressed kernel is actually a small bootstrap binary followed by a compressed stream. It is possible to scan the kernel zImage to look for the compressed stream, and decompress it from there. I wrote a script to do decompression and extraction of the symbols info automatically. It should work on any recent kernel, provided it is not relocatable and you know the base address where it is loaded. It takes options for the number of bits and endianness of the architecture, but defaults to values suitable for ARM. The base address, however, always needs to be provided. It can be found, on ARM kernels, in dmesg:
$ adb shell dmesg   grep "\.init"
<5>[01-01 00:00:00.000] [0: swapper]      .init : 0xc0008000 - 0xc0037000   ( 188 kB)
The base address in the example above is 0xc0008000. If like me you re interested in loading the module on an Android device, then what you have as a binary kernel is probably a complete boot image. A boot image contains other things besides the kernel, so you can t use it directly with the script. Except if the kernel in that boot image is compressed, in which case the part of the script that looks for the compressed image will find it anyways. If the kernel is not compressed, you can use the unbootimg program as outlined in this old post of mine to get the kernel image out of your boot image. Once you have the kernel image, the script can be invoked as follows:
$ python extract-symvers.py -B 0xc0008000 kernel-filename > Module.symvers
Symbols and signature info could also be extracted from binary modules, but I was not interested in that information so the script doesn t handle that. Building our module Now that we have a proper Module.symvers for the kernel we want to load our module in, we can finally build the module: (again, assuming arm-eabi-gcc is in your PATH, and that you have a shell opened in the kernel source directory)
$ cp /path/to/Module.symvers build/
$ make M=/path/to/module/source ARCH=arm CROSS_COMPILE=arm-eabi- O=build modules
And that s it. You can now copy the resulting hello.ko onto the device and load it. and enjoy
$ adb shell
# insmod hello.ko
# dmesg   grep insmod
<6>[mm-dd hh:mm:ss.xxx] [id: insmod]Hello world
# lsmod
hello 586 0 - Live 0xbf008000 (P)
# rmmod hello
# dmesg   grep rmmod
<6>[mm-dd hh:mm:ss.xxx] [id: rmmod]Goodbye world

5 August 2012

Stefano Zacchiroli: bits from the DPL for July 2012

Monthly DPL bits, fresh from the oven.
Tip to feel good about the release #476: before reading this, grab and fix one of the RC bugs affecting Wheezy. Done? Now you're ready for a slightly less exciting report of DPL activities. Highlights Assets Logo & trademark Note that the actual logo relicensing should be done by SPI, via their board, upon request of mine (as Debian Project liaison). We won't make it for the next SPI board meeting, as it is on 4 days away. But we can aim for the subsequent meeting, on September 13th. If all goes well (big "if"), we will enjoy a DFSG-free logo after that date. Internal organization Recent flurry of re-organization in the tech-ctte --- which I somewhat triggered pushing for periodic meetings --- seems to be proceeding well. I'm very happy about it, as we all need to trust that tech-ctte decisions will be not only sound, but also prompt. If you're interested into this topic, some recent evidence of the ongoing reorganization and its result can be found in their DebConf12 BoF, minutes of the last meeting, a set of forthcoming GRs, and the recent great decision of posting decisions results to d-d-a (as it happened for node/nodejs). Kudos to tech-ctte members for the recent activism! I haven't worked on it myself directly, but I highlight Enrico's work on server side archival of NM conversations. It has the potential of enabling automatic detection of stuck NM processes. I'm a bit rusty as AM now, but I think missing that ability is one of the main remaining causes of frustration when joining Debian. So, if you are an AM, please opt-in and use this feature with your appicants. If you are not an AM why not? :-) Miscellanea Some misc legal stuff: and some misc "political" stuff: Happy RC bug squashing,
Cheers.
PS the boring day-to-day activity log for July 2012 is available at master:/srv/leader/news/bits-from-the-DPL.txt.201207

Craig Small: Context sensitive menus with GtkTreeView

A project I now maintain called GJay uses the GTK+ toolkit and has a GtkTreeView that shows the directories and the songs in them. I was wanting to add a context sensitive menu on that view so that you could do things to the item you have right-clicked on; generally file specific things like give me information about this song or queue it to play. My only problem was, how to do it? A few Google searches showed things that were almost, but not quite, what I was after. The main problem being either the documentation was incomplete or it assumed I was after the selected field (the row I may of left-clicked on) and not the one I right-clicked on to get this event. This GtkTreeView uses a store where NAME_COLUMN is defined at 0, meaning it is the first column. The program uses this column to store the filename of the song. So first I needed to create an event to kick things off, we need to connect the button-press-event to our tree_view, which calls a function in this case view_on_button_pressed.
 g_signal_connect(tree_view, "button-press-event", 
   G_CALLBACK(view_on_button_pressed), NULL);
gboolean view_on_button_pressed(GtkWidget *tree_view, 
                                GdkEventButton *event, 
                                gpointer user_data)  
  GtkTreeSelection *selection;
  GtkTreePath *tree_path;
  GtkTreeModel *tree_model;
  GtkTreeIter tree_iter;
  gchar *name;
 
  if (event-&gt;type == GDK_BUTTON_PRESS &amp;&amp; event-&gt;button == 3)  
    tree_model = gtk_tree_view_get_model(GTK_TREE_VIEW(tree_view));
    if (gtk_tree_view_get_path_at_pos(GTK_TREE_VIEW(tree_view),
          (int)event-&gt;x, (int)event-&gt;y,
          &amp;tree_path, NULL, NULL, NULL))  
      if (gtk_tree_model_get_iter(tree_model, &amp;tree_iter, tree_path))  
        gtk_tree_model_get(tree_model, &amp;tree_iter, NAME_COLUMN, &amp;name, -1);
        g_print("rc name is %s\n", name);


So a breakdown of what my callback is doing: The program, now that it knows the song title, can then go off and generate a menu for that song.

2 August 2012

Russell Coker: Sam Harris on Lying

The Neuroscientist and atheism advocate Sam Harris has written a short blog post about a journalist named Jonah Lehrer who destroyed his career through false quotes and lies about them [1]. The main point of the article seems to be to promote his new eBook about Lying. The book is available for free until the end of the week (not sure if that is Friday, Saturday, or Sunday and in what time zone get it quick if you want it). The book is very short, 58 pages with a single column of large font text. If written a densely as a typical research paper it would probably be about 12 pages. But it has some good points to make. He makes a good moral case against most forms of lying, even answering questions such as do I look fat . It seems that anyone who was to follow his advice would be unusually honest even by Aspie standards. Related posts:
  1. Lies and Online Dating Separating Fact From Fiction: An Examination of Deceptive Self-Presentation in...
  2. Links January 2012 Cops in Tennessee routinely steal cash from citizens [1]. They...
  3. Desks Lindsay Holmwood has written about the benefits of a standing...

1 August 2012

Russell Coker: Hetzner now Offers SSD

Hetzner is offering new servers with SSD, good news for people who want to run ZFS (for ZIL and/or L2ARC). See the EX server configuration list for more information [1]. Unfortunately they don t specify what brand of SSD, this is a concern for me as some of the reports about SSD haven t been that positive, getting whichever SSD is cheapest isn t appealing. A cheap SSD might be OK for L2ARC (read cache), but for ZIL (write cache) reliability is fairly important. If anyone has access to a Hetzner server with SSD then please paste the relevant output of lsscsi into a comment. The next issue is that they only officially offer it on the new EX 8S server. SSD will be of most interest to people who also want lots of RAM (the zfsonlinux.org code has given me kernel panics when running with a mere 4G of RAM even when I did the recommended tuning to reduce ARC size). Also people who want more capable storage options will tend to want more RAM if only for disk caching. But I m sure that there are plenty of people who would be happy to have SSD on a smaller and cheaper server. The biggest SSD offering of 240G is bigger than a lot of servers. I run a Hetzner server that has only 183G of disk space in use (and another 200G of backups). If the backups were on another site then the server in question could have just a RAID-1 of SSD for all it s storage. In this case it wouldn t be worth doing as the server doesn t have much disk IO load, but it would be nice to have the option the exact same server plus some more IO load would make SSD the ideal choice. The biggest problem is that the EX 8S server is really expensive. Hard drives which are included in the base price for cheaper options are now expensive additions. A server with 2*3TB disks and 2*240G SSD is E167 per month! That s more expensive than three smaller servers that have 2*3TB disks! The good news for someone who wants SSD is that the Hetzner server auction has some better deals [2]. As is always the case with auction sites the exact offers will change by the moment, but currently they offer a server with 2*120G SSD and 24G of RAM for E88 per month and a server with 2*120G SSD, 2*1.5T HDD, and 24G of RAM for E118. E88 is a great deal if your storage fits in 240G and E118 could be pretty good if you only have 1.5T of data that needs ZFS features. The main SSD offering is still a good option for some cases. A project that I did a couple of years ago would probably have worked really well on a E167/month server with 2*3TB and 2*240G SSD. It was designed around multiple database servers sharding the load which was largely writes, so SSD would have allowed a significant reduction in the number of servers. They also don t offer SSD on their storage servers which is a significant omission. I presume that they will fix that soon enough. 13 disks and 2 SSD will often be more useful than 15 disks. That s assuming the SSD doesn t suck of course. The reason this is newsworthy is that most hosted server offerings have very poor disk IO and no good options for expanding it. For servers that you host yourself it s not too difficult to buy extra trays of disks or even a single rack-mount server that has any number of internal disks in the range 2 to 24 and any choice as to how you populate them. But with rented servers it s typically 2 disks with no options to add SSD or other performance enhancements and no possibility of connecting a SAN. As an aside it would still be nice if someone ran a data center that supported NetApp devices and gave the option of connecting an arbitrary number of servers to a NetApp Filer (or a redundant pair of Filers). If anyone knows of a hosting company that provides options for good disk IO which are better than just providing SSD or cheaper than E167 per month then please provide the URL in a comment. Update: It seems that I can get SSD added to one of the cheaper servers. This is a good option as I have some servers that already have the flexi-pack due to a need for more IP addresses. Related posts:
  1. Servers vs Phones Hetzner have recently updated their offerings to include servers with...
  2. Hetzner Failover Konfiguration The Wiki documenting how to configure IP failover for Hetzner...
  3. Dedicated vs Virtual Servers A common question about hosting is whether to use a...

Rapha&#235;l Hertzog: My Debian Activities in July 2012

This is my monthly summary of my Debian related activities. If you re among the people who made a donation to support my work (72.65 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. This month has been a short one since I have been away for 2 weeks of vacation. Dpkg My dpkg work encompasses a bunch of small tasks: Packaging I updated nautilus-dropbox to version 1.4.0 and python-django-registration to version 0.8. Both have been uploaded to unstable and I initially wanted to request an unblock for the latter, but it turns out it has gained reverse dependencies and version 0.8 introduces API changes so it s not an option at this point of the freeze. QA work I investigated and fixed #678356 where it had been reported that the PTS static news were no longer working as expected. At the start of the month, I also unblocked the mostly-unknown but important mole service it was out of date of several weeks and several people were annoyed that the information about new upstream versions was no longer up-to-date. Vacation Almost no Debian work during my vacation but the lack of Wifi nearby made me look for solutions to connect my computer through my Nokia N900 3G/GPRS connection. I discovered the Mobile Hotspot application (homepage) and it worked like a charm (although it required Maemo s non-default devel repository to be able to install the alternative kernel for power users ). The Debian Handbook Michal iha proposed us to host a Weblate instance to help translate the book with a web interface. He kindly agreed to implement some improvements to better suit my requirements. Those have been completed and the weblate instance is now live at debian.weblate.org. There s no requirement to use Weblate for translations teams but for those that do, it sure makes it easier to recruit volunteers who have no prior knowledge of Git and PO files. If you want to help, please checkout this page first though, you should not start using Weblate without getting in touch with the respective translations teams. Apart from translations, I also had the pleasure to merge some patches from Philipp Kern who improved the section covering IPv6 and a few other parts. We can make the book even better if more people share their expertise in the part of the book where they know better than me and Roland. :-) Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

31 July 2012

Martin Pitt: My impressions from GUADEC

I have had the pleasure of attending GUADEC in full this year. TL;DR: A lot of great presentations + lots of hall conversations about QA stuff + the obligatory be er,ach = . Last year I just went to the hackfest, and I never made it to any previous one, so GUADEC 2012 was a kind of first-time experience for me. It was great to put some faces and personal impressions to a lot of the people I have worked with for many years, as well as catching up with others that I did meet before. I discussed various hardware/software testing stuff with Colin Walters, Matthias Clasen, Lennart Poettering, Bertrand Lorentz, and others, so I have a better idea how to proceed with automated testing in plumbing and GNOME now. It was also really nice to meet my fellow PyGObject co-maintainer Paolo Borelli, as well as seeing Simon Schampier and Ignacio Casal Quinteiro again. No need to replicate the whole schedule here (see for yourself on the interwebs), so I just want to point out some personal highlights in the presentations: There were a lot of other good ones, some of them technical and some amusing and enlightening, such as Frederico s review of the history of GNOME. On Monday I prepared and participated in a PyGObject hackfest, but I ll blog about this separately. I want to thank all presenters for the excellent program, as well as the tireless GUADEC organizer team for making everything so smooth and working flawlessly! Great Job, and see you again in Strasbourg or Brno!

Christian Perrier: Discovering a new package: HotelDruid

What is good in "my" job in Debian are opportunities to discover new interesting packages. While surveying the completion of debconf translations in unstable, I thus noticed a new package named "hoteldruid", that has a few questions and interaction with users. After my usual mumble because French and a few other languages were *finally* virtually 100% in unstable for a few days...... I went on my usual task in such cases: propose a review of debconf templates and package description to my fellow debian-l10n-english co-workers (/me bends to Justin B. Rye, our tireless, picky, efficient and very clever Master Reviewer for over 5 years now). Then I discovered what HotelDruid is about: this is a piece of PHP-based software meant to manage....an hotel or bed and breakfast...or any kind of such facility. Real end-user software. Really useful software. For real people...:-) Not the gazillionth obscure development language, or yet another encryption library, or yet another mysterious virtualization thing used by 10 people in the world (even if they host thousands of machines). These are the free software pieces I like the most. Probably Marco Maria Francesco De Santis (the upstream author and Debian package maintainer) somewhere in, I guess, Italy is running a small B&B (or maybe his parents, or his wife/cousin/whatever) *and* is a free software addict. And he wanted to run his business with free software. Same for this French genealogist who once wanted to display his data over the web (and make a real use of that obscure Ocaml language.....yes, pun itended to my friends, here). Of the person who wrote LedgerSMB to manage his business. Or those who use free software to manage hospitals (hi Andreas) or schools (hi DebianEdu folks...and special hi to Petter). Real software for real people. Of course, developed with obscure geeky things used only by those weird geeks who like to sometimes travel half a planet to just gather together and develop the best free operating system ever. Guess what? I like this! And guess what? I proposed the HotelDruid author to check whether we could imrove....translation, of course..:-)

Russell Coker: ZFS on Debian/Wheezy

As storage capacities increase the probability of data corruption increases as does the amount of time required for a fsck on a traditional filesystem. Also the capacity of disks is increasing a lot faster than the contiguous IO speed which means that the RAID rebuild time is increasing, for example my first hard disk was 70M and had a transfer rate of 500K/s which meant that the entire contents could be read in a mere 140 seconds! The last time I did a test on a more recent disk a 1TB SATA disk gave contiguous transfer rates ranging from 112MB/s to 52MB/s which meant that reading the entire contents took 3 hours and 10 minutes, and that problem is worse with newer bigger disks. The long rebuild times make greater redundancy more desirable. BTRFS vs ZFS Both BTRFS and ZFS checksum all data to cover the case where a disk returns corrupt data, they don t need a fsck program, and the combination of checksums and built-in RAID means that they should have less risk of data loss due to a second failure during rebuild. ZFS supports RAID-Z which is essentially a RAID-5 with checksums on all blocks to handle the case of corrupt data as well as RAID-Z2 which is a similar equivalent to RAID-6. RAID-Z is quite important if you don t want to have half your disk space taken up by redundancy or if you want to have your data survive the loss or more than one disk, so until BTRFS has an equivalent feature ZFS offers significant benefits. Also BTRFS is still rather new which is a concern for software that is critical to data integrity. I am about to install a system to be a file server and Xen server which probably isn t going to be upgraded a lot over the next few years. It will have 4 disks so ZFS with RAID-Z offers a significant benefit over BTRFS for capacity and RAID-Z2 offers a significant benefit for redundancy. As it won t be upgraded a lot I ll start with Debian/Wheezy even though it isn t released yet because the system will be in use without much change well after Squeeze security updates end. ZFS on Wheezy Getting ZFS to basically work isn t particularly hard, the ZFSonLinux.org site has the code and reasonable instructions for doing it [1]. The zfsonlinux code doesn t compile out of the box on Wheezy although it works well on Squeeze. I found it easier to get a the latest Ubuntu working with ZFS and then I rebuilt the Ubuntu packages for Debian/Wheezy and they worked. This wasn t particularly difficult but it s a pity that the zfsonlinux site didn t support recent kernels. Root on ZFS The complication with root on ZFS is that the ZFS FAQ recommends using whole disks for best performance so you can avoid alignment problems on 4K sector disks (which is an issue for any disk large enough that you want to use it with ZFS) [2]. This means you have to either use /boot on ZFS (which seems a little too experimental for me) or have a separate boot device. Currently I have one server running with 4*3TB disks in a RAID-Z array and a single smaller disk for the root filesystem. Having a fifth disk attached by duct-tape to a system that is only designed for four disks isn t ideal, but when you have an OS image that is backed up (and not so important) and a data store that s business critical (but not needed every day) then a failure on the root device can be fixed the next day without serious problems. But I want to fix this and avoid creating more systems like it. There is some good documentation on using Ubuntu with root on ZFS [3]. I considered using Ubuntu LTS for the server in question, but as I prefer Debian and I can recompile Ubuntu packages for Debian it seems that Debian is the best choice for me. I compiled those packages for Wheezy, did the install and DKMS build, and got ZFS basically working without much effort. The problem then became getting ZFS to work for the root filesystem. The Ubuntu packages didn t work with the Debian initramfs for some reason and modules failed to load. This wasn t necessarily a show-stopper as I can modify such things myself, but it s another painful thing to manage and another way that the system can potentially break on upgrade. The next issue is the unusual way that ZFS mounts filesystems. Instead of having block devices to mount and entries in /etc/fstab the ZFS system does things for you. So if you want a ZFS volume to be mounted as root you configure the mountpoint via the zfs set mountpoint command. This of course means that it doesn t get mounted if you boot with a different root filesystem and adds some needless pain to the process. When I encountered this I decided that root on ZFS isn t a good option. So for this new server I ll install it with an Ext4 filesystem on a RAID-1 device for root and /boot and use ZFS for everything else. Correct Alignment After setting up the system with a 4 disk RAID-1 (or mirror for the pedants who insist that true RAID-1 has only two disks) for root and boot I then created partitions for ZFS. According to fdisk output the partitions /dev/sda2, /dev/sdb2 etc had their first sector address as a multiple of 2048 which I presume addresses the alignment requirement for a disk that has 4K sectors. Installing ZFS deb http://www.coker.com.au wheezy zfs I created the above APT repository (only AMD64) for ZFS packages based on Darik Horn s Ubuntu packages (thanks for the good work Darik). Installing zfs-dkms, spl-dkms, and zfsutils gave a working ZFS system. I could probably have used Darik s binary packages but I think it s best to rebuild Ubuntu packages to use on Debian. The server in question hasn t gone live in production yet (it turns out that we don t have agreement on what the server will do). But so far it seems to be working OK. Related posts:
  1. Discovering OS Bugs and Using Snapshots I m running Debian/Unstable on an EeePC 701, I ve got an...
  2. Starting with BTRFS Based on my investigation of RAID reliability [1] I have...
  3. ZFS vs BTRFS on Cheap Dell Servers I previously wrote about my first experiences with BTRFS [1]....

30 July 2012

Johannes Schauer: port bootstrap build-ordering tool report 4

A copy of this post is sent to soc-coordination@lists.alioth.debian.org as well as to debian-bootstrap@lists.mister-muffin.de.

Diary

July 2
  • playing around with syntactic dependency graphs and how to use them to flatten dependencies

July 4
  • make work with dose 3.0.2
  • add linux-amd64 to source architectures
  • remove printing in build_compile_rounds
  • catch Not_found exception and print warning
  • use the whole installation set in crosseverything.ml instead of flattened dependencies
  • detect infinite loop and quit in crosseverything.ml
  • use globbing in _tags file
  • use wildcards and patsubst in makefile

July 5
  • throw a warning if there exist binary packages without source packages
  • add string_of_list and string_of_pkglist and adapt print_pkg_list and print_pkg_list_full to use them
  • fix and extend flatten_deps - now also tested with Debian Sid

July 6
  • do not exclude the crosscompiled packages from being compiled in crosseverything.ml
  • clean up basebuildsystem.ml, remove old code, use BootstrapCommon code
  • clean up basenocycles.ml, remove unused code and commented out code
  • add option to print statistics about the generated dependency graph
  • implement most_needed_fast_wrong as well as most_needed_slow_correct and make both available through the menu

July 7
  • allow to investigate all scc, not only the full graph and the scc containing the investigated package
  • handle Not_found in src_list_from_bin_list with warning message
  • handle the event of the whole archive actually being buildable
  • replace raise Failure with failwith
  • handle incorrectly typed package names
  • add first version of reduced_dist.ml to create a self-contained mini distribution out of a big one

July 8
  • add script to quickly check for binary packages without source package
  • make Debian Sid default in makefile
  • add *.d.byte files to .gitignore
  • README is helpful now
  • more pattern matching and recursiveness everywhere

July 9
  • fix termination condition of reduced_dist.ml
  • have precise as default ubuntu distribution
  • do not allow to investigate an already installable package

July 10
  • milestone: show all cycles in a graph
  • add copyright info (LGPL3+)

July 11
  • advice to use dose tools in README

July 16
  • write apt_pkg based python filter script replacing grep-dctrl

July 17
  • use Depsolver.listcheck more often
  • add dist_graph.ml
  • refactor dependency graph code into its own module

July 18
  • improve package selection for reduced_dist.ml
  • improve performance of cycle enumeration code

July 20
  • implement buildprofile support into dose3

July 22
  • let dist_graph.ml use commandline arguments

July 23
  • allow dose3 to generate source package lists without Build- Depends Conflicts -Indep

July 29
  • implement crosscompile support into dose3

Results

Readme There is not yet a writeup on how everything works and how all the pieces of the code work together but the current README file provides a short introduction on how to use the tools.
  • build and runtime dependencies
  • compile instructions
  • execution examples for each program
  • step by step guide how to analyze the dependency situation
  • explanation of general commandline options
A detailed writeup about the inner workings of everything will be part of a final documentation stage.

License All my code is now released under the terms of the LGPL either version 3, or (at your option) any later version. A special linking exception is made to the license which can be read at the top of the provided COPYING file. The exception is necessary because Ocaml links statically, which means that without that exception, the conditions of distribution would basically equal GPL3+.

reduced_dist.ml Especially the Debian archive is huge and one might want to work on a reduced selection of packages first. Having a smaller selection of the archive would be significantly faster and would also not add thousands of packages that are not important for an extended base system. I call a reduced distribution a set of source packages A and a set of binary packages B which fulfill the following three properties:
  • all source packages A must be buildable with only binary packages B being available
  • all binary packages B except for architecture:all packages must be buildable from source packages A
The set of binary packages B and source packages A can be retrieved using the reduced_dist program. It allows to either build the most minimal reduced distribution or one that includes a certain package selection. To filter out the package control stanzas for a reduced distribution from a full distribution, I originally used a call to grep-dctrl but later replaced that by a custom python script called filter-packages.py. This script uses python-apt to filter Packages and Sources files for a certain package selection.

dist_graph.ml It soon became obvious that there were not many independent dependency cycle situation but just one big scc that would contain 96% of the packages that are involved in build dependency cycles. Therefor it made sense to write a program that does not iteratively build the dependency graph starting from a single package, but which builds a dependency graph for a whole archive.

Cycles I can now enumerate all cycles in the dependency graph. I covered the theoretical part in another blog post and wrote an email about the achievement to the list. Both resources contain more links to the respective sourcecode. The dependency graph generated for Debian Sid has 39486 vertices. It has only one central scc with 1027 vertices and only eight other scc with 2 to 7 vertices. All the other source and binary packages in the dependency graph for the archive are degenerate components of length one. Obtaining the attached result took 4 hours on my machine (Core i5 @ 2.53GHz). 1.5 h of that were needed to build the dependency graph, the other 2.5 hours were needed to run johnson's algorithm on the result. Memory consumption of the program was at about 700 MB. It is to my joy that apparently the runtime of the cycle finding algorithm for a whole Debian Sid repository as well as the memory requirements are within orders of magnitude that are justifiable when being run on off-the-shelf hardware. It must also be noted that nothing is optimized for performance yet. A list of all cycles in Debian Sid up to length 4 can be retrieved from this email. This cycle analysis assumes that only essential packages, build-essential and dependencies and debhelper are available. Debhelper is not an essential or build-essential package but 79% of the archive build-depends on it. The most interesting cycles are probably those of length 2 that need packages that they build themselves. Noticeable examples for these situations are vala, python, mlton, fpc, sbcl and ghc. Languages seem love to need themselves to be built.

Buildprofiles There is a long discussion of how to encode staged build dependency information in source packages. While the initial idea was to use Build-Depends-StageN fields, this solution would duplicate large parts of the Build-Depends field, which leads to bitrot as well as it is inflexible to possible other build "profiles". To remedy the situation it was proposed to use field names like Build-Depends[stage1 embedded] but this would also duplicate information and would break with the rfc822 format of package description files. A document maintained by Guillem Jover gives even more ideas and details. Internally, Patrick and me decided for another idea of Guillem Jover to annotate staged build dependencies. The format reads like:
Build-Depends: huge (>= 1.0) [i386 arm] <!embedded !bootstrap>, tiny
So each build profile would follow a dependency in <> "brackets" an have a similar format as architecture options. Patrick has a patch for dpkg that implements this functionality while I patched dose3.

Dropping Build-Depends-Indep and Build-Conflicts-Indep When representing the dependencies of a source package, dose3 concatenates its Build-Depends and Build-Depends-Indep dependency information. So up to now, a source package could only be compiled, if it manages to compile all of its binary packages including architecture:all packages. But when bootstrapping a new architecture, it should be sufficient to only build the architecture dependent packages and therefor to only build the build-arch target in debian/rules and not the build-indep target. Only considering the Build-Depends field and dismissing the Build-Depends-Indep field, reduced the main scc from 1027 vertices to 979 vertices. The amount of cycles up to length four reduced from 276 to 206. Especially the cycles containing gtk-doc-tools, doxygen, debiandoc-sgml and texlive-latex-base got much less. Patrick managed to add a Build-Depends-Indep field to four packages so far which reduced the scc further by 14 vertices down to 965 vertices. So besides staged build dependencies and cross building there is now a third method that can be applied to break dependency cycles: add Build-Depends-Indep information to them or update existing information. I submitted a list of packages that have a binary-indep and/or a build-indep target in their debian/rules to the list. I also submitted a patch for dose3 to be able to specify to ignore Build-Depends-Indep and Build-Conflicts-Indep information.

Dose3 crossbuilding So far I only looked at dependency situations in the native case. While the native case contains a huge scc of about 1000 packages, the dependency situation will be much nicer when cross building. But dose3 was so far not able to simulate cross building of source packages. I wrote a patch that implements this functionality and will allow me to write programs that help analyze the cross-situation as well.

Debconf Presentation Wookey was giving a talk at debconf12 for which I was supplying him with slides. The slides in their final version can be downloaded here

Future Patrick maintains a list of "weak" build dependencies. Those are dependencies that are very likely to be droppable in either a staged build or using Build-Depends-Indep. I must make use of this list to make it easier to find packages that can easily be removed of their dependencies. I will have to implement support for resolving the main scc using staged build dependencies. Since it is unlikely that Patrick will be fast enough in supplying me with modified packages, I will need to create myself a database of dummy packages. Another open task is to allow to analyze the crossbuilding dependency situation. What I'm currently more or less waiting on is the inclusion of my patches into dose3 as well as a decision on the buildprofile format. More people need to discuss about it until it can be included into tools as well as policy. Every maintainer of a package can help making bootstrapping easier by making sure that as many dependencies as possible are part of the Build-Depends-Indep field.

29 July 2012

Joey Hess: build a dynamic webapp in Yesod in just three days

This screencast shows what I built. Scroll down for my Yesod braindump. <video controls="controls" src="http://joeyh.name/screencasts/git-annex-webapp.ogg"></video> video link I've been astonished how quickly this went together. This is my first time using any sort of web framework, and I used a still unusual one, Yesod. It's my first time using Bootstrap too. It's also the first time I've done any AJAX programming! Bootstrap was something I'd heard of and seen some suspiciously similar looking sites built with, but it was really a pleasant surprise. Being able to make things that work and look good on the web without struggling with CSS is such a nice change. For the first time, it makes the web feel like a UI toolkit to me. As I've learned Yesod, I kept seeing problems the web framework solves that I either solved in an ad-hoc basis in Ikiwiki, or didn't realize were problems. In the former group are things like having a consistent way to store a URL to redirect to after an action (such as logging in) finishes, and generating urls programmatically in ways that avoid broken links. In the latter group are things like exploiting types to guarantee mistakes can't be made. And also the abstraction of widgets, which combine html, css, and javascript, in a way that can be composed with other widgets. Overall, I'm really enjoying Yesod, and it's making me productive in new ways. I also see a lot of potential in Yesod to improve from where it is.
    webpage = bootstrap Dynamic $ do
        setTitle "FooCorp"
        login <- getLogin
        navbar [FixedTop] $ do
            brand "FooCorp"
            link AboutR
            link BlogR
            nav [PullRight] $
                link . maybe LoginR ProfileR login
        div [ContainerFluid] $ content login
        where
            content Nothing = heroUnit $ do
                para $ "We're the FooCorp for you."
                button "Register Today" [Primary, Large] SignUpR
                carousel
                    [ amazingFeatures
                    , aboutFooCorp
                    , pricing
                    ]
            content (Just user)  = do
                para $ "Welcome back " ++ name user ++ "!"
                showProfile user

Jordi Mallach: GUADEC 2012

I've been in A Coru a for this year's GUADEC since Tuesday night, and it rocked. I did a late registration after my first week at Collabora, which is sponsoring my stay here.
I came one day early to participate, as Debian's representative, at the yearly GNOME Advisory Board meeting, for the first time. It was a positive experience, which helped me get a grasp of the big picture of what the GNOME Foundation does. I also had the pleasure of visiting Igalia's awesome offices in the city, and puting faces to many names during the meeting. I presented an overview of Debian's relation to GNOME, how our packaging team works and what are our goals and biggest problems as a GNOME downstream. We stirred some good debate as some other Advisory Board members share part of our problems. I should be posting a summary of what happened there for debian-project@ldo as soon as I have the time to scribble it. I've met with GNOME Hispano people I hadn't seen since 2004 or 2006 in the best case, and catched up with many of them. I've also met many GPUL members I had know for over a decade via IRC, but never had met in person, and it was about time. And of course, I've got to known a good number of my new workmates at Collabora, and had fun with them around the conference, the beach and the numerous post-conference events. Last, but not least, I ended up participating in the GNOME Olympics, substituting Rodrigo in Team B Core Dumped , along with Stefano, John, Bastien, Chema and Adam. WE WON, not thanks to me, but the statistics shine: I've won all FreeFA World Cups I've played :P so here's a PROtip: if you want to win next year, be sure to be my team mate, and more importantly, be sure Adam is not your rival. :) Unfortunately, I'm only attending the core days so tonight I'll be flying back to Madrid on my way home in Val ncia. See you next year! A Coru a is a city that has impressed me quite a bit, and I'm looking forward to coming back for some more standard vacation at some point. :)

28 July 2012

Vincent Bernat: Switching to the awesome window manager

I have happily used FVWM as my window manager for more than 10 years. However, I recently got tired of manually arranging windows and using the mouse so much. A window manager is one of the handful pieces of software getting in your way at every moment which explains why there are so many of them and why we might put so much time in it. I decided to try a tiling window manager. While i3 seemed pretty hot and powerful (watch the screencast!), I really wanted something configurable and extensible with some language. So far, the common choices are: I chose awesome, despite the fact that StumpWM vote for Lisp seemed a better fit (but it is more minimalist). I hope there is some parallel universe where I enjoy StumpWM. Visually, here is what I got so far: awesome dual screen setup

Awesome configuration Without a configuration file, awesome does nothing. It does not come with any hard-coded behavior: everything needs to be configured through its Lua configuration file. Of course, a default one is provided but you can also start from scratch. If you like to control your window manager, this is somewhat wonderful. awesome is well documented. The wiki provides a FAQ, a good introduction and the API reference is concise enough to be read from the top to the bottom. Knowing Lua is not mandatory since it is quite easy to dive into such a language. I have posted my configuration on GitHub. It should not be used as is but some snippets may be worth to be stolen and adapted into your own configuration. The following sections put light on some notable points.

Keybindings Ten years ago was the epoch of scavanger hunts to recover IBM Model M keyboards from waste containers. They were great to type on and they did not feature the infamous Windows keys. Nowadays, this is harder to get such a keyboard. All my keyboards now have Windows keys. This is a major change with respect to configure a window manager: the left Windows key is mapped to Mod4 and is usually unused by most applications and can therefore be dedicated to the window manager. The main problem with the ability to define many keybindings is to remember the less frequently used one. I have monkey-patched awful.key module to be able to attach a documentation string to a keybinding. I have documented the whole process on the awesome wiki. awesome online help

Quake console A Quake console is a drop-down terminal which can be toggled with some key. I was heavily relying on it in FVWM. I think this is still a useful addition to any awesome configuration. There are several possible solutions documented in the awesome wiki. I have added my own1 which works great for me. Quake console

XRandR XRandR is an extension which allows to dynamically reconfigure outputs: you plug an external screen to your laptop and you issue some command to enable it:
$ xrandr --output VGA-1 --auto --left-of LVDS-1
awesome detects the change and will restart automatically. Laptops usually come with a special key to enable/disable an external screen. Nowadays, this key does nothing unless configured appropriately. Out of the box, it is mapped to XF86Display symbol. I have associated this key to a function that will cycle through possible configurations depending on the plugged screens. For example, if I plug an external screen to my laptop, I can cycle through the following configurations:
  • only the internal screen,
  • only the external screen,
  • internal screen on the left, external screen on the right,
  • external screen on the left, internal screen on the right,
  • no change.
The proposed configuration is displayed using naughty, the notification system integrated in awesome. Notification of screen reconfiguration

Widgets I was previously using Conky to display various system-related information, like free space, CPU usage and network usage. awesome comes with widgets that can fit the same use. I am relying on vicious, a contributed widget manager, to manage most of them. It allows one to attach a function whose task is to fetch values to be displayed. This is quite powerful. Here is an example with a volume widget:
local volwidget = widget(  type = "textbox"  )
vicious.register(volwidget, vicious.widgets.volume,
         '<span font="Terminus 8">$2 $1%</span>',
        2, "Master")
volwidget:buttons(awful.util.table.join(
             awful.button(   , 1, volume.mixer),
             awful.button(   , 3, volume.toggle),
             awful.button(   , 4, volume.increase),
             awful.button(   , 5, volume.decrease)))
You can also use a function to format the text as you wish. For example, you can display a value in red if it is too low. Have a look at my battery widget for an example. Various widgets

Miscellaneous While I was working on my awesome configuration, I also changed some other desktop-related bits.

Keyboard configuration I happen to setup all my keyboards to use the QWERTY layout. I use a compose key to input special characters like . I have also recently use Caps Lock as a Control key. All this is perfectly supported since ages by X11 I am also mapping the Pause key to XF86ScreenSaver key symbol which will in turn be bound to a function that will trigger xautolock to lock the screen. Thanks to a great article about extending the X keyboard map with xkb, I discovered that X was able to switch from one layout to another using groups2. I finally opted for this simple configuration:
$ setxkbmap us,fr '' compose:rwin ctrl:nocaps grp:rctrl_rshift_toggle
$ xmodmap -e 'keysym Pause = XF86ScreenSaver'
I switch from us to fr by pressing both left Control and left Shift keys.

Getting rid of most GNOME stuff Less than one year ago, to take a step forward to the future, I started to heavily rely on some GNOME components like GNOME Display Manager, GNOME Power Manager, the screen saver, gnome-session, gnome-settings-daemon and others. I had numerous problems when I tried to setup everything without pulling the whole GNOME stack. At each GNOME update, something was broken: the screensaver didn t start automatically anymore until a full session restart or some keybindings were randomly hijacked by gnome-settings-daemon. Therefore, I have decided to get rid of most of those components. I have replaced GNOME Power Manager with system-level tools like sleepd and the PM utilities. I replaced the GNOME screensaver with i3lock and xautolock. GDM has been replaced by SLiM which now features ConsoleKit support3. I use ~/.gtkrc-2.0 and ~/.config/gtk-3.0/settings.ini to configure GTK+. The future will wait.

Terminal color scheme I am using rxvt-unicode as my terminal with a black background (and some light transparency). The default color scheme is suboptimal on the readability front. Sharing terminal color schemes seems a popular activity. I finally opted for the derp color scheme which brings a major improvement over the default configuration. Comparison of terminal color schemes I have also switched to Xft for font rendering using DejaVu Sans Mono as my default font (instead of fixed) with the following configuration in ~/.Xresources:
Xft.antialias: true
Xft.hinting: true
Xft.hintstyle: hintlight
Xft.rgba: rgb
URxvt.font: xft:DejaVu Sans Mono-8
URxvt.letterSpace: -1
The result is less crisp but seems a bit more readable. I may switch back in the future. Comparison of terminal fonts

Next steps My reliance to the mouse has been greatly reduced. However, I still need it for casual browsing. I am looking at luakit a WebKit-based browser extensible with Lua for this purpose.

  1. The console gets its own unique name. This allows awesome to reliably detect when it is spawned, even on restart. It is how the Quake console works in the mod of FVWM I was using.
  2. However, the layout is global, not per-window. If you are interested by a per-window layout, take a look at kbdd.
  3. Nowadays, you cannot really survive without ConsoleKit. Many PolicyKit policies do not rely on groups any more to grant access to your devices.

John Goerzen: How to get started programming?

I have been asked for advice from several people recently on how to get started programming, or how to further develop a nascent interest in coding or software engineering. The people asking the questions range in age from about 10 years old to older than me. These are people that, for various reasons, are not very easily able to take computer science courses right now. One would think that, since I ve been doing this for somewhere around a quarter century (oh I do feel old now), that I d be ready to offer up some great advice. And offer some suggestions I have. But I m not convinced they re good ones. I have two main tensions. The first is that I, like many in the communities I tend to hang out in such as Debian s, have a personality that leads me to take a deep dive into details of anything that holds my interest. Whether it s Linux, Haskell, or amateur radio, I want to do more than skim the surface if I m having fun with it. Many people are not like that. They may have a lot of fun programming in Visual Basic, not really caring that other languages are out there. Or some people are not like this yet. I feel unqualified to provide good advice to people that are different from me in that way. To put it a different way: most people don t want to wait 4 years to be useful, and want to start out right away and get better over time (and I was the same way too.) The second is related. I learned programming at a time when, other than BASIC, interpreted languages were not really available to me. (Yes, they were available, but not to me.) I cut my teeth on BASIC, Pascal, and C. Although I rarely use C anymore, I can still drop into it at a moment s notice and be perfectly comfortable. I feel it was a fundamentally valuable experience, and that it would be very hard to become a great programmer without ever having lived and breathed something like C, where memory and pointers must be managed manually. Having said that, it is probably possible to become a good coder without ever having touched C. Here, then, is an edited version of some rambly advice I sent to someone recently, where learning OOP was particularly mentioned. I would welcome your comments and suggestions. I may point people that ask to this post in the future. For simply learning how to write code, Dive Into Python has long been a decent resource, though it may assume more experience than some have. I haven t read them myself, but I ve also heard good things about the How to Think Like a Computer Scientist series from Green Tea Press. They re all available as free PDF downloads, too! Eric S. Raymond s The Art of Unix Programming is another work I ve heard good things about, despite having never read it myself. A quick glance at the table of contents makes me think that even if people don t wind up working on Unix, the lessons and philosophy should be informative. It seems that many Computer Science programs are using Java for the core of their instruction, or even almost exclusively. Whether that is good or bad, I m not completely sure. It certainly gets people into OOP more deeply, but I m a right tool for the job kind of person. Despite the hype, OO like everything else isn t the right tool for every job. It is fine for people to dive straight into OO and become good programmers/engineers. However, I think it would be difficult to become a great programmer/engineer without ever having a solid understanding of a more low-level language, such as C in particular. I did my CS work when it was mostly based in C, and am glad for it. If someone never has to manage memory or pointers, I suspect they will be at a disadvantage in the long run for not being able to understand or work with the system at a more fundamental level. If a person knows C, plus some concepts of OO and Functional Programming (FP), it should be easy to pick up just about any other language out there. I used to think Python was a great first language, but during the 2.x series they added so much fluff and so many special cases that I m less enthusiastic now, though I don t know how much of that got cleaned up in 3.x. I am not too keen on Java as a first language, because too many things that should be simple aren t. I have a fondness for Haskell, and its close relationship to mathematics could make it a great first language or maybe a poor one, depending on your perspective. One other thing I think it s important for good programmers to have experience with all three major models of programming (procedural, OO, functional.) Even if a person winds up working mostly in one universe, knowledge of and experience with the others is important and informative and, in my experience, leads to better algorithms and architecture all around.

Next.

Previous.