Search Results: "reg"

13 March 2012

Joachim Breitner: ghc-heap-view: Complete referential opacity

During the last week, I created ghc-heap-view, a library to investigate the actual memory representation of Haskell values. It is inspired by vacuum and the GHCi debugger, but goes beyond them by allowing the user to look inside thunks and functions and see what other values they refer to. Let me demonstrate it by running the included demo: ghc-heap-view-demo Here are a four different lists, where the first three are already evaluated.
The first one, l, was defined as a top level constant as
> l = [1,2,3]
and is now found at 0x00000000006d1750/2 (where the /2 is the pointer tag information) and fully evaluated:
  ConsClosure  info = StgInfoTable  ptrs = 2, nptrs = 0, tipe = CONSTR_STATIC, srtlen = 1 , 
                 ptrArgs = [0x00000000006d16e0/1,0x00000000006d1730/2],
                 dataArgs = [], descr = "ghc-prim:GHC.Types.:" 
The second one, l2, is locally defined
> let l2 = 4:l
and now found at 0x00007fdce19fe4b0/2. See how the cons-cell references l!
  ConsClosure  info = StgInfoTable  ptrs = 2, nptrs = 0, tipe = CONSTR_2_0, srtlen = 1 ,
                 ptrArgs = [0x00000000006dca50/1,0x00000000006d1750/2],
                 dataArgs = [],
                 descr = "ghc-prim:GHC.Types.:" 
And the binding
> args <- map length  fmap  getArgs
evaluates to the one , global empty list at 0x00000000006db640/1:
  ConsClosure  info = StgInfoTable  ptrs = 0, nptrs = 0, tipe = CONSTR_NOCAF_STATIC, srtlen = 0 ,
                 ptrArgs = [],
                 dataArgs = [],
                 descr = "ghc-prim:GHC.Types.[]" 
And now we have, at 0x00007fdce19fe4c8, the concatenation of them, but unevaluated:
> let x = l ++ l2 ++ args
The thunk keeps a reference to l2 and args, but not l, as that is at a static address, unless you are running this in GHCi:
  ThunkClosure  info = StgInfoTable  ptrs = 2, nptrs = 0, tipe = THUNK_2_0, srtlen = 1 ,
                  ptrArgs = [0x00007fdce19fe4b0/2,0x00000000006db640/1],
                  dataArgs = [] 
Now to some more closure types. m and m' locally bound of type the unboxed type Int#, with values 42 resp. 23.
> let f = \x n -> take (I# m + I# x) n ++ args
  t = f m' l2
So here is (0x00007fdce1937d50/2), referencing its free variables args and 42:
  FunClosure  info = StgInfoTable  ptrs = 1, nptrs = 1, tipe = FUN_1_1, srtlen = 65553 ,
                ptrArgs = [0x00000000006db640/1],
                dataArgs = [42] 
And t is a thunk that applies f (also referenced here) to an unboxed value (23) and l2:
  ThunkClosure  info = StgInfoTable  ptrs = 2, nptrs = 1, tipe = THUNK, srtlen = 0 ,
                  ptrArgs = [0x00007fdce19fe4b0/2,0x00007fdce1937d50/2],
                  dataArgs = [23] 
Lastly, here is the standard example for self reference:
> let x = id (:) () x
This is what x (0x00007fdce1947940) looks like, at least without -O:
  ThunkClosure  info = StgInfoTable  ptrs = 0, nptrs = 0, tipe = THUNK, srtlen = 1 ,
                  ptrArgs = [],
                  dataArgs = [] 
So it is unevaluated. Let us evaluate it using seq. Now we have, still at 0x00007fdce1947940:
  IndClosure  info = StgInfoTable  ptrs = 1, nptrs = 0, tipe = BLACKHOLE, srtlen = 0 ,
                indirectee = 0x00007fdce194cc98/2 
The thunk was replaced by an indirection. If we look at the target, 0x00007fdce194cc98/2, we see that it is a newly created cons-cell referencing the original location of x:
  ConsClosure  info = StgInfoTable  ptrs = 2, nptrs = 0, tipe = CONSTR_2_0, srtlen = 1 ,
                 ptrArgs = [0x00000000006db620/1,0x00007fdce1947940],
                 dataArgs = [],
                 descr = "ghc-prim:GHC.Types.:" 
After running the garbage collector (performGC), we find that the address of x is now 0x00007fdce19f30d0/2 and that the self-reference is without indirections:
  ConsClosure  info = StgInfoTable  ptrs = 2, nptrs = 0, tipe = CONSTR_2_0, srtlen = 1 ,
                 ptrArgs = [0x00000000006db620/1,0x00007fdce19f30d0/2],
                 dataArgs = [],
                 descr = "ghc-prim:GHC.Types.:" 
Future plans The output of ghc-heap-view is not really pretty yet; even the indentation in this blog post was added manually by me, so this really needs a pretty printer providing a nicer, possibly more compact representation, including something like what vacuum provides. Maybe vacuum can be ported to use this library, and also include the thunk s and function s references in the output. Maybe also the GHCi debugger can be extended to show more information about unevaluated expressions using this. Internally, the library is not very polished yet either. It only handles those closures types that I have seen so far, and is likely to break horribly if run in a threaded or debugging enabled runtime. How it works Obviously, this is not standard Haskell 98 code, but rather deep trickery involving the GHC API and some C code. Initially I tried to use the API that vacuum and the GHCi debugger rely on, which is an operation
unpackClosure# :: a -> (# Addr#, Array# b, ByteArray# #)
which takes any Haskell value and returns the address to its info table, the pointers and the non-pointer-data in the closure. Unfortunately, it was not complete in that it was meant only for data closures and will for other closure types, e.g. thunks, return no data and no pointers (as can be seen in the code). So I implemented my own version of this operation:
foreign import prim "slurpClosurezh" slurpClosure# :: Any -> (# Addr#, ByteArray#, Array# b #)
where the returned ByteArray# contains the complete closure, including extra information fields such as the arity of a function. The Array# is again the list of pointers in the closure. At first glance, this is a duplication, as the pointers are of course also contained in the ByteArray#. But as soon as the GHC runtime reigns again, a garbage collector run can happen, the referenced values will move somewhere else, and the words that once were pointers in the ByteArray# become useless. But the corresponding entries in the Array# are updated by the garbage collector, as it knows that these are pointers, and not just words. This way, we get both a faithful copy of the closure on the heap and useful references to the contained data. Here is a demonstration of this effect:
$ ghci -XMagicHash -package ghc-heap-view
GHCi, version 7.4.1: http://www.haskell.org/ghc/  :? for help
Loading package ghc-prim ... linking ... done.
[..]
Loading package ghc-7.4.1 ... linking ... done.
Loading package ghc-heap-view-0.1 ... linking ... done.
Prelude> let  a = [1,2,3,4]; b = 5:a 
Prelude> :m + GHC.HeapView 
Prelude GHC.HeapView> rawHeapData <- getClosureRaw b
Prelude GHC.HeapView> rawHeapData 
(0x000000004080d658,[1082185320,140040739366568,140040739365928],[0x00007f5dc68626a8,0x00007f5dc6862428])
Prelude GHC.HeapView> System.Mem.performGC
Prelude GHC.HeapView> rawHeapData 
(0x000000004080d658,[1082185320,140040739366568,140040739365928],[0x00007f5dc41b3ad8,0x00007f5dc41b3b28]) 
The function rawHeapData is a thin wrapper around slurpClosure# which turns the primitive array in normal lists. Note that the second component of the triple is unchanged, but the third is updated by the garbage collector. Of course this means that the Show instance for the data type that ghc-heap-view uses to reference values is not referential transparent either. The foreign function import above is of type prim , i.e. does not call a C function but rather a Cmm function. Cmm is a reduced C that GHC uses internally to compile the Haskell code to, and most primitive operations are implemented in this language although I do quickly call regular C from my Cmm code to do the more complicated stuff, mainly figuring out what words of the closure are pointers. The knowledgeable reader might notice that I am passing a boxed value of type Any to the foreign function. This is currently not possible with foreign prim functions, and to actually use that code, you need the patch in GHC ticket #5931. But you can use ghc-heap-view without that as well (and the Cabal package will by default use that path), using the following hack to obtain the pointer to a Haskell value on the Heap as an unboxed type that can pass to the primitive operation:
foreign import prim "slurpClosurezh" slurpClosure'# :: Word#  -> (# Addr#, ByteArray#, Array# b #)
data Ptr' a = Ptr' a
aToWord# :: Any -> Word#
aToWord# a = case Ptr' a of mb@(Ptr' _) -> case unsafeCoerce# mb :: Word of W# addr -> addr
slurpClosure# :: Any -> (# Addr#, ByteArray#, Array# b #)
slurpClosure# a = slurpClosure'# (aToWord# a)
This works because a Word and a Ptr' have the same closure layout, only differing in the fact that one stores an a, and the other stores a Word#. Once we obtained the raw representation of the closure, we do the parsing in Haskell. Using the info table and the raw closure, we have enough information to tell which words have to be replaced by the appropriate pointer (which might already have been updated by the garbage collector) in the pointers list. This work was supported by a scholarship from the Deutsche Telekom Stiftung.

Flattr this post

Vasudev Kamath: Tag Generation problem in Jekyll

After converting my blog to use Jekyll and hosting it on Github one problem I faced is missing tagging feature for post. I quickly came across this I used plugin from the site and copied and modified some files from authors websites git repository. Only way to use tags on Github was to generate tags locally and move it to Github. To put more light on the point Github disables jekyll plugin so it won't generate the tags after you push your changes to Github repository. You need to follow these steps.
  1. Create posts
  2. Generate site locally by running jekyll
  3. Copy out _site/tag to your website root folder
I did this and it worked. But funny part was when I created new post and tagged it and followed above step for some reason tags won't reflect on respective tag's page and I had no clue why. After banging head for a while I noticed that Previously coped tag folder in site's root is overwriting the tags generated by Jekyll plugin!. Gosh so much for my stupidity :). Now I've written a script to generate tags after writing each new post. It deletes the existing tag directory first and then regenerates tag and copies it out to website root and then it commits the tag directory. Here it is
#!/bin/sh
TAG=tag/
SITE=_site/
if [ -d $ TAG  ]; then
    echo "Deleting $ TAG  directory..."
    rm -rf $ TAG 
fi
echo "Regenerating Site..."
jekyll
echo "Copying $ TAG  ..."
cp -a $ SITE /$ TAG  .
echo "Commiting Changes..."
git commit $ TAG  -m "Latest TAG build"
Hope that helps. Cya!

12 March 2012

Stefano Zacchiroli: debian contributions to the linux kernel

The statistics of the "who wrote Linux x.y.z" series date back to at least 2.6.20. According to my experience talking with users and Free Software enthusiasts, those statistics really make a dent in the public perception of who is giving back upstream. Obviously, one should not take a single upstream, even if it is as important as the Linux kernel, as a measure of how much a given Free Software entity is giving back upstream overall. But users still seem to be fascinated by them. As a result, I have often had to answer the question: why Debian doesn't show up on those statistics?. My answer has always been something along the lines that Debian Developers who maintain Linux kernel packages, the almighty Debian Kernel Team, do that mostly as part of their volunteer engagement in Debian. As a consequence, they do not earmark their contributions as if they worked for a company and they add up to the hobbyist count instead (although you can you can routinely spot individual Debian Kernel Team members among the most active contributors for specific Linux releases). The above is the true and honest answer. But every time I've given it, I couldn't help feeling that the user who asked went home with a "yeah, well" afterthought. If you don't want to take my word of it, fine. Here is what Greg K-H had to say about Debian contributions in a recent blog post about the stable Linux kernel:
I would personally like to thank the Debian kernel developers, specifically Ben Hutchings, Maximilian Attems, Dann Frazier, Bastian Blank, and Moritz Muehlenhoff. They went above and beyond what any "normal" developer would have done, ferreting patches out of the kernel.org releases and the different vendor kernels and bug tracking systems, backporting them to the 2.6.32 kernel, testing, and then forwarding them on to me. Their dedication to their user community is amazing for such a "volunteer" group of developers. I firmly believe that without their help, the 2.6.32 kernel would not have been the success that it was. The users of Red Hat and SuSE products owe them a great debt. Buy them a beer the next time you see them, they more than deserve it.
I'll take good care of following his wise advice. Please do the same.
(Thanks to Sylvestre for pointing me to Greg's blog post.)

Vincent Sanders: Time flies when you are having fun.

It has been months since I last put something here, so I think that requires a quick catchup.

The family Christmas was a brilliantly restful affair mostly spent doing nothing at home, just slightly tinged with anticipation of starting the new job.

I arranged to rent a room in Cambridge with just a moderate three mile walk to work. This has meant that after a decade of my daily commute being the steps downstairs to my desk I am now walking six miles a day!

Because of this unexpected physical exertion I seem to be slowly loosing weight instead of gaining it. Alas there is still a long way to go before I am my recommended weight (unless I gain three feet in height ;-)

Work has been fabulous, lots of great people doing interesting stuff. I was here only a month before I got sent to San Francisco for the Linaro connect event. Though getting on the outbound plane amidst the worst snowstorm in recent times was both tiring and not a little stressful.

The waking up at 03:00 to get the 04:00 coach from Cambridge to Heathrow would not have been too much of an issue If I had managed to travel down from Leeds and arrive before 02:00. The coach was so much fun that I arrived at 08:40 just as check in was closing for my 09:45 flight.

This was my first experience of San Francisco (although I have been to LA and Portland previously) and while most of the time was spent out in Redwood city at the conference venue Robert did take us for cocktails, comedy and cable cars which was a wonderful night out.

Since my return from the US I have also attended the Debian Bug Squashing Party in Cambridge and had a thoroughly amusing time with many of the usual suspects though I was encouraged to see a few new faces about too.

The commute up and down the country is getting tedious and seems to vary between taking two and four hours depending on traffic. This is encouraging me to consider moving the family as soon as I can. They are all doing great and seem to be thriving despite my absence during weekdays.

I hope to put finger to keyboard here a bit more regularly in the forthcoming weeks though a lot of my personal time is being swallowed with commuting and not being directed towards my open source pursuits.

Michal &#268;iha&#345;: Weblate 0.5

Continuing with fast release pace for Weblate, I've just released version 0.5. It brings lot of bug fixes (thanks for everybody who has provided feedback), lot of new translations (thanks to translators) and as a special bonus it can use few machine translation services. Full list of changes for 0.5: You can find more information about Weblate on it's website, the code is hosted on Github. If you are curious how it looks, you can try it out on demo server. You can login there with demo account using demo password or register your own user. Weblate is now also being used https://l10n.cihar.com/ as official translating service for phpMyAdmin, Gammu, Weblate itself and others.

Filed under: English Weblate 0 comments Flattr this!

9 March 2012

Gunnar Wolf: I am going to DebConf12!

I have just bought our plane tickets to Managua, so I can finally say this: Going-to-banner-180x150-grey Yes, many of you will ask what happened, I was bragging everywhere I wanted to go by land, driving from Mexico City to Managua. I'd love to, and I'm sure it's completely doable... But we have family issues to attend on July 21, in Argentina. So we will have a beautiful flight schedule (and carbon footprint) for this July:
June 30
Mexico San Salvador Managua, 17:35-20:30. Yes, this means I will not be in Mexico to cast my vote on July 1st. Well, I had already accepted this would happen... And the price difference was quite sensible.
July 15
Managua San Jos Mexico, 16:25-22:20
July 16
Mexico Santiago Buenos Aires (AEP), 20:30-09:55
July 23
Buenos Aires (EZE) Lima Mexico, 08:35-19:00
Several people have asked me on the best airline options for this trip. In our case, to Managua, it was with TACA, US$518 total. You can get tickets for ~US$30 less, but the flight goes through Panama instead of San Salvador, for an extra 1000Km And instead of ~3hr it makes slightly over 6. Yes, on our way back we will be routed a bit South to San Jos , but it's not as bad, and it's for a very short layover. For Argentina? Well, we have always found LAN to be the cheapest and most convenient. This time, TACA/Avianca was a very close second, which lost due to almost doubling the flight+layover time Why aren't we taking a Mexico Managua Buenos Aires flight instead? Because it's ~US$150 more expensive per person. Not *that* much, but still some money. And by returning to Mexico and having a night at home, we will save us the hassle of carrying Winter clothes to Nicaragua and Summer clothes to Argentina. Oh, and if you are planning on dropping by home while we are away and robbing all of our stuff: There's not that much to take from there, and we have already arranged for somebody to be there while we are away. But thanks for thinking about us, anyway! [update] And what about DebConf12 registration? When is the system opening for us all to register? Soon, dear friends, we are talking about some related issues, and you will have your registrationi open soon.

Michal &#268;iha&#345;: Weblate 0.4

Yesterday, I've finalized Weblate 0.4. It improved handling of plural strings, added documentation and implemented support for secondary languages. If you ask for 0.3, well I managed to release two versions in the day, but I expect to slow down this pace. Full list of changes for 0.3: Full list of changes for 0.4: You can find more information about Weblate on it's website, the code is hosted on Github. If you are curious how it looks, you can try it out on demo server. You can login there with demo account using demo password or register your own user. Weblate is now also being used https://l10n.cihar.com/ as official translating service for phpMyAdmin, Gammu and others.

Filed under: English Weblate 0 comments Flattr this!

8 March 2012

Rapha&#235;l Hertzog: People Behind Debian: Gregor Herrmann, member of the Perl team

Photo by Aigars Mahinovs

I followed Gregor s evolution within Debian because I used to be somewhat active in the Perl team. His case is exemplar because it shows that you don t need to be an IT professional to join Debian and to make a difference. His QA page is impressive with hundreds of packages maintained and hundreds of non-maintainer uploads too. While he started out slowly, I remember meeting him at Debconf 7 in Edinburgh and after that he really got more implicated. Again a case of someone joining for technical reasons but getting more involved and staying there for social reasons! :-) Let s jump into the interview and learn more about him. Raphael: Who are you? Gregor: I m 41 years old, and I live in Innsbruck, Austria, in a shared apartment with a friend of mine. In my day job, I m working at the regional addiction prevention agency, so I m one of the few Debian guys who s not an IT student or professional. I started maintaining packages in 2006, and I am a DD since April 2008. Raphael: How did you start contributing to Debian? Gregor: After having used Debian on servers for some years, I finally switched to it on the desktop after some procrastinating. Soon afterwards I wanted to know more about the making-of , started to join mailing lists, filed bugs, and tried to learn packaging. Luckily I quickly found a permanent sponsor Tony Mancill, and we re still co-maintaining each others packages. And when I packaged my first Perl modules, Gunnar Wolf invited me to join the Debian Perl Group, an offer I accepted a few days later. And I m still there :) Later, the NM process, although it involved some waiting times, was also a good learning experience due to my AM Wouter Verhelst. (And in the meantime the organization of the NM process has vastly improved, from what I hear.) So my starting point for joining Debian was my curiosity but what really helped me to find my way into the project was the support of the people who invited and helped me. Raphael: What s your biggest achievement within Debian or Ubuntu? Gregor: I m not sure I can name a single big achievement but I guess I can say that my contributions to the Debian Perl Group have helped to make and keep the team a success story. Raphael: The pkg-perl team seems to work very well. As an active member, can you explain us how it is organized? How do you explain its success? In particular it seems to be a great entry point for new contributors. Gregor: The team is huge, both in numbers of members and packages (over 2200). Since last DebConf we manage our source packages in git, we have 2 mailing lists and an IRC channel, and we manage to keep an overview by using PET, the Package Entropy Tracker. It s true that we get new members on a regular basis; we try to invite people (like it happened to me 6 years ago :) ) but there are also quite a few new contributors who find our docs and introduce themselves on the mailing list. Maybe someone should conduct a study and ask them what motivated them to join. :) We hand out group membership/commit access quickly, and we try to mentor new contributors actively during their early times in the group. Some of them leave for other projects after some time, but many also stay and become DDs later. I m not sure what the reasons for the group s success are, maybe a combination of: For everyone interested in joining the Debian Perl Group, our Welcome page on the wiki is a good starting point. Raphael: What are your plans for Debian Wheezy? Gregor: Nothing overly exciting. What I should do is getting a newer JabRef into Debian (which involves packaging some new Java libraries any takers?). A solution for libdatetime-timezone-perl (which ships timezone data converted to Perl modules and tends to get outdated when the timezone data change) would be nice; let s see if #660404 leads to some results And some Perl packages will also need a bit of work for the hardening build flags release goal (cf. #657853). Raphael: What s the biggest problem of Debian? Gregor: Inertia. While I really like the fact that Debian is a volunteer project, and that every contributor works when and on what they decide to work on, I get the feeling that Debian could do better in moving forward, innovating, taking decisions. I also think that more uniformity in managing source packages would make things easier; it s quite amazing to see how many source formats, packaging helpers, patch systems, RCSs etc. are used all over the archive. I m not advocating for mono-cultures, and I consider this diversity a strength in general, but having to find out first how this particular package works when preparing a bug fix can be annoying. On the bright side, I think that the myth Debian and its mailing lists are mostly about flames can be seen as dispelled in the meantime. Sure, sometimes the tone could be a bit more civil, but in general most of the interactions I ve seen in the last years were friendly and helpful. IMO, the Debian Project consists of mostly nice and cooperative people, and that s what makes it fun for me. Raphael: You re one of the most dedicated participants to RCBW (Release Critical Bugs of the Week), an initiative to fix RC bugs every week. How much time do you spend on it? What would you advise to people who are considering to join the movement? Gregor: I got into the habit of fixing RC bugs after having been invited to my first Bug Squashing Party in Munich some years ago. During this weekend I saw that fixing RC bugs can be fun, is often not that difficult, and gives a warm fuzzy feeling :) I can definitely recommend attending a BSP if one happens to be organized near you. After tasting blood at this first BSP I tried to continue looking at RC bugs, and I guess I spend something around half an hour per day on it. I usually blog about it once a week, in order to motivate others to join in. And joining is easy: just take a look at the tips people like Zack, Vorlon, or me have written. You don t have to be a DD to help, many of my NMUs are based on patches that others kindly prepare and send to the BTS kudos! Another nice aspect is that the RC bug list contains problems from different fields: general packaging problems, language-specific issues, policy violations, etc. So there s something for everybody, and you don t have to be an expert in all fields to fix a specific bug. What s rewarding about fixing RC bugs is not only the feeling of accomplishment and the knowledge about having helped the next release I also received quite a few Thank you mails from maintainers who were busy at that time and appreciated the help. Raphael: Do you have wishes for Debian Wheezy? Gregor: Well, there s not so much left of the Wheezy release cycle if we manage to freeze in June :) Some quick thoughts for Wheezy and Wheezy+1: Raphael: Is there someone in Debian that you admire for their contributions? Gregor: There are many people in Debian I admire, too many to name them all. The first one that comes to my mind is Russ Allbery who not only does great work from lintian to Debian policy but who also sets a great example of communicating in a perfectly polite and respectful way even in heated discussions.
Thank you to Gregor for the time spent answering my questions. I hope you enjoyed reading his answers as I did. Note that older interviews are indexed on wiki.debian.org/PeopleBehindDebian.

Subscribe to my newsletter to get my monthly summary of the Debian/Ubuntu news and to not miss further interviews. You can also follow along on Identi.ca, Google+, Twitter and Facebook.

2 comments Liked this article? Click here. My blog is Flattr-enabled.

7 March 2012

Philipp Kern: Daily builds of debian-installer/s390x now available

Thanks to klibc being fixed, rootskel finally built in the archive and hence we've now finally enabled the daily builds of debian-installer for s390x. They're still untested, though, and I hope to come around to that in the near future.

In other news I've spent some more time chasing weird 64bit big endian issues in glib. Newer versions have regressed in their support and again assume that certain fields are either 32bit/64bit little endian or 32bit big endian, which is unhelpful. Sadly the testsuite is guilty as well, which doesn't make debugging any easier. I still suspect a bug in either gio or GClosure's interface to libffi, let's hope that when that one's found that the remainder of the archive is building just fine (Currently a lot is blocking on glib-networking which fails in its testsuite. And of course there are still usertagged bugs that need to be fixed.)

It would be cool if we could run more testsuites during package building and find the bugs in them. glib does have one, but its failures are non-fatal for the build (also because there are so many failures). That would make porting to future architectures a tad easier.

Michal &#268;iha&#345;: Weblate 0.2

Thanks to great feedback I've received on Weblate, I've decided to release 0.2 version quite soon to fix things where people complained most. It improves validation of some forms and there are lot of improvements in editing translations, especially plurals. Full list of changes includes: You can find more information about Weblate on it's website, the code is hosted on Github. If you are curious how it looks, you can try it out on demo server. You can login there with demo account using demo password or register your own user. PS: As a special bonus, Weblate now comes also with documentation (also available in docs directory in sources).

Filed under: English Weblate 0 comments Flattr this!

6 March 2012

Michal &#268;iha&#345;: Announcing Weblate

After about week of (not so heavy) development, I can announce availability of Weblate - web based translation tool with tight Git integration. The project was started because I was not happy with existing solutions (see my blog post) as all of them was missing some features I find useful. I started with quite simple definition:
Minimalistic web based translation with direct commit to git on each translation made. There is no plan in heavy conflict resolution as these should be primarily handled on git side.
Also the project started with defined list of features: Pretty much all of that is completed right now, however there will be definitely some issues which will need fixing. All important information about the project are available on it's website, the code is hosted on Github. If you are curious how it looks, you can try it out on demo server. You can login there with demo account using demo password or register your own user. Please give it some testing as I plan to deploy it on http://l10n.cihar.com/ pretty soon.

Filed under: Django English Weblate 5 comments Flattr this!

5 March 2012

Vincent Bernat: Asynchronicity & Net-SNMP AgentX protocol

One of the best way to add SNMP support to an application is the use of AgentX protocol: an application can act as a subagent and handle requests from a master agent using AgentX protocol. The most widespread implementation for such a task is the one from Net-SNMP. TL;DR: An application asynchronously leveraging Net-SNMP AgentX implementation has many opportunities to get stuck when the master agent becomes temporarily unavailable. A mostly efficient workaround is to dedicate a master agent for AgentX and delegate MIB handling to a subagent.

Pinging the master agent Net-SNMP uses an event-based model. It also provides some synchronous functions but they are built on top of the asynchronous ones. It is shipped with its own event loop. Therefore, Net-SNMP AgentX protocol implementation seems a fine choice to add SNMP support to an event-based program, for example in Keepalived, a VRRP daemon and a monitoring daemon for LVS clusters. Unfortunately, an AgentX subagent is expected to check, at a regular interval, if the master agent is alive . This is handled automatically with Net-SNMP implementation as long as you call run_alarms() function which will call agentx_check_session():
/*
 * check a session validity for connectivity to the master agent.  If
 * not functioning, close and start attempts to reopen the session 
 */
void
agentx_check_session(unsigned int clientreg, void *clientarg)
 
    /* [...] */
    DEBUGMSGTL(("agentx/subagent", "checking status of session %p\n", ss));
    if (!agentx_send_ping(ss))  
        snmp_log(LOG_WARNING,
                 "AgentX master agent failed to respond to ping.  Attempting to re-register.\n");
        /*
         * master agent disappeared?  Try and re-register.
         * close first, just to be sure .
         */
        agentx_unregister_callbacks(ss);
        agentx_close_session(ss, AGENTX_CLOSE_TIMEOUT);
        /* [...] */
        if (main_session != NULL)  
            /* [...] */
            main_session = NULL;
            agentx_reopen_session(0, NULL);
         
        else  
            snmp_close(main_session);
            main_session = NULL;
         
      else  
        DEBUGMSGTL(("agentx/subagent", "session %p responded to ping\n",
                    ss));
     
 
This piece of code will end up calling (directly or indirectly) the following functions1 which are using agentx_synch_response():
  • agentx_send_ping()
  • agentx_open_session()
  • agentx_reopen_session()
  • agentx_close_session()
  • agentx_register()
  • agentx_unregister()
  • agentx_register_index()
  • agentx_unregister_index()
  • agentx_add_agentcaps()
  • agentx_remove_agentcaps()
agentx_synch_response() will synchronously wait for an answer from the master agent. Your event-based program will just sit here doing nothing while this happens. For example, keepalived may be unable to send VRRP probes resulting in some serious havoc in your cluster. Functions prefixed by agentx_ are not part of NetSNMP API and could therefore be rewritten to do their work asynchronously. Unfortunately, talk is cheap. Moreover, there exists other deep paths that will block a subagent. For example, the low-level connection to the master agent (using TCP or a Unix socket, but not with UDP) will use a blocking connect() call. It seems quite difficult to fix this. Here are some (partial) workarounds:
  • Call agentx_check_session() less often. The default interval is 15 seconds. Disabling it completely or using a very high value is not advised because this function is the only way to reestablish a connection to the master agent when it is, for example, restarted. Here is how to change the delay to 120 seconds:
    netsnmp_ds_set_int(NETSNMP_DS_APPLICATION_ID,
                       NETSNMP_DS_AGENT_AGENTX_PING_INTERVAL, 120);
    
  • Don t call agentx_check_session() if we know the master agent is alive. For example, if it just sent us a new request, no need to ping it. I have written a patch implementing such a workaround. The ABI is left untouched, therefore, you only need to recompile Net-SNMP libraries.
  • Use a lower timeout and no retry. By default, the timeout for synchronous requests is 1 second and a failed request will be retried 5 times. Because several synchronous functions are used in a row, you may be trapped for as long as 30 seconds with those settings. Here is how2 to disable the retry mechanism and to set the timeout to a very low value:
    static int
    snmp_setup_session_cb(int majorID, int minorID,
                  void *serverarg, void *clientarg)
     
        netsnmp_session *sess = serverarg;
        sess->timeout = ONE_SEC / 3;
        sess->retries = 0;
        return 0;
     
    void some_init_function()
     
        /* [...] */
        snmp_register_callback(SNMP_CALLBACK_LIBRARY,
           SNMP_CALLBACK_SESSION_INIT,
           snmp_setup_session_cb, NULL);
        /* [...] */


Unresponsive master agent Why is the master agent unresponsive? snmpd is also an event-based program and, trust me, there are a lot of places where it will become unresponsive. Here are two examples:
  • When using the pass or the pass_persist directive, Net-SNMP will block until the delegated command outputs a complete line.
    /* var_extensible_pass() in agent/mibgroup/ucd-snmp/pass.c */
    /*
     * valid call.  Exec and get output 
     */
    if ((fd = get_exec_output(passthru)) != -1)  
        file = fdopen(fd, "r");
        if (fgets(buf, sizeof(buf), file) == NULL)  
            fclose(file);
            wait_on_exec(passthru);
            /* [...] */
            continue;
         
        /* [...] */
        fclose(file);
        wait_on_exec(passthru);
        /* [...] */
     
    
  • DISMAN-PING-MIB implementation will just hang while pinging the remote host. If the host is down and you have requested 5 probes with a timeout of 1 second, snmpd will be unresponsive for 5 seconds. A similar problem exists with DISMAN-TRACEROUTE-MIB.

Minimal master agent More and more code is running in the main agent. You cannot expect it to not block. But we could add a minimal master agent to the mix: it will handle only a few MIB modules by itself while most MIB modules will be delagated to a complete agent running as a subagent. Your own subagent will connect to the minimal master agent. Schema showing the use of a minimal master agent It is quite easy to turn snmpd into a subagent: just use -X flag. We should also disable unwanted MIB modules for each agent with -I flag. For the minimal master agent, we only enable some modules. All other modules3 will be served by snmpd acting as a subagent.
$ MODS="snmp_mib,sysORTable,usmConf,usmStats,usmUser,vacm_conf,vacm_context,vacm_vars"
$ snmpd -Lsd -Lf /dev/null -u snmp -g snmp \
>   -C -c /etc/snmp/snmpd.master.conf \
>   -p /var/run/snmpd.master.pid \
>   -I $MODS
$ snmpd -Lsd -Lf /dev/null -u snmp -g snmp \
>   -p /var/run/snmpd.pid -X \
>   -I -$MODS
Access control configuration should be placed in /etc/snmp/snmpd.master.conf, as well as master agentx directive. Other directives (like pass, pass_persist, load, sysname, ) in /etc/snmp/snmpd.conf. The minimal master agent is very unlikely to block and while the ground cause is still here, it is now very much mitigated. You may extend this solution by splicing snmpd into several subagents: one handling safe modules, one handling pass and pass_persist stuff and a last one for unsafe modules (like DISMAN-PING-MIB).

  1. agentx_reopen_session() will call agentx_close_session() and agentx_open_session(). agentx_register() and the following functions will be called by those two functions.
  2. NETSNMP_DS_AGENT_AGENTX_TIMEOUT and NETSNMP_DS_AGENT_AGENTX_RETRIES variables are only used by the master agent, not by a subagent.
  3. Use snmpd -Dmib_init -H to get the list of modules. You may want to add smux module to the master agent.

DebConf team: DebConf12 Website online (Posted by Felix Delattre)

After using our small pre-website for some time now, we are very happy to announce the official website has gone live: http://debconf12.debconf.org Now it is the right time for you to get involved supporting the event or just enjoy the design and help us to spread the new website, f.e. by using our nice banners in the artwork section. Please stay tuned: Registration is going to be opened soon.
Michal &#268;iha&#345;: Ruzyn airport

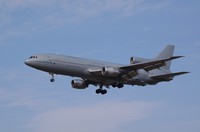
During weekend, I had great opportunity not only to visit Prague Airport, but also to taste airspotting. As photography is my hobby, this was interesting experience, though I don't think it would be my favorite thing to capture. Anyway we could see some interesting places - L1011 TriStar KC1 from Royal Air Force, two Boeings 747-400F and Boeing 777-300. The Boeings being the biggest airplanes you can regularly see in Prague. So lets stop talking and here are few pictures:

Filed under: English Photography 0 comments Flattr this!

John Sullivan: Plus One

In mailing list discussions, I've noticed that the practice of replying "+1" to messages with which one agrees has become very widespread. I think this is interesting for a lot of reasons, such as what it shows about habits picked up in communicating via social network sites that grew out of e-mail percolating back to e-mail. We seem to have really grown to like this idea of "voting" for people's messages, and if there's no "Like" or "+1" button on their message, we'll make our own. (Likewise, apparently a person's name is no longer sufficient to indicate that one is addressing them in an e-mail -- am I right, @dear_reader?) The problem for me is that I have my venerable awesome e-mail client Gnus set to hide quoted text in messages by default with (add-hook 'gnus-article-prepare-hook (lambda () (gnus-article-hide-citation 1))), and it thinks that "+" is the start of a quoted line -- so it hides the "+1". While there's a certain poetic justice to that, it confuses me because it makes the message look empty, and someone could do something like "+1 I'm pregnant too", causing me to miss some very important news. The fix for this is to change the regexp pattern Gnus uses to decide if a line is a message quote or not. gnus-message-cite-prefix-regexp is built using message-cite-prefix-regexp, so I changed the value of the latter, removing the literal "+". I also found while investigating this that I already configure that variable in order to add "#>" which someone sometime during my 9 years of using Gnus must have used. The net result is (setq message-cite-prefix-regexp "\\([ ]*[-_.#[:word:]]+>+\\ [ ]*[]> ]\\)+"). (Note that some of those whitespace characters are tabs, which probably won't display properly here, but you can compare to the default value to see what I actually changed). +1?

4 March 2012

Gregor Herrmann: RC bugs 2012/09

as usual, here's my RCBW report. like in the last weeks, a mixture of NMUs and mails to the BTS, grabbing and writing patches, ...

Stefano Zacchiroli: bits from the DPL for February 2012

Released a few hours ago, here is the monthly report of DPL activities for February 2012.
Howdy, dear Project Members,
here's another round of updates about what has happened in DPL land, this time during February 2012. Highlights Quit a bit of highlights for this month: Talks, interviews, and the like Sprints Plenty of sprints related news! It would be amazing to have an average of one sprint per month for 2012, and we're on good track for it. If you want to help, organize one for your team as documented on the wiki. Legal stuff Appointments In addition to the GSoC admins delegation (see above), I've agreed with former secretary Kurt Roeckx to reappoint him as a secretary for another year. Many thanks, Kurt! Miscellaneous Happy Debian hacking.
PS as usual, the boring day-to-day activity log is available at master:/srv/leader/news/bits-from-the-DPL.*

3 March 2012

Julian Andres Klode: hardlink 0.2 RC1 released

I have just released version 0.2 RC1 of my hardlink program. Compared to the 0.1.X series, the program has been rewritten in C, as Python was to memory-hungry for people with millions of files. The new program uses almost the same algorithm and has almost completely the same bugs as the old version. The code should be portable to all UNIX-like platforms supporting nftw(). I have tested the code on Debian, FreeBSD 9, and Minix 3.2. For storing path names, it uses a flexible array member on C99 compilers, a zero-length-array on GNU compilers, and a array of length 1 on all other compilers (which should work everywhere as far as I heard). The new version may have slightly different behaviour compared to 0.1.2 when regular expressions are specified on the command-line, as a result of the switch from Python s regular expression engine to PCRE (if compiled with PCRE support, you can also use POSIX extended regular expressions if you like). The code is significantly faster than the old code (in situations where it s not I/O bound), and uses much less memory than the old one. Per file, we now store a <tt>struct stat</tt>, a pointer, an int, a char, and the filename; as well as three pointers for a binary search tree (which uses tsearch()). It should also be compatible to Red Hat s original hardlink tool now command-line-wise, there is at least a -c option now. The history and the name conflict are interesting, but probably nothing for this post. We re even less resistant against changing trees than Fedora s tool (and derived) currently, but should otherwise be better (and far more complicated and feature-packed). And we don t require mmap(), but use fread() instead. There was no real performance difference in testing. And we are not GPL-licensed, but use the MIT/Expat license. The package is currently entering Debian experimental for testing purposes. If you have used hardlink previously, or are just curious, give it try. And the makefile is now compatible with the various BSD makes out there, if that s interesting for you. Link to website: http://jak-linux.org/projects/hardlink/
Filed under: General

Sylvain Beucler: Cross-compiling with CMake

I'm working on porting FreeGLUT for Android, and FreeGLUT is switching to CMake. I'm more familiar with the GNU Autotools myself, and I'm used to cross-compile with a simple:
./configure --host=arm-linux-androideabi
Can we do that with CMake? Well, it's not well-documented, but yes :) Let's see how to do that for Android (smartphones) and MinGW (.exe for windows).
The principle is: Here's a simple toolchain script:
SET(CMAKE_SYSTEM_NAME Linux)  # Tell CMake we're cross-compiling
include(CMakeForceCompiler)
# Prefix detection only works with compiler id "GNU"
# CMake will look for prefixed g++, cpp, ld, etc. automatically
CMAKE_FORCE_C_COMPILER(arm-linux-androideabi-gcc GNU)
SET(ANDROID TRUE)
Note: SET(ANDROID TRUE) is not mandatory for CMake, it's just used to detect an Android build in the particular case of FreeGLUT development. Here's how to invoke it:
PATH=/usr/src/ndk-standalone-9/bin:$PATH
cd /usr/src/freeglut-3.0.0/
mkdir cross-android/ && cd cross-android/
cmake \
  -D CMAKE_TOOLCHAIN_FILE=../android_toolchain.cmake \
  -D CMAKE_INSTALL_PREFIX=/freeglut \
  ..
make -j4
make install DESTDIR=$(pwd)

Now here's a slightly more complex toolchain for MinGW. The main issue with MinGW is that there are at least 4 possible prefixes depending on which version and which distro you're using. So I ask the user to specify it with GNU_HOST:
SET(CMAKE_SYSTEM_NAME Windows)
include(CMakeForceCompiler)
IF("$ GNU_HOST " STREQUAL "")
    SET(GNU_HOST i586-mingw32msvc)
ENDIF()
# Prefix detection only works with compiler id "GNU"
CMAKE_FORCE_C_COMPILER($ GNU_HOST -gcc GNU)
# CMake doesn't automatically look for prefixed 'windres', do it manually:
SET(CMAKE_RC_COMPILER $ GNU_HOST -windres)
I wanted to print an error when GNU_HOST is not specified, but the toolchain script is loaded multiple times, and the command-line variables are not always set (CMake is not super-clean in that regard). So I defined a default, that works. Sample invocation:
  apt-get install mingw-w64
  mkdir cross-woe/ && cd cross-woe/
  cmake \
    -D GNU_HOST=x86_64-w64-mingw32 \
    -D CMAKE_TOOLCHAIN_FILE=../mingw_cross_toolchain.cmake \
    -D CMAKE_INSTALL_PREFIX=/freeglut \
    ..
  make -j4
  make install DESTDIR=$(pwd)

I used this technique to cross-compile my projects, or other projects that use CMake. mingw-cross-env uses this technique (abeilt with explicit definition of all compiler tools) to provide pre-built windows libraries without altering the existing CMake scripts. Do you people have tips or a better technique to cross-compile with CMake?

Ingo Juergensmann: Goodbye Google, hello Diaspora!

Well, at least in Germany there was lot of press coverage about Google changing its data protection policies and joining the user profiles of their services like Youtube, GMail, Google+ and so on. There were even HowTos to delete some tracking relevant data and history before of March 1st. like on German Spiegel Online news magazine. Because I'm no big fan of Google and being a strong privacy advocate, I tried to follow the steps mentioned there and got some surprises. First of all I discovered in Googles Dashboard that Google already joined my private account or email address with the one I used at work when I was testing some Android phones for some reasons. The mail address from work was considered as primary address and I couldn't change this. I could delete my private mail address from that account, but not the primary address from work. So, time was pressing because 1st of March was coming near, only one hour left, but what to do know? I'm already using plugins like Ghostery and AdBlockPlus for some time now to minimize the chance of being tracked and such. I registered with Google+ to have a look onto it and to reserve my name and account there, but I was not actively using it for privacy reasons nor do I use Facebook. Therefor the decision was simple and easy: deleting my Google account was probably the best idea I got on that day. That was easy and a quick win for my privacy concerns! On the other hand having some sort of a social network can be nice. And I'm a fan of decentralized solutions like Jabber, which I prefer over AIM/ICQ. I'm running my own Jabber server for some years now, so it was a natural thought to me to make this step for a social network as well. Diaspora* started as a distributed social network in 2010 after some students listened to a speech by Eben Moglen about "Freedom in the Cloud" and is currently still in Alpha stage of development. But it is working and it is running on free software. That's a fairly good reason alone to prefer, support and use Diaspora* over other proprietary social networks like G+ or Facebook, isn't it? So, give it a try! Everyone can run a Diaspora* node, called "pod", on their own server. There are some good installation guides available at Github.com Wiki even covering installation on Debian! Although these installation HowTo is quite good there are some pitfalls left. For example you'll need good SSL cert from an CA authority that is wildly installed on all systems. CAcert seems not to be supported and self-signed certs and CAs doesn't work either. Without a good SSL cert you won't be able to interconnect with other Diaspora* pods. Another pitfall for Debian seems to be the installation of Ruby. First I used the Debian Ruby packages, but got some errors when starting the server that some CSS files couldn't be found. After using the RVM installation metioned in the installation guide these problems were solved (please note that the described way of using RVM didn't work for me either and I got help from some really helpful people on #diaspora-de@freenode). But anyway, I managed to get Diaspora* up and running on my own server and get it to interconnect with other pods. Although installing Diaspora* from source is currently a little pain compared with the ease and comfort of pre-built Debian packages, it's worth the effort! Everyone who consider Google evil and Facebook bad should consider switching to Diaspora*! The more people join, the better the social network will get! Help to fight against the AOL-ism of the Internet by using open and non-proprietary APIs and software like Jabber and Diaspora*! You can find my Diaspora* pod at: http://nerdwind.de/ where my account is "ij".
Kategorie:
File attachments:

Next.

Previous.