Search Results: "will"

26 October 2015

Simon Josefsson: Combining Dnsmasq and Unbound

For my home office network I have been using Dnsmasq for some time. Dnsmasq provides me with DNS, DHCP, DHCPv6, and IPv6 Router Advertisement. I run dnsmasq on a Debian Jessie server, but it works similar with OpenWRT if you want to use a smaller device. My entire /etc/dnsmasq.d/local configuration used to look like this:
dhcp-authoritative
interface=eth1
read-ethers
dhcp-range=192.168.1.100,192.168.1.150,12h
dhcp-range=2001:9b0:104:42::100,2001:9b0:104:42::1500
dhcp-option=option6:dns-server,[::]
enable-ra
Here dhcp-authoritative enable DHCP. interface=eth1 says to listen on eth1 only, which is my internal (IPv4 NAT) network. I try to keep track of the MAC address of all my devices in a /etc/ethers file, so I use read-ethers to have dnsmasq give stable IP addresses for them. The dhcp-range is used to enable DHCP and DHCPv6 on my internal network. The dhcp-option=option6:dns-server,[::] statement is needed to inform the DHCP clients of the DNS resolver s IPv6 address, otherwise they would only get the IPv4 DNS server address. The enable-ra parameter enables IPv6 router advertisement on the internal network, thereby removing the need to run radvd too useful since I prefer to use copyleft software. Recently I had a desire to use DNSSEC, and enabled it in Dnsmasq using the following statements:
dnssec
trust-anchor=.,19036,8,2,49AAC11D7B6F6446702E54A1607371607A1A41855200FD2CE1CDDE32F24E8FB5
dnssec-check-unsigned
The dnssec keyword enable DNSSEC validation in dnsmasq, using the indicated trust-anchor (get the root-anchors from IANA). The dnssec-check-unsigned deserves some more discussion. The dnsmasq manpage describes it as follows:
As a default, dnsmasq does not check that unsigned DNS replies are legitimate: they are assumed to be valid and passed on (without the authentic data bit set, of course). This does not protect against an attacker forging unsigned replies for signed DNS zones, but it is fast. If this flag is set, dnsmasq will check the zones of unsigned replies, to ensure that unsigned replies are allowed in those zones. The cost of this is more upstream queries and slower performance.
For example, this means that dnsmasq s DNSSEC functionality is not secure against active man-in-the-middle attacks between dnsmasq and the DNS server it is using. Even if example.org used DNSSEC properly, an attacker could fake that it was unsigned to dnsmasq, and I would get potentially incorrect values in return. We all know that the Internet is not a secure place, and your threat model should include active attackers. I believe this mode should be the default in dnsmasq, and users should have to configure dnsmasq to not be in that mode if they really want to (with the obvious security warning). Running with this enabled for a couple of days resulted in frustration about not being able to reach a couple of domains. The behaviour was that my clients would hang indefinitely or get a SERVFAIL, both resulting in lack of service. You can enable query logging in dnsmasq with log-queries and enabling this I noticed three distinct form of error patterns:
jow13gw dnsmasq 460 - -  forwarded www.fritidsresor.se to 213.80.101.3
jow13gw dnsmasq 460 - -  validation result is BOGUS
jow13gw dnsmasq 547 - -  reply cloudflare-dnssec.net is BOGUS DNSKEY
jow13gw dnsmasq 547 - -  validation result is BOGUS
jow13gw dnsmasq 547 - -  reply linux.conf.au is BOGUS DS
jow13gw dnsmasq 547 - -  validation result is BOGUS
The first only happened intermittently, the second did not cause any noticeable problem, and the final one was reproducible. To be fair, I only found the last example after starting to search for problem reports (see post confirming bug). At this point, I had a confirmed bug in dnsmasq that affect my use-case. I want to use official packages from Debian on this machine, so installing newer versions manually is not an option. So I started to look into alternatives for DNS resolving, and quickly found Unbound. Installing it was easy:
apt-get install unbound
unbound-control-setup 
I created a local configuration file in /etc/unbound/unbound.conf.d/local.conf as follows:
server:
	interface: 127.0.0.1
	interface: ::1
	interface: 192.168.1.2
	interface: 2001:9b0:104:42::2
	access-control: 127.0.0.1 allow
	access-control: ::1 allow
	access-control: 192.168.1.2/24 allow
	access-control: 2001:9b0:104:42::2/64 allow
	outgoing-interface: 155.4.17.2
	outgoing-interface: 2001:9b0:1:1a04::2
#	log-queries: yes
#	verbosity: 2
The interface keyword determine which IP addresses to listen on, here I used the loopback interface and the local address of the physical network interface for my internal network. The access-control allows recursive DNS resolving from those networks. And outgoing-interface specify my external Internet-connected interface. log-queries and/or verbosity are useful for debugging. To make things work, dnsmasq has to stop providing DNS services. This can be achieved with the port=0 keyword, however that will also disable informing DHCP clients about the DNS server to use. So this has to be added in manually. I ended up adding the two following lines to /etc/dnsmasq.d/local:
port=0
dhcp-option=option:dns-server,192.168.1.2
Restarting unbound and dnsmasq now leads to working (and secure) internal DNSSEC-aware name resolution over both IPv4 and IPv6. I can verify that resolution works, and that Unbound verify signatures and reject bad domains properly with dig as below, or use online DNSSEC resolver test page although I m not sure how confident you can be in the result from that page.
$ host linux.conf.au
linux.conf.au has address 192.55.98.190
linux.conf.au mail is handled by 1 linux.org.au.
$ host sigfail.verteiltesysteme.net
;; connection timed out; no servers could be reached
$ 
I use Munin to monitor my services, and I was happy to find a nice Unbound Munin plugin. I installed the file in /usr/share/munin/plugins/ and created a Munin plugin configuration file /etc/munin/plugin-conf.d/unbound as follows:
[unbound*]
user root
env.statefile /var/lib/munin-node/plugin-state/root/unbound.state
env.unbound_conf /etc/unbound/unbound.conf
env.unbound_control /usr/sbin/unbound-control
env.spoof_warn 1000
env.spoof_crit 100000
I run munin-node-configure --shell sh to enable it. To work unbound has to be configured as well, so I create a /etc/unbound/unbound.conf.d/munin.conf as follows.
server:
	extended-statistics: yes
	statistics-cumulative: no
	statistics-interval: 0
remote-control:
	control-enable: yes
The graphs may be viewed at my munin instance.

Russ Allbery: Review: Hawk

Review: Hawk, by Steven Brust
Series: Vlad Taltos #14
Publisher: Tor
Copyright: October 2014
ISBN: 0-7653-2444-X
Format: Hardcover
Pages: 320
This is the fourteenth book in the Vlad Taltos series (not counting the various associated books and other series), builds directly on the long-term plot arc of the series (finally!), and is deeply entangled with Vlad's friends and former life as a Jhereg boss. As you might imagine from that introduction, this is absolutely not the place to start with this series. For the past few books, Brust has been following a pattern of advancing the series plot in one book and then taking the next book to fill in past history or tell some side story. That means, following Tiassa, we were due some series advancement, and that's exactly what we get. We also, finally, get some more details about Lady Teldra. Nothing all that revelatory, but certainly intriguing, and more than just additional questions (at last). When Brust finally takes this gun off the wall and fires it, the resulting bits of world-building might be even better than Issola. At its heart, though, Hawk is a caper novel. If you're like me, you're thinking "it's about time." I think this is the sort of story Brust excels at, particularly with Vlad as his protagonist. Even better, unlike some of the other multi-part novels, this is a book-length caper focused on a very important goal, and with the potential to get rid of some annoyances in Vlad's life that have lingered for rather too long. We see many of Vlad's Dragaeran friends, but (apart from Daymar) mostly in glimpses. This is Vlad's book, with heavy helpings of Loiosh. The caper is also a nicely twisty one, involving everything from different types of magic to the inner workings of the Jhereg organization. As is typical for Vlad's schemes, there are several false fronts and fake goals, numerous unexpected twists, and a rather fun guest appearance. Oh, and lots and lots of snark, of course. I think my favorite part of the book was the interaction between Vlad and Kragar, which added a lot of emotional depth both to this story and to some of the previous stories of Vlad's life as a Jhereg. And I'm hoping that where Brust leaves things at the end of this book implies a Vlad who is more free to act, to see his friends, and to get entangled in Imperial politics, since I think that leads to the best stories. Of course, if Brust holds to pattern, the next book will be backfill or side stories and we'll have to wait longer for a continuation of the main story. As much as I like those side stories, I'm hoping Brust will break pattern. I'm increasingly eager to see where this story will go. The all-too-brief interaction with Sethra in this book promises so much for the future. If you like the Vlad Taltos books overall, you'll probably like this one. It's a return to the old scheming Vlad, but tempered by more experience and different stakes. There's a bit of lore, a bit of world-building, and a lot of Vlad being tricky. This series is still going strong fourteen books in. Rating: 8 out of 10

Craig Small: ps standards and locales

I looked at two interesting issues today around the ps program in the procps project. One had a solution and the other I m puzzled about. ps User-defined Format Issue #9 was quite the puzzle. The output of ps changed depending if a different option had a hyphen before it or not. First, the expected output
$ ps p $$ -o pid=pid,comm=comm
 pid comm
31612 bash
Next, the unusual output.
$ ps -p $$ -o pid=pid,comm=comm
pid,comm=comm
 31612
The difference being the second we have -p not p. The second unexpected thing about this is, it was designed that way. Unix98 standard apparently permits this sort of craziness. To me it is a useless feature that will more likely than not confuse people. Within ps, depending on what sort of flags you start with, you use a sysv parser or a bsd parser. One of them triggered the Unix98 compatibility option while the other did not, hence the change in behavior. The next version of procps will ship with a ps that has the user-defined output format of the first example. I had a look at the latest standard, IEEE 1003.1-2013, doesn t seem to have anything like that in it. Short Month Length This one has got me stuck. A user has reported in issue #5 that when they use their locale columns such as start time get mis-aligned because their short month is longer than 3 characters. They also mention some other columns for memory etc are not long enough but that s a generic problem that is impossible to fix sensibly. OK, for the month problem the fix would be to know what the month length is and set the column width for those columns to that plus a bit more for the other fixed components, simple really. Except; how do you know for a specific locale what their short month length is? I always assumed it was three! I haven t found anything that has this information. Note, I m not looking for strlen() but some function that has the maximum length for short month names (e.g. Jan, Feb, Mar etc). This also got me thinking how safe some of those date to string functions are if you have a static buffer as the destination. It s not safe to assume they will be DD MMM YYYY because there might be more Ms. So if you know how to work out the short month name length, let me know!

25 October 2015

Johannes Schauer: unshare without superuser privileges

TLDR: With the help of Helmut Grohne I finally figured out most of the bits necessary to unshare everything without becoming root (though one might say that this is still cheated because the suid root tools newuidmap and newgidmap are used). I wrote a Perl script which documents how this is done in practice. This script is nearly equivalent to using the existing commands lxc-usernsexec [opts] -- unshare [opts] -- COMMAND except that these two together cannot be used to mount a new proc. Apart from this problem, this Perl script might also be useful by itself because it is architecture independent and easily inspectable for the curious mind without resorting to sources.debian.net (it is heavily documented at nearly 2 lines of comments per line of code on average). It can be retrieved here at https://gitlab.mister-muffin.de/josch/user-unshare/blob/master/user-unshare Long story: Nearly two years after my last last rant about everything needing superuser privileges in Linux, I'm still interested in techniques that let me do more things without becoming root. Helmut Grohne had told me for a while about unshare(), or user namespaces as the right way to have things like chroot without root. There are also reports of LXC containers working without root privileges but they are hard to come by. A couple of days ago I had some time again, so Helmut helped me to get through the major blockers that were so far stopping me from using unshare in a meaningful way without executing everything with sudo. My main motivation at that point was to let dpkg-buildpackage when executed by sbuild be run with an unshared network namespace and thus without network access (except for the loopback interface) because like pbuilder I wanted sbuild to enforce the rule not to access any remote resources during the build. After several evenings of investigating and doctoring at the Perl script I mentioned initially, I came to the conclusion that the only place that can unshare the network namespace without disrupting anything is schroot itself. This is because unsharing inside the chroot will fail because dpkg-buildpackage is run with non-root privileges and thus the user namespace has to be unshared. But this then will destroy all ownership information. But even if that wasn't the case, the chroot itself is unlikely to have (and also should not) tools like ip or newuidmap and newgidmap installed. Unsharing the schroot call itself also will not work. Again we first need to unshare the user namespace and then schroot will complain about wrong ownership of its configuration file /etc/schroot/schroot.conf. Luckily, when contacting Roger Leigh about this wishlist feature in bug#802849 I was told that this was already implemented in its git master \o/. So this particular problem seems to be taken care of and once the next schroot release happens, sbuild will make use of it and have unshare --net capabilities just like pbuilder already had since last year. With the sbuild case taken care of, the rest of this post will introduce the Perl script I wrote. The name user-unshare is really arbitrary. I just needed some identifier for the git repository and a filename. The most important discovery I made was, that Debian disables unprivileged user namespaces by default with the patch add-sysctl-to-disallow-unprivileged-CLONE_NEWUSER-by-default.patch to the Linux kernel. To enable it, one has to first either do

echo 1   sudo tee /proc/sys/kernel/unprivileged_userns_clone > /dev/null
or
sudo sysctl -w kernel.unprivileged_userns_clone=1
The tool tries to be like unshare(1) but with the power of lxc-usernsexec(1) to map more than one id into the new user namespace by using the programs newgidmap and newuidmap. Or in other words: This tool tries to be like lxc-usernsexec(1) but with the power of unshare(1) to unshare more than just the user and mount namespaces. It is nearly equal to calling:
lxc-usernsexec [opts] -- unshare [opts] -- COMMAND
Its main reason of existence are: I hoped that systemd-nspawn could do what I wanted but it seems that its requirement for being run as root will not change any time soon Another tool in Debian that offers to do chroot without superuser privileges is linux-user-chroot but that one cheats by being suid root. Had I found lxc-usernsexec earlier I would've probably not written this. But after I found it I happily used it to get an even better understanding of the matter and further improve the comments in my code. I started writing my own tool in Perl because that's the language sbuild was written in and as mentioned initially, I intended to use this script with sbuild. Now that the sbuild problem is taken care of, this is not so important anymore but I like if I can read the code of simple programs I run directly from /usr/bin without having to retrieve the source code first or use sources.debian.net. The only thing I wasn't able to figure out is how to properly mount proc into my new mount namespace. I found a workaround that works by first mounting a new proc to /proc and then bind-mounting /proc to whatever new location for proc is requested. I didn't figure out how to do this without mounting to /proc first partly also because this doesn't work at all when using lxc-usernsexec and unshare together. In this respect, this perl script is a bit more powerful than those two tools together. I suppose that the reason is that unshare wasn't written with having being called without superuser privileges in mind. If you have an idea what could be wrong, the code has a big FIXME about this issue. Finally, here a demonstration of what my script can do. Because of the /proc bug, lxc-usernsexec and unshare together are not able to do this but it might also be that I'm just not using these tools in the right way. The following will give you an interactive shell in an environment created from one of my sbuild chroot tarballs:
$ mkdir -p /tmp/buildroot/proc
$ ./user-unshare --mount-proc=/tmp/buildroot/proc --ipc --pid --net \
    --uts --mount --fork -- sh -c 'ip link set lo up && ip addr && \
    hostname hoothoot-chroot && \
    tar -C /tmp/buildroot -xf /srv/chroot/unstable-amd64.tar.gz; \
    /usr/sbin/chroot /tmp/buildroot /sbin/runuser -s /bin/bash - josch && \
    umount /tmp/buildroot/proc && rm -rf /tmp/buildroot'
(unstable-amd64-sbuild)josch@hoothoot-chroot:/$ whoami
josch
(unstable-amd64-sbuild)josch@hoothoot-chroot:/$ hostname
hoothoot-chroot
(unstable-amd64-sbuild)josch@hoothoot-chroot:/$ ls -lha /proc   head
total 0
dr-xr-xr-x 218 nobody nogroup    0 Oct 25 19:06 .
drwxr-xr-x  22 root   root     440 Oct  1 08:42 ..
dr-xr-xr-x   9 root   root       0 Oct 25 19:06 1
dr-xr-xr-x   9 josch  josch      0 Oct 25 19:06 15
dr-xr-xr-x   9 josch  josch      0 Oct 25 19:06 16
dr-xr-xr-x   9 root   root       0 Oct 25 19:06 7
dr-xr-xr-x   9 josch  josch      0 Oct 25 19:06 8
dr-xr-xr-x   4 nobody nogroup    0 Oct 25 19:06 acpi
dr-xr-xr-x   6 nobody nogroup    0 Oct 25 19:06 asound
Of course instead of running this long command we can also instead write a small shell script and execute that instead. The following does the same things as the long command above but adds some comments for further explanation:
#!/bin/sh

set -exu

# I'm using /tmp because I have it mounted as a tmpfs
rootdir="/tmp/buildroot"

# bring the loopback interface up
ip link set lo up

# show that the loopback interface is really up
ip addr

# make use of the UTS namespace being unshared
hostname hoothoot-chroot

# extract the chroot tarball. This must be done inside the user namespace for
# the file permissions to be correct.
#
# tar will fail to call mknod and to change the permissions of /proc but we are
# ignoring that
tar -C "$rootdir" -xf /srv/chroot/unstable-amd64.tar.gz true

# run chroot and inside, immediately drop permissions to the user "josch" and
# start an interactive shell
/usr/sbin/chroot "$rootdir" /sbin/runuser -s /bin/bash - josch

# unmount /proc and remove the temporary directory
umount "$rootdir/proc"
rm -rf "$rootdir"
and then:
$ mkdir -p /tmp/buildroot/proc
$ ./user-unshare --mount-proc=/tmp/buildroot/proc --ipc --pid --net --uts --mount --fork -- ./chroot.sh
As mentioned in the beginning, the tool is nearly equivalent to calling lxc-usernsexec [opts] -- unshare [opts] -- COMMAND but because of the problem with mounting proc (mentioned earlier), lxc-usernsexec and unshare cannot be used with above example. If one tries anyways one will only get:
$ lxc-usernsexec -m b:0:1000:1 -m b:1:558752:1 -- unshare --mount-proc=/tmp/buildroot/proc --ipc --pid --net --uts --mount --fork -- ./chroot.sh
unshare: mount /tmp/buildroot/proc failed: Invalid argument
I'd be interested in finding out why that is and how to fix it.

Russ Allbery: Review: The Thrilling Adventures of Lovelace and Babbage

Review: The Thrilling Adventures of Lovelace and Babbage, by Sydney Padua
Publisher: Pantheon
Copyright: 2015
ISBN: 0-307-90827-5
Format: Hardcover
Pages: 317
I seem to be writing a lot of reviews lately where any reader can easily do their own research and see if this is something they'd like. This is another of those, but perhaps a bit more obscure. As Padua explains in the preface, the first Lovelace and Babbage strip was intended to be a one-off joke. A friend suggested that she draw a comic telling the (short and rather tragic) life of Ada Lovelace, widely considered the first computer programmer even though the computer for which she wrote programs was never built: Charles Babbage's Analytic Engine. Padua found the story of Babbage and Lovelace's collaboration fascinating but too grim, and so wrote an alternate ending involving a pocket universe in which Babbage and Lovelace lived on to fight crime! Or at least fought against street organs and poetry. Padua meant this as a joke. The Internet took it as a teaser. Quite to her surprise, she found herself writing occasional additional episodes and getting lost in fascinating research about Lovelace and Babbage. The result is all at 2dgoggles.com. This book is a curated collection of those comics, including much of their (extensive) footnotes and research notes, in a very attractive and well-constructed book form. The best review, therefore, would be to go read some of the comics yourself, easily accessible via the Comics tab on the web site, and see if this is the sort of thing you'd enjoy. There is some material in the book that isn't on the web site, but most of it is there (including one full story that didn't make it into the book). There are a few reasons to buy a collection like this of material that previously appeared on the Internet. One, of course, is out of gratitude to support the author, which is the main reason I bought it. If you want to do that, though, you probably already know you do. Another reason is for additional unpublished material, but that's not really the case here. But a third is that, despite all the technology of the web, books can sometimes provide a more elegant and beautiful presentation. And that's very much the case for The Thrilling Adventures of Lovelace and Babbage. The hardcover is a beautiful work of art. It has what you would expect from a hardcover graphic novel, of course: sturdy paper, lovely story headings in the form of Victorian-style posters, and very nice artwork beneath the dust jacket. (I've been so happy to see that in the last few hardcovers I've reviewed.) But, best of all, it presents the primary research notes on each page underneath comic panels. Those who have been reading Lovelace and Babbage as it appears on the web know Padua's copious research notes. But they're normally presented at the end of each complete part, and I found myself often not reading them in detail. This might not be the case for everyone, but at least for me this presentation works so much better. Historical notes are at the bottom of (nearly) every page, in context. This might sound like it would distract from and break up the flow of the story, but at least for me it does the opposite. The comics feel so much richer when intermixed with the actual history (which in some cases is surprisingly similar to what seemed to be wild, invented scenarios). The historical notes also have end notes, and quite substantial ones. I found that organization less successful (readers of my reviews will know I have a long-standing antipathy towards end notes for anything other than cross-references), but I have to admit I have no idea how Padua would have fit those on the same page as footnotes. They're also written well enough, and with sufficient detail, that I could usually read a chapter and then read all the end notes and mostly remember what they referred to. Padua also takes advantage of the format to play a few neat games with frame breaks: characters commenting on the notes, stabbing things into them, or otherwise affecting them. I have to admit to some mild frustration where this makes the notes unreadable, since they're nearly as fascinating as the comics, but the overall effect is still worth it. (And, of course, the full notes are available on the web if one wishes to look them up.) Rounding out the book version are a few of the best original source documents that Padua found, thankfully excerpted and well-edited to not outlive their welcome for those of us who don't like poring over Victorian letters. And, finally, some beautiful illustrations of the mechanisms of the Analytic Engine with supporting descriptions of how they were supposed to work. I'm not particularly mechanically inclined, nor that fascinated by steampunk, and I still found these diagrams impressive and fun to look at. Someone more interested in such things will be in for a treat. I've been thoroughly enjoying the (sadly infrequent) installments of Lovelace and Babbage for years now, and am utterly delighted by their hardcover appearance. If you already knew about Padua's work and have any interest in nice hardcovers of such things, I don't think you'll regret the purchase. If you haven't heard of her, or this series, before, some quick reading at the web site should quickly reveal whether this is something you'd enjoy. Rating: 9 out of 10

24 October 2015

Mart n Ferrari: Tales from the SRE trenches - Part 1

A few weeks ago, I was offered the opportunity to give a guest talk in the Romanian Association for Better Software. RABS is a group of people interested in improving the trade, and regularly hold events where invited speakers give presentations on a wide array of topics. The speakers are usually pretty high-profile, so this is quite a responsibility! To make things more interesting, much of the target audience works on enterprise software, under Windows platforms. Definitely outside my comfort zone! Considering all this, we decided the topic was going to be about Site Reliability Engineering (SRE), concentrating on some aspects of it which I believe could be useful independently of the kind of company you are working for. I finally gave the talk last Monday, and the audience seemed to enjoy it, so I am going to post here my notes, hopefully some other people will like it too.

Why should I care? I prepared this thinking of an audience of software engineers, so why would anyone want to hear about this idea that only seems to be about making the life of the operations people better? The thing is, having your work as a development team supported by an SRE team will also benefit you. This is not about empowering Ops to hit you harder when things blow apart, but to have a team that is your partner. A partner that will help you grow, handle the complexities of a production environment so you can concentrate on cool features, and that will get out of the way when things are running fine. A development team may seem to only care about adding features that will drive more and more users to your service. But an unreliable service is a service that loses users, so you should care about reliability. And what better to have a team has Reliability on their name?

What is SRE? SRE means Site Reliability Engineering, Reliability Engineering applied to "sites". Wikipedia defines Reliability Engineering as:
[..] engineering that emphasizes dependability in the life-cycle management of a product.
This is, historically, a branch of engineering that made possible to build devices that will work as expected even when their components were inherently unreliable. It focused on improving component reliability, establishing minimum requirements and expectations, and a heavy usage of statistics to predict failures and understand underlying problems. SRE started as a concept at Google about 12 years ago, when Ben Treynor joined the company and created the SRE team from a group of 7 production engineers. There is no good definition of what Site Reliability Engineering means; while the term and some of its ideas are clearly inspired in the more traditional RE, he defines SRE with these words1:
Fundamentally, it's what happens when you ask a software engineer to design an operations function.

Only hire coders After reading that quote it is not surprising that the first item in the SRE checklist2, is to only hire people who can code properly for SRE roles. Writing software is a key part of being SRE. But this does not mean that there is no separation between development and operations, nor that SRE is a fancy(er) name for DevOps3. It means treating operations as a software engineering problem, using software to solve problems that used to be solved by hand, implementing rigorous testing and code reviewing, and taking decisions based on data, not just hunches. It also implies that SREs can understand the product they are supporting, and that there is a common ground and respect between SREs and software engineers (SWEs). There are many things that make SRE what it is, some of these only make sense within a special kind of company like Google: many different development and operations teams, service growth that can't be matched by hiring, and more importantly, firm commitment from top management to implement these drastic rules. Therefore, my focus here is not to preach on how everybody should adopt SRE, but to extract some of the most useful ideas that can be applied in a wider array of situations. Nevertheless, I will first try to give an overview of how SRE works at Google.
That's it for today. In the next post I will talk about how to end the war between developers and SysAdmins. Stay tuned!

  1. http://www.site-reliability-engineering.info/2014/04/what-is-site-reliability-engineering.html
  2. SRE checklist extracted from Treynor's talk at SREcon14: https://www.usenix.org/conference/srecon14/technical-sessions/presentation/keys-sre
  3. By the way, I am still not sure what DevOps mean, it seems that everyone has a different definition for it.
Comment

Vincent Sanders: It takes courage to sit on a jury. How many of us want to decide the fate of another person's life or freedom?

I think Regina Brett has a point although having now experienced being a juror in a British crown court I have a much better understanding of both the process and effectiveness of the jury system.

The actual process of becoming a juror on a case is something I had not been aware of previously. You simply receive a letter telling you to be at the court on a specific date and that you are required to be available for at least ten days, possibly more. The only qualification to receive the letter is to be on the electoral roll and it is an invitation with few options to refuse without serious repercussions.

When you arrive at the court you are directed to the Jury lounge (practical hint: take a book) where you notice there are over forty people, which would seem odd until you realise there are three courtrooms and they each need a jury, even then there are an excess of people which is because of the selection process.

The process of jury selection is fairly simple, an usher for a court comes and calls fourteen names which forms the jury in waiting. The group is taken up to the court waiting room (this room gets terribly familiar over the forthcoming weeks) and then twelve names are called.

As each person is called they enter the jury box in order which persists for the entire trial (practical hint:remember your juror number). Before each person is sworn or affirmed there is the possibility they will be found unsuitable and will be replaced by one of the previously unselected jurors. Any unselected jurors are then sent back to the jury lounge and become available for forming another jury in waiting.

Anyone unselected at the end of the process has to remain available to return to the court to form a jury in waiting when a previous trial ends until they have exhausted their duty. There were a few of these unfortunate people who were kept in a state of limbo for several days and I am relieved this did not happen to me.

Being a juror, from a purely practical perspective, felt like working an office job for ten days. Duties consisting of attending a series of meetings with strange rules and the typically understated British approach to mentioning the result of breaking them.

I participated in two cases, both of which were (almost by definition) unpleasant happenings, these were a case of Grievous bodily harm and an offence under section 7 of the Sexual Offences Act 2003.

Both cases were challenging in their own ways the first because of the way the case was presented and the second because of its subject matter. One of the most important rules is "Do not discuss anything with anyone as it might be perjury" so going along with that I will not be discussing any details. Because I cannot be specific this post has become a little impersonal, you will have to forgive me as I found I had to remove a great deal of more content which was not appropriate.

An important thing to note is that the trials bore no resemblance to TV courtroom drama. The trials proceed in a professional manner with very little theatrics. The prosecution barrister commences outlining the case against the accused, calling witnesses and reading into evidence uncontested material. The defence then gets to present their case, again calling witnesses and placing documents into evidence.

One of the striking things about this process is that if the barristers do not call a witness or present evidence that would seem to be pertinent, the jury must not draw inference from that omission, which is especially bizarre when a central witness referred to by almost everyone involved with the case is not called.

Once the case is presented the jury is sequestered in a room and must come to a unanimous decision on each of the charges. This was, for me, the most challenging part of the whole process. Twelve people with unique views on the information presented have to attempt to discuss the evidence and not simply go with their first impressions based on their preconceptions.

The jury is allowed to ask for some evidence to be repeated and if deliberations take some time the jury may be instructed that a majority of 10 to 2 may be accepted. I imagine at some point the jury will run out of time to make a decision and something else will happen but I did not experience this.

Overall the experience was enlightening if not enjoyable, I understand the process a lot more and am happy to have discharged my duty and am equally glad the responsibility will not come around again for at least a few years.

23 October 2015

Clint Adams: Beware of typhoons or tsunamis

The 12 member nations of the Trans-Pacific Partnership pact have agreed to prohibit demands that companies reveal software source code*, a step that appears aimed at curbing efforts by China to gain access to this sensitive information, The Yomiuri Shimbun has learned. Source code is the confidential information for software and is a blueprint embedded in many commonly used products, such as vehicles, mobile phones and home appliances. Source code is usually tightly guarded because it conatins commands that make using the software easier. China requires foreign companies operating there to hand over source code, a move that has sparked sharp criticism from many countries. Observers believe the decision by TPP participants to ban demands to reveal this code is intended to restrain China's move. The TPP's electronic commerce chapter in principle prohibits the 12 member nations from demanding access to source code for mass-produced software. According to the Economy, Trade and Industry Ministry, the Japan-Mongolia economic partnership agreement signed in February contains a stipulation banning demands for such information, but there are very few other examples around the world. Japan, the United States and other nations that are home to many information technology companies want to make the stipulation effectively a global standard, and they are considering whether to incorporate such a condition in economic partnership agreements that will be inked in the future. Source code is an important corporate secret for development firms. *Source code A software program written in a language a computer understands. As well as containing expert details about the unique functions of the product, the software is essential for fixing glitches and making improvements. Hackers have attempted to access source code because gaining this information would make it easier to create viruses that could exploit any software defects. In the software business, it is rarely made public, as it is considered a corporate secret.
Petter Reinholdtsen: "Free Culture" by @lessig - The background story for Creative Commons - new edition available

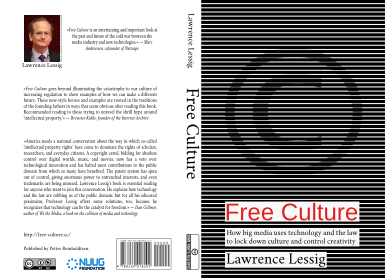
Click here to buy the book. In 2004, as the Creative Commons movement gained momentum, its creator Lawrence Lessig wrote the book Free Culture to explain the problems with increasing copyright regulation and suggest some solutions. I read the book back then and was very moved by it. Reading the book inspired me and changed the way I looked on copyright law, and I would love it if more people would read it too. Because of this, I decided in the summer of 2012 to translate it to Norwegian Bokm l and publish it for those of my friends and family that prefer to read books in Norwegian. I translated the book using docbook and a gettext PO file, and a byproduct of this process is a new edition of the English original. I've been in touch with the author during by work, and he said it was fine with him if I also published an English version. So I decided to do so. Today, I made this edition available for sale on Lulu.com, for those interested in a paper book. This is the cover:

The Norwegian Bokm l version will be available for purchase in a few days. I also plan to publish a French version in a few weeks or months, depending on the amount of people with knowledge of French to join the translation project. So far there is only one active person, but the French book is almost completely translated but need some proof reading. The book is also available in PDF, ePub and MOBI formats from my github project page. Note the ePub and MOBI versions have some formatting problems I believe is due to bugs in the docbook tool dbtoepub (Debian BTS issues #795842 and #796871), but I have not taken the time to investigate. I recommend the PDF and ePub version for now, as they seem to show up fine in the viewers I have available. After the translation to Norwegian Bokm l was complete, I was able to secure some sponsoring from the NUUG Foundation to print the book. This is the reason their logo is located on the back cover. I am very grateful for their contribution, and will use it to give a copy of the Norwegian edition to members of the Norwegian Parliament and other decision makers here in Norway.

22 October 2015

Pau Garcia i Quiles: FOSDEM Desktops DevRoom 2016

It is now official: KDE will be present again at FOSDEM in the 2016 edition, on the 30th and 31st of January, 2016. Talks will take place at the Desktops DevRoom, on Sunday the 31st, but not exclusively: in past years, there were Qt and KDE-related talks at the mobile devroom, lightning talks, distributions, open document editors and more. KDE will be sharing the room with other desktop environments, as usual: Gnome, Unity, Enlightenment, Razor, etc. Representatives from those communities will be helping me in managing and organizing the devroom: Christophe Fergeau, Michael Zanetti, Philippe Caseiro and J rome Leclanche. I would like to extend the invitation to any other free/open source desktop environment and/or related stuff. Check last year s schedule for an example. Closed-source shops (Microsoft, Apple, Oracle, etc) are ALSO invited, provided that you will talk about something related to open source. We will publish the Call for Talks for the Desktops DevRoom 2016 soon. Stay tuned. In the meanwhile, you can subscribe to the Desktops DevRoom mailing list to be informed of important and useful information, and talk about FOSDEM and specific issues of the Desktops DevRoom.

Russ Allbery: Review: What If?

Review: What If?, by Randall Munroe
Publisher: Houghton Mifflin Harcourt
Copyright: 2014
ISBN: 0-544-27299-4
Format: Hardcover
Pages: 295
This is another one of those reviews that's somewhat pointless to write, at least beyond telling people who for some strange reason aren't xkcd readers that this is a thing that exists in the world. What If? is a collection of essays from that feature on the xkcd web site and new essays in the same vein. (Over half are new to this collection.) If you've read them, you know what to expect; if you haven't, and have any liking at all for odd scientific facts or stick figures, you're in for a treat. So, short review: The subtitle is Serious Scientific Answers to Absurd Hypothetical Questions, and it's exactly what it says on the tin, except that "serious" includes a healthy dose of trademark xkcd humor. Go read what-if.xkcd.com for numerous samples of Munroe's essay style. If you like what you see, this is a whole book of that: a nice, high-quality hardcover (at least the edition I bought), featuring the same mix of text and cartoon commentary, and with new (and in some cases somewhat longer) material. You probably now have all the information necessary to make a purchasing decision. If you need more motivation, particularly to buy a physical copy, the inside of the dust jacket of the hardcover is a detailed, labeled map of the world after a drain in the Marianas Trench has emptied most of the oceans onto Mars. And the book inside the dust jacket is embossed with what happens after the dinosaur on the cover is lowered into, or at least towards, the Great Pit of Carkoon. This made me particularly happy, since too often hardcovers inside the dust jacket look just like every other hardcover except for the spine lettering. Very few of them have embossed Star Wars references. Personally, I think that's a great reason to buy the hardcover even if, like me, you've been following What If? on the web religiously since it started. But of course the real draw is the new material. There's enough of it that I won't try any sort of comprehensive list, but rest assured that it's of equal or better quality than the web-published essays we know and love. My favorite of the new pieces is the answer to the question "what would happen if you made a periodic table out of cube-shaped bricks, where each brick was made of the corresponding element?" As with so many What If? questions, it starts with killing everyone in the vicinity, and then things get weird. Another nice touch in this collection is what I'd call "rejected questions": questions that people submitted but that didn't inspire an essay. Most of these (I wish all) get a single cartoon of reaction to the question itself, which include some of the funniest (and most touching) panels in the book. Ebook formatting has gotten much better, so there's some hope that at least some platforms could do justice to this book with its embedded cartoons. Putting the footnotes properly at the bottom of each page (thank you!) might be a challenge, though. Writing mixed with art is one of the things I think benefits greatly from a physical copy, and the hardcover is a satisfying and beautiful artifact. (I see there's also an audio book, but I'm sure how well that could work; so much of the joy of What If? is the illustrations, and I'm dubious that one could adequately describe them.) Prior web readers will be relieved to know that the mouse-over text is preserved as italic captions under the cartoons, although sadly most cartoons are missing captions. (As I recall, that's also the case for the early web What If? essays, but later essays have mouse-over text for nearly every cartoon.) Anyway, this is a thing that exists. If you follow xkcd, you probably knew that already, given that the book was published last year and I only now got around to reading it. (My current backlog is... impressive.) If you were not previously aware of What If? or of xkcd itself, now you are, and I envy you the joy of discovery. A short bit of reading will tell you for certain whether this is something you want to purchase. If your relationship to physics is at all similar to mine, I suspect the answer will be yes. A small personal note: I just now realized how much the style of What If? resembles the mixed text and illustrations of One Two Three... Infinity. Given how foundational that book was to my love of obscure physics facts, my love of What If? is even less surprising. Rating: 10 out of 10

21 October 2015

Daniel Pocock: A mission statement for free real-time communications

At FOSDEM 2013, the RTC panel in the main track used the tag line "Can we finally replace Skype, Viber, Twitter and Facebook?" Does replacing something else have the right ring to it though? Or does such a goal create a negative impression? Even worse, does the term Skype replacement fall short of being a mission statement that gives people direction and sets expectations of what we would actually like to replace it with? Towards a clearer definition Lets consider what a positive statement might look like:
Making it as easy as possible to make calls to other people and to receive calls from other people for somebody who chooses only to use genuinely Free Software, open standards, a free choice of service providers and a credible standard of privacy.
If you agree with this or if you feel you can propose a more precise statement, please come and share your thoughts on the Free RTC email list. The value of a mission statement should not be underestimated. With the right mission statement, it should be possible to envision what the future will look like if we succeed and also if we don't. With the vision of success in mind, it should be easier for developers and the wider free software community to identify the steps that must be taken to make progress.

DebConf team: DebConf15 dates are set, come and join us! (Posted by DebConf15 team)

At DebConf14 in Portland, Oregon, USA, next year s DebConf team presented their conference plans and announced the conference dates: DebConf15 will take place from 15 to 22 August 2015 in Heidelberg, Germany. On the Open Weekend on 15/16 August, we invite members of the public to participate in our wide offering of content and events, before we dive into the more technical part of the conference during following week. DebConf15 will also be preceeded by DebCamp, a time and place for teams to gather for intensive collaboration. A set of slides from a quick show-case during the DebConf14 closing ceremony provide a quick overview of what you can expect next year. For more in-depth information, we invite you to watch the video recording of the full session, in which the team provides detailed information on the preparations so far, location and transportation to the venue at Heidelberg, the different rooms and areas at the Youth Hostel (for accommodation, hacking, talks, and social activities), details about the infrastructure that are being worked on, and the plans around the conference schedule. We invite everyone to join us in organising this conference. There are different areas where your help could be very valuable, and we are always looking forward to your ideas. Have a look at our wiki page, join our IRC channels and subscribe to our mailing lists. We are also contacting potential sponsors from all around the globe. If you know any organisation that could be interested, please consider handing them our sponsorship brochure or contact the fundraising team with any leads. Let s work together, as every year, on making the best DebConf ever!

Russell Coker: LUV Server Upgrade to Jessie

On Sunday night I started the process of upgrading the LUV server to Debian/Jessie from Debian/Wheezy. My initial plan was to just upgrade Apache first but dependencies required upgrading systemd too. One problem I ve encountered in the past is that the Wheezy version of systemd will often hang on an upgrade to a newer version. Generally the solution to this is to run systemctl daemon-reexec from another terminal. The problem in this case was that not all the libraries needed for systemd had been installed, so systemd could re-exec itself but immediately aborted. The kernel really doesn t like it when process 1 aborts repeatedly and apparently immediately hanging is the result. At the time I didn t know this, all I knew was that my session died and the server stopped responding to pings immediately after I requested a reexec. The LUV server is hosted at VPAC for free. As their staff have actual work to do they couldn t spend a lot of time working on the LUV server. They told me that the screen was flickering and suspected a VGA cable. I got to the VPAC server room with the spare LUV server (LUV had been given 3 almost identical Sun servers from Barwon Water) at 16:30. By 17:30 I had fixed the core problem (boot with init=/bin/bash , mount the root filesystem rw, finish the upgrade of systemd and it s dependencies, and then reboot normally). That got it into a stage where the Xen server for Wikimedia Au was working but most LUV functionality wasn t working. By 23:00 on Monday I had the full list server functionality working for users, this is the main feature that users want when it s not near a meeting time. I can t remember whether it was Monday night or Tuesday morning when I got the Drupal site going (the main LUV web site). Last night at midnight I got the last of the Mailman administrative interface going, I admit I could have got it going a bit earlier by putting SE Linux in permissive mode, but I don t think that the members would have benefited from that (I ll upload a SE Linux policy package that gets Mailman working on Jessie soon). Now it s Wednesday and I m still fixing some cron jobs. Along the way I noticed some problems with excessive disk space use that I m fixing now and I ve also removed some Wikimedia related configuration files that were obsolete and would have prevented anyone from using a wikimedia.org.au address to subscribe to the LUV mailing lists. Now I believe that everything is working correctly and generally working better than before. Lessons Learned While Sunday night wasn t a bad time to start the upgrade it wasn t the best. If I had started the upgrade on Monday morning there would have been less down-time. Another possibility might be to do the upgrade while near the VPAC office during business hours, I could have started the upgrade while at a nearby cafe and then visited the server room immediately if something went wrong. Doing an upgrade on a day when there s no meeting within a week was a good choice. It wasn t really a conscious choice as I m usually doing other LUV work near the meeting day which precludes doing other LUV work that doesn t need to be done soon. But in future it would be best to consciously plan upgrades for a date when users aren t going to need the service much. While the Wheezy systemd bug is unlikely to ever be fixed there are work-arounds that shouldn t result in a broken server. At the moment it seems that the best option would be to kill -9 the systemctl processes that hang until the packages that systemd depends on are installed. The problem is that the upgrade hangs while the new systemctl tries to tell the old systemd to restart daemons. If we can get past that to the stage where the shared objects are installed then it should be ok. The Apache upgrade from 2.2.x to 2.4.x changed the operation of some access control directives and it took me some time to work out how to fix that. Doing a Google search on the differences between those would have led me to the Apache document about upgrading from 2.2 to 2.4 [1]. That wouldn t have prevented some down-time of the web sites but would have allowed me to prepare for it and to more quickly fix the problems when they became apparent. Also the rather confusing configuration of the LUV server (supporting many web sites that are no longer used) didn t help things. I think that removing cruft from an installation before an upgrade would be better than waiting until after things break. Next time I do an upgrade of such a server I ll write notes about it while I go. That will give a better blog post about it if it becomes newsworthy enough to be blogged about and also more opportunities to learn better ways of doing it. Sorry for the inconvenience.

Antoine Beaupr : Proprietary VDSL2 Linux routers adventures

I recently bought a wireless / phone adapter / VDSL modem from my Internet Service Provider (ISP) during my last outage. It generally works fine as a VDSL modem, but unfortunately, I can't seem to get used to configuring the device through their clickety web user interface... Furthermore, I am worried that I can't backup the config in a meaningful way, that is: if the device fails, I will probably not find the same model again and because they run a custom Linux distributions, the chances of the backup being possible to restore on another machine are basically zero. No way i will waste my time configuring this black box. So I started looking at running a distribution like OpenWRT on it.
(Unfortunately, I don't even dare hoping to run a decent operating system like Debian on those devices, if only because of the exotic chipsets that require all sorts of nasty hacks to run...)
The machine is a SmartRG SR630n (specs). I am linking to third party site, because the SmartRG site doesn't seem to know about their own product (!). I paid extra for this device to get one that would do both Wifi and VoIP, so i could replace two machines: my current Soekris net5501 router and a Cisco ATA 186 phone adapter that seems to mysteriously defy the challenges of time. (I don't remember when I got that thing, but it's at least from 2006.) Unfortunately, it seems that SmartRG are running a custom, proprietary Linux distribution. According to my ISP, init is a complete rewrite that reads an XML config file (and indeed it's the format of the backup files) and does the configuration through a shared memory scheme (!?). According to DSL reports, the device seems to be running a Broadcom 63168 SOC (system on a chip) that is unsupported in Linux. There are some efforts to write drivers for those from scratch, but they have been basically stalled for years now. Here are more details on the sucker: Now the next step would logically be to "simply" build a new image with OpenWRT and install it in place. Then I would need to figure out a way to load the binary blobs into the OpenWRT kernel and run all the ADSL utilities as well. It's basically impossible: the odds of the binary modules being compatible with another arbitrary release of the Linux kernel are near zero. Furthermore, the userland tool are most likely custom as well. And worse of all: it seems that Bell Canada deployed a custom "Lucent Stinger" DSLAM which requires a custom binary firmware in the modem. This could be why the SmartRG is so bizarre in the first place. As long as the other end is non-standard, we are all screwed. And those Stinger DSLAM will stick around for a long time, thanks to bell.
See this other good explanation of Stinger.
Which means this machine is now yet another closed box sitting on the internet without firmware upgrades, totally handicapped. I will probably end up selling it back for another machine that has OpenWRT support for their VDSL modems. But there are very few such machines, and with a lot of those, VDSL support is often marked as "spotty" or "in progress". Some machines are supported but are basically impossible to find. There's the Draytek modems are also interesting because, apparently, some models run OpenWRT out of the box too, which is a huge benefit. This is because they use the more open Lantiq SOC. Which are probably not going to support Stinger lines. Still, there are some very interesting projects out there... The Omnia is one I am definitely interested in right now. I really like their approach... But then they don't have a VDSL chipset in there (I asked for one, actually). And the connectors are only mini-PCIe, which makes it impossible to connect a VDSL PCI card into it. I could find a single VDSL2 PCI card online, and it could be supported, but only the annex B is available, not the annex A, and it seems the network is using "annex A" according to the ADSL stats i had in 2015-05-28-anarcat-back-again. With such a card, I could use my existing Soekris net5501 router, slam a DSL card into it, and just use the SmartRG as a dumb wifi router/phone adapter. Then it will remain to see how supported are those VDSL cards in FreeBSD (they provide Linux source code, so that's cool). And of course, all this assumes the card works with the "Stinger" mode, which is probably not the case anyways. Besides, I have VDSL2 here, not the lowly ADSL2+. By the way, Soekris keeps on pushing new interesting products out: their net6501, with 2 extra Gig-E cards could be a really interesting high-end switch, all working with free software tools. A friend has a SmartRG 505n modem, which looks quite similar, except without the ATA connectors. And those modems are the ones that Teksavvy recommends ("You may use a Cellpipe 7130 or Sagemcom F@ST 2864 in lieu of our SmartRG SR505N for our DSL 15/10, DSL 25 or DSL 50 services."). Furthermore, Teksavvy provides a firmware update for the 505n - again, no idea if it works with the 630n. Of course, the 505n doesn't run OpenWRT either. So, long story short, again I got screwed by my ISP: I thought i would get a pretty hackable device, "running Linux" that my ISP said over the phone. I got weeks of downtime, no refund, and while i got a better line (more reliable, higher bandwidth), my costs doubled. And I have yet another computing device to worry about: instead of simplifying and reducing waste, I actually just added crap on top of my already cluttered desk. Next time, maybe I'll tell you about how my ISP overbilled me, broke IPv6 and drops large packets to the floor. I haven't had a response from them in months now... hopefully they will either answer and fix all of this (doubtful) or I'll switch to some other provider, probably Teksavvy. Many thanks to the numerous people in the DSL reports Teksavvy forum that have amazing expertise. They are even building a map of Bell COs... Thanks also to Taggart for helping me figure out how the firmware images work and encouraging me to figure out how my machine works overall.
Note: all the information shared here is presented in the spirit of the fair use conditions of copyright law.

20 October 2015

Russ Allbery: Review: The Oathbound

Review: The Oathbound, by Mercedes Lackey
Series: Vows and Honor #1
Publisher: DAW
Copyright: July 1988
ISBN: 0-88677-414-4
Format: Mass market
Pages: 302
This book warrants a bit of explanation. Before Arrows of the Queen, before Valdemar (at least in terms of publication dates), came Tarma and Kethry short stories. I don't know if they were always intended to be set in the same world as Valdemar; if not, they were quickly included. But they came from another part of the world and a slightly different sub-genre. While the first two Valdemar trilogies were largely coming-of-age fantasy, Tarma and Kethry are itinerant sword-and-sorcery adventures featuring two women with a soul bond: the conventionally attractive, aristocratic mage Kethry, and the celibate, goddess-sworn swordswoman Tarma. Their first story was published, appropriately, in Marion Zimmer Bradley's Swords and Sorceress III. This is the first book about Tarma and Kethry. It's a fix-up novel: shorter stories, bridged and re-edited, and glued together with some additional material. And it does not contain the first Tarma and Kethry story. As mentioned in my earlier Valdemar reviews, this is a re-read, but it's been something like twenty years since I previously read the whole Valdemar corpus (as it was at the time; I'll probably re-read everything I have on hand, but it's grown considerably, and I may not chase down the rest of it). One of the things I'd forgotten is how oddly, from a novel reader's perspective, the Tarma and Kethry stories were collected. Knowing what I know now about publishing, I assume Swords and Sorceress III was still in print at the time The Oathbound was published, or the rights weren't available for some other reason, so their first story had to be omitted. Whatever the reason, The Oathbound starts with a jarring gap that's no less irritating in this re-read than it was originally. Also as is becoming typical for this series, I remembered a lot more world-building and character development than is actually present in at least this first book. In this case, I strongly suspect most of that characterization is in Oathbreakers, which I remember as being more of a coherent single story and less of a fix-up of puzzle and adventure stories with scant time for character growth. I'll be able to test my memory shortly. What we do get is Kethry's reconciliation of her past, a brief look at the Shin'a'in and the depth of Tarma and Kethry's mutual oath (unfortunately told more than shown), the introduction of Warrl (again, a relationship that will grow a great deal more depth later), and then some typical sword and sorcery episodes: a locked room mystery, a caravan guard adventure about which I'll have more to say later, and two rather unpleasant encounters with a demon. The material is bridged enough that it has a vague novel-like shape, but the bones of the underlying short stories are pretty obvious. One can tell this isn't really a novel even without the tell of a narrative recap in later chapters of events that you'd just read earlier in the same book. What we also get is rather a lot of rape, and one episode of seriously unpleasant "justice." A drawback of early Lackey is that her villains are pure evil. My not entirely trustworthy memory tells me that this moderates over time, but early stories tend to feature villains completely devoid of redeeming qualities. In this book alone one gets to choose between the rapist pedophile, the rapist lord, the rapist bandit, and the rapist demon who had been doing extensive research in Jack Chalker novels. You'll notice a theme. Most of the rape happens off camera, but I was still thoroughly sick of it by the end of the book. This was already a cliched motivation tactic when these stories were written. Worse, as with the end of Arrow's Flight, the protagonists don't seem to be above a bit of "turnabout is fair play." When you're dealing with rape as a primary plot motivation, that goes about as badly as you might expect. The final episode here involves a confrontation that Tarma and Kethry brought entirely on themselves through some rather despicable actions, and from which they should have taken a lesson about why civilized societies have criminal justice systems. Unfortunately, despite an ethical priest who is mostly played for mild amusement, no one in the book seems to have drawn that rather obvious conclusion. This, too, I recall as getting better as the series goes along and Lackey matures as a writer, but that only helps marginally with the early books. Some time after the publication of The Oathbound and Oathbreakers, something (presumably the rights situation) changed. Oathblood was published in 1998 and includes not only the first Tarma and Kethry story but also several of the short stories that make up this book, in (I assume) something closer to their original form. That makes The Oathbound somewhat pointless and entirely skippable. I re-read it first because that's how I first approached the series many years ago, and (to be honest) because I'd forgotten how much was reprinted in Oathblood. I'd advise a new reader to skip it entirely, start with the short stories in Oathblood, and then read Oathbreakers before reading the final novella. You'd miss the demon stories, but that's probably for the best. I'm complaining a lot about this book, but that's partly from familiarity. If you can stomach the rape and one stunningly unethical protagonist decision, the stories that make it up are solid and enjoyable, and the dynamic between Tarma and Kethry is always a lot of fun (and gets even better when Warrl is added to the mix). I think my favorite was the locked room mystery. It's significantly spoiled by knowing the ending, and it has little deeper significance, but it's a classic sort unembellished, unapologetic sword-and-sorcery tale that's hard to come by in books. But since it too is reprinted (in a better form) in Oathblood, there's no point in reading it here. Followed by Oathbreakers. Rating: 6 out of 10

Ritesh Raj Sarraf: Controlling ill behaving applications with Linux Cgroups

For some time, I have been wanting to read more on Linux Cgroups to explore possibilities of using it to control Ill behaving applications. At this time, while I'm stuck in travel, it has given me some time to look into it. In our Free Software world, most of the things are do-o-cracy, i.e. when your use case is not the common one, it is typically you who has to explore possible solutions. It could be Bugs, Feature Requests or as is in my case, performance issues. But that is not to assume that we do not have better quality software in Free Software world. Infact, in my opinion, some of the tools available are far much more better than the competition in terms of features, and to add a sweetener (or nutritional facts) to it is the fact that Free Software liberates the user. One of my favorite tool, for photo management, is Digikam. Digikam is a big project, very featureful, and has some functionalities that may not be available in the competition. But as is with most Free Software projects, Digikam is a tool which underneath consumes many more subprojects from the Free Software ecosystem. For anyone who has used Digikam, may know some of the bugs that surface on it. Not necessarily a bug in Digikam, but maybe in one of the underneath libraries/tools that it consumes (Exiv, libkface, marble, OpenCV, libPGF etc). But the bottom line is that the overall Digikam experience (and if I may say: the overall GNU/Linux experience) takes a hit. Digikam has pretty powerful features for annotation, tagging, facial recognition. These features, together with Digikam, make it a compelling product. But the problem is that many of these projects are independent. Thus tight integration is a challenge. And at times, bugs can be hard to find, root cause and fix. Let's take a real example here. If you were to use Digikam today (version 4.13.0) with annotation, tagging and facial recognition as some of the core features for your use case, you may run into frustrating overall experience. Not just that, the bugs would also effect your overall GNU/Linux experience. The facial recognition feature, if triggered, will eat up all your memory. Thus leading you to uncover Linux's long old memory bug. The tagging feature, if triggered, again will lead to frequent I/O. Thus again leading to a stalled Linux system because of blocked CPU cycled, for nothing. So one of the items on my TODO list was to explore Linux Cgroups, and see if it was cleanly possible to tame a process to a confinement, so that even if it was ill behaving (for whatever reasons), your machine does not take the beating. And now that the cgroups consumer dust has kinda settled down, systemd was my first obvious choice to look at. systemd provides a helper utility, systemd-run, for similar tasks. With systemd-run, you could apply all the resource controller logic to the given process, typically cpu, memory and blkio. And restrict it to a certain set. You can also define what user to run the service as.
rrs@learner:/var/tmp/Debian-Build/Result$ systemd-run -p BlockIOWeight=10 find /
Running as unit run-23805.service.
2015-10-20 / 21:37:44         
rrs@learner:/var/tmp/Debian-Build/Result$ systemctl status -l run-23805.service
  run-23805.service - /usr/bin/find /
   Loaded: loaded
  Drop-In: /run/systemd/system/run-23805.service.d
            50-BlockIOWeight.conf, 50-Description.conf, 50-ExecStart.conf
   Active: active (running) since Tue 2015-10-20 21:37:44 CEST; 6s ago
 Main PID: 23814 (find)
   Memory: 12.2M
      CPU: 502ms
   CGroup: /system.slice/run-23805.service
            23814 /usr/bin/find /
Oct 20 21:37:45 learner find[23814]: /proc/3/net/raw6
Oct 20 21:37:45 learner find[23814]: /proc/3/net/snmp
Oct 20 21:37:45 learner find[23814]: /proc/3/net/stat
Oct 20 21:37:45 learner find[23814]: /proc/3/net/stat/rt_cache
Oct 20 21:37:45 learner find[23814]: /proc/3/net/stat/arp_cache
Oct 20 21:37:45 learner find[23814]: /proc/3/net/stat/ndisc_cache
Oct 20 21:37:45 learner find[23814]: /proc/3/net/stat/ip_conntrack
Oct 20 21:37:45 learner find[23814]: /proc/3/net/stat/nf_conntrack
Oct 20 21:37:45 learner find[23814]: /proc/3/net/tcp6
Oct 20 21:37:45 learner find[23814]: /proc/3/net/udp6
2015-10-20 / 21:37:51         
But, out of the box, graphical applications do not work. I haven't looked, but it should be doable by giving it the correct environment details.
Underneath, systemd is using the same Linux Control Groups to limit resources for individual applications. So, in cases where you have a requirement and do not have systemd, or you directly want to make use of cgroups, it could be easily done with basic cgroups tools like cgroup-tools.
With cgroup-tools, I now have a simple cgroups hierarchy set for my current use case, i.e. Digikam
rrs@learner:/var/tmp/Debian-Build/Result$ ls /sys/fs/cgroup/memory/rrs_customCG/
cgroup.clone_children           memory.kmem.tcp.limit_in_bytes      memory.numa_stat
cgroup.event_control            memory.kmem.tcp.max_usage_in_bytes  memory.oom_control
cgroup.procs                    memory.kmem.tcp.usage_in_bytes      memory.pressure_level
digikam/                        memory.kmem.usage_in_bytes          memory.soft_limit_in_bytes
memory.failcnt                  memory.limit_in_bytes               memory.stat
memory.force_empty              memory.max_usage_in_bytes           memory.swappiness
memory.kmem.failcnt             memory.memsw.failcnt                memory.usage_in_bytes
memory.kmem.limit_in_bytes      memory.memsw.limit_in_bytes         memory.use_hierarchy
memory.kmem.max_usage_in_bytes  memory.memsw.max_usage_in_bytes     notify_on_release
memory.kmem.slabinfo            memory.memsw.usage_in_bytes         tasks
memory.kmem.tcp.failcnt         memory.move_charge_at_immigrate
2015-10-20 / 21:45:38         
rrs@learner:/var/tmp/Debian-Build/Result$ ls /sys/fs/cgroup/memory/rrs_customCG/digikam/
cgroup.clone_children           memory.kmem.tcp.max_usage_in_bytes  memory.oom_control
cgroup.event_control            memory.kmem.tcp.usage_in_bytes      memory.pressure_level
cgroup.procs                    memory.kmem.usage_in_bytes          memory.soft_limit_in_bytes
memory.failcnt                  memory.limit_in_bytes               memory.stat
memory.force_empty              memory.max_usage_in_bytes           memory.swappiness
memory.kmem.failcnt             memory.memsw.failcnt                memory.usage_in_bytes
memory.kmem.limit_in_bytes      memory.memsw.limit_in_bytes         memory.use_hierarchy
memory.kmem.max_usage_in_bytes  memory.memsw.max_usage_in_bytes     notify_on_release
memory.kmem.slabinfo            memory.memsw.usage_in_bytes         tasks
memory.kmem.tcp.failcnt         memory.move_charge_at_immigrate
memory.kmem.tcp.limit_in_bytes  memory.numa_stat
2015-10-20 / 21:45:53         
rrs@learner:/var/tmp/Debian-Build/Result$ cat /sys/fs/cgroup/cpu/rrs_customCG/cpu.shares 
1024
2015-10-20 / 21:48:44         
rrs@learner:/var/tmp/Debian-Build/Result$ cat /sys/fs/cgroup/cpu/rrs_customCG/digikam/cpu.shares 
512
2015-10-20 / 21:49:05         
rrs@learner:/var/tmp/Debian-Build/Result$ cat /sys/fs/cgroup/memory/rrs_customCG/memory.limit_in_bytes 
9223372036854771712
2015-10-20 / 22:20:14         
rrs@learner:/var/tmp/Debian-Build/Result$ cat /sys/fs/cgroup/memory/rrs_customCG/digikam/memory.limit_in_bytes 
2764369920
2015-10-20 / 22:20:27         
rrs@learner:/var/tmp/Debian-Build/Result$ cat /sys/fs/cgroup/blkio/rrs_customCG/blkio.weight
500
2015-10-20 / 21:51:43         
rrs@learner:/var/tmp/Debian-Build/Result$ cat /sys/fs/cgroup/blkio/rrs_customCG/digikam/blkio.weight
10
2015-10-20 / 21:51:50         
The base group, $USER_customCG needs super admin privileges. Which once set appropriately, allows the user to further self-define sub-groups. And users can then also define separate limits per sub-group.
With the resource limitations set in place, my overall experience on very recent hardware (Intel Haswell Core i7, 8 GiB RAM, 500 GB SSHD, 128 GB SSD) has improved considerably. It still is not perfect, but it definitely is a huge improvement over what I had to go through ealire: A stalled machine for hours.
top - 21:54:38 up 1 day,  6:46,  1 user,  load average: 7.22, 7.51, 7.37
Tasks: 299 total,   1 running, 298 sleeping,   0 stopped,   0 zombie
%Cpu0  :  7.1 us,  3.0 sy,  1.0 ni, 11.1 id, 77.8 wa,  0.0 hi,  0.0 si,  0.0 st
%Cpu1  :  6.0 us,  4.0 sy,  2.0 ni, 49.0 id, 39.0 wa,  0.0 hi,  0.0 si,  0.0 st
%Cpu2  :  5.0 us,  2.0 sy,  0.0 ni, 24.8 id, 68.3 wa,  0.0 hi,  0.0 si,  0.0 st
%Cpu3  :  5.9 us,  5.0 sy,  0.0 ni, 21.8 id, 67.3 wa,  0.0 hi,  0.0 si,  0.0 st
MiB Mem : 7908.926 total,   96.449 free, 4634.922 used, 3177.555 buff/cache
MiB Swap: 8579.996 total, 3454.746 free, 5125.250 used. 2753.324 avail Mem 
PID to signal/kill [default pid = 8879] 
  PID  PPID nTH USER        PR  NI S %CPU %MEM     TIME+ COMMAND                           UID 
 8879  8868  18 rrs         20   0 S  8.2 31.2  37:44.64 digikam                          1000 
10255  9960   4 rrs         39  19 S  1.0  0.8  19:47.73 tracker-miner-f                  1000 
10157  9960   7 rrs         20   0 S  0.5  3.0  32:29.76 gnome-shell                      1000 
    7     2   1 root        20   0 S  0.2        0:53.48 rcu_sched                           0 
  401     1   1 root        20   0 S  0.2  1.3   0:54.93 systemd-journal                     0 
10269  9937   4 rrs         20   0 S  0.2  0.4   2:34.50 gnome-terminal-                  1000 
15316     1  14 rrs         20   0 S  0.2  3.7  30:05.96 evolution                        1000 
23777     2   1 root        20   0 S  0.2        0:05.73 kworker/u16:0                       0 
23814     1   1 root        20   0 D  0.2  0.0   0:02.00 find                                0 
24049     2   1 root        20   0 S  0.2        0:01.29 kworker/u16:3                       0 
24052     2   1 root        20   0 S  0.2        0:02.94 kworker/u16:4                       0 
    1     0   1 root        20   0 S       0.1   0:18.24 systemd                             0 
The reporting tools may not be correct here. Because from what is being reported above, I should be having a machine stalled, and heavily paging, while the kernel scanning its list of processes to find the best process to kill. From this approach of jailing processes, the major side effect I can see is that the process (Digikam) is now starved of resources and will take much much much more time than what it would have been usually. But in the usual cases, it takes up all, and ends up starving (and getting killed) for consuming all available resources. So I guess it is better to be on a balanced resource diet. :-)

Categories:

Keywords:

Like:

18 October 2015

Lunar: Reproducible builds: week 25 in Stretch cycle

What happened in the reproducible builds effort this week: Toolchain fixes Niko Tyni wrote a new patch adding support for SOURCE_DATE_EPOCH in Pod::Man. This would complement or replace the previously implemented POD_MAN_DATE environment variable in a more generic way. Niko Tyni proposed a fix to prevent mtime variation in directories due to debhelper usage of cp --parents -p. Packages fixed The following 119 packages became reproducible due to changes in their build dependencies: aac-tactics, aafigure, apgdiff, bin-prot, boxbackup, calendar, camlmix, cconv, cdist, cl-asdf, cli-common, cluster-glue, cppo, cvs, esdl, ess, faucc, fauhdlc, fbcat, flex-old, freetennis, ftgl, gap, ghc, git-cola, globus-authz-callout-error, globus-authz, globus-callout, globus-common, globus-ftp-client, globus-ftp-control, globus-gass-cache, globus-gass-copy, globus-gass-transfer, globus-gram-client, globus-gram-job-manager-callout-error, globus-gram-protocol, globus-gridmap-callout-error, globus-gsi-callback, globus-gsi-cert-utils, globus-gsi-credential, globus-gsi-openssl-error, globus-gsi-proxy-core, globus-gsi-proxy-ssl, globus-gsi-sysconfig, globus-gss-assist, globus-gssapi-error, globus-gssapi-gsi, globus-net-manager, globus-openssl-module, globus-rsl, globus-scheduler-event-generator, globus-xio-gridftp-driver, globus-xio-gsi-driver, globus-xio, gnome-control-center, grml2usb, grub, guilt, hgview, htmlcxx, hwloc, imms, kde-l10n, keystone, kimwitu++, kimwitu-doc, kmod, krb5, laby, ledger, libcrypto++, libopendbx, libsyncml, libwps, lprng-doc, madwimax, maria, mediawiki-math, menhir, misery, monotone-viz, morse, mpfr4, obus, ocaml-csv, ocaml-reins, ocamldsort, ocp-indent, openscenegraph, opensp, optcomp, opus, otags, pa-bench, pa-ounit, pa-test, parmap, pcaputils, perl-cross-debian, prooftree, pyfits, pywavelets, pywbem, rpy, signify, siscone, swtchart, tipa, typerep, tyxml, unison2.32.52, unison2.40.102, unison, uuidm, variantslib, zipios++, zlibc, zope-maildrophost. The following packages became reproducible after getting fixed: Packages which could not be tested: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which have not made their way to the archive yet: Lunar reported that test strings depend on default character encoding of the build system in ongl. reproducible.debian.net The 189 packages composing the Arch Linux core repository are now being tested. No packages are currently reproducible, but most of the time the difference is limited to metadata. This has already gained some interest in the Arch Linux community. An explicit log message is now visible when a build has been killed due to the 12 hours timeout. (h01ger) Remote build setup has been made more robust and self maintenance has been further improved. (h01ger) The minimum age for rescheduling of already tested amd64 packages has been lowered from 14 to 7 days, thanks to the increase of hardware resources sponsored by ProfitBricks last week. (h01ger) diffoscope development diffoscope version 37 has been released on October 15th. It adds support for two new file formats (CBFS images and Debian .dsc files). After proposing the required changes to TLSH, fuzzy hashes are now computed incrementally. This will avoid reading entire files in memory which caused problems for large packages. New tests have been added for the command-line interface. More character encoding issues have been fixed. Malformed md5sums will now be compared as binary files instead of making diffoscope crash amongst several other minor fixes. Version 38 was released two days later to fix the versioned dependency on python3-tlsh. strip-nondeterminism development strip-nondeterminism version 0.013-1 has been uploaded to the archive. It fixes an issue with nonconformant PNG files with trailing garbage reported by Roland Rosenfeld. disorderfs development disorderfs version 0.4.1-1 is a stop-gap release that will disable lock propagation, unless --share-locks=yes is specified, as it still is affected by unidentified issues. Documentation update Lunar has been busy creating a proper website for reproducible-builds.org that would be a common location for news, documentation, and tools for all free software projects working on reproducible builds. It's not yet ready to be published, but it's surely getting there. Homepage of the future reproducible-builds.org website  Who's involved?  page of the future reproducible-builds.org website Package reviews 103 reviews have been removed, 394 added and 29 updated this week. 72 FTBFS issues were reported by Chris West and Niko Tyni. New issues: random_order_in_static_libraries, random_order_in_md5sums.

17 October 2015

Simon Richter: Key Transition

So, since several years I've had a second gpg key, 4096R/6AABE354. Several of you have already signed it, and I've been using it in Debian for some time already, but I've not announced it more widely yet, and I occasionally still get mail encrypted to the old key (which remains valid and usable, but it's 1024R). Of course, I've also made a formal transition statement:
-----BEGIN PGP SIGNED MESSAGE-----
Hash: SHA1
OpenPGP Key Transition Statement for Simon Richter
I have created a new OpenPGP key and will be transitioning away from
my old key.  The old key has not been compromised and will continue to
be valid for some time, but I prefer all future correspondence to be
encrypted to the new key, and will be making signatures with the new
key going forward.
I would like this new key to be re-integrated into the web of trust.
This message is signed by both keys to certify the transition.  My new
and old keys are signed by each other.  If you have signed my old key,
I would appreciate signatures on my new key as well, provided that
your signing policy permits that without re-authenticating me.
The old key, which I am transitioning away from, is:
pub   1024D/5706A4B4 2002-02-26
      Key fingerprint = 040E B5F7 84F1 4FBC CEAD  ADC6 18A0 CC8D 5706 A4B4
The new key, to which I am transitioning, is:
pub   4096R/6AABE354 2009-11-19
      Key fingerprint = 9C43 2534 95E4 DCA8 3794  5F5B EBF6 7A84 6AAB E354
The entire key may be downloaded from: http://www.simonrichter.eu/simon.asc
To fetch the full new key from a public key server using GnuPG, run:
  gpg --keyserver keys.gnupg.net --recv-key 6AABE354
If you already know my old key, you can now verify that the new key is
signed by the old one:
  gpg --check-sigs 6AABE354
If you are satisfied that you've got the right key, and the User IDs
match what you expect, I would appreciate it if you would sign my key:
  gpg --sign-key 6AABE354
You can upload your signatures to a public keyserver directly:
  gpg --keyserver keys.gnupg.net --send-key 6AABE354
Or email sr@simonrichter.eu (possibly encrypted) the output from:
  gpg --armor --export 6AABE354
If you'd like any further verification or have any questions about the
transition please contact me directly.
To verify the integrity of this statement:
  wget -q -O- http://www.simonrichter.eu/key-transition-2015-03-09.txt   gpg --verify
   Simon
-----BEGIN PGP SIGNATURE-----
Version: GnuPG v1
iQEcBAEBAgAGBQJU/bbEAAoJEH69OHuwmQgRWOIH/AogHxhhVO5Tp5FFGpBFwljf
NzKTPBExMhZ/8trAzYybOWFv3Bx4AGdWkYfDnxP6oxQJOXVq4KL6ZcPPuIZuZ6fZ
bu0XHdPMU89u0TymR/WJENRCOcydRBe/lZs+zdJbKQtEZ+on4uNXxHpUiZPi1xxM
ggSdVBKn2PlCBcYih40S9Oo/rM9uBmYcFavX7JMouBSzgX78cVoIcY6zPRmHoq4k
TkGKfvHeSu+wbzWRmDwu/PFHRA4TKNvR6oeO+Et1yk454zjrHMXineBILRvvMCIA
t54pV6n+XzOUmtXcKnkIGltK+ZaJSV6am0swtx84RaevVXrknIQE8NvlA4MNgguI
nAQBAQIABgUCVP23tAAKCRDSx966V9+/u3j4BACVHifAcO86jAc5dn+4OkFZFhV1
l3MKIolL+E7Q7Ox+vJunGJJuGnOnazUK+64yDGZ2JxNJ4QNWD1FOs/Ng2gm82Vin
ArBtyp1ZGWUa+349X+1qarUQF9qAaUXDZjFp5Hzh/o6KC4t3eECxcb41og3LUTQD
VuG2KWNXYBe5P5ak9Q==
=o61r
-----END PGP SIGNATURE-----

Joey Hess: it's a bird, it's a plane, it's a super monoid for propellor

I've been doing a little bit of dynamically typed programming in Haskell, to improve Propellor's Info type. The result is kind of interesting in a scary way. Info started out as a big record type, containing all the different sorts of metadata that Propellor needed to keep track of. Host IP addresses, DNS entries, ssh public keys, docker image configuration parameters... This got quite out of hand. Info needed to have its hands in everything, even types that should have been private to their module. To fix that, recent versions of Propellor let a single Info contain many different types of values. Look at it one way and it contains DNS entries; look at it another way and it contains ssh public keys, etc. As an migr from lands where you can never know what type of value is in a $foo until you look, this was a scary prospect at first, but I found it's possible to have the benefits of dynamic types and the safety of static types too. The key to doing it is Data.Dynamic. Thanks to Joachim Breitner for suggesting I could use it here. What I arrived at is this type (slightly simplified):
newtype Info = Info [Dynamic]
    deriving (Monoid)
So Info is a monoid, and it holds of a bunch of dynamic values, which could each be of any type at all. Eep! So far, this is utterly scary to me. To tame it, the Info constructor is not exported, and so the only way to create an Info is to start with mempty and use this function:
addInfo :: (IsInfo v, Monoid v) => Info -> v -> Info
addInfo (Info l) v = Info (toDyn v : l)
The important part of that is that only allows adding values that are in the IsInfo type class. That prevents the foot shooting associated with dynamic types, by only allowing use of types that make sense as Info. Otherwise arbitrary Strings etc could be passed to addInfo by accident, and all get concated together, and that would be a total dynamic programming mess. Anything you can add into an Info, you can get back out:
getInfo :: (IsInfo v, Monoid v) => Info -> v
getInfo (Info l) = mconcat (mapMaybe fromDynamic (reverse l))
Only monoids can be stored in Info, so if you ask for a type that an Info doesn't contain, you'll get back mempty. Crucially, IsInfo is an open type class. Any module in Propellor can make a new data type and make it an instance of IsInfo, and then that new data type can be stored in the Info of a Property, and any Host that uses the Property will have that added to its Info, available for later introspection.
For example, this weekend I'm extending Propellor to have controllers: Hosts that are responsible for running Propellor on some other hosts. Useful if you want to run propellor once and have it update the configuration of an entire network of hosts. There can be whole chains of controllers controlling other controllers etc. The problem is, what if host foo has the property controllerFor bar and host bar has the property controllerFor foo? I want to avoid a loop of foo running Propellor on bar, running Propellor on foo, ... To detect such loops, each Host's Info should contain a list of the Hosts it's controlling. Which is not hard to accomplish:
newtype Controlling = Controlled [Host]
    deriving (Typeable, Monoid)
isControlledBy :: Host -> Controlling -> Bool
h  isControlledBy  (Controlled hs) = any (== hostName h) (map hostName hs)
instance IsInfo Controlling where
    propigateInfo _ = True
mkControllingInfo :: Host -> Info
mkControllingInfo controlled = addInfo mempty (Controlled [controlled])
getControlledBy :: Host -> Controlling
getControlledBy = getInfo . hostInfo
isControllerLoop :: Host -> Host -> Bool
isControllerLoop controller controlled = go S.empty controlled
  where
    go checked h
          controller  isControlledBy  c = True
        -- avoid checking loops that have been checked before
          hostName h  S.member  checked = False
          otherwise = any (go (S.insert (hostName h) checked)) l
      where
        c@(Controlled l) = getControlledBy h
This is all internal to the module that needs it; the rest of propellor doesn't need to know that the Info is using used for this. And yet, the necessary information about Hosts is gathered as propellor runs.
So, that's a useful technique. I do wonder if I could somehow make addInfo combine together values in the list that have the same type; as it is the list can get long. And, to show Info, the best I could do was this:
 instance Show Info where
            show (Info l) = "Info " ++ show (map dynTypeRep l)
The resulting long list of the types of vales stored in a host's info is not a useful as it could be. Of course, getInfo can be used to get any particular type of value:
*Main> hostInfo kite
Info [InfoVal System,PrivInfo,PrivInfo,Controlling,DnsInfo,DnsInfo,DnsInfo,AliasesInfo, ...
*Main> getInfo (hostInfo kite) :: AliasesInfo
AliasesInfo (fromList ["downloads.kitenet.net","git.joeyh.name","imap.kitenet.net","nntp.olduse.net" ...
And finally, I keep trying to think of a better name than "Info".

Next.

Previous.