Search Results: "nate"

30 January 2025

Daniel Lange: Printing labels with the DYMO LabelWriter Wireless (and LabelWriter 5xx) on Debian Linux

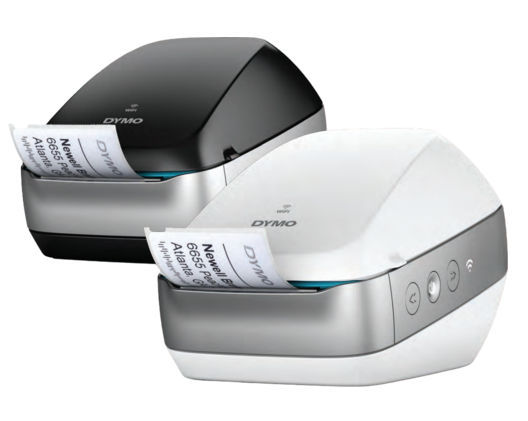
In 2020 my company bought a DYMO LabelWriter Wireless. It is an awesome little device for thermal printing a wide variety of labels. The labels are easily available both from DYMO and from third parties so the pricing is quite acceptable. Unfortunately DYMO supplies their DYMO Connect Software only for Microsoft Windows and MacOSX. A mobile app of the same name for Android and Apple iOS devices is available in the app stores. There is a SDK for Linux and there are drivers published for Linux but the LabelWriter Wireless was not supported on Linux when I tried to get it running for Debian in 2020. Image of the DYMO LabelWriter Wireless in the white and black versions This year I have had a new look at the situation as we still use the LabelWriter Wireless printers a lot and the company runs fully on Linux. So it is always a chore to run a Windows VM just to run DYMO Connect. Continue reading "Printing labels with the DYMO LabelWriter Wireless (and LabelWriter 5xx) on Debian Linux"

Dirk Eddelbuettel: RcppStreams 0.1.4: Maintenance

Streamulus A new maintenance release of RcppStreams is now on CRAN marking the first release in almost six years. RcppStreams brings the excellent Streamulus C++ template library for event stream processing to R. Streamulus, written by Irit Katriel, uses clever template meta-programming (via Boost Fusion) to implement an embedded domain-specific event language created specifically for event stream processing. This release covers only package and CRAN-specific updates. The NEWS file entries follows below:

Changes in version 0.1.4 (2024-01-29)
  • Package maintenance with updates to DESCRIPTION and README.md
  • Continunous integration has been update multiple times
  • No longer set a C++ compilation standard

Courtesy of my CRANberries, there is also a diffstat report for this release. More detailed information is on the RcppStreams page page and of course on the Streamulus page. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

29 January 2025

Keith Packard: picolibc-i18n

Internationalization support in Picolibc There are two major internationalization APIs in the C library: locales and iconv. Iconv is an isolated component which only performs charset conversion in ways that don't interact with anything else in the library. Locales affect pretty much every API that deals with strings and covers charset conversion along with a huge range of localized information from character classification to formatting of time, money, people's names, addresses and even standard paper sizes. Picolibc inherits it's implementation of both of these from newlib. Given that embedded applications rarely need advanced functionality from either these APIs, I hadn't spent much time exploring this space. Newlib locale code When run on Cygwin, Newlib's locale support is quite complete as it leverages the underlying Windows locale support. Without Windows support, everything aside from charset conversion and character classification data is stubbed out at the bottom of the stack. Because the implementation can support full locale functionality, the implementation is designed for that, with large data structures and lots of code. Charset conversion and character classification data for locales is all built-in; none of that can be loaded at runtime. There is support for all of the ISO-8859 charsets, three JIS variants, a bunch of Windows code pages and a few other single-byte encodings. One oddity in this code is that when using a JIS locale, wide characters are stored in EUC-JP rather than Unicode. Every other locale uses Unicode. This means APIs like wctype are implemented by mapping the JIS-encoded character to Unicode and then using the underlying Unicode character classification tables. One consequence of this is that there isn't any Unicode to JIS mapping provided as it isn't necessary. When testing the charset conversion and Unicode character classification data, I found numerous minor errors and a couple of pretty significant ones. The JIS conversion code had the most serious issue I found; most of the conversions are in a 2d array which is manually indexed with the wrong value for the length of each row. This led to nearly every translated value being incorrect. The charset conversion tables and Unicode classification data are now generated using python charset support and the standard Unicode data files. In addition, tests have been added which compare Picolibc to the system C library for every supported charset. Newlib iconv code The iconv charset support is completely separate from the locale charset support with a much wider range of supported targets. It also supports loading charset data from files at runtime, which reduces the size of application images. Because the iconv and locale implementations are completely separate, the charset support isn't the same. Iconv supports a lot more charsets, but it doesn't support all of those available to locales. For example, Iconv has Big5 support which locale lacks. Conversely, locale has Shift-JIS support which iconv does not. There's also a difference in how charset names are mapped in the two APIs. The locale code has a small fixed set of aliases, which doesn't include things like US-ASCII or ANSI X3.4. In contrast, the iconv code has an extensive database of charset aliases which are compiled into the library. Picolibc has a few tests for the iconv API which verify charset names and perform some translations. Without an external reference, it's hard to know if the results are correct. POSIX vs C internationalization In addition to including the iconv API, POSIX extends locale support in a couple of ways:
  1. Exposing locale objects via the newlocale, uselocale, duplocale and freelocale APIs.
  2. uselocale sets a per-thread locale, rather than the process-wide locale.
Goals for Picolibc internationalization support For charsets, supporting UTF-8 should cover the bulk of embedded application needs, and even that is probably more than what most applications require. Most (all?) compilers use Unicode for wide character and string constants. That means wchar_t needs to be Unicode in every locale. Aside from charset support, the rest of the locale infrastructure is heavily focused on creating human-consumable strings. I don't think it's a stretch to say that none of this is very useful these days, even for systems with sophisticated user interactions. For picolibc, the cost to provide any of this would be high. Having two completely separate charset conversion datasets makes for a confusing and error-prone experience for developers. Replacing iconv with code that leverages the existing locale support for translating between multi-byte and wide-character representations will save a bunch of source code and improve consistency. Embedded systems can be very sensitive to memory usage, both read-only and read-write. Applications not using internationalization capabilities shouldn't pay a heavy premium even when the library binary is built with support. For the most sensitive targets, the library should be configurable to remove unnecessary functionality. Picolibc needs to be conforming with at least the C language standard, and as much of POSIX as makes sense. Fortunately, the requirements for C are modest as it only includes a few locale-related APIs and doesn't include iconv. Finally, picolibc should test these APIs to make sure they conform with relevant standards, especially character set translation and character classification. The easiest way to do this is to reference another implementation of the same API and compare results. Switching to Unicode for JIS wchar_t This involved ripping the JIS to Unicode translations out of all of the wide character APIs and inserting them into the translations between multi-byte and wide-char representations. The missing Unicode to JIS translation was kludged by iterating over all JIS code points until a matching Unicode value was found. That's an obvious place for a performance improvement, but at least it works. Tiny locale This is a minimal implementation of locales which conforms with the C language standard while providing only charset translation and character classification data. It handles all of the existing charsets, but splits things into three levels
  1. ASCII
  2. UTF-8
  3. Extended, including any or all of: a. ISO 8859 b. Windows code pages and other 8-bit encodings c. JIS (JIS, EUC-JP and Shift-JIS)
When built for ASCII-only, all of the locale support is short-circuited, except for error checking. In addition, support in printf and scanf for wide characters is removed by default (it can be re-enabled with the -Dio-wchar=true meson option). This offers the smallest code size. Because the wctype APIs (e.g. iswupper) are all locale-specific, this mode restricts them to ASCII-only, which means they become wrappers on top of the ctype APIs with added range checking. When built for UTF-8, character classification for wide characters uses tables that provide the full Unicode range. Setlocale now selects between two locales, "C" and "C.UTF-8". Any locale name other than "C" selects the UTF-8 version. If the locale name contains "." or "-", then the rest of the locale name is taken to be a charset name and matched against the list of supported charsets. In this mode, only "us_ascii", "ascii" and "utf-8" are recognized. Because a single byte of a utf-8 string with the high-bit set is not a complete character, all of the ctype APIs in this mode can use the same implementation as the ASCII-only mode. This means the small ctype implementation is available. Calling setlocale(LC_ALL, "C.UTF-8") will allow the application to use the APIs which translate between multi-byte and wide-characters to deal with UTF-8 encoded strings. In addition, scanf and printf can read and write UTF-8 strings into wchar_t strings. Locale names are converted into locale IDs, an enumeration which lists the available locales. Each ID implies a specific charset as that's the only thing which differs between them. This means a locale can be encoded in a few bytes rather than an array of strings. In terms of memory usage, applications not using locales and not using the wctype APIs should see only a small increase in code space. That's due to the wchar_t support added to printf and scanf which need to translate between multi-byte and wide-character representations. There aren't any tables required as ASCII and UTF-8 are directly convertible to Unicode. On ARM-v7m, The added code in printf and scanf add up to about 1kB and another 32 bytes of RAM is used. The big difference when enabling extended charset support is that all of the charset conversion and character classification operations become table driven and dependent on the locale. Depending on the extended charsets supported, these can be quite large. With all of the extended charsets included, this adds an additional 30kB of code and static data and uses another 56 bytes of RAM. There are two known gaps in functionality compared with the newlib code:
  1. Locale strings that encode different locales for different categories. That's nominally required by POSIX as LC_ALL is supposed to return a string sufficient to restore the locale, but the only category which actually matters is LC_CTYPE.
  2. No nl_langinfo support. This would be fairly easy to add, returning appropriate constant values for each parameter.
Tiny locale was merged to picolibc main in this PR Tiny iconv Replacing the bulky newlib iconv code was far easier than swapping locale implementations. Essentially all that iconv does is compute two functions, one which maps from multi-byte to wide-char in one locale and another which maps from wide-char to multi-byte in another locale. Once the JIS locales were fixed to use Unicode, the new iconv implementation was straightforward. POSIX doesn't provide any _l version of mbrtowc or wcrtomb, so using standard C APIs would have been clunky. Instead, the implementation uses the internal APIs to compute the correct charset conversion functions. The entire implementation fits in under 200 lines of code. Tiny iconv is in process in this PR Future directions Right now, both of these new bits of code sit in the source tree parallel to the old versions. I'm not seeing any particular reason to keep the old versions around; they have provided a useful point of comparison in developing the new code, but I don't think they offer any compelling benefits going forward.

Russ Allbery: Review: The Sky Road

Review: The Sky Road, by Ken MacLeod
Series: Fall Revolution #4
Publisher: Tor
Copyright: 1999
Printing: August 2001
ISBN: 0-8125-7759-0
Format: Mass market
Pages: 406
The Sky Road is the fourth book in the Fall Revolution series, but it represents an alternate future that diverges after (or during?) the events of The Sky Fraction. You probably want to read that book first, but I'm not sure reading The Stone Canal or The Cassini Division adds anything to this book other than frustration. Much more on that in a moment. Clovis colha Gree is a aspiring doctoral student in history with a summer job as a welder. He works on the platform for the project, which the reader either slowly discovers from the book or quickly discovers from the cover is a rocket to get to orbit. As the story opens, he meets (or, as he describes it) is targeted by a woman named Merrial, a tinker who works on the guidance system. The early chapters provide only a few hints about Clovis's world: a statue of the Deliverer on a horse that forms the backdrop of their meeting, the casual carrying of weapons, hints that tinkers are socially unacceptable, and some division between the white logic and the black logic in programming. Also, because this is a Ken MacLeod novel, everyone is obsessed with smoking and tobacco the way that the protagonists of erotica are obsessed with sex. Clovis's story is one thread of this novel. The other, told in the alternating chapters, is the story of Myra Godwin-Davidova, chair of the governing Council of People's Commissars of the International Scientific and Technical Workers' Republic, a micronation embedded in post-Soviet Kazakhstan. Series readers will remember Myra's former lover, David Reid, as the villain of The Stone Canal and the head of the corporation Mutual Protection, which is using slave labor (sort of) to support a resurgent space movement and its attempt to take control of a balkanized Earth. The ISTWR is in decline and a minor power by all standards except one: They still have nuclear weapons. So, first, we need to talk about the series divergence. I know from reading about this book on-line that The Sky Road is an alternate future that does not follow the events of The Stone Canal and The Cassini Division. I do not know this from the text of the book, which is completely silent about even being part of a series. More annoyingly, while the divergence in the Earth's future compared to The Cassini Division is obvious, I don't know what the Jonbar hinge is. Everything I can find on-line about this book is maddeningly coy. Wikipedia claims the divergence happens at the end of The Sky Fraction. Other reviews and the Wikipedia talk page claim it happens in the middle of The Stone Canal. I do have a guess, but it's an unsatisfying one and I'm not sure how to test its correctness. I suppose I shouldn't care and instead take each of the books on their own terms, but this is the type of thing that my brain obsesses over, and I find it intensely irritating that MacLeod didn't explain it in the books themselves. It's the sort of authorial trick that makes me feel dumb, and books that gratuitously make me feel dumb are less enjoyable to read. The second annoyance I have with this book is also only partly its fault. This series, and this book in particular, is frequently mentioned as good political science fiction that explores different ways of structuring human society. This was true of some of the earlier books in a surprisingly superficial way. Here, I would call it hogwash. This book, or at least the Myra portion of it, is full of people doing politics in a tactical sense, but like the previous books of this series, that politics is mostly embedded in personal grudges and prior romantic relationships. Everyone involved is essentially an authoritarian whose ability to act as they wish is only contested by other authoritarians and is largely unconstrained by such things as persuasion, discussions, elections, or even theory. Myra and most of the people she meets are profoundly cynical and almost contemptuous of any true discussion of political systems. This is the trappings and mechanisms of politics without the intellectual debate or attempt at consensus, turning it into a zero-sum game won by whoever can threaten the others more effectively. Given the glowing reviews I've seen in relatively political SF circles, presumably I am missing something that other people see in MacLeod's approach. Perhaps this level of pettiness and cynicism is an accurate depiction of what it's like inside left-wing political movements. (What an appalling condemnation of left-wing political movements, if so.) But many of the on-line reviews lead me to instead conclude that people's understanding of "political fiction" is stunted and superficial. For example, there is almost nothing Marxist about this book it contains essentially no economic or class analysis whatsoever but MacLeod uses a lot of Marxist terminology and sets half the book in an explicitly communist state, and this seems to be enough for large portions of the on-line commentariat to conclude that it's full of dangerous, radical ideas. I find this sadly hilarious given that MacLeod's societies tend, if anything, towards a low-grade libertarianism that would be at home in a Robert Heinlein novel. Apparently political labels are all that's needed to make political fiction; substance is optional. So much for the politics. What's left in Clovis's sections is a classic science fiction adventure in which the protagonist has a radically different perspective from the reader and the fun lies in figuring out the world-building through the skewed perspective of the characters. This was somewhat enjoyable, but would have been more fun if Clovis had any discernible personality. Sadly he instead seems to be an empty receptacle for the prejudices and perspective of his society, which involve a lot of quasi-religious taboos and an essentially magical view of the world. Merrial is a more interesting character, although as always in this series the romance made absolutely no sense to me and seemed to be conjured by authorial fiat and weirdly instant sexual attraction. Myra's portion of the story was the part I cared more about and was more invested in, aided by the fact that she's attempting to do something more interesting than launch a crewed space vehicle for no obvious reason. She at least faces some true moral challenges with no obviously correct response. It's all a bit depressing, though, and I found Myra's unwillingness to ground her decisions in a more comprehensive moral framework disappointing. If you're going to make a protagonist the ruler of a communist state, even an ironic one, I'd like to hear some real political philosophy, some theory of sociology and economics that she used to justify her decisions. The bits that rise above personal animosity and vibes were, I think, said better in The Cassini Division. This series was disappointing, and I can't say I'm glad to have read it. There is some small pleasure in finishing a set of award-winning genre books so that I can have a meaningful conversation about them, but the awards failed to find me better books to read than I would have found on my own. These aren't bad books, but the amount of enjoyment I got out of them didn't feel worth the frustration. Not recommended, I'm afraid. Rating: 6 out of 10

28 January 2025

Russ Allbery: Review: Moose Madness

Review: Moose Madness, by Mar Delaney
Publisher: Kalikoi
Copyright: May 2021
ASIN: B094HGT1ZB
Format: Kindle
Pages: 68
Moose Madness is a sapphic shifter romance novella (on the short side for a novella) by the same author as Wolf Country. It was originally published in the anthology Her Wild Soulmate, which appears to be very out of print. Maggie (she hates the nickname Moose) grew up in Moose Point, a tiny fictional highway town in (I think) Alaska. (There is, unsurprisingly, an actual Moose Point in Alaska, but it's a geographic feature and not a small town.) She stayed after graduation and is now a waitress in the Moose Point Pub. She's also a shifter; specifically, she is a moose shifter like her mother, the town mayor. (Her father is a fox shifter.) As the story opens, the annual Moose Madness festival is about to turn the entire town into a blizzard of moose kitsch. Fiona Barton was Maggie's nemesis in high school. She was the cool, popular girl, a red-headed wolf shifter whose friend group teased and bullied awkward and uncoordinated Maggie mercilessly. She was also Maggie's impossible crush, although the very idea seemed laughable. Fi left town after graduation, and Maggie hadn't thought about her for years. Then she walks into Moose Point Pub dressed in biker leathers, with piercings and one side of her head shaved, back in town for a wedding in her pack. Much to the shock of both Maggie and Fi, they realize that they're soulmates as soon as their eyes meet. Now what? If you thought I wasn't going to read the moose and wolf shifter romance once I knew it existed, you do not know me very well. I have been saving it for when I needed something light and fun. It seemed like the right palette cleanser after a very disappointing book. Moose Madness takes place in the same universe as Wolf Country, which means there are secret shifters all over Alaska (and presumably elsewhere) and they have the strong magical version of love at first sight. If one is a shifter, one knows immediately as soon as one locks eyes with one's soulmate and this feeling is never wrong. This is not my favorite romance trope, but if I get moose shifter romance out of it, I'll endure. As you can tell from the setup, this is enemies-to-lovers, but the whole soulmate thing shortcuts the enemies to lovers transition rather abruptly. There's a bit of apologizing and air-clearing at the start, but most of the novella covers the period right after enemies have become lovers and are getting to know each other properly. If you like that part of the arc, you will probably enjoy this, but be warned that it's slight and somewhat obvious. There's a bit of tension from protective parents and annoying pack mates, but it's sorted out quickly and easily. If you want the characters to work for the relationship, this is not the novella for you. It's essentially all vibes. I liked the vibes, though! Maggie is easy to like, and Fi does a solid job apologizing. I wish there was quite a bit more moose than we get, but Delaney captures the combination of apparent awkwardness and raw power of a moose and has a good eye for how beautiful large herbivores can be. This is not the sort of book that gives a moment's thought to wolves being predators and moose being, in at least some sense, prey animals, so if you are expecting that to be a plot point, you will be disappointed. As with Wolf Country, Delaney elides most of the messier and more ethically questionable aspects of sometimes being an animal. This is a sweet, short novella about two well-meaning and fundamentally nice people who are figuring out that middle school and high school are shitty and sometimes horrible but don't need to define the rest of one's life. It's very forgettable, but it made me smile, and it was indeed a good palette cleanser. If you are, like me, the sort of person who immediately thought "oh, I have to read that" as soon as you saw the moose shifter romance, keep your expectations low, but I don't think this will disappoint. If you are not that sort of person, you can safely miss this one. Rating: 6 out of 10

27 January 2025

Russ Allbery: Review: The House That Fought

Review: The House That Fought, by Jenny Schwartz
Series: Uncertain Sanctuary #3
Publisher: Jenny Schwartz
Copyright: December 2020
Printing: September 2024
ASIN: B0DBX6GP8Z
Format: Kindle
Pages: 199
The House That Fought is the third and final book of the self-published space fantasy trilogy starting with The House That Walked Between Worlds. I read it as part of the Uncertain Sanctuary omnibus, which is reflected in the sidebar metadata. At the end of the last book, one of Kira's random and vibe-based trust decisions finally went awry. She has been betrayed! She's essentially omnipotent, the betrayal does not hurt her in any way, and, if anything, it helps the plot resolution, but she has to spend some time feeling bad about it first. Eventually, though, the band of House residents return to the problem of Earth's missing magic. By Earth here, I mean our world, which technically isn't called Earth in the confusing world-building of this series. Earth within this universe is an archetypal world that is the origin world for humans, the two types of dinosaurs, and Neanderthals. There are numerous worlds that have split off from it, including Human, the one world where humans are dominant, which is what we think of as Earth and what Kira calls Earth half the time. And by worlds, I mean entire universes (I think?), because traveling between "worlds" is dimensional travel, not space travel. But there is also space travel? The world building started out confusing and has degenerated over the course of the series. Given that the plot, such as it is, revolves around a world-building problem, this is not a good sign. Worse, though, is that the quality of the writing has become unedited, repetitive drivel. I liked the first book and enjoyed a few moments of the second book, but this conclusion is just bad. This is the sort of book that the maxim "show, don't tell" was intended to head off. The dull, thudding description of the justification for every character emotion leaves no room for subtlety or reader curiosity.
Evander was elf and I was human. We weren't the same. I had magic. He had the magic I'd unconsciously locked into his augmentations. We were different and in love. Speaking of our differences could be a trigger. I peeked at him, worried. My customary confidence had taken a hit. "We're different," he answered my unspoken question. "And we work anyway. We'll work to make us work."
There is page after page after page of this sort of thing: facile emotional processing full of cliches and therapy-speak, built on the most superficial of relationships. There's apparently a romance now, which happened with very little build-up, no real discussion or communication between the characters, and only the most trite and obvious relationship work. There is a plot underneath all this, but it's hard to make it suspenseful given that Kira is essentially omnipotent. Schwartz tries to turn the story into a puzzle that requires Kira figure out what's going on before she can act, but this is undermined by the confusing world-building. The loose ends the plot has accumulated over the previous two books are mostly dropped, sometimes in a startlingly casual way. I thought Kira would care who killed her parents, for example; apparently, I was wrong. The previous books caught my attention with a more subtle treatment of politics than I expect from this sort of light space fantasy. The characters had, I thought, a healthy suspicion of powerful people and a willingness to look for manipulation or ulterior motives. Unfortunately, we discover here that this is not due to an appreciation of the complexity of power and motive in governments. Instead, it's a reflexive bias against authority and structured society that sounds like an Internet libertarian complaining about taxes. Powerful people should be distrusted because all governments are corrupt and bad and steal your money in order to waste it. Oh, except for the cops and the military; they're generally good people you should trust. In retrospect, I should have expected this turn given the degree to which Schwartz stressed the independence of sorcerers. I thought that was going somewhere more interesting than sorcerers as self-appointed vigilantes who are above the law and can and should do anything they damn well please. Sadly, it was not. Adding to the lynch mob feeling, the ending of this book is a deeply distasteful bit of magical medieval punishment that I thought was vile, and which is, of course, justified by bad things happening to children. No societal problems were solved, but Kira got her petty revenge and got to be gleeful and smug about it. This is apparently what passes for a happy ending. I don't even know what to say about the bizarre insertion of Christianity, which makes little sense given the rest of the world-building. It's primarily a way for Kira to avoid understanding or thinking about an important part of the plot. As sadly seems to often be the case in books like this, Kira's faith doesn't appear to prompt any moral analysis or thoughtful ethical concern about her unlimited power, just certainty that she's right and everyone else is wrong. This was dire. It is one of those self-published books that I feel a little bad about writing this negative of a review about, because I think most of the problem was that the author's skill was not up to the story that she wanted to tell. This happens a lot in self-published fiction, particularly since Kindle Unlimited has started rewarding quantity over quality. But given how badly the writing quality degraded over the course of the series, and how offensive the ending was, I do want to warn other people off of the series. There is so much better fiction out there. Avoid this one, and probably the rest of the series unless you're willing to stop after the first book. Rating: 2 out of 10

26 January 2025

Dirk Eddelbuettel: RcppBDT 0.2.7 on CRAN: Maintenance

Another minor maintenance release for the RcppBDT package is now on CRAN. The RcppBDT package is an early adopter of Rcpp and was one of the first packages utilizing Boost and its Date_Time library. The now more widely-used package anytime is a direct descentant of RcppBDT. This release follows the recent updates of other package updating their C++ compilation standard along with other standard package updates. No feature or interface changes. The NEWS entry follows:

Changes in version 0.2.7 (2025-01-25)
  • The package no longer sets a C++ compilation standard
  • Package infrastructure, documentation and continuous integration support have been updated
  • Several manual pages now have package anchors for the code link
  • A demo/ file has been move to inst/examples/

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Otto Kek l inen: 10 habits to help becoming a Debian Maintainer

Featured image of post 10 habits to help becoming a Debian MaintainerBecoming a Debian maintainer is a journey that combines technical expertise, community collaboration, and continuous learning. In this post, I ll share 10 key habits that will both help you navigate the complexities of Debian packaging without getting lost, and also enable you to contribute more effectively to one of the world s largest open source projects.

1. Read and re-read the Debian Policy, the Developer s Reference and the git-buildpackage manual Anyone learning Debian packaging and aspiring to become a Debian maintainer is likely to wade through a lot of documentation, only to realize that much of it is outdated or sometimes outright incorrect. Therefore, it is important to learn right from the start which sources are the most reliable and truly worth reading and re-reading. I recommend these documents, in order of importance:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive, and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • The git-buildpackage man pages: While the Policy focuses on the end result and is intentionally void of practical instructions on creating or maintaining Debian packages, the Developer s Reference goes into greater detail. However, it too lacks step-by-step instructions. For the exact commands, consult the man pages of git-buildpackage and its subcommands (e.g., gbp clone, gbp import-orig, gbp pq, gbp dch, gbp push). See also my post on Debian source package git branch and tags for an easy to understand diagrams.

2. Make reading man pages a habit In addition to the above, try to make a habit of checking out the man page of every new tool you use to ensure you are using it as intended. The best place to read accurate and up-to-date documentation is manpages.debian.org. The manual pages are maintained alongside the tools by their developers, ensuring greater accuracy than any third-party documentation. If you are using a tool in the way the tool author documented, you can be confident you are doing the right thing, even if it wasn t explicitly mentioned in some third-party guide about Debian packaging best practices.

3. Read and write emails While members of the Debian community have many channels of communication, the mailing lists are by far the most prominent. Asking questions on the appropriate list is a good way to get current advice from other people doing Debian packaging. Staying subscribed to lists of interest is also a good way to read about new developments as they happen. Note that every post is public and archived permanently, so the discussions on the mailing lists also form a body of documentation that can later be searched and referred to. Regularly writing short and well-structured emails on the mailing lists is great practice for improving technical communication skills a useful ability in general. For Debian specifically, being active on mailing lists helps build a reputation that can later attract collaborators and supporters for more complex initiatives.

4. Create and use an OpenPGP key Related to reputation and identity, OpenPGP keys play a central role in the Debian community. OpenPGP is used to various degrees to sign git commits and tags, sign and encrypt email, and most importantly to sign Debian packages so their origin can be verified. The process of becoming a Debian Maintainer and eventually a Debian Developer culminates in getting your OpenPGP key included in the Debian keyring, which is used to control who can upload packages into the Debian archive. The earlier you create a key and start using it to gain reputation for that specific key that is used to sign your work, the better. Note that due to a recent schism in the OpenPGP standards working group, it is safest to create an OpenPGP key using GnuPG version 2.2.x (not 2.4.x), or using Sequoia-PGP.

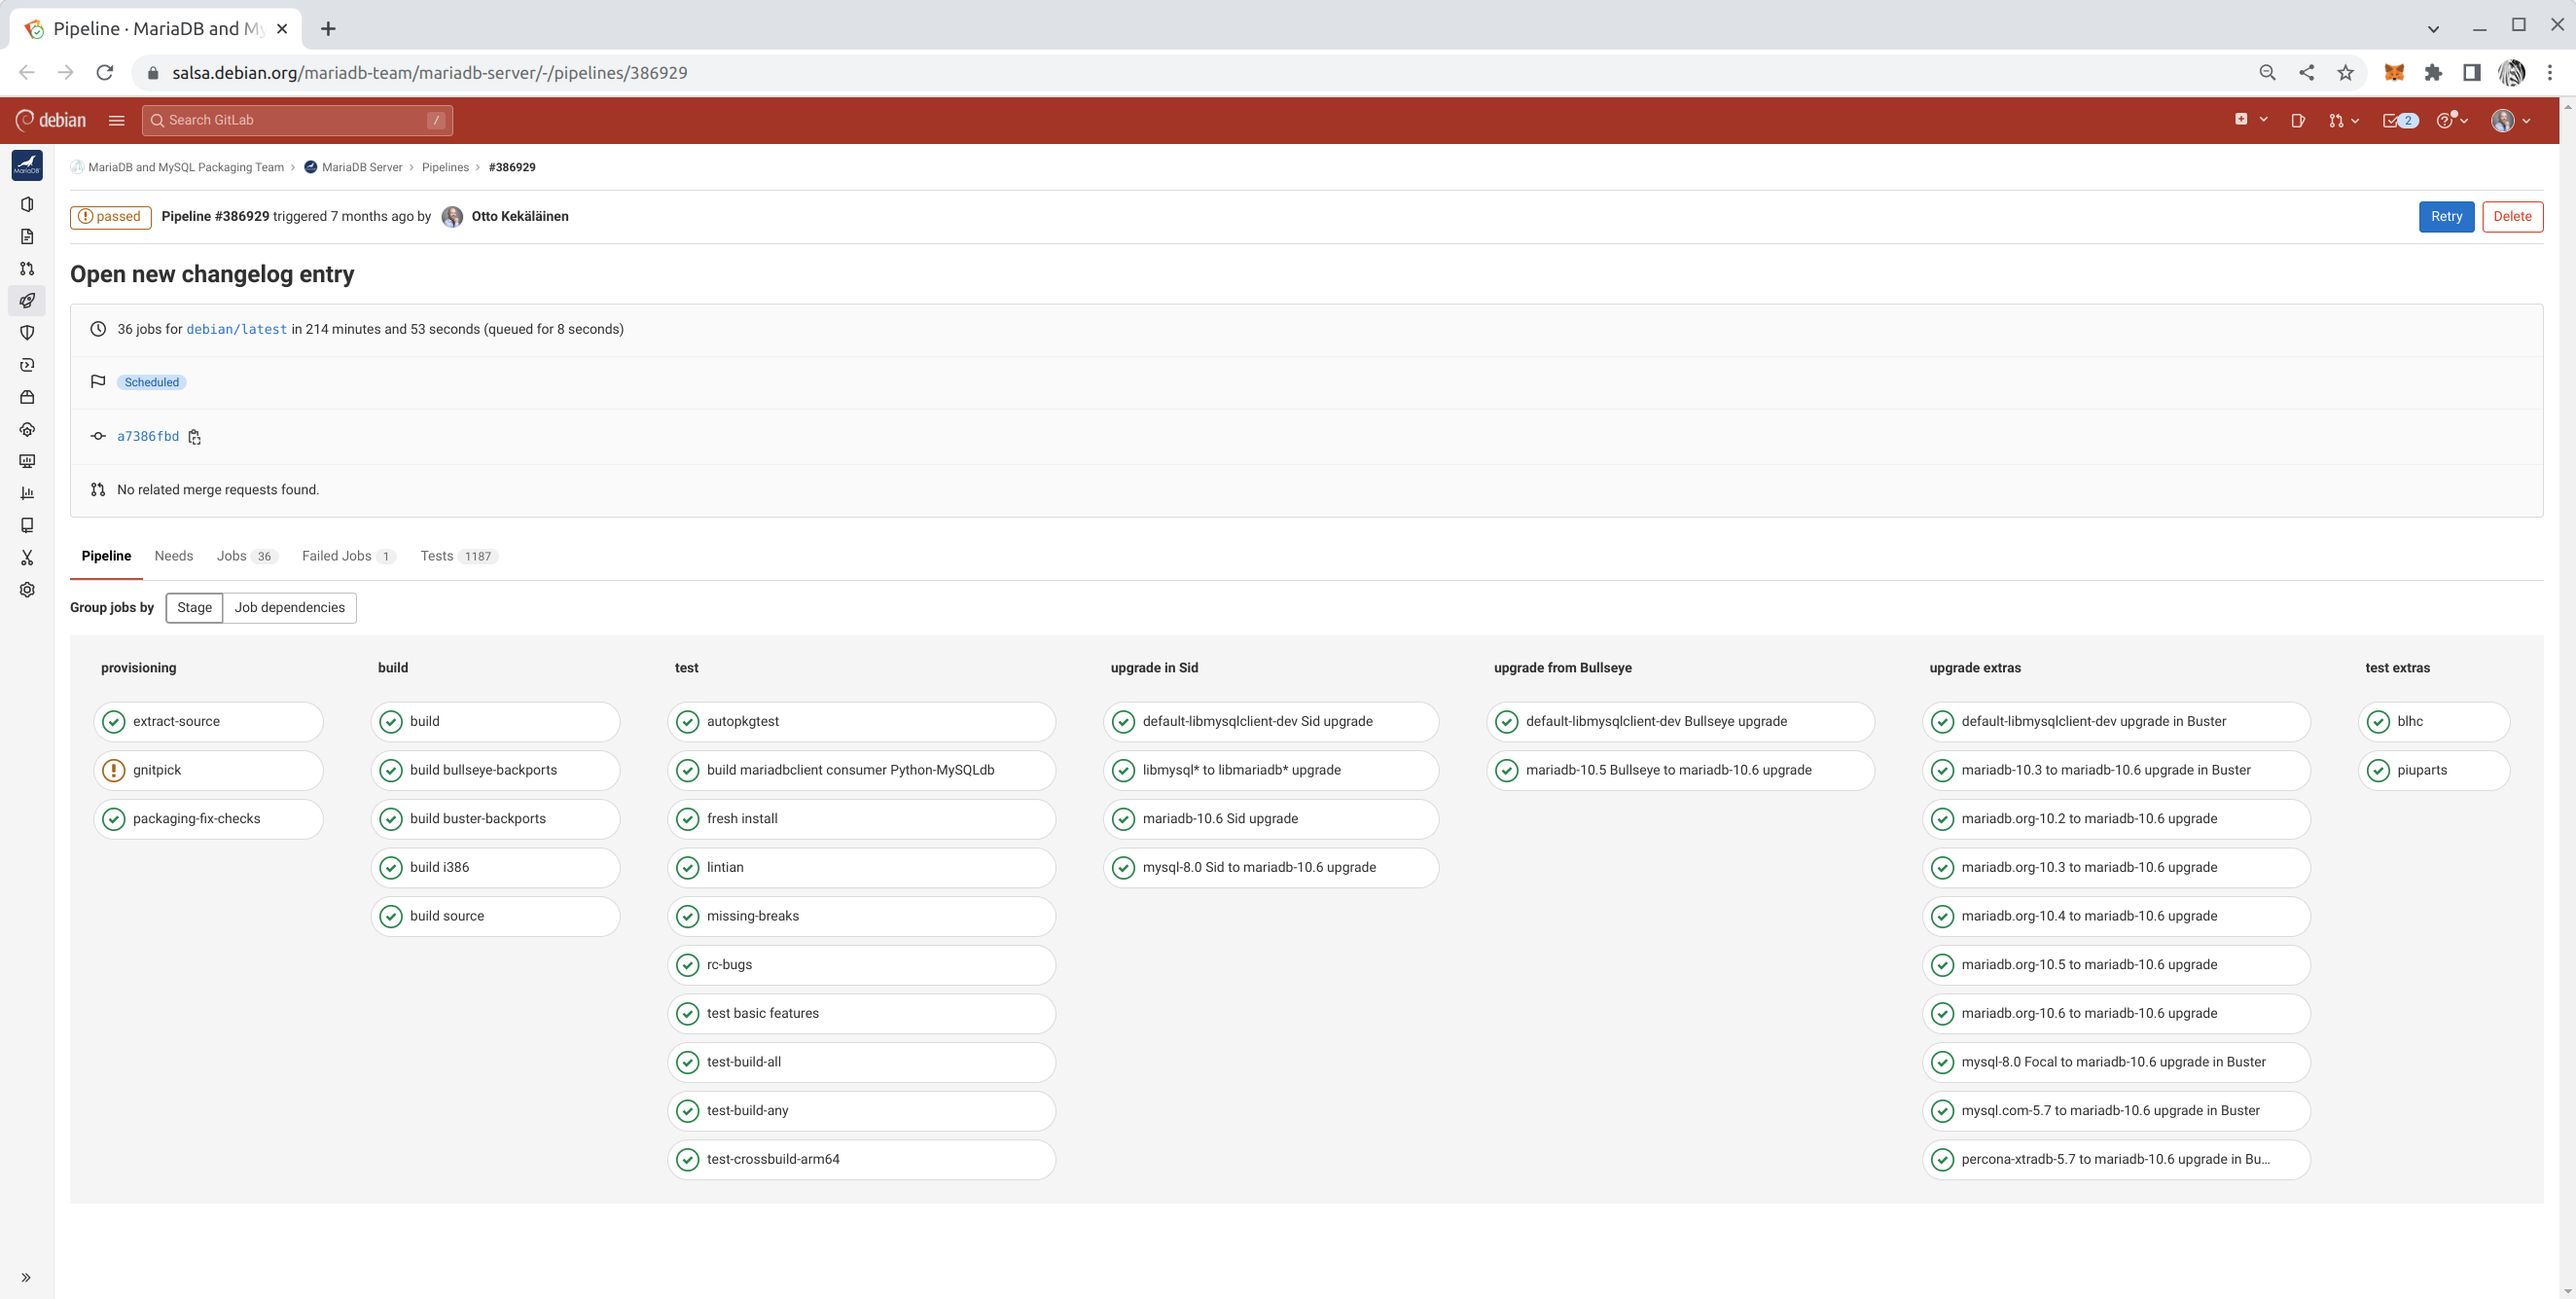
5. Integrate Salsa CI in all work One reason Debian remains popular, even 30 years after its inception, is due to its culture of maintaining high standards. For a newcomer, learning all the quality assurance tools such as Lintian, Piuparts, Adequate, various build variations, and reproducible builds may be overwhelming. However, these tasks are easier to manage thanks to Salsa CI, the continuous integration pipeline in Debian that runs tests on every commit at salsa.debian.org. The earlier you activate Salsa CI in the package repository you are working on, the faster you will achieve high quality in your package with fewer missteps. You can also further customize a package specific salsa-ci.yml to have more testing coverage. Example Salsa CI pipeline with customizations

6. Fork on Salsa and use draft Merge Requests to solicit feedback All modern Debian packages are hosted on salsa.debian.org. If you want to make a change to any package, it is easy to fork, make an initial attempt at the change, and publish it as a draft Merge Request (MR) on Salsa to solicit feedback. People might have surprising reasons to object to the change you propose, or they might need time to get used to the idea before agreeing to it. Also, some people might object to a vague idea out of suspicion but agree once they see the exact implementation. There may also be a surprising number of people supporting your idea, and if there is an MR, they have a place to show their support at. Don t expect every Merge Request to be accepted. However, proposing an idea as running code in an MR is far more effective than raising the idea on a mailing list or in a bug report. Get into the habit of publishing plenty of merge requests to solicit feedback and drive discussions toward consensus.

7. Use git rebase frequently Linear git history is much easier to read. The ease of reading git log and git blame output is vital in Debian, where packages often have updates from multiple people spanning many years even decades. Debian packagers likely spend more time than the average software developer reading git history. Make sure you master git commands such as gitk --all, git citool --amend, git commit -a --fixup <commit id>, git rebase -i --autosquash <target branch>, git cherry-pick <commit id 1> <id 2> <id 3>, and git pull --rebase. If rebasing is not done on your initiative, rest assured others will ask you to do it. Thus, if the commands above are familiar, rebasing will be quick and easy for you.

8. Reviews: give some, get some In open source, the larger a project becomes, the more it attracts contributions, and the bottleneck for its growth isn t how much code developers can create but how much code submissions can be properly reviewed. At the time of writing, the main Salsa group Debian has over 800 open merge requests pending reviews and approvals. Feel free to read and comment on any merge request you find. You don t have to be a subject matter expert to provide valuable feedback. Even if you don t have specific feedback, your comment as another human acknowledging that you read the MR and found no issues is viewed positively by the author. Besides, if you spend enough time reviewing MRs in a specific domain, you will eventually become an expert in it. Code reviews are not just about providing feedback to the submitter; they are also great learning opportunities for the reviewer. As a rule of thumb, you should review at least twice as many merge requests as you submit yourself.

9. Improve Debian by improving upstream It is common that while packaging software for Debian, bugs are uncovered and patched in Debian. Do not forget to submit the fixes upstream, and add a Forwarded field to the file in debian/patches! As the person building and packaging something in Debian, you automatically become an authority on that software, and the upstream is likely glad to receive your improvements. While submitting patches upstream is a bit of work initially, getting improvements merged upstream eventually saves time for everyone and makes packaging in Debian easier, as there will be fewer patches to maintain with each new upstream release.

10. Don t hold any habits too firmly Last but not least: Once people learn a specific way of working, they tend to stick to it for decades. Learning how to create and maintain Debian packages requires significant effort, and people tend to stop learning once they feel they ve reached a sufficient level. This tendency to get stuck in a local optimum is understandable and natural, but try to resist it. It is likely that better techniques will evolve over time, so stay humble and re-evaluate your beliefs and practices every few years. Mastering these habits takes time, but each small step brings you closer to making a meaningful impact on Debian. By staying curious, collaborative, and adaptable, you can ensure your contributions stand the test of time just like Debian itself. Good luck on your journey toward becoming a Debian Maintainer!

25 January 2025

Steve Kemp: The CP/M emulator now works better!

I keep saying I'm "done" with my CP/M emulator, but then I keep overhauling it in significant ways. Today is no exception. In the past the emulator used breakpoints to detect when calls to the system BIOS, or BDOS, were made. That was possible because the BIOS and BDOS entry points are at predictable locations. For example a well-behaved program might make a system call with code like this:
    LD A,42
    LD C,4
    CALL 0x0005
So setting a breakpoint on 0x0005 would let you detect a system-call was being made, inspect the registers to see which system-call was being made and then carry out the appropriate action in your emulator before returning control back to the program. Unfortunately some binaries patch the RAM, changing the contents of the entry points, or changing internal jump-tables, etc. The end result is that sometimes code running at the fixed addresses is not your BIOS at all, but something else. By trapping/faulting/catching execution here you break things, badly. So today's new release fixes that! No more breakpoints. Instead we deploy a "real BDOS" in RAM that will route system-calls to our host emulator via a clever trick. For BDOS functions the C-register will contain the system call to operate, our complete BDOS implementation is:
    OUT (C),C
    RET
The host program can catch writes to output ports, and will know that "OUT (3), 3" means "Invoke system call #3", for example. This means binary patches to entry-points, or any internal jump-tables won't confuse things and so long as control eventually reaches my BIOS or BDOS code areas things will work. I also added a new console-input driver, since I have a notion of pluggable input and output devices, which just reads input from a file. Now I can prove that my code works. Pass the following file to the input-driver and we have automated testing:
A:
ERA HELLO.COM
ERA HELLO.HEX
ERA HELLO.PRN
hello
ASM HELLO
LOAD HELLO
DDT HELLO.com
t
t
t
t
t
t
t
t
t
C-c
EXIT
Here we: I can test the output and confirm there are no regressions. Neat. Anyway new release, today. Happy.

24 January 2025

Sam Hartman: Feeling Targeted: Executive Order Ending Wasteful DEIA Efforts

As most here know, I m totally blind. One of my roles involves a contract for the US Government, under which I have a government email account. The department recently received a message talking about our work to end, to the maximum extend permitted by law, all diversity, equity, inclusion, and accessibility efforts in the government in accordance with the recently signed executive order. We are all reminded that if we timely identify the contracts and positions that are related to these efforts, there will be no consequences. There are a lot of times in my life when I have felt marginalized frustrated and angry that people weren t interested in working with me to make the small changes that would help me fit in. As an example with this government job, I asked to have access to a screen reader so that I could use my computer. My preferred adaptive software was not approved, even though it was thousands of dollars cheaper than the option the government wanted and could have been installed instantly rather than waiting for a multi-week ordering process. When the screen reader eventually became available, the government-provided installer was not accessible: a blind person could not use it. When I asked for help, the government added an additional multi-week delay because they weren t sure that the license management technology for the software they had chosen met the government s security and privacy policies. Which is to say that even with people actively working toward accessibility, sharing a commitment that accessibility is important, we have a lot of work to do. I feel very targeted at the current time. Now we are removing as many of the resources that help me be effective and feel welcome as we can. Talking about the lack of consequences now is just a way to remind everyone that there will be consequences later and get the fear going. The witch hunt is coming, and if people do a good enough job of turning in all the people who could help me feel welcome, they won t face consequences. Yes, I understand that the Americans with Disabilities act is still law, but its effectiveness will be very different in a climate where you need to eliminate accessibility positions to avoid consequences than in a climate where accessibility is a goal.

comment count unavailable comments

23 January 2025

Dirk Eddelbuettel: qlcal 0.0.14 on CRAN: Calendar Updates

The fourteenth release of the qlcal package arrivied at CRAN today, following the QuantLib 1.37 release two days ago. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases synchronizes qlcal with the QuantLib release 1.37 (made this week), and moves a demo/ file to examples/.

Changes in version 0.0.14 (2025-01-23)
  • Synchronized with QuantLib 1.37 released two days ago
  • Calendar updates for United States and New Zealand
  • The demo/ file is now in inst/examples/

This update includes the inclusion of the January 9, 2025, holiday for the memorial of President Carter that was observed at the NYSE and shown by the allUScalendars.R example:
edd@rob:~/git/qlcal-r/inst/examples(master)$ Rscript allUScalendars.R 
           LiborImpact NYSE GovernmentBond NERC FederalReserve SOFR
2025-01-01        TRUE TRUE           TRUE TRUE           TRUE TRUE
2025-01-09          NA TRUE             NA   NA             NA   NA
2025-01-20        TRUE TRUE           TRUE   NA           TRUE TRUE
2025-02-17        TRUE TRUE           TRUE   NA           TRUE TRUE
2025-04-18          NA TRUE           TRUE   NA             NA TRUE
2025-05-26        TRUE TRUE           TRUE TRUE           TRUE TRUE
2025-06-19        TRUE TRUE           TRUE   NA           TRUE TRUE
2025-07-04        TRUE TRUE           TRUE TRUE           TRUE TRUE
2025-09-01        TRUE TRUE           TRUE TRUE           TRUE TRUE
2025-10-13        TRUE   NA           TRUE   NA           TRUE TRUE
2025-11-11        TRUE   NA           TRUE   NA           TRUE TRUE
2025-11-27        TRUE TRUE           TRUE TRUE           TRUE TRUE
2025-12-25        TRUE TRUE           TRUE TRUE           TRUE TRUE
edd@rob:~/git/qlcal-r/inst/examples(master)$ 
Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

21 January 2025

Dirk Eddelbuettel: ttdo 0.0.10 on CRAN: Small Extension

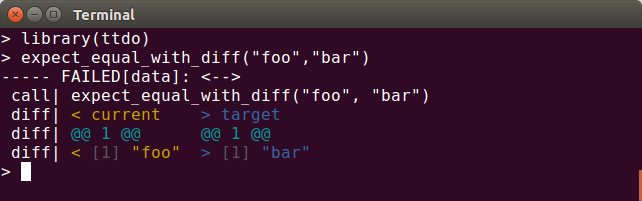
A new minor release of our ttdo package arrived on CRAN a few days ago. The ttdo package extends the excellent (and very minimal / zero depends) unit testing package tinytest by Mark van der Loo with the very clever and well-done diffobj package by Brodie Gaslam to give us test results with visual diffs (as shown in the screenshot below) which seemingly is so compelling an idea that it eventually got copied by another package which shall remain unnamed And as of this release, we also support visual diffs as provided by tinysnapshot by Vincent Arel-Bundock. ttdo screenshot This release chiefly adds support for visual diff plots. As we extend tinytest for use in the R autograder we maintain and deploy within the lovely PrairieLearn framework, we need to encode the diffplot that has been produced by the autograder (commonly in a separate Docker process) to communicate it back to the controlling (Docker also) instance of PrairieLearn. We also did the usual bits of package maintenance keeping badges, URLs, continuous integration and minor R coding standards current. As usual, the NEWS entry follows.

Changes in ttdo version 0.0.10 (2025-01-21)
  • Regular packaging updates to badges and continuous integration setup
  • Add support for a 'visual difference' taking advantage of a tinysnapshot feature returning a ttvd-typed result
  • Added (versioned) dependency on tinysnapshot (to also get the plot 'style' enhancement in the most recent version) and base64enc
  • Return ttdo-typed result if diffobj-printed result is returned
  • Ensure all package-documentation links in manual page have anchors to the package

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Ravi Dwivedi: The Arduous Luxembourg Visa Process

In 2024, I was sponsored by The Document Foundation (TDF) to attend the LibreOffice annual conference in Luxembourg from the 10th to the 12th of October. Being an Indian passport holder, I needed a visa to visit Luxembourg. However, due to my Kenya trip coming up in September, I ran into a dilemma: whether to apply before or after the Kenya trip. To obtain a visa, I needed to submit my application with VFS Global (and not with the Luxembourg embassy directly). Therefore, I checked the VFS website for information on processing time, which says:
As a rule, the processing time of an admissible Schengen visa application should not exceed 15 calendar days (from the date the application is received at the Embassy).
It also mentions:
If the application is received less than 15 calendar days before the intended travel date, the Embassy can deem your application inadmissible. If so, your visa application will not be processed by the Embassy and the application will be sent back to VFS along with the passport.
If I applied for the Luxembourg visa before my trip, I would run the risk of not getting my passport back in time, and therefore missing my Kenya flight. On the other hand, if I waited until after returning from Kenya, I would run afoul of the aforementioned 15 working days needed by the embassy to process my application. I had previously applied for a Schengen visa for Austria, which was completed in 7 working days. My friends who had been to France told me they got their visa decision within a week. So, I compared Luxembourg s application numbers with those of other Schengen countries. In 2023, Luxembourg received 3,090 applications from India, while Austria received 39,558, Italy received 52,332 and France received 176,237. Since Luxembourg receives a far fewer number of applications, I expected the process to be quick. Therefore, I submitted my visa application with VFS Global in Delhi on the 5th of August, giving the embassy a month with 18 working days before my Kenya trip. However, I didn t mention my Kenya trip in the Luxembourg visa application. For reference, here is a list of documents I submitted: I submitted flight reservations instead of flight tickets . It is because, in case of visa rejection, I would have lost a significant amount of money if I booked confirmed flight tickets. The embassy also recommends the same. After the submission of documents, my fingerprints were taken. The expenses for the visa application were as follows:
Service Description Amount (INR)
Visa Fee 8,114
VFS Global Fee 1,763
Courier 800
Total 10,677
Going by the emails sent by VFS, my application reached the Luxembourg embassy the next day. Fast-forward to the 27th of August 14th day of my visa application. I had already booked my flight ticket to Nairobi for the 4th of September, but my passport was still with the Luxembourg embassy, and I hadn t heard back. In addition, I also obtained Kenya s eTA and got vaccinated for Yellow Fever, a requirement to travel to Kenya. In order to check on my application status, I gave the embassy a phone call, but missed their calling window, which was easy to miss since it was only 1 hour - 12:00 to 1:00 PM. So, I dropped them an email explaining my situation. At this point, I was already wondering whether to cancel the Kenya trip or the Luxembourg one, if I had to choose. After not getting a response to my email, I called them again the next day. The embassy told me they would look into it and asked me to send my flight tickets over email. One week to go before my flight now. I followed up with the embassy on the 30th by a phone call, and the person who picked up the call told me that my request had already been forwarded to the concerned department and is under process. They asked me to follow up on Monday, 2nd September. During the visa process, I was in touch with three other Indian attendees.1 In the meantime, I got to know that all of them had applied for a Luxembourg visa by the end of the month of August. Back to our story, over the next two days, the embassy closed for the weekend. I began weighing my options. On one hand, I could cancel the Kenya trip and hope that Luxembourg goes through. Even then, Luxembourg wasn t guaranteed as the visa could get rejected, so I might have ended up missing both the trips. On the other hand, I could cancel the Luxembourg visa application and at least be sure of going to Kenya. However, I thought it would make Luxembourg very unlikely because it didn t leave 15 working days for the embassy to process my visa after returning from Kenya. I also badly wanted to attend the LibreOffice conference because I couldn t make it two years ago. Therefore, I chose not to cancel my Luxembourg visa application. I checked with my travel agent and learned that I could cancel my Nairobi flight before September 4th for a cancelation fee of approximately 7,000 INR. On the 2nd of September, I was a bit frustrated because I hadn t heard anything from the embassy regarding my request. Therefore, I called the embassy again. They assured me that they would arrange a call for me from the concerned department that day, which I did receive later that evening. During the call, they offered to return my passport via VFS the next day and asked me to resubmit it after returning from Kenya. I immediately accepted the offer and was overjoyed, as it would enable me to take my flight to Nairobi without canceling my Luxembourg visa application. However, I didn t have the offer in writing, so it wasn t clear to me how I would collect my passport from VFS. The next day, I would receive it when I would be on my way to VFS in the form of an email from the embassy which read:
Dear Mr. Dwivedi, We acknowledge the receipt of your email. As you requested, we are returning your passport exceptionally through VFS, you can collect it directly from VFS Delhi Center between 14:00-17:00 hrs, 03 Sep 2024. Kindly bring the printout of this email along with your VFS deposit receipt and Original ID proof. Once you are back from your trip, you can redeposit the passport with VFS Luxembourg for our processing. With best regards,
Consular Section GRAND DUCHY OF LUXEMBOURG
Embassy in New Delhi
I took a printout of the email and submitted it to VFS to get my passport. This seemed like a miracle - just when I lost all hope of making it to my Kenya flight and was mentally preparing myself to miss it, I got my passport back exceptionally and now I had to mentally prepare again for Kenya. I had never heard of an embassy returning passport before completing the visa process before. The next day, I took my flight to Nairobi as planned. In case you are interested, I have written two blog posts on my Kenya trip - one on the OpenStreetMap conference in Nairobi and the other on my travel experience in Kenya. After returning from Kenya, I resubmitted my passport on the 17th of September. Fast-forward to the 25th of September; I didn t hear anything from the embassy about my application process. So, I checked with TDF to see whether the embassy reached out to them. They told me they confirmed my participation and my hotel booking to the visa authorities on the 19th of September (6 days ago). I was wondering what was taking so long after the verification. On the 1st of October, I received a phone call from the Luxembourg embassy, which turned out to be a surprise interview. They asked me about my work, my income, how I came to know about the conference, whether I had been to Europe before, etc. The call lasted around 10 minutes. At this point, my travel date - 8th of October - was just two working days away as the 2nd of October was off due to Gandhi Jayanti and 5th and 6th October were weekends, leaving only the 3rd and the 4th. I am not sure why the embassy saved this for the last moment, even though I submitted my application 2 months ago. I also got to know that one of the other Indian attendees missed the call due to being in their college lab, where he was not allowed to take phone calls. Therefore, I recommend that the embassy agree on a time slot for the interview call beforehand. Visa decisions for all the above-mentioned Indian attendees were sent by the embassy on the 4th of October, and I received mine on the 5th. For my travel date of 8th October, this was literally the last moment the embassy could send my visa. The parcel contained my passport and a letter. The visa was attached to a page in the passport. I was happy that my visa had been approved. However, the timing made my task challenging. The enclosed letter stated:
Subject: Your Visa Application for Luxembourg
Dear Applicant, We would like to inform you that a Schengen visa has been granted for the 8-day duration from 08/10/2024 to 30/10/2024 for conference purposes in Luxembourg. You are requested to report back to the Embassy of Luxembourg in New Delhi through an email (email address redacted) after your return with the following documents:
  • Immigration Stamps (Entry and Exit of Schengen Area)
  • Restaurant Bills
  • Shopping/Hotel/Accommodation bills
Failure to report to the Embassy after your return will be taken into consideration for any further visa applications.
I understand the embassy wanting to ensure my entry and exit from the Schengen area during the visa validity period, but found the demand for sending shopping bills excessive. Further, not everyone was as lucky as I was as it took a couple of days for one of the Indian attendees to receive their visa, delaying their plan. Another attendee had to send their father to the VFS center to collect their visa in time, rather than wait for the courier to arrive at their home. Foreign travel is complicated, especially for the citizens of countries whose passports and currencies are weak. Embassies issuing visas a day before the travel date doesn t help. For starters, a last-minute visa does not give enough time for obtaining a forex card as banks ask for the visa. Further, getting foreign currency (Euros in our case) in cash with a good exchange rate becomes difficult. As an example, for the Kenya trip, I had to get US Dollars at the airport due to the plan being finalized at the last moment, worsening the exchange rate. Back to the current case, the flight prices went up significantly compared to September, almost doubling. The choice of airlines also got narrowed, as most of the flights got booked by the time I received my visa. With all that said, I think it was still better than an arbitrary rejection. Credits: Contrapunctus, Badri, Fletcher, Benson, and Anirudh for helping with the draft of this post.

  1. Thanks to Sophie, our point of contact for the conference, for putting me in touch with them.

20 January 2025

Dirk Eddelbuettel: RcppMsgPack 0.2.4 on CRAN: Maintenance

Another maintenance release of RcppMsgPack got onto CRAN today. MessagePack itself is an efficient binary serialization format. It lets you exchange data among multiple languages like JSON. But it is faster and smaller. Small integers are encoded into a single byte, and typical short strings require only one extra byte in addition to the strings themselves. RcppMsgPack brings both the C++ headers of MessagePack as well as clever code (in both R and C++) Travers wrote to access MsgPack-encoded objects directly from R. This is the first release in over six years, and contains mostly maintenance. One somewhat embarassing aspect is that Travers and I forgot about a PR that had been ready all this since the last release, it has now been integrated. Details follow from the NEWS file.

Changes in version 0.2.4 (2025-01-19)
  • Use Rcpp::RawVector instead of std::vector<unsigned char> saving extra copy (Travers in #16)
  • Several updates to README.md with R Journal paper, add badges, add Authors@R, add CITATION file, add repo info to DESCRIPTION
  • Update continuous integration via r-ci
  • Update to no longer require compilation standard

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the [issue tracker][issue tickets] at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

19 January 2025

Fran ois Marier: Blocking comment spammers on an Ikiwiki blog

Despite comments on my ikiwiki blog being fully moderated, spammers have been increasingly posting link spam comments on my blog. While I used to use the blogspam plugin, the underlying service was likely retired circa 2017 and its public repositories are all archived. It turns out that there is a relatively simple way to drastically reduce the amount of spam submitted to the moderation queue: ban the datacentre IP addresses that spammers are using.

Looking up AS numbers It all starts by looking at the IP address of a submitted comment: From there, we can look it up using whois:
$ whois -r 2a0b:7140:1:1:5054:ff:fe66:85c5
% This is the RIPE Database query service.
% The objects are in RPSL format.
%
% The RIPE Database is subject to Terms and Conditions.
% See https://docs.db.ripe.net/terms-conditions.html
% Note: this output has been filtered.
%       To receive output for a database update, use the "-B" flag.
% Information related to '2a0b:7140:1::/48'
% Abuse contact for '2a0b:7140:1::/48' is 'abuse@servinga.com'
inet6num:       2a0b:7140:1::/48
netname:        EE-SERVINGA-2022083002
descr:          servinga.com - Estonia
geoloc:         59.4424455 24.7442221
country:        EE
org:            ORG-SG262-RIPE
mnt-domains:    HANNASKE-MNT
admin-c:        CL8090-RIPE
tech-c:         CL8090-RIPE
status:         ASSIGNED
mnt-by:         MNT-SERVINGA
created:        2020-02-18T11:12:49Z
last-modified:  2024-12-04T12:07:26Z
source:         RIPE
% Information related to '2a0b:7140:1::/48AS207408'
route6:         2a0b:7140:1::/48
descr:          servinga.com - Estonia
origin:         AS207408
mnt-by:         MNT-SERVINGA
created:        2020-02-18T11:18:11Z
last-modified:  2024-12-11T23:09:19Z
source:         RIPE
% This query was served by the RIPE Database Query Service version 1.114 (SHETLAND)
The important bit here is this line:
origin:         AS207408
which referts to Autonomous System 207408, owned by a hosting company in Germany called Servinga.

Looking up IP blocks Autonomous Systems are essentially organizations to which IPv4 and IPv6 blocks have been allocated. These allocations can be looked up easily on the command line either using a third-party service:
$ curl -sL https://ip.guide/as207408   jq .routes.v4 >> servinga
$ curl -sL https://ip.guide/as207408   jq .routes.v6 >> servinga
or a local database downloaded from IPtoASN. This is what I ended up with in the case of Servinga:
[
  "45.11.183.0/24",
  "80.77.25.0/24",
  "194.76.227.0/24"
]
[
  "2a0b:7140:1::/48"
]

Preventing comment submission While I do want to eliminate this source of spam, I don't want to block these datacentre IP addresses outright since legitimate users could be using these servers as VPN endpoints or crawlers. I therefore added the following to my Apache config to restrict the CGI endpoint (used only for write operations such as commenting):
<Location /blog.cgi>
        Include /etc/apache2/spammers.include
        Options +ExecCGI
        AddHandler cgi-script .cgi
</Location>
and then put the following in /etc/apache2/spammers.include:
<RequireAll>
    Require all granted
    # https://ipinfo.io/AS207408
    Require not ip 46.11.183.0/24
    Require not ip 80.77.25.0/24
    Require not ip 194.76.227.0/24
    Require not ip 2a0b:7140:1::/48
</RequireAll>
Finally, I can restart the website and commit my changes:
$ apache2ctl configtest && systemctl restart apache2.service
$ git commit -a -m "Ban all IP blocks from Servinga"

Future improvements I will likely automate this process in the future, but at the moment my blog can go for a week without a single spam message (down from dozens every day). It's possible that I've already cut off the worst offenders. I have published the list I am currently using.

18 January 2025

Dominique Dumont: How we solved storage API throttling on our Azure Kubernetes clusters

Hi This issue was quite puzzling, so I m sharing how we investigated this issue. I hope it can be useful for you. My client informed me that he was no longer able to install new instances of his application. k9s showed that only some pods could not be created, only the ones that created physical volume (PV). The description of these pods showed a HTTP error 429 when creating pods: New PVC could not be created because we were throttled by Azure storage API. This issue was confirmed by Azure diagnostic console on Kubernetes ( menu Diagnose and solve problems Cluster and Control Plane Availability and Performance Azure Resource Request Throttling ). We had a lot of throttling:
2025-01-18_11-01-k8s-throttles.png
Which were explained by the high call rate:
2025-01-18_11-01-k8s-calls.png
The first clue was found at the bottom of Azure diagnostic page:
2025-01-18_11-27-throttles-by-user-agent.png
According, to this page, throttling is done by services whose user agent is:
Go/go1.23.1 (amd64-linux) go-autorest/v14.2.1 Azure-SDK-For-Go/v68.0.0
storage/2021-09-01microsoft.com/aks-operat azsdk-go-armcompute/v1.0.0 (go1.22.3; linux)
The main information is Azure-SDK-For-Go, which means the program making all these calls to storage API is written in Go. All our services are written in Typescript or Rust, so they are not suspect. That leaves controllers running in kube-systems namespace. I could not find anything suspects in the logs of these services. At that point I was convinced that a component in Kubernetes control plane was making all those calls. Unfortunately, AKS is managed by Microsoft and I don t have access to the control plane logs. However, we re realized that we had quite a lot of volumesnapshots that are created in our clusters using k8s-scheduled-volume-snapshotter: We suspected that kubernetes reconciliation loop is throttled when checking the status of all these snapshots. May be so, but we also had the same issues and throttle rates on preprod and prod were the number of snapshots were quite different. We tried to get more information using Azure console on our snapshot account, but it was also broken by the throttling issue. We were so puzzled that we decided to try L odagan s advice (tout cr mer pour repartir sur des bases saines, loosely translated as burn everything down to start from scratch ) and we destroyed piece by piece our dev cluster while checking if the throttling stopped. First, we removed all our applications, no change. Then, all ancillary components like rabbitmq, cert-manager were removed, no change. Then, we tried remove the namespace containing our applications. But, we faced another issue: Kubernetes was unable to remove the namespace because it could not destroy some PVC and volumesnapshots. That was actually good news, because it meant that we were close to the actual issue. We managed to destroy the PVC and volumesnapshots by removing their finalizers. Finalizers are some kind of markers that tell kubernetes that something needs to be done before actually deleting a resource. The finalizers were removed with a command like:
kubectl patch volumesnapshots $ volumesnapshot  \
  -p ' \"metadata\": \"finalizers\":null '  --type merge
Then, we got the first progress : the throttling and high call rate stopped on our dev cluster. To make sure that the snapshots were the issue, we re-installed the ancillary components and our applications. Everything was copacetic. So, the problem was indeed with PVC and snapshots. Even though we have backups outside of Azure, we weren t really thrilled at trying L odagan s method on our prod cluster So we looked for a better fix to try on our preprod cluster. Poking around in PVC and volumesnapshots, I finally found this error message in the description on a volumesnapshotcontents:
Code="ShareSnapshotCountExceeded" Message="The total number of snapshots
for the share is over the limit."
The number of snapshots found in our cluster was not that high. So I wanted to check the snapshots present in our storage account using Azure console, which was still broken. Fortunately, Azure CLI is able to retry HTTP calls when getting 429 errors. I managed to get a list of snapshots with
az storage share list --account-name [redacted] --include-snapshots \
      tee preprod-list.json
There, I found a lot of snapshots dating back from 2024. These were no longer managed by Kubernetes and should have been cleaned up. That was our smoking gun. I guess that we had a chain of events like: To make things worse, k8s-scheduled-volume-snapshotter creates new snapshots when it cannot list the old ones. So we had 4 new snapshots per day instead of one. Since we had the chain of events, fixing the issue was not too difficult (but quite long ):
  1. stop k8s-scheduled-volume-snapshotter by disabling its cron job
  2. delete all volumesnapshots and volume snapshots contents from k8s.
  3. since Azure API was throttled, we also had to remove their finalizers
  4. delete all snapshots from azure using az command and a Perl script (this step took several hours)
  5. re-enable k8s-scheduled-volume-snapshotter
After these steps, preprod was back to normal. I m now applying the same recipe on prod. We still don t know why we had all these stale snapshots. It may have been a human error or a bug in k8s-scheduled-volume-snapshotter. Anyway, to avoid this problem is the future, we will: My name is Dominique Dumont, I m a devops freelance. You can find the devops and audit services I propose on my website or reach out to me on LinkedIn. All the best

16 January 2025

Sergio Talens-Oliag: Command line tools to process templates

I ve always been a fan of template engines that work with text files, mainly to work with static site generators, but also to generate code, configuration files, and other text-based files. For my own web projects I used to go with Jinja2, as all my projects were written in Python, while for static web sites I used the template engines included with the tools I was using, i.e. Liquid with Jekyll and Go Templates (based on the text/template and the html/template go packages) for Hugo. When I needed to generate code snippets or configuration files from shell scripts I used to go with sed and/or envsubst, but lately things got complicated and I started to use a command line application called tmpl that uses the Go Template Language with functions from the Sprig library.

tmplI ve been using my fork of the tmpl program to process templates on CI/CD pipelines (gitlab-ci) to generate configuration files and code snippets because it uses the same syntax used by helm (easier to use by other DevOps already familiar with the format) and the binary is small and can be easily included into the docker images used by the pipeline jobs. One interesting feature of the tmpl tool is that it can read values from command line arguments and from multiple files in different formats (YAML, JSON, TOML, etc) and merge them into a single object that can be used to render the templates. There are alternatives to the tmpl tool and I ve looked at them (i.e. simple ones like go-template-cli or complex ones like gomplate), but I haven t found one that fits my needs. For my next project I plan to evaluate a move to a different tool or template format, as tmpl is not being actively maintained (as I said, I m using my own fork) and it is not included on existing GNU/Linux distributions (I packaged it for Debian and Alpine, but I don t want to maintain something like that without an active community and I m not interested in being the upstream myself, as I m trying to move to Rust instead of Go as the compiled programming language for my projects).

Mini JinjaLooking for alternate tools to process templates on the command line I found the minijinja rust crate, a minimal implementation of the Jinja2 template engine that also includes a small command line utility (minijinja-cli) and I believe I ll give it a try on the future for various reasons:
  • I m already familiar with the Jinja2 syntax and it is widely used on the industry.
  • On my code I can use the original Jinja2 module for Python projects and MiniJinja for Rust programs.
  • The included command line utility is small and easy to use, and the binaries distributed by the project are good enough to add them to the docker container images used by CI/CD pipelines.
  • As I want to move to Rust I can try to add functionalities to the existing command line client or create my own version of it if they are needed (don t think so, but who knows).

15 January 2025

Dirk Eddelbuettel: RcppFastFloat 0.0.5 on CRAN: New Upstream, Updates

A new minor release of RcppFastFloat just arrived on CRAN. The package wraps fast_float, another nice library by Daniel Lemire. For details, see the arXiv preprint or published paper showing that one can convert character representations of numbers into floating point at rates at or exceeding one gigabyte per second. This release updates the underlying fast_float library version to the current version 7.0.0, and updates a few packaging aspects.

Changes in version 0.0.5 (2025-01-15)
  • No longer set a compilation standard
  • Updates to continuous integration, badges, URLs, DESCRIPTION
  • Update to fast_float 7.0.0
  • Per CRAN Policy comment-out compiler 'diagnostic ignore' instances

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the [issue tracker][issue tickets] at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

14 January 2025

Dirk Eddelbuettel: RProtoBuf 0.4.23 on CRAN: Mulitple Updates

A new maintenance release 0.4.23 of RProtoBuf arrived on CRAN earlier today, about one year after the previous update. RProtoBuf provides R with bindings for the Google Protocol Buffers ( ProtoBuf ) data encoding and serialization library used and released by Google, and deployed very widely in numerous projects as a language and operating-system agnostic protocol. This release brings a number of contributed PRs which are truly appreciate. As the package dates back fifteen+ years, some code corners can be crufty which was addressed in several PRs, as were two updates for ongoing changes / new releases of ProtoBuf itself. I also made the usual changes one does to continuous integrations, README badges and URL as well as correcting one issue the checkbashism script complained about. The following section from the NEWS.Rd file has full details.

Changes in RProtoBuf version 0.4.23 (2022-12-13)
  • More robust tests using toTextFormat() (Xufei Tan in #99 addressing #98)
  • Various standard packaging updates to CI and badges (Dirk)
  • Improvements to string construction in error messages (Michael Chirico in #102 and #103)
  • Accommodate ProtoBuf 26.x and later (Matteo Gianella in #104)
  • Accommodate ProtoBuf 6.30.9 and later (Lev Kandel in #106)
  • Correct bashism issues in configure.ac (Dirk)

Thanks to my CRANberries, there is a diff to the previous release. The RProtoBuf page has copies of the (older) package vignette, the quick overview vignette, and the pre-print of our JSS paper. Questions, comments etc should go to the GitHub issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

13 January 2025

Kentaro Hayashi: Stick to boot from 6.11 linux-image

Since Dec 2024, there is a compatibility issue with linux-image 6.12 and nvidia-driver 535.216.03. #1089513 - nvidia-driver: crash in drm_open_helper on Linux 6.12.3 - Debian Bug report logs It seems that the upstream was already fixed this issue in newer release, but not available yet on Debian sid. If you keep installed linux-image-amd64 or linux-headers-amd64, it will be booted from 6.12 by default. Surely it will boot, but it still has the resolution issue. It can't be your daily driver. Thus workaround is sticking to boot from 6.11 linux-image. As usually older image was listed in "Advanced options for ..." submenu, you need to explicitly choose 6.11 image during booting. In such a case, the changing default boot image is useful. (another option is just purge all 6.12 linux-image, linux-image-amd64 and linux-headers-amd64, but it's out of scope in this article) See /boot/grub/grub.cfg and collect each menuentry_id_option. You need to collect the following menuentry id. Then, edit GRUB_DEFAULT entry in /etc/default/grub. GRUB_DEFAULT should be combination with [1] and [2] which is concatenated with ">" e.g. NOTE: the actual value might vary on your environment
GRUB_DEFAULT="gnulinux-advanced-2e0e7dd0-7e10-4b58-92f7-518dabb5b547>gnulinux-6.11.10-amd64-advanced-2e0e7dd0-7e10-4b58-92f7-518dabb5b547"
After that, update grub entry with sudo update-grub. /boot/grub/grub.cfg will be updated correctly.

Next.

Previous.