For a while I have been eyeing with the TI eZ430 Chronos watch, a slightly bulky sports watch that not only comes with a built-in thermometer, barometer and accelerometer, but also a freely programmable micro controller (from the TI MSP430 family hence the name). In addition it has a small radio chip included and can communicate wirelessly with the computer, or possibly other devices. All in all, a very geeky toy.
A week ago I managed to buy one quite cheaply via eBay (30 including shipping). It took me a while to get an overview of the various resources about the device. Here is what I have learned.
Hardware: I have the new edition (the included debug board and wireless access point are white). This means that I cannot update the software of the watch via the wireless connection, and it means that most software written for it does not support the new altimeter sensor (yet).
Development: Debian is a very suitable development platform; the packages mspdebug and gcc-msp430 provide all I need to compile (make config && make) and upload (mspdebug rf2500 "prog ../foo.txt") new software.
Code: Besides the original software that comes with the device (which supports the new hardware), there are two main lines of community-driven developments: OpenChronos and openchronos-ng. The former is (as the name suggests) older and maintained mostly by forks in variousplaces. The latter is newer, its UI deviates further from the original software and seems to be slightly more active.
Communication: Both of these have their own mailinglists (openchronos, where I did not get a reply yet, and ti-chronos-development, where my messages are still waiting for moderation). I found only one IRC channel, #openchronos on freenode, with similarly little activity.
After I found that out, I tried to hack a bit on the various software. The first issue I had (and still have) is that I cannot use the buttons of the device while it is attached to the debug board. They do work if forget to take out the battery, but supposedly that is bad for the battery. So my compile-upload-test-cycle becomes a compile-upload-detach-insert-battery-test-remove-battery-attach-cycle. I could not find out how to emulate button presses using mspdebug. Any suggestions are welcome.
The other problem was the new altimeter hardware: Neither OpenChronos nor openchronos-ng support that yet. I originally planned to port the driver from the official software to a random OpenChronos fork when I read that Richard Rondu did that to openchronos-ng yet. I found the code in a month-old merge-request.
I tried it, it worked, and I started to clean up the code a bit and add a variometer mode to it, e.g. displaying the current rate of climb my ultimate goal is to use this as a surprisingly cheap variometer for paragliding. After a day of hacking and quickly lifting the watch from the room floor to the room ceiling and back I believe that it works okish, although quite a few parameter can benefit from more tweaking: sample rate (currently 20Hz), length of history (currently 2s) and the linear regression method (currently simply the difference between the average of the samples of the current second with the samples of the last second). As always, patches welcome, the code is in my fork on sf.net.
Next to do would be to enable some buzzing noise depending on the rate of change; during flight I don t want to decipher a low-contract LCD screen. But it is questionable whether the buzzer is loud enough we ll see. I was also happy to hear that there are other zE430-hackers in Karlsruhe, one of them for example tries to make the alarm clock sleep-cycle-aware.
Here in the US, the Affordable Care Act is finally going into effect, with
accompanying drama. I managed to get signed up today at healthcare.gov.
After not having health insurance since 2000, I will finally be covered
starting January 1 2014.
Since my income is mosty publically known
anyway, I thought it might be helpful to blog about some details.
I was uninsured for 14 years due to a combination of three factors:
Initially, youthful stupidity and/or a perfectly resonable cost/benefit
analysis. (Take your pick.)
Due to the US health insurance system being obviously broken,
and my preference to avoid things that are broken. Especially when
the breakage involved insurers refusing to cover me at any sane level
due to a minor and easily controlled pre-existing condition.
Since I'm not much motivated by income levels, and am very motivated to
have time to work on things that are important to me, my income has
been on average pretty low, and perhaps more importantly, I have
intentionally avoided being a full-time employee of anyone
at any point in the past 14 years (have rejected job offers), and
so was not eligible for any employee plans which were the only
reasonable way to be covered in the US. (See point #2.)
So, if you're stuck waiting in line on healthcare.gov (is this an entirely new
online experience brought to us by the US government?), or have seen any of
the dozen or so failure modes that I saw just trying to register for a
login to the site, yeah, it's massively overloaded right now, and it's also
quite broken on a number of technical levels. But you can eventually get
though it.
Based on some of the bugs I saw, it may help to have an large number of
email addresses and use a different one for each application attempt. It
also wouldn't hurt to write some programs to automate the attempts, because
otherwise you may have to fill out the same form dozens of times. And no,
you can't use "you+foo@bar.com" for your email; despite funding the
development of RFC-822 in the 80's, the US government is clueless about
what consititutes a valid email address.
But my "favorite" misfeature of the site is that it refuses to let you enter
any accented characters, or characters not in the latin alphabet when
signing up. Even if they're, you know, part of your name. (Welcome back
to Ellis Island..) I want to check the
git repository to see if I
can find the backstory for these and other interesting technical
decisions, but they have forgotten to push anything to it for over 3
months.
The good news is that once you get past the initial signup process, and
assuming you get the confirmation mail before the really short expiration
period of apparently less than 1 hour (another interesting technical
choice, given things like greylisting), the actual exchange is not badly
overloaded, and nor is it very buggy (comparatively). I was able to
complete an application in about an hour.
The irony is that after all that, I was only able to choose from one
health insurer covering my area on the so-called "exchange". (Blue
Cross/Blue Shield) I also signed up for dental insurance (it was a welcome
surprise that the site offers this at all) and had a choice of two insurers
for that.
The application process was made more uncertian for me since I have no
idea what I'll end up doing for money once my current
crowdsourced year of work is done. The site
wants you to know how much income you'll have in 2014, and my guess is
anywhere between $6000 (from a rental property) and about what I made
this year (approx $25000 before taxes). Or up, if I say, answered the
Google pings. The best choice seemed to be to answer what I made this year,
which is also close to what I made last year.
So, I'll be paying around $200/month for a combination of not very good
health insurance, and not very good dental insurance. There is around
$750/year of financial aid to people at my guesstimated 2014 income level,
which would drop that to $140/month, but I will let them refund me whatever
that turns out to be in a lump sum later instead.
For comparison, I am lucky to spend rather less renting a three bedroom
house situated in 25 acres of woods..
It's strange to think that all of this is an improvement to the system here in
the US, especially given all the better options that could have been passed
instead, but it seems that it probably is. Especially when I consider the
many people around me who are less fortunate than myself. If you'd like a
broader perspective on this, see Tobias Buckell's
"American healthcare was already socialized by Reagan, we re just fighting about how to pay for it".
XMir's been delayed from Ubuntu 13.10. The stated reason is that multi-monitor support isn't sufficiently reliable. That's true, but it's far from the only problem that XMir still has:
It's still broken on some single-monitor systems
Some machines have display corruption. There are writes to freed memory. To be fair, some of the behaviour that's been seen has been down to underlying bugs in the Xorg drivers that were never triggered under normal use but are hit by XMir. Others are down to implicit assumptions made in the drivers that XMir happens to violate. The problem is that there doesn't appear to have been enough room in the schedule to deal with these interactions, presumably because nobody accounted for the inevitable "This thing we thought would be easy turns out to be difficult" part of the project.
The input driver bug still isn't really fixed
I've mentioned this bug before. It's now marked "Fix released" which is kind of true but not really. Mir now tells XMir that the VT is changing before the VT is changed, but it doesn't wait for that to complete before switching the VTs. Until XMir is scheduled and runs, it's still receiving input events. In most circumstances that window is small, so there's no real risk of triggering it accidentally.
There's one corner case where it might still cause problems. Simply running isn't enough - XMir has to make progress through its event loop. That'll only happen if the X server is processing its wakeup events, and it's possible to effectively stall that by submitting a sufficiently awkward drawing request to the server. The X server will appear to freeze, and if the user then attempts to work out what's going on by switching to a VT and logging in, those input events will still be going to XMir. It's left as an exercise to the reader to construct ways to take advantage of this.
This can't happen in Xorg because the VT switch is blocked until the input devices have been released. Mir could have done the same, but doesn't because of a conscious design decision - in the Ubuntu Phone world, clients stop doing things when they're told to. Ubuntu Desktop is expected to behave the same way.
This is an unfortunate situation to be in. Ubuntu Desktop was told that they were switching to XMir, but Mir development seems to be driven primarily by the needs of Ubuntu Phone. XMir has to do things that no other Mir client will ever cope with, and unless Mir development takes that into account it's inevitably going to suffer breakage like this. Canonical management needs to resolve this if there's any hope of ever shipping XMir as the default desktop environment.
It's still missing features
XMir doesn't support colour profiles. XRandR properties aren't exposed, so there's no way to control TV output encoding or overscan. There's still no hardware cursor support. Switching to XMir now would reduce functionality without providing any user-visible gain.
It's clear that XMir has turned into a larger project than Canonical had originally anticipated, but that's hardly surprising. There's only one developer with previous X experience working on it full-time, and the announced schedule provided no opportunity to deal with unexpected problems. As if that weren't enough, there's obvious conflict between Ubuntu Desktop and Ubuntu Phone when it comes to developer time and required functionality. The one hardware vendor who's willing to take a public stand has demonstrated that they have no interest in supporting XMir, despite Canonical assuring people that they were already engaging in productive negotiations with GPU manufacturers.
Multiple monitor support may be the single most obvious feature where XMir is lacking, but it's not the only one. Technically and politically, this code is a long way from being ready for prime time. Without significant community contribution, Canonical need to focus on prioritising it appropriately rather than expecting a tiny number of developers to perform miracles. Or, alternatively, they could just drop XMir entirely and focus on Unity 8.
Download links often point to CGI scripts which actually generate (or
just fetch, i.e. proxy) the actual file to be downloaded, e.g. URLs
like http://www.example.com/download.cgi?file=foobar.txt.
Most of such CGI scripts send the real file name in the Content-Disposition header as specified
in the MIME Specification.
All browsers I know (well, at least those I use regularily :-) handle
that perfectly and propose the file name sent in the
Content-Disposition header as file name for saving the downloaded name
which is usually exactly what I want.
All browsers do that, , just not my favourite commandline
download tool GNU Wget Downloading the above URL with wget would look
like this with default settings:
Meh!
But luckily Wget can do that, it s just not enabled by default
because it s an experimental and possibly buggy feature, at least
according to the man page. Well, works for me! :-)
You can easily enabled it by default for either your user or the whole
system by placing the following line in your ~/.wgetrc or /etc/wgetrc:
content-disposition = on
Given the CGI script sends an appropriate Content-Disposition header,
the above output now looks like this:
Now Wget does what I mean!
You can also set this as flag on the commandline, but typing
wget --content-disposition everytime is surely
not what I want. ;-)
As a user of a shell you have most likely had the need to export a variable to another process; i.e. set/modify an environment variable.
Now, how do you stop exporting an environment variable? can you export anything else?
The bash shell offers the -n option of the export built-in, claiming it "remove[s] the export property". However, this feature is not part of the POSIX:2001 standard and is, therefore, a bashism.
A portable way to stop exporting an environment variable is to unset it. E.g. the effect of "export MY_VAR=foo" can be reverted by calling "unset MY_VAR" - surely enough, this will also destroy the content of the variable.
An equivalent could then be:
# to stop exporting/"unexport" the MY_VAR environment variable:
my_var="$MY_VAR" ; unset MY_VAR ;
MY_VAR="$my_var" ; unset my_var ;
The above code will make a copy of the variable before destroying it and then restoring its content.
How about exporting other things? did you know that you can export shell functions?
With the bash shell, you can export a function with the -f parameter of the export built-in. Needless to say, this is a bashism. Its secret? it's just an environment variable with the name of the function and the rest of the function definition as its value.
Try this:
$ echo="()   /bin/echo 'have some bash' ;  " bash -c 'echo "Hello World!"'
have some bash
Yes, this means that if you can control the content of an environment variable passed to bash you can probably execute whatever code you want. It comes handy when you want to alter a script's behaviour without modifying the script itself.
This week's lesson on the Arte y cultura en circulaci n: crear y compartir en tiempos digitales course talks about piracy and the circulation of culture, a topic that over time has been debated over and over. And a topic, yes, that can always lead to interesting discussions.
This time, we are requested to choose one among ten ideas among the media groups' discourse on what piracy is and means for the "cultural industry". There are tons of material written already on several of those ten lines (i.e. piracy disincentivates creativity, or two that can be seen as two faces of the same argument, If a consumer can have free access to cultural products, he will stop spending his money on them and Every time a consumer has access to an illegal copy, the industry loses a sale), and some are quite obvious (i.e. Piracy makes job positions be lost... Just look at the amount of people the unauthorized distribution industry feeds! Or possibly, Piracy is a prosper industry that gives money to people distributing illegal products Of course, that is true. The problem is, what causes said products to be illegal to begin with? Should they be so?). Some other ideas talk about harsher penalties and ways to punish illegal copying in order to drive actors out of that sector (and into the... void?)
So, I chose item #4: Cultural products have a high cost because their production is complex (and a tag could be made, linking complex with expensive). I think this item can lead to a long discussion as to what does this complexity and cost mean.
Some cultural products do require quite a bit of investment, yes. Others don't. How do content producers make the jump to produce expensive works?
If I am a new programmer/artist/writer/screenplayer/whatever, most likely, my products will be not very complex or expensive. I will start small. And if I excel at my work, somebody will look at me and, in some way, become my patron, my sponsor. Being a sponsor might mean that, based on the results of my good work, I could get hired as a software developer at a large company, or an editorial company would buy the patrimonial rights of my book/music (be it for a fixed fee or for a percentage of sales), or whatever. But the leap is not made quantically A newcomer to the cultural scene will at first, most likely, have a hard time selling his products.
At first, it takes convincing just getting people to take a shot at looking at your work ( Hey, please take a look at my program and tell me what you think about it! , Would you be interested in listening to my latest song? And those two are by far ahead of the first attempts where the interactions would more likely be Turn off that $#^#!^ computer, it's well past bedtime or stop murdering that guitar, I'm having a headache ). Maybe the toughest part is to get people to agree to read/hear your work. And there, you start into a continuum Selling your CDs while performing on the street, then getting to play to a bar, then getting somebody to want to produce (maybe even "discover"!) you. Publish some short stories in your school magazine, then in a "From our audience" section in a larger magazine, then a collective book, your self-published book, yet-unwritten books by contract... The same story over and over again, in each different field.
Ok, yes, but... This logic succession still leaves space for the Important Producers with the Mighty Big Pockets for the most wanted/largest productions, right? And were unauthorized distribution (piracy) to be the norm (as it currently is, dare I say), wouldn't they stop producing an important portion of cultural works?
I'd be tempted to say so. However, a different actor comes into play. When Mighty Big Pockets comes into play, they no longer worry only about getting money from each cultural creation, but from all derived uses of it. And the cultural creation industry (when seen as an industry) goes very much hand in hand with the advertising, marketing industries They end up blending with each other.
So, the biggest best sellers will most likely have a hit from illegal copiers. Books are still a great business, but hey An even better business is (usually) movie making. And when you make a movie out of a great story, you will surely link some advertising into it (or at the very least, push advertising/product pushing campaigns to go after it). And there, illegal distribution actually helps the money circle to grow stronger. In the early 1990s, the link between dinosaurs and carbonated drinks was a top seller (because Pepsi was a Jurassic Park sponsor). Although I have always loathed the madness around the World Cups (and basically anything that involves football of any kind), I can perfectly remember several of the theme songs for most of the world cups played during my lifetime.
So, in short... No. Illegal distribution does marginally little harm to the money income to the cultural business, at any level. And where it does get some direct harm, it increases the money flux given the auxiliary channels.
After 1.5 month of work, I am proud to officialy release OUnit 2.0.0. This is a major rewrite of OUnit to include various feature that I think was missing from OUnit1. The very good news is that the port of the OASIS test suite has proven that this new version of OUnit can drastically improve the running time of a test suite.
OUnit is a unit test framework for OCaml. It allows one to easily create unit-tests for OCaml code. It is based on HUnit, a unit testing framework for Haskell. It is similar to JUnit, and other XUnit testing frameworks.
Download OUnit v2.0.0Documentation of v2.0.0Website
The basic features:
better configuration setup
environment variable
command line options
configuration files
improved output of the tests:
allow vim quickfix to jump in the log file where the error has happened
output HTML report
output JUnit report
systematic logging (verbose always on), but output log in a file
choose how to run your test:
run tests in parallel using processes (auto-detect number of CPU and run as many worker processes)
run tests concurrently using threads
use the old sequential runner
choose which test to run with a chooser that can do smart selection of tests:
simple: just run test in sequence
failfirst: run the tests that failed in the last run first and skip the success if they are still failing
some refactoring:
bracket: use a registration in the context but easier to use
remove all useless functions in the OUnit2 interface
non-fatal section: allow to fail inside non-fatal section without quitting immediately the whole test
allow to use OUnit1 test inside OUnit2 (smooth the transition)
timer that makes tests fail if they take too long, only when using the processes runner (I was not able to do it cleanly using threads and sequential)
allow to parametrize filenames so that you can use OUNIT_OUTPUT_FILE=ounit-$(suite_name),log and have $(suite_name) replace by the test suite name
create locks to avoid accessing the same resources within a single process or the whole application (typically to avoid doing a chdir while another thread is doing a chdir elsewhere)
create a in_testdata_dir function to locate test data, if any
Migration path
OUnit 2.0.0 still provides the OUnit module which is exactly the same as the last OUnit 1.X version. This way, you are not forced to migrate. However, this means that you will gain no advantage of the new release and even some slowdown due to increase complexity of the code. Though, I strongly recommend to upgrade to OUnit2.
Here is a checklist to do the migration:
replace all open OUnit by open OUnit2
the test function now takes test_ctxt argument, so replace all fun () -> ...) by fun test_ctxt -> ...
bracket are now inlined so bracket setUp f tearDown is now let x = bracket setUp tearDown test_ctxt in
make sure that you don't change global process state like chdir or Unix.putenv or that you don't rely on another test setting something for the next test
The OASIS test suite migration
In order to check that everything was working correctly, I have migrated the OASIS test suite to OUnit2. This is a big test suite (210 test cases) and it includes quite big sequences of tests (end to end tests from calling oasis setup to compiling and installing the results). This was really time consuming and I wish to see a significant speedup for the tests with OUnit2.
You can see the result in term of code of the full migration here.
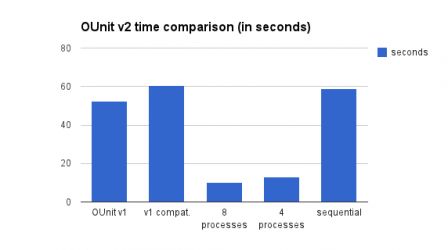
Here are the results on my Intel Core i7 920/SSD:
oUnit1 over oUnit2: 60.39s (OUnit v2.0.0 using the OUnit v1 layer)
Migration to OUnit2 (166 tests):
processes (8 shards): 10.12s
processes (autodect, 4 shards): 12.99s
sequential: 58.77s
The migration was quite heavy because this test suite had a big design problem. It uses in-place modification of the test data. I think I pick this design because I thought this was a good idea to decrease the running time. As a matter of fact, this was a huge mistake, that keeps popping failed test cases because one of the previous tests was failing. I have refactored all this and now we start by copying the test data into a temporary directory, which ensure that everything is always starting from pristine test data.
During the redesign, I have decided to reduce the number of tests by merging some of them. This should have no big impact on the running time, although this is not as pure 1:1 comparison with OUnit v1. Although it is still testing exactly the same thing. This explain the loss of ~50 tests, which in fact has been merged in other tests.
The overall speedup is 4x compared to OUnit v1, when using processes. However there is a 12% increase compared to OUnit v1 for sequential and a 15% increase when using OUnit v1 compatibility layer. While this is not very good score, I hope this is small enough to compensate the huge win of being able to run tests in parallel with processes.
And now the magic !
At this point, if you read carefully the numbers, you would have noticed that there is a 4.5x decrease in speed when you compare sequential and 4 processes for OUnit2. Since we are only actively testing in 4 shards, it looks strange. I don't expect a super-linear speedup due to the use of processes. I have checked that every tests was indeed running and found no solutions to this mystery. Right now, I think this is due to the fact that we are running less tests in more processes which should lighten the load of the GC (which may not trigger at all). I am not sure about this explanation and will welcome any bug report which shows a problem in the implementation of either sequential or processes runner. Although, this is great.
Help still wanted
If you find any bugs with OUnit v2, this is the time to submit a bug.
OUnit BTS
If you want to try to fix bugs by yourself, please checkout the latest version of OUnit:
$> darcs get http://forge.ocamlcore.org/anonscm/darcs/ounit/ounit
A new version of Rcpp is now
on the CRAN network for
GNU R;
binaries for Debian have been uploaded
as well.
Once more, this release brings a large number of exciting changes to
Rcpp. Some concern
usability, some bring new features, some increase performance; see
below for the detailed list. We have now released three updates on a
quarterly cycle; if we keep this up the next version ought to be ready at the
end of December.
As in the past, we tested the release rather rigorously by checking against all
packages I could (relatively easily) built on my server: this time it
successfully passed \code R CMD check for all 107 packages I can build
locally out of a total of 136 packages. (Two failed: one for an error in
\code Makevars , and one for the need of an X11 server during tests; this may
get addressed in the in test script next time). As all of these 107 packages
passed, we do not expect any issues with dependent packages. Should
there be issues we would appreciate a note, preferably with reproducible
code, to the
rcpp-devel
mailing list.
The complete NEWS
entry for 0.10.4 is below; more details are in the ChangeLog file in the package and on the
Rcpp Changelog page.
Changes in Rcpp version 0.10.5 (2013-09-28)
Changes in R code:
New R function demangle that calls the DEMANGLE macro.
New R function sizeof to query the byte size of a
type. This returns an object of S3 class bytes that has a print method showing bytes and bits.
Changes in Rcpp API:
Add defined(__sun) to lists of operating systems to test for when checking for lack of backtrace() needed for stack traces.
as<T*>, as<const T*>, as<T&>
and as<const T&> are now supported, when T is a class exposed by modules, i.e. with RCPP_EXPOSED_CLASS
DoubleVector as been added as an alias to NumericVector
New template function is<T> to identify if an R object
can be seen as a T. For example is<DataFrame>(x).
This is a building block for more expressive dispatch in various places
(modules and attributes functions).
wrap can now handle more types, i.e. types that iterate over
std::pair<const KEY, VALUE> where KEY can be converted to a
String and VALUE is either a primitive type (int, double)
or a type that wraps. Examples :
std::map<int, double> : we can make a String from an int, and double is primitive
boost::unordered_map<double, std::vector<double> >: we can make
a String from a double and std::vector<double> can wrap itself
Other examples of this are included at the end of the wrap unit test
file (runit.wrap.R and wrap.cpp).
wrap now handles containers of classes handled by modules. e.g. if you expose a class Foo via modules, then you can wrap
vector<Foo>, ... An example is included in the wrap unit test file.
RcppLdFlags(), often used in Makevars files of
packages using Rcpp, is now exported from the package namespace.
Changes in Attributes:
Objects exported by a module (i.e. by a RCPP_MODULE call
in a file that is processed by sourceCpp) are now directly
available in the environment. We used to make the module object
available, which was less useful.
A plugin for openmp has been added to support use of OpenMP.
Rcpp::export now takes advantage of the more flexible
as<>, handling constness and referenceness of the input types.
For users, it means that for the parameters of function exported by modules,
we can now use references, pointers and const versions of them.
The file Module.cpp file has an example.
No longer call non-exported functions from the tools package
No longer search the inline package as a fallback when loading plugins for the the Rcpp::plugins attribute.
Changes in Modules:
We can now expose functions and methods that take
T& or const T& as arguments. In these situations
objects are no longer copied as they used to be.
Changes in sugar:
is_na supports classes DatetimeVector and DateVector
Changes in Rcpp documentation:
The vignettes have been moved from inst/doc/ to the vignettes directory which is now preferred.
The appearance of the vignettes has been refreshed by switching to the Bistream Charter font, and microtype package.
Deprecation of RCPP_FUNCTION_*:
The macros from the preprocessor_generated.h file
have been deprecated. They are still available, but they print a message in addition to their expected behavior.
The macros will be permanently removed in the first Rcpp release after July 2014.
Users of these macros should start replacing them with more up-to-date code, such as using 'Rcpp attributes' or 'Rcpp modules'.
"Big Data" has been hyped a lot, and due to this now is burning down to
get some reality checking. It's been already overdue, but it is now happening.
I have seen a lot of people be very excited about NoSQL databases; and
these databases do have their use cases. However, you just cannot put
everything into NoSQL mode and expect it to just work. That is why we have
recently seen NewSQL databases, query languages for NoSQL databases etc. -
and in fact, they all move towards relational database management again.
Sound new database systems seem to be mostly made up of three aspects:
in-memory optimization instead of optimizing for on-disk operation (memory just
has become a lot cheaper the last 10 years), the execution of queries on the
servers that store the actual data (you may want to call this "stored
procedures" if you like SQL, or "map-reduce" if you like buzzwords), and
optimized memory layouts (many of the benefits of "colum store" databases
come from having a single, often primitive, datatype for the full column to
scan, instead of alternating datatypes in records.
However, here is one point you need to consider: is your data actually
this "big"? Big as in: Google scale.
I see people use big data and Hadoop a lot when they just
shouldn't. I see a lot of people run Hadoop in a VM on their
laptop. Ouch.
The big data technologies are not a one-size-fits-all solution. They are
the supersize-me solution, and supersize just does not fit every task.
When you look at the cases where Hadoop is really successful, it is mostly
in keeping the original raw data, and enabling people to re-scan the
full data again when e.g. their requirements changed. This is where Hadoop
is really good at: managing 100 TB of data, and allowing you to quickly filter
out the few GB that you really need for your current task.
For the actual analysis - or when you don't have 100 TB, and a large
cluster anyway - then just don't try to hadoopify everything.
Here is a raw number from a current experiment. I have a student work
on indexing image data; he is implementing some state of the art techniques.
For these, a large number of image features are extracted, and then clustering
is used to find "typical" features to improve image search.
The benchmarking image set is 56 GB (I have others with 2 TB
to use next). The subset the student is currently processing is 13 GB.
Extracting 2.3 million 128 dimensional feature vectors reduces this to about
1.4 GB. As you can see, the numbers drop quickly.
State of the art seems to be to load the data into Hadoop, and run
clustering (actually, this is more of a vector quantization than clustering)
into 1000 groups. Mahout is the obvious candidate to run this on Hadoop.
However, as I've put a lot of effort into the data mining software
ELKI, I considered also to try
processing it in ELKI.
By cutting the data into 10 MB blocks, Mahout/Hadoop can run the
clustering in 52x parallel mappers. k-Means is an iterative algorithm, so it
needs multiple processes. I have fixed the number of iterations to 10, which
should produce a good enough approximation for my use cases.
K-means is embarrassingly parallel, so one would expect the cluster to really shine
at this task. Well, here are some numbers:
Mahout k-Means took 51 minutes on average per iteration
(The raw numbers are 38:24, 62:29, 46:21, 56:20, 52:15, 45:11, 57:12, 44:58,
52:01, 50:26, so you can see there is a surpisingly high amount of variance
there).
ELKI k-Means on a single CPU core took 4 minutes 25 seconds
per iteration, and 45 minutes total, including parsing the input
data from an ascii file. Maybe I will try a parallel implementation next.
So what is happening? Why is ELKI beating Mahout by a factor of 10x?
It's (as always) a mixture of a number of things:
ELKI is quite well optimized. The Java Hotspot VM does a good job at
optimizing this code, and I have seen it to be on par with R's k-means, which
is written in C. I'm not sure if Mahout has received a similar amount of
optimization yet. (In fact, 15% of the Mahout runtime was garbage
collection runtime - indicating that it creates too many objects.)
ELKI can use the data in a uniform way, similar to a column store database.
It's literally crunching the raw double[] arrays. Mahout on the
other hand - as far as I can tell - is getting the data from a sequence file,
which then is deserialized into a complex object. In addition to the actual
data, it might be expecting sparse and dense vectors mixed etc.
Size: this data set fits well into memory. Once this no longer holds,
ELKI will no longer be an option. Then MapReduce/Hadoop/Mahout wins.
In particular, such an implementation will by design not keep the
whole data set in memory, but need to de-serialize it from disk again on
each iteration. This is overhead, but saves memory.
Design: MapReduce is designed for huge clusters, where you must expect
nodes to crash during your computation. Well, chances are that my computer
will survive 45 minutes, so I do not need this for this data size. However,
when you really have large data, and need multiple hours on 1000
nodes to process it, then this becomes important to survive losing
a node. The cost is that all interim results are written to the distributed
filesystem. This extra I/O comes, again, at a cost.
Let me emphasize this: I'm not saying, Hadoop/Mahout is bad. I'm
saying: this data set is not big enough to make Mahout beneficial.
Conclusions: As long as your data fits into your main memory and
takes just a few hours to compute, don't go for Hadoop.
It will likely be faster on a single node by avoiding the overhead
associated with (current) distributed implementations.
Sometimes, it may also be a solution to use the cluster only for preparing
the data, then get it to a powerful workstation, and analyze it there. We did
do this with the images: for extracting the image features, we used a
distributed implementation (not on Hadoop, but on a dozen PCs).
I'm not saying it will stay that way. I have plans for starting
"Project HELKI", aka "ELKI on Hadoop". Because I do sometimes hit the
barrier of what I can compute on my 8 core CPU in an "reasonable" amount
of time. And of course, Mahout will improve over time, and hopefully lose
some of its "Java boxing" weight.
But before trying to run everything on a cluster, always try to run it
on a single node first. You can still figure out how to scale up later, once
you really know what you need.
And last but not least, consider whether scaling up really makes sense.
K-means results don't really get better with a larger data set. They are
averages, and adding more data will likely only change the last few
digits. Now if you have an implementation that doesn't pay attention to
numerical issues, you might end up with more numerical error than you gained
from that extra data.
In fact, k-means can effectively be accelerated by processing a sample
first, and only refining this on the full data set then. And:
sampling is the most important "big data" approach. In particular when
using statistical methods, consider whether more data can really be expected to
improve your quality.
Better algorithms: K-means is a very crude heuristic. It optimizes the sum
of squared deviations, which may be not too meaningful for your problem. It is
not very noise tolerant, either. And there are thousands of variants. For
example bisecting k-means, which no longer is embarrassingly parallel (i.e.
it is not as easy to implement on MapReduce), but took just 7 minutes doing
20 iterations for each split. The algorithm can be summarized as starting with
k=2, then always splitting the largest cluster in two until you have the
desired k. For many use cases, this result will be just as good as the full
k-means result.
Don't get me wrong. There are true big data problems. Web scale search,
for example. Or product and friend recommendations at Facebook scale.
But chances are that you don't have this amount of data.
Google probably doesn't employ k-means at that scale either.
(actually, Google runs k-means on 5 mio keypoints for vector quantization;
which, judging my experience here, can still be done one a single host; in
particular with hierarchical approaches such as bisecting k-means)
Don't choose the wrong tool for the wrong problem!
Just saw this ad today at my Institute's door. Rough translation:
Interim programmer sought
Requisites:
High school
One year of experience
Theorical and practical exams on the area
Familiarity handling electronic equipment, such as computers, perforators/punchers, terminals and similar.
[Yes, this is a joke post. I don't know how anybody is using such an obsolete job description. A job description at least three decades out of date]
[Well, yes, I understand it, because I knowhow that particular union works. But I cannot accept it is for real]
[...And no, please don't apply for the job. You will be miserable in the unlikely event you are chosen]
Continuing last month progress report onOUnit2. The release is just a few days away, I am testing real life application and the core of the work is already in the VCS.
The basic features:
better configuration setup
environment variable
command line options
configuration files
improved output of the tests:
allow vim quickfix to jump in the log file where the error has happened
output HTML report
output JUnit report
systematic logging (verbose always on), but output log in a file
choose how to run your test:
run tests in parallel using processes (auto-detect number of CPU and run as many worker processes)
run tests concurrently using threads
use the old sequential runner
choose which test to run with a chooser that can do smart selection of tests:
simple: just run test in sequence
failfirst: run the tests that failed in the last run first and skip the success if they are still failing
some refactoring:
bracket: use a registration in the context but easier to use
remove all useless functions in the OUnit2 interface
non-fatal section: allow to fail inside non-fatal section without quitting immediately the whole test
allow to use OUnit1 test inside OUnit2 (smooth the transition)
timer that makes tests fail if they take too long, only when using the processes runner (I was not able to do it cleanly using threads and sequential)
allow to parametrize filenames so that you can use OUNIT_OUTPUT_FILE=ounit-$(suite_name),log and have $(suite_name) replace by the test suite name
create locks to avoid accessing the same resources within a single process or the whole application (typically to avoid doing a chdir while another thread is doing a chdir elsewhere)
create a in_testdata_dir function to locate test data, if any
Still remaining to do, but quite straightforward:
sys admin (website, release process)
update the whole documentation
Some things that I decided not to do for OUnit 2.0 release:
introduce a 'cached' state to avoid rerunning a test if you can programmaticaly determine that the result will be the same.
The main development is now done, but before releasing I decided to test it first on a real scale application. The first big migration to OUnit2, will be the OASIS test suite. This is a pretty big test suite (100+ tests) that takes a fair amount of time to run. I hope that during the next week I will be able to port the whole test suite and come back with some timing results.
You can follow my progress on porting OASIS to OUnit 2.0, in github.
Help wanted
If you have a long standing issue with OUnit, this is the time to submit a bug.
OUnit BTS
If you want to try the dev version of OUnit:
$> darcs get http://forge.ocamlcore.org/anonscm/darcs/ounit/ounit
Patches always welcome.
You can read the documentation of the devel version the website.
The third lesson of the Arte y cultura en circulaci n: crear y compartir en tiempos digitales course was quite easy, at least for me, as it's one of the topics I've been involved with for a long time: Authors' rights and ways to exercise them.
This lesson starts by talking about the paradoxes created in the reality beneath copyright mostly due to the zero-cost-for-perfect-copy reality we live in today, and then goes on to introduce the most widely spread licensing schemes for cultural works nowadays: The Creative Commons licensing schemes.
What I felt very interesting is that the lesson tackles the most common issues raised by authors choosing CC licensing: The Non-Commercial and Non-Derivatives restrictions. While authors are usually not very hard to convince about the virtues (and their personal benefit) in CC licensing, it's usually hard for authors to accept and relinquish the "locks" on non-derivability and non-commercial-use.
Now, as to the homework: This time, I have to admit it was a no-brainer to me. The homework was to take part of a "Licenciat n": Publish some work under a open or free license (a work of any kind; it can be text, photo, video, etc.; it can be a new or a pre-existing work) and argue as to why did you choose said license.
Even the act of writing this blog post means I'm releasing some work. The bottom of my blog reads, All the material found at this site is freely available, and you can use it as you wish, except when the document mentions explicitly different conditions. Yes, this is not a widely known, preexisting licensing scheme, and more or less goes along the lines of CC0 There are some good things I have posted in this blog, some things I am proud about. This post goes more towards the average quality: Not adding anything of great value to the world, just reiterating/reposting what is already said. But I know this blog is syndicated over several different places, and its content might be copied over to other places. I don't need to know or be notified about it. I just care for people to be able to reach back if they want to do it.
But, of course, if I'm asked to do a homework, I prefer not to have it so self-referential. What else to license?
We are over halfway across the Wiki Loves Monuments contest for 2013. This year I am clearly not as active on it as I was last year, but yesterday I uploaded about 60 photos from our recent trips, from historical monuments in some towns/cities within ~150Km of Mexico City: Puebla, Tlaxcala, Cacaxtla, Toluca, Santiago Tianguistenco. I intend to upload more. Those photos are licensed CC-BY-SA. Why? Mainly, because it is the defaul for the contest. One of the lessons learned working on Debian is that the less the license I choose deviates from what the upstream authors of a larger project prefer, the more useful my work will be. And being Wikimedia a host of many related projects, I prefer to completely abide by their recommendations unless there is a real, strong reason not to do so.
Also, I know that at least most the photos I am uploading are not of contest quality (although some are quite nice, but we don't take that long to take a shot, and our camera is probably too basic to get a quality shot, if not by mere chance). I am using the WLM contest as an excuse to categorize and upload my pictures Of course, I'm not including personal photos, but... If I found a building, place or landscape interesting enough to take a photo of, why not make said photo available for whoever needs it, in a canonical, easy to reach media repository (as Wikimedia Commons) is)?
And finally, I think it's time to start getting more open and forward-going with a project that I have been giving a lot of work during the past year, a project that has been even eating quite a bit of my Debian time: My upcoming book. While this book is not yet freely licensed (it is freely distributed online, but does not yet have an explicit license, and I mention it on my teaching/project page. Why? Because it still has some figures and data which are not mine, and which I have to re-elaborate to be able to legally license it.
But anyway I am writing a book on the subject of Operating Systems, and am basing my teaching on it. The first semester was basically hell for me, as I was working almost full time on it, and needed to allocate some time as well to the rest of my formal work. This second semester has been quite smoother. And there is a very important (to me) initiative to which I (or should I now start saying, we) submitted this work: The LATIn Project: An initiative to collaboratively create quality, freely redistributable text books for the university level, natively in Spanish, for their use in Latin American countries.
I was not able to propose this book due to some formalities Projects have to be proposed by professors in participant universities, and UNAM is not one of them. However, I offered this work to people in the Universidad Nacional de Rosario, Argentina, and they managed to push the project forward. Together with people from Universidad Aut noma de Aguascalientes (M xico) and Universidad del Cauca (Colombia), the project was approved by LATIn.
And this LATIn project can also be seen as a why do you agree to license your work this way? candidate: I have already written most of what I'd be happy to call a full book. Of course, I do expect my colleagues to chime in with more content, and I expect us to produce a true collaborative project. But as I am not part of the member universities, they will get paid for their contribution And not me. What do I have to gain from this?
More than anything else, the circulation of my work. I'm sure that, were I to publish from UNAM, I would have a good projection. I was (am!) thinking of looking for opportunities to present the book to teachers on the subject, as well as to computing engineering/science students, but the most attractive part (for me) for LATIn is that part of the prize will be that the book will be used to base work on for teaching at least during 2014 in the three said universities And of course, my/our work will only start then, as we will have to further circulate the work.
Anyway... I expected this post to be small. But as you can see, I am happy with important work perspectives :-)
One of the earlier examples of students using MIT computer resources
to lay the groundwork for a later commercial endeavour, Zork was
originally written in a LISP derivative called MDL.
This was later tuned into the Zork Implementation Language, a domain
specific language that was compiled to target the Z-machine rather
than a specific piece of hardware. Combined with machine-specific
Z-machine interpreters, this allowed rapid porting of games to a wide
range of platforms - the only thing that needed to be rewritten was
the interpreter, and that could be reused for any future games running
on the same hardware.
Infocom were eventually acquired and killed off, but fan interest in
their games continued. New Z-machine interpreters were written in
order to allow their games (including Zork) to be run on platforms
that Infocom had never targetted. One of the best known is Frotz. This has the advantage
of being (a) portable and (b) including a "dumb" UI that makes no
assumptions about the availablity of any vaguely useful
functionality. Like, say, a Curses library.
So, Frotz seemed like the natural choice when this happened. But despite having a set of functionality that makes it look much
more like an OS than a boot environment, UEFI doesn't actually expose
a standard C library. The EFI
Application Development Kit solves this particular design
decision. Porting Frotz ended up involving far more fixing up of Frotz
bugs that tripped up -Werror than anything else. One note, though -
make sure you include DevShell in the list of required packages at
build time, otherwise file i/o will mysteriously fail.
The tying of file i/o to the shell protocol unfortunately means that
Frotz can't be directly launched by the firmware. The Boot to Zork images
therefore contain a UEFI shell in the standard boot location
(\EFI\BOOT\BOOTX64.EFI) which is executed when the firmware attempts
to boot the device. The shell then looks for a file called
"startup.nsh" in the root directory of the boot device and executes
it. Unfortunately this doesn't actually set the shell equivalent of
the current device, and so just launching Frotz from startup.nsh fails
when Frotz can't open the Zork data file. The solution for this is
simple, if ugly - the script walks through the list of devices,
looking for one that contains ZORK1.DAT in the root directory. It then
changes to that device and launches Frotz. If Frotz exits, it then
resets the system.
This could be avoided by doing some more work and turning Frotz into a
more UEFI-native application. Teaching Frotz to make native UEFI calls
would avoid the requirement for the shell protocols, and the firmware
provides a mechanism to obtain the path of the currently running
executable which would avoid the need to explicitly locate the
device. But I'm lazy and this was a "I'm spending the day on a plane"
project initially inspired by a Sazerac-fuelled conversation during
the UEFI plugfest, not a demonstration of UEFI best practices.
UEFI Boot To Zork and the source code to the modified Frotz can be downloaded here.
Review: Throne of the Crescent Moon, by Saladin Ahmed
Series:
Crescent Moon Kingdoms #1
Publisher:
DAW
Copyright:
January 2013
ISBN:
0-7564-0778-8
Format:
Mass market
Pages:
367
Doctor Adoulla Makhslood is the last ghul hunter in Dhamsawaat. He's an
old man, and tired, and increasingly uncertain whether he wants to
continue putting his life in danger to fight one more fight. But there
are no replacements; his young and idealistic dervish apprentice, despite
obvious skill, is too inexperienced and uninterested in the knowledge and
investigation that makes Adoulla so good at what he does. So, when a
young boy shows up on his doorstep, a survivor of a vicious ghul attack,
he goes hunting once again. And both finds something much darker and
stronger than he expected and meets an unexpected ally: a shape-shifting
girl who is herself a survivor of something far worse than ghuls.
Throne of the Crescent Moon is a first-novel fantasy that has made
quite a splash, including a Hugo nomination (although I thought a win was
unlikely, and I was right). One of the more interesting comments I've
read about it was the observation by
Jo Walton that if it had come out in 1980, it would have been an
amazing, unusually wonderful, non-normative book. That it isn't is
evidence of the changes in fantasy since then. The field has grown.
As you might guess from the publisher's insistence on comparing it with
The Arabian Nights, and from the names mentioned above, this book
is set in an unspecified Middle Eastern culture and draws heavily from its
mythology. It does not contain any western characters; the entire story
is native to its region. The same is true of the mythology, which gave it
a refreshing originality for me. And while I'm not the best one to judge,
the presentation of that setting seemed free of the tint of the exotic.
People live here, there are factions and multiple cultures, and the
supernatural is a backdrop to most of the city.
This would be very unusual decades ago. It's a bit less unusual now, and
the story itself is a familiar ensemble fantasy, if refreshingly free of
extended map exploration journeys. Ahmed brings together five characters
with very different backgrounds and throws their varying talents at a
problem. A few of those elements are a bit too familiar: female
sexuality as a threat to male power is a world-building element that I
could do without, for example. I also found the villain completely
inadequate in its unidimensional evil (reinforced with a few more torture
scenes than I needed to read), and even the attempted complication felt
too predictable to me.
Except for one touch of perspective, I'd call Throne of the
Crescent Moon a competent, enjoyable, but somewhat forgettable fantasy
novel, albeit one that's refreshingly concerned with a city instead of
countrysides and travel. That touch is in the age of several of the
protagonists. We get sections following several of the main characters
in tight third person, but Adoulla is the first protagonist and the focus
of much of the book. And Adoulla is neither young nor inexperienced,
and is not going through the typical fantasy bildungsroman.
He's old, experienced, a bit set in his ways, cranky, cantankerous, and
deeply in love with his city. In tone, this shifts the story towards
Star Wars as seen through the eyes of Obi-Wan Kenobi instead of
Luke Skywalker. And that change I really liked, and would be happy to see
become more common in fantasy.
There was a bit of a downside for me in three of the five main characters
being older. At times, Throne of the Crescent Moon has an elegiac
tone, a feeling of life, power, and time slipping away and cultures and
ways of life being lost. That's not my favorite thematic element. I tend
to find it more depressing than I really want in my reading. But, here,
the mature perspective more than makes up for some occasional negativity.
I particularly liked how the older characters treated the likely budding
young romance, which would have been the center of many books in this
genre, with bemused detachment and playful encouragement without giving it
more significance than it deserves. There's another romance that ends up
being more significant, and which needs the weight of time and well-lived
lives to become so.
I don't think this book deserves a Hugo, but it is an enjoyable fantasy
with some interesting characters and a refreshing perspective and setting.
The villain really isn't adequate to the story, there's a bit too much
torture for my liking, and I could have done without a few of the tropes,
but it's a solid entry in its genre and a pleasant few hours of reading.
And despite being advertised as the first of a series, it comes to a
satisfying conclusion.
Rating: 7 out of 10
On a regular basis, I find myself the odd-man-out when it comes to talking
about how to work with Python on Debian systems. I'm going to write this and
post it so that I might be able to point people at my thoughts without having
to write the same email in response to each thread that pops up.
Turns out I don't fit in with the Debian hardliners (which is to say, the
mindset that pip sucks and shouldn't exist), nor do I fit in with the Python
hardliners (which is to say apt and dpkg are out of date, and neither have
a place on a Development machine).
I think our discourse on this topic has become petty and stupid in general.
Let's all try to step back and drop a bit of the attitude.
pip doesn't suck, and neither does apt.
The truth is, both sides are wrong. As with any subject, the real
answer here is much more nuanced than either side presents it. I'm going to
try and present my opinion on this, in the way that both my Pythonista self
and my Debianite self see the issue. Hopefully I can keep this short, to
the point, and caked with logic.
The case for dpkg (the Debianite in me)
In defense of dpkg and apt, imagine having to install python-gnome2
on all your systems when you install. It'd be hell on earth.
Imagine having a user try to do this. It's insane to assume that
end-users will be using pip for this purpose.
pip is fun and all, but it's also installing 100% untrusted code to your
system (perhaps as root, if you're using pip with sudo for some reason),
and hasn't been reviewed for software freeness, which is something Debian
(and Debian users) take seriously. This isn't even to mention the hell that
pip wreaks on dpkg controlled files / packages.
Try to remember how much of your system running (yes, right now) is running
because of Python or Python modules. Try to imagine how much of a pain in
the ass it'd be if you couldn't boot into GNOME to use nm-applet to connect
to wifi to pip install something. I'm sure even the most extreme pip'er
understands the need for Operating System level package management.
Debian also has a bigger problem scope - we're not maintaining a library
in Debian for kicks, we're maintaining it so that end user applications may
use the library. When we update something like Django, we have to make sure
that we don't break anything using it (although, to be honest, the fact that we
package webapps is an entire rant for later) before we get to update it to the
newest release.
Hell, with a few coffees, I could automate the process of releasing a .deb
with a new upstream release, 100% unattended. I won't, however, since this is
an insane idea. Let's go over a brief list of things I do before uploading a
new package:
Review the entire codebase for simple mistakes.
Review the entire codebase for license issues.
Review the entire codebase for files without source, and track down
(and include source for) any sourceless files (such as pickle
files, etc).
Get to know the upstream, get to know open bugs, write something using
the lib, in case I need to debug later.
Install the package.
Test the package.
Work out any Debian package issues (this is easy).
Now, a brief list of things I do before I update a package:
Review the changes between the last uploaded version (in diff format, if
it's sane, otherwise get the VCS and review), ensure all the above are still
OK.
Review for Debian-local issues (such as how it will upgrade, using
piuparts, and adequate, etc).
Check to make sure it won't break any reverse dependencies.
Review for bugfixes that I might need to bring back to the stable release.
Figure out if I should (or even can) backport the package, if API is
stable.
Review for bugs (upstream or in Debian) that I need to mention in the
debian/changelog.
Clearly, this isn't a quick-and-dirty task. It's not a matter of getting a
package updated (technically), it's a much more detailed process than that.
This is also why Debian is so highly regarded for its technical virtuosity,
and why the
ISS decided to deploy Debian in space,
despite other commercial distros such as Red Hat, or Ubuntu, and
community distros, such as Fedora or Arch.
It's also not Debian's job to package the world in the archive. This is an
insane task, and it's not Debian's place to do it. We introduce libraries
as things need them, not because we wrote some new library that someone
may find slightly useful at some point in the future. maybe.
Upstream developers and language communities (not only Python here) tend to
lose sight of why we're doing this in the first place, which
is our users. This isn't some sort of technical pissing contest to see who can
distribute the software in the best way. Debian-folk always keep end users
as our highest priority.
I quote the
Debian Social Contract, when I say
that Our priorities are our users and free software. No one's trying to
get developers to use dpkg to create software. In fact, as you'll see
below, I actively discourage using system modules for development.
The case for pip (the Pythonista in me)
In defense of pip, the idea that Debian will keep the latest versions of
packages is insane. The idea that we can keep pace with upstream releases is
nuts, and the idea that every upstream release on pypi is ready to ship is
bananas. b-a-n-a-n-a-annas.
As a developer, I don't want to support every release, and I surely don't want
other people depending on some random snapshot.
Often times, I'll put stuff up on pypi as a preview, or to release often, and
solicit feedback without having to give out instructions on using a git
checkout (it's also easier to have them try a version from pypi so I can
cross-ref the git tag to reproduce issues when they file them)
pypi is easy, ubiquitous and works regardless of the platform, which means
less of my development time is spent packaging stuff up for platforms I don't
really care about (Arch, Fedora, OSX, Windows), even though I value
feedback from users on those systems. The effort it takes to release something
is limited to python setup.py sdist upload, and it's in a place (and in a
shape) that anyone can use it without having 10 sets of platform-local
instructions.
Even ignoring all the above, when I'm writing a new app or bit of code,
I want to be sure I'm targeting the latest version of the code I depend on,
so that future changes to API won't hit me as hard. By following
along with my dependencies' development, I can be sure that my code breaks
early, and breaks in development, not production. Upstreams also tend to not
like bug reports against old branches, so ensuring I have the latest code from
pypi means I can properly file bugs.
Lastly, I prefer virtualenv based setups for development, since I'm usually
working on many things at once. This often means version mismatches in
libraries, which brings in API changes (another whole rant here as well).
I don't want to keep installing and uninstalling packages to switch between
the two projects, and using a chroot(8) means a lot of overhead and that it's
disconnected from my development environment / filesystem, so I resort to
virtualenv to isolate my Development environment.
Final notes
I don't want to keep arguing about this. Just accept that the world's a big
place and that there exist use-cases that both apt and pip need to exist
and work in the way they're working now. At the very least, try and understand
there exist smart people on both sides, and no one is trying to screw anyone
over or keep their own little private club to themselves. Hopefully, going
forward, we can make sure that the integration between these two tools gets
better, not worse.
Help make this dream a reality. Contribute to a productive tone, not a
destructive one. In short:
Use pip without sudo always. Don't tell people to use sudo.
Use apt or dpkg when deploying system-wide.
Understand people are going to package, and they will be more concerned
about software using your library then keeping your library up to date.
Understand Debian Developers and package maintainers have to do a lot of
work when updating or sponsoring an upload.
Understand upstream developers can't be bothered to fix every issue
with every release (release early, release often) with some snapshot
you introduced into unstable.
Use pip and virtualenv in development setups, so we can upgrade your
app when we upgrade the lib.
I have just uploaded Lintian 2.5.18 to unstable. While fixing 22 bugs, it only features 5 new tags.
debian-changelog-has-wrong-weekday
debian-rules-missing-good-practice-target-dfsg
empty-udeb-package
file-name-in-PATH-is-not-ASCII
misplaced-extra-member-in-deb
The release also include fixes to some false-positives, such as python:any dependencies triggering python-script-but-no-python-dep, a rewritten README file. We also included a patch to make Lintian accept the Original-Maintainer field by default for non-Debian vendors (even if they do not have a profile and Lintian ends up loading the debian/main profile).
We also added support for running Lintian directly from a git checkout or source tree without setting LINTIAN_ROOT (or passing root). Since that was the primary use-case for root that option has now been deprecated. I also had lintian and lintian-info require the include-dir and [no-]user-dir options as the first if given at all.
I would like to thank Bastien Roucari s, Gaudenz Steinlin, Gunnar Wolf, J r my Bobbio and Lucas Nussbaum for contributing to Lintian and the many who submitted reports or suggestions for improvements. I would also like to thank Brian hugmeir Fraser, who assisted me in identifying and working around a bug in Perl s glob function when run under threads (filed upstream as RT#119897).
Well at least he should be according to Sartre though I am not entirely convinced the repercussions of my choice to manufacture another folding chair were entirely thought through.
After my most recent posting the urge to do "just one more iteration" became too great and I succumbed. I therefore present version 4 of my folding chair which corrects all the previously discovered issues.
The popliteal height (420mm) and buttock popliteal length (400mm) are both comfortable for a wide selection of people. The seat slopes a few degrees front to back and the back rest no longer comes further forward than the rear of the seat.
There is a small gap above where the seat folds in when flat but that is only an aesthetic issue when being stored.
Manufacture wise the design is simple to produce although I really will have to teach our CNC router how to use the round over bit to reduce the finishing steps as currently that takes longer than the CNC operation.
In future if I make more of these I will use this design and, once she is less annoyed at me for making another chair, I am going to consult with my wife on adding some cushioning material to the seat and backrest.
And of course that concludes my furniture making for a while...yeah, right!
there have been comments which have complained about my usage of space on sheets and suggested I waste too much material. That is probably true and in my own defence I have not been working with this machine for very long and am not quite used to what I can "get away with" yet.
I was looking at the sheet after removing the last chair design and had a thought, I had not attempted a side X type folding design and perhaps I could squeeze one into the offcuts? I kinda got carried away, it roughly went:
Measure the available offcut space
Measured the remaining 18mm dowel leftover from my dowel hinge experiments
Found the largest width and height area I could get out of the sheet the CNC router ruined.
Sketched a design
Capture design to a DXF
Carefully spread the pieces over the available material in the CAM software
Generate a toolpath.
Cut material
If all of that sounds like and utterly mad way to design a size X stool, you are of course correct, but it worked, and it was a very fast process taking less than four hours from idea to stool.
There are a couple of issues:
the popliteal height is 470mm ( I was aiming at 420 and missed...badly)
It uses a lot of expensive hardwood dowel (1373mm plus cutting width and only way I could get it accurate was to use the disc sander to remove fractions till the length was correct)
I used pockets for the interference seat joints rather than through cuts and discovered that you need to allow tolerance depth (the pegs are 10mm deep and the sockets need to be at least 10.2 not the 10mm I cut)
Dowel joints are great but have a small surface area so friction fit joints work loose.
The seat went together dry fit and Paul tested it for me, however that last issue soon made me realise that this time I was going to have to resort to glue. Yes, sorry, this design needs to be glued to remain stable (I know plywood contains glue...please stop telling me that).
It is pretty simple to put together and aside from needing half the clamps in makespace to hold it in place while the glue dried, I had no trouble.
Though this is definitely not a case of use glue "sparingly" I put generous amounts in all the dowel joints and all the seat slots and got very little ooze so I guess it could have used more.
The final varnished stool is pretty robust but folds up nicely the concept of hooking to its own pivot dowel means it stays closed when flat which makes it very portable.
Total cost was an estimated 10.00 ( 4.25 dowel, 2.50 of 24mm ply, 1.75 for 18mm ply, 0.50 tool wear, 1.00 varnish) though the materials in my case could be argued to have cost nothing.
It has been suggested that I could make an entire picnic table and chairs set this way but if I did I would reduce the stool height by 50mm and examine ways to use less dowel.
Or in this case my final (and yes I am going to do something else next) chair design. It is based on the stool, in fact it is the stool design with the outer legs extended and a back rest added.
The modified design reduces the dowel requirements to 775mm but requires a bit more sheet material (cannot get this one entirely from offcuts).
Total cost was an estimated 10.50 ( 2.50 dowel, 4.50 of 24mm ply, 1.75 for 18mm ply, 0.50 tool wear, 1.25 varnish).
Because it is based on the stool design it suffers from the height issue and in addition the back rest is a bit far back to be completely comfortable.
Neither of the side X designs have flaws that interest me enough to follow the iterative approach again to solve them. Both the designs work well enough and rounded out my adventures with folding chairs and indeed furniture for now.
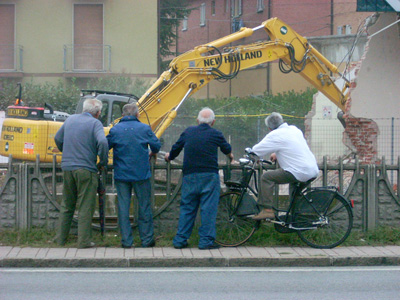
Umarell /uma'r l/ (oo-mah-rell), n; pl. Umarells. People in a community who
offer all sorts of comments to those who are trying to get some work done,
but who are not doing any work themselves.
Etymology and further details
Umarell is a word that entered Italian slang in Bologna and is spreading to
nearby towns, occasionally even across Italy. It comes from the
Bolognese for "cute/odd
little man".
"Umarells" are those people, usually retired men, who spend time watching
construction works, often holding their hands behind their back, occasionally
commenting on what is going on, sometimes trying to tell the workers what to
do.
It's easy to find exampleson theinternet; the word was popularised
by a blog collecting photos, which has even
been published into a book.
With some Italian Debian friends, we realised that umarell is the perfect
word to describe those people in a community, who offer all sorts of comments
to those who are trying to get some work done, but who are not doing any work
themselves.
I think that it is a word that fits perfectly, and since I'm likely going to
use it blissfully anywhere, here is a page that temporarily explains what it
means until the Oxford English Dictionary picks it up.
I ve been running several Deb-o-Matic instances on several servers since ages. This service, meant to provide a way to automate the build of Debian source packages, has been the starting point for a lot of Italian developers to start packaging, and eventually become Debian or Ubuntu developers. I can t exactly tell how many packages Deb-o-Matic servers have built so far, but it has been the primary build and test environment for at least three Debian Developers since four years.
This service was hosted for free since the beginning, but the good things always come to an end. My provider decided they cannot keep our servers running (its core business is totally unrelated to hosting servers), and asked me to shut them down. I started with the two kfreebsd-* machines, and soon I will shut down i386 and amd64 as well. When all services will be down, I ll take care of removing the debian.net domains I created for them.
Deb-o-Matic development won t stop, but developers who used Deb-o-Matic daily will have to find a different solution to build and test their packages.
 For a while I have been eyeing with the TI eZ430 Chronos watch, a slightly bulky sports watch that not only comes with a built-in thermometer, barometer and accelerometer, but also a freely programmable micro controller (from the TI MSP430 family hence the name). In addition it has a small radio chip included and can communicate wirelessly with the computer, or possibly other devices. All in all, a very geeky toy.
A week ago I managed to buy one quite cheaply via eBay (30 including shipping). It took me a while to get an overview of the various resources about the device. Here is what I have learned.
 Here in the US, the Affordable Care Act is finally going into effect, with
accompanying drama. I managed to get signed up today at healthcare.gov.
After not having health insurance since 2000, I will finally be covered
starting January 1 2014.
Since my income is mosty
 XMir's been
 Download links often point to CGI scripts which actually generate (or
just fetch, i.e. proxy) the actual file to be downloaded, e.g. URLs
like
 This week's lesson on the
 After 1.5 month of work, I am proud to officialy release OUnit 2.0.0. This is a major rewrite of OUnit to include various feature that I think was missing from OUnit1. The very good news is that the port of the
 The migration was quite heavy because this test suite had a big design problem. It uses in-place modification of the test data. I think I pick this design because I thought this was a good idea to decrease the running time. As a matter of fact, this was a huge mistake, that keeps popping failed test cases because one of the previous tests was failing. I have refactored all this and now we start by copying the test data into a temporary directory, which ensure that everything is always starting from pristine test data.
During the redesign, I have decided to reduce the number of tests by merging some of them. This should have no big impact on the running time, although this is not as pure 1:1 comparison with OUnit v1. Although it is still testing exactly the same thing. This explain the loss of ~50 tests, which in fact has been merged in other tests.
The overall speedup is 4x compared to OUnit v1, when using processes. However there is a 12% increase compared to OUnit v1 for sequential and a 15% increase when using OUnit v1 compatibility layer. While this is not very good score, I hope this is small enough to compensate the huge win of being able to run tests in parallel with processes.
And now the magic !
At this point, if you read carefully the numbers, you would have noticed that there is a 4.5x decrease in speed when you compare sequential and 4 processes for OUnit2. Since we are only actively testing in 4 shards, it looks strange. I don't expect a super-linear speedup due to the use of processes. I have checked that every tests was indeed running and found no solutions to this mystery. Right now, I think this is due to the fact that we are running less tests in more processes which should lighten the load of the GC (which may not trigger at all). I am not sure about this explanation and will welcome any bug report which shows a problem in the implementation of either sequential or processes runner. Although, this is great.
Help still wanted
If you find any bugs with OUnit v2, this is the time to submit a bug.
 A new version of

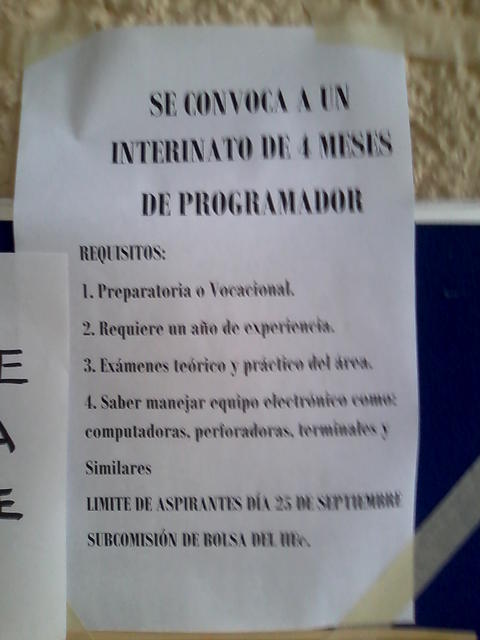
 On a regular basis, I find myself the odd-man-out when it comes to talking
about how to work with Python on Debian systems. I'm going to write this and
post it so that I might be able to point people at my thoughts without having
to write the same email in response to each thread that pops up.
Turns out I don't fit in with the Debian hardliners (which is to say, the
mindset that


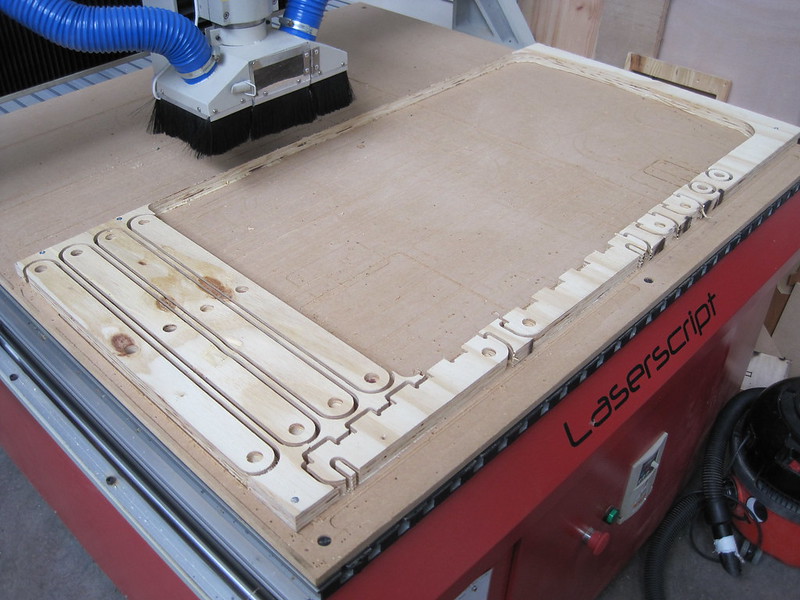

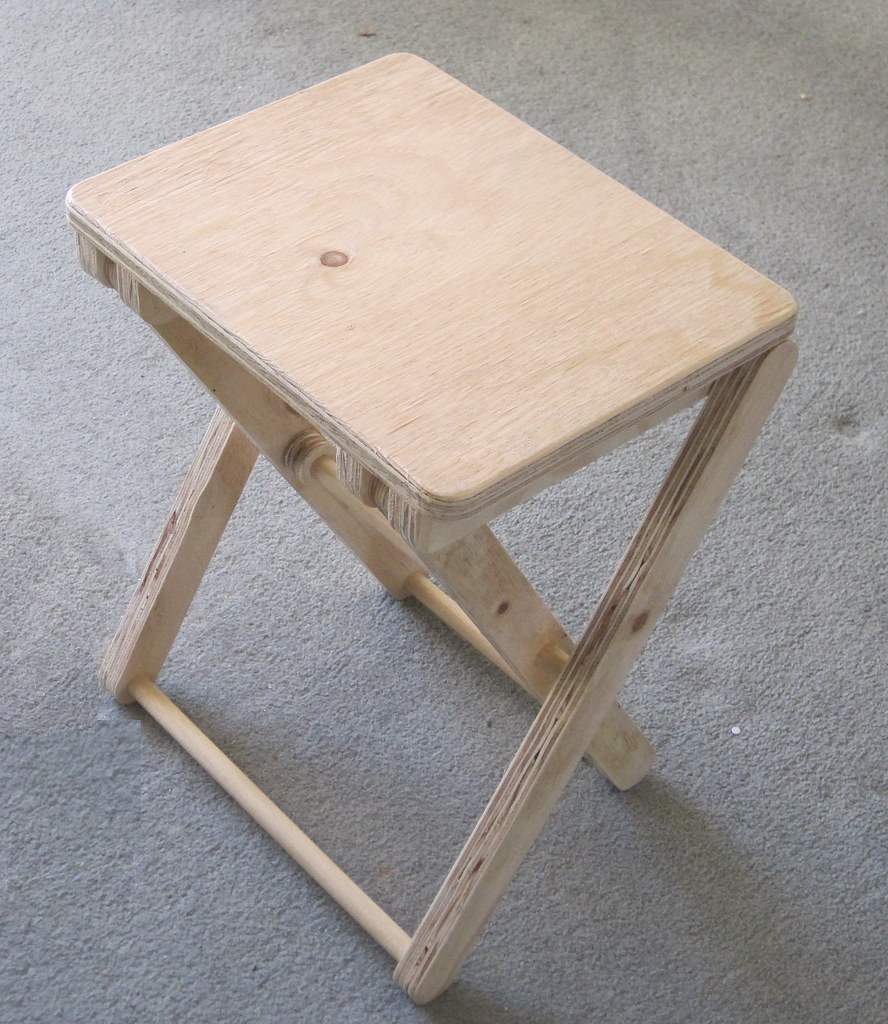
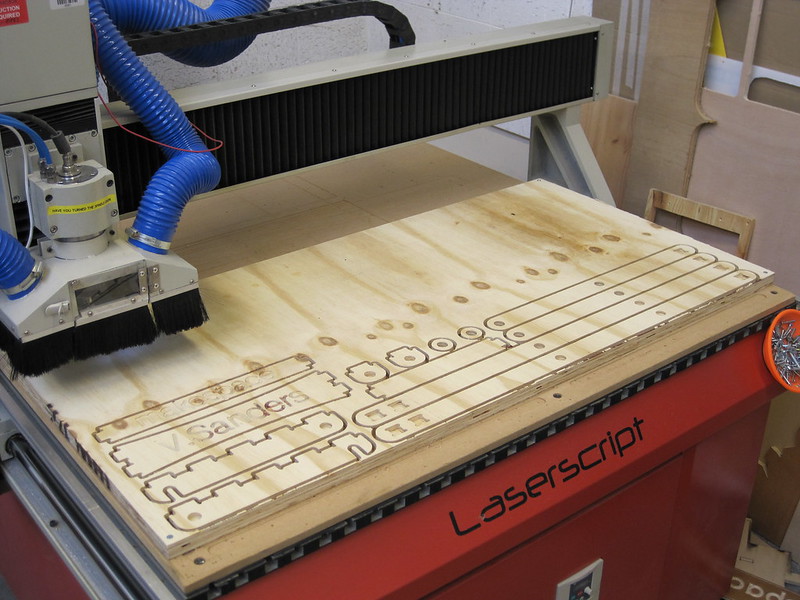
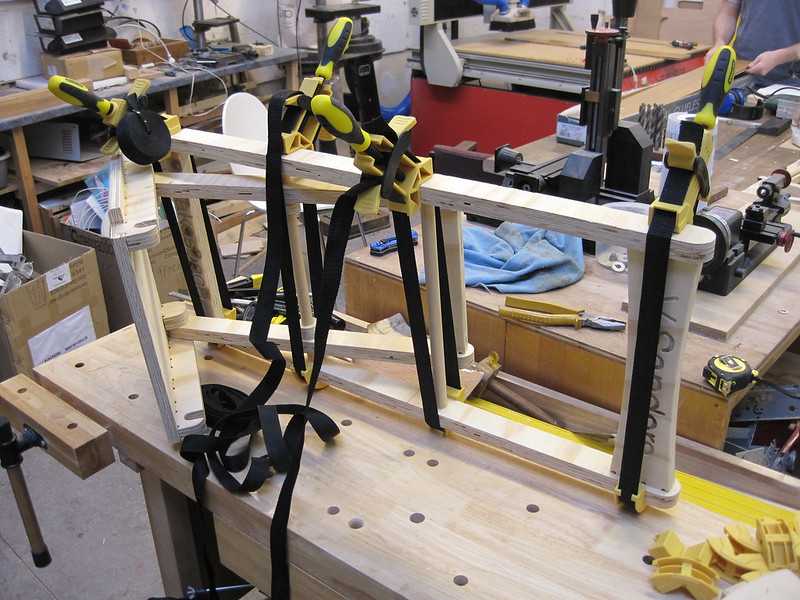
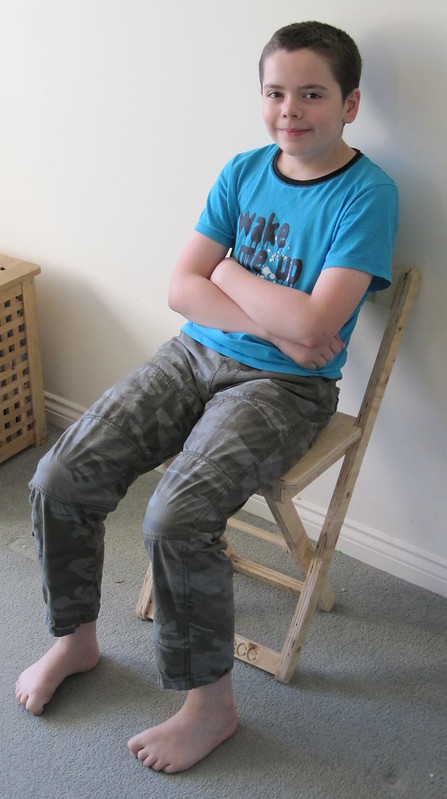
 I ve been running several